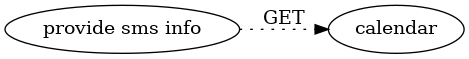Search Results: "will"

3 October 2012

Petter Reinholdtsen: Why is your local library collecting the "wrong" computer books?

I just read the blog post from Tim Retout about the computer science book collection available in his local library, and just wanted to share my comment on his theory about computer books becoming obsolete so soon. That is part of the reason why the selection is so sad in almost any local library (it is in mine too), but I believe the major contributing factor is that the people buying books to the library have no way to know a good and future computer classic from trash. And they need to know which one will become a classic in the future, as they would normally buy one of the recently published books. During my university years, I worked for a while at the university library, and even there the person in charge of buying computer related books (and in fact any natural science related book), did not know enough about computers to make a good educated guess. Once, just before Christmas, they had some leftover money on the book budget and I was asked if I could pick out a lot of computer books in the university book store, for the library to buy for their collection. I had a great time picking all the books I dreamt of buying and reading, and the books I knew were classics (like most of the Stevens collection). I picked several of the generic O'Reilly books (ie documenting protocols, formats and systems, not specific versions of products) and stayed away from the 'teach yourself X in N days' class. I had a great time, and probably picked out more than a hundred books for the library that evening. The sad fact is that there is no way a overworked librarian is going to know that for example The Practice of Programming is a must-have in any computer library, and they will most of the time end up picking the wrong books to buy. Perhaps you can help your local library make better choices by giving the suggestions for books to get? I know they would love to hear from you, even if their budget might block them from getting your favourite book right away.

Kumar Appaiah: A backup workflow with bup

It's important to back things up. You should also make your life easier by using some good software. I use obnam for some backups, but I wanted to try out bup for a new backup workflow I needed. I will describe the workflow here.The situation: I have a laptop with things to be backed up. I also have a Raspberry Pi which I use as a network attached storage (it has a 1 TB external drive attached to it) and runs Raspbian Wheezy on it. Naturally, you can do this on any NAS running some GNU/Linux variant. In addition, I also have an external portable USB hard disk where another backup copy will be stored. How do I automate this?Here is how I went about this process. First, for the Raspberry Pi:
  1. First, identify the directory or directories to be backed up. To keep this simple, the directory I am backing up is /home/kumar/Work.
  2. On the Raspberry Pi, install bup. If you want to build it from the git clone, you would need python-dev, and pandoc for the documentation.
    sudo aptitude install pandoc python-dev
    git clone git://github.com/apenwarr/bup.git
    cd bup;make;sudo make install
    
  3. Initialize the backup directory on the Raspberry Pi:
    BUP_DIR=/home/kumar/BACKUPS bup init
    BACKUPS is the place where bup is asked to store the backups (much like it's analogue of .git). You can store all your backups within this directory, and you can still classify backup sets within this directory with different names (much like git branches).
  4. On the local machine, initialize the backup directory.
    bup index -uv /home/kumar/Work
  5. Back it up. This will take time the first time, if the Work directory has several contents within it.
    bup save -r kumar@<raspberry_pi_ip_address>:BACKUPS -n workbackup /home/kumar/Work
    
    workbackup is the name of the backup set. This can be paperbackup or databackup or notesbackup so that several classes can be backed up within the BACKUPS directory.
  6. Now, you have backed things up. Make changes in the Work directory. For instance, add/edit/remove/move some files.
  7. Rerun the index and save commands from steps 4 and 5 above. Enjoy the speedup and ability to rewind to the previous state.
  8. Test restoration of ONE directory of backup (just to save time) on Pi itself directly on the Pi:
    bup -d /home/kumar/BACKUPS/ restore -C /tmp/ /workbackup/latest/home/kumar/Work/offset-coupling-params
    
    Then scp it back if you need it.
  9. Alternative: Use fuse. On the Pi:
    sudo aptitude install python-fuse
    sudo adduser kumar fuse
    mkdir Mount
    bup -d /home/kumar/BACKUPS fuse Mount
    Then cd into Mount and cp/scp the correct files wherever.
    fusermount -u Mount
    
  10. Once happy, write the bup index/bup save commands into a script and run it periodically to back up (check this at the end of the post). Have fun.
Next, to prepare the external hard disk, I went with the old-style autofs automounting solution:
  1. To automount the disk, in /etc/auto.master, add
    /auto			/etc/auto.misc	--timeout=60
    
  2. In /etc/auto.misc add:
    backupdrive	-fstype=btrfs	:UUID="7927a7ab-8c3f-4198-bd73-d3cc519a9ac3"
    
    fstype may need changing for your file system, and UUID can be found using blkid on the exact partition of the hard disk you wish to back up to.
  3. Initialize the backup directory:
    sudo mkdir /auto/backupdrive/BACKUPS
    sudo chown kumar.kumar /auto/backupdrive/BACKUPS
    bup -d /auto/backupdrive/BACKUPS/ init
    
  4. Index and back up:
    bup -d /auto/backupdrive/BACKUPS/ index -uv /home/kumar/Work
    bup -d /auto/backupdrive/BACKUPS/ save -n workbackup /home/kumar/Work
    
  5. Make changes in the Work directory. Add/edit/remove/move files.
  6. Rerun index and save commands from step 5. Enjoy the speed.
  7. Test restoration of ONE directory of backup from removable disk:
    bup -d /auto/backupdrive/BACKUPS/ restore -C /tmp/ /workbackup/latest/home/kumar/Work/offset-coupling-params
    
  8. Once happy, write the bup index/bup save commands into a script and run it periodically to back up. Have fun.
Finally, a quick script to automate all of the above.
#!/bin/sh
bup index -u /home/kumar/Work
bup save -r kumar@<raspberry_pi_ip_address>:BACKUPS -n workbackup /home/kumar/Work
if ls /auto/backupdrive/ 2> /dev/null;then
    echo Backing up to the removable disk...
    bup -d /auto/backupdrive/BACKUPS/ index -u /home/kumar/Work
    bup -d /auto/backupdrive/BACKUPS/ save -n workbackup /home/kumar/Work
    echo Backed up to the removable disk! Yay!
else
    echo WARNING: Not backing up to the removable disk
fi
What this script does it, it backs up to the NAS, and then checks if the external disk is connected. If the disk is mounted, then it backs up to that disk as well. It might be a good idea to cron or anacron this script, or have someone remind you to run this periodically. The only limitation I have is that you can't use bup restore to restore from a remote repository yet, but that isn't a huge issue for me now. In addition, metadata is not stored by the bup save/restore commands. You would have to use split and join with tar to get that. However, bup is fast moving, so I'd expect these features soon. Till then, this workflow works all right for data only backups.Although this is just a mental dump of the procedure I made for myself, suggestions for improvement are welcome. Thanks.

2 October 2012

Michael Stapelberg: Hello Planet Debian

Hello Planet Debian. This post serves as a confirmation that my feed/blog setup is working. I am a DD since a few months and will blog occasionally about my Debian activities.

Andrea Veri: An interview with Allan Day

A few days ago I had the great pleasure to interview Allan Day, GNOME designer and enthusiastic contributor. Me: Hello Allan, mind presenting yourself? Allan: I m a designer working on the GNOME Project. I ve been involved for quite a few years now. Last year I was lucky to be hired by Red Hat to work in their Desktop Team. Me: Can you tell us something more about GNOME 4? Can we alias it GNOME OS? Allan: GNOME 4 isn t something that is being seriously considered right now, at least as far as I m aware. Those of us in the GNOME Project are thinking about the future though, and have been setting some big goals for the next few years. Who knows, maybe those things will lead to a big new version? It s probably too soon to tell though. Me: Which new features will be introduced in the incoming GNOME 3.6, and what about GNOME 3.8? Allan: 3.6 is already out, so you can read the release notes if you want to find out about it. I was really happy with it, and the last release had quite a lot of new features. My personal favourites where the input sources work, the Lock Screen and the work we need on notifications and the Message Tray. Oh, and I m really pleased with the new Clocks application that we released a preview of. Members of the community are still proposing features for 3.8, so it s a little early to say what we will be working on for the next six months. I think I d be happy if we can continue to polish the core user experience, and hopefully get some more new applications off the ground. Me: GNOME Fallback is due to be completely dropped, are you in favor of that choice and why? Allan: I think that s mostly a technical discussion, and I m not a developer. Also, GNOME needs to have an open discussion about that question as a community which is something we might be doing at this year s Boston
Summit. What I would say is that it is important for us to deliver high quality user experiences, so if fallback mode isn t good enough, or if it is holding back the primary GNOME 3 UX, then we obviously need to think about what needs to happen. Me: Ubuntu has recently released the first two Alphas of the Ubuntu GNOME Remix, do you think this will strengthen the cooperation between GNOME and Canonical as in the past? Allan: As far as I understand it, the GNOME Remix is a community effort, and isn t coming from Canonical itself. That said, we always want to see more involvement in GNOME by Canonical and Ubuntu. Me: Do you see anything in the current GNOME 3 that would require an improvement? and can you add a few words about the brand new login screen recently introduced? Allan: GNOME 3 is getting better all the time, and I m particularly pleased with the latest version. That said, there is plenty of work still to do. I think the big area for us right now is to filling the missing blanks in our application story, so we have a suite of consistent core applications. That will enable people to access content more easily, and will serve as a springboard for other new GNOME applications. What to say about the Lock Screen?! Well, it was originally conceived as something that is like a screensaver, but is really really useful (rather than just looking pretty). We wanted something that looks cool when the machine is locked, but we also wanted to add plenty of features on top, like having media playback controls and built-in notifications. The idea is to make some things possible without having to enter a password, like pausing your music or checking to see if you have received any emails. Me: Many have argued new contributors most of the times aren t redirected correctly to their area of interest, thus they lose interest in contributing and leave. Do you feel anything could be improved in how GNOME welcomes new contributors? Allan: That s a good observation. I agree that one of the hardest things about contributing to open source projects is finding the right place to start. In GNOME we are working to help with this, such as through new mentoring schemes, but there is certainly more that we could do. One thing would be to run more online events, like bug days. Another thing is advertising good tasks for newcomers; we do some of that, but we could be better at it. Me: Anything else you would like to add? Allan: Just that anyone is always welcome in GNOME! That s what we re about really creating opportunities for people, having fun and making great technologies.

Andrea Veri: An interview with Allan Day

A few days ago I had the great pleasure to interview Allan Day, GNOME designer and enthusiastic contributor. Me: Hello Allan, mind presenting yourself? Allan: I m a designer working on the GNOME Project. I ve been involved for quite a few years now. Last year I was lucky to be hired by Red Hat to work in their Desktop Team. Me: Can you tell us something more about GNOME 4? Can we alias it GNOME OS? Allan: GNOME 4 isn t something that is being seriously considered right now, at least as far as I m aware. Those of us in the GNOME Project are thinking about the future though, and have been setting some big goals for the next few years. Who knows, maybe those things will lead to a big new version? It s probably too soon to tell though. Me: Which new features will be introduced in the incoming GNOME 3.6, and what about GNOME 3.8? Allan: 3.6 is already out, so you can read the release notes if you want to find out about it. I was really happy with it, and the last release had quite a lot of new features. My personal favourites where the input sources work, the Lock Screen and the work we need on notifications and the Message Tray. Oh, and I m really pleased with the new Clocks application that we released a preview of. Members of the community are still proposing features for 3.8, so it s a little early to say what we will be working on for the next six months. I think I d be happy if we can continue to polish the core user experience, and hopefully get some more new applications off the ground. Me: GNOME Fallback is due to be completely dropped, are you in favor of that choice and why? Allan: I think that s mostly a technical discussion, and I m not a developer. Also, GNOME needs to have an open discussion about that question as a community which is something we might be doing at this year s Boston
Summit. What I would say is that it is important for us to deliver high quality user experiences, so if fallback mode isn t good enough, or if it is holding back the primary GNOME 3 UX, then we obviously need to think about what needs to happen. Me: Ubuntu has recently released the first two Alphas of the Ubuntu GNOME Remix, do you think this will strengthen the cooperation between GNOME and Canonical as in the past? Allan: As far as I understand it, the GNOME Remix is a community effort, and isn t coming from Canonical itself. That said, we always want to see more involvement in GNOME by Canonical and Ubuntu. Me: Do you see anything in the current GNOME 3 that would require an improvement? and can you add a few words about the brand new login screen recently introduced? Allan: GNOME 3 is getting better all the time, and I m particularly pleased with the latest version. That said, there is plenty of work still to do. I think the big area for us right now is to filling the missing blanks in our application story, so we have a suite of consistent core applications. That will enable people to access content more easily, and will serve as a springboard for other new GNOME applications. What to say about the Lock Screen?! Well, it was originally conceived as something that is like a screensaver, but is really really useful (rather than just looking pretty). We wanted something that looks cool when the machine is locked, but we also wanted to add plenty of features on top, like having media playback controls and built-in notifications. The idea is to make some things possible without having to enter a password, like pausing your music or checking to see if you have received any emails. Me: Many have argued new contributors most of the times aren t redirected correctly to their area of interest, thus they lose interest in contributing and leave. Do you feel anything could be improved in how GNOME welcomes new contributors? Allan: That s a good observation. I agree that one of the hardest things about contributing to open source projects is finding the right place to start. In GNOME we are working to help with this, such as through new mentoring schemes, but there is certainly more that we could do. One thing would be to run more online events, like bug days. Another thing is advertising good tasks for newcomers; we do some of that, but we could be better at it. Me: Anything else you would like to add? Allan: Just that anyone is always welcome in GNOME! That s what we re about really creating opportunities for people, having fun and making great technologies.

Philipp Kern: How to maintain an OpenWRT installation

I wondered how to properly maintain an OpenWRT installation that needs to track trunk for one reason or another. For instance the OpenWRT release pace is quite slow and "new" devices or various fixes are only available in this particular branch.

Now the OpenWRT project does offer snapshot builds. These are images built with the default config for the particular device type. You can even upgrade most models using sysupgrade, which preserves a list of configuration files you specify when flashing the new image, instead of doing a dreadful tftp upload. But you still lose all the packages you installed and accumulate a bit of cruft when reinstalling them. If you do not flash new images, you will be unable to install kernel modules after a while, because the kernel version they're based upon was updated.

So what's suggested is this:
The advantage of building an image that includes all the packages is that you don't get to reinstall them and due to the use of squashfs, all files provided by those packages are actually kept in compressed form in flash. The image I built has a size of about 7 MB and contains "heavyweight" packages like isc-dhcpd, bind, openvpn (using openssl), bash, vim-tiny, tcpdump-mini, luci, and a webserver with TLS support.

As always: Take great care when you're flashing devices. The devices I bought cannot be bricked, but this might not be true for all devices that run OpenWRT. You might need and go doing a tftp image upload if something goes wrong. Check the OpenWRT wiki for instructions and possibly make your computer ready for them before starting to play with your box. For my Buffalo WZR-HP-AG300H the sysupgrade procedure is stable.

Russell Coker: Asperger Syndrome Disability vs Over Pathologising

Is Asperger Syndrome a Disability? Some people tell me that I m disabled. Usually it s an unstated implication such as referring to Asperger Syndrome as a disability with the assumption that I ll agree. One time I had someone assume that I had never had a paid job because they knew I m an Aspie, maybe I should boast more about my career successes. One interesting take on this is represented by Maco s bost about Disablism/Ablism where she says Vocab note: A person has an impairment. Society s treatment of that impairment is what disables the person [1]. The same concept is presented by BRAINHE in their Social Model of Disability document [2]. The Wikipedia page on Ableism says The ableist worldview holds that disability is an error, a mistake, or a failing, rather than a simple consequence of human diversity, akin to race, ethnicity, sexual orientation or gender [3]. This is fairly close to the position that Neurodiversity [4] advocates take on Autism. Jaarsma P and Welin S wrote an interesting paper titled Autism as a Natural Human Variation: Reflections on the Claims of the Neurodiversity Movement [5] which considers these issues in depth and comes to the conclusion that High Functioning Autism (for which Asperger Syndrome is generally regarded as a synonym) is a difference while Low Functioning Autism is a disability. I think that generally we should accept the opinion of the person in question. Someone who is unable to communicate or is too young to make an informed decision could have their disability status determined by carers. But anyone who is capable of making an informed decision and communicating it should have their opinion respected. I am not going to argue with any of the people who claim that they are disabled due to an Autism Spectrum Disorder. But I don t think that I am disabled and I think that people shouldn t argue with me about this. Over Pathologising Lynne Soraya wrote an interesting article for Psychology Today about one aspect of the supposed over-diagnosis [6]. She responds to Paul Steinberg, a psychiatrist who made a number of claims about Asperger Syndrome which lack evidence. Paul s main idea seems to be that anyone who has social problems but who seems to be successful regardless shouldn t have an Autism Spectrum diagnosis and he claims that such people should be regarded as having a social disability instead. His main idea seems to be that having a diagnosis is a bad thing, but his idea of having a social disability diagnosis instead doesn t seem so great. In many other discussions I ve seen people claim that a large number of diagnosis of anything is a problem. Their idea seems to be that the vast majority of the population shouldn t have a diagnosis for anything and that whenever a significant number of people are diagnosed with a psychological condition (and 1% of the population seems to be a significant number) then it s a problem. I don t think that having a large portion of the population diagnosed is necessarily a problem, I think that it would be OK if the majority of the population was diagnosed with something. The issue is not whether people are diagnosed but what happens after the diagnosis. When a child is diagnosed their parents can help them deal with whatever the issues are this may or may not require further involvement with psychologists or special schools. For the milder cases (of Autism, ADHD, and other conditions) merely knowing what areas will cause difficulty and teaching kids how to deal with them will be enough to solve many problems. When someone is diagnosed as a child but doesn t have obvious symptoms as an adult that is more likely to be an indication that they were taught good coping mechanisms and protected from bad situations as a child not that the diagnosis was wrong. There are some serious issues with special schools and psychiatric drugs, but diagnosis doesn t necessarily imply mistreatment and avoiding a diagnosis is not the correct way to avoid such mistreatment. When someone is diagnosed as an adult they have to learn to deal with it. The general lack of psychologists (waiting times as long as 6 months are common) and the fact that most psychologists won t do any good for someone on the Autism Spectrum is a real problem. But merely knowing the source of your problems is a major step towards alleviating or solving them. One of the arguments that is commonly used against so-called over-diagnosis is that adults don t show apparent symptoms. The issue here is that with some effort and planning adults on the spectrum can act like NTs. Acting like an NT doesn t imply being an NT, it usually requires a lot of ongoing effort that could be applied to other things if society didn t expect us to act like NTs all the time. Conclusion I wish people would stop telling me that I m either disabled or too high functioning to be on the Autism Spectrum. I will never think like an NT and I don t want to, so I ll always be an Aspie. By most objective measures I m at least as successful as the general population in all things that require social skills, so unless something like always losing at Poker is considered a disability I don t think that it s reasonable to consider me to be disabled. It would be nice if I could lock the people who claim that Autism is always a disability in a room with the people who think it s over-diagnosed and let them debate it, no matter which side lost the debate the result would be good! Update: I removed a broken link to a Youtube video, I published this post from a 3G connection and didn t test that the Youtube link still worked. For some reason the author had marked it private since the last time I visited it. Related posts:
  1. Autism vs Asperger Syndrome Diagnostic Changes for Autism Spectrum Disorders Currently Asperger Syndrome (AS)...
  2. Is Asperger Syndrome a Good Thing? A meme that keeps going around is that Asperger Syndrome...
  3. Autism Awareness and the Free Software Community It s Autism Awareness Month April is Autism Awareness month, there...

Joachim Breitner: Dennis Felsing s thesis on ghc-vis submitted

Last week, my first student ever submitted his bachelor thesis Visualization of Lazy Evaluation and Sharing about a tool he created that allows you to investigate the heap of a running Haskell program, including unevaluated values and their sharing properties, in a visual and interactive manner. You can see it in action at the end of the video of my lightning talk about ghc-dup at the Haskell Implementors Workshop this year, and read more about it on Dennis ghc-vis web page. I m quite happy about the result and I think I can get used to have other people implement my ideas and needs :-) Dennis said he is willing to continue the maintenance of the tool, so give it a shot and bombard him with bug reports and feature requests!

1 October 2012

Andrew Pollock: [opinion] On helicopter parenting and strangers in day care facilities

It appears that a recent incident at a different campus of the "preschool" (I call it day care) that Zoe goes to has gotten the attention of the Free-Range Kids blog. Firstly, I need to say that on the parenting spectrum, I definitely self-identify closer to the free-range end than the helicopter end. I'm not sure that I'd let an 8 year old ride the New York subway on their own, but Zoe's not 8 yet, so I really can't say. Sarah and I received the same email that is reprinted on the blog, on Friday night, and we were both (very) mildly alarmed at the situation, but not particularly concerned, mostly because it wasn't the facility that Zoe goes to. I'm not sure I'd be that much more concerned if it was, to be honest. I did like the statistics that the parent quoted in response. I thought that that put things into perspective, but didn't really take abductions by estranged parents into consideration. My one reaction to reading the email was, "why did they wait until after the incident to escalate it?" but then, from my own experiences in dropping off or picking up Zoe, I could totally understand not all the staff knowing on sight all the parents or guardians that do pickups and drop offs. This does lead to one asking how they know who to buzz in, but that's another can of worms. Anyway, I read the 50 or so varyingly indignant comments on the Free Range Kids blog, and since they were talking about the company that I give a not inconsequential amount of money to, I feel the need to write a response. The whole episode raises the question: who was this person and what were they doing there? Some of the commentators hypothesize that they were casing the joint for a future incident, or just giving themselves an impromptu tour before placing their child there (Zoe and I toured before we signed up, but that was an official, prearranged thing). It really is unfortunate that the staff didn't challenge this person, but as I said, they probably all had to review the video surveillance footage together to ascertain that none of them knew who the person was. I consider this a bit of a deficiency itself, but I don't really expect them to all have photographic memory, especially if one parent mostly does drop off and pick up. The other (expensive) option would be to issue each authorized person with an electronically revocable proximity card, so they can let themselves in, but I feel that that's taking things to the extreme. They staff all carry portable radios. If they don't have a discreet "code" they can call when one of them sees a person they don't know, I'm sure they will have after this incident. I personally found the majority of the comments on the Free Range Kids blog to be on the extreme overreaction side of things. As much as I'm a believer in Free Range parenting, I think the day care provider has mostly reacted appropriately. Do I agree with their "locked facility" policy? It's my first experience with a commercial day care facility, so I don't have anything to compare it with. As I said earlier, I can totally understand where they're coming from in terms of limiting their liability. Previously, Zoe was in a "home day care" facility, without any locks, and I for one wasn't constantly worrying about someone wandering into that provider's home and abducting my daughter, so I guess the whole "locked facility" thing is on the more extreme end of the scale for me in the first place, but like I said, I'm uncalibrated for commercial day care centres. I'd certainly like to see the primary school environment that Zoe goes to not be such a locked down affair.

Vasudev Kamath: Weekly Log - 01102012

Well this weeks log comes bit late as my week got extended till today ;-). I had working day at office on Saturday and Sunday due to 2nd Quarter end and instead today is declared as compensatory holiday and tomorrow any how is Gandhi Jayanti. So here it goes. Debian Related Most of my work this week was done for Debian-IN team Well most of this weeks work involved KGB ;-) Personal Works Misc Played Cricket after very long time (Guess after 10 long years). Well it was not official match or anything it was just another Gully Cricket. After the match it came to mind that I need regular physical workout :-P. Well that's it Cya till next week :-)

Christoph Berg: mkfs.ext3 -b 1024

If you think you are smart and create an ext filesystem with 1024 bytes blocksize because there will be zillions of very small files, and then run into ENOSPC errors while there's both space and inodes left, you will probably see ext3_dx_add_entry: Directory index full! in the kernel log. Turns out that there's a limit of approximately 300,000 files per directory with 1k blocks, after which some hash tables are full. Recreate the filesystem with 2k blocks and the limit will be MUCH higher.

Jonas Smedegaard: Building a remote-control for real cars

SMS is used to lock car doors Copenhagen Carpool soon receive a new batch of electric cars. The new cars will contain a cellphone tied to the door locks, to only let into the car the member who booked its current timeslot. I am setting up the system to connect the cars with their booking calendar. The general idea is to
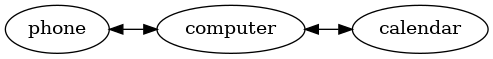
  1. Connect a standard cellphone to a computer.
  2. Forward sms messages received on the phone to the calendar.
  3. Send messages from the calendar through the phone.
  4. Leave the system in a corner, turned on 24/7.
Most of my work is in trying to avoid ways things might go wrong which so often happens when computers are involved. What if
  • messages are delayed or lost?
  • a chain of messages arrive out of order?
  • messages are sent faster than they can be delivered?

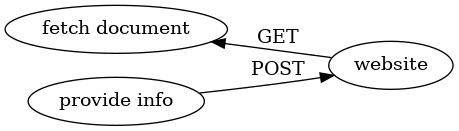
Reliable conversation Human conversation is most reliable when using plain speak. Slang, sarcasm or jokes raise the risk of misunderstandings. This is quite similar in computer conversation. When surfing the Web, you normally "GET" a web page or "POST" new data like a search query. The words "GET" and "POST" are "plain speak" of the World Wide Web defined as a principle called "REST" or "RESTful design". I use the Kannel tool to talk directly to the phones. When an sms arrives on the phone, Kannel "GET"s it to the calendar. That's weakly expressed better if it had "POST"ed the message instead. Kannel is a quite reliable tool, but not RESTful in conversations. That requires extra attention at other parts of the setup to avoid breakage in special situations. That worries me.

Each car has a blog So I setup a gateway from Kannel to RESTful conversation. And choose classic blogging as style of conversation:
  • The carpool fleet is a blogroll
  • each car has a blog
  • each sms emitted from a car is a blog entry
Blogging comes in two flavors, RSS and Atom. Both cover distribution of messages. I use Atom because it is newest and coolest, and because it also covers creating and editing meesages with the AtomPub extension. AtomPub allows the calendar to create an empty message which then triggers an sms from the car which "fills it in." AtomPub also let the calendar "PUT" tags onto existing messages, to mark them as processed, read etc., and let an admin or a cleanup script "DELETE" outdated entries or blogs. The words "PUT" and "DELETE" are RESTful conversation as well.

The system is dancing! My sms-to-blog gateway is written in Perl, using the Dancer toolkit. Dancer makes it simple to setup a RESTful web conversation, and when I contacted the authors on IRC, they swiftly added support for the non-RESTful quirk that I needed. My sms-to-blog gateway is not yet ready, but basic routines work. The project is public, and code is Free Software.

Cyril Brulebois: d-i hacking recipe #2: Adding a wireless module

Problem #2: How to add a wireless module to a d-i image? Slightly longer version: As reported in #686605, a whole wireless module family is missing from the linux kernel udebs, meaning they re missing from the d-i images. Please note the hypothesis here is that the regular linux kernel images contain the relevant modules, only the udebs don t. Recipe #2: Craft a local udeb!
  1. The following assumes one is interested in adding a wireless module, but that can be adapted to other module families. The relevant udeb base name is nic-wireless-modules.
  2. When it comes to linux kernel modules, picking the right ones is important, so one has to consider the ABI. Right now, the current ABI in testing is 3.2.0-3-amd64. The complete udeb name is therefore nic-wireless-modules-3.2.0-3-amd64-di.
  3. If you re running a kernel with the same ABI, all good, relevant modules should be available under /lib/modules/$(uname -r), which is what will be assumed below. Otherwise, one would have to download a proper linux-image-$ABI package, and extract it into a temporary directory to grab the wanted module(s).
  4. Determine the relevant module and its dependencies. As an example, I ll pick a Realtek module: rtl8192cu.ko. If it s loaded, one can use the following to detect its dependencies:
    $ lsmod grep rtl8192cu
    rtl8192cu              78863  0
    rtlwifi                81350  1 rtl8192cu
    rtl8192c_common        52602  1 rtl8192cu
    mac80211              192768  4 iwlwifi,rtl8192c_common,rtlwifi,rtl8192cu
    cfg80211              137140  3 mac80211,iwlwifi,rtlwifi
    usbcore               128498  7 ehci_hcd,usbhid,uvcvideo,rtlwifi,rtl8192cu
    
    But it isn t even needed to load the module to get those dependencies:
    $ /sbin/modinfo /lib/modules/3.2.0-3-amd64/kernel/drivers/net/wireless/rtlwifi/rtl8192cu/rtl8192cu.ko grep ^depends
    depends:        rtlwifi,mac80211,rtl8192c-common,usbcore
    
    Compared to what the d-i image contains, only rtlwifi and rtl8192c-common are missing.
  5. Fetch the udeb using http://packages.debian.org/ or browsing your favourite mirror if you know the paths by heart.
  6. Extract the udeb into a temporary data/ directory, along with its meta data:
    dpkg -x nic-wireless-modules-3.2.0-3-amd64-di_3.2.23-1_amd64.udeb data
    dpkg --control nic-wireless-modules-3.2.0-3-amd64-di_3.2.23-1_amd64.udeb data/DEBIAN
    
  7. Copy the 3 modules under the relevant subdirectory under data/.
  8. Update the version in data/DEBIAN/control, for example by adding the +local1 suffix.
  9. Build a new binary package, using fakeroot to avoid owner/group noise in the diff:
    fakeroot dpkg -b data nic-wireless-modules-3.2.0-3-amd64-di_3.2.23-1+local1_amd64.udeb
    
  10. Use debdiff to check the results:
    $ debdiff nic-wireless-modules-3.2.0-3-amd64-di_3.2.23-1*_amd64.udeb
    Files in second .deb but not in first
    -------------------------------------
    -rw-r--r--  root/root   /lib/modules/3.2.0-3-amd64/kernel/drivers/net/wireless/rtlwifi/rtl8192cu/rtl8192c-common.ko
    -rw-r--r--  root/root   /lib/modules/3.2.0-3-amd64/kernel/drivers/net/wireless/rtlwifi/rtl8192cu/rtl8192cu.ko
    -rw-r--r--  root/root   /lib/modules/3.2.0-3-amd64/kernel/drivers/net/wireless/rtlwifi/rtlwifi.ko
    Control files: lines which differ (wdiff format)
    ------------------------------------------------
    Version: [-3.2.23-1-]  +3.2.23-1+local1+ 
    
  11. Put the resulting udeb under localudebs/ in your d-i build tree, and rebuild your image as usual. Almost-tada!
Why almost ? Because a firmware is needed, so one can go back to the 7th step, extract the proper file (lib/firmware/rtlwifi/rtl8192cufw.bin) from the non-free firmware-realtek package, and add it under data/lib/firmware/realtek/. Rebuild the udeb, rebuild the d-i image. Then: tada!

Cyril Brulebois: d-i hacking recipe #1: Extracting logs without network

Foreword: This is the first blog post of a mini-series, trying to document some recipes about Debian Installer hacking. VirtualBox will probably be mentioned on a regular fashion, but most of those recipes should be easily adaptable to qemu/kvm. Problem #1: How to share some d-i logs without using the network? Slightly longer version: Investigating some issues on a wired-less virtual machine (Network Adapter 1 Disable Network Adapter), it s hard to get log files out of the virtual machine. Recipe #1: Use serial ports! Serial Ports Port 1 Enable Serial Port, then pick Raw File as Port Mode, and specify a file on the host system to gather logs. There s nothing to do on d-i side, the serial console appears automatically as /dev/ttyS0. From a console, one can extract the needed bits:
cp /var/log/syslog /dev/ttyS0
dmesg > /dev/ttyS0

30 September 2012

Russell Coker: Links September 2012

Scott Adams has an interesting idea for political debates he calls Fact Bubbler [1]. It sounds implausible the first time you read it, but then so did Wikipedia. Arstechnica has an interesting article on software defined radio [2]. This could change many things. The Nieder Family has another update on the way patents threaten their daughter s ability to communicate [3]. Also Apple is making things worse by taking pre-emptive strikes against iPhone apps which are involved in legal disputes never use an iPhone (or other proprietary system) for anything important if you have a choice. In more positive news crowd-funded gene sequencing has found an explanation for Maya Nieder s developmental delays [4]. This will revolutionise medicine! Steven Cherry of IEEE Spectrum has an interesting interview with Peter Cappelli about the difficulties that computer and engineering companies have in hiring talented people [5]. The Guardian has an interesting article about the non-profit investigative reporting organisation ProPublica [6]. See the ProPublica.org site for some quality news reports [7]. Michael O.Church wrote an interesting and insightful article about the fate of a Just a Programmer in a startup funded by Venture Capitalists [8]. It doesn t sound good at all. EyeNetra is developing a smart-phone based system for testing eyes [9]. It s apparently possible to manufacture glasses for $0.75 so the cost and difficulty of performing eye tests is the main factor that prevents poor people in developing countries from getting glasses. So a cheap portable eye testing system is going to help many people get the glasses they need. Bryan Gardiner wrote an interesting article for Wired about the Gorilla glass that is used in most mobile phones and tablets [10]. Maco wrote an interesting article about crochet and reverse-engineering along with a Python program to print a crochet pattern [11]. I wonder whether anyone has tried to make a crochet robot, something like a 3D printer but which crochet s things rather than printing them. Holding the wool would be a real challenge, it s not nearly as easy as printing on something that s stuck down and incapable of movement.
  1. [1] http://dilbert.com/blog/entry/fact_bubbler/
  2. [2] http://arstechnica.com/tech-policy/2012/07/how-software-defined-radio-could-revolutionize-wireless/
  3. [3] http://niederfamily.blogspot.com.au/2012/06/silencing-of-maya.html
  4. [4] http://blog.ted.com/2012/07/17/newly-discovered-gene-may-explain-4-year-olds-rare-disease-thanks-to-ted-fellow-jimmy-lin/
  5. [5] http://spectrum.ieee.org/podcast/at-work/tech-careers/why-bad-jobsor-no-jobshappen-to-good-workers
  6. [6] http://www.guardian.co.uk/technology/2012/jul/02/propublica-investigative-reporting
  7. [7] http://www.propublica.org/
  8. [8] http://michaelochurch.wordpress.com/2012/07/08/dont-waste-your-time-in-crappy-startup-jobs/
  9. [9] http://eyenetra.com/
  10. [10] http://www.wired.com/wiredscience/2012/09/ff-corning-gorilla-glass/all/
  11. [11] http://ubuntulinuxtipstricks.blogspot.com.au/2010/10/algorithms-reverse-engineering-and.html
Related posts:
  1. Links April 2012 Karen Tse gave an interesting TED talk about how to...
  2. Links May 2012 Vijay Kumar gave an interesting TED talk about autonomous UAVs...
  3. Links July 2012 The New York Times has an interesting article about hacker...

29 September 2012

Jonathan Carter: LLXC: My little python3-lxc based project


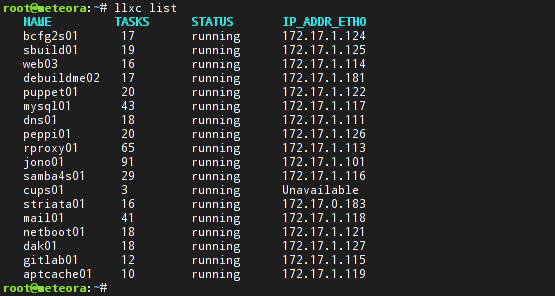
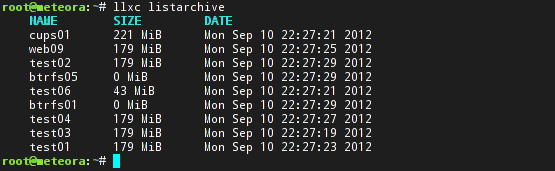
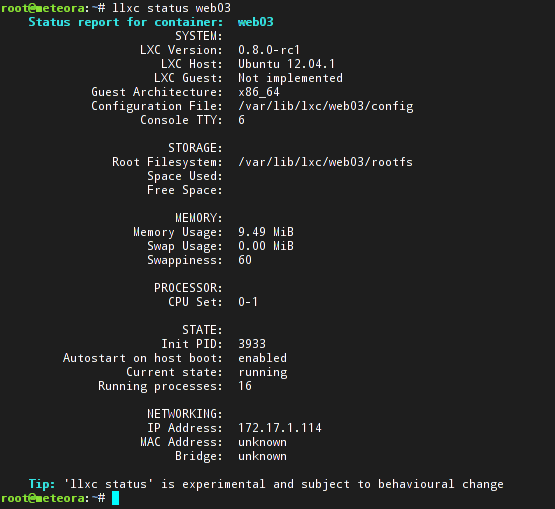
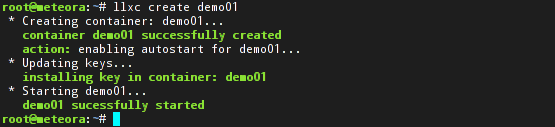
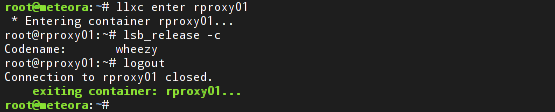
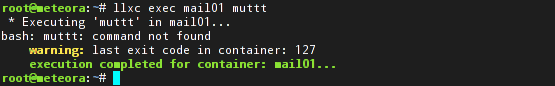
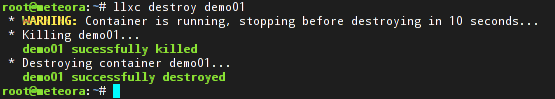
My foray into the world of LXC and RLXC A few months ago, I started trying out LXC (Linux Containers). Before that I used to use OpenVZ, which is an older and more mature contextualization implementation. I was pleased with how well LXC worked and started replacing my personal OpenVZ hosts with LXC. It worked great, but it had a few quirks. While LXC itself works well, the user scripts that ship with it has some space for improvement. The lxc-list command lists anything that s a directory in /var/lib/lxc, so if you have a lost+found directory, it will list it as a container (This has since been fixed upstream). Also, in some cases it would list containers twice or not at all. I was a bit annoyed with that, since OpenVZ s vzlist tool prints out a nice table of your containers along with their IP addresses and other information. Since it s very trivial to implement what I want in a shell script, I went ahead and did just that and called it RLXC. I also missed the vzctl exec <containername> command to execute commands in containers and vzctl enter <containername> to gain a shell inside the container, so I added some more functionality to it so that I could configure ssh keys for these containers and use rlxc enter and rlxc exec like I used to do with the OpenVZ tools, but by using SSH. I also realised that there are others too who wanted similar improvements in the LXC scripts and decided to continue improving RLXC and making it public. Enter LLXC I spoke to St phane about my ideas at the time and he introduced me to python3-lxc that he introduced on his blog yesterday. It provides Python bindings for liblxc, so I took the advantage of that and mostly re-implemented RLXC in Python and called it LLXC. The name doesn t particularly mean anything, I m open to suggestions for what to call it, if anyone cares. Here are some screenshots that explains some of it better than I could do in words: How to get it As St phane mentioned in the python3-lxc blog entry, the API hasn t yet been finalized and llxc itself is in an early state and many changes are planned, so it s definitely not meant for production use yet, but since we believe in release early, release often in the free software community, here goes Currently, llxc.py itself is *very* Ubuntu specific and its only been tested on Ubuntu 12.04, but that will be fixed once more of its kinks have been ironed out. Some people are also working on getting python3-lxc on other distributions, which will help a lot. The llxc.py script itself is hosted on Github: https://github.com/highvoltage/llxc For python3-lxc and friends, you need to enable St phane s experimental PPA: https://launchpad.net/~stgraber/+archive/experimental You will then need to install the following packages: lxc, python3-lxc, python3-crypto, lvm, btrfs-tools To generate the ssh keys used for ssh interaction between the containers, you need to run llxc gensshkeys . The enter and exec commands also rely on your containers being in dns or in your /etc/hosts file, at least for now, which you may have to configure manually. The Future There is a lot that I m planning to add, mostly to scratch my own itches. These include: I ll have some packaging for this available soon and work on making more things work right out of the box, updates will follow. Also, feedback and patches are very welcome!

28 September 2012

Don Armstrong: Switching to KGB from CIA

CIA.vc has unfortunately disappeared, and is unlikely to return any time soon. I personally have decided to switch to KGB, but other alternatives such as FBI and irker exist. To switch, you first need to find or set up a kgb bot. If this is a Debian associated FOSS project, feel free to contact me or join #kgb-devel on irc.oftc.net and ask for someone to allow your project to talk to their bot. Once you've found a bot, we need to set up the client. [I'll talk about bot set up at the end.]

kgb-client configuration Install the kgb-client and kgb-client-git packages. Currently, kgb only supports subversion and git, but I suspect this will be rectified shortly. For git repositories, add a post-receive hook like the following:
#!/bin/sh
tee hooks/reflog   kgb-client --conf /path/to/kgbclient.conf --repository git --git-reflog -
For subversion repositories, add a post-commit hook like the following:
#!/bin/sh
kgb-client --conf /path/to/kgbclient.conf --repository svn "$1" "$2"
Then update the configuration file /path/to/kgbclient.conf:
---
repo-id: my-repository
servers:
 - uri: http://servername:9999/
   password: verysecret
# optional link to a website where the commits are;
# needs newish kgb-client and server
web-link: http://example.com/?p=my-repository;a=commitdiff;h=$ commit 
Then, send the bot owner the password, repo-id, channel, and network you'd like the changes to be reported to.

Configuring kgb-bot The bots just listen to soap requests and if the password matches, sends the commit to the appropriate IRC channel. To set one up, install kgb-bot. Then, enable the bot (set BOT_ENBALED=1 in /etc/default/kgb-bot), and configure the bot's configuration file /etc/kgb-bot/kgb.conf:
---
soap:
  server_addr: 0.0.0.0
  server_port: 9999
  service_name: KGB
queue_limit: 150
log_file: "/var/log/kgb-bot.log"
repositories:
  # just a name to identify it
  my-repository:
    # needs to be the same on the client
    password: verysecret
networks:
  oftc:
    nick: KGB-you
    ircname: KGB bot
    username: kgb
    password: ~
    nickserv_password: yournickservpassword
    server: irc.oftc.net
    port: 6667
  freenode:
    nick: KGB-you
    ircname: KGB bot
    username: kgb
    password: ~
    nickserv_password: yournickservpassword
    server: irc.freenode.net
    port: 6667
channels:
  - name: '#your-channel'
    network: oftc
    repos:
     - your-repo
  - name: '#commits'
    network: freenode
    repos:
     - your-repo
Then start the bot (/etc/init.d/kgb-bot start), and watch as it joins channels and reports your changes! You'll probably actually want to register whatever nick you are using on the networks, etc... but you can figure that out yourself!

Keith Packard: DRI-Next

Thoughts about DRI.Next On the way to the X Developer s Conference in Nuremberg, Eric and I chatted about how the DRI2 extension wasn t really doing what we wanted. We came up with some fairly rough ideas and even held an informal presentation about it. We didn t have slides that day, having come up with the content for the presentation in the hours just before the conference started. This article is my attempt to capture both that discussion and further conversations held over roast pork dinners that week. A brief overview of DRI2 Here s a list of the three things that DRI2 currently offers. Application authentication. The current kernel DRM authentication mechanism restricts access to the GPU to applications connected to the DRM master. DRI2 implements this by having the application request the DRM cookie from the X server which can then be passed to the kernel to gain access to the device. This is fairly important because once given access to the GPU, an application can access any flink d global buffers in the system. Given that the application sends screen data to the X server using flink d buffers, that means all screen data is visible to any GPU-accessing application. This bypasses any GPU hardware access controls. Allocating buffers. DRI2 defines a set of attachment points for buffers which can be associated with an X drawable. An application needing a specific set of buffers for a particular rendering operation makes a request of the X server which allocates the buffers and passes back their flink names. The server automatically allocates new buffers when window sizes change, sending an event to the application so that it knows to request the new buffers at some point in the future. Presenting data to the user. The original DRI2 protocol defined only the DRI2CopyRegion request which copied data between the allocated buffers. SwapBuffers was implemented by simply copy data from the back buffer to the front buffer. This didn t provide any explicit control over frame synchronization, so a new request, DRI2SwapBuffers, was added to expose controls for that. This new request only deals with the front and back buffers, and either copies from back to front or exchanges those two buffers. Along with DRI2SwapBuffers, there are new requests that wait for various frame counters and expose those to GL applications through the OMLsynccontrol extension What s wrong with DRI2? DRI2 fixed a lot of the problems present with the original DRI extension, and made reliable 3D graphics on the Linux desktop possible. However, in the four years since it was designed, we ve learned a lot, and the graphics environment has become more complex. Here s a short list of some DRI2 issues that we d like to see fixed. Proposed changes for DRI.Next Given the three basic DRI2 operations (authentication, allocation, presentation), how can those be improved? Eliminate DRI/DRM magic-cookie based authentication Kristian H gsberg, Martin Peres, Timoth e Ravier & Daniel Vetter gave a talk on DRM2 authentication at XDC this year that outlined the problems with the current DRM access control model and proposed some fairly simple solutions, including using separate device nodes one for access to the GPU execution environment and a separate, more tightly controlled one, for access to the display engine. Combining that with the elimination of flink for communicating data between applications and there isn t a need for the current magic-cookie based authentication mechanism; simple file permissions should suffice to control access to the GPU. Of course, this ignores the whole memory protection issue when running on a GPU that doesn t provide access control, but we already have that problem today, and this doesn t change that, other than to eliminate the global uncontrolled flink namespace. Allocate all buffers in the application DRI2 does buffer allocation in the X server. This ensures that that multiple (presumably cooperating) applications drawing to the same window will see the same buffers, as is required by the GLX extension. We suspected that this wasn t all that necessary, and it turns out to have been broken several years ago. This is the traditional way in X to phase out undesirable code, and provides an excellent opportunity to revisit the original design. Doing buffer allocations within the client has several benefits: Present buffers through DMA-buf The new DMA-buf infrastructure provides a cross-driver/cross-process mechanism for sharing blobs of data. DMA-buf provides a way to take a chunk of memory used by one driver and pass it to another. It also allows applications to create file descriptors that reference these objects. For our purposes, it s the file descriptor which is immediately useful. This provides a reliable and secure way to pass a reference from an underlying graphics buffer from the client to the X server by sending the file descriptor over the local X socket. An additional benefit is that we get automatic integration of data from other devices in the system, like video decoders or non-primary GPUs. The Prime support added in DRI version 2.8 hacks around this by sticking a driver identifier in the driverType value. Once the buffer is available to the X server, we can create a request much like the current DRI2SwapBuffers request, except instead of implicitly naming the back and front buffers, we can pass an arbitrary buffer and have those contents copied or swapped to the drawable. We also need a way to copy a region into the drawable. I don t know if that needs the same level of swap control, but it seems like it would be nice. Perhaps the new SwapBuffers request could take a region and offset as well, copying data when swapping isn t possible. Managing buffer allocations One trivial way to use this new buffer allocation mechanism would be to have applications allocate a buffer, pass it to the X server and then simply drop their reference to it. The X server would keep a reference until the buffer was no longer in use, at which point the buffer memory would be reclaimed. However, this would eliminate a key optimization in current drivers the ability to re-use buffers instead of freeing and allocating new ones. Re-using buffers takes advantage of the work necessary to setup the buffer, including constructing page tables, allocating GPU memory space and flushing caches. Notifying the application of idle buffers Once the X server is finished using a buffer, it needs to notify the application so that the buffer can be re-used. We could send these notifications in X events, but that ends up in the twisty mess of X client event handling which has already caused so much pain with Invalidate events. The obvious alternative is to send them back in a reply. That nicely controls where the data are delivered, but causes the application to block waiting for the X server to send the reply. Fortunately, applications already want to block when swapping buffers so that they get throttled to the swap buffers rate. That is currently done by having them wait for the DRI2SwapBuffers reply. This provides a nice place to stick the idle buffer data. We can simply list buffers which have become idle since the last SwapBuffers reply was delivered. Releasing buffer memory Applications which update only infrequently end up with a back buffer allocated after their last frame which can t be freed by the system. The fix for this is to mark the buffer purgable, but that can only be done after all users of the buffer are finished with it. With this new buffer management model, the application effectively passes ownership of its buffers to the X server, and the X server knows when all use of the buffer are finished. It could mark buffers as purgable at that point. When the buffer was sent back in the SwapBuffers reply, the application would be able to ask the kernel to mark it un-purgable again. A new extension? Or just a new DRI2 version? If we eliminate the authentication model and replace the buffer allocation and presentation interfaces, what of the existing DRI2 protocol remains useful? The only remaining bits are the other synchronization requests: DRI2GetMSC, DRI2WaitMSC, DRI2WaitSBC and DRI2SwapInterval. Given this, does it make more sense to leave DRI2 as it is and plan on deprecating, and eventually eliminating, it? Doing so would place a support burden on existing applications, as they d need to have code to use the right extension for the common requests. They ll already need to support two separate buffer management versions though, so perhaps this burden isn t that onerous?

Gunnar Wolf: Rethinking copyright in the digital era: Dialogs on arts, regulation and culture availability Museo del Chopo, Mexico City

I was invited as a panelist for the Laboratorio Repensar el derecho de autor y el derecho de copia en la era digital:
di logo sobre artes, regulaciones y disponibilidad de la cultura
at the beautiful Foro del Dinosaurio in the Museo del Chopo, located very centrally in Mexico City. The list of speakers is quite interesting, and makes me very interested and happy to be there. The laboratory will be next week, Wednesday through Friday. I am scheduled to be part of the 17:00 table, Knowledge availability and regulation in Internet, coordinated by Pedro Mendiz bal (Creative Commons Per ), and together with Juan Vouts s (Biblotecologic Research Institute, UNAM), Armida Aponte (Creative Commons M xico). The other topics that will be covered are: Sadly, it does not seem they have planned for remote people to follow along. I will ask and update here if there is any way for people outside Mexico City to tune in For people able to attend, it's free entrance (and certificates will be given to people pre-registered, if you are interested, call 5535-2288 ext. 123) For further details on the participants, go to the laboratory's web page. Update: The talks will be streamed! http://www.chopo.unam.mx/chopoenvivo.html, via UStream.

Steve Kemp: So about that off-site encrypted backup idea ..

I'm just back from having spent a week in Helsinki. Despite some minor irritations (the light-switches were always too damn low) it was a lovely trip. There is a lot to be said for a place, and a culture, where shrugging and grunting counts as communication. Now I'm back, catching up on things, and mostly plotting and planning how to handle my backups going forward. Filesystem backups I generally take using backup2l, creating local incremental backup archives then shipping them offsite using rsync. For my personal stuff I have a bunch of space on a number of hosts and I just use rsync to literally copy my ~/Images, ~/Videos, etc.. In the near future I'm going to have access to a backup server which will run rsync, and pretty much nothing else. I want to decide how to archive my content to that - securely. The biggest issue is that my images (.CR2 + .JPG) will want to be encrypted remotely, but not locally. So I guess if I re-encrypt transient copies and rsync them I'll end up having to send "full" changes each time I rsync. Clearly that will waste bandwidth. So my alternatives are to use incrementals, as I do elsewhere, then GPG-encrypt the tar files that are produced - simple to do with backup2l - and us rsync. That seems like the best plan, but requires that I have more space available locally since : I guess I will ponder. It isn't horrific to require local duplication, but it strikes me as something I'd rather avoid - especially given that we're talking about rsync from a home-broadband which will take weeks at best for the initial copy.

Next.

Previous.