Martin F. Krafft: Configuration management

Puppet
I've really had it with Puppet. I used to be able to put up
with all its downsides
- Non-Unix approach to everything (own transport, self-made PKI,
non-intuitive configuration language, a faint attempt at versioning
(bitbucket), and much much more )
- Ruby
- Abysmal slowness
- Lack of basic functionality (e.g. replace a line of text)
- Host management and configuration programming intertwined, lack
of a high-level approach to defining functionality
- Horrific error messages
- Catastrophic upgrade paths
- Did I mention Ruby and its speed?
- Lack of IPv6 support
- [I could keep going ]
but now that my fourth attempt to upgrade my complex
configuration from version 0.25.5 to version 2.7 failed due to a
myriad of completely incomprehensible errors ("err: Could not run
Puppet configuration client: interning empty string") and many
hours were lost in trying to hunt these down using binary searches,
I am giving up. Bye bye Puppet.
An alternative
But I need an alternative. I want a system that is capable of
handling a large number of hosts, but not so complex that one
wouldn't put it to use for half a dozen machines. The configuration
management system I want looks about as follows: It
- makes use of existing infrastructure (e.g. SSH transport and
public keys, Unix toolchain, Debian package management and
debconf)
- interacts with the package management system (Debian only in my
case)
- can provision files whose contents might depend on context,
particular machine data and conditionals. There should be a unified
templating approach for static and dynamic files, with the ability
to override the source of data (e.g. a default template used unless
a template exists for a class of machine, or a specific
hostname)
- can edit files on the target machine in a flexible and robust
manner
- can remove files
- can run commands when files change
- can reference data from other machines (e.g. obtain the
certificate fingerprint of each hosts that define me as their SMTP
smarthost)
- can control running services (i.e. enable init.d scripts, check
that a process is running
- is written in a sensible language
- is modular and easily extensible, ideally using a well-known
language (e.g. Python!)
- allows to specify infrastructure with tags ("all webservers",
"all machines in Zurich", "machines that are in Munich and receive
mail"), but with the ability to override every parameter for a
specific host
- should just do configuration management, and not try to take
away jobs from monitoring software
- logs changes per-machine and collects data about applied
configurations in a central location
- is configured using flat files that are human-readable so that
the configuration may be stored in Git (e.g. YAML, not
XML)
- can be configured using scripts in a flexible way
Since for me, Ruby is a downside of Puppet, I won't look at
Chef, but from this page, I gleaned
a couple of links: Ansible,
Quattor, Salt, and bcfg2 (which uses XML
though). And of course, there remains the ephemeral cfengine.
cfengine
I haven't used cfengine since
2002, but I am not convinced it's worth a new look because it seems
to be an academic project with gigantic complexity and a whole
vernacular to its own. There is no doubt that it is a powerful
solution, and the most mature of all of them, but it's far away
from the Unix-like simplicity that I've come to love in almost 20
years of Debian.
Do correct me if I am wrong.
Ansible
Ansible looks interesting. It
seems rather bottom-up, first introducing a way to remotely execute
commands on hosts, which you can then later extend/automate to
manage the host configurations. It uses SSH for transport, and its
reason-to-be made me
want to look at it.
My ventures into the Ansible domain are not over yet, but I've
put them on hold. First of all, it's not yet packaged for Debian
(Ubuntu-PPA
packages work on Debian squeeze and wheezy).
Second, I was put off a bit by its gratuitous use of the shell
to run commands, as well as other design decisions.
Check this out: there are modules for the remote execution of
commands, namely "shell", "command", and "raw". The shell modules
should be self-explanatory; the command module
provides some idempotency, such as not running the command if a
file exists (or not). To do this, it creates a Python script in
/tmp on the target and then executes that like
so:
$SHELL -c /tmp/ansible/ansible-1350291485.22-74945524909437/command
Correct me if I am wrong, but there is zero need for
this shell indirection. My attempts at finding an answer on IRC
were met by user "daniel_hozac" with a reason along the lines of
"it's needed, believe me", and on the mailing list, I am told that
only the shell can execute a script by parsing the interpreter line
at the top of the module.
Finally, the raw execution
module also executes using the shell
And there a few other design decisions that I can't quite
explain, around the command-line switch --sudo see
the aforementioned message
In short: running a command like
ansible -v arnold.madduck.net -a "/usr/bin/apt-get update" --sudo
does not invoke apt-get with sudo, as
one might like; it invokes the shell that runs the Python script
that runs the command. Effectively therefore, you need to allow
sudo shell execution, and for proper automation, this
has to be possible without a password. And then you might just as
well allow root logins again.
The author seems to think that "core behaviour" is that sudo
allows all execution and that limiting the commands to run is not a
use-case that Ansible will support. Apparently, I was the first to
ever suggest this.
There are always ways around (e.g. skip --sudo and
just use sudo as the command, simply ignore the
useless shell invocation and trust that your machine can handle it,
but when such design decisions remain incomprehensible and get
defended by the project people, then I am hesitant to invest more
time on principle.
Salt
Finally, I've looked at Salt, which is what I've spent most
time on so far. From the discussions I started on
host targeting and
data collection, it soon became apparent that Salt is very thin
and flexible, and that the user community is accomodating.
Unfortunately, Salt does not use SSH, but at least it reuses
existing functionality (ZeroMQ). As opposed to the push/pull
model, Salt "minions" interestingly maintain a persistent
connection to the server (which is not yet very stable), and
while non-root usage is still not unproblematic, at least
there has already been work done in this direction.
I think I will investigate Salt more as it does look like it can
do what I want. The YAML-based syntax does seem a bit brittle, but
it's the best I've found so far.
NP:
The Pineapple Thief: Someone Here is Missing
- makes use of existing infrastructure (e.g. SSH transport and public keys, Unix toolchain, Debian package management and debconf)
- interacts with the package management system (Debian only in my case)
- can provision files whose contents might depend on context, particular machine data and conditionals. There should be a unified templating approach for static and dynamic files, with the ability to override the source of data (e.g. a default template used unless a template exists for a class of machine, or a specific hostname)
- can edit files on the target machine in a flexible and robust manner
- can remove files
- can run commands when files change
- can reference data from other machines (e.g. obtain the certificate fingerprint of each hosts that define me as their SMTP smarthost)
- can control running services (i.e. enable init.d scripts, check that a process is running
- is written in a sensible language
- is modular and easily extensible, ideally using a well-known language (e.g. Python!)
- allows to specify infrastructure with tags ("all webservers", "all machines in Zurich", "machines that are in Munich and receive mail"), but with the ability to override every parameter for a specific host
- should just do configuration management, and not try to take away jobs from monitoring software
- logs changes per-machine and collects data about applied configurations in a central location
- is configured using flat files that are human-readable so that the configuration may be stored in Git (e.g. YAML, not XML)
- can be configured using scripts in a flexible way
cfengine
I haven't used cfengine since
2002, but I am not convinced it's worth a new look because it seems
to be an academic project with gigantic complexity and a whole
vernacular to its own. There is no doubt that it is a powerful
solution, and the most mature of all of them, but it's far away
from the Unix-like simplicity that I've come to love in almost 20
years of Debian.
Do correct me if I am wrong.
Ansible
Ansible looks interesting. It
seems rather bottom-up, first introducing a way to remotely execute
commands on hosts, which you can then later extend/automate to
manage the host configurations. It uses SSH for transport, and its
reason-to-be made me
want to look at it.
My ventures into the Ansible domain are not over yet, but I've
put them on hold. First of all, it's not yet packaged for Debian
(Ubuntu-PPA
packages work on Debian squeeze and wheezy).
Second, I was put off a bit by its gratuitous use of the shell
to run commands, as well as other design decisions.
Check this out: there are modules for the remote execution of
commands, namely "shell", "command", and "raw". The shell modules
should be self-explanatory; the command module
provides some idempotency, such as not running the command if a
file exists (or not). To do this, it creates a Python script in
/tmp on the target and then executes that like
so:
$SHELL -c /tmp/ansible/ansible-1350291485.22-74945524909437/command
Correct me if I am wrong, but there is zero need for
this shell indirection. My attempts at finding an answer on IRC
were met by user "daniel_hozac" with a reason along the lines of
"it's needed, believe me", and on the mailing list, I am told that
only the shell can execute a script by parsing the interpreter line
at the top of the module.
Finally, the raw execution
module also executes using the shell
And there a few other design decisions that I can't quite
explain, around the command-line switch --sudo see
the aforementioned message
In short: running a command like
ansible -v arnold.madduck.net -a "/usr/bin/apt-get update" --sudo
does not invoke apt-get with sudo, as
one might like; it invokes the shell that runs the Python script
that runs the command. Effectively therefore, you need to allow
sudo shell execution, and for proper automation, this
has to be possible without a password. And then you might just as
well allow root logins again.
The author seems to think that "core behaviour" is that sudo
allows all execution and that limiting the commands to run is not a
use-case that Ansible will support. Apparently, I was the first to
ever suggest this.
There are always ways around (e.g. skip --sudo and
just use sudo as the command, simply ignore the
useless shell invocation and trust that your machine can handle it,
but when such design decisions remain incomprehensible and get
defended by the project people, then I am hesitant to invest more
time on principle.
Salt
Finally, I've looked at Salt, which is what I've spent most
time on so far. From the discussions I started on
host targeting and
data collection, it soon became apparent that Salt is very thin
and flexible, and that the user community is accomodating.
Unfortunately, Salt does not use SSH, but at least it reuses
existing functionality (ZeroMQ). As opposed to the push/pull
model, Salt "minions" interestingly maintain a persistent
connection to the server (which is not yet very stable), and
while non-root usage is still not unproblematic, at least
there has already been work done in this direction.
I think I will investigate Salt more as it does look like it can
do what I want. The YAML-based syntax does seem a bit brittle, but
it's the best I've found so far.
NP:
The Pineapple Thief: Someone Here is Missing
/tmp on the target and then executes that like
so:
$SHELL -c /tmp/ansible/ansible-1350291485.22-74945524909437/command
--sudo see
the aforementioned message
In short: running a command like
ansible -v arnold.madduck.net -a "/usr/bin/apt-get update" --sudo
apt-get with sudo, as
one might like; it invokes the shell that runs the Python script
that runs the command. Effectively therefore, you need to allow
sudo shell execution, and for proper automation, this
has to be possible without a password. And then you might just as
well allow root logins again.
The author seems to think that "core behaviour" is that sudo
allows all execution and that limiting the commands to run is not a
use-case that Ansible will support. Apparently, I was the first to
ever suggest this.
There are always ways around (e.g. skip --sudo and
just use sudo as the command, simply ignore the
useless shell invocation and trust that your machine can handle it,
but when such design decisions remain incomprehensible and get
defended by the project people, then I am hesitant to invest more
time on principle.

 # Copyright (C) YEAR Free Software Foundation, Inc.
# This file is distributed under the same license as the PACKAGE package.
# FIRST AUTHOR <email>, YEAR.
#
#, fuzzy
msgid ""
msgstr ""
"Project-Id-Version: PACKAGE VERSION\n"
"POT-Creation-Date: 2012-10-12 11:14+0300\n"
"PO-Revision-Date: YEAR-MO-DA HO:MI+ZONE\n"
"Last-Translator: FULL NAME <email>\n"
"Language-Team: LANGUAGE <ll>\n"
"Language: \n"
"MIME-Version: 1.0\n"
"Content-Type: text/plain; charset=UTF-8\n"
"Content-Transfer-Encoding: 8bit\n"
#. type: Title #
#, no-wrap
msgid "Status hos doktoren"
msgstr ""
#. type: Plain text
#, no-wrap
msgid "\n"
msgstr ""
#. type: Plain text
#, no-wrap
msgid "\n"
msgstr ""
#. type: Plain text
#, no-wrap
msgid ""
"**Jonas Smedegaard** [dr.jones at pobox.com "
"](mailto:friends%40jones.dk?Subject=Status%20hos%20doktoren&In-Reply-To=1.5.4.32.19971011010004.0067de34%40kaospilot.dk) "
"\n"
msgstr ""
#. type: Plain text
msgid "_Sat Oct 11 15:22:00 CEST 1997_"
msgstr ""
#. type: Bullet: ' * '
#:
msgid "Previous message: [Spamming? ](000001.html)"
msgstr ""
#. type: Bullet: ' * '
#:
msgid ""
"**Messages sorted by:**

 Credit Unions are financial co-operatives where a
 Sometimes one stumbles upon artists by accident and immediately falls in love with them. A link to a video from
 For writing tests for GVFS (
 So, a couple of days ago, I came home tired after a intense weekend of learning Akonadi and hacking on KDEPIM.
At each meal, we attended 12 people, but it wasn t the same people every time. And a couple of people participated remotely.
Several people, including me, got their feet wet in kdepim & akonadi code. Talks about the future with Qt 6 and Qt 7 and Akonadi 3 were also held in the corners.
Hopefully, others will tell more closely about what they did, including fixing kmail memory usage to not grow until all headers of all emails was in memory and improving the address completion job to help filling in to/cc/bcc fields.
Personally, I started off several times with the same issue. Not doing several synchronous calls from KMail to Akonadi during message writing and sending. On my way, I cleaned up some code and started over a couple of times. And the code is still a work in progress on my laptop. But the most important synchronous call is in that WIP patch now actually asynchronous \o/. There is still work to do on that area though and I hope to get around polishing it and finishing it this month somehow. I currently have function names like second_half_of_generateCryptoMessages and this_function_should_be_renamed .
And next up will
 A few days ago I wrote

 Phishing is a fraud technique that consists in reproducing the content of a
targeted website, directing users to it, and recording their credentials when
they log into your website. It is like fishing fish with fake food, only you
phish humans with fake websites.
Well, I have a good news for the phishers: people are using more and more
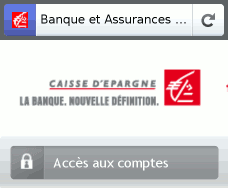
smartphones, and mobile browsers are making your job really easy.
In fact, many regular smartphone user simply have no way to tell your fake
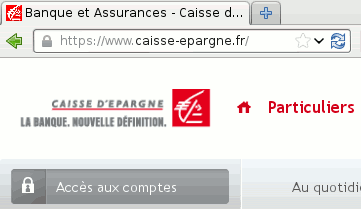
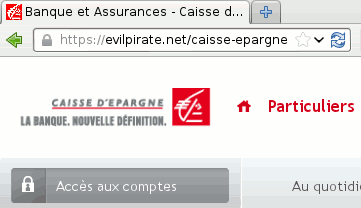
website apart from the real one.For instance, this is what my bank website looks like in my desktop browser,
and what a corresponding phishing website would look like:
 The GNOME infrastructure runs a



 * In case you re not watching my twitter (and other social medias), I ve moved to none other than Bangalore. I m working with

 I'm off to Spain to attend and speak at the

 Update for 06/10/2012
Well I had not written the weekly work log for the last week that
is because the week was short (oh yeah thanks to all these bandhs
our week got fluctuated and to be frank the week was only 4 days
long) and second was my lazyness. Here goes the update
* After a long discussion with
 There may be a situation where you want to create a Debian source package without having to unpack the upstream source. One case is where you store your debian/ directory in a version control system of its own and to build your package, you pass the .dsc file to a tool like pbuilder or some remote builder. Now a modern debian source package is just a text file (the .dsc file) that references two tarballs, one being the upstream source and the other being the Debian directory. Thanks to Niels Thykier on #debian, I found the magic invocation of dpkg-source that allows you to create the .dsc directly from the two tarballs, the control file and the changelog: