Search Results: "tar"

4 November 2012

Paul Wise: Remembering the dead

Last week was el D a de los Muertos (the Day of the Dead), a Mexican holiday where people gather to remember their dead. Today I would like to remember <predator>. pred was a core member of the cat@lyst collective, a group of folks providing computers, Internet and other tech resources to the activists of Sydney, Australia. I knew pred as cat@lyst's hardware geek, he was always scrounging computers from roadsides, coaxing them back to life and setting them to work supporting cat@lyst. I only knew pred through email and just missed out on meeting him due to the cancer that eventually killed him. pred wrote extensively during his life and of his experiences while dying of cancer. After he died, some friends compiled some of his writing into a book, simply named pred.txt. His full writings also happen to have been archived on the net. Through the book and his writings I came to learn that he was much more than just a hardware geek and gain some more insight into who he was. pred was a geek, activist, anarchist, urban explorer, scientist in the area of molecular genetics, cancer victim and all-around awesome dude. I still miss him.

3 November 2012

Russ Allbery: Welcome, Planet Debian

As part of a discussion about something else on debian-project, it seemed clear that people were interested in more than just Debian-relevant posts on the Planet Debian aggregator. I'd previously only pushed Debian-related posts there, but I asked explicitly and people want the full feed. So this is the first untagged post going there (and something of a test). The difference, for Planet Debian readers, is that you'll get a lot more book reviews (of non-technical books), and a smattering of software announcements. You'll also get posts like the below whenever I buy more books. I got into the habit of making haul posts from enjoying a friend's version of that, and now I use them as a way of keeping track of what I've already bought until I get around to putting stuff into a real book database. (I'm currently leaning towards Tellico, for what it's worth.) I'll try to add at least a bit of commentary so that it won't just be a list of books. If I can get back into the habit, you'll also get regular postings of photographs. I've been out of the habit for about a year, though, so we'll see how that goes. Anyway, a small haul: Kevin Barry Dark Lies the Island (mainstream)
J. Robert Lennon Familiar (mainstream)
Ken & Jo Walton GURPS: Celtic Myth (RPG) This is notable because it's my first Indiespensible shipment. Powell's Books, from which I buy nearly all of my books, has a subscription club called Indiespensible, which sends a new novel, usually from independent presses, every six weeks. I've been eyeing this for a long time and finally decided to go ahead and try it for a while. I mostly read science fiction and fantasy, so this is a good way to try to read more mainstream fiction, and since I know absolutely nothing about what's good in mainstream fiction, something curated is a good idea. I haven't cracked open either of the books yet, but I quite enjoyed the chocolate toffee. GURPS: Celtic Myth was because I discovered that there was a role-playing supplement by one of my favorite authors, so that had to be acquired, even if I'm not a GURPS player.

2 November 2012

Neil Williams: Introducing pyBit - Buildd Integration Toolkit

pyBit - cross-platform package building using AMQP


Message queues provide a simple way to create a distributed, cross-platform buildd toolkit to build packages using a collection of buildds, direct from various VCS clients. pyBit is intended to support rapidly evolving software collections and can support multiple VCS frontends and multiple build backends. Cross building is expected to be supported for some backends. The initial backend uses dpkg for Debian with subversion providing the source and sbuild doing the actual build.

pyBit includes support for cancelling selected builds and using multiple buildd clients per architecture, per platform and per suite.

Hooks are available or in development for subversion and git, other VCS hooks can be added. A RESTful web API provides live build reports and can generate build jobs for specific packages using particular VCS branches on selected architectures to support re-building packages at any point in the development process. Build history is stored using postgresql.

Other buildd systems can rebuild long lists of packages or build lots of binary packages from relatively slow moving source packages. PyBit exists to handle much more rapid software development across a wide range of platforms, VCS inputs and architectures. Buildd clients which are under-used can be tasked with building multiple suites or adding cross-build support. Buildd clients which are over-utilised are easily identified and adding new machines to an existing architecture / platform / suite pool should be easy. Hook activation automatically cancels any ongoing build for the same architecture, platform and suite to avoid wasting time on an interim version.

The emphasis in pyBit is to have fast builds with redundant clients, reliable reporting using a flexible and intuitive frontend. To this end, there is no need for a source package to be uploaded. Depending on the VCS hook in use, builds can happen every time a particular file is changed (e.g. debian/changelog for a native Debian package) or at every push (for a distributed VCS) or whatever is appropriate for a particular software collection. Builds are checked for available build-dependencies and packages re-queued if the build-dependencies are not yet met.

In the longer term, it may well be possible to use more than one server / database combination to support more builds and more platforms.

So far, we've got to a working model and tagged 0.1.0 as the first downloadable release. There is a lot more to do, especially adding more documentation, more VCS hooks, support for more VCS methods on the buildd clients and more buildd client scripts for platforms other than Debian. (The git hook and git source client are expected to let pyBit be self-buildable but a certain amount of configuration will be required for the server and each client which makes it not-quite self-hosting.)

pyBit concentrates on preparing collections of binary packages which can be used to build others, rather than trying to rebuild everything every time - this allows more rapid upstream software development and encourages modular, re-usable software. pyBit will also support rebuilding specific versions, architectures, suites or platforms via the RESTful web API. Access to this frontend can be controlled through any of the standard methods.

Components are loosely coupled via JSON encoded messages sent using rabbitMQ and curl. A new client can be added at any time and it will simply pick up buildd jobs from the relevant queue.

Development has now moved to Github and if anyone wants to look at new clients and new hooks, just contact the team by email or via IRC (#pybit on irc.oftc.net). Current development is based on Debian Squeeze 6.0.6 with backports and also on Debian Wheezy - more testing is welcome. Patches are also very welcome, pyBit is licensed under GPL2+.

There is no intrinsic reason why pyBit could not support any buildd platform capable of taking source from a known location and building a set of binaries. Packages are added to the queues whenever the hook is activated, so adding new packages to the collection is simply a case of triggering the existing hook.

Another interesting challenge for pyBit would be to trigger a hook on a new source code repository and just let it work through every package until everything is built. That probably won't work with the current 0.1.0 code but if that is what you'd like to work on, join the team.

Vincent Bernat: Network virtualization with VXLAN

Virtual eXtensible Local Area Network (VXLAN) is a protocol to overlay a virtualized L2 network over an existing IP network with little setup. It is currently described in an Internet-Draft. It adds the following perks to VLANs while still providing isolation:
  1. It uses a 24-bit VXLAN Network Identifier (VNI) which should be enough to address any scale-based concerns of multitenancy.
  2. It wraps L2 frames into UDP datagrams. This allows one to rely on some interesting properties of IP networks like availability and scalability. A VXLAN segment can be extended far beyond the typical reach of today VLANs.
The VXLAN Tunnel End Point (VTEP) originates and terminates VXLAN tunnels. Thanks to a serie of patches from Stephen Hemminger, Linux can now act as a VTEP. Let s see how this works.

About IPv6 When possible, I try to use IPv6 for my labs. This is not the case here for several reasons:
  1. IP multicast is required and PIM-SM implementations for IPv6 are not widespread yet. However, they exist. This explains why I use XORP for this lab: it supports PIM-SM for both IPv4 and IPv6.
  2. VXLAN Internet-Draft specifically addresses only IPv4. This seems a bit odd for a protocol running on top of UDP and I hope this will be fixed soon. This is not a major stopper since some VXLAN implementations support IPv6.
  3. However, the current implementation for Linux does not support IPv6. IPv6 support will be added later.
Once IPv6 support is available, the lab should be easy to adapt.

Lab So, here is the lab used. R1, R2 and R3 will act as VTEPs. They do not make use of PIM-SM. Instead, they have a generic multicast route on eth0. E1, E2 and E3 are edge routers while C1, C2 and C3 are core routers. The proposed lab is not resilient but convenient to explain how things work. It is built on top of KVM hosts. Have a look at my previous article for more details on this. VXLAN lab The lab is hosted on GitHub. I have made the lab easier to try by including the kernel I have used for my tests. XORP comes preconfigured, you just have to configure the VXLAN part. For this, you need a recent version of ip.
$ sudo apt-get install screen vde2 kvm iproute xorp git
$ git clone git://git.kernel.org/pub/scm/linux/kernel/git/shemminger/iproute2.git
$ cd iproute2
$ ./configure && make
You get  ip' as  ip/ip' and  bridge' as  bridge/bridge'.
$ cd ..
$ git clone git://github.com/vincentbernat/network-lab.git
$ cd network-lab/lab-vxlan
$ ./setup

Unicast routing The first step is to setup unicast routing. OSPF is used for this purpose. The chosen routing daemon is XORP. With xorpsh, we can check if OSPF is working as expected:
root@c1# xorpsh
root@c1$ show ospf4 neighbor   
  Address         Interface             State      ID              Pri  Dead
192.168.11.11    eth0/eth0              Full      3.0.0.1          128    36
192.168.12.22    eth1/eth1              Full      3.0.0.2          128    33
192.168.101.133  eth2/eth2              Full      2.0.0.3          128    36
192.168.102.122  eth3/eth3              Full      2.0.0.2          128    38
root@c1$ show route table ipv4 unicast ospf   
192.168.1.0/24  [ospf(110)/2]
                > to 192.168.11.11 via eth0/eth0
192.168.2.0/24  [ospf(110)/2]
                > to 192.168.12.22 via eth1/eth1
192.168.3.0/24  [ospf(110)/3]
                > to 192.168.102.122 via eth3/eth3
192.168.13.0/24 [ospf(110)/2]
                > to 192.168.102.122 via eth3/eth3
192.168.21.0/24 [ospf(110)/2]
                > to 192.168.101.133 via eth2/eth2
192.168.22.0/24 [ospf(110)/2]
                > to 192.168.12.22 via eth1/eth1
192.168.23.0/24 [ospf(110)/2]
                > to 192.168.101.133 via eth2/eth2
192.168.103.0/24        [ospf(110)/2]
                > to 192.168.102.122 via eth3/eth3

Multicast routing Once unicast routing is up and running, we need to setup multicast routing. There are two protocols for this: IGMP and PIM-SM. The former one allows routers to forward multicast datagrams while the first one allows hosts to subscribe to a multicast group.

IGMP IGMP is used by hosts and adjacent routers to establish multicast group membership. In our case, it will be used by R2 to let E2 know it subscribed to 239.0.0.11 (a multicast group). Configuring XORP to support IGMP is simple. Let s test with iperf to have a multicast listener on R2:
root@r2# iperf -u -s -l 1000 -i 1 -B 239.0.0.11
------------------------------------------------------------
Server listening on UDP port 5001
Binding to local address 239.0.0.11
Joining multicast group  239.0.0.11
Receiving 1000 byte datagrams
UDP buffer size:  208 KByte (default)
------------------------------------------------------------
On E2, we can now check that R2 is properly registered for 239.0.0.11:
root@e2$ show igmp group
Interface    Group           Source          LastReported Timeout V State
eth0         239.0.0.11      0.0.0.0         192.168.2.2      248 2     E
XORP documentation contains a good overview of IGMP.

PIM-SM PIM-SM is far more complex. It does not have its own topology discovery protocol and relies on routing information from other protocols, OSPF in our case. I will describe here a simplified view on how PIM-SM works. XORP documentation contains more details about PIM-SM. The first step for all PIM-SM routers is to elect a rendez-vous point (RP). In our lab, only C1, C2 and C3 have been configured to be elected as a RP. Moreover, we give better priority to C3 to ensure it wins. RP election
root@e1$ show pim rps   
RP              Type      Pri Holdtime Timeout ActiveGroups GroupPrefix       
192.168.101.133 bootstrap 100      150     135            0 239.0.0.0/8
Let s suppose we start iperf on both R2 and R3. Using IGMP, they subscribe to multicast group 239.0.0.11 with E2 and E3 respectively. Then, E2 and E3 send a join message (also known as a (*,G) join) to the RP (C3) for that multicast group. Using the unicast path from E2 and E3 to the RP, the routers along the paths build the RP tree (RPT), rooted at C3. Each router in the tree knows how to send multicast packets to 239.0.0.11: it will send them to the leaves. RP tree
root@e3$ show pim join   
Group           Source          RP              Flags
239.0.0.11      0.0.0.0         192.168.101.133 WC   
    Upstream interface (RP):   eth2
    Upstream MRIB next hop (RP): 192.168.23.133
    Upstream RPF'(*,G):        192.168.23.133
    Upstream state:            Joined 
    Join timer:                5
    Local receiver include WC: O...
    Joins RP:                  ....
    Joins WC:                  ....
    Join state:                ....
    Prune state:               ....
    Prune pending state:       ....
    I am assert winner state:  ....
    I am assert loser state:   ....
    Assert winner WC:          ....
    Assert lost WC:            ....
    Assert tracking WC:        O.O.
    Could assert WC:           O...
    I am DR:                   O..O
    Immediate olist RP:        ....
    Immediate olist WC:        O...
    Inherited olist SG:        O...
    Inherited olist SG_RPT:    O...
    PIM include WC:            O...
Let s suppose that R1 wants to send multicast packets to 239.0.0.11. It sends them to R1 which does not have any information on how to contact all the members of the multicast group because it is not the RP. Therefore, it encapsulates the multicast packets into PIM Register packets and sends them to the RP. The RP decapsulates them and sends them natively. The multicast packets are routed from the RP to R2 and R3 using the reverse path formed by the join messages. Multicast routing via the RP
root@r1# iperf -c 239.0.0.11 -u -b 10k -t 30 -T 10
------------------------------------------------------------
Client connecting to 239.0.0.11, UDP port 5001
Sending 1470 byte datagrams
Setting multicast TTL to 10
UDP buffer size:  208 KByte (default)
------------------------------------------------------------
root@e1# tcpdump -pni eth0
10:58:23.424860 IP 192.168.1.1.35277 > 239.0.0.11.5001: UDP, length 1470
root@c3# tcpdump -pni eth0
10:58:23.552903 IP 192.168.11.11 > 192.168.101.133: PIMv2, Register, length 1480
root@e2# tcpdump -pni eth0
10:58:23.896171 IP 192.168.1.1.35277 > 239.0.0.11.5001: UDP, length 1470
root@e3# tcpdump -pni eth0
10:58:23.824647 IP 192.168.1.1.35277 > 239.0.0.11.5001: UDP, length 1470
As presented here, the routing is not optimal: packets from R1 to R2 could avoid the RP. Moreover, encapsulating multicast packets into unicast packets is not efficient either. At some point, the RP will decide to switch to native multicast1. Rooted at R1, the shortest-path tree (SPT) for the multicast group will be built using source-specific join messages (also known as a (S,G) join). Multicast routing without RP From here, each router in the tree knows how to handle multicast packets from R1 to the group without involving the RP. For example, E1 knows it must duplicate the packet and sends one through the interface to C3 and the other one through the interface to C1:
root@e1$ show pim join   
Group           Source          RP              Flags
239.0.0.11      192.168.1.1     192.168.101.133 SG SPT DirectlyConnectedS 
    Upstream interface (S):    eth0
    Upstream interface (RP):   eth1
    Upstream MRIB next hop (RP): 192.168.11.111
    Upstream MRIB next hop (S):  UNKNOWN
    Upstream RPF'(S,G):        UNKNOWN
    Upstream state:            Joined 
    Register state:            RegisterPrune RegisterCouldRegister 
    Join timer:                7
    KAT(S,G) running:          true
    Local receiver include WC: ....
    Local receiver include SG: ....
    Local receiver exclude SG: ....
    Joins RP:                  ....
    Joins WC:                  ....
    Joins SG:                  .OO.
    Join state:                .OO.
    Prune state:               ....
    Prune pending state:       ....
    I am assert winner state:  ....
    I am assert loser state:   ....
    Assert winner WC:          ....
    Assert winner SG:          ....
    Assert lost WC:            ....
    Assert lost SG:            ....
    Assert lost SG_RPT:        ....
    Assert tracking SG:        OOO.
    Could assert WC:           ....
    Could assert SG:           .OO.
    I am DR:                   O..O
    Immediate olist RP:        ....
    Immediate olist WC:        ....
    Immediate olist SG:        .OO.
    Inherited olist SG:        .OO.
    Inherited olist SG_RPT:    ....
    PIM include WC:            ....
    PIM include SG:            ....
    PIM exclude SG:            ....
root@e1$ show pim mfc  
Group           Source          RP             
239.0.0.11      192.168.1.1     192.168.101.133
    Incoming interface :      eth0
    Outgoing interfaces:      .OO.
root@e1$ exit
[Connection to XORP closed]
root@e1# ip mroute
(192.168.1.1, 239.0.0.11)        Iif: eth0       Oifs: eth1 eth2

Setting up VXLAN Once IP multicast is running, setting up VXLAN is quite easy. Here are the software requirements:
  • A recent kernel. Pick at least 3.7-rc3. You need to enable CONFIG_VXLAN option. You also currently need a patch on top of it to be able to specify a TTL greater than 1 for multicast packets.
  • A recent version of ip. Currently, you need the version from git.
On R1, R2 and R3, we create a vxlan42 interface with the following commands:
root@rX# ./ip link add vxlan42 type vxlan id 42 \
>                               group 239.0.0.42 \
>                               ttl 10 dev eth0
root@rX# ip link set up dev vxlan42
root@rX# ./ip -d link show vxlan42
10: vxlan42: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1460 qdisc noqueue state UNKNOWN mode DEFAULT 
link/ether 3e:09:1c:e1:09:2e brd ff:ff:ff:ff:ff:ff
vxlan id 42 group 239.0.0.42 dev eth0 port 32768 61000 ttl 10 ageing 300
Let s assign an IP in 192.168.99.0/24 for each router and check they can ping each other:
root@r1# ip addr add 192.168.99.1/24 dev vxlan42
root@r2# ip addr add 192.168.99.2/24 dev vxlan42
root@r3# ip addr add 192.168.99.3/24 dev vxlan42
root@r1# ping 192.168.99.2                    
PING 192.168.99.2 (192.168.99.2) 56(84) bytes of data.
64 bytes from 192.168.99.2: icmp_req=1 ttl=64 time=3.90 ms
64 bytes from 192.168.99.2: icmp_req=2 ttl=64 time=1.38 ms
64 bytes from 192.168.99.2: icmp_req=3 ttl=64 time=1.82 ms
--- 192.168.99.2 ping statistics ---
3 packets transmitted, 3 received, 0% packet loss, time 2003ms
rtt min/avg/max/mdev = 1.389/2.375/3.907/1.098 ms
We can check the packets are encapsulated:
root@r1# tcpdump -pni eth0
tcpdump: verbose output suppressed, use -v or -vv for full protocol decode
listening on eth0, link-type EN10MB (Ethernet), capture size 65535 bytes
11:30:36.561185 IP 192.168.1.1.43349 > 192.168.2.2.8472: UDP, length 106
11:30:36.563179 IP 192.168.2.2.33894 > 192.168.1.1.8472: UDP, length 106
11:30:37.562677 IP 192.168.1.1.43349 > 192.168.2.2.8472: UDP, length 106
11:30:37.564316 IP 192.168.2.2.33894 > 192.168.1.1.8472: UDP, length 106
Moreover, if we send broadcast packets (with ping -b or ARP requests), they are encapsulated into multicast packets:
root@r1# tcpdump -pni eth0
11:31:27.464198 IP 192.168.1.1.41958 > 239.0.0.42.8472: UDP, length 106
11:31:28.463584 IP 192.168.1.1.41958 > 239.0.0.42.8472: UDP, length 106
Recent versions of iproute also comes with bridge, an utility allowing one to inspect the FDB of bridge-like interfaces:
root@r1# ../bridge/bridge fdb show vxlan42
3e:09:1c:e1:09:2e dev vxlan42 dst 192.168.2.2 self 
0e:98:40:c6:58:10 dev vxlan42 dst 192.168.3.3 self

Demo For a demo, have a look at the following video (it is also available as an Ogg Theora video).
<iframe frameborder="0" height="270" src="http://www.dailymotion.com/embed/video/xusell" width="480"></iframe>

  1. The decision is usually done when the bandwidth used by the follow reachs some threshold. With XORP, this can be controlled with switch-to-spt-threshold. However, I was unable to make this works as expected. XORP never sends the appropriate PIM packets to make the switch. Therefore, for this lab, it has been configured to switch to native multicast at the first received packet.

Erich Schubert: DBSCAN and OPTICS clustering

DBSCAN [wikipedia] and OPTICS [wikipedia] are two of the most well-known density based clustering algorithms. You can read more on them in the Wikipedia articles linked above.
An interesting property of density based clustering is that these algorithms do not assume clusters to have a particular shape. Furthermore, the algorithms allow "noise" objects that do not belong to any of the clusters. K-means for examples partitions the data space in Voronoi cells (some people claim it produces spherical clusters - that is incorrect). See Wikipedia for the true shape of K-means clusters and an example that canot be clustered by K-means. Internal measures for cluster evaluation also usually assume the clusters to be well-separated spheres (and do not allow noise/outlier objects) - not surprisingly, as we tend to experiment with artificial data generated by a number of Gaussian distributions.
The key parameter to DBSCAN and OPTICS is the "minPts" parameter. It roughly controls the minimum size of a cluster. If you set it too low, everything will become clusters (OPTICS with minPts=2 degenerates to a type of single link clustering). If you set it too high, at some point there won't be any clusters anymore, only noise. However, the parameter usually is not hard to choose. If you for example expect clusters to typically have 100 objects, I'd start with a value of 10 or 20. If your clusters are expected to have 10000 objects, then maybe start experimenting with 500.
The more difficult parameter for DBSCAN is the radius. In some cases, it will be very obvious. Say you are clustering users on a map. Then you might know that a good radius is 1 km. Or 10 km. Whatever makes sense for your particular application. In other cases, the parameter will not be obvious, or you might need multiple values. That is when OPTICS comes into play.
OPTICS is based on a very clever idea: instead of fixing MinPts and the Radius, we only fix minpts, and plot the radius at which an object would be considered dense by DBSCAN. In order to sort the objects on this plot, we process them in a priority heap, so that nearby objects are nearby in the plot. this image on Wikipedia shows an example for such a plot.
OPTICS comes at a cost compared to DBSCAN. Largely because of the priority heap, but also as the nearest neighbor queries are more complicated than the radius queries of DBSCAN. So it will be slower, but you no longer need to set the parameter epsilon. However, OPTICS won't produce a strict partitioning. Primarily it produces this plot, and in many situations you will actually want to visually inspect the plot. There are some methods to extract a hierarchical partitioning out of this plot, based on detecting "steep" areas.
The open source ELKI data mining framework (package "elki" in Debian and Ubuntu) has a very fast and flexible implementation of both algorithms. I've benchmarked this against GNU R ("fpc" package") and Weka, and the difference is enormous. ELKI without index support runs in roughly 11 minutes, with index down to 2 minutes for DBSCAN and 3 minutes for OPTICS. Weka takes 11 hours and GNU R/fpc takes 100 minutes (DBSCAN, no OPTICS available). And the implementation of OPTICS in Weka is not even complete (it does not support proper cluster extraction from the plot). Many of the other OPTICS implementations you can find with Google (e.g. in Python or MATLAB) seem to be based on this Weka version ...
ELKI is open source. So if you want to peek at the code, here are direct links: DBSCAN.java, OPTICS.java.
Some part of the code may be a bit confusing at first. The "Parameterizer" classes serve the purpose of allowing automatic UI generation, for example. So there is quite a bit of meta code involved.
Plus, ELKI is quite extensively optimized. For example, it does not use Java Collections much anymore. Java Iterators, for example, require returning an object on next();. The C++ style iterators used by ELKI can have multiple values, and primitive values.
for(DBIDIter id = relation.iterDBIDs(); id.valid(); id.advance())
is a typical for loop in ELKI, iterating over all objects of a relation, but the whole loop requires creating (and GC'ing) a single object. And actually, this is as literal as a for loop can get.
ModifiableDBIDs processedIDs = DBIDUtil.newHashSet(size);
is another example. Essentially, this is like a HashSet<DBID>. Except that it is a lot faster, because the object IDs do not need to live a Java objects, but can internally be stored more efficiently (the only currently available implementation of the DBID layer uses primitive integers).
Java advocates always accuse you of premature optimization when you avoid creating objects for primitives. Yet, in all my benchmarking, I have seen this continuously to have a major impact how many objects you allocate. At least when it is inside a loop that is heavily used. Java collections with boxed primitives just eat a lot of memory, and the memory management overhead does often make a huge difference. Which is why libraries such as Trove (which ELKI uses a lot) exist. Because memory usage does make a difference.
(Avoiding boxing/unboxing systematically in ELKI yielded approximately a 4x speedup. But obviously, ELKI involves a lot of numerical computations.)

Lisandro Dami&aacute;n Nicanor P&eacute;rez Meyer: Is your KDE slooooow? Check your loopback interface

While digging Debian Qt-KDE's bugs, it has become more common to find people reporting that their KDE is very slow. Most of the time (if not every time) it turns out that the loopback interface is down. Sometimes the user did something wrong, sometimes some network manager, but the end result is the same: KDE is terribly slow.

A user filled a bug upstream to ask for a dialogue in KDE that warns the user about this fact. Let's hope it get's implemented :-)

OK, so, how do I check that my lo interface is up?

You can simply run:

$ /sbin/ifconfig
eth0 Link encap:Ethernet HWaddr 00:1f:c6:ba:70:f3

lo Link encap:Local Loopback
inet addr:127.0.0.1 Mask:255.0.0.0
inet6 addr: ::1/128 Scope:Host
UP LOOPBACK RUNNING MTU:16436 Metric:1
RX packets:1807 errors:0 dropped:0 overruns:0 frame:0
TX packets:1807 errors:0 dropped:0 overruns:0 carrier:0
collisions:0 txqueuelen:0
RX bytes:494525 (482.9 KiB) TX bytes:494525 (482.9 KiB)

The last entry "lo" tells us that the interface is up.

In Debian, the file /etc/network/interfaces should have something like:

# The loopback network interface
auto lo
iface lo inet loopback

So, next time you find a KDE session is slow, you know what to do ;-)

1 November 2012

Antoine Beaupr : My short computing history

This is a long story. I wanted to document which tools I used on my desktop, but then realized it was difficult to do this without an historical context. This therefore, became a history of my computer usage and programming habits.

Before the desktop: vic 20 and apple My first contacts with computers were when my uncle showed me his Apple computers at his home. He was working at UQAM and had access to all sorts of crazy computers. My memory is vague, but I believe he showed me a turtle moving around the screen, which I suspect was Logo, and some rabbit game which I was quite fond of. Later, I hooked up with a Vic-20 (similar to a Commodore 64) and typed in my first programs. Back then, you would painstakingly transcribe the program from a book into the screen, type RUN at the end and really hope that you didn't make a typo. You could also read and write data off audio tape with an external tape drive, which was really amazing. To put things into perspective, the Vic-20 would plug into your television for a display, and the computer was "in the keyboard". Old school shit. The language was BASIC, which was awful. Later, we got luxurious and had the privilege of a Macintosh Plus computer. 3000$ plus the printer, that was quite something. Still, that modern system could run Word, had games, and a 9" black and white screen. But the best part, and where I really started to learn to program, is with Hypercard, the crazy software written by Bill Atkinson that became the inspiration for wikis, the Myst computer game and, to a certain extent, popularized the concept of hyperlinking, which is the basic principle of the World Wide Web.

The early years: afterstep and FreeBSD But my real computer life all started with FreeBSD 2.2.x (probably 2.2.5), around 1997, when I installed my first FLOSS operating system. This was just amazing: source code for everything, down to the compilers themselves, I was amazed, since I was coming from a Mac (still had that Mac Plus lying around) and Windows (95!) world. Back then, X11 (XFree86, it was called) was a fantasy. Something I would compile with the FreeBSD ports system and sometimes would be able to run. Window managers were some weird things I wasn't sure how to use, but I figured out twm (yuck!) but was still amazed. At the university, we had SGI workstations (remember the Indigo machines?) on which I started setting up the Afterstep window manager, which I used for a long time. The web browser was Netscape Communicator 4, and lo and behold, it also did email, although I mostly used Pine over a modem terminal to the university. Internet access at home was spotty and was dependent on students compiling discreetly copies of slirp which were allowing us, in a really clunky way, to run a PPP session over those terminal lines. That actually got my account suspended because I messed up my sendmail configuration and was sending emails that appeared to be coming as , which freaked out the sysadmins that be over there. The hardware was a Pentium 166Mhz with 32MB of ram and 20GB of disk space, which was a huge improvement over the 1MB of ram and 20MB of (external!) hard disk that the Mac Plus was proud of. By then, I started programming in more languages: I learned the basics of shell scripting, C programming and I had learned Pascal in a college class.

The real freedom: Debian and... enlightenment? I then switched to Debian, thanks to my friend scyrma, which showed me the power of dselect which, for a FreeBSD user, was really impressive. Imagine that: you could just install software and all dependencies without compiling anything! ;) I don't exactly remember when that was, but it was probably Woody. I probably still used afterstep, but at that time, changing window managers was like changing t-shirts and we would waste countless hours fiddling around with borders and background images and other silly things. I remember running Enlightenment and writing software for it, for example, but not much else. Back then, email was still over pine, but a new web browser was rearing its ugly head, Mozilla, and was quickly trimmed down to Phoenix, shortly lived as Mozilla Firebird, only to be finally renamed Mozilla Firefox, and was unleashed as a stable release to an unsuspecting Internet Explorer and Microsoft-dominated world. Throughout this chaos, I also used various Mozilla derivatives like Galeon since all of this was pretty unstable and heavy for my poor computers. This was probably around 2002 to 2005. By then, I had formal classes on programming languages, was forced to learn Java, discovered C++, and learned more C as the university assumed that you knew that language in the data structures and algorithm class, which some students really didn't find funny at all. I also learned some Prolog and Haskell back then. Through my experiences with free software, I discovered various eclectic programming languages like TCL, and kept an eye out for other languages like lisp (thanks to Emacs), Forth (thanks to the FreeBSD boot loader), HTML/CSS/Javascript (no thanks to the web). There are probably others I am forgetting here, voluntarily or not.

The years of the desktops: rox, sawfish and gnome Another stable increment on my desktop was the use of the sawfish window manager and the rox desktop, mostly because of the awesome Rox file manager that had no equal in the rest of the free software world. Gnome was an atrocity and KDE even more so: bloated and unstable. Eventually, however, KDE and Gnome not only matured, but simply took over the whole of the graphical environment psyche of the free world. People nowadays don't even know what a window manager is and assume that you now have a "desktop environment", which, for me, is a real desk with a bunch of papers, a radio transceiver and maybe a computer with a screen lying around. So I did use KDE, and then Gnome. I switched from KDE to Gnome because I felt that Gnome left me more space to run my own stuff without starting crazy daemons to preload everything. At this point, Firefox was the new thing and basically stable enough for daily use. This lasted until around 2009, I guess. On the programming side, I had picked up Perl because I had to learn it to work at Ericsson (don't ask) and learned PHP to pay my rent, which I consider one of the biggest professional mistakes I have made so far in that story. It is around that time that Koumbit was founded by me and other friends.

The tiles fall on the gnomes: awesome desktop and sysadmin programming At some point, friends (mostly comar and millette) introduced me to wmii as the best thing since sliced bread. I banged my head against it with great pains, but I really enjoyed the hands off approach to window management. Tiling window managers really got a hold on me there, and in fact we can say on the whole desktop, with recent Gnome 3 taking up some tiling concepts itself. I have since then switched to the Awesome Window Manager which is probably the worst name you can use for software (try googling for "Awesome crash" to get an idea). I have switched from Firefox to Chromium, after having repeated crashes from Firefox on a site that Chrome would load fine. I was expecting Chrome to crash only one tab, because of its design, and it turned out to not crash at all, and I have since given up on Firefox totally. I have also given up on desktop environments. While I have given them a chance in quick setups and still use them when forced to, I find them too bloated and single-minded for my needs. I want control over my desktop, and those tools work very hard to remove control and hide it behind user interfaces that treat me like a brain-dead dog. Finally, I have kept on programming in PHP for work, because that's what we do over there (unfortunately). Mostly because of Drupal and Aegir, in which I was and still am deeply involved. But I am quite fond of Python for my personnal project and still use shell scripting to get myself out of trouble or automate data processing from time to time. I have a rule though: once a program hits 100 lines of shell scripting, it needs to be rewritten, usually in Perl because the syntax is closer. During the years 2009 to 2012, I have started to work more and more on system administration however. In 2010, I became a Debian Developer and a lot of my work at Koumbit revolves around system administration, optimisation and maintenance. I work oncall and sometimes get called during the night to nurse servers (which is why I am up writing this right now).

The future of programming I have become seriously disgruntled with programming. I have seen the emergence of the web, where programmers felt it was relevant to rewrite 30 years of programs into the web framework (webmail? wtf?), and now we are seeing the same thing happen with mobile devices, the tracking devices they call phones and "pads", we should rather say. And again they are trying to make people pay for trivial software. I am tired of seeing our community reinvent the wheel every 10 years because of infatuated egos and marketing sprints. We are wasting great minds on this, a lot of energy and precious time. I would rather maintain 5 year old imperfect software than coordinate a 5 year project to rewrite that software into another imperfect software. That is what is happening right now, and it's going nowhere. So here's the current state of affairs, some perls, some tiles, but mostly system administration and less programming. Through all this time, the common pattern is that I have learned to solve problems and document my work, which are key concepts of the job of a system administrator, which is what I really am now. Somehow, that popped into my life like a natural fit. Maybe, one day, I will retire and become a shepherd in far away mountains, but I will always have in my mind the strong desire to fix shit up and make things right with the world. Maybe get involved in a project like Open Source Ecology and especially their Global Village Construction Set to make sure humankind survives all that stupidity.

31 October 2012

Mirco Bauer: Mono 3.0 Preview Packages for Debian and Ubuntu

Just after the Mono 3.0 release was announced I started working on Debian packages and after a couple of days of hard work I already have some preview packages for you. The preview packages are currently limited to the AMD64 architecture but can be installed on Debian/Testing (Wheezy), Debian/Unstable (Sid) and Ubuntu/Quantal (12.10). After these preview packages have received some successful feedback (please leave feedback via comments!), I will upload them to Debian/Experimental. In case you are shocked why I have packages in just 8 days after the official Mono 3.0 release, there are 3 factors that play a big role:
  1. New packaging workflow
    • Downstream patches are management in git branches
    • Release Early, Release Often: I no longer port and test every patch very carefully (especially with architecture specific patches), instead I port them with my best knowledge and upload them to debian.meebey.net and/or Debian/Experimental and use that as test ground. If regressions happen, let them happen, and make further uploads to address them.
  2. New packaging style
  3. Sponsored packaging
    • As my employer needs Mono packages for an upcoming software project, I was granted to work on Mono packages in worktime.
Install instructions OBLIGATORY WARNING: DO NOT USE THESE PREVIEW PACKAGES ON PRODUCTION SYSTEMS NOR BLAME ME IF YOUR MONO SOFTWARE NO LONGER WORKS! Add this line to your /etc/apt/sources.list file:
deb http://debian.meebey.net/experimental/mono /
Now update the APT database and install mono-complete from that repository:
apt-get update
apt-get install mono-complete

Paul Tagliamonte: dput-ng -- the next generation of your friendly upload tool

Hello, World! Arno and I have been in the middle of a 3 week long quest to rewrite dput. We feature tons of improvements over the old dput, such as: Support for even core features are treated as plugins, so derivative distributions should be able to add features without maintaining a patch against dput (current situation). In addition, I ve implemented some show-ey post-upload hooks, such as a Twitter plugin. Here s how it s defined:
import twitter
import json
import os
def tweet(changes, profile, interface):
    tweet = "I've just uploaded %s/%s to %s's %s suite #debian" % (
        changes['Source'],
        changes['Version'],
        profile['name'],
        changes['Distribution']
    )
    if len(tweet) > 140:
        tweet = tweet[:140]
    obj = json.load(open(os.path.expanduser("~/.twitter.json"), 'r'))
    t = twitter.Api(
        consumer_key=obj['consumer_key'],
        consumer_secret=obj['consumer_secret'],
        access_token_key=obj['oath_token'],
        access_token_secret=obj['oath_secret']
    )
    t.PostUpdates(tweet)
This file is placed in ~/.dput.d/scripts, as tweet.py, and the plugin def file is placed in ~/.dput.d/processors (since it s a post-upload processor), which looks like:
 
    "name": "Tweet after an upload.",
    "path": "tweet.tweet"
 
I know this sounds confusing, but it s actually quite nice. Check out the plugin in action Feedback, and contributors more then welcome! Documentation is at dput.rtfd.org. It s all a bit pre-beta at the moment, but the authors are using it for all their uploads, and should be stable for users who don t mind a bit of breakage. We ve filed the ITP, and updates on it & and upload will follow shortly. We re just weeding out some final major issues. Should be stable enough for general use in the next 30 days or so.

30 October 2012

Nathan Handler: Debian Screencast Challenge

Today in #debian-mentors, a brief discussion about screencasts came up. Some people felt that a series of short screencasts might be a nice addition to the existing Debian Developer documentation. After seeing the popularity of of Ubuntu's various video series over the years, I tend to agree that video documentation can be a nice way to supplement traditional text-based documentation. No, this is not designed to replace the existing documentation; it is merely designed to provide an alternative method for people to learn the material. From past experience, I know that if I were to start making screencasts by myself, I would end up making one or two before getting bored and moving on to a new project. That is why I am posing a challenge to the Debian community: I will make one screencast for every screencast made by someone in the Debian community. These screencasts can and should be short (only a couple of minutes in length) and focus on accomplishing one small task or explaining a single concept related to Debian Development. I discovered a Debian Screencasts page on the Debian wiki that links to Ubuntu's guide to creating screencasts. While I have done some traditional documentation work in the past, I have never really tried doing screencasts. As a result, this will be a bit of a learning experience for me at first. If you are interested in taking me up on this challenge, simply send me an email (nhandler [at] ubuntu [dot] com) or poke me on IRC (nhandler@ freenode,oftc ). This will allow us to coordinate and plan the screencasts. As I mentioned earlier, I have no experience creating screencasts, so if you are familar with the Debian Development processes and think this challenge sounds interesting, feel free to contact me.

Rapha&#235;l Hertzog: Auto Mounting Windows Shares in GNOME with Gigolo and gvfs-fuse

The traditional way to mount Windows (or Samba) shares involves hardcoding the credentials in a plain-text file and some /etc/fstab entry to mount it automatically at boot time. If you don t want to store a plain-text copy of your password, you re bound to mount your shares interactively. This is clearly sub-optimal and I thought that there must be a better way to handle this in the context of a GNOME desktop (which already supports connecting to such shares in the file browser). So I looked for a solution and after a bit of googling I found one. Start by installing a few packages:
$ sudo apt-get install gigolo gvfs-fuse
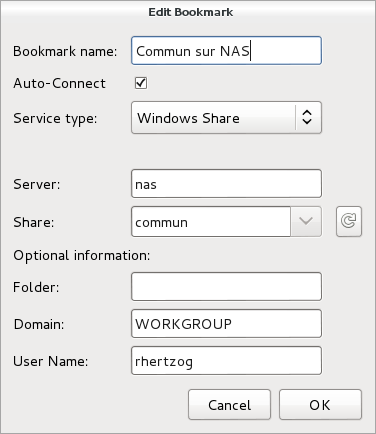
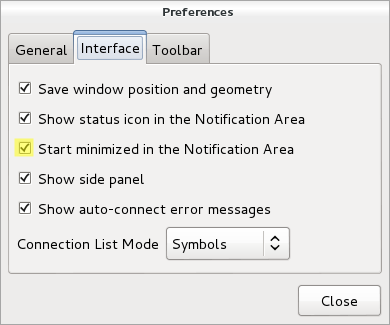
Launch Gigolo, setup your shares as bookmarks and mark them as Auto-Connect . During (first) connection, you will be prompted for your password and you have the possibility to store it in the GNOME keyring (and here it s encrypted, not in plain-text!). You should also configure the Gigolo preferences so that it starts minimized in the system tray (because we re going to run it on session startup):
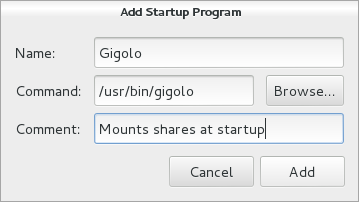
The last step is to ensure that Gigolo is executed at the start of each GNOME session. Unfortunately this GNOME feature is no longer accessible from the control center so you have to execute gnome-session-properties manually (from a terminal or the command line accessible via Alt+F2). Click on Add to add a new startup program: You re done! The main limitation is that those shares are not real mounts, instead they are available within GNOME s virtual file system (GVFS). If you use only 100% GNOME application, then it s not a problem but otherwise it s pretty annoying. You can t cd in those shares from a terminal for example. There s a workaround though, it s called gvfs-fuse and you installed it right at the start of this HOWTO. This service hooks into GVFS and exports all the virtual filesystem(s) in a real fuse-based mount that is automatically setup in ~/.gvfs/. However for this to work, the user must be in the fuse group. So you should run something like this:
$ sudo adduser $USER fuse
By the way, I haven t found a way to use a non-hidden directory so if you want this directory to be more visible, I suggest that you create a symlink pointing to it.
Do you want to read more HOWTO like this one? Click here to subscribe to my free newsletter, you can opt to receive future articles by email.

No comment Liked this article? Click here. My blog is Flattr-enabled.

Wouter Verhelst: The fastest slug in the world (probably)

How fast do slugs travel? Empirical evidence tells me that's about 1 meter per hour1. But not this slug. IMAG0114 As I was driving home from $CUSTOMER, I noticed something on my car. At first I thought it was bird poop, but then bird poop doesn't move. As the animal crawled higher and higher next to my windshield (while I was driving down the highway), I thought it would soon be blown off; but no, it bravely held on. Since it was crawling against my driving direction, that meant it was hurling down the highway at about 119.999 kph. I'm not sure if slugs have emotions; but if they do, the poor animal must've been terribly scared. Since these weird 120kph winds kept blowing on this weird and not very sticky surface that is the rubber and the metal edge to the side of the winshield, the animal kept going until it found that the glass of the windshield itself is actually a very interesting place for it to settle. By that time I had reached a usable exit, so I went off. As I reduced the car's speed once off the highway, the animal had decided that it was fairly nice outside its house now, and was starting to move horizontally along my windshield. Not exactly what I wanted it to do. So I took the above picture with the wrong camera (I remembered a mere few minutes later that I had my DSLR in the back of my car), took it off, and released it into the nearby bushes. Of course, by that time I'd driven several dozens of kilometers away from wherever it was that I picked it up, so the animal will probably never get home again. But hey, I'm sure it'll love the new bushes. 1 Once, over half a lifetime ago, I noticed a slug sitting by the side of the road. Not having much else to do, I sat down and watched it. By the time it had moved some two meters, it had gotten dark and cold, and I went home. At that point, my parents told me they'd started to worry because I was two hours late from school. I could be slightly wrong about the numbers, though. It's been a long time.

Matthew Garrett: Getting started with UEFI development

It's not difficult to write a UEFI application under Linux. You'll need three things:


So, let's write a trivial UEFI application. Here's one from the gnu-efi source tree:
#include <efi.h>
#include <efilib.h>
EFI_STATUS
efi_main (EFI_HANDLE image, EFI_SYSTEM_TABLE *systab)
 
        SIMPLE_TEXT_OUTPUT_INTERFACE *conout;
        conout = systab->ConOut;
        InitializeLib(image, systab);
        uefi_call_wrapper(conout->OutputString, 2, conout, L"Hello World!\n\r");
        return EFI_SUCCESS;
 
The includes are fairly obvious. efi.h gives you UEFI functions defined by the specification, and efilib.h gives you functions provided by gnu-efi. The runtime will call efi_main() rather than main(), so that's our main function. It returns an EFI_STATUS which will in turn be returned to whatever executed the binary. The EFI_HANDLE image is a pointer to the firmware's context for this application, which is used in certain calls. The EFI_SYSTEM_TABLE *systab is a pointer to the UEFI system table, which in turn points to various other tables.

So far so simple. Now things get interesting. The heart of the UEFI programming model is a set of protocols that provide interfaces. Each of these interfaces is typically a table of function pointers. In this case, we're going to use the simple text protocol to print some text. First, we get a pointer to the simple text output table. This is always referenced from the system table, so we can simply assign it. InitializeLib() just initialises some internal gnu-efi functions - it's not technically required if we're purely calling native UEFI functions as we are here, but it's good style since forgetting it results in weird crashes.

Anyway. We now have conout, a pointer to a SIMPLE_TEXT_OUTPUT_INTERFACE structure. This is described in section 11.4 of the UEFI spec, but looks like this:
typedef struct _EFI_SIMPLE_TEXT_OUTPUT_PROTOCOL  
    EFI_TEXT_RESET Reset;
    EFI_TEXT_STRING OutputString;
    EFI_TEXT_TEST_STRING TestString;
    EFI_TEXT_QUERY_MODE QueryMode;
    EFI_TEXT_SET_MODE SetMode;
    EFI_TEXT_SET_ATTRIBUTE SetAttribute;
    EFI_TEXT_CLEAR_SCREEN ClearScreen;
    EFI_TEXT_SET_CURSOR_POSITION SetCursorPosition;
    EFI_TEXT_ENABLE_CURSOR EnableCursor;
    SIMPLE_TEXT_OUTPUT_MODE *Mode;
  EFI_SIMPLE_TEXT_OUTPUT_PROTOCOL;
The majority of these are functions - the only exception is the SIMPLE_TEXT_OUTPUT_MODE pointer, which points to the current mode. In an ideal world you'd be able to just call these directly, but sadly UEFI and Linux calling conventions are different and we need some thunking. That's where the uefi_call_function() call comes in. This takes a UEFI function as its first argument (in this case, conout->OutputString), the number of arguments (2, in this case) and then the arguments. Checking the spec for OutputString, we see this:
typedef
EFI_STATUS
(EFIAPI *EFI_TEXT_STRING) (
    IN EFI_SIMPLE_TEXT_OUTPUT_PROTOCOL *This,
    IN CHAR16 *String
);
The first argument is a pointer to the specific instance of the simple text output protocol. This permits multiple instances of the same protocol to exist on a single machine, without having to duplicate all of the code. The second argument is simply a UCS-2 string. Our conout pointer is a pointer to the protocol, so we pass that as the first argument. For the second argument, we pass L"Hello World!\n", with the L indicating that this is a wide string rather than a simple 8-bit string. uefi_call_function() then rearranges these arguments into the appropriate calling convention and calls the UEFI function. The firmware then prints "Hello World!" on the screen. Success.

(Warning: uefi_call_function() does no type checking on its arguments, so if you pass in a struct instead of a pointer it'll build without complaint and then give you a bizarre error at runtime)

Finally, we clean up by simply returning EFI_SUCCESS. Nothing more for us to worry about. That's the simple case. What about a more complicated one? Let's do something with that EFI_HANDLE that got passed into efi_main().
#include <efi.h>
#include <efilib.h>
EFI_STATUS
efi_main (EFI_HANDLE image, EFI_SYSTEM_TABLE *systab)
 
        EFI_LOADED_IMAGE *loaded_image = NULL;
        EFI_GUID loaded_image_protocol = LOADED_IMAGE_PROTOCOL;
        EFI_STATUS status;
        InitializeLib(image, systab);
        status = uefi_call_wrapper(systab->BootServices->HandleProtocol,
                                3,
                                image, 
                                &loaded_image_protocol, 
                                (void **) &loaded_image);
        if (EFI_ERROR(status))  
                Print(L"handleprotocol: %r\n", status);
         
        Print(L"Image base        : %lx\n", loaded_image->ImageBase);
        Print(L"Image size        : %lx\n", loaded_image->ImageSize);
        Print(L"Image file        : %s\n", DevicePathToStr(loaded_image->FilePath));
        return EFI_SUCCESS;
 
UEFI handles can have multiple protocols attached to them. A handle may represent a piece of physical hardware, or (as in this case) it can represent a software object. In this case we're going to get a pointer to the loaded image protocol that's associated with the binary we're running. To do this we call the HandleProtocol() function from the Boot Services table. Boot services are documented in section 6 of the UEFI specification and are the interface to the majority of UEFI functionality. HandleProtocol takes an image and a protocol identifier, and hands back a pointer to the protocol. UEFI protocol identifiers are all GUIDs and defined in the specification. If you call HandleProtocol on a handle that doesn't implement the protocol you request, you'll simply get an error back in the status argument. No big deal.

The loaded image protocol is fairly different to the simple text output protocol in that it's almost entirely data rather than function pointers. In this case we're printing the address that our executable was loaded at and the size of our relocated executable. Finally, we print the path of the file. UEFI device paths are documented in section 9.2 of the UEFI specification. They're a binary representation of a file path, which may include the path of the device that the file is on. DevicePathToStr is a gnu-efi helper function that converts the objects it understands into a textual representation. It doesn't cover the full set of specified UEFI device types, so in some corner cases it may print "Unknown()".

That covers how to use protocols attached to the image handle. How about protocols that are attached to other handles? In that case we can do something like this:
#include <efi.h>
#include <efilib.h>
EFI_STATUS
efi_main (EFI_HANDLE image_handle, EFI_SYSTEM_TABLE *systab)
 
        EFI_STATUS status;
        EFI_GRAPHICS_OUTPUT_PROTOCOL *gop;
        EFI_GUID gop_guid = EFI_GRAPHICS_OUTPUT_PROTOCOL_GUID;
        InitializeLib(image_handle, systab);
        status = uefi_call_wrapper(systab->BootServices->LocateProtocol,
                                   3,
                                   &gop_guid,
                                   NULL,
                                   &gop);
        Print(L"Framebuffer base is at %lx\n", gop->Mode->FrameBufferBase);
        return EFI_SUCCESS;
 
This will find the first (where first is an arbitrary platform ordering) instance of a protocol and return a pointer to it. If there may be multiple instances of a protocol (as there often are with the graphics output protocol) you should use LocateHandleBuffer() instead. This returns an array of handles that implement the protocol you asked for - you can then use HandleProtocol() to give you the instance on the specific handle. There's various helpers in gnu-efi like LibLocateHandle() that make these boilerplate tasks easier. You can find the full list in /usr/include/efi/efilib.h.

That's a very brief outline of how to use basic UEFI functionality. The spec documents the full set of UEFI functions available to you, including things like direct block access, filesystems and networking. The process is much the same in all cases - you locate the handle that you want to interact with, open the protocol that's installed on it and then make calls using that protocol.Building these examplesBuilding these examples is made awkward due to UEFI wanting PE-COFF binaries and Linux toolchains building ELF binaries. You'll want a makefile something like this:
ARCH            = $(shell uname -m   sed s,i[3456789]86,ia32,)
LIB_PATH        = /usr/lib64
EFI_INCLUDE     = /usr/include/efi
EFI_INCLUDES    = -nostdinc -I$(EFI_INCLUDE) -I$(EFI_INCLUDE)/$(ARCH) -I$(EFI_INCLUDE)/protocol
EFI_PATH        = /usr/lib64/gnuefi
EFI_CRT_OBJS    = $(EFI_PATH)/crt0-efi-$(ARCH).o
EFI_LDS         = $(EFI_PATH)/elf_$(ARCH)_efi.lds
CFLAGS          = -fno-stack-protector -fpic -fshort-wchar -mno-red-zone $(EFI_INCLUDES)
ifeq ($(ARCH),x86_64)
        CFLAGS  += -DEFI_FUNCTION_WRAPPER
endif
LDFLAGS         = -nostdlib -znocombreloc -T $(EFI_LDS) -shared -Bsymbolic -L$(EFI_PATH) -L$(LIB_PATH) \
                  $(EFI_CRT_OBJS) -lefi -lgnuefi
TARGET  = test.efi
OBJS    = test.o
SOURCES = test.c
all: $(TARGET)
test.so: $(OBJS)
       $(LD) -o $@ $(LDFLAGS) $^ $(EFI_LIBS)
%.efi: %.so
        objcopy -j .text -j .sdata -j .data \
                -j .dynamic -j .dynsym  -j .rel \
                -j .rela -j .reloc -j .eh_frame \
                --target=efi-app-$(ARCH) $^ $@
There's rather a lot going on here, but the important stuff is the CFLAGS line and everything after that. First, we need to disable the stack protection code - there's nothing in the EFI runtime for it to call into, so we'll build a binary with unresolved symbols otherwise. Second, we need to build position independent code, since UEFI may relocate us anywhere. short-wchar is needed to indicate that strings like L"Hi!" should be 16 bits per character, rather than gcc's default of 32 bits per character. no-red-zone tells the compiler not to assume that there's 256 bytes of stack available to it. Without this, the firmware may modify stack that the binary was depending on.

The linker arguments are less interesting. We simply tell it not to link against the standard libraries, not to merge relocation sections, and to link in the gnu-efi runtime code. Nothing very exciting. What's more interesting is that we build a shared library. The reasoning here is that we want to perform all our linking, but we don't want to build an executable - the Linux executable runtime code would be completely pointless in a UEFI binary. Once we have our .so file, we use objcopy to pull out the various sections and rebuild them into a PE-COFF binary that UEFI will execute.

comment count unavailable comments

29 October 2012

Nathan Handler: Hello Chronicle!

Over the years, I have had many different blogs. I mainly use them to post updates regarding my work in the FOSS community, with most of these relating to Ubuntu/Debian. My most recent blog was a Wordpress instance I ran on a VPS provided by a friend. This worked pretty well, but for various reasons, I no longer have access to that box. Earlier today, I started thinking about launching a new blog. The first problem I had to overcome was deciding where to host it. Many of the groups I am involved with provide members with a ~/public_html directory that can be used to host simple HTML+Javascript+CSS websites. However, most of these sites do not have the ability to use PHP, CGI, or access databases. I realized rather quickly that if I were to find a blogging platform that I could run from a ~/public_html directory on one of those machines, I would never have the problem of not having a host for my blog ever again. There is a near infinite number of free web hosts that can handle simple HTML sites. One key feature of any blog is the ability for readers to subscribe to it. Usually, the blogging platform handles automatically updating the feed when a new post is published. However, my simple HTML blog would not be able to do that. Since I knew I did not want to manually update the feeds, I started looking for a way to generate the feed locally on my personal machine and then push it to the remote site that is hosting my blog. About this time, I started compiling a list of features I would need to make this blogging platform usable. In no particular order, they included: After some searching, I found an application developed by Steve Kemp called Chronicle. Chronicle supports all of the features I described plus many more. It is also very quick and easy to setup. If you are running Debian, Chronicle is available from the repositories. Start by installing Chronicle. Note that these steps should all be done on your personal machine, not the machine that is going to host your blog.
sudo apt-get install chronicle
There are a few other packages that you can install to extend the functionality of Chronicle
sudo apt-get install memcached libcache-memcached-perl libhtml-calendarmonthsimple-perl libtext-vimcolor-perl libtext-markdown-perl
Next, create a few folders to hold our blog. We will store our raw blog posts in ~/blog/input and have the generated HTML versions go in ~/blog/output.
mkdir -p ~/blog/ input,output 
Now, we need to configure some preferences. We will base our preferences on the global configuration file shipped with the package.
cp /etc/chroniclerc ~/.chroniclerc
Open up the new ~/.chroniclerc file in your favorite editor. It is pretty well commented, but I will still explain the changes I made. input is the path to where your blog posts can be found. These are the raw blog posts, not the generated HTML versions of the posts. In our example, this should be set to ~/blog/input. pattern tells Chronicle which files in the input directory are blog posts. We will use a .txt extension to denote these files. Therefore, set pattern to *.txt. output is the directory where Chronicle should store the generated HTML versions of the blog posts. This should be ~/blog/output theme-dir is the directory that holds all of the themes. Chronicle ships with a couple of sample themes that you can use. Set this to /usr/share/chronicle/themes theme is the name of the theme you want to use. We will just use the default them, so set this to default entry-count specifies how many blog posts should be displayed on the HTML index page for the blog. I like to keep this fairly small, so I set mine to 10. rss-count is similar to entry-count, but it specifies the number of blog posts to include in the RSS feed. I also set this to 10 format specifies the format used in the raw blog posts. I write mine in markdown, but multimarkdown, textile, and html are also supported. Since most ~/public_html directories do not support CGI. We will disable comments by setting no-comments to 1 suffix gets appended to the filenames of all of the generated blog posts. Set this to .html url_prefix is the first part of the URL for the blog. If the index.html file for the blog is going to be available at http://example.com/blog/ , set this to *http://example.com/~user/blog/ blog_title is whatever you want your blog to be called. The title is displayed at the top of the site. Set it to something like Your Name's Blog post-build is a very useful setting. It allows us to have Chronicle perform some action after it finishes running. We will use this to copy our blog to the remote host's public_html directory. Set this field to something like scp -r output/* user@example.com:~/public_html/blog. You will probably want to setup SSH so that you do not need to enter a password each time. Finally, date-archive-path will allow you to get the nice year/month directories to sort your posts. Set this to 1. Your final ~/.chroniclerc should look something like this:
input = ~/blog
pattern = *.txt
output = ~/blog/output
theme-dir = /usr/share/chronicle/themes
theme = default
entry-count = 10
rss-count = 10
format = markdown
no-comments = 1
suffix = .html
url_prefix = http://example.com/~user/blog/
blog_title    = Your Name's Blog
post-build = scp -r output/* user2@example.com:~/public_html/blog
date-archive-path = 1
You are now ready to start writing your first blog post. Open up ~/blog/MyFirstBlogPost.txt in your favorite text editor. Modify it to look like this:
Title: My First Blog Post
Tags: MyTag
Date: October 29, 2012
This is my **first** blog post.
Notice the metadata stored at the top? This is required for every post. Chronicle uses it to figure out the post title, tags, and date. It has some logic to try and guess this information if missing, but it is probably safest if you specify it. The empty line between the metadata and the post content is also required. Remember, we configured Chronicle to treat these as Markdown files, so feel free to utilize any Markdown formatting you wish. Finally, run chronicle from a terminal. If all goes well, it should generate your blog and copy the files to the remote host. You can now go to http://example.com/~user/blog to view it. One final suggestion would be to store the entire blog in a git repository. This will allow you to utilize all of the features of a VCS, such as reverting any accidental changes or allowing multiple people to collaborate on a blog post at the same time.

28 October 2012

Sandro Tosi: Start a MySQL instance to run Debian package build-time tests

I'm the maintainer of MySQL Connector/Python Debian package, and it's shipped with several unittests, but they require a MySQL instance to be run against, so up to know I wasn't able to run them at build-time.

But I want to change that, so I wanted to find a way to spawn a MySQL instance just for testing purposes. I've searched a lot, and then found a package solving the same problem: php5.

The package has a setup-mysql.sh script that takes care of starting/stopping the instances, and debian/rules file sets up instance parameters and then it starts the instance before the tests and then stops it after them.

It's a very interesting solution, so I thought of sharing + taking notes to self, just in case I need it in other situations.

Roland Mas: Guitar Hero drumkits and MIDI, again

Almost a year after my previous post, I felt inclined to spend another Sunday (this one was chilly rather than rainy) working on my script to integrate the drumkit of Guitar Hero World Tour for Wii within a MIDI environment. And wiigh2midi got, if not a rewrite, then at least a few enhancements since I last mentioned it here. It's still not something that I'd put in everyone's hands, but it's coming to be seriously usable. I wonder if there'd be any interest in me packaging that and uploading it to Debian? It would need some cleanup first (and a more generic name, since it's far from restricted to Guitar Hero controllers or drumkits), but I guess it could be useful. Ping me if you're interested.

Timo Jyrinki: UDS GTA04 Hacking

I'm sitting at the Bella Sky lobby bar while UDS people keep pouring in. I guess I have to start this UDS with some hacking (and a little beer)! I bootstrapped an Ubuntu armhf rootfs and coupled it with QtMoko's kernel already earlier after I received my GTA04 but it didn't boot right away so I had nothing to report. I wanted armhf so I chose QtMoko's 'experimental' Debian armhf rootfs + boot files as the reference to look at while working on the Ubuntu rootfs. I now went through again some of the configuration files, and voil :


Now running apt-get install unity over SSH :) It will require OpenGL ES 2.0 hw acceleration to run, now that the support was integrated in Ubuntu 12.10. I will therefore need to tinker what kind of OMAP3 armhf binary blobs there are available, and what's again the situation with X.org DDX driver as well. I always feel that the fun starts at this point for me, when I've the device booting and I can SSH in. That's why I'm happy the work from Golden Delicious GmbH and QtMoko helped me to get here...

Davide Viti: snip2code

A friend of mine is working on a new project: http://www.snip2code.com
It's very much oriented to programmers: it's the place to go when you're looking for a code snippet and you don't want to reinvent the wheel.

Give it a go if you think it sounds interesting

Iustin Pop: Open Source collaboration, 2012

I'm interrupting my blog silence (which was due to the fact that I didn't have anything interesting to say) to note two things: first, but less important, spammers are still active as ever - I had ~2K spam comments and another ~2K in pending moderation. And second, and the actual subject of this post, is how easy collaboration has become. In the last year or so (where ~so means since I last looked), GitHub has introduced a very nice collaboration work-flow: This is soo easy (what, 3-4 clicks?) that I expect it will increase trivial fix-ups against Open Source projects hosted on GitHub or other services with similar capabilities. I did in the past week two or three such trivial fixes myself; this is not much note that I'm not talking about code fixes; but still, it is something that I think will definitely improve many, many projects. The same way that Wikis made it easy to improve documentation sites, this could make it easier for end-users to improve upstream's project documentation, when stored in a VCS as opposed to a Wiki. Yay! On the other hand, I still have a few patches sent months ago to an upstream email address, since they don't have a issue tracker (not even speaking about a place to submit merge requests). These will probably languish and disappear, as opposed to visible/public "hey, this is a patch to fix tiny typo in File.hs!". Yes, I like this a lot. Now, if only all projects would have a public VCS and issue tracker :) PS: yes, I'm talking here about GitHub, which is not Open Source software itself. I regard that as a (temporary) inconvenience, which dies not detract from the significant advantage it brings to the table.
27 October 2012

Soeren Sonnenburg: Shogun at Google Summer of Code 2012

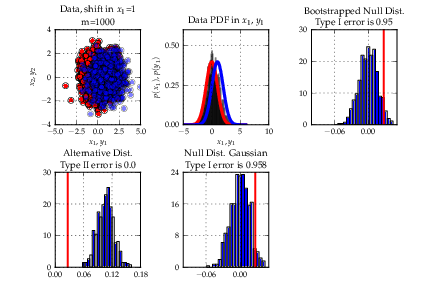
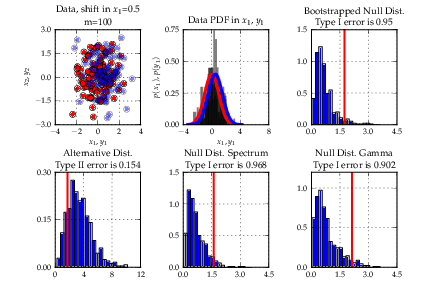
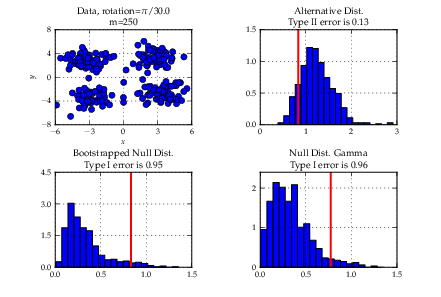
The summer came finally to an end and (yes in Berlin we still had 20 C end of October), unfortunately, so did GSoC with it. This has been the second time for SHOGUN to be in GSoC. For those unfamiliar with SHOGUN - it is a very versatile machine learning toolbox that enables unified large-scale learning for a broad range of feature types and learning settings, like classification, regression, or explorative data analysis. I again played the role of an org admin and co-mentor this year and would like to take the opportunity to summarize enhancements to the toolbox and my GSoC experience: In contrast to last year, we required code-contributions in the application phase of GSoC already, i.e., a (small) patch was mandatory for your application to be considered. This reduced the number of applications we received: 48 proposals from 38 students instead of 70 proposals from about 60 students last year but also increased the overall quality of the applications. In the end we were very happy to get 8 very talented students and have the opportunity of boosting the project thanks to their hard and awesome work. Thanks to google for sponsoring three more students compared to last GSoC. Still we gave one slot back to the pool for good to the octave project (They used it very wisely and octave will have a just-in-time compiler now, which will benefit us all!). SHOGUN 2.0.0 is the new release of the toolbox including of course all the new features that the students have implemented in their projects. On the one hand, modules that were already in SHOGUN have been extended or improved. For example, Jacob Walker has implemented Gaussian Processes (GPs) improving the usability of SHOGUN for regression problems. A framework for multiclass learning by Chiyuan Zhang including state-of-the-art methods in this area such as Error-Correcting Output Coding (ECOC) and ShareBoost, among others. In addition, Evgeniy Andreev has made very important improvements w.r.t. the accessibility of SHOGUN. Thanks to his work with SWIG director classes, now it is possible to use python for prototyping and make use of that code with the same flexibility as if it had been written in the C++ core of the project. On the other hand, completely new frameworks and other functionalities have been added to the project as well. This is the case of multitask learning and domain adaptation algorithms written by Sergey Lisitsyn and the kernel two-sample or dependence test by Heiko Strathmann. Viktor Gal has introduced latent SVMs to SHOGUN and, finally, two students have worked in the new structured output learning framework. Fernando Iglesias made the design of this framework introducing the structured output machines into SHOGUN while Michal Uricar has implemented several bundle methods to solve the optimization problem of the structured output SVM. It has been very fun and interesting how the work done in different projects has been put together very early, even during the GSoC period. Only to show an example of this dealing with the generic structured output framework and the improvements in the accessibility. It is possible to make use of the SWIG directors to implement the application specific mechanisms of a structured learning problem instance in python and then use the rest of the framework (written in C++) to solve this new problem. Students! You all did a great job and I am more than amazed what you all have achieved. Thank you very much and I hope some of you will stick around. Besides all these improvements it has been particularly challenging for me as org admin to scale the project. While I could still be deeply involved in each and every part of the project last GSoC, this was no longer possible this year. Learning to trust that your mentors are doing the job is something that didn't come easy to me. Having had about monthly all-hands meetings did help and so did monitoring the happiness of the students. I am glad that it all worked out nicely this year too. Again, I would like to mention that SHOGUN improved a lot code-base/code-quality wise. Students gave very constructive feedback about our (lack) of proper Vector/Matrix/String/Sparse Matrix types. We now have all these implemented doing automagic memory garbage collection behind scenes. We have started to transition to use Eigen3 as our matrix library of choice, which made quite a number of algorithms much easier to implement. We generalized the Label framework (CLabels) to be tractable for not just classification and regression but multitask and structured output learning. Finally, we have had quite a number of infrastructure improvements. Thanks to GSoC money we have a dedicated server for running the buildbot/buildslaves and website. The ML Group at TU Berlin does sponsor virtual machines for building SHOGUN on Debian and Cygwin. Viktor Gal stepped up providing buildslaves for Ubuntu and FreeBSD. Gunnar Raetschs group is supporting redhat based build tests. We have Travis CI running testing pull requests for breakage even before merges. Code quality is now monitored utilizing LLVMs scan-build. Bernard Hernandez appeared and wrote a fancy new website for SHOGUN. A more detailed description of the achievements of each of the students follows:

Next.

Previous.