Search Results: "ag"

7 May 2016

Russ Allbery: rra-c-util 6.0

Quite some time ago, I added strlcat and strlcpy functions to my portability C library. I've subsequently become convinced that those functions are a bad idea, and have been moving all of my code to asprintf and other functions. This release completes that change for all the code provided by rra-c-util and removes strlcpy and strlcat from rra-c-util. network_set_freebind, network_set_reuseaddr, and network_set_v6only, to set various socket options, are now public functions, since INN wanted to use them directly rather than only as part of other interfaces. This release also has new Autoconf probes for Perl that assist with linking with embedded Perl, checking the Perl version, and checking for Perl modules, and a fix to the OpenSSL Autoconf macros for 1.1.0. It also adds a replacement for gss_oid_equal for older versions of Heimdal that lack it. Finally, rra-c-util 6.0 implements the transition in C TAP Harness 4.0 from SOURCE and BUILD to C_TAP_SOURCE and C_TAP_BUILD for all the test suite helper code provided by this package. You can get the latest version from the rra-c-util distribution page.

Russ Allbery: C TAP Harness 4.0

When I originally wrote my test framework for C, I used SOURCE and BUILD as the preprocessor symbols and environment variables that pointed to the source and build directories of the software being tested. Subsequent discussion and thought convinced me that I should have used some sort of prefix on those variables to distinguish from other uses. This release starts the process of changing to C_TAP_SOURCE and C_TAP_BUILD instead. You now have to use the new names when setting preprocessor directives when building the test harness. For now, the test harness will set all four environment variables, but test code should switch to the new environment variables, since I'll drop the old SOURCE and BUILD variables in a later release. I also fixed a missing va_end() call in is_double(), thanks to a report from Julien LIE. You can get the latest release from the C TAP Harness distribution page.

Elena 'valhalla' Grandi: Pyra preorders

Pyra preorders

If you've met me at a conference you may have noticed that instead of a laptop I was using a handeld which looks like a laptop scaled down to nintendo DS size, the https://en.wikipedia.org/wiki/Openpandora.

I've used it as my main computing device while travelling for a few years, even for work (as a programmer)so happily that when EvilDragon announced at FOSDEM (link points to youtube video) https://www.youtube.com/watch?v=4T-w1KqrVsM that he was working on a successor device I started saving money for it even before I knew many details about the specs, other that they would have been way better than the Pandora ones (which is getting painful to use a browser on, because of its 256MB RAM).

Immagine/fotohttp://social.gl-como.it/photos/valhalla/image/5a9fdfadf33e40e9e3517b18ca7cba68

Now this successor device is almost ready, they have opened the preorders https://www.dragonbox.de/en/45-pyra, and they have already reached the absolute minimum number of orders for mass production and are almost there for a more reasonable number of 1000 devices, so if you want a chance to get one of the first batch devices now it's time to visit their store.

A few highlights, from my point of view, include:

* It will run Debian with just a custom kernel/bootloader (and a few configuration only packages): most of the kernel mods are being submitted upstream, so maybe one day there won't even be a need for this kernel (but e.g. with Pandora upstream didn't accept the custom way they managed the keyboard; on the Pyra the keyboard is managed in a more standard way, but there may be other similar issues).

* It has been designed with modularity in mind: the CPU board is socketed on the main board and in the future upgrades may require just replacing the CPU board. I haven't read the details on the actual licensing, but it seems that the hardware design will be open enough that 3rd party boards may also be a possibility.

* just like on Pandora: real keyboard. hardware analog volume wheel. Huge user-replaceable battery (I don't think that there are any independent reviews of the pyra battery yet, but the one on the Pandora is still able to go through a day of FOSDEM i.e. alternating often between on with wifi and suspendend and only go down to 50% or so charge). Stylus (and 3d-printed quill) friendly touchscreen. Long term support from the producer.

* The 4G version has been designed in such a way that the GSM modem can be actually turned off (just like on the https://neo900.org/)

There are of course a few bad parts:

* PowerVR. The good news is that there is a risk that no 3d drivers will be available at all, and this means that the Pyra has been tested and considered good enough with just (FOSS) software acceleration.

* The price: yes, it is expensive. I'm happy I've saved money in advance for it, otherwise I wouldn't have been able to afford it. Some of it is a problem of small production, some is actual product quality. If you consider that it can take the place of both a laptop (and small ones are getting quite expensive, now that netbooks have disappeared) and a smartphone (I don't do lots of voice calls) it will start going down from "oh so **** high" to "high, but not unreasonably so"

Disclaimer: I have preordered one, so I am interested in the success of the project because it will mean better software and better support for the device.

Edit: forgot the link to the press kit the images comes from http://cloud.openpandora.org/index.php/s/a0Q0TXV8gh5NLAC?path=%2F, which also includes more infos on specs etc.

Craig Small: Displaying Linux Memory

Memory management is hard, but RAM management may be even harder. Most people know the vague overall concept of how memory usage is displayed within Linux. You have your total memory which is everything inside the box; then there is used and free which is what the system is or is not using respectively. Some people might know that not all used is used and some of it actually is free. It can be very confusing to understand, even for a someone who maintains procps (the package that contains top and free, two programs that display memory usage). So, how does the memory display work? What free shows The free program is part of the procps package. It s central goal is to give a quick overview of how much memory is used where. A typical output (e.g. what I saw when I typed free -h ) could look like this:
      total   used    free   shared  buff/cache  available
Mem:    15G   3.7G    641M     222M         11G        11G
Swap:   15G   194M     15G
I ve used the -h option for human-readable output here for the sake of brevity and because I hate typing long lists of long numbers. People who have good memories (or old computers) may notice there is a missing -/+ buffers/cache line. This was intentionally removed in mid-2014 because as the memory management of Linux got more and more complicated, these lines became less relevant. These used to help with the not used used memory problem mentioned in the introduction but progress caught up with it. To explain what free is showing, you need to understand some of the underlying statistics that it works with. This isn t a lesson on how Linux its memory (the honest short answer is, I don t fully know) but just enough hopefully to understand what free is doing. Let s start with the two simple columns first; total and free. Total Memory This is what memory you have available to Linux. It is almost, but not quite, the amount of memory you put into a physical host or the amount of memory you allocate for a virtual one. Some memory you just can t have; either due to early reservations or devices shadowing the memory area. Unless you start mucking around with those settings or the virtual host, this number stays the same. Free Memory Memory that nobody at all is using. They haven t reserved it, haven t stashed it away for future use or even just, you know, actually using it. People often obsess about this statistic but its probably the most useless one to use for anything directly. I have even considered removing this column, or replacing it with available (see later what that is) because of the confusion this statistic causes. The reason for its uselessness is that Linux has memory management where it allocates memory it doesn t use. This decrements the free counter but it is not truly used . If you application needs that memory, it can be given back. A very important statistic to know for running a system is how much memory have I got left before I either run out or I start to serious swap stuff to swap drives. Despite its name, this statistic will not tell you that and will probably mislead you. My advice is unless you really understand the Linux memory statistics, ignore this one. Who s Using What Now we come to the components that are using (if that is the right word) the memory within a system. Shared Memory Shared memory is often thought of only in the context of processes (and makes working out how much memory a process uses tricky but that s another story) but the kernel has this as well. The shared column lists this, which is a direct report from the Shmem field in the meminfo file. Slabs For things used a lot within the kernel, it is inefficient to keep going to get small bits of memory here and there all the time. The kernel has this concept of slabs where it creates small caches for objects or in-kernel data strucutures that slabinfo(5) states [such as] buffer heads, inodes and dentries . So basically kernel stuff for the kernel to do kernelly things with. Slab memory comes in two flavours. There is reclaimable and unreclaimable. This is important because unreclaimable cannot be handed back if your system starts to run out of memory. Funny enough, not all reclaimable is, well, reclaimable. A good estimate is you ll only get 50% back, top and free ignore this inconvenient truth and assume it can be 100%. All of the reclaimable slab memory is considered part of the Cached statistic. Unreclaimable is memory that is part of Used. Page Cache and Cached Page caches are used to read and write to storage, such as a disk drive. These are the things that get written out when you use sync and make the second read of the same file much faster. An interesting quirk is that tmpfs is part of the page cache. So the Cached column may increase if you have a few of these. The Cached column may seem like it should only have Page Cache, but the Reclaimable part of the Slab is added to this value. For some older versions of some programs, they will have no or all Slab counted in Cached. Both of these versions are incorrect. Cached makes up part of the buff/cache column with the standard options for free or has a column to itself for the wide option. Buffers The second component to the buff/cache column (or separate with the wide option) is kernel buffers. These are the low-level I/O buffers inside the kernel. Generally they are small compared to the other components and can basically ignored or just considered part of the Cached, which is the default for free. Used Unlike most of the previous statistics that are either directly pulled out of the meminfo file or have some simple addition, the Used column is calculated and completely dependent on the other values. As such it is not telling the whole story here but it is reasonably OK estimate of used memory. Used component is what you have left of your Total memory once you have removed: Notice that the unreclaimable part of slab is not in this calculation, which means it is part of the used memory. Also note this seems a bit of a hack because as the memory management gets more complicated, the estimates used become less and less real. Available In early 2014, the kernel developers took pity on us toolset developers and gave us a much cleaner, simpler way to work out some of these values (or at least I d like to think that s why they did it). The available statistic is the right way to work out how much memory you have left. The commit message explains the gory details about it, but the great thing is that if they change their mind or add some new memory feature the available value should be changed as well. We don t have to worry about should all of slab be in Cached and are they part of Used or not, we have just a number directly out of meminfo. What does this mean for free? Poor old free is now at least 24 years old and it is based upon BSD and SunOS predecessors that go back way before then. People expect that their system tools don t change by default and show the same thing over and over. On the other side, Linux memory management has changed dramatically over those years. Maybe we re all just sheep (see I had to mention sheep or RAMs somewhere in this) and like things to remain the same always. Probably if free was written now; it would only need the total, available and used columns with used merely being total minus available. Possibly with some other columns for the wide option. The code itself (found in libprocps) is not very hard to maintain so its not like this change will same some time but for me I m unsure if free is giving the right and useful result for people that use it.

Dirk Eddelbuettel: BH 1.60.0-2

A new minor release of BH is now on CRAN. BH provides a large part of the Boost C++ libraries as a set of template headers for use by R, possibly with Rcpp as well as other packages. This release uses the same Boost 1.60.0 version of Boost as the last release, but adds three more library: bimap, flyweight and icl. A brief summary of changes from the NEWS file is below.
Changes in version 1.60.0-2 (2016-05-06)
  • Added Boost bimap via GH pull request #24 by Jim Hester.
  • Added Boost icl via GH pull request #27 by Jay Hesselbert.
  • Added Boost flyweight as requested in GH ticket #26.
Courtesy of CRANberries, there is also a diffstat report for the most recent release. Comments and suggestions are welcome via the mailing list or the issue tracker at the GitHubGitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Keith Packard: Altos1.6.3

AltOS 1.6.3 Bdale and I are pleased to announce the release of AltOS version 1.6.3. AltOS is the core of the software for all of the Altus Metrum products. It consists of firmware for our cc1111, STM32L151, STMF042, LPC11U14 and ATtiny85 based electronics and Java-based ground station software. Version 1.6.3 adds idle mode to AltosDroid and has bug fixes for our host software on desktops, laptops an android devices along with BlueTooth support for Windows. 1.6.3 is in Beta test for Android; if you want to use the beta version, join the AltosDroid beta program AltOS AltOS fixes: AltosUI and TeleGPS Applications AltosUI and TeleGPS New Features: AltosUI and TeleGPS Fixes: AltosDroid AltosDroid new features: AltosDroid bug fixes: Documentation

6 May 2016

Norbert Preining: Yubikey NEO

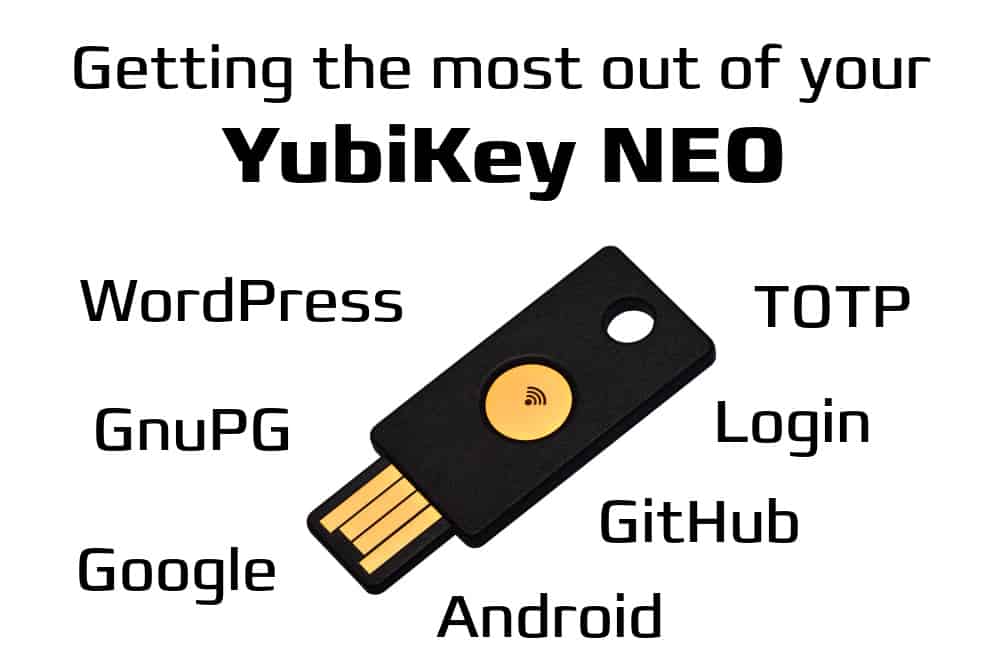
Two Factor authentication and general improvement of my security infrastructure was long on my todo list. Some month ago I finally purchased a Yubikey NEO from Yubico and try to consistently use it as second factor, as well as gpg signing/encrypting device. yubikey-neo I am trying to get the best out of my Yubikey NEO by using as many of its functionality, in particular: Smartcard for my GNuPG keys, OTP similar to Google Authenticator and similar, as well as challenge-response for additional login security, as well as all that over NFC to not keep keys/passwords on my mobile phone. While there are loads of guides (see the previous article on GnuPG for some of them), many of them are out-of-date for current distributions and GnuPG etc. So I tried to collect all I could find not the least to have a place to look it up in case I forget it again. The Hardware The Yubikey NEO is a great peace of hardware. I not even remotely understand how they manage that this little beast can do all these things and still work out without mixing things up. As far as I understand (please correct me) it has three independent circuits of communication: On top of these circuit of communication there is a variety of applications to make the most out of your Yubikey: Yubikey mode setup There are several modes, and using the ykpersonalize tool (readily available for Windows, Mac, Linux, and in the Debian package yubikey-personalization) one can program the key to work in a variety of modes. I chose to activate all options by passing in -m86 which stand for OTP/U2F/CCID composite device with MODE_FLAG_EJECT.
$ ykpersonalize -m86
Firmware version 3.4.3 Touch level 1792 Unconfigured
 
The USB mode will be set to: 0x86
 
Commit? (y/n) [n]: y
$
It is a good idea to unplug and replug the key after this operation. Yubikey udev rules for user access To allow users but root to use the Yubikey, additional udev rules are necessary:
SUBSYSTEMS=="usb", ATTRS idVendor =="1050", ATTRS idProduct =="0116", TAG+="uaccess"
which I put into /etc/udev/rules.d/99-yubikeys.rules on Debian. After that another unplug and replug should allow normal user to access the key. This can be checked by calling getfacl on the newly created /dev/hidraw? device. Using the HID/Challenge-Response mode (slot 2) If you want to secure your login with an additional second factor, there are several options documented on the Yubico site concerning yubico-pam. Since I cannot be sure to be always online with my laptop, I choose Challenge-Response authentication, and followed one-to-one Yubico s docs Local Authentication Using Challenge Response. Basically it boils down to install libpam-yubico, select mode-challenge-response when asked for configuration. Then one needs to personalizing the key (in particular slot 2) for challenge response with:
$ ykpersonalize -2 -ochal-resp -ochal-hmac -ohmac-lt64 -oserial-api-visible
...
Commit? (y/n) [n]: y
$
Next we need to save the challenge and expected response to the user s directory:
$ mkdir $HOME/.yubico
$ ykpamcfg -2 -v
...
Stored initial challenge and expected response in '/home/norbert/.yubico/challenge-123456'.
$
It might be a good idea to try this out, and if it works, activate it also for root. But be careful no key no login  Challenge: I am currently searching for a method to replace the second factor of they key optionally with a different authentication method, like a very difficult passphrase. This way I could log in even without my key, but in this case would need the complicated passphrase. From my reading of the pam manuals it seems to be possible, and I am planning to use pam_ssh and a specific login key with a complicated passphrase. I will report back when this is done. YubiOATH (TOTP) Time based One Time Passwords (aka Google Authenticator style) Without any setup whatsoever this worked out of the box. I use the Yubico Authenticator on my Android phone, and the dedicated application for the Linux desktop to create second factors for all kind of applications. Currently I am using it with Google login, Github, DropbBox, and WordPress (via the Two Factor plugin which can also be tweaked to use the NEO key as USB key via the FIDO U2F). Challenge: If I start the Yubico Personalization GUI, I see two free slots so where are the TOTPs computed? That also means that I have one slot free and for now I don t know what to do with it  Yubikey OpenGPG applet setup The Yubikeys support OpenPGP, and the applet is pre-installed (afaik), meaning you can directly configure the key and upload your keys. Here I use gpg2 (2.1) as it seems to better support card operations. To not interfere with the current gpg setup I use a temporary gpg home:
$ mkdir gpgtmp
$ chmod go-rwx gpgtmp
$ gpg2 --homedir gpgtmp --list-keys
gpg: keybox 'gpgtmp/pubring.kbx' created
gpg: gpgtmp/trustdb.gpg: trustdb created
Warning: The YubiKey NEO only supports 2048bit keys. If you want 4096bit keys you need to use one of the newer YubiKey 4, which gives you this option, but does not have support for NFC, and thus no way to interact with an Android (or other) mobile phone. Check the correct version of the applet There has been a bug in an older version of the applet, but since 2 years all keys sold should have a correct applet. You can check by:
$ gpg-connect-agent --homedir gpgtmp --hex "scd apdu 00 f1 00 00" /bye"
gpg-connect-agent: no running gpg-agent - starting '/usr/bin/gpg-agent'
gpg-connect-agent: waiting for the agent to come up ... (5s)
gpg-connect-agent: connection to agent established
D[0000]  01 00 10 90 00                                     .....           
OK
Looking at the output one sees D[0000] 01 00 10 which means applet version 1.0.10, which is the first version fixed. Replace pins of the key The standard pins are 123456 for the user pin, and 12345678 for the admin pin. These need immediate change! Warning: When changing the ping the normal pin must be 6 (at least?) digits, and the admin pin 8 (at least?), other gpg2 cannot use the key anymore. No idea why.
$ gpg2 --homedir gpgtmp --card-edit
 
Reader ...........: 1050:0116:X:0
Application ID ...: D2760001240102000006036457190000
Version ..........: 2.0
Manufacturer .....: Yubico
Serial number ....: 03645719
Name of cardholder: [not set]
Language prefs ...: [not set]
Sex ..............: unspecified
URL of public key : [not set]
Login data .......: [not set]
Signature PIN ....: forced
Key attributes ...: rsa2048 rsa2048 rsa2048
Max. PIN lengths .: 127 127 127
PIN retry counter : 3 3 3
Signature counter : 0
Signature key ....: [none]
Encryption key....: [none]
Authentication key: [none]
General key info..: [none]
 
gpg/card> admin
Admin commands are allowed
 
gpg/card> passwd
gpg: OpenPGP card no. D2760001240102000006036457190000 detected
 
1 - change PIN
2 - unblock PIN
3 - change Admin PIN
4 - set the Reset Code
Q - quit
 
Your selection? 3
PIN changed.
 
1 - change PIN
2 - unblock PIN
3 - change Admin PIN
4 - set the Reset Code
Q - quit
 
Your selection? 1
PIN changed.
 
1 - change PIN
2 - unblock PIN
3 - change Admin PIN
4 - set the Reset Code
Q - quit
 
Your selection? q
 
gpg/card> quit
After this you need to use the new pins for all changes. Setup basic data The key can also save some basic data about yourself, like name, sex, language preferences, login name, and url to obtain the public key. As before start gpg2 and then change these infos in the following way>
gpg/card> name
Cardholder's surname: Preining
Cardholder's given name: Norbert
 
gpg/card> sex
Sex ((M)ale, (F)emale or space): M
 
gpg/card> lang
Language preferences: de
 
gpg/card> login
Login data (account name): norbert
 
gpg/card> url
URL to retrieve public key: https://www.preining.info/preining-norbert.asc
 
gpg/card> list
 
Reader ...........: 1050:0116:X:0
Application ID ...: D2760001240102000006036457190000
Version ..........: 2.0
Manufacturer .....: Yubico
Serial number ....: 03645719
Name of cardholder: Norbert Preining
Language prefs ...: de
Sex ..............: male
URL of public key : https://www.preining.info/preining-norbert.asc
Login data .......: norbert
Signature PIN ....: forced
Key attributes ...: rsa2048 rsa2048 rsa2048
Max. PIN lengths .: 127 127 127
PIN retry counter : 3 3 3
Signature counter : 0
Signature key ....: [none]
Encryption key....: [none]
Authentication key: [none]
General key info..: [none]
 
gpg/card> quit
Move sub keys to Yubikey As laid out in the article on GnuPG subkeys, we are having three subkeys for signing, encryption, and authentication. In reality I will practically only use the signing key, but upload all three keys to the card. In the following I expect that you have a setup more or less similar to the one described in the article linked before. Again, we use GnuPG v2, mostly because it was the version that worked out of the box. In addition, if you are setting up a similar stage like in my GNuPG article with gpg1 keys on the mail server, then you don t want the gpg1 keys being removed. Basically you must have the Yubikey plugged in and call keytocard after selecting each key in turn (and deselecting it afterwards). Warning: There is another bug in the GnuPG applet that was fixed in later versions (but not in 1.0.10), namely that not all keys are accepted. This is a bit a pain. I needed to recreate a subkey to obtain a key that can be loaded onto the Yubikey. Unfortunately, Yubico has also stopped/disabled the ability to update applets (although I have to say their documentation is an incredible rubbish with respect to applets and upgrades ). As before, assume that $MASTERKEY contains the hex id of your master key.
$ gpg2 --edit-key $MASTERKEY
gpg (GnuPG) 2.1.11; Copyright (C) 2016 Free Software Foundation, Inc.
This is free software: you are free to change and redistribute it.
There is NO WARRANTY, to the extent permitted by law.
 
Secret key is available.
 
sec  rsa4096/0x6CACA448860CDC13
     created: 2010-09-14  expires: 2017-02-06  usage: SC  
     trust: ultimate      validity: ultimate
ssb  rsa4096/0xD1D2BD14810F62B3
     created: 2010-09-14  expires: 2017-02-06  usage: E   
ssb  rsa2048/0xEC00B8DAD32266AA
     created: 2016-02-07  expires: 2017-02-06  usage: S   
ssb  rsa2048/0xBF361ED434425B4C
     created: 2016-02-07  expires: 2017-02-06  usage: E   
ssb  rsa2048/0x9C7CA4E294F04D49
     created: 2016-02-07  expires: 2017-02-06  usage: A   
[ultimate] (1). Norbert Preining <norbert@preining.info>
[ultimate] (2)  Norbert Preining <preining@logic.at>
[ultimate] (3)  Norbert Preining <preining@debian.org>
[ultimate] (4)  Norbert Preining <preining@jaist.ac.jp>
[ultimate] (5)  [jpeg image of size 4185]
 
gpg> key 2
 
sec  rsa4096/0x6CACA448860CDC13
     created: 2010-09-14  expires: 2017-02-06  usage: SC  
     trust: ultimate      validity: ultimate
ssb  rsa4096/0xD1D2BD14810F62B3
     created: 2010-09-14  expires: 2017-02-06  usage: E   
ssb* rsa2048/0xEC00B8DAD32266AA
     created: 2016-02-07  expires: 2017-02-06  usage: S   
ssb  rsa2048/0xBF361ED434425B4C
     created: 2016-02-07  expires: 2017-02-06  usage: E   
ssb  rsa2048/0x9C7CA4E294F04D49
     created: 2016-02-07  expires: 2017-02-06  usage: A   
[ultimate] (1). Norbert Preining <norbert@preining.info>
[ultimate] (2)  Norbert Preining <preining@logic.at>
[ultimate] (3)  Norbert Preining <preining@debian.org>
[ultimate] (4)  Norbert Preining <preining@jaist.ac.jp>
[ultimate] (5)  [jpeg image of size 4185]
 
gpg> keytocard
Please select where to store the key:
   (1) Signature key
   (3) Authentication key
Your selection? 1
 
sec  rsa4096/0x6CACA448860CDC13
     created: 2010-09-14  expires: 2017-02-06  usage: SC  
     trust: ultimate      validity: ultimate
ssb  rsa4096/0xD1D2BD14810F62B3
     created: 2010-09-14  expires: 2017-02-06  usage: E   
ssb* rsa2048/0xEC00B8DAD32266AA
     created: 2016-02-07  expires: 2017-02-06  usage: S   
ssb  rsa2048/0xBF361ED434425B4C
     created: 2016-02-07  expires: 2017-02-06  usage: E   
ssb  rsa2048/0x9C7CA4E294F04D49
     created: 2016-02-07  expires: 2017-02-06  usage: A   
[ultimate] (1). Norbert Preining <norbert@preining.info>
[ultimate] (2)  Norbert Preining <preining@logic.at>
[ultimate] (3)  Norbert Preining <preining@debian.org>
[ultimate] (4)  Norbert Preining <preining@jaist.ac.jp>
[ultimate] (5)  [jpeg image of size 4185]
 
gpg> key 2
 
sec  rsa4096/0x6CACA448860CDC13
     created: 2010-09-14  expires: 2017-02-06  usage: SC  
     trust: ultimate      validity: ultimate
ssb  rsa4096/0xD1D2BD14810F62B3
     created: 2010-09-14  expires: 2017-02-06  usage: E   
ssb  rsa2048/0xEC00B8DAD32266AA
     created: 2016-02-07  expires: 2017-02-06  usage: S   
ssb  rsa2048/0xBF361ED434425B4C
     created: 2016-02-07  expires: 2017-02-06  usage: E   
ssb  rsa2048/0x9C7CA4E294F04D49
     created: 2016-02-07  expires: 2017-02-06  usage: A   
[ultimate] (1). Norbert Preining <norbert@preining.info>
[ultimate] (2)  Norbert Preining <preining@logic.at>
[ultimate] (3)  Norbert Preining <preining@debian.org>
[ultimate] (4)  Norbert Preining <preining@jaist.ac.jp>
[ultimate] (5)  [jpeg image of size 4185]
 
gpg> key 3
 
sec  rsa4096/0x6CACA448860CDC13
     created: 2010-09-14  expires: 2017-02-06  usage: SC  
     trust: ultimate      validity: ultimate
ssb  rsa4096/0xD1D2BD14810F62B3
     created: 2010-09-14  expires: 2017-02-06  usage: E   
ssb  rsa2048/0xEC00B8DAD32266AA
     created: 2016-02-07  expires: 2017-02-06  usage: S   
ssb* rsa2048/0xBF361ED434425B4C
     created: 2016-02-07  expires: 2017-02-06  usage: E   
ssb  rsa2048/0x9C7CA4E294F04D49
     created: 2016-02-07  expires: 2017-02-06  usage: A   
[ultimate] (1). Norbert Preining <norbert@preining.info>
[ultimate] (2)  Norbert Preining <preining@logic.at>
[ultimate] (3)  Norbert Preining <preining@debian.org>
[ultimate] (4)  Norbert Preining <preining@jaist.ac.jp>
[ultimate] (5)  [jpeg image of size 4185]
 
gpg> keytocard
Please select where to store the key:
   (2) Encryption key
Your selection? 2
 
sec  rsa4096/0x6CACA448860CDC13
     created: 2010-09-14  expires: 2017-02-06  usage: SC  
     trust: ultimate      validity: ultimate
ssb  rsa4096/0xD1D2BD14810F62B3
     created: 2010-09-14  expires: 2017-02-06  usage: E   
ssb  rsa2048/0xEC00B8DAD32266AA
     created: 2016-02-07  expires: 2017-02-06  usage: S   
ssb* rsa2048/0xBF361ED434425B4C
     created: 2016-02-07  expires: 2017-02-06  usage: E   
ssb  rsa2048/0x9C7CA4E294F04D49
     created: 2016-02-07  expires: 2017-02-06  usage: A   
[ultimate] (1). Norbert Preining <norbert@preining.info>
[ultimate] (2)  Norbert Preining <preining@logic.at>
[ultimate] (3)  Norbert Preining <preining@debian.org>
[ultimate] (4)  Norbert Preining <preining@jaist.ac.jp>
[ultimate] (5)  [jpeg image of size 4185]
 
gpg> key 3
 
sec  rsa4096/0x6CACA448860CDC13
     created: 2010-09-14  expires: 2017-02-06  usage: SC  
     trust: ultimate      validity: ultimate
ssb  rsa4096/0xD1D2BD14810F62B3
     created: 2010-09-14  expires: 2017-02-06  usage: E   
ssb  rsa2048/0xEC00B8DAD32266AA
     created: 2016-02-07  expires: 2017-02-06  usage: S   
ssb  rsa2048/0xBF361ED434425B4C
     created: 2016-02-07  expires: 2017-02-06  usage: E   
ssb  rsa2048/0x9C7CA4E294F04D49
     created: 2016-02-07  expires: 2017-02-06  usage: A   
[ultimate] (1). Norbert Preining <norbert@preining.info>
[ultimate] (2)  Norbert Preining <preining@logic.at>
[ultimate] (3)  Norbert Preining <preining@debian.org>
[ultimate] (4)  Norbert Preining <preining@jaist.ac.jp>
[ultimate] (5)  [jpeg image of size 4185]
 
gpg> key 4
 
sec  rsa4096/0x6CACA448860CDC13
     created: 2010-09-14  expires: 2017-02-06  usage: SC  
     trust: ultimate      validity: ultimate
ssb  rsa4096/0xD1D2BD14810F62B3
     created: 2010-09-14  expires: 2017-02-06  usage: E   
ssb  rsa2048/0xEC00B8DAD32266AA
     created: 2016-02-07  expires: 2017-02-06  usage: S   
ssb  rsa2048/0xBF361ED434425B4C
     created: 2016-02-07  expires: 2017-02-06  usage: E   
ssb* rsa2048/0x9C7CA4E294F04D49
     created: 2016-02-07  expires: 2017-02-06  usage: A   
[ultimate] (1). Norbert Preining <norbert@preining.info>
[ultimate] (2)  Norbert Preining <preining@logic.at>
[ultimate] (3)  Norbert Preining <preining@debian.org>
[ultimate] (4)  Norbert Preining <preining@jaist.ac.jp>
[ultimate] (5)  [jpeg image of size 4185]
 
gpg> keytocard
Please select where to store the key:
   (3) Authentication key
Your selection? 3
 
sec  rsa4096/0x6CACA448860CDC13
     created: 2010-09-14  expires: 2017-02-06  usage: SC  
     trust: ultimate      validity: ultimate
ssb  rsa4096/0xD1D2BD14810F62B3
     created: 2010-09-14  expires: 2017-02-06  usage: E   
ssb  rsa2048/0xEC00B8DAD32266AA
     created: 2016-02-07  expires: 2017-02-06  usage: S   
ssb  rsa2048/0xBF361ED434425B4C
     created: 2016-02-07  expires: 2017-02-06  usage: E   
ssb* rsa2048/0x9C7CA4E294F04D49
     created: 2016-02-07  expires: 2017-02-06  usage: A   
[ultimate] (1). Norbert Preining <norbert@preining.info>
[ultimate] (2)  Norbert Preining <preining@logic.at>
[ultimate] (3)  Norbert Preining <preining@debian.org>
[ultimate] (4)  Norbert Preining <preining@jaist.ac.jp>
[ultimate] (5)  [jpeg image of size 4185]
 
gpg> key 4
 
sec  rsa4096/0x6CACA448860CDC13
     created: 2010-09-14  expires: 2017-02-06  usage: SC  
     trust: ultimate      validity: ultimate
ssb  rsa4096/0xD1D2BD14810F62B3
     created: 2010-09-14  expires: 2017-02-06  usage: E   
ssb  rsa2048/0xEC00B8DAD32266AA
     created: 2016-02-07  expires: 2017-02-06  usage: S   
ssb  rsa2048/0xBF361ED434425B4C
     created: 2016-02-07  expires: 2017-02-06  usage: E   
ssb  rsa2048/0x9C7CA4E294F04D49
     created: 2016-02-07  expires: 2017-02-06  usage: A   
[ultimate] (1). Norbert Preining <norbert@preining.info>
[ultimate] (2)  Norbert Preining <preining@logic.at>
[ultimate] (3)  Norbert Preining <preining@debian.org>
[ultimate] (4)  Norbert Preining <preining@jaist.ac.jp>
[ultimate] (5)  [jpeg image of size 4185]
 
gpg> save
After that your keys are on the Yubikey (and only there!), and GNuPG will require the PIN (user pin) to sign/encrypt documents. Usage Many things have been said above, but to sum up when and how I am using the YubiKey now: Conclusions With this setup I am now quite content, but not completely. What I still want to do is full disk encryption where I need the Yubikey to boot and again, with an alternative for a very long passphrase. At the end, adding a second factor to the login is not really optimal, and only protects you against quick hacks. If the laptop is actually stolen, only full disc protection helps. Access to the hardware always guarantees that one has access to everything on the disc. Another thing I want to do is re-use the GnuPG key on the Yubikey as ssh key for logging into remote systems. That would mean that I get rid of even more keys on my laptop. But this is still in the work  The other open question is what to use the other available slot of the Yubikey for? I thought about some passwords (possible), but I don t feel to happy about having my password issued with the press of a key. But all in all, I like the setup much more than before and not having any GnuPG key on the laptop is a big plus.

Scarlett Clark: Kubuntu: Debian: KDE: Outreachy! Yay! Upcoming changes

I was approved to participate in Outreachy!
https://www.gnome.org/outreachy/ I will be working on the Debian reproducible builds.
https://wiki.debian.org/ReproducibleBuilds Some of you in the Debian community might know me from working with the debian-qt-kde team
as we (Kubuntu) collaborated in packaging for some time. Will this affect my current volunteer work for my current projects? Absolutely.
I am currently putting in 10-18 hours a day in volunteer work. Obviously, I cannot give up sleep.
I love all of my projects dearly, but after some recent events, I have found that I absolutely must
resurrect my career. AKA I need to make money to be able to stand on my own two feet without relying on
someone else. I do appreciate the donations, but they do not even dent my student loans :-).
So with all of that said, this will be a positive move in my career path. I have not sorted out how my current projects contributions will change, but I can tell you
Debian reproducible builds will be number one priority come May 20th. This will last for 3 months.
Then my focus will be on getting a paying job. Please understand, I need this. One needs money to survive, and working for donations is not working.
I feel the Outreachy work will improve my chances at obtaining a paid job in the open source field.
I have been chasing my dream job for some time now, and it is time to go get it. I will post again, when I have sorted out how I will split up my time.
Thank you my friends.

Norbert Preining: Michael K hlmeier: Zwei Herren am Strand

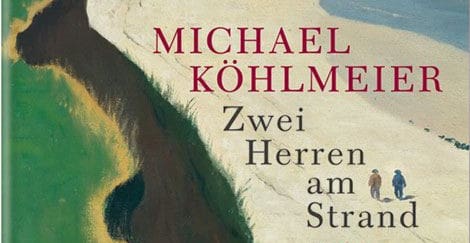
This recent book of the Austrian author Michael K hlmeier, Zwei Herren am Strand (Hanser Verlag), spins a story about an imaginative friendship between Charlie Chaplin and Winston Churchill. While there might not as be more different people than these two, in the book they are connected by a common fight the fight against their own depression, explicitly as well as implicitly by fighting Nazi Germany. Zwei Herren am Strand_ Roman - Michael Koehlmeier In a series of short chapters the story of these two great man from the beginning of the last century is told, mixing reality with a good portion of fantasy, especially when it comes to their meetings and uncommon friendship. For me this book is in best tradition of Michael K hlmeier, whom I consider an excellent story teller. I loved his (unfinished trilogy of) books on Greek mythology (Telemach and Calypso), but found that after these books he got lost too much in radio programs of story telling. While in itself good, I preferred his novels. Thus, I have to admit that I have forgotten about K hlmeier for some years, until recently I found this little book, which reminded me of him and his excellent stories. A book that is if you are versed in German well worth enjoying, especially if one likes funny and a bit queer stories.

Matthias Klumpp: Adventures in D programming

I recently wrote a bigger project in the D programming language, the appstream-generator (asgen). Since I rarely leave the C/C++/Python realm, and came to like many aspects of D, I thought blogging about my experience could be useful for people considering to use D. Disclaimer: I am not an expert on programming language design, and this is not universally valid criticism of D just my personal opinion from building one project with it. Why choose D in the first place? The previous AppStream generator was written in Python, which wasn t ideal for the task for multiple reasons, most notably multiprocessing and LMDB not working well together (and in general, multiprocessing being terrible to work with) and the need to reimplement some already existing C code in Python again. So, I wanted a compiled language which would work well together with the existing C code in libappstream. Using C was an option, but my least favourite one (writing this in C would have been much more cumbersome). I looked at Go and Rust and wrote some small programs performing basic operations that I needed for asgen, to get a feeling for the language. Interfacing C code with Go was relatively hard since libappstream is a GObject-based C library, I expected to be able to auto-generate Go bindings from the GIR, but there were only few outdated projects available which did that. Rust on the other hand required the most time in learning it, and since I only briefly looked into it, I still can t write Rust code without having the coding reference open. I started to implement the same examples in D just for fun, as I didn t plan to use D (I was aiming at Go back then), but the language looked interesting. The D language had the huge advantage of being very familiar to me as a C/C++ programmer, while also having a rich standard library, which included great stuff like std.concurrency.Generator, std.parallelism, etc. Translating Python code into D was incredibly easy, additionally a gir-d-generator which is actively maintained exists (I created a small fork anyway, to be able to directly link against the libappstream library, instead of dynamically loading it). What is great about D? This list is just a huge braindump of things I had on my mind at the time of writing  Interfacing with C There are multiple things which make D awesome, for example interfacing with C code and to a limited degree with C++ code is really easy. Also, working with functions from C in D feels natural. Take these C functions imported into D:
extern(C):
nothrow:
struct _mystruct  
alias mystruct_p = _mystruct*;
mystruct_p = mystruct_create ();
mystruct_load_file (mystruct_p my, const(char) *filename);
mystruct_free (mystruct_p my);
You can call them from D code in two ways:
auto test = mystruct_create ();
// treating "test" as function parameter
mystruct_load_file (test, "/tmp/example");
// treating the function as member of "test"
test.mystruct_load_file ("/tmp/example");
test.mystruct_free ();
This allows writing logically sane code, in case the C functions can really be considered member functions of the struct they are acting on. This property of the language is a general concept, so a function which takes a string as first parameter, can also be called like a member function of string. Writing D bindings to existing C code is also really simple, and can even be automatized using tools like dstep. Since D can also easily export C functions, calling D code from C is also possible. Getting rid of C++ cruft There are many things which are bad in C++, some of which are inherited from C. D kills pretty much all of the stuff I found annoying. Some cool stuff from D is now in C++ as well, which makes this point a bit less strong, but it s still valid. E.g. getting rid of the #include preprocessor dance by using symbolic import statements makes sense, and there have IMHO been huge improvements over C++ when it comes to metaprogramming. Incredibly powerful metaprogramming Getting into detail about that would take way too long, but the metaprogramming abilities of D must be mentioned. You can do pretty much anything at compiletime, for example compiling regular expressions to make them run faster at runtime, or mixing in additional code from string constants. The template system is also very well thought out, and never caused me headaches as much as C++ sometimes manages to do. Built-in unit-test support Unittesting with D is really easy: You just add one or more unittest blocks to your code, in which you write your tests. When running the tests, the D compiler will collect the unittest blocks and build a test application out of them. The unittest scope is useful, because you can keep the actual code and the tests close together, and it encourages writing tests and keep them up-to-date. Additionally, D has built-in support for contract programming, which helps to further reduce bugs by validating input/output. Safe D While D gives you the whole power of a low-level system programming language, it also allows you to write safer code and have the compiler check for that, while still being able to use unsafe functions when needed. Unfortunately, @safe is not the default for functions though. Separate operators for addition and concatenation D exclusively uses the + operator for addition, while the ~ operator is used for concatenation. This is likely a personal quirk, but I love it very much that this distinction exists. It s nice for things like addition of two vectors vs. concatenation of vectors, and makes the whole language much more precise in its meaning. Optional garbage collector D has an optional garbage collector. Developing in D without GC is currently a bit cumbersome, but these issues are being addressed. If you can live with a GC though, having it active makes programming much easier. Built-in documentation generator This is almost granted for most new languages, but still something I want to mention: Ddoc is a standard tool to generate code documentation for D code, with a defined syntax for describing function parameters, classes, etc. It will even take the contents of a unittest scope to generate automatic examples for the usage of a function, which is pretty cool. Scope blocks The scope statement allows one to execute a bit of code before the function exists, when it failed or was successful. This is incredibly useful when working with C code, where a free statement needs to be issued when the function is exited, or some arbitrary cleanup needs to be performed on error. Yes, we do have smart pointers in C++ and with some GCC/Clang extensions a similar feature in C too. But the scopes concept in D is much more powerful. See Scope Guard Statement for details. Built-in syntax for parallel programming Working with threads is so much more fun in D compared to C! I recommend taking a look at the parallelism chapter of the Programming in D book. Pure functions D allows to mark functions as purely-functional, which allows the compiler to do optimizations on them, e.g. cache their return value. See pure-functions. D is fast! D matches the speed of C++ in almost all occasions, so you won t lose performance when writing D code that is, unless you have the GC run often in a threaded environment. Very active and friendly community The D community is very active and friendly so far I only had good experience, and I basically came into the community asking some tough questions regarding distro-integration and ABI stability of D. The D community is very enthusiastic about pushing D and especially the metaprogramming features of D to its limits, and consists of very knowledgeable people. Most discussion happens at the forums/newsgroups at forum.dlang.org. What is bad about D? Half-proprietary reference compiler This is probably the biggest issue. Not because the proprietary compiler is bad per se, but because of the implications this has for the D ecosystem. For the reference D compiler, Digital Mars D (DMD), only the frontend is distributed under a free license (Boost), while the backend is proprietary. The FLOSS frontend is what the free compilers, LLVM D Compiler (LDC) and GNU D Compiler (GDC) are based on. But since DMD is the reference compiler, most features land there first, and the Phobos standard library and druntime is tuned to work with DMD first. Since major Linux distributions can t ship with DMD, and the free compilers GDC and LDC lack behind DMD in terms of language, runtime and standard-library compatibility, this creates a split world of code that compiles with LDC, GDC or DMD, but never with all D compilers due to it relying on features not yet in e.g. GDCs Phobos. Especially for Linux distributions, there is no way to say use this compiler to get the best and latest D compatibility . Additionally, if people can t simply apt install latest-d, they are less likely to try the language. This is probably mainly an issue on Linux, but since Linux is the place where web applications are usually written and people are likely to try out new languages, it s really bad that the proprietary reference compiler is hurting D adoption in that way. That being said, I want to make clear DMD is a great compiler, which is very fast and build efficient code. I only criticise the fact that it is the language reference compiler. UPDATE: To clarify the half-proprietary nature of the compiler, let me quote the D FAQ:
The front end for the dmd D compiler is open source. The back end for dmd is licensed from Symantec, and is not compatible with open-source licenses such as the GPL. Nonetheless, the complete source comes with the compiler, and all development takes place publically on github. Compilers using the DMD front end and the GCC and LLVM open source backends are also available. The runtime library is completely open source using the Boost License 1.0. The gdc and ldc D compilers are completely open sourced.
Phobos (standard library) is deprecating features too quickly This basically goes hand in hand with the compiler issue mentioned above. Each D compiler ships its own version of Phobos, which it was tested against. For GDC, which I used to compile my code due to LDC having bugs at that time, this means that it is shipping with a very outdated copy of Phobos. Due to the rapid evolution of Phobos, this meant that the documentation of Phobos and the actual code I was working with were not always in sync, leading to many frustrating experiences. Furthermore, Phobos is sometimes removing deprecated bits about a year after they have been deprecated. Together with the older-Phobos situation, you might find yourself in a place where a feature was dropped, but the cool replacement is not yet available. Or you are unable to import some 3rd-party code because it uses some deprecated-and-removed feature internally. Or you are unable to use other code, because it was developed with a D compiler shipping with a newer Phobos. This is really annoying, and probably the biggest source of unhappiness I had while working with D especially the documentation not matching the actual code is a bad experience for someone new to the language. Incomplete free compilers with varying degrees of maturity LDC and GDC have bugs, and for someone new to the language it s not clear which one to choose. Both LDC and GDC have their own issues at time, but they are rapidly getting better, and I only encountered some actual compiler bugs in LDC (GDC worked fine, but with an incredibly out-of-date Phobos). All issues are fixed meanwhile, but this was a frustrating experience. Some clear advice or explanation which of the free compilers is to prefer when you are new to D would be neat. For GDC in particular, being developed outside of the main GCC project is likely a problem, because distributors need to manually add it to their GCC packaging, instead of having it readily available. I assume this is due to the DRuntime/Phobos not being subjected to the FSF CLA, but I can t actually say anything substantial about this issue. Debian adds GDC to its GCC packaging, but e.g. Fedora does not do that. No ABI compatibility D has a defined ABI too bad that in reality, the compilers are not interoperable. A binary compiled with GDC can t call a library compiled with LDC or DMD. GDC actually doesn t even support building shared libraries yet. For distributions, this is quite terrible, because it means that there must be one default D compiler, without any exception, and that users also need to use that specific compiler to link against distribution-provided D libraries. The different runtimes per compiler complicate that problem further. The D package manager, dub, does not yet play well with distro packaging This is an issue that is important to me, since I want my software to be easily packageable by Linux distributions. The issues causing packaging to be hard are reported as dub issue #838 and issue #839, with quite positive feedback so far, so this might soon be solved. The GC is sometimes an issue The garbage collector in D is quite dated (according to their own docs) and is currently being reworked. While working with asgen, which is a program creating a large amount of interconnected data structures in a threaded environment, I realized that the GC is significantly slowing down the application when threads are used (it also seems to use UNIX signals SIGUSR1 and SIGUSR2 to stop/resume threads, which I still find odd). Also, the GC performed poorly on memory pressure, which did get asgen killed by the OOM killer on some more memory-constrained machines. Triggering a manual collection run after a large amount of these interconnected data structures wasn t needed anymore solved this problem for most systems, but it would of course have been better to not needing to give the GC any hints. The stop-the-world behavior isn t a problem for asgen, but it might be for other applications. These issues are at time being worked on, with a GSoC project laying the foundation for further GC improvements. version is a reserved word Okay, that is admittedly a very tiny nitpick, but when developing an app which works with packages and versions, it s slightly annoying. The version keyword is used for conditional compilation, and needing to abbreviate it to ver in all parts of the code sucks a little (e.g. the Package interface can t have a property version , but now has ver instead). The ecosystem is not (yet) mature In general it can be said that the D ecosystem, while existing for almost 9 years, is not yet that mature. There are various quirks you have to deal with when working with D code on Linux. It s always nothing major, usually you can easily solve these issues and go on, but it s annoying to have these papercuts. This is not something which can be resolved by D itself, this point will solve itself as more people start to use D and D support in Linux distributions gets more polished. Conclusion I like to work with D, and I consider it to be a great language the quirks it has in its toolchain are not that bad to prevent writing great things with it. At time, if I am not writing a shared library or something which uses much existing C++ code, I would prefer D for that task. If a garbage collector is a problem (e.g. for some real-time applications, or when the target architecture can t run a GC), I would not recommend to use D. Rust seems to be the much better choice then. In any case, D s flat learning curve (for C/C++ people) paired with the smart choices taken in language design, the powerful metaprogramming, the rich standard library and helpful community makes it great to try out and to develop software for scenarios where you would otherwise choose C++ or Java. Quite honestly, I think D could be a great language for tasks where you would usually choose Python, Java or C++, and I am seriously considering to replace quite some Python code with D code. For very low-level stuff, C is IMHO still the better choice. As always, choosing the right programming language is only 50% technical aspects, and 50% personal taste  UPDATE: To get some idea of D, check out the D tour on the new website tour.dlang.org.

Russ Allbery: Review: The Language of Power

Review: The Language of Power, by Rosemary Kirstein
Series: Steerswomen #4
Publisher: Rosemary Kirstein
Copyright: 2004, 2014
Printing: April 2014
ISBN: 0-9913546-3-X
Format: Kindle
Pages: 400
This is the fourth book in the Steerswomen series and definitely not the place to start. It's also a difficult series to review without spoilers, so I won't be able to provide too many details about the plot. I will say that this is a reunion and a return of sorts to themes from earlier in the series, rather than a direct follow-up to the revelations at the end of The Lost Steersman. Rowan is back in the Inner Lands, continuing to investigate the affairs of wizards. In particular, she's digging into the past of the town of Donner, following up on the report of an earlier steerswoman and investigating a now-dead wizard who seemed to act far different from a typical wizard. And Bel is back at her side again, watching her back. The first half of The Language of Power goes over somewhat familiar ground. Similar to both The Steerswoman and The Lost Steersman, Rowan is poking around in a city, getting to know unfamiliar people, being a steerswoman, and winning people over with her unique charm. But that's a theme I don't mind seeing repeated, since Rowan is one of my favorite protagonists from any series I've read. She's both ethical and respectful in a way that doesn't feel artificial or constructed. She thinks oddly and dives into sudden fascinations, and she does rely on the conventions for interacting with steerswomen, but the more time one spends with her, the better one likes her. This is true of both the reader and the town inhabitants, and Kirstein is brilliant at writing the gradual getting-to-know and growing-respect process. Events in The Language of Power slowly build up to another confrontation with wizards, and this one is full of major revelations about the world. Some of the ambiguity of earlier books is firmly resolved, we find out a lot more about how wizards view themselves and their abilities, and tons of new questions are raised. It's not a conclusion in any way, which is a bit unfortunate given that the next book is still being written (twelve years later, although thankfully it's being actively worked on as I write this). But we get the first clear look at the substratum of the world that Kirstein is building in this series. This sounds satisfying, and to some extent it is, but any regular SFF reader will have guessed at many of the revelations here. I was pretty sure the world was following one of two possible patterns partway through the second book, certain which it was during the third book, and was nodding right along with the revelations in this book. I'm trying to avoid spoilers, but if you read a lot of SFF, chances are you've read about something akin to this background before. That takes a bit of the thrill out of the revelations, unfortunately. What adds the excitement and thrill back in are Rowan's reactions. It's very difficult to write a character who comes from an entirely different perspective than either the author or the reader, and Kirstein does an amazing job. Not perfect, quite, at least for me: there were a few points where I thought Rowan was more baffled or more upset than it felt like she should have been. But they are few and far between, and it's quite possible my expectations are the ones that wouldn't ring true if written into the story. It's just such a delight to see Rowan analyzing the world, incorporating new revelations into her growing world model, and figuring out how to take the most moral action at any point. I would happily read another dozen books of this (but I wish they were all already written). If you've read the previous three books, definitely pick up this one as well. For me, it narrowly misses being the best book of the series (I think that's still The Outskirter's Secret because of the difficulty of the perspective change Kirstein pulls off), but it's a close competition. And the final reveal at the very end of this book points to upcoming adventures that I can hardly wait to read. Rating: 8 out of 10

Dirk Eddelbuettel: RcppArmadillo 0.6.700.6.0

armadillo image A second Armadillo release 6.700.6 came out in the 6.700 series, and we uploaded RcppArmadillo 0.6.700.6.0 to CRAN and Debian. This followed the usual thorough reverse-dependecy checking of by now 220 packages using. This release is a little unusual in that it contains both upstream bugfixes in the same series (see below) but also two nice bug fixes from the RcppArmadillo side. Both were squashed by George G. Vega Yon via two focused pull request. The first ensures that we can now use ARMA_64BIT_WORD (provided C++11 is turned on too) allowing for much bigger Armadillo objects. And the second plugs a small leak in the sparse matrix converter I had added a while back. Nice work, all told! Armadillo is a powerful and expressive C++ template library for linear algebra aiming towards a good balance between speed and ease of use with a syntax deliberately close to a Matlab. Changes in this release are as follows:
Changes in RcppArmadillo version 0.6.700.6.0 (2016-05-05)
  • Upgraded to Armadillo 6.700.6 (Catabolic Amalgamator Deluxe)
    • fix for handling empty matrices by kron()
    • fix for clang warning in advanced matrix constructors
    • fix for false deprecated warning in trunc_log() and trunc_exp()
    • fix for gcc-6.1 warning about misleading indentation
    • corrected documentation for the solve() function
  • Added support for int64_t (ARMA_64BIT_WORD) when required during compilation time. (PR #90 by George G. Vega Yon, fixing #88)
  • Fixed bug in SpMat exporter (PR #91 by George G. Vega Yon, fixing #89 and #72)
Courtesy of CRANberries, there is also a diffstat report for this release. As always, more detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

5 May 2016

Sean Whitton: dh_make_elpa & dh_elpa_test

I recently completed and released some work on Debian s tooling for packaging Emacs Lisp addons to GNU Emacs. Emacs grew a package manager called package.el a few years ago, and last year David Bremner wrote the dh_elpa tool to simplify packaging addons for Debian by leveraging package.el features. Packaging a series of addons for Debian left me with a wishlist of features for dh_elpa and I was recently able to implement them. Debian tooling generally uses Perl, a language I didn t know before starting on this project. I was fortunate enough to receive a free review copy of Perl 5 by Example when I attended a meeting of the Bay Area Linux Users Group while I was visiting San Francisco a few months ago. I accepted the book with the intent of doing this work. dh_make_elpa dh_make_elpa (at present available from Debian experimental) is a Perl script to convert a git repository cloned from the upstream of an Emacs Lisp addon to a rudimentary Debian package. It performs a lot of guesswork, and its simple heuristics are something I hope to improve on. Since I am new to object-oriented program design in Perl and I wanted to leverage object-oriented Debian tooling library code, I took the structure of my project from dh_make_perl. In this manner I found it easy and pleasant to write a maintainable script. dh_elpa_test A lot of Emacs Lisp addon packages use a program called Cask to manage the Emacs Lisp dependencies needed to run their test suites. That meant that dh_auto_test often fails to run Emacs Lisp addon package test suites. Since the Debian packaging toolchain already has advanced dependency management, it s undesirable to involve Cask in the package build pipeline if it can be avoided. I had been copying and pasting the code needed to make the tests run in our environment to the debian/rules files of each package whose test suite I wanted to run. dh_elpa_test tries to detect Emacs Lisp addon package test suites and run them with the workarounds needed in our environment. This avoids boilerplate in debian/rules. dh_elpa_test also disables dh_auto_test to avoid a inadvertent Cask invocation. Future & acknowledgements My hope for this work was to make it easier and faster to package Emacs Lisp addon packages for Debian, for my own sake and for anyone new who is interested in joining the pkg-emacsen team. In the future, I want to have dh_elpa_test generate an autopkgtest definition so that a Testsuite: pkg-emacsen line in debian/control is enough to have an Emacs Lisp addon package test suite run on Debian CI. I m very grateful to David Bremner for reviewing and supporting this work, and also for supporting my Emacs Lisp addon packaging work more generally.
4 May 2016

Petter Reinholdtsen: The Pyra - handheld computer with Debian preinstalled

A friend of mine made me aware of The Pyra, a handheld computer which will be delivered with Debian preinstalled. I would love to get one of those for my birthday. :) The machine is a complete ARM-based PC with micro HDMI, SATA, USB plugs and many others connectors, and include a full keyboard and a 5" LCD touch screen. The 6000mAh battery is claimed to provide a whole day of battery life time, but I have not seen any independent tests confirming this. The vendor is still collecting preorders, and the last I heard last night was that 22 more orders were needed before production started. As far as I know, this is the first handheld preinstalled with Debian. Please let me know if you know of any others. Is it the first computer being sold with Debian preinstalled?

Debian Java Packaging Team: What's new since Jessie?

Jessie was released one year ago now and the Java Team has been busy preparing the next release. Here is a quick summary of the current state of the Java packages: Outlook, goals and request for help Java and Friends Package updates The packages listed below detail the changes in jessie-backports and testing. Libraries and Debian specific tools have been excluded. Packages added to jessie-backports: Packages removed from testing: Packages added to testing: Packages upgraded in testing:

3 May 2016

Mart n Ferrari: New sources for contributors.debian.org

Many people might not be aware of it, but since a couple of years ago, we have an excellent tool for tracking and recognising contributors to the Debian Project: Debian Contributors Debian is a big project, and there are many people working that do not have great visibility, specially if they are not DDs or DMs. We are all volunteers, so it is very important that everybody gets credited for their work. No matter how small or unimportant they might think their work is, we need to recognise it! One great feature of the system is that anybody can sign up to provide a new data source. If you have a way to create a list of people that is helping in your project, you can give them credit! If you open the Contributors main page, you will get a list of all the groups with recent activity, and the people credited for their work. The data sources page gives information about each data source and who administers it. For example, my Contributors page shows the many ways in which the system recognises me, all the way back to 2004! That includes commits to different projects, bug reports, and package uploads. I have been maintaining a few of the data sources that track commits to Git and Subversion repositories: The last two are a bit problematic, as they group together all commits to the respective VCS repositories without distinguishing to which sub-projects the contributions were made. The Go and Perl groups' contributions are already extracted from that big pile of data, but it would be much nicer if each substantial packaging team had their own data source. Sadly, my time is limited, so this is were you come into the picture! If you are a member of a team, and want to help with this effort, adopt a new data source. You can be providing commit logs, but it is not limited to that; think of translators, event volunteers, BSP attendants, etc. The initial work is very small, and there is almost no maintenance. There is information on how to contribute here and here, but I would be more than happy to guide you if you contact me. Comment

Carl Chenet: Feed2tweet, your RSS feed to Twitter Python self-hosted app

Feed2tweet is a self-hosted Python app to send you RSS feed to Twitter. Feed2tweet is in production for Le Journal du hacker, a French Hacker News-style FOSS website and LinuxJobs.fr, the job board of the French-speaking FOSS community. linuxjobs-horizontale Feed2tweet 0.3 now only runs with Python 3. It also fixes a nasty bug with RSS feeds modifying the RSS entry orders. Have a look at the Feed2tweet 0.3 changelog: Using Feed2tweet? Send us bug reports/feature requests/push requests/comments about it!

Carl Chenet: Feed2tweet, your RSS feed to Twitter Python self-hosted app

Feed2tweet is a self-hosted Python app to send you RSS feed to Twitter. Feed2tweet is in production for Le Journal du hacker, a French Hacker News-style FOSS website and LinuxJobs.fr, the job board of the French-speaking FOSS community. linuxjobs-horizontale Feed2tweet 0.3 now only runs with Python 3. It also fixes a nasty bug with RSS feeds modifying the RSS entry orders. Have a look at the Feed2tweet 0.3 changelog: Using Feed2tweet? Send us bug reports/feature requests/push requests/comments about it!

Jamie McClelland: Monitoring Deflect

May First/People Link has several members that are targets of politically motivated denial of service attacks (mostly groups that support reproductive justice for women and palestinian rights). To fight off the attacks, we work closely with Deflect - a non-governmental organization based in Canada that fights against this kind of censorship. When a site is down, it's not always easy to understand why. Deflect runs as many as 5 edge servers, any of them could be down. And, of course, the origin server could also be down. I tried using a commericial/free as in beer service for monitoring up time, but when it reported the site being down, I had no idea which part was down. So... httping to the rescue. Unfortunately, it depends on --divert-connect which is only available in Debian Stretch. I run the script via a cron job and output the results to a log file.
    #!/bin/bash
    # Test all given edges 
    domain="$1"
    origin="$2"
    proto=http
    if [ -n "$3" ]; then
        proto="$3"
    fi
    if [ -z "$domain" ]; then
        printf "Please pass the domain as first argument.\n"
        exit 1
    fi
    if ! ping -c 1 4.2.2.1 >/dev/null; then
        # printf "We are offline. Not running.\n"
        exit 1
    fi
    ips=$(dig +short "$domain")
    if [ "$?" -ne "0" ]; then
        # printf "DNS lookup failure. Not running.\n"
        exit 1
    fi
    if [ -n "$origin" ]; then
        ips="$ips $origin"
    fi
    l=
    if [ "$proto" = "https" ]; then
        l=-l
    fi
    for ip in $ips; do
        date=$(date +%Y.%m.%d-%H:%M)
        for i in 1 2 3; do
            out=$(httping $l -m -t 5 -c 1 --divert-connect "$ip" "$proto://$domain")
            [ -z "$out" ] && out=1
            printf "%s %s %s\n" "$date" "$ip" "$out"
        done
    done

Rapha&#235;l Hertzog: My Free Software Activities in April 2016

My monthly report covers a large part of what I have been doing in the free software world. I write it for my donators (thanks to them!) but also for the wider Debian community because it can give ideas to newcomers and it s one of the best ways to find volunteers to work with me on projects that matter to me. Debian LTS I handled a new LTS sponsor that wanted to see wheezy keep supporting armel and armhf. This was not part of our initial plans (set during last Debconf) and I thus mailed all teams that were impacted if we were to collectively decide that it was OK to support those architectures. While I was hoping to get a clear answer rather quickly, it turns out that we never managed to get an answer to the question from all parties. Instead the discussion drifted on the more general topic of how we handle sponsorship/funding in the LTS project. Fortunately, the buildd maintainers said they were OK with this and the ftpmasters had no objections, and they both implicitly enacted the decision: Ansgar Burchardt kept the armel/armhf architectures in the wheezy/updates suite when he handled the switch to the LTS team, and Aur lien Jarno also configured wanna-build to keep building armel/armhf for the suite. The DSA team did not confirm that this change was not interfering with one of their plans to decommission some hardware. Build daemons are a shared resource anyway and a single server is likely to handle builds for multiple releases. DebConf 16 This month I registered for DebConf 16 and submitted multiple talk/BoF proposals: I want to share the setup we use in Kali as it can be useful for other derivatives and also for Debian itself to help smooth the relationship with derivatives. I also want to open again the debate on the usage of money within Debian. It s a hard topic but we should really strive to take some official position on what s possible and what s not possible. With Debian LTS and its sponsorship we have seen that we can use money to some extent without hurting the Debian project as a whole. Can this be transposed to other teams or projects? What are the limits? Can we define a framework and clear rules? I expect the discussion to be very interesting in the BoF. Mehdi Dogguy has agreed to handle this BoF with me. Packaging Django. I uploaded 1.8.12 to jessie-backports and 1.9.5 to unstable. I filed two upstream bugs (26473 and 26474) for two problems spotted by lintian. Unfortunately, when I wanted to upload it to unstable, the test suite did not ran. I pinned this down to a sqlite regression. Chris Lamb filed #820225 and I contacted the SQLite and Django upstream developers by email to point them to this issue. I helped the SQLite upstream author (Richard Hipp) to reproduce the issue and he was quick to provide a patch which landed in 3.12.1. Later in the month I made another upload to fix an upgrade bug (#821789). GNOME 3.20. As for each new version, I updated gnome-shell-timer to ensure it works with the new GNOME. This time I spent a bit more time to fix a regression (805347) that dates back to a while and that would never be fixed otherwise since the upstream author orphaned this extension (as he no longer uses GNOME). I have also been bitten by display problems where accented characters would be displayed below the character that follows. With the help of members of the GNOME team, we found out that this was a problem specific to the cantarell font and was only triggered with Harfbuzz 1.2. This is tracked in Debian with #822682 on harfbuzz and #822762 in fonts-cantarell. There s a new upstream release (with the fix) ready to be packaged but unfortunately it is blocked by the lack of a recent fontforge in Debian. I thus mailed debian-mentors in the hope to find volunteers to help the pkg-fonts team to package a newer version Misc Debian/Kali work Distro Tracker. I started to mentor Vladimir Likic who contacted me because he wants to contribute to Distro Tracker. I helped him to setup his development environment and we fixed a few issues in the process. Bug reports. I filed many bug reports, most of them due to my work on Kali: I also investigated #819958 that was affecting testing since it has been reported to Kali as well. And I made an NMU of dh-make-golang to fix #819472 that I reported earlier. Thanks See you next month for a new summary of my activities.

No comment Liked this article? Click here. My blog is Flattr-enabled.

Next.

Previous.