Search Results: "spa"

13 November 2008

Tore S. Bekkedal: Following memes for fun and prophets.

Cute meme du jour: Well, OK. Page 56, fifth sentence:
“The functions of other software interrupt service routines are quite variable; The I/O postprocessing interrupt service routine has a specific function to perform but is data-driven by the I/O request packets (IRPs) in its work queue.”
I know at least one of the slightly more than one people (I count too, right?) who read my blog (Hi, Ian!) might well realize what book this came from: VAX/VMS Internals and Data Structures, by Ruth Goldenberg and Lawrence Kenah. Yes, the book really was the closest to me - I have an overdesk shelf, and it was the furthest out. The book, by the way, is a fascinating read; I don’t know of any other book that lays out the design of an entire OS kernel in the really quite elegant way that this book does. I got mine signed by Ruth, too, which is pretty damn cool. :) One highlight of this book are the quotes at the beginning of each chapter - sometimes funny, sometimes profound, frequently both. I decided to list those from the first part here, for the enjoyment of both my readers.
Part I
Chapter 1, System Overview:
For the fashion of Minas Tirith was such that it was built on seven levels, each delved into a hill, and about each was set a wall, and in each wall was a gate.
- J. R. R. Tolkien, The Return of the King
Chapter 2, VAX Interrupts and Exceptions
“By indirections find directions out.”
- Shakespeare, Hamlet, 2, i
3, Hardware Interrupts
While I nodded, nearly napping, suddenly there came a tapping,
As of someone gently rapping, rapping at my chamber door.
Edgar Allan Poe, The Raven
4. Software Interrupts
And now I see with eye serene
The very pulse of the machine.
William Wordsworth, She Was A Phantom Of Delight
5. Condition Handling
“Would you tell me, please, which way I ought to go from here?”
“That depends a good deal on where you want to get to,” said the Cat.
Lewis Carroll, Alice’s Adventures in Wonderland
6. System Service Dispatching
Between the idea
And the reality
Between the motion
And the act
Falls the Shadow
T. S. Eliot, The Hollow Men
7. ASTs (Asynchronous Software Traps, ed.)
What you want, what you’re hanging around in the world
waiting for, is for something to occur to you.
Robert Frost
8. Synchronization Techniques
“Time,” said George, “why I can give you a definition of time. It’s what keeps everything from happening at once.”
Ray Cummings, The Man Who Mastered Time
9. Event Flags
I claim not to have controlled events, but confess plainly that events have controlled me.
Abraham Lincoln, Letter to A. G. Hodges, April 4, 1864
10. Lock Management
‘Tis in my memory lock’d
And you yourself shall keep the key of it.
Shakespeare, Hamlet, 1, iii
11. Time Support
Love, all alike, no season knows, nor clime,
Nor hours, days, months, which are the rags of time.
John Donne, The Sun Rising
12. Scheduling
It is equally bad when one speeds on the guest unwilling to go, and when he holds back one who is hastening. Rather one should befriend the guest who is there, but speed him when he wishes.
Homer, The Oddysey
13. Process Control and Communication
I was alone and unable to comunicate with anyone. I did not know the names of anything. I did not even know things had names. Then one day, after she had tried a number of approaches, my teacher held my hand under the water pump on our farm. As the cool water ran over my hand and arm, she spelled the word water in my other hand. She spelled it over and over, and suddenly I knew there was a name for things and that I would never be completely alone again.
Helen Keller

12 November 2008

Jaldhar Vyas: Diwali: The Aftermath

Shailu with no front teeth I HAVE NO FRONT TEETH. YOUR ARGUMENT IS INVALID.

Stefano Zacchiroli: batteries alpha2 Debian packages

OCaml Batteries alpha 2: Debian packages Out of popular request (wow, people on #ocaml@freenode are very excited about the Batteries thingy, good!), I've prepared Debian packages for OCaml Batteries Included, version alpha 2 (which does include the support for transparent gzip-ed channels). Packaging shameless plug: packaging this version has been a nice showcase for TopGit as now I've a couple of inter-dependent branches. TopGit has indeed rocked my world, yay. (Well, I also have to admit to myself that this tiny bit of TopGit mention wont assolve me from the need to advertiseblog about TopGit, ... eventually!) Packages have been uploaded to experimental. As usually I build/upload for amd64, but experimental in Debian is auto-built so eventually the will show up also for other architectures, of course including i386. If you want to take them directly from experimental you have to add this line to your /etc/apt/sources.list:
    deb http://ftp.de.debian.org/debian/ experimental main non-free contrib

and then install requesting explicitly experimental (for some time now, experimental is treated specially, and it won't be used by APT unless explicitly asked for):
    apt-get install -t experimental ocaml-batteries-included

The Debian version (roughly) corresponding to alpha 2 is 0.20081112+gitBB342A7-1. Alternatively, you can grab the packages from my people.d.o space. Since people were interested I've made available both amd64 and i386 builds there.

11 November 2008

Michal Čihař: Gammu test version 1.21.91

Good news everyone, new Gammu testing version is out. Fixes are there for everybody, starting in AT engine initialization, going through FBUS and Nokia drivers up to OBEX handling in Siemens phones. Full list of changes: You can download from usual place: http://cihar.com/gammu/, Debian users will find packages in experimental soon.

10 November 2008

Ian Wienand: When craziness wraps around...

Rob Landley writes:
A common trick years ago was to set up your routing tables and then have PID 1 exit so the kernel paniced, because the paniced kernel would continue to route packets with _no_userspace_running_. Darn hard to hack a system like that.
This is such a ridiculously stupid idea I think it has wrapped all the way around to the point where it just grazes "genius"!

John Goerzen: Looking back at Wordpress

I've hosted this blog on three different platforms: Drupal, Wordpress, and at present, Serendipity.

Back in 2006, I rejected Wordpress, noting that most of its plugins were incompatible with the current version, its main anti-spam software wasn't Free, there was no central plugin directory. And, while Wordpress supported PostgreSQL, many plugins didn't.

Serendipity, at the time, had none of those problems.

However, I've been having other problems with Serendipity since then. People have repeatedly had trouble with captchas. The RSS feeds have long had subtle incompatibilities with certain aggregators, leading to duplicate posts.

I'm looking back at Wordpress now. It looks like it is a lot more mature than it was 2.5 years ago. Perhaps it's time to switch back.

I hope it will support PostgreSQL better now, but I note that its website seems to list MySQL only these days. Ah well, can't have it all, I guess.

Kurt Roeckx: Finding which sector belongs to which file on a RAID device.

I got this nice message (and some others) in my log today:
smartd: Device: /dev/sdd, 2 Currently unreadable (pending) sectors After running a smartctl -t long /dev/sdd smartctl now reports:
ID# ATTRIBUTE_NAME          FLAG     VALUE WORST THRESH TYPE      UPDATED  WHEN_FAILED RAW_VALUE
  5 Reallocated_Sector_Ct   0x0033   200   200   140    Pre-fail  Always       -       0
  9 Power_On_Hours          0x0032   089   089   000    Old_age   Always       -       8719
196 Reallocated_Event_Count 0x0032   200   200   000    Old_age   Always       -       0
197 Current_Pending_Sector  0x0012   200   200   000    Old_age   Always       -       2
198 Offline_Uncorrectable   0x0010   200   200   000    Old_age   Offline      -       0
[...]
SMART Error Log Version: 1
ATA Error Count: 10 (device log contains only the most recent five errors)
[...]
Error 10 occurred at disk power-on lifetime: 8692 hours (362 days + 4 hours)
  When the command that caused the error occurred, the device was active or idle.
  After command completion occurred, registers were:
  ER ST SC SN CL CH DH
  -- -- -- -- -- -- --
  40 51 08 78 e5 89 e0  Error: UNC 8 sectors at LBA = 0x0089e578 = 9037176
  Commands leading to the command that caused the error were:
  CR FR SC SN CL CH DH DC   Powered_Up_Time  Command/Feature_Name
  -- -- -- -- -- -- -- --  ----------------  --------------------
  25 00 08 78 e5 89 2f 00  45d+06:36:27.880  READ DMA EXT
  25 00 08 70 e5 89 2f 00  45d+06:36:27.798  READ DMA EXT
  25 00 08 68 e5 89 2f 00  45d+06:36:27.308  READ DMA EXT
  25 00 08 e0 77 e5 35 00  45d+06:36:27.295  READ DMA EXT
  25 00 08 60 e5 89 2f 00  45d+06:36:26.653  READ DMA EXT
[...]
Error 9 occurred at disk power-on lifetime: 8692 hours (362 days + 4 hours)
  When the command that caused the error occurred, the device was active or idle.
  After command completion occurred, registers were:
  ER ST SC SN CL CH DH
  -- -- -- -- -- -- --
  40 51 08 60 e5 89 e0  Error: UNC 8 sectors at LBA = 0x0089e560 = 9037152
SMART Self-test log structure revision number 1
Num  Test_Description    Status                  Remaining  LifeTime(hours)  LBA_of_first_error
# 1  Extended offline    Completed: read failure       90%      8715         797566305
# 2  Extended offline    Completed without error       00%      8198         -
Notice that 197 Current_Pending_Sector indicates that there are 2 sectors with a problem. Note that the SMART error log shows LBA sectors 9037176 (0x89e578) and 9037152 (0x89e560) but it's limited to 0xffffff. The self test logs shows us the proper LBA error at 797566305 (0x2f89e561) which has a 0x2f in front, and also shows us that it's the second sector in the block of 8 we tried to read. The kernel log also shows:
ata4.00: exception Emask 0x0 SAct 0x0 SErr 0x0 action 0x0
ata4.00: (BMDMA2 stat 0xc0009)
ata4.00: cmd 25/00:08:60:e5:89/00:00:2f:00:00/e0 tag 0 cdb 0x0 data 4096 in
         res 51/40:00:61:e5:89/00:00:2f:00:00/f0 Emask 0x9 (media error)
So I've tried to reproduce the error with:
# dd if=/dev/sdd of=797566305 skip=797566305 bs=512 count=1 iflag=direct
1+0 records in
1+0 records out
512 bytes (512 B) copied, 1.27727 s, 0.4 kB/s
Notice that it can actually read that block, it just seems to take a while. And the error log now contains:
  After command completion occurred, registers were:
  ER ST SC SN CL CH DH
  -- -- -- -- -- -- --
  40 51 01 61 e5 89 e0  Error: UNC 1 sectors at LBA = 0x0089e561 = 9037153
Because it's part of a RAID device I could just let the whole disk resync, but I was a little curious which files were in it. So I found this document that explains on how to find which files has the problem. But it only has examples covering ext2/ext3 on a partition and LVM and nothing about RAID device. So it looks like someone using RAID 0 will have a hard time finding the file that's having a problem. So following the document we start with:
# fdisk -lu /dev/sdd
Disk /dev/sdd: 500.1 GB, 500107862016 bytes
255 heads, 63 sectors/track, 60801 cylinders, total 976773168 sectors
Units = sectors of 1 * 512 = 512 bytes
Disk identifier: 0x000578f9
   Device Boot      Start         End      Blocks   Id  System
/dev/sdd1   *          63      385559      192748+  fd  Linux raid autodetect
/dev/sdd2       972864270   976768064     1951897+  fd  Linux raid autodetect
/dev/sdd3          385560   972864269   486239355   fd  Linux raid autodetect
Partition table entries are not in disk order
In /proc/mdstat we see:
md1 : active raid5 sda3[0] sdd3[3] sdc3[2] sdb3[1]
      1458717696 blocks level 5, 64k chunk, algorithm 2 [4/4] [UUUU]
So sdd3 is part of md1 and I have an ext3 filesytsem on that. Tune2fs -l grep Block gives:
Block count:              364679424
Block size:               4096
Blocks per group:         32768
mdadm tells me:
# mdadm -QE /dev/sdd3
/dev/sdd3:
          Magic : a92b4efc
        Version : 00.90.00
           UUID : 747b071a:a70f723b:c3a9ed44:15845cbf
  Creation Time : Mon Nov 12 20:13:51 2007
     Raid Level : raid5
  Used Dev Size : 486239232 (463.71 GiB 497.91 GB)
     Array Size : 1458717696 (1391.14 GiB 1493.73 GB)
   Raid Devices : 4
  Total Devices : 4
Preferred Minor : 1
    Update Time : Mon Nov 10 10:57:28 2008
          State : clean
 Active Devices : 4
Working Devices : 4
 Failed Devices : 0
  Spare Devices : 0
       Checksum : 4b3147f4 - correct
         Events : 78
         Layout : left-symmetric
     Chunk Size : 64K
      Number   Major   Minor   RaidDevice State
this     3       8       51        3      active sync   /dev/sdd3
   0     0       8        3        0      active sync   /dev/sda3
   1     1       8       19        1      active sync   /dev/sdb3
   2     2       8       35        2      active sync   /dev/sdc3
   3     3       8       51        3      active sync   /dev/sdd3
I've been told that 0.90 stores the superblock at the end of the device, so that makes it a little easier. And this seems to agree:
# cat /sys/block/md1/md/dev-sdd3/offset
0
We have a left-symmetric layout, so in raid5_compute_sector() we see
	stripe = chunk_number / data_disks;
	*dd_idx = chunk_number % data_disks;
[...]
	case ALGORITHM_LEFT_SYMMETRIC:
		*pd_idx = data_disks - stripe % raid_disks;
		*dd_idx = (*pd_idx + 1 + *dd_idx) % raid_disks;
So it looks like the chunks are located on the disk like:
stripesdasdbsdcsdd
0D 0D 1D 2P 0-2
1D 4D 5P 3-5D 3
2D 8P 6-8D 6D 7
3P 9-11D 9D 10D 11
4D 12D 13D 14P 12-14
With each of those 64K. The problem is at 797566305 and the partition started at 385560. So that's at sector 797180745 inside partition sdd3. Each sector is 512 bytes and a chunk is 65536 bytes which gets us 128 sectors per chunk. If we want to know which the stride the sector is on we do: 797180745/128=6227974.5703125 This means that the stripe is number 6227974 and that it's sector 0.5703125*128=73 on sdd3 within that chunk. The parity is on disk: pd_idx = 3 - 6227974 % 4 = 1, being sdb. To get the chunk we need to multiply with the number of data disks (3) and since it's the forth disk and the parity is on the second disk we need to add 1 and get: 6227974*3+1=18683923 So calculating that back to sectors we multiply it with the number of sectors per chunk again and add our offset in the chunk: 18683923*128+73=2391542217 To test that our math is any good we try:
# dd if=/dev/md1 of=797566305.2 skip=2391542217 bs=512 count=1 iflag=direct
1+0 records in
1+0 records out
512 bytes (512 B) copied, 5.99103 s, 0.1 kB/s
We see an error message in the kernel log, there are 2 new errors in the error log, so it seems that everything is calculated correctly. The files are also identical. The file system is in blocks of 4096 bytes, so for the file system this is block 2391542217*512/4096=298942777.125 Then we use debugfs:
# debugfs
debugfs 1.41.2 (02-Oct-2008)
debugfs:  open /dev/md1
debugfs:  icheck 298942777
Block   Inode number
298942777       <block not found>
Which isn't making any sense to me, since I get that error about every 2 hour when a certain cronjob runs. 298942777 / 32768 (Blocks per group) = 9123.00955. So I wonder if ext3 is keeping some meta data there and debugfs doesn't tell that? Anyway, at some point I was running a smartctl -t long /dev/sdd again because I couldn't reproduce the error anymore, the cronjob started, and I then found alot of errors in my log again and now it included:
raid5:md1: read error corrected (8 sectors at 797180744 on sdd3)
It's so much fun that disks always behaves the same trying to read the same sector. Smartctl now reports:
  5 Reallocated_Sector_Ct   0x0033   200   200   140    Pre-fail  Always       -       0
196 Reallocated_Event_Count 0x0032   200   200   000    Old_age   Always       -       0
197 Current_Pending_Sector  0x0012   200   200   000    Old_age   Always       -       0
198 Offline_Uncorrectable   0x0010   200   200   000    Old_age   Offline      -       0
I assume the kernel removed the pending sector by writing to it. The other pending error was already gone for some time, I assume new data got written to that one.

Uwe Hermann: OpenOCD, a Free Software JTAG utility with ARM and MIPS support

JTAG adapter for parallel port Just FYI, I've recently updated the OpenOCD Debian package in unstable. OpenOCD is a Free Software JTAG utility which currently supports quite a large number of JTAG adapters and various CPUs/targets (many ARM and now also some MIPS ones). It's being used by a number of Free Software related projects such as OpenMoko and many others. Here's an example of how you usually use the (new) OpenOCD with a cheapo parallel port JTAG device. First, start the OpenOCD server, providing it an interface config file and a target config file (you can copy/adapt them from /usr/lib/openocd/ interface,target /*.cfg, or use those files directly if they work for your target, of course).
  $ openocd -f parport.cfg -f lpc2148.cfg
Then, in another xterm for example, connect to the now-running OpenOCD telnet server. Here you can now run various commands to probe, control and program the JTAG device(s). Try help for a list of commands. As an example, for flashing a binary onto some LPC2148 eval board you would do something like this:
  $ telnet localhost 4444
  Trying 127.0.0.1...
  Connected to localhost.
  Escape character is '^]'.
  Open On-Chip Debugger
  > reset init
  JTAG device found: 0x4f1f0f0f (Manufacturer: 0x787, Part: 0xf1f0, Version: 0x4)
  srst pulls trst - can not reset into halted mode. Issuing halt after reset.
  target state: halted
  target halted in Thumb state due to debug-request, current mode: Supervisor
  cpsr: 0x800000f3 pc: 0x7fffd2a2
  requesting target halt and executing a soft reset
  target state: halted
  target halted in ARM state due to debug-request, current mode: Supervisor
  cpsr: 0x800000d3 pc: 0x00000000
  > flash write_image /home/foo/program.bin 0
  wrote 1236 byte from file /home/foo/program.bin in 0.533683s (2.261701 kb/s)
  > resume 0
The final resume 0 will start to execute your program on the ARM LPC2148 microcontroller. Check out the openocd info page (info openocd on the command line) for lots more documentation.

David Welton: Generating Rails Fixtures From Large Datasets

I've been working with Tomaso Minelli doing some Rails work, and one thing we needed to do was set up some tests. The situation we are in is that we already have a large set of data to work with in our development environment, but getting that data into .yml files is no easy task. Since we have a fairly large number of interdependent tables, dumping one of them alone is pretty useless, unless you manage to get the other tables it links to, and so on and so forth. Dumping all the data would make testing quite slow, and really is too much to be useful. Here's the rough solution we arrived at:

@fixtures =  
@seen =  
# Do something with a fixture.  In this case, we store it for later.
def handle_fixture(record)
  @fixtures[record.class.table_name]  = []
  @fixtures[record.class.table_name] << record
end
# Get some sort of unique way of identifiying a record - class name and id.
def unique_record(record)
  return record.class.to_s + " " + record.id.to_s
end
# Grab all the relations of a class and add them to the queue.
def add_fixture(record)
  ur = unique_record(record)
  if @seen[ur]
    puts "LOOP!"
    return
  end
  @seen[ur] = true
  puts "Fixture for # record.class.name  - ID # record.id "
  handle_fixture(record)
  record.class.reflections.each do  k, r 
    begin
      if r.macro == :has_many  
          r.macro == :has_and_belongs_to_many
        related = record.send(r.name).send('find', :all, :limit => STARTING_LIMIT)
      else
        related = record.send(r.name)
      end
      related = [related] unless related.is_a?(Array)
      related.each do  related_record 
        if related_record
          puts "    New Record # related_record.class.name  # related_record.id "
          @todo << related_record
        end
      end
    rescue => e
      puts "    ERROR: # e :\n# e.backtrace.inspect "
    end
  end
end
@todo = []
namespace :db do
  namespace :fixtures do
    desc 'Create YAML test fixtures starting from a single model using reflections'
    task :modelbase => :environment do
      STARTING_CLASS = Foobar
      STARTING_FIND  = :all
      STARTING_LIMIT = 1
      tmp = 0
      totale = STARTING_CLASS.find(STARTING_FIND, :limit => STARTING_LIMIT).size
      STARTING_CLASS.find(STARTING_FIND, :limit => STARTING_LIMIT).each do  m 
        tmp += 1
        puts "# tmp  su # totale : # m.id "
        @todo << m
      end
      while true
        if @todo.length == 0
          break
        end
        add_fixture(@todo.pop)
      end
      puts "\n\n# '='*80 \nScan Finished\n# '='*80 \n\n"
      @fixtures.each do  name, fixture 
        if fixture.size > 0
          i = "000"
          filename = "# RAILS_ROOT /test/fixtures/# name .yml"
          puts "Create # filename  for class # fixture.class.name "
          FileUtils.mkdir(File.dirname(filename)) unless Dir[File.dirname(filename)].size > 0
          File.open("# RAILS_ROOT /test/fixtures/# name .yml", 'w') do  file 
            file.write fixture.inject( )    hash, record 
              hash["# record.class.table_name _# i.succ! "] = record.attributes
              hash
             .to_yaml
          end
        else
          puts "Fixture for # name  is EMPTY"
        end
      end
    end
  end
end
It's written in a somewhat quick and dirty way, but it gets the job done. What it does: It takes a single class - hopefully a well connected one - fetches a few of them, and goes from there, exploring all the other objects that the initial ones are connected to, and then dumping them in .yml files in the fixtures/ directory. It could certainly use more work:
  • Additional starter classes, for ones that aren't connected to others.
  • Intelligent examination of data and data sets...
  • For example you could check to see what classes aren't connected to the others and use them as starter classes.
  • If you wanted to waste a lot of cycles, you could also try and aim for a representative set of examples. For an object that has_many something elses, you could try and find one with zero, one with one, and one with a lot, to cover various cases. That could quickly get out of hand for largish data sets though.
  • I'm sure there are various other tweaks, knobs, and levers that could be added to work more efficiently. I'd love to see them!

Biella Coleman: Epic Lulz will be had (aka: I am giving a talk)


Screenshot-coleman-scientology-slides - OpenOffice.org Impress -1, originally uploaded by the biella.
“Old and New Net Wars over Free Speech, Freedom and Secrecy or How to Understand the Lulz battle against the C0$ Gabriella Coleman, Assistant Professor, New York University Thursday November 13: noon - 2:00pm
Columbia University Communications Colloquium
270B IAB (International Affairs Building update Open the public! You may need ID to get into the building but I am not sure. This is the case with NYU…

Biella Coleman: Epic Lulz will be had (aka: I am giving a talk)


Screenshot-coleman-scientology-slides - OpenOffice.org Impress -1, originally uploaded by the biella.
“Old and New Net Wars over Free Speech, Freedom and Secrecy or How to Understand the Lulz battle against the C0$ Gabriella Coleman, Assistant Professor, New York University Thursday November 13: noon - 2:00pm
Columbia University Communications Colloquium
270B IAB (International Affairs Building update Open the public! You may need ID to get into the building but I am not sure. This is the case with NYU…

Matthew Garrett: Android

As a brief introduction to this - I first read through the Android code when interviewing with Google for an opening with the Android kernel team. I didn't get the job, and while I don't think anything that follows here is as a result of residual bitterness you might want to take some of it with a pinch of salt.

Anyway. Android is a Linux kernel with a heavily customised user layer that bears little resemblance to any traditional Linux system. I write in C because using pointer arithmetic lets people know that you're virile so this Java-like thing is of little interest to me and I'm going to ignore it and just look at the kernel, because after all that's what I'm paid to be good at.

The short summary of the rest of this post is that I'm not planning on giving up my iphone yet.

The Android kernel source lives in a git tree here. It can pretty much be logically split into two parts - the port to Qualcomm's MSM7xxx series chips and the special Android customisations. A bunch of the MSM7xxx port code has been merged through the ARM tree and is now upstream, and Brian Swetland seems to have been fairly active in looking after that. Full marks to Google there. This code is handy outside the Android world and benefits anyone wanting to run Linux on similar devices.

The Android-specific code is more... interesting.

As I mentioned, the Android application layer isn't Unix in any real sense. The kernel reflects this. It ranges from pragmatic (if hacky) approaches like encoding security policy and capabilities in group IDs that are hardcoded into the kernel through to implementing an in-kernel IPC mechanism (apparently related to the OpenBinder implementation from Palm, but judging by the copyrights a complete rewrite). To an extent, I'm fine with this. Something like Binder is pretty clearly not going upstream, so the fact that it engages in bizarre design decisions like sticking chunks of its interface in /proc is pretty irrelevant. What's more interesting is the code that should be generalisable.

I work on power management, so I'm always interested in what kind of power management functionality and interfaces people want. Plumbers included a nice discussion with someone from an embedded company I can't remember, culminating in us deciding that the existing cpufreq interface did what they wanted and so no new interfaces needed to be defined. Google was going to be an interesting case of a large company hiring people both from the embedded world and also the existing Linux development community and then producing an embedded device that was intended to compete with the very best existing platforms. I had high hopes that this combination of factors would result in the Linux community as a whole having a better idea what the constraints and requirements for high-quality power management in the embedded world were, rather than us ending up with another pile of vendor code sitting on an FTP site somewhere in Taiwan that implements its power management by passing tokenised dead mice through a wormhole.

To a certain extent, my hopes were fulfilled. We got a git server in California.

Android contains something called the android_power driver (ignore the references to CSMI, which is a piece of OMAP-specific hardware for communicating with the baseband - I'm not sure what they're doing in there). As far as I can tell, this is an interface that handles the device being locked and unlocked, and associated powering down of certain bits of hardware. Except it's shit. Devices register device handlers and a level where they wish to be suspended. There's no direct concept of intra-device dependencies so you end up with stuff like:
android_early_suspend_t early_suspend;
android_early_suspend_t slightly_earlier_suspend;
to deal with the fact that the MSM framebuffer driver depends on the MDDI driver having brought the link bank up and so needs its suspend method called before the MDDI driver but its resume method to be called after, and the only way to handle that is to register two methods - the "slightly earlier" one which has a suspend method but no resume, and the "early" one which has a resume method but no suspend one.

Of course, this also means that all of your device runtime power management policy ends up in the kernel. Userspace indicates what state it wants to go to and the kernel decides what's going to get powered down. This kind of coarse grained approach means that as your hardware setup becomes more complex you hit combinatorial explosion. Expressing all the useful combinations of hardware state simply becomes impractical if all you're exposing is a single variable. What would be more useful is the ability for userland to interact with individual pieces of hardware.

The amusing thing is that in many cases Linux already has this. Take a look at the backlight and LCD class drivers, for instance. They provide a trivial mechanism for userspace to indicate its desires and then modify the device power state. It's true that there are other pieces of hardware that don't currently have interfaces to provide this kind of information. And that's where cooperation with the existing community comes in. We've already successfully fleshed out interfaces for runtime power management for several hardware classes, with the main thing blocking us being a lack of awareness of what the use cases for the remaining classes are. But linux-pm has seen nobody from the Android team, and so we end up with a lump of code solving a problem that shouldn't exist.

When Robert Love gave his presentation on Android at Lugradio Live in SF back in April, he talked about how one of the reasons that Google weren't releasing the source for their userland stack until they shipped phones was to prevent it being seen as throwing unfinished code over the wall and then ignoring the community. It's unfortunate that this is almost exactly what's happened with their kernel. Right now the fact that Android is based on Linux is doing almost nothing to benefit the larger Linux community. What could have been a valuable opportunity for us to gain understanding of an interesting problem has instead ended up as yet another embedded vendor kernel, despite all the assurances I got from various people at Google.

Disappointing.

9 November 2008

Raphael Geissert: yummy yummy


Andrew Pollock: [tech] Keeping hard drives cool

I've had this crazy ATA over Ethernet SAN for my MythTV setup for as long as I've been running MythTV. I'm using minotaur, an old Pentium III 1RU VA Linux server as the "head". Originally, I had 4 IDE hard drives, attached to minotaur via IDE-USB adapters. This worked perfectly fine, but I missed the ability to query SMART information, and do other low-level drive tweaking with hddparm So a while ago, NewEgg had a sale on 750Gb SATA drives, and I bought a 4 port eSATA card, and took the plunge with SATA. That all went fine. The entire time, I've had the 4 hard drives themselves just sitting on top of minotaur, on cork trivets. The whole arrangement is in the bottom of our linen closet, as this is where the patch panel for the apartment is. I've graphed the temperature of linen closet for some time now, but the benefit of having hard drives connected via SATA was that I could easily graph the temperature of them as well, which I started doing recently. The catalyst for wanting to do this was that I had a drive fail, and I was concerned that they were getting too hot, just sitting in the closet with no airflow. Matt Bottrell's recent reminder of Google's research into hard drive failures also helped bring this concern to forefront. Seagate's product documentation for the Barracuda 7200.10 claims that ambient operating temperature must be between 0 C and 60 C. I'm assuming that's the environment the hard drive is in, and not the temperature of the drive itself as reported by something like hddtemp. The closet is typically in the high 30's. If you believe what SMART reports, it seems to imply that anything over 45 C is a Bad Thingtm. So after I had a drive fail, I figured I should probably try to do something about the temperature situation, and started looking around for an external enclosure. I'd previously had problems with the IEC-to-Molex power supplies I was using to power the disks, and think that they'd been the cause of some failures of my IDE disks, so was quite eager to stop using them as well, which was something else an external enclosure would give me. I had trouble finding an enclosure that presented 4 separate eSATA ports, and I was talking to Marc about SATA port multipliers, when he mentioned he had a brand-new unused full-height SCSI enclosure, for four disks, which was surplus to his requirements. Since all I really needed was external power and cooling, I thought I could cannibalise this to my needs. Sure enough, I could just remove the SCSI cables and their Centronics connectors, and feed the eSATA cables out the gap they left, and use the molex-SATA power splitters I already had. Because the enclosure was intended for full-height 3.5" hard drives, there was plenty of air space between each disk. The enclosure included two fans. The results? Well the graph speaks for itself:

Graph of hard drive temperatures (I'm not entirely sure why minotaur's internal disk occasionally reports a very low temperature) The added bonus is I've cleaned up the rats nest of cables in the linen closet. So thanks very much, Marc!

Christine Spang: Switching to Colemak

Way back in mid-late May, I switched keyboard layouts from standard US QWERTY to Colemak. I’d played around with the layout a bit before that and thought it seemed pretty solid, but it hadn’t been a good time to switch then. (I did, however, snag the idea of remapping Caps Lock to Backspace from that early trial though, and to this day that’s probably the most annoying thing about typing on QWERTY, because I associate Caps Lock with Backspace on both layouts now. Anyway.) This time, however, I strategically timed it to coincide with the end of classes, so I had no assignments due and could make a fool out of myself during the first few days of my summer job. Smashing success. It only took a couple days to get past the point of extremely frustrating slowness. Two weeks in I was up to 40wpm, which was about the point where I stopped noticing that I’d taken a backwards step in typing speed, as it didn’t really hinder anything I did on a regular basis. By the end of the summer I was back up to the same speed as I’d been prior to switching (around 75wpm). I didn’t really do any typing lessons after the first few days, as I found just doing whatever I would normally do on a computer much more interesting. The biggest hurdle after the initial adaptation of actually being able to type on the layout was, for a command-line lover like myself, dealing with “hjkl” not being a convenient way of navigating around in console apps like mutt, vim, aptitude, and less. After a bit of experimentation, I stole an idea from this page and started adapting my dotfiles to make these programs use ne for jk and st for hl, and that seems to be working out well. The worst key that this clobbers in general is n, but it’s pretty easy to remap that to QWERTY’s n, which is easy to remember and is the hardly-used k on the Colemak layout. For any interested others, I’ve thrown the relevant dotfile snippets up here. I’d been putting off blogging this because I wanted to finish setting up dotfiles/homedirs-in-git la Joey Hess beforehand, but I figure I’ll never actually get it done if I keep using that excuse. For mutt, the given snippet goes in your .muttrc (or whatever you source keybindings into your muttrc from). The same goes for vim. Aptitude keybindings go in .aptitude/config. For less, it’s a little more arcane: first you stick your keybindings in .lesskey, and then you run the command lesskey. I also remapped screen’s escape key to ctrl-t. Why not Dvorak? Dvorak seems to be the most well-known QWERTY alternative around, so why didn’t I switch to that if I wanted something better? I did try Dvorak first, but the incredibly uncomfortable combination of ls on the right pinky was a complete deal-breaker. I also found it very slow-going to try to adapt to Dvorak after typing on QWERTY for years. The Colemak FAQ has some more notes on Dvorak deficiencies that it addresses. Overall, I’ve found typing on Colemak to be remarkably lacking in anything that particularly bothers me. I still type on QWERTY a little, but mostly just for login prompts on Athena workstations and the desktop machine in my room which my roommate sometimes uses. I have to glance down at the keyboard when typing on QWERTY to get it back in my head, but generally I only need it for a few minutes anyway and it’s no big deal. As long as I glance down occasionally I can still maintain a speed level well above that of frustration. On the plus side, this means that if I look at the keyboard when typing normally in Colemak, I get screwed up because I start thinking in QWERTY. So it’s good touch-typing reinforcement in general.

Adeodato Sim : Five films (#3)

After a summer during which I didn’t get to watch many movies, I’m back on track now. Here we go:

Simon McVittie: Spec-writing On A Plane

(Written on Friday 16th, posted on Monday)

As I write this, I'm on a plane off the coast of the Netherlands, on the way back from a couple of days designing APIs with Rob McQueen and the RTCom people at NRC Helsinki (who we work with on the chat and VoIP functionality for Nokia internet tablets).

We've had a very useful couple of days, mainly designing the next-generation channel requesting and dispatch API for Telepathy (the same APIs I've been doing preparatory work for on the Telepathy mailing list in the last couple of weeks). API sketches for review and comment are either on are on Merge Monkey or on the way there.

Before even reaching Nokia, Rob and I did a lot of design on the plane over to Helsinki, and I took some notes: here they are, by way of a glimpse at how the Telepathy design process works when we don't have a whiteboard[1] :-)

  • Geoloc looks good in principle, needs some more work
    • add more docstrings
    • add a way to ask people for uncached info (RequestLocations)
    • move access control to Co.I.Presence, call it RichPresenceAccessControl?
  • DeliveryReporting looks good, ish
    • improve wording of delivery-echo and rationale
    • when sending a delivery report, add a reason for the status (using Channel_Text_Send_Error?)
  • Uniqueness requirement for (channel, handle_type != 0, handle) is in the way - let's drop it
  • MSN should use "authentic" 1-1 chats, and use Ch.I.UpgradeableToRoom (name tbd) to migrate the underlying switchboard to be a room
  • XMPP should use Ch.I.UpgradeableToRoom too, but the 1-1 channel may also stay open
  • Mutable handle => handle 0 must stay (for requestotron's benefit)
  • bundles ftw
  • renaming: we want SelfHandleChanged in the core
  • TpC* - add ability to subscribe to ifaces ay construct time (blocks Ready) or later
  • Dispatching: when registering a c'handler, specify everything it can handle
  • If a new bundle can be handled in its entirety by the same handler (call it 'the bundle handler'), do it. Otherwise split it up completely (there is no 'bundle handler').
  • If a channel in an existing bundle can be handled by the bundle handler, send it there, else send to the default handler.
  • Group - add SelfHandleChanged, maybe? Also Connection
  • Add HandleOwners: prop a uu , HandleOwnersChanged(a uu , au)
  • Use TargetHandleType, TargetHandle
  • Stringified initiator handle as a separate property
  • Maybe even a FirstMessage property, although this stretches the definition of "immutable"
  • org.freedesktop.Telepathy.Client interface

Nokia's Mikhail Zabaluev kindly took notes for some further discussion we had with him and Alberto Mardegan about the dispatch API, which he already posted to the mailing list.

We hope this API will make it possible to integrate Telepathy into the desktop better - it should make it a lot easier to share connections between processes in a useful way and hand out incoming channels to the appropriate handlers, which was always a major goal for Telepathy. It should also let us and others implement exciting new notification mechanisms (hi to the people on IRC and the mailing list wanting to patch their media players to integrate with Telepathy! :-)
[1]When we do have a whiteboard, the design process is: "Robot101 scribbles on a whiteboard, smcv writes down <tp:rationale> elements"

Simon McVittie: Implementing D-Bus services with telepathy-glib

(Part 1 of an ongoing series: shiny things in telepathy-glib)
16:46 < epmf> tp-glib is made of magic

—#telepathy, 2008-04-15

Rob pointed out today that I'd been promising to blog about telepathy-glib for several months and still haven't done so. I think there's too much to cover in one blog post, so I'll start with the oldest part - implementing a service (typically a Telepathy connection manager).

While telepathy-glib is (obviously) intended for Telepathy implementors, I think the ideas we've been implementing are likely to be useful for any D-Bus API, particularly flexible/complex APIs where an object implements many interfaces.

Introduction to telepathy-glib telepathy-glib started out as a collection of code extracted from our XMPP connection manager, telepathy-gabble, but at some point it grew beyond that into a wrapper around/partial replacement for dbus-glib. We've been quite pleased with it, really :-) My first major round of work on telepathy-glib, during the first half of 2007, was to split it out from telepathy-gabble (versions up to 0.5.9 were released as part of Gabble 0.5.x tarballs, in fact), leading to the release of the 0.6.x stable branch in late September. This was very helpful for implementing connection managers - Salut, Idle and telepathy-sofiasip (our connection managers for link-local XMPP, IRC and SIP) all started off by forking/cargo-culting from Gabble, and achieved huge code reductions by porting to telepathy-glib. Also, Will Thompson used it in his Summer of Code project, telepathy-haze, to go from nothing to a working and useful Telepathy implementation based on libpurple in a matter of a few months. The second major round of work, which I'll discuss in a later article, added client code to telepathy-glib, obsoleting the older/worse libtelepathy and allowing client programs like Empathy and telepathy-stream-engine to be written using telepathy-glib. In the process, I accidentally reinvented DBusGProxy :-) More details to come later!
Some background: service-side code generation
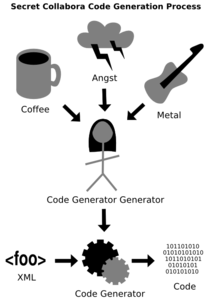
The secret Collabora code-generation process

(credit: daf)

Supporting D-Bus in the GObject world has always involved quite a lot of code generation. The core API of dbus-glib is heavily reliant on varargs functions, which aren't type-safe and are easy to get wrong. dbus-glib contains a program called dbus-binding-tool, which is meant to generate reasonably sane GObject APIs for D-Bus objects. Unfortunately, it seems to be intended to generate a whole GObject at a time. Early versions of telepathy-gabble used dbus-binding-tool plus a script called gengobject.py to generate API stubs for the exported objects; developers then filled in the blanks, and hey presto, we had a GObject on D-Bus. This was fine up to a point, but had a couple of major drawbacks. Whenever we changed the D-Bus API (quite common during the early development of Telepathy), there was a very laborious and error-prone merging process. We ended up with the following process:
  • copy the D-Bus introspection XML from the telepathy-spec repository into a directory xml/pristine (actually, the canonical form for the spec was Python for a while, and we had a script that exported a contrived object onto D-Bus and introspected itself to get the XML - but that's another story!)
  • preprocess the introspection XML to add the dbus-glib CFunctionName annotation, resulting in a directory xml/modified
  • run dbus-binding-tool and a Python script gengobject.py to generate C source in xml/src
  • three-way-diff the old version of xml/src, the new version of xml/src, and the real C code in src to create a new version of src
  • pray that the diff process hadn't randomly exchanged functions' implementations
  • update the resulting code in src so it worked
  • check the whole mess back into darcs
  • hope that nobody else had made changes that would result in darcs conflicts
If you haven't yet gathered, this was a bit of a nightmare. Also, it was very easy to return the wrong thing from a method without noticing - because all the APIs were varargs, the compiler didn't notice, and the first we'd know about it was a mysterious segfault under certain circumstances.
How telepathy-glib fixes code generation telepathy-glib improves on this by taking advantage of this innocuous-looking feature in dbus-glib:
commit 355ef78d98d6fc65715845d56232199162cab12a
Author: Steve Fr cinaux <steve istique net>
Date:   Thu Aug 17 11:48:20 2006 +0200
    Interface support for bindings.
Instead of running dbus-binding-tool or creating GObjects with D-Bus interfaces, we put the entire Telepathy spec through glib-ginterface-gen.py, a distant descendant of Gabble's gengobject.py. For each interface in the spec, we generate a GInterface that mirrors the D-Bus interface. Any GObject that implements the GInterface automatically gets the D-Bus interface if it's exported onto D-Bus. There are a few non-obvious refinements, though:
  • The signature of the method implementation is always in the mode that dbus-glib calls "asynchronous", where the method implementation can either send a reply message before or after it returns. For "slow" methods, this is the only thing you can do. For instance, many Telepathy D-Bus methods can't return anything until some TCP round-trips to the server have happened. This is also the only thing you can do if you want to extract extra information, like the sender's unique name, from the method-call message (dbus-glib's "synchronous" API doesn't allow this to be done). For "fast" methods, sending a reply message before returning is just as easy as using the "synchronous" API (it's just a difference of syntax), and has an API consistent with that of the "slow" methods, making it easier for service authors.

  • The layout of the GInterface vtable is private, and (auto-generated) accessor functions are used to fill in implementations. This means our ABI doesn't change just because we re-ordered functions in the spec.

  • If no implementation is provided for a method, we just raise an appropriate error (org.freedesktop.Telepathy.Errors.NotImplemented), rather than suffering an assertion failure. This means we can safely add methods to an interface.

  • While we're generating code anyway, we generate some static inline wrapper functions which wrap dbus_g_method_return(), to have type-safe method returns. You can easily check that a method replies with correct types, by checking that the implementation of Foo() replies by calling tp_svc_some_interface_return_from_foo().

  • Similarly, we generate wrapper functions to emit signals, to get type-safe signal emission.

Not all interfaces are stable enough to be included in telepathy-glib's stable API and ABI, so some of our other projects include a copy of the telepathy-glib code-generation tools, and generate their own "mini-telepathy-glib" (traditionally in a /extensions/ directory) for their implementation-specific (drafts of) interfaces. This isn't yet as polished as it ought to be (mainly because we don't want to freeze the augmented-introspection-XML format that we write the Telepathy spec in, because it's rather ad-hoc and hackish in places) but it works quite well in practice. To see what this looks like in practice, have a look at the examples in telepathy-glib, or at a Telepathy connection manager like telepathy-gabble.
Mixins and base classes Another feature of telepathy-glib which makes life easier for connection manager authors is that it provides "mixins" and base classes which implement some of the GInterfaces. There's absolutely nothing magic about the base classes - they don't have any access to private implementation details of the GInterfaces, they just implement them like everyone else does. The "mixins" are only slightly more magical - they store some extra state inside the structures representing GObjects and their classes, and use it to provide default implementations of some or all of the methods on a particular interface (or two interfaces, in the case of the new TpMessageMixin). I'll leave it up to Rob to explain those in greater detail, since I seem to remember that he invented them :-P The examples and regression tests in telepathy-glib are quite good examples of how these work in practice.

Simon McVittie: A magical xrandr incantation

Here's a handy incantation I use with the Intel X.org graphics driver on my laptop.

Put this script somewhere convenient:

#!/bin/sh
if xrandr   grep '^VGA connected' >/dev/null
then
    #echo "VGA connected"
    xrandr --output VGA --above LVDS --auto
    xrandr --output LVDS --auto
else
    #echo "VGA not connected"
    xrandr --auto
fi 2>&1   logger -t xrandr-hotkey

and bind it to your "switch video mode" key, e.g. Fn+F7 on my Thinkpad X60s. For instance, I run xbindkeys, so I saved it as autoxrandr and put this in ~/xbindkeysrc:

"exec /home/smcv/bin/autoxrandr"
    XF86Display

Now if you press the "switch video mode" key with a monitor plugged in, you'll get the external monitor appearing above the laptop panel (my preferred configuration - I've balanced my monitor on an N800 box to get the bottom of the screen level with the top of my laptop's screen). If you press that key again after unplugging the VGA cable, the laptop will turn off the VGA output and pull all the windows onto the built-in screen.

Simon McVittie: Encrypted root filesystem on a Debian laptop

I've been meaning to document this for ages... My laptop is set up with an encrypted root filesystem using LVM and dmcrypt. It also has a small Debian stable system for recovery purposes (I don't have a CD drive, so if everything goes horribly wrong, I can't just boot from a live CD). Here's how to set up something similar:

Step 1. Set up the recovery system Start the Debian lenny (beta) installer as usual. (I originally used etch, but these instructions are for lenny - either should work.) When you get to "Partition disks", choose "Manual". Here's the partitioning scheme to use:
  • main partition for LVM, taking up the whole disk minus 1GB or so. select "Do not use", for now
  • 1GB recovery partition at the end of the disk (this will also be the main system's /boot, since /boot needs to be unencrypted anyway). Use the defaults: ext3 mounted at /.
Finish partitioning and write changes to disk, and wait for the base system to install. Say yes to installing Grub to the MBR for now (it might be possible to do the install more cleanly by installing Grub to the recovery partition's boot sector instead - I haven't tested that). Reboot into the freshly installed recovery system and satisfy yourself that it works.

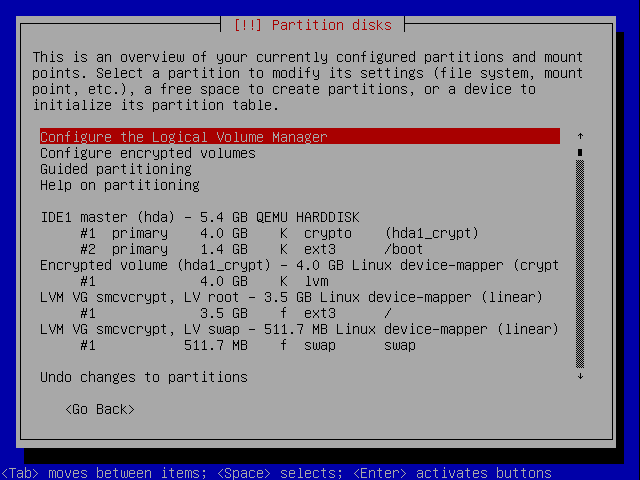
Step 2. Set up the main system Now boot the Debian installer again. This time it's for your installed system. At the "Partition disks" stage, choose "Manual" again. Select the main partition and choose "Use as: physical volume for encryption". Next select "Configure encrypted volumes". Your main partition will now be randomized - this is slow - and some time later you'll be asked for a passphrase. You'll have to type this in at each boot. Select the contents of the "disk" Encrypted volume (hda1_crypt) and choose Use as: physical volume for LVM. Now "Configure the Logical Volume Manager" and create a Volume Group. I always use the laptop's hostname as the VG name (this reduces confusion if you ever plug the disk into another machine for disaster recovery). Create a Logical Volume called swap, the size you want your swap space to be. If you plan to use suspend-to-disk, this needs to be at least as large as your RAM. Create a Logical Volume called root, for the root filesystem. If you want separate "partitions" for things like /home, now is a good time to create them too; if you want to use my schroot howto, leave some unallocated space in the VG for that. Set your swap LV to be used as a swap area, and your root LV to be used as ext3 mounted at /. If you wanted extra LVs, set them up too. Also set your recovery partition to be used as ext3, mounted on /boot, and not reformatted. It should now look something like this (smcvcrypt is the name of a KVM virtual machine in which I've been testing these instructions, normally you'd have the laptop's hostname there). Screenshot from d-i Proceed with the installation. Install Grub to the MBR - this will temporarily make the recovery system unbootable, but shrug never mind. Finish the installation and reboot into your new main system.

Step 3. Make them dual-boot Within the main system your recovery system is also visible, at /boot. Bind-mount /dev onto /boot/dev, chroot into /boot, and run "update-grub /dev/hda2", where hda2 is the partition where the recovery partition is. Leave the chroot. Edit /boot/grub/menu.lst and put this right at the end:
title Go to recovery system
root (hd0,1)
chainloader +1
(Replace (hd0,1) with what Grub thinks the recovery partition is - the second number is the partition number starting from 0, so /dev/hda5 would be (hd0,4) and so on.) Also edit /boot/boot/grub/menu.lst and put this right at the end:
title Back to main system
root (hd0)
chainloader +1
Also, still in /boot/boot/grub/menu.lst, go to the top of the file and change the colour scheme to something else (I used a red background) to indicate that this boot menu is for the recovery system. Reboot and try it out. You should now have an extra boot menu option, "Recovery system". Selecting it will switch to the recovery system's boot menu, which has an option to switch back, and so on. Each boot menu also has some entries for kernels, any of which will boot with the appropriate root filesystem (encrypted root for the main system, unencrypted for the recovery system). Success!

Next.

Previous.