Search Results: "ema"

9 March 2008

Daniel Jacobowitz: Seeking Alan Curry

I’m trying to reach Alan Curry, pacman@TheWorld.com, about some GDB work he did last year. That address now bounces. He’s a regular Debian bug submitter, though none of his bugs have a newer address for him listed. So the best idea I could come up with was to ask the lazyweb - Alan, are you out there? Or does anyone else reading Planet Debian know how to reach him? Leave a comment or send me email if you do. Thanks. Updated: Yes, I did try Google. Thanks to all those who pointed out world.std.com (alias for TheWorld.com), and clss.net (most recently used in 2005; no active nameservers); sorry I forgot to mention that.

Enrico Zini: ldap-userdb-fields

Fields used by an LDAP Unix user database Some notes about LDAP for Unix user management: Meaning of fields for objectClass posixAccount: Meaning of fields for objectClass posixGroup: For objectClass inetOrgPerson: what you put there can be used as if it were a vCard by mail programs and contact lists. Now, the name of people could potentially be split in cn,givenName,sn,gecos and displayName (possibly more): how would normal user tools deal with the redundancy? To show a gecos field, pam_ldap will search for a gecos field first, then automatically fallback on building a gecos field out of the other suitable info it finds. To show a name, sane programs try displayName first and if it's not present they guess using the rest. Then there is the issue of how to chose the dn to identify users, groups and so on. Users usually go in uid=$USERNAME,ou=People,$SUFFIX, while groups would usually go in cn=$GROUPNAME,ou=Groups,$SUFFIX. Should you need to create the People and Groups organizational units, this could be the proper bit of LDIF:
dn: ou=$NAME,$SUFFIX
ou: $NAME
objectClass: organizationalUnit
To add fields that are not already part of a schema, one needs to create their own schema. To do that, one needs to first obtain (free of charge) a Private Enterprise Number that is used in various places in the schema definition. Making up your own one means risking conflicts if you eventually grow larger. But it is rarely needed, because for most things there are already schemas available. Many thanks to Wouter and noshadow for allowing me to crudely extract all this content from their brains.

Biella Coleman: Dead Media Archive

When you join an academic department, you are just one body and mind among many others doing what you do: teach, write, go to conferences, answer a lot of student emails, advise, etc. However, what you don’t get to do is really see your colleagues very often. While we come together far too frequently for faculty meetings, once you are done, you just want to scuttle out of the room (and as quickly as possible) to continue what seems to be an endless stream of work. But over the course of months and years, there are times and moments when you do come across your colleagues and their work: you may assign some of their work in your class class, go see them speak at an event, or learn about their work over coffee. This weekend during a PhD prospective weekend, I finally got to learn about what is probably one of the coolest projects to come out of my department, The Dead Media Archive run by Ben Kafka and Alex Galloway for their Dead Media Archeology Class. Loosely inspired by a mailing list by the same name started years ago by Bruce Sterling (which eventually suffered its own death), they are collecting information and analyzing the significance of all sorts of Dead Media, some of which were quite present and important for our economy and communication systems, others which flickered much more briefly as a bright idea but never really caught on. As part of their class assignments, students have to write in-depth descriptions, histories, and analysis’ of these objects and they are fantastic; so if you are into dead media, do check out the archive.

Bernhard R. Link: Why I am putting dpkg on hold on my unstable boxes right now...

A hijack of an important package makes me always uneasy. But reading the next two messages to the debian-dpkg list, which I can only read as "oh, I broke make dist. But why should I follow sane practises, all hail my workflow" and "oh, I brake Changelog, that's on purpose because I consider it a bad idea, if you want it make write some scripts to generate it" does nothing to make me believe such a person can be a good maintainer.

David Welton: Bypassing Android's "Resources"

Android relies heavily on something called "resources" to access portions of the system that aren't directly in the Java code. For instance, if you had an ogg file that you wanted to use to play a sound with, you would add it as res/raw/foo.ogg. Then, during compilation, the aapt tool transforms all your resources into a Java file called R.java, which is basically a series of integers that can be used to reference the actual resources. For instance, to set up our hypothetical ogg file, we would do:
MediaPlayer mp = MediaPlayer.create(context, R.raw.foo);
That's all well and good as far as it goes, and if you don't have any reason not to use it, you should. However, with Hecl, one of my goals is to make it very easy to create applications. This means: I'm not there yet, on the Android platform, which is a bit more complex than Java ME (where it is indeed so easy to create new Hecl .jars that it's possible to do it on the fly via this web site: http://builder.hecl.org), but I am making progress. One thing that a user might want to do is add their own files to the .apk file that actually gets installed on the phone. Since it's just a zip file, that's pretty easy:
zip -r Hecl.apk res/raw/foo.ogg
However, without a resource, there is no way to access that file, so the question is: how can we get ahold of it somehow? The first piece of the puzzle is Java's ZipFile class, which lets us open up a zip compressed file, such as the .apk file that contains the ogg file we're interested in in this case. The critical passage is getting ahold of the actual filename on the Android filesystem of the code that's currently running. It turns out to not be too difficult, if a bit obscure:
String filename = this.getPackageManager().getApplicationInfo(packagename, 0).sourceDir;
With that information in hand, we can feed it to ZipFile, and then access the contents at run time. It's not a perfect nor complete solution, yet. So many of the Android API's require a resource ID, so it takes some extra coding to do things from the InputStream that we can get out of the zip file, but there may be ways to make this easier. For instance, we could simply dump the contents of raw/ into an application specific data directory the first time an application runs, in order to at least be able to access the files as files, rather than InputStreams connected to ZipEntries. In any case, at least it's possible to access files added to the .apk without requiring the compilation step. I'm not sure how many other use cases there might be for direct access to the .apk file, but if other people need to do this, hopefully this information will be helpful.

8 March 2008

Clint Adams: The Legend of Bagger Baggs

One day the Stranger arrived. He was a tall and lanky teen, his face peppered with acne and sparse pubescent hair. He wore a wide-brimmed hat, a long coat, a scarf, and he was Strange. Some newcomers prefer to observe, to gauge the breadth and nuance of Social Custom, and to keep low profiles until they are comfortable enough to risk a misstep. This newcomer preferred to wield a bean bag, and to go door to door, knocking, introducing himself, and asking if there might be any nice conversation lurking inside in which he might join. Predictably, most people were horrified, frightened, and offended. They responded in a hostile fashion, and branded him Bean Bag Boy, or Bag Boy for short. A few others viewed him instead as a free spirit, a visionary, a unique character, and a Cool Guy. Perhaps they bought into the crap that society spews forth as part of its Campaign for Cognitive Dissonance. Perhaps they were just confused. Those that admired him branded him Doctor Who, a moniker of affection and respect. I will never understand this, even though I know which drugs they were on (Prozac, Zoloft, LSD, THC, psylocybin, and PCP, respectively). Bag Boy learned to keep mostly to those who appreciated his insane ramblings. Had he been motivated and competent, he probably could have been a minor cult leader. Instead, he fell out of public view for a while. When he returned, he had two younger companions: a boy and a girl. It became immediately obvious what to call them. The female, whose name, eerily enough, was Baggs, would be Bag Girl. Since Bag Boy already possessed that name, the male would have to be Little Bag. Little Bag was an enigma unto himself, and went on to have many adventures of his own. Once he called me a Zenmaster, so I will refrain from mentioning him for a long time. Bag Girl was no less a character. She detested being called by either her given name or her surname, and instead preferred to brandish an agglutinative designation of her own choosing: one part temporal adjective, one part finite act of performance. This contrasted delightfully with her appearance, which was not dissimilar to a three-foot-tall chinchilla. Most were content to call her by her chosen appellation, though some would add her real surname (to which she fumed bitterly), and one insisted on calling her by her given name, as a hostile act of hatred. Bag Girl's main hobby was a menagerie of characters that she explained were her multiple personalities. Unlike persons suffering from dissociative identity disorder, Bag Girl had full knowledge of her personalities and their doings. One of these personalities was a 90-year-old elf named Galiganda Dulin. Another was a man named Sayjon, who bore a suspicious resemblance to Pink Floyd's fascist alter ego from The Wall. In fact, Bag Girl had been profoundly affected by The Wall, although she had watched it while on LSD, so interpolation based on these data may be tainted.

7 March 2008

Jacobo Tarrío Barreiro: Asking hard questions

Oh, please, I don t think I ever had a favourite film: Here is an image of a form that asks me for my favourite movie. I cannot remember what I wrote here when I signed up more than two years ago. And, of course, there s something good about this form, and something (else) bad about it: The bad: this is displayed just after it has verified my email address. The good: at least it s not asking for my mother s maiden name.

Peter Eisentraut: Notification about available package upgrades

I'm sure most people have one of these, but here is my yet-another email-me-when-I-need-to-upgrade-something crontab entry, after I found cron-apt too complex:
0 */8 * * *     apt-get -qq update && apt-get -dqq dist-upgrade && apt-get -qq --simulate dist-upgrade   grep ^Inst

If your root mail goes to some place you read (probably a good idea), you will get a list of packages it wants to upgrade. When running stable, this will also effectively send you alerts about security updates.

Adam Rosi-Kessel: Aircard Dilemma

I’ve been provided the latest Verizon and Sprint EVDO cards to evaluate in the field for the past month. I now have to decide which to keep. It’s a close call (no pun intended). I’ve tested them both over various areas in Greater Boston and Washington DC. Key observations: (1) Speed: The Verizon card is usually faster. I’ve clocked up to 2.5 Mbps using the Speakeasy speed test on Verizon. That’s getting to be respectable enough to use a VPN without annoyance. My top rate on the Sprint card is about 2.0 Mbps, but usually it’s more like 1Mbps down / 0.5 Mbps up. (2) Coverage: There are more Verizon “dead” spots with no service at all. In those spots, the Sprint card invariably works fine. I’ve noticed this in some government buildings as well as on the T in Boston. (3) Device: The Verizon card I’m testing is a USB device (UM150) with an extendable antenna and the ability to power on/off right from the device. The Sprint card is one of those newfangled half-width PCMCIA cards, which requires an adapter for my laptop. There are pros and cons to each: the Verizon card is more compact when closed up and fits easily in my coat’s lapel pocket, but it seems quite precarious when actually plugged into the laptop. It could fall out easily or break if someone hit it with their bag walking by. The Sprint card, by contrast, is quite sturdy. I certainly can’t throw my laptop in my case with the Verizon card still plugged in, while the Sprint PCMCIA card can stay in without trouble. A colleague warns me, though, by keeping the PC card in I’ve created an opening for my dust and whatnot to enter the laptop. (4) Software: Finally, the (Windows) software for the Sprint card is much better than for the Verizon card. The updated Verizon software is as flaky as the last iteration. It definitely doesn’t like it if you try to disconnect after you go out of EVDO range. It also doesn’t usually survive a sleep cycle, and sometimes requires manual intervention in the task manager or a reboot to clean things up. It also has some silly features like a control panel to launch your web browser and email client. I’m not sure anyone wants to use their dial-up client that way The Sprint software has its own share of silliness by having nonstandard decoration (it looks like someone thought “skinning” it would be cool, so they took away any resemblance of regular window frame). But it’s stable and solid, survives suspend/resume, and I’ve yet to have to kill it even once. So there you have it. If anyone wants to speak in favor of one or the other, please do so in the comments. As a side note, I’m promoting broader use of the term “aircard” to make it easier to speak with nontechnical people about the difference between EVDO/WWAN and “WiFi.” Technorati Tags: , , , ,

6 March 2008

Anthony Towns: The second half...

Continuing from where we left off… The lower bound for me becoming a DD was 8th Feb ‘98 when I applied; for comparison, the upper bound as best I can make out was 23rd Feb, when I would have received this mail through the debian-private list:
Resent-Date: 23 Feb 1998 18:18:57 -0000
From: Martin Schulze 
To: Debian Private 
Subject: New accepted maintainers
Hi folks,
I wish you a pleasant beginning of the week.  Here are the first good
news of the week (probably).
This is the weekly progress report about new-maintainers.  These people
have been accepted as new maintainer for Debian GNU/Linux within the
last week.
[...]
Anthony Towns <ajt@debian.org>
    Anthony is going to package the personal proxy from
    distributed.net - we don't have the source... He may adopt the
    transproxy package, too.
Regards,
        Joey
I never did adopt transproxy – apparently Adam Heath started fixing bugs in it a few days later anyway, and it was later taken over by Bernd Eckenfels (ifconfig upstream!) who’s maintained it ever since. Obviously I did do other things instead, which brings us back to where we left off…
Geez, this was meant to be briefer...

Neil Williams: Testing installers and system breakage

OK, this is just one of those things that just shouldn't happen but always seem to happen anyway. :-(
In testing an installation method for Emdebian, creating certain system config files for the target device ended up with a test script putting the Emdebian config file onto the main system. Yes, permissions would have stopped this but the other part of the test routine is udev and ensuring the device has a working console, hence the script needs to run under sudo to unpack the device nodes.
Just goes to show, developing scripts that work under sudo is a minefield of bugs. The law of unintended consequences means strange things can happen on the development box.
What did I do?
Oh, just replaced /etc/group with a installer copy.
Not much broke - except that 'ls' listed the group as 1000 instead of 'neil' and I stopped getting email.
I didn't twig initially - but then I realised that exim could not find the exim group because the Emdebian rootfs doesn't have exim or any MTA. All my email had arrived but it was frozen in the exim queue because exim couldn't work out how to proceed without an exim group.
Ah well. Good to know that I had a backup of /etc/group.
:-)
Suddenly, sudo runq dropped several hundred emails onto dovecot. Hey ho.
If only I could get USB to serial working on this HP laptop, I could play with these things on a box that is less important to my overall day to day work.
Still, nice to know exim did the right thing. Thanks, exim.
;-)

Christian Perrier: Women in FLOSS: samba

For people who have interest in the development of gender equity in FLOSS development, here's a short news item. Yesterday, the Samba Team announced the "pre2" version of samba 3.2.0, scheduled to be released during the SambaXP conference next month in G ttingen (to German friends around: of course, I'll be there: Apr 14-18). That release was announced by Karolin Seeger, whoc is now replacing Jerry Carter as Samba's release manager. As far as I know, Karolin is indeed the first female memer of the Samba Team (which includes about 20-30 people). Guess what: that release seems to be a pretty good one. I'm already working on the Debian package. The release is indeed the first one to include many patches we bringed from Debian, for instance those aimed at following the FHS. Steve Langasek is the one to be rewarded for this as he bringed very valuable input in the discussion I had with Jerry Carter to convince him to include these patches..:-)

Ond&#345;ej &#268;ert&iacute;k: Sage Days 8

Between February 29 and March 4, 2008 I attended the Sage Days 8, hosted at the Enthought headquarters in Austin, Texas. This was my 5th time in the USA and it was a marvelous experience, as with all my visits in the states.

As usual, I had some adventures in Atlanta, that interested readers can find at the end of this post. Anyway, on the Austin's airport I met Peter and his wife Crystal, Fernando, Benjamin, Jarrod, Eric and Clement. We went to have a dinner and then me and Clement were staying at Peter's house:
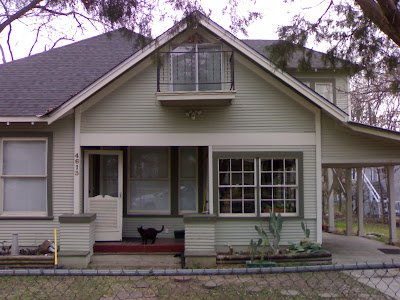


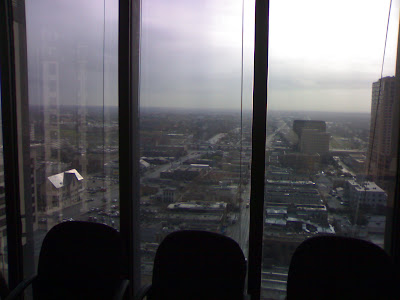
You can see the neighbor's cat and Peter's dog Trinity behind the window. The next day we went to Enthought, that was providing us with a breakfast and a lunch each day - and it was delicious. After the breakfast, we gathered in the room and introduced ourselves. Enthought rents 3/4 of the 21th floor in the Bank of America building, so when I looked left I saw:


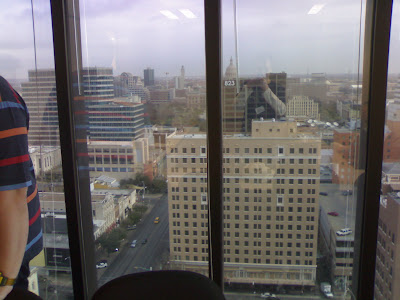
When I looked behind I saw:


and in front of me, I saw all the participants (I took photos of all participants together with names). As you can see, there were really good people in there, like Travis (creator of NumPy), William (main author of Sage), Eric (CEO of Enthought), Fernando (author of IPython), Jarrod (the release manager of SciPy), Michael (the release manager of Sage) etc. See also the Fernando's welcome speech and the video of each of us introducting himself.

The views from the windows are terrific. I enjoyed working on each of the 4 sides of the skyscraper with completely different scenery, or when the sun is going down, that's also very cool.

We spent the whole Friday doing presentations, some of which you can find here. Then we went to Eric's house to have a big dinner together.

On Saturday, Sunday and Monday we were all hacking on many different things. I joined Fernando, Benjamin, Brian and Stefan on ipython1, Travis was implementing a new type (gmp integer) in NumPy, William wrote a manipulate command in Sage, Eric did the same in Traits, Gary and Michael implemented parallel testing of Sage, ...

On Tuesday we had final status reports and people left in the afternoon. In the evening we went with Clement to have a dinner and then we visited some bars on the 6th street, having a beer in each.

On Wednesday I visited John and Roy from the Computational Fluid Dynamics Lab at the University of Texas, Austin, who wrote the libMesh library, that I extensively used and also created a Debian package of. It was very influential to see the libMesh "from behind", also John and Roy are cool people (not mentioning the Debian tradition of having good relations with upstream:). Then I visited some professors at the same campus, after which I went into the Capitol and then I took the bus to the Barton Creek Square Mall to buy some ipods and jeans, so that I can say I have jeans from Texas. BTW, the ipod works excellent in Debian - I plugged it in and it just shows on my Gnome desktop. It's true that naively dragging mp3 files on it didn't make it play, but these instructions made it work.

On Thursday I fixed the remaining release blockers in SymPy and made a new release. In the evening, I am going to meet Aswin, he also uses SciPy and also is a friend of Kumar, who is now maintaining python-numpy and python-scipy Debian packages with me (Kumar also knows Prabhu, the author of Mayavi2 hosted at Enthought, so it's all connected).

Anyway, the whole workshop was an excellent experience for me. I learned a lot of new things and being able to speak with people who wrote tools that I use almost everyday is important. We also extensively discussed the future of all the projects (Sage, SciPy, NumPy, IPython, Cython, SymPy). See my summarizing email to the SymPy mailinglist.

Another thing, that I find very interesting is that Microsoft is financing the windows port of Sage, that will make basically anything that uses Python/Cython/C/Fortran very easy to install on windows (just a spkg package in sage). I find it really cool that MS is not only supporting but even financing a truly opensource project.

Finally the promised adventure in Atlanta: we took off the Prague airport on February 28th with a 2 hours delay (due to some paperwork as we were told by the captain). As I had 3 hours in Atlanta for the connection to Austin and I had to go through immigration, it was clear that I'll miss it. But I was not surprised, last time I was flying through Atlanta, they canceled my flight to LA completely. We arrived in Atlanta an hour and a half before my departure, then I was waiting for about an hour at immigration, it was incredibly slow. When I had around 20 min to departure, I had to ask people standing in front of me if they let me in, they were very nice and did. I was leaving immigration 10 min to my departure, then I was running to get my luggage and myself through customs and screening, it was 5 min to my departure when I ran down to the display with departure times. Then I was sprinting like hell to the terminal D to only see the clerk doing some final paperwork with all the people already boarded and the jetway door shut. After a little persuading he let me in too, fortunately there was still one seat left, so I made it. You can imagine my pleasant surprise in Austin when I discovered, that my luggage made it too, considering that I handed it to the Atlanta's airport personnel exactly 10 min prior the departure.

5 March 2008

Eddy Petri&#537;or: email harvesting prevention - simple and efficient

On this page I've seen this nice way of preventing email addresses harvesting (I have noscripts installed):


When javascript is enabled/permited, it looks like this:


The code is really simple and could be easily automatically applied to pages (the code obfuscates even more, but that is irrelevant - see the original source for the code):
<script language='JavaScript' type='text/javascript'>
<!--
var prefix = 'ma' + 'il' + 'to';
var path = 'hr' + 'ef' + '=';
var addy35780 = 'g.martinez' + '@';
addy35780 = addy35780 + 'pcbsd' + '.' + 'es';
document.write( '<a ' + path + '\'' + prefix + ':' + addy35780 + '\'>' );
document.write( addy35780 );
document.write( '<\/a>' );
//-->\n </script><script language='JavaScript' type='text/javascript'>
<!--
document.write( '<span style=\'display: none;\'>' );
//-->
</script>This e-mail address is being protected from spam bots, you need JavaScript enabled to view it
<script language='JavaScript' type='text/javascript'>
<!--
document.write( '</' );
document.write( 'span>' );
//-->
</script>


BTW, the PC-BSD site looks really nice, unlike Debian's.

Adeodato Sim : One day with Git

1. Bzr Exactly 2 years ago I started using bzr. I wanted to start using one of the new distributed VCS for my small projects, and I chose bzr. Not having the time/energy to do an exhaustive comparison among them and try them all to see which one I liked most, I read some articles about them, and decided that bzr would be the most appropriate for me, and that I’d stick to it if I was satisfied enough. (JFTR, at that time it was very important for me the ability to serve branches over plain HTTP, and bzr was the only one in which HTTP was a first-class citizen.) I’ve found bzr easy to use and to learn, powerful enough, customizable enough via plugins, and in general, not requiring a whole lot of attention to get things done. Also, not slow enough as to abandon it. 2. Git Yesterday somebody posted in #bzr a link to this post by Elijah Newren, where one comment said:
There’s one thing I keep telling people though: Learning git is like learning vi — it’s different from the VCS/text editors you know on a fundamental level. But once you’ve overcome that problem, you’ll not want to go back. Ever.
Which pretty much matched the idea I had of git. In the summer after my first year at Uni, I told myself: “OK, let’s learn vim.” And I think it’s one of the decisions that has paid off the most. Like learning to touch type. Reading the above quoted paragraph made more urgent the doubts I had been sporadically having during the past year: maybe I would have been better served by choosing Git instead of Bzr in the first place. What would be my life like if I had stayed with joe? 3. More about Git So yesterday I decided to spend a couple hours (or three) getting the feel of it, trying to find cool stuff. Until now, whenever I had had the need to use git, I just sticked to the bare minimum, without diving into it. I’m going to mention only two examples of the cool stuff I found. And I’ll confirm that, in my opinion, the comparison to vi really holds.
  1. commands have lots of options. Tons. And some are incredibly cool, for example git log -S. It allows you to show entries whose diff contains the given string (or pattern, with --pickaxe-regex). I was missing bzr’s log --message, but it was obviously there, as log --grep.
  2. Elijah has another entry that talks about what he dubs the “libmo”, and how it’s different between git and the rest, because of the “index is not automatic” schema. In particular, that entry opened my eyes about one very useful use of the index: putting there parts of an upcoming commit that are known to be correct, and that need no further inspection. Doing that with git add -p makes those parts no longer appear in your git diff, which is... whoa. I like to review before committing a lot. However, with other VCSen I always find myself reviewing/glancing at the same parts over and over. So having a way to review what’s pending or WIP is something to die for. And I know even before getting addicted to it!
4. More about Bzr I’m not sure I want to completely switch from bzr to git, not yet anyway. However, I think I’ll try it for some new projects, or migrate some minor ones. Before I can migrate everything I’ll need a bzr frontend for git-fast-import. One of the bzr authors, Ian Clatworthy, has written bzr-fastimport, and he tells me a simple exporter would not be very hard to write, and that he may even put some work into it. Also, I’m (still?) not very sold with some of the git standard practice of throwing away parts of your history regularly. We’ll see about that. Finally, one feature of bzr I would love to see in git is indented formatting for non-mainline revisions in log output (for git, in --topo-order mode only). This is most needed when you’re not rewriting your history for submission to mainline, I’ll reckon. Compare —date-order to —topo-sort to —topo-sort with —indent. Update: For this —indent thing, one could use tig, which after pressing g offers a sort of tree view in a curses-based interfaces. Somebody had mentioned this on IRC, and Peter Baumann kindly mentioned again over e-mail after reading this entry.

Martin F. Krafft: Mobile phone business opportunities

Since Switzerland s three main cell phone providers (Swisscom, Sunrise, and Orange) are apparently happy to remain stagnant, here are two business opportunities, in case you re fidgety and looking to get rich. The second actually applies to all of Europe, or even the world.

  1. provide a true EDGE flat rate. The three providers all have unlimited data options, but cap their offers at 1.5-2.5 Gb/month, after which you end up paying horrendous amounts for each additional Megabyte. The marketing people are, of course, aware of this unlimited lie, while the casual customer does not have to be since s/he won t generate this amount of traffic.
  2. peer with local providers and come up with a plan that allows me to roam about and use my phone from anywhere in Europe (or the world) for the exact same fees as always. I realise this will be quite difficult because it involves a large number of peering agreements, but think of the potential: I d switch immediately, I d even forego any remaining term I still have on my contract, and I am sure I am not the only one.
Once you hit the black numbers, please hand over a small percentage of your stakes for my ingenious ideas. NP: Gazpacho: Night Update: Gunnar replied with a peek into the situation in Mexiko. Yes, I am spoiled.

4 March 2008

John Goerzen: Git Feature Branches

I'm really liking this.

So I set up some Git feature branches to help get Redmine patches from their BTS into their SVN trunk faster. (I don't know why, but it seems to take a *very* long time for that to happen.)

Each BTS patch gets a Git feature branch. My Git repo for this project has about 21 branches in it.

So, I pull upstream into a branch called, well, upstream.

Each feature branch is created off upstream.

Then, the master branch merges all the feature branches in. I wrote a simple git-merge-fb shell script that just runs git-merge for each feature branch. Very simple. I expect to have a git-pull-fb script of some sort that merges upstream into each feature branch when I update against upstream. It could also run a diff at the end to see if there is any difference remaining, and if not, delete the branch.

It's trivial to give an updated diff to upstream for any given patch: git diff feature-blah..upstream will do it.

I only wish gitweb had a way to do that so I could just hand out a URL that always corresponds to the latest diff against upstream for a given feature. Now that would rock.

Axel Beckert: Is ikiwiki a Website Meta Language killer?

On this year’s Chemitzer Linux-Tage (CLT, engl. “Chemnitz Linux Days’) I attended a few talks of which especially formorer’s ikiwiki talk was very interesting. I attended his talk since I found out that ikiwiki is command line wiki compiler in contrary to the thousands of solely web based wikis out there. As a big fan of statically generated content this idea sounded very interesting to me. But just having a short look at ikiwiki’s web page didn’t help to get started and it seemed as if I had not the right idea of how ikiwiki works to get started. So formorer’s talk seemed to be a good possibility to get an idea of how ikiwiki works without much effort. During the talk I noticed that ikiwiki can many things I do with the Website Meta Language (WML), but can do some more things WML can’t do out of the box:
  1. It’s not only a framework to generate web pages, it’s more like a content management system (CMS).
  2. Versioning is intergal part of ikiwiki without reinventing the wheel: It works out of the box with — beyond others — Subversion, Git and Mercurical (Hg).
And when formorer showed that even Tobi Oetiker uses ikiwiki, I noticed that ikiwiki probably could be a WML killer, since I knew Tobi as a WML fan. And ikiwiki looks very appealing for the WML fan inside me, too… OTOH: Intergrating WML as a backend to ikiwiki could be an interesting idea, though. Hearing what kind of input files ikiwiki can process, I also got the idea of using hnb (Hierachical Notebook) files as input for ikiwiki. hnb files are already XML and so a conversion to XHTML shouldn’t be that hard. But when searching the web for “ikiwiki hnb” I found the blog postings of a few people switching away from hnb, e.g. to vimoutliner. Since I’m an Emacs addict and don’t like vim very much (if I use a vi, I use nvi or elvis), I searched for “emacs hnb” and indeed found someone who switched from hnb to org-mode – of which I never heard before. Unfortunately org-mode doesn’t seem to be in Debian (Update 00:23: Yeah, yeah, I now know it’s included in emacs22, but emacs22 hasn’t made it into kfreebsd-i386 yet, so I didn’t notice. See the comments. :-) but I’ll play around with it a little bit. Unfortunately a first test wasn’t that promising. But we’ll see.

Now playing: Men at Work — Down Under

Benjamin Mako Hill: Comment, No Comment

There are many blogs called No Comment. Most of them allow comments, but not all. Unavailable for Comment is in fact available for comments, although it seems that few have taken advantage of the fact. Most blogs called Comment also allow comments although the blog Daily Comment (which is not daily) does not. The blog Leaveacomment.com does not seem to have the domain leaveacomment.com but allows its visitors to leave comments.

Stefano Zacchiroli: transitioning the caml

Debian testing transitions: OCaml 3.10.1 ... and 3.10.2! The shape of OCaml 3.10.1 in Debian wrt the testing transition is getting better. As you can see from the OCaml status page in Debian we are almost there. This has been the first OCaml transition (almost) entirely done with binNMUs. We requested about 100 binNMUs, with the corresponding dep-waits, and the buildds did the fine exercise. Since binNMUs do not rebuild arch:all packages, some remaining bits had to be uploaded by hand, I've finished that fine exercise last Sunday. In 5 days from now or so the wait time for that bits should be over and OCaml 3.10.1 should happily transition to testing. The binNMUs requests, as well as the dep-waits, have been generated mechanically using a script contributed by Stephane Glondu, exploiting the build-dependencies information we already had. A small bug in the various involved scripts let a missing dep-wait slip through and we had to re-request builds for ocamlnet, but beside that all went fine ... it will go even better next time (now that the bugs has been fixed). ... and speaking about the next time :-), OCaml 3.10.2 has been released a few days ago (what a timing, eh?). Yesterday I've uploaded it to experimental, you can get if from there to test if everything is fine with it. As soon as the current transition is over we can right ahead requests the new binNMUs and hope to have 3.10.2 in Lenny.

Next.

Previous.

