Search Results: "will"

21 November 2012

Antonio Terceiro: Today I am turning 20 ...

in hexadecimal. I have been waiting for a long time to be able to make this joke, and I will still be able to do it for the next 9 years! :-)

Dirk Eddelbuettel: Rcpp attributes: A simple example 'making pi'

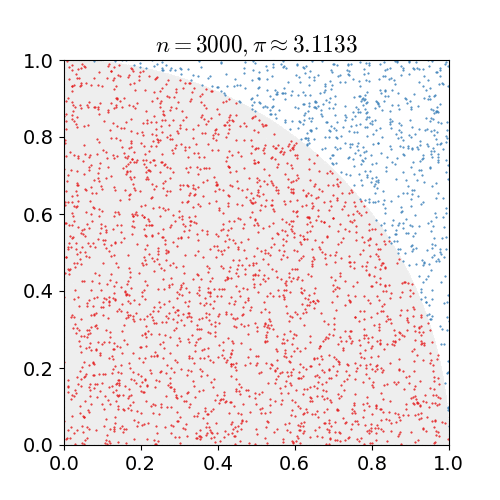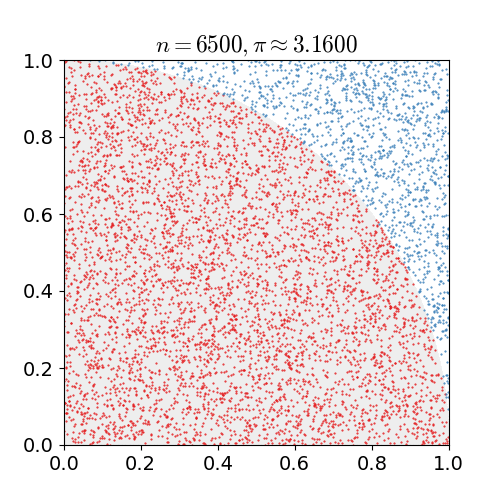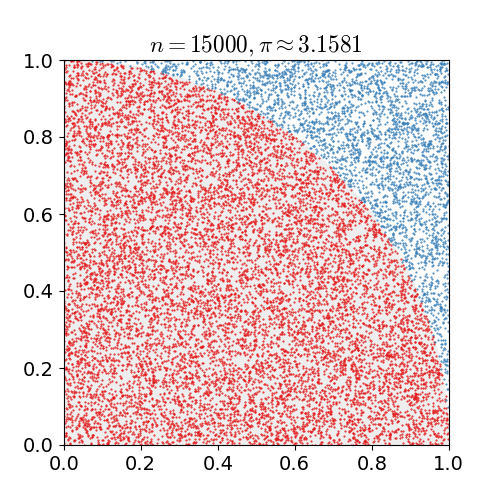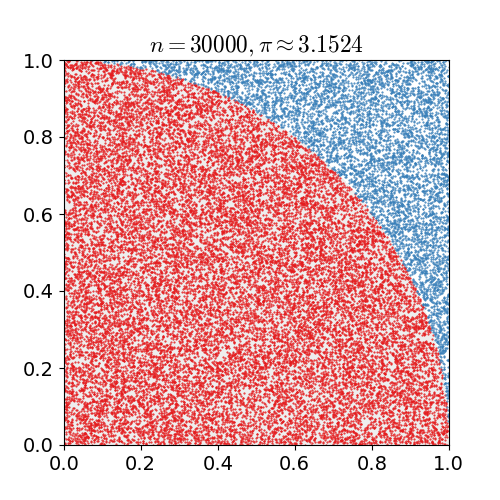
We introduced Rcpp 0.10.0 with a number of very nice new features a few days ago, and the activity on the rcpp-devel mailing list has been pretty responsive which is awesome. But because few things beat a nice example, this post tries to build some more excitement. We will illustrate how Rcpp attributes makes it really easy to add C++ code to R session, and that that code is as easy to grasp as R code. Our motivating example is everybody's favourite introduction to Monte Carlo simulation: estimating . A common method uses the fact the unit circle has a surface area equal to . We draw two uniform random numbers x and y, each between zero and one. We then check for the distance of the corresponding point (x,y) relative to the origin. If less than one (or equal), it is in the circle (or on it); if more than one it is outside. As the first quadrant is a quarter of a square of area one, the area of the whole circle is -- so our first quadrant approximates over four. The following figure, kindly borrowed from Wikipedia with full attribution and credit, illustrates this: Example of simulating pi Now, a vectorized version (drawing N such pairs at once) of this approach is provided by the following R function.
piR <- function(N)  
    x <- runif(N)
    y <- runif(N)
    d <- sqrt(x^2 + y^2)
    return(4 * sum(d < 1.0) / N)
 
And in C++ we can write almost exactly the same function thanks the Rcpp sugar vectorisation available via Rcpp:
#include <Rcpp.h>
using namespace Rcpp;
// [[Rcpp::export]]
double piSugar(const int N)  
    RNGScope scope;		// ensure RNG gets set/reset
    NumericVector x = runif(N);
    NumericVector y = runif(N);
    NumericVector d = sqrt(x*x + y*y);
    return 4.0 * sum(d < 1.0) / N;
 
Sure, there are small differences: C++ is statically typed, R is not. We need one include file for declaration, and we need one instantiation of the RNGScope object to ensure random number draws remain coordinated between the calling R process and the C++ function calling into its (compiled C-code based) random number generators. That way we even get the exact same draws for the same seed. But the basic approach is identical: draw a vector x and vector y, compute the distance to the origin and then obtain the proportion within the unit circle -- which we scale by four. Same idea, same vectorised implementation in C++. But the real key here is the one short line with the [[Rcpp::export]] attribute. This is all it takes (along with sourceCpp() from Rcpp 0.10.0) to get the C++ code into R. The full example (which assumes the C++ file is saved as piSugar.cpp in the same directory) is now:
#!/usr/bin/r
library(Rcpp)
library(rbenchmark)
piR <- function(N)  
    x <- runif(N)
    y <- runif(N)
    d <- sqrt(x^2 + y^2)
    return(4 * sum(d < 1.0) / N)
 
sourceCpp("piSugar.cpp")
N <- 1e6
set.seed(42)
resR <- piR(N)
set.seed(42)
resCpp <- piSugar(N)
## important: check results are identical with RNG seeded
stopifnot(identical(resR, resCpp))
res <- benchmark(piR(N), piSugar(N), order="relative")
print(res[,1:4])
and it does a few things: set up the R function, source the C++ function (and presto: we have a callable C++ function just like that), compute two simulations given the same seed and ensure they are in fact identical -- and proceed to compare the timing in a benchmarking exercise. That last aspect is not even that important -- we end up being almost-but-not-quite twice as fast on my machine for different values of N. The real takeaway here is the ease with which we can get a C++ function into R --- and the new process completely takes care of passing parameters in, results out, and does the compilation, linking and loading. More details about Rcpp attributes are in the new vignette. Now enjoy the .

Update:One somewhat bad typo fixed.

Update:Corrected one background tag.

Axel Beckert: zutils: zcat and friends on Steroids

I recently wrote about tools to handle archives conveniently. If you just have to handle compressed text files, there are some widely known shortcut commands to mimic common commands on files compressed with a specific compression format.
gzip bzip2 lzma xz
cat zcat bzcat lzcat xzcat
cmp zcmp bzcmp lzcmp xzcmp
diff zdiff bzdiff lzdiff xzdiff
grep zgrep bzgrep lzgrep xzgrep
egrep zegrep bzegrep lzegrep xzegrep
fgrep zfgrep bzfgrep lzfgrep xzfgrep
more zmore bzmore lzmore xzmore
less zless bzless lzless xzless
In Debian and derivatives, those tools are part of the according package for that compression utility, i.e. the zcat command is part of the gzip package and the xzfgrep command is part of the xz-utils package. But despite this matrix is quite easy to remember, the situation has a few drawbacks: This is where the zutils project comes in: zutils provides the functionality of most of these utilities, too, but with one big difference: You don t have to remember, think about or type which compression method has been used for your data, just use zcat, zcmp, zdiff, zgrep, zegrep, or zfgrep and it works independently of what compression method has been used if any or if there are different compression types mixed in the parameters to the same command:
$ zfgrep foobar bla.txt fnord.gz hurz.xz quux.lz bar.lzma
Especially if you use logrotate and let logrotate compress old logs, it s very comfortable that one command suffices to concatenate all the available logfiles, including the current uncompressed one:
$ zcat /var/log/syslog*    
Additionally, zutils versions of these tools also support lzip-compressed files. The zutils package is available in Debian starting with Wheezy and in Ubuntu since Oneiric. When being installed, it replaces the original z* utilities from the gzip package by diverting them away. The only drawback so far is that there neither a zless nor a zmore utility from the zutils project, so zless bla.txt fnord.gz hurz.xz quux.lz bar.lzma will not work as expected even after installing zutils as it is still the one from the gzip package and hence it will show you just the first two files in plain text, but not the remaining ones.

20 November 2012

Michal &#268;iha&#345;: Weblate hook at Github

Github now provides native hook for Weblate. This means that all you need to do to link these two together is to enter URL of your Weblate installation and you are done. This was actually my first code in Ruby and I don't think I will start to like it, Python still looks nicer to me :-). However it was not that hard as I expected and I've even contribute (simple) testcase for this service.

Filed under: English Weblate 3 comments Flattr this!

Pablo Lorenzzoni: Decision-making by flipping a coin

Yesterday I was discussing in an online board how to break a decision deadlock in life. There are real deadlocks, but I don t think they are very frequent most of the time, doing a pros and cons analysis is enough to decide what to do. Sometimes our judgement is impaired by lack of objectivity or by our inability to see things from a different point of view (it s hard to think straight when everything seems to be falling apart around you); talking to a friend or relative can help in these situations. But there are times when nothing helps. When you are really stuck and nothing seems to break the deadlock. At these times I give it one or two days, sleep on the issue and if I cannot come up with a decision I assume the alternatives are equivalent to me and just flip a coin. Of course, this will do if you can postpone the decision, giving yourself (and your inner self) time to decide on a course-of-action. But is there some way to speed up the process? During the discussion, someone came up with a rather smart quote by Rothstein character in Boardwalk Empire TV series:
Flip a coin. When it s in the air, you ll know what side you re hoping for.
I found it an interesting way to give your inner self an ultimatum: decide or luck will decide instead. I ve never did it like that, for I would not flip a coin unless it s my last resort. Being such a clever psychological idea, I doubted it originated in the TV series itself, so I went on pursue of the original idea. I found a Danish poet and mathematician called Piet Hein, who wrote a poem about it circa 1969:
A PSYCHOLOGICAL TIP Whenever you re called on to make up your mind,
and you re hampered by not having any,
the best way to solve the dilemma, you ll find,
is simply by spinning a penny.
No not so that chance shall decide the affair
while you re passively standing there moping;
but the moment the penny is up in the air,
you suddenly know what you re hoping.
And also, there are a Donald Duck comic called Flip Decision circa 1953 that introduces Flipism philosophy, which supports a rather radical anecdotal variant: make all decisions by flipping a coin. Piet Hein or Rothstein character idea is much better than Flipism, of course. Does anyone knows any older sources of the same idea?

19 November 2012

Steve Langasek: Pflaumenkuchen

This was a good year for plums in the garden, both for the yellow plums and for the Italian prunes - enough so that it took some doing to figure out what to do with them all. Since I'm not in a hurry to set up a still and make slivovic, and you can only pawn so many plums off on friends and neighbors, I had on the order of 15 pounds of Italian prunes to dispense with. With our change of diet to eliminate extra carbs, Patty and I have both been experimenting with reduced-carb desserts in the kitchen. And I've always been fond of central European (e.g., German) desserts, which tend to be sweetened much more lightly than American equivalents. Indeed, my earliest impression of "coffee cake" comes from the home of an elderly couple who were friends of the family, who served a delicious plum cake in their home. She was from Bavaria, so I guess she probably wouldn't have called it Zwetchgendatschi like the Austrians do (if they even really call it that; I have my suspicions that this is a made-up name designed to poke fun at the foreigners). Maybe she would have called it Pflaumenkuchen. The Internet calls it "Polish plum cake". Whatever you call it, it's tasty, and I aimed to recreate it at home. The plums are now nearly a month gone, but after multiple iterations the cake turned out well enough that I feel compelled to share it with the Internet. Since we have friends who are dairy-intolerant, this particular recipe is tailored to be low-carb and dairy-free. It doesn't lose anything in the taste for being made with a restricted set of ingredients. The original recipe did call for a streusel, and a non-dairy streusel is pretty pointless so this recipe simply omits it. Metric cooks, avert your eyes. ;)
  • 1 c almond flour
  • 1 tsp baking powder
  • tsp salt
  • c Steviva blend
  • 3 tbsp grapeseed oil
  • c milk
  • 1 large egg
  • 12 fresh plums, pitted and halved
  • tsp cloves
Lightly coat an 8"x8" pan with cooking spray. Heat oven to 350 degrees. In medium bowl, combine flour, baking powder, salt and Steviva. Add grapeseed oil, milk and egg. Beat at medium speed 4 minutes. Pour batter into prepared pan. Place plums on top, cut side up, pushing down slightly into batter. Sprinkle cloves over the plums. Bake about 50 minutes or until a toothpick tests clean. Let the cake cool in the pan so the plum juices will be reabsorbed to create a moist cake. Sprinkle with confectioners' sugar, if desired, and cut into 16 squares.
[edit: the Internet is bad at me for my badly spelled german. Spelling corrected. ;)]

Steve Langasek: Pflaumkuchen

This was a good year for plums in the garden, both for the yellow plums and for the Italian prunes - enough so that it took some doing to figure out what to do with them all. Since I'm not in a hurry to set up a still and make slivovic, and you can only pawn so many plums off on friends and neighbors, I had on the order of 15 pounds of Italian prunes to dispense with. With our change of diet to eliminate extra carbs, Patty and I have both been experimenting with reduced-carb desserts in the kitchen. And I've always been fond of central European (e.g., German) desserts, which tend to be sweetened much more lightly than American equivalents. Indeed, my earliest impression of "coffee cake" comes from the home of an elderly couple who were friends of the family, who served a delicious plum cake in their home. She was from Bavaria, so I guess she probably wouldn't have called it Zwetchgendatschi like the Austrians do (if they even really call it that; I have my suspicions that this is a made-up name designed to poke fun at the foreigners). Maybe she would have called it Pflaumkuchen. The Internet calls it "Polish plum cake". Whatever you call it, it's tasty, and I aimed to recreate it at home. The plums are now nearly a month gone, but after multiple iterations the cake turned out well enough that I feel compelled to share it with the Internet. Since we have friends who are dairy-intolerant, this particular recipe is tailored to be low-carb and dairy-free. It doesn't lose anything in the taste for being made with a restricted set of ingredients. The original recipe did call for a streusel, and a non-dairy streusel is pretty pointless so this recipe simply omits it. Metric cooks, avert your eyes. ;)
  • 1 c almond flour
  • 1 tsp baking powder
  • tsp salt
  • c Steviva blend
  • 3 tbsp grapeseed oil
  • c milk
  • 1 large egg
  • 12 fresh plums, pitted and halved
  • tsp cloves
Lightly coat an 8"x8" pan with cooking spray. Heat oven to 350 degrees. In medium bowl, combine flour, baking powder, salt and Steviva. Add grapeseed oil, milk and egg. Beat at medium speed 4 minutes. Pour batter into prepared pan. Place plums on top, cut side up, pushing down slightly into batter. Sprinkle cloves over the plums. Bake about 50 minutes or until a toothpick tests clean. Let the cake cool in the pan so the plum juices will be reabsorbed to create a moist cake. Sprinkle with confectioners' sugar, if desired, and cut into 16 squares.

Vasudev Kamath: Weekly Log - 17/23 - 112012

The last week was quite productive as I was on vacation and at home town but sadly I couldn't complete this post so again merging the work with this week but this week ain't much productive as I was tired from journey back and didn't get enough time to recover. So here it goes. Debian Related Upstream Related I raised a pull request #8 on Gubbi fixing the Makefile to more organized and introducing xz compression in it. Additionally I removed distribution specific stuffs from Makefile and made it generic. That's all for the two weeks. This week there will be foss.in and we will be having some Debian specific mini conference, including some Debian basics to newbies and some bug squashing if any :-). So more to report next week, till then Cya.

Russ Allbery: Review: Inversions

Review: Inversions, by Iain M. Banks
Publisher: Pocket
Copyright: 1998
Printing: May 2001
ISBN: 0-7434-1196-X
Format: Mass market
Pages: 376
Inversions poses a special challenge for book metadata for reviews that try to avoid spoilers. If you've looked at my index of reviews, I may have arguably already spoiled you. I'm going to discuss the book with that spoiler, as most reviews do, because I think it's a better book knowing that information up-front. But if you want to avoid any spoilers, stop reading here, and avoid looking at its placement in my review index. Inversions consists of the interleaved stories of two people: a strange female doctor to the king of Haspide, and the bodyguard of the Protector of Tassassen. The doctor's story is told in the form of letters written by the doctor's apprentice to his "Master," who has clearly told him to spy on the doctor. (The identity of this person is revealed during the story.) The bodyguard's story is told in the third person and presented as a reconstruction of events. The stories never meet, although the two countries have some indirect political exchanges. The doctor becomes entangled in court intrigue and several murders, and the bodyguard protects the Protector (a general in charge of what was effectively a military coup against the former regime) during a war with neighboring barons who had initially supported him. Both stories reach conclusions, but somewhat unsatisfactory ones. The two characters never meet in the book. All of this is set among countries at a medieval level of technology. The doctor faces scorn and derision, not to mention outright opposition, both because she's a woman (she's only permitted to claim the title of doctor due to the king's favor and her claimed citizenship in a far-away land with strange customs) and because she uses more effective and more modern techniques. Other physicians still bleed patients, but the doctor is clearly aware of the germ theory of disease, dismisses contageon via bad odors, and otherwise strikes the reader as someone with advanced medical knowledge trying to practice it in primitive conditions. The spoiler, which is never stated outright but which is relatively apparent from various hints and allusions dropped by the characters, as well as at least one event that would otherwise have to be supernatural, is that Inversions actually takes place in the Culture milieu. How this planet and these stories fit into that milieu remains unexplained throughout the story, but we do get some clues in supposedly made-up stories that the bodyguard tells the son of the Protector, stories that are recognizable to Culture readers as less fictional than they sound in a medieval context. Banks has a tendency to play with unusual narrative structure and to fall on the mainstream side of SF plot construction. Inversions is a very closely-observed pair of entwined stories told in a way that downplays most of the dramatic structure and rising action and that undermines feelings of conclusion or catharsis. Despite having, on later reflection, two clear plots with clear conclusions, it feels more like parallel slices of life and stubbornly refuses to advertise any conclusions or deeper meaning. Whether that works will probably have a lot to do with the reader's tolerance for trying to draw one's own conclusions. I found it frustrating and unsatisfying, but knowing going in that it's a Culture novel helped by adding some deeper structure to give the story a modicum of meaning. Insofar as there's a larger theme, it's the exploration of the conflict between the two Culture citizens that is presented, thinly disguised, in the bodyguard's stories. This connection is not obvious; even determining how to map the two characters into the stories is a touch challenging. But if one is aware of it and looking for it in advance, it provides a bit of broader structure and some basis for judging the actions of the doctor and the bodyguard against a larger plan. I needed that to wring enjoyment from the book; I never cared enough about the characters otherwise to fully engage with either story. With the puzzle, and the constant search for connections to Culture concepts, it's somewhat more interesting, but it's still maddeningly indirect. (And, from various other Internet reactions, I don't think I'm missing something obvious.) It's possible that I went into the book with some incorrect assumptions that undermined my enjoyment. Hopefully this review will help other readers. Knowing that this is a Culture book and enjoying the process of finding references makes it more fun (and most of the references aren't too hard to find). But don't expect lots of closure from the stories, and don't expend to find out "what's really going on." It's not that sort of book. If you enjoy the individual stories for themselves, you'll have the best chance of enjoying the book as a whole, with the Culture references providing a fun additional layer. If the basic stories don't appeal, the Culture material probably isn't enough to make the book engrossing. Rating: 6 out of 10

18 November 2012

Sven Mueller: Ingress

As some may have noticed, Google launched something that is unusual for the company: A game. A mobile alternate reality game, to be precise. See allthingsd article for a bit more information. In my opinion this game is most interesting to people who are mildly interested in geo-caching. You spend most of the gaming time either looking for the right portals (geo-location that is an interesting place for one reason or another, many located at sculptures, murals or (more scarcely) interesting local businesses), or trying to solve the puzzles that appear in the game itself or on http://www.nianticproject.com/. I was one of the beta testers and really enjoy the game, especially in areas with more players. As the game is most fun when people coordinate a bit, I started a google group for the munich area for one of the two teams (the enlightenment), but I will only let people enter that group who can be verified to be on that team. On a side note: I still have a few invites to the game left, so if you are interested, please leave a comment and enter your gmail.com email address (you need a Google account to play anyway) while doing so. I will send out invites in the order I received the requests (which I admit might not always be the same in which they were submitted. First come first serve and no guarantee to get an invitation though. Your email address you enter when commenting isn t shown to anyone and I don t share them with anyone but the game (and thus Google). EDIT: So short time went past, but I already ran out of invites (note that I didn t approve comments that really only were like please send me an invite , but still did sent one out). Feel free to still ask me for an invite, I will send some out as I get new ones, but this might take anything between a few days and some weeks. PS: For the lucky ones who got invites: You don t strictly need to do the training offered when you start the game for the first time, but I strongly encourage you to do so.
PPS: I m opening my group to any enlightened players in Germany. I will share some useful information about some game details there in the near future (nothing company confidential of course, just information anyone can gather in the game or from the published information). EDIT: As noted before, I don t have any more invites to give away. As I still get like 4 requests for invites per day, and now have more than 30 unfulfilled requests pending (with no new invites to give in sight), I m now disabling comments. Disclaimer: I work for Google since a few months ago, but this post solely represents my own opinions and hasn t been endorsed by Google in any way.

Russ Allbery: Powell's anniversary haul

Powell's was holding an anniversary sale and giving out free gift cards with a qualifying order, so it seemed like a good idea to pick up a few books. Ben Aaronovitch Midnight Riot (sff)
Patricia Briggs Alpha & Omega (sff)
Patricia Briggs Moon Called (sff)
Mark Forster Get Everything Done (non-fiction)
Lynn Galli Wasted Heart (romance)
Sam Harris Lying (non-fiction)
K.E. Lane And Playing the Role of Herself (romance)
Jack McDevitt Firebird (sff)
Marshall Rosenberg Nonviolent Communication (non-fiction)
Deborah Tannen The Argument Culture (non-fiction)
Bill Willingham, et al. Fables: Animal Farm (graphic novel) I'm not sure if the Forster will be worth the cost, but I've really liked his other writing about time management, so I thought I'd take a chance on it. I think the Tannen and the Rosenberg are on roughly the same topic, but I arrived at them through different recommendation paths. I've been feeling like reading about how to communicate lately. The McDevitt novel is the latest in the Alex Benedict series. I'm only a couple of books away from being caught up. I've gotten lots of positive recommendations for Aaronovitch's series, so thought I'd get the first one. There's also a variety of random stuff, mostly on the Kindle, that I'd not added to one of these posts, noted here mostly for my own records. Alpha & Omega is a novella rather than a novel, which I grabbed because I picked up and read Cry Wolf during vacation.

Neil Williams: Long term maintenance of perl cross-build support in Debian

After prompts from Wookey and Steve McIntyre, I decided to look at #285559 and #633884 for perl cross-build support and then port that support forward to the current perl in Wheezy and on to the version of perl currently in experimental. The first patch is for perl 5.8, the second for perl 5.12, neither of which is available currently in Debian. snapshot.debian.org provided the 5.12 source but then that no longer cross-builds with the patch.

The problem, as with any cross build, is that the build must avoid trying to execute binaries compiled within the build to achieve the test results required by ./configure (or in the case of perl, Configure). dpkg-cross has one collection of cache values but the intention was always to migrate the package-specific support data into the packages themselves and keep the architecture-specific data in dpkg-cross or dpkg-dev. Therefore, the approach taken in #633884 would be correct, if only there was a way of ensuring that the cached values remain in sync with the relevant Debian package.

I'll note here that I am aware of other ways of cross-building perl, this is particularly concerned with cross-building the Debian configuration of perl as a Debian package and using Debian or Emdebian cross-compilers. After all, the objective is to support bootstrapping Debian onto new architectures. However, I fully expect this to be just as usable with Ubuntu packages of perl compiled with, e.g. Linaro cross-compilers but I haven't yet looked at the differences between perl in Debian vs Ubuntu in any detail.

I've just got perl 5.14.2 cross-building for armel using the Emdebian gcc-4.4 cross-compiler (4.4.5-8) on a Debian sid amd64 machine without errors (it needs testing, which I'll look at later), so now is the time to document how it is done and what needs to be fixed. I've already discussed part of this with the current perl maintainers in Debian and, subject to just how the update mechanism works, have outline approval for pushing these changes into the Debian package and working with upstream where appropriate. The cache data itself might live in a separate source package which will use a strict dependency on perl to ensure that it remains in sync with the version which it can cross-build. Alternatively, if I can correctly partition the cache data between architecture-specific (and therefore generated from the existing files) and package_$version specific, then it may be possible to push a much smaller patch into the Debian perl package. This would start with some common data, calculate the arch-specific data and then look for some version-specific data, gleaned from Debian porter boxes whilst the version is in Debian experimental.

The key point is that I've offered to provide this support for the long term, ensuring that we don't end up with future stable releases of Debian having a perl package which cannot be cross-built. (To achieve that, we will also end up with versions of perl in Debian testing which also cross-build.)

This cross-build is still using dpkg-cross paths, not MultiArch paths, and this will need to be changed eventually. (e.g. by the source package providing two binaries, one which uses MultiArch and one which expects dpkg-cross paths.) The changes include patches for the upstream Makefile.SH, debian/rules and the cache data itself. Depending on where the cache data finally lives, the new support might or might not use the upstream Cross/ directory as the current contents date from the Zaurus support and don't appear to be that useful for current versions of perl.

The cache data itself has several problems:

  1. It is tightly tied to the version of perl which generated it.

  2. It is, as expected, architecture-dependent

  3. It is, unfortunately, very sensitive to the specific configuration used by the distribution itself


That last point is important because it means that the cache data is not useful upstream as a block. It also means that generating the cache data for a specific Debian package means running the generation code on the native architecture with all of the Debian build-dependencies installed for the full perl build. This is going to complicate the use of this method for new architectures like arm64.

My objective for the long term maintenance of this code is to create sufficient data that a new architecture can be bootstrapped by judicious use of some form of template. Quite how that works out, only time will tell. I expect that this will involve isolating the data which is truly architecture-specific which doesn't change between perl versions from the data which is related to the tests for build-dependencies which does change between perl versions and then work out how to deal with any remainder. A new architecture for a specific perl version should then just be a case of populating the arch-specific data such as the size of a pointer/char and the format specifiers for long long etc. alongside the existing (and correct) data for the current version of perl.

Generating the cache data natively

The perl build repeats twice (three builds in total) and each build provides and requires slightly different cache data - static, debug and shared. Therefore, the maintenance code will need to provide a script which can run the correct configuration step for each mode, copy out the cache data for each one and clean up. The script will need to run inside a buildd chroot on a porter box (I'm looking at using abel.debian.org and harris.debian.org for this work so far) so that the derived data matches what the corresponding Debian native build would use. The data then needs slight modification - typically to replace the absolute paths with PERL_BUILD_DIR. It may also be necessary to change the value of cc, ranlib and other compiler-related values to the relevant cross-compiler executables. That should be possible to arrange within the build of the cache data support package itself, allowing new cache files to be dropped in directly from the porter box.

The configuration step may need to be optimised within debian/rules of perl itself as it currently proceeds on from the bare configuration to do some actual building but I need to compare the data to see if a bare config is modified later. The test step can be omitted already. Each step is performed as:

DEB_BUILD_OPTIONS="nocheck" fakeroot debian/rules perl.static


That is repeated for perl.debug and libperl.so.$(VERSION) where $VERSION comes from :

/bin/bash debian/config.debian --full-version


The files to be copied out are:


There is a lot of scope for templating of some form here, e.g. config.h.debug is 4,686 lines long but only 41 of those lines differ between amd64 and armhf for the same version of perl (and some of those can be identified from existing architecture-specific constants) which should make for a much smaller patch.

Architecture-specific cache data for perl

So far, the existing patches only deal with armel and armhf. If I compare the differences between armel & armhf, it comes down to:

  1. compiler names (config.h.*)

  2. architecture names (config.sh.*)

  3. architecture-based paths (config.sh.*)


However, comparing armel and armhf doesn't provide sufficient info for deriving arm64 or mips etc. Comparing the same versions for armhf and amd64 shows the range of differences more clearly. Typical architecture differences exist like the size of a long, flags to denote if the compiler can cast negative floats to 32bit ints and the sprintf format specifier strings for handling floats and doubles. The data also includes some less expected ones like:

armhf: #define Netdb_host_t const void * /**/
amd64: #define Netdb_host_t char * /**/


I'm not at all sure why that is arch-specific - if anyone knows, email codehelp @ d.o - same address if anyone fancies helping out ....

Cross-builds and debclean

When playing with the cross-build, remember to use the cross-build clean support, not just debclean:


dpkg-architecture -aarmel -c fakeroot debian/rules clean


That wasted quite a bit of my time initially with having to blow away the entire tree, unpack it from original apt sources and repatch it. (Once Wheezy is out, may actually investigate getting debclean to support the -a switch).

OK, that's an introduction, I'm planning on pushing the cross-build support code onto github soon-ish and doing some testing of the cross-built perl binaries in a chroot on an armel box. I'll detail that in another blog post when it's available.

Next step is to look at perl 5.16 and then current perl upstream git to see how to get Makefile.SH fixed for the long term.

Jamie McClelland: New Privacy Arguments are Needed

Another decent article on online privacy was published by the NYT this morning. The article documents the collection and centralized aggregation of consumer data online. It ends with a strong message about consumers becoming the "product" - which echoes what Noam Chomsky and Ben Bagdikian have been saying for decades. The problem with this critique is that it doesn't go far enough. Chomsky and Bagdikian didn't say readers are the product of modern journalism and that's bad because nobody wants to be a product. They critiqued the model because it produces terrible journalism and democracy suffers as a result. Similarly, the online trading of audiences and the invasion of our privacy that results has more important implications than "don't be a sucker" which seems to be the gist of the privacy argument these days. Honestly, I don't stay awake at night worrying that Nike knows I'm looking for a pair of sneakers, or even that they know my income. I do stay awake at night worrying that people are tagging my photo on Facebook, which could allow the New York Police Dept to submit a photo of protesters to Facebook and get a list of names and addresses of the people in the photo. Or it could allow the police to track my movements via existing networks of surveillance cameras by matching my image to my name. Would that require a search warrant? How would that impact my trust in my government to know that my movements are being tracked? Or worse, to know they might be tracked but I'll never know if they are or aren't? Many governments (including the US) have sordid histories of infiltrating political organizations and intentionally sowing dissent. Having access to activists' purchasing habits provides a treasure trove of material for this purpose that previously was labor intensive for cops to collect. It also provides leverage during interrogation, a time of heightened emotional vulnerability where the mere mention of a private detail of one's life can have a powerful impact. How can we prevent law enforcement from having access to these details of our lives? And then there's the dragnet. A central database of consumer habits provides a tantalizing collection of information that could be searched for people who fit a profile of a crime. Is solving the crime at hand worth the invasion of privacy that results from people being investigating only based on their consumer habits? How would we measure the impact an investigation like this would have on our confidence in democracy and government? The corporate advertisers promoting this kind of data collection argue that these problems are the price of progress. However, the ideology behind these technology developments is capitalism, not some intrinsic aspect of the Internet or network communications. Historically, the Internet has developed based on a drive toward de-centralization. Email and web sites, the bedrock of Internet activity, are based on these principles: anyone can add their own email server or web server and everyone can seamlessly access it. In contrast, the logic of capitalism as it relates to the Internet, is one of centralization and aggregating data. Facebook and Google want you to use their platforms for all your online activities so they have as complete a picture as possible of what you like and do. As the New York Times article describes, companies like Rubicon want to track all your movements and aggregate that data for profit. We have a choice. We can carefully evaluate our use of corporate services and consider the implications it has not only on our lives but on society as a whole. And, we can choose to use and support services that promote open standards and interoperability that will respect our personal privacy values. Want a practical example? Friendica is software designed to allow you to post status alerts, photos, videos and other information about yourself in a way similar to Facebook. However, it has one big difference: you can host your account on any server running the software anywhere in the world. You can still "friend" people on different servers, but we don't have to all trust the same organization to host it. Furthermore, Friendica allows you to post once and automatically cross-post to your Twitter, Facebook or other similar services. Sound good? You are welcome to try out an account on the May First/People Link install: https://friends.mayfirst.org/.

Michal &#268;iha&#345;: Roadmap for Weblate 1.4

As Weblate 1.3 is out, it's time to think about features for next release. My current plan is to go more into two areas. First is improving support for machine translations. I have some ideas how to integrate these in interesting ways, I just hope my (poor) Javascript knowledge will not prevent me doing it that way. The second area is improving testsuite. Right now it really does not cover much and I'd like to cover at least basic functionality with different file formats. I'll see how much I will be able to cover, but at least I will try to cover as much as possible :-).

Filed under: English Weblate 0 comments Flattr this!

Russ Allbery: Review: A Hero's Tale

Review: A Hero's Tale, by Catherine M. Wilson
Series: Women Were Warriors #3
Publisher: Shield Maiden
Copyright: 2008
ISBN: 0-9815636-3-5
Format: Kindle
Pages: 301

This is an ebook, so metadata may be inaccurate or missing. See notes on ebooks for more information. A Hero's Tale is the third book in the When Women Were Warriors trilogy, which is best thought of as a single long novel. Reading it independently will miss most of the significance of the plot, since one wouldn't know many of the important characters. A Hero's Tale follows the pattern of the second book: even less quiet contemplation, and even more in the way of events and plot. Tamras completes her training, in a somewhat unexpected way (and in a rather interesting reworking of gender roles), but then both Maara's past and the problems of A Journey of the Heart catch up with them. There is, accordingly, quite a bit more action, or at least war councils and political maneuvering, than the previous books, and somewhat less time for thoughtful wisdom. That also means that A Hero's Tale shifts a bit more towards the traditional fantasy coming-of-age story, where the heroine is able to shift armies and win conflicts with an understated and self-deprecating skill that comes inevitably but indirectly out of all of her previous experiences. I think Wilson is still fairly original in how she presents those tropes, with an interesting focus on empathy and compassion that is all too rare in this sort of story, but this book does feel a lot more like a story that one has read before. If you're particularly allergic to that story shape, you may find this entry somewhat disappointing. One of the things I loved about it, though, was Wilson's avoidance of traditional villains. There is one, so it's not a complete avoidance, but nearly everyone in this story has their own viewpoint and perspective and is on the side of right in their own way. Wilson uses Tamras's empathy and willingness to listen and understand to let the reader see various different perspectives without moving away from the first-person perspective. It's very nicely done. I thought the handling of the emotional arc of the story was more mixed. Tamras is seriously tested in some moments that aimed for heartbreaking, but I thought they fell short of the emotional punch they were supposed to carry since the story shape had already made it obvious that everything would turn out okay in the end. The story is so gentle that Wilson hadn't established any willingness to end something badly, which robs a lot of the punch from emotional turmoil. I also had quite a bit of trouble with the principle of love above all else, particularly for someone in Tamras's position. Maybe that's because I'm still too entrenched in the attitude towards politics that this series argues against, but I had a hard time not seeing her as personally indulgent. Both of those factors blunted the emotional climax for me, leaving it moving but not as heartbreaking as I think Wilson was aiming for. (This is the point where a friend will tell me that I think too much about books while I'm reading them.) That said, Wilson continues to write one of the best mentoring relationships that I've seen in fiction. The dynamic between Tamras and Maara is just beautiful, and remains so through the end of the book. So many traditional issues with rivalry, growth, replacement of the mentor, and relative social position that are ignored or dealt with ham-handedly in other stories are handled adeptly and quietly. Maara is by far my favorite character of this series, largely because of how she handles that relationship. I could identify with her more easily than with Tamras at various points in the story, and I thought the understated ending was quietly beautiful. If you enjoyed the rest of the series, definitely read A Hero's Tale for the conclusion. If you've been hungry for more typical action, you'll get some of it here. I wish a few deep emotions other than love had been in play, but, despite that, When Women Were Warriors is still quietly and delightfully different than most things I've read, and worth the price. Rating: 8 out of 10

17 November 2012

Antoine Beaupr : First stable release of the Drupal OpenID Provider

A short announcement to mark the release of the first stable OpenID provider for Drupal. Started by James Walker around 4 years ago, I have since then got commit access and taken care of the module for the last 2 years. And while it was not an easy task, with the help of the community, this module was able to mature to a fully featured, flexible and standard implementation during that time. One has to wonder however, is it too late for OpenID?

A bit of history Drupal was one of the pioneers in OpenID support. Back in 2006 when the protocol was still in its infancy (less than a year old!), Drupal was adding OpenID support to its 4.7 release through a contrib module and two years later, the Drupal 6.0 release was sporting OpenID in core, although not without significant interoperability issues. Still, we could say that rapid adoption by such a popular CMS as Drupal really boosted OpenID's adoption. At about the same time, Yahoo, Sourceforge, Myspace, Microsoft and Google would all join the OpenID bandwagon. On the OpenID "provider" side of things, things were not so great however. Back when I started experimenting with this, it wasn't actually that easy to host your own OpenID provider, to allow your users to login to other OpenID-enabled sites. While there are a lot of different libraries to provide OpenID support in your application there was not (and still isn't) any software that gives you an OpenID provider and is dedicated to that. No official reference implementation either, other than the code from the one of the founding companies of OpenID, JanRain. There was an OpenID provider module in Drupal, but there was no official release done until a two beta releases in 2010.

Koumbit's community involvement It is about that time I started getting involved in the project. Koumbit needed an easy way for our workers to log into multiple sites without too much trouble, so I started looking at OpenID provider implementations. The lack of dedicated software somehow made the Drupal implementation a natural fit, and I started experimenting with the module, filing bugs and reviewing patches, as there were a lot of interoperability and design issues with the provider. After a while, walkah was kind enough to give me full access to the project and I started doing regular releases (every few months), culminating in today's official 1.0 release for both Drupal 6 and Drupal 7, which I am very proud and happy about. While I am here, I want to send many thanks to the people behind the Drupal 7 port: paranojik, mikecar, xamanu and testing from neizod. A lot of issues were also patched, reviewed and tested by numerous contributors that are unfortunately difficult to track down other than reading the commit log. So we at Koumbit have been running our own OpenID provider for a good while now, and it has the key advantage of being connected to our LDAP directory (with the D6 LDAP integration module so it is, in a sense, a central point for authentication at Koumbit. Very often people don't clearly understand what their LDAP password does, and I can easily remind them "it's the OpenID thing", or "try your password in the OpenID site" if they think they have forgotten it. So much goes on in the web browser these days that it makes everything much easier.

The problem with Drupal's OpenID provider However, it is kind of embarrassing that it took so long. More than 6 years after the OpenID protocol was written, we have a stable OpenID provider. Now, this may be because I am overly conservative about stable releases, but I don't think so: the OpenID provider module had, for a long time, serious interoperability issues with OpenID sites. There was also a clear lack of features on the OpenID provider, a gap that various third party modules, now documented on the OpenID provider homepage are now trying to fill. There is also serious security issues with the protocol itself. The complexity and lack of clarity of the OpenID specification have rendered my work quite difficult at time, as the protocol has significant ambiguities and no clear reference implementation. OpenID is unfortunately renowned to be vulnerable to phishing and while Koumbit's use of the HTTPS protocol alleviates some of those issues (especially the redirect session hijack), tools like sslstrip can bypass those protections easily. The privacy aspect is also problematic, as the user is usually not free to choose which information from his or her profile is divulged to the site they are logging into. Of course those issues may be overlooked if the security trade off is not worth it. In the case of Koumbit, we use OpenID on a lot of client sites, but usually nothing critical, and we train our users to pay attention to the HTTPS icon when login in their OpenID account.

Are there alternatives? But unfortuantely, the reality is that there are not really any alternatives to OpenID out there. Mozilla's new BrowserID initiative (now rebranded Persona, boy those guys sure love rebranding..) is interesting, but actually has even more flaws than OpenID itself. Not only is it not resolving the phishing problem, it actually creates new problems, including my personal favorite, trusting server-side Javascript code, which OpenID is not using that much. I should also mention the Shibboleth module which has a surprising number of installs recorded on Drupal.org, but that depends on the much more complicated Shibboleth federation, for which there is no server implementation for Drupal, from what I understand. Oauth, on the other end, is even more widely used, and has server-side components like Oauth Login Provider and Services 3.x. We could also simply give up and use our souls stored at Facebook, Google and Twitter for authentication everywhere. Maybe OpenID opened the door for those corporations to see that there is a real opportunity in leveraging user's profile to track their online activity. It is not something that OpenID was necessarily designed for but it's an idea that certainly permeates Facebook connect and "like" buttons or Twitter and Google online business strategies, where you are the product sold to advertisers. I personally believe we should keep the struggle for distributed and standard identity mechanisms for the web that respect users' privacy. With Drupal's OpenID Provider, it is possible to create a secure, privacy-aware identity provider, although I still have to perform that damn security audit. Experiments with those third party modules should also be encouraged and I welcome any feedback on those modules. While I do not plan to attend OpenID conferences or do significant development on the OpenID provider right now, I will certainly make sure Koumbit keeps its commitment to maintaining stewardship on the OpenID provider module in Drupal. I encourage people to try it out, submit issues and patches to make it even better. Long life to OpenID! PS: if people are interested in funding that security audit, I would be happy to perform this through my regular work at Koumbit.org, just file a request at services@koumbit.org.

Raphael Geissert: Better routing, less bad apples

Another month, another update to http.debian.net. This time around most of the work was done outside the redirector's code base, as strange as it may sound.

The redirector heavily relies on the mirrors doing at least a couple of things right, for the rest it can and does compensate. When it needs to compensate, certain requests are redirected to automatically-detected good mirrors, thus avoiding mirrors that might work fine for some parts of the day but cause headaches during the rest.

So, part of the work done since the last update was to prod more mirror administrators to upgrade to the latest version of ftpsync. This reduces the number of mirrors for which compensation is needed in order to avoid errors during installations and upgrades. Hopefully, no additional work is needed for the redirector to notice the upgrades. This results in immediate improvements.

However, not all mirrors comply with the bare minimum requirements. As stated in my previous blog post, running rsync once is not enough. When mirrors break these assumptions they lead to the "bad apple" effect. The effects in this case are temporary errors, as experienced by some people. The interesting part of those issues is that the affected population may quickly change given the redirector's use of geo location and the way it creates mirror subsets.

As interesting as the distribution of the effects may be, they are not really welcome. So I put together some code to attempt to detect the bad apples. This resulted in a list of mirrors that have now been disabled in the redirector and whose administrators are going to be contacted so that they comply with the minimum requirements. Given that detection is time-sensitive, there's no 100% guarantee that all of them have been identified so far. The code to detect them will have to be adapted and integrated into the redirector's code base to be proactive on avoiding this kind of issues.

Last but not least, the redirector is now using a database of AS peers for better (re-)routing. This is the next move towards a decision making based more on network location/topology than in geographic location. This first use of a peers database is limited to IPv4 and is based on a recent routing table dump and on feedback provided by interested people. If you are a mirror or network administrator, or you are familiar with the topology of your network please drop me an email so that the redirector can make a better use of your peering agreements.

N.b. in the case of the database, the term peer may also include transit providers. It is used to refer to and establish a relationship between two AS(N)s.


Feedback is, as always, welcome. I read each and every email but it may take me some time to get to it, or reply.

Sylvestre Ledru: Mini Debconf & merchandising

Next week end, November 24th and 25th, the mini Debconf will take place at EPITA in Paris. Mehdi Dogguy and I worked hard on the organization and on building a great program for this 2012 conference. This mini debconf will cover many subjects like Gnome (both as upstream and downstream), the Release team, how the Linux is packaged in Debian, etc.
The keynote will be "Free software and Debian, 20 years after" by Roberto Di Cosmo. Also, some merchandising will be proposed during the event by the association Debian France. Here is a quick list: Polos
long-sleeved polo
Long-sleeved polo

40 euros - 10 pieces Sleeveless polo
Sleeveless polo

25 euros - 100 pieces Thanks to Tanguy Ortolo for taking take of the order. Buff
Buff Debian
Buff Debian

18 euros - 75 pieces. It is described as Original Multifunctional Headwear. Real life example in video.
I love them! Finally, we will sell two kinds of Debian branded Sticker Portable:
Sticker Debian
Sticker Debian

1 euro - 100 pieces. They can be also ordered on the it2l website. Thanks to J r me Lemaire for providing these great products. If these products are successful, we will probably produce more for FOSDEM! For more information about the conference:
The official website
Wiki page for subscription

Michal &#268;iha&#345;: phpMyAdmin documentation now in Spanish

Since converting the phpMyAdmin documentation to new format and updating it's content, I was quite frightened how this will affect translated versions of it. Fortunately giving it more attractive format and more advertisement lead to increased contributions. Since Friday, we already have one language which has reached 100% - Spanish. Mat as Bellone simply did there awesome job and went through all fuzzy and new strings in just few days. Now I'm looking forward to other contributors as well, I hope we will be able to deliver translated manual for phpMyAdmin 4.0 in many languages. I'll definitely try to translate to Czech, but any help with that is welcome.

Filed under: English Phpmyadmin 2 comments Flattr this!

Petter Reinholdtsen: Why isn't the value of copyright taxed?

While working on a Norwegian translation of the Free Culture by Lawrence Lessig (76% done), which cover the problems with todays copyright law and how it stifles creativity, one idea occurred to me. The idea is to get the tax office to help make more works enter the public domain and also help make it easier to clear rights for using copyrighted works. I mentioned this idea briefly during Yesterdays presentation by John Perry Barlow, and concluded that it was best to put it in writing for a wider audience. The idea is not really based on the argument that copyrighted works are "intellectual property", as the core requirement is that copyrighted work have value for the copyright holder and the tax office like to collect their share from any value controlled by the citizens in a country. I'm sharing the idea here to let others consider it and perhaps shoot it down with a fresh set of arguments. Most valuables are taxed by the government. At least here in Norway, the amount of money you have, the value of our land property, the value of your house, the value of your car, the value of our stocks and other valuables are all added together. If the tax value of these values exceed your debt, you have to pay the tax office some taxes for these values. And copyrighted work have value. It have value for the rights holder, who can earn money selling access to the work. But it is not included in the tax calculations? Why not? If the government want to tax copyrighted works, it would want to maintain a database of all the copyrighted works and who are the rights holders for a given works, to be able to associate the works value to the right citizen or company for tax purposes. If such database exist, it will become a lot easier to find out who to talk to for clearing permissions to use a copyrighted work, which is a very hard operation with todays copyright law. To ensure that copyright holders keep the database up-to-date, it would have to become a requirement to be able to collect money for granting access to copyrighted works that the work is listed in the database with the correct right holder. If copyright causes copyright holders to have to pay more taxes, they will have a small incentive to "disown" their copyright, and let the work enter the public domain. For works with several right holders one of the right holders could state (and get it registered in the database) that she do not need to be consulted when clearing rights to use the work in question and thus will not get any income from that work. Stating this would have to be impossible to revert and stop the tax office from adding the value of that work to the given citizens tax calculation. I assume the copyright law would stay the same, allowing creators to pick a license of their choosing, and also allowing them to put their work directly in the public domain. The existence of such database will make it even easier to clear rights, and if the right holders listed in the database is taxed, this system would increase the amount of works that enter the public domain. The effect would be that the tax office help to make it easier to get rights to use the works that have not yet entered the public domain and help to get more work into the public domain and . Why have such taxing not happened yet? I am sure the tax office would like to tax copyrighted work values if they could.

Next.

Previous.
