Search Results: "reg"

4 March 2024

Colin Watson: Free software activity in January/February 2024

Two months into my new gig and it s going great! Tracking my time has taken a bit of getting used to, but having something that amounts to a queryable database of everything I ve done has also allowed some helpful introspection. Freexian sponsors up to 20% of my time on Debian tasks of my choice. In fact I ve been spending the bulk of my time on debusine which is itself intended to accelerate work on Debian, but more details on that later. While I contribute to Freexian s summaries now, I ve also decided to start writing monthly posts about my free software activity as many others do, to get into some more detail. January 2024 February 2024

3 March 2024

Petter Reinholdtsen: RAID status from LSI Megaraid controllers using free software

The last few days I have revisited RAID setup using the LSI Megaraid controller. These are a family of controllers called PERC by Dell, and is present in several old PowerEdge servers, and I recently got my hands on one of these. I had forgotten how to handle this RAID controller in Debian, so I had to take a peek in the Debian wiki page "Linux and Hardware RAID: an administrator's summary" to remember what kind of software is available to configure and monitor the disks and controller. I prefer Free Software alternatives to proprietary tools, as the later tend to fall into disarray once the manufacturer loose interest, and often do not work with newer Linux Distributions. Sadly there is no free software tool to configure the RAID setup, only to monitor it. RAID can provide improved reliability and resilience in a storage solution, but only if it is being regularly checked and any broken disks are being replaced in time. I thus want to ensure some automatic monitoring is available. In the discovery process, I came across a old free software tool to monitor PERC2, PERC3, PERC4 and PERC5 controllers, which to my surprise is not present in debian. To help change that I created a request for packaging of the megactl package, and tried to track down a usable version. The original project site is on Sourceforge, but as far as I can tell that project has been dead for more than 15 years. I managed to find a more recent fork on github from user hmage, but it is unclear to me if this is still being maintained. It has not seen much improvements since 2016. A more up to date edition is a git fork from the original github fork by user namiltd, and this newer fork seem a lot more promising. The owner of this github repository has replied to change proposals within hours, and had already added some improvements and support for more hardware. Sadly he is reluctant to commit to maintaining the tool and stated in my first pull request that he think a new release should be made based on the git repository owned by hmage. I perfectly understand this reluctance, as I feel the same about maintaining yet another package in Debian when I barely have time to take care of the ones I already maintain, but do not really have high hopes that hmage will have time to spend on it and hope namiltd will change his mind. In any case, I created a draft package based on the namiltd edition and put it under the debian group on salsa.debian.org. If you own a Dell PowerEdge server with one of the PERC controllers, or any other RAID controller using the megaraid or megaraid_sas Linux kernel modules, you might want to check it out. If enough people are interested, perhaps the package will make it into the Debian archive. There are two tools provided, megactl for the megaraid Linux kernel module, and megasasctl for the megaraid_sas Linux kernel module. The simple output from the command on one of my machines look like this (yes, I know some of the disks have problems. :).
# megasasctl 
a0       PERC H730 Mini           encl:1 ldrv:2  batt:good
a0d0       558GiB RAID 1   1x2  optimal
a0d1      3067GiB RAID 0   1x11 optimal
a0e32s0     558GiB  a0d0  online   errs: media:0  other:19
a0e32s1     279GiB  a0d1  online  
a0e32s2     279GiB  a0d1  online  
a0e32s3     279GiB  a0d1  online  
a0e32s4     279GiB  a0d1  online  
a0e32s5     279GiB  a0d1  online  
a0e32s6     279GiB  a0d1  online  
a0e32s8     558GiB  a0d0  online   errs: media:0  other:17
a0e32s9     279GiB  a0d1  online  
a0e32s10    279GiB  a0d1  online  
a0e32s11    279GiB  a0d1  online  
a0e32s12    279GiB  a0d1  online  
a0e32s13    279GiB  a0d1  online  
#
In addition to displaying a simple status report, it can also test individual drives and print the various event logs. Perhaps you too find it useful? In the packaging process I provided some patches upstream to improve installation and ensure a Appstream metainfo file is provided to list all supported HW, to allow isenkram to propose the package on all servers with a relevant PCI card. As usual, if you use Bitcoin and want to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

Dirk Eddelbuettel: RcppArmadillo 0.12.8.1.0 on CRAN: Upstream Fix, Interface Polish

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1130 other packages on CRAN, downloaded 32.8 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 578 times according to Google Scholar. This release brings a new upstream bugfix release Armadillo 12.8.1 prepared by Conrad yesterday. It was delayed for a few hours as CRAN noticed an error in one package which we all concluded was spurious as it could be reproduced outside of the one run there. Following from the previous release, we also use the slighty faster Lighter header in the examples. And once it got to CRAN I also updated the Debian package. The set of changes since the last CRAN release follows.

Changes in RcppArmadillo version 0.12.8.1.0 (2024-03-02)
  • Upgraded to Armadillo release 12.8.1 (Cortisol Injector)
    • Workaround in norm() for yet another bug in macOS accelerate framework
  • Update README for RcppArmadillo usage counts
  • Update examples to use '#include <RcppArmadillo/Lighter>' for faster compilation excluding unused Rcpp features

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Ben Hutchings: FOSS activity in February 2024

29 February 2024

Russell Coker: Links February 2024

In 2018 Charles Stross wrote an insightful blog post Dude You Broke the Future [1]. It covers AI in both fiction and fact and corporations (the real AIs) and the horrifying things they can do right now. LongNow has an interesting article about the concept of the Magnum Opus [2]. As an aside I ve been working on SE Linux for 22 years. Cory Doctorow wrote an insightful article about the incentives for enshittification of the Internet and how economic issues and regulations shape that [3]. CCC has a lot of great talks, and this talk from the latest CCC about the Triangulation talk on an attak on Kaspersky iPhones is particularly epic [4]. GoodCar is an online sales site for electric cars in Australia [5]. Ulrike wrote an insightful blog post about how the reliance on volunteer work in the FOSS community hurts diversity [6]. Cory Doctorow wrote an insightful article about The Internet s Original Sin which is misuse of copyright law [7]. He advocates for using copyright strictly for it s intended purpose and creating other laws for privacy, labor rights, etc. David Brin wrote an interesting article on neoteny and sexual selection in humans [8]. 37C3 has an interesting lecture about software licensing for a circular economy which includes environmental savings from better code [9]. Now they track efficiency in KDE bug reports!

28 February 2024

Dirk Eddelbuettel: RcppEigen 0.3.4.0.0 on CRAN: New Upstream, At Last

We are thrilled to share that RcppEigen has now upgraded to Eigen release 3.4.0! The new release 0.3.4.0.0 arrived on CRAN earlier today, and has been shipped to Debian as well. Eigen is a C++ template library for linear algebra: matrices, vectors, numerical solvers, and related algorithms. This update has been in the works for a full two and a half years! It all started with a PR #102 by Yixuan bringing the package-local changes for R integration forward to usptream release 3.4.0. We opened issue #103 to steer possible changes from reverse-dependency checking through. Lo and behold, this just stalled because a few substantial changes were needed and not coming. But after a long wait, and like a bolt out of a perfectly blue sky, Andrew revived it in January with a reverse depends run of his own along with a set of PRs. That was the push that was needed, and I steered it along with a number of reverse dependency checks, and occassional emails to maintainers. We managed to bring it down to only three packages having a hickup, and all three had received PRs thanks to Andrew and even merged them. So the plan became to release today following a final fourteen day window. And CRAN was convinced by our arguments that we followed due process. So there it is! Big big thanks to all who helped it along, especially Yixuan and Andrew but also Mikael who updated another patch set he had prepared for the previous release series. The complete NEWS file entry follows.

Changes in RcppEigen version 0.3.4.0.0 (2024-02-28)
  • The Eigen version has been upgrade to release 3.4.0 (Yixuan)
  • Extensive reverse-dependency checks ensure only three out of over 400 packages at CRAN are affected; PRs and patches helped other packages
  • The long-running branch also contains substantial contributions from Mikael Jagan (for the lme4 interface) and Andrew Johnson (revdep PRs)

Courtesy of CRANberries, there is also a diffstat report for the most recent release. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

26 February 2024

Freexian Collaborators: Long term support for Samba 4.17

Freexian is pleased to announce a partnership with Catalyst to extend the security support of Samba 4.17, which is the version packaged in Debian 12 Bookworm. Samba 4.17 will reach upstream s end-of-support this upcoming March (2024), and the goal of this partnership is to extend it until June 2028 (i.e. the end of Debian 12 s regular security support). One of the main aspects of this project is that it will also include support for Samba as Active Directory Domain Controller (AD-DC). Unfortunately, support for Samba as AD-DC in Debian 11 Bullseye, Debian 10 Buster and older releases has been discontinued before the end of the life cycle of those Debian releases. So we really expect to improve the situation of Samba in Debian 12 Bookworm, ensuring full support during the 5 years of regular security support. We would like to mention that this is an experiment, and we will do our best to make it a success, and to try to continue it for Samba versions included in future Debian releases. Our long term goal is to bring confidence to Samba s upstream development community that they can mark some releases as being supported for 5 years (or more) and that the corresponding work will be funded by companies that benefit from this work (because we would have already built that community). If your company relies on Samba and wants to help sustain LTS versions of Samba, please reach out to us. For companies using Debian, the simplest way is to subscribe to our Debian LTS offer at a gold level (or above) and let us know that you want to contribute to Samba LTS when you send your subscription form. For others, please reach out to us at sales@freexian.com and we will figure out a way to contribute. In the mean time, this project has been possible thanks to the current LTS sponsors and ELTS customers. We hope the whole community of Debian and Samba users will benefit from it. For any question, don t hesitate to contact us.

25 February 2024

Russ Allbery: Review: The Fund

Review: The Fund, by Rob Copeland
Publisher: St. Martin's Press
Copyright: 2023
ISBN: 1-250-27694-2
Format: Kindle
Pages: 310
I first became aware of Ray Dalio when either he or his publisher plastered advertisements for The Principles all over the San Francisco 4th and King Caltrain station. If I recall correctly, there were also constant radio commercials; it was a whole thing in 2017. My brain is very good at tuning out advertisements, so my only thought at the time was "some business guy wrote a self-help book." I think I vaguely assumed he was a CEO of some traditional business, since that's usually who writes heavily marketed books like this. I did not connect him with hedge funds or Bridgewater, which I have a bad habit of confusing with Blackwater. The Principles turns out to be more of a laundered cult manual than a self-help book. And therein lies a story. Rob Copeland is currently with The New York Times, but for many years he was the hedge fund reporter for The Wall Street Journal. He covered, among other things, Bridgewater Associates, the enormous hedge fund founded by Ray Dalio. The Fund is a biography of Ray Dalio and a history of Bridgewater from its founding as a vehicle for Dalio's advising business until 2022 when Dalio, after multiple false starts and title shuffles, finally retired from running the company. (Maybe. Based on the history recounted here, it wouldn't surprise me if he was back at the helm by the time you read this.) It is one of the wildest, creepiest, and most abusive business histories that I have ever read. It's probably worth mentioning, as Copeland does explicitly, that Ray Dalio and Bridgewater hate this book and claim it's a pack of lies. Copeland includes some of their denials (and many non-denials that sound as good as confirmations to me) in footnotes that I found increasingly amusing.
A lawyer for Dalio said he "treated all employees equally, giving people at all levels the same respect and extending them the same perks."
Uh-huh. Anyway, I personally know nothing about Bridgewater other than what I learned here and the occasional mention in Matt Levine's newsletter (which is where I got the recommendation for this book). I have no independent information whether anything Copeland describes here is true, but Copeland provides the typical extensive list of notes and sourcing one expects in a book like this, and Levine's comments indicated it's generally consistent with Bridgewater's industry reputation. I think this book is true, but since the clear implication is that the world's largest hedge fund was primarily a deranged cult whose employees mostly spied on and rated each other rather than doing any real investment work, I also have questions, not all of which Copeland answers to my satisfaction. But more on that later. The center of this book are the Principles. These were an ever-changing list of rules and maxims for how people should conduct themselves within Bridgewater. Per Copeland, although Dalio later published a book by that name, the version of the Principles that made it into the book was sanitized and significantly edited down from the version used inside the company. Dalio was constantly adding new ones and sometimes changing them, but the common theme was radical, confrontational "honesty": never being silent about problems, confronting people directly about anything that they did wrong, and telling people all of their faults so that they could "know themselves better." If this sounds like textbook abusive behavior, you have the right idea. This part Dalio admits to openly, describing Bridgewater as a firm that isn't for everyone but that achieves great results because of this culture. But the uncomfortably confrontational vibes are only the tip of the iceberg of dysfunction. Here are just a few of the ways this played out according to Copeland: In one of the common and all-too-disturbing connections between Wall Street finance and the United States' dysfunctional government, James Comey (yes, that James Comey) ran internal security for Bridgewater for three years, meaning that he was the one who pulled evidence from surveillance cameras for Dalio to use to confront employees during his trials. In case the cult vibes weren't strong enough already, Bridgewater developed its own idiosyncratic language worthy of Scientology. The trials were called "probings," firing someone was called "sorting" them, and rating them was called "dotting," among many other Bridgewater-specific terms. Needless to say, no one ever probed Dalio himself. You will also be completely unsurprised to learn that Copeland documents instances of sexual harassment and discrimination at Bridgewater, including some by Dalio himself, although that seems to be a relatively small part of the overall dysfunction. Dalio was happy to publicly humiliate anyone regardless of gender. If you're like me, at this point you're probably wondering how Bridgewater continued operating for so long in this environment. (Per Copeland, since Dalio's retirement in 2022, Bridgewater has drastically reduced the cult-like behaviors, deleted its archive of probings, and de-emphasized the Principles.) It was not actually a religious cult; it was a hedge fund that has to provide investment services to huge, sophisticated clients, and by all accounts it's a very successful one. Why did this bizarre nightmare of a workplace not interfere with Bridgewater's business? This, I think, is the weakest part of this book. Copeland makes a few gestures at answering this question, but none of them are very satisfying. First, it's clear from Copeland's account that almost none of the employees of Bridgewater had any control over Bridgewater's investments. Nearly everyone was working on other parts of the business (sales, investor relations) or on cult-related obsessions. Investment decisions (largely incorporated into algorithms) were made by a tiny core of people and often by Dalio himself. Bridgewater also appears to not trade frequently, unlike some other hedge funds, meaning that they probably stay clear of the more labor-intensive high-frequency parts of the business. Second, Bridgewater took off as a hedge fund just before the hedge fund boom in the 1990s. It transformed from Dalio's personal consulting business and investment newsletter to a hedge fund in 1990 (with an earlier investment from the World Bank in 1987), and the 1990s were a very good decade for hedge funds. Bridgewater, in part due to Dalio's connections and effective marketing via his newsletter, became one of the largest hedge funds in the world, which gave it a sort of institutional momentum. No one was questioned for putting money into Bridgewater even in years when it did poorly compared to its rivals. Third, Dalio used the tried and true method of getting free publicity from the financial press: constantly predict an upcoming downturn, and aggressively take credit whenever you were right. From nearly the start of his career, Dalio predicted economic downturns year after year. Bridgewater did very well in the 2000 to 2003 downturn, and again during the 2008 financial crisis. Dalio aggressively takes credit for predicting both of those downturns and positioning Bridgewater correctly going into them. This is correct; what he avoids mentioning is that he also predicted downturns in every other year, the majority of which never happened. These points together create a bit of an answer, but they don't feel like the whole picture and Copeland doesn't connect the pieces. It seems possible that Dalio may simply be good at investing; he reads obsessively and clearly enjoys thinking about markets, and being an abusive cult leader doesn't take up all of his time. It's also true that to some extent hedge funds are semi-free money machines, in that once you have a sufficient quantity of money and political connections you gain access to investment opportunities and mechanisms that are very likely to make money and that the typical investor simply cannot access. Dalio is clearly good at making personal connections, and invested a lot of effort into forming close ties with tricky clients such as pools of Chinese money. Perhaps the most compelling explanation isn't mentioned directly in this book but instead comes from Matt Levine. Bridgewater touts its algorithmic trading over humans making individual trades, and there is some reason to believe that consistently applying an algorithm without regard to human emotion is a solid trading strategy in at least some investment areas. Levine has asked in his newsletter, tongue firmly in cheek, whether the bizarre cult-like behavior and constant infighting is a strategy to distract all the humans and keep them from messing with the algorithm and thus making bad decisions. Copeland leaves this question unsettled. Instead, one comes away from this book with a clear vision of the most dysfunctional workplace I have ever heard of, and an endless litany of bizarre events each more astonishing than the last. If you like watching train wrecks, this is the book for you. The only drawback is that, unlike other entries in this genre such as Bad Blood or Billion Dollar Loser, Bridgewater is a wildly successful company, so you don't get the schadenfreude of seeing a house of cards collapse. You do, however, get a helpful mental model to apply to the next person who tries to talk to you about "radical honesty" and "idea meritocracy." The flaw in this book is that the existence of an organization like Bridgewater is pointing to systematic flaws in how our society works, which Copeland is largely uninterested in interrogating. "How could this have happened?" is a rather large question to leave unanswered. The sheer outrageousness of Dalio's behavior also gets a bit tiring by the end of the book, when you've seen the patterns and are hearing about the fourth variation. But this is still an astonishing book, and a worthy entry in the genre of capitalism disasters. Rating: 7 out of 10

Jacob Adams: AAC and Debian

Currently, in a default installation of Debian with the GNOME desktop, Bluetooth headphones that require the AAC codec1 cannot be used. As the Debian wiki outlines, using the AAC codec over Bluetooth, while technically supported by PipeWire, is explicitly disabled in Debian at this time. This is because the fdk-aac library needed to enable this support is currently in the non-free component of the repository, meaning that PipeWire, which is in the main component, cannot depend on it.

How to Fix it Yourself If what you, like me, need is simply for Bluetooth Audio to work with AAC in Debian s default desktop environment2, then you ll need to rebuild the pipewire package to include the AAC codec. While the current version in Debian main has been built with AAC deliberately disabled, it is trivial to enable if you can install a version of the fdk-aac library. I preface this with the usual caveats when it comes to patent and licensing controversies. I am not a lawyer, building this package and/or using it could get you into legal trouble. These instructions have only been tested on an up-to-date copy of Debian 12.
  1. Install pipewire s build dependencies
    sudo apt install build-essential devscripts
    sudo apt build-dep pipewire
    
  2. Install libfdk-aac-dev
    sudo apt install libfdk-aac-dev
    
    If the above doesn t work you ll likely need to enable non-free and try again
    sudo sed -i 's/main/main non-free/g' /etc/apt/sources.list
    sudo apt update
    
    Alternatively, if you wish to ensure you are maximally license-compliant and patent un-infringing3, you can instead build fdk-aac-free which includes only those components of AAC that are known to be patent-free3. This is what should eventually end up in Debian to resolve this problem (see below).
    sudo apt install git-buildpackage
    mkdir fdk-aac-source
    cd fdk-aac-source
    git clone https://salsa.debian.org/multimedia-team/fdk-aac
    cd fdk-aac
    gbp buildpackage
    sudo dpkg -i ../libfdk-aac2_*deb ../libfdk-aac-dev_*deb
    
  3. Get the pipewire source code
    mkdir pipewire-source
    cd pipewire-source
    apt source pipewire
    
    This will create a bunch of files within the pipewire-source directory, but you ll only need the pipewire-<version> folder, this contains all the files you ll need to build the package, with all the debian-specific patches already applied. Note that you don t want to run the apt source command as root, as it will then create files that your regular user cannot edit.
  4. Fix the dependencies and build options To fix up the build scripts to use the fdk-aac library, you need to save the following as pipewire-source/aac.patch
    --- debian/control.orig
    +++ debian/control
    @@ -40,8 +40,8 @@
                 modemmanager-dev,
                 pkg-config,
                 python3-docutils,
    -               systemd [linux-any]
    -Build-Conflicts: libfdk-aac-dev
    +               systemd [linux-any],
    +               libfdk-aac-dev
     Standards-Version: 4.6.2
     Vcs-Browser: https://salsa.debian.org/utopia-team/pipewire
     Vcs-Git: https://salsa.debian.org/utopia-team/pipewire.git
    --- debian/rules.orig
    +++ debian/rules
    @@ -37,7 +37,7 @@
     		-Dauto_features=enabled \
     		-Davahi=enabled \
     		-Dbluez5-backend-native-mm=enabled \
    -		-Dbluez5-codec-aac=disabled \
    +		-Dbluez5-codec-aac=enabled \
     		-Dbluez5-codec-aptx=enabled \
     		-Dbluez5-codec-lc3=enabled \
     		-Dbluez5-codec-lc3plus=disabled \
    
    Then you ll need to run patch from within the pipewire-<version> folder created by apt source:
    patch -p0 < ../aac.patch
    
  5. Build pipewire
    cd pipewire-*
    debuild
    
    Note that you will likely see an error from debsign at the end of this process, this is harmless, you simply don t have a GPG key set up to sign your newly-built package4. Packages don t need to be signed to be installed, and debsign uses a somewhat non-standard signing process that dpkg does not check anyway.
  1. Install libspa-0.2-bluetooth
    sudo dpkg -i libspa-0.2-bluetooth_*.deb
    
  2. Restart PipeWire and/or Reboot
    sudo reboot
    
    Theoretically there s a set of services to restart here that would get pipewire to pick up the new library, probably just pipewire itself. But it s just as easy to restart and ensure everything is using the correct library.

Why This is a slightly unusual situation, as the fdk-aac library is licensed under what even the GNU project acknowledges is a free software license. However, this license explicitly informs the user that they need to acquire a patent license to use this software5:
3. NO PATENT LICENSE NO EXPRESS OR IMPLIED LICENSES TO ANY PATENT CLAIMS, including without limitation the patents of Fraunhofer, ARE GRANTED BY THIS SOFTWARE LICENSE. Fraunhofer provides no warranty of patent non-infringement with respect to this software. You may use this FDK AAC Codec software or modifications thereto only for purposes that are authorized by appropriate patent licenses.
To quote the GNU project:
Because of this, and because the license author is a known patent aggressor, we encourage you to be careful about using or redistributing software under this license: you should first consider whether the licensor might aim to lure you into patent infringement.
AAC is covered by a number of patents, which expire at some point in the 2030s6. As such the current version of the library is potentially legally dubious to ship with any other software, as it could be considered patent-infringing3.

Fedora s solution Since 2017, Fedora has included a modified version of the library as fdk-aac-free, see the announcement and the bugzilla bug requesting review. This version of the library includes only the AAC LC profile, which is believed to be entirely patent-free3. Based on this, there is an open bug report in Debian requesting that the fdk-aac package be moved to the main component and that the pipwire package be updated to build against it.

The Debian NEW queue To resolve these bugs, a version of fdk-aac-free has been uploaded to Debian by Jeremy Bicha. However, to make it into Debian proper, it must first pass through the ftpmaster s NEW queue. The current version of fdk-aac-free has been in the NEW queue since July 2023. Based on conversations in some of the bugs above, it s been there since at least 20227. I hope this helps anyone stuck with AAC to get their hardware working for them while we wait for the package to eventually make it through the NEW queue. Discuss on Hacker News
  1. Such as, for example, any Apple AirPods, which only support AAC AFAICT.
  2. Which, as of Debian 12 is GNOME 3 under Wayland with PipeWire.
  3. I m not a lawyer, I don t know what kinds of infringement might or might not be possible here, do your own research, etc. 2 3 4
  4. And if you DO have a key setup with debsign you almost certainly don t need these instructions.
  5. This was originally phrased as explicitly does not grant any patent rights. It was pointed out on Hacker News that this is not exactly what it says, as it also includes a specific note that you ll need to acquire your own patent license. I ve now quoted the relevant section of the license for clarity.
  6. Wikipedia claims the base patents expire in 2031, with the extensions expiring in 2038, but its source for these claims is some guy s spreadsheet in a forum. The same discussion also brings up Wikipedia s claim and casts some doubt on it, so I m not entirely sure what s correct here, but I didn t feel like doing a patent deep-dive today. If someone can provide a clear answer that would be much appreciated.
  7. According to Jeremy B cha: https://bugs.debian.org/cgi-bin/bugreport.cgi?bug=1021370#17

21 February 2024

Niels Thykier: Expanding on the Language Server (LSP) support for debian/control

I have spent some more time on improving my language server for debian/control. Today, I managed to provide the following features:
  • The X- style prefixes for field names are now understood and handled. This means the language server now considers XC-Package-Type the same as Package-Type.

  • More diagnostics:

    • Fields without values now trigger an error marker
    • Duplicated fields now trigger an error marker
    • Fields used in the wrong paragraph now trigger an error marker
    • Typos in field names or values now trigger a warning marker. For field names, X- style prefixes are stripped before typo detection is done.
    • The value of the Section field is now validated against a dataset of known sections and trigger a warning marker if not known.
  • The "on-save trim end of line whitespace" now works. I had a logic bug in the server side code that made it submit "no change" edits to the editor.

  • The language server now provides "hover" documentation for field names. There is a small screenshot of this below. Sadly, emacs does not support markdown or, if it does, it does not announce the support for markdown. For now, all the documentation is always in markdown format and the language server will tag it as either markdown or plaintext depending on the announced support.

  • The language server now provides quick fixes for some of the more trivial problems such as deprecated fields or typos of fields and values.

  • Added more known fields including the XS-Autobuild field for non-free packages along with a link to the relevant devref section in its hover doc.

This covers basically all my known omissions from last update except spellchecking of the Description field. An image of emacs showing documentation for the Provides field from the language server.
Spellchecking Personally, I feel spellchecking would be a very welcome addition to the current feature set. However, reviewing my options, it seems that most of the spellchecking python libraries out there are not packaged for Debian, or at least not other the name I assumed they would be. The alternative is to pipe the spellchecking to another program like aspell list. I did not test this fully, but aspell list does seem to do some input buffering that I cannot easily default (at least not in the shell). Though, either way, the logic for this will not be trivial and aspell list does not seem to include the corrections either. So best case, you would get typo markers but no suggestions for what you should have typed. Not ideal. Additionally, I am also concerned with the performance for this feature. For d/control, it will be a trivial matter in practice. However, I would be reusing this for d/changelog which is 99% free text with plenty of room for typos. For a regular linter, some slowness is acceptable as it is basically a batch tool. However, for a language server, this potentially translates into latency for your edits and that gets annoying. While it is definitely on my long term todo list, I am a bit afraid that it can easily become a time sink. Admittedly, this does annoy me, because I wanted to cross off at least one of Otto's requested features soon.
On wrap-and-sort support The other obvious request from Otto would be to automate wrap-and-sort formatting. Here, the problem is that "we" in Debian do not agree on the one true formatting of debian/control. In fact, I am fairly certain we do not even agree on whether we should all use wrap-and-sort. This implies we need a style configuration. However, if we have a style configuration per person, then you get style "ping-pong" for packages where the co-maintainers do not all have the same style configuration. Additionally, it is very likely that you are a member of multiple packaging teams or groups that all have their own unique style. Ergo, only having a personal config file is doomed to fail. The only "sane" option here that I can think of is to have or support "per package" style configuration. Something that would be committed to git, so the tooling would automatically pick up the configuration. Obviously, that is not fun for large packaging teams where you have to maintain one file per package if you want a consistent style across all packages. But it beats "style ping-pong" any day of the week. Note that I am perfectly open to having a personal configuration file as a fallback for when the "per package" configuration file is absent. The second problem is the question of which format to use and what to name this file. Since file formats and naming has never been controversial at all, this will obviously be the easy part of this problem. But the file should be parsable by both wrap-and-sort and the language server, so you get the same result regardless of which tool you use. If we do not ensure this, then we still have the style ping-pong problem as people use different tools. This also seems like time sink with no end. So, what next then...?
What next? On the language server front, I will have a look at its support for providing semantic hints to the editors that might be used for syntax highlighting. While I think most common Debian editors have built syntax highlighting already, I would like this language server to stand on its own. I would like us to be in a situation where we do not have implement yet another editor extension for Debian packaging files. At least not for editors that support the LSP spec. On a different front, I have an idea for how we go about relationship related substvars. It is not directly related to this language server, except I got triggered by the language server "missing" a diagnostic for reminding people to add the magic Depends: $ misc:Depends [, $ shlibs:Depends ] boilerplate. The magic boilerplate that you have to write even though we really should just fix this at a tooling level instead. Energy permitting, I will formulate a proposal for that and send it to debian-devel. Beyond that, I think I might start adding support for another file. I also need to wrap up my python-debian branch, so I can get the position support into the Debian soon, which would remove one papercut for using this language server. Finally, it might be interesting to see if I can extract a "batch-linter" version of the diagnostics and related quickfix features. If nothing else, the "linter" variant would enable many of you to get a "mini-Lintian" without having to do a package build first.

20 February 2024

Niels Thykier: Language Server (LSP) support for debian/control

About a month ago, Otto Kek l inen asked for editor extensions for debian related files on the debian-devel mailing list. In that thread, I concluded that what we were missing was a "Language Server" (LSP) for our packaging files. Last week, I started a prototype for such a LSP for the debian/control file as a starting point based on the pygls library. The initial prototype worked and I could do very basic diagnostics plus completion suggestion for field names.
Current features I got 4 basic features implemented, though I have only been able to test two of them in emacs.
  • Diagnostics or linting of basic issues.
  • Completion suggestions for all known field names that I could think of and values for some fields.
  • Folding ranges (untested). This feature enables the editor to "fold" multiple lines. It is often used with multi-line comments and that is the feature currently supported.
  • On save, trim trailing whitespace at the end of lines (untested). Might not be registered correctly on the server end.
Despite its very limited feature set, I feel editing debian/control in emacs is now a much more pleasant experience. Coming back to the features that Otto requested, the above covers a grand total of zero. Sorry, Otto. It is not you, it is me.
Completion suggestions For completion, all known fields are completed. Place the cursor at the start of the line or in a partially written out field name and trigger the completion in your editor. In my case, I can type R-R-R and trigger the completion and the editor will automatically replace it with Rules-Requires-Root as the only applicable match. Your milage may vary since I delegate most of the filtering to the editor, meaning the editor has the final say about whether your input matches anything. The only filtering done on the server side is that the server prunes out fields already used in the paragraph, so you are not presented with the option to repeat an already used field, which would be an error. Admittedly, not an error the language server detects at the moment, but other tools will. When completing field, if the field only has one non-default value such as Essential which can be either no (the default, but you should not use it) or yes, then the completion suggestion will complete the field along with its value. This is mostly only applicable for "yes/no" fields such as Essential and Protected. But it does also trigger for Package-Type at the moment. As for completing values, here the language server can complete the value for simple fields such as "yes/no" fields, Multi-Arch, Package-Type and Priority. I intend to add support for Section as well - maybe also Architecture.
Diagnostics On the diagnostic front, I have added multiple diagnostics:
  • An error marker for syntax errors.
  • An error marker for missing a mandatory field like Package or Architecture. This also includes Standards-Version, which is admittedly mandatory by policy rather than tooling falling part.
  • An error marker for adding Multi-Arch: same to an Architecture: all package.
  • Error marker for providing an unknown value to a field with a set of known values. As an example, writing foo in Multi-Arch would trigger this one.
  • Warning marker for using deprecated fields such as DM-Upload-Allowed, or when setting a field to its default value for fields like Essential. The latter rule only applies to selected fields and notably Multi-Arch: no does not trigger a warning.
  • Info level marker if a field like Priority duplicates the value of the Source paragraph.
Notable omission at this time:
  • No errors are raised if a field does not have a value.
  • No errors are raised if a field is duplicated inside a paragraph.
  • No errors are used if a field is used in the wrong paragraph.
  • No spellchecking of the Description field.
  • No understanding that Foo and X[CBS]-Foo are related. As an example, XC-Package-Type is completely ignored despite being the old name for Package-Type.
  • Quick fixes to solve these problems... :)
Trying it out If you want to try, it is sadly a bit more involved due to things not being uploaded or merged yet. Also, be advised that I will regularly rebase my git branches as I revise the code. The setup:
  • Build and install the deb of the main branch of pygls from https://salsa.debian.org/debian/pygls The package is in NEW and hopefully this step will soon just be a regular apt install.
  • Build and install the deb of the rts-locatable branch of my python-debian fork from https://salsa.debian.org/nthykier/python-debian There is a draft MR of it as well on the main repo.
  • Build and install the deb of the lsp-support branch of debputy from https://salsa.debian.org/debian/debputy
  • Configure your editor to run debputy lsp debian/control as the language server for debian/control. This is depends on your editor. I figured out how to do it for emacs (see below). I also found a guide for neovim at https://neovim.io/doc/user/lsp. Note that debputy can be run from any directory here. The debian/control is a reference to the file format and not a concrete file in this case.
Obviously, the setup should get easier over time. The first three bullet points should eventually get resolved by merges and upload meaning you end up with an apt install command instead of them. For the editor part, I would obviously love it if we can add snippets for editors to make the automatically pick up the language server when the relevant file is installed.
Using the debputy LSP in emacs The guide I found so far relies on eglot. The guide below assumes you have the elpa-dpkg-dev-el package installed for the debian-control-mode. Though it should be a trivially matter to replace debian-control-mode with a different mode if you use a different mode for your debian/control file. In your emacs init file (such as ~/.emacs or ~/.emacs.d/init.el), you add the follow blob.
(with-eval-after-load 'eglot
    (add-to-list 'eglot-server-programs
        '(debian-control-mode . ("debputy" "lsp" "debian/control"))))
Once you open the debian/control file in emacs, you can type M-x eglot to activate the language server. Not sure why that manual step is needed and if someone knows how to automate it such that eglot activates automatically on opening debian/control, please let me know. For testing completions, I often have to manually activate them (with C-M-i or M-x complete-symbol). Though, it is a bit unclear to me whether this is an emacs setting that I have not toggled or something I need to do on the language server side.
From here As next steps, I will probably look into fixing some of the "known missing" items under diagnostics. The quick fix would be a considerable improvement to assisting users. In the not so distant future, I will probably start to look at supporting other files such as debian/changelog or look into supporting configuration, so I can cover formatting features like wrap-and-sort. I am also very much open to how we can provide integrations for this feature into editors by default. I will probably create a separate binary package for specifically this feature that pulls all relevant dependencies that would be able to provide editor integrations as well.

19 February 2024

Matthew Garrett: Debugging an odd inability to stream video

We have a cabin out in the forest, and when I say "out in the forest" I mean "in a national forest subject to regulation by the US Forest Service" which means there's an extremely thick book describing the things we're allowed to do and (somewhat longer) not allowed to do. It's also down in the bottom of a valley surrounded by tall trees (the whole "forest" bit). There used to be AT&T copper but all that infrastructure burned down in a big fire back in 2021 and AT&T no longer supply new copper links, and Starlink isn't viable because of the whole "bottom of a valley surrounded by tall trees" thing along with regulations that prohibit us from putting up a big pole with a dish on top. Thankfully there's LTE towers nearby, so I'm simply using cellular data. Unfortunately my provider rate limits connections to video streaming services in order to push them down to roughly SD resolution. The easy workaround is just to VPN back to somewhere else, which in my case is just a Wireguard link back to San Francisco.

This worked perfectly for most things, but some streaming services simply wouldn't work at all. Attempting to load the video would just spin forever. Running tcpdump at the local end of the VPN endpoint showed a connection being established, some packets being exchanged, and then nothing. The remote service appeared to just stop sending packets. Tcpdumping the remote end of the VPN showed the same thing. It wasn't until I looked at the traffic on the VPN endpoint's external interface that things began to become clear.

This probably needs some background. Most network infrastructure has a maximum allowable packet size, which is referred to as the Maximum Transmission Unit or MTU. For ethernet this defaults to 1500 bytes, and these days most links are able to handle packets of at least this size, so it's pretty typical to just assume that you'll be able to send a 1500 byte packet. But what's important to remember is that that doesn't mean you have 1500 bytes of packet payload - that 1500 bytes includes whatever protocol level headers are on there. For TCP/IP you're typically looking at spending around 40 bytes on the headers, leaving somewhere around 1460 bytes of usable payload. And if you're using a VPN, things get annoying. In this case the original packet becomes the payload of a new packet, which means it needs another set of TCP (or UDP) and IP headers, and probably also some VPN header. This still all needs to fit inside the MTU of the link the VPN packet is being sent over, so if the MTU of that is 1500, the effective MTU of the VPN interface has to be lower. For Wireguard, this works out to an effective MTU of 1420 bytes. That means simply sending a 1500 byte packet over a Wireguard (or any other VPN) link won't work - adding the additional headers gives you a total packet size of over 1500 bytes, and that won't fit into the underlying link's MTU of 1500.

And yet, things work. But how? Faced with a packet that's too big to fit into a link, there are two choices - break the packet up into multiple smaller packets ("fragmentation") or tell whoever's sending the packet to send smaller packets. Fragmentation seems like the obvious answer, so I'd encourage you to read Valerie Aurora's article on how fragmentation is more complicated than you think. tl;dr - if you can avoid fragmentation then you're going to have a better life. You can explicitly indicate that you don't want your packets to be fragmented by setting the Don't Fragment bit in your IP header, and then when your packet hits a link where your packet exceeds the link MTU it'll send back a packet telling the remote that it's too big, what the actual MTU is, and the remote will resend a smaller packet. This avoids all the hassle of handling fragments in exchange for the cost of a retransmit the first time the MTU is exceeded. It also typically works these days, which wasn't always the case - people had a nasty habit of dropping the ICMP packets telling the remote that the packet was too big, which broke everything.

What I saw when I tcpdumped on the remote VPN endpoint's external interface was that the connection was getting established, and then a 1500 byte packet would arrive (this is kind of the behaviour you'd expect for video - the connection handshaking involves a bunch of relatively small packets, and then once you start sending the video stream itself you start sending packets that are as large as possible in order to minimise overhead). This 1500 byte packet wouldn't fit down the Wireguard link, so the endpoint sent back an ICMP packet to the remote telling it to send smaller packets. The remote should then have sent a new, smaller packet - instead, about a second after sending the first 1500 byte packet, it sent that same 1500 byte packet. This is consistent with it ignoring the ICMP notification and just behaving as if the packet had been dropped.

All the services that were failing were failing in identical ways, and all were using Fastly as their CDN. I complained about this on social media and then somehow ended up in contact with the engineering team responsible for this sort of thing - I sent them a packet dump of the failure, they were able to reproduce it, and it got fixed. Hurray!

(Between me identifying the problem and it getting fixed I was able to work around it. The TCP header includes a Maximum Segment Size (MSS) field, which indicates the maximum size of the payload for this connection. iptables allows you to rewrite this, so on the VPN endpoint I simply rewrote the MSS to be small enough that the packets would fit inside the Wireguard MTU. This isn't a complete fix since it's done at the TCP level rather than the IP level - so any large UDP packets would still end up breaking)

I've no idea what the underlying issue was, and at the client end the failure was entirely opaque: the remote simply stopped sending me packets. The only reason I was able to debug this at all was because I controlled the other end of the VPN as well, and even then I wouldn't have been able to do anything about it other than being in the fortuitous situation of someone able to do something about it seeing my post. How many people go through their lives dealing with things just being broken and having no idea why, and how do we fix that?

(Edit: thanks to this comment, it sounds like the underlying issue was a kernel bug that Fastly developed a fix for - under certain configurations, the kernel fails to associate the MTU update with the egress interface and so it continues sending overly large packets)

comment count unavailable comments

16 February 2024

Mike Gabriel: Debian Edu 12 - Call for Testing

This is a call for testing of Debian Edu based on Debian bookworm. With the Debian 12.5 point release all required packages have landed in the Debian Edu ISO images that allow you to install a Debian Edu system based on Debian 12. ISO Image Downloads You can find the Blueray Disc ISO image (use for main server installation) at: http://cdimage.debian.org/cdimage/release/current/amd64/iso-bd/debian-ed... For standalone workstation installations or installations on an already up-and-running Debian Edu site, please use the netinst ISO image: http://cdimage.debian.org/cdimage/release/current/amd64/iso-cd/debian-ed... Quick Start HowTo For testing Debian Edu 12, set up e.g. LXD or libVirt and install (at least) three virtual machines. In your virtualization software prepare an internal network where the VMs can reach one another without needing access to your local network. The three VMs: Happy testing! Further Readings Overall installation profile concept of Debian Edu:
https://wiki.debian.org/DebianEdu/BeforeGettingStarted Debian Edu 12 manual:
https://jenkins.debian.net/userContent/debian-edu-doc/ Debian Edu 12 status page:
https://wiki.debian.org/DebianEdu/Status/Bookworm

13 February 2024

Matthew Palmer: Not all TLDs are Created Equal

In light of the recent cancellation of the queer.af domain registration by the Taliban, the fragile and difficult nature of country-code top-level domains (ccTLDs) has once again been comprehensively demonstrated. Since many people may not be aware of the risks, I thought I d give a solid explainer of the whole situation, and explain why you should, in general, not have anything to do with domains which are registered under ccTLDs.

Top-level What-Now? A top-level domain (TLD) is the last part of a domain name (the collection of words, separated by periods, after the https:// in your web browser s location bar). It s the com in example.com, or the af in queer.af. There are two kinds of TLDs: country-code TLDs (ccTLDs) and generic TLDs (gTLDs). Despite all being TLDs, they re very different beasts under the hood.

What s the Difference? Generic TLDs are what most organisations and individuals register their domains under: old-school technobabble like com , net , or org , historical oddities like gov , and the new-fangled world of words like tech , social , and bank . These gTLDs are all regulated under a set of rules created and administered by ICANN (the Internet Corporation for Assigned Names and Numbers ), which try to ensure that things aren t a complete wild-west, limiting things like price hikes (well, sometimes, anyway), and providing means for disputes over names1. Country-code TLDs, in contrast, are all two letters long2, and are given out to countries to do with as they please. While ICANN kinda-sorta has something to do with ccTLDs (in the sense that it makes them exist on the Internet), it has no authority to control how a ccTLD is managed. If a country decides to raise prices by 100x, or cancel all registrations that were made on the 12th of the month, there s nothing anyone can do about it. If that sounds bad, that s because it is. Also, it s not a theoretical problem the Taliban deciding to asssert its bigotry over the little corner of the Internet namespace it has taken control of is far from the first time that ccTLDs have caused grief.

Shifting Sands The queer.af cancellation is interesting because, at the time the domain was reportedly registered, 2018, Afghanistan had what one might describe as, at least, a different political climate. Since then, of course, things have changed, and the new bosses have decided to get a bit more active. Those running queer.af seem to have seen the writing on the wall, and were planning on moving to another, less fraught, domain, but hadn t completed that move when the Taliban came knocking.

The Curious Case of Brexit When the United Kingdom decided to leave the European Union, it fell foul of the EU s rules for the registration of domains under the eu ccTLD3. To register (and maintain) a domain name ending in .eu, you have to be a resident of the EU. When the UK ceased to be part of the EU, residents of the UK were no longer EU residents. Cue much unhappiness, wailing, and gnashing of teeth when this was pointed out to Britons. Some decided to give up their domains, and move to other parts of the Internet, while others managed to hold onto them by various legal sleight-of-hand (like having an EU company maintain the registration on their behalf). In any event, all very unpleasant for everyone involved.

Geopolitics on the Internet?!? After Russia invaded Ukraine in February 2022, the Ukranian Vice Prime Minister asked ICANN to suspend ccTLDs associated with Russia. While ICANN said that it wasn t going to do that, because it wouldn t do anything useful, some domain registrars (the companies you pay to register domain names) ceased to deal in Russian ccTLDs, and some websites restricted links to domains with Russian ccTLDs. Whether or not you agree with the sort of activism implied by these actions, the fact remains that even the actions of a government that aren t directly related to the Internet can have grave consequences for your domain name if it s registered under a ccTLD. I don t think any gTLD operator will be invading a neighbouring country any time soon.

Money, Money, Money, Must Be Funny When you register a domain name, you pay a registration fee to a registrar, who does administrative gubbins and causes you to be able to control the domain name in the DNS. However, you don t own that domain name4 you re only renting it. When the registration period comes to an end, you have to renew the domain name, or you ll cease to be able to control it. Given that a domain name is typically your brand or identity online, the chances are you d prefer to keep it over time, because moving to a new domain name is a massive pain, having to tell all your customers or users that now you re somewhere else, plus having to accept the risk of someone registering the domain name you used to have and capturing your traffic it s all a gigantic hassle. For gTLDs, ICANN has various rules around price increases and bait-and-switch pricing that tries to keep a lid on the worst excesses of registries. While there are any number of reasonable criticisms of the rules, and the Internet community has to stay on their toes to keep ICANN from totally succumbing to regulatory capture, at least in the gTLD space there s some degree of control over price gouging. On the other hand, ccTLDs have no effective controls over their pricing. For example, in 2008 the Seychelles increased the price of .sc domain names from US$25 to US$75. No reason, no warning, just pay up .

Who Is Even Getting That Money? A closely related concern about ccTLDs is that some of the cool ones are assigned to countries that are not great. The poster child for this is almost certainly Libya, which has the ccTLD ly . While Libya was being run by a terrorist-supporting extremist, companies thought it was a great idea to have domain names that ended in .ly. These domain registrations weren t (and aren t) cheap, and it s hard to imagine that at least some of that money wasn t going to benefit the Gaddafi regime. Similarly, the British Indian Ocean Territory, which has the io ccTLD, was created in a colonialist piece of chicanery that expelled thousands of native Chagossians from Diego Garcia. Money from the registration of .io domains doesn t go to the (former) residents of the Chagos islands, instead it gets paid to the UK government. Again, I m not trying to suggest that all gTLD operators are wonderful people, but it s not particularly likely that the direct beneficiaries of the operation of a gTLD stole an island chain and evicted the residents.

Are ccTLDs Ever Useful? The answer to that question is an unqualified maybe . I certainly don t think it s a good idea to register a domain under a ccTLD for vanity purposes: because it makes a word, is the same as a file extension you like, or because it looks cool. Those ccTLDs that clearly represent and are associated with a particular country are more likely to be OK, because there is less impetus for the registry to try a naked cash grab. Unfortunately, ccTLD registries have a disconcerting habit of changing their minds on whether they serve their geographic locality, such as when auDA decided to declare an open season in the .au namespace some years ago. Essentially, while a ccTLD may have geographic connotations now, there s not a lot of guarantee that they won t fall victim to scope creep in the future. Finally, it might be somewhat safer to register under a ccTLD if you live in the location involved. At least then you might have a better idea of whether your domain is likely to get pulled out from underneath you. Unfortunately, as the .eu example shows, living somewhere today is no guarantee you ll still be living there tomorrow, even if you don t move house. In short, I d suggest sticking to gTLDs. They re at least lower risk than ccTLDs.

+1, Helpful If you ve found this post informative, why not buy me a refreshing beverage? My typing fingers (both of them) thank you in advance for your generosity.

Footnotes
  1. don t make the mistake of thinking that I approve of ICANN or how it operates; it s an omnishambles of poor governance and incomprehensible decision-making.
  2. corresponding roughly, though not precisely (because everything has to be complicated, because humans are complicated), to the entries in the ISO standard for Codes for the representation of names of countries and their subdivisions , ISO 3166.
  3. yes, the EU is not a country; it s part of the roughly, though not precisely caveat mentioned previously.
  4. despite what domain registrars try very hard to imply, without falling foul of deceptive advertising regulations.

12 February 2024

Gunnar Wolf: Heads up! A miniDebConf is approaching in Santa Fe, Argentina

I realize it s a bit late to start publicly organizing this, but better late than never I m happy some Debian people I have directly contacted have already expressed interest. So, lets make this public! For all interested people who are reasonably close to central Argentina, or can be persuaded to come here in a month s time You are all welcome! It seems I managed to convince my good friend Mart n Bayo (some Debian people will remember him, as he was present in DebConf19 in Curitiba, Brazil) to get some facilities for us to have a nice Debian get-together in Central Argentina.
Where? We will meet at APUL Asociaci n de Personal no-docente de la Universidad Nacional del Litoral, in downtown Santa Fe, Argentina.

When? Saturday, 2024.03.09. It is quite likely we can get some spaces for continuing over Sunday if there is demand.

What are we planning? We have little time for planning but we want to have a space for Debian-related outreach (so, please think about a topic or two you d like to share with general free software-interested, not too technical, audience). Please tell me by mail (gwolf@debian.org) about any ideas you might have. We also want to have a general hacklab-style area to hang out, work a bit in our projects, and spend a good time together.

Logistics I have briefly commented about this with our dear and always mighty DPL, and Debian will support Debian-related people interested in attending; please check personally with me for specifics on how to handle this case by case. My intention is to cover costs for travel, accomodation (one or two nights) and food for whoever is interested in coming over.

More information As I don t want to direct people to keep an eye on my blog post for updates, I ll copy this information (and keep it updated!) at the Debian Wiki / DebianEvents / ar / 2024 / MiniDebConf / Santa Fe please refer to that page!

Contact

Codes of Conduct DebConf and Debian Code of Conduct apply. See the DebConf Code of Conduct and the Debian Code of Conduct.

Registration Registration is free, but needed. See the separate Registration page.

Talks Please, send your proposal to gwolf@debian.org

11 February 2024

Freexian Collaborators: Debian Contributions: Upcoming Improvements to Salsa CI, /usr-move, and more! (by Utkarsh Gupta)

Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

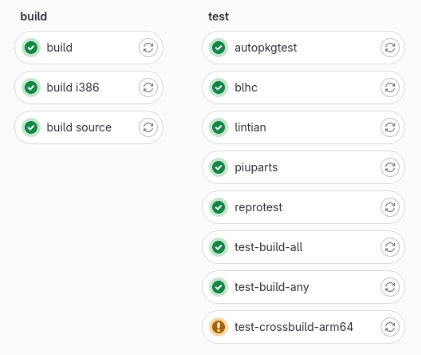
Upcoming Improvements to Salsa CI, by Santiago Ruano Rinc n Santiago started picking up the work made by Outreachy Intern, Enock Kashada (a big thanks to him!), to solve some long-standing issues in Salsa CI. Currently, the first job in a Salsa CI pipeline is the extract-source job, used to produce a debianize source tree of the project. This job was introduced to make it possible to build the projects on different architectures, on the subsequent build jobs. However, that extract-source approach is sub-optimal: not only it increases the execution time of the pipeline by some minutes, but also projects whose source tree is too large are not able to use the pipeline. The debianize source tree is passed as an artifact to the build jobs, and for those large projects, the size of their source tree exceeds the Salsa s limits. This is specific issue is documented as issue #195, and the proposed solution is to get rid of the extract-source job, relying on sbuild in the very build job (see issue #296). Switching to sbuild would also help to improve the build source job, solving issues such as #187 and #298. The current work-in-progress is very preliminary, but it has already been possible to run the build (amd64), build-i386 and build-source job using sbuild with the unshare mode. The image on the right shows a pipeline that builds grep. All the test jobs use the artifacts of the new build job. There is a lot of remaining work, mainly making the integration with ccache work. This change could break some things, it will also be important to test how the new pipeline works with complex projects. Also, thanks to Emmanuel Arias, we are proposing a Google Summer of Code 2024 project to improve Salsa CI. As part of the ongoing work in preparation for the GSoC 2024 project, Santiago has proposed a merge request to make more efficient how contributors can test their changes on the Salsa CI pipeline.

/usr-move, by Helmut Grohne In January, we sent most of the moving patches for the set of packages involved with debootstrap. Notably missing is glibc, which turns out harder than anticipated via dumat, because it has Conflicts between different architectures, which dumat does not analyze. Patches for diversion mitigations have been updated in a way to not exhibit any loss anymore. The main change here is that packages which are being diverted now support the diverting packages in transitioning their diversions. We also supported a few packages with non-trivial changes such as netplan.io. dumat has been enhanced to better support derivatives such as Ubuntu.

Miscellaneous contributions
  • Python 3.12 migration trundles on. Stefano Rivera helped port several new packages to support 3.12.
  • Stefano updated the Sphinx configuration of DebConf Video Team s documentation, which was broken by Sphinx 7.
  • Stefano published the videos from the Cambridge MiniDebConf to YouTube and PeerTube.
  • DebConf 24 planning has begun, and Stefano & Utkarsh have started work on this.
  • Utkarsh re-sponsored the upload of golang-github-prometheus-community-pgbouncer-exporter for Lena.
  • Colin Watson added Incus support to autopkgtest.
  • Colin discovered Perl::Critic and used it to tidy up some poor practices in several of his packages, including debconf.
  • Colin did some overdue debconf maintenance, mainly around tidying up error message handling in several places (1, 2, 3).
  • Colin figured out how to update the mirror size documentation in debmirror, last updated in 2010. It should now be much easier to keep it up to date regularly.
  • Colin issued a man-db buster update to clean up some irritations due to strict sandboxing.
  • Thorsten Alteholz adopted two more packages, magicfilter and ifhp, for the debian-printing team. Those packages are the last ones of the latest round of adoptions to preserve the old printing protocol within Debian. If you know of other packages that should be retained, please don t hesitate to contact Thorsten.
  • Enrico participated in /usr-merge discussions with Helmut.
  • Helmut sent patches for 16 cross build failures.
  • Helmut supported Matthias Klose (not affiliated with Freexian) with adding -for-host support to gcc-defaults.
  • Helmut uploaded dput-ng enabling dcut migrate and merging two MRs of Ben Hutchings.
  • Santiago took part in the discussions relating to the EU Cyber Resilience Act (CRA) and the Debian public statement that was published last year. He participated in a meeting with Members of the European Parliament (MEPs), Marcel Kolaja and Karen Melchior, and their teams to clarify some points about the impact of the CRA and Debian and downstream projects, and the improvements in the last version of the proposed regulation.

9 February 2024

Reproducible Builds (diffoscope): diffoscope 256 released

The diffoscope maintainers are pleased to announce the release of diffoscope version 256. This version includes the following changes:
* CVE-2024-25711: Use a determistic name when extracting content from GPG
  artifacts instead of trusting the value of gpg's --use-embedded-filenames.
  This prevents a potential information disclosure vulnerability that could
  have been exploited by providing a specially-crafted GPG file with an
  embedded filename of, say, "../../.ssh/id_rsa".
  Many thanks to Daniel Kahn Gillmor <dkg@debian.org> for reporting this
  issue and providing feedback.
  (Closes: reproducible-builds/diffoscope#361)
* Temporarily fix support for Python 3.11.8 re. a potential regression
  with the handling of ZIP files. (See reproducible-builds/diffoscope#362)
You find out more by visiting the project homepage.

8 February 2024

Dirk Eddelbuettel: RcppArmadillo 0.12.8.0.0 on CRAN: New Upstream, Interface Polish

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1119 other packages on CRAN, downloaded 32.5 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 575 times according to Google Scholar. This release brings a new (stable) upstream (minor) release Armadillo 12.8.0 prepared by Conrad two days ago. We, as usual, prepared a release candidate which we tested against the over 1100 CRAN packages using RcppArmadillo. This found no issues, which was confirmed by CRAN once we uploaded and so it arrived as a new release today in a fully automated fashion. We also made a small change that had been prepared by GitHub issue #400: a few internal header files that were cluttering the top-level of the include directory have been moved to internal directories. The standard header is of course unaffected, and the set of full / light / lighter / lightest headers (matching we did a while back in Rcpp) also continue to work as one expects. This change was also tested in a full reverse-dependency check in January but had not been released to CRAN yet. The set of changes since the last CRAN release follows.

Changes in RcppArmadillo version 0.12.8.0.0 (2024-02-06)
  • Upgraded to Armadillo release 12.8.0 (Cortisol Injector)
    • Faster detection of symmetric expressions by pinv() and rank()
    • Expanded shift() to handle sparse matrices
    • Expanded conv_to for more flexible conversions between sparse and dense matrices
    • Added cbrt()
    • More compact representation of integers when saving matrices in CSV format
  • Five non-user facing top-level include files have been removed (#432 closing #400 and building on #395 and #396)

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

7 February 2024

Reproducible Builds: Reproducible Builds in January 2024

Welcome to the January 2024 report from the Reproducible Builds project. In these reports we outline the most important things that we have been up to over the past month. If you are interested in contributing to the project, please visit our Contribute page on our website.

How we executed a critical supply chain attack on PyTorch John Stawinski and Adnan Khan published a lengthy blog post detailing how they executed a supply-chain attack against PyTorch, a popular machine learning platform used by titans like Google, Meta, Boeing, and Lockheed Martin :
Our exploit path resulted in the ability to upload malicious PyTorch releases to GitHub, upload releases to [Amazon Web Services], potentially add code to the main repository branch, backdoor PyTorch dependencies the list goes on. In short, it was bad. Quite bad.
The attack pivoted on PyTorch s use of self-hosted runners as well as submitting a pull request to address a trivial typo in the project s README file to gain access to repository secrets and API keys that could subsequently be used for malicious purposes.

New Arch Linux forensic filesystem tool On our mailing list this month, long-time Reproducible Builds developer kpcyrd announced a new tool designed to forensically analyse Arch Linux filesystem images. Called archlinux-userland-fs-cmp, the tool is supposed to be used from a rescue image (any Linux) with an Arch install mounted to, [for example], /mnt. Crucially, however, at no point is any file from the mounted filesystem eval d or otherwise executed. Parsers are written in a memory safe language. More information about the tool can be found on their announcement message, as well as on the tool s homepage. A GIF of the tool in action is also available.

Issues with our SOURCE_DATE_EPOCH code? Chris Lamb started a thread on our mailing list summarising some potential problems with the source code snippet the Reproducible Builds project has been using to parse the SOURCE_DATE_EPOCH environment variable:
I m not 100% sure who originally wrote this code, but it was probably sometime in the ~2015 era, and it must be in a huge number of codebases by now. Anyway, Alejandro Colomar was working on the shadow security tool and pinged me regarding some potential issues with the code. You can see this conversation here.
Chris ends his message with a request that those with intimate or low-level knowledge of time_t, C types, overflows and the various parsing libraries in the C standard library (etc.) contribute with further info.

Distribution updates In Debian this month, Roland Clobus posted another detailed update of the status of reproducible ISO images on our mailing list. In particular, Roland helpfully summarised that all major desktops build reproducibly with bullseye, bookworm, trixie and sid provided they are built for a second time within the same DAK run (i.e. [within] 6 hours) . Additionally 7 of the 8 bookworm images from the official download link build reproducibly at any later time. In addition to this, three reviews of Debian packages were added, 17 were updated and 15 were removed this month adding to our knowledge about identified issues. Elsewhere, Bernhard posted another monthly update for his work elsewhere in openSUSE.

Community updates There were made a number of improvements to our website, including Bernhard M. Wiedemann fixing a number of typos of the term nondeterministic . [ ] and Jan Zerebecki adding a substantial and highly welcome section to our page about SOURCE_DATE_EPOCH to document its interaction with distribution rebuilds. [ ].
diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made a number of changes such as uploading versions 254 and 255 to Debian but focusing on triaging and/or merging code from other contributors. This included adding support for comparing eXtensible ARchive (.XAR/.PKG) files courtesy of Seth Michael Larson [ ][ ], as well considerable work from Vekhir in order to fix compatibility between various and subtle incompatible versions of the progressbar libraries in Python [ ][ ][ ][ ]. Thanks!

Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework (available at tests.reproducible-builds.org) in order to check packages and other artifacts for reproducibility. In January, a number of changes were made by Holger Levsen:
  • Debian-related changes:
    • Reduce the number of arm64 architecture workers from 24 to 16. [ ]
    • Use diffoscope from the Debian release being tested again. [ ]
    • Improve the handling when killing unwanted processes [ ][ ][ ] and be more verbose about it, too [ ].
    • Don t mark a job as failed if process marked as to-be-killed is already gone. [ ]
    • Display the architecture of builds that have been running for more than 48 hours. [ ]
    • Reboot arm64 nodes when they hit an OOM (out of memory) state. [ ]
  • Package rescheduling changes:
    • Reduce IRC notifications to 1 when rescheduling due to package status changes. [ ]
    • Correctly set SUDO_USER when rescheduling packages. [ ]
    • Automatically reschedule packages regressing to FTBFS (build failure) or FTBR (build success, but unreproducible). [ ]
  • OpenWrt-related changes:
    • Install the python3-dev and python3-pyelftools packages as they are now needed for the sunxi target. [ ][ ]
    • Also install the libpam0g-dev which is needed by some OpenWrt hardware targets. [ ]
  • Misc:
    • As it s January, set the real_year variable to 2024 [ ] and bump various copyright years as well [ ].
    • Fix a large (!) number of spelling mistakes in various scripts. [ ][ ][ ]
    • Prevent Squid and Systemd processes from being killed by the kernel s OOM killer. [ ]
    • Install the iptables tool everywhere, else our custom rc.local script fails. [ ]
    • Cleanup the /srv/workspace/pbuilder directory on boot. [ ]
    • Automatically restart Squid if it fails. [ ]
    • Limit the execution of chroot-installation jobs to a maximum of 4 concurrent runs. [ ][ ]
Significant amounts of node maintenance was performed by Holger Levsen (eg. [ ][ ][ ][ ][ ][ ][ ] etc.) and Vagrant Cascadian (eg. [ ][ ][ ][ ][ ][ ][ ][ ]). Indeed, Vagrant Cascadian handled an extended power outage for the network running the Debian armhf architecture test infrastructure. This provided the incentive to replace the UPS batteries and consolidate infrastructure to reduce future UPS load. [ ] Elsewhere in our infrastructure, however, Holger Levsen also adjusted the email configuration for @reproducible-builds.org to deal with a new SMTP email attack. [ ]

Upstream patches The Reproducible Builds project tries to detects, dissects and fix as many (currently) unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including: Separate to this, Vagrant Cascadian followed up with the relevant maintainers when reproducibility fixes were not included in newly-uploaded versions of the mm-common package in Debian this was quickly fixed, however. [ ]

If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

6 February 2024

Robert McQueen: Flathub: Pros and Cons of Direct Uploads

I attended FOSDEM last weekend and had the pleasure to participate in the Flathub / Flatpak BOF on Saturday. A lot of the session was used up by an extensive discussion about the merits (or not) of allowing direct uploads versus building everything centrally on Flathub s infrastructure, and related concerns such as automated security/dependency scanning. My original motivation behind the idea was essentially two things. The first was to offer a simpler way forward for applications that use language-specific build tools that resolve and retrieve their own dependencies from the internet. Flathub doesn t allow network access during builds, and so a lot of manual work and additional tooling is currently needed (see Python and Electron Flatpak guides). And the second was to offer a maybe more familiar flow to developers from other platforms who would just build something and then run another command to upload it to the store, without having to learn the syntax of a new build tool. There were many valid concerns raised in the room, and I think on reflection that this is still worth doing, but might not be as valuable a way forward for Flathub as I had initially hoped. Of course, for a proprietary application where Flathub never sees the source or where it s built, whether that binary is uploaded to us or downloaded by us doesn t change much. But for an FLOSS application, a direct upload driven by the developer causes a regression on a number of fronts. We re not getting too hung up on the malicious developer inserts evil code in the binary case because Flathub already works on the model of verifying the developer and the user makes a decision to trust that app we don t review the source after all. But we do lose other things such as our infrastructure building on multiple architectures, and visibility on whether the build environment or upload credentials have been compromised unbeknownst to the developer. There is now a manual review process for when apps change their metadata such as name, icon, license and permissions which would apply to any direct uploads as well. It was suggested that if only heavily sandboxed apps (eg no direct filesystem access without proper use of portals) were permitted to make direct uploads, the impact of such concerns might be somewhat mitigated by the sandboxing. However, it was also pointed out that my go-to example of Electron app developers can upload to Flathub with one command was also a bit of a fiction. At present, none of them would pass that stricter sandboxing requirement. Almost all Electron apps run old versions of Chromium with less complete portal support, needing sandbox escapes to function correctly, and Electron (and Chromium s) sandboxing still needs additional tooling/downstream patching to run inside a Flatpak. Buh-boh. I think for established projects who already ship their own binaries from their own centralised/trusted infrastructure, and for developers who have understandable sensitivities about binary integrity such such as encryption, password or financial tools, it s a definite improvement that we re able to set up direct uploads with such projects with less manual work. There are already quite a few applications including verified ones where the build recipe simply fetches a binary built elsewhere and unpacks it, and if this already done centrally by the developer, repeating the exercise on Flathub s server adds little value. However for the individual developer experience, I think we need to zoom out a bit and think about how to improve this from a tools and infrastructure perspective as we grow Flathub, and as we seek to raise funds for different sources for these improvements. I took notes for everything that was mentioned as a tooling limitation during the BOF, along with a few ideas about how we could improve things, and hope to share these soon as part of an RFP/RFI (Request For Proposals/Request for Information) process. We don t have funding yet but if we have some prospective collaborators to help refine the scope and estimate the cost/effort, we can use this to go and pursue funding opportunities.

Next.

Previous.


