Search Results: "cas"

9 November 2008

Christine Spang: Switching to Colemak

Way back in mid-late May, I switched keyboard layouts from standard US QWERTY to Colemak. I’d played around with the layout a bit before that and thought it seemed pretty solid, but it hadn’t been a good time to switch then. (I did, however, snag the idea of remapping Caps Lock to Backspace from that early trial though, and to this day that’s probably the most annoying thing about typing on QWERTY, because I associate Caps Lock with Backspace on both layouts now. Anyway.) This time, however, I strategically timed it to coincide with the end of classes, so I had no assignments due and could make a fool out of myself during the first few days of my summer job. Smashing success. It only took a couple days to get past the point of extremely frustrating slowness. Two weeks in I was up to 40wpm, which was about the point where I stopped noticing that I’d taken a backwards step in typing speed, as it didn’t really hinder anything I did on a regular basis. By the end of the summer I was back up to the same speed as I’d been prior to switching (around 75wpm). I didn’t really do any typing lessons after the first few days, as I found just doing whatever I would normally do on a computer much more interesting. The biggest hurdle after the initial adaptation of actually being able to type on the layout was, for a command-line lover like myself, dealing with “hjkl” not being a convenient way of navigating around in console apps like mutt, vim, aptitude, and less. After a bit of experimentation, I stole an idea from this page and started adapting my dotfiles to make these programs use ne for jk and st for hl, and that seems to be working out well. The worst key that this clobbers in general is n, but it’s pretty easy to remap that to QWERTY’s n, which is easy to remember and is the hardly-used k on the Colemak layout. For any interested others, I’ve thrown the relevant dotfile snippets up here. I’d been putting off blogging this because I wanted to finish setting up dotfiles/homedirs-in-git la Joey Hess beforehand, but I figure I’ll never actually get it done if I keep using that excuse. For mutt, the given snippet goes in your .muttrc (or whatever you source keybindings into your muttrc from). The same goes for vim. Aptitude keybindings go in .aptitude/config. For less, it’s a little more arcane: first you stick your keybindings in .lesskey, and then you run the command lesskey. I also remapped screen’s escape key to ctrl-t. Why not Dvorak? Dvorak seems to be the most well-known QWERTY alternative around, so why didn’t I switch to that if I wanted something better? I did try Dvorak first, but the incredibly uncomfortable combination of ls on the right pinky was a complete deal-breaker. I also found it very slow-going to try to adapt to Dvorak after typing on QWERTY for years. The Colemak FAQ has some more notes on Dvorak deficiencies that it addresses. Overall, I’ve found typing on Colemak to be remarkably lacking in anything that particularly bothers me. I still type on QWERTY a little, but mostly just for login prompts on Athena workstations and the desktop machine in my room which my roommate sometimes uses. I have to glance down at the keyboard when typing on QWERTY to get it back in my head, but generally I only need it for a few minutes anyway and it’s no big deal. As long as I glance down occasionally I can still maintain a speed level well above that of frustration. On the plus side, this means that if I look at the keyboard when typing normally in Colemak, I get screwed up because I start thinking in QWERTY. So it’s good touch-typing reinforcement in general.

Simon McVittie: Implementing D-Bus services with telepathy-glib

(Part 1 of an ongoing series: shiny things in telepathy-glib)
16:46 < epmf> tp-glib is made of magic

—#telepathy, 2008-04-15

Rob pointed out today that I'd been promising to blog about telepathy-glib for several months and still haven't done so. I think there's too much to cover in one blog post, so I'll start with the oldest part - implementing a service (typically a Telepathy connection manager).

While telepathy-glib is (obviously) intended for Telepathy implementors, I think the ideas we've been implementing are likely to be useful for any D-Bus API, particularly flexible/complex APIs where an object implements many interfaces.

Introduction to telepathy-glib telepathy-glib started out as a collection of code extracted from our XMPP connection manager, telepathy-gabble, but at some point it grew beyond that into a wrapper around/partial replacement for dbus-glib. We've been quite pleased with it, really :-) My first major round of work on telepathy-glib, during the first half of 2007, was to split it out from telepathy-gabble (versions up to 0.5.9 were released as part of Gabble 0.5.x tarballs, in fact), leading to the release of the 0.6.x stable branch in late September. This was very helpful for implementing connection managers - Salut, Idle and telepathy-sofiasip (our connection managers for link-local XMPP, IRC and SIP) all started off by forking/cargo-culting from Gabble, and achieved huge code reductions by porting to telepathy-glib. Also, Will Thompson used it in his Summer of Code project, telepathy-haze, to go from nothing to a working and useful Telepathy implementation based on libpurple in a matter of a few months. The second major round of work, which I'll discuss in a later article, added client code to telepathy-glib, obsoleting the older/worse libtelepathy and allowing client programs like Empathy and telepathy-stream-engine to be written using telepathy-glib. In the process, I accidentally reinvented DBusGProxy :-) More details to come later!
Some background: service-side code generation
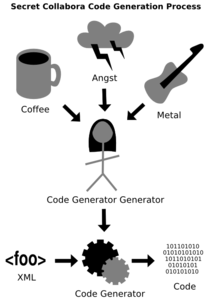
The secret Collabora code-generation process

(credit: daf)

Supporting D-Bus in the GObject world has always involved quite a lot of code generation. The core API of dbus-glib is heavily reliant on varargs functions, which aren't type-safe and are easy to get wrong. dbus-glib contains a program called dbus-binding-tool, which is meant to generate reasonably sane GObject APIs for D-Bus objects. Unfortunately, it seems to be intended to generate a whole GObject at a time. Early versions of telepathy-gabble used dbus-binding-tool plus a script called gengobject.py to generate API stubs for the exported objects; developers then filled in the blanks, and hey presto, we had a GObject on D-Bus. This was fine up to a point, but had a couple of major drawbacks. Whenever we changed the D-Bus API (quite common during the early development of Telepathy), there was a very laborious and error-prone merging process. We ended up with the following process:
  • copy the D-Bus introspection XML from the telepathy-spec repository into a directory xml/pristine (actually, the canonical form for the spec was Python for a while, and we had a script that exported a contrived object onto D-Bus and introspected itself to get the XML - but that's another story!)
  • preprocess the introspection XML to add the dbus-glib CFunctionName annotation, resulting in a directory xml/modified
  • run dbus-binding-tool and a Python script gengobject.py to generate C source in xml/src
  • three-way-diff the old version of xml/src, the new version of xml/src, and the real C code in src to create a new version of src
  • pray that the diff process hadn't randomly exchanged functions' implementations
  • update the resulting code in src so it worked
  • check the whole mess back into darcs
  • hope that nobody else had made changes that would result in darcs conflicts
If you haven't yet gathered, this was a bit of a nightmare. Also, it was very easy to return the wrong thing from a method without noticing - because all the APIs were varargs, the compiler didn't notice, and the first we'd know about it was a mysterious segfault under certain circumstances.
How telepathy-glib fixes code generation telepathy-glib improves on this by taking advantage of this innocuous-looking feature in dbus-glib:
commit 355ef78d98d6fc65715845d56232199162cab12a
Author: Steve Fr cinaux <steve istique net>
Date:   Thu Aug 17 11:48:20 2006 +0200
    Interface support for bindings.
Instead of running dbus-binding-tool or creating GObjects with D-Bus interfaces, we put the entire Telepathy spec through glib-ginterface-gen.py, a distant descendant of Gabble's gengobject.py. For each interface in the spec, we generate a GInterface that mirrors the D-Bus interface. Any GObject that implements the GInterface automatically gets the D-Bus interface if it's exported onto D-Bus. There are a few non-obvious refinements, though:
  • The signature of the method implementation is always in the mode that dbus-glib calls "asynchronous", where the method implementation can either send a reply message before or after it returns. For "slow" methods, this is the only thing you can do. For instance, many Telepathy D-Bus methods can't return anything until some TCP round-trips to the server have happened. This is also the only thing you can do if you want to extract extra information, like the sender's unique name, from the method-call message (dbus-glib's "synchronous" API doesn't allow this to be done). For "fast" methods, sending a reply message before returning is just as easy as using the "synchronous" API (it's just a difference of syntax), and has an API consistent with that of the "slow" methods, making it easier for service authors.

  • The layout of the GInterface vtable is private, and (auto-generated) accessor functions are used to fill in implementations. This means our ABI doesn't change just because we re-ordered functions in the spec.

  • If no implementation is provided for a method, we just raise an appropriate error (org.freedesktop.Telepathy.Errors.NotImplemented), rather than suffering an assertion failure. This means we can safely add methods to an interface.

  • While we're generating code anyway, we generate some static inline wrapper functions which wrap dbus_g_method_return(), to have type-safe method returns. You can easily check that a method replies with correct types, by checking that the implementation of Foo() replies by calling tp_svc_some_interface_return_from_foo().

  • Similarly, we generate wrapper functions to emit signals, to get type-safe signal emission.

Not all interfaces are stable enough to be included in telepathy-glib's stable API and ABI, so some of our other projects include a copy of the telepathy-glib code-generation tools, and generate their own "mini-telepathy-glib" (traditionally in a /extensions/ directory) for their implementation-specific (drafts of) interfaces. This isn't yet as polished as it ought to be (mainly because we don't want to freeze the augmented-introspection-XML format that we write the Telepathy spec in, because it's rather ad-hoc and hackish in places) but it works quite well in practice. To see what this looks like in practice, have a look at the examples in telepathy-glib, or at a Telepathy connection manager like telepathy-gabble.
Mixins and base classes Another feature of telepathy-glib which makes life easier for connection manager authors is that it provides "mixins" and base classes which implement some of the GInterfaces. There's absolutely nothing magic about the base classes - they don't have any access to private implementation details of the GInterfaces, they just implement them like everyone else does. The "mixins" are only slightly more magical - they store some extra state inside the structures representing GObjects and their classes, and use it to provide default implementations of some or all of the methods on a particular interface (or two interfaces, in the case of the new TpMessageMixin). I'll leave it up to Rob to explain those in greater detail, since I seem to remember that he invented them :-P The examples and regression tests in telepathy-glib are quite good examples of how these work in practice.

8 November 2008

Steve McIntyre: 3rd Free Software Congress in Valencia

I spent much of this week in Alicante. It was wonderful to have a few days away from the beginnings of Winter in Cambridge - Alicante's in South West Spain, right on the Mediterranean. It's a lovely city, although it was very quiet due to the time of year. I was invited down to Alicante by organisers of the Congr s de Programari Lliure, Comunitat Valenciana, to present a talk about Debian. That I did, and as always my slides and photos are available in case people are interested. I wasn't too sure about what level to aim the talk, so I deliberately went for a general introduction to Debian. That seems to have been the correct level - nobody threw anything at me, and nobody was visibly falling asleep. *grin* It's also the first time I've ever given a talk with official translators, which is a weird experience! The main topic for the conference was the new release of Lliurex, Valencia's own GNU/Linux distribution targeted primarily at use in schools. The conference was massive; I was told there were about 1500 attendees in all, most of whom were teachers who wanted to come and learn more about Free Software. There was a good spread of talks and workshops, covering topics from development through to deployment in the classroom. The level of enthusiasm for Free Software here was immense - lots of people were keen to learn more about it and get involved. I was told that out of the 15 regions/states of Spain, 11 of them have now started their own distributions to use in schools! Extremadura were the first region to experiment with Free Software like this, and their success with LinEx was a clear inspiration to their neighbours elsewhere in Spain. As well as the obvious cost advantages of moving from proprietary to Free Software, the local governments also love the freedom to use and modify their software however they like - including the ability to provide their own translations. Conference welcome I met up with a lot of cool people at the conference too. The local education minister (Alejandro Font de Mora) was keen to talk with all the speakers and very enthusiastic about the future of Free Software in his schools. As is increasingly common at FS events around the world, there were of course quite a few Debian people around too. Luciano and Miriam were also giving talks, and I bumped into Rene and Miguel and a whole bunch of others whose names I'm too crap to remember - sorry! I also spoke a lot with Kurt Gramlich, the mega-enthusiastic Skolelinux developer who was also happy to push Debian to everybody he spoke to *grin*. Jon "Maddog" Hall had some excellent ideas that I'm sure we'll all hear more about soon, and his talk was excellent. He did a very good job of explaining how Free Software makes such a difference, including how it helps people to make money. He also explained that due to travel he had missed Halloween at home and he wanted to share the experience of scary masks with the people at the conference: Maddog Bush I had a great time in Alicante, and I'm very grateful for the invitation to go there. I wish that the UK was as far as advanced as Spain in the use of Free Software in education - they've done a huge amount of good work in this area and I'm glad we can help them.

Joerg Jaspert: Debian mirror scripts

With a small mail to our mirrors-announce list, I just opened the work of more than one month to the public. Even better, I strongly encourage every mirror admin to use my scripts, or at least scripts that follow a minimal set of rules I wrote down… Some long time (somewhere in April or May this year) I got added to the Debian mirroradm group. First it was only to get some problems with packages.debian.org solved, but later on I started doing more. This group is basically the one that handles the archvsync user on .debian.org machines and also manages the official Debian mirrors listing. As the archvsync user exists on multiple .debian.org machines, and many of them do mirror a copy of our archive for various reasons, all of them had some version of a mirroring script, and sometimes also a version of a pushmirror script. Unfortunately, as they all had been maintained mostly on their own per machine - they sometimes had evolved a bit different. Additionally all of them had a few problems which could leave us with a broken mirror behind, despite it looking all well. So on Sept. 26 I decided to trash it all and rewrite the script and put it all in a VCS (and selected git). For that I set myself a few goals, like (in no particular order) Now, 109 commits and more than a month later, I was finally able to open the scripts to the wide public. (Had multiple people test them before this, but thats always different than a real “release”). The scripts are in use on all .debian.org machines and some other mirrors already, so I’m fairly sure they work.
As I already wrote, Debian mirror admins are strongly encouraged to use this scriptset and not to invent their own. In case you miss a feature either send me a mail describing it, or better, a patch implementing it. I’m happy to implement as much as possible (and sensible :) ) And while it is discouraged to use own scripts, sometimes people have reasons to have their own, so there is now a minimal set of functionality that such a script MUST support. All of those requirements are easy to fulfill. Well, at least the MUST ones. The first one is basically a given, all scripts I know are doing this already. The second one sounds more complicated, but actually might just be about 4 lines of actual code changes. Just touch an extra file before you gain a lockfile (to avoid two scripts running at the same time) and then rerun rsync as long as that extra file is around. (It helps to rm this trigger file right before you call rsync :) ). The should directive is actually a little more work to implement correctly. I won’t show source here, read the ftpsync script if you want to see it, but I try some small explanation. Background: Debian mirror synchronisation is usually done by scripts that get started via ssh. As mirror operators (understandably) do not like their upstream mirror to be able to login, this is done using “ssh triggers”, a feature I wrote about earlier. Those are sshkeys using a forced command, so nothing else than this command will be run, ever. SSH, if used with such forced commands, has the helpful feature that it sets the environment variable SSH_ORIGINAL_COMMAND containing the original arguments. Which means that, if the mirror pushes you with “ssh yourhost -l mirror sleep 1” you will see *sleep 1 in that variable. It is what many mirror operators currently use when pushing their downstreams. Now, we can use that to tell the receiving end all things we want it to know. If you look in my script you will see that I defined a little more than the minimal arguments. But none of the additional ones are a requirement, they only make life much easier. My script currently understands, additional to the 3 minimal ones:
As if that wasn’t enough, I also had to rewrite the runmirrors script. The old 10-line one just didn’t cope with the more general approach. This script is used to “push” your downstream mirrors, telling them that they need to update. (Which is the only sane way to run a mirror. cron is just not made for mirrors that can update at random times!). One nice new feature of it is the ability to update multiple mirrors nearly at the same time. This is extremely helpful in case of DNS Round Robin entries like security.debian.org (multiple hosts offering the same archive under one hostname). You do not want to have such hosts out of sync. Not even for a minute, if you can avoid that. So we now push the mirrors with sync:stage1 as argument. Then we wait until all of them have finished the stage1 sync before we push them all again, this time with sync:stage2 as argument. This will erase any update delays thanks to network latency / low bandwidth one of the security mirrors might have, as the large transfers (all the binary and source packages) are done in stage1. They can take time, a normal user won’t notice it - the Package and Source indices are not transferred yet. They arevery small and as such transfered pretty fast whenever stage1 is done everywhere and we tell mirrors to do stage2.
All in all it was a pretty nice exercise writing those scripts. Comments: 0

7 November 2008

Axel Beckert: e-mail.is-not-s.ms

When I first read http://two.sentenc.es/ in (if I remember correctly) madduck’s signature, I thought something like “This can’t be! Why are people castrating themself?” Although I really understand that the inventor has good reasons for such a personal policy, I notice how much time I waste by trying to fit all the information I want to transmit in the 160 characters a short messages allows — or, even worse, into the 140 characters microblogging services like identi.ca or Twitter allow. So I had to oppose something to this, but even to only reach the coolness level of the domain “sentenc.es” is hard, you probably can’t top it at all. For luck, I’m not alone and Venty had the right idea for a hostname which has at least some geeky niveau. So here it is, our pleading for e-mails as long and detailed as necessary:

http://e-mail.is-not-s.ms/ A German version will be available soon at http://e-mail.ist-nicht-s.ms/. Feel free to add either URL to your e-mail signature. :-) Oh, and thanks to the Government of Montserrat which allows strangers to register .ms domains without any hassles. :-) Update / FAQ Seems to be necessary to make a few things clear…

  1. No, I do not think that everyone using two.sentenc.es has neither style nor knows anything about grammar or punctuation. What I say is that the site two.sentenc.es itself with its comparision to short messages (and especially without reading the author’s blog post about the site’s background) indirectly suggests to drop grammar, punctuation and style by cramming all information into a limit number of characters as often done with short messages or microblogging. And the limitation in senctences leads to tapeworm sentences which I try to avoid since they’re considered bad style, too.
  2. And yes, it’s consciously written and designed to be the opposite of two.sentenc.es — even the colors and the font — and therefore is of course very close to the original. See it as it parody or satire if the closeness makes you angry.
  3. And no, I currently don’t care if the site makes less sense if you don’t know two.sentenc.es — people usually can follow hyperlinks on websites.
  4. We weren’t the first ones who noticed that e-mail is not SMS. An example of the problem described above from 2001.

6 November 2008

Mike Hommey: Emptying a deleted file

Yesterday, at work, we had the typical case where df would say there is (almost) no space left on some device, while du doesn’t see as much data present as you would expect from this situation. This happens when you delete a file that another process has opened (and, obviously, not yet closed). In typical UNIX filesystems, files are actually only entries in a directory, pointing (linking) to the real information about the content, the inode. The inode contains the information about how many such links exist on the filesystem, the link count. When you create a hard link (ln without -s), you create another file entry in some directory, linking to the same inode as the “original” file. You also increase the link count for the inode. Likewise, when removing a file, the entry in the directory is removed (though most of the time, really only skipped, but that’s another story), and the link count decreased. When the link count is zero, usually, the inode is marked as deleted. Except when the usage count is not zero. When a process opens a file, the kernel keeps a usage count for the corresponding inode in memory. When some process is reading from a file, it doesn’t really expect it to disappear suddenly. So, as long as the usage count is not null, even when the link count in the inode is zero, the content is kept on the disk and still takes space on the filesystem. On the other hand, since there is no entry left in any directory linking to the inode, the size for this content can’t be added to du’s total. Back to our problem, the origin was that someone had to free some space on a 1GB filesystem, and thought a good idea would be to delete that 860MB log file that nobody cares about. Except that it didn’t really remove it, but he didn’t really check. Later, the “filesystem full” problem came back at someone else, who came to ask me what files from a small list he could remove. But the files were pretty small, and that wouldn’t have freed enough space. That gave me the feeling that we probably were in this typical case I introduced this post with, which du -sk confirmed: 970MB used on the filesystem according to df, but only 110MB worth of data… Just in case you would need to find the pid of the process having the deleted file still opened, or even better, get access to the file itself, you can use the following command:
find -L /proc/*/fd -type f -links 0
(this works on Linux ; remove -L on recent Solaris ; on other OSes, you can find the pid with lsof) Each path this command returns can be opened and its content accessed with a program, such as cat. That will give access to the deleted content. I already adressed how to re-link such a file, which somehow works under Linux, but in my case, all that mattered was to really remove the file, this time. But we didn’t know if it was safe to stop the process still holding the file, nor how to properly restart it. We were left without a possible resolution, but still needed to come up with something before the filesystem gets really full while waiting to be able to deal with the root of the problem. The first crazy idea I had was to attach a debugger to the process, and use it to close the file descriptor and open a new file instead (I think you can find some examples with google). But there was no debugger installed. So, I had this other crazy idea: would truncate() work on these /proc/$pid/fd files? You know what? It does work. So I bought us some time by running:
perl -e 'truncate("/proc/$pid/fd/$fd", 0);'
(somehow, there is no standard executable to do a truncate(), so I always resort to perl) Afterwards, I also verified the same works under Linux (where you wouldn’t really know what it’d do with these files that are symbolic links to somewhere that doesn’t exist). The even simpler following command works, too.
> /proc/$pid/fd/$fd
It doesn’t truncate() but open() with O_WRONLY O_CREAT O_TRUNC, and close() right after (to simplify), which has the same effect. Good to know, isn’t it?

Eddy Petri&#537;or: Coordinating localization via git

Note: this is quite long and might not be interesting for people not involved with /in either of: debian i18n, debian l10n, git, shell scripting.


For some time now I have been the de-facto coordinator of the Romanian localization team. During this time I was faced multiple times with problems related to motivation of the team members, setting goals for a release, coordination of the changes inside the team, integration of new translators in the team, loosing team members, my lack of time on some occasions and other problems.

I thought a lot about how to improve on those points and I was never satisfied with the answers I got. What I think was the worst problem in the team was the inability to set clear goals, especially during lenny's development cycle.

During sarge's and etch's development cycles we were in an infancy state and setting as the goal to have a fully translated installation process was really enough to keep people motivated. For sarge we missed by a small margin, but the translations were of poor quality, while for etch we worked more on improving the translations.


But during lenny it was bad, really bad. My free time had been shrinking for a while, starting with etch's release, and we were unable to set clear goal, since for etch we managed to have the installation process fully translated and a few other translations. There was no way for us to reach 100% translations during lenny's development cycle, so setting that as a goal was really unrealistic. Percents by themselves don't mean anything for people, and as long as there's no substance to those numbers, there's no motivation to reach for one arbitrary percent.

I tried to set as a goal translating the packages installed by default in a new installation, but that hit the eternal question How do we know easily which are those packages?. This remained sometimes unanswered or got an unsatisfying answer. Also, there was a goal to have correct diacritics for Romanian in lenny, to have aspell-ro that uses the correct diacritics.

I even got to a point that I, myself, lost my motivation and set myself a personal goal of overrunning the level the translations that the language just above Romanian had in the po-debconf l10n statistics (ranking between languages). This was nice way for me to keep myself motivated, but I had my reserves in making this motivation public out of fear of being misinterpreted, because, by a strange coincidence, that next language was Hungarian, and in Romania's history there was some friction between Hungaria and Romania, while there are still some tensions with the Hungarian minority in Romania, in areas where they represent the local majority.

I managed to reach my personal goal, but this wasn't addressing the big picture.


So, sometime around the start of this year I started thinking about ways to coordinate the Romanian localization team in order to have:
For short, a tool that would allow the team to work more efficiently while having the possibility to set clear goals in order to keep people motivated.


So after some pondering, I thought that creating a repository with the translations and the helper tools that would do the funky sync, checks, stats would be the best way to do that. So I started hacking on that somewhere around July-August and I published the result, but without much publicity, since it is still incomplete.

Some of the technical details are still in a haze, but I have a general idea and I got some basic functionality.


Today I decided that I should announce this semi-officially though my blog, maybe I get some input, ideas, or even contributions (I really should write a TODO).


I give you the Debian L10n Romanian coordination repository.

This is a git repository that has some tools to facilitate translation coordination and the translations that are current in the distro for the team.


Can be cloned with:

git clone git://git.debian.org/git/users/eddyp-guest/debian-ro-repo.git

or, if you're behind a restrictive firewall:

git clone http://git.debian.org/git/users/eddyp-guest/debian-ro-repo.git


Currently the work flow for updating a translation is as follows:
  1. source _bin/polibs (. _bin/polibs)
  2. cd foo
  3. po_refresh
  4. complete the translation
  5. po_rearrange "ro.po"
  6. git add "ro.po" && git commit -m "updated translation for foo"
  7. send the translation ("git format-patch origin" and send the patches by mail, or, alternatively, just "git push")


Features:
Planned features:

Problems:

I was hoping that the release notes for lenny would facilitate from this infrastructure, but unfortunately I was lately in a really inactive period wrt Debian.


Questions, suggestions, ideas are welcome.

Martin Michlmayr: European Commission publishes guidelines on the procurement of FOSS

The Open Source Repository and Observatory (OSOR), a new site sponsored by the European Commission to foster the exchange of FOSS related information and software among European public administrations, recently published guidelines on the procurement of open source software. Public administrations in Europe have to follow public tender procedures and the new guidelines give practical and legal advice on how open source software and related services can be incorporated into the procurement process. Rishab Ghosh, who presented the guidelines at the Open Source World Conference in Malaga, argued that the procurement guidelines were needed because of two reasons. First, they studied recent tenders and found that many explicitly mentioned proprietary applications. 16% of 3615 software tenders explicitly asked for products from top 10 software vendors, such as Microsoft, SAP and Oracle. This practice may be illegal because public tenders generally have to describe functional requirements in a general way instead of specifying specific products. Second, many public administrations don't have any experience with the procurement of FOSS. In fact, they often don't know whether or under which circumstances they are allowed to adopt and ask for FOSS solutions. The guidelines are specifically designed in order to clearly and simply explain how public administrations can acquire open source and they don't assume that a country has adopted a specific policy regarding open source. The guidelines include a long section about open standards, open source and how they relate. Both open standards and open source align very well with the needs of public administrations who have an "obligation to support interoperability, transparency and flexibility, as well as economical use of public funds". The guidelines argue that the exit cost, i.e. the cost incurred in moving to another IT system, is also an important consideration but one that is often neglected. The adoption of a proprietary solution without open standards may limit the future choice, thereby increasing the long-time costs and giving the proprietary vendor an unfair advantage in future tenders. The procurement guidelines describe two ways of acquiring FOSS: it is possible to go the usual route of publishing a tender for the supply of software (possibly with related services). However, in the case of FOSS, it is also possible to download the software directly from the Internet. This is possible because the software is not only free of charge but comes with no contractual obligations. If there were any obligations involved with the download (such as fees, the agreement to an EULA or the requirement to purchase services in the future), software download is not an allowed method. What I like about the guidelines is that they explicitly say that downloading software has to be part of the formal procurement process. You have to think about your requirements, look at various alternatives, and so on, and not just blindly download something from the Internet. When it comes to the procurement of FOSS, the guidelines don't suggest that tenders should explicitly ask for FOSS. Instead, they should describe the functional requirements of the software as well as certain properties. For example, a tender could specify that the public administration as well as third parties must have the right to study, distribute and modify the software. In a sense, the guidelines suggest that tenders should include the principles of the Free Software Definition along with justifications for these requirements. Personally, I think there is a great need for these procurement guidelines. There are many public administrations that don't know how to acquire FOSS and these guidelines offer clear advice. Furthermore, I find the guidelines very balanced. They don't recommend that you should always ask for FOSS but incorporate FOSS principles into tenders where it makes sense. It remains to be seen whether the procurement guidelines will have an impact on the FOSS adoption in Europe, but I surely hope so. (Originally published on FOSSBazaar)

MJ Ray: Elections and SPI: Open Voting Foundation

So, as everyone knows by now, the party which is a lot like our Conservatives won the US elections (instead of the other party which is a lot like our Conservatives). I’m particularly touched by Aq’s comment:-
The mood in America has been likened to the one here in 97 when we managed to kick the conservatives out for the first time in about 20 years, which amuses me. However, the fact that ours failed to live up to that optimism doesn t mean yours necessarily won t
Oh well, at least it was better than drifting further to the right (in both cases). I’ll wait and see whether it lives up to the optimism. As you may know, SPI is associated with the Open Voting Foundation. That doesn’t sit well with me - while paper voting is imperfect, it seems more verifiable and scalable than machine voting. I’ve been assured that OVF seeks to replace current election machines, rather than spread machine voting to new places and it looks like my area is not under immediate threat (ORG latest news), so I’m not working on it just now. Broadly, I agree with Simon Rumble on Voting machines: a solution searching for a problem?
So without even going into the serious problems with voting machines, it seems they don’t actually solve any actual problems, and I suspect cost a lot more to operate
I’m currently finding out more about standing for election to The Cooperative Group committee and ThePhoneCoop board - I’m not sure yet, but I think both still use paper voting. Cooperatives-SW and TTLLP both use in-person voting. What’s the current thinking here? What’s best?

Russell Coker: EC2 and IP Addresses

One of the exciting things about having a cloud computing service is how to talk to the rest of the world. It’s all very well to have a varying number of machines in various locations, but you need constant DNS names at least (and sometimes constant IP addresses) to do most useful things. I have previously described how to start an EC2 instance and login to it - which includes discovering it’s IP address [1]. It would not be difficult (in theory at least) to use nsupdate to change DNS records after an instance is started or terminated. One problem is that there is no way of knowing when an instance is undesirably terminated (IE killed by hardware failure) apart from polling ec2-describe-instances so it seems impossible to remove a DNS name before some other EC2 customer gets a dynamic IP address. So it seems that in most cases you will want a constant IP address (which Amazon calls an Elastic IP address) if you care about this possibility. For the case of an orderly shutdown you could have a script remove the DNS record, wait for the timeout period specified by the DNS server (so that all correctly operating DNS caches have purged the record) and then terminate the instance. One thing that interests me is the possibility of running front-end mail servers on EC2. Mail servers that receive mail from the net can take significant amounts of CPU time and RAM for spam and virus filters. Instead of having the expense of running enough MX servers to sustain the highest possible load even while one of the servers has experienced a hardware failure there is a possibility of running an extra EC2 instance at peak times with the possibility of running a large instance for a peak time when one of the dedicated servers has experienced a problem. The idea of having a mail server die and have someone else’s server take the IP address and receive the mail is too horrible to contemplate, so an Elastic IP address is required. It is quite OK to have a set of mail servers of which not all servers run all the time (this is why the MX record was introduced to the DNS) so having a server run periodically at periods of high load (one of the benefits of the EC2 service) will not require changes to the DNS. I think it’s reasonably important to minimise the amount of changes to the DNS due to the possibility of accidentally breaking it (which is a real catastrophe) and the possibility of servers caching DNS data for longer than they should. The alternative is to change the MX record to not point to the hostname of the server when the instance is terminated. I will be interested to read comments on this issue. The command ec2-allocate-address will allocate a public IP address for your use. Once the address is allocated it will cost $0.01 per hour whenever it is unused. There are also commands ec2-describe-addresses (to list all addresses allocated to you), ec2-release-address (to release an allocated address), ec2-associate-address to associate an IP address with a running instance, and ec2-disassociate-address to remove such an association. The command “ec2-associate-address -i INSTANCE ADDRESS” will associate an IP address with the specified instance (replace INSTANCE with the instance ID - a code starting with “i-” that is returned from ec2-describe-instances. The command “ec2-describe-instances grep ^INSTANCE cut -f2” will give you a list of all instance IDs in use - this is handy if your use of EC2 involves only one active instance at a time (all the EC2 API commands give output in tab-separated lists and can be easily manipulated with grep and cut). Associating an IP address with an instance is documented as taking several minutes, while Amazon provides no guarantees or precise figures as to how long the various operations take it seems that assigning an IP address is one of the slower operations. I expect that is due to the requirement for reconfiguring a firewall device (which services dozens or maybe hundreds of nodes) while creating or terminating an instance is an operation that is limited in scope to a single Xen host. One result that I didn’t expect was that associating an elastic address is that the original address that was assigned to the instance is removed. I had a ssh connection open to an instance when I assigned an elastic address and my connection was broken. It makes sense to remove addresses that aren’t needed (IPv4 addresses are a precious commodity) and further reading of the documentation revealed that this is the documented behavior. One thing I have not yet investigated is whether assigning an IP address from one instance to another is atomic. Taking a few minutes to assign an IP address is usually no big deal, but having an IP address be unusable for a few minutes while in the process of transitioning between servers would be quite inconvenient. It seems that a reasonably common desire would be to have a small instance running and to then transition the IP address to a large (or high-CPU) instance if the load gets high, having this happen without the users noticing would be a good thing.

MJ Ray: Elections and SPI: Open Voting Foundation

So, as everyone knows by now, the party which is a lot like our Conservatives won the US elections (instead of the other party which is a lot like our Conservatives). I’m particularly touched by Aq’s comment:-
The mood in America has been likened to the one here in 97 when we managed to kick the conservatives out for the first time in about 20 years, which amuses me. However, the fact that ours failed to live up to that optimism doesn t mean yours necessarily won t
Oh well, at least it was better than drifting further to the right (in both cases). I’ll wait and see whether it lives up to the optimism. As you may know, SPI is associated with the Open Voting Foundation. That doesn’t sit well with me - while paper voting is imperfect, it seems more verifiable and scalable than machine voting. I’ve been assured that OVF seeks to replace current election machines, rather than spread machine voting to new places and it looks like my area is not under immediate threat (ORG latest news), so I’m not working on it just now. Broadly, I agree with Simon Rumble on Voting machines: a solution searching for a problem?
So without even going into the serious problems with voting machines, it seems they don’t actually solve any actual problems, and I suspect cost a lot more to operate
I’m currently finding out more about standing for election to The Cooperative Group committee and ThePhoneCoop board - I’m not sure yet, but I think both still use paper voting. Cooperatives-SW and TTLLP both use in-person voting. What’s the current thinking here? What’s best?

5 November 2008

Francois Marier: Converting any video to a podcast

If you don't always have time to sit down in front of your computer to watch long video presentations (lectures, talks, etc.), then you might find this simple script useful. That's what I use to convert any video file to a podcast that I can listen to on the go.

First, dump the audio using mplayer to a file called audiodump.wav:
mplayer -vo null -ao pcm:fast input_video_file
Then, if you want, you can downsample that wave file (using sox) since voice doesn't need the same quality as music:
sox audiodump.wav --rate 32000 -1 --channels 1 audiodump_small.wav vol 0.9 dither
Finally, encode the file as in the SPEEX format (if your music player supports it):
speexenc --denoise --vbr --dtx audiodump_small.wav output.spx
You could also use the OGG Vorbis format:
oggenc --downmix --output=output.ogg audiodump.wav
or create an MP3 using lame:
lame -mm audiodump.wav output.mp3
It works very well with Youtube videos, but you have to download the video first using youtube-dl or clive.

Lucas Nussbaum: Universal Studios Automated Copyright Notice System

FTWCA copyright issues, there’s interesting stuff on Universal Studios’ Automated Copyright Notice System website.

4 November 2008

Jaldhar Vyas: Oops!

Well That wasn't supposed to happen. But it did so nothing remains but to congratulate the victors and prepare for the next round. People seem to think I ought to be more upset about this but I'm not. While I'm sure there will be a round of recriminations or two, McCain-Palin gave it as good a shot as they were going to do under the circumstances so there's really no point in wondering about what might have been.

Enrico Zini: Iterating filehandles in python, and buffering

Iterating filehandles in python, and buffering Given this simple python script:
#!/usr/bin/python
from subprocess import *
proc = Popen(["/bin/sh", "-c", "for i in  seq 1 10 ; do echo $i; sleep 1; done"], stdout=PIPE, bufsize=1)
a = proc.stdout.__iter__()
print a.next()
it is interesting to notice that a.next() takes 10 seconds to run. I tried with bufsize=1 (line buffered) and bufsize=0 (no buffering). I tried:
sh -c 'for i in  seq 1 10 ; do echo $i; sleep 1; done'   cat
sh -c 'for i in  seq 1 10 ; do echo $i; sleep 1; done'   less
sh -c 'for i in  seq 1 10 ; do echo $i; sleep 1; done' > /tmp/test

in all those three cases you see the output one line at a time, so it looks like python is doing the buffering. Using readline() instead of the generator works:
#!/usr/bin/python
from subprocess import *
proc = Popen(["/bin/sh", "-c", "for i in  seq 1 10 ; do echo $i; sleep 1; done"], stdout=PIPE, bufsize=1)
print proc.stdout.readline()
Therefore python is doing funny buffering when using __iter__() on a file object. Good to know. Here is how to get an iterator that does not introduce unwanted buffering:
def iterlines(fd):
    while True:
        line = fd.readline()
        if len(line) == 0: break
        yield line

Russell Coker: Support Gay Marriage in case You Become Gay

A common idea among the less educated people who call themselves “conservative” seems to be that they should oppose tax cuts for themselves and support tax cuts for the rich because they might become rich and they want to prepare for that possibility. The US census data [1] shows that less than 1% of males aged 15+ earn $250K. For females it’s less than 0.2%. On the Wikipedia page about homosexuality [2] it is claimed that 2%-7% of the population are gay (and 12% of Norwegians have at least tried it out). Apparently homosexuality can strike suddenly, you never know when a right-wing politician or preacher will suddenly and unexpectedly be compelled to hire gay whores (as Ted Haggard [3] did) or come out of the closet (as Jim Kolbe [4] did). So it seems that based on percentages you are more likely to become gay than to become rich. So it would be prudent to prepare for that possibility and lobby for gay marriage in case your sexual preference ever changes. But on a serious note, of the people who earn $250K or more (an income level that has been suggested for higher tax rates) there will be a great correlation between the amount of education and the early start to a career. Go to a good university and earn more than the median income in your first job, and you will be well on track to earning $250K. A common misconception is that someone who has not had a great education can still be successful by starting their own company. While there are a few people who have done that, the vast majority of small companies fail in the first few years. Working hard doesn’t guarantee success, for a company to succeed you need to have the right product at the right time - this often depends on factors that you can’t predict (such as the general state of the economy and any new products released by larger companies).

2 November 2008

Joerg Jaspert: archive.debian.org, old bugs and list archives

sarge archived As already written a few days ago I was going to archive Sarge on archive.debian.org. That is done, you can get sarge from there now. The dists/sarge directory also already disappeared from the regular mirrors a few days ago. Im not simply deleting all source and binary packages from Sarge. Instead I am doing a removal of 1000 packages every second day, which ends up in batches of about 10000 removed files every other day. While that is a little more work on the archive side I think it pays off - many mirrors, including Debians own ones, limit the amount of files they delete in one mirror run and it is much less work than asking every mirror admin to make sure it will work on their system. Oh, just in case you mirror archive.debian.org somewhere: Make sure to use -H in your rsync call, will save about 30G of disk space.
Sarge AMD64, volatile and backports Now, while I was already working on archive.debian.org I thought it could do a little more than it did in the past. So I also went and put the Sarge AMD64 release on it, in a seperate directory. And as it would have felt lonely I put sarge-backports and sagre-volatile right beside it.
security and non-us non-us.debian.org is a service thats dead since the sarge release. Finally it also got archived on archive.debian.org (it helps that this service is, since a long time, no longer on a host in the US). security.debian.org now also appears on archive.debian.org, and the security archive will soon lose the files of old releases like slink, potato, woody and also sarge.
0.93R6, Rex and Buzz I got a few responses to my post about old releases and now we also provide 0.93R6. And to make it even better we now also have the binary packages for Rex and Buzz again. I still would like to see even older releases, including alpha and beta versions, so if you have such old things somewhere - tell me. Just make sure they somehow include the source too. I do have 0.91 for example, but it is missing any kind of source except for one package and one patchset. :(
Old list archives, old bugs On one of the CD images I thankfully got from J.H.M. Dassen I found another nice thing - old mailinglist archives from 1995 and 1996 as well as old bugs, #350 - #1626. The list- and bugpeople both got a tarball and just need to import them to make them available again. (Well, Don will kill me for that just, the bugs are html and textfile dumps, so he needs to parse them to get them in the right format for debbugs. But I’m sure he will manage. :) ). Comments: 2

Decklin Foster: Tap that class

And now, something entirely impractical. I picked up Beginning Ruby by Peter Cooper the other day to look for some teaching material. Flipping through, I came across a basic feature that had heretofore escaped my notice: the Struct class. If you want to use a class for nothing more than bundling together a few values, you can create a Struct instead of writing out initialize and attr_accessor yourself. The idiom is like this:
class Server < Struct.new(:host, :port, :password)
  def to_s
    port == 6600 ? host : "# host :# port "
  end
end
That particular one's from Njiiri (which may clue you in that it took me several months to get around to writing this post). For educational purposes, it's nice: you can point out how we give a name to a class (I've also tried to explain assignment as "naming" rather than "storing"), that there's an unnamed class (classes are also objects!), and overriding a method (which uses the dynamically defined stuff), without any boilerplate to get in the way. So it's tempting to use this in a lesson. Unfortunately, Ruby is a little bit weird here, and you run into those distracting "practical" issues about the particular language you're working in. Your classes can't subclass Class, and thus you can't say Foo.new like you can Struct.new. Struct is actually implemented in C (or Java, or whatever's native). So you have to do some handwaving. This is because the "metaclasses" we have in Ruby are implemented, so to speak, as singleton classes of objects (including class objects). I do not mean this as a criticism of Matz at all, but they seem like more of a serendipitous thing than an intentional design -- "hey, if we implement classes in this particular way, we get this sort of metaclassing automatically [1]." (The clearest explanation of why this is that I've found is in the first chapter of Advanced Rails by Brad Ediger.) I wanted to be able to just subclass Class, rather than have all that fun power that we normally get to abuse in Ruby, only because I think this is the clearest way to explain the abstraction. Even I still have trouble describing singletons in plain English. Struct is intuitively a class of classes, and factors out similar/boring stuff -- a good practice. It could be an example of how to refactor some simple classes, if only we could follow it. I decided to give up on the idea for my tutorial, but it kept me up at night. Ruby metaclasses clearly can do anything that the sort of Struct-like metaclasses I have in my mind -- "parametric" classes, if you will -- can do, and I can dynamically define just about anything; why not make it happen? We can instantiate Class itself, but the tool we have to shape that class is singleton methods. This can certainly be abstracted away. So, I whipped something up. Before getting to it, though, let's visit a new construct in Ruby 1.9 and 1.8.7: Object#tap. Apart from the obvious debugging use described in its documentation, it makes it quite easy to factor out this pattern:
def gimme_a_thing
  thing = Thing.new
  thing.do_stuff_to_it
  thing
end
Into something closer to the style of functional or declarative programming:
def gimme_a_thing
  Thing.new.tap  thing 
    thing.do_stuff_to_it
  end
end
(Well, "do stuff" is obviously still procedural, but A for effort.) Which one is "better" could probably be the subject of much debate, but: I really prefer the second one; even though it has exactly the same effect, it looks like "what" rather than "how" (something else I try to beat into impressionable young heads. :-)), which is I think easier to write tests for. I'm going to use it here, because it's shorter. Now, Object#tap passes the object as an argument to the block; in our case, we are going to define a metaclass, so we want to work with self, instead. So we define a new version, class_tap -- by analogy with class_def, I suppose --- which class_evals the block rather than simply evaluating it:
class Class
  def class_tap(&blk)
    tap  _self  _self.class_eval &blk  
  end
end
And to do the following trickery, we make use of MetAid, written by why the lucky stiff -- it's very small, so we could always just incorporate the bits we want into the code here, but this short file provides a common vocabulary for talking about metaclass stuff which is quite valuable. Now, we can write a method to create our new classes on the fly. Here's what I came up with:
require 'metaid'
class << Class
  def meta(_super=Object, &blk)
    new.class_tap do                     # 1
      meta_def :new do  *args            # 2
        Class.new(_super).class_tap do   # 3
          class_exec *args, &blk         # 4
        end
      end
    end
  end
end
(Note the "class << Class", opening the singleton, rather than "class Class", opening Class itself. Also, the distinction between new and Class.new -- they are the same method, but from inside the meta_def we're no longer in the Class class.) The lines of meta itself mean:
  1. The value of this thing is a generated class, which we will describe thusly:
  2. Its singleton class has a new method, which gives you a value that is:
  3. Another generated class, which is defined by:
  4. the original block, which now gets run with new's arguments.
Nary an assignment in sight! The (embarrassing) caveat is that methods in the block that defines the new class instance cannot use def to create methods as normal. A def is evaluated in a totally fresh scope (I don't think I get the opinion behind this decision, to be honest), so we need to use class_def instead. This is, I must admit, rather hideous. Perhaps someday the language will change. But, first things first: now we can implement Struct in pure Ruby.
class MyStruct < Class.meta \
  do  *args 
    attr_accessor *args
    class_def :initialize do  *instance_args 
      args.zip(instance_args).each do  attr, val 
        instance_variable_set :"@# attr ", val
      end
    end
  end
end
The real Struct class does a few other nice things for you, but this is the heart of it; I can go back to that Njiiri example and just swap in MyStruct for Struct (Providing an instant performance gain of -200%... :-)). Here's a "shapes" example from my abandoned OO lesson:
class Polygon < Struct.new(:sides)
  def perimeter
    @sides.inject(&:+)
  end
end
class RegularPolygonClass < Class.meta(Polygon) \
  do  n_sides 
    class_def :initialize do  side_length 
      @sides = [side_length] * n_sides
    end
    class_def :area do
      @sides.size * @sides.first**2 / Math.tan(Math::PI / @sides.size) / 4
    end
  end
end
class Square < RegularPolygonClass.new(4); end
class Pentagon < RegularPolygonClass.new(5); end
(Note that area has no free variables and thus could actually be defined with def. It would just look funny.) You only have to change one number here to make new polygon classes, rather than accumulating parameter lint or explicitly subclassing and redefining something implicit just for the derived class [2]. In a way it the exact analogue of the imperative vs. tap style described above. There is quite a bit of aesthetics involved; one way is not "right". Apart from the syntactical wart, I like being able to do things this way. Ruby is, as they say, optimized for programmer happiness and the principle of least surprise. Still, I'm sure it is quite slow, and I don't particularly need it for any real-world application right now. For an intro to OO it's way too much complexity to have lurking unexplained beneath the surface and still requires getting bogged down in the language you happen to be using. But hey! It's neat.

[1]I basically try to do this whenever possible, anyway. Design decisions are like sex: they're better when they're free.
[2]Of course, if Ruby class variables were not leaked across the entire inheritance hierarchy, something as trivial as this one-variable example would be... trivial. At least, few people would actually miss metaprogramming features. Blub blub blub.

Matthew Garrett: Ultamatix

First, let me make one thing clear. This isn't constructive criticism. This is just criticism. It's directed at software that's so wrong-headed that there's no way to make it significantly better, and everyone involved would be much better spending their time doing something else instead of trying to fix any of what I'm about to describe. It's not worth it. Sit in a park or something instead. Meet new and interesting people. Take up a hobby that doesn't involve writing shell scripts for Linux. You'll be happier. I'll be happier. Everyone wins.

Anyway. I wrote about Automatix some time ago. It died and the world became a better place. More recently it's been resurrected as something called Ultamatix. In summary, don't bother. It's crap. And dangerous. But mostly crap. Again, I'm going to utterly ignore the UI code and just concentrate on what it runs.
There's almost certainly more. I got bored. The worrying thing about this is that the Ultamatix author read my criticisms of Automatix and appears to have attempted to fix all of them. The problem with this is that there's clearly a complete lack of understanding of the fundamental problem in several cases. For example, one of my criticisms of Automatix:

sudo sed -i "s/^vboxusers\(.*\):$/vboxusers\1:$AXUSER/" /etc/group

- assumes that the system isn't using some sort of user directory service.


and the Ultamatix response:

Fixed...Got rid of Virtualbox

Except exactly the same problem is present at other points in Ultamatix, as noted above. Taking a bug list and slavishly fixing or deleting all the bugs isn't helpful if you then proceed to add the same bug back in 24 other places. In that respect, it's even worse than Automatix - the author's managed to produce a huge steaming pile of shite despite having been told how to avoid doing so beforehand. He may be no newbie to programming, but if not it's a perfect example of how experience doesn't imply competence.

Don't install this package. Don't let anyone else install this package. If you see anyone advocating the installation of this package, call them a fool. There's absolutely no excuse whatsoever for the existence of this kind of crap.

Minor update:
The above was looking at 1.8.0-4. It turns out that there's a 1.8.0-5 that's not linked off the website. There's no substantive difference, but some of the numbers may be slightly different.

Russell Coker: Integrity and Mailing Lists

One significant dividing factor between mailing lists is the difference between summary lists (where the person who asks a question receives replies off-list and then sends a summary to the list) and the majority of mailing lists which are discussion lists (where every reply goes to the list by default). I have seen an argument put forward that trusting the answers on a mailing list that operates under the summary list model is inherently risky and that peer review is required. It could be argued that the process of sending a summary to the list is the peer review. I’m sure that if someone posts a summary which includes some outrageously bad idea then there will be some commentary in response. Of course the down-side to this is that it takes a few days for responses to the question to arrive and as it’s common that computer problems need to be solved in hours not days the problem will be solved (one way or another) before the summary message is written. But the idea of peer review in mailing lists seems to fall down in many other ways. The first problem with the idea of peer review is that the usual aim of mailing lists is that most people will first ask google and only ask the list if a reasonable google search fails (probably most mailing lists would fall apart under the load of repeated questions otherwise). Therefore I expect that the majority of such problems to be solved by reading a web page (with no peer review that is easily accessible). Some of those web pages contain bad advice and part of the skill involved in solving any problem relates to recognising which advice to follow. Also it’s not uncommon for a question on a discussion list to result in a discussion with two or more radically different points of view being strongly supported. I think that as a general rule there is little benefit in asking for advice if you lack any ability to determine whether the advice is any good, and which of the possible pieces of good advice actually apply to your situation. Sometimes you can recognise good advice by the people who offer it, in a small community such as a mailing list it’s easy to recognise the people who have a history of offering reasonable advice. It seems that the main disadvantage of asking google when compared to asking a mailing list is that the google results will in most cases contain links to web sites written by people who you don’t know. Sometimes the advice is easy to assess, for example if someone recommends a little-known and badly documented command-line option for a utility it’s easy to read the man page and not overly difficult to read the source to discover whether it is a useful solution. Even testing a suggested solution is usually a viable option. Also it’s often the case that doing a google search on a recommended solution will be very informative (sometimes you see web pages saying “here’s something I tried which failed”). Recommendations based on personal experience are less reliable due to statistical issues (consider the the regular disagreements about the reliability of hard disks where some people claim that RAID is not necessary due to not having seen failures while others claim that RAID-5 is inadequate because it has failed them). There are also issues of different requirements, trivial issues such as the amount of money that can be spent will often determine which (if any) of the pieces of good advice can be adopted. The fact that a large number of people (possibly the majority of Internet users) regularly forward as fact rumors that are debunked by Snopes.com (the main site for debunking urban legends) seems to indicate that it is always going to be impossible to increase the quality of advice beyond a certain level. A significant portion of the people on the net are either unwilling to spend a small amount of effort in determining the accuracy of information that they send around or are so gullible that they believe such things beyond the possibility of doubt. Consider that the next time you ask for advice on a technical issue, you may receive a response from someone who forwarded a rumor that was debunked by Snopes. Sometimes technical advice is just inherently dangerous because it is impossible to verify the integrity of some code that is being shared, or because it may be based on different versions of software. In a previous blog post I analyse some issues related to security of the Amazon EC2 service [1]. While the EC2 service is great in many ways (and implements a good well-documented set of security features on the servers) the unsigned code for managing it and the old versions of the images that they offer to customers raise some serious issues that provide avenues for attack. Getting the EC2 management tools to work correctly on Debian is not trivial, I have released patches but will not release packages for legal reasons. It seems most likely to me that someone will release packages based on my patches (either because they don’t care about the legal issues or they have legal advice suggesting that such things are OK - maybe due to residing in a different jurisdiction). Then people who download such packages will have to determine whether they trust the person who built them. They may also have the issue of Amazon offering a newer version of the software than that which is packaged for Debian (for all I know Amazon released a new version yesterday). The term integrity when applied to computers refers to either accidental or malicious damage to data [2]. In the context of mailing list discussions this means both poorly considered advice and acts of malice (which when you consider spam and undisclosed conflicts of interest are actually quite common). If you ask for advice in any forum (and I use the term in it’s broadest sense to cover web “forums”, IRC, twitter, etc) then getting a useful result will depend on having the majority of members of the forum possessing sufficient integrity and skill, being able to recognise the people whose advice should be followed, or being able to recognise good advice on it’s own. I can think of few examples of forums of which I have been involved where the level of skill was sufficient to provide quality answers (and refutations for bad answers) for all areas of discussion that were on topic. People whose advice should generally be followed will often offer advice on areas where their skills are less well developed, someone whose advice can be blindly followed in regard to topic A may not be a reliable source for advice on topic B - which can cause confusion if the topics in question are closely related. Finally a fundamental difference between “peer review” (as applied to conferences and academic journals) is that review for conferences and journals is conducted before the presentation. Not only does the work have to be good enough to pass the review, but the people doing it will never be sure what the threshold is (and will generally want to do more than a minimal effort) so the quality will be quite high. While peer review in mailing lists is mostly based around the presence or absence of flames. A message which doesn’t attract flames will either have some minimal quality or be related to a topic that is not well known (so no-one regards it as being obviously wrong). Update: The “peer review” process of publishing a post on my blog revealed that I had incorrectly used who’s instead of whose.

Next.

Previous.