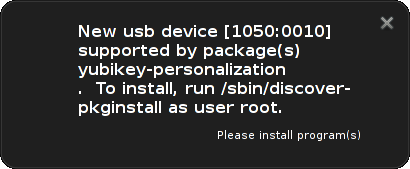
For this prototype to be really useful, some way to automatically
install the proposed packages by pressing the "Please install
program(s)" button should to be implemented.
If this idea seem useful to you, and you want to help make it
happen, please help me update the discover-data database with mappings
from hardware to Debian packages. Check if 'discover-pkginstall -l'
list the package you would like to have installed when a given
hardware device is inserted into your computer, and report bugs using
reportbug if it isn't. Or, if you know of a better way to provide
such mapping, please let me know.
This prototype need more work, and there are several questions that
should be considered before it is ready for production use. Is dbus
the correct way to detect new hardware? At the moment I look for HAL
dbus events on the system bus, because that is the events I could see
on my Debian Squeeze KDE desktop. Are there better events to use?
How should the user be notified? Is the desktop notification
mechanism the best option, or should the background daemon raise a
popup instead? How should packages be installed? When should they
not be installed?
If you want to help getting such feature implemented in Debian,
please send me an email. :)
-d command-line option that changes the
default directory for storing status files.
You can get the latest version from the postfaq distribution page.
Earlier this morning, JJ announced what we had been working on for the last
few weeks: the Rcpp Gallery.
Now, as our luck will have it, the Rcpp-devel list received
his message
but did not transmit it for an apparent mail system outage at WU Vienna: no sign at the
Gmane archive of rcpp-devel
or in the personal mailboxen of myself or anybody I spoke to. Hence, so far,
and preceding this blog announcement, the only way word got out was via this
earlier tweet of mine
from about 12 hours ago.
The Rcpp Gallery is really the brainchild of JJ. It builds on what he
contributed over the last few months in not one but two implementations: Rcpp
Attributes. These are described in a
vignette of their own.
They provide very powerful new functions like sourceCpp
which allow the easiest-yet way to get compiled code into R---see for example these
posts from my blog about
simulating pi
in essentially five lines of R or five lines of C++, or this post about using
the GSL with ease
from R. The Rcpp Gallery also builds on Yihui's excellent
knitr package which
gained the ability to process C++ code just like R code, as well as some
Ruby /
Jekyll magic to build a website on the github
infrastructure. I helped a little on the side by (at long last) learning how
to do prettier websites thanks to Boostrap and its theming extensions.
So what does it do, and what is it for? Have a look around the Rcpp Gallery site.
Each post is based on a single C++ (or Markdown) file which gets digested by
knitr and Rcpp, with the actual output shown alongside the marked up code and
explanatory text. Raw sources are available, just pass them into the
sourceCpp() function from a current Rcpp release and you should have the
same output.
Our idea is to have this as a repository for useful code: from simple and
introductory to fancy and featureful. We already seeded it with several dozen posts
covered anything from lesser known but powerful STL idioms, to Rcpp sugar, to tieing
in Armadillo or GSL, random number generation and of course benchmarking---as
we do love performance.
The entire content is in this github repository,
and our page on
how to contribute
details how you can get involved.
We are looking forward to what is to come. In many ways, we are only just getting started.
A friend wrote me a simple question today. My response turned out to be longer than i expected, but i hope it's useful (and maybe other people will have better suggestions) so i thought i'd share it here too: Angela Starita wrote: I'd like to save my work in a location where I can access it from any computer. I'm wary of using the mechanisms provided by Google and Apple. Can you suggest another service?Here's my reply: I think you're right to be wary of the big cloud providers, who have a tendency to inspect your data to profile you, to participate in arbitrary surveillance regimes, and to try to sell your eyeballs to advertisers. Caveat: You have to trust the client machine too But it's also worth remembering that the network service provider is not the only source of risk. If you really mean "accessing your data from any computer", that means the computer you're using to access the data can do whatever it wants with it. That is, you need to trust both the operator of these "cloud" services, *and* the administrator/operating system of the client computer you're using to access your data. For example, if you log into any "secure" account from a terminal in a web caf , that leaves you vulnerable to the admins of the web caf (and, in the rather-common case of sloppily-administered web terminals, vulnerable to the previous user(s) of the terminal as well). Option 0: Portable physical storage One way to have your data so that you can access it from "any computer" is to not rely on the network at all, but rather to carry a high-capacity MicroSD card (and USB adapter) around with you (you'll probably want to format the card with a widely-understood filesystem like FAT32 instead of NTFS or HFS+ or ext4, which are only understood by some of the major operating systems, but not all). Here is some example hardware: Almost every computer these days has either a microSD slot or a USB port, while some computers are not connected to the network. This also means that you don't have to rely on someone else to manage servers that keep your data available all the time. Note that going the microSD route doesn't remove the caveat about needing to trust the client workstation you're using, and it has another consideration: You'd be responsible for your own backup in the case of hardware failure. You're responsible for your own backup in the case of online storage too, of course -- but the better online companies are probably better equipped than most of us to deal with hardware failure. OTOH, they're also susceptible to some data loss scenarios that we aren't as individual humans (e.g. the company might go bankrupt, or get bought by a competitor who wants to terminate the service, or have a malicious employee who decides to take revenge). Backup of a MicroSD card isn't particularly hard, though: just get a USB stick that's the same size, and regularly duplicate the contents of the MicroSD card to the USB stick. One last consideration is storage size -- MicroSD cards are currently limited to 32GB or 64GB. If you have significantly more data than that, this approach might not be possible, or you might need to switch to a USB hard disk, which would limit your ability to use the data on computers that don't have a USB port (such as some smartphones). Option 1: Proprietary service providers If you don't think this portable physical storage option is the right choice for you, here are a couple proprietary service providers who offer some flavor of "cloud" storage while claiming to not look at the contents of your data: I'm not particularly happy with either of those, though, in part because the local client software they want you to run is proprietary, so there's no way to verify that they are actually unable to access the contents of your data. But i'd be a lot happier with either wuala or spideroak than i would be with google drive, dropbox, or iCloud. Option 2: What i really want I'm much more excited about the network-accessible, free-software, privacy-sensitive network-based storage tool known as git-annex assistant. The project is spearheaded by Joey Hess, who is one of the most skilled and thoughtful software developers i know of. "assistant" (and git-annex, from which it derives) has the advantage of being pretty agnostic about the backend service (many plugins for many different cloud providers) and allows you to encrypt your data locally before sending it to the remote provider. This also means you can put your encrypted data in more than one provider, so that if one of the providers fails for some reason, you can be relatively sure that you have another copy available. But "assistant" won't be ready for Windows or Android for several months (builds are available for Linux and Mac OS X now), so i don't know if it meets the criterion for "accessible from any computer". And, of course, even with the encryption capabilities, the old caveat about needing to trust the local client machine still applies.
So I got an iPod Nano (6th generation) for Christmas this year, just in time since my trusty old iPod Mini started beg for retirement after almost 8 years of usage.
Since my old iPod was working like a charm all those years I expected a smooth sailing when I plugged in my new iPod Nano. Gnome recognized it correctly and mounted the device. The iPod showed up in Rhythmbox as I was used to and I started to fill it with some music. Everything worked as expected: Rhythmbox copied the music to the iPod without complaining and after unmounting the iPod and starting it it was emtpy. Whait, what? Why is it empty? Didn t I just So I tried again, and again with the same result.
Half an hour later I found out that libgpod (the iPod driver for Linux) supports all iPods except the iPod Nano 6G. Bummer. Apparently Apple changed the algorithm to calculate the checksums of the files on the device and since that algorithm is unknown you cannot successfully write on it with free software.
That means technically this device is unusable for Linux users since iTunes doesn t run on Linux. However, there seems to be a way to use the iPod Nano with libgpod if you are trusting this guy and willing to use his binary (only!) file with libgpod (which I am not). And somehow the guys over at Spotify managed to get the iPod Nano running in their Linux client but they don t provide the code either.
Being already more than two years old, I don t have much hope that the iPod Nano will work on Linux with libgpod in the foreseeable future. On the bright side I can say the device is not totally useless as it comes with FM radio
I'm looking for a new position as a Software Developer in eastern Switzerland, southern Germany or remote. Please have a look at my CV if some of the following buzzwords sound interesting to you:
This is my monthly summary of my free software related activities. If you re among the people who made a donation to support my work (836.78 , thanks everybody!), then you can learn how I spent your money. Otherwise it s just an interesting status update on my various projects.
Debian Packaging
I uploaded Zim 0.58, WordPress 3.5 (and I had to file a ticket about the availability of sources of minified javascript files again) and another security update for python-django (696535).
Speaking of python-django, I forwarded one bug report of Anders Kaseorg concerning Django s bash completion (#695811).
I also sponsored the upload of ledgersmb 1.3.25-1.
Other Debian work
I contributed some patches to improve debian-installer support in live-build. I also added a work-around for bug #652946 in live-installer and committed a fix for this same bug in a jessie branch of partman-target.
I also prepared a bugfix for a counter-productive behavior of choose-mirror (#695261, it was not possible to override the codename of the release to install via preseed if you install from a CD with a full base system).
I discovered an oddity in the Packages.diff/Index file for the architectures armhf and s390x, I reported it to ftpmasters in #696792.
(All those issues were discovered while working for a customer)
Debian France
I spent quite some time on Debian France this month again. I started by setting up an internal gitolite to manage our accounting/administrative documents.
Then I updated galette, the web application that we are using to manage our database of members. In the process, I filed two bugs that we discovered. I immediately tested Galette by registering 4 members that joined during the former mini-Debconf in Paris.
We have plans to automate the membership renewal process so we have opened a Paypal account. This month we also cleared the last steps so that I and Sylvestre Ledru have full control on the Debian France bank account.
I also registered the new officers at the Tribunal d instance de Sarreguemines .
Salt bug reports
During the last mini-debconf, I discovered Salt (thanks to Julien Cristau!) and since I had to switch some servers of mine, I took this opportunity to upgrade to wheezy and try out salt at the same time.
It took much more time than expected but the result is pleasant. The configuration of all my servers is now well documented/specified in a central Git repository, and moving services is much easier than before.
In the process, I filed quite some bugs (#2865, #2851, #2866 and #2875), most of them have been fixed in the 0.11.1 release that just happened.
Thanks
I wish you a happy new year and all the best for 2013!
See you next month for a new summary of my activities.
4 comments Liked this article? Click here. My blog is Flattr-enabled.
I'm still working on perl-cross-debian (just uploaded 0.0.2) and there's more to do on that with upstream but part of the reason to work on perl cross-building is to do what I can to help with the ARM64 port.
aarch64-linux-gnu-gcc -Wp,-MD,usr/klibc/.__static_init.o.d -nostdinc -iwithprefix
include -I/ PKGBUILDDIR /usr/include/arch/x86_64 -Iusr/include/arch/x86_64
-I/ PKGBUILDDIR /usr/include/bits64
-Iusr/include/bits64 -I/ PKGBUILDDIR /usr/klibc/../include
-Iusr/klibc/../include -I/ PKGBUILDDIR /usr/include -Iusr/include
-I/ PKGBUILDDIR /linux/include -Ilinux/include
-I/ PKGBUILDDIR /linux/arch/x86/include -Ilinux/arch/x86/include
-D__KLIBC__=2 -D__KLIBC_MINOR__=0 -D_BITSIZE=64 -fno-stack-protector -fwrapv -m64 -Os
-fno-asynchronous-unwind-tables -fomit-frame-pointer -falign-functions=1 -falign-jumps=1 -falign-loops=1
-W -Wall -Wno-sign-compare -Wno-unused-parameter -c -o usr/klibc/__static_init.o usr/klibc/__static_init.c
aarch64-linux-gnu-gcc: error: unrecognized command line option '-m64'
make[4]: *** [usr/klibc/__static_init.o] Error 1
--- a/usr/klibc/arch/arm/MCONFIG
+++ b/usr/klibc/arch/arm/MCONFIG
@@ -30,6 +30,13 @@
ifeq ($(CONFIG_AEABI),y)
KLIBCREQFLAGS += -mabi=aapcs-linux -mno-thumb-interwork
else
+# aarch64
+ifeq ($(CONFIG_AARCH64),y)
+KLIBCREQFLAGS +=
+KLIBCOPTFLAGS += -mgeneral-regs-only
+else
KLIBCREQFLAGS += -mabi=apcs-gnu -mno-thumb-interwork
endif
endif
+endif
+
debian/rules
ifeq ($(DEB_HOST_ARCH),arm64)
DEB_MAKE_ENVVARS := ARCH=arm CONFIG_AARCH64=y CPU_ARCH=armv8-a CPU_TUNE=generic
endif
....
code/debian/cross/klibc/klibc-2.0.1/linux/arch/arm/include -Ilinux/arch/arm/include -D__KLIBC__=2
-D__KLIBC_MINOR__=0 -D_BITSIZE=32 -fno-stack-protector -fwrapv -fno-exceptions -Os
-march=armv8-a -mtune=generic -mgeneral-regs-only -W -Wall -Wno-sign-compare -Wno-unused-parameter
-c -o ../foo.o usr/klibc/arch/arm/crt0.S
usr/klibc/arch/arm/crt0.S: Assembler messages:
usr/klibc/arch/arm/crt0.S:19: Error: operand 1 should be an integer register -- mov r0,sp'
usr/klibc/arch/arm/crt0.S:20: Error: operand 1 should be an integer register -- mov r1,#0'
--- a/usr/klibc/arch/arm/crt0.S
+++ b/usr/klibc/arch/arm/crt0.S
@@ -15,9 +15,13 @@
#ifdef __thumb__
.thumb_func
#endif
-
+#ifdef __aarch64__
+_start: mov x0, sp
+ mov x1, #0
+ bl __libc_init
+#else
_start: mov r0, sp
mov r1, #0
bl __libc_init
-
+#endif
.size _start,.-_start
....
klibc-2.0.1/linux/arch/arm/include -Ilinux/arch/arm/include
-D__KLIBC__=2 -D__KLIBC_MINOR__=0 -D_BITSIZE=32 -fno-stack-protector -fwrapv -fno-exceptions -Os
-march=armv8-a -mtune=generic -mgeneral-regs-only -W -Wall -Wno-sign-compare -Wno-unused-parameter
-c -o usr/klibc/arch/arm/setjmp.o usr/klibc/arch/arm/setjmp.S
usr/klibc/arch/arm/setjmp.S: Assembler messages:
usr/klibc/arch/arm/setjmp.S:32: Error: unknown mnemonic stmia' -- stmia r0, r4,r5,r6,r7,r8,r9,r10,fp,sp,lr '
usr/klibc/arch/arm/setjmp.S:33: Error: operand 1 should be an integer register -- mov r0,#0'
usr/klibc/arch/arm/setjmp.S:34: Error: operand 1 should be an integer register -- mov pc,lr'
usr/klibc/arch/arm/setjmp.S:42: Error: unknown mnemonic ldmia' -- ldmia r0, r4,r5,r6,r7,r8,r9,r10,fp,sp,lr '
usr/klibc/arch/arm/setjmp.S:43: Error: unknown mnemonic movs' -- movs r0,r1'
usr/klibc/arch/arm/setjmp.S:44: Error: unknown mnemonic moveq' -- moveq r0,#1'
usr/klibc/arch/arm/setjmp.S:45: Error: operand 1 should be an integer register -- mov pc,lr'
make[5]: *** [usr/klibc/arch/arm/setjmp.o] Error 1
ldconfig: /usr/lib/aarch64-linux-gnu/*.so is for unknown machine 183. in every build log (success or fail) is apparently entirely normal until more packages get fixed. Really slows down scanning the build log. =item into a
numeric list, something that I really couldn't fix with Pod::Parser.
Also fixed in this release is the bug that got me started down this path:
mishandling of URLs with anchor text.
This is the second Perl module that I've converted to my new coding style
and augmented test suite, and I'm getting a little bit faster at it, but
it still took me a full day. (Although that included the Pod::Simple
rewrite, which required touching most of the code.) I'm not entirely sure
that should have been my top priority today, but oh well, I had to do it
sometime.
You can get the latest version from my web
tools distribution page. I also uploaded a new Debian package to my
personal repository.
I also released spin 1.80, a follow-on from the previous release, that
fixes a bug in the new code to determine last modification date from Git.
int global = 100;
int function(int i)
return i + global;
$gcc -c function.c $objdump --disassemble function.o 0000000000000000 <function>: 0: 55 push %rbp 1: 48 89 e5 mov %rsp,%rbp 4: 89 7d fc mov %edi,-0x4(%rbp) 7: 8b 05 00 00 00 00 mov 0x0(%rip),%eax # d <function+0xd> d: 03 45 fc add -0x4(%rbp),%eax 10: c9 leaveq 11: c3 retqLets just go through that for clarity:
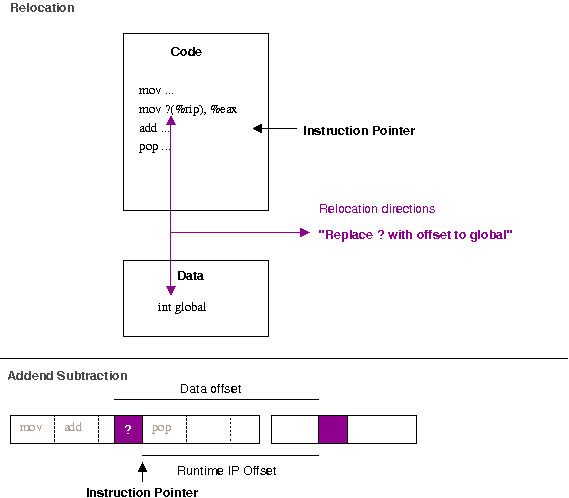
The top portion of the image above gives some idea of how it works. We
can examine relocations in binaries with the readelf tool.
$ readelf --relocs ./function.o Relocation section '.rela.text' at offset 0x518 contains 1 entries: Offset Info Type Sym. Value Sym. Name + Addend 000000000009 000800000002 R_X86_64_PC32 0000000000000000 global + fffffffffffffffcThere are many different types of relocations for different situations; the exact rules for different relocation types are described in the ABI documentation for the architecture. The R_X86_64_PC32 relocation is defined as "the base of the section the symbol is within, plus the symbol value, plus the addend". The addend makes it look more tricky than it is; remember that when an instruction is executing the instruction pointer points to the next instruction to be executed. Therefore, to correctly find the data relative to the instruction pointer, we need to subtract the extra. This can be seen more clearly when layed out in a linear fashion (as in the bottom of the above diagram). If you try and build a shared object (dynamic library) with an object file with this type of relocation, you should get something like:
$ gcc -shared function.c /usr/bin/ld: /tmp/ccQ2ttcT.o: relocation R_X86_64_32 against a local symbol' can not be used when making a shared object; recompile with -fPIC /tmp/ccQ2ttcT.o: could not read symbols: Bad value collect2: ld returned 1 exit statusIf you look back at the disassembly, we notice that the R_X86_64_32 relocation has left only 4-bytes (32-bits) of space left for the relocation entry (the zeros in 7: 8b 15 00 00 00 00). So why does this matter when you're creating a shared library? The first thing to remember is that in a shared library situation, we can not depend on the local value of global actually being the one we want. Consider the following example, where we override the value of global with a LD_PRELOAD library.
$ cat function.c
int global = 100;
int function(int i)
return i + global;
$ gcc -fPIC -shared -o libfunction.so function.c
$ cat preload.c
int global = 200;
$ gcc -shared preload.c -o libpreload.so
$ cat program.c
#include <stdio.h>
int function(int i);
int main(void)
printf("%d\n", function(10));
$ gcc -L. -lfunction program.c -o program
$ LD_LIBRARY_PATH=. ./program
110
$ LD_PRELOAD=libpreload.so LD_LIBRARY_PATH=. ./program
210
If the code in libfunction.so were to have a fixed offset into its
own data section, it will not be able to be overridden at run-time by
the value provided by libpreload.so. Additionally, there are only
4-bytes available to patch in for the address of global -- since a
shared library could conceivably be loaded anywhere in the 64-bit
(8-byte) address space we therefore need 8-bytes of space to cover
ourselves for all possible addresses global might turn up at.
The two basic possibilities for an object file are to be either linked
into an executable or linked into a shared-library. In the executable
case, the value of global will be in the exectuable's data
section, which should definitely be reachable with a 32-bit offset of
the current instruction-pointer. The instruction-pointer relative
address can simply be patched in and the executable is finalised.
But what about the shared-library case, where we know the value of
global could essentially be anywhere within the 64-bit address
space? It is possible to leave 8-bytes of space for the address of
global, by telling gcc to use the large-code model. e.g.
$ gcc -c -mcmodel=large function.c $ objdump --disassemble ./function.o ./function.o: file format elf64-x86-64 Disassembly of section .text: 0000000000000000 <function>: 0: 55 push %rbp 1: 48 89 e5 mov %rsp,%rbp 4: 89 7d fc mov %edi,-0x4(%rbp) 7: 48 b8 00 00 00 00 00 movabs $0x0,%rax e: 00 00 00 11: 8b 10 mov (%rax),%edx 13: 8b 45 fc mov -0x4(%rbp),%eax 16: 01 d0 add %edx,%eax 18: 5d pop %rbp 19: c3 retqHowever, this creates a problem if you really want to share this code. By having to patch in an address of global directly, this means the run-time code above does not remain unchanged. Two separate processes therefore can't share this code -- they each need separate copies that are identical but for their own addresses of global patched into it. By enabling Position Independent Code (PIC, with the flag -fPIC) you can ensure the code remains share-able. PIC means that the output binary does not expect to be loaded at a particular base address, but is happy being put anywhere in memory (compare the output of readelf --segments on a binary such as /bin/ls to that of any shared library). This is obviously critical for implementing lazy-loading (i.e. only loaded when required) shared-libraries, where you may have many libraries loaded in essentially any order at any location. Of course, any problem in computer science can be solved with a layer of abstraction and that is essentially what is done when compiling with -fPIC. To examine this case, let's see what happens with PIC turned on.
$ gcc -fPIC -shared -c function.c $ objdump --disassemble ./function.o ./function.o: file format elf64-x86-64 Disassembly of section .text: 0000000000000000 <function>: 0: 55 push %rbp 1: 48 89 e5 mov %rsp,%rbp 4: 89 7d fc mov %edi,-0x4(%rbp) 7: 48 8b 05 00 00 00 00 mov 0x0(%rip),%rax # e <function+0xe> e: 8b 00 mov (%rax),%eax 10: 03 45 fc add -0x4(%rbp),%eax 13: c9 leaveq 14: c3 retqIt's almost the same! We setup the frame pointer with the first two instructions as before. We push the first argument into memory in the pre-allocated "red-zone" as before. Then, however, we do an IP relative load of an address into rax. Next we de-reference this into eax (e.g. eax = *rax in C) before adding the incoming argument to it and returning.
$ readelf --relocs ./function.o Relocation section '.rela.text' at offset 0x550 contains 1 entries: Offset Info Type Sym. Value Sym. Name + Addend 00000000000a 000800000009 R_X86_64_GOTPCREL 0000000000000000 global + fffffffffffffffcThe magic here is again in the relocations. Notice this time we have a P_X86_64_GOTPCREL relocation. This says "replace the data at offset 0xa with the global offset table (GOT) entry of global.
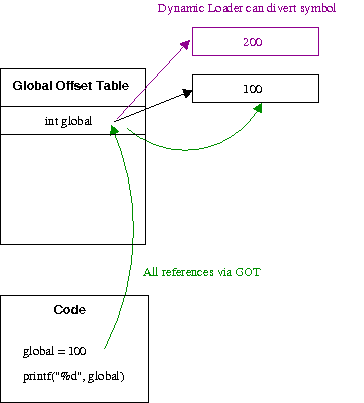
As shown above, the GOT ensures the abstraction required so symbols
can be diverted as expected. Each entry is essentially a pointer to
the real data (hence the extra dereference in the code above). Since
we can assume the GOT is at a fixed offset from the program code
within plus or minus 2Gib, the code can use a 32-bit IP relative
address to gain access to the table entries.
So, taking a look a the final shared-library binary we see a final
offset hard-coded
$ gcc -shared -fPIC -o libfunction.so function.c $ objdump --disassemble ./libfunction.so 00000000000006b0 <function>: 6b0: 55 push %rbp 6b1: 48 89 e5 mov %rsp,%rbp 6b4: 89 7d fc mov %edi,-0x4(%rbp) 6b7: 48 8b 05 8a 02 20 00 mov 0x20028a(%rip),%rax # 200948 <_DYNAMIC+0x1d8> 6be: 8b 10 mov (%rax),%edx 6c0: 8b 45 fc mov -0x4(%rbp),%eax 6c3: 01 d0 add %edx,%eax 6c5: 5d pop %rbp 6c6: c3 retq 6c7: 90 nopEvery process who wants to share this code just needs to make sure they have their unique address of global at 0x20028a(%rip). Since each process has a separate address-space, this means they can all have different values for global but share the same code! Thus the default of the small-code model is sensible. It is exceedingly rare for an executable to need more than 4-byte offsets for a relative access to a variable in it's data region, so using a full 8-byte value would just be a waste of space. Although leaving 8-bytes would allow access to the variable anywhere in the 64-bit address space; when building a shared library, you really want to use -fPIC to ensure the library can actually be shared, which introduces a different relocation and access to data via the GOT. This should explain why gcc -shared function.c works on x86-32, but does not work on x86-64. Inspecting the code reveals why:
$ objdump --disassemble ./function.o 00000000 <function>: 0: 55 push %ebp 1: 89 e5 mov %esp,%ebp 3: a1 00 00 00 00 mov 0x0,%eax 8: 03 45 08 add 0x8(%ebp),%eax b: 5d pop %ebp c: c3 ret $ readelf --relocs ./function.o Relocation section '.rel.text' at offset 0x2ec contains 1 entries: Offset Info Type Sym.Value Sym. Name 00000004 00000701 R_386_32 00000000 globalWe start out the same, with the first two instructions setting up the frame pointer. However, next we load a memory value into eax -- as we can see from the relocation information, the address of global. Next we add the incoming argument from the stack (0x8(%ebp)) to the value in this memory location; implicitly dereferencing it. But since we only have a 32-bit address-space, the 4-bytes allocated is enough to access any possible address. So while this can work, you're not creating position-independent code and hence not enabling code-sharing. The disadvantage of PIC code is that you require "bouncing" through the GOT, which requires more loads and reads to find an address than directly referencing it. However, if your program is at the point that this is becoming a performance issue you're probably not reading this blog! Hopefully, this helps clear up that possibly cryptic error message. Further searches around position-independent code, global-offset tables and code-sharing should also yield you more information if it remains unclear.
This issue is about a bit specific situation in Germany and it's (mainly tax-financed) public service broadcasting. If you think you are not interested, please skip this entry. :)
Just beginning from scratch... In Germany we have (like most european countries) a public service broadcasting. Starting with 2013 the system collecting the funding of the public service broadcasting changed from GEZ to Beitragsservice.
On Twitter the author stated that the shutdown was cause by problems with the copyright law. Das Erste, ZDF and WDR denied that they has anything todo with this recent issue. The question is ... what is the direct cause for shutting down such a good service. This smells a bit like the PirateBay issue, but in this case the content which is Mediathek providing access to isn't pirated, but legal hosted. So where is the real issue?
In my mind, the german citizen has payed to produce this content and should have the right to access the content is an usable way. The Mediathek App did provide such a way and it is really pissing me off that this access isn't available anymore, at least for this reason. Actually I don't see any solution to access our payed content in a decent way.
Footnote: I think it's obscenely, that publishing houses and commercial broadcaster trying to gain their turnover at the expense of the german citizen by forcing the german legislature to implement Depublication,.
t
directory and (mostly) run make test with no further customization.
If you want to see the driver scripts for all of the below that I'm
currently using, see the t directory of the
Term::ANSIColor distribution. They'll
slowly make their way into my other modules, and probably, despite the
name of the package, rra-c-util, since
that's my equivalent of gnulib and I have tools to synchronize shared code
from that package. The driver script generally tests whether the module
is installed, skips the test if not, and otherwise dispatches to the "test
everything" routine in the module.
Test::MinimumVersion: This tests that you're not accidentally
using a newer Perl feature than you were expecting. It's very handy if
you want to support backward compatibility to a particular version of
Perl. It knows about features as far back as 5.004_05. It won't be able
to catch everything, but it will catch some of the most obvious things.
Test::Perl::Critic: This is sort of the thousand-pound gorilla.
Test::Perl::Critic runs all of your code through perlcritic and reports
any errors. You will probably need to combine this with a perlcriticrc
file in your distribution that you configure it to use, since otherwise
the person running the tests may have customized perlcritic. If you let
it run perltidy to check for formatting problems, you'll also want a
perltidyrc. See the driver script mentioned above for how I set that up.
I usually configure this test to only run for me (by checking an
environment variable) since the results vary a lot depending on what
version of perlcritic is installed, and it's likely new versions will
cause the test to start failing. If you use this, expect to need to add
## no critic annotations to your code.
Test::Pod: Checks for syntax errors in your POD documentation
so that you won't have those embarassing POD ERRORS sections. Note that
the latest version of podlators turns
syntax errors into fatal errors, so soon you won't have to worry as much
about this. But if you'd been using this module all along, you wouldn't
have to worry about the fact that pod2man may start faliing due to syntax
errors you never fixed!
Test::Pod::Coverage: Only of interest to module distributions,
not ramdom scripts, this checks that every sub provided by your module has
POD documentation. It understands various subs that don't need to be
documented (such as the ones you provide to implement a tied class) and
lets you mark some subs as not requiring documentation.
Test::Pod::Spelling: Checks your POD documentation for spelling
mistakes with a spell checker. (Note that perlcritic, and hence
Test::Perl::Critic, can also do this, but I use this module separately
since I think the output is more readable.) You will almost certainly
want to make this test maintainer-only, since spell checkers and spelling
dictionaries vary a lot. But it prevents a lot of embarassment when you
read your documentation on search.cpan.org and find that obvious spelling
error you never saw before.
Test::Strict: Checks all Perl code to ensure that it compiles,
checks whether it has use strict, and optionally checks whether it
has use warnings. This is great; I use this even with packages
that just have a few Perl utility scripts in a package otherwise written
in C, since I previously kept releasing packages with helper scripts with
obvious syntax errors since I didn't run them much. Another place it's
useful is if you have internal Debian packages that wrap up Perl utility
scripts; just create a small test suite with this module and run it from
override_dh_auto_check and you won't ever release a package with scripts
that won't run. You can also do test suite coverage testing with this
module (and Devel::Cover), but that you'll want to mark maintainer-only
since it takes a while.
Test::Synopsis: Checks the code in the SYNOPSIS section of any
POD documentation to ensure that it compiles. No more syntax errors in
your example code in the documentation!
All of these modules are, of course, packaged for Debian (thanks largely
to the wonderful Perl packaging team!), and otherwise available on CPAN.
There are a variety of others, of course; these are just the main ones
that I've found personally useful.
One final whine, however: all this wonderful Perl testing infrastructure
desperately needs a common module and a common interface for providing a
list of files to check. Every one of these modules reinvents that wheel,
and most of them do it a slightly different way than all the others. Most
of them check in either blib or lib (or sometimes both).
Most of them also add t. Most of them don't include
Makefile.PL, but some of them do. Almost none of them look in
examples. Some have a simple way to add more files or directories;
some don't. Some can be run from the t directory and still find
things, but most of them can't. And of course the syntax is different in
every case! Most of the work in my driver scripts is finding the right
way to add a few additional directories to the scope of the testing, and
in one annoying case (Test::Synopsis), I actually had to use
Perl::Critic::Utils (for lack of a better module) to build a list of files
to check instead of using the build-in file list, since the build-in file
list required all module code be in lib.
A module to abstract out all of this and provide a common interface would
be easy to write. Most of the work would involve talking to all the
authors of all these different modules and asking them to use it. If
someone in the Perl community felt like doing that, it would make life so
much easier for everyone.
Big release notes since 1.0:
We ve got a new list dput-ng-maint@lists.alioth.debian.org feel free to subscribe!
1.3:
* Avoid failing on upload if a pre/post upload hook is missing from the
Filesystem.
* Fix "dcut raises FtpUploadException" by correctly initializing the uploader
classes from dcut (Closes: #696467)
1.2:
* Add bash completions for dput-ng (Closes: #695412).
* Add in a script to set the default profile depending on the building
distro (Ubuntu support)
* Fix a bug where meta-class info won't be loaded if the config file has the
same name.
* Add an Ubuntu upload target.
* Added .udeb detection to the check debs hook.
* Catch the correct exception falling out of bin/dcut
* Fix the dput manpages to use --uid rather then the old --dm flag.
* Fix the CLI flag registration by setting required=True
in cancel and upload.
* Move make_delayed_upload above the logging call for sanity's sake.
* Fix "connects to the host even with -s" (Closes: #695347)
Thanks to everone who s contributed!
7 Bernhard R. Link
4 Ansgar Burchardt
3 Luca Falavigna
2 Michael Gilbert
2 Salvatore Bonaccorso
1 Benjamin Drung
1 Gergely Nagy
1 Jakub Wilk
1 Jimmy Kaplowitz
1 Luke Faraone
1 Sandro Tosi
This has been your every-once-in-a-while dput-ng update.
We re looking for more code contributions (to make sure everyone s happy), doc updates (etc) or ideas.
You may have noticed that I recently started posting more updates again. The reason is, I switched over from Wordpress to Octopress as blogging engine.
The idea was driven, cause my used theme K2 got stuck and with the upcoming release of Debian wheezy I'm forced to switch to a more recent Wordpress release, which is likely incompatible.
Let s start a convention: bare-metal machines have the linguistic male
gender ( der Computer , he needs to be
rebooted), whereas VMs have the linguistic female gender ( die virtuelle Maschine , she runs better
since the last upgrade of Linux-KVM), and neutral linguistic gender is
used when you cannot or do not want or need to make such distinction.master:/srv/leader/news/bits-from-the-DPL.txt.201212
Recently, I've started programming in Common Lisp.
My idea here is to use cl-irc, an IRC library
into an event loop. This can be
really useful, for example to trigger action based on time, using timers.
Creating a connection
The first step is to create a basic cl-irc:connection object on our own.
This can be achieved easily with this:
(require :cl-irc)
(defun connect (server)
(cl-irc:make-connection :connection-type 'cl-irc:connection
:client-stream t
:network-stream ?
:server-name server))
cl-async:tcp-connect
to establish a TCP connection.
As you can read in this function's documentation, all we need to pass is the
server address, two callbacks for read and general events, and the :stream
option to get a stream rather than a socket.
So you would do something like:
(require :cl-irc)
(require :cl-async)
(defun connection-socket-read (socket stream)
(format t "We should read the IRC message from ~a ~%" stream))
(defun connection-socket-event (ev)
(format t "Socket event: ~a~%" ev))
(defun connect (server &optional (port 6667))
(cl-irc:make-connection :connection-type 'cl-irc:connection
:client-stream t
:network-stream (as:tcp-connect server port
#'connection-socket-read
#'connection-socket-event
:stream t)
:server-name server))
(as:start-event-loop (lambda () (connect "irc.oftc.net")))
connection-socket-read and handle them in the name of
our connection object you used? We can't link both together at this point.
We can't build a closure, because as the time we use as:tcp-connect we
don't have the cl-irc:connection instance. Also we can't change easily the
read-cb parameter of our network-stream established by as:tcp-connect,
simply because cl-async doesn't use to do allow that.
Building a closure
So one solution here is to hack cl-irc:make-connection so we can build an
cl-irc:connection instance without providing in advance the
network-stream, allowing us to build a closure including the
cl-irc:connection to read event for. This is what we're going to do in the
connect function.
(require :cl-irc)
(require :cl-async)
(require :flexi-streams)
(defun connection-socket-read (connection)
(loop for message = (cl-irc::read-irc-message connection)
while message
do (cl-irc:irc-message-event connection message)))
(defun connection-socket-event (ev)
(format t "Socket event: ~a~%" ev))
(defun connect (server port nickname
&key
(username nil)
(realname nil)
(password nil))
;; Build an instance of cl-irc:connection, without any network/output stream
(let* ((connection (make-instance 'cl-irc:connection
:user username
:password password
:server-name server
:server-port port
:client-stream t))
;; Use as:tcp-connect to build our network stream, and build a
;; closure calling connection-socket-read' with our connection'
;; as arguments
(network-stream (as:tcp-connect server port
(lambda (socket stream)
(declare (ignore socket stream))
(connection-socket-read connection))
#'connection-socket-event
:stream t)))
;; Set the network stream on the connection
(setf (cl-irc:network-stream connection) network-stream)
;; Set the output stream on the connection
(setf (cl-irc:output-stream connection)
;; This is grabbed from cl-irc:make-connection
(flexi-streams:make-flexi-stream
network-stream
:element-type 'character
:external-format '(:utf8 :eol-style :crlf)))
;; Now handle the IRC protocol authentication pass
(unless (null password)
(cl-irc:pass connection password))
(cl-irc:nick connection nickname)
(cl-irc:user- connection (or username nickname) 0 (or realname nickname))
connection))
(as:start-event-loop (lambda () (connect "irc.oftc.net" 6667 "jd-blog")))
cl-irc. Each time the socket has something to read, the
function connection-socket-read will be called on the
non-blocking mode socket. If there's no message to be read, then the
function will exit and the loop will continue to run.
Using timers
You can now modify the last line with this:
(defun say-hello (connection)
(cl-irc:privmsg connection "#jd-blog" "Hey I read your blog!")
(as:delay (lambda () (say-hello connection)) :time 60))
(as:start-event-loop (lambda ()
(let ((connection (connect "irc.oftc.net" 6667 "jd-blog")))
(cl-irc:join connection "#jd-blog")
(say-hello connection))))
Next.