Search Results: "ed"

31 October 2016

Steve McIntyre: Twenty years...

So, it's now been twenty years since I became a Debian Developer. I couldn't remember the exact date I signed up, but I decided to do some forensics to find out. First, I can check on the dates on my first Debian system, as I've kept it running as a Debian system ever since!
jack:~$ ls -alt /etc
...
-rw-r--r--   1 root   root     6932 Feb 10  1997 pine.conf.old
-rw-r--r--   1 root   root     6907 Dec 29  1996 pine.conf.old2
-rw-r--r--   1 root   root    76739 Dec  7  1996 mailcap.old
-rw-r--r--   1 root   root     1225 Oct 20  1996 fstab.old
jack:~$
I know that I did my first Debian installation in late October 1996, migrating over from my existing Slackware installation with the help of my friend Jon who was already a DD. That took an entire weekend and it was painful, so much so that several times that weekend I very nearly bailed and went back. But, I stuck with it and after a few more days I decided I was happier with Debian than with the broken old Slackware system I'd been using. That last file (fstab.old) is the old fstab file from the Slackware system, backed up just before I made the switch. I was already a software developer at the time, so of course the first thing I wanted to do once I was happy with Debian was to become a DD and take over the Debian maintenance of mikmod, the module player I was working on at the time. So, I mailed Bruce to ask for an account (there was none of this NM concept back then!) and I think he replied the next day. Unfortunately, I don't have the email in my archives any more due to a disk crash back in the dim and distant past. But I can see that the first PGP key I generated for the sake of joining Debian dates from October 30th 1996 which gives me a date of 31st October 1996 for joining Debian. Twenty years, wow... Since then, I've done lots in the project. I'm lucky enough to been to 11 DebConfs, hosted all around the world. I'm massively proud to have been voted DPL for two of those twenty years. I've worked on a huge number of different things in Debian, from the audio applications I started with to the installer (yay, how things come back to bite you!), from low-level CD and DVD tools (and making our CD images!) to a wiki engine written in python. I've worked hard to help make the best Operating System on the planet, both for my own sake and the sake of our users. Debian has been both excellent fun and occasionally a huge cause of stress in my life for the last 20 years, but despite the latter I wouldn't go back and change anything. Why? Through Debian, I've made some great friends: in Cambridge, in the UK, in Europe, on every continent. Thanks to you all, and here's to (hopefully) many years to come!

Jonas Meurer: debian lts report 2016.10

Debian LTS Report for October 2016 October 2016 was my second month as a payed Debian LTS Team member. I was allocated 12 hours and spent 10,25 hours of them as follows:

Enrico Zini: Links for November 2016

So You Want To Learn Physics... [archive]
This post is a condensed version of what I've sent to people who have contacted me over the years, outlining what everyone needs to learn in order to really understand physics.
Operation Tamarisk [archive]
Operation Tamarisk was a Cold War-era operation run by the military intelligence services of the U.S., U.K., and France through their military liaison missions in East Germany, that gathered discarded paper, letters, and garbage from Soviet trash bins and military maneuvers, including used toilet paper.
Mortara case
Of how in Bologna, where I live, in the 1850s/1860s, when my grand-grand-granddad lived, the Papal State seized a child from a Jewish family on the basis of a former servant's testimony that she had administered emergency baptism to the boy when he fell sick as an infant.

Chris Lamb: Free software activities in October 2016

Here is my monthly update covering what I have been doing in the free software world (previously):

Debian & Reproducible builds

Whilst anyone can inspect the source code of free software for malicious flaws, most GNU/Linux distributions provide binary (or "compiled") packages to end users. The motivation behind the Reproducible Builds effort is to allow verification that no flaws have been introduced either maliciously and accidentally during this compilation process by promising identical binary packages are always generated from a given source.

  • Presented a talk entitled "Reproducible Builds" talk at Software Freedom Kosova, in Prishtina, Republic of Kosovo.

  • I filed my 2,500th bug in the Debian BTS: #840972: golang-google-appengine: accesses the internet during build.

  • In order to build packages reproducibly, one not only needs identical sources but also some external and sharable definition of the environment used for a particular build, stipulating such things such as the version numbers of the required build-dependencies. It is not currently clear how to handle these .buildinfo files after the archive software has processed them and how to make them available to the world so I started development on a proof-of-concept server to see what issues arise in practice. It is available at buildinfo.debian.net.

  • Chaired an IRC meeting and ran a poll to determine a regular time .

  • Submitted two design proposals to our wiki page.

  • Improvements to our tests.reproducible-builds.org testing framework:

    • Move regular "Scheduled in..." messages to the #debian-reproducible-changes IRC channel.
    • Use our log_info method instead of manual echo calls.
    • Correct an "all sources packages" "all source packages" typo.
    • Submit .buildinfo files to buildinfo.debian.net.
    • Create GPG key on nodes for buildinfo.debian.net at deploy time, not "lazily".

My work in the Reproducible Builds project was also covered in our weekly reports. (#75, #76, #77 & #78).

I also submitted 14 patches to fix specific reproducibility issues in bio-eagle, cf-python, fastx-toolkit, fpga-icestorm, http-icons, lambda-align, mypy, playitslowly, seabios, stumpwm, sympa, tj3, wims-help & xotcl.
Debian LTS

This month I have been paid to work 13 hours on Debian Long Term Support (LTS). In that time I did the following:
  • Seven days of "frontdesk" duties, triaging CVEs, etc.
  • Issued DLA 647-1 for freeimage correcting an out-of-bounds write vulnerability in the XMP image handling functionality.
  • Issued DLA 649-1 for python-django fixing a possible CSRF protection bypass on sites that use Google Analytics.
  • Issued DLA 654-1 for libxfixes preventing an integer overflow when a malicious client sent INT_MAX as a "length".
  • Issued DLA 662-1 for quagga correcting a programming error where two constants were confused that could cause stack overrun in IPv6 routing code.
  • Issued DLA 688-1 for cairo to prevent a DoS attack where a malicious SVG could generate invalid pointers.

Uploads
  • gunicorn:
    • 19.6.0-7 Set supplementary groups when changing uid, add an example systemd .service file to gunicorn-examples, and expand README.Debian to make it clearer what to do now that /etc/gunicorn.d has been removed.
    • 19.6.0-8 Correct previous supplementary groups patch to be compatible with Python 3.
  • redis:
    • 3:3.2.4-2 Ensure that sentinel's configuration actually writes to a pidfile location so that systemd can detect that the daemon has started.
    • 3:3.2.5-1 New upstream release.
  • libfiu:
    • 0.94-8 Fix FTBFS under Bash due to lack of && in debian/rules.
    • 0.94-9 Ensure the build is reproducible by sorting injected modules.
  • aptfs (2:0.8-2) Minor cosmetic changes.

NMUs
  • libxml-dumper-perl (0.81-1.2) Move away from a unsupported debhelper compat level 4.
  • netatalk (2.2.5-1.1) Drop build-dependency on hardening-includes.

QA uploads
  • anon-proxy (00.05.38+20081230-4) Move to a supported debhelper compatibility level 9.
  • ara (1.0.32) Make the build reproducible.
  • binutils-m68hc1x (1:2.18-8) Make the build reproducible & move to a supported debhelper compatibility level.
  • fracplanet (0.4.0-5) Make the build reproducible.
  • libnss-ldap (265-5) Make the build reproducible.
  • python-uniconvertor (1.1.5-3) Fix an "option release requires an argument" FTBFS. (#839375)
  • ripole (0.2.0+20081101.0215-3) Actually include the ripole binary in package. (#839919) & enable hardening flags.
  • twitter-bootstrap (2.0.2+dfsg-10) Fix incorrect copyright formatting when building under Bash. (#824592)
  • zpaq (1.10-3) Make the build reproducible.


Debian FTP Team

As a Debian FTP assistant I ACCEPTed 147 packages: ace-link, amazon-s2n, avy, basez, bootstrap-vz, bucklespring, camitk, carettah, cf-python, debian-reference, dfcgen-gtk, efivar, entropybroker, fakesleep, gall, game-data-packager, gitano, glare, gnome-panel, gnome-shell-extension-dashtodock, gnome-shell-extension-refreshwifi, gnome-shell-extension-remove-dropdown-arrows, golang-github-gogits-go-gogs-client, golang-github-gucumber-gucumber, golang-github-hlandau-buildinfo, golang-github-hlandau-dexlogconfig, golang-github-hlandau-goutils, golang-github-influxdata-toml, golang-github-jacobsa-crypto, golang-github-kjk-lzma, golang-github-miekg-dns, golang-github-minio-sha256-simd, golang-github-nfnt-resize, golang-github-nicksnyder-go-i18n, golang-github-pointlander-compress, golang-github-pointlander-jetset, golang-github-pointlander-peg, golang-github-rfjakob-eme, golang-github-thecreeper-go-notify, golang-github-twstrike-gotk3adapter, golang-github-unknwon-goconfig, golang-gopkg-dancannon-gorethink.v1, golang-petname, haskell-argon2, haskell-binary-parsers, haskell-bindings-dsl, haskell-deriving-compat, haskell-hackage-security, haskell-hcwiid, haskell-hsopenssl-x509-system, haskell-megaparsec, haskell-mono-traversable-instances, haskell-prim-uniq, haskell-raaz, haskell-readable, haskell-readline, haskell-relational-record, haskell-safe-exceptions, haskell-servant-client, haskell-token-bucket, haskell-zxcvbn-c, irclog2html, ironic-ui, lace, ledger, libdancer2-plugin-passphrase-perl, libdatetime-calendar-julian-perl, libdbix-class-optimisticlocking-perl, libdbix-class-schema-config-perl, libgeo-constants-perl, libgeo-ellipsoids-perl, libgeo-functions-perl, libgeo-inverse-perl, libio-async-loop-mojo-perl, libmojolicious-plugin-assetpack-perl, libmojolicious-plugin-renderfile-perl, libparams-validationcompiler-perl, libspecio-perl, libtest-time-perl, libtest2-plugin-nowarnings-perl, linux, lua-scrypt, mono, mutt-vc-query, neutron, node-ansi-font, node-buffer-equal, node-defaults, node-formatio, node-fs-exists-sync, node-fs.realpath, node-is-buffer, node-jison-lex, node-jju, node-jsonstream, node-kind-of, node-lex-parser, node-lolex, node-loud-rejection, node-random-bytes, node-randombytes, node-regex-not, node-repeat-string, node-samsam, node-set-value, node-source-map-support, node-spdx-correct, node-static-extend, node-test, node-to-object-path, node-type-check, node-typescript, node-unset-value, nutsqlite, opencv, openssl1.0, panoramisk, perl6, pg-rage-terminator, pg8000, plv8, puppet-module-oslo, pymoc, pyramid-jinja2, python-bitbucket-api, python-ceilometermiddleware, python-configshell-fb, python-ewmh, python-gimmik, python-jsbeautifier, python-opcua, python-pyldap, python-s3transfer, python-testing.common.database, python-testing.mysqld, python-testing.postgresql, python-wheezy.template, qspeakers, r-cran-nleqslv, recommonmark, rolo, shim, swift-im, tendermint-go-clist, tongue, uftrace & zaqar-ui.

Antoine Beaupr : My free software activities, October 2016

Debian Long Term Support (LTS) This is my 7th month working on Debian LTS, started by Raphael Hertzog at Freexian, after a long pause during the summer. I have worked on the following packages and CVEs: I have also helped review work on the following packages:
  • imagemagick: reviewed BenH's work to figure out what was done. unfortunately, I forgot to officially take on the package and Roberto started working on it in the meantime. I nevertheless took time to review Roberto's work and outline possible issues with the original patchset suggested
  • tiff: reviewed Raphael's work on the hairy TIFFTAG_* issues, all the gory details in this email
The work on ImageMagick and GraphicsMagick was particularly intriguing. Looking at the source of those programs makes me wonder why were are still using them at all: it's a tangled mess of C code that is bound to bring up more and more vulnerabilities, time after time. It seems there's always an "Magick" vulnerability waiting to be fixed out there... I somehow hoped that the fork would bring more stability and reliability, but it seems they are suffering from similar issues because, fundamentally, they haven't rewritten ImageMagick... It looks this is something that affects all image programs. The review I have done on the tiff suite give me the same shivering sensation as reviewing the "Magick" code. It feels like all image libraries are poorly implemented and then bound to be exploited somehow... Nevertheless, if I had to use a library of the sort in my software, I would stay away from the "Magick" forks and try something like imlib2 first... Finally, I also did some minor work on the user and developer LTS documentation and some triage work on samba, xen and libass. I also looked at the dreaded CVE-2016-7117 vulnerability in the Linux kernel to verify its impact on wheezy users. I also looked at implementing a --lts flag for dch (see bug #762715). It was difficult to get back to work after such a long pause, but I am happy I was able to contribute a significant number of hours. It's a bit difficult to find work sometimes in LTS-land, even if there's actually always a lot of work to be done. For example, I used to be one of the people doing frontdesk work, but those duties are now assigned until the end of the year, so it's unlikely I will be doing any of that for the forseable future. Similarly, a lot of packages were assigned when I started looking at the available packages. There was an interesting discussion on the internal mailing list regarding unlocking package ownership, because some people had packages locked for weeks, sometimes months, without significant activity. Hopefully that situation will improve after that discussion. Another interesting discussion I participated in is the question of whether the LTS team should be waiting for unstable to be fixed before publishing fixes in oldstable. It seems the consensus right now is that it shouldn't be mandatory to fix issues in unstable before we fix security isssues in oldstable and stable. After all, security support for testing and unstable is limited. But I was happy to learn that working on brand new patches is part of our mandate as part of the LTS work. I did work on such a patch for tar which ended up being adopted by the original reporter, although upstream ended up implementing our recommendation in a better way. It's coincidentally the first time since I start working on LTS that I didn't get the number of requested hours, which means that there are more people working on LTS. That is a good thing, but I am worried it may also mean people are more spread out and less capable of focusing for longer periods of time on more difficult problems. It also means that the team is growing faster than the funding, which is unfortunate: now is a good time as any to remind you to see if you can make your company fund the LTS project if you are still running Debian wheezy.

Other free software work It seems like forever that I did such a report, and while I was on vacation, a lot has happened since the last report.

Monkeysign I have done extensive work on Monkeysign, trying to bring it kicking and screaming in the new world of GnuPG 2.1. This was the objective of the 2.1 release, which collected about two years of work and patches, including arbitrary MUA support (e.g. Thunderbird), config files support, and a release on PyPI. I have had to release about 4 more releases to try and fix the build chain, ship the test suite with the program and have a primitive preferences panel. The 2.2 release also finally features Tor suport! I am also happy to have moved more documentation to Read the docs, part of which I mentionned in in a previous article. The git repositories and issues were also moved to a Gitlab instance which will hopefully improve the collaboration workflow, although we still have issues in streamlining the merge request workflow. All in all, I am happy to be working on Monkeysign, but it has been a frustrating experience. In the last years, I have been maintaining the project largely on my own: although there are about 20 contributors in Monkeysign, I have committed over 90% of the commits in the code. New contributors recently showed up, and I hope this will release some pressure on me being the sole maintainer, but I am not sure how viable the project is.

Funding free software work More and more, I wonder how to sustain my contributions to free software. As a previous article has shown, I work a lot on the computer, even when I am not on a full-time job. Monkeysign has been a significant time drain in the last months, and I have done this work on a completely volunteer basis. I wouldn't mind so much except that there is a lot of work I do on a volunteer basis. This means that I sometimes must prioritize paid consulting work, at the expense of those volunteer projects. While most of my paid work usually revolves around free sofware, the benefits of paid work are not always immediately obvious, as the primary objective is to deliver to the customer, and the community as a whole is somewhat of a side-effect. I have watched with interest joeyh's adventures into crowdfunding which seems to be working pretty well for him. Unfortunately, I cannot claim the incredible (and well-deserved) reputation Joey has, and even if I could, I can't live with 500$ a month. I would love to hear if people would be interested in funding my work in such a way. I am hesitant in launching a crowdfunding campaign because it is difficult to identify what exactly I am working on from one month to the next. Looking back at earlier reports shows that I am all over the place: one month I'll work on a Perl Wiki (Ikiwiki), the next one I'll be hacking at a multimedia home cinema (Kodi). I can hardly think of how to fund those things short of "just give me money to work on anything I feel like", which I can hardly ask for of anyone. Even worse, it feels like the audience here is either friends or colleagues. It would make little sense for me to seek funding from those people: colleagues have the same funding problems I do, and I don't want to empoverish my friends... So far I have taken the approach of trying to get funding for work I am doing, bit by bit. For example, I have recently been told that LWN actually pays for contributed articles and have started running articles by them before publishing them here. This is looking good: they will publish an article I wrote about the Omnia router I have recently received. I give them exclusive rights on the article for two weeks, but I otherwise retain full ownership over the article and will publish them after the exclusive period here. Hopefully, I will be able to find more such projects that pays for the work I do on a day to day basis.

Open Street Map editing I have ramped up my OpenStreetMap contributions, having (temporarily) moved to a different location. There are lots of things to map here: trails, gaz stations and lots of other things are missing from the map. Sometimes the effort looks a bit ridiculous, reminding me of my early days of editing OSM. I have registered to OSM Live, a project to fund OSM editors that, I must admit, doesn't help much with funding my work: with the hundreds of edits I did in October, I received the equivalent of 1.80$CAD in Bitcoins. This may be the lowest hourly salary I have ever received, probably going at a rate of 10 per hour! Still, it's interesting to be able to point people to the project if someone wants to contribute to OSM mappers. But mappers should have no illusions about getting a decent salary from this effort, I am sorry to say.

Bounties I feel this is similar to the "bounty" model used by the Borg project: I claimed around $80USD in that project for what probably amounts to tens of hours of work, yet another salary that would qualify as "poor". Another example is a feature I would like to implement in Borg: support for protocols other than SSH. There is currently no bounty on this, but a similar feature, S3 support has one of the largest bounties Borg has ever seen: $225USD. And the claimant for the bounty hasn't actually implemented the feature, instead backing up to S3, the patch (to a third-party tool) actually enables support for Amazon Cloud Drive, a completely different API. Even at $225, I wouldn't be able to complete any of those features and get a decent salary. As well explained by the Snowdrift reviews, bounties just don't work at all... The ludicrous 10% fee charged by Bountysource made sure I would never do business with them ever again anyways.

Other work There are probably more things I did recently, but I am having difficulty keeping track of the last 5 months of on and off work, so you will forgive that I am not as exhaustive as I usually am.

James Bromberger: The Debian Cloud Sprint 2016

I m at an airport, about to board the first of three flights across the world, from timezone +8 to timezone -8. I ll be in transit 27 hours to get to Seattle, Washington state. I m leaving my wife and two young children behind. My work has given me a days worth of leave under the Corporate Social Responsibility program, and I m taking three days annual leave, to do this. 27 hours each way in transit, for 3 days on the ground. Why? Backstory I started playing in technology as a kid in the 1980s; my first PC was a clone (as they were called) 286 running MS-DOS. It was clunky, and the most I could do to extend it was to write batch scripts. As a child I had no funds for commercial compilers, no network connections (this was pre Internet in Australia), no access to documentation, and no idea where to start programming properly. It was a closed world. I hit university in the summer of 1994 to study Computer Science and French. I d heard of Linux, and soon found myself installing the Linux distributions of the day. The Freedom of the licensing, the encouragement to use, modify, share, was in stark contrast to the world of consumer PCs of the late 1980 s. It was there at the UCC at UWA I discovered Debian. Some of the kind network/system admins at the University maintained a Debian mirror on the campus LAN, updated regularly and always online. It was fast, and more importantly, free for me to access. Back in the 1990s, bandwidth in Australia was incredibly expensive. The vast distances of the country mean that bandwidth was scarce. Telcos were in races to put fiber between Perth and the Eastern States, and without that in place, IP connectivity was constrained, and thus costly. Over many long days and nights I huddled down, learning window managers, protocols, programming and scripting languages. I became a system/network administrator, web developer, dev ops engineer, etc. My official degree workload, algorithmic complexity, protocol stacks, were interesting, but fiddling with Linux based implementations was practical. Volunteer After years of consuming the output of Debian and running many services with it I decided to put my hand up and volunteer as a Debian Developer: it was time to give back. I had benefited from Debian, and I saw others benefit from it as well. As the 2000 s started, I had my PGP key in the Debian key ring. I had adopted a package and was maintaining it load balancing Apache web servers. The web was yet to expand to the traffic levels you see today; most web sites were served from one physical web server. Site Reliability Engineering was a term not yet dreamed of. What became more apparent was the applicability of Linux, Open Source, and in my line-of-sight Debian to a wider community beyond myself and my university peers. Debain was being used to revive recycled computers that were being donated to charities; in some cases, unable to transfer commercial software licenses with the hardware that was no longer required by organisations that had upgraded. It appeared that Debian was being used as a baseline above which society in general had access to fundamental capability of computing and network services. The removal of subscriptions, registrations, and the encouragement of distribution meant this occurred at rates that could never be tracked, and more importantly, the consensus was that it should not be automatically tracked. The privacy of the user is paramount more important than some statistics for the Developer to ponder. When the Bosnia-Herzegovina war ended in 1995, I recall an email from academics there, having found some connectivity, writing to ask if they would be able to use Debian as part of their re-deployment of services for the Tertiary institutions in the region. This was an unnecessary request as Debian GNU/Linux is freely available, but it was a reminder that, for the country to have tried to procure commercial solutions at that time would have been difficult. Instead, those that could do the task just got on with it. There s been many similar project where the grass-roots organisations non profits, NGOs, and even just loose collectives of individuals have turned to Linux, Open Source, and sometimes Debian to solve their problems. Many fine projects have been established to make technology accessible to all, regardless of race, gender, nationality, class, or any other label society has used to divide humans. Big hat tip to Humanitarian Open Street Map, Serval Project. I ve always loved Debian s position on being the Universal operating system. Its vast range of packages and wide range of computing architectures supported means that quite often a litmus test of is project X a good project? was met with is it packaged for Debian? . That wide range of architectures has meant that administrators of systems had fewer surprises and a faster adoption cycle when changing platforms, such as the switch from x86 32 bit to x86 64 bit. Enter the Cloud I first laid eyes on the AWS Cloud in 2008. It was nothing like the rich environment you see today. The first thing I looked for was my favourite operating system, so that what I already knew and was familiar with was available in this environment to minimise the learning curve. However there were no official images, which was disconcerting. In 2012 I joined AWS as an employee. Living in Australia they hired me into the field sales team as a Solution Architect a sort of pre-sales tech with a customer focused depth in security. It was a wonderful opportunity, and I learnt a great deal. It also made sense (to me, at least) to do something about getting Debian s images blessed. It turned out, that I had to almost define what that was: images endorsed by a Debian Developer, handed to the AWS Marketplace team. And so since 2013 I have done so, keeping track of Debian s releases across the AWS regions, collaborating with other Debian folk on other cloud platforms to attempt a unified approach to generating and maintaining these images. This included (for a stint) generating them into the AWS GovCloud Region, and still into the AWS China (Beijing) Region the other side of the so-called Great Firewall of China. So why the trip? We ve had focus groups at the Debconf (Debian conference) around the world, but its often difficult to get the right group of people in the same rooms at the same time. So the proposal was to hold a focused Debian Cloud Sprint. Google was good enough to host this, for all the volunteers across all the cloud providers. Furthermore, donated funds were found to secure the travel for a set of people to attend who otherwise could not. I was lucky enough to be given a flight. So here I am, in the terminal in Australia: my kids are tucked up in bed, dreaming of the candy they just collected for Halloween. It will be a draining week I am sure, but if it helps set and improve the state of Debian then its worth it.

30 October 2016

Enrico Zini: Bremen Freimarkt Parade

Look! They are having a parade with people dressed like Debian releases! Bremen Freimarkt Parade

Dirk Eddelbuettel: RProtoBuf 0.4.7: Mostly harmless

CRAN requested a release updating any URLs for Omegahat to the (actually working) omegahat.net URL. The RProtoBuf package had this in one code comment (errr...) and on bibfile entry. Oh well -- so that caused this 0.4.7 release which arrived on CRAN today. It contains the requested change, and pretty much nothing else. RProtoBuf provides R bindings for the Google Protocol Buffers ("Protobuf") data encoding and serialization library used and released by Google, and deployed as a language and operating-system agnostic protocol by numerous projects. The NEWS file summarises the release as follows:

Changes in RProtoBuf version 0.4.7 (2016-10-27)
  • At the request of CRAN, two documentation instances referring to the Omegehat repository were updated to http://omegahat.net

CRANberries also provides a diff to the previous release. The RProtoBuf page has an older package vignette, a 'quick' overview vignette, a unit test summary vignette, and the pre-print for the JSS paper. Questions, comments etc should go to the GitHub issue tracker off the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Dirk Eddelbuettel: drat 0.1.2: Mostly harmless

CRAN requested a release updating any URLs for Omegahat to the (actually working) omegahat.net URL. So that caused this 0.1.2 release which arrived on CRAN yesterday. It contains the requested change along with one or two other mostly minor changes which accumulated since the last release. drat stands for drat R Archive Template, and helps with easy-to-create and easy-to-use repositories for R packages. Since its inception in early 2015 it has found reasonably widespread adoption among R users because repositories is what we use. In other words, friends don't let friends use install_github(). Just kidding. Maybe. Or not. The NEWS file summarises the release as follows:

Changes in drat version 0.1.2 (2016-10-28)
  • Changes in drat documentation
    • The FAQ vignette added a new question Why use drat
    • URLs were made canonical, omegahat.net was updated from .org
    • Several files (README.md, Description, help pages) were edited

Courtesy of CRANberries, there is a comparison to the previous release. More detailed information is on the drat page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Iain R. Learmonth: Powers to Investigate

The Communication Data Bill was draft legislation introduced first in May 2012. It sought to compel ISPs to store details of communications usage so that it can later be used for law enforcement purposes. In 2013 the passage of this bill into law had been blocked and the bill was dead. In 2014 we saw the Data Retention and Investigatory Powers Act 2014 appear. This seemed to be in response to the Data Retention Directive being successfully challenged at the European Court of Justice by Digital Rights Ireland on human rights grounds, with a judgment given in 2014. It essentially reimplemented the Data Retention Directive along with a whole load of other nasty things. The Data Retention and Investigatory Powers Act contained a sunset clause with a date set for 2016. This brings us to the Investigatory Powers Bill which it looks will be passing into law shortly. Among a range of nasty powers, this legislation will be able to force ISPs to record metadata about every website you visit, every connection you make to a server on the Internet. This is sub-optimal for the privacy minded, with my primary concern being that this is a treasure trove of data and it s going to be abused by someone. It s going to be too much for someone to resist. The existence of this power in the bill seemed to confuse the House of Lords:
It is not for me to explain why the Government want in the Bill a power that currently does not exist, because internet connection records do not exist, and which the security services say they do not want but which the noble and learned Lord says might be needed in the future. It is not for me to justify this power; I am saying to the House why I do not believe it is justified. The noble and learned Lord and the noble Lord, Lord Rosser, made the point that this is an existing power, but how can you have an existing power to acquire something that will not exist until the Bill is enacted? Lord Paddick (link)
Of course, the internet connection records are meaningless when your traffic is routed via a proxy or VPN, and there is a Kickstarter in progress that I would love to succeed: OnionDSL. The premise of OnionDSL is that instead of having an IPv4/IPv6 connection to the Internet, you join a private network that does not provide any routing to the global Internet and instead provides only a Tor bridge. I cannot think of anything that I do from home that I cannot do via Tor and have been considering switching to Qubes OS as the operating system on my day-to-day laptop to allow me to direct basically everything through Tor. The idea of provisioning a non-IP service via DSL is not new to me, I ve come across it before with cjdns which provides an encrypted IPv6 network using public key cryptography for network address allocation and a distributed hash table for routing. Peering between cjdns nodes can be performed over Ethernet and cjdns over Ethernet could be provisioned in place of the traditional PPP over Ethernet (PPPoE) to provide access directly to cjdns without providing any routing to the global Internet. If OnionDSL is funded, I think it s very likely I would be considering becoming a customer. (Assuming the government doesn t attempt to also outlaw Tor).

29 October 2016

Lars Wirzenius: Obnam 1.20 released

I have just released version 1.20 of Obnam, my backup program. It's been nine months since the previous release, and that's a long time: I've had an exciting year, and not entirely in a good way. Unfortuntely that's eaten up a lot of my free time and enthusiasm for my hobby projects. See below for a snippet of NEWS, with a summary of the user-visible changes. A lot of the effort has gone into improving FORMAT GREEN ALBATROSS, but that isn't documented in the NEWS file. I've received patches and actionable bug reports from a number of people, and I'm grateful for those. I try to credit them by name in the NEWS file. Obnam NEWS This file summarizes changes between releases of Obnam. NOTE: Obnam has an EXPERIMENTAL repository format under development, called green-albatross-20160813. It is NOT meant for real use. It is likely to change in incompatible ways without warning. DO NOT USE it unless you're willing to lose your backup. Version 1.20, released 2016-10-29 Minor changes: Bug fixes:
Iain R. Learmonth: live-wrapper 0.4 released!

Last week saw the quiet upload of live-wrapper 0.4 to unstable. I would have blogged at the time, but there is another announcement coming later in this blog post that I wanted to make at the same time. live-wrapper is a wrapper around vmdebootstrap for producing bootable live images using Debian GNU/Linux. Accompanied by the live-tasks package in Debian, this provides the toolchain and configuration necessary for building live images using Cinnamon, GNOME, KDE, LXDE, MATE and XFCE. There is also work ongoing to add a GNUstep image to this. Building a live image with live-wrapper is easy:
sudo apt install live-wrapper
sudo lwr
This will build you a file named output.iso in the current directory containing a minimal live-image. You can the test this in QEMU:
qemu-system-x86_64 -m 2G -cdrom live.iso
You can find the latest documentation for live-wrapper here and any feedback you have is appreciated. So far it looks that booting from CD and USB with both ISOLINUX (BIOS) and GRUB (EFI) are all working as expected on real hardware. The second announcement that I wanted to accompany this announcement is that we will be running a vmdebootstrap sprint where we will be working on live-wrapper at the MiniDebConf in Cambridge. I will be working on installer integration while Ana Custura will be investigating bootloaders and their customisation. I d like to thank the Debian Project and those who have given donations to it for supporting our travel and accomodation costs for this sprint.

Iain R. Learmonth: live-wrapper 0.4 released!

Last week saw the quiet upload of live-wrapper 0.4 to unstable. I would have blogged at the time, but there is another announcement coming later in this blog post that I wanted to make at the same time. live-wrapper is a wrapper around vmdebootstrap for producing bootable live images using Debian GNU/Linux. Accompanied by the live-tasks package in Debian, this provides the toolchain and configuration necessary for building live images using Cinnamon, GNOME, KDE, LXDE, MATE and XFCE. There is also work ongoing to add a GNUstep image to this. Building a live image with live-wrapper is easy:
sudo apt install live-wrapper
sudo lwr
This will build you a file named output.iso in the current directory containing a minimal live-image. You can the test this in QEMU:
qemu-system-x86_64 -m 2G -cdrom live.iso
You can find the latest documentation for live-wrapper here and any feedback you have is appreciated. So far it looks that booting from CD and USB with both ISOLINUX (BIOS) and GRUB (EFI) are all working as expected on real hardware. The second announcement that I wanted to accompany this announcement is that we will be running a vmdebootstrap sprint where we will be working on live-wrapper at the MiniDebConf in Cambridge. I will be working on installer integration while Ana Custura will be investigating bootloaders and their customisation. I d like to thank the Debian Project and those who have given donations to it for supporting our travel and accomodation costs for this sprint.

Jaldhar Vyas: Dawkins Weasel

Happy Dhanteras from Bappy Lahiri
It's already Dhan Terash so I better pick up the pace if I want to beat my blogging challenge before Diwali so in this post I'll discuss a program I wrote earlier this year.
I dread to look up anything on Wikipedia because I always end up going down a rabbit hole and surfacing hours later on a totally unrelated topic. Case in point, some months ago, I ended up on the page of the title. This is an interesting little experiment illustrating how random selection can result in the evolution of a specific form. The algorithm is:

  1. Start with a random string of 28 characters.
  2. Make 100 copies of this string, with a 5% chance per character of that character being replaced with a random character.
  3. Compare each new string with "METHINKS IT IS LIKE A WEASEL", and give each a score (the number of letters in the string that are correct and in the correct position).
  4. If any of the new strings has a perfect score (== 28), halt.
  5. Otherwise, take the highest scoring string, and go to step 2.
I had to try this myself so I wrote a little implementation in C++. A sample run looks like this:
  
$ ./weasel
0000 DNCFICBLUZVC JF KKNVJJASCJRW (0)
0001 DNIFICOLUZVC JFLIKNVAJASCJEW (6)
0002 DNNWICKSUZVCRSFLIKNVA ASCJEL (11)
0003 DNNWICKSUZVCRSFLIKNVA ASCJEL (11)
0004 MNNVICKSQZVCRSFLIKNVA WSCJEL (13)
0005 MENVICKSQZVCRSFLIKNVA WSCJEL (14)
0006 MENVISKS ZTCRSFLIKNVA WLCJEL (16)
0007 MENVISKS ZTCRSFLIKNVA WLCJEL (16)
0008 MEDHISKS ZTCISFLIKNVA WLCJEL (18)
0009 MEDHISKS ZTCISFLIKNVA WLCJEL (18)
0010 MEDHISKS ZTCISFLIKNVA WLCJEL (18)
0011 MEDHISKS ZTCIS LIKTKA WLCZEL (19)
0012 MEDHISKS ZTCIS LIKTKA WLCZEL (19)
0013 MEDHISKS ZTCIS LIKT A WLCZEL (20)
0014 MEDHISKS ZTCIS LIKT A WLCZEL (20)
0015 MEDHISKS ZTCIS LIKE A WLAZEL (22)
0016 MEDHIGKS ITCIS LIKE A WLAZEL (23)
0017 MEDHIGKS ITCIS LIKE A WLAZEL (23)
0018 MEDHIGKS ITCIS LIKE A WLAZEL (23)
0019 MEDHIGKS ITCIS LIKE A WLAZEL (23)
0020 MEDHIGKS ITCIS LIKE A WLAZEL (23)
0021 MEDHIGKS ITCIS LIKE A WLAZEL (23)
0022 METHINKS ITCIS LIKE A WLASEL (26)
0023 METHINKS ITCIS LIKE A WLASEL (26)
0024 METHINKS ITCIS LIKE A WLASEL (26)
0025 METHINKS ITCIS LIKE A WEASEL (27)
0026 METHINKS ITCIS LIKE A WEASEL (27)
0027 METHINKS ITCIS LIKE A WEASEL (27)
0028 METHINKS ITCIS LIKE A WEASEL (27)
0029 METHINKS ITCIS LIKE A WEASEL (27)
0030 METHINKS ITCIS LIKE A WEASEL (27)
0031 METHINKS ITCIS LIKE A WEASEL (27)
0032 METHINKS ITCIS LIKE A WEASEL (27)
0033 METHINKS ITCIS LIKE A WEASEL (27)
0034 METHINKS ITCIS LIKE A WEASEL (27)
0035 METHINKS ITCIS LIKE A WEASEL (27)
0036 METHINKS ITCIS LIKE A WEASEL (27)
0037 METHINKS ITCIS LIKE A WEASEL (27)
0038 METHINKS ITCIS LIKE A WEASEL (27)
0039 METHINKS ITCIS LIKE A WEASEL (27)
0040 METHINKS ITCIS LIKE A WEASEL (27)
0041 METHINKS ITCIS LIKE A WEASEL (27)
0042 METHINKS ITCIS LIKE A WEASEL (27)
0043 METHINKS ITCIS LIKE A WEASEL (27)
0044 METHINKS ITCIS LIKE A WEASEL (27)
0045 METHINKS ITCIS LIKE A WEASEL (27)
0046 METHINKS ITCIS LIKE A WEASEL (27)
0047 METHINKS ITCIS LIKE A WEASEL (27)
0048 METHINKS ITCIS LIKE A WEASEL (27)
0049 METHINKS ITCIS LIKE A WEASEL (27)
0050 METHINKS ITCIS LIKE A WEASEL (27)
0051 METHINKS ITCIS LIKE A WEASEL (27)
0052 METHINKS ITCIS LIKE A WEASEL (27)
0053 METHINKS ITCIS LIKE A WEASEL (27)
0054 METHINKS IT IS LIKE A WEASEL (28)

My program lets you adjust the input string, the number of copies, and the mutation threshold. I also thought it might be interesting to implement the Generator design pattern. In C++ this is done by making a class which implements begin() and end() methods and atleast a forward iterator. You can find the source code on Github.

28 October 2016

Russ Allbery: Term::ANSIColor 4.06

A small maintenance release to my Perl module for generating and manipulating ANSI color escape sequences. In 4.00, I added 256-color support, using ansi0 through ansi15 for the colors that match the normal 16 colors and then rgbNNN and greyN names for the RGB and greyscale colors. One module user requested the ability to address all of the colors via ansi0 through ansi255 so that there's a consistent naming scheme for all the colors. This release adds that. (The more specific names are still returned by uncolor() when reversing escape sequences.) This module tends to get included all over the place, so I did spend a bit of time when preparing this release trying to determine if adding a bunch more entries to various internal hash tables and arrays would noticably increase memory usage, since Perl is notoriously bad about memory consumption. It does cause a small increase, but it's on the order of about 100KB, and a minimum Perl program to load the module requires about 5.5MB of memory (aie), so it wasn't enough for me to do anything about. It does look like if I lazily added entries to the built-in hash tables and instead added some more code to calculate escape sequences on the fly, I could save about 300KB of memory usage in the module. Not sure if it's worth it given how small the memory usage is compared to Perl itself, but maybe I'll look at that later when I'm feeling like fiddling with the module again. (Oh, and all the documentation was regenerated by DocKnot, since I'm still having fun with that. It needed a few new features, which will be in an upcoming 1.01 release.) You can get the latest version from the Term::ANSIColor distribution page.

Matthew Garrett: Of course smart homes are targets for hackers

The Wirecutter, an in-depth comparative review site for various electrical and electronic devices, just published an opinion piece on whether users should be worried about security issues in IoT devices. The summary: avoid devices that don't require passwords (or don't force you to change a default and devices that want you to disable security, follow general network security best practices but otherwise don't worry - criminals aren't likely to target you.

This is terrible, irresponsible advice. It's true that most users aren't likely to be individually targeted by random criminals, but that's a poor threat model. As I've mentioned before, you need to worry about people with an interest in you. Making purchasing decisions based on the assumption that you'll never end up dating someone with enough knowledge to compromise a cheap IoT device (or even meeting an especially creepy one in a bar) is not safe, and giving advice that doesn't take that into account is a huge disservice to many potentially vulnerable users.

Of course, there's also the larger question raised by the last week's problems. Insecure IoT devices still pose a threat to the wider internet, even if the owner's data isn't at risk. I may not be optimistic about the ease of fixing this problem, but that doesn't mean we should just give up. It is important that we improve the security of devices, and many vendors are just bad at that.

So, here's a few things that should be a minimum when considering an IoT device:
  • Does the vendor publish a security contact? (If not, they don't care about security)
  • Does the vendor provide frequent software updates, even for devices that are several years old? (If not, they don't care about security)
  • Has the vendor ever denied a security issue that turned out to be real? (If so, they care more about PR than security)
  • Is the vendor able to provide the source code to any open source components they use? (If not, they don't know which software is in their own product and so don't care about security, and also they're probably infringing my copyright)
  • Do they mark updates as fixing security bugs? (If not, they care more about hiding security issues than fixing them)
  • Has the vendor ever threatened to prosecute a security researcher? (If so, again, they care more about PR than security)
  • Does the vendor provide a public minimum support period for the device? (If not, they don't care about security or their users)

    I've worked with big name vendors who did a brilliant job here. I've also worked with big name vendors who responded with hostility when I pointed out that they were selling a device with arbitrary remote code execution. Going with brand names is probably a good proxy for many of these requirements, but it's insufficient.

    So here's my recommendations to The Wirecutter - talk to a wide range of security experts about the issues that users should be concerned about, and figure out how to test these things yourself. Don't just ask vendors whether they care about security, ask them what their processes and procedures look like. Look at their history. And don't assume that just because nobody's interested in you, everybody else's level of risk is equal.


  • comment count unavailable comments

    Alessio Treglia: The logical contradictions of the Universe

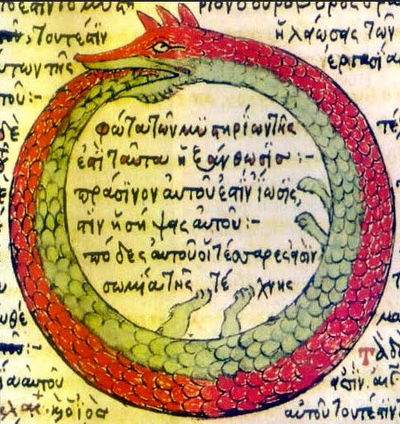
    Ouroboros

    Ouroboros

    Is Erwin Schr dinger s wave function which did in the atomic and subatomic world an operation altogether similar to the one performed by Newton in the macroscopic world an objective reality or just a subjective knowledge? Physicists, philosophers and epistemologist have debated at length on this matter. In 1960, theoretical physicist Eugene Wigner has proposed that the observer s consciousness is the dividing line that triggers the collapse of the wave function[1], and this theory was later taken up and developed in recent years. The rules of quantum mechanics are correct but there is only one system which may be treated with quantum mechanics, namely the entire material world. There exist external observers which cannot be treated within quantum mechanics, namely human (and perhaps animal) minds, which perform measurements on the brain causing wave function collapse [2]. The English mathematical physicist and philosopher of science Roger Penrose developed the hypothesis called Orch-OR (Orchestrated objective reduction) according to which consciousness originates from processes within neurons, rather than from the connections between neurons (the conventional view). The mechanism is believed to be a quantum physical process called objective reduction which is orchestrated by the molecular structures of the microtubules of brain cells (which constitute the cytoskeleton of the cells themselves). Together with the physician Stuart Hameroff, Penrose has suggested a direct relationship between the quantum vibrations of microtubules and the formation of consciousness.

    <Read More [by Fabio Marzocca]>

    Jaldhar Vyas: Get Ready For Bikini Season With These n Weird Tricks

    It all started last June when my son had his Janoi (Yagnopavita) ceremony -- the ritual by which a Brahmana boy becomes "twice-born" and eligible to study the Vedas. As well as a profound religious experience, it is also an important social occasion with a reception for as many friends and family as can attend. (I think our final guest total was ~250.) This meant new outfits for everyone which might be exciting for some people but not me. I still don't know why I couldn't just keep wearing the khes and pitambar from the puja but no, apparently that's a faux pas. So I relented and agreed to wear my "darbari" suit from my wedding. And it didn't fit. I knew I had gained some weight in the intermediate 17 years but the thing was sitcom levels of too small. I ended up having to purchase a new one, a snazzy (and shiny!) maroon number with gold stripes (or were they black stripes?) Problem having been solved, much was eaten, more weight was gained and then I forgot about the whole thing. Tip 1: Actually Do Something. I have over the years tried to improve my physical condition but it has never gotten very far. For instance I have a treadmill/coatrack and a couple of years ago I began using it in earnest. I got to the point where I actually ran a 10K race without dying. But I did not train systematically and I ended up in some pain which caused me to stop working out for a while and then I never got around to restarting. Diets have also failed because I don't have a clear idea of what and how much I am eating. All I know is that women go into the kitchen and when they come out they have food. By what eldritch process this occurs is a mystery, I just eat whats given to me thankful that the magic happens. Once I was moved to try and help but quickly fell afoul of the lack of well-defined algorithms in Gujarati home cooking.
    "How much saffron should I add?"
    "this much."
    "How much is this much in SI units?"
    "You're annoying me. Get out."
    Fast forward to March of this year. For my birthday, my wife got me a Fitbit fitness tracker. This is what I had needed all this time. It measure heart rate, distance travelled, time slept and several other pieces of info you can use to really plan a fitness regimen rationally. For example, I was chagrined to learn that sometimes when I'm at the computer, I am so immobile that the fitbit thought I was asleep. So I started planning to taken more frequent breaks. (A recent firmware upgrade has added the ability to nudge to walk atleast 250 paces each daytime hour which is handy for this.) Also by checking my heart rate I discovered that I went on the treadmill I ran too fast thereby stressing my body for little gain and ending up going too slow to get much aerobic effect. Now I can pace myself appropriately for maximum cardiac efficiency without ending up injuring myself and giving up. I also get a little more activity each day by simple changes such as taking the stairs instead of the lift and instead of getting off at the 14th street PATH I go all the way to 34th street and walk down. Tip 2: You must have data in order to see what you did right or wrong and to plan what you need to do moving forward. One caveat about these fitness trackers. They are not anywhere as accurate as a proper checkup from a doctor who specializes in such things. If you want to do any kind of pro or amateur athletics you probably should not rely on them but for the average shlub who just wants to avoid appearing on the news being winched off his sofa by the fire brigade they are good enough. Another practice I began was keeping a food diary. It can be a real eye-opener to see how much you are actually eating. It is probably much more than you thought. I am fortunate that my diet is pretty good to begin with. Vegetarian, (not vegan, Hindus eat dairy products,) mostly home-cooked with fresh ingredients, not fried or processed, and I don't drink alcohol. However there were a few optimizations I could make. I drink a lot of soda; atleast two cans a day. I really ought to stop altogether but in lieu of that I have atleast switched from Coke to Coke Zero thereby saving a lot of empty calories. I now eat 4 rotlis with my dinner instead of six. We as a family eat more green vegetables instead of potatos, skim milk instead of whole fat, canola oil instead of corn oil, and less rice and don't slather ghee on everything quite so much. One entirely new practice I've adopted that may seem faddish but works for me is intermittent fasting. The idea is to steadily train your body to need less food by eating all your days allowed amount pf calories during a 6-8 hour window and not eating at all during the remaining time. It's hard to get used to for many people but I fast atleast 2-3 times a month for religious reasons anyway so I adapted pretty quickly. The fitbit tells me how many calories I am expending and how many I can eat to maintain a healthy level of weight loss but other than that I don't bother with "food groups" or specific diets such as paleo, or low-carb etc. As long as what you eat is reasonably balanced and you are burning more calories than you are adding, it should be enough for weight loss. Indeed from the end of March to now, I've lost 3 stones (20Kg) even with the occasional "cheat" day. Tip 3: All published diets are bullshit without scientifically proven efficacy. Don't bother with them. Experiment instead and see what works for you and your metabolism. As long as you are getting all the proper nutrients (you shouldn't need a supplement unless you have an actual medical condition.) and you have a net calorie deficit, it's all good. If you eat food you enjoy, you are more likely to stick to your diet. The proper amount of sleep is one area of a healthy lifestyle I am still doing poorly in and the reasons are not all raven-related. I have always had problems with insomnia and was once actually diagnosed with sleep apnea. Losing weight has helped a lot but the fitbit is still reporting that I toss and turn a lot during the night. And that's when I'm in bed in the first place. I stay up much too late which can also lead to subsidiary bad behaviours such as midnight snacking. It's something I need to work on. Tip 4: Stop blogging at all hours of the night, It's not doing you any good. So that's what I'm doing. Moving forward, I need to deal with the sleep thing and I would also like to start some program of strength-training, I'm doing ok in terms of aerobic exercise but from what I've read, you also have to build up muscles to keep weight loss permanent. The difficulty is that it would involve joining a gym and then actually going to that gym so I've put it off for now. The immediate threat is Diwali (and Thanksgiving and Christmas...) My wife bought 4 lbs of sweets today and I can feel their presence in the fridge calling to me.

    27 October 2016

    Russ Allbery: DocKnot 1.00

    I'm a bit of a perfectionist about package documentation, and I'm also a huge fan of consistency. As I've slowly accumulated more open source software packages (alas, fewer new ones these days since I have less day-job time to work on them), I've developed a standard format for package documentation files, particularly the README in the package and the web pages I publish. I've iterated on these, tweaking them and messing with them, trying to incorporate all my accumulated wisdom about what information people need. Unfortunately, this gets very tedious, since I have dozens of packages at this point and rarely want to go through the effort of changing every one of them every time I come up with a better way of phrasing something or change some aspect of my standard package build configuration. I also have the same information duplicated in multiple locations (the README and the web page for the package). And there's a lot of boilerplate that's common for all of my packages that I don't want to keep copying (or changing when I do things like change all eyrie.org URLs to HTTPS). About three years ago, I started seriously brainstorming ways of automating this process. I made a start on it during one self-directed day at my old job at Stanford, but only got it far enough to generate a few basic files. Since then, I keep thinking about it, keep wishing I had it, and keep not putting the work into finishing it. During this vacation, after a week and a half of relaxing and reading, I finally felt like doing a larger development project and finally started working on this for long enough to build up some momentum. Two days later, and this is finally ready for an initial release. DocKnot uses metadata (which I'm putting in docs/metadata) that's mostly JSON plus some documentation fragments and generates README, the web page for the package (in thread, the macro language I use for all my web pages), and (the other thing I've wanted to do and didn't want to tackle without this tool) README.md, a Markdown version of README that will look nice on GitHub. The templates that come with the package are all rather specific to me, particularly the thread template which would be unusable by anyone else. I have no idea if anyone else will want to use this package (and right now the metadata format is entirely undocumented). But since it's a shame to not release things as free software, and since I suspect I may need to upload it to Debian since, technically, this tool is required to "build" the README file distributed with my packages, here it is. I've also uploaded it to CPAN (it's my first experiment with the App::* namespace for things that aren't really meant to be used as a standalone Perl module). You can get the latest version from the DocKnot distribution page (which is indeed generated with DocKnot). Also now generated with DocKnot are the rra-c-util and C TAP Harness distribution pages. Let me know if you see anything weird; there are doubtless still a few bugs.

    26 October 2016

    Christoph Egger: Installing a python systemd service?

    As web search engines and IRC seems to be of no help, maybe someone here has a helpful idea. I have some service written in python that comes with a .service file for systemd. I now want to build&install a working service file from the software's setup.py. I can override the build/build_py commands of setuptools, however that way I still lack knowledge wrt. the bindir/prefix where my service script will be installed. Solution Turns out, if you override the install command (not the install_data!), you will have self.root and self.install_scripts (and lots of other self.install_*). As a result, you can read the template and write the desired output file after calling super's run method. The fix was inspired by GateOne (which, however doesn't get the --root parameter right, you need to strip self.root from the beginning of the path to actually make that work as intended). As suggested on IRC, the snippet (and my software) no use pkg-config to get at the systemd path as well. This is a nice improvement orthogonal to the original problem. The implementation here follows bley.
    
    def systemd_unit_path():
        try:
            command = ["pkg-config", "--variable=systemdsystemunitdir", "systemd"]
            path = subprocess.check_output(command, stderr=subprocess.STDOUT)
            return path.decode().replace('\n', '')
        except (subprocess.CalledProcessError, OSError):
            return "/lib/systemd/system"
    class my_install(install):
        _servicefiles = [
            'foo/bar.service',
            ]
        def run(self):
            install.run(self)
            if not self.dry_run:
                bindir = self.install_scripts
                if bindir.startswith(self.root):
                    bindir = bindir[len(self.root):]
                systemddir = "%s%s" % (self.root, systemd_unit_path())
                for servicefile in self._servicefiles:
                    service = os.path.split(servicefile)[1]
                    self.announce("Creating %s" % os.path.join(systemddir, service),
                                  level=2)
                    with open(servicefile) as servicefd:
                        servicedata = servicefd.read()
                    with open(os.path.join(systemddir, service), "w") as servicefd:
                        servicefd.write(servicedata.replace("%BINDIR%", bindir))
    
    Comments, suggestions and improvements, of course, welcome!

    Next.

    Previous.