Johannes Schauer: Bootstrappable Debian - New Milestone
 This post is about the port bootstrap build ordering tool (naming suggestions
welcome) which was started as a Debian Google Summer of Code project in
2012 and continued to be developed afterwards. Sources are available
through gitorious.
In the end of November 2012, I managed to put down an approximation algorithm
to the feedback arc set problem which allowed to break the dependency
graph into a directed acyclic graph with only few removed build dependencies. I
wrote about this effort on our mailinglist but didnt mention it here
because it was still too much of a proof-of-concept. Later, in January 2013, I
mentioned the result of this algorithm in an email wookey and me wrote to
debian-devel mailinglist.
Many things happened since November 2012:
Processing pipeline instead of monolithic tools
The tools I developed so far tried to accomplish everything by themselves,
reusing functionality implemented in a central library. Therefor, if one wanted
to try out even trivial new things, it mostly meant to hack some OCaml code.
Pietro Abate suggested to instead develop smaller tools which could work
independently of each other, would only execute one algorithm each and could
easily be connected together in different ways to achieve different effects.
This switch is now done and all functionality from the old tools is moved into
a new toolset. The exchange format between the tools is either plain text files
in deb822 control format (Packages/Sources files) or a dependency graph. The
dependency graph is currently marshalled by OCaml but future versions should
work with just passing a GraphML (an XML graph format) representation
around.
This new way of doing things seems close to the UNIX philosophy (each program
does one thing well, data is stored as text, every program is a filter). For
example the deb822 control output can easily be manipulated using
grep-dctrl(1) and there exist many tools which can read, analyze and
manipulate GraphML. It is a big improvement over the old, monolithic tools
which did not allow to manipulate any intermediate result by external, existing
tools. Currently, a shell script (native.sh) will execute all tools in a
meaningful order, connecting them together correctly. The same tools will be
used for a future cross.sh but they will be connected differently.
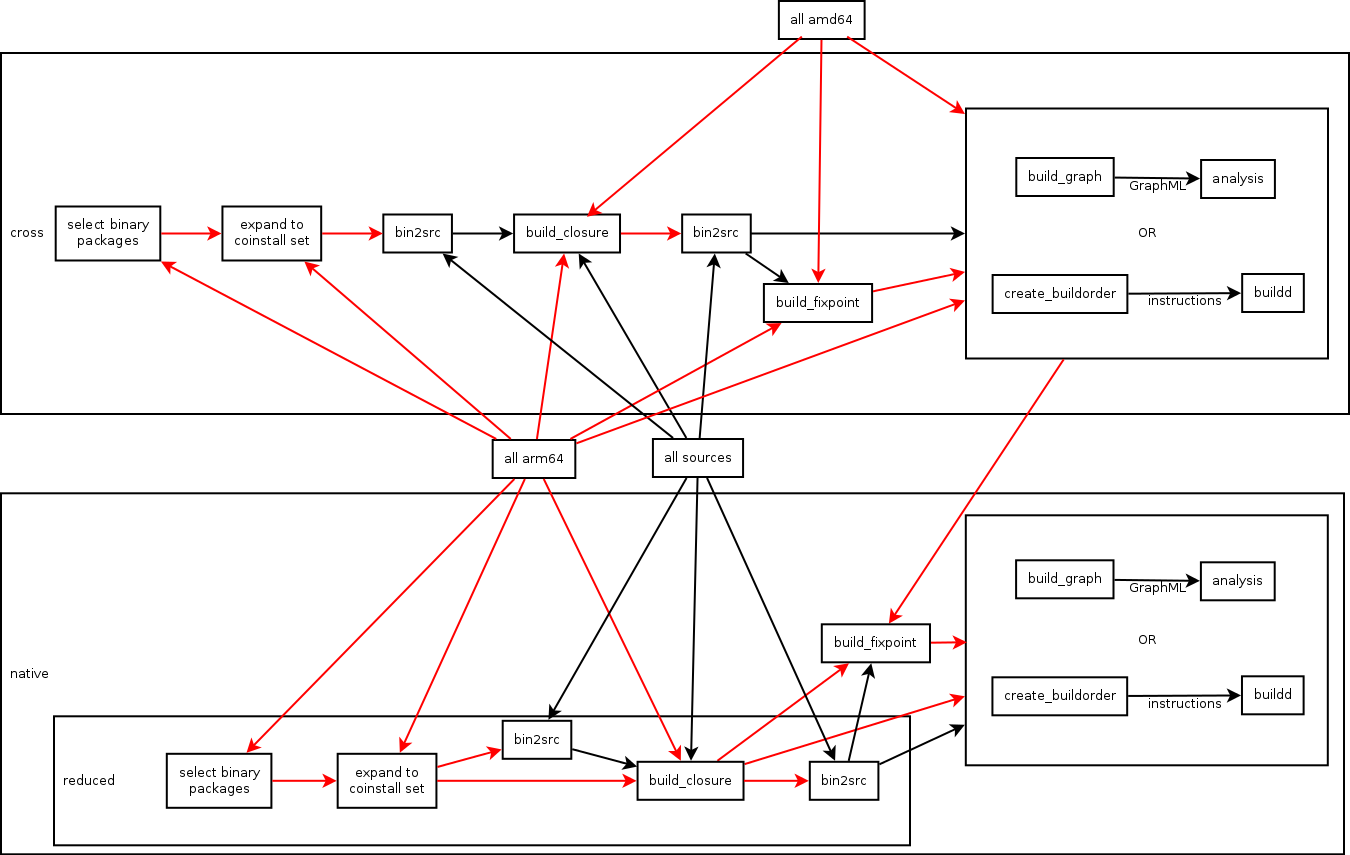
I wrote about a first proposal of what the individual tools should do and how
they should be connected in this email from which I also linked a
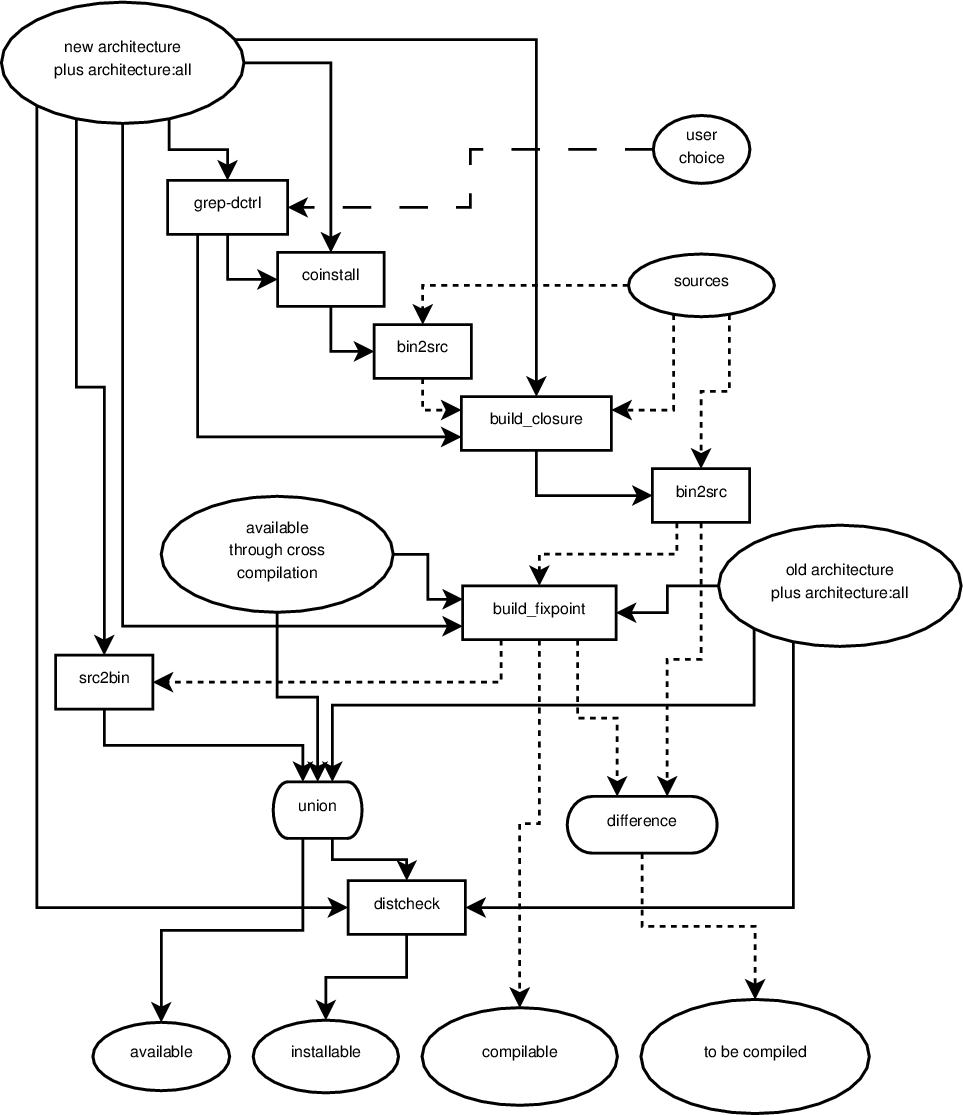
confusing overview of the pipeline. This overview has recently been
improved to be even more confusing and the current version of the lower half
(the native part) now looks like this:
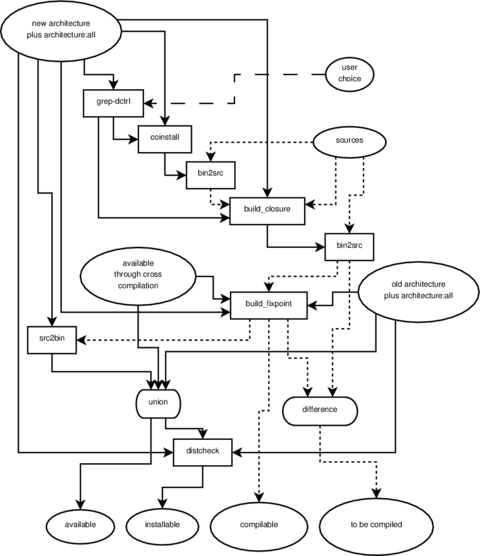 Solid arrows represent a flow of binary packages, dottend arrows represent a
flow of source packages, ovals represent a set of packages, boxes with rounded
corners represent set operations, rectangular boxes represent filters. There is
only one input to a filter, which is the arrow connected to the top of the box.
Outgoing arrows from the bottom represent the filtered input. Ingoing arrows
to either side are arguments to the filter and control how the filter behaves
depending on the algorithm. I will explain this better once the pipeline proved
to be less in flux. The pipeline is currently executed like this by
native.sh.
Two new ways to break dependency cycles have been discovered
So far, we knew of three ways to formally break dependency cycles:
- remove build dependencies through build profiles
- find out that the build dependency is only used to build arch:all
packages and therefor put it into Build-Depends-Indep
- cross compile some source packages
Two new methods can be added to the above:
- if a dependency relationship is not strong (pdf), then a different
installationset can be chosen
- if a depended upon package is Multi-Arch:foreign then a binary package of an
existing architecture might be able to satisfy the dependency.
Dependency graph definition changed
Back in September when I was visiting irill, Pietro found a flaw in how
the dependency graph used to be generated. He supplied a new definition of the
dependency graph which does away with the problem he found. After fixing some
small issues with his code, I changed all the existing algorithms to use the
new graph definition. The old graph is as of today removed from the repository.
Thanks to Pietro for supplying the new graph definition - I must still admit
that my OCaml foo is not strong enough to have come up with his code.
Added complexity for profile built source packages
As mentioned in the introduction, wookey and me addressed the debian-devel list
with a proposal on necessary changes for an automated bootstrapping of Debian.
During the discussiong, two important things came up which are to be considered
by the dependency graph algorithms:
- profile built source packages may not create all binary packages
- profile built source packages may need additional build dependencies
Both things make it necessary to alter the dependency graph during the
generation of a feedback arc set and feedback vertex set beyond the simple
removal of edges. Luckily, the developed approximation algorithms can be
extended to support such changes in the graph.
Different feedback arc set algorithms
The initially developed feedback arc set algorithm is well suited to discover
build dependency edges which should be dropped. It performs far worse when
creating the final build order because it only considers edges by itself and
not how many edges of a source package can be dropped by profile building it.
The adjusted algorithm for generating a build order is more of a feedback
vertex set algorithm because instead of greedily finding the edge with most
cycles through it, it greedily finds the source package which would break most
cycles if it was profile built.
Generating a build order with less profile built source packages
After implementing all the features above I now feel more confident to publish
the current status of the tools to a wider audience.
The following test shows a run of the aforementioned ./native.sh shell
script. Its final output is a list of source packages which have to be profile
built and a build order. Using the resulting build order, starting from a
minimal build system (essential:yes, build-essential and debhelper), all source
packages will be compiled which are needed to compile all binary packages in
the system. The result will therefor be a list of source and binary packages
which fulfill the following property:
- all binary packages can be built from the available source packages
- all source packages can be built with the available binary packages
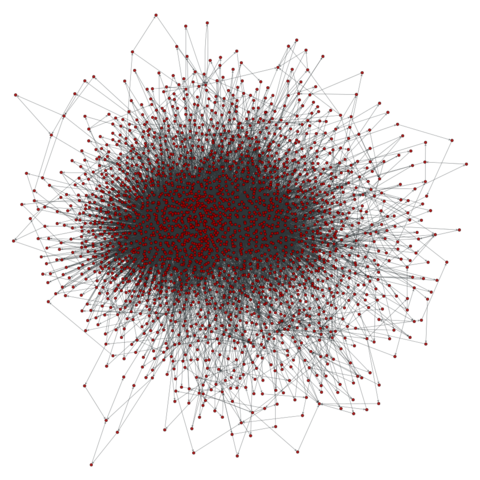
I called this a "reduceded distribution" in earlier posts. The interesting
property of this specific selection is, that it contains the biggest problem
set of Debian when bootstrapping it: a 900 to 1000 nodes big strongly connected
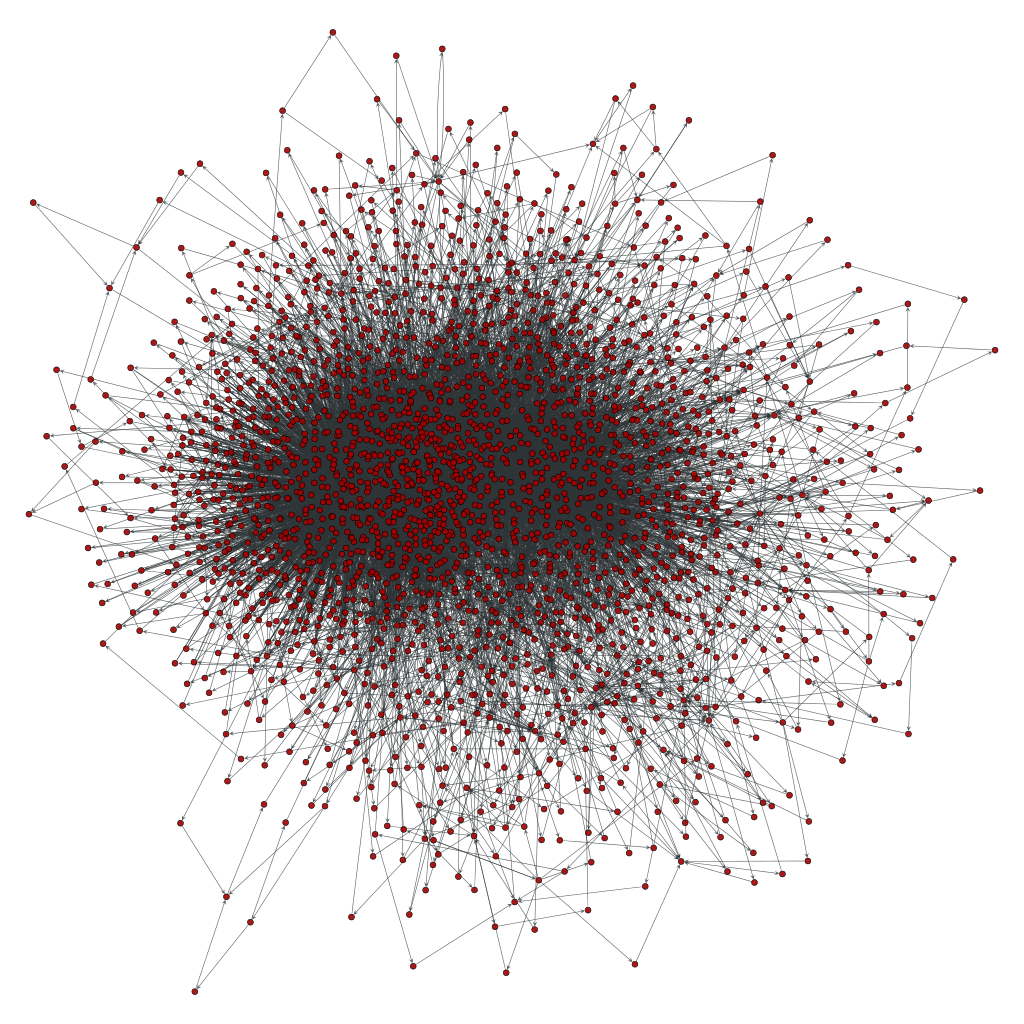
component. Here is a visualization of the problem:
 Source packages do not yet come with build profiles and the cross build
situation can not yet be analyzed, so the following assumptions were made:
- the minimal build system can be cross compiled from nothing
- the reduced build dependencies harvested from Gentoo and supplied by Daniel
Schepler, Patrick McDermott, Thorsten Glaser and Wookey are correct
- the current list of weak build dependencies can be dropped from any
source package
- even when profile built, all source packages build all binary packages
- the 14 forcefully broken build dependencies do not significantly change the
output in real life
The last point is about 14 build dependencies which were decided to be broken
by the feedback arc set algorithm but for which other data sources did not
indicate that they are actually breakable. Those 14 are dynamically generated
by native.sh.
If above assumptions should not be too far from the actual situation, then not
more than 73 source packages have to be modified to bootstrap a reduced
distribution. This reduced distribution even includes dependency-wise "big"
packages like webkit, metacity, iceweasel, network-manager, tracker,
gnome-panel, evolution-data-server, kde-runtime, libav and nautilus. By
changing one line in native.sh one could easily develop a build order which
generates gnome-desktop or really any given (meta-)package selection.
All of native.sh takes only 80 seconds to execute on my system (Core i5, 2.5
GHz, singlethreaded). Here is the final build order which creates 2044 binary
packages from 613 source packages.
- nspr, libio-pty-perl, libmcrypt, unzip, libdbi-perl, cdparanoia, libelf, c-ares, liblocale-gettext-perl, libibverbs, numactl, ilmbase, tbb, check, libogg, libatomic-ops, libnl($), orc($), libaio, tcl8.4, kmod, libgsm, lame, opencore-amr, tcl8.5, exuberant-ctags, mhash, libtext-iconv-perl, libutempter, pciutils, gperf, hspell, recode, tcp-wrappers, fdupes, chrpath, libbsd, zip, procps, wireless-tools, cpufrequtils, ed, libjpeg8, hesiod, pax, less, dietlibc, netkit-telnet, psmisc, docbook-to-man, libhtml-parser-perl, libonig, opensp($), libterm-size-perl, linux86, libxmltok, db-defaults, java-common, sharutils, libgpg-error, hardening-wrapper, cvsps, p11-kit, libyaml, diffstat, m4
- openexr, enca, help2man, speex, libvorbis, libid3tag, patch, openjade1.3, openjade, expat, fakeroot, libgcrypt11($), ustr, sysvinit, netcat, libirman, html2text, libmad, pth, clucene-core, libdaemon($), texinfo, popt, net-tools, tar, libsigsegv, gmp, patchutils($), dirac, cunit, bridge-utils, expect, libgc, nettle, elfutils, jade, bison
- sed, indent, findutils, fastjar, cpio, chicken, bzip2, aspell, realpath, dctrl-tools, rsync, ctdb, pkg-config($), libarchive, gpgme1.0, exempi, pump, re2c, klibc, gzip, gawk, flex-old, original-awk, mawk, libtasn1-3($), flex($), libtool
- libcap2, mksh, readline6, libcdio, libpipeline, libcroco, schroedinger, desktop-file-utils, eina, fribidi, libusb, binfmt-support, silgraphite2.0, atk1.0($), perl, gnutls26($), netcat-openbsd, ossp-uuid, gsl, libnfnetlink, sg3-utils, jbigkit, lua5.1, unixodbc, sqlite, wayland, radvd, open-iscsi, libpcap, linux-atm, gdbm, id3lib3.8.3, vo-aacenc, vo-amrwbenc, fam, faad2, hunspell, dpkg, tslib, libart-lgpl, libidl, dh-exec, giflib, openslp-dfsg, ppl($), xutils-dev, blcr, bc, time, libdatrie, libpthread-stubs, guile-1.8, libev, attr, libsigc++-2.0, pixman, libpng, libssh2, sqlite3, acpica-unix, acl, a52dec
- json-c, cloog-ppl, libverto, glibmm2.4, rtmpdump, libdbd-sqlite3-perl, nss, freetds, slang2, libpciaccess, iptables, e2fsprogs, libnetfilter-conntrack, bash, libthai, python2.6($), libice($), libpaper, libfontenc($), libxau, libxdmcp($), openldap($), cyrus-sasl2($), openssl, python2.7($)
- psutils, libevent, stunnel4, libnet-ssleay-perl, libffi, readline5, file, libvoikko, gamin, libieee1284, build-essential, libcap-ng($), lcms($), keyutils, libxml2, libxml++2.6, gcc-4.6($), binutils, dbus($), libsm($), libxslt, doxygen($)
- liblqr, rarian, xmlto, policykit-1($), libxml-parser-perl, tdb, devscripts, eet, libasyncns, libusbx, icu, linux, libmng, shadow, xmlstarlet, tidy, gavl, flac, dbus-glib($), libxcb, apr, krb5, alsa-lib
- usbutils, enchant, neon27, uw-imap, libsndfile, yasm, xcb-util, gconf($), shared-mime-info($), audiofile, ijs($), jbig2dec, libx11($)
- esound, freetype, libxkbfile, xvidcore, xcb-util-image, udev($), libxfixes, libxext($), libxt, libxrender
- tk8.4, startup-notification, libatasmart, fontconfig, libxp, libdmx, libvdpau, libdrm, libxres, directfb, libxv, libxxf86dga, libxxf86vm, pcsc-lite, libxss, libxcomposite, libxcursor, libxdamage, libxi($), libxinerama, libxrandr, libxmu($), libxpm, libxfont($)
- xfonts-utils, libxvmc, xauth, libxtst($), libxaw($)
- pmake, corosync, x11-xserver-utils, x11-xkb-utils, coreutils, xft, nas, cairo
- libedit, cairomm, tk8.5, openais, pango1.0($)
- ocaml, blt, ruby1.8, firebird2.5, heimdal, lvm2($)
- cvs($), python-stdlib-extensions, parted, llvm-2.9, ruby1.9.1, findlib, qt4-x11($)
- xen, mesa, audit($), avahi($)
- x11-utils, xorg-server, freeglut, libva
- jasper, tiff3, python3.2($)
- openjpeg, qt-assistant-compat, v4l-utils, qca2, jinja2, markupsafe, lcms2, sip4, imlib2, netpbm-free, cracklib2, cups($), postgresql-9.1
- py3cairo, pycairo, pam, libgnomecups, gobject-introspection($)
- gdk-pixbuf, libgnomeprint, gnome-menus, gsettings-desktop-schemas, pangomm, consolekit, vala-0.16($), colord($), atkmm1.6
- libgee, gtk+3.0($), gtk+2.0($)
- gtkmm2.4, poppler($), openssh, libglade2, libiodbc2, gcr($), libwmf, systemd($), gcj-4.7, java-atk-wrapper($)
- torque, ecj($), vala-0.14, gnome-keyring($), gcc-defaults, gnome-vfs($)
- libidn, libgnome-keyring($), openmpi
- mpi-defaults, dnsmasq, wget, lynx-cur, ghostscript, curl
- fftw3, gnupg, libquvi, xmlrpc-c, raptor, liboauth, groff, fftw, boost1.49, apt
- boost-defaults, libsamplerate, cmake, python-apt
- qjson, qtzeitgeist, libssh, qimageblitz, pkg-kde-tools, libical, dwarves-dfsg, automoc, attica, yajl, source-highlight, pygobject, pygobject-2, mysql-5.5($)
- libdbd-mysql-perl, polkit-qt-1, libdbusmenu-qt, raptor2, dbus-python, apr-util
- rasqal, serf, subversion($), apache2
- git, redland
- xz-utils, util-linux, rpm, man-db, make-dfsg, libvisual, cryptsetup, libgd2, gstreamer0.10
- mscgen, texlive-bin
- dvipng, luatex
- libconfig, transfig, augeas, blas, libcaca, autogen, libdbi, linuxdoc-tools, gdb, gpm
- ncurses, python-numpy($), rrdtool, w3m, iproute, gcc-4.7, libtheora($), gcc-4.4
- libraw1394, base-passwd, lm-sensors, netcf, eglibc, gst-plugins-base0.10
- libiec61883, qtwebkit, libvirt, libdc1394-22, net-snmp, jack-audio-connection-kit($), bluez
- redhat-cluster, gvfs($), pulseaudio($)
- phonon, libsdl1.2, openjdk-6($)
- phonon-backend-gstreamer($), gettext, libbluray, db, swi-prolog, qdbm, swig2.0($)
- highlight, libselinux, talloc, libhdate, libftdi, libplist, python-qt4, libprelude, libsemanage, php5
- samba, usbmuxd, libvpx, lirc, bsdmainutils, libiptcdata, libgtop2, libgsf, telepathy-glib, libwnck3, libnotify, libunique3, gnome-desktop3, gmime, glib2.0, json-glib, libgnomecanvas, libcanberra, orbit2, udisks, d-conf, libgusb
- libgnomeprintui, libimobiledevice, nautilus($), libbonobo, librsvg
- evas, wxwidgets2.8, upower, gnome-disk-utility, libgnome
- ecore, libbonoboui
- libgnomeui
- graphviz
- exiv2, libexif, lapack, soprano, libnl3, dbus-c++
- atlas, libffado, graphicsmagick, libgphoto2, network-manager
- pygtk, jackd2, sane-backends, djvulibre
- libav($), gpac($), ntrack, python-imaging, imagemagick, dia
- x264($), matplotlib, iceweasel
- strigi, opencv, libproxy($), ffms2
- kde4libs, frei0r, glib-networking
- kde-baseapps, kate, libsoup2.4
- geoclue, kde-runtime, totem-pl-parser, libgweather, librest, libgdata
- webkit
- zenity, gnome-online-accounts
- metacity, evolution-data-server
- gnome-panel
- tracker
The final recompilation of profile built source packages is omitted. Source
packages marked with a ($) are selected to be profile built. All source
packages listed in the same line can be built in parallel as they do not depend
upon each other.
This order looks convincing as it first compiles a multitude of source packages
which have no or only few build dependencies lacking. Later steps allow fewer
source packages to be compiled in parallel. The amount of needed build
dependencies is highest in the source packages that are built last.
- remove build dependencies through build profiles
- find out that the build dependency is only used to build arch:all packages and therefor put it into Build-Depends-Indep
- cross compile some source packages
- if a dependency relationship is not strong (pdf), then a different installationset can be chosen
- if a depended upon package is Multi-Arch:foreign then a binary package of an existing architecture might be able to satisfy the dependency.
Dependency graph definition changed
Back in September when I was visiting irill, Pietro found a flaw in how
the dependency graph used to be generated. He supplied a new definition of the
dependency graph which does away with the problem he found. After fixing some
small issues with his code, I changed all the existing algorithms to use the
new graph definition. The old graph is as of today removed from the repository.
Thanks to Pietro for supplying the new graph definition - I must still admit
that my OCaml foo is not strong enough to have come up with his code.
Added complexity for profile built source packages
As mentioned in the introduction, wookey and me addressed the debian-devel list
with a proposal on necessary changes for an automated bootstrapping of Debian.
During the discussiong, two important things came up which are to be considered
by the dependency graph algorithms:
- profile built source packages may not create all binary packages
- profile built source packages may need additional build dependencies
Both things make it necessary to alter the dependency graph during the
generation of a feedback arc set and feedback vertex set beyond the simple
removal of edges. Luckily, the developed approximation algorithms can be
extended to support such changes in the graph.
Different feedback arc set algorithms
The initially developed feedback arc set algorithm is well suited to discover
build dependency edges which should be dropped. It performs far worse when
creating the final build order because it only considers edges by itself and
not how many edges of a source package can be dropped by profile building it.
The adjusted algorithm for generating a build order is more of a feedback
vertex set algorithm because instead of greedily finding the edge with most
cycles through it, it greedily finds the source package which would break most
cycles if it was profile built.
Generating a build order with less profile built source packages
After implementing all the features above I now feel more confident to publish
the current status of the tools to a wider audience.
The following test shows a run of the aforementioned ./native.sh shell
script. Its final output is a list of source packages which have to be profile
built and a build order. Using the resulting build order, starting from a
minimal build system (essential:yes, build-essential and debhelper), all source
packages will be compiled which are needed to compile all binary packages in
the system. The result will therefor be a list of source and binary packages
which fulfill the following property:
- all binary packages can be built from the available source packages
- all source packages can be built with the available binary packages
I called this a "reduceded distribution" in earlier posts. The interesting
property of this specific selection is, that it contains the biggest problem
set of Debian when bootstrapping it: a 900 to 1000 nodes big strongly connected
component. Here is a visualization of the problem:
Source packages do not yet come with build profiles and the cross build
situation can not yet be analyzed, so the following assumptions were made:
- the minimal build system can be cross compiled from nothing
- the reduced build dependencies harvested from Gentoo and supplied by Daniel
Schepler, Patrick McDermott, Thorsten Glaser and Wookey are correct
- the current list of weak build dependencies can be dropped from any
source package
- even when profile built, all source packages build all binary packages
- the 14 forcefully broken build dependencies do not significantly change the
output in real life
The last point is about 14 build dependencies which were decided to be broken
by the feedback arc set algorithm but for which other data sources did not
indicate that they are actually breakable. Those 14 are dynamically generated
by native.sh.
If above assumptions should not be too far from the actual situation, then not
more than 73 source packages have to be modified to bootstrap a reduced
distribution. This reduced distribution even includes dependency-wise "big"
packages like webkit, metacity, iceweasel, network-manager, tracker,
gnome-panel, evolution-data-server, kde-runtime, libav and nautilus. By
changing one line in native.sh one could easily develop a build order which
generates gnome-desktop or really any given (meta-)package selection.
All of native.sh takes only 80 seconds to execute on my system (Core i5, 2.5
GHz, singlethreaded). Here is the final build order which creates 2044 binary
packages from 613 source packages.
- nspr, libio-pty-perl, libmcrypt, unzip, libdbi-perl, cdparanoia, libelf, c-ares, liblocale-gettext-perl, libibverbs, numactl, ilmbase, tbb, check, libogg, libatomic-ops, libnl($), orc($), libaio, tcl8.4, kmod, libgsm, lame, opencore-amr, tcl8.5, exuberant-ctags, mhash, libtext-iconv-perl, libutempter, pciutils, gperf, hspell, recode, tcp-wrappers, fdupes, chrpath, libbsd, zip, procps, wireless-tools, cpufrequtils, ed, libjpeg8, hesiod, pax, less, dietlibc, netkit-telnet, psmisc, docbook-to-man, libhtml-parser-perl, libonig, opensp($), libterm-size-perl, linux86, libxmltok, db-defaults, java-common, sharutils, libgpg-error, hardening-wrapper, cvsps, p11-kit, libyaml, diffstat, m4
- openexr, enca, help2man, speex, libvorbis, libid3tag, patch, openjade1.3, openjade, expat, fakeroot, libgcrypt11($), ustr, sysvinit, netcat, libirman, html2text, libmad, pth, clucene-core, libdaemon($), texinfo, popt, net-tools, tar, libsigsegv, gmp, patchutils($), dirac, cunit, bridge-utils, expect, libgc, nettle, elfutils, jade, bison
- sed, indent, findutils, fastjar, cpio, chicken, bzip2, aspell, realpath, dctrl-tools, rsync, ctdb, pkg-config($), libarchive, gpgme1.0, exempi, pump, re2c, klibc, gzip, gawk, flex-old, original-awk, mawk, libtasn1-3($), flex($), libtool
- libcap2, mksh, readline6, libcdio, libpipeline, libcroco, schroedinger, desktop-file-utils, eina, fribidi, libusb, binfmt-support, silgraphite2.0, atk1.0($), perl, gnutls26($), netcat-openbsd, ossp-uuid, gsl, libnfnetlink, sg3-utils, jbigkit, lua5.1, unixodbc, sqlite, wayland, radvd, open-iscsi, libpcap, linux-atm, gdbm, id3lib3.8.3, vo-aacenc, vo-amrwbenc, fam, faad2, hunspell, dpkg, tslib, libart-lgpl, libidl, dh-exec, giflib, openslp-dfsg, ppl($), xutils-dev, blcr, bc, time, libdatrie, libpthread-stubs, guile-1.8, libev, attr, libsigc++-2.0, pixman, libpng, libssh2, sqlite3, acpica-unix, acl, a52dec
- json-c, cloog-ppl, libverto, glibmm2.4, rtmpdump, libdbd-sqlite3-perl, nss, freetds, slang2, libpciaccess, iptables, e2fsprogs, libnetfilter-conntrack, bash, libthai, python2.6($), libice($), libpaper, libfontenc($), libxau, libxdmcp($), openldap($), cyrus-sasl2($), openssl, python2.7($)
- psutils, libevent, stunnel4, libnet-ssleay-perl, libffi, readline5, file, libvoikko, gamin, libieee1284, build-essential, libcap-ng($), lcms($), keyutils, libxml2, libxml++2.6, gcc-4.6($), binutils, dbus($), libsm($), libxslt, doxygen($)
- liblqr, rarian, xmlto, policykit-1($), libxml-parser-perl, tdb, devscripts, eet, libasyncns, libusbx, icu, linux, libmng, shadow, xmlstarlet, tidy, gavl, flac, dbus-glib($), libxcb, apr, krb5, alsa-lib
- usbutils, enchant, neon27, uw-imap, libsndfile, yasm, xcb-util, gconf($), shared-mime-info($), audiofile, ijs($), jbig2dec, libx11($)
- esound, freetype, libxkbfile, xvidcore, xcb-util-image, udev($), libxfixes, libxext($), libxt, libxrender
- tk8.4, startup-notification, libatasmart, fontconfig, libxp, libdmx, libvdpau, libdrm, libxres, directfb, libxv, libxxf86dga, libxxf86vm, pcsc-lite, libxss, libxcomposite, libxcursor, libxdamage, libxi($), libxinerama, libxrandr, libxmu($), libxpm, libxfont($)
- xfonts-utils, libxvmc, xauth, libxtst($), libxaw($)
- pmake, corosync, x11-xserver-utils, x11-xkb-utils, coreutils, xft, nas, cairo
- libedit, cairomm, tk8.5, openais, pango1.0($)
- ocaml, blt, ruby1.8, firebird2.5, heimdal, lvm2($)
- cvs($), python-stdlib-extensions, parted, llvm-2.9, ruby1.9.1, findlib, qt4-x11($)
- xen, mesa, audit($), avahi($)
- x11-utils, xorg-server, freeglut, libva
- jasper, tiff3, python3.2($)
- openjpeg, qt-assistant-compat, v4l-utils, qca2, jinja2, markupsafe, lcms2, sip4, imlib2, netpbm-free, cracklib2, cups($), postgresql-9.1
- py3cairo, pycairo, pam, libgnomecups, gobject-introspection($)
- gdk-pixbuf, libgnomeprint, gnome-menus, gsettings-desktop-schemas, pangomm, consolekit, vala-0.16($), colord($), atkmm1.6
- libgee, gtk+3.0($), gtk+2.0($)
- gtkmm2.4, poppler($), openssh, libglade2, libiodbc2, gcr($), libwmf, systemd($), gcj-4.7, java-atk-wrapper($)
- torque, ecj($), vala-0.14, gnome-keyring($), gcc-defaults, gnome-vfs($)
- libidn, libgnome-keyring($), openmpi
- mpi-defaults, dnsmasq, wget, lynx-cur, ghostscript, curl
- fftw3, gnupg, libquvi, xmlrpc-c, raptor, liboauth, groff, fftw, boost1.49, apt
- boost-defaults, libsamplerate, cmake, python-apt
- qjson, qtzeitgeist, libssh, qimageblitz, pkg-kde-tools, libical, dwarves-dfsg, automoc, attica, yajl, source-highlight, pygobject, pygobject-2, mysql-5.5($)
- libdbd-mysql-perl, polkit-qt-1, libdbusmenu-qt, raptor2, dbus-python, apr-util
- rasqal, serf, subversion($), apache2
- git, redland
- xz-utils, util-linux, rpm, man-db, make-dfsg, libvisual, cryptsetup, libgd2, gstreamer0.10
- mscgen, texlive-bin
- dvipng, luatex
- libconfig, transfig, augeas, blas, libcaca, autogen, libdbi, linuxdoc-tools, gdb, gpm
- ncurses, python-numpy($), rrdtool, w3m, iproute, gcc-4.7, libtheora($), gcc-4.4
- libraw1394, base-passwd, lm-sensors, netcf, eglibc, gst-plugins-base0.10
- libiec61883, qtwebkit, libvirt, libdc1394-22, net-snmp, jack-audio-connection-kit($), bluez
- redhat-cluster, gvfs($), pulseaudio($)
- phonon, libsdl1.2, openjdk-6($)
- phonon-backend-gstreamer($), gettext, libbluray, db, swi-prolog, qdbm, swig2.0($)
- highlight, libselinux, talloc, libhdate, libftdi, libplist, python-qt4, libprelude, libsemanage, php5
- samba, usbmuxd, libvpx, lirc, bsdmainutils, libiptcdata, libgtop2, libgsf, telepathy-glib, libwnck3, libnotify, libunique3, gnome-desktop3, gmime, glib2.0, json-glib, libgnomecanvas, libcanberra, orbit2, udisks, d-conf, libgusb
- libgnomeprintui, libimobiledevice, nautilus($), libbonobo, librsvg
- evas, wxwidgets2.8, upower, gnome-disk-utility, libgnome
- ecore, libbonoboui
- libgnomeui
- graphviz
- exiv2, libexif, lapack, soprano, libnl3, dbus-c++
- atlas, libffado, graphicsmagick, libgphoto2, network-manager
- pygtk, jackd2, sane-backends, djvulibre
- libav($), gpac($), ntrack, python-imaging, imagemagick, dia
- x264($), matplotlib, iceweasel
- strigi, opencv, libproxy($), ffms2
- kde4libs, frei0r, glib-networking
- kde-baseapps, kate, libsoup2.4
- geoclue, kde-runtime, totem-pl-parser, libgweather, librest, libgdata
- webkit
- zenity, gnome-online-accounts
- metacity, evolution-data-server
- gnome-panel
- tracker
The final recompilation of profile built source packages is omitted. Source
packages marked with a ($) are selected to be profile built. All source
packages listed in the same line can be built in parallel as they do not depend
upon each other.
This order looks convincing as it first compiles a multitude of source packages
which have no or only few build dependencies lacking. Later steps allow fewer
source packages to be compiled in parallel. The amount of needed build
dependencies is highest in the source packages that are built last.
- profile built source packages may not create all binary packages
- profile built source packages may need additional build dependencies
Different feedback arc set algorithms
The initially developed feedback arc set algorithm is well suited to discover
build dependency edges which should be dropped. It performs far worse when
creating the final build order because it only considers edges by itself and
not how many edges of a source package can be dropped by profile building it.
The adjusted algorithm for generating a build order is more of a feedback
vertex set algorithm because instead of greedily finding the edge with most
cycles through it, it greedily finds the source package which would break most
cycles if it was profile built.
Generating a build order with less profile built source packages
After implementing all the features above I now feel more confident to publish
the current status of the tools to a wider audience.
The following test shows a run of the aforementioned ./native.sh shell
script. Its final output is a list of source packages which have to be profile
built and a build order. Using the resulting build order, starting from a
minimal build system (essential:yes, build-essential and debhelper), all source
packages will be compiled which are needed to compile all binary packages in
the system. The result will therefor be a list of source and binary packages
which fulfill the following property:
- all binary packages can be built from the available source packages
- all source packages can be built with the available binary packages
I called this a "reduceded distribution" in earlier posts. The interesting
property of this specific selection is, that it contains the biggest problem
set of Debian when bootstrapping it: a 900 to 1000 nodes big strongly connected
component. Here is a visualization of the problem:
Source packages do not yet come with build profiles and the cross build
situation can not yet be analyzed, so the following assumptions were made:
- the minimal build system can be cross compiled from nothing
- the reduced build dependencies harvested from Gentoo and supplied by Daniel
Schepler, Patrick McDermott, Thorsten Glaser and Wookey are correct
- the current list of weak build dependencies can be dropped from any
source package
- even when profile built, all source packages build all binary packages
- the 14 forcefully broken build dependencies do not significantly change the
output in real life
The last point is about 14 build dependencies which were decided to be broken
by the feedback arc set algorithm but for which other data sources did not
indicate that they are actually breakable. Those 14 are dynamically generated
by native.sh.
If above assumptions should not be too far from the actual situation, then not
more than 73 source packages have to be modified to bootstrap a reduced
distribution. This reduced distribution even includes dependency-wise "big"
packages like webkit, metacity, iceweasel, network-manager, tracker,
gnome-panel, evolution-data-server, kde-runtime, libav and nautilus. By
changing one line in native.sh one could easily develop a build order which
generates gnome-desktop or really any given (meta-)package selection.
All of native.sh takes only 80 seconds to execute on my system (Core i5, 2.5
GHz, singlethreaded). Here is the final build order which creates 2044 binary
packages from 613 source packages.
- nspr, libio-pty-perl, libmcrypt, unzip, libdbi-perl, cdparanoia, libelf, c-ares, liblocale-gettext-perl, libibverbs, numactl, ilmbase, tbb, check, libogg, libatomic-ops, libnl($), orc($), libaio, tcl8.4, kmod, libgsm, lame, opencore-amr, tcl8.5, exuberant-ctags, mhash, libtext-iconv-perl, libutempter, pciutils, gperf, hspell, recode, tcp-wrappers, fdupes, chrpath, libbsd, zip, procps, wireless-tools, cpufrequtils, ed, libjpeg8, hesiod, pax, less, dietlibc, netkit-telnet, psmisc, docbook-to-man, libhtml-parser-perl, libonig, opensp($), libterm-size-perl, linux86, libxmltok, db-defaults, java-common, sharutils, libgpg-error, hardening-wrapper, cvsps, p11-kit, libyaml, diffstat, m4
- openexr, enca, help2man, speex, libvorbis, libid3tag, patch, openjade1.3, openjade, expat, fakeroot, libgcrypt11($), ustr, sysvinit, netcat, libirman, html2text, libmad, pth, clucene-core, libdaemon($), texinfo, popt, net-tools, tar, libsigsegv, gmp, patchutils($), dirac, cunit, bridge-utils, expect, libgc, nettle, elfutils, jade, bison
- sed, indent, findutils, fastjar, cpio, chicken, bzip2, aspell, realpath, dctrl-tools, rsync, ctdb, pkg-config($), libarchive, gpgme1.0, exempi, pump, re2c, klibc, gzip, gawk, flex-old, original-awk, mawk, libtasn1-3($), flex($), libtool
- libcap2, mksh, readline6, libcdio, libpipeline, libcroco, schroedinger, desktop-file-utils, eina, fribidi, libusb, binfmt-support, silgraphite2.0, atk1.0($), perl, gnutls26($), netcat-openbsd, ossp-uuid, gsl, libnfnetlink, sg3-utils, jbigkit, lua5.1, unixodbc, sqlite, wayland, radvd, open-iscsi, libpcap, linux-atm, gdbm, id3lib3.8.3, vo-aacenc, vo-amrwbenc, fam, faad2, hunspell, dpkg, tslib, libart-lgpl, libidl, dh-exec, giflib, openslp-dfsg, ppl($), xutils-dev, blcr, bc, time, libdatrie, libpthread-stubs, guile-1.8, libev, attr, libsigc++-2.0, pixman, libpng, libssh2, sqlite3, acpica-unix, acl, a52dec
- json-c, cloog-ppl, libverto, glibmm2.4, rtmpdump, libdbd-sqlite3-perl, nss, freetds, slang2, libpciaccess, iptables, e2fsprogs, libnetfilter-conntrack, bash, libthai, python2.6($), libice($), libpaper, libfontenc($), libxau, libxdmcp($), openldap($), cyrus-sasl2($), openssl, python2.7($)
- psutils, libevent, stunnel4, libnet-ssleay-perl, libffi, readline5, file, libvoikko, gamin, libieee1284, build-essential, libcap-ng($), lcms($), keyutils, libxml2, libxml++2.6, gcc-4.6($), binutils, dbus($), libsm($), libxslt, doxygen($)
- liblqr, rarian, xmlto, policykit-1($), libxml-parser-perl, tdb, devscripts, eet, libasyncns, libusbx, icu, linux, libmng, shadow, xmlstarlet, tidy, gavl, flac, dbus-glib($), libxcb, apr, krb5, alsa-lib
- usbutils, enchant, neon27, uw-imap, libsndfile, yasm, xcb-util, gconf($), shared-mime-info($), audiofile, ijs($), jbig2dec, libx11($)
- esound, freetype, libxkbfile, xvidcore, xcb-util-image, udev($), libxfixes, libxext($), libxt, libxrender
- tk8.4, startup-notification, libatasmart, fontconfig, libxp, libdmx, libvdpau, libdrm, libxres, directfb, libxv, libxxf86dga, libxxf86vm, pcsc-lite, libxss, libxcomposite, libxcursor, libxdamage, libxi($), libxinerama, libxrandr, libxmu($), libxpm, libxfont($)
- xfonts-utils, libxvmc, xauth, libxtst($), libxaw($)
- pmake, corosync, x11-xserver-utils, x11-xkb-utils, coreutils, xft, nas, cairo
- libedit, cairomm, tk8.5, openais, pango1.0($)
- ocaml, blt, ruby1.8, firebird2.5, heimdal, lvm2($)
- cvs($), python-stdlib-extensions, parted, llvm-2.9, ruby1.9.1, findlib, qt4-x11($)
- xen, mesa, audit($), avahi($)
- x11-utils, xorg-server, freeglut, libva
- jasper, tiff3, python3.2($)
- openjpeg, qt-assistant-compat, v4l-utils, qca2, jinja2, markupsafe, lcms2, sip4, imlib2, netpbm-free, cracklib2, cups($), postgresql-9.1
- py3cairo, pycairo, pam, libgnomecups, gobject-introspection($)
- gdk-pixbuf, libgnomeprint, gnome-menus, gsettings-desktop-schemas, pangomm, consolekit, vala-0.16($), colord($), atkmm1.6
- libgee, gtk+3.0($), gtk+2.0($)
- gtkmm2.4, poppler($), openssh, libglade2, libiodbc2, gcr($), libwmf, systemd($), gcj-4.7, java-atk-wrapper($)
- torque, ecj($), vala-0.14, gnome-keyring($), gcc-defaults, gnome-vfs($)
- libidn, libgnome-keyring($), openmpi
- mpi-defaults, dnsmasq, wget, lynx-cur, ghostscript, curl
- fftw3, gnupg, libquvi, xmlrpc-c, raptor, liboauth, groff, fftw, boost1.49, apt
- boost-defaults, libsamplerate, cmake, python-apt
- qjson, qtzeitgeist, libssh, qimageblitz, pkg-kde-tools, libical, dwarves-dfsg, automoc, attica, yajl, source-highlight, pygobject, pygobject-2, mysql-5.5($)
- libdbd-mysql-perl, polkit-qt-1, libdbusmenu-qt, raptor2, dbus-python, apr-util
- rasqal, serf, subversion($), apache2
- git, redland
- xz-utils, util-linux, rpm, man-db, make-dfsg, libvisual, cryptsetup, libgd2, gstreamer0.10
- mscgen, texlive-bin
- dvipng, luatex
- libconfig, transfig, augeas, blas, libcaca, autogen, libdbi, linuxdoc-tools, gdb, gpm
- ncurses, python-numpy($), rrdtool, w3m, iproute, gcc-4.7, libtheora($), gcc-4.4
- libraw1394, base-passwd, lm-sensors, netcf, eglibc, gst-plugins-base0.10
- libiec61883, qtwebkit, libvirt, libdc1394-22, net-snmp, jack-audio-connection-kit($), bluez
- redhat-cluster, gvfs($), pulseaudio($)
- phonon, libsdl1.2, openjdk-6($)
- phonon-backend-gstreamer($), gettext, libbluray, db, swi-prolog, qdbm, swig2.0($)
- highlight, libselinux, talloc, libhdate, libftdi, libplist, python-qt4, libprelude, libsemanage, php5
- samba, usbmuxd, libvpx, lirc, bsdmainutils, libiptcdata, libgtop2, libgsf, telepathy-glib, libwnck3, libnotify, libunique3, gnome-desktop3, gmime, glib2.0, json-glib, libgnomecanvas, libcanberra, orbit2, udisks, d-conf, libgusb
- libgnomeprintui, libimobiledevice, nautilus($), libbonobo, librsvg
- evas, wxwidgets2.8, upower, gnome-disk-utility, libgnome
- ecore, libbonoboui
- libgnomeui
- graphviz
- exiv2, libexif, lapack, soprano, libnl3, dbus-c++
- atlas, libffado, graphicsmagick, libgphoto2, network-manager
- pygtk, jackd2, sane-backends, djvulibre
- libav($), gpac($), ntrack, python-imaging, imagemagick, dia
- x264($), matplotlib, iceweasel
- strigi, opencv, libproxy($), ffms2
- kde4libs, frei0r, glib-networking
- kde-baseapps, kate, libsoup2.4
- geoclue, kde-runtime, totem-pl-parser, libgweather, librest, libgdata
- webkit
- zenity, gnome-online-accounts
- metacity, evolution-data-server
- gnome-panel
- tracker
The final recompilation of profile built source packages is omitted. Source
packages marked with a ($) are selected to be profile built. All source
packages listed in the same line can be built in parallel as they do not depend
upon each other.
This order looks convincing as it first compiles a multitude of source packages
which have no or only few build dependencies lacking. Later steps allow fewer
source packages to be compiled in parallel. The amount of needed build
dependencies is highest in the source packages that are built last.
./native.sh shell
script. Its final output is a list of source packages which have to be profile
built and a build order. Using the resulting build order, starting from a
minimal build system (essential:yes, build-essential and debhelper), all source
packages will be compiled which are needed to compile all binary packages in
the system. The result will therefor be a list of source and binary packages
which fulfill the following property:
- all binary packages can be built from the available source packages
- all source packages can be built with the available binary packages
 Source packages do not yet come with build profiles and the cross build
situation can not yet be analyzed, so the following assumptions were made:
- the minimal build system can be cross compiled from nothing
- the reduced build dependencies harvested from Gentoo and supplied by Daniel Schepler, Patrick McDermott, Thorsten Glaser and Wookey are correct
- the current list of weak build dependencies can be dropped from any source package
- even when profile built, all source packages build all binary packages
- the 14 forcefully broken build dependencies do not significantly change the output in real life
native.sh.
If above assumptions should not be too far from the actual situation, then not
more than 73 source packages have to be modified to bootstrap a reduced
distribution. This reduced distribution even includes dependency-wise "big"
packages like webkit, metacity, iceweasel, network-manager, tracker,
gnome-panel, evolution-data-server, kde-runtime, libav and nautilus. By
changing one line in native.sh one could easily develop a build order which
generates gnome-desktop or really any given (meta-)package selection.
All of native.sh takes only 80 seconds to execute on my system (Core i5, 2.5
GHz, singlethreaded). Here is the final build order which creates 2044 binary
packages from 613 source packages.
- nspr, libio-pty-perl, libmcrypt, unzip, libdbi-perl, cdparanoia, libelf, c-ares, liblocale-gettext-perl, libibverbs, numactl, ilmbase, tbb, check, libogg, libatomic-ops, libnl($), orc($), libaio, tcl8.4, kmod, libgsm, lame, opencore-amr, tcl8.5, exuberant-ctags, mhash, libtext-iconv-perl, libutempter, pciutils, gperf, hspell, recode, tcp-wrappers, fdupes, chrpath, libbsd, zip, procps, wireless-tools, cpufrequtils, ed, libjpeg8, hesiod, pax, less, dietlibc, netkit-telnet, psmisc, docbook-to-man, libhtml-parser-perl, libonig, opensp($), libterm-size-perl, linux86, libxmltok, db-defaults, java-common, sharutils, libgpg-error, hardening-wrapper, cvsps, p11-kit, libyaml, diffstat, m4
- openexr, enca, help2man, speex, libvorbis, libid3tag, patch, openjade1.3, openjade, expat, fakeroot, libgcrypt11($), ustr, sysvinit, netcat, libirman, html2text, libmad, pth, clucene-core, libdaemon($), texinfo, popt, net-tools, tar, libsigsegv, gmp, patchutils($), dirac, cunit, bridge-utils, expect, libgc, nettle, elfutils, jade, bison
- sed, indent, findutils, fastjar, cpio, chicken, bzip2, aspell, realpath, dctrl-tools, rsync, ctdb, pkg-config($), libarchive, gpgme1.0, exempi, pump, re2c, klibc, gzip, gawk, flex-old, original-awk, mawk, libtasn1-3($), flex($), libtool
- libcap2, mksh, readline6, libcdio, libpipeline, libcroco, schroedinger, desktop-file-utils, eina, fribidi, libusb, binfmt-support, silgraphite2.0, atk1.0($), perl, gnutls26($), netcat-openbsd, ossp-uuid, gsl, libnfnetlink, sg3-utils, jbigkit, lua5.1, unixodbc, sqlite, wayland, radvd, open-iscsi, libpcap, linux-atm, gdbm, id3lib3.8.3, vo-aacenc, vo-amrwbenc, fam, faad2, hunspell, dpkg, tslib, libart-lgpl, libidl, dh-exec, giflib, openslp-dfsg, ppl($), xutils-dev, blcr, bc, time, libdatrie, libpthread-stubs, guile-1.8, libev, attr, libsigc++-2.0, pixman, libpng, libssh2, sqlite3, acpica-unix, acl, a52dec
- json-c, cloog-ppl, libverto, glibmm2.4, rtmpdump, libdbd-sqlite3-perl, nss, freetds, slang2, libpciaccess, iptables, e2fsprogs, libnetfilter-conntrack, bash, libthai, python2.6($), libice($), libpaper, libfontenc($), libxau, libxdmcp($), openldap($), cyrus-sasl2($), openssl, python2.7($)
- psutils, libevent, stunnel4, libnet-ssleay-perl, libffi, readline5, file, libvoikko, gamin, libieee1284, build-essential, libcap-ng($), lcms($), keyutils, libxml2, libxml++2.6, gcc-4.6($), binutils, dbus($), libsm($), libxslt, doxygen($)
- liblqr, rarian, xmlto, policykit-1($), libxml-parser-perl, tdb, devscripts, eet, libasyncns, libusbx, icu, linux, libmng, shadow, xmlstarlet, tidy, gavl, flac, dbus-glib($), libxcb, apr, krb5, alsa-lib
- usbutils, enchant, neon27, uw-imap, libsndfile, yasm, xcb-util, gconf($), shared-mime-info($), audiofile, ijs($), jbig2dec, libx11($)
- esound, freetype, libxkbfile, xvidcore, xcb-util-image, udev($), libxfixes, libxext($), libxt, libxrender
- tk8.4, startup-notification, libatasmart, fontconfig, libxp, libdmx, libvdpau, libdrm, libxres, directfb, libxv, libxxf86dga, libxxf86vm, pcsc-lite, libxss, libxcomposite, libxcursor, libxdamage, libxi($), libxinerama, libxrandr, libxmu($), libxpm, libxfont($)
- xfonts-utils, libxvmc, xauth, libxtst($), libxaw($)
- pmake, corosync, x11-xserver-utils, x11-xkb-utils, coreutils, xft, nas, cairo
- libedit, cairomm, tk8.5, openais, pango1.0($)
- ocaml, blt, ruby1.8, firebird2.5, heimdal, lvm2($)
- cvs($), python-stdlib-extensions, parted, llvm-2.9, ruby1.9.1, findlib, qt4-x11($)
- xen, mesa, audit($), avahi($)
- x11-utils, xorg-server, freeglut, libva
- jasper, tiff3, python3.2($)
- openjpeg, qt-assistant-compat, v4l-utils, qca2, jinja2, markupsafe, lcms2, sip4, imlib2, netpbm-free, cracklib2, cups($), postgresql-9.1
- py3cairo, pycairo, pam, libgnomecups, gobject-introspection($)
- gdk-pixbuf, libgnomeprint, gnome-menus, gsettings-desktop-schemas, pangomm, consolekit, vala-0.16($), colord($), atkmm1.6
- libgee, gtk+3.0($), gtk+2.0($)
- gtkmm2.4, poppler($), openssh, libglade2, libiodbc2, gcr($), libwmf, systemd($), gcj-4.7, java-atk-wrapper($)
- torque, ecj($), vala-0.14, gnome-keyring($), gcc-defaults, gnome-vfs($)
- libidn, libgnome-keyring($), openmpi
- mpi-defaults, dnsmasq, wget, lynx-cur, ghostscript, curl
- fftw3, gnupg, libquvi, xmlrpc-c, raptor, liboauth, groff, fftw, boost1.49, apt
- boost-defaults, libsamplerate, cmake, python-apt
- qjson, qtzeitgeist, libssh, qimageblitz, pkg-kde-tools, libical, dwarves-dfsg, automoc, attica, yajl, source-highlight, pygobject, pygobject-2, mysql-5.5($)
- libdbd-mysql-perl, polkit-qt-1, libdbusmenu-qt, raptor2, dbus-python, apr-util
- rasqal, serf, subversion($), apache2
- git, redland
- xz-utils, util-linux, rpm, man-db, make-dfsg, libvisual, cryptsetup, libgd2, gstreamer0.10
- mscgen, texlive-bin
- dvipng, luatex
- libconfig, transfig, augeas, blas, libcaca, autogen, libdbi, linuxdoc-tools, gdb, gpm
- ncurses, python-numpy($), rrdtool, w3m, iproute, gcc-4.7, libtheora($), gcc-4.4
- libraw1394, base-passwd, lm-sensors, netcf, eglibc, gst-plugins-base0.10
- libiec61883, qtwebkit, libvirt, libdc1394-22, net-snmp, jack-audio-connection-kit($), bluez
- redhat-cluster, gvfs($), pulseaudio($)
- phonon, libsdl1.2, openjdk-6($)
- phonon-backend-gstreamer($), gettext, libbluray, db, swi-prolog, qdbm, swig2.0($)
- highlight, libselinux, talloc, libhdate, libftdi, libplist, python-qt4, libprelude, libsemanage, php5
- samba, usbmuxd, libvpx, lirc, bsdmainutils, libiptcdata, libgtop2, libgsf, telepathy-glib, libwnck3, libnotify, libunique3, gnome-desktop3, gmime, glib2.0, json-glib, libgnomecanvas, libcanberra, orbit2, udisks, d-conf, libgusb
- libgnomeprintui, libimobiledevice, nautilus($), libbonobo, librsvg
- evas, wxwidgets2.8, upower, gnome-disk-utility, libgnome
- ecore, libbonoboui
- libgnomeui
- graphviz
- exiv2, libexif, lapack, soprano, libnl3, dbus-c++
- atlas, libffado, graphicsmagick, libgphoto2, network-manager
- pygtk, jackd2, sane-backends, djvulibre
- libav($), gpac($), ntrack, python-imaging, imagemagick, dia
- x264($), matplotlib, iceweasel
- strigi, opencv, libproxy($), ffms2
- kde4libs, frei0r, glib-networking
- kde-baseapps, kate, libsoup2.4
- geoclue, kde-runtime, totem-pl-parser, libgweather, librest, libgdata
- webkit
- zenity, gnome-online-accounts
- metacity, evolution-data-server
- gnome-panel
- tracker
 My 1Tb laptop drive started misbehaving a few weeks ago, just spending a lot of time spinning when it should have been reading frequently changed files (like the browser cache). I was tempted to blame the browser at that point as no other packages appeared affected.
 I moved to Boston in 2005 at the same time that
 Today I planed to move my FTP server to a new system running

 If anyone s in the area, there will be a Debian BSP this weekend at SIPB s MIT office.
Hope to see everyone there!
Check out details @
 I want to like LDAP. Every so often I do interesting things with it, and I start to think I like it, then some software that claims to support LDAP fails to do so properly and I remember I hate it again.
I guess the problem with LDAP is that most people are scared by it, unless you reach a certain level of scale you don't need it. That makes installing it out of the blue a scary prospect, and that means that lots of toy-software applications don't even consider using it until they're mature and large.
When you bolt-on support for LDAP to an existing project you have to make compromises; do you create local entries in your system for these scary-remote-LDAP-users? Do you map group members from LDAP into your own group system? ANd so on.
To be fair to the application developers if the requirements for installation were "Install LDAP" they'd probably have a damn smaller userbase, and so we cannot blame OpenLDAP, or the other servers.
All the same it is a shame.
The very next piece of software I ever write that needs to handle logins will use LDAP and only LDAP. How hard can it be?
In happier news
 Having obtained

 GNOME 3.4 for Debian wheezy is shaping up quite well. A handful of bugs remain to be fixed, but we are now in a polishing phase, as expected given the freeze status.
With upstream introducing heavy changes in new versions, it is time to think of what will happen with GNOME when we introduce version 3.8 in unstable. Namely, there are two categories of changes that have a heavy impact on Debian:


 In a pipeline, a black cat can become a white cat with the help of
some middleware.


 when it s a prediction .
In the 4th January edition of the Guardian Weekly , the front page story,
entitled Meet the world s new boomers