Search Results: "cas"

13 December 2008

Mike Hommey: Shared subtrees

As reply to my previous post about per-process namespaces, Russell wrote about pam-namespace and shared subtrees. As he reports, pam-namespace (that I discovered by the occasion) can do what I was suggesting would be nice for pam-tmpdir. Anyways, I was actually already planning to write about shared subtrees and how they can be useful with namespaces. In this first post, I will introduce shared subtrees, while in a follow-up post I will introduce how they can usefully be used with namespaces. As a preliminary note, you should know that while etch’s kernel supports shared subtrees, etch’s mount doesn’t support the necessary options. Lenny’s mount is unfortunately uninstallable on etch due to its dependency on a newer libc. But you can find a smount utility’s source code in Documentation/filesystems/sharedsubtree.txt in the kernel source, where other explanations about the feature are available. So, you can either backport lenny’s util-linux to etch, or build smount to replicate what I will be doing below. If you are using smount, just replace
mount --make-type path
with
smount path type
As seen in my previous post, bind-mounting allows to attach a file hierarchy at some other place in the virtual file system.
mount --bind / /mnt
will make all the contents of / (/bin, /etc, …) available through /mnt (/mnt/bin, /mnt/etc, …). On the other hand, sub-mounts will be ignored in such a case. For instance, /usr is usually a different mount point from /. It means /mnt/usr will be empty (provided it is empty in the underlying physical filesystem), instead of containing the same as /usr:
$ mount --bind / /mnt
$ ls /mnt/usr
$ ls /usr
bin games include lib lib32 lib64 local sbin share src X11R6
$ umount /mnt
If you also want /usr to be bind-mounted, you must use --rbind instead of --bind:
$ mount --rbind / /mnt
$ ls /mnt/usr
bin games include lib lib32 lib64 local sbin share src X11R6
$ ls /usr
bin games include lib lib32 lib64 local sbin share src X11R6
Obviously, sub-sub-mounts will also be propagated. Since recursively bind-mounting will create a bunch of mount points, unmounting can become a hassle. You can use the following command to unmount everything:
$ awk '$2 ~ /^\/mnt/ print $2 ' /proc/mounts sort -r xargs umount
Now, this is where shared subtrees come in. After the bind mount has been done, if you mount something on either side of the bind mount, the new mount is not propagated. This is called private subtrees, and is the default. But before doing anything else, let’s setup our testing environment:
$ mkdir -p /a/a /b
$ touch /a/b /a/c
$ ls /a
a b c
$ ls /b
After, bind-mounting /a onto /b, let’s see what happens when mounting something under /a, then under /b:
$ mount --bind /a /b
$ ls /b
a b c
$ mount --bind /usr /a/a
$ ls /a/a
bin games include lib lib32 lib64 local sbin share src X11R6
$ ls /b/a
$ umount /a/a
$ mount --bind /usr /b/a
$ ls /a/a
$ ls /b/a
bin games include lib lib32 lib64 local sbin share src X11R6
$ umount /b/a
As I said earlier, these new mounts are not propagated. Note that I used bind-mounts as sub mounts, but it would work all the same with other kind of mounts (device, fuse, etc.). There are 2 other modes that allow to have some propagation: shared and slave. shared allows mounts on both ends to be shared. Note you need to set the mode before bind-mounting:
$ umount /b
$ mount --bind /a /a
# This is needed because /a is not initially a mount point and you can only apply subtree modes to mount points.
$ mount --make-shared /a
$ mount --bind /a /b
$ mount /dev/sda1 /a/a
$ ls /a/a
config-2.6.26-1-amd64 grub initrd.img-2.6.26-1-amd64 System.map-2.6.26-1-amd64 vmlinuz-2.6.26-1-amd64
$ ls /b/a
config-2.6.26-1-amd64 grub initrd.img-2.6.26-1-amd64 System.map-2.6.26-1-amd64 vmlinuz-2.6.26-1-amd64
$ umount /a/a
$ mount /dev/sda1 /b/a
$ ls /a/a
config-2.6.26-1-amd64 grub initrd.img-2.6.26-1-amd64 System.map-2.6.26-1-amd64 vmlinuz-2.6.26-1-amd64
$ ls /b/a
config-2.6.26-1-amd64 grub initrd.img-2.6.26-1-amd64 System.map-2.6.26-1-amd64 vmlinuz-2.6.26-1-amd64
$ umount /b/a
You can even mount on one end and unmount from the other:
$ mount /dev/sda1 /a/a
$ umount /b/a
$ ls /a/a
slave allows mounts on the “master” end (/a in our case) to propagate to the “slave” end (/b), but not the other way around. The “master” end need to be shared :
$ umount /b
$ mount --make-shared /a
# Only for completeness, we already set /a as shared earlier.
$ mount --bind /a /b
$ mount --make-slave /b
$ mount /dev/sda1 /a/a
$ ls /a/a
config-2.6.26-1-amd64 grub initrd.img-2.6.26-1-amd64 System.map-2.6.26-1-amd64 vmlinuz-2.6.26-1-amd64
$ ls /b/a
config-2.6.26-1-amd64 grub initrd.img-2.6.26-1-amd64 System.map-2.6.26-1-amd64 vmlinuz-2.6.26-1-amd64
$ umount /a/a
$ mount /dev/sda1 /b/a
$ ls /a/a
$ ls /b/a
config-2.6.26-1-amd64 grub initrd.img-2.6.26-1-amd64 System.map-2.6.26-1-amd64 vmlinuz-2.6.26-1-amd64
$ umount /b/a
There is a third mode, unbindable, that does something different:
$ umount /b
$ mount --make-unbindable /a
$ mount --bind /a /b
mount: wrong fs type, bad option, bad superblock on /a,
       missing codepage or helper program, or other error
       In some cases useful info is found in syslog - try
       dmesg tail or so
$ mount --bind /a/a /b
mount: wrong fs type, bad option, bad superblock on /a,
       missing codepage or helper program, or other error
       In some cases useful info is found in syslog - try
       dmesg tail or so
As you can see, it disallows bind mounting of /a and its subdirectories to some other place. Finally, to put back the default mode, you can use:
$ mount --make-private /a
Similarly to --bind, there is also a recursive version of each: rshared, rslave, runbindable and rprivate, to apply these to sub-mounts.

12 December 2008

Biella Coleman: First Impressions

Today I spent most of the day hacking away at a new syllabus on technology and the body for a class I am teaching next semester. I am still hoping to find a (good) reading on body modification that covers body tattoos (any suggestions welcome) to complement my readings on other forms of body modification. Later in the day, after talking about my quest to find a great article on tattoos, my friend mentioned to me that she thought the mark on my face under my left eye was a tattoo. When I got home later, I asked a number of friends on IRC what they thought the mark on my face was they first met me and most of the answers were makeup or tattoo (and people have tried to rub it off my face, which, yes, makes for a pretty uncomfortable social situation). I guess if one thinks it is smeared eyeliner, one might think I am a total chump for being so sloppy with my makeup and if someone thinks is it is tattoo one might think I am either a bad ass for daring to tattoo my face, or bad ass for different reasons (and I have had many a conversation usually with security guys and drug dealers asking whether I once was in a gang). Or perhaps people might think I am just an old-fashioned attention-seeker. Back in college, when I had a nose ring most everyone thought the mark was a tattoo and I would receive many comments and complements on my innovative sense of aesthetics (the nose ring did bring out the mark quite a bit). Today, after having these conversations it really hit me that, while I really don’t mind or care all that much what impression of me is formed, it is probably the case that in many instances, this tiny mark on my face, which has been with me since birth, does feed into the formation of first impressions.

Raphael Geissert: Re: Per-process namespaces


Mike Hommey blogged today about Per-process namespaces.
That reminded me to blog about switchsh, a very useful program (now in sid) to help workaround those programs that believe that /bin/sh is always /bin/bash, in other words: it bind-mounts bash as /bin/sh.

Package description follows:
Small program to bind-mount bash as /bin/sh for its child processes.

It can be used when bash is not the default shell interpreter but a given
program makes use of bashisms (features not required by Policy for sh) and one
wants to run it without changing (or can not change) the default sh.


Let's take a look at how switchsh can help us:

$ cat evil_script.sh
#!/bin/sh
echo -ne "Hello!\nPlease enter your name: "
read
echo "So, you are $REPLY, right?"


$ readlink /bin/sh
dash
$ ./evil_script.sh
-ne Hello!
Please enter your name:
read: 4: arg count
So, you are , right?
$ switchsh ./evil_script.sh
Hello!
Please enter your name: Raphael
So, you are Raphael, right?

But lets consider the following case:
$ cat evil_script.pl
#!/usr/bin/perl -W
my $res =  git gc &>/dev/null ;
if ($? eq 0)  
    print "Done\n";
  else  
    print STDERR "bang! something went wrong\n";


$ ./evil_script.pl
fatal: Not a git repository
Done
$ switchsh ./evil_script.pl
bang! something went wrong

But what happens when bashisms are used on a binary object? Say in OpenOffice.org, in X.org, Wine, or any other large project that take not less than a couple of hours to build in a "normal" machine? you really want to have switchsh in those cases (and file a bug as soon as you notice that running a program with and without switchsh makes it behave differently).

Russell Coker: Christmas Toys for Children

It’s almost Christmas and time to buy scientific toys for children. Here are some random ideas, of course it’s probably too late for the online stores to deliver - but there’s always next year. The MikroKopter is a kit helicopter based on four propellors (two rotating in each direction) and is capable of semi-autonomous flight while carrying a decent payload (such as a digital camera) [1]. The parts cost over E700 and the skill involved in assembling it is significant, but it would be an excellent present for anyone who is 14+. Of course the type of helicopter described in my previous post [2] is a much more affordable present and can be used by a young child. The scitoys.com site has a good range of scientific toys for sale [3], they are assembled into kits. The United Nuclear site has a huge range of chemical supplies and related things [4] that can be used for making some great science experiments and toys. They also have really detailed information about the potential hazards of the things that they sell (not that I was planning to buy Cesium or Uranium anyway). If buying exotic alloys elsewhere it’s probably a good idea to check the United Nuclear site for the hazard information (not all sites provide as much information as they should). Professor Bunsen is an Australian site selling similar produces to SciToys [5]. The range is slightly different, and if you are in Australia then it’s safer to buy locally - there is a significant amount of stuff on the United Nuclear site that would be unlikely to pass Australian customs. The Spirograph is a good way to introduce mathematical concepts to children [6], it would probably be a good present for children who’s parents are not interested in maths and science. Lego [7] is always good, but there are also other similar products to consider. Meccano is good for older children, but the ranges for younger children have some deficiencies (the 2+ stuff requires the finger strength of an adult to assemble all parts). The Italian company Quercetti has some great products [9]. Unfortunately their web site is only in Italian and they have no links to sites in other countries/languages (they do have the names of some distributors who may have web sites). Their products includes a gears set (suitable for teaching children as young as 1yo) and a model car with an engine that has pistons moving inside a clear plastic case, a two-speed gearbox, and a fully functional differential (designed for 2yo+). For more hands-on tasks that require supervision (not something that can go under a tree) one good option for ages 3+ is to disassemble a variety of computers and computer parts. CD-ROM drives are good because you can connect a 9V battery to the head assembly motor or the tray eject motor to make it work. Hard disks have insanely strong magnets inside them - don’t give two such magnets to a child. A multi-meter is a great educational toy that can be used for many great experiements (as well as for practical tasks such as determining which battery of a set is flat) [10]. The parts from a hard disk can be used to demonstrate how a generator works (the mechanism to move the heads provides you with strong magnets and a coil that fits them). Note that an analogue meter is needed for such experiments as the amount of electricity generated is small and AC - a digital meter will average it out to zero (at least for the more affordable meters that I have used). It’s probably best to own both a digital meter and an analogue one, the minimum age for owning such a meter is probably about 10, the minimum age for using one with supervision is about 3. An oscilloscope is a great educational toy [11], unfortunately they are quite expensive (Ebay seems to have nothing below about $450). They can be used for all sort of fun tasks such as measuring the speed of sound. The wikipedia page notes that you can get PC based Oscilloscopes (PCO) which are cheaper. I wonder if they have Linux support for such things… The OLPC is a great computer for kids in developing countries [12]. They are now available in Australia [13]. For most children in first-world countries a second-hand laptop of a more traditional design is probably a better option. There are a significant number of old laptops gathering dust which can easily have Linux installed with a variety of educational software. Buying an OLPC on the “give one get one” deal costs $400US plus tax and shipping, while a second-hand laptop can be purchased for significantly less than that. While giving an OLPC to some random needy child is a good thing, as the person who gives a laptop locally is probably going to provide support for it there are some benefits to giving a regular laptop. Conferences often have bags of random junk to give out to delegates, and trade shows always have lots of little toys with company logos on them. Such things are usually of little use - but children like them. Also the trinkets that computer companies give away are often educational. If you have a cupboard filled with such things then unloading them on some children is a good idea - of course you have to make sure that anything you give to young children can’t be swallowed and has no sharp points.

Mike Hommey: Per-process namespaces

Linux has had this neat feature for quite some time now: since 2.4.19 according to the docs. Yet, it is neither very known nor very used. I couldn’t even find a program that would create a new namespace for its subprocesses, similar to what chroot does with the root of the file hierarchy. This neat feature allows each process to have a different set of mount points. While you most of the time want processes to share their mount points, there are some cases where you may want to have some processes have a different set of mount points. Combined with bind mounts, it can allow some useful setups. In case you are not familiar with bind mounts, they allow to “attach” a part of the file hierarchy to some place else. For example:
$ ls /mnt
$ ls /usr
bin games include lib lib32 lib64 local sbin share src X11R6
$ mount --bind /usr /mnt
$ ls /mnt
bin games include lib lib32 lib64 local sbin share src X11R6
Now, take pam-tmpdir, for example. It sets $TMPDIR and $TMP to point to a user-specific temporary directory. Sadly, it is pretty useless for applications that don’t follow the standards of using these environment variables. Without namespaces, if you’d create a temporary directory and bind-mount it to /tmp, this new /tmp would be visible to everyone, to every process. But with namespaces, you can make this new /tmp only available to subprocesses. If pam-tmpdir were to do this, it would also allow applications trying to write to /tmp without resorting to $TMP or $TMPDIR to be using the temporary space, without impacting external processes, that would still be using the original /tmp. On x86-64, you can run both 64-bits and 32-bits applications. 64-bits applications would take libraries from /usr/lib, and 32-bits applications would search libraries in /usr/lib32. But badly crafted 32-bits applications could be trying to load libraries from /usr/lib, where only 64-bits versions are available. With namespaces, the broken 32-bits application could have /usr/lib32 bind-mounted to /usr/lib without the 64-bits applications knowing. You could certainly get a similar result with the following set of commands:
$ mount --rbind / /chroot
$ mount --rbind /usr/lib32 /chroot/usr/lib
$ chroot /chroot $application
(–rbind also attaches submounts, contrary to –bind) The downside, here, is that external processes will see all this setup under /chroot. The whole setup would be invisible to external processes if namespaces were used. Another nice use of namespaces would be to mount encrypted volumes under a different namespace, so that only a limited set of processes would be allowed to read the decrypted data. The sad thing is that you need the admin capability to create a new namespace, so that would need to be done by a setuid root program. There are, as far as a few hours fiddling showed me, 2 system calls that will setup a new namespace: clone(2), and unshare(2). The second is easier to use, though only available since 2.6.16. But while etch ships 2.6.18, the glibc coming with it doesn’t implement unshare(2), so we need to use syscall(2) instead. The following code will run /bin/sh, or any command given as argument after creating a new namespace. The new process and its subprocesses will inherit the new namespace.
#include <sched.h>
#include <syscall.h>
#include <unistd.h>
int main(int argc, char *argv[])
  syscall(SYS_unshare, CLONE_NEWNS);
  if (argc > 1)
    return execvp(argv[1], &argv[1]);
  return execv("/bin/sh", NULL);

This tool, once built, is called newns in the following example.
$ mkdir /tmp/abc
$ ./newns
$ mount -n --bind /tmp/abc /tmp
$ touch /tmp/a
$ ls /tmp
a
<in another terminal>
$ ls /tmp
abc
$ ls /tmp/abc
a
When using namespaces, it is better not to have mount fill /etc/mtab, using the -n argument. /proc/mounts will contain the proper mount information about the namespace of the process reading it. /proc/PID/mounts will contain the mount information for the given process. As bind mounts also work on files, you can override some files. The following will run dash instead of bash (in subprocesses, too, obviously):
$ ./newns sh -c "mount -n --bind /bin/dash /bin/bash; /bin/bash"
Back to the idea of having encrypted volumes only available to some processes, the following should work (unverified):
$ ./newns sh -c "encfs /tmp/crypt-raw /tmp/crypt; /bin/bash"
Only the opened bash, and its subprocesses, would have access to /tmp/crypt. The newns tool used above could, to allow normal users to be able to fiddle with namespaces, be improved to be a setuid root program that would drop its privileges right after unshare(2) to take the same privileges as the calling process. As you can see, per-process namespaces have a wide range of possible uses ; it’s astonishing that it’s not more used yet, considering its age. Additionally to per-process namespaces, there are also a bunch of other (more recent) features that allow to implement vserver-like features with a vanilla kernel, such as networking netspaces (work under progress, though), PID namespaces and utsname (see uname(2)) namespaces. Actually, these features are designed to be used by vserver and openvz. I am looking forward to having unprivileged mounts implemented, so that users could fool around with bind mounts. Unprivileged namespaces would be a nice addition.

Chris Lawrence: Corollary of the day

King Politics thinks the GOP anti-bailout faction has the politics of the day wrong:
The time for pragmatism is now, but Senate Republicans don t recognize that. Senate Republicans have yet to realize that the GOP lost so many seats in 2006 and 2008 because the American public has a greater desire for pragmatism than ideology.
I think that s true to a point but I suspect it has more to do with post-Katrina George W. Bush than any coherent definition of ideology. As much as the Democrats would like to pretend otherwise, ideological is not a term I d readily apply to the bumbling nature of Bush s second term. Nor am I really convinced that the average voter is doing much more than engaging in post-hoc rationalized-as-something-else economic voting, which doubtless makes me no fun at parties when I play a public opinion scholar. ( Yes, all this crap matters at the margins, and occasionally elections are won at the margins, but most of the time it doesn t matter. ) But I digress. There is a broader lesson, though, in that to the extent the Democrats believe that their recent success is due to their ideology it is at their long-term peril, particularly if they bypass pragmatism in favor of catering to the cobbled-together collection of rent-seekers that passes for the Democratic coalition. To the extent bailing out Detroit is seen as a Democatic handout to its paymasters particularly with the emerging frame of the greedy unions are standing in the way trumping any sort of concept that any deal that tells the UAW to can their contract is essentially an impairment of the obligation of contract (which, believe it or not, is unconstitutional) the auto bailout won t go over well in the 48 or so states that don t host significant Big Three production. On a related note, Steven Taylor notes the defining-down of the filibuster by the media to mean failure to win a cloture vote. While I accept the point graciously, I think this may be more a failure of us as a profession than the media per se; modern congressional procedures (not just filibusters and holds, but also esoterica such as the Rules Committee and UCAs), even superficially treated, aren t a strong point of most American government textbooks, and more often than not that s the only real government orientation budding journalists will get. I make a point of assigning Barbara Sinclair s Unorthodox Lawmaking in my Congress classes, but I doubt the average journalist gets that in-depth in their undergrad days. So here at least I think the blame falls somewhat closer to home than we might want to admit.

Chris Lawrence: Corollary of the day

King Politics thinks the GOP anti-bailout faction has the politics of the day wrong:
The time for pragmatism is now, but Senate Republicans don t recognize that. Senate Republicans have yet to realize that the GOP lost so many seats in 2006 and 2008 because the American public has a greater desire for pragmatism than ideology.
I think that s true to a point but I suspect it has more to do with post-Katrina George W. Bush than any coherent definition of ideology. As much as the Democrats would like to pretend otherwise, ideological is not a term I d readily apply to the bumbling nature of Bush s second term. Nor am I really convinced that the average voter is doing much more than engaging in post-hoc rationalized-as-something-else economic voting, which doubtless makes me no fun at parties when I play a public opinion scholar. ( Yes, all this crap matters at the margins, and occasionally elections are won at the margins, but most of the time it doesn t matter. ) But I digress. There is a broader lesson, though, in that to the extent the Democrats believe that their recent success is due to their ideology it is at their long-term peril, particularly if they bypass pragmatism in favor of catering to the cobbled-together collection of rent-seekers that passes for the Democratic coalition. To the extent bailing out Detroit is seen as a Democatic handout to its paymasters particularly with the emerging frame of the greedy unions are standing in the way trumping any sort of concept that any deal that tells the UAW to can their contract is essentially an impairment of the obligation of contract (which, believe it or not, is unconstitutional) the auto bailout won t go over well in the 48 or so states that don t host significant Big Three production. On a related note, Steven Taylor notes the defining-down of the filibuster by the media to mean failure to win a cloture vote. While I accept the point graciously, I think this may be more a failure of us as a profession than the media per se; modern congressional procedures (not just filibusters and holds, but also esoterica such as the Rules Committee and UCAs), even superficially treated, aren t a strong point of most American government textbooks, and more often than not that s the only real government orientation budding journalists will get. I make a point of assigning Barbara Sinclair s Unorthodox Lawmaking in my Congress classes, but I doubt the average journalist gets that in-depth in their undergrad days. So here at least I think the blame falls somewhat closer to home than we might want to admit.

11 December 2008

Russell Coker: Please Turn off Your Spam Protection

Hi, I’d like to send an email from a small domain that you’ve never heard of or from a big ISP that’s known for being slack about spam (*), I can’t send the mail to you because of your anti-spam measures. I think that this is unfair, it’s discrimination, and you are cutting off your nose to spite your face in rejecting my mail. So please reconfigure your mail server now and accept more spam in your inbox, my message is important enough to justify the extra time you will spend manually deleting mail and the risk of accidentally deleting legitimate mail while deleting heaps of spam (I am in fact more important than you). By not accepting my mail you are being an asshole. I only receive a dozen spam messages a day and I don’t mind it, without even knowing you or having bothered to do a web search to see how well your email address is known I’m sure that you don’t receive any more spam than me and therefore you too can turn off most anti-spam measures and manually sort through the spam. You don’t really have a problem with spam, you are just paranoid, I’m sure that you installed your anti-spam measures before receiving any spam and then never bothered to check the hit rates. My sys-admin knows that one of the DNSBLs has an old entry from when his server was broken, but he won’t request that it be removed - so you can change your server because my sys-admin doesn’t want to click on a URL that you sent him. The RFC-ignorant.org service is used and run by ignorant people - I know this without even reading their web site to discover how it works. The above is a summary of a number of complaints that I have received about my anti-spam measures. I’ve para-phrased them so that they make sense, I have not actually had someone directly say “I’m more important than you so you should just accept more spam”, but the implication is quite clear. Now there are some legitimate reasons for requesting that anti-spam measures be reduced. In the distant past almost everyone had working reverse DNS entries which matched the forward entries and it was common to reject mail from systems that didn’t have valid DNS. Nowadays there are many big ISPs that delegate IP address space without permitting reverse DNS entries, and there are companies that have one department in charge of IP addresses (who don’t have a clue about reverse DNS) and another department running mail servers (who are cluefull). So the environment has changed to make reverse DNS checks a non-viable anti-spam measure. Requesting that people remove such checks is reasonable. Anti-spam measures that attack innocent third parties are bad. Sending “warnings” about viruses has made no sense for many years as all modern viruses fake the sender address, an employee of one company once admitted to me that they were sending out anti-virus “warning” messages as a way of sending unsolicited advertising to random people (I reported them as a spam source). Some time ago on a routine upgrade of ClamAV I accidentally copied in a default configuration file that made it send such warnings - I was grateful when someone informed me of my mistake so that I could fix it. Challenge-response is another technology that causes harm to others. I think it makes a lot of sense for mailing lists (every modern list server will confirm subscription requests), while it does result in sending unwanted mail to innocent third parties (every time a new virus becomes prevalent I receive a number of confirmation messages from list servers), but it’s not something that I will use on a regular email account (but I am prepared to do paid work implementing CR for other people). Requesting that manually implemented blocks be removed is quite reasonable. Occasionally I find that mail from one of my servers is blocked because a previous owner of the IP address space did bad things. In such a situation it is quite reasonable to provide an assurance that the new owner takes abuse issues seriously and to request that the block be removed. Requesting that I make any change to my system without making a minimal effort to get your broken mail server fixed is totally unreasonable. If the system administrator is not prepared to click on a URL to get their system removed from a black-list or if the user is unwilling to report the problem to the sysadmin then I will probably be unwilling to make any change to my system. The only exceptions to this rule are for clients, colleagues, and for people who use mail services that are large and unresponsive to users (IE the users don’t directly pay). I recently made a white-list entry for a large European ISP that is used by a Debian Developer for their work, as the ISP is known to be unresponsive to requests and mail related to Debian work is important to me I added a white-list entry. One thing I am planning to do is to document my anti-spam measures and then allow people the opportunity of suggesting new anti-spam measures that I haven’t tried yet if they want me to turn off any of my current protections. (*) I’m not aware of any big ISP that takes strong measures against spamming customers and customers whose computers are trojaned. I am aware of one having done it in the past, but I suspect that they may have ceased doing so after their brush with bankruptcy. I suspect that many ISPs simply rate-limit their customers connections to the outbound mail relays and hope that they don’t get enough infected customers at any time to get themselves listed as a spam source.

10 December 2008

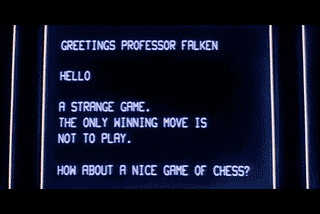
Biella Coleman: The Only Winning Move is Not To Play


nice-game-chess, originally uploaded by the biella.
Today I wrapped up both of my classes. Usually the end of class/semester represents and is experienced as nothing short of pure, unadulterated joy and at both ends of the stick (student and professors alike experience similar emotions :-). Like my students, I am pretty beat and more than ready for a break. But I have to admit, I experienced the end of my hacker class with a tinge of sadness. This is the third time I have taught this class and each time, it seems like it becomes harder and harder to contain the class conversation and I enjoy them through and through. The last few classes were brimming with talk, which is what should exactly happen because by the last month students are walking/talking on a foundation built over the course of many weeks. There is not much I would have changed about the syllabus (most of the readings were great-to-stellar) nor the class. But if there is one thing I am sorry about it is that we never watched War Games. The last time I taught the class, I was able to arrange various movie sessions and we watched War Games, Tron, and Sneakers (among a few others) and the students not only learned something about hacker media representations but did a little out-of-class bonding with the movies and lots of food. Since space is such an issue at NYU, I decided not to forage or hunt for a suitable room (I have since found a connection who I think can hook me up with a room). But by missing War Games, we missed an important event in the history of hackerdom. The movie undoubtedly led to many a kids asking for a modem for xmas and I am sure led to a spike in hacking and phreaking 9 months later (or however long it takes for a kid to plead for a modem, get it, learn some new tricks etc). It is also the case that while it helped usher in the image of the hacker as nefarious computer trickster, David Lightman was also a pretty cool, cute, and likable kid. Not a nerd but a geek. It perhaps represents the glimmerings of the transformation of the negative nerd into the positive geek (oh and the list keeps the list of girl geeks growing ), signaling the spread of the computer into mainstream society. So next time I teach the class, there will certainly be more movies, War Games on the top of the list so that we can learn that “the only winning move is not to play.”

Erich Schubert: Four months in job review

I've been at my new job for almost four months now. After I had completed my degree, my advisors at the university quickly offered me a position. When I heard back e.g. from Google where I had submitted an application, I had already started my new job.
So from my current point of view it was the best thing to do:

Lucas Nussbaum: Debian on a Dell E4300

I received a new laptop, a Dell Latitude E4300. I was a bit anxious with its level of support on Linux, because it only recently started being shipping, and it s full of recent Intel hardware. Also, with lenny being frozen for 5 months, we are currently a bit behind regarding hardware support. I installed lenny on it, as I usually run testing+APT pinning. What I m describing here is what is unsupported in lenny out of the box. Wireless:
Needs a 2.6.27 kernel (iwlagn driver), Lenny only has 2.6.26. Downloaded from the kernel team s unofficial repo. Firmware isn t packaged in Debian (firmware-iwlwifi needs an update). Needed to download it from Intel. Graphics:
Intel device, unsupported with lenny s driver (but vesa works surprisingly well, oI only noticed that I was using vesa when I tried to play a video and found out I had no xv support).
Works with experimental s Xorg and the experimental intel driver, but that Xorg needs some polishing. The evdev driver now handles all inputs, so the keymap has to be configured differently (as usual, #debian-x people were very helpful). Suspend/Resume:
Works out of the box using pm-utils. No need for quirks. All in all, it was easier than I expected, and support will probably be perfect for lenny+1/2 ;)

David Welton: Slicehost vs Linode

Since hosting is the major expense for DedaSys LLC, and obviously a critical part of much of what I do, getting the right one is very important. Naturally, "the right one" for me may not be the right one for everyone. I am a fair sysadmin for small numbers of machines, so I don't mind doing that myself - I don't need, nor want to pay for hand holding.
Since this post has become fairly popular, I am going to link to my Linode affiliate URL if you'd like to sign up with Linode - thanks! Other than running my sites there, I have no other affiliation with Linode. And, if you're more a fan of Slicehost, here is my referral page on Slicehost.
I recently moved everything over to Slicehost on the recommendations of friends, and am so far fairly happy with the experience. It's cheaper, simpler, and more flexible than Layered Tech was. To boot, I also like the fact that Slicehost is run out of St. Louis, Missouri, rather than some really expensive tech center like San Francisco or Boston. Hosting is basically a commodity, and much like you wouldn't want to put a factory in San Francisco, you don't want your hosting their either. However, I discovered something annoying about Slicehost: they use x86_64 servers, which, per se, doesn't really matter to me - I use open source code that can run on any number of architectures. The problem is that this particular architecture uses more memory than plain old x86. Significantly more. My Layered Tech server with 1 gig of memory was hitting the swap space a bit, but the same code on a slice was swapping quite heavily, despite the fact that I'd moved PostgreSQL off to its own slice. Since I pretty much exclusively run Rails, I decided to look into Phusion's "Ruby Enterprise Edition", which is basically just some nice hacking on Ruby's garbage collection mechanism. What they've done is nice, and I may end up using it, but ultimately it's buying me space that I would also gain from simply moving back to x86. With that in mind, I decided to take another look at what appears to be emerging as one of Slicehost's main competitors, Linode, who *do* use x86 servers. Here are my results, which are admittedly not all that scientific, but what the heck - you're getting them for free, and they were pretty quick to whip up. Service, Support, Setup But before we begin with the numbers, I want to add a few words of caution. One of the big things about hosting, to me at least, is how they deal with unexpected random negative events. Connections going down, disk breakage, DoS attacks, and so on. It's really hard to get an idea of just what sort of people you're dealing with until you've "ridden the river together". I don't really know what sort of response times, uptime, and all that either Slicehost or Linode have, so there are potentially some big intangibles there that are not quite as easy to draw pretty charts for. In terms of the console/setup/management tools, I liked Slicehost's simplicity more - Linode gives you more options, but they're a bit fiddly and cluttered feeling at times. For instance, Linode lets you pick how much swap space to give your disk image, but doesn't include a bit of javascript to balance out the swap and regular partitions, so that if you type in a larger swap number, you have to do the math and subtract that from the other number. Annoying, but not a big deal. Linode lets you pick various data centers in the US (no Europe, yet). Slicehost gives you the option to do backups of your disk images, which is nice, and something that Linode lacks. Comparing plans Since I'm interested in comparing hardware and machines I actually have access to, here are the plans I am currently signed up with, and the salient numbers:
Slicehost 1024 Slicehost 512 Linode 720
Memory 1024 512 720
Bandwidth 400 200 400
Disk 40 20 24
Cost 70 38 39.95
Memory / Dollar: Bandwidth / Dollar: Disk / Dollar: Linode mostly comes out ahead, but not by that much, except for bandwidth. However, let's take a crude look at x86_64 vs x86 memory usage. First, ./script/console (a Rails console) for the same code base on two different machines, showing the virtual memory size (VSZ) and resident set size (RSS): And just to look at something else that's a bit smaller, I ran the following script:
puts File.open("/proc/self/status", "r").read
And got the following data: Being charitable with those numbers, we get x86 taking up 77% the memory that x86_64 does. So let's add that to our comparison of how much memory you're getting per dollar on Slicehost and Linode: Wow! That's a fairly significant difference. Performance That's most of what we can glean from published numbers, and running a few simple experiments. However, there's another factor that's important: performance. "Virtual Private Server" systems, or simply VPS's, got a bad name in the past because they were "overbooked" - too many virtual servers competing for the same CPU resources on one machine. Slicehost and Linode both look like they want to avoid that kind of bad reputation, and so far all the systems I have used have felt snappy and responsive. Now here's where we get really unscientific... I decided to try and do something, even if it wasn't much, to get some kind of objective measurement of what kind of CPU I was getting on the machines. This is really unscientific, because the machines do have other duties (I don't have the cash, time or inclination to set up random servers just for testing), and of course, who knows what else is sharing the computer with my systems: if you get a relatively unused computer, you can apparently pick up extra cycles for yourself, over and above your guaranteed minimum. But c'est la vie, and so I decided to do some numbers anyway. I picked a C implementation of mandelbrot from the language shootout more or less "for the hell of it" (I'm going to keep repeating "unscientific" and invite someone to do better tests than I have). I ran this code every 20 minutes for a couple days, and then averaged out the run times: As expected, the higher power Slicehost 1024 machine wins out in terms of raw speed (less time is better), but not by that much over the Linode system. Indeed, when we factor in the relative prices, Linode comes out ahead, again: So it looks like we're not paying a CPU penalty for having more memory, bandwidth, disk, etc... Notes
  • Nothing in these statistics is indicative of future directions that both Linode and Slicehost might take. Slicehost was recently acquired by Rackspace, and that could have effects on the service they provide. Maybe one or both will come under financial pressure and start "overbooking" their servers.
  • The spreadsheet I used is available via Google docs, for the curious. I did most of the work in OpenOffice, and then uploaded it though, because working with the web spreadsheet was kind of painful. Unfortunately, you can't select non-contiguous data ranges in the Google spreadsheet, so the labels are interspersed with the data. Yuck. Also, Google docs doesn't handle 'time' values nicely, which is what the performance data was originally. The spreadsheet is here: http://spreadsheets.google.com/pub?key=pVDeZF6ire2YwATBYb4mBKQ
  • The standard deviation on the processing times is higher for both slices than the linode system. Not quite sure what that means in terms of what's going on under the hood, but I thought it was interesting.

Russell Coker: New version of Bonnie++ and Violin Memory

I have just released version 1.03e of my Bonnie++ benchmark [1]. The only change is support for direct IO in Bonnie++ (via the -D command-line parameter). The patch for this was written by Dave Murch of Violin Memory [2]. Violin specialise in 2RU storage servers based on DRAM and/or Flash storage. One of their products is designed to handle a sustained load of 100,000 write IOPS (in 4K blocks) and 200,000 read IOPS per second for it’s 10 year life (but it’s not clear whether you could do 100,000 writes AND 200,000 reads in a second). The only pricing information that they have online is a claim that flash costs less than $50 per gig, while that would be quite affordable for dozens of gigs and not really expensive for hundreds of gigs, as they are discussing a device with 4TB capacity it sounds rather expensive - but of course it would be a lot cheaper than using hard disks if you need that combination of capacity and performance. I wonder how much benefit you would get from using a Violin device to manage the journals for 100 servers in a data center. It seems that 1000 writes per second is near the upper end of the capacity of a 2RU server for many common work-loads, this is of course just a rough estimation based on observations of some servers that I run. If the main storage was on a SAN then using data journaling and putting the journals on a Violin device seems likely to improve latency (data is committed faster and the application can report success to the client sooner) while also reducing the load on the SAN disks (which are really expensive). Now given that their price point is less than $50 per gig, it seems that a virtual hosting provider could provide really fast storage to their customers for a quite affordable price. $5 per month per gig for flash storage in a virtual hosting environment would be an attractive option for many people. Currently if you have a small service that you want hosted a virtual server is the best way to do it, and as most providers offer little information on the disk IO capacity of their services it seems quite unlikely that anyone has taken any serious steps to prevent high load from one customer from degrading the performance of the rest. With flash storage you not only get a much higher number of writes per second, but one customer writing data won’t seriously impact read speed for other customers (with hard drive one process that does a lot of writes can cripple the performance of processes that do reads). The experimental versions of Bonnie++ have better support for testing some of these usage scenarios. One new feature is measuring the worst-case latency of all operations in each section of the test run. I will soon release Bonnie++ version 1.99 which includes direct IO support, it should show some significant benefits for all usage cases involving Violin devices, ZFS (when configured with multiple types of storage hardware), NetApp Filers, and other advanced storage options. For a while I have been dithering about the exact feature list of Bonnie++ 2.x. After some pressure from a contributor to the OpenSolaris project I have decided to freeze the feature list at the current 1.94 level plus direct IO support. This doesn’t mean that I will stop adding new features in the 2.0x branch, but I will avoid doing anything that can change the results. So in future benchmark results made from Bonnie++ version 1.94 can be directly compared to results that will be made from version 2.0 and above. There is one minor issue, new versions of GCC have in the past made differences to some of the benchmark results (the per-character IO test was the main one) - but that’s not my problem. As far as I am concerned Bonnie++ benchmarks everything from the compiler to the mass storage device in terms of disk IO performance. If you compare two systems with different kernels, different versions of GCC, or other differences then it’s up to you to make appropriate notes of what was changed. This means that the OpenSolaris people can now cease using the 1.0x branch of Bonnie++, and other distributions can do the same if they wish. I have just uploaded version 1.03e to Debian and will request that it goes in Lenny - I believe that it is way too late to put 1.9x in Lenny. But once Lenny is released I will upload version 2.00 to Debian/Unstable and that will be the only version supported in Debian after that time.

9 December 2008

Martin Michlmayr: Recovery mode for QNAP devices available now

QNAP recently released an upgrade for u-boot, the boot loader used on most QNAP devices, that adds a recovery mode. With this recovery mode, a backup image is requested via TFTP and then written to flash. This is useful in case there are problems during the installation or an upgrade of Debian. While Debian itself works well on QNAP and another NAS devices, we get reports from users every once in a while that their machine stopped booting (either after an upgrade or for no good reason) and it's usually impossible to say why since these devices are headless. The recovery mode allows them to put an image into flash that is known to work or an image of the installer that can be used as a rescue option. Essentially, the recovery mode removes the need for a serial console in many cases. I've added information about the recovery mode for the QNAP TS-109, TS-209 and TS-409/TS-409U, including installation instructions of users already running Debian.

David Welton: Ruby Shootout

Antonio Cangiano has an interesting set of Ruby benchmarks here: http://antoniocangiano.com/2008/12/09/the-great-ruby-shootout-december-2008/ The two results that were interesting to me were that JRuby does so well, and that REE ("Ruby Enterprise Edition") was a significant improvement over "plain old Ruby" too. I knew that the JRuby guys have done a lot of work, and done a nice job with their implementation, but didn't realize just how good it was. REE is a clever idea, but not that much code, and aimed at memory usage, not CPU, so it's interesting to see how much faster it ends up according to these tests. A few things that would be interesting to see:
  • Raw startup time. Yeah, that probably penalizes JRuby, but it is still a scripting language, and using it like one isn't possible if it takes forever to start up. How much slower is it?
  • A more detailed look at REE's times. How is it that it's that much faster because of some memory tweaks?
In any case, it's a nice bit of work by Antonio - grazie! Update - old, slow davidw missed the fact that there was a startup time benchmark included. Oops.

David Welton: Ruby Shootout

Antonio Cangiano has an interesting set of Ruby benchmarks here: http://antoniocangiano.com/2008/12/09/the-great-ruby-shootout-december-2008/ The two results that were interesting to me were that JRuby does so well, and that REE ("Ruby Enterprise Edition") was a significant improvement over "plain old Ruby" too. I knew that the JRuby guys have done a lot of work, and done a nice job with their implementation, but didn't realize just how good it was. REE is a clever idea, but not that much code, and aimed at memory usage, not CPU, so it's interesting to see how much faster it ends up according to these tests. A few things that would be interesting to see: In any case, it's a nice bit of work by Antonio - grazie! Update - old, slow davidw missed the fact that there was a startup time benchmark included. Oops.

Lucas Nussbaum: The Project membership procedures GR

So, the call for vote on the “Project membership procedures” GR was sent. Since I took part in the discussions that lead to that GR, I feel obliged to explain my point of view. What this GR isn’t about
This GR isn’t about the merits of Joerg Jaspert’s proposal. I personally don’t think that the changes he wants to implement are what we need in Debian, but even if I fully agreed with those changes, I would still disagree with the process that led to those changes. Also, this GR isn’t about Joerg Jaspert himself. I deeply respect him and his awesome work for Debian. And I’m sure that this vote could have been triggered by decisions announced by someone else. What this GR is about
I think that the question we are asked to vote on is:
Some people in Debian have a special role, and special privileges. Does it allow them to change important aspects of our project, without the approval of all the other developers?
Or, put differently:
Where is our limit between Doocracy and Democracy?
I’m all for listening to developers who contribute(d) a lot. I think that most people, when skimming through posts in a big thread on -devel@, will look for posts from people who did a lot of work for Debian, or who usually post interesting ideas. However, that doesn’t mean that those people should feel empowered to decide changes to important parts of our project, without first discussing those changes with all other developers, and making sure that those changes are consensual. So, I hope that we will send a clear message that says: you are very welcome to propose changes, but please make sure that they are properly discussed within the developers before they are implemented. Joerg’s initial mail on d-d-a, with a few s/decision/proposal/, and a final question phrased like “Any comments? Suggestions? Other ideas?”, could have been the start of an interesting discussion about how we can integrate non-developing contributors in Debian. And if too many developers disagreed, we could have had an opinion poll (it would be great to have an infrastructure for running polls inside Debian, like what Jeroen did three times a long time ago), or even a GR, like we did for Debian Maintainers. For this actual vote, there are two similar options on the ballot (choices 1 and 2, respectively “amendment text A” and the original text on the vote page). I proposed this amendement (choice 1) because the original text is unclear, and mixes several different questions, forcing voters to answer several (secondary) questions at once, like: The amendment aims at going straight to the point. And yes, it is only asking the DAMs, but if the developers ask the DAMs not to do something, and the DAMs do it anyway, we clearly have a bigger problem. I believe that the way those decisions were announced was a mistake (that unfortunately none of the people involved have been willing to admit), not that the DAMs are trying to take-over Debian, so there’s no need for a stronger wording.

Wouter Verhelst: The advantages of a home-grown comment system

A while ago, I was investigating the possibility to move blog backend to something else; something like, say, drupal, so that I wouldn't have to maintain it too much myself. For those who care, this blog is a very strange contraption based on subversion, blosxom, php, and a postres backend for the comments. I've now dropped that migration thought, for a very simple reason: comment spam. A while back, the spammers had found my blog, and started placing comments using a bot. They might think that these comments will eventually show up on my website, but that's wrong; I always moderate away spam. First, they posted a few comments. I changed a few details about the form, and the bots (who only went to the POST URL, never checking whether the form they requested was unchanged) failed miserably. Then, they posted loads and loads of comments, in a weird attempt to overrun me with comments. One psql run and one DELETE statement later, those comments were gone -- and one minor form change later, the bots failed miserably, again. This went on for a few months, until the stupid spammer finally understood that he was wasting loads of his time in trying to post something on a website that wasn't ever going to enable his comments, anyway. Or so I thought. You see, the thing they're really after is my pagerank. In itself, grep.be is nothing special -- but planet.grep.be is, and apparently some of that pagerank score trickles to the other grep.be subdomains. Or, at least, that's what the spammers seem to think, in case it isn't (I wouldn't know). When the comment spam on my blog had been silent for a few weeks, I found that the spammers had found my gallery installation, and had posted some several thousand comments there. One DELETE statement later they were gone, but a few hours later some of them were back. I don't know the gallery source code well enough to pull the same trick here (disable comments until manual moderation), and unless I want to do something like using a CAPTCHA on my gallery site (I don't) or disabling comments altogether (I don't, either), I'll just have to resort to removing these comments from the database. At least by doing that, I can remove them all in one go. And at least the spammers are easily recognizable. For now. Perhaps I'll have to look into changing gallery's source code after all... or, perhaps, just use something else. Sigh. Stupid spammers

Josselin Mouette: RubyGem is from Mars, apt-get is from Earth

There is again some ongoing debate about Ruy gems and how to integrate them cleanly into the operating system. Let s put aside the fact such tools are useful on Windows and MacOS which don t have decent packaging systems. This is not a reason to dictate stupid requirements for other operating systems. Still, even without that, gems, eggs and the like are great tools for development; tools that developers can t work without today. They allow to easily setup a development environment with everything needed, at the latest versions. However they were not meant for integration and production environments, and will never be suitable for them. We re living in another world indeed: a world where servers must be up 24/7, where security issues flood your inbox every day, where you need dozens of servers running the very same software. This world is the Earth. Python eggs and Ruby gems were designed for the same target audience and with similar requirements; as such, they share the same deficiencies when it comes to other audiences:
  1. They replace the operating system s packaging tool. This is very nice to not wait for the packagers when you want the latest development version, but you lose track of what is actually installed. In production, you need to know exactly what s installed and at what version. You also need to know what you will need to update in case of a security issue.
  2. They install packages automatically on the system. This is really the biggest WTF; there are some reasons to do that to begin with, but they are all wrong.
  3. They use a specific file format. This requirement comes mostly from the Windows world, and it really makes no sense on Unix. It makes it much harder to integrate complex applications using components in different languages.
  4. They ship all files at the same place, happily violating the FHS and making it even harder to integrate with other things.
Python tools (setuptools and easy_install) have shifted their philosophy and brought a few small improvements which allow us to easily work around issues 1-3. These tools now include all you need to build a development environment in any directory that will not have an impact on the system packaging, making a clear distinction between the two targets. Furthermore, the metadata is shipped separately and can safely be included in a distribution package. Similarly, modules will not be installed automatically on your system. I have yet to see such a move from Ruby developers. However, what we are still missing is something along the lines of dh_make_perl: starting from a CPAN module, it will generate a clean and working Debian package in a few minutes. There have been some similar attempts for Python, but nothing as efficient. And I am certainly guilty of not having done something in this area, as one of the most knowledgeable of issues we encounter while packaging Python modules. As a note, I should add the underlying issue behind all of this is still the same: the NIH syndrome. Developers are reinventing the wheel, engine and transmission. Which is not that bad per se, but by not looking at existing solutions for the problem of making a car move, they are inventing a square wheel, a steam-powered engine and a superconductor-powered magnetic transmission. For example, while trying to fix the 4th of items listed earlier and they are really willing to fix it and several more general issues, setuptools developers forgot to look at the existing solutions: Certainly, the existing tools are everything but perfect, and not necessarily suitable for Ruby and Python, but some of the design ideas behind them are clearly the good solutions to some of the issues of software development and integration. Adapting these ideas to radically different languages is going to take more time than just throwing other layers of symlink farms.

Wouter Verhelst: Rails: followup

I received quite some comments on my rant about Ruby on Rails a few days ago; I guess I must have received some inbound link on a ruby-fanboy-website or some such. Most of it is just bashing me since, I'll admit, my post wasn't very constructive (and which according to my policy of only blocking spammers I've not moderated away), some of it just posits another opinion about packaging (which is valid), and one Eric Anderson gave a good and constructive set of arguments that I just have to reply to. First of all, yes, I hate RubyGems more than I hate Ruby on Rails. However, Ruby on Rails is the major success story in the Ruby community, and the main reason why people use that language; it's not unfair to say that I won't use RoR because of RubyGems. But perhaps I should've been clearer. Anyway. Eric mentions that RubyGems "solves two problems that other packaging systems are not addressing": the ability to install two versions of the same library, and the ability to install a single package on multiple operating systems. Well, first of all, the latter one simply is not true. There's CPAN.pm, which does much the same thing as RubyGems; but much of CPAN can be easily turned into a Debian (or RPM, or whatnot) package. The few cases where it can't, you're usually dealing with a broken CPAN package, anyway. There are similar things for Python (egg), and, heck, even TeX (CTAN). The fact that other scripting languages have proper and working packaging systems only outlines that there really isn't an excuse for the horrors of RubyGems. Second, the fact that you even need to be able to install multiple versions of a library really shows that there's a problem with your development ecosystem. C, Perl, and Python programmers are used to stable APIs, and prefer not to change their APIs all that much. Most packaging systems reflect that preference, and deal with incompatible API changes the way they should: as the exception, rather than the rule. The people in the Ruby ecosystem clearly have a different opinion on that, which probably results in the difference in packaging system requirements. Personally, I prefer the non-Ruby way—I'll leave the discussion about "what happens when you need to do an urgent security update of one of your libraries but the API has changed three times since you last looked at it and now the library update breaks your application" as an excercise to the reader. In closing, I'd like to reply to this one sentence that Eric put in his comment:
And of course there is no reason software cannot start as a gem (for people close to the ruby community) but as it's popularity increases packages can be created that are more tightly integrated into the native package manager.
Well, in an ideal world, he'd be right: there would be no reason. Unfortunately, in the RubyGems world—which is far, far away from an ideal world—the fact is that packaging RubyGems in a sane way so that they'll integrate with the rest of a Debian system is simply impossible. You simply cannot currently go from a gem and create a package out of that, because of how gems are done. That, more than anything, was what I was objecting to. I can understand that many Ruby developers do not care about this much; that they are used to RubyGems, and that they can geet anything they need using that system. However, they should understand that different people have different preferences, and that packages for systems other than RubyGems is going to be necessary if their software is to become popular beyond the select set of people who care enough about Ruby. I personally know of plenty of people (myself included) who prefer things to be installed as operating-system level packages on the Linux systems they install; and even if it's not your personal preference to do things that way, you should at the very least not stand in the way of those who do.

Next.

Previous.
