Search Results: "tar"

10 February 2013

David Bremner: First Steps with Argyll and ColorHug

In April of 2012 I bought a ColorHug colorimeter. I got a bit discouraged when the first thing I realized was that one of my monitors needed replacing, and put the the colorhug in a drawer until today. With quite a lot of help and encouragment from Pascal de Bruijn, I finally got it going. Pascal has written an informative blog post on color management. That's a good place to look for background. This is more of a "write down the commands so I don't forget" sort of blog post, but it might help somebody else trying to calibrate their monitor using argyll on the command line. I'm not running gnome, so using gnome color manager turns out to be a bit of a hassle. I run Debian Wheezy on this machine, and I'll mention the packages I used, even though I didn't install most of them today.
  1. Find the masking tape, and tear off a long enough strip to hold the ColorHug on the monitor. This is probably the real reason I gave up last time; it takes about 45minutes to run the calibration, and I lack the attention span/upper-arm-strength to hold the sensor up for that long. Apparently new ColorHugs are shipping with some elastic.
  2. Update the firmware on the colorhug. This is a gui-wizard kindof thing.
     % apt-get install colorhug-client
     % colorhug-flash 
    
  3. Set the monitor to factory defaults. On this ASUS PA238QR, that is brightness 100, contrast 80, R=G=B=100. I adjusted the brightness down to about 70; 100 is kindof eye-burning IMHO.
  4. Figure out which display is which; I have two monitors.
     % dispwin -\?
    
    Look under "-d n"
  5. Do the calibration. This is really verbatim from Pascal, except I added the ENABLE_COLORHUG=true and -d 2 bits.
     % apt-get install argyll
     % ENABLE_COLORHUG=true dispcal -v -d 2 -m -q m -y l -t 6500 -g 2.2 test
     % targen -v -d 3 -G -f 128 test
     % ENABLE_COLORHUG=true dispread -v -d 2 -y l -k test.cal test
     % colprof -v -A "make" -M "model" -D "make model desc" -C   "copyright" -q m -a G test
    
  6. Load the profile
     % dispwin -d 2 -I test.icc           
    
    It seems this only loads the x property _ICC_PROFILE_1 instead of _ICC_PROFILE; whether this works for a particular application seems to be not 100% guaranteed. It seems ok for darktable and gimp.

Stefano Zacchiroli: bits from the DPL for January 2013

(insert here: I've been to FOSDEM, I got a nasty flu, and other $lame_excuses for the delay in sending out this report) Dear Project Members, here's the monthly DPL activity report, this time for January 2013. About the next DPL This is the last DPL report before the start of the election process for the next term: around early March, about 20 days from now, the Secretary will send out the call for nominations. I'd like to respond (also) here to inquiries I'm receiving these days: I will not run again as DPL. So you have about 20 days to mob^Wconvince other DDs to run, or decide to run yourself. Do not to wait for the vary last minute, as that makes for lousy campaigns. I'm available to give feedback about my DPL experience to prospective candidates, ... and also to join mobbing^Wconvincing actions toward potential candidates. Just contact me. Call for helps Assets Cloud Images Work has gone on also on the front of supporting Debian installation in public "clouds". Thanks to Arnaud Patard, Jose Miguel Parrella Romero, Pierre Couzy, and Gianugo Rabellino, we now have Debian testing images for Microsoft Azure. Together with Amazon EC2, this is the second large provider supporting Debian via images maintained by Debian Developers. More providers are welcome, exactly as more hardware/CD vendors shipping Debian are always welcome. If you want to contribute support for other providers just show up on the -cloud mailing list and say so. Some documentation effort in view of Wheezy are in need of help too, in order to let our users know about "cloud" options, see #695681. DPL helpers The DPL helpers experiment goes on. We have had 2 more IRC meetings in January (see the minutes). Documentation of the "team" communication channels (mailing list, IRC, Git, etc.) is now available from the DPL wiki page. Talks I've given an invited Debian talk at Polytech'Grenoble, as part of a free software event organized for students of local universities. Slides of the talk are available. I'd like to thank Vincent Danjean for the event organization. Let's release Wheezy now!
Cheers.
PS the day-to-day activity log for January 2013 is available at the usual place master:/srv/leader/news/bits-from-the-DPL.txt.201301

Matthew Garrett: Linux Foundation Secure Boot support released - what does it mean?

The UEFI bootloader that the Linux Foundation have been working on has just been released. That means we now have two signed bootloaders available - this one and shim.
Does this mean Linux distributions can now support Secure Boot?They've actually been able to for a while. Ubuntu shipped with Secure Boot support last October, and Fedora shipped with Secure Boot support in January. Both used Shim rather than the Linux Foundation loader, and Shim's also being used by a variety of smaller distributions. The LF loader is a different solution to the same problem.
Is the Linux Foundation the preferred loader for distributions?Probably not in most cases. One of the primary functional differences between Shim and the LF loader is that the LF loader is based around cryptographic hashes rather than signing keys. This means that the user has to explicitly add a hash to the list of permitted binaries whenever a distribution updates their bootloader or kernel. Doing that involves being physically present at the machine, so it's kind of a pain.
Why use it at all, then?Being hash based means that you don't need to maintain any signing infrastructure. This means that distributions can support Secure Boot without having to change their build process at all. Shim already supports this use case (and some distributions are using it), but the LF loader has nicer UI for managing it.
Any other reasons?Actually, yes. Shim implements Secure Boot loading in a less than entirely ideal way - it duplicates the firmware's entire binary loading, validation, relocation and execution code. This is necessary because the UEFI specification doesn't provide any mechanism for adding additional authentication mechanisms. The main downside of this is that the standard UEFI LoadImage() and StartImage() calls don't work under Shim. The LF loader hooks into the low-level security architecture and installs its own handlers, which means the standard UEFI interfaces work. The upshot is that you can use bootloaders like Gummiboot or efilinux without having to modify them to call out to Shim.
Why doesn't Shim do the same?The UEFI architecture is slightly complicated. The UEFI specification itself defines the upper layers of the firmware, basically covering everything that UEFI applications and operating systems need. It doesn't define the lower layers of a UEFI implementation. Those are contained in the UEFI Platform Initialization spec, and that's what defines the security architecture interfaces that the LF loader hooks into. The problem is that it's completely valid to implement the UEFI specification without implementing the Platform Initialization specification, and if anyone does that then the LF loader will fail.
Can't you try both approaches?Yes, and that's actually pretty much the plan now. I'm working on integrating the LF loader's UI and security code into Shim with the aim of producing one loader that'll satisfy the full set of use cases, and James is happy with this.
Which should I use?Depends. If you want to support gummiboot (and aren't willing to patch it to call out to Shim), you'll need to use the LF loader. If you want to use key-based signing setups to avoid forcing re-enrolment on updates, you'll need to use Shim. If you're somewhere in the middle, you can probably use either. Once we've got the code merged, you won't have to make a choice.

comment count unavailable comments

Hideki Yamane: license for MIBs

Unfortunately, most of MIBs doesn't meet DFSG since RFC is non-free. However, RFC5378 was released and it says "code components in RFCs are licensed under Simplified BSD license (BSD-3-clause)", See Trust Legal Provisions (TLP) Documents page.

Code components are

ABNF definitions, XML Schemas, XML DTDs, XML RelaxNG definitions, tables of values, MIBs, PIBs, ASN.1, and classical programming source code
So, recent MIBs can be included to Debian package :)

But it isn't enough because those RFCs are almost 30/260, 90% are not DFSG-free. And 190/260 RFCs are owned by ISOC and IETF trustee, I hope thay will release old MIBs code in RFCs under DFSG-free license as same as after RFC5378.

Bernhard R. Link: Debian version strings

As I did not find a nice explanation of Debian version numbers to point people at, here some random collection of information about: All our packages have a version. For the package managers to know which to replace with which, those versions needs an ordering. As version orderings are like opinions (everyone has one), none of them would match any single one chosen for our tools to implement. So maintainers of Debian packages sometimes have to translate those versions into something the Debian tools understand. But first let's start with some basics: A Debian version string is of the form: [Epoch:]Upstream-Version[-Debian-Revision] To make this form unique, the Upstream-Version may not contain an colon if there is no epoch and not contain a minus, if there is no Debian-Revision. The Epoch must be an integer (so no colons allowed). And the Debian-Revision may not contain a minus sign (so the Debian-Revision is everything right of the right-most minus sign, or empty if there is no such sign). Two versions are compared by comparing all three parts. If the epochs differ, the biggest epoch wins. With same epochs, the biggest upstream version wins. With same epochs and same upstream versions, the biggest revision wins. Comparing first the upstream version and then the revision is the only sensible thing to do, but it can have counter-intuitive effects if you try to compare versions with minus signs as Debian versions:
$ dpkg --compare-versions '1-2' '<<' '1-1-1' && echo true   echo false
true
$ dpkg --compare-versions '1-2-1' '<<' '1-1-1-1' && echo true   echo false
false
To compare two version parts (Upstream-Version or Debian-Revision), the string is split into pairs of digits and non digits. Consecutive digits are treated as a number and compared numerrically. Non-digit parts are compared just like ASCII strings with the exception that letters are sorted before non-letters and the tilde is treated specially (see below). So 3pl12 and 3pl3s are slit into (3, 'pl', 12, '') and (3, 'pl', 3, 's') and the first is the larger version. Comparing digits as characters makes not sense at least at the beginning of the string (otherweise version 10.1 would be smaller than 9.3). For digits later in the string there are two different version schemes competing here: There is GNU style 0.9.0 followed by 0.10.0 and decimal fractions like 0.11 < 0.9. Here a version comparison algorithm has to choose one and the one chosen by dpkg is both the one supporting the GNU numbering and also the one easier supporting the other scheme: Imagine one software going 0.8 0.9 0.10 and one going 1.1 1.15 1.2. With out versioning scheme the first just works, while the second has to be translated into 1.1 1.15 1.20 to still be monotonic. The other way around, we would have to translate the first form to 0.08 0.09 0.10, or better 0.008 0.009 0.010 as we do not know how big those numbers will be, i.e. one would have to know beforehand where the numbers will end up, while adding zeros as needed for our scheme can be done with only knowing the previous numbers. Another decision to be taken is how to treat non-numbers. The way dpkg did this was assuming adding stuff to the end increases numbers. This has the advantage to not needing to special case dots, as say 0.9.6.9 will be bigger than 0.9.6 naturally. I think back then this decision was also easier as usually anything attached was making the version bigger and one often saw versions like 3.3.bl.3 to denote some patches done atop of 3.3 in the 3th revision. But this scheme has the disadvantage that version schemes like 1.0rc1 1.0rc2 1.0 do not map naturally. The classic way to work arround this is to translate that into 1.0rc1 1.0rc2 1.0.0 which works because the dot is a non-letter (it also works with 1.0-rc1 and 1.0+rc1 as the dot has a bigger ASCII number than minus or plus). The new way is the specially treated tilde character. This character was added some years ago to sort before anything else, including an empty string. This means that 1.0~rc1 is less than 1.0:
dpkg --compare-versions '1.0~rc1-1' '<<' '1.0-1' && echo true   echo false
This scheme is especially useful if you want to create a package sorting before a package already there, as you for example do want with backports (as a user having a backport installed upgrading to the next distribution should get the backport replaced with the actual package). That's why backport usually having versions like 1.0-2~bpo60+1. Here 1.0-2 is the version of the un-backported version; bpo60 is a note that this is backported to Debian 6 (AKA squeeze) and the +1 is the number of the backport in case there are multiple tries necessary. (Note the use of the plus sign as the minus sign is not allowed in revisions and would make the part before a part of the upstream version). Now, when to use which technique? Some common examples:

Richard Hartmann: Cables

Leaving for Finland in less than 5 hours and my GPS keeps acting up, external disks refuse to be mounted, and copying data off of SD cards results in I/O errors... The SD card I/O errors are apparently caused by my still-half-broken ThinkPad X201 which never got fixed properly. To be specific, the internal card reader is acting up. But to get back to the GPS and my external drives... I had feared my ThinkPad was in its death throes when I decided to try another cable. Lo and behold, everything (other than my built-in SD card reader) started to work all of a sudden. This is the third time I've had issues with random USB cables. For Micro USB I decided to only use ones that came packaged with a phone or similar as those tend to be high quality. If anyone has a suggestion about where to source high-quality Mini USB cables after returning from Finland, please let me know.

8 February 2013

Philipp Kern: Mozilla's direction

Am I the only one who's disappointed with the route Mozilla's taking and left wondering what the direction is? First they killed off the development of Thunderbird because, as we all know, people mainly use webmail these days. Then they presented us their view that the big Certificate Authorities are too big to fail, as CAs gravely violated our trust (c.f. Trustwave and their MitM authority). And "now" they're also blocking the introduction of new formats into their browser because they cannot be the one who innovates. Instead Microsoft and Apple obviously need to take the lead in introducing a format into their browsers because otherwise it wouldn't be useful. Even though it's safe to say that Chrome and Firefox make up for more than half of the desktop browser market share. It might be that Chrome's nibbling from Firefox's, still IE seems to be in decline and Safari is rather a further mention than something many people would care strongly about.

There were of course some valid reasons for not supporting WebP yet. But most of them got fixed in the meantime and all we hear is the referal to proprietary vendors who need to move first. If I'd want to depend on such vendors I'd go with proprietary operating systems. (Having to deal with hardware products of proprietary vendors at $dayjob is enough.) So what's up Mozilla? The solution is to ignore your users and tag bugs with patches wontfix?

The only real advantage of Firefox over Chromium these days is the vast amount of plugins and extensions (e.g. Pentadactyl, for which there is no real equivalent available). Another sad fact is that you need to pull Firefox from a 3rd party repository (even though packages are coming from the 2nd party) to get a current version onto your Debian system to work with the web. But then it's not Mozilla who's to blame here. Maybe we should've introduced one Iceweasel version that's allowed to have reverse-dependencies and one that cannot.

(This post might contain hyberboles, which should be considered as such.)

Russ Allbery: Still here

Well, I had a very nice run at the start of this year in writing journal entries nearly every day, and then I seem to have gotten much quieter. This is not actually because less stuff is going on, but I started working on larger projects without meaningful daily progress, and I also got drawn into some very rewarding creative work that has kicked my schedule in the ass. Schedules are something that I've always struggled with. I'm fairly convinced that I have even more than the natural human tendency towards a longer than 24-hour schedule. (I lived in 28-hour days and 6-day weeks for one full quarter when I was a college student and rather liked it, but it wasn't practical enough to stay with.) This means that, without applying a lot of discipline, I tend to stay up later and later because I'm engaged in interesting things and don't want to stop, and then drift further and further out of sync with the world. When I was just out of college and working as just another member of a team that wasn't very close-knit, I just shrugged and let it happen. I used to get into work at about two or three in the afternoon and work until well past midnight. It had some lovely properties, such as getting to work most of my "day" after everyone else had left and the building was quiet. Unfortunately, it's really not compatible with a lead position that requires interaction with people and quite a few meetings and other types of coordination. Given that I can't just let my schedule go wherever, I realized a year or two ago that I do much better if I can stick to a fairly reliable and consistent schedule and go to bed at a regular time, even if I'm involved in something. It cuts off my evenings in a way I don't like, but it makes mornings much more pleasant and it makes it easier to schedule and stick with various chores like exercise. But it's remarkably hard to get back into that mode once I've gotten out of it, particularly when I get caught up in things in the evenings. This meander is mostly my way of getting these thoughts out of my head and on a screen in front of me so that I'll think about them and build up enough willpower to go back to a regular schedule. It really is worth it; I was keeping one through most of January and it had a lot to do with why January was awesome. Hopefully a more sustantive update tomorrow.

7 February 2013

Russell Coker: Links February 2013

Aaron on Software wrote an interesting series of blog posts about psychology and personal development collectively Titled Raw Nerve , here s a link to part 2 [1]. The best sections IMHO are 2, 3, and 7. The Atlantic has an insightful article by Thomas E. Ricks about the failures in leadership in the US military that made the problems in Afghanistan and Iraq a lot worse than they needed to be [2] Kent Larson gave an interesting TED talk about how to fit more people in cities [3]. He covers issues of power use, transport, space use, and sharing. I particularly liked the apartments that transform and the design for autonomous vehicles that make eye contact with pedestrians. Andrew McAfee gave an interesting TED talk titled Are Droids Taking Our Jobs [4]. I don t think he adequately supported his conclusion that computers and robots are making things better for everyone (he also presented evidence that things are getting worse for many people), but it was an interesting talk anyway. I Psychopath is an interesting documentary about Sam Vaknin who is the world s most famous narcissist [5]. The entire documentary is available from Youtube and it s really worth watching. The movie Toy Story has been recreated in live action by a couple of teenagers [6]. That s a huge amount of work. Rory Stewart gave an interesting TED talk about how to rebuild democracy [7]. I think that his arguments against using the consequences to argue for democracy and freedom (he suggests not using the torture doesn t work and women s equality doubles the workforce arguments) are weak, but he made interesting points all through his talk. Ernesto Sirolli gave an interesting TED talk about aid work and development work which had a theme of Want to help someone? Shut up and listen! [8]. That made me think of Mary Gardiner s much quoted line from the comments section of her Wikimania talk which was also shut up and listen . Waterloo Labs has some really good engineering Youtube videos [9]. The real life Mario Kart game has just gone viral but there are lots of other good things like the iPhone controlled car and eye controlled Mario Brothers. Robin Chase of Zipcar gave an interesting TED talk about various car sharing systems (Zipcar among others), congestion taxes, the environmental damage that s caused by cars, mesh networks, and other things [10]. She has a vision of a future where most cars are shared and act as nodes in a giant mesh network. Madeleine Albright gave an interesting TED talk about being a female diplomat [11]. She s an amazing speaker. Ron Englash gave an interesting TED talk about the traditional African use of fractals [12]. Among the many interesting anecdotes concerning his research in Africa he was initiated as a priest after explaining Georg Cantor s set theories. Racialicious has an insightful article about the low expectations that members of marginalised groups have of members of the privileged groups [13]. Rick Falkvinge has a radical proposal for reforming copyrights with a declared value system [14]. I don t think that this will ever get legislative support, but if it did I think it would work well for books and songs. I think that some thought should be given to how this would work for Blogs and other sources of periodical content. Obviously filing for every blog post would be an unreasonable burden. Maybe aggregating a year of posts into one copyright assignment block would work. Scott Fraser gave an interesting TED talk about the problem with eyewitness testimony [15]. He gave a real-world example of what had to be done to get an innocent man acquitted, it s quite amazing. Sarah Kendzior wrote an interesting article for al Jazeera about the common practice in American universities to pay Adjunct Professors wages that are below the poverty line [16]. That s just crazy, when students pay record tuition fees there s more than enough money to pay academics decent wages, where does all the money go to anyway?

Christoph Berg: PostgreSQL minor releases

We've just put the new PostgreSQL minor releases live on apt.postgresql.org. Building 5 major versions for 10 distributions produces quite a lot of stuff: Compiling took a bit more than 10 hours on a 2-cpu VM. Of course that includes running regression tests and the postgresql-common testsuite. Note: This will be the last update published on pgapt.debian.net. Please update your sources.list entries to point to apt.postgresql.org!

Ian Wienand: Shared libraries and execute permissions

In the few discussions you can find on the web about shared-libraries and execute-permissions, you can find a range of various opinions but not a lot about what goes when you execute a library. The first thing to consider is how the execute-permission interacts with the dynamic loader. When mapping a library, the dynamic-loader doesn't care about file-permissions; it cares about mapping specific internal parts of the .so. Specifically, it wants to map the PT_LOAD segments as-per the permissions specified by the program-header. A random example:
 $ readelf --segments /usr/lib/x86_64-linux-gnu/libcrypto.so.1.0.0
Elf file type is DYN (Shared object file)
Entry point 0x77c00
There are 7 program headers, starting at offset 64
Program Headers:
  Type           Offset             VirtAddr           PhysAddr
                 FileSiz            MemSiz              Flags  Align
  LOAD           0x0000000000000000 0x0000000000000000 0x0000000000000000
                 0x00000000001b5ea4 0x00000000001b5ea4  R E    200000
  LOAD           0x00000000001b6b60 0x00000000003b6b60 0x00000000003b6b60
                 0x0000000000028dc4 0x000000000002c998  RW     200000
The permissions to load the code and data segments are given the Flags output. Code has execute-permissions, and data has write-permissions. These flags are mapped into flags for the mmap call, which the loader then uses to map the various segments of the file into memory. So, do you actually need execute-permissions on the underlying file to mmap that segment as executable? No, because you can read it. If I can read it, then I can copy the segment to another area of memory I have already mapped with PROT_EXEC and execute it there anyway. Googling suggests that some systems do require execute-permissions on a file if you want to directly mmap pages from it with PROT_EXEC (and if you dig into the kernel source, there's an ancient system call uselib that looks like it comes from a.out days, given it talks about loading libraries at fixed addresses, that also wants this). This doesn't sound like a terrible hardening step; I wouldn't be surprised if some hardening patches require it. Maximum compatability and historical-features such as a.out also probably explains why gcc creates shared libraries with execute permissions by default. Thus, should you feel like it, you can run a shared-library. Something trivial will suffice:
int function(void)  
      return 100;
 
$ gcc -fPIC -shared -o libfoo.so foo.c
$ ./libfoo.so
Segmentation fault
This is a little more interesting (to me anyway) to dig into. At a first pass, why does this even vaguely work? That's easy -- an ELF file is an ELF file, and the kernel is happy to map those PT_LOAD segments in and jump to the entry point for you:
$ readelf --segments ./libfoo.so
Elf file type is DYN (Shared object file)
Entry point 0x570
There are 6 program headers, starting at offset 64
Program Headers:
  Type           Offset             VirtAddr           PhysAddr
                 FileSiz            MemSiz              Flags  Align
  LOAD           0x0000000000000000 0x0000000000000000 0x0000000000000000
                 0x000000000000070c 0x000000000000070c  R E    200000
  LOAD           0x0000000000000710 0x0000000000200710 0x0000000000200710
                 0x0000000000000238 0x0000000000000240  RW     200000
What's interesting here is that the shared-library has an entry point (e_entry) at all. ELF defines it as:
This member gives the virtual address to which the system first transfers control, thus starting the process. If the file has no associated entry point, this member holds zero.
First things first, where did that entry point come from? The ld manual tells us that the linker will set the entry point based upon the following hierarchy:
  • the -e entry command-line option;
  • the ENTRY(symbol) command in a linker script;
  • the value of a target specific symbol
  • the address of the first byte of the .text section, if present;
  • The address 0.
We know we're not specifying an entry point. The ENTRY command is interesting; we can check our default-link script to see if that is specified:
$ ld --verbose   grep ENTRY
ENTRY(_start)
Interesting. Obviously we didn't specify a _start; so do we have one? A bit of digging leads to the crt files, for C Run-Time. These are little object files automatically linked in by gcc that actually do the support-work to get a program to the point that main is ready to run. So, if we go and check out the crt files, one can find a definition of _start in crt1.o
$ nm /usr/lib/x86_64-linux-gnu/crt1.o
crt1.o:
0000000000000000 R _IO_stdin_used
0000000000000000 D __data_start
                 U __libc_csu_fini
                 U __libc_csu_init
                 U __libc_start_main
0000000000000000 T _start
0000000000000000 W data_start
                 U main
But do we have that for our little shared-library? We can get a feel for what gcc is linking in by examining the output of -dumpspecs. Remembering gcc is mostly just a driver that calls out to other things, a specs file is what gcc uses to determine which arguments pass around to various stages of a compile:
$ gcc -dumpspecs
...
*startfile:
% !shared: % pg p profile:gcrt1.o%s;pie:Scrt1.o%s;:crt1.o%s 
 crti.o%s % static:crtbeginT.o%s;shared pie:crtbeginS.o%s;:crtbegin.o%s 
The format isn't really important here (of course you can read about it); but the gist is that various flags, such as -static or -pie get passed different run-time initailisation helpers to link-in. But we can see that if we're creating a shared library we won't be getting crt1.o. We can double-confirm this by checking the output of gcc -v (cut down for clarity).
$ gcc -v -fPIC -shared -o libfoo.so foo.c
Using built-in specs.
 ...
/usr/lib/gcc/x86_64-linux-gnu/4.4.5/collect2 -shared -o libfoo.so
/usr/lib/gcc/x86_64-linux-gnu/4.4.5/../../../../lib/crti.o
/usr/lib/gcc/x86_64-linux-gnu/4.4.5/crtbeginS.o
/tmp/ccRpsQU3.o
/usr/lib/gcc/x86_64-linux-gnu/4.4.5/crtendS.o
/usr/lib/gcc/x86_64-linux-gnu/4.4.5/../../../../lib/crtn.o
So this takes us further down ld's entry-point logic to pointing to the first bytes of .text, which is where the entry-point comes from. So that solves the riddle of the entry point. There's one more weird thing you notice when you run the library, which is the faulting address in kern.log:
libfoo.so[8682]: segfault at 1 ip 0000000000000001 sp 00007fffcd63ec48 error 14 in libfoo.so[7f54c51fa000+1000]
The first thing is decoding error; 14 doesn't seem to have any relation to anything. Of course everyone has the Intel 64 Architecture Manual (or mm/fault.c that also mentions the flags) to decode this into 1110 which means "no page found for a user-mode write access with reserved-bits found to be set" (there's another post in all that someday!). So why did we segfault at 0x1, which is an odd address to turn up? Let's disassemble what actually happens when this starts.
00000000000004a0 <call_gmon_start>:
 4a0:   48 83 ec 08             sub    $0x8,%rsp
 4a4:   48 8b 05 2d 03 20 00    mov    0x20032d(%rip),%rax        # 2007d8 <_DYNAMIC+0x190>
 4ab:   48 85 c0                test   %rax,%rax
 4ae:   74 02                   je     4b2 <call_gmon_start+0x12>
 4b0:   ff d0                   callq  *%rax
 4b2:   48 83 c4 08             add    $0x8,%rsp
 4b6:   c3                      retq
We're moving something in rax and testing it; if true we call that value, otherwise skip and retq. In this case, objdump is getting a bit confused telling us that 2007d8 is related to _DYNAMIC; in fact we can check the relocations to see it's really the value of __gmon_start__:
$ readelf --relocs ./libfoo.so
Relocation section '.rela.dyn' at offset 0x3f0 contains 4 entries:
  Offset          Info           Type           Sym. Value    Sym. Name + Addend
000000200810  000000000008 R_X86_64_RELATIVE                    0000000000200810
0000002007d8  000200000006 R_X86_64_GLOB_DAT 0000000000000000 __gmon_start__ + 0
0000002007e0  000300000006 R_X86_64_GLOB_DAT 0000000000000000 _Jv_RegisterClasses + 0
0000002007e8  000400000006 R_X86_64_GLOB_DAT 0000000000000000 __cxa_finalize + 0
Relocation section '.rela.plt' at offset 0x450 contains 1 entries:
  Offset          Info           Type           Sym. Value    Sym. Name + Addend
000000200808  000400000007 R_X86_64_JUMP_SLO 0000000000000000 __cxa_finalize + 0
Thus call_gmon_start, rather unsurprisingly, checks the value of __gmon_start__ and calls it if it is set. Presumably this is set as part of profiling and called during library initialisation -- but it is clearly not an initialiser by itself. The retq ends up popping a value off the stack and jumping to it, which in this case just happens to be 0x1 -- which we can confirm with gdb by putting a breakpoint on the first text address and examining the stack-pointer:
(gdb) x/2g $rsp
0x7fffffffe7d8:        0x0000000000000000      0x0000000000000001
So that gives us our ultimate failure. Of course, if you're clever, you can get around this and initalise yourself correctly and actually make your shared-library do something when executed. The canonical example of this is libc.so itself:
$ /lib/x86_64-linux-gnu/libc-2.13.so
GNU C Library (Debian EGLIBC 2.13-37) stable release version 2.13, by Roland McGrath et al.
Copyright (C) 2011 Free Software Foundation, Inc.
This is free software; see the source for copying conditions.
...
You can trace through how this actually does work in the same way as we traced through why the trivial example doesn't work. If you wondering my opinion on executable-bits for shared-libraries; I would not give them execute permissions. I can't see it does anything but open the door to confusion. However, understanding exactly why the library segfaults the way it does actually ends up being a fun little tour around various parts of the toolchain!

MJ Ray: One of them, one of us

Interesting stuff is happening again and I m doing a bit of travelling where I m not driving much, so I can write some blog posts. If this train stops bouncing quite so much! I think most readers are interested in technology and collaborative work, so it makes sense to alternate those two themes most of the time. So that s what I ll aim for, probably a few posts each week for the next few weeks. Let me know in the comments or our co-op s contract form if there s anything in particular you d like us to cover, else I ll start with my recent experiences installing Debian 6 on a new laptop and the fun of running a business at tax return time.
Craig Sanders: Dead Can Dance

I saw Dead Can Dance at the Palais in St Kilda last night their first tour back in Australia in over 20 years. I ve wanted to see them perform live since I first discovered their music in the dim dark past bought the tickets as soon as the tour was announced last year and have been waiting impatiently ever since. The first act was percussionist David Kuckhermann who played solo and then joined DCD for the main act. He mostly played the handpan, which looks a lot like an upside-down wok with dimples on it. His tambourine solo was oustanding. Overall, a great start to the evening. I hadn t heard of him before, but I think I ll be ordering some of his CDs. Lisa Gerrard s voice was, as always, trance-inducingly sublime and Brendan Perry with a fine voice of his own really shines in a live performance. Definitely not a disappointment around three hours of amazing performance, old favourites and new, and the discovery (for me) of a new performer. If I have one (minor) complaint, it s that the volume was a little too loud, causing occasional distortion and difficulty distinguishing the lyrics on some of Brendan Perry s singing. Lisa Gerrard sings without words glossolalia and much higher than Perry so wasn t affected as much. If you haven t heard DCD or Lisa Gerrard s solo albums before, do so you re in for a treat labelled as world fusion , they re impossible to describe accurately while they started out as Dark Wave or as-goth-as-it-gets in the early 80s, they play across many genres and have strong influences from Middle Eastern, Mediaeval, world music, ambient, and more, they re in a genre of their own. You can t even say they re a bit like so-and-so because they aren t. Dead Can Dance is a post from: Errata

6 February 2013

Biella Coleman: Edward Tufte was a phreak

It has been so very long since I have left a trace here. I guess moving to two new countries (Canada and Quebec), starting a new job, working on Anonymous, and finishing my first book was a bit much. I miss this space, not so much because what I write here is any good. But it a handy way for me to keep track of time and what I do and even think. My life feels like a blur at times and hopefully here I can see its rhythms and changes a little more clearly if I occasionally jot things down here. So I thought it would nice to start with something that I found surprising: famed information designer, Edward Tufte, a professor emeritus at Yale was a phone phreak (and there is a stellar new book on the topic by former phreak Phil Lapsley. He spoke about his technological exploration during a sad event, a memorial service in NYC which I attended for the hacker and activist Aaron Swartz. I had my wonderful RA transcribe the speech, so here it is [we may not have the right spelling for some of the individuals so please let us know of any mistakes]:
Edward Tufte s Speech From Aaron Swartz s Memorial
Speech starts 41:00 [video cuts out in beginning]
We would then meet over the years for a long talk every now and then, and my responsibility was to provide him with a reading list, a reading list for life and then about two years ago Quinn had Aaron come to Connecticut and he told me about the four and a half million downloads of scholarly articles and my first question is, Why isn t MIT celebrating this? .
[Video cuts out again]
Obviously helpful in my career there, he then became president of the Mellon foundation, he then retired from the Mellon foundation, but he was asked by the Mellon foundation to handle the problem of JSTOR and Aaron. So I wrote Bill Bullen(sp?) an email about it, I said first that Aaron was a treasure and then I told a personal story about how I had done some illegal hacking and been caught at it and what happened. In 1962, my housemate and I invented the first blue box, that s a device that allows for free, undetectable, unbillable long distance telephone calls. And we got this up and played around with it and the end of our research came when we concluded what was the longest long distance call ever made, which was from Palo Alto to New York time-of-day via Hawaii, well during our experimentation, AT&T, on the second day it turned out, had tapped our phone and uh but it wasn t until about 6 months later when I got a call from the gentleman, AJ Dodge, senior security person at AT&T and I said, I know what you re calling about. and so we met and he said You what you are doing is a crime that would , you know all that. But I knew it wasn t serious because he actually cared about the kind of engineering stuff and complained that the tone signals we were generating were not the standard because they record them and play them back in the network to see what numbers they we were that you were trying to reach, but they couldn t break though the noise of our signal. The upshot of it was that uh oh and he asked why we went off the air after about 3 months, because this was to make long distance telephone calls for free and I said this was because we regarded it as an engineering problem and we made the longest long distance call and so that was it. So the deal was, as I explained in my email to Bill Bullen, that we wouldn t try to sell this and we were told, I was told that crime significance would pay a great deal for this, we wouldn t do any more of it and that we would turn our equipment over to AT&T, and so they got a complete vacuum tube isolator kit for making long distance phone calls. But I was grateful for AJ Dodge and I must say, AT&T that they decided not to wreck my life. And so I told Bill Bullen that he had a great opportunity here, to not wreck somebody s life, course he thankfully did the right thing.
Aaron s unique quality was that he was marvelously and vigorously different. There is a scarcity of that. Perhaps we can be all a little more different too.
Thank you very much.

Vincent Sanders: Two years of 3D printing

Almost two years ago my good friend Phil Hands invited me to attend a workshop at bath university to build a 3D printer. I had previously looked at the Reprap project and considered building the Darwin model, alas lack of time and funds had prevented me form proceeding.

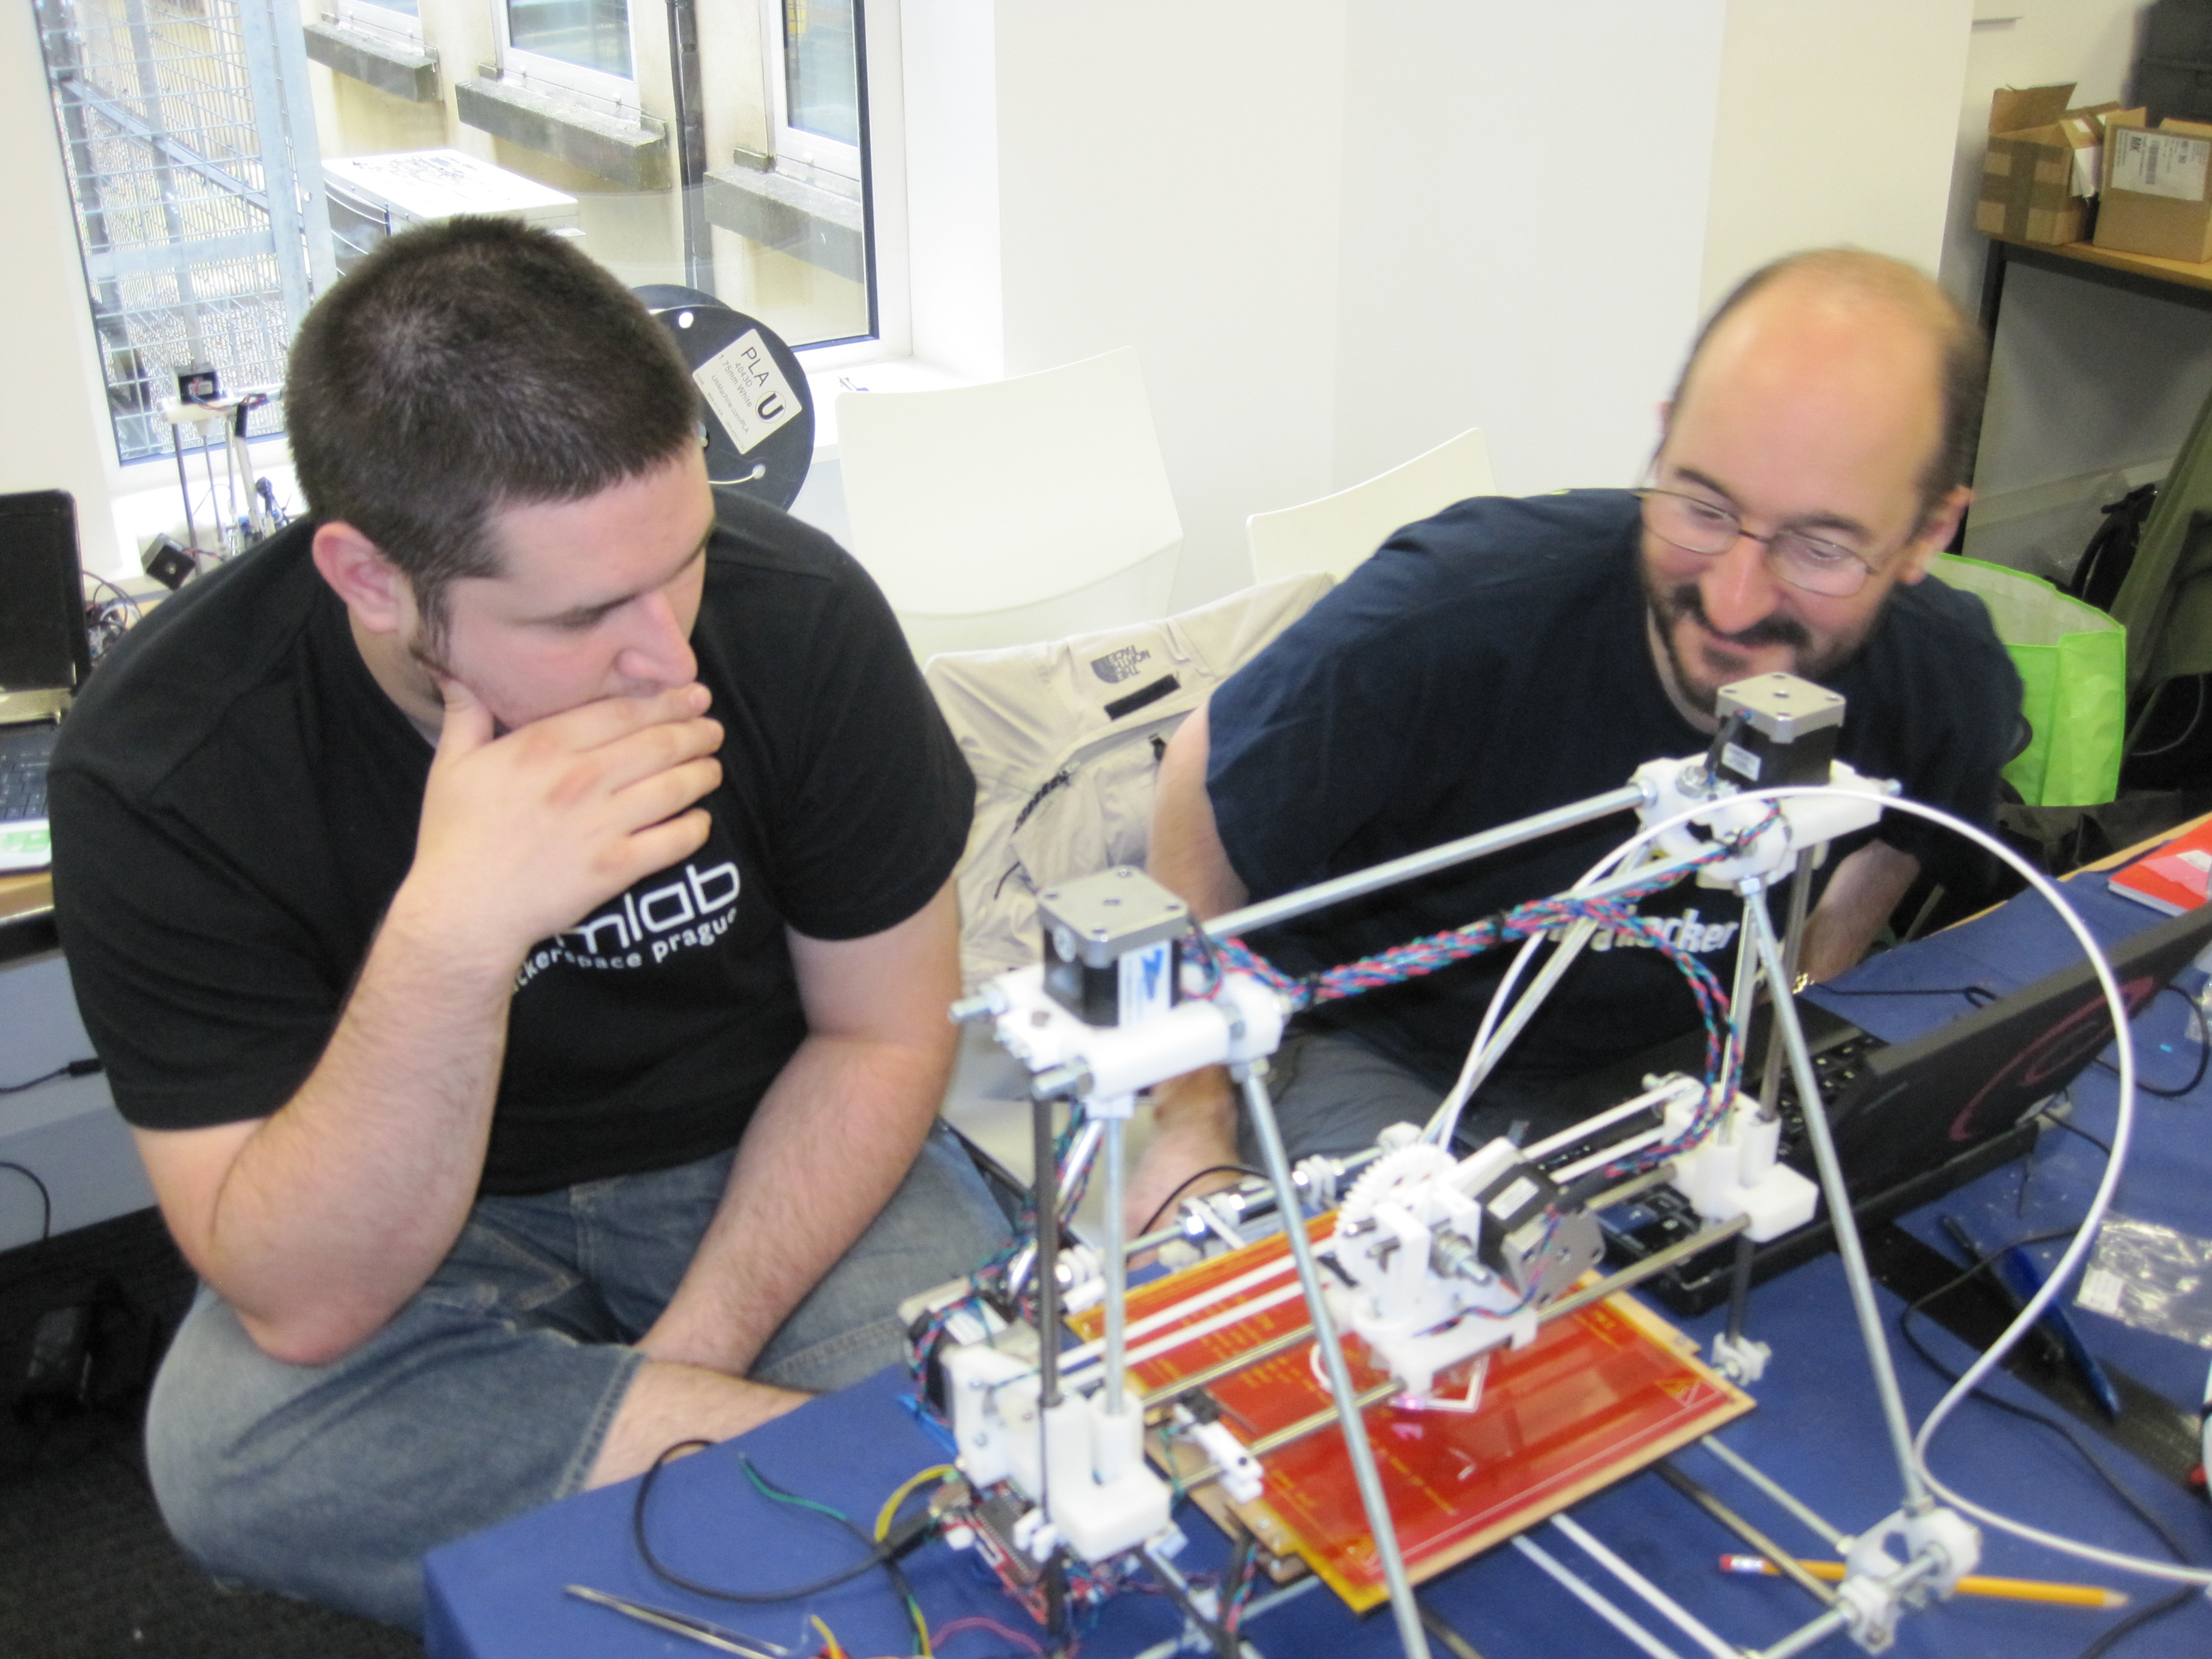
Jo Prusa and Phil Hands watching a heart print.
The workshop was to build a new, much simpler, design called the Prusa. Of course the workshop was booked and paid for well in advance which left me looking forwards to the event with anticipation. Of course I would not betaking the results of the workshop home as Phil had paid for it, so I started investigating what I would need for my own machine.

Of course at this point I muttered the age old phrase of "how hard can it be" and started acquiring parts for my own printer. By the time the workshop happened I already had my machine working as a plotter. I learned a lot from the Bath masterclass and a few days afterwards my own machine was complete.

First print
The results were underwhelming to say the least. There then came months and months of trial and error to fix various issues:
  • The filament feed bolt had to be replaced with a better one with sharper teeth.
  • The thermistor which reads the extruder temperature needed replacing (it still reads completely the wrong temperature even now).
  • The Y axis was completely inverted and needed re-wiring and the limit switches moving.
  • Endlessly replacing the printer firmware with new versions because every setting change requires a complete recompile and re-flash.
  • The bushings on the Y axis were simply not up to the job and the entire assembly needed replacing with ball bearings and a heated bed otherwise prints would be completely warped.
  • The Z axis couplings kept failing until I printed some alternates that worked much better
Once these issues had been fixed I started getting acceptable levels of output though the software in the workflow used to produce toolpaths (skeinforge) was exceptionally difficult to use and prone to producing poor results.

Alas the fundamental design issues of the Prusa remain. The A frame design provides exceptional rigidity in one plane...the other two? not so much. This coupled with an exceptionally challenging calibration to get the frame parallel and square means the printer is almost never true.

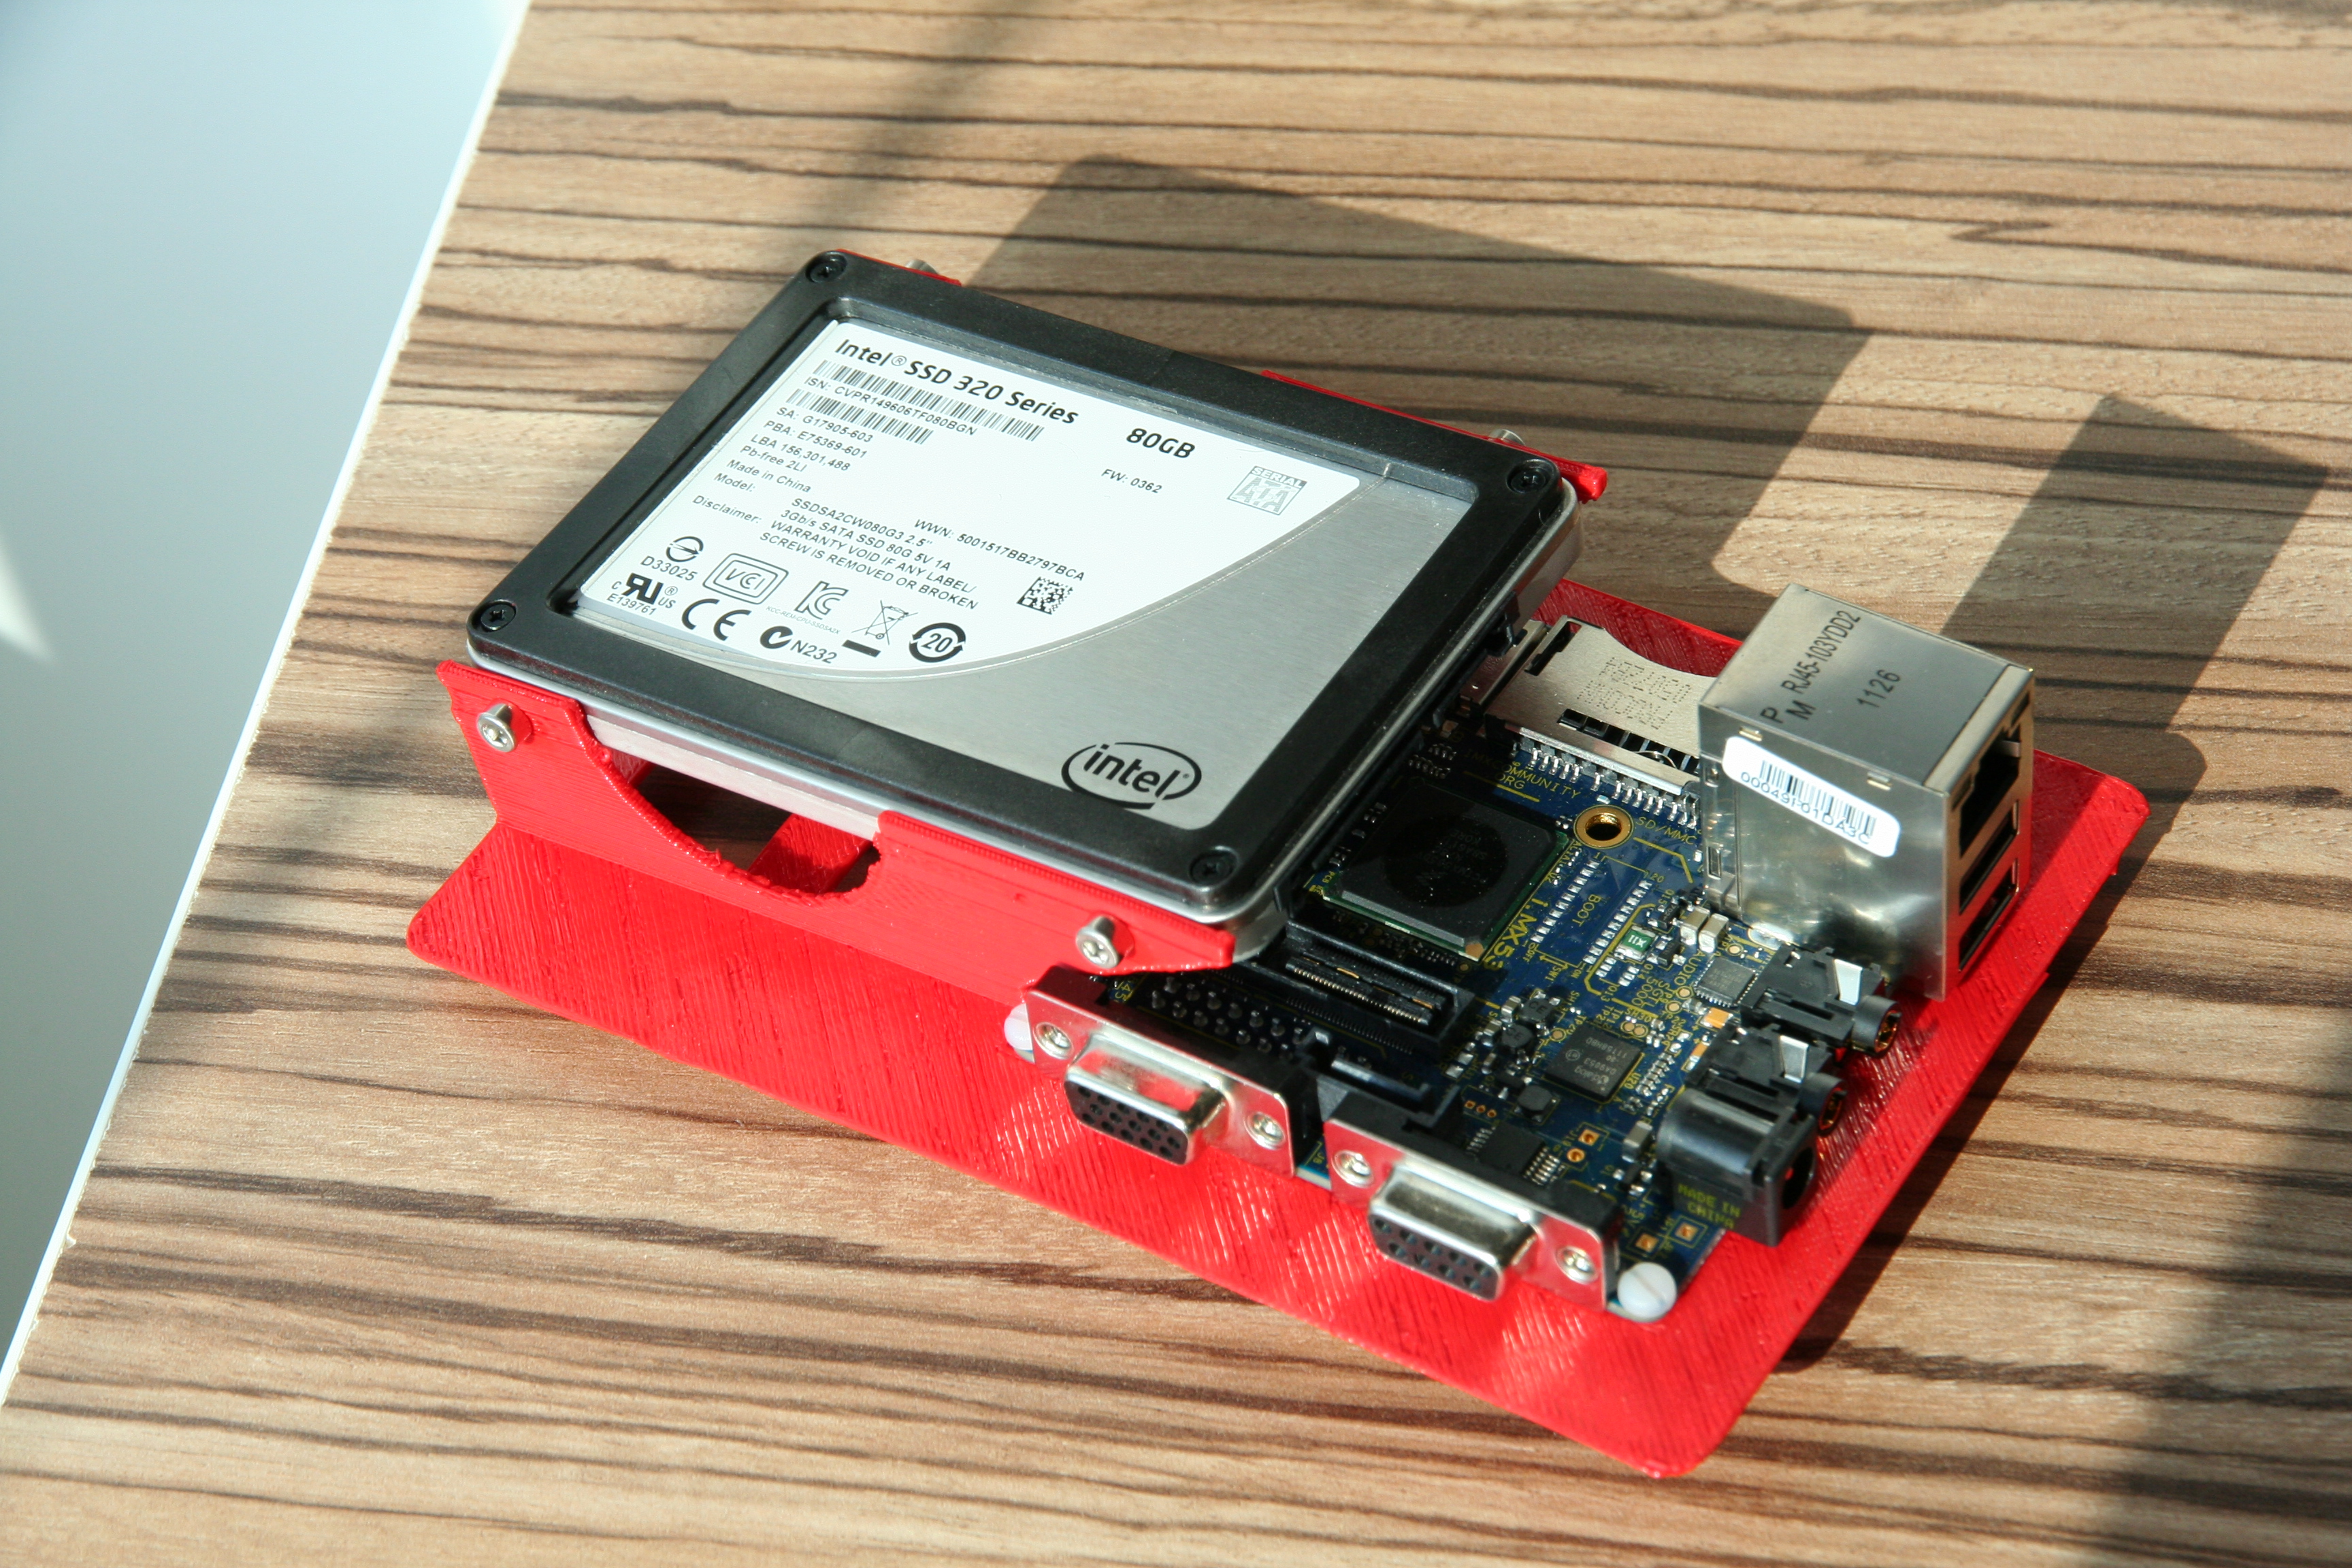
Prototype iMX53 dev board eurocard carrier printed on my printer
In operation the lack of rigidity in the x axis means the whole frame vibrates badly even with extra struts to try and improve its rigidity. I am not the first to notice these design flaws and indeed Chris has done something about it by creating a much superior design.

I do however have a working printer and have developed a workflow and understanding of what I can expect to work.

Improvements in the software means that slic3r has replaced skeinforge and gives superior results and the CAD software is continuously improving.

Currently I mainly use the printer to generate prototypes and simple profiles and then send the resulting designs to shapeways for final production though simpler designs are usable directly from the machine.

Because I am away from home a lot and moving the machine is simply not a workable option the printer does not get used for "fun" anywhere near as much as I had hoped and the workflow limitations mean I have not been able to make it available to my friends to use as a communal device.


Thomas Goirand: Openstack Folsom fully uploaded to Experimental

It s been a long time I wanted to blog about my recent work on the Openstack packaging. I finally can find a bit of time to do it. For those who don t know yet Openstack, it s a fairly recent (less than 3 years) cloud computing suite, which is becoming quite huge. If you plan on deploying a private cloud, you should definitively have a look into it. When the Openstack project started, I immediately was interested. I started packaging the Cactus release (that is, the 3rd version of Openstack), created the Alioth group (at the exact moment when Alioth was migrated to new hardware which added some fun so lucky I was!), and began to work on the Debian version (Openstack used to be an Ubuntu only project). After some success in integrating some Debian specific patches into the Ubuntu packages, I left it a bit aside, and skipped completely the Diablo release (which was never uploaded in Debian). Then, I worked a bit on the Essex release before the freeze of Wheezy last June, together with other DDs (big up to Julien, Loic, Ghe, Sileth!). I (re-)started serious packaging work for Openstack just right after Folsom (eg: version 2012.2) was released early last October. I literally worked days and nights on it, in order to provide more automation so that it could become more easy to install. Indeed, it used to be very complicated and painful, with lots of manual tasks to perform on the shell. It s hopefully a lot easier now, with most of the manual boring shell work replaced by debconf and scripts. But I m sure there s more that can be done still. After 4 months of effort, I finally pressed the red button and uploaded everything at once to Debian Experimental since Openstack Essex (version 2012.1) is in Wheezy, I can t of course upload to SID unless Wheezy is out -. This represent 32 sources packages in total (some of them are already uploaded and approved by the FTP masters: sorry to give you so much more work guys ), and 104 binary packages (and counting ). So this isn t exactly small And I already have some fixes for what s currently waiting in the NEW queue: CVE fixes, missing build-depends which we ve found using the Jenkins server of eNovance who sponsors the packaging work, etc. I probably will post again here to announce when Folsom is completely approved by the FTP masters and reaches Debian experimental. In the mean while, it s available on GPLHost non-official repositories (see the howto linked bellow). If you would like to test the latest Openstack release (called Folsom, or 2012.2, if you are following well ), you can read the quite verbose howto I wrote here: https://wiki.debian.org/OpenStackHowto/Folsom If you do test it (don t be afraid, it s not that hard ), I will be very happy to hear from you, and receive any feedback / critics you may have. Note that I would strongly recommend to use the Folsom release, rather than what is currently in Wheezy, for many reasons which would be too long to list in this blog post (let me still drop a few reasons here: less bugs, more automations and it s more easy to install). Now, Openstack is a constantly evolving software, with so many companies and developers involved. I don t think my work on this beast will ever be finished. But it doesn t mater, as it s been quite some fun, and I will enjoy to do more. The next release of Openstack is schedule for next April (they release at the same time as Ubuntu). I hope to be able to join the Portland summit, and see all the persons I have worked with over IRC and mailing list. This time, I hope to be able to release Openstack packages at the same time as the upstream source code is released (Debian packages have historically been lagging a few months behind). The pre-version is by the way already in Alioth. Last, a (private) message for our famous cheese-master: please wait until everything leaves the NEW queue before bugging everyone with translations. We probably should have a serious talk about how to make it less redundant, easier to translate, and probably find a way to avoid duplication of messages across all packages.

Joachim Breitner: Evaluation-State Assertions in Haskell

I have just uploaded a new version of ghc-heap-view to Hackage that provides Evaluation state assertions in the module GHC.AssertNF. Imagine you are writing a web application in Haskell that sports a global number-of-visitors counter in an IORef Int. For every request, you call modifyIORef (+1). Eventually, you notice your very popular web site to hog more and more memory. So you browse to the internal page that shows the counter, and you have to wait for a long time until you eventually see the result (or get a stack overflow). The reason: The applications of (+1) were not performed until you looked at the number; instead, a long chain of such computation first filled your heap and then your stack. So you have learned the hard way that you might want to avoid space leaks, and want calculations to be done during the request that caused them, and want the IORef to always contain fully evaluated data. So you stumble about modifyIORef' in Data.IORef and indeed, this fixes your problem. Later, you notice that you want to count POST and GET requests separately. You change the type to IORef (Int, Int) and call modifyIORef' (first (+1)) or modifyIORef' (second (+1)). And suddenly, the space leak is back (which you only notice after the next push to the real site, because your local tests never caused enough requests to make it noticeable). So you not only want to fix it, you also want to ensure that it does not break again. In other words, you want to ensure the policy that values stored in an IORef are always in normal form. You achieve this with the following alternative to modifyIORef':
modifyIORef'Assert :: IORef a -> (a -> a) -> IO ()
modifyIORef'Assert ref f = do
    x <- readIORef ref
    let x' = f x
    x'  seq  return ()
    assertNF x'
    writeIORef ref x'
Using this instead of modifyIORef' will print this warning to standard error output right the first time you call modifyIORef'Assert (first (+1)):
Parameter not in normal form: 2 thunks found:
let x1 = (S# 1,S# 1)
in _bh (_thunk x1 (_bco (S# 1)),_sel x1)
(Otherwise, the program runs as usual.) So obviously, you need to use a strict variant of first (or strict pairs):
first' :: (a -> b) -> (a, c) -> (b, c)
first' f (x,y) = let   x' = f x; r = (x', y)   in x'  seq  r  seq  r
With this, the warning goes away. Whenever you now change the type of the IORef or modify it in a too-lazy-way, you can be sure that you ll be warned about it, before the space leak itself becomes noticeable. In the production code, you might want to disable the check. For that, simply put disableAssertNF somewhere in your main function. Why is this better than just calling deepseq in modifyIORef'Assert? Because this way, the code still creates unwanted thunks that are then evaluated before storing them in the IORef, whereas with assertNF you are told about the thunks and can prevent them from being created in the first place. Also, assertNF does not add a type class constraint. This is just one example application for assertNF (and its variants assertNFNamed, which includes a name in the warning to better spot the cause, and $assertNFHere, which uses Template Haskell to include the current source code position in the warning), and I hope that there are more. If you happen to make use of it, I d like to hear your story.

Lior Kaplan: RTL status for Libre Office 4.0.0

LibreOffice 4.0.0 will be released soon, and it s a good time to summarize its RTL status. Similar to 3.5.0, the RTL work started with LibreOffice conference in October, showing the current state (see LibreOffice RTL status 2012 presentation) and listing the top problems. The main goal of this talk is to raise awareness to RTL issues and recruit developer to help fix them. This was exactly what happened with fdo#44657 which is about Calc not having a scroll bar in RTL user interface. This way RTL bug #1 for almost a year. In total, version 4.0.0 has 8 bugs fixed (mainly Calc, Presenter Console and toolbars). In addition it has 5 language specific bugs fixed. Full lists are at https://wiki.documentfoundation.org/RTL_Bugs#4.0.0 and https://wiki.documentfoundation.org/RTL_Bugs#4.0.0_2. Beside working on fixing bugs for the 4.0.0, another focus was put on making sure the fixes are available for the 3.6.x users. This resulted with cherry picking 11 out of 13 bug fixes (part of 3.6.4 and 3.6.5 releases). More fixes are already underway in the master branch, and will also be part of 4.0.1 maintenance release (full list at https://wiki.documentfoundation.org/RTL_Bugs#4.0.1). Beside thanking the core developers for their help (patches, code review), I d like to thank the guys from The National Program for Free and Open Source Software Technologies (Motah) at King Abdulaziz City for Science and Technology (KACST) in Saudi Arabia, which have joined the RTL team during this release, and their effect is well noticed. Despite all the work done, we still have a share of RTL bugs for the next release, these are the 7 top priority RTL bugs, any help would be appreciated.
  1. fdo#33302 Brackets inverted in rtl text (mac only)
  2. fdo#53030 Calc deletes current sheet, not right-clicked on sheet when trying to delete opposite directionality sheets
  3. fdo#56403 RTL UI: with RTL locales presentations appear with text align to the right instead of to the left
  4. fdo#37128 Writer saves text alignment of RTL paragraph not according to the ODF specification
  5. fdo#44029 docx files with RTL paragraphs aren t compatible with Word
  6. fdo#43093 FILEOPEN: [docx] MS Office documents opens with wrong alignment and directionality
  7. fdo#56408 Brackets are not handled correctly with mixed English/Latin and Hebrew/Arabic texts

Filed under: i18n & l10n, LibreOffice

5 February 2013

Russ Allbery: WebAuth 4.4.2

When I was testing C code coverage analysis tools using WebAuth, I really should have investigated the segfault that I started getting in the test suite before releasing 4.4.1. But since valgrind didn't report any problems, I thought it was something specific to code coverage. Nope, uninitialized variable inside the WebKDC code. Which valgrind didn't catch at all for some reason. Now fixed, and I did check for similar issues, but it's sort of disturbing that valgrind completely missed it, particularly for a variable whose address is taken and therefore which I wouldn't think would be optimized away. Since I hate to release WebAuth to only fix one thing, I also tested out-of-tree builds for the first time in a while and fixed a pile of issues around how the Perl module builds work. There's got to be a better way. Maybe sometime I'll try to come up with some patches to teach Module::Build how to handle VPATH. I also imported some additional Autoconf glue that will hopefully help Hurd builds proceed farther, although I didn't promise anything in NEWS since WebAuth has not yet successfully built on Hurd. You can get the latest release from the official WebAuth distribution site or from my WebAuth distribution pages.

DebConf team: DebConf13 venue and dates (Posted by Moray Allan, Didier Raboud and the DebConf team)

This post is a quick status update on DebConf13, for those who aren t following the debconf-team mailing list. As you may know, this year s DebConf will be held at Le Camp, in Vaumarcus, Switzerland. Our concept for this DebConf is to hold it in a natural environment, away from distractions. We hope you will enjoy spending time together with other Debian collaborators in this beautiful part of Switzerland, on the shore of Lake Neuch tel. Dates DebConf13 will take place from Sunday 11. August 2013 to Sunday 18. August 2013. (We will use Saturday 10. August 2013 to prepare the venue for the conference.) You may notice that the dates don t cover two weeks like in the last few years (there is no separate DebCamp week). For budget reasons, current plans are to merge the two weeks activities into an 8 day period. If you think that s a pity, it s not too late to change it just join the fundraising team and start working quickly! Travel If you want to start arranging your travel to attend DebConf, some initial travel suggestions may be useful: The DebConf13 map shows the venue and the bus line (with some stops). Registration We expect to open registration around the start of March. Currently we are still evaluating some possible new conference management systems, which we hope might avoid the frustrations some attendees have had in the past with Pentabarf. Help welcome As always, the DebConf team is looking for volunteers. Some jobs need technical skills (e.g. testing conference management system setups, working on the website), but many DebConf tasks are about working to deadlines on non-technical issues (e.g. fundraising, budgeting, talk scheduling). You can see more information about some of the jobs to be done on the DebConf wiki. Please do think about getting involved and sharing your ideas with us, to help us make DebConf an even more useful event for Debian in the future. We look forward to welcoming you to Vaumarcus!

Next.

Previous.