Search Results: "zed"

30 September 2021

Holger Levsen: 20210930-Debian-Reunion-Hamburg-2021

Debian Reunion Hamburg 2021 is almost over... The Debian Reunion Hamburg 2021 is almost over now, half the attendees have already left for Regensburg, while five remaining people are still busy here, though tonight there will be two concerts at the venue, plus some lovely food and more. Together with the day trip tomorrow (involving lots of water but hopefully not from above...) I don't expect much more work to be done, so that I feel comfortable publishing the following statistics now, even though I expect some more work will be done while travelling back or due to renewed energy from the event! So I might update these numbers later :-) Together we did: I think that's a pretty awesome and am very happy we did this event! Debian Reunion / MiniDebConf Hamburg 2022 - save the date, almost! Thus I think we should have another Debian event at Fux in 2022, and after checking suitable free dates with the venue I think what could work out is an event from Monday May 23rd until Sunday May 29th 2022. What do you think? For now these dates are preliminary. If you know any reasons why these dates could be less than optimal for such an event, please let me know. Assuming there's no feedback indicating this is a bad idea, the dates shall be finalized by November 1st 2021. Obviously assuming having physical events is still and again a thing! ;-)

29 September 2021

Ingo Juergensmann: LetsEncrypt CA Chain Issues with Ejabberd

UPDATE:
It s not as simple as described below, I m afraid It appears that it s not that easy to obtain new/correct certs from LetsEncrypt that are not cross-signed by DST Root X3 CA. Additionally older OpenSSL version (1.0.x) seems to have problems. So even when you think that your system is now ok, the remote server might refuse to accept your SSL cert. The same is valid for the SSL check on xmpp.net, which seems to be very outdated and beyond repair. Honestly, I think the solution needs to be provided by LetsEncrypt
I was having some strange issues on my ejabberd XMPP server the other day: some users complained that they couldn t connect anymore to the MUC rooms on my server and in the logfiles I discovered some weird warnings about LetsEncrypt certificates being expired although they were just new and valid until end of December. It looks like this:
[warning] <0.368.0>@ejabberd_pkix:log_warnings/1:393 Invalid certificate in /etc/letsencrypt.sh/certs/buildd.net/fullchain.pem: at line 37: certificate is no longer valid as its expiration date has passed
and
[warning] <0.18328.2>@ejabberd_s2s_out:process_closed/2:157 Failed to establish outbound s2s connection nerdica.net -> forum.friendi.ca: Stream closed by peer: Your server's certificate is invalid, expired, or not trusted by forum.friendi.ca (not-authorized); bouncing for 237 seconds
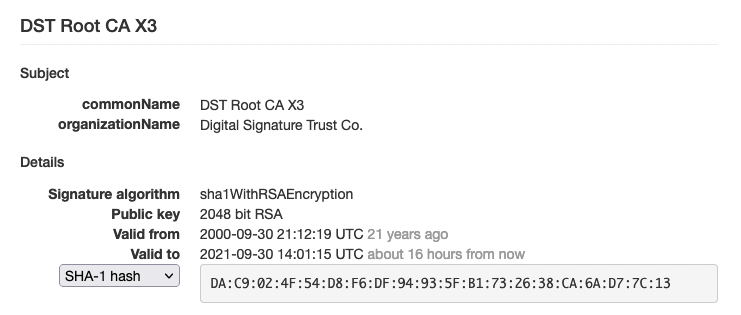
When checking out with some online tools like SSLlabs or XMPP.net the result was strange, because SSLlabs reported everything was ok while XMPP.net was showing the chain with X3 and D3 certs as having a short term validity of a few days:
After some days of fiddling around with the issue, trying to find a solution, it appears that there is a problem in Ejabberd when there are some old SSL certifcates being found by Ejabberd that are using the old CA chain. Ejabberd has a really nice feature where you can just configure a SSL cert directory (or a path containing wildcars. Ejabberd then reads all of the SSL certs and compare them to the list of configured domains to see which it will need and which not. What helped (for me at least) was to delete all expired SSL certs from my directory, downloading the current CA file pems from LetsEncrypt (see their blog post from September 2020), run update-ca-certificates and ejabberdctl restart (instead of just ejabberdctl reload-config). UPDATE: be sure to use dpkg-reconfigure ca-certificates to uncheck the DST Root X3 cert (and others if necessary) before renewing the certs or running update-ca-certificates. Otherwise the update will bring in the expired cert again. Currently I see at least two other XMPP domains in my server logs having certicate issues and in some MUCs there are reports of other domains as well. Disclaimer: Again: this helped me in my case. I don t know if this is a bug in Ejabberd or if this procedure will help you in your case nor if this is the proper solution. But maybe my story will help you solving your issue if you experience SSL certs issues in the last few days, especially now that the R3 cert has already expired and the X3 cert following in a few hours.

27 September 2021

Russ Allbery: Review: The Problem with Work

Review: The Problem with Work, by Kathi Weeks
Publisher: Duke University Press
Copyright: 2011
ISBN: 0-8223-5112-9
Format: Kindle
Pages: 304
One of the assumptions baked deeply into US society (and many others) is that people are largely defined by the work they do, and that work is the primary focus of life. Even in Marxist analysis, which is otherwise critical of how work is economically organized, work itself reigns supreme. This has been part of the feminist critique of both capitalism and Marxism, namely that both devalue domestic labor that has traditionally been unpaid, but even that criticism is normally framed as expanding the definition of work to include more of human activity. A few exceptions aside, we shy away from fundamentally rethinking the centrality of work to human experience. The Problem with Work begins as a critical analysis of that centrality of work and a history of some less-well-known movements against it. But, more valuably for me, it becomes a discussion of the types and merits of utopian thinking, including why convincing other people is not the only purpose for making a political demand. The largest problem with this book will be obvious early on: the writing style ranges from unnecessarily complex to nearly unreadable. Here's an excerpt from the first chapter:
The lack of interest in representing the daily grind of work routines in various forms of popular culture is perhaps understandable, as is the tendency among cultural critics to focus on the animation and meaningfulness of commodities rather than the eclipse of laboring activity that Marx identifies as the source of their fetishization (Marx 1976, 164-65). The preference for a level of abstraction that tends not to register either the qualitative dimensions or the hierarchical relations of work can also account for its relative neglect in the field of mainstream economics. But the lack of attention to the lived experiences and political textures of work within political theory would seem to be another matter. Indeed, political theorists tend to be more interested in our lives as citizens and noncitizens, legal subjects and bearers of rights, consumers and spectators, religious devotees and family members, than in our daily lives as workers.
This is only a quarter of a paragraph, and the entire book is written like this. I don't mind the occasional use of longer words for their precise meanings ("qualitative," "hierarchical") and can tolerate the academic habit of inserting mostly unnecessary citations. I have less patience with the meandering and complex sentences, excessive hedge words ("perhaps," "seem to be," "tend to be"), unnecessarily indirect phrasing ("can also account for" instead of "explains"), or obscure terms that are unnecessary to the sentence (what is "animation of commodities"?). And please have mercy and throw a reader some paragraph breaks. The writing style means substantial unnecessary effort for the reader, which is why it took me six months to read this book. It stalled all of my non-work non-fiction reading and I'm not sure it was worth the effort. That's unfortunate, because there were several important ideas in here that were new to me. The first was the overview of the "wages for housework" movement, which I had not previously heard of. It started from the common feminist position that traditional "women's work" is undervalued and advocated taking the next logical step of giving it equality with paid work by making it paid work. This was not successful, obviously, although the increasing prevalence of day care and cleaning services has made it partly true within certain economic classes in an odd and more capitalist way. While I, like Weeks, am dubious this was the right remedy, the observation that household work is essential to support capitalist activity but is unmeasured by GDP and often uncompensated both economically and socially has only become more accurate since the 1970s. Weeks argues that the usefulness of this movement should not be judged by its lack of success in achieving its demands, which leads to the second interesting point: the role of utopian demands in reframing and expanding a discussion. I normally judge a political demand on its effectiveness at convincing others to grant that demand, by which standard many activist campaigns (such as wages for housework) are unsuccessful. Weeks points out that making a utopian demand changes the way the person making the demand perceives the world, and this can have value even if the demand will never be granted. For example, to demand wages for housework requires rethinking how work is defined, what activities are compensated by the economic system, how such wages would be paid, and the implications for domestic social structures, among other things. That, in turn, helps in questioning assumptions and understanding more about how existing society sustains itself. Similarly, even if a utopian demand is never granted by society at large, forcing it to be rebutted can produce the same movement in thinking in others. In order to rebut a demand, one has to take it seriously and mount a defense of the premises that would allow one to rebut it. That can open a path to discussing and questioning those premises, which can have long-term persuasive power apart from the specific utopian demand. It's a similar concept as the Overton Window, but with more nuance: the idea isn't solely to move the perceived range of accepted discussion, but to force society to examine its assumptions and premises well enough to defend them, or possibly discover they're harder to defend than one might have thought. Weeks applies this principle to universal basic income, as a utopian demand that questions the premise that work should be central to personal identity. I kept thinking of the Black Lives Matter movement and the demand to abolish the police, which (at least in popular discussion) is a more recent example than this book but follows many of the same principles. The demand itself is unlikely to be met, but to rebut it requires defending the existence and nature of the police. That in turn leads to questions about the effectiveness of policing, such as clearance rates (which are far lower than one might have assumed). Many more examples came to mind. I've had that experience of discovering problems with my assumptions I'd never considered when debating others, but had not previously linked it with the merits of making demands that may be politically infeasible. The book closes with an interesting discussion of the types of utopias, starting from the closed utopia in the style of Thomas More in which the author sets up an ideal society. Weeks points out that this sort of utopia tends to collapse with the first impossibility or inconsistency the reader notices. The next step is utopias that acknowledge their own limitations and problems, which are more engaging (she cites Le Guin's The Dispossessed). More conditional than that is the utopian manifesto, which only addresses part of society. The least comprehensive and the most open is the utopian demand, such as wages for housework or universal basic income, which asks for a specific piece of utopia while intentionally leaving unspecified the rest of the society that could achieve it. The demand leaves room to maneuver; one can discuss possible improvements to society that would approach that utopian goal without committing to a single approach. I wish this book were better-written and easier to read, since as it stands I can't recommend it. There were large sections that I read but didn't have the mental energy to fully decipher or retain, such as the extended discussion of Ernst Bloch and Friedrich Nietzsche in the context of utopias. But that way of thinking about utopian demands and their merits for both the people making them and for those rebutting them, even if they're not politically feasible, will stick with me. Rating: 5 out of 10

22 September 2021

Gunnar Wolf: New book out! Mecanismos de privacidad y anonimato en redes, una visi n transdisciplinaria

Three years ago, I organized a fun and most interesting colloquium at Facultad de Ingenier a, UNAM about privacy and anonymity online. I would have loved to share this earlier with the world, but The university s processes are quite slow (and, to be fair, I also took quite a bit of time to push things through). But today, I m finally happy to share the result of that work with all of you. We managed to get 11 of the talks in the colloquium as articles. The back-cover text reads (in Spanish):
We live in an era where human to human interactions are more and more often mediated by technology. This, of course, means everything leaves a digital trail, a trail that can follow and us relentlessly. Privacy is recognized, however, as a human right although one that is under growing threats. Anonymity is the best tool to secure it. Throughout history, clear steps have been taken legally, technically and technologically to defend it. Various studies point out this is not only a known issue for the network's users, but that a large majority has searched for alternatives to protect their communications' privacy. This book stems from a colloquium held by *Laboratorio de Investigaci n y Desarrollo de Software Libre* (LIDSOL) of Facultad de Ingenier a, UNAM, towards the end of 2018, where we invited experts from disciplines so far apart as law and systems development, psychology and economics, to contribute with their experiences to a transdisciplinary vision.
If this interests you, you can get the book at our institutional repository. Oh, and What about the birds? In Spanish (Mexican only?), we have a saying, hay p jaros en el alambre , meaning watch your words, as uninvited people might be listening, as birds resting over the wires over which phone calls used to be made (back in the day where wiretapping was that easy). I found the design proposed by our editor ingenious and very fitting for our topic!

Ian Jackson: Tricky compatibility issue - Rust's io::ErrorKind

This post is about some changes recently made to Rust's ErrorKind, which aims to categorise OS errors in a portable way. Audiences for this post Background and context Error handling principles Handling different errors differently is often important (although, sadly, often neglected). For example, if a program tries to read its default configuration file, and gets a "file not found" error, it can proceed with its default configuration, knowing that the user hasn't provided a specific config. If it gets some other error, it should probably complain and quit, printing the message from the error (and the filename). Otherwise, if the network fileserver is down (say), the program might erroneously run with the default configuration and do something entirely wrong. Rust's portability aims The Rust programming language tries to make it straightforward to write portable code. Portable error handling is always a bit tricky. One of Rust's facilities in this area is std::io::ErrorKind which is an enum which tries to categorise (and, sometimes, enumerate) OS errors. The idea is that a program can check the error kind, and handle the error accordingly. That these ErrorKinds are part of the Rust standard library means that to get this right, you don't need to delve down and get the actual underlying operating system error number, and write separate code for each platform you want to support. You can check whether the error is ErrorKind::NotFound (or whatever). Because ErrorKind is so important in many Rust APIs, some code which isn't really doing an OS call can still have to provide an ErrorKind. For this purpose, Rust provides a special category ErrorKind::Other, which doesn't correspond to any particular OS error. Rust's stability aims and approach Another thing Rust tries to do is keep existing code working. More specifically, Rust tries to:
  1. Avoid making changes which would contradict the previously-published documentation of Rust's language and features.
  2. Tell you if you accidentally rely on properties which are not part of the published documentation.
By and large, this has been very successful. It means that if you write code now, and it compiles and runs cleanly, it is quite likely that it will continue work properly in the future, even as the language and ecosystem evolves. This blog post is about a case where Rust failed to do (2), above, and, sadly, it turned out that several people had accidentally relied on something the Rust project definitely intended to change. Furthermore, it was something which needed to change. And the new (corrected) way of using the API is not so obvious. Rust enums, as relevant to io::ErrorKind (Very briefly:) When you have a value which is an io::ErrorKind, you can compare it with specific values:
    if error.kind() == ErrorKind::NotFound   ...
  
But in Rust it's more usual to write something like this (which you can read like a switch statement):
    match error.kind()  
      ErrorKind::NotFound => use_default_configuration(),
      _ => panic!("could not read config file  :  ", &file, &error),
     
  
Here _ means "anything else". Rust insists that match statements are exhaustive, meaning that each one covers all the possibilities. So if you left out the line with the _, it wouldn't compile. Rust enums can also be marked non_exhaustive, which is a declaration by the API designer that they plan to add more kinds. This has been done for ErrorKind, so the _ is mandatory, even if you write out all the possibilities that exist right now: this ensures that if new ErrorKinds appear, they won't stop your code compiling. Improving the error categorisation The set of error categories stabilised in Rust 1.0 was too small. It missed many important kinds of error. This makes writing error-handling code awkward. In any case, we expect to add new error categories occasionally. I set about trying to improve this by proposing new ErrorKinds. This obviously needed considerable community review, which is why it took about 9 months. The trouble with Other and tests Rust has to assign an ErrorKind to every OS error, even ones it doesn't really know about. Until recently, it mapped all errors it didn't understand to ErrorKind::Other - reusing the category for "not an OS error at all". Serious people who write serious code like to have serious tests. In particular, testing error conditions is really important. For example, you might want to test your program's handling of disk full, to make sure it didn't crash, or corrupt files. You would set up some contraption that would simulate a full disk. And then, in your tests, you might check that the error was correct. But until very recently (still now, in Stable Rust), there was no ErrorKind::StorageFull. You would get ErrorKind::Other. If you were diligent you would dig out the OS error code (and check for ENOSPC on Unix, corresponding Windows errors, etc.). But that's tiresome. The more obvious thing to do is to check that the kind is Other. Obvious but wrong. ErrorKind is non_exhaustive, implying that more error kinds will appears, and, naturally, these would more finely categorise previously-Other OS errors. Unfortunately, the documentation note
Errors that are Other now may move to a different or a new ErrorKind variant in the future.
was only added in May 2020. So the wrongness of the "obvious" approach was, itself, not very obvious. And even with that docs note, there was no compiler warning or anything. The unfortunate result is that there is a body of code out there in the world which might break any time an error that was previously Other becomes properly categorised. Furthermore, there was nothing stopping new people writing new obvious-but-wrong code. Chosen solution: Uncategorized The Rust developers wanted an engineered safeguard against the bug of assuming that a particular error shows up as Other. They chose the following solution: There is now a new ErrorKind::Uncategorized which is now used for all OS errors for which there isn't a more specific categorisation. The fallback translation of unknown errors was changed from Other to Uncategorised. This is de jure justified by the fact that this enum has always been marked non_exhaustive. But in practice because this bug wasn't previously detected, there is such code in the wild. That code now breaks (usually, in the form of failing test cases). Usually when Rust starts to detect a particular programming error, it is reported as a new warning, which doesn't break anything. But that's not possible here, because this is a behavioural change. The new ErrorKind::Uncategorized is marked unstable. This makes it impossible to write code on Stable Rust which insists that an error comes out as Uncategorized. So, one cannot now write code that will break when new ErrorKinds are added. That's the intended effect. The downside is that this does break old code, and, worse, it is not as clear as it should be what the fixed code looks like. Alternatives considered and rejected by the Rust developers Not adding more ErrorKinds This was not tenable. The existing set is already too small, and error categorisation is in any case expected to improve over time. Just adding ErrorKinds as had been done before This would mean occasionally breaking test cases (or, possibly, production code) when an error that was previously Other becomes categorised. The broken code would have been "obvious", but de jure wrong, just as it is now, So this option amounts to expecting this broken code to continue to be written and continuing to break it occasionally. Somehow using Rust's Edition system The Rust language has a system to allow language evolution, where code declares its Edition (2015, 2018, 2021). Code from multiple editions can be combined, so that the ecosystem can upgrade gradually. It's not clear how this could be used for ErrorKind, though. Errors have to be passed between code with different editions. If those different editions had different categorisations, the resulting programs would have incoherent and broken error handling. Also some of the schemes for making this change would mean that new ErrorKinds could only be stabilised about once every 3 years, which is far too slow. How to fix code broken by this change Most main-line error handling code already has a fallback case for unknown errors. Simply replacing any occurrence of Other with _ is right. How to fix thorough tests The tricky problem is tests. Typically, a thorough test case wants to check that the error is "precisely as expected" (as far as the test can tell). Now that unknown errors come out as an unstable Uncategorized variant that's not so easy. If the test is expecting an error that is currently not categorised, you want to write code that says "if the error is any of the recognised kinds, call it a test failure". What does "any of the recognised kinds" mean here ? It doesn't meany any of the kinds recognised by the version of the Rust stdlib that is actually in use. That set might get bigger. When the test is compiled and run later, perhaps years later, the error in this test case might indeed be categorised. What you actually mean is "the error must not be any of the kinds which existed when the test was written". IMO therefore the right solution for such a test case is to cut and paste the current list of stable ErrorKinds into your code. This will seem wrong at first glance, because the list in your code and in Rust can get out of step. But when they do get out of step you want your version, not the stdlib's. So freezing the list at a point in time is precisely right. You probably only want to maintain one copy of this list, so put it somewhere central in your codebase's test support machinery. Periodically, you can update the list deliberately - and fix any resulting test failures. Unfortunately this approach is not suggested by the documentation. In theory you could work all this out yourself from first principles, given even the situation prior to May 2020, but it seems unlikely that many people have done so. In particular, cutting and pasting the list of recognised errors would seem very unnatural. Conclusions This was not an easy problem to solve well. I think Rust has done a plausible job given the various constraints, and the result is technically good. It is a shame that this change to make the error handling stability more correct caused the most trouble for the most careful people who write the most thorough tests. I also think the docs could be improved.
edited shortly after posting, and again 2021-09-22 16:11 UTC, to fix HTML slips


comment count unavailable comments

20 September 2021

Jamie McClelland: Putty Problems

I upgraded my first servers from buster to bullseye over the weekend and it went very smoothly, so big thank you to all the debian developers who contributed your labor to the bullseye release! This morning, however, I hit a snag when the first windows users tried to login. It seems like a putty bug (see update below). First, the user received an error related to algorithm selection. I didn t record the exact error and simply suggested that the user upgrade. Once the user was running the latest version of putty (0.76), they received a new error:
Server refused public-key signature despite accepting key!
I turned up debugging on the server and recorded:
Sep 20 13:10:32 container001 sshd[1647842]: Accepted key RSA SHA256:t3DVS5wZmO7DVwqFc41AvwgS5gx1jDWnR89apGmFpf4 found at /home/XXXXXXXXX/.ssh/authorized_keys:6
Sep 20 13:10:32 container001 sshd[1647842]: debug1: restore_uid: 0/0
Sep 20 13:10:32 container001 sshd[1647842]: Postponed publickey for XXXXXXXXX from xxx.xxx.xxx.xxx port 63579 ssh2 [preauth]
Sep 20 13:10:33 container001 sshd[1647842]: debug1: userauth-request for user XXXXXXXXX service ssh-connection method publickey [preauth]
Sep 20 13:10:33 container001 sshd[1647842]: debug1: attempt 2 failures 0 [preauth]
Sep 20 13:10:33 container001 sshd[1647842]: debug1: temporarily_use_uid: 1000/1000 (e=0/0)
Sep 20 13:10:33 container001 sshd[1647842]: debug1: trying public key file /home/XXXXXXXXX/.ssh/authorized_keys
Sep 20 13:10:33 container001 sshd[1647842]: debug1: fd 5 clearing O_NONBLOCK
Sep 20 13:10:33 container001 sshd[1647842]: debug1: /home/XXXXXXXXX/.ssh/authorized_keys:6: matching key found: RSA SHA256:t3DVS5wZmO7DVwqFc41AvwgS5gx1jDWnR89apGmFpf4
Sep 20 13:10:33 container001 sshd[1647842]: debug1: /home/XXXXXXXXX/.ssh/authorized_keys:6: key options: agent-forwarding port-forwarding pty user-rc x11-forwarding
Sep 20 13:10:33 container001 sshd[1647842]: Accepted key RSA SHA256:t3DVS5wZmO7DVwqFc41AvwgS5gx1jDWnR89apGmFpf4 found at /home/XXXXXXXXX/.ssh/authorized_keys:6
Sep 20 13:10:33 container001 sshd[1647842]: debug1: restore_uid: 0/0
Sep 20 13:10:33 container001 sshd[1647842]: debug1: auth_activate_options: setting new authentication options
Sep 20 13:10:33 container001 sshd[1647842]: Failed publickey for XXXXXXXXX from xxx.xxx.xxx.xxx port 63579 ssh2: RSA SHA256:t3DVS5wZmO7DVwqFc41AvwgS5gx1jDWnR89apGmFpf4
Sep 20 13:10:39 container001 sshd[1647514]: debug1: Forked child 1648153.
Sep 20 13:10:39 container001 sshd[1648153]: debug1: Set /proc/self/oom_score_adj to 0
Sep 20 13:10:39 container001 sshd[1648153]: debug1: rexec start in 5 out 5 newsock 5 pipe 8 sock 9
Sep 20 13:10:39 container001 sshd[1648153]: debug1: inetd sockets after dupping: 4, 4
The server log seems to agree with the client returned message: first the key was accepted, then it was refused. We re-generated a new key. We turned off the windows firewall. We deleted all the putty settings via the windows registry and re-set them from scratch. Nothing seemed to work. Then, another windows user reported no problem (and that user was running putty version 0.74). So the first user downgraded to 0.74 and everything worked fine.

Update Wow, very impressed with the responsiveness of putty devs! And, who knew that putty is available in debian?? Long story short: putty version 0.76 works on linux and, from what I can tell, works for everyone except my one user. Maybe it s their provider doing some filtering? Maybe a nuance to their version of Windows?

12 September 2021

Russ Allbery: DocKnot 5.00

This release is the culmination of a project that I've been wanting to do for two years, but nearly all the work was done in the past week. That experience made me rethink some of my skepticism, but I'll get to that part of the story later. In March of 1999, I got tired of writing HTML by hand and wrote a small program called spin that implemented a macro language that translated into HTML. This makes it one of the oldest programs for which I have a continuous development history, predating podlators by three months. I think only News::Gateway (now very dormant) and Term::ANSIColor (still under active development but very stable) are older, as long as I'm not counting orphaned packages like newsyslog. I've used spin continuously ever since. It's grown features and an ecosystem of somewhat hackish scripts to do web publishing things I've wanted over the years: journal entries like this one, book reviews, a simple gallery (with some now-unfortunate decisions about maximum image size), RSS feeds, and translation of lots of different input files into HTML. But the core program itself, in all those years, has been one single Perl script written mostly in my Perl coding style from the early 2000s before I read Perl Best Practices. My web site is long overdue for an overhaul. Just to name a couple of obvious problems, it looks like trash on mobile browsers, and I'm using URL syntax from the early days of the web that, while it prompts some nostalgia for tildes, means all the URLs are annoyingly long and embed useless information such as the fact each page is written in HTML. Its internals also use a lot of ad hoc microformats (a bit of RFC 2822 here, a text-based format with significant indentation there, a weird space-separated database) and are supported by programs that extract meaning from human-written pages and perform automated updates to them rather than having a clear separation between structure and data. This will be a very large project, but it's the sort of quixotic personal project that I enjoy. Maintaining my own idiosyncratic static site generator is almost certainly not an efficient use of my time compared to, say, converting everything to Hugo. But I have 3,428 pages (currently) written in the thread macro language, plus numerous customizations that cater to my personal taste and interests, and, most importantly, I like having a highly customized system that I know exactly how to automate. The blocker has been that I didn't want to work on spin as it existed. It badly needed a structural overhaul and modernization, and even more badly needed a test suite since every release involved tedious manual testing by pouring over diffs between generations of the web site. And that was enough work to be intimidating, so I kept putting it off. I've separately been vaguely aware that I have been spending too much time reading Twitter (specifically) and the news (in general). It would be one thing if I were taking in that information to do something productive about it, but I haven't been. It's just doomscrolling. I've been thinking about taking a break for a while but it kept not sticking, so I decided to make a concerted effort this week. It took about four days to stop wanting to check Twitter and forcing myself to go do something else productive or at least play a game instead. Then I managed to get started on my giant refactoring project, and holy shit, Twitter has been bad for my attention span! I haven't been able to sustain this level of concentration for hours at a time in years. Twitter's not the only thing to blame (there are a few other stressers that I've fixed in the past couple of years), but it's obviously a huge part. Anyway, this long personal ramble is prelude to the first release of DocKnot that includes my static site generator. This is not yet the full tooling from my old web tools page; specifically, it's missing faq2html, cl2xhtml, and cvs2xhtml. (faq2html will get similar modernization treatment, cvs2xhtml will probably be rewritten in Perl since I have some old, obsolete scripts that may live in CVS forever, and I may retire cl2xhtml since I've stopped using the GNU ChangeLog format entirely.) But DocKnot now contains the core of my site generation system, including the thread macro language, POD conversion (by way of Pod::Thread), and RSS feeds. Will anyone else ever use this? I have no idea; realistically, probably not. If you were starting from scratch, I'm sure you'd be better off with one of the larger and more mature static site generators that's not the idiosyncratic personal project of one individual. It is packaged for Debian because it's part of the tool chain for generating files (specifically README.md) that are included in every package I maintain, and thus is part of the transitive closure of Debian main, but I'm not sure anyone will install it from there for any other purpose. But for once making something for someone else isn't the point. This is my quirky, individual way to maintain web sites that originated in an older era of the web and that I plan to keep up-to-date (I'm long overdue to figure out what they did to HTML after abandoning the XHTML approach) because it brings me joy to do things this way. In addition to adding the static site generator, this release also has the regular sorts of bug fixes and minor improvements: better formatting of software pages for software that's packaged for Debian, not assuming every package has a TODO file, and ignoring Autoconf 2.71 backup files when generating distribution tarballs. You can get the latest version of DocKnot from CPAN as App-DocKnot, or from its distribution page. I know I haven't yet updated my web tools page to reflect this move, or changed the URL in the footer of all of my pages. This transition will be a process over the next few months and will probably prompt several more minor releases.

Vincent Bernat: Short feedback on Cisco pyATS and Genie Parser

Cisco pyATS is a framework for network automation and testing. It includes, among other things, an open-source multi-vendor set of parsers and models, Genie Parser. It features 2700 parsers for various commands over many network OS. On the paper, this seems a great tool!
>>> from genie.conf.base import Device
>>> device = Device("router", os="iosxr")
>>> # Hack to parse outputs without connecting to a device
>>> device.custom.setdefault("abstraction",  )["order"] = ["os", "platform"]
>>> cmd = "show route ipv4 unicast"
>>> output = """
... Tue Oct 29 21:29:10.924 UTC
...
... O    10.13.110.0/24 [110/2] via 10.12.110.1, 5d23h, GigabitEthernet0/0/0/0.110
... """
>>> device.parse(cmd, output=output)
 'vrf':  'default':  'address_family':  'ipv4':  'routes':  '10.13.110.0/24':  'route': '10.13.110.0/24',
       'active': True,
       'route_preference': 110,
       'metric': 2,
       'source_protocol': 'ospf',
       'source_protocol_codes': 'O',
       'next_hop':  'next_hop_list':  1:  'index': 1,
          'next_hop': '10.12.110.1',
          'outgoing_interface': 'GigabitEthernet0/0/0/0.110',
          'updated': '5d23h' 
First deception: pyATS is closed-source with some exceptions. This is quite annoying if you run into some issues outside Genie Parser. For example, although pyATS is using the ssh command, it cannot leverage my ssh_config file: pyATS resolves hostnames before providing them to ssh. There is no plan to open source pyATS. Then, Genie Parser has two problems:
  1. The data models used are dependent on the vendor and OS, despite the documentation saying otherwise. For example, the data model used for IPv4 interfaces is different between NX-OS and IOS-XR.
  2. The parsers rely on line-by-line regular expressions to extract data and some Python code as glue. This is fragile and may break silently.
To illustrate the second point, let s assume the output of show ipv4 vrf all interface is:
  Loopback10 is Up, ipv4 protocol is Up
    Vrf is default (vrfid 0x60000000)
    Internet protocol processing disabled
  Loopback30 is Up, ipv4 protocol is Down [VRF in FWD reference]
    Vrf is ran (vrfid 0x0)
    Internet address is 203.0.113.17/32
    MTU is 1500 (1500 is available to IP)
    Helper address is not set
    Directed broadcast forwarding is disabled
    Outgoing access list is not set
    Inbound  common access list is not set, access list is not set
    Proxy ARP is disabled
    ICMP redirects are never sent
    ICMP unreachables are always sent
    ICMP mask replies are never sent
    Table Id is 0x0
Because the regular expression to parse an interface name does not expect the extra data after the interface state, Genie Parser ignores the line starting the definition of Loopback30 and parses the output to this structure:1
 
  "Loopback10":  
    "int_status": "up",
    "oper_status": "up",
    "vrf": "ran",
    "vrf_id": "0x0",
    "ipv4":  
      "203.0.113.17/32":  
        "ip": "203.0.113.17",
        "prefix_length": "32"
       ,
      "mtu": 1500,
      "mtu_available": 1500,
      "broadcast_forwarding": "disabled",
      "proxy_arp": "disabled",
      "icmp_redirects": "never sent",
      "icmp_unreachables": "always sent",
      "icmp_replies": "never sent",
      "table_id": "0x0"


While this bug is simple to fix, this is an uphill battle. Any existing or future slight variation in the output of a command could trigger another similar undetected bug, despite the extended test coverage. I have reported and fixed several other silent parsing errors: #516, #529, and #530. A more robust alternative would have been to use TextFSM and to trigger a warning when some output is not recognized, like Batfish, a configuration analysis tool, does. In the future, we should rely on YANG for data extraction, but it is currently not widely supported. SNMP is still a valid possibility but much information is not accessible through this protocol. In the meantime, I would advise you to only use Genie Parser with caution.

  1. As an exercise, the astute reader is asked to write the code to extract the IPv4 from this structure.

11 September 2021

John Goerzen: Facebook Is Censoring People For Mentioning Open-Source Social Network Mastodon

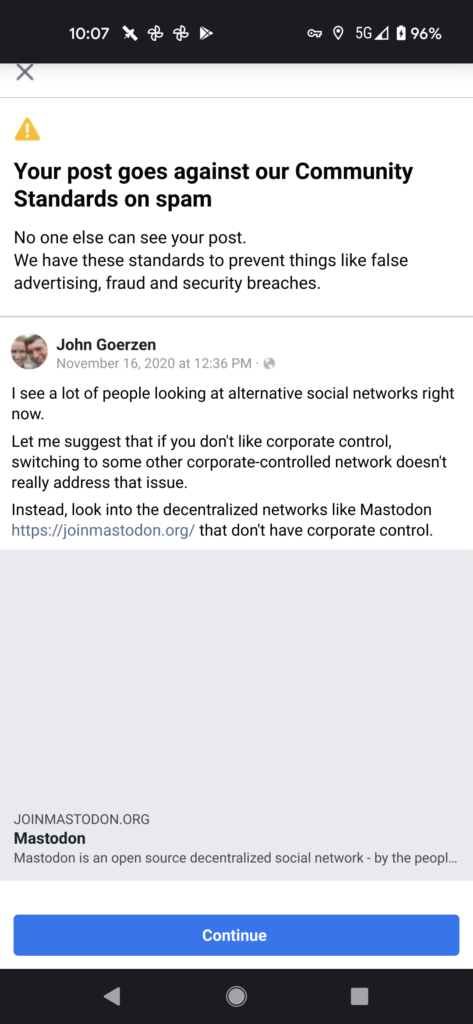
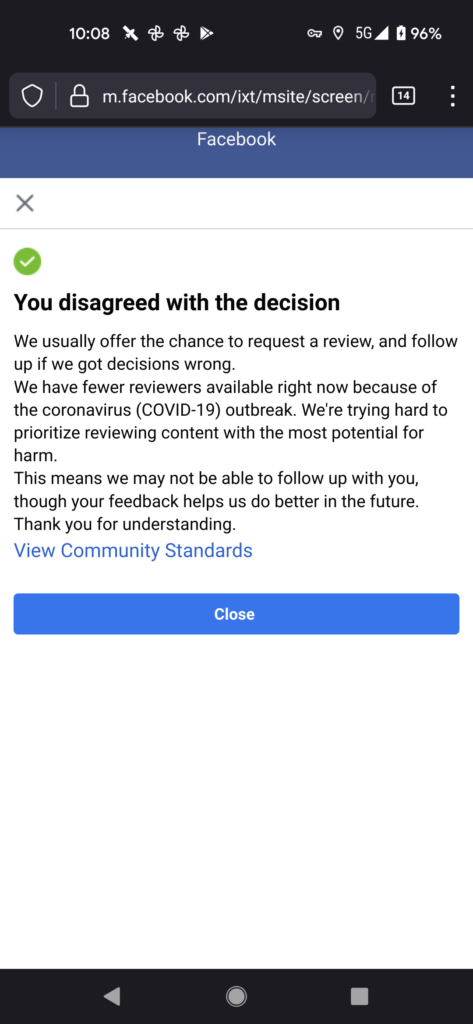
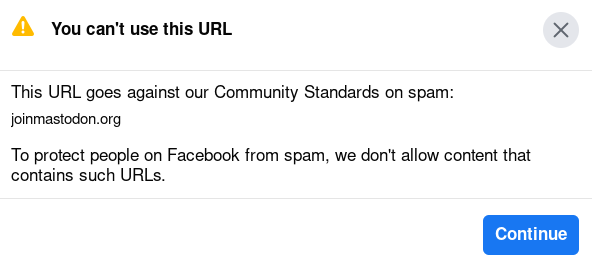
Update: Facebook has reversed itself over this censorship, but I maintain that whether the censorship was algorithmic or human, it was intentional either way. Details in my new post. Last November, I made a brief post to Facebook about Mastodon. Mastodon is an open-source and open social network, which is decentralized and all about user control instead of corporate control. I ve blogged about Mastodon and the dangers of Facebook before, but rarely mentioned Mastodon on Facebook itself. Today, I received this notice that Facebook had censored my post about Mastodon: Facebook censoring a post Wonder with me for a second what this one-off post I composed myself might have done to trip Facebook s filter . and it is probably obvious that what tripped the filter was the mention of an open source competitor, even though Facebook is much more enormous than Mastodon. I have been a member of Facebook for many years, and this is the one and only time anything like that has happened. Why they decided today to take down that post I have no idea. In case you wondered about their sincerity towards stamping out misinformation which, on the rare occasions they do something about, they deprioritize rather than remove as they did here this probably answers your question. Or, are they sincere about thinking they re such a force for good by connecting the world s people? Well, only so long as the world s people don t say nice things about alternatives to Facebook, I guess. Well, you might be wondering, Why not appeal, since they obviously made a mistake? Because, of course, you can t: Indeed I did tick a box that said I disagreed, but there was no place to ask why or to question their action. So what would cause a non-controversial post from a long-time Facebook member that has never had anything like this happen, to disappear? Greed. Also fear. Maybe I d feel sorry for them if they weren t acting like a bully. Edit: There are reports from several others on Mastodon of the same happening this week. I am trying to gather more information. It sounds like it may be happening on Twitter as well. Edit 2: And here are some other reports from both Facebook and Twitter. Definitely not just me. Edit 3: While trying to reply to someone on Facebook, that was trying to defend Facebook, I mentioned joinmastodon.org and got this: Anyone else seeing it? Edit 4: It is far more than just me, clearly. More reports are out there; for instance, this one and that one.
9 September 2021

Dirk Eddelbuettel: RcppSMC 0.2.5 on CRAN: Build Update

A week after the 0.2.5 release bringing the recent Google Summer of Code for RcppSMC to CRAN, we have a minor bug-fix release consistently, essentially, of one line. Everybody s favourite OS and toolchain did not know what to make of pow(), and I seemingly failed to test there, so shame on me. But now all is good thanks to proper use of std::pow(). RcppSMC provides Rcpp-based bindings to R for the Sequential Monte Carlo Template Classes (SMCTC) by Adam Johansen described in his JSS article. Sequential Monte Carlo is also referred to as Particle Filter in some contexts. The package now features the Google Summer of Code work by Leah South in 2017, and by Ilya Zarubin in 2021. This release is summarized below.

Changes in RcppSMC version 0.2.5 (2021-09-09)
  • Compilation under Solaris is aided via std::pow use (Dirk in #65 fixing #64)

Courtesy of my CRANberries, there is a diffstat report for this release. More information is on the RcppSMC page. Issues and bugreports should go to the GitHub issue tracker. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Bits from Debian: DebConf21 online closes

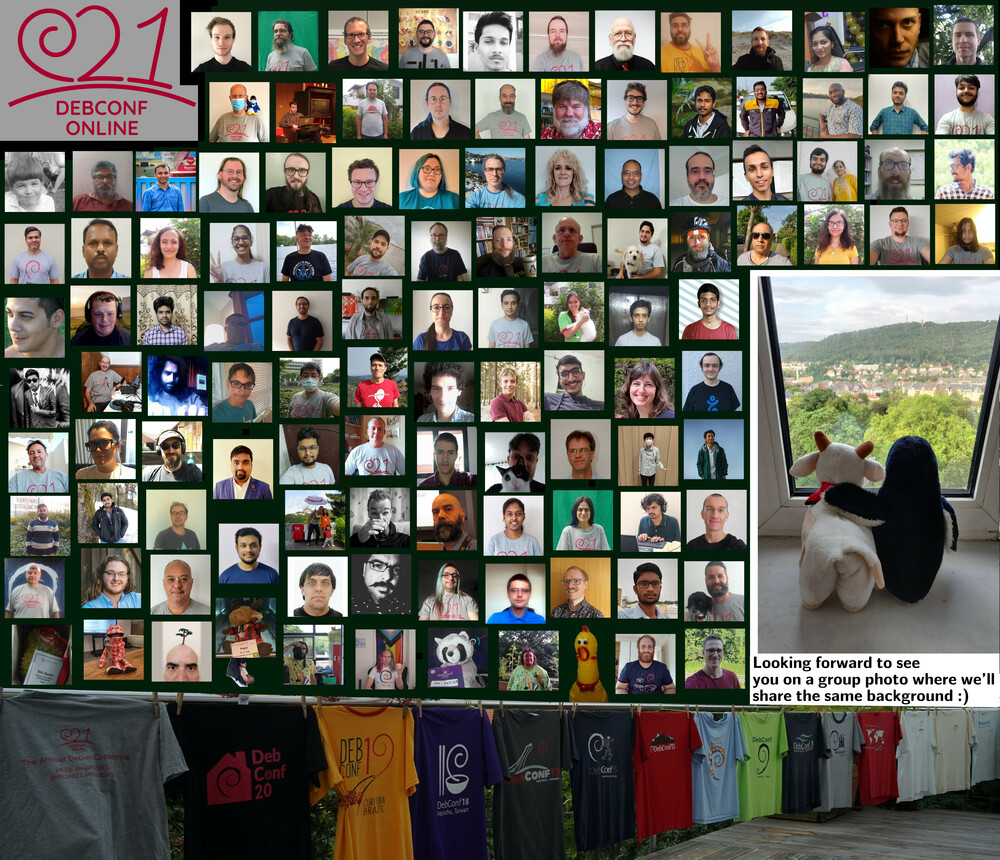
DebConf21 group photo - click to enlarge On Saturday 28 August 2021, the annual Debian Developers and Contributors Conference came to a close. DebConf21 has been held online for the second time, due to the coronavirus (COVID-19) disease pandemic. All of the sessions have been streamed, with a variety of ways of participating: via IRC messaging, online collaborative text documents, and video conferencing meeting rooms. With 740 registered attendees from more than 15 different countries and a total of over 70 event talks, discussion sessions, Birds of a Feather (BoF) gatherings and other activities, DebConf21 was a large success. The setup made for former online events involving Jitsi, OBS, Voctomix, SReview, nginx, Etherpad, a web-based frontend for voctomix has been improved and used for DebConf21 successfully. All components of the video infrastructure are free software, and configured through the Video Team's public ansible repository. The DebConf21 schedule included a wide variety of events, grouped in several tracks: The talks have been streamed using two rooms, and several of these activities have been held in different languages: Telugu, Portuguese, Malayalam, Kannada, Hindi, Marathi and English, allowing a more diverse audience to enjoy and participate. Between talks, the video stream has been showing the usual sponsors on the loop, but also some additional clips including photos from previous DebConfs, fun facts about Debian and short shout-out videos sent by attendees to communicate with their Debian friends. The Debian publicity team did the usual live coverage to encourage participation with micronews announcing the different events. The DebConf team also provided several mobile options to follow the schedule. For those who were not able to participate, most of the talks and sessions are already available through the Debian meetings archive website, and the remaining ones will appear in the following days. The DebConf21 website will remain active for archival purposes and will continue to offer links to the presentations and videos of talks and events. Next year, DebConf22 is planned to be held in Prizren, Kosovo, in July 2022. DebConf is committed to a safe and welcome environment for all participants. During the conference, several teams (Front Desk, Welcome team and Community team) have been available to help so participants get their best experience in the conference, and find solutions to any issue that may arise. See the web page about the Code of Conduct in DebConf21 website for more details on this. Debian thanks the commitment of numerous sponsors to support DebConf21, particularly our Platinum Sponsors: Lenovo, Infomaniak, Roche, Amazon Web Services (AWS) and Google. About Debian The Debian Project was founded in 1993 by Ian Murdock to be a truly free community project. Since then the project has grown to be one of the largest and most influential open source projects. Thousands of volunteers from all over the world work together to create and maintain Debian software. Available in 70 languages, and supporting a huge range of computer types, Debian calls itself the universal operating system. About DebConf DebConf is the Debian Project's developer conference. In addition to a full schedule of technical, social and policy talks, DebConf provides an opportunity for developers, contributors and other interested people to meet in person and work together more closely. It has taken place annually since 2000 in locations as varied as Scotland, Argentina, and Bosnia and Herzegovina. More information about DebConf is available from https://debconf.org/. About Lenovo As a global technology leader manufacturing a wide portfolio of connected products, including smartphones, tablets, PCs and workstations as well as AR/VR devices, smart home/office and data center solutions, Lenovo understands how critical open systems and platforms are to a connected world. About Infomaniak Infomaniak is Switzerland's largest web-hosting company, also offering backup and storage services, solutions for event organizers, live-streaming and video on demand services. It wholly owns its datacenters and all elements critical to the functioning of the services and products provided by the company (both software and hardware). About Roche Roche is a major international pharmaceutical provider and research company dedicated to personalized healthcare. More than 100.000 employees worldwide work towards solving some of the greatest challenges for humanity using science and technology. Roche is strongly involved in publicly funded collaborative research projects with other industrial and academic partners and have supported DebConf since 2017. About Amazon Web Services (AWS) Amazon Web Services (AWS) is one of the world's most comprehensive and broadly adopted cloud platform, offering over 175 fully featured services from data centers globally (in 77 Availability Zones within 24 geographic regions). AWS customers include the fastest-growing startups, largest enterprises and leading government agencies. About Google Google is one of the largest technology companies in the world, providing a wide range of Internet-related services and products such as online advertising technologies, search, cloud computing, software, and hardware. Google has been supporting Debian by sponsoring DebConf for more than ten years, and is also a Debian partner sponsoring parts of Salsa's continuous integration infrastructure within Google Cloud Platform. Contact Information For further information, please visit the DebConf21 web page at https://debconf21.debconf.org/ or send mail to press@debian.org.

6 September 2021

Vincent Bernat: Switching to the i3 window manager

I have been using the awesome window manager for 10 years. It is a tiling window manager, configurable and extendable with the Lua language. Using a general-purpose programming language to configure every aspect is a double-edged sword. Due to laziness and the apparent difficulty of adapting my configuration about 3000 lines to newer releases, I was stuck with the 3.4 version, whose last release is from 2013. It was time for a rewrite. Instead, I have switched to the i3 window manager, lured by the possibility to migrate to Wayland and Sway later with minimal pain. Using an embedded interpreter for configuration is not as important to me as it was in the past: it brings both complexity and brittleness.
i3 dual screen setup
Dual screen desktop running i3, Emacs, some terminals, including a Quake console, Firefox, Polybar as the status bar, and Dunst as the notification daemon.
The window manager is only one part of a desktop environment. There are several options for the other components. I am also introducing them in this post.

i3: the window manager i3 aims to be a minimal tiling window manager. Its documentation can be read from top to bottom in less than an hour. i3 organize windows in a tree. Each non-leaf node contains one or several windows and has an orientation and a layout. This information arbitrates the window positions. i3 features three layouts: split, stacking, and tabbed. They are demonstrated in the below screenshot:
Example of layouts
Demonstration of the layouts available in i3. The main container is split horizontally. The first child is split vertically. The second one is tabbed. The last one is stacking.
Tree representation of the previous screenshot
Tree representation of the previous screenshot.
Most of the other tiling window managers, including the awesome window manager, use predefined layouts. They usually feature a large area for the main window and another area divided among the remaining windows. These layouts can be tuned a bit, but you mostly stick to a couple of them. When a new window is added, the behavior is quite predictable. Moreover, you can cycle through the various windows without thinking too much as they are ordered. i3 is more flexible with its ability to build any layout on the fly, it can feel quite overwhelming as you need to visualize the tree in your head. At first, it is not unusual to find yourself with a complex tree with many useless nested containers. Moreover, you have to navigate windows using directions. It takes some time to get used to. I set up a split layout for Emacs and a few terminals, but most of the other workspaces are using a tabbed layout. I don t use the stacking layout. You can find many scripts trying to emulate other tiling window managers but I did try to get my setup pristine of these tentatives and get a chance to familiarize myself. i3 can also save and restore layouts, which is quite a powerful feature. My configuration is quite similar to the default one and has less than 200 lines.

i3 companion: the missing bits i3 philosophy is to keep a minimal core and let the user implements missing features using the IPC protocol:
Do not add further complexity when it can be avoided. We are generally happy with the feature set of i3 and instead focus on fixing bugs and maintaining it for stability. New features will therefore only be considered if the benefit outweighs the additional complexity, and we encourage users to implement features using the IPC whenever possible. Introduction to the i3 window manager
While this is not as powerful as an embedded language, it is enough for many cases. Moreover, as high-level features may be opinionated, delegating them to small, loosely coupled pieces of code keeps them more maintainable. Libraries exist for this purpose in several languages. Users have published many scripts to extend i3: automatic layout and window promotion to mimic the behavior of other tiling window managers, window swallowing to put a new app on top of the terminal launching it, and cycling between windows with Alt+Tab. Instead of maintaining a script for each feature, I have centralized everything into a single Python process, i3-companion using asyncio and the i3ipc-python library. Each feature is self-contained into a function. It implements the following components:
make a workspace exclusive to an application
When a workspace contains Emacs or Firefox, I would like other applications to move to another workspace, except for the terminal which is allowed to intrude into any workspace. The workspace_exclusive() function monitors new windows and moves them if needed to an empty workspace or to one with the same application already running.
implement a Quake console
The quake_console() function implements a drop-down console available from any workspace. It can be toggled with Mod+ . This is implemented as a scratchpad window.
back and forth workspace switching on the same output
With the workspace back_and_forth command, we can ask i3 to switch to the previous workspace. However, this feature is not restricted to the current output. I prefer to have one keybinding to switch to the workspace on the next output and one keybinding to switch to the previous workspace on the same output. This behavior is implemented in the previous_workspace() function by keeping a per-output history of the focused workspaces.
create a new empty workspace or move a window to an empty workspace
To create a new empty workspace or move a window to an empty workspace, you have to locate a free slot and use workspace number 4 or move container to workspace number 4. The new_workspace() function finds a free number and use it as the target workspace.
restart some services on output change
When adding or removing an output, some actions need to be executed: refresh the wallpaper, restart some components unable to adapt their configuration on their own, etc. i3 triggers an event for this purpose. The output_update() function also takes an extra step to coalesce multiple consecutive events and to check if there is a real change with the low-level library xcffib.
I will detail the other features as this post goes on. On the technical side, each function is decorated with the events it should react to:
@on(CommandEvent("previous-workspace"), I3Event.WORKSPACE_FOCUS)
async def previous_workspace(i3, event):
    """Go to previous workspace on the same output."""
The CommandEvent() event class is my way to send a command to the companion, using either i3-msg -t send_tick or binding a key to a nop command. The latter is used to avoid spawning a shell and a i3-msg process just to send a message. The companion listens to binding events and checks if this is a nop command.
bindsym $mod+Tab nop "previous-workspace"
There are other decorators to avoid code duplication: @debounce() to coalesce multiple consecutive calls, @static() to define a static variable, and @retry() to retry a function on failure. The whole script is a bit more than 1000 lines. I think this is worth a read as I am quite happy with the result.

dunst: the notification daemon Unlike the awesome window manager, i3 does not come with a built-in notification system. Dunst is a lightweight notification daemon. I am running a modified version with HiDPI support for X11 and recursive icon lookup. The i3 companion has a helper function, notify(), to send notifications using DBus. container_info() and workspace_info() uses it to display information about the container or the tree for a workspace.
Notification showing i3 tree for a workspace
Notification showing i3 s tree for a workspace

polybar: the status bar i3 bundles i3bar, a versatile status bar, but I have opted for Polybar. A wrapper script runs one instance for each monitor. The first module is the built-in support for i3 workspaces. To not have to remember which application is running in a workspace, the i3 companion renames workspaces to include an icon for each application. This is done in the workspace_rename() function. The icons are from the Font Awesome project. I maintain a mapping between applications and icons. This is a bit cumbersome but it looks great.
i3 workspaces in Polybar
For CPU, memory, brightness, battery, disk, and audio volume, I am relying on the built-in modules. Polybar s wrapper script generates the list of filesystems to monitor and they get only displayed when available space is low. The battery widget turns red and blinks slowly when running out of power. Check my Polybar configuration for more details.
Various modules for Polybar
Polybar displaying various information: CPU usage, memory usage, screen brightness, battery status, Bluetooth status (with a connected headset), network status (connected to a wireless network and to a VPN), notification status, and speaker volume.
For Bluetooh, network, and notification statuses, I am using Polybar s ipc module: the next version of Polybar can receive an arbitrary text on an IPC socket. The module is defined with a single hook to be executed at the start to restore the latest status.
[module/network]
type = custom/ipc
hook-0 = cat $XDG_RUNTIME_DIR/i3/network.txt 2> /dev/null
initial = 1
It can be updated with polybar-msg action "#network.send.XXXX". In the i3 companion, the @polybar() decorator takes the string returned by a function and pushes the update through the IPC socket. The i3 companion reacts to DBus signals to update the Bluetooth and network icons. The @on() decorator accepts a DBusSignal() object:
@on(
    StartEvent,
    DBusSignal(
        path="/org/bluez",
        interface="org.freedesktop.DBus.Properties",
        member="PropertiesChanged",
        signature="sa sv as",
        onlyif=lambda args: (
            args[0] == "org.bluez.Device1"
            and "Connected" in args[1]
            or args[0] == "org.bluez.Adapter1"
            and "Powered" in args[1]
        ),
    ),
)
@retry(2)
@debounce(0.2)
@polybar("bluetooth")
async def bluetooth_status(i3, event, *args):
    """Update bluetooth status for Polybar."""
The middle of the bar is occupied by the date and a weather forecast. The latest also uses the IPC mechanism, but the source is a Python script triggered by a timer.
Date and weather in Polybar
Current date and weather forecast for the day in Polybar. The data is retrieved with the OpenWeather API.
I don t use the system tray integrated with Polybar. The embedded icons usually look horrible and they all behave differently. A few years back, Gnome has removed the system tray. Most of the problems are fixed by the DBus-based Status Notifier Item protocol also known as Application Indicators or Ayatana Indicators for GNOME. However, Polybar does not support this protocol. In the i3 companion, The implementation of Bluetooth and network icons, including displaying notifications on change, takes about 200 lines. I got to learn a bit about how DBus works and I get exactly the info I want.

picom: the compositor I like having slightly transparent backgrounds for terminals and to reduce the opacity of unfocused windows. This requires a compositor.1 picom is a lightweight compositor. It works well for me, but it may need some tweaking depending on your graphic card.2 Unlike the awesome window manager, i3 does not handle transparency, so the compositor needs to decide by itself the opacity of each window. Check my configuration for details.

systemd: the service manager I use systemd to start i3 and the various services around it. My xsession script only sets some environment variables and lets systemd handles everything else. Have a look at this article from Micha G ral for the rationale. Notably, each component can be easily restarted and their logs are not mangled inside the ~/.xsession-errors file.3 I am using a two-stage setup: i3.service depends on xsession.target to start services before i3:
[Unit]
Description=X session
BindsTo=graphical-session.target
Wants=autorandr.service
Wants=dunst.socket
Wants=inputplug.service
Wants=picom.service
Wants=pulseaudio.socket
Wants=policykit-agent.service
Wants=redshift.service
Wants=spotify-clean.timer
Wants=ssh-agent.service
Wants=xiccd.service
Wants=xsettingsd.service
Wants=xss-lock.service
Then, i3 executes the second stage by invoking the i3-session.target:
[Unit]
Description=i3 session
BindsTo=graphical-session.target
Wants=wallpaper.service
Wants=wallpaper.timer
Wants=polybar-weather.service
Wants=polybar-weather.timer
Wants=polybar.service
Wants=i3-companion.service
Wants=misc-x.service
Have a look on my configuration files for more details.

rofi: the application launcher Rofi is an application launcher. Its appearance can be customized through a CSS-like language and it comes with several themes. Have a look at my configuration for mine.
Rofi as an application launcher
It can also act as a generic menu application. I have a script to control a media player and another one to select the wifi network. It is quite a flexible application.
Rofi as a wifi network selector
Rofi to select a wireless network

xss-lock and i3lock: the screen locker i3lock is a simple screen locker. xss-lock invokes it reliably on inactivity or before a system suspend. For inactivity, it uses the XScreenSaver events. The delay is configured using the xset s command. The locker can be invoked immediately with xset s activate. X11 applications know how to prevent the screen saver from running. I have also developed a small dimmer application that is executed 20 seconds before the locker to give me a chance to move the mouse if I am not away.4 Have a look at my configuration script.
Demonstration of xss-lock, xss-dimmer and i3lock with a 4 speedup.

The remaining components
  • autorandr is a tool to detect the connected display, match them against a set of profiles, and configure them with xrandr.
  • inputplug executes a script for each new mouse and keyboard plugged. This is quite useful to load the appropriate the keyboard map. See my configuration.
  • xsettingsd provides settings to X11 applications, not unlike xrdb but it notifies applications for changes. The main use is to configure the Gtk and DPI settings. See my article on HiDPI support on Linux with X11.
  • Redshift adjusts the color temperature of the screen according to the time of day.
  • maim is a utility to take screenshots. I use Prt Scn to trigger a screenshot of a window or a specific area and Mod+Prt Scn to capture the whole desktop to a file. Check the helper script for details.
  • I have a collection of wallpapers I rotate every hour. A script selects them using advanced machine learning algorithms and stitches them together on multi-screen setups. The selected wallpaper is reused by i3lock.

  1. Apart from the eye candy, a compositor also helps to get tear-free video playbacks.
  2. My configuration works with both Haswell (2014) and Whiskey Lake (2018) Intel GPUs. It also works with AMD GPU based on the Polaris chipset (2017).
  3. You cannot manage two different displays this way e.g. :0 and :1. In the first implementation, I did try to parametrize each service with the associated display, but this is useless: there is only one DBus user session and many services rely on it. For example, you cannot run two notification daemons.
  4. I have only discovered later that XSecureLock ships such a dimmer with a similar implementation. But mine has a cool countdown!

5 September 2021

Antoine Beaupr : Automating major Debian upgrades

It's major upgrade time again! The Debian project just published the Debian 11 "bullseye" release, and it's pretty awesome! This makes me realized that I have never written here about my peculiar upgrade process, and figured it was worth bringing that up to a wider audience. My upgrade process also has a notable changes section which includes major version changes (e.g. Inkscape 1.0!), new packages (e.g. podman!) and important behavior changes (e.g. driverless scanning and printing!). I'm particularly interested to hear about any significant change I might have missed. If you know of a cool new package that shipped with bullseye and that I forgot, do let me know! But that's for the cool new stuff. We need to talk about the problems with Debian major upgrades.

Background I have been maintaining detailed upgrade guides, on my wiki, starting with the jessie release, but I have actually written such guides for Koumbit.org as far back as Debian squeeze in 2011 (another worker wrote the older Debian lenny upgrade guide in 2009). Koumbit, since then, has kept maintaining those guides all the way to the latest bullseye upgrade, through 7 major releases! Over the years, those guides evolved from a quick "cheat-sheet" format copied from the release notes into a more or less "scripted" form that I currently use. Each guide has a procedure made of a few steps that can be basically copy-pasted to batch-upgrade a host (or multiple hosts in parallel) as quickly as possible. There is also the predict-os script which allows you to keep track of progress of the upgrades in a Puppet cluster.

Limitations of the official procedure In comparison with my procedure, the official upgrade guide is mostly designed to upgrade a single machine, typically a workstation, with a rather slow and exhaustive process. The PDF version of the upgrade guide is 14 pages long! This, obviously, does not work when you have tens or hundreds of machines to upgrade. Debian upgrades are notorious for being extremely reliable, but we have a lot of packages, and there are always corner cases where the upgrade will just fail because of a bug specific to your environment. Those will only be fixed after some back and forth in the community (and that's assuming users report those bugs, which is not always the case). There's no obvious way to deploy "hot fixes" in this context, at least not without fixing the package and publishing it on an unofficial Debian archive while the official ones catch up. This is slow and difficult. Or some packages require manual labor. Examples of this are the PostgreSQL or Ganeti packages which require you to upgrade your clusters by hand, while the old and new packages live side by side. Debian packages bring you far in the upgrade process, but sometimes not all the way. Which means every Debian install needs to be manually upgraded and inspected when a new release comes out. That's slow and error prone and we can do better.

How to automate major upgrades I have a proposal to automate this. It's been mostly dormant in the Debian wiki, for 5 years now. Fundamentally, this is a hard problem: Debian gets installed in so many different environments, from workstations to physical servers to virtual machines, embedded systems and so on, that it's extremely hard to come up with a "one size fits all" system. The (manual) procedure I'm using is mostly targeting servers, but I'm also using it on workstations. And I'll note that it's specific to my home setup: I have a different procedure at work, although it has a lot of common code. To automate this, I would factor out that common code with hooks where you could easily inject special code like "you need to upgrade ferm first", "you need an extra reboot here", or "this is how you finish the PostgreSQL upgrade". With Debian getting closer to a 2 year release cycle, with the previous release being supported basically only one year after the new stable comes out, I feel more and more strongly that this needs better automation. So I'm thinking that I should write a prototype for this. Ubuntu has do-release-upgrade that is too Ubuntu-specific to be reused. An attempt at collaborating on this has been mostly met with silence from Ubuntu's side as well. I'm thinking that using something like Fabric, Mitogen, or Transilience: anything that will allow me to write simple, portable Python code that can run transparently on a local machine (for single systems upgrades, possibly with a GUI frontend) to remote servers (for large clusters of servers, maybe with canaries and grouping using Cumin). I'll note that Koumbit started experimenting with Puppet Bolt in the bullseye upgrade process, but that feels too site-specific to be useful more broadly.

Trade-offs I am not sure where this stands in the XKCD time trade-off evaluation, because the table doesn't actually cover the time frequency of Debian release (which is basically "biennial") and the amount of time the upgrade would take across a cluster (which varies a lot, but that I estimate to be between one to 6 hours per machine). Assuming I have 80 machines to upgrade, that is 80 to 480 hours (between ~3 to 20 days) of work! It's unclear how much work such an automated system would shave off, however. Assuming things are an order of magnitude faster (say I upgrade 10 machines at a time), I would shave off between 3 and 18 days of work, which implies I might allow myself to spend a minimum of 5 days working on such a project.

The other option: never upgrade Before people mention those: I am aware of containers, Kubernetes, and other deployment mechanisms. Indeed, those may be a long-term solution, we currently can't afford to migrate everything over to containers right now: that is a huge migration and a total paradigm shift. At that point, whatever is left might not even be Debian in the first place. And besides, if you run Kubernetes, you still need to run some OS underneath and upgrade that, so that problem never completely disappears. Still, maybe that's the final answer: never upgrade. For some stateless machines like DNS replicas or load balancers, that might make a lot of sense as there's no or little data to carry to the new host. But this implies a seamless and fast provisioning process, and we don't have that either: at my work, installing a machine takes about as long as upgrading it, and that's after a significant amount of work automating that process, partly writing my own Debian installer with Fabric (!).

What is your process? I'm curious to hear what people think of those ideas. It strikes me as really odd that no one has really tackled that problem yet, considering how many clusters of Debian machines are out there. Surely people are upgrading those, and not following that slow step by step guide, right? I suspect everyone is doing the same thing: we all have our little copy-paste script we batch onto multiple machines, sometimes in parallel. That is what the Debian.org sysadmins are doing as well. There must be a better way. What is yours?

My upgrades so far So far, I have upgraded 2 out of my 3 home machines running buster -- others have been installed directly in bullseye -- with only my main, old, messy server left. Upgrades have been pretty painless so far (see another report, for example), much better than the previous buster upgrade. Obviously, for me personal use, automating this is pointless. Work-side, however, is another story: we have over 80 boxes to upgrade there and that will take a while. The last stretch to buster cycle took about two years to complete, so we might be done by the time the next release (12, "bookworm") is released, but that's actually a full year after "buster" becomes EOL, so it's actually too late... At least I fixed the installers so that new the machines we create all ship with bullseye, so we stopped accumulating new buster hosts...
Thanks to lelutin and pabs for reviewing a draft of this post.

3 September 2021

Dirk Eddelbuettel: RcppSMC 0.2.4 on CRAN: Even More GSoC !!

A brand new release 0.2.4 of the RcppSMC package arrived on CRAN earlier today, with a dual delay for CRAN closing for a well-earned break, and then being overwhelmed when reopening. Other than that the processing was again versy smooth. RcppSMC provides Rcpp-based bindings to R for the Sequential Monte Carlo Template Classes (SMCTC) by Adam Johansen described in his JSS article. Sequential Monte Carlo is also referred to as Particle Filter in some contexts. The package started when I put some Rcpp bindings together based on Adam s paper and library. It grew when Adam and I supervised Leah South during the 2017 iteration of the Google Summer of Code. And now it grew again as we have Adam, Leah and myself looking over the shoulders of Ilya Zarubin who did very fine work during the 2021 iteration of the Google Summer of Code that just concluded! So we are now GSoC squared! This release is effectively all work by Ilya and summarized below.

Changes in RcppSMC version 0.2.4 (2021-09-01)
  • Multiple Sequential Monte Carlo extensions (Ilya Zarubin as part of Google Summer of Code 2021)
    • Provide informative user output (convergence diagnostics) for PMMH example #50 (Ilya in #50 and #52 addressing #25, bullet point 5)
    • Support for tracking of ancestral lines for base sampler class (Ilya in #56)
    • Support for conditional SMC via derived conditionalSampler class (Ilya in #60)
  • Add URL and BugReports to DESCRIPTION (Dirk in #53)

Courtesy of my CRANberries, there is a diffstat report for this release. More information is on the RcppSMC page. Issues and bugreports should go to the GitHub issue tracker. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

2 September 2021

Eddy Petri&#537;or: Stretch to Buster upgrade issues: "Grub error: symbol grub_is_lockdown not found", missing RTL8111/8168/8411 Ethernet driver and RTL8821CE Wireless adapter on Linux Kernel 5.10 (and 4.19)

I have been Debian Stretch running on my HP Pavilion 14-ce0000nq laptop since buying it back in April 2019, just before my presence at Oxidizeconf where I presented "How to Rust When Standards Are Defined in C".Debian Buster (aka Debian 10) was released about 4 months later and I've been postponing the upgrade as my free time isn't what it used to be. I also tend to wait for the first or even second update of the release to avoid any sharp edges.As this laptop has a Realtek 8821CE wireless card that wasn't officially supported in the Linux kernel, I had to use an out-of-tree hacked driver to have the wireless work on Stretch kernels such as 4.19, it didn't even got along with DKMS, so all compilations and installations of it, I did them manually. More reason to wait for a newer release that would contain a driver inside the official kernel.I was waiting for the inevitable and dreading the wireless issues, but since mid-august Bullseye became stable, turning Stretch into oldoldstable, I decided that I had to do the upgrade, at least to buster.The Grub error and the fix
Everything went quite smooth, except that after the reboot, the laptop failed to boot with this Grub error:

error: symbol grub_is_lockdown not found
I looked for a solution and it seemed everyone was stuck or the solution was unclear.There is even a bug report in Debian about this error, bug #984760.
Adding to the pile of confusion my own confused solution: I tried supergrubdisk2/rescatux, it didn't work for me, it might have been a combination of me using LVM and grub-efi-amd64. I also tried to boot in rescue mode the Buster first DVD (to avoid the need for network), I was able to enter the partition, mount the EFI partition, too, but since I didn't want to mess the setup even more or depend on an external USB stick, I didn't know where should I try to write the Grub EFI config - the root partition is on an NVME storage.When buying the laptop it had FreeDOS installed on it and some HP rescue app, which I did not wipe when installing Debian. I even forgot where or how was the EFI installed on the disk and EFI, even if it should be more reliable and simpler, I never got the hang of it.
In the end, I realized that I could via BIOS actually select manually which EFI executable should be booted into, so I was able to boot with some manual intervention during boot into the regular system.I tried regenerating the grub configuration, installing it and also tried restoring the default proper boot sequence (and I even installed refind in the system during my fumbling), but I think somewhere between grub-efi-amd64 reconfiguration and its reinstallation I managed to do the right thing, as the default boot screen is the Grub one now.Hints for anyone reading this in the hope to fix the same issue, hopefully it will make things better, not worse (see the text below):1) regenerate the grub config:
update-grub2
2) reinstall grub-efi-amd64 and make Debian the default
dpkg-reconfigure -plow grub-efi-amd64
When reinstalling grub-efi-amd64 onto the disk, I think the scariest questions were to these:

Force extra installation to the EFI removable media path?

Some EFI-based systems are buggy and do not handle new bootloaders correctly. If you force an extra installation of GRUB to the EFI removable media path, this should ensure that this system will boot Debian correctly despite such a problem. However, it may remove the ability to boot any other operating systems that also depend on this path. If so, you will need to make sure that GRUB is configured successfully to be able to boot any other OS installations correctly.

and
Update NVRAM variables to automatically boot into Debian?

GRUB can configure your platform's NVRAM variables so that it boots into Debian automatically when powered on. However, you may prefer to disable this behavior and avoid changes to your boot configuration. For example, if your NVRAM variables have been set up such that your system contacts a PXE server on every boot, this would preserve that behavior.

I think the first can be safely answered "No" if you don't plan on booting via a removable USB stick, while the second is the one that does the restoring.The second question is probably safe if you don't use PXE boot or other boot method, at least that's what I understand. But if you do, I suspect by installing refind, by playing with the multiple efi* named packages and tools, you can restore that, or it might be that your BIOS allows that directly.
I just did a walk through of these 2 steps again on my laptop and answered "No" to the removable media question as it leads to errors when the media was not inserted (in my case the internal SD card reader), and "Yes" to making Debian the default.It seems that for me this broke the FreeDOS and HP utilities boot entries from Grub, but I still can boot via the BIOS options and my goal was to have Debian boot correctly by default.
Fixing the missing RTL811/8168/8411 Ethernet card issue
As a side note for people with computers having Realtek RTL8111/8168/8411 Gigabit Ethernet Controller and upgrading to Buster or switching to a newer kernel, please note that you might end up having the unpleasant surprise even your Ethernet card to disappear because the r8169 driver is not loader by default.I had to add it to /etc/modules so is loaded by default:
eddy@aptonia:/ $ cat /etc/modules
# /etc/modules: kernel modules to load at boot time.
#
# This file contains the names of kernel modules that should be loaded
# at boot time, one per line. Lines beginning with "#" are ignored.
r8169

The 5.10 compatible driver for RTL8821CE wireless adapterAfter the upgrade to Buster, the oldstable version of the kernel, 4.19, the hacked version of the driver I've been using on Stretch on 4.9 kernels was no longer compatible - failed to compile due to missing symbols.The fix for me was to switch to the DKMS compatible driver from https://github.com/tomaspinho/rtl8821ce, as this seems to work for both 4.19 and 5.10 kernels (installed from backports).
I installed it via a modification of the manual install method only for the 4.19 and 5.10 kernels, leaving the legacy 4.9 kernels working with the hacked driver. You can do the same if instead of running the provided script, you do its steps manually and you install only for the kernel versions you want, instead of the default to install for all:I looked inside the dkms-install.sh script to do the required steps:Copy the driver, add it to the dkms set of known drivers:
DRV_NAME=rtl8821ce
DRV_VERSION=v5.5.2_34066.20200325

cp -r . /usr/src/$ DRV_NAME -$ DRV_VERSION

dkms add -m $ DRV_NAME -v $ DRV_VERSION
But you just build and install them only for the select kernel versions of your choice:
dkms build -m $ DRV_NAME -v $ DRV_VERSION -k 5.10.0-0.bpo.8-amd64
dkms install -m $ DRV_NAME -v $ DRV_VERSION -k 5.10.0-0.bpo.8-amd64
Or, without the variables:
dkms build rtl8821ce/v5.5.2_34066.20200325 -k 4.19.0-17-amd64
dkms install rtl8821ce/v5.5.2_34066.20200325 -k 4.19.0-17-amd64
dkms status should confirm everything is in place and I think you need to update grub2 again after this.
Please note this driver is no longer maintained and the 5.10 tree should support the RTL8821CE wireless card with the rtw88 driver from the kernel, but for me it did not. I'll probably try this at a later time, or after I upgrade to the current Debian stable, Bullseye.

Ian Jackson: partial-borrow: references to restricted views of a Rust struct

tl;dr:
With these two crazy proc-macros you can hand out multipe (perhaps mutable) references to suitable subsets/views of the same struct. Why In Otter I have adopted a style where I try to avoid giving code mutable access that doesn't need it, and try to make mutable access come with some code structures to prevent "oh I forgot a thing" type mistakes. For example, mutable access to a game state is only available in contexts that have to return a value for the updates to send to the players. This makes it harder to forget to send the update. But there is a downside. The game state is inside another struct, an Instance, and much code needs (immutable) access to it. I can't pass both &Instance and &mut GameState because one is inside the other. My workaround involves passing separate references to the other fields of Instance, leading to some functions taking far too many arguments. 14 in one case. (They're all different types so argument ordering mistakes just result in compiler errors talking about arguments 9 and 11 having wrong types, rather than actual bugs.) I felt this problem was purely a restriction arising from limitations of the borrow checker. I thought it might be possible to improve on it. Weeks passed and the question gradually wormed its way into my consciousness. Eventually, I tried some experiments. Encouraged, I persisted. What and how partial-borrow is a Rust library which solves this problem. You sprinkle #[Derive(PartialBorrow)] and partial!(...) and then you can pass a reference which grants mutable access to only some of the fields. You can also pass a reference through which some fields are inaccessible. You can even split a single mut reference into multiple compatible references, for example granting mut access to mutually-nonverlapping subsets. The core type is Struct__Partial (for some Struct). It is a zero-sized type, but we prevent anyone from constructing one. Instead we magic up references to it, always ensuring that they have the same address as some Struct. The fields of Struct__Partial are also ZSTs that exist ony as references, and they Deref to the actual field (subject to compile-type borrow compatibility checking). Soundness and testing partial-borrow is primarily a nontrivial procedural macro which autogenerates reams of unsafe. Of course I think it's sound, but I thought that the last two times before I added a test which demonstrated otherwise. So it might be fairer to say that I have tried to make it sound and that I don't know of any problems... Reasoning about the correctness of macro-generated code is not so easy. One problem is that there is nowhere good to put the kind of soundness arguments you would normally add near uses of unsafe. I decided to solve this by annotating an instance of the macro output. There's a not very complicated script using diff3 to help fold in changes if the macro output changes - merge conflicts there mean a possible re-review of the argument text. Of course I also have test cases that run with miri, and test cases for expected compiler errors for uses that need to be forbidden for soundness. But this is quite hairy and I'm worried that it might be rather "my first insane unsafe contraption". Also the pointer/reference trickery is definitely subtle, and depends heavily on knowing what Rust's aliasing and pointer provenance rules really are. Stacked Borrows is not entirely trivial to reason about in fiddly corner cases. So for now I have only called it 0.1.0 and left a note in the docs. I haven't actually made Otter use it yet but that's the rather more boring software integration part, not the fun "can I do this mad thing" part so I will probably leave that for a rainy day. Possibly a rainy day after someone other than me has looked at partial-borrow (preferably someone who understands Stacked Borrows...). Fun! This was great fun. I even enjoyed writing the docs. The proc-macro programming environment is not entirely straightforward and there are a number of things to watch out for. For my first non-adhoc proc-macro this was, perhaps, ambitious. But you don't learn anything without trying...
edited 2021-09-02 16:28 UTC to fix a typo


comment count unavailable comments

30 August 2021

Andrew Cater: Oh, my goodness, where's the fantastic barbeque [OMGWTFBBQ 2021]

I'm guessing the last glasses will be through the dishwasher (again) and Pepper the dog can settle down without having to cope with so many people.For those who don't know - Steve and his wife Jo (Sledge and Randombird) hold a barbeque in their garden every August Bank Holiday weekend [UK Bank Holiday on the last Monday in August]. The barbeque is not small - it's the dominating feature in the suburban garden, brick built, with a dedication stone, lights, electricity. The garden is small, generally made smaller by forty or so Debian friends and allies standing and sitting around. People are talking, arguing, hugging people they've not seen for (literal) years and putting the world to rights. This is Debian central point - with large quantities of meat and salads, an amount of beer/alcohol and "Cambridge gin" and general goodwill. This year was more than usually atmospheric because for some of us it was the first time with a large group of people in a while. Side conversations abound: for me it was learning something about the high energy particle physics community, how to precision build helicopters, fly quadcopters and precision 3D print anything, the maths of Isy counting crochet stitches to sew together randomly sized squares ... and, of course, obligatory things like how random is random and what's good enough entropy. And a few sessions of the game of our leader.
This is also a place for stuff to get done: I was unashamedly using this to upgrade the storage in my laptop while there were sensible engineers around. A corner of the table, a RattusRattus and it was quickly sorted - then a discussion around the internals of Thinkpads as he took his apart. Then getting a full install - Gb Ethernet to the Debian mirror in the cupboard six feet away is faster bandwidth than a jumbo jet full of tapes. Then getting mail to work again - it's handy when the mailserver owner is next to you, having come in from the garden to help, and finally IRC. And not just me: "You need a GPG key signed - there's three DPLs here, there's a release manager - but you've just missed one of the DAMs." plus an in-depth GPG how-to session on the other side of the table.I was the luckiest one with the most comfortable bed in the house overnight but I couldn't stay for last night. Thanks once again to all involved but especially Steve and Jo who do this for the love of it, and the fun, and the community and the family. Oh, and thanks to Lenovo - not just for being a platinum sponsor of Debconf but also for providing the official laptop of this and most Debian occasions

28 August 2021

Anton Gladky: 2021/08, FLOSS activity

LTS This is my sixth month of working for LTS. I was assigned 12 hrs and worked all of them.

Released DLAs
  1. DLA 2742-1 ffmpeg_7:3.2.15-0+deb9u3
    • CVE-2020-22036: A heap-based Buffer Overflow vulnerability in filter_intra at libavfilter/vf_bwdif.c, which might lead to memory corruption and other potential consequences.
    • CVE-2020-22032: A heap-based Buffer Overflow vulnerability in gaussian_blur, which might lead to memory corruption and other potential consequences.
    • CVE-2020-22031: A Heap-based Buffer Overflow vulnerability in filter16_complex_low, which might lead to memory corruption and other potential consequences.
    • CVE-2020-22028: Buffer Overflow vulnerability in filter_vertically_8 at libavfilter/vf_avgblur.c, which could cause a remote Denial of Service.
    • CVE-2020-22026: Buffer Overflow vulnerability exists in the config_input function at libavfilter/af_tremolo.c, which could let a remote malicious user cause a Denial of Service.
    • CVE-2020-22025: A heap-based Buffer Overflow vulnerability exists in gaussian_blur at libavfilter/vf_edgedetect.c, which might lead to memory corruption and other potential consequences.
    • CVE-2020-22023: A heap-based Buffer Overflow vulnerabililty exists in filter_frame at libavfilter/vf_bitplanenoise.c, which might lead to memory corruption and other potential consequences.
    • CVE-2020-22022: A heap-based Buffer Overflow vulnerability exists in filter_frame at libavfilter/vf_fieldorder.c, which might lead to memory corruption and other potential consequences.
    • CVE-2020-22021: Buffer Overflow vulnerability at filter_edges function in libavfilter/vf_yadif.c, which could let a remote malicious user cause a Denial of Service.
    • CVE-2020-22020: Buffer Overflow vulnerability in the build_diff_map function in libavfilter/vf_fieldmatch.c, which could let a remote malicious user cause a Denial of Service.
    • CVE-2020-22016: A heap-based Buffer Overflow vulnerability at libavcodec/get_bits.h when writing .mov files, which might lead to memory corruption and other potential consequences.
    • CVE-2020-22015: Buffer Overflow vulnerability in mov_write_video_tag due to the out of bounds in libavformat/movenc.c, which could let a remote malicious user obtain sensitive information, cause a Denial of Service, or execute arbitrary code.
    • CVE-2020-21041: Buffer Overflow vulnerability exists via apng_do_inverse_blend in libavcodec/pngenc.c, which could let a remote malicious user cause a Denial of Service
    • CVE-2021-3566: The tty demuxer did not have a read_probe function assigned to it. By crafting a legitimate ffconcat file that references an image, followed by a file the triggers the tty demuxer, the contents of the second file will be copied into the output file verbatim (as long as the -vcodec copy option is passed to ffmpeg).
    • CVE-2021-38114: libavcodec/dnxhddec.c does not check the return value of the init_vlc function. Crafted DNxHD data can cause unspecified impact.
  2. DLA 2742-2 ffmpeg_7:3.2.15-0+deb9u4 During the backporting of one of patches in CVE-2020-22021 one line was wrongly interpreted and it caused the regression during the deinterlacing process. Thanks to Jari Ruusu for the reporting the issue and for the testing of prepared update.

LTS-Meeting
  • I attended the Debian LTS team Jitsi-meeting (though the connection was extremely bad).
  • Partly participated in preparation of Debconf21 BoF Funding Projects to Improve Debian .

Debian Science Team
  • Partly participated in Debconf21 Debian Science BoF.

Other FLOSS activities
  • Reviewed many merge requests in Yade open source project, merge some of them.

Andrew Cater: "If you do it twice, it's tradition" - says nattie

Thanks to all who've made Debconf 21 such a good place to be.

A song for Debconf21 ["What shall we do with the drunken sailor"]


What shall we do with the online Debconf?What shall we do with the online Debconf?What shall we do with the online Debconf?

Earl-y in the morning

Close it up as we agreed it

Save each script in case we need it

Work out how we best live-feed itNext year s Debconf s dawning

Next year s Kosovo and Pristina

This virtual Debconf needs no cleaner

Hope when COVID s gone we re keener

To meet up every morning


Thanks to the Debconf orga team

Thanks to those who Loopy meme

Things are not always as they seeem

In virtual Debconf s morning

Bullseye s out its share is rising

Debconf s fun and quite surprising

Linux 30 :)

Yours and my thing - Debian s 28

Thanks to all who video d sessions

Debconf T-shirts - prized possessions

Debcamp bug-fixed some regressions

Now onto next year!


A closing song for Debconf 21 [Frere Jacques/Brueder Martin]

DebConf21

Virtual DebConf s

Now all through

Closed for you

Kosovo is next year

See you in Pristina!!

DebConf 22

Twenty twenty-two

25 August 2021

Bits from Debian: DebConf21 welcomes its sponsors!

DebConf21 logo DebConf21 is taking place online, from 24 August to 28 August 2021. It is the 22nd Debian conference, and organizers and participants are working hard together at creating interesting and fruitful events. We would like to warmly welcome the 19 sponsors of DebConf21, and introduce them to you. We have five Platinum sponsors. Our first Platinum sponsor is Lenovo. As a global technology leader manufacturing a wide portfolio of connected products, including smartphones, tablets, PCs and workstations as well as AR/VR devices, smart home/office and data center solutions, Lenovo understands how critical open systems and platforms are to a connected world. Our next Platinum sponsor is Infomaniak. Infomaniak is Switzerland's largest web-hosting company, also offering backup and storage services, solutions for event organizers, live-streaming and video on demand services. It wholly owns its datacenters and all elements critical to the functioning of the services and products provided by the company (both software and hardware). Roche is our third Platinum sponsor. Roche is a major international pharmaceutical provider and research company dedicated to personalized healthcare. More than 100,000 employees worldwide work towards solving some of the greatest challenges for humanity using science and technology. Roche is strongly involved in publicly funded collaborative research projects with other industrial and academic partners and has supported DebConf since 2017. Amazon Web Services (AWS) is our fourth Platinum sponsor. Amazon Web Services is one of the world's most comprehensive and broadly adopted cloud platform, offering over 175 fully featured services from data centers globally (in 77 Availability Zones within 24 geographic regions). AWS customers include the fastest-growing startups, largest enterprises and leading government agencies. Google is our fifth Platinum sponsor. Google is one of the largest technology companies in the world, providing a wide range of Internet-related services and products such as online advertising technologies, search, cloud computing, software, and hardware. Google has been supporting Debian by sponsoring DebConf for more than ten years, and is also a Debian partner sponsoring parts of Salsa's continuous integration infrastructure within Google Cloud Platform. Our Gold sponsor is the Matanel Foundation. The Matanel Foundation operates in Israel, as its first concern is to preserve the cohesion of a society and a nation plagued by divisions. The Matanel Foundation also works in Europe, in Africa and in South America. Our Silver sponsors are: arm: the World s Best SoC Design Portfolio, Arm powered solutions have been supporting innovation for more than 30 years and are deployed in over 160 billion chips to date, Hudson-Trading, a company researching and developing automated trading algorithms using advanced mathematical techniques, Ubuntu the Operating System delivered by Canonical, Globo, the largest media conglomerate in Brazil, founded in Rio de Janeiro in 1925 and distributing high-quality content across multiple platforms, Two Sigma, rigorous inquiry, data analysis, and invention to help solve the toughest challenges across financial services and GitLab, an open source end-to-end software development platform with built-in version control, issue tracking, code review, CI/CD, and more. Bronze sponsors: Univention, Gandi.net, daskeyboard, InterFace AG and credativ. And finally, our Supporter level sponsor, ISG.EE. Thanks to all our sponsors for their support! Their contributions make it possible for a large number of Debian contributors from all over the globe to work together, help and learn from each other in DebConf21. Participating in DebConf21 online The 22nd Debian Conference is being held online, due to COVID-19, from August 24 to 28, 2021. Talks, discussions, panels and other activities run from 12:00 to 02:00 UTC. Visit the DebConf21 website at https://debconf21.debconf.org to learn about the complete schedule, watch the live streaming and join the different communication channels for participating in the conference.

Next.

Previous.