Search Results: "xam"

29 April 2023

Enrico Zini: Gtk4 model-backed radio button in Python

Gtk4 has interesting ways of splitting models and views. One that I didn't find very well documented, especially for Python bindings, is a set of radio buttons backed by a common model. The idea is to define an action that takes a string as a state. Each radio button is assigned a string matching one of the possible states, and when the state of the backend action is changed, the radio buttons are automatically updated. All the examples below use a string for a value type, but anything can be used that fits into a GLib.Variant. The model This defines the action. Note that enables all the usual declarative ways of a status change:
mode = Gio.SimpleAction.new_stateful(
        name="mode-selection",
        parameter_type=GLib.VariantType("s"),
        state=GLib.Variant.new_string(""))
gtk_app.add_action(self.mode)
The view
def add_radio(model: Gio.SimpleAction, id: str, label: str):
    button = Gtk.CheckButton(label=label)
    # Tell this button to activate when the model has the given value
    button.set_action_target_value(GLib.Variant.new_string(id))
    # Build the name under which the action is registesred, plus the state
    # value controlled by this button: clicking the button will set this state
    detailed_name = Gio.Action.print_detailed_name(
            "app." + model.get_name(),
            GLib.Variant.new_string(id))
    button.set_detailed_action_name(detailed_name)
    # If the model has no current value set, this sets the first radio button
    # as selected
    if not model.get_state().get_string():
        model.set_state(GLib.Variant.new_string(id))
Accessing the model To read the currently selected value:
current = model.get_state().get_string()
To set the currently selected value:
model.set_state(GLib.Variant.new_string(id))

Simon Josefsson: How To Trust A Machine

Let s reflect on some of my recent work that started with understanding Trisquel GNU/Linux, improving transparency into apt-archives, working on reproducible builds of Trisquel, strengthening verification of apt-archives with Sigstore, and finally thinking about security device threat models. A theme in all this is improving methods to have trust in machines, or generally any external entity. While I believe that everything starts by trusting something, usually something familiar and well-known, we need to deal with misuse of that trust that leads to failure to deliver what is desired and expected from the trusted entity. How can an entity behave to invite trust? Let s argue for some properties that can be quantitatively measured, with a focus on computer software and hardware: Essentially, this boils down to: Trust, Verify and Hold Accountable. To put this dogma in perspective, it helps to understand that this approach may be harmful to human relationships (which could explain the social awkwardness of hackers), but it remains useful as a method to improve the design of computer systems, and a useful method to evaluate safety of computer systems. When a system fails some of the criteria above, we know we have more work to do to improve it. How far have we come on this journey? Through earlier efforts, we are in a fairly good situation. Richard Stallman through GNU/FSF made us aware of the importance of free software, the Reproducible/Bootstrappable build projects made us aware of the importance of verifiability, and Certificate Transparency highlighted the need for accountable signature logs leading to efforts like Sigstore for software. None of these efforts would have seen the light of day unless people wrote free software and packaged them into distributions that we can use, and built hardware that we can run it on. While there certainly exists more work to be done on the software side, with the recent amazing full-source build of Guix based on a 357-byte hand-written seed, I believe that we are closing that loop on the software engineering side. So what remains? Some inspiration for further work: Onwards and upwards, happy hacking! Update 2023-05-03: Added the Liberating property regarding free software, instead of having it be part of the Verifiability and Transparency .

28 April 2023

Enrico Zini: Handling keyboard-like devices

CNC control panel and Bluetooth pedal page turner I acquired some unusual input devices to experiment with, like a CNC control panel and a bluetooth pedal page turner. These identify and behave like a keyboard, sending nice and simple keystrokes, and can be accessed with no drivers or other special software. However, their keystrokes appear together with keystrokes from normal keyboards, which is the expected default when plugging in a keyboard, but not what I want in this case. I'd also like them to be readable via evdev and accessible by my own user. Here's the udev rule I cooked up to handle this use case:
# Handle the CNC control panel
SUBSYSTEM=="input", ENV ID_VENDOR =="04d9", ENV ID_MODEL =="1203", \
   OWNER="enrico", ENV ID_INPUT =""
# Handle the Bluetooth page turner
SUBSYSTEM=="input", ENV ID_BUS =="bluetooth", ENV LIBINPUT_DEVICE_GROUP =="*/ mac ", ENV ID_INPUT_KEYBOARD ="1" \
   OWNER="enrico", ENV ID_INPUT ="", SYMLINK+="input/by-id/bluetooth- mac -kbd"
SUBSYSTEM=="input", ENV ID_BUS =="bluetooth", ENV LIBINPUT_DEVICE_GROUP =="*/ mac ", ENV ID_INPUT_TABLET ="1" \
   OWNER="enrico", ENV ID_INPUT ="", SYMLINK+="input/by-id/bluetooth- mac -tablet"
The bluetooth device didn't have standard rules to create /dev/input/by-id/ symlinks so I added them. In my own code, I watch /dev/input/by-id with inotify to handle when devices appear or disappear. I used udevadm info /dev/input/event to see what I could use to identify the device. The Static device configuration via udev page of libinput's documentation has documentation on the various elements specific to the input subsystem Grepping rule files in /usr/lib/udev/rules.d was useful to see syntax examples. udevadm test /dev/input/event was invaluable for syntax checking and testing my rule file while working on it. Finally, this is an extract of a quick prototype Python code to read keys from the CNC control panel:
import libevdev
KEY_MAP =  
    libevdev.EV_KEY.KEY_GRAVE: "EMERGENCY",
    # InputEvent(EV_KEY, KEY_LEFTALT, 1)
    libevdev.EV_KEY.KEY_R: "CYCLE START",
    libevdev.EV_KEY.KEY_F5: "SPINDLE ON/OFF",
    # InputEvent(EV_KEY, KEY_RIGHTCTRL, 1)
    libevdev.EV_KEY.KEY_W: "REDO",
    # InputEvent(EV_KEY, KEY_LEFTALT, 1)
    libevdev.EV_KEY.KEY_N: "SINGLE STEP",
    # InputEvent(EV_KEY, KEY_LEFTCTRL, 1)
    libevdev.EV_KEY.KEY_O: "ORIGIN POINT",
    libevdev.EV_KEY.KEY_ESC: "STOP",
    libevdev.EV_KEY.KEY_KPPLUS: "SPEED UP",
    libevdev.EV_KEY.KEY_KPMINUS: "SLOW DOWN",
    libevdev.EV_KEY.KEY_F11: "F+",
    libevdev.EV_KEY.KEY_F10: "F-",
    libevdev.EV_KEY.KEY_RIGHTBRACE: "J+",
    libevdev.EV_KEY.KEY_LEFTBRACE: "J-",
    libevdev.EV_KEY.KEY_UP: "+Y",
    libevdev.EV_KEY.KEY_DOWN: "-Y",
    libevdev.EV_KEY.KEY_LEFT: "-X",
    libevdev.EV_KEY.KEY_RIGHT: "+X",
    libevdev.EV_KEY.KEY_KP7: "+A",
    libevdev.EV_KEY.KEY_Q: "-A",
    libevdev.EV_KEY.KEY_PAGEDOWN: "-Z",
    libevdev.EV_KEY.KEY_PAGEUP: "+Z",
 
class KeyReader:
    def __init__(self, path: str):
        self.path = path
        self.fd: IO[bytes]   None = None
        self.device: libevdev.Device   None = None
    def __enter__(self):
        self.fd = open(self.path, "rb")
        self.device = libevdev.Device(self.fd)
        return self
    def __exit__(self, exc_type, exc, tb):
        self.device = None
        self.fd.close()
        self.fd = None
    def events(self) -> Iterator[dict[str, Any]]:
        for e in self.device.events():
            if e.type == libevdev.EV_KEY:
                if (val := KEY_MAP.get(e.code)):
                    yield  
                        "name": val,
                        "value": e.value,
                        "sec": e.sec,
                        "usec": e.usec,
                     
Edited: added rules to handle the Bluetooth page turner

Shirish Agarwal: John Grisham s books, Evolution removed from textbooks

Gray Mountain John Grisham I have been perusing John Grisham s books, some read and some re-read again. Almost all of the books that Mr. Grisham wrote are relevant even today. The Gray Mountain talks about how mountain top removal was done in Applachia, the U.S. (South). In fact NASA made a summary which either was borrowed from this book or the author borrowed from NASA, either could be true although seems it might be the former. And this is when GOI just made a new Forest Conservation Bill 2023 which does the opposite. There are many examples of the same, the latest from my own city as an e.g. Vetal Tekdi is and was a haven for people animals, birds all kinds of ecosystem and is a vital lung of the city, one of the few remaining green spaces in the city but BJP wants to commercialize it as it has been doing for everything, I haven t been to the Himalayas since 4-5 years back as I hear the rape of the land daily. Even after Joshimath tragedy, if people are not opening the eyes what can I do  The more I say, the more depressed I will become so will leave it for now. In many ways the destruction seems similar to the destruction that happened in Brazil under Jair Bolsonaro. So as can be seen from what I have shared this book was mostly about environment and punitive damages and also how punitive damages have been ceiling in America (South). This was done via lobbying by the coal groups and apparently destroyed people s lives, communities, even whole villages. It also shared how most people called black lung and how those claims had been denied by Coal Companies all the time. And there are hardly any unions. While the book itself is a fiction piece, there is a large amount of truth in it. And that is one of the reasons people write a fiction book. You could write about reality using fictional names and nobody can sue you while you set the reality as it is. In many ways, it is a tell-all.

The Testament John Grisham One of the things I have loved about John Grisham is he understands human condition. In this book it starts with an eccentric billionaire who makes a will which leaves all his property to an illegitimate child who coincidentally also lives in Brazil, she is a missionary. The whole book is about human failings as well as about finding the heir. I am not going to give much detail as the book itself is fun.

The Appeal John Grisham In this, we are introduced to a company that does a chemical spill for decades and how that leads to lobbying and funding Judicial elections. It does go into quite a bit of length how private money coming from Big business does all kind of shady things to get their person elected to the Supreme Court. Sadly, this seems to happen all the time, for e.g. two weeks ago. This piece from the Atlantic also says the same. Again, won t tell as there is a bit of irony at the end of the book.

The Rainmaker John Grisham This in short is about how Insurance Companies stiff people. It s a wonderful story that has all people in grey including our hero. An engaging book that sorta tells how the Insurance Industry plays the game. In India, the companies are safe as they ask for continuance for years together and their object is to delay the hearings till the grandchildren are not alive unlike in the U.S. or UK. It also does tell how more lawyers are there then required. Both of which are the same in my country.

The Litigators John Grisham This one is about Product Liability, both medicines as well as toys for young kids. What I do find funny a bit is how the law in States allows people to file cases but doesn t protect people while in EU they try their best that if there is any controversy behind any medicine or product, they will simply ban it. Huge difference between the two cultures.

Evolution no longer part of Indian Education A few days ago, NCERT (one of the major bodies) that looks into Indian Education due to BJP influence has removed Darwin s Theory of Evolution. You can t even debate because the people do not understand adaptability. So the only conclusion is that Man suddenly appeared out of nowhere. If that is so, then we are the true aliens. They discard the notion that we and Chimpanzees are similar. Then they also have to discard this finding that genetically we are 96% similar.

27 April 2023

Simon Josefsson: A Security Device Threat Model: The Substitution Attack

I d like to describe and discuss a threat model for computational devices. This is generic but we will narrow it down to security-related devices. For example, portable hardware dongles used for OpenPGP/OpenSSH keys, FIDO/U2F, OATH HOTP/TOTP, PIV, payment cards, wallets etc and more permanently attached devices like a Hardware Security Module (HSM), a TPM-chip, or the hybrid variant of a mostly permanently-inserted but removable hardware security dongles. Our context is cryptographic hardware engineering, and the purpose of the threat model is to serve as as a thought experiment for how to build and design security devices that offer better protection. The threat model is related to the Evil maid attack. Our focus is to improve security for the end-user rather than the traditional focus to improve security for the organization that provides the token to the end-user, or to improve security for the site that the end-user is authenticating to. This is a critical but often under-appreciated distinction, and leads to surprising recommendations related to onboard key generation, randomness etc below.

The Substitution Attack
An attacker is able to substitute any component of the device (hardware or software) at any time for any period of time.
Your takeaway should be that devices should be designed to mitigate harmful consequences if any component of the device (hardware or software) is substituted for a malicious component for some period of time, at any time, during the lifespan of that component. Some designs protect better against this attack than other designs, and the threat model can be used to understand which designs are really bad, and which are less so.

Terminology The threat model involves at least one device that is well-behaving and one that is not, and we call these Good Device and Bad Device respectively. The bad device may be the same physical device as the good key, but with some minor software modification or a minor component replaced, but could also be a completely separate physical device. We don t care about that distinction, we just care if a particular device has a malicious component in it or not. I ll use terms like security device , device , hardware key , security co-processor etc interchangeably. From an engineering point of view, malicious here includes unintentional behavior such as software or hardware bugs. It is not possible to differentiate an intentionally malicious device from a well-designed device with a critical bug. Don t attribute to malice what can be adequately explained by stupidity, but don t na vely attribute to stupidity what may be deniable malicious.

What is some period of time ? Some period of time can be any length of time: seconds, minutes, days, weeks, etc. It may also occur at any time: During manufacturing, during transportation to the user, after first usage by the user, or after a couple of months usage by the user. Note that we intentionally consider time-of-manufacturing as a vulnerable phase. Even further, the substitution may occur multiple times. So the Good Key may be replaced with a Bad Key by the attacker for one day, then returned, and later this repeats a month later.

What is harmful consequences ? Since a security key has a fairly well-confined scope and purpose, we can get a fairly good exhaustive list of things that could go wrong. Harmful consequences include:
  • Attacker learns any secret keys stored on a Good Key.
  • Attacker causes user to trust a public generated by a Bad Key.
  • Attacker is able to sign something using a Good Key.
  • Attacker learns the PIN code used to unlock a Good Key.
  • Attacker learns data that is decrypted by a Good Key.

Thin vs Deep solutions One approach to mitigate many issues arising from device substitution is to have the host (or remote site) require that the device prove that it is the intended unique device before it continues to talk to it. This require an authentication/authorization protocol, which usually involves unique device identity and out-of-band trust anchors. Such trust anchors is often problematic, since a common use-case for security device is to connect it to a host that has never seen the device before. A weaker approach is to have the device prove that it merely belongs to a class of genuine devices from a trusted manufacturer, usually by providing a signature generated by a device-specific private key signed by the device manufacturer. This is weaker since then the user cannot differentiate two different good devices. In both cases, the host (or remote site) would stop talking to the device if it cannot prove that it is the intended key, or at least belongs to a class of known trusted genuine devices. Upon scrutiny, this solution is still vulnerable to a substitution attack, just earlier in the manufacturing chain: how can the process that injects the per-device or per-class identities/secrets know that it is putting them into a good key rather than a malicious device? Consider also the consequences if the cryptographic keys that guarantee that a device is genuine leaks. The model of the thin solution is similar to the old approach to network firewalls: have a filtering firewall that only lets through intended traffic, and then run completely insecure protocols internally such as telnet. The networking world has evolved, and now we have defense in depth: even within strongly firewall ed networks, it is prudent to run for example SSH with publickey-based user authentication even on locally physical trusted networks. This approach requires more thought and adds complexity, since each level has to provide some security checking. I m arguing we need similar defense-in-depth for security devices. Security key designs cannot simply dodge this problem by assuming it is working in a friendly environment where component substitution never occur.

Example: Device authentication using PIN codes To see how this threat model can be applied to reason about security key designs, let s consider a common design. Many security keys uses PIN codes to unlock private key operations, for example on OpenPGP cards that lacks built-in PIN-entry functionality. The software on the computer just sends a PIN code to the device, and the device allows private-key operations if the PIN code was correct. Let s apply the substitution threat model to this design: the attacker replaces the intended good key with a malicious device that saves a copy of the PIN code presented to it, and then gives out error messages. Once the user has entered the PIN code and gotten an error message, presumably temporarily giving up and doing other things, the attacker replaces the device back again. The attacker has learnt the PIN code, and can later use this to perform private-key operations on the good device. This means a good design involves not sending PIN codes in clear, but use a stronger authentication protocol that allows the card to know that the PIN was correct without learning the PIN. This is implemented optionally for many OpenPGP cards today as the key-derivation-function extension. That should be mandatory, and users should not use setups that sends device authentication in the clear, and ultimately security devices should not even include support for that. Compare how I build Gnuk on my PGP card with the kdf_do=required option.

Example: Onboard non-predictable key-generation Many devices offer both onboard key-generation, for example OpenPGP cards that generate a Ed25519 key internally on the devices, or externally where the device imports an externally generated cryptographic key. Let s apply the subsitution threat model to this design: the user wishes to generate a key and trust the public key that came out of that process. The attacker substitutes the device for a malicious device during key-generation, imports the private key into a good device and gives that back to the user. Most of the time except during key generation the user uses a good device but still the attacker succeeded in having the user trust a public key which the attacker knows the private key for. The substitution may be a software modification, and the method to leak the private key to the attacker may be out-of-band signalling. This means a good design never generates key on-board, but imports them from a user-controllable environment. That approach should be mandatory, and users should not use setups that generates private keys on-board, and ultimately security devices should not even include support for that.

Example: Non-predictable randomness-generation Many devices claims to generate random data, often with elaborate design documents explaining how good the randomness is. Let s apply the substitution threat model to this design: the attacker replaces the intended good key with a malicious design that generates (for the attacker) predictable randomness. The user will never be able to detect the difference since the random output is, well, random, and typically not distinguishable from weak randomness. The user cannot know if any cryptographic keys generated by a generator was faulty or not. This means a good design never generates non-predictable randomness on the device. That approach should be mandatory, and users should not use setups that generates non-predictable randomness on the device, and ideally devices should not have this functionality.

Case-Study: Tillitis I have warmed up a bit for this. Tillitis is a new security device with interesting properties, and core to its operation is the Compound Device Identifier (CDI), essentially your Ed25519 private key (used for SSH etc) is derived from the CDI that is computed like this:
cdi = blake2s(UDS, blake2s(device_app), USS)
Let s apply the substitution threat model to this design: Consider someone replacing the Tillitis key with a malicious key during postal delivery of the key to the user, and the replacement device is identical with the real Tillitis key but implements the following key derivation function:
cdi = weakprng(UDS , weakprng(device_app), USS)
Where weakprng is a compromised algorithm that is predictable for the attacker, but still appears random. Everything will work correctly, but the attacker will be able to learn the secrets used by the user, and the user will typically not be able to tell the difference since the CDI is secret and the Ed25519 public key is not self-verifiable.

Conclusion Remember that it is impossible to fully protect against this attack, that s why it is merely a thought experiment, intended to be used during design of these devices. Consider an attacker that never gives you access to a good key and as a user you only ever use a malicious device. There is no way to have good security in this situation. This is not hypothetical, many well-funded organizations do what they can to derive people from having access to trustworthy security devices. Philosophically it does not seem possible to tell if these organizations have succeeded 100% already and there are only bad security devices around where further resistance is futile, but to end on an optimistic note let s assume that there is a non-negligible chance that they haven t succeeded. In these situations, this threat model becomes useful to improve the situation by identifying less good designs, and that s why the design mantra of mitigate harmful consequences is crucial as a takeaway from this. Let s improve the design of security devices that further the security of its users!

Arturo Borrero Gonz lez: Kubecon and CloudNativeCon 2023 Europe summary

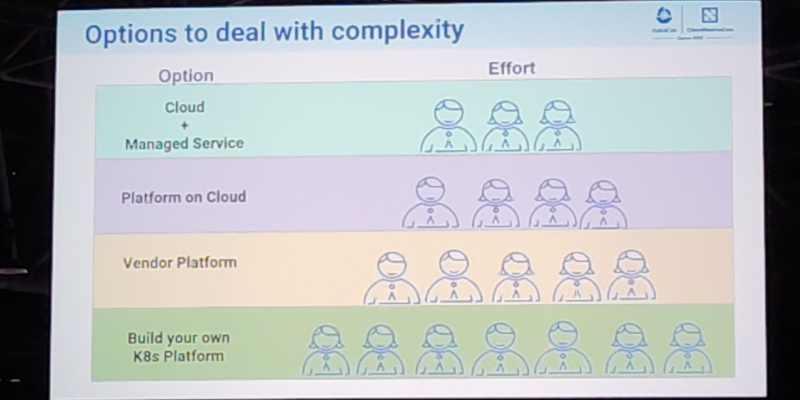
Post logo This post serves as a report from my attendance to Kubecon and CloudNativeCon 2023 Europe that took place in Amsterdam in April 2023. It was my second time physically attending this conference, the first one was in Austin, Texas (USA) in 2017. I also attended once in a virtual fashion. The content here is mostly generated for the sake of my own recollection and learnings, and is written from the notes I took during the event. The very first session was the opening keynote, which reunited the whole crowd to bootstrap the event and share the excitement about the days ahead. Some astonishing numbers were announced: there were more than 10.000 people attending, and apparently it could confidently be said that it was the largest open source technology conference taking place in Europe in recent times. It was also communicated that the next couple iteration of the event will be run in China in September 2023 and Paris in March 2024. More numbers, the CNCF was hosting about 159 projects, involving 1300 maintainers and about 200.000 contributors. The cloud-native community is ever-increasing, and there seems to be a strong trend in the industry for cloud-native technology adoption and all-things related to PaaS and IaaS. The event program had different tracks, and in each one there was an interesting mix of low-level and higher level talks for a variety of audience. On many occasions I found that reading the talk title alone was not enough to know in advance if a talk was a 101 kind of thing or for experienced engineers. But unlike in previous editions, I didn t have the feeling that the purpose of the conference was to try selling me anything. Obviously, speakers would make sure to mention, or highlight in a subtle way, the involvement of a given company in a given solution or piece of the ecosystem. But it was non-invasive and fair enough for me. On a different note, I found the breakout rooms to be often small. I think there were only a couple of rooms that could accommodate more than 500 people, which is a fairly small allowance for 10k attendees. I realized with frustration that the more interesting talks were immediately fully booked, with people waiting in line some 45 minutes before the session time. Because of this, I missed a few important sessions that I ll hopefully watch online later. Finally, on a more technical side, I ve learned many things, that instead of grouping by session I ll group by topic, given how some subjects were mentioned in several talks. On gitops and CI/CD pipelines Most of the mentions went to FluxCD and ArgoCD. At that point there were no doubts that gitops was a mature approach and both flux and argoCD could do an excellent job. ArgoCD seemed a bit more over-engineered to be a more general purpose CD pipeline, and flux felt a bit more tailored for simpler gitops setups. I discovered that both have nice web user interfaces that I wasn t previously familiar with. However, in two different talks I got the impression that the initial setup of them was simple, but migrating your current workflow to gitops could result in a bumpy ride. This is, the challenge is not deploying flux/argo itself, but moving everything into a state that both humans and flux/argo can understand. I also saw some curious mentions to the config drifts that can happen in some cases, even if the goal of gitops is precisely for that to never happen. Such mentions were usually accompanied by some hints on how to operate the situation by hand. Worth mentioning, I missed any practical information about one of the key pieces to this whole gitops story: building container images. Most of the showcased scenarios were using pre-built container images, so in that sense they were simple. Building and pushing to an image registry is one of the two key points we would need to solve in Toolforge Kubernetes if adopting gitops. In general, even if gitops were already in our radar for Toolforge Kubernetes, I think it climbed a few steps in my priority list after the conference. Another learning was this site: https://opengitops.dev/. Group On etcd, performance and resource management I attended a talk focused on etcd performance tuning that was very encouraging. They were basically talking about the exact same problems we have had in Toolforge Kubernetes, like api-server and etcd failure modes, and how sensitive etcd is to disk latency, IO pressure and network throughput. Even though Toolforge Kubernetes scale is small compared to other Kubernetes deployments out there, I found it very interesting to see other s approaches to the same set of challenges. I learned how most Kubernetes components and apps can overload the api-server. Because even the api-server talks to itself. Simple things like kubectl may have a completely different impact on the API depending on usage, for example when listing the whole list of objects (very expensive) vs a single object. The conclusion was to try avoiding hitting the api-server with LIST calls, and use ResourceVersion which avoids full-dumps from etcd (which, by the way, is the default when using bare kubectl get calls). I already knew some of this, and for example the jobs-framework-emailer was already making use of this ResourceVersion functionality. There have been a lot of improvements in the performance side of Kubernetes in recent times, or more specifically, in how resources are managed and used by the system. I saw a review of resource management from the perspective of the container runtime and kubelet, and plans to support fancy things like topology-aware scheduling decisions and dynamic resource claims (changing the pod resource claims without re-defining/re-starting the pods). On cluster management, bootstrapping and multi-tenancy I attended a couple of talks that mentioned kubeadm, and one in particular was from the maintainers themselves. This was of interest to me because as of today we use it for Toolforge. They shared all the latest developments and improvements, and the plans and roadmap for the future, with a special mention to something they called kubeadm operator , apparently capable of auto-upgrading the cluster, auto-renewing certificates and such. I also saw a comparison between the different cluster bootstrappers, which to me confirmed that kubeadm was the best, from the point of view of being a well established and well-known workflow, plus having a very active contributor base. The kubeadm developers invited the audience to submit feature requests, so I did. The different talks confirmed that the basic unit for multi-tenancy in kubernetes is the namespace. Any serious multi-tenant usage should leverage this. There were some ongoing conversations, in official sessions and in the hallway, about the right tool to implement K8s-whitin-K8s, and vcluster was mentioned enough times for me to be convinced it was the right candidate. This was despite of my impression that multiclusters / multicloud are regarded as hard topics in the general community. I definitely would like to play with it sometime down the road. On networking I attended a couple of basic sessions that served really well to understand how Kubernetes instrumented the network to achieve its goal. The conference program had sessions to cover topics ranging from network debugging recommendations, CNI implementations, to IPv6 support. Also, one of the keynote sessions had a reference to how kube-proxy is not able to perform NAT for SIP connections, which is interesting because I believe Netfilter Conntrack could do it if properly configured. One of the conclusions on the CNI front was that Calico has a massive community adoption (in Netfilter mode), which is reassuring, especially considering it is the one we use for Toolforge Kubernetes. Slide On jobs I attended a couple of talks that were related to HPC/grid-like usages of Kubernetes. I was truly impressed by some folks out there who were using Kubernetes Jobs on massive scales, such as to train machine learning models and other fancy AI projects. It is acknowledged in the community that the early implementation of things like Jobs and CronJobs had some limitations that are now gone, or at least greatly improved. Some new functionalities have been added as well. Indexed Jobs, for example, enables each Job to have a number (index) and process a chunk of a larger batch of data based on that index. It would allow for full grid-like features like sequential (or again, indexed) processing, coordination between Job and more graceful Job restarts. My first reaction was: Is that something we would like to enable in Toolforge Jobs Framework? On policy and security A surprisingly good amount of sessions covered interesting topics related to policy and security. It was nice to learn two realities:
  1. kubernetes is capable of doing pretty much anything security-wise and create greatly secured environments.
  2. it does not by default. The defaults are not security-strict on purpose.
It kind of made sense to me: Kubernetes was used for a wide range of use cases, and developers didn t know beforehand to which particular setup they should accommodate the default security levels. One session in particular covered the most basic security features that should be enabled for any Kubernetes system that would get exposed to random end users. In my opinion, the Toolforge Kubernetes setup was already doing a good job in that regard. To my joy, some sessions referred to the Pod Security Admission mechanism, which is one of the key security features we re about to adopt (when migrating away from Pod Security Policy). I also learned a bit more about Secret resources, their current implementation and how to leverage a combo of CSI and RBAC for a more secure usage of external secrets. Finally, one of the major takeaways from the conference was learning about kyverno and kubeaudit. I was previously aware of the OPA Gatekeeper. From the several demos I saw, it was to me that kyverno should help us make Toolforge Kubernetes more sustainable by replacing all of our custom admission controllers with it. I already opened a ticket to track this idea, which I ll be proposing to my team soon. Final notes In general, I believe I learned many things, and perhaps even more importantly I re-learned some stuff I had forgotten because of lack of daily exposure. I m really happy that the cloud native way of thinking was reinforced in me, which I still need because most of my muscle memory to approach systems architecture and engineering is from the old pre-cloud days. List of sessions I attended on the first day: List of sessions I attended on the second day: List of sessions I attended on third day: The videos have been published on Youtube.

24 April 2023

Jonathan Dowland: Separate hledgers

In a previous blog post I described the use of virtual postings to track accidental personal/family expenses. I've always been uncomfortable with that, and in hledger 1yr I outlined a potential scheme for finally addressing the virtual posting problem. separate journals My outline built on top of continuing to maintain both personal and family financial data in the same place, but I've decided that this can't work, because the different "directions" (or signs) of accidental transactions originating from either the family or personal side can't be addressed with any kind of alternate view on the same data. To illustrate with an example. A negative balance in family:liabilities:jon means "family owes jon". A coffee bought by mistake on the family credit card will have a negative posting on the credit card, and thus a positive one on the liabilities account. ("jon owes family"). That's fine. But what about when I buy family stuff on a personal card? The other side of of the transaction is also going to have a positive sign, so it can't be posted to family:liabilities:jon: it would have to go to somewhere else, like jon:liabilities:family. Now I have two accounts which track versions of the same thing, and they cannot be combined with a simple transaction since they're looking at the same value from opposite directions (and signs). Back when I first described the problem I was using a single journal file for all my transactions. After moving to lots of separate journal files (in hledger 1yr), it's become clearer to me that I don't need to maintain the Family and Personal data together, at all: they can be entirely separate journals. getting data between journals When I moved to a new set of ledger files for 2023, I needed to carry forward the balances from 2022 in the form of "opening balance" transactions. This was achieved by a report on the 2022 data, exported as CSV, and imported into the 2023 data (all following the scheme outlined by fully-fledged hledger.)) Separate Personal and Family journals need some information from each other, and I can achieve that in the same way as for opening balances: with an export of the relevant transactions as CSV, then imported on the other side. HLedger's CSV import system is flexible enough that we can effectively invert the sign of liabilities, addressing the problem above. Worked example We start with an accidental coffee purchased on the family card (and so this belongs to the Family ledger)
2022-08-20 coffee
    liabilities:creditcard             -3
    liabilities:jon:expenses:coffee     3
I've encoded the expense category that the Personal ledger will be interested in (the last bit, expenses:coffee) as a sub-account of the liabilities category that the Family ledger is interested in1 (the first bit, liabilities:jon). When viewed on the Family side, the expense category is not interesting, and we can hide it with HLedger's alias feature2:
    alias /^liabilities:jon(.*)$/ = liabilities:jon
It then looks like this from the Family side:
2022-08-20 coffee
    liabilities:creditcard             -3
    liabilities:jon                     3
This transaction (and others like it) are exported via
hledger reg -f family/2023-back.journal liabilities:jon: -O csv \
        jon/import/family/liabilities.csv
(The trailing colon on liabilities:jon: is important here!) In the resulting CSV file, the running example transaction looks like
"55","2022-08-20","","coffee","liabilities:jon:expenses:coffee","  3.00","  3.00"
This is then converted into a journal file by hledger import. The rules file for the import is very simple: the fields date, description, account1 and amount are taken as-is; account2 is hard-coded to liabilities:family. The resulting transaction looks like
2022-08-20 coffee
    liabilities:jon:expenses:coffee     3
    liabilities:family                 -3
Before this journal is included by the main one, we have to adjust the expense account, to remove the liabilities:jon: prefix. The import rules can't do this3 , so we use another journal file as a go-between with another alias rule:
    alias /^liabilities.jon:/ =
This results, finally, in the following transaction in the Personal ledger:
2022-08-20 coffee
    expenses:coffee                     3
    liabilities:family                 -3
avoiding double-counting There's one set of transactions that we don't want to export across this divide, and that's because they're already there: any time I transfer money from myself to the family accounts (or vice versa) to address the accrued debt, the transaction is visible from both my family and personal statements. To avoid exporting these and double-counting them, I make sure those transactions don't post to an account matching the pattern used in the hledger reg report. That's what the trailing colon is for: It ensures I only export transactions which are to a sub-account of liabilities:jon, and not to the root account liabilities:jon itself: which is where I put the repayment transactions. I could instead use a more explicit sub-account like liabilities:jon:repayments or similar, since the trailing colon is quite subtle, but this works for me. Wrap up I've been really on the fence as to whether the complexity of this scheme is worth it to avoid the virtual postings. The previous scheme was much simpler. I have definitely made some mistakes with it, which didn't get caught by the double-entry rules that virtual postings ignore, but they're for small sums of money anyway. On the other hand, a lot of the "machinery" of this already existed for getting opening balances between calendar years, and the gory details are written down and hidden inside the Makefile. I also expect that I will continue to see advantages in having Family and Personal entirely separate, as they can each develop and adapt to their own needs without having to consider the other side of things every time. It's a running experiment, and time will tell if it's a good idea.

  1. This scheme was originally suggested to me by Pranesh on Twitter (described in dues), but I discounted it at the time because of the exact arrangement they suggested, not realising the broader idea might work.
  2. I've hand-waved one problem with using hledger aliases here. If we use them as described, to hide the Personal expense details, we need them to not be applied when performing the CSV-generating report. Therefore, in practise I have them in a front-most family/2023.journal file, which imports the data from another family/2023-back.journal, and the CSV export is performed on the backing journal with the data and not the alias.
  3. HLedger import rules can't manipulate the fields from the CSV a great deal, but one change I proposed and started hacking on would allow for this: to expose Regexp match-groups as interpolatable tokens: https://github.com/simonmichael/hledger/issues/2009.

21 April 2023

Steve Kemp: Managing header-spacing in markdown/org-mode files

It seems I'm having a theme recently on this blog, of making emacs-related posts. Here's another. I write a bunch of stuff in markdown, such as my emacs init-file, blog-posts and other documents. I try to be quite consistent about vertical spacing, for example a post might look like this:
# header1
Some top-level stuff.
## header2
Some more details.
## header2
Some more things on a related topic.
# header2
Here I'm trying to breakup sections, so there is a "big gap" between H1 and smaller gaps between the lesser-level headings. After going over my init file recently, making some changes, I noticed that the spacing was not at all consistent. So I figured "How hard could it be to recognize headers and insert/remove newlines before them?" A trivial regexp search for "^#" identifies headers, and that counting the "#" characters lets you determine their depth. From their removing any previous newlines is the work of a moment, and inserting the appropriate number to ensure consistency is simple. I spent 15 minutes writing the initial implementation, which was markdown-specific, then another 30 minutes adding support for org-mode files - because my work-diary is written using the org-diary package (along with other helpers, such as the org-tag-cloud. Anyway the end result is that now when I save a markdown/org file the headers are updated automatically:

20 April 2023

Dirk Eddelbuettel: qlcal 0.0.5 on CRAN: Updates from QuantLib 1.3.0

The fifth release of the still new-ish qlcal package arrivied at CRAN just now. qlcal delivers the calendaring parts of QuantLib. It is provided (for the R package) as a set of included files, so the package is self-contained and does not depend on an external QuantLib library (which can be demanding to build). qlcal covers over sixty country / market calendars and can compute holiday lists, its complement (i.e. business day lists) and much more. This release brings updates to five calendars from the QuantLib 1.30 release from this week.

Changes in version 0.0.5 (2023-04-19)
  • Calendars routines for Australia, Denmark, New Zealand, Turkey and the US have been updated from QuantLib 1.30.
  • Support for 'Australia/ASX' has been added.
  • Added demo showing all US holidays in current year

We also added a quick little demo using xts to column-bind calendars produced from each of the different US sub-calendars. This is a slightly updated version of the sketch we tooted a few days ago. The output now is
> print(Reduce(cbind, Map(makeHol, cals)))
           LiborImpact NYSE GovernmentBond NERC FederalReserve
2023-01-02        TRUE TRUE           TRUE TRUE           TRUE
2023-01-16        TRUE TRUE           TRUE   NA           TRUE
2023-02-20        TRUE TRUE           TRUE   NA           TRUE
2023-04-07          NA TRUE             NA   NA             NA
2023-05-29        TRUE TRUE           TRUE TRUE           TRUE
2023-06-19        TRUE TRUE           TRUE   NA           TRUE
2023-07-04        TRUE TRUE           TRUE TRUE           TRUE
2023-09-04        TRUE TRUE           TRUE TRUE           TRUE
2023-10-09        TRUE   NA           TRUE   NA           TRUE
2023-11-10        TRUE   NA             NA   NA             NA
2023-11-23        TRUE TRUE           TRUE TRUE           TRUE
2023-12-25        TRUE TRUE           TRUE TRUE           TRUE
> 
(and we just discovered a tiny h -> hols bug in the demo so see the git repo sorry!). The release was finalized uploaded yesterday morning. But because we have to set CXX_STD=CXX14 as satisfy requirements of some of the Boost headers, we get ourselves a NOTE and with that a manual inspection and a delay of 1 1/2 days. Not really all that meaningful in the grand scheme of things but still suboptimal relative to the fully automated passage this release should have gotten. Oh well. Courtesy of my CRANberries, there is a diffstat report for this release. See the project page and package documentation for more details, and more examples. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Simon Josefsson: Sigstore for Apt Archives: apt-cosign

As suggested in my initial announcement of apt-sigstore my plan was to look into stronger uses of Sigstore than rekor, and I m now happy to announce that the apt-cosign plugin has been added to apt-sigstore and the operational project debdistcanary is publishing cosign-statements about the InRelease file published by the following distributions: Trisquel GNU/Linux, PureOS, Gnuinos, Ubuntu, Debian and Devuan. Summarizing the commands that you need to run as root to experience the great new world:
# run everything as root: su / sudo -i / doas -s
apt-get install -y apt gpg bsdutils wget
wget -nv -O/usr/local/bin/apt-verify-gpgv https://gitlab.com/debdistutils/apt-verify/-/raw/main/apt-verify-gpgv
chmod +x /usr/local/bin/apt-verify-gpgv
mkdir -p /etc/apt/verify.d
ln -s /usr/bin/gpgv /etc/apt/verify.d
echo 'APT::Key::gpgvcommand "apt-verify-gpgv";' > /etc/apt/apt.conf.d/75verify
wget -O/usr/local/bin/cosign https://github.com/sigstore/cosign/releases/download/v2.0.1/cosign-linux-amd64
echo 924754b2e62f25683e3e74f90aa5e166944a0f0cf75b4196ee76cb2f487dd980  /usr/local/bin/cosign   sha256sum -c
chmod +x /usr/local/bin/cosign
wget -nv -O/etc/apt/verify.d/apt-cosign https://gitlab.com/debdistutils/apt-sigstore/-/raw/main/apt-cosign
chmod +x /etc/apt/verify.d/apt-cosign
mkdir -p /etc/apt/trusted.cosign.d
dist=$(lsb_release --short --id   tr A-Z a-z)
wget -O/etc/apt/trusted.cosign.d/cosign-public-key-$dist.txt "https://gitlab.com/debdistutils/debdistcanary/-/raw/main/cosign/cosign-public-key-$dist.txt"
echo "Cosign::Base-URL \"https://gitlab.com/debdistutils/canary/$dist/-/raw/main/cosign\";" > /etc/apt/apt.conf.d/77cosign
Then run your usual apt-get update and look in the syslog to debug things. This is the kind of work that gets done while waiting for the build machines to attempt to reproducibly build PureOS. Unfortunately, the results is that a meager 16% of the 765 added/modifed packages are reproducible by me. There is some infrastructure work to be done to improve things: we should use sbuild for example. The build infrastructure should produce signed statements for each package it builds: One statement saying that it attempted to reproducible build a particular binary package (thus generated some build logs and diffoscope-output for auditing), and one statements saying that it actually was able to reproduce a package. Verifying such claims during apt-get install or possibly dpkg -i is a logical next step. There is some code cleanups and release work to be done now. Which distribution will be the first apt-based distribution that includes native support for Sigstore? Let s see. Sigstore is not the only relevant transparency log around, and I ve been trying to learn a bit about Sigsum to be able to support it as well. The more improved confidence about system security, the merrier!

Dima Kogan: =numpy.percentile= API update

The numpy devs did a bad thing. Don't be like the numpy devs. The current (version 1.24) docs for numpy.percentile say this about the method keyword argument:
Changed in version 1.22.0: This argument was previously called "interpolation" ...
They renamed a keyword argument. So if you had working code that did
np.percentile( ...., interpolation=xxx, ....)
then running it in the most recent numpy would throw lots of Deprecation warnings at you, and presumably eventually it will stop working completely. This isn't great. The obvious answer is to change the code to
np.percentile( ...., method=xxx, ....)
But then if you run it on a machine with an older numpy install, then it won't work at all! There isn't a trivial method for users of numpy to conform to this change without breaking stuff. In other words, the numpy devs gave their users pointless homework. I just did this homework with this commit to mrcal. It creates a percentile_compat() function that figures out which flavor of argument we should use, and uses it. Here it is:
def percentile_compat(*args, **kwargs):
    r'''Wrapper for np.percentile() to handle their API change
In numpy 1.24 the "interpolation" kwarg was renamed to "method". I need to pass
the right thing to work with both old and new numpy. This function tries the
newer method, and if that fails, uses the old one. The test is only done the
first time.
It is assumed that this is called with the old 'interpolation' key.
    '''
    if not 'interpolation' in kwargs or \
       percentile_compat.which == 'interpolation':
        return np.percentile(*args, **kwargs)
    kwargs_no_interpolation = dict(kwargs)
    del kwargs_no_interpolation['interpolation']
    if percentile_compat.which == 'method':
        return np.percentile(*args, **kwargs_no_interpolation,
                             method = kwargs['interpolation'])
    # Need to detect
    try:
        result = np.percentile(*args, **kwargs_no_interpolation,
                               method = kwargs['interpolation'])
        percentile_compat.which = 'method'
        return result
    except:
        percentile_compat.which = 'interpolation'
        return np.percentile(*args, **kwargs)
percentile_compat.which = None
Please take it and use it. I give up all copyright.

19 April 2023

Ian Jackson: The Rust Foundation's bad draft trademark policy

tl;dr The Rust Foundation s proposed new trademark policy is far too restrictive, and will cause (more) drama unless it is substantially revised. Process Rust is a trademark owned by the Foundation. The Rust Foundation still seems to be finding its feet. Evidently, one of the items on its backlog was to update the trademark policy. Apparently they have been working on this for some time, in an informal working group. In August, there was a survey. (I saw it in This Week In Rust, the community-curated newsletter where most important stuff appears, and responded.) I don t think the results of this survey have been published anywhere. Last week (12th April) the Foundation published an official Inside Rust blog post linking to a draft. They included a link to a feedback survey, closing on the 17th of April i.e., it was open for 5 days. This is far too short a period for formal feedback on such a draft. Especially given that this process has apparently already been generating significant controversy within parts of the Rust community. Substance Overall, this policy is poor. It is far too restrictive. It is likely to lead to (further) controversy and argument, including conflicts with Rust s downstreams. It does not serve the needs of the Rust community. In particular, the Rust community does not need the trademark to: The community does need the trademark to: It might be useful to use the trademark to strengthen licensing or CoC compliance. For example, good faith redistributions of a modified Rust, as Rust , would be Free Software, even though the copyright licence permits proprietary derivatives; so use of the Rust trademark should probably require use of a Free licence. There should be a series of blanket permissions to use the word Rust in for example: Currently there aren t. For example the current Debian practice of calling Rust libraries rust-<name-of-crate> is probably in violation. There are a number of more detailed problems with the wording. Values The policy has all the hallmarks of excessive influence from traditional trademark lawyers and not enough influence from the Free Software community. I would like to remind the Free Software activists on the inside of this process that the lawyers are there to serve you and the community. The values embodied in trademark law often conflict with the values of the Free Software community. The Rust Project should adopt a trademark policy which follows the community s values - even if that might weaken our ability to sue evildoers. Next steps The Foundation should take a step back and pause the process. Then, the Foundation should restart the process from a much earlier stage, with much wider publicity. Each stage should be widely advertised to the whole community, with opportunities for feedback. This should include publishing the results of the August 2022 survey. The Foundation should publish a sketch of the legal advice they have received, publicly say what the plausible options are and what their consequences might be (for the community, for downstreams, and for the Foundation s enforcement ability). (Some of this will no doubt repeat the work that has been done in the informal trademark working group. That work wasn t widely enough advertised.) Echoes of a dispute from 2006 Mozilla made a very similar mistake with Firefox in 2006. The official policy stated that no-one was allowed to distribute Firefox with any patches, unless those patches had been pre-approved by Mozilla. Debian is committed to Software Freedom. This must includes the freedom to modify the software as one sees fit, even if the original authors don t agree. Now, overly-restrictive trademark policies are hardly new. Debian often takes the practical view that usually the upstream with such a policy doesn t really mean it. But Mozilla decided they did mean it. They contacted Debian asking for Debian to get their patches approved. Since that wasn t acceptable to Debian, they stopped using the word Firefox . For a decade, Debian s Firefox browser was called Iceweasel . We don t want something similar happening to Rust .

comment count unavailable comments

18 April 2023

Matthew Garrett: PSA: upgrade your LUKS key derivation function

Here's an article from a French anarchist describing how his (encrypted) laptop was seized after he was arrested, and material from the encrypted partition has since been entered as evidence against him. His encryption password was supposedly greater than 20 characters and included a mixture of cases, numbers, and punctuation, so in the absence of any sort of opsec failures this implies that even relatively complex passwords can now be brute forced, and we should be transitioning to even more secure passphrases.

Or does it? Let's go into what LUKS is doing in the first place. The actual data is typically encrypted with AES, an extremely popular and well-tested encryption algorithm. AES has no known major weaknesses and is not considered to be practically brute-forceable - at least, assuming you have a random key. Unfortunately it's not really practical to ask a user to type in 128 bits of binary every time they want to unlock their drive, so another approach has to be taken.

This is handled using something called a "key derivation function", or KDF. A KDF is a function that takes some input (in this case the user's password) and generates a key. As an extremely simple example, think of MD5 - it takes an input and generates a 128-bit output, so we could simply MD5 the user's password and use the output as an AES key. While this could technically be considered a KDF, it would be an extremely bad one! MD5s can be calculated extremely quickly, so someone attempting to brute-force a disk encryption key could simply generate the MD5 of every plausible password (probably on a lot of machines in parallel, likely using GPUs) and test each of them to see whether it decrypts the drive.

(things are actually slightly more complicated than this - your password is used to generate a key that is then used to encrypt and decrypt the actual encryption key. This is necessary in order to allow you to change your password without having to re-encrypt the entire drive - instead you simply re-encrypt the encryption key with the new password-derived key. This also allows you to have multiple passwords or unlock mechanisms per drive)

Good KDFs reduce this risk by being what's technically referred to as "expensive". Rather than performing one simple calculation to turn a password into a key, they perform a lot of calculations. The number of calculations performed is generally configurable, in order to let you trade off between the amount of security (the number of calculations you'll force an attacker to perform when attempting to generate a key from a potential password) and performance (the amount of time you're willing to wait for your laptop to generate the key after you type in your password so it can actually boot). But, obviously, this tradeoff changes over time - defaults that made sense 10 years ago are not necessarily good defaults now. If you set up your encrypted partition some time ago, the number of calculations required may no longer be considered up to scratch.

And, well, some of these assumptions are kind of bad in the first place! Just making things computationally expensive doesn't help a lot if your adversary has the ability to test a large number of passwords in parallel. GPUs are extremely good at performing the sort of calculations that KDFs generally use, so an attacker can "just" get a whole pile of GPUs and throw them at the problem. KDFs that are computationally expensive don't do a great deal to protect against this. However, there's another axis of expense that can be considered - memory. If the KDF algorithm requires a significant amount of RAM, the degree to which it can be performed in parallel on a GPU is massively reduced. A Geforce 4090 may have 16,384 execution units, but if each password attempt requires 1GB of RAM and the card only has 24GB on board, the attacker is restricted to running 24 attempts in parallel.

So, in these days of attackers with access to a pile of GPUs, a purely computationally expensive KDF is just not a good choice. And, unfortunately, the subject of this story was almost certainly using one of those. Ubuntu 18.04 used the LUKS1 header format, and the only KDF supported in this format is PBKDF2. This is not a memory expensive KDF, and so is vulnerable to GPU-based attacks. But even so, systems using the LUKS2 header format used to default to argon2i, again not a memory expensive KDFwhich is memory strong, but not designed to be resistant to GPU attack (thanks to the comments pointing out my misunderstanding here). New versions default to argon2id, which is. You want to be using argon2id.

What makes this worse is that distributions generally don't update this in any way. If you installed your system and it gave you pbkdf2 as your KDF, you're probably still using pbkdf2 even if you've upgraded to a system that would use argon2id on a fresh install. Thankfully, this can all be fixed-up in place. But note that if anything goes wrong here you could lose access to all your encrypted data, so before doing anything make sure it's all backed up (and figure out how to keep said backup secure so you don't just have your data seized that way).

First, make sure you're running as up-to-date a version of your distribution as possible. Having tools that support the LUKS2 format doesn't mean that your distribution has all of that integrated, and old distribution versions may allow you to update your LUKS setup without actually supporting booting from it. Also, if you're using an encrypted /boot, stop now - very recent versions of grub2 support LUKS2, but they don't support argon2id, and this will render your system unbootable.

Next, figure out which device under /dev corresponds to your encrypted partition. Run

lsblk

and look for entries that have a type of "crypt". The device above that in the tree is the actual encrypted device. Record that name, and run

sudo cryptsetup luksHeaderBackup /dev/whatever --header-backup-file /tmp/luksheader

and copy that to a USB stick or something. If something goes wrong here you'll be able to boot a live image and run

sudo cryptsetup luksHeaderRestore /dev/whatever --header-backup-file luksheader

to restore it.

(Edit to add: Once everything is working, delete this backup! It contains the old weak key, and someone with it can potentially use that to brute force your disk encryption key using the old KDF even if you've updated the on-disk KDF.)

Next, run

sudo cryptsetup luksDump /dev/whatever

and look for the Version: line. If it's version 1, you need to update the header to LUKS2. Run

sudo cryptsetup convert /dev/whatever --type luks2

and follow the prompts. Make sure your system still boots, and if not go back and restore the backup of your header. Assuming everything is ok at this point, run

sudo cryptsetup luksDump /dev/whatever

again and look for the PBKDF: line in each keyslot (pay attention only to the keyslots, ignore any references to pbkdf2 that come after the Digests: line). If the PBKDF is either "pbkdf2" or "argon2i" you should convert to argon2id. Run the following:

sudo cryptsetup luksConvertKey /dev/whatever --pbkdf argon2id

and follow the prompts. If you have multiple passwords associated with your drive you'll have multiple keyslots, and you'll need to repeat this for each password.

Distributions! You should really be handling this sort of thing on upgrade. People who installed their systems with your encryption defaults several years ago are now much less secure than people who perform a fresh install today. Please please please do something about this.

comment count unavailable comments

Matthew Palmer: Rutie and Magnus, Two Good Ways to Build Ruby Extensions in Rust

I wrote the Ruby bindings for the Enquo Project, my attempt to bring queryable encryption to all databases, using the Rutie library. Recently, I ve rewritten the bindings to use Magnus instead, and I thought I d put down my thoughts about the whole situation.

The Story So Far The Enquo Project core cryptography is all written in Rust, as seems to be the vogue these days. Rust is fast, safe, and easily interoperable with most of the rest of the modern software development ecosystem, making it a good choice as a language to implement the cryptographic primitives that Enquo needs, like Order-Revealing Encryption. Of course, since not everyone writes their applications in Rust, we need to provide the functionality of the Enquo client in the languages that people do use, such as Ruby, Python, and so on. Since re-writing all that cryptographic code in a myriad of languages would be tedious and error-prone, we instead provide bindings to the core Rust code. These are just thin shims of code that translate the data types and function calls between Rust and the target language.
Shim in a Can Wrong sort of shim, but canned language bindings would be handy
As I m most familiar with Ruby and its development ecosystem (particularly Ruby on Rails), it was natural that I d make Ruby bindings for Enquo as my first target. Rummaging around, it seemed that Rutie was a good library to use, so off I went.

What are Rutie and Magnus, Anyway? Both libraries share the same goal: provide the ability to write some Rust code, run that through a compiler, and produce something that can be loaded by the Ruby interpreter and used just like any other Ruby class. They re both fairly high level interfaces, trying to abstract away much of the gory details, and do a lot of the common heavy lifting that can make writing bindings fiddly and annoying. Things like mapping data types (like strings and integers) between Rust data types and the closest equivalents in Ruby. This mapping never goes perfectly smoothly. For example, Ruby integers don t have a fixed range of values they can represent you can store a huge number like 2256 more-or-less as easily as you can the number 12. But Rust, being a lower-level language, only has a set of integer types that have fixed boundaries, like the u32 type, which can only store integers between zero and about four billion (232 - 1, to be precise). There s also lots of little things that need to be just right, also, like translating the different memory management approaches of the languages, and dealing with a myriad of fiddly little issues like passing arguments and return values in and out of method calls, helpers for defining classes and methods (and pointing to the correct Rust functions), and so on.
A mass of tangled pipes and valves This is what I imagine it looks like inside these libraries
(Herv Cozanet / Wikimedia Commons, CC-BY-SA)
All in all, these libraries are fairly significant pieces of work, and I m mighty glad that someone else has taken on the job of building (and maintaining!) them.

So Why the Change? Good question. It s important to say at the outset that there s nothing particularly wrong with Rutie. I found using Rutie to be very straightforward, and the Ruby bindings came together very quickly and easily. If someone chose to use Rutie for their project, I m sure they d have a good experience. What made me take the time to rewrite using Magnus was a set of a few tiny things, which together gave me enough of a shove to do the work. Firstly, I d had a hiccup with Rutie s support of newer versions of Ruby, particularly 3.2 (PR). Also, I d hit a couple of segfault issues, which were ultimately caused by Ruby garbage-collecting data out from underneath me. These were ultimately my fault, of course, but Rutie wasn t helping me out in avoiding the problems in the first place. Finally, while Rutie helped translate data types, there was still a bit of boilerplate and ugliness that needed to be included. This wasn t a showstopper, but I m appreciating the extra smoothness that Magnus provides here. As an example, here s what s required in Rutie to get native Rust data types from Ruby method parameters (and the self reference to the current object):
fn enquo_field_decrypt_text(ciphertext_obj: RString, context_obj: RString) -> RString  
    let ciphertext = ciphertext_obj.to_str_unchecked();
    let context = context_obj.to_vec_u8_unchecked();
    let field = rbself.get_data(&*FIELD_WRAPPER);
    // etc etc etc
The equivalent in Magnus is just the function signature:
fn decrypt_text(&self, ciphertext: String, context: String) -> Result<String, magnus::Error>  
You can also see there that Magnus signals an exception via the Result return value, while Rutie s approach to raising an exception involves poking the Ruby VM directly, which always struck me as a bit ugly. There are several other minor things in Magnus (like its cleaner approach to wrapping structs so they can be stored in Ruby objects) that I m appreciating, too. Never discount the power of ergonomics for making a happy developer.

The End Result I spent a bit over half of last weekend doing the rewrite maybe ten hours of so. Since Magnus did more type checking and data validation, and its approach to error handling was smoother, I took the opportunity to rewrite a bunch of Ruby wrapper code I d written (which just existed to check things like ranges of values and string encodings) into Rust, as well. To make sure that the conversion was accurate, I added a heap more unit tests to the bindings. I also took the opportunity to restructure the codebase to split the code for the different Ruby classes into separate files, which I hadn t done initially as the code had originally accreted, rather than being purposefully written. All up, though, my rewrite ended up removing over 60 lines (excluding the extra specs I added):
$ git diff --stat -- lib ext/enquo/src
 ruby/ext/enquo/src/field.rs         342 ++++++++++++++++++++++++++++++++++++++
 ruby/ext/enquo/src/lib.rs           338 ++++---------------------------------
 ruby/ext/enquo/src/root.rs           39 +++++
 ruby/ext/enquo/src/root_key.rs       67 ++++++++
 ruby/lib/enquo.rb                     6 +-
 ruby/lib/enquo/field.rb             173 -------------------
 ruby/lib/enquo/root.rb               28 ----
 ruby/lib/enquo/root_key.rb            1 -
 ruby/lib/enquo/root_key/static.rb    27 ---
 9 files changed, 479 insertions(+), 542 deletions(-)
Considering that I was translating from a higher level language into a lower level one, the removal of so much code is quite remarkable. Magnus was able to automagically replace rather a lot of raise ArgumentError if something.isnt_right code in those .rb files. So, in conclusion, if you, too, are building Ruby extensions in Rust, while Rutie is a solid choice (and you probably should stick with it if you re already using it), I highly recommend giving Magnus a look for your next extension.

17 April 2023

Matthew Garrett: Booting modern Intel CPUs

CPUs can't do anything without being told what to do, which leaves the obvious problem of how do you tell a CPU to do something in the first place. On many CPUs this is handled in the form of a reset vector - an address the CPU is hardcoded to start reading instructions from when power is applied. The address the reset vector points to will typically be some form of ROM or flash that can be read by the CPU even if no other hardware has been configured yet. This allows the system vendor to ship code that will be executed immediately after poweron, configuring the rest of the hardware and eventually getting the system into a state where it can run user-supplied code.

The specific nature of the reset vector on x86 systems has varied over time, but it's effectively always been 16 bytes below the top of the address space - so, 0xffff0 on the 20-bit 8086, 0xfffff0 on the 24-bit 80286, and 0xfffffff0 on the 32-bit 80386. Convention on x86 systems is to have RAM starting at address 0, so the top of address space could be used to house the reset vector with as low a probability of conflicting with RAM as possible.

The most notable thing about x86 here, though, is that when it starts running code from the reset vector, it's still in real mode. x86 real mode is a holdover from a much earlier era of computing. Rather than addresses being absolute (ie, if you refer to a 32-bit address, you store the entire address in a 32-bit or larger register), they are 16-bit offsets that are added to the value stored in a "segment register". Different segment registers existed for code, data, and stack, so a 16-bit address could refer to different actual addresses depending on how it was being interpreted - jumping to a 16 bit address would result in that address being added to the code segment register, while reading from a 16 bit address would result in that address being added to the data segment register, and so on. This is all in order to retain compatibility with older chips, to the extent that even 64-bit x86 starts in real mode with segments and everything (and, also, still starts executing at 0xfffffff0 rather than 0xfffffffffffffff0 - 64-bit mode doesn't support real mode, so there's no way to express a 64-bit physical address using the segment registers, so we still start just below 4GB even though we have massively more address space available).

Anyway. Everyone knows all this. For modern UEFI systems, the firmware that's launched from the reset vector then reprograms the CPU into a sensible mode (ie, one without all this segmentation bullshit), does things like configure the memory controller so you can actually access RAM (a process which involves using CPU cache as RAM, because programming a memory controller is sufficiently hard that you need to store more state than you can fit in registers alone, which means you need RAM, but you don't have RAM until the memory controller is working, but thankfully the CPU comes with several megabytes of RAM on its own in the form of cache, so phew). It's kind of ugly, but that's a consequence of a bunch of well-understood legacy decisions.

Except. This is not how modern Intel x86 boots. It's far stranger than that. Oh, yes, this is what it looks like is happening, but there's a bunch of stuff going on behind the scenes. Let's talk about boot security. The idea of any form of verified boot (such as UEFI Secure Boot) is that a signature on the next component of the boot chain is validated before that component is executed. But what verifies the first component in the boot chain? You can't simply ask the BIOS to verify itself - if an attacker can replace the BIOS, they can replace it with one that simply lies about having done so. Intel's solution to this is called Boot Guard.

But before we get to Boot Guard, we need to ensure the CPU is running in as bug-free a state as possible. So, when the CPU starts up, it examines the system flash and looks for a header that points at CPU microcode updates. Intel CPUs ship with built-in microcode, but it's frequently old and buggy and it's up to the system firmware to include a copy that's new enough that it's actually expected to work reliably. The microcode image is pulled out of flash, a signature is verified, and the new microcode starts running. This is true in both the Boot Guard and the non-Boot Guard scenarios. But for Boot Guard, before jumping to the reset vector, the microcode on the CPU reads an Authenticated Code Module (ACM) out of flash and verifies its signature against a hardcoded Intel key. If that checks out, it starts executing the ACM. Now, bear in mind that the CPU can't just verify the ACM and then execute it directly from flash - if it did, the flash could detect this, hand over a legitimate ACM for the verification, and then feed the CPU different instructions when it reads them again to execute them (a Time of Check vs Time of Use, or TOCTOU, vulnerability). So the ACM has to be copied onto the CPU before it's verified and executed, which means we need RAM, which means the CPU already needs to know how to configure its cache to be used as RAM.

Anyway. We now have an ACM loaded and verified, and it can safely be executed. The ACM does various things, but the most important from the Boot Guard perspective is that it reads a set of write-once fuses in the motherboard chipset that represent the SHA256 of a public key. It then reads the initial block of the firmware (the Initial Boot Block, or IBB) into RAM (or, well, cache, as previously described) and parses it. There's a block that contains a public key - it hashes that key and verifies that it matches the SHA256 from the fuses. It then uses that key to validate a signature on the IBB. If it all checks out, it executes the IBB and everything starts looking like the nice simple model we had before.

Except, well, doesn't this seem like an awfully complicated bunch of code to implement in real mode? And yes, doing all of this modern crypto with only 16-bit registers does sound like a pain. So, it doesn't. All of this is happening in a perfectly sensible 32 bit mode, and the CPU actually switches back to the awful segmented configuration afterwards so it's still compatible with an 80386 from 1986. The "good" news is that at least firmware can detect that the CPU has already configured the cache as RAM and can skip doing that itself.

I'm skipping over some steps here - the ACM actually does other stuff around measuring the firmware into the TPM and doing various bits of TXT setup for people who want DRTM in their lives, but the short version is that the CPU bootstraps itself into a state where it works like a modern CPU and then deliberately turns a bunch of the sensible functionality off again before it starts executing firmware. I'm also missing out the fact that this entire process only kicks off after the Management Engine says it can, which means we're waiting for an entirely independent x86 to boot an entire OS before our CPU even starts pretending to execute the system firmware.

Of course, as mentioned before, on modern systems the firmware will then reprogram the CPU into something actually sensible so OS developers no longer need to care about this[1][2], which means we've bounced between multiple states for no reason other than the possibility that someone wants to run legacy BIOS and then boot DOS on a CPU with like 5 orders of magnitude more transistors than the 8086.

tl;dr why can't my x86 wake up with the gin protected mode already inside it

[1] Ha uh except that on ACPI resume we're going to skip most of the firmware setup code so we still need to handle the CPU being in fucking 16-bit mode because suspend/resume is basically an extremely long reboot cycle

[2] Oh yeah also you probably have multiple cores on your CPU and well bad news about the state most of the cores are in when the OS boots because the firmware never started them up so they're going to come up in 16-bit real mode even if your boot CPU is already in 64-bit protected mode, unless you were using TXT in which case you have a different sort of nightmare that if we're going to try to map it onto real world nightmare concepts is one that involves a lot of teeth. Or, well, that used to be the case, but ACPI 6.4 (released in 2021) provides a mechanism for the OS to ask the firmware to wake the CPU up for it so this is invisible to the OS, but you're still relying on the firmware to actually do the heavy lifting here

comment count unavailable comments

14 April 2023

Russ Allbery: Review: Babel

Review: Babel, by R.F. Kuang
Publisher: Harper Voyage
Copyright: August 2022
ISBN: 0-06-302144-7
Format: Kindle
Pages: 544
Babel, or the Necessity of Violence: An Arcane History of the Oxford Translators' Revolution, to give it its full title, is a standalone dark academia fantasy set in the 1830s and 1840s, primarily in Oxford, England. The first book of R.F. Kuang's previous trilogy, The Poppy War, was nominated for multiple awards and won the Compton Crook Award for best first novel. Babel is her fourth book. Robin Swift, although that was not his name at the time, was born and raised in Canton and educated by an inexplicable English tutor his family could not have afforded. After his entire family dies of cholera, he is plucked from China by a British professor and offered a life in England as his ward. What follows is a paradise of books, a hell of relentless and demanding instruction, and an unpredictably abusive emotional environment, all aiming him towards admission to Oxford University. Robin will join University College and the Royal Institute of Translation. The politics of this imperial Britain are almost precisely the same as in our history, but one of the engines is profoundly different. This world has magic. If words from two different languages are engraved on a metal bar (silver is best), the meaning and nuance lost in translation becomes magical power. With a careful choice of translation pairs, and sometimes additional help from other related words and techniques, the silver bar becomes a persistent spell. Britain's industrial revolution is in overdrive thanks to the country's vast stores of silver and the applied translation prowess of Babel. This means Babel is also the only part of very racist Oxford that accepts non-white students and women. They need translators (barely) more than they care about maintaining social hierarchy; translation pairs only work when the translator is fluent in both languages. The magic is also stronger when meanings are more distinct, which is creating serious worries about classical and European languages. Those are still the bulk of Babel's work, but increased trade and communication within Europe is eroding the meaning distinctions and thus the amount of magical power. More remote languages, such as Chinese and Urdu, are full of untapped promise that Britain's colonial empire wants to capture. Professor Lowell, Robin's dubious benefactor, is a specialist in Chinese languages; Robin is a potential tool for his plans. As Robin discovers shortly after arriving in Oxford, he is not the first of Lowell's tools. His predecessor turned against Babel and is trying to break its chokehold on translation magic. He wants Robin to help. This is one of those books that is hard to review because it does some things exceptionally well and other things that did not work for me. It's not obvious if the latter are flaws in the book or a mismatch between book and reader (or, frankly, flaws in the reader). I'll try to explain as best I can so that you can draw your own conclusions. First, this is one of the all-time great magical system hooks. The way words are tapped for power is fully fleshed out and exceptionally well-done. Kuang is a professional translator, which shows in the attention to detail on translation pairs. I think this is the best-constructed and explained word-based magic system I've read in fantasy. Many word-based systems treat magic as its own separate language that is weirdly universal. Here, Kuang does the exact opposite, and the result is immensely satisfying. A fantasy reader may expect exploration of this magic system to be the primary point of the book, however, and this is not the case. It is an important part of the book, and its implications are essential to the plot resolution, but this is not the type of fantasy novel where the plot is driven by character exploration of the magic system. The magic system exists, the characters use it, and we do get some crunchy details, but the heart of the book is elsewhere. If you were expecting the typical relationship of a fantasy novel to its magic system, you may get a bit wrong-footed. Similarly, this is historical fantasy, but it is the type of historical fantasy where the existence of magic causes no significant differences. For some people, this is a pet peeve; personally, I don't mind that choice in the abstract, but some of the specifics bugged me. The villains of this book assert that any country could have done what Britain did in developing translation magic, and thus their hoarding of it is not immoral. They are obviously partly lying (this is a classic justification for imperialism), but it's not clear from the book how they are lying. Technologies (and magic here works like a technology) tend to concentrate power when they require significant capital investment, and tend to dilute power when they are portable and easy to teach. Translation magic feels like the latter, but its effect in the book is clearly the former, and I was never sure why. England is not an obvious choice to be a translation superpower. Yes, it's a colonial empire, but India, southeast Asia, and most certainly Africa (the continent largely not appearing in this book) are home to considerably more languages from more wildly disparate families than western Europe. Translation is not a peculiarly European idea, and this magic system does not seem hard to stumble across. It's not clear why England, and Oxford in particular, is so dramatically far ahead. There is some sign that Babel is keeping the mechanics of translation magic secret, but that secret has leaked, seems easy to develop independently, and is simple enough that a new student can perform basic magic with a few hours of instruction. This does not feel like the kind of power that would be easy to concentrate, let alone to the extreme extent required by the last quarter of this book. The demand for silver as a base material for translation magic provides a justification for mercantilism that avoids the confusing complexities of currency economics in our actual history, so fine, I guess, but it was a bit disappointing for this great of an idea for a magic system to have this small of an impact on politics. I'll come to the actual thrust of this book in a moment, but first something else Babel does exceptionally well: dark academia. The remainder of Robin's cohort at Oxford is Remy, a dark-skinned Muslim from Calcutta; Victoire, a Haitian woman raised in France; and Letty, the daughter of a British admiral. All of them are non-white except Letty, and Letty and Victoire additionally have to deal with the blatant sexism of the time. (For example, they have to live several miles from Oxford because women living near the college would be a "distraction.") The interpersonal dynamics between the four are exceptionally well done. Kuang captures the dislocation of going away to college, the unsettled life upheaval that makes it both easy and vital to form suddenly tight friendships, and the way that the immense pressure from classes and exams leaves one so devoid of spare emotional capacity that those friendships become both unbreakable and badly strained. Robin and Remy almost immediately become inseparable in that type of college friendship in which profound trust and constant companionship happen first and learning about the other person happens afterwards. It's tricky to talk about this without spoilers, but one of the things Kuang sets up with this friend group is a pointed look at intersectionality. Babel has gotten a lot of positive review buzz, and I think this is one of the reasons why. Kuang does not pass over or make excuses for characters in a place where many other books do. This mostly worked for me, but with a substantial caveat that I think you may want to be aware of before you dive into this book. Babel is set in the 1830s, but it is very much about the politics of 2022. That does not necessarily mean that the politics are off for the 1830s; I haven't done the research to know, and it's possible I'm seeing the Tiffany problem (Jo Walton's observation that Tiffany is a historical 12th century women's name, but an author can't use it as a medieval name because readers think it sounds too modern). But I found it hard to shake the feeling that the characters make sense of their world using modern analytical frameworks of imperialism, racism, sexism, and intersectional feminism, although without using modern terminology, and characters from the 1830s would react somewhat differently. This is a valid authorial choice; all books are written for the readers of the time when they're published. But as with magical systems that don't change history, it's a pet peeve for some readers. If that's you, be aware that's the feel I got from it. The true center of this book is not the magic system or the history. It's advertised directly in the title the necessity of violence although it's not until well into the book before the reader knows what that means. This is a book about revolution, what revolution means, what decisions you have to make along the way, how the personal affects the political, and the inadequacy of reform politics. It is hard, uncomfortable, and not gentle on its characters. The last quarter of this book was exceptional, and I understand why it's getting so much attention. Kuang directly confronts the desire for someone else to do the necessary work, the hope that surely the people with power will see reason, and the feeling of despair when there are no good plans and every reason to wait and do nothing when atrocities are about to happen. If you are familiar with radical politics, these aren't new questions, but this is not the sort of thing that normally shows up in fantasy. It does not surprise me that Babel struck a nerve with readers a generation or two younger than me. It captures that heady feeling on the cusp of adulthood when everything is in flux and one is assembling an independent politics for the first time. Once I neared the end of the book, I could not put it down. The ending is brutal, but I think it was the right ending for this book. There are two things, though, that I did not like about the political arc. The first is that Victoire is a much more interesting character than Robin, but is sidelined for most of the book. The difference of perspectives between her and Robin is the heart of what makes the end of this book so good, and I wish that had started 300 pages earlier. Or, even better, I wish Victoire has been the protagonist; I liked Robin, but he's a very predictable character for most of the book. Victoire is not; even the conflicts she had earlier in the book, when she didn't get much attention in the story, felt more dynamic and more thoughtful than Robin's mix of guilt and anxiety. The second is that I wish Kuang had shown more of Robin's intellectual evolution. All of the pieces of why he makes the decisions that he does are present in this book, and Kuang shows his emotional state (sometimes in agonizing detail) at each step, but the sense-making, the development of theory and ideology beneath the actions, is hinted at but not shown. This is a stylistic choice with no one right answer, but it felt odd because so much of the rest of the plot is obvious and telegraphed. If the reader shares Robin's perspective, I think it's easy to fill in the gaps, but it felt odd to read Robin giving clearly thought-out political analyses at the end of the book without seeing the hashing-out and argument with friends required to develop those analyses. I felt like I had to do a lot of heavy lifting as the reader, work that I wish had been done directly by the book. My final note about this book is that I found much of it extremely predictable. I think that's part of why reviewers describe it as accessible and easy to read; accessibility and predictability can be two sides of the same coin. Kuang did not intend for this book to be subtle, and I think that's part of the appeal. But very few of Robin's actions for the first three-quarters of the book surprised me, and that's not always the reading experience I want. The end of the book is different, and I therefore found it much more gripping, but it takes a while to get there. Babel is, for better or worse, the type of fantasy where the politics, economics, and magic system exist primarily to justify the plot the author wanted. I don't think the societal position of the Institute of Translation that makes the ending possible is that believable given the nature of the technology in question and the politics of the time, and if you are inclined to dig into the specifics of the world-building, I think you will find it frustrating. Where it succeeds brilliantly is in capturing the social dynamics of hothouse academic cohorts, and in making a sharp and unfortunately timely argument about the role of violence in political change, in a way that the traditionally conservative setting of fantasy rarely does. I can't say Babel blew me away, but I can see why others liked it so much. If I had to guess, I'd say that the closer one is in age to the characters in the book and to that moment of political identity construction, the more it's likely to appeal. Rating: 7 out of 10
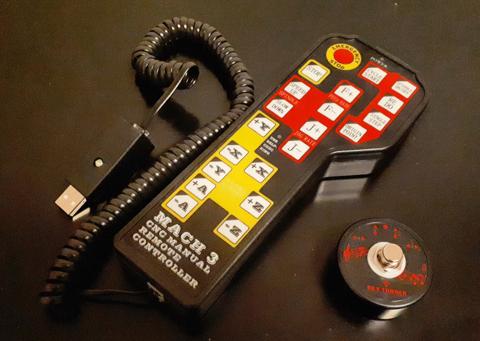
John Goerzen: Easily Accessing All Your Stuff with a Zero-Trust Mesh VPN

Probably everyone is familiar with a regular VPN. The traditional use case is to connect to a corporate or home network from a remote location, and access services as if you were there. But these days, the notion of corporate network and home network are less based around physical location. For instance, a company may have no particular office at all, may have a number of offices plus a number of people working remotely, and so forth. A home network might have, say, a PVR and file server, while highly portable devices such as laptops, tablets, and phones may want to talk to each other regardless of location. For instance, a family member might be traveling with a laptop, another at a coffee shop, and those two devices might want to communicate, in addition to talking to the devices at home. And, in both scenarios, there might be questions about giving limited access to friends. Perhaps you d like to give a friend access to part of your file server, or as a company, you might have contractors working on a limited project. Pretty soon you wind up with a mess of VPNs, forwarded ports, and tricks to make it all work. With the increasing prevalence of CGNAT, a lot of times you can t even open a port to the public Internet. Each application or device probably has its own gateway just to make it visible on the Internet, some of which you pay for. Then you add on the question of: should you really trust your LAN anyhow? With possibilities of guests using it, rogue access points, etc., the answer is probably no . We can move the responsibility for dealing with NAT, fluctuating IPs, encryption, and authentication, from the application layer further down into the network stack. We then arrive at a much simpler picture for all. So this page is fundamentally about making the network work, simply and effectively.

How do we make the Internet work in these scenarios? We re going to combine three concepts:
  1. A VPN, providing fully encrypted and authenticated communication and stable IPs
  2. Mesh Networking, in which devices automatically discover optimal paths to reach each other
  3. Zero-trust networking, in which we do not need to trust anything about the underlying LAN, because all our traffic uses the secure systems in points 1 and 2.
By combining these concepts, we arrive at some nice results:
  • You can ssh hostname, where hostname is one of your machines (server, laptop, whatever), and as long as hostname is up, you can reach it, wherever it is, wherever you are.
    • Combined with mosh, these sessions will be durable even across moving to other host networks.
    • You could just as well use telnet, because the underlying network should be secure.
  • You don t have to mess with encryption keys, certs, etc., for every internal-only service. Since IPs are now trustworthy, that s all you need. hosts.allow could make a comeback!
  • You have a way of transiting out of extremely restrictive networks. Every tool discussed here has a way of falling back on routing things via a broker (relay) on TCP port 443 if all else fails.
There might sometimes be tradeoffs. For instance:
  • On LANs faster than 1Gbps, performance may degrade due to encryption and encapsulation overhead. However, these tools should let hosts discover the locality of each other and not send traffic over the Internet if the devices are local.
  • With some of these tools, hosts local to each other (on the same LAN) may be unable to find each other if they can t reach the control plane over the Internet (Internet is down or provider is down)
Some other features that some of the tools provide include:
  • Easy sharing of limited access with friends/guests
  • Taking care of everything you need, including SSL certs, for exposing a certain on-net service to the public Internet
  • Optional routing of your outbound Internet traffic via an exit node on your network. Useful, for instance, if your local network is blocking tons of stuff.
Let s dive in.

Types of Mesh VPNs I ll go over several types of meshes in this article:
  1. Fully decentralized with automatic hop routing This model has no special central control plane. Nodes discover each other in various ways, and establish routes to each other. These routes can be direct connections over the Internet, or via other nodes. This approach offers the greatest resilience. Examples I ll cover include Yggdrasil and tinc.
  2. Automatic peer-to-peer with centralized control In this model, nodes, by default, communicate by establishing direct links between them. A regular node never carries traffic on behalf of other nodes. Special-purpose relays are used to handle cases in which NAT traversal is impossible. This approach tends to offer simple setup. Examples I ll cover include Tailscale, Zerotier, Nebula, and Netmaker.
  3. Roll your own and hybrid approaches This is a grab bag of other ideas; for instance, running Yggdrasil over Tailscale.

Terminology For the sake of consistency, I m going to use common language to discuss things that have different terms in different ecosystems:
  • Every tool discussed here has a way of dealing with NAT traversal. It may assist with establishing direct connections (eg, STUN), and if that fails, it may simply relay traffic between nodes. I ll call such a relay a broker . This may or may not be the same system that is a control plane for a tool.
  • All of these systems operate over lower layers that are unencrypted. Those lower layers may be a LAN (wired or wireless, which may or may not have Internet access), or the public Internet (IPv4 and/or IPv6). I m going to call the unencrypted lower layer, whatever it is, the clearnet .

Evaluation Criteria Here are the things I want to see from a solution:
  • Secure, with all communications end-to-end encrypted and authenticated, and prevention of traffic from untrusted devices.
  • Flexible, adapting to changes in network topology quickly and automatically.
  • Resilient, without single points of failure, and with devices local to each other able to communicate even if cut off from the Internet or other parts of the network.
  • Private, minimizing leakage of information or metadata about me and my systems
  • Able to traverse CGNAT without having to use a broker whenever possible
  • A lesser requirement for me, but still a nice to have, is the ability to include others via something like Internet publishing or inviting guests.
  • Fully or nearly fully Open Source
  • Free or very cheap for personal use
  • Wide operating system support, including headless Linux on x86_64 and ARM.

Fully Decentralized VPNs with Automatic Hop Routing Two systems fit this description: Yggdrasil and Tinc. Let s dive in.

Yggdrasil I ll start with Yggdrasil because I ve written so much about it already. It featured in prior posts such as:

Yggdrasil can be a private mesh VPN, or something more Yggdrasil can be a private mesh VPN, just like the other tools covered here. It s unique, however, in that a key goal of the project is to also make it useful as a planet-scale global mesh network. As such, Yggdrasil is a testbed of new ideas in distributed routing designed to scale up to massive sizes and all sorts of connection conditions. As of 2023-04-10, the main global Yggdrasil mesh has over 5000 nodes in it. You can choose whether or not to participate. Every node in a Yggdrasil mesh has a public/private keypair. Each node then has an IPv6 address (in a private address space) derived from its public key. Using these IPv6 addresses, you can communicate right away. Yggdrasil differs from most of the other tools here in that it does not necessarily seek to establish a direct link on the clearnet between, say, host A and host G for them to communicate. It will prefer such a direct link if it exists, but it is perfectly happy if it doesn t. The reason is that every Yggdrasil node is also a router in the Yggdrasil mesh. Let s sit with that concept for a moment. Consider:
  • If you have a bunch of machines on your LAN, but only one of them can peer over the clearnet, that s fine; all the other machines will discover this route to the world and use it when necessary.
  • All you need to run a broker is just a regular node with a public IP address. If you are participating in the global mesh, you can use one (or more) of the free public peers for this purpose.
  • It is not necessary for every node to know about the clearnet IP address of every other node (improving privacy). In fact, it s not even necessary for every node to know about the existence of all the other nodes, so long as it can find a route to a given node when it s asked to.
  • Yggdrasil can find one or more routes between nodes, and it can use this knowledge of multiple routes to aggressively optimize for varying network conditions, including combinations of, say, downloads and low-latency ssh sessions.
Behind the scenes, Yggdrasil calculates optimal routes between nodes as necessary, using a mesh-wide DHT for initial contact and then deriving more optimal paths. (You can also read more details about the routing algorithm.) One final way that Yggdrasil is different from most of the other tools is that there is no separate control server. No node is special , in charge, the sole keeper of metadata, or anything like that. The entire system is completely distributed and auto-assembling.

Meeting neighbors There are two ways that Yggdrasil knows about peers:
  • By broadcast discovery on the local LAN
  • By listening on a specific port (or being told to connect to a specific host/port)
Sometimes this might lead to multiple ways to connect to a node; Yggdrasil prefers the connection auto-discovered by broadcast first, then the lowest-latency of the defined path. In other words, when your laptops are in the same room as each other on your local LAN, your packets will flow directly between them without traversing the Internet.

Unique uses Yggdrasil is uniquely suited to network-challenged situations. As an example, in a post-disaster situation, Internet access may be unavailable or flaky, yet there may be many local devices perhaps ones that had never known of each other before that could share information. Yggdrasil meets this situation perfectly. The combination of broadcast auto-detection, distributed routing, and so forth, basically means that if there is any physical path between two nodes, Yggdrasil will find and enable it. Ad-hoc wifi is rarely used because it is a real pain. Yggdrasil actually makes it useful! Its broadcast discovery doesn t require any IP address provisioned on the interface at all (it just uses the IPv6 link-local address), so you don t need to figure out a DHCP server or some such. And, Yggdrasil will tend to perform routing along the contours of the RF path. So you could have a laptop in the middle of a long distance relaying communications from people farther out, because it could see both. Or even a chain of such things.

Yggdrasil: Security and Privacy Yggdrasil s mesh is aggressively greedy. It will peer with any node it can find (unless told otherwise) and will find a route to anywhere it can. There are two main ways to make sure you keep unauthorized traffic out: by restricting who can talk to your mesh, and by firewalling the Yggdrasil interface. Both can be used, and they can be used simultaneously. I ll discuss firewalling more at the end of this article. Basically, you ll almost certainly want to do this if you participate in the public mesh, because doing so is akin to having a globally-routable public IP address direct to your device. If you want to restrict who can talk to your mesh, you just disable the broadcast feature on all your nodes (empty MulticastInterfaces section in the config), and avoid telling any of your nodes to connect to a public peer. You can set a list of authorized public keys that can connect to your nodes listening interfaces, which you ll probably want to do. You will probably want to either open up some inbound ports (if you can) or set up a node with a known clearnet IP on a place like a $5/mo VPS to help with NAT traversal (again, setting AllowedPublicKeys as appropriate). Yggdrasil doesn t allow filtering multicast clients by public key, only by network interface, so that s why we disable broadcast discovery. You can easily enough teach Yggdrasil about static internal LAN IPs of your nodes and have things work that way. (Or, set up an internal gateway node or two, that the clients just connect to when they re local). But fundamentally, you need to put a bit more thought into this with Yggdrasil than with the other tools here, which are closed-only. Compared to some of the other tools here, Yggdrasil is better about information leakage; nodes only know details, such as clearnet IPs, of directly-connected peers. You can obtain the list of directly-connected peers of any known node in the mesh but that list is the public keys of the directly-connected peers, not the clearnet IPs. Some of the other tools contain a limited integrated firewall of sorts (with limited ACLs and such). Yggdrasil does not, but is fully compatible with on-host firewalls. I recommend these anyway even with many other tools.

Yggdrasil: Connectivity and NAT traversal Compared to the other tools, Yggdrasil is an interesting mix. It provides a fully functional mesh and facilitates connectivity in situations in which no other tool can. Yet its NAT traversal, while it exists and does work, results in using a broker under some of the more challenging CGNAT situations more often than some of the other tools, which can impede performance. Yggdrasil s underlying protocol is TCP-based. Before you run away screaming that it must be slow and unreliable like OpenVPN over TCP it s not, and it is even surprisingly good around bufferbloat. I ve found its performance to be on par with the other tools here, and it works as well as I d expect even on flaky 4G links. Overall, the NAT traversal story is mixed. On the one hand, you can run a node that listens on port 443 and Yggdrasil can even make it speak TLS (even though that s unnecessary from a security standpoint), so you can likely get out of most restrictive firewalls you will ever encounter. If you join the public mesh, know that plenty of public peers do listen on port 443 (and other well-known ports like 53, plus random high-numbered ones). If you connect your system to multiple public peers, there is a chance though a very small one that some public transit traffic might be routed via it. In practice, public peers hopefully are already peered with each other, preventing this from happening (you can verify this with yggdrasilctl debug_remotegetpeers key=ABC...). I have never experienced a problem with this. Also, since latency is a factor in routing for Yggdrasil, it is highly unlikely that random connections we use are going to be competitive with datacenter peers.

Yggdrasil: Sharing with friends If you re open to participating in the public mesh, this is one of the easiest things of all. Have your friend install Yggdrasil, point them to a public peer, give them your Yggdrasil IP, and that s it. (Well, presumably you also open up your firewall you did follow my advice to set one up, right?) If your friend is visiting at your location, they can just hop on your wifi, install Yggdrasil, and it will automatically discover a route to you. Yggdrasil even has a zero-config mode for ephemeral nodes such as certain Docker containers. Yggdrasil doesn t directly support publishing to the clearnet, but it is certainly possible to proxy (or even NAT) to/from the clearnet, and people do.

Yggdrasil: DNS There is no particular extra DNS in Yggdrasil. You can, of course, run a DNS server within Yggdrasil, just as you can anywhere else. Personally I just add relevant hosts to /etc/hosts and leave it at that, but it s up to you.

Yggdrasil: Source code, pricing, and portability Yggdrasil is fully open source (LGPLv3 plus additional permissions in an exception) and highly portable. It is written in Go, and has prebuilt binaries for all major platforms (including a Debian package which I made). There is no charge for anything with Yggdrasil. Listed public peers are free and run by volunteers. You can run your own peers if you like; they can be public and unlisted, public and listed (just submit a PR to get it listed), or private (accepting connections only from certain nodes keys). A peer in this case is just a node with a known clearnet IP address. Yggdrasil encourages use in other projects. For instance, NNCP integrates a Yggdrasil node for easy communication with other NNCP nodes.

Yggdrasil conclusions Yggdrasil is tops in reliability (having no single point of failure) and flexibility. It will maintain opportunistic connections between peers even if the Internet is down. The unique added feature of being able to be part of a global mesh is a nice one. The tradeoffs include being more prone to need to use a broker in restrictive CGNAT environments. Some other tools have clients that override the OS DNS resolver to also provide resolution of hostnames of member nodes; Yggdrasil doesn t, though you can certainly run your own DNS infrastructure over Yggdrasil (or, for that matter, let public DNS servers provide Yggdrasil answers if you wish). There is also a need to pay more attention to firewalling or maintaining separation from the public mesh. However, as I explain below, many other options have potential impacts if the control plane, or your account for it, are compromised, meaning you ought to firewall those, too. Still, it may be a more immediate concern with Yggdrasil. Although Yggdrasil is listed as experimental, I have been using it for over a year and have found it to be rock-solid. They did change how mesh IPs were calculated when moving from 0.3 to 0.4, causing a global renumbering, so just be aware that this is a possibility while it is experimental.

tinc tinc is the oldest tool on this list; version 1.0 came out in 2003! You can think of tinc as something akin to an older Yggdrasil without the public option. I will be discussing tinc 1.0.36, the latest stable version, which came out in 2019. The development branch, 1.1, has been going since 2011 and had its latest release in 2021. The last commit to the Github repo was in June 2022. Tinc is the only tool here to support both tun and tap style interfaces. I go into the difference more in the Zerotier review below. Tinc actually provides a better tap implementation than Zerotier, with various sane options for broadcasts, but I still think the call for an Ethernet, as opposed to IP, VPN is small. To configure tinc, you generate a per-host configuration and then distribute it to every tinc node. It contains a host s public key. Therefore, adding a host to the mesh means distributing its key everywhere; de-authorizing it means removing its key everywhere. This makes it rather unwieldy. tinc can do LAN broadcast discovery and mesh routing, but generally speaking you must manually teach it where to connect initially. Somewhat confusingly, the examples all mention listing a public address for a node. This doesn t make sense for a laptop, and I suspect you d just omit it. I think that address is used for something akin to a Yggdrasil peer with a clearnet IP. Unlike all of the other tools described here, tinc has no tool to inspect the running state of the mesh. Some of the properties of tinc made it clear I was unlikely to adopt it, so this review wasn t as thorough as that of Yggdrasil.

tinc: Security and Privacy As mentioned above, every host in the tinc mesh is authenticated based on its public key. However, to be more precise, this key is validated only at the point it connects to its next hop peer. (To be sure, this is also the same as how the list of allowed pubkeys works in Yggdrasil.) Since IPs in tinc are not derived from their key, and any host can assign itself whatever mesh IP it likes, this implies that a compromised host could impersonate another. It is unclear whether packets are end-to-end encrypted when using a tinc node as a router. The fact that they can be routed at the kernel level by the tun interface implies that they may not be.

tinc: Connectivity and NAT traversal I was unable to find much information about NAT traversal in tinc, other than that it does support it. tinc can run over UDP or TCP and auto-detects which to use, preferring UDP.

tinc: Sharing with friends tinc has no special support for this, and the difficulty of configuration makes it unlikely you d do this with tinc.

tinc: Source code, pricing, and portability tinc is fully open source (GPLv2). It is written in C and generally portable. It supports some very old operating systems. Mobile support is iffy. tinc does not seem to be very actively maintained.

tinc conclusions I haven t mentioned performance in my other reviews (see the section at the end of this post). But, it is so poor as to only run about 300Mbps on my 2.5Gbps network. That s 1/3 the speed of Yggdrasil or Tailscale. Combine that with the unwieldiness of adding hosts and some uncertainties in security, and I m not going to be using tinc.

Automatic Peer-to-Peer Mesh VPNs with centralized control These tend to be the options that are frequently discussed. Let s talk about the options.

Tailscale Tailscale is a popular choice in this type of VPN. To use Tailscale, you first sign up on tailscale.com. Then, you install the tailscale client on each machine. On first run, it prints a URL for you to click on to authorize the client to your mesh ( tailnet ). Tailscale assigns a mesh IP to each system. The Tailscale client lets the Tailscale control plane gather IP information about each node, including all detectable public and private clearnet IPs. When you attempt to contact a node via Tailscale, the client will fetch the known contact information from the control plane and attempt to establish a link. If it can contact over the local LAN, it will (it doesn t have broadcast autodetection like Yggdrasil; the information must come from the control plane). Otherwise, it will try various NAT traversal options. If all else fails, it will use a broker to relay traffic; Tailscale calls a broker a DERP relay server. Unlike Yggdrasil, a Tailscale node never relays traffic for another; all connections are either direct P2P or via a broker. Tailscale, like several others, is based around Wireguard; though wireguard-go rather than the in-kernel Wireguard. Tailscale has a number of somewhat unique features in this space:
  • Funnel, which lets you expose ports on your system to the public Internet via the VPN.
  • Exit nodes, which automate the process of routing your public Internet traffic over some other node in the network. This is possible with every tool mentioned here, but Tailscale makes switching it on or off a couple of quick commands away.
  • Node sharing, which lets you share a subset of your network with guests
  • A fantastic set of documentation, easily the best of the bunch.
Funnel, in particular, is interesting. With a couple of tailscale serve -style commands, you can expose a directory tree (or a development webserver) to the world. Tailscale gives you a public hostname, obtains a cert for it, and proxies inbound traffic to you. This is subject to some unspecified bandwidth limits, and you can only choose from three public ports, so it s not really a production solution but as a quick and easy way to demonstrate something cool to a friend, it s a neat feature.

Tailscale: Security and Privacy With Tailscale, as with the other tools in this category, one of the main threats to consider is the control plane. What are the consequences of a compromise of Tailscale s control plane, or of the credentials you use to access it? Let s begin with the credentials used to access it. Tailscale operates no identity system itself, instead relying on third parties. For individuals, this means Google, Github, or Microsoft accounts; Okta and other SAML and similar identity providers are also supported, but this runs into complexity and expense that most individuals aren t wanting to take on. Unfortunately, all three of those types of accounts often have saved auth tokens in a browser. Personally I would rather have a separate, very secure, login. If a person does compromise your account or the Tailscale servers themselves, they can t directly eavesdrop on your traffic because it is end-to-end encrypted. However, assuming an attacker obtains access to your account, they could:
  • Tamper with your Tailscale ACLs, permitting new actions
  • Add new nodes to the network
  • Forcibly remove nodes from the network
  • Enable or disable optional features
Of note is that they cannot just commandeer an existing IP. I would say the riskiest possibility here is that could add new nodes to the mesh. Because they could also tamper with your ACLs, they could then proceed to attempt to access all your internal services. They could even turn on service collection and have Tailscale tell them what and where all the services are. Therefore, as with other tools, I recommend a local firewall on each machine with Tailscale. More on that below. Tailscale has a new alpha feature called tailnet lock which helps with this problem. It requires existing nodes in the mesh to sign a request for a new node to join. Although this doesn t address ACL tampering and some of the other things, it does represent a significant help with the most significant concern. However, tailnet lock is in alpha, only available on the Enterprise plan, and has a waitlist, so I have been unable to test it. Any Tailscale node can request the IP addresses belonging to any other Tailscale node. The Tailscale control plane captures, and exposes to you, this information about every node in your network: the OS hostname, IP addresses and port numbers, operating system, creation date, last seen timestamp, and NAT traversal parameters. You can optionally enable service data capture as well, which sends data about open ports on each node to the control plane. Tailscale likes to highlight their key expiry and rotation feature. By default, all keys expire after 180 days, and traffic to and from the expired node will be interrupted until they are renewed (basically, you re-login with your provider and do a renew operation). Unfortunately, the only mention I can see of warning of impeding expiration is in the Windows client, and even there you need to edit a registry key to get the warning more than the default 24 hours in advance. In short, it seems likely to cut off communications when it s most important. You can disable key expiry on a per-node basis in the admin console web interface, and I mostly do, due to not wanting to lose connectivity at an inopportune time.

Tailscale: Connectivity and NAT traversal When thinking about reliability, the primary consideration here is being able to reach the Tailscale control plane. While it is possible in limited circumstances to reach nodes without the Tailscale control plane, it is a fairly brittle setup and notably will not survive a client restart. So if you use Tailscale to reach other nodes on your LAN, that won t work unless your Internet is up and the control plane is reachable. Assuming your Internet is up and Tailscale s infrastructure is up, there is little to be concerned with. Your own comfort level with cloud providers and your Internet should guide you here. Tailscale wrote a fantastic article about NAT traversal and they, predictably, do very well with it. Tailscale prefers UDP but falls back to TCP if needed. Broker (DERP) servers step in as a last resort, and Tailscale clients automatically select the best ones. I m not aware of anything that is more successful with NAT traversal than Tailscale. This maximizes the situations in which a direct P2P connection can be used without a broker. I have found Tailscale to be a bit slow to notice changes in network topography compared to Yggdrasil, and sometimes needs a kick in the form of restarting the client process to re-establish communications after a network change. However, it s possible (maybe even probable) that if I d waited a bit longer, it would have sorted this all out.

Tailscale: Sharing with friends I touched on the funnel feature earlier. The sharing feature lets you give an invite to an outsider. By default, a person accepting a share can make only outgoing connections to the network they re invited to, and cannot receive incoming connections from that network this makes sense. When sharing an exit node, you get a checkbox that lets you share access to the exit node as well. Of course, the person accepting the share needs to install the Tailnet client. The combination of funnel and sharing make Tailscale the best for ad-hoc sharing.

Tailscale: DNS Tailscale s DNS is called MagicDNS. It runs as a layer atop your standard DNS taking over /etc/resolv.conf on Linux and provides resolution of mesh hostnames and some other features. This is a concept that is pretty slick. It also is a bit flaky on Linux; dueling programs want to write to /etc/resolv.conf. I can t really say this is entirely Tailscale s fault; they document the problem and some workarounds. I would love to be able to add custom records to this service; for instance, to override the public IP for a service to use the in-mesh IP. Unfortunately, that s not yet possible. However, MagicDNS can query existing nameservers for certain domains in a split DNS setup.

Tailscale: Source code, pricing, and portability Tailscale is almost fully open source and the client is highly portable. The client is open source (BSD 3-clause) on open source platforms, and closed source on closed source platforms. The DERP servers are open source. The coordination server is closed source, although there is an open source coordination server called Headscale (also BSD 3-clause) made available with Tailscale s blessing and informal support. It supports most, but not all, features in the Tailscale coordination server. Tailscale s pricing (which does not apply when using Headscale) provides a free plan for 1 user with up to 20 devices. A Personal Pro plan expands that to 100 devices for $48 per year - not a bad deal at $4/mo. A Community on Github plan also exists, and then there are more business-oriented plans as well. See the pricing page for details. As a small note, I appreciated Tailscale s install script. It properly added Tailscale s apt key in a way that it can only be used to authenticate the Tailscale repo, rather than as a systemwide authenticator. This is a nice touch and speaks well of their developers.

Tailscale conclusions Tailscale is tops in sharing and has a broad feature set and excellent documentation. Like other solutions with a centralized control plane, device communications can stop working if the control plane is unreachable, and the threat model of the control plane should be carefully considered.

Zerotier Zerotier is a close competitor to Tailscale, and is similar to it in a lot of ways. So rather than duplicate all of the Tailscale information here, I m mainly going to describe how it differs from Tailscale. The primary difference between the two is that Zerotier emulates an Ethernet network via a Linux tap interface, while Tailscale emulates a TCP/IP network via a Linux tun interface. However, Zerotier has a number of things that make it be a somewhat imperfect Ethernet emulator. For one, it has a problem with broadcast amplification; the machine sending the broadcast sends it to all the other nodes that should receive it (up to a set maximum). I wouldn t want to have a lot of programs broadcasting on a slow link. While in theory this could let you run Netware or DECNet across Zerotier, I m not really convinced there s much call for that these days, and Zerotier is clearly IP-focused as it allocates IP addresses and such anyhow. Zerotier provides special support for emulated ARP (IPv4) and NDP (IPv6). While you could theoretically run Zerotier as a bridge, this eliminates the zero trust principle, and Tailscale supports subnet routers, which provide much of the same feature set anyhow. A somewhat obscure feature, but possibly useful, is Zerotier s built-in support for multipath WAN for the public interface. This actually lets you do a somewhat basic kind of channel bonding for WAN.

Zerotier: Security and Privacy The picture here is similar to Tailscale, with the difference that you can create a Zerotier-local account rather than relying on cloud authentication. I was unable to find as much detail about Zerotier as I could about Tailscale - notably I couldn t find anything about how sticky an IP address is. However, the configuration screen lets me delete a node and assign additional arbitrary IPs within a subnet to other nodes, so I think the assumption here is that if your Zerotier account (or the Zerotier control plane) is compromised, an attacker could remove a legit device, add a malicious one, and assign the previous IP of the legit device to the malicious one. I m not sure how to mitigate against that risk, as firewalling specific IPs is ineffective if an attacker can simply take them over. Zerotier also lacks anything akin to Tailnet Lock. For this reason, I didn t proceed much further in my Zerotier evaluation.

Zerotier: Connectivity and NAT traversal Like Tailscale, Zerotier has NAT traversal with STUN. However, it looks like it s more limited than Tailscale s, and in particular is incompatible with double NAT that is often seen these days. Zerotier operates brokers ( root servers ) that can do relaying, including TCP relaying. So you should be able to connect even from hostile networks, but you are less likely to form a P2P connection than with Tailscale.

Zerotier: Sharing with friends I was unable to find any special features relating to this in the Zerotier documentation. Therefore, it would be at the same level as Yggdrasil: possible, maybe even not too difficult, but without any specific help.

Zerotier: DNS Unlike Tailscale, Zerotier does not support automatically adding DNS entries for your hosts. Therefore, your options are approximately the same as Yggdrasil, though with the added option of pushing configuration pointing to your own non-Zerotier DNS servers to the client.

Zerotier: Source code, pricing, and portability The client ZeroTier One is available on Github under a custom business source license which prevents you from using it in certain settings. This license would preclude it being included in Debian. Their library, libzt, is available under the same license. The pricing page mentions a community edition for self hosting, but the documentation is sparse and it was difficult to understand what its feature set really is. The free plan lets you have 1 user with up to 25 devices. Paid plans are also available.

Zerotier conclusions Frankly I don t see much reason to use Zerotier. The virtual Ethernet model seems to be a weird hybrid that doesn t bring much value. I m concerned about the implications of a compromise of a user account or the control plane, and it lacks a lot of Tailscale features (MagicDNS and sharing). The only thing it may offer in particular is multipath WAN, but that s esoteric enough and also solvable at other layers that it doesn t seem all that compelling to me. Add to that the strange license and, to me anyhow, I don t see much reason to bother with it.

Netmaker Netmaker is one of the projects that is making noise these days. Netmaker is the only one here that is a wrapper around in-kernel Wireguard, which can make a performance difference when talking to peers on a 1Gbps or faster link. Also, unlike other tools, it has an ingress gateway feature that lets people that don t have the Netmaker client, but do have Wireguard, participate in the VPN. I believe I also saw a reference somewhere to nodes as routers as with Yggdrasil, but I m failing to dig it up now. The project is in a bit of an early state; you can sign up for an upcoming closed beta with a SaaS host, but really you are generally pointed to self-hosting using the code in the github repo. There are community and enterprise editions, but it s not clear how to actually choose. The server has a bunch of components: binary, CoreDNS, database, and web server. It also requires elevated privileges on the host, in addition to a container engine. Contrast that to the single binary that some others provide. It looks like releases are frequent, but sometimes break things, and have a somewhat more laborious upgrade processes than most. I don t want to spend a lot of time managing my mesh. So because of the heavy needs of the server, the upgrades being labor-intensive, it taking over iptables and such on the server, I didn t proceed with a more in-depth evaluation of Netmaker. It has a lot of promise, but for me, it doesn t seem to be in a state that will meet my needs yet.

Nebula Nebula is an interesting mesh project that originated within Slack, seems to still be primarily sponsored by Slack, but is also being developed by Defined Networking (though their product looks early right now). Unlike the other tools in this section, Nebula doesn t have a web interface at all. Defined Networking looks likely to provide something of a SaaS service, but for now, you will need to run a broker ( lighthouse ) yourself; perhaps on a $5/mo VPS. Due to the poor firewall traversal properties, I didn t do a full evaluation of Nebula, but it still has a very interesting design.

Nebula: Security and Privacy Since Nebula lacks a traditional control plane, the root of trust in Nebula is a CA (certificate authority). The documentation gives this example of setting it up:
./nebula-cert sign -name "lighthouse1" -ip "192.168.100.1/24"
./nebula-cert sign -name "laptop" -ip "192.168.100.2/24" -groups "laptop,home,ssh"
./nebula-cert sign -name "server1" -ip "192.168.100.9/24" -groups "servers"
./nebula-cert sign -name "host3" -ip "192.168.100.10/24"
So the cert contains your IP, hostname, and group allocation. Each host in the mesh gets your CA certificate, and the per-host cert and key generated from each of these steps. This leads to a really nice security model. Your CA is the gatekeeper to what is trusted in your mesh. You can even have it airgapped or something to make it exceptionally difficult to breach the perimeter. Nebula contains an integrated firewall. Because the ability to keep out unwanted nodes is so strong, I would say this may be the one mesh VPN you might consider using without bothering with an additional on-host firewall. You can define static mappings from a Nebula mesh IP to a clearnet IP. I haven t found information on this, but theoretically if NAT traversal isn t required, these static mappings may allow Nebula nodes to reach each other even if Internet is down. I don t know if this is truly the case, however.

Nebula: Connectivity and NAT traversal This is a weak point of Nebula. Nebula sends all traffic over a single UDP port; there is no provision for using TCP. This is an issue at certain hotel and other public networks which open only TCP egress ports 80 and 443. I couldn t find a lot of detail on what Nebula s NAT traversal is capable of, but according to a certain Github issue, this has been a sore spot for years and isn t as capable as Tailscale. You can designate nodes in Nebula as brokers (relays). The concept is the same as Yggdrasil, but it s less versatile. You have to manually designate what relay to use. It s unclear to me what happens if different nodes designate different relays. Keep in mind that this always happens over a UDP port.

Nebula: Sharing with friends There is no particular support here.

Nebula: DNS Nebula has experimental DNS support. In contrast with Tailscale, which has an internal DNS server on every node, Nebula only runs a DNS server on a lighthouse. This means that it can t forward requests to a DNS server that s upstream for your laptop s particular current location. Actually, Nebula s DNS server doesn t forward at all. It also doesn t resolve its own name. The Nebula documentation makes reference to using multiple lighthouses, which you may want to do for DNS redundancy or performance, but it s unclear to me if this would make each lighthouse form a complete picture of the network.

Nebula: Source code, pricing, and portability Nebula is fully open source (MIT). It consists of a single Go binary and configuration. It is fairly portable.

Nebula conclusions I am attracted to Nebula s unique security model. I would probably be more seriously considering it if not for the lack of support for TCP and poor general NAT traversal properties. Its datacenter connectivity heritage does show through.

Roll your own and hybrid Here is a grab bag of ideas:

Running Yggdrasil over Tailscale One possibility would be to use Tailscale for its superior NAT traversal, then allow Yggdrasil to run over it. (You will need a firewall to prevent Tailscale from trying to run over Yggdrasil at the same time!) This creates a closed network with all the benefits of Yggdrasil, yet getting the NAT traversal from Tailscale. Drawbacks might be the overhead of the double encryption and double encapsulation. A good Yggdrasil peer may wind up being faster than this anyhow.

Public VPN provider for NAT traversal A public VPN provider such as Mullvad will often offer incoming port forwarding and nodes in many cities. This could be an attractive way to solve a bunch of NAT traversal problems: just use one of those services to get you an incoming port, and run whatever you like over that. Be aware that a number of public VPN clients have a kill switch to prevent any traffic from egressing without using the VPN; see, for instance, Mullvad s. You ll need to disable this if you are running a mesh atop it.

Other

Combining with local firewalls For most of these tools, I recommend using a local firewal in conjunction with them. I have been using firehol and find it to be quite nice. This means you don t have to trust the mesh, the control plane, or whatever. The catch is that you do need your mesh VPN to provide strong association between IP address and node. Most, but not all, do.

Performance I tested some of these for performance using iperf3 on a 2.5Gbps LAN. Here are the results. All speeds are in Mbps.
Tool iperf3 (default) iperf3 -P 10 iperf3 -R
Direct (no VPN) 2406 2406 2764
Wireguard (kernel) 1515 1566 2027
Yggdrasil 892 1126 1105
Tailscale 950 1034 1085
Tinc 296 300 277
You can see that Wireguard was significantly faster than the other options. Tailscale and Yggdrasil were roughly comparable, and Tinc was terrible.

IP collisions When you are communicating over a network such as these, you need to trust that the IP address you are communicating with belongs to the system you think it does. This protects against two malicious actor scenarios:
  1. Someone compromises one machine on your mesh and reconfigures it to impersonate a more important one
  2. Someone connects an unauthorized system to the mesh, taking over a trusted IP, and uses the privileges of the trusted IP to access resources
To summarize the state of play as highlighted in the reviews above:
  • Yggdrasil derives IPv6 addresses from a public key
  • tinc allows any node to set any IP
  • Tailscale IPs aren t user-assignable, but the assignment algorithm is unknown
  • Zerotier allows any IP to be allocated to any node at the control plane
  • I don t know what Netmaker does
  • Nebula IPs are baked into the cert and signed by the CA, but I haven t verified the enforcement algorithm
So this discussion really only applies to Yggdrasil and Tailscale. tinc and Zerotier lack detailed IP security, while Nebula expects IP allocations to be handled outside of the tool and baked into the certs (therefore enforcing rigidity at that level). So the question for Yggdrasil and Tailscale is: how easy is it to commandeer a trusted IP? Yggdrasil has a brief discussion of this. In short, Yggdrasil offers you both a dedicated IP and a rarely-used /64 prefix which you can delegate to other machines on your LAN. Obviously by taking the dedicated IP, a lot more bits are available for the hash of the node s public key, making collisions technically impractical, if not outright impossible. However, if you use the /64 prefix, a collision may be more possible. Yggdrasil s hashing algorithm includes some optimizations to make this more difficult. Yggdrasil includes a genkeys tool that uses more CPU cycles to generate keys that are maximally difficult to collide with. Tailscale doesn t document their IP assignment algorithm, but I think it is safe to say that the larger subnet you use, the better. If you try to use a /24 for your mesh, it is certainly conceivable that an attacker could remove your trusted node, then just manually add the 240 or so machines it would take to get that IP reassigned. It might be a good idea to use a purely IPv6 mesh with Tailscale to minimize this problem as well. So, I think the risk is low in the default configurations of both Yggdrasil and Tailscale (certainly lower than with tinc or Zerotier). You can drive the risk even lower with both.

Final thoughts For my own purposes, I suspect I will remain with Yggdrasil in some fashion. Maybe I will just take the small performance hit that using a relay node implies. Or perhaps I will get clever and use an incoming VPN port forward or go over Tailscale. Tailscale was the other option that seemed most interesting. However, living in a region with Internet that goes down more often than I d like, I would like to just be able to send as much traffic over a mesh as possible, trusting that if the LAN is up, the mesh is up. I have one thing that really benefits from performance in excess of Yggdrasil or Tailscale: NFS. That s between two machines that never leave my LAN, so I will probably just set up a direct Wireguard link between them. Heck of a lot easier than trying to do Kerberos! Finally, I wrote this intending to be useful. I dealt with a lot of complexity and under-documentation, so it s possible I got something wrong somewhere. Please let me know if you find any errors.
This blog post is a copy of a page on my website. That page may be periodically updated.

13 April 2023

Russ Allbery: Review: Once Upon a Tome

Review: Once Upon a Tome, by Oliver Darkshire
Publisher: W.W. Norton & Company
Copyright: 2022
Printing: 2023
ISBN: 1-324-09208-4
Format: Kindle
Pages: 243
The full title page of this book, in delightful 19th century style, is:
Once Upon a Tome: The Misadventures of a Rare Bookseller, wherein the theory of the profession is partially explained, with a variety of insufficient examples, by Oliver Darkshire. Interspersed with several diverting FOOTNOTES of a comical nature, ably ILLUSTRATED by Rohan Eason, PUBLISHED by W.W. Norton, and humbly proposed to the consideration of the public in this YEAR 2023
That may already be enough to give you a feel for this book. Oliver Darkshire works for Sotheran's Rare Books and Prints in London, most notably running their highly entertaining Twitter account. This is his first book. If you have been hanging out in the right corners of Twitter, you have probably been anticipating the release of this book, and may already have your own copy. If you have not (and to be honest it's increasingly dubious whether there are right corners of Twitter left), you're in for a treat. Darkshire has made Sotheran's a minor Twitter phenomenon due to tweets like this:
CUSTOMER: oh thank heavens I have been searching for a rare book expert with the knowledge to solve my complex problem ME (extremely and unhelpfully specialized): ok well the words are usually on the inside and I can see that's true here, so that's a good start I find I know lots of things until anyone asks me about it or there is a question to answer, at which point I know nothing, I am a void, a tragic bucket of ignorance
My hope was that Once Upon a Tome would be the same thing at book length, and I am delighted to report that's exactly what it is. By the time I finished reading the story of Darkshire's early training, I knew I was going to savor every word.
The hardest part, though, lies in recording precisely in what ways a book has survived the ravages of time. An entire lexicon of book-related terminology has evolved over hundreds of years for exactly this purpose terminology that means absolutely nothing to the average observer. It's traditional to adopt this baroque language when describing your books, for two reasons. The first is that the specific language of the book trade allows you to be exceedingly accurate and precise without using hundreds of words, and the second is that the elegance of it serves to dull the blow a little. Most rare books come with some minor defects, but that doesn't mean one has to be rude about it.
You will learn something about rare book selling in this book, and more about Darkshire's colleagues, but primarily this is a book-length attempt to convey the slightly uncanny experience of working in a rare bookstore in an entertaining way. Also, to be fully accurate, it is an attempt shift the bookstore sideways in the reader's mind into a fantasy world that mostly but not entirely parallels ours; as the introduction mentions, this is not a strictly accurate day-by-day account of life at the store, and stories have been altered and conflated in the telling. Rare bookselling is a retail job but a rather strange one, with its own conventions and unusual customers. Darkshire memorably divides rare book collectors into Smaugs and Draculas: Smaugs assemble vast lairs of precious items, Draculas have one very specific interest, and one's success at selling a book depends on identifying which type of customer one is dealing with. Like all good writing about retail jobs, half of the fun is descriptions of the customers.
The Suited Gentlemen turn up annually, smartly dressed in matching suits and asking to see any material we have on Ayn Rand. Faces usually obscured by large dark glasses, they move without making a sound, and only travel in pairs. Sometimes they will bark out a laugh at nothing in particular, as if mimicking what they think humans do.
There are more facets than the typical retail job, though, since the suppliers of the rare book trade (book runners, estate sales, and collectors who have been sternly instructed by spouses to trim down their collections) are as odd and varied as the buyers. This sort of book rests entirely on the sense of humor of the author, and I thought Darkshire's approach was perfect. He has the knack of poking fun at himself as much as he pokes fun at anyone around him. This book conveys an air of perpetual bafflement at stumbling into a job that suits him as well as this one does, praise of the skills of his coworkers, and gently self-deprecating descriptions of his own efforts. Combine that with well-honed sentences, a flair for brief and memorable description, and an accurate sense of how long a story should last, and one couldn't ask for more from this style of book.
The book rest where the bible would be held (leaving arms free for gesticulation) was carved into the shape of a huge wooden eagle. I m given to understand this is the kind of eloquent and confusing metaphor one expects in a place of worship, as the talons of the divine descend from above in a flurry of wings and death, but it seemed to alarm people to come face to face with the beaked fury of God as they entered the bookshop.
I've barely scratched the surface of great quotes from this book. If you like rare books, bookstores, or even just well-told absurd stories of working a retail job, read this. It reminds me of True Porn Clerk Stories, except with much less off-putting subject matter and even better writing. (Interestingly to me, it also shares with those stories, albeit for different reasons, a more complicated balance of power between the retail worker and the customer than the typical retail establishment.) My one wish is that I would have enjoyed more specific detail about the rare books themselves, since Darkshire only rarely describes successful retail transactions. But that's only a minor quibble. This was a pure delight from cover to cover and exactly what I was hoping for when I preordered it. Highly recommended. Rating: 9 out of 10

12 April 2023

Jonathan Dowland: blog after death

I've been pondering what should happen to personal websites once the owner has passed, or otherwise "moved on". Some time ago I stumbled across a blog by Kev Quirk, who wrote
I d need to come up with contingency plans for...This website, and any other websites and own/manage
I thought it was a strange idea, to have a contingency plan for a personal site to survive its writer. Even a site such as my own, which (as sites go) would be trivial to host/mirror (since it's static), who would want to do that? Why would they do that? On the other hand, whether something I've written is useful or not is largely independent of whether I'm alive and well. And if anything I've written is useful independently from me (to pick a recent example, my notes on imaging optical media), should it persist somewhere? I've long thought of personal sites much like any website, which is to say, implicitly eternal, despite mountains of evidence that practically the reverse is true. I was influenced a long time ago by the article Cool URIs don't change. Thinking more about "digital legacy" led me to start believing that personal sites are ultimately not the right place for any kind of content that should have some persistence. (You might well have started with that assumption!) Yesterday via Planet Debian I read Aur lien Jarno's recent blog post where they have deprecated all of their personal site bar their blog. Quoting Aur lien:
Wikipedia is a much better platform for sharing knowledge than random websites.
This struck me as an interesting idea. Wikipedia is a reasonable place for a lot of material that might otherwise be hosted on personal sites, and as a "living website", content can be adapted, corrected, etc. over time. Wikipedia is clearly not the right place for much other material that might exist on personal sites (it's not the right place for my aforementioned article). I'm not sure where might be. Perhaps we, as a culture, need to move away from the notion of personal sites, and devise a more collective concept. Or perhaps it's no bad thing that, without intervention, this stuff disappears.

Jamie McClelland: Doing whatever Gmail says

As we slowly move our members to our new email infrastructure, an unexpected twist turned up: One member reported getting the Gmail warning:
Be careful with this message The sender hasn t authenticated this message so Gmail can t verify that it actually came from them.
They have their email delivered to May First, but have configured Gmail to pull in that email using the Check mail from other accounts feature. It worked fine on our old infrastructure, but started giving this message when we transitioned. A further twist: he only receives this message from email sent by other people in his organization - in other words email sent via May First gets flagged, email sent from other people does not. These Gmail messages typically warn users about email that has failed (or lacks) both SPF and DKIM. However, before diving into the technical details, my first thought was: why is Gmail giving a warning on a message that wasn t even delivered to them? It s always nice to get confirmation from others that this is totally wrong behavior. Unfortunately, when it s Gmail, it doesn t matter if they are wrong. We all have to deal with it. So next, I decided to investigate why this message failed both DKIM (digital signature) and SPF (ensuring the message was sent from an authorized server). Examining the headers immediately turned up the SPF failure:
Authentication-Results: mx.google.com;
       spf=fail (google.com: domain of xxx@xxx.org does not designate n.n.n.n as permitted sender) smtp.mailfrom=xxx@xxx.org
The IP address Google checked to ensure the message was sent by an authorized server is the IP address of our internal mail filter server in our new email infrastructure. That s the last hop before delivery to the user s mailbox, so that s the last hop Gmail sees. This is why Gmail is totally wrong to run this check: all email messages retreived via their mail fecthing service are going to fail the SPF test because Gmail has no way of knowing what the actual last hop is. So why is this problem only showing up after we transitioned to our new infrastructure? Because our old infrastructure had only one mail server for every user. The one mail server was the MX server and the relay server, so it was included in their SPF record. And why does this only affect mail sent via May First and not other domains? Because we add our DKIM signature to outgoing email, not to email delivered internally. Therefore, these messages both fail the SPF check and also don t have a DKIM signature. Other messages have a DKIM signature. Ugggg. So what do we do now? Clearly, something dumb and simple is in order: I added the IP addresses of our internal filter servers to our global SPF record. Someday, years from now, after Gmail is long gone (or has fixed this dumb behavior), when I m doing whatever retired people like me do, someone will notice that our internal filter server IPs are included in our SPF record. Hopefully they will fix the problem, but instead they ll probably think: no idea why these are here - something will probably break if I remove them.

Next.

Previous.