Search Results: "beh"

23 December 2020

John Goerzen: Every Storm Runs Out Of Rain

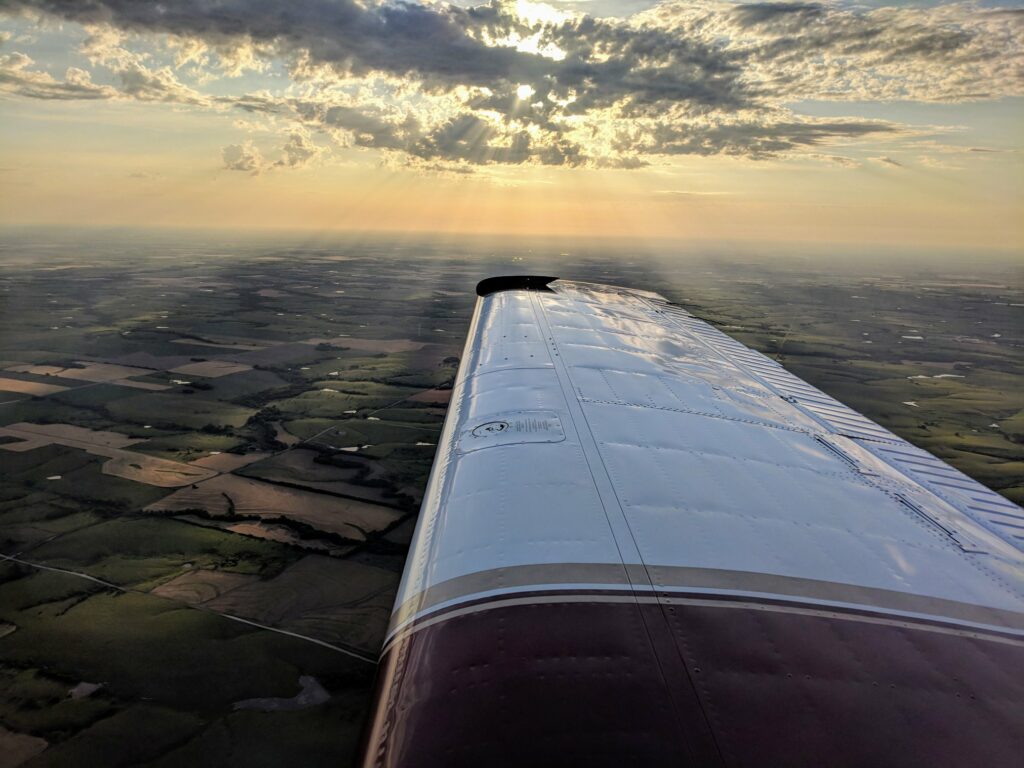
Every storm runs out of rain. Maya Angelou
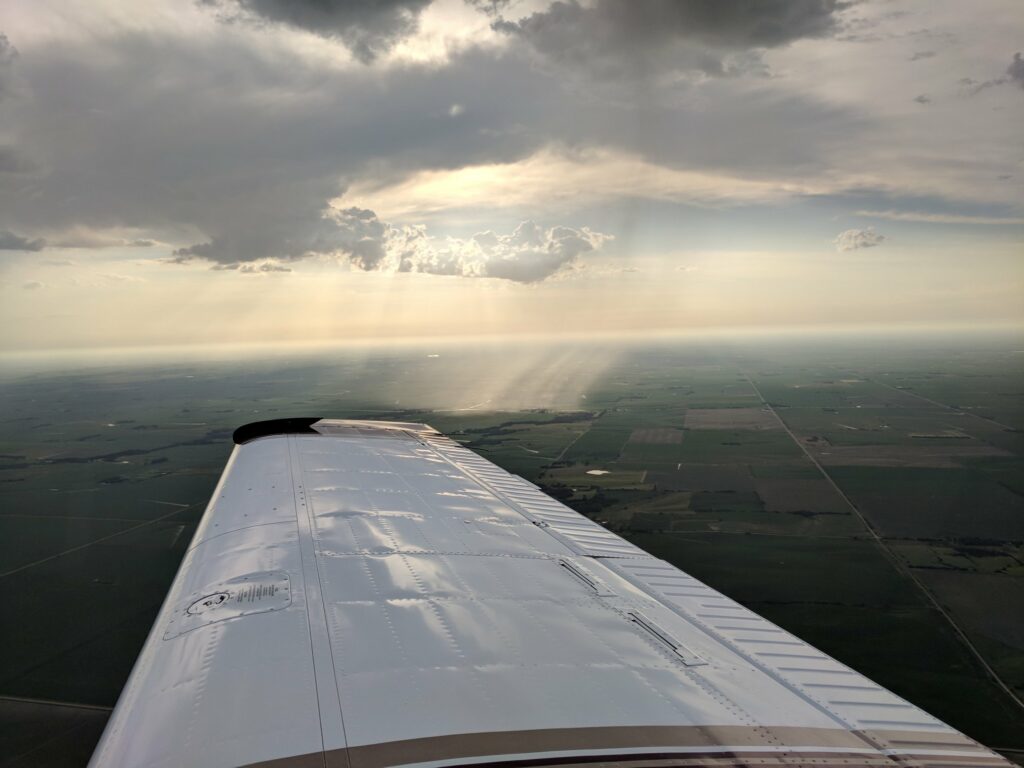
There are a lot of rain clouds in life these days. May we all remember that days like this one are behind us and also ahead of us. Every storm runs out of rain.
That was the start of a series of photos from my collection & quotes I shared with friends during the initial lockdown in spring. I ll be sharing some here. And here we all are, still dealing with this and it s more severe in a lot of ways. One of my colleagues won t be able to see his parents this Christmas for the first time in over 40 years. But this storm will run out rain. And look how the scene changed, in just a few minutes. This is coming!

21 December 2020

Russ Allbery: Review: Behind the Throne

Review: Behind the Throne, by K.B. Wagers
Series: Indranan War #1
Publisher: Orbit
Copyright: August 2016
ISBN: 0-316-30859-5
Format: Kindle
Pages: 416
Hail is a gunrunner, an outlaw and criminal, someone who knows how to survive violence and navigate by personal loyalty. That world knows her as Cressen Stone. What her colleagues don't know is that she's also an Imperial Princess. Hailimi Mercedes Jaya Bristol left that world twenty years earlier in secret pursuit of her father's killer and had no intention of returning. But her sisters are dead, her mother's health is failing, and two Imperial Trackers have been sent to bring her back to her rightful position as heir. I'm going to warn up-front that the first half of this novel was rough to the point of being unreadable. Wagers tries much too hard to establish Hail as a reluctant heroine torn between her dislike of royal protocols and her grief and anger at the death of her sisters. The result is excessively melodramatic and, to be frank, badly written. There are a lot of passages like this:
His words slammed into me, burning like the ten thousand volts of a Solarian Conglomerate police Taser.
(no, there's no significance to the Solarian Conglomerate here), or, just three paragraphs later:
The air rushed out of my lungs. Added grief for a niece I'd never known. One more log on the pyre set to burn my freedom to ashes. The hope I'd had of getting out of this mess was lost in that instant, and I couldn't do anything but stare at Emmory in abject shock.
Given how much air rushes out of Hail's lungs and how often she's struck down with guilt or grief, it's hard to believe she doesn't have brain damage. Worse, Hail spends a great deal of the first third of the book whining, which given that the book is written in first person gets old very quickly. Every emotion is overwritten and overstressed as Hail rails against obvious narrative inescapability. It's blatantly telegraphed from the first few pages that Hail is going to drop into the imperial palace like a profane invasion force and shake everything up, but the reader has to endure far too long of Hail being dramatically self-pitying about the plot. I almost gave up on this book in irritation (and probably should have). And then it sort of grew on me, because the other thing Wagers is doing (also not subtly) is a story trope for which I have a particular weakness: The fish out of water who nonetheless turns out to be the person everyone needs because she's systematically and deliberately kind and thoughtful while not taking any shit. Hail left Pashati young and inexperienced, with a strained relationship with her mother and a habit of letting her temper interfere with her ability to negotiate palace politics. She still has the temper, but age, experience, and confidence mean that she's decisive and confident in a way she never was before. The second half of this book is about Hail building her power base and winning loyalty by being loyal and decent. It's still not great writing, but there's something there I enjoyed reading. Wagers's setting is intriguing, although it makes me a bit nervous. The Indranan Empire was settled by colonists of primarily Indian background. The court trappings, mythology, and gods referenced in Behind the Throne are Hindu-derived, and I suspect (although didn't confirm) that the funeral arrangements are as well. Formal wear (and casual wear) for women is a sari. There's a direct reference to the goddess Lakshimi (not Lakshmi, which Wikipedia seems to indicate is the correct spelling, although transliteration is always an adventure). I was happy to see this, since there are more than enough SF novels out there that seem to assume only western countries go into space. But I'm never sure whether the author did enough research or has enough personal knowledge to pull off the references correctly, and I personally wouldn't know the difference. The Indranan Empire is also matriarchal, and here Wagers goes for an inversion of sexism that puts men in roughly the position women were in the 1970s. They can, in theory, do most jobs, but there are many things they're expected not to do, there are some explicit gender lines in power structures, and the role of men in society is a point of political conflict. It's skillfully injected as social background, with a believable pattern of societal prejudice that doesn't necessarily apply to specific men in specific situations. I liked that Wagers did this without giving the Empire itself any feminine-coded characteristics. All admirals are women because the characters believe women are obviously better military leaders, not because of some claptrap about nurturing or caring or some other female-coded reason from our society. That said, this gender role inversion didn't feel that significant to the story. The obvious "sexism is bad, see what it would be like if men were subject to it" message ran parallel to the main plot and never felt that insightful to me. I'm therefore not sure it was successful or worth the injection of sexism into the reading experience, although it certainly is different from the normal fare of space empires. I can't recommend Behind the Throne because a lot of it just isn't very good. But I still kind of want to because I sincerely enjoyed the last third of the book, despite some lingering melodrama. Watching Hail succeed by being a decent, trustworthy, loyal, and intelligent person is satisfying, once she finally stops whining. The destination is probably not worth the journey, but now that I've finished the first book, I'm tempted to grab the second. Followed by After the Crown. Rating: 6 out of 10

16 December 2020

John Goerzen: Non-Creepy Technology Purchasing & Gifting Guides

This time of year, a lot of people are thinking of buying gadgets and phones as gifts. But there are a lot of tech companies that have unethical practices, from terrible working conditions in their factories to spying on their users. Here are some buying guides to help you find gadgets that are fun and not creepy. The Free Software Foundation s Ethical Tech Giving Guide is a fantastic resource from what s probably the pickiest organization out there when it comes to tech. Not only do they highlight good devices, they also explain why and why you should, for instance, avoid the iPhone (their history of silencing political activists and spying on users). The FSF also has a Guide to DRM-Free Living talks about books, video, audio, and software that respects your freedom by letting you make your own backups, move it to other devices, and continue to use your purchases even if you have no Internet or the company you bought them from goes bankrupt. This is a fantastic and HUGE resource; there are hundreds of organizations out there that provide content in a way that respects your rights and many of them do it for free, legally, as well. PrivacyTools has a fantastic series of guides on everything from email providers to operating systems, as well as links to a number of other guides. The DeGoogle wiki on Reddit (as well as the sidebar) has a lot of fantastic alternatives to things like Chromebooks, Chrome, Gmail, etc. Related resources Here are some resources for education (what the issues are) and information about what companies and products to avoid. In addition to the FSF s other fantastic resources above, they also have a list of proprietary malware. It lists things, practices, and companies to avoid, and talks about the reasons why. Their addictions page is particularly good and relevant to my recent post on the problems of the attention economy. The Surveillance Self-Defense site from the Electronic Frontier Foundation is a fantastic introduction into how corporate surveillance works and how to defend against it. Use with a grain of salt: Mozilla, the people behind Firefox, have a site called Privacy Not Included that rates products by how creepy they are. They focus more narrowly on privacy than the more expansive set of freedoms the FSF considers (privacy is one of a number of things the FSF looks at), and in some cases I would say Mozilla is too generous (eg, with the Amazon Kindle, a number of their data points are just incorrect.)

14 December 2020

Russ Allbery: rra-c-util 8.4

I've released a new version of my collection of utility libraries, Autoconf macros, and similar support infrastructure, primarily to include changes in the upcoming remctl and INN releases. Highlights: The general support policy for rra-c-util is now that I will drop support for systems older than fifteen years if it becomes annoying to support them. That's still extremely conservative, but may let me drop some more support code that is essentially never used. The replacements for missing IPv6 functions are probably next on the chopping block. Thanks to Julien LIE and Bo Lindbergh for their contributions to this release. You can get the latest release from the rra-c-util distribution page.

13 December 2020

Russ Allbery: Review: Because Internet

Review: Because Internet, by Gretchen McCulloch
Publisher: Riverhead Books
Copyright: 2019
ISBN: 0-7352-1095-0
Format: Kindle
Pages: 276
If you're familiar with linguistics as a field of scientific study (as opposed to the tool-based fields of grammar or writing advice), you'll be familiar with the dichotomy between written and spoken language. We may spend more time thinking about written language since it is central to most types of education and carries much of the intellectual and social weight of society. Linguists, however, see spoken language as more fundamental, since speech is wired into our brains and universal in human societies. Written language is a recent and somewhat artificial invention. One also learns from linguistics that spoken language does not follow many of the rules of written language that we painstakingly memorized in school. In casual speech, people split infinitives, speak in partial and run-on sentences, ignore nit-picking pronoun case rules, and rarely notice or care about the difference between less and fewer. Spoken language does have rules, but they're more subtle and nuanced than the grammar rules we learn in school. (I think the real fun of linguistics is separating the rules that native speakers follow effortlessly from the artificial rules used as education markers.) This is, in part, because nearly all spoken language is informal, whereas nearly all written language is formal. Enter the Internet, and enter this book. For the first time in human history we have both an explosion of informal writing and easy availability of that writing to linguists for study. Informal writing is not entirely new, of course. We've had personal letters for nearly as long as we've had writing, not to mention private notes, diaries, and other writing intended for tiny audiences. But consider who wrote private letters and, on top of that historical filter, whose private letters were preserved for linguistic research. Until relatively recently, only the upper classes were literate and had access to the infrastructure to write and send letters. Someone's letters or private notes were unlikely to be preserved unless they were someone famous and important, and thus often well-educated and more likely to take a more formal tone in writing. If you compare this to the Internet-driven blizzard of work and personal email, SMS conversations, chatrooms, and social media posts, the difference is obvious in both volume and level of informality. We're all on the Internet, we all read and write with a frequency that would be staggering to the average person from even fifty years ago, and while one may take a bit of additional care with a tricky email to one's manager, the SMS message to one's friend is as informal of a use of language as a conversation over coffee. Gretchen McCulloch is a professional linguist and Because Internet is about exactly this phenomenon: the new conventions of informal writing, how it has changed and evolved, and the new subtleties and shortcuts we've invented to make written communication easier. That goes beyond words and grammar to encompass punctuation, emoji and emoticons, memes and reaction gifs, and even the subtleties of timing, whitespace, and the construction of virtual places via our choices in how and where we write. This topic is my catnip, so it's not surprising I love this book. I've been heavily involved with online communities that communicate in writing since 1993 (making me, in McCulloch's classification, an Old Internet Person; each wave of introduction to the Internet has its own conventions that can be in conflict with later waves). I've now spent more than half my life carrying out most of my social activity and most of my closest friendships primarily in writing, so I found a lot of satisfaction in a linguistic study that takes that seriously rather than treating it as a curiosity. But, even better, I was amazed at how much I didn't know, in part because I am from a specific wave. I have a deep intuition for the Usenet conventions, but not as good of an understanding of the ones from AIM and LiveJournal one wave later (the Full Internet People). And I had a lot to learn about the conventions of the Instagram and Snapchat cluster (the Post Internet People, who have never known life without the Internet). One of the things that struck me while reading this book is how most of the language innovations that McCulloch describes are addressing the old complaint that written communication is inferior to face-to-face conversation because it lacks emotional nuance. My knee-jerk reply is that, no, written communication is full of emotional nuance and the complainer is just bad at reading it, but that's somewhat unfair. A better statement of the problem is that there is not a standardized language for emotional nuance in written communication, in part because it's so new in human history. Most humans are extremely good at reading facial expressions and body language for emotional cues, and those physical expressions are largely subconscious, reliable, and similar among different people (particularly within a culture; one can get in trouble with body language variations across cultures). This is not true of writing. With friends I've talked to over chat for twenty-five years, I can read volumes about their emotional state in a couple of short lines of text. But with strangers, despite decades of Internet communications, I will still misread cues and misinterpret simple intentions. The other standard response to this complaint is that it is possible to put extensive emotional nuance into formal writing. Just get better at writing! This is true, but unhelpful. There's a reason why we give book contracts to people who are very good at investing formal writing with emotional nuance. It's difficult, time-consuming, and requires a great deal of practice. That may be appropriate for formal, paid writing, but it won't do for informal writing, which by definition needs to be as effortless as possible. It's therefore unsurprising that once millions of people were using the Internet regularly for informal writing, they started adding new mechanisms, shortcuts, and conventions for emotional nuance. The standardization is growing, but conventions still vary widely between waves of Internet users. One of the most fascinating parts of this book for me was McCulloch's explanation of why periods (and, to a lesser extent, capital letters) in short chat messages are perceived by younger users as harsh or passive-aggressive. I still have the formal writing mindset of treating proper capitalization and punctuation as a point of pride, but McCulloch makes an excellent argument for letting go of my biases and understanding how and why language is changing. The realization I had while reading this is that many of the changes that look like sloppiness or laziness to someone trained in formal writing have the effect of giving language greater dynamic range. If one always uses periods uniformly, the period becomes meaningless except as a sentence boundary (which is redundant with newlines in most short informal chat messages). If one normally doesn't use it, and then suddenly starts using it, the period can carry semantic weight. It can convey a snippy tone of voice, a note of annoyance, or other subtle shades of meaning. I still use periods in most of my Slack messages because habits are hard to break, but I'm remembering to leave them off some of the time and paying more attention to what emotional weight they're carrying when present. Because Internet is therefore the rare book that meets the bar of changing my day-to-day behavior. "lol" is another excellent example that McCulloch spends some time on. It started life as LOL, an abbreviation for "laughing out loud," and that's still how it's stuck in my head. But, as McCulloch explains, it no longer means that to newer waves of Internet users. It now carries a far more complicated and nuanced meaning that has very little to do with physical laughter and that doesn't easily translate to a single word or sentence. I went from being mildly irritated by and mildly superior towards the ubiquitous "lol" to realizing that it's a fascinating new word that carries primarily emotional nuance and that I don't understand well enough to read or use properly (yet). One more example of the type of analysis McCulloch brings to this book: emoji. The tendency when talking about emoji is to treat them as rebuses (pictures that stand in for a word, or at least a specific concept). They are sometimes used that way, but McCulloch argues that they more often function in the same role that gestures play in informal speech, including the gestures that have no simple name and no independent meaning outside of the context of the words being said at the same time. This seems obvious in retrospect, but before reading Because Internet I had never thought about what a gesture is, what function it plays in speech, and how that could be translated into informal written communication. If you're as interested in this area as I am, this is great stuff. I'd seen several mentions of this book go past on Twitter and kept holding off because I had lots of things to read and was worried it would only cover the superficial things I already knew as a long-time Internet user who has listened to a few lectures on linguistics. That was not the case at all. I learned so much from this book and had a delightful time reading it. If you're also interested in these topics, recommended. Rating: 9 out of 10
11 December 2020

Reproducible Builds (diffoscope): diffoscope 163 released

The diffoscope maintainers are pleased to announce the release of diffoscope version 163. This version includes the following changes:
[ Chris Lamb ]
* Bug fixes & new features:
  - Normalise "ret" to "retq" in objdump output to support multiple versions
    of obdump(1). (Closes: #976760, reproducible-builds/diffoscope#227)
  - Don't show progress indicators when running zstd(1).
    (Closes: reproducible-builds/diffoscope#226)
  - Move the slightly-confusing behaviour of loading an "existing diff" if a
    single file is passed to diffoscope to the new --load-existing-diff
    command.
* Output improvements:
  - Use pprint.pformat in the JSON comparator to serialise the differences
    from jsondiff to make the output render better.
  - Correct tense in --debug log output.
* Code quality:
  * Don't use an old-style "super" call.
  - Rewrite the filter routine for post-processing output from readelf(1).
  - Update my copyright years.
  - Remove unncessary PEP 263 encoding lines (replaced via PEP 3120).
  - Use "minimal" instead of "basic" as a variable name to match the
    underlying package name.
  - Add comment regarding Java tests for diffoscope contributors who are not
    using Debian. (Re: reproducible-builds/diffoscope!58)
* Debian packaging:
  - Update debian/copyright to match copyright notices in source-tree.
    (Closes: reproducible-builds/diffoscope#224)
  - Ensure the new "diffoscope-minimal" package has a different short
    description from the main "diffoscope" one.
[ Jean-Romain Garnier ]
* Add tests for OpenJDK 14.
[ Conrad Ratschan ]
* Add comparator for "legacy" uboot uImage files.
  (MR: reproducible-builds/diffoscope!69)
You find out more by visiting the project homepage.

10 December 2020

John Goerzen: How the Attention Economy Hurts You via Social Media Sites like Facebook

There is a whole science to manipulating our attention. And because there is a lot of money to be made by doing this well, it means we all encounter attempts to manipulate what we pay attention to each day. What is this, and how is it harmful? This post will be the first on a series on the topic. Why is attention so important? When people use Facebook, they use it for free. Facebook generally doesn t even try to sell them anything, yet has billions in revenues. What, then, is Facebook s product? Well, really, it s you. Or, more specifically, your attention. Facebook sells your attention to advertisers. Everything they do is in service to that. They want you to spend more time on the site so they can show you more ads. (I should say here that I m using Facebook as an example, but this applies to other social media companies too.) Seeking to maximize attention So if your attention is so important to their profit, it follows naturally that they would seek ways to get people to spend more time on their site. And they do. They track all sorts of metrics, including engagement (if you click like , comment, share, or otherwise interact with content). They know which sorts of things are likely to capture your (and I mean you in specific!) attention and show you that. Your neighbor may have different interests and Facebook judges different things are likely to capture their attention. Manipulating your attention Attention turning into money isn t unique for social media. In fact, in the article If It Bleeds, It Leads: Understanding Fear-Based Media, Psychology Today writes:
In previous decades, the journalistic mission was to report the news as it actually happened, with fairness, balance, and integrity. However, capitalistic motives associated with journalism have forced much of today s television news to look to the spectacular, the stirring, and the controversial as news stories. It s no longer a race to break the story first or get the facts right. Instead, it s to acquire good ratings in order to get advertisers, so that profits soar. News programming uses a hierarchy of if it bleeds, it leads. Fear-based news programming has two aims. The first is to grab the viewer s attention. In the news media, this is called the teaser. The second aim is to persuade the viewer that the solution for reducing the identified fear will be in the news story. If a teaser asks, What s in your tap water that YOU need to know about? a viewer will likely tune in to get the up-to-date information to ensure safety.
You ve probably seen fear-based messages a lot on Facebook. They will highlight messages to liberals about being afraid of what Trump is doing, and to conservatives about being afraid of what Biden is doing. They may or may not even intentionally be doing this; it is their algorithm predicts that those would maximize time and engagement for certain people, so that s what they see. Fear leads to controversy It s not just fear, though. Social media also loves controversy. There s nothing that makes people really want to stay on Facebook like anger. See something controversial and you ll see hundreds or thousands of people are there arguing about it and in the process, giving Facebook their attention. A quick Internet search will show you numerous articles on how marketing companes can leverage controvery to get attention and engagement with their campaigns. Consequences of maximizing fear and controversy What does it mean to society at large and to you personally that large companies make a lot of money by maximizing fear and controversy? The most obvious way is it leads to less common ground. If the posts and reactions that show common ground are never seen because they don t drive engagement, it poisons the well; left and right hate each other with ever more vigor a profitable outcome to Facebook, but a poisonous one to all of us. I have had several friendships lost because I a liberal in agreement with these friends on political matters still talk to Trump voters. On the other side, we ve seen people storm the Michigan statehouse with weapons. How did that level of disagreement and even fear behind it get so firmly embedded in our society? Surely the fact that social media shows us things designed to stimulate fear and anger must play a role. What does it do to our ability to have empathy for, and understand, others? The Facebook groups I ve been in for like-minded people have largely been flooded with memes calling the President rump and other things clearly designed to make people angry or fearful. It s a worthless experience, and not just that, but it s a harmful experience. When our major media TV and social networks all are optimizing for fear, anger, and controvesry, we have a society beholden to fear, anger, and controvesy. In my next installment, I m going to talk about what to do about this, including the decentralized social networks of the Fediverse that are specifically designed to put you back in charge of your attention. Update 2020-12-16: There are two followup articles for this: how to join the Fediverse and non-creepy technology purchasing and gifting guides. The latter references the FSF s page on software manipulation towards addiction, which is particularly relevant to this topic.

5 December 2020

Andrew Cater: And the last few architectures are getting done - Debian 10.7 edging ever closer

And we're through the live images as far as we can reasonably go. There remain a couple of MIPS architectures to build and IBM s390x - we have no hardware to test these.It's now 23:30 UTC - so that's 12 1/2 hours since we started and Sledge has another couple of hours to wait before the last images can be signed and the image release can be pushed.Thanks so much to Sledge, RattusRattus, Isy, Schweer and jlsantos - who came back to us after a significant internet outage local to them in California - to those who popped by - hi Kibi and Manty - and to all who labour behind the scenes to make each release "just work"Here's to the next one - in another couple of months, I'm guessing.

1 December 2020

Shirish Agarwal: The Constitution of Knowledge

Truth, Untruths and Education in India. I read this somewhat disturbing and yet pretty raw truth from foreign affairs. It took me quite a few days to not only digest but also say yes and see the same situation playing out in India. I have been seeing the discourse on Twitter and while a part of it is the equivalent of road rage, a huge part is a disconnect to not acknowledge and be civil. We may come to different conclusions from the same data but being civil seems to be difficult for a lot of people. One part is of course ego, where nobody wants to lose, but more than that are the plain comprehension issues. Most of the literature, good literature is unfortunately based in English.

And while we can have differing opinions of what constitutes good literature, for me it s books like Battle of Belonging,The:On Nationalism, Patriotism, and What it Means Shashi Tharoor. From what little I have understood, the book makes the case of civic nationalism which is far more inclusive than the narrow confines of patriotism. Now this begs the question when you have such books and many books which do tell you about different aspects of social, political and knowledge, why are so many people prone to disinformation in India similar to U.S. and probably other countries as well. One of the biggest reasons per-se is lack of education and quality education. When the number of graduates is less than five percent how do you expect that population to be able to take decisions in their economic self-interest? So sadly the understanding is ingrained from WhatsApp and there is no need to check from alternate sources. And just like Mr. Trump followers, they believe those versions to be the unvarnished truth. I do understand that no truth is immutable except for life and death. All others are imperfect unless it is validated by some sort of scientific validation behind it. At the same time, these truths may themselves be invalidated if a stronger scientific evidence establishes itself. This is the reason why hypothesis and facts themselves are challenged again and again. Sharing couple of examples below.

Nationalization of Banking, RERA and RCEP Most of the people want freedom of the banks i.e. private banking don t really know that private banking existed at a time in free India before they were nationalized and these banks failed at surprisingly regular intervals. Now it isn t as if this fact is hidden but it is not as popular as maybe some other facts or ideas. Now the Government in the center obviously doesn t want to share these facts as they want corporates in banking. And if that fact is known by many people it will be a huge setback to their plans. RBI failures have been to many to count. Even recent legislations like RERA and others which were supposed to bring relief to millions of potential homeowners has become a pawn in the hands of builders and this has been known. One of the interesting points of RCEP which is not so much in public domain is that RCEP would have a mere 4.5% duty on most products which will go down to 1.5% over a 20 year period. Now with India staying out of it, we have done two things. We have said that we will not be competitive even after 20 years of this which is the more damning part. And we will not take part in the growth that other countries will have due to this. Contempt Proceedings against Comic Artist because she has an opinion on SC The fall in SC and constitutional values grows day by day. The AG today consented to have contempt proceedings against a comic artist saying she insulted the SC. Gone are the days when an artist made fun of the PM, and she gave him a Padam Shri (one of the highest civilian honors) for his contributions. Then, even dissent or being cynical was looked as being a contribution to the national effort rather than today. This is the reason why India has been continuously falling in the Global Freedom of Expression Index. I have seen censoring many a time here. I, myself has been locked out of Wikipedia many times. Can you imagine, being locked out of Wikipedia which is perhaps one of the more neutral sites on the web. And then there was this wikibio thing, such a sad thing to happen. Guessing this is the future of the Indian interweb.
Stick figure by Sanitary Panels on SC

30 November 2020

Chris Lamb: Free software activities in November 2020

Here is my monthly update covering what I have been doing in the free software world during November 2020 (previous month):

Reproducible Builds One of the original promises of open source software is that distributed peer review and transparency of process results in enhanced end-user security. However, whilst anyone may inspect the source code of free and open source software for malicious flaws, almost all software today is distributed as pre-compiled binaries. This allows nefarious third-parties to compromise systems by injecting malicious code into ostensibly secure software during the various compilation and distribution processes. The motivation behind the Reproducible Builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised. The project is proud to be a member project of the Software Freedom Conservancy. Conservancy acts as a corporate umbrella allowing projects to operate as non-profit initiatives without managing their own corporate structure. If you like the work of the Conservancy or the Reproducible Builds project, please consider becoming an official supporter.
This month, I:
I also made the following changes to diffoscope:

Debian I performed the following uploads to the Debian Linux distribution this month: I also filed a release-critical bug against the minidlna package which could not be successfully purged from the system without reporting a cannot remove '/var/log/minidlna' error. (#975372)

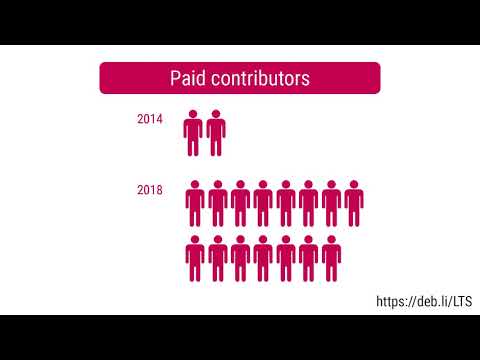
Debian LTS This month I have worked 18 hours on Debian Long Term Support (LTS) and 12 hours on its sister Extended LTS project, including: You can find out more about the Debian LTS project via the following video:

28 November 2020

Russ Allbery: Review: Nine Goblins

Review: Nine Goblins, by T. Kingfisher
Publisher: Red Wombat Tea Company
Copyright: 2013
ASIN: B00G9GSEXO
Format: Kindle
Pages: 140
The goblins are at war, a messy multi-sided war also involving humans, elves, and orcs. The war was not exactly their idea, although the humans would claim otherwise. Goblins kept moving farther and farther into the wilderness to avoid human settlements, and then they ran out of wilderness, and it wasn't clear what else to do. For the Nineteenth Infantry, the war is a confusing business, full of boredom and screaming and being miserable and following inexplicable orders. And then they run into a wizard. Wizards in this world are not right in the head, and by not right I mean completely psychotic. That's the only way that you get magical powers. Wizards are therefore incredibly dangerous and scarily unpredictable, so when the Whinin' Nineteenth run into a human wizard who shoots blue out of his mouth, making him stop shooting blue out of his mouth becomes a high priority. Goblins have only one effective way of stopping things: charge at them and hit them with something until they stop. Wizards have things like emergency escape portals. And that's how the entire troop of nine goblins ended up far, far behind enemy lines. Sings-to-Trees's problems, in contrast, are rather more domestic. At the start of the book, they involve, well:
Sings-to-Trees had hair the color of sunlight and ashes, delicately pointed ears, and eyes the translucent green of new leaves. His shirt was off, he had the sort of tanned muscle acquired from years of healthy outdoor living, and you could have sharpened a sword on his cheekbones. He was saved from being a young maiden's fantasy unless she was a very peculiar young maiden by the fact that he was buried up to the shoulder in the unpleasant end of a heavily pregnant unicorn.
Sings-to-Trees is the sort of elf who lives by himself, has a healthy appreciation for what nursing wild animals involves, and does it anyway because he truly loves animals. Despite that, he was not entirely prepared to deal with a skeleton deer with a broken limb, or at least with the implications of injured skeleton deer who are attracted by magical disturbances showing up in his yard. As one might expect, Sings-to-Trees and the goblins run into each other while having to sort out some problems that are even more dangerous than the war the goblins were unexpectedly removed from. But the point of this novella is not a deep or complex plot. It pushes together a bunch of delightfully weird and occasionally grumpy characters, throws a challenge at them, and gives them space to act like fundamentally decent people working within their constraints and preconceptions. It is, in other words, an excellent vehicle for Ursula Vernon (writing as T. Kingfisher) to describe exasperated good-heartedness and stubbornly determined decency.
Sings-to-Trees gazed off in the middle distance with a vague, pleasant expression, the way that most people do when present at other people's minor domestic disputes, and after a moment, the stag had stopped rattling, and the doe had turned back and rested her chin trustingly on Sings-to-Trees' shoulder. This would have been a touching gesture, if her chin hadn't been made of painfully pointy blades of bone. It was like being snuggled by an affectionate plow.
It's not a book you read for the twists and revelations (the resolution is a bit of an anti-climax). It's strength is in the side moments of characterization, in the author's light-hearted style, and in descriptions like the above. Sings-to-Trees is among my favorite characters in all of Vernon's books, surpassed only by gnoles and a few characters in Digger. The Kingfisher books I've read recently have involved humans and magic and romance and more standard fantasy plots. This book is from seven years ago and reminds me more of Digger. There is less expected plot machinery, more random asides, more narrator presence, inhuman characters, no romance, and a lot more focus on characters deciding moment to moment how to tackle the problem directly in front of them. I wouldn't call it a children's book (all of the characters are adults), but it has a bit of that simplicity and descriptive focus. If you like Kingfisher in descriptive mode, or enjoy Vernon's descriptions of D&D campaigns on Twitter, you are probably going to like this. If you don't, you may not. I thought it was slight but perfect for my mood at the time. Rating: 7 out of 10

22 November 2020

Arturo Borrero Gonz lez: How to use nftables from python

Netfilter logo One of the most interesting (and possibly unknown) features of the nftables framework is the native python interface, which allows python programs to access all nft features programmatically, from the source code. There is a high-level library, libnftables, which is responsible for translating the human-readable syntax from the nft binary into low-level expressions that the nf_tables kernel subsystem can run. The nft command line utility basically wraps this library, where all actual nftables logic lives. You can only imagine how powerful this library is. Originally written in C, ctypes is used to allow native wrapping of the shared lib object using pure python. To use nftables in your python script or program, first you have to install the libnftables library and the python bindings. In Debian systems, installing the python3-nftables package should be enough to have everything ready to go. To interact with libnftables you have 2 options, either use the standard nft syntax or the JSON format. The standard format allows you to send commands exactly like you would do using the nft binary. That format is intended for humans and it doesn t make a lot of sense in a programmatic interaction. Whereas JSON is pretty convenient, specially in a python environment, where there are direct data structure equivalents. The following code snippet gives you an example of how easy this is to use:
#!/usr/bin/env python3

import nftables
import json
nft = nftables.Nftables()
nft.set_json_output(True)
rc, output, error = nft.cmd("list ruleset")
print(json.loads(output))
This is functionally equivalent to running nft -j list ruleset. Basically, all you have to do in your python code is: The key here is to use the JSON format. It allows adding ruleset modification in batches, i.e. to create tables, chains, rules, sets, stateful counters, etc in a single atomic transaction, which is the proper way to update firewalling and NAT policies in the kernel and to avoid inconsistent intermediate states. The JSON schema is pretty well documented in the libnftables-json(5) manpage. The following example is copy/pasted from there, and illustrates the basic idea behind the JSON format. The structure accepts an arbitrary amount of commands which are interpreted in order of appearance. For instance, the following standard syntax input:
flush ruleset
add table inet mytable
add chain inet mytable mychain
add rule inet mytable mychain tcp dport 22 accept
Translates into JSON as such:
  "nftables": [
      "flush":   "ruleset": null  ,
      "add":   "table":  
        "family": "inet",
        "name": "mytable"
     ,
      "add":   "chain":  
        "family": "inet",
        "table": "mytable",
        "chain": "mychain"
     
      "add":   "rule":  
        "family": "inet",
        "table": "mytable",
        "chain": "mychain",
        "expr": [
              "match":  
                "left":   "payload":  
                    "protocol": "tcp",
                    "field": "dport"
                 ,
                "right": 22
             ,
              "accept": null  
        ]
     
] 
I encourage you to take a look at the manpage if you want to know about how powerful this interface is. I ve created a git repository to host several source code examples using different features of the library: https://github.com/aborrero/python-nftables-tutorial. I plan to introduce more code examples as I learn and create them. There are several relevant projects out there using this nftables python integration already. One of the most important pieces of software is firewalld. They started using the JSON format back in 2019. In the past, people interacting with iptables programmatically would either call the iptables binary directly or, in the case of some C programs, hack libiptc/libxtables libraries into their source code. The native python approach to use libnftables is a huge step forward, which should come handy for developers, network engineers, integrators and other folks using the nftables framework in a pythonic environment. If you are interested to know how this python binding works, I invite you to take a look at the upstream source code, nftables.py, which contains all the magic behind the scenes.

21 November 2020

Giovanni Mascellani: Having fun with signal handlers

As every C and C++ programmer knows far too well, if you dereference a pointer that points outside of the space mapped on your process' memory, you get a segmentation fault and your programs crashes. As far as the language itself is concerned, you don't have a second chance and you cannot know in advance whether that dereferencing operation is going to set a bomb off or not. In technical terms, you are invoking undefined behaviour, and you should never do that: you are responsible for knowing in advance if your pointers are valid, and if they are not you keep the pieces. However, turns out that most actual operating system give you a second chance, although with a lot of fine print attached. So I tried to implement a function that tries to dereference a pointer: if it can, it gives you the value; if it can't, it tells you it couldn't. Again, I stress this should never happen in a real program, except possibly for debugging (or for having fun). The prototype is
word_t peek(word_t *addr, int *success);
The function is basically equivalent to return *addr, except that if addr is not mapped it doesn't crash, and if success is not NULL it is set to 0 or 1 to indicate that addr was not mapped or mapped. If addr was not mapped the return value is meaningless. I won't explain it in detail to leave you some fun. Basically the idea is to install a handler for SIGSEGV: if the address is invalid, the handler is called, which basically fixes everything by advancing a little bit the instruction pointer, in order to skip the faulting instruction. The dereferencing instruction is written as hardcoded Assembly bytes, so that I know exactly how many bytes I need to skip. Of course this is very architecture-dependent: I wrote the i386 and amd64 variants (no x32). And I don't guarantee there are no bugs or subtelties! Another solution would have been to just parse /proc/self/maps before dereferencing and check whether the pointer is in a mapped area, but it would have suffered of a TOCTTOU problem: another thread might have changed the mappings between the time when /proc/self/maps was parsed and when the pointer was dereferenced (also, parsing that file can take a relatively long amount of time). Another less architecture-dependent but still not pure-C approach would have been to establish a setjmp before attempting the dereference and longjmp-ing back from the signal handler (but again you would need to use different setjmp contexts in different threads to exclude race conditions). Have fun! (and again, don't try this in real programs) EDIT I realized I should specify the language for source code highlighting to work decently. Now it's better! EDIT 2 I also realized that my version of peek has problems when there are other threads, because signal actions are per-process, not per-thread (as I initially thought). See the comments for a better version (though not perfect).
#define _GNU_SOURCE
#include <stdint.h>
#include <signal.h>
#include <assert.h>
#include <stdlib.h>
#include <stdio.h>
#include <ucontext.h>
#ifdef __i386__
typedef uint32_t word_t;
#define IP_REG REG_EIP
#define IP_REG_SKIP 3
#define READ_CODE __asm__ __volatile__(".byte 0x8b, 0x03\n"  /* mov (%ebx), %eax */ \
                                       ".byte 0x41\n"        /* inc %ecx */ \
                                       : "=a"(ret), "=c"(tmp) : "b"(addr), "c"(tmp));
#endif
#ifdef __x86_64__
typedef uint64_t word_t;
#define IP_REG REG_RIP
#define IP_REG_SKIP 6
#define READ_CODE __asm__ __volatile__(".byte 0x48, 0x8b, 0x03\n"  /* mov (%rbx), %rax */ \
                                       ".byte 0x48, 0xff, 0xc1\n"  /* inc %rcx */ \
                                       : "=a"(ret), "=c"(tmp) : "b"(addr), "c"(tmp));
#endif
static void segv_action(int sig, siginfo_t *info, void *ucontext)  
    (void) sig;
    (void) info;
    ucontext_t *uctx = (ucontext_t*) ucontext;
    uctx->uc_mcontext.gregs[IP_REG] += IP_REG_SKIP;
 
struct sigaction peek_sigaction =  
    .sa_sigaction = segv_action,
    .sa_flags = SA_SIGINFO,
    .sa_mask = 0,
 ;
word_t peek(word_t *addr, int *success)  
    word_t ret;
    int tmp, res;
    struct sigaction prev_act;
    res = sigaction(SIGSEGV, &peek_sigaction, &prev_act);
    assert(res == 0);
    tmp = 0;
    READ_CODE
    res = sigaction(SIGSEGV, &prev_act, NULL);
    assert(res == 0);
    if (success)  
        *success = tmp;
     
    return ret;
 
int main()  
    int success;
    word_t number = 22;
    word_t value;
    number = 22;
    value = peek(&number, &success);
    printf("%d %d\n", success, value);
    value = peek(NULL, &success);
    printf("%d %d\n", success, value);
    value = peek((word_t*)0x1234, &success);
    printf("%d %d\n", success, value);
    return 0;
 

Michael Stapelberg: Winding down my Debian involvement

This post is hard to write, both in the emotional sense but also in the I would have written a shorter letter, but I didn t have the time sense. Hence, please assume the best of intentions when reading it it is not my intention to make anyone feel bad about their contributions, but rather to provide some insight into why my frustration level ultimately exceeded the threshold. Debian has been in my life for well over 10 years at this point. A few weeks ago, I have visited some old friends at the Z rich Debian meetup after a multi-year period of absence. On my bike ride home, it occurred to me that the topics of our discussions had remarkable overlap with my last visit. We had a discussion about the merits of systemd, which took a detour to respect in open source communities, returned to processes in Debian and eventually culminated in democracies and their theoretical/practical failings. Admittedly, that last one might be a Swiss thing. I say this not to knock on the Debian meetup, but because it prompted me to reflect on what feelings Debian is invoking lately and whether it s still a good fit for me. So I m finally making a decision that I should have made a long time ago: I am winding down my involvement in Debian to a minimum.

What does this mean? Over the coming weeks, I will:
  • transition packages to be team-maintained where it makes sense
  • remove myself from the Uploaders field on packages with other maintainers
  • orphan packages where I am the sole maintainer
I will try to keep up best-effort maintenance of the manpages.debian.org service and the codesearch.debian.net service, but any help would be much appreciated. For all intents and purposes, please treat me as permanently on vacation. I will try to be around for administrative issues (e.g. permission transfers) and questions addressed directly to me, permitted they are easy enough to answer.

Why? When I joined Debian, I was still studying, i.e. I had luxurious amounts of spare time. Now, over 5 years of full time work later, my day job taught me a lot, both about what works in large software engineering projects and how I personally like my computer systems. I am very conscious of how I spend the little spare time that I have these days. The following sections each deal with what I consider a major pain point, in no particular order. Some of them influence each other for example, if changes worked better, we could have a chance at transitioning packages to be more easily machine readable.

Change process in Debian The last few years, my current team at work conducted various smaller and larger refactorings across the entire code base (touching thousands of projects), so we have learnt a lot of valuable lessons about how to effectively do these changes. It irks me that Debian works almost the opposite way in every regard. I appreciate that every organization is different, but I think a lot of my points do actually apply to Debian. In Debian, packages are nudged in the right direction by a document called the Debian Policy, or its programmatic embodiment, lintian. While it is great to have a lint tool (for quick, local/offline feedback), it is even better to not require a lint tool at all. The team conducting the change (e.g. the C++ team introduces a new hardening flag for all packages) should be able to do their work transparent to me. Instead, currently, all packages become lint-unclean, all maintainers need to read up on what the new thing is, how it might break, whether/how it affects them, manually run some tests, and finally decide to opt in. This causes a lot of overhead and manually executed mechanical changes across packages. Notably, the cost of each change is distributed onto the package maintainers in the Debian model. At work, we have found that the opposite works better: if the team behind the change is put in power to do the change for as many users as possible, they can be significantly more efficient at it, which reduces the total cost and time a lot. Of course, exceptions (e.g. a large project abusing a language feature) should still be taken care of by the respective owners, but the important bit is that the default should be the other way around. Debian is lacking tooling for large changes: it is hard to programmatically deal with packages and repositories (see the section below). The closest to sending out a change for review is to open a bug report with an attached patch. I thought the workflow for accepting a change from a bug report was too complicated and started mergebot, but only Guido ever signaled interest in the project. Culturally, reviews and reactions are slow. There are no deadlines. I literally sometimes get emails notifying me that a patch I sent out a few years ago (!!) is now merged. This turns projects from a small number of weeks into many years, which is a huge demotivator for me. Interestingly enough, you can see artifacts of the slow online activity manifest itself in the offline culture as well: I don t want to be discussing systemd s merits 10 years after I first heard about it. Lastly, changes can easily be slowed down significantly by holdouts who refuse to collaborate. My canonical example for this is rsync, whose maintainer refused my patches to make the package use debhelper purely out of personal preference. Granting so much personal freedom to individual maintainers prevents us as a project from raising the abstraction level for building Debian packages, which in turn makes tooling harder. How would things look like in a better world?
  1. As a project, we should strive towards more unification. Uniformity still does not rule out experimentation, it just changes the trade-off from easier experimentation and harder automation to harder experimentation and easier automation.
  2. Our culture needs to shift from this package is my domain, how dare you touch it to a shared sense of ownership, where anyone in the project can easily contribute (reviewed) changes without necessarily even involving individual maintainers.
To learn more about how successful large changes can look like, I recommend my colleague Hyrum Wright s talk Large-Scale Changes at Google: Lessons Learned From 5 Yrs of Mass Migrations .

Fragmented workflow and infrastructure Debian generally seems to prefer decentralized approaches over centralized ones. For example, individual packages are maintained in separate repositories (as opposed to in one repository), each repository can use any SCM (git and svn are common ones) or no SCM at all, and each repository can be hosted on a different site. Of course, what you do in such a repository also varies subtly from team to team, and even within teams. In practice, non-standard hosting options are used rarely enough to not justify their cost, but frequently enough to be a huge pain when trying to automate changes to packages. Instead of using GitLab s API to create a merge request, you have to design an entirely different, more complex system, which deals with intermittently (or permanently!) unreachable repositories and abstracts away differences in patch delivery (bug reports, merge requests, pull requests, email, ). Wildly diverging workflows is not just a temporary problem either. I participated in long discussions about different git workflows during DebConf 13, and gather that there were similar discussions in the meantime. Personally, I cannot keep enough details of the different workflows in my head. Every time I touch a package that works differently than mine, it frustrates me immensely to re-learn aspects of my day-to-day. After noticing workflow fragmentation in the Go packaging team (which I started), I tried fixing this with the workflow changes proposal, but did not succeed in implementing it. The lack of effective automation and slow pace of changes in the surrounding tooling despite my willingness to contribute time and energy killed any motivation I had.

Old infrastructure: package uploads When you want to make a package available in Debian, you upload GPG-signed files via anonymous FTP. There are several batch jobs (the queue daemon, unchecked, dinstall, possibly others) which run on fixed schedules (e.g. dinstall runs at 01:52 UTC, 07:52 UTC, 13:52 UTC and 19:52 UTC). Depending on timing, I estimated that you might wait for over 7 hours (!!) before your package is actually installable. What s worse for me is that feedback to your upload is asynchronous. I like to do one thing, be done with it, move to the next thing. The current setup requires a many-minute wait and costly task switch for no good technical reason. You might think a few minutes aren t a big deal, but when all the time I can spend on Debian per day is measured in minutes, this makes a huge difference in perceived productivity and fun. The last communication I can find about speeding up this process is ganneff s post from 2008. How would things look like in a better world?
  1. Anonymous FTP would be replaced by a web service which ingests my package and returns an authoritative accept or reject decision in its response.
  2. For accepted packages, there would be a status page displaying the build status and when the package will be available via the mirror network.
  3. Packages should be available within a few minutes after the build completed.

Old infrastructure: bug tracker I dread interacting with the Debian bug tracker. debbugs is a piece of software (from 1994) which is only used by Debian and the GNU project these days. Debbugs processes emails, which is to say it is asynchronous and cumbersome to deal with. Despite running on the fastest machines we have available in Debian (or so I was told when the subject last came up), its web interface loads very slowly. Notably, the web interface at bugs.debian.org is read-only. Setting up a working email setup for reportbug(1) or manually dealing with attachments is a rather big hurdle. For reasons I don t understand, every interaction with debbugs results in many different email threads. Aside from the technical implementation, I also can never remember the different ways that Debian uses pseudo-packages for bugs and processes. I need them rarely enough to establish a mental model of how they are set up, or working memory of how they are used, but frequently enough to be annoyed by this. How would things look like in a better world?
  1. Debian would switch from a custom bug tracker to a (any) well-established one.
  2. Debian would offer automation around processes. It is great to have a paper-trail and artifacts of the process in the form of a bug report, but the primary interface should be more convenient (e.g. a web form).

Old infrastructure: mailing list archives It baffles me that in 2019, we still don t have a conveniently browsable threaded archive of mailing list discussions. Email and threading is more widely used in Debian than anywhere else, so this is somewhat ironic. Gmane used to paper over this issue, but Gmane s availability over the last few years has been spotty, to say the least (it is down as I write this). I tried to contribute a threaded list archive, but our listmasters didn t seem to care or want to support the project.

Debian is hard to machine-read While it is obviously possible to deal with Debian packages programmatically, the experience is far from pleasant. Everything seems slow and cumbersome. I have picked just 3 quick examples to illustrate my point. debiman needs help from piuparts in analyzing the alternatives mechanism of each package to display the manpages of e.g. psql(1). This is because maintainer scripts modify the alternatives database by calling shell scripts. Without actually installing a package, you cannot know which changes it does to the alternatives database. pk4 needs to maintain its own cache to look up package metadata based on the package name. Other tools parse the apt database from scratch on every invocation. A proper database format, or at least a binary interchange format, would go a long way. Debian Code Search wants to ingest new packages as quickly as possible. There used to be a fedmsg instance for Debian, but it no longer seems to exist. It is unclear where to get notifications from for new packages, and where best to fetch those packages.

Complicated build stack See my Debian package build tools post. It really bugs me that the sprawl of tools is not seen as a problem by others.

Developer experience pretty painful Most of the points discussed so far deal with the experience in developing Debian, but as I recently described in my post Debugging experience in Debian , the experience when developing using Debian leaves a lot to be desired, too.

I have more ideas At this point, the article is getting pretty long, and hopefully you got a rough idea of my motivation. While I described a number of specific shortcomings above, the final nail in the coffin is actually the lack of a positive outlook. I have more ideas that seem really compelling to me, but, based on how my previous projects have been going, I don t think I can make any of these ideas happen within the Debian project. I intend to publish a few more posts about specific ideas for improving operating systems here. Stay tuned. Lastly, I hope this post inspires someone, ideally a group of people, to improve the developer experience within Debian.

Michael Stapelberg: Debian Code Search: positional index, TurboPFor-compressed

See the Conclusion for a summary if you re impatient :-)

Motivation Over the last few months, I have been developing a new index format for Debian Code Search. This required a lot of careful refactoring, re-implementation, debug tool creation and debugging. Multiple factors motivated my work on a new index format:
  1. The existing index format has a 2G size limit, into which we have bumped a few times, requiring manual intervention to keep the system running.
  2. Debugging the existing system required creating ad-hoc debugging tools, which made debugging sessions unnecessarily lengthy and painful.
  3. I wanted to check whether switching to a different integer compression format would improve performance (it does not).
  4. I wanted to check whether storing positions with the posting lists would improve performance of identifier queries (= queries which are not using any regular expression features), which make up 78.2% of all Debian Code Search queries (it does).
I figured building a new index from scratch was the easiest approach, compared to refactoring the existing index to increase the size limit (point ). I also figured it would be a good idea to develop the debugging tool in lock step with the index format so that I can be sure the tool works and is useful (point ).

Integer compression: TurboPFor As a quick refresher, search engines typically store document IDs (representing source code files, in our case) in an ordered list ( posting list ). It usually makes sense to apply at least a rudimentary level of compression: our existing system used variable integer encoding. TurboPFor, the self-proclaimed Fastest Integer Compression library, combines an advanced on-disk format with a carefully tuned SIMD implementation to reach better speeds (in micro benchmarks) at less disk usage than Russ Cox s varint implementation in github.com/google/codesearch. If you are curious about its inner workings, check out my TurboPFor: an analysis . Applied on the Debian Code Search index, TurboPFor indeed compresses integers better:

Disk space
8.9G codesearch varint index
5.5G TurboPFor index Switching to TurboPFor (via cgo) for storing and reading the index results in a slight speed-up of a dcs replay benchmark, which is more pronounced the more i/o is required.

Query speed (regexp, cold page cache)
18s codesearch varint index
14s TurboPFor index (cgo)

Query speed (regexp, warm page cache)
15s codesearch varint index
14s TurboPFor index (cgo) Overall, TurboPFor is an all-around improvement in efficiency, albeit with a high cost in implementation complexity.

Positional index: trade more disk for faster queries This section builds on the previous section: all figures come from the TurboPFor index, which can optionally support positions. Conceptually, we re going from:
type docid uint32
type index map[trigram][]docid
to:
type occurrence struct  
    doc docid
    pos uint32 // byte offset in doc
 
type index map[trigram][]occurrence
The resulting index consumes more disk space, but can be queried faster:
  1. We can do fewer queries: instead of reading all the posting lists for all the trigrams, we can read the posting lists for the query s first and last trigram only.
    This is one of the tricks described in the paper AS-Index: A Structure For String Search Using n-grams and Algebraic Signatures (PDF), and goes a long way without incurring the complexity, computational cost and additional disk usage of calculating algebraic signatures.
  2. Verifying the delta between the last and first position matches the length of the query term significantly reduces the number of files to read (lower false positive rate).
  3. The matching phase is quicker: instead of locating the query term in the file, we only need to compare a few bytes at a known offset for equality.
  4. More data is read sequentially (from the index), which is faster.

Disk space A positional index consumes significantly more disk space, but not so much as to pose a challenge: a Hetzner EX61-NVME dedicated server ( 64 /month) provides 1 TB worth of fast NVMe flash storage.
6.5G non-positional
123G positional
93G positional (posrel) The idea behind the positional index (posrel) is to not store a (doc,pos) tuple on disk, but to store positions, accompanied by a stream of doc/pos relationship bits: 1 means this position belongs to the next document, 0 means this position belongs to the current document. This is an easy way of saving some space without modifying the TurboPFor on-disk format: the posrel technique reduces the index size to about . With the increase in size, the Linux page cache hit ratio will be lower for the positional index, i.e. more data will need to be fetched from disk for querying the index. As long as the disk can deliver data as fast as you can decompress posting lists, this only translates into one disk seek s worth of additional latency. This is the case with modern NVMe disks that deliver thousands of MB/s, e.g. the Samsung 960 Pro (used in Hetzner s aforementioned EX61-NVME server). The values were measured by running dcs du -h /srv/dcs/shard*/full without and with the -pos argument.

Bytes read A positional index requires fewer queries: reading only the first and last trigram s posting lists and positions is sufficient to achieve a lower (!) false positive rate than evaluating all trigram s posting lists in a non-positional index. As a consequence, fewer files need to be read, resulting in fewer bytes required to read from disk overall. As an additional bonus, in a positional index, more data is read sequentially (index), which is faster than random i/o, regardless of the underlying disk.
1.2G
19.8G
21.0G regexp queries
4.2G (index)
10.8G (files)
15.0G identifier queries The values were measured by running iostat -d 25 just before running bench.zsh on an otherwise idle system.

Query speed Even though the positional index is larger and requires more data to be read at query time (see above), thanks to the C TurboPFor library, the 2 queries on a positional index are roughly as fast as the n queries on a non-positional index ( 4s instead of 3s). This is more than made up for by the combined i/o matching stage, which shrinks from 18.5s (7.1s i/o + 11.4s matching) to 1.3s.
3.3s (index)
7.1s (i/o)
11.4s (matching)
21.8s regexp queries
3.92s (index)
1.3s
5.22s identifier queries Note that identifier query i/o was sped up not just by needing to read fewer bytes, but also by only having to verify bytes at a known offset instead of needing to locate the identifier within the file.

Conclusion The new index format is overall slightly more efficient. This disk space efficiency allows us to introduce a positional index section for the first time. Most Debian Code Search queries are positional queries (78.2%) and will be answered much quicker by leveraging the positions. Bottomline, it is beneficial to use a positional index on disk over a non-positional index in RAM.

11 November 2020

Reproducible Builds: Reproducible Builds in October 2020

Welcome to the October 2020 report from the Reproducible Builds project. In our monthly reports, we outline the major things that we have been up to over the past month. As a brief reminder, the motivation behind the Reproducible Builds effort is to ensure flaws have not been introduced in the binaries we install on our systems. If you are interested in contributing to the project, please visit our main website.

General On Saturday 10th October, Morten Linderud gave a talk at Arch Conf Online 2020 on The State of Reproducible Builds in Arch. The video should be available later this month, but as a teaser:
The previous year has seen great progress in Arch Linux to get reproducible builds in the hands of the users and developers. In this talk we will explore the current tooling that allows users to reproduce packages, the rebuilder software that has been written to check packages and the current issues in this space.
During the Reproducible Builds summit in Marrakesh in 2019, developers from the GNU Guix, NixOS and Debian distributions were able to produce a bit-for-bit identical GNU Mes binary despite using three different versions of GCC. Since this summit, additional work resulted in a bit-for-bit identical Mes binary using tcc, and last month a fuller update was posted to this effect by the individuals involved. This month, however, David Wheeler updated his extensive page on Fully Countering Trusting Trust through Diverse Double-Compiling, remarking that:
GNU Mes rebuild is definitely an application of [Diverse Double-Compiling]. [..] This is an awesome application of DDC, and I believe it s the first publicly acknowledged use of DDC on a binary
There was a small, followup discussion on our mailing list. In openSUSE, Bernhard M. Wiedemann published his monthly Reproducible Builds status update. This month, the Reproducible Builds project restarted our IRC meetings, managing to convene twice: the first time on October 12th (summary & logs), and later on the 26th (logs). As mentioned in previous reports, due to the unprecedented events throughout 2020, there will be no in-person summit event this year. On our mailing list this month El as Alejandro posted a request for help with a local configuration

Software development This month, we tried to fix a large number of currently-unreproducible packages, including: Bernhard M. Wiedemann also reported three issues against bison, ibus and postgresql12.

Tools diffoscope is our in-depth and content-aware diff utility. Not only could you locate and diagnose reproducibility issues, it provides human-readable diffs of all kinds too. This month, Chris Lamb uploaded version 161 to Debian (later backported by Mattia Rizzolo), as well as made the following changes:
  • Move test_ocaml to the assert_diff helper. [ ]
  • Update tests to support OCaml version 4.11.1. Thanks to Sebastian Ramacher for the report. (#972518)
  • Bump minimum version of the Black source code formatter to 20.8b1. (#972518)
In addition, Jean-Romain Garnier temporarily updated the dependency on radare2 to ensure our test pipelines continue to work [ ], and for the GNU Guix distribution Vagrant Cascadian diffoscope to version 161 [ ]. In related development, trydiffoscope is the web-based version of diffoscope. This month, Chris Lamb made the following changes:
  • Mark a --help-only test as being a superficial test. (#971506)
  • Add a real, albeit flaky, test that interacts with the try.diffoscope.org service. [ ]
  • Bump debhelper compatibility level to 13 [ ] and bump Standards-Version to 4.5.0 [ ].
Lastly, disorderfs version 0.5.10-2 was uploaded to Debian unstable by Holger Levsen, which enabled security hardening via DEB_BUILD_MAINT_OPTIONS [ ] and dropped debian/disorderfs.lintian-overrides [ ].

Website and documentation This month, a number of updates to the main Reproducible Builds website and related documentation were made by Chris Lamb:
  • Add a citation link to the academic article regarding dettrace [ ], and added yet another supply-chain security attack publication [ ].
  • Reformatted the Jekyll s Liquid templating language and CSS formatting to be consistent [ ] as well as expand a number of tab characters [ ].
  • Used relative_url to fix missing translation icon on various pages. [ ]
  • Published two announcement blog posts regarding the restarting of our IRC meetings. [ ][ ]
  • Added an explicit note regarding the lack of an in-person summit in 2020 to our events page. [ ]

Testing framework The Reproducible Builds project operates a Jenkins-based testing framework that powers tests.reproducible-builds.org. This month, Holger Levsen made the following changes:
  • Debian-related changes:
    • Refactor and improve the Debian dashboard. [ ][ ][ ]
    • Track bugs which are usertagged as filesystem , fixfilepath , etc.. [ ][ ][ ]
    • Make a number of changes to package index pages. [ ][ ][ ]
  • System health checks:
    • Relax disk space warning levels. [ ]
    • Specifically detect build failures reported by dpkg-buildpackage. [ ]
    • Fix a regular expression to detect outdated package sets. [ ]
    • Detect Lintian issues in diffoscope. [ ]
  • Misc:
    • Make a number of updates to reflect that our sponsor Profitbricks has renamed itself to IONOS. [ ][ ][ ][ ]
    • Run a F-Droid maintenance routine twice a month to utilise its cleanup features. [ ]
    • Fix the target name in OpenWrt builds to ath79 from ath97. [ ]
    • Add a missing Postfix configuration for a node. [ ]
    • Temporarily disable Arch Linux builds until a core node is back. [ ]
    • Make a number of changes to our thanks page. [ ][ ][ ]
Build node maintenance was performed by both Holger Levsen [ ][ ] and Vagrant Cascadian [ ][ ][ ], Vagrant Cascadian also updated the page listing the variations made when testing to reflect changes for in build paths [ ] and Hans-Christoph Steiner made a number of changes for F-Droid, the free software app repository for Android devices, including:
  • Do not fail reproducibility jobs when their cleanup tasks fail. [ ]
  • Skip libvirt-related sudo command if we are not actually running libvirt. [ ]
  • Use direct URLs in order to eliminate a useless HTTP redirect. [ ]

If you are interested in contributing to the Reproducible Builds project, please visit the Contribute page on our website. However, you can also get in touch with us via:

8 November 2020

Russell Coker: Links November 2020

KDE has a long term problem of excessive CPU time used by the screen locker [1]. Part of it is due to software GL emulation, and part of it is due to the screen locker doing things like flashing the cursor when nothing else is happening. One of my systems has an NVidia card and enabling GL would cause it to crash. So now I have kscreenlocker using 30% of a CPU core even when the screen is powered down. Informative NYT article about the latest security features for iPhones [2]. Android needs new features like this! Russ Allbery wrote an interesting review of the book Hand to Mouth by Linda Tirado [3], it s about poverty in the US and related things. Linda first became Internet famous for her essay Why I Make Terrible Decisions or Poverty Thoughts which is very insightful and well written, this is the latest iteration of that essay [4]. This YouTube video by Ruby Payne gives great insights to class based attitudes towards time and money [5]. News Week has an interesting article about chicken sashimi, apparently you can safely eat raw chicken if it s prepared well [6]. Vanity Fair has an informative article about how Qanon and Trumpism have infected the Catholic Church [7]. Some of Mel Gibson s mental illness is affecting a significant portion of the Catholic Church in the US and some parts in the rest of the world. Noema has an interesting article on toxic Internet culture, Japan s 2chan, 4chan, 8chan/8kun, and the conspiracy theories they spawned [8]. Benjamin Corey is an ex-Fundie who wrote an amusing analysis of the Biblical statements about the anti-Christ [9]. NYMag has an interesting article The Final Gasp of Donald Trump s Presidency [10]. Mother Jones has an informative article about the fact that Jim Watkins (the main person behind QAnon) has a history of hosting child porn on sites he runs [11], but we all knew QAnon was never about protecting kids. Eand has an insightful article America s Problem is That White People Want It to Be a Failed State [12].

6 November 2020

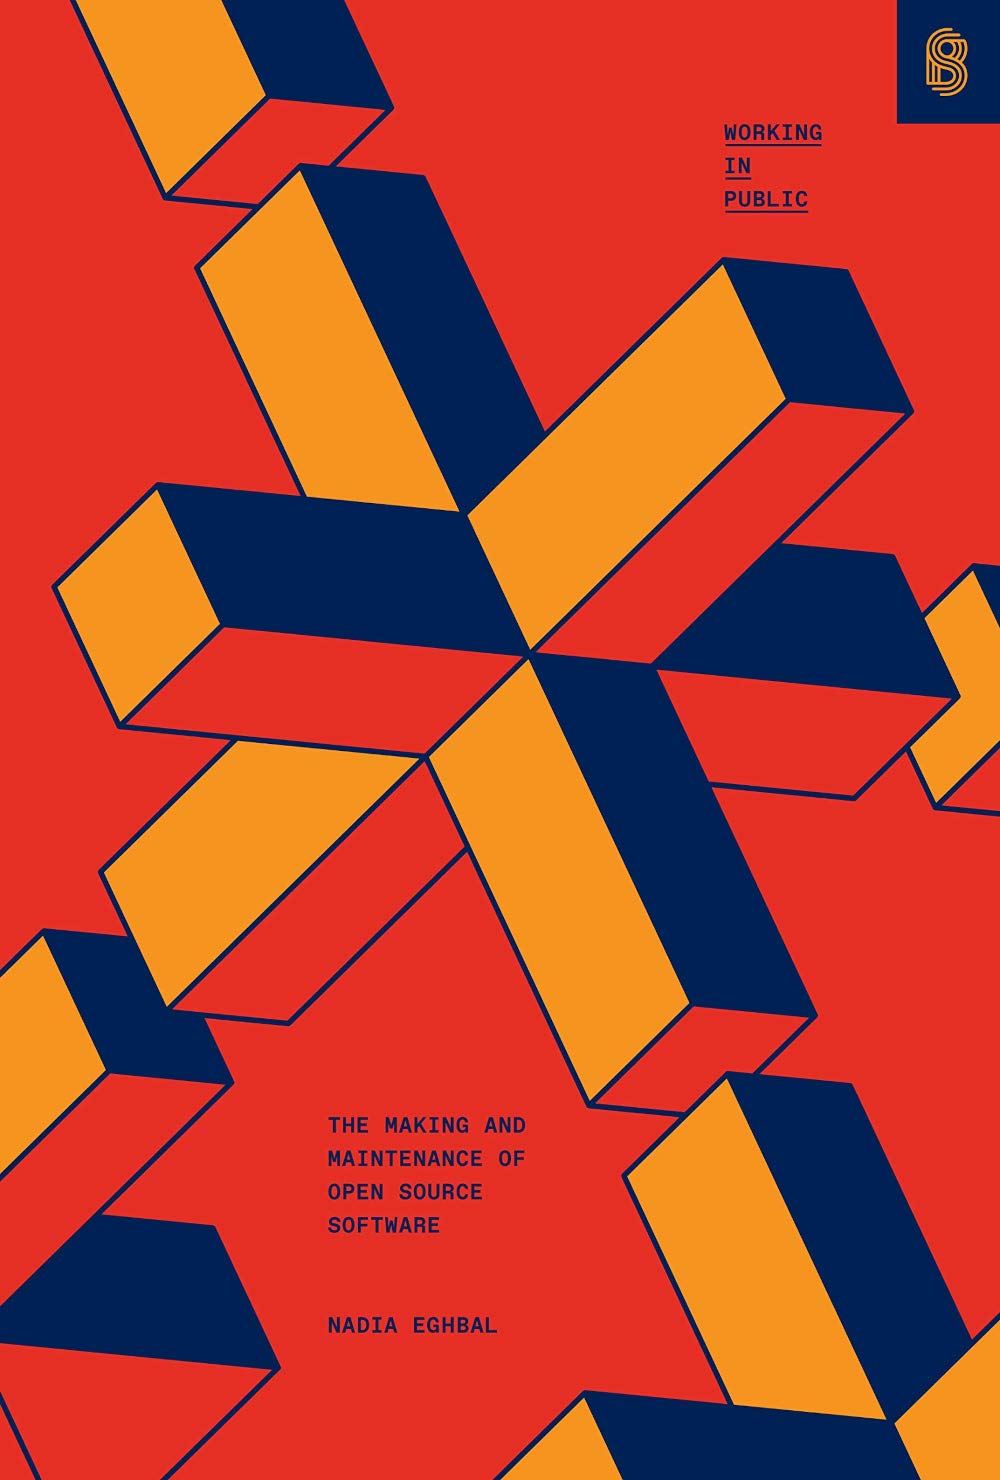
Louis-Philippe V ronneau: Book Review: Working in Public by Nadia Eghbal

I have a lot of respect for Nadia Eghbal, partly because I can't help to be jealous of her work on the economics of Free Software1. If you are not already familiar with Eghbal, she is the author of Roads and Bridges: The Unseen Labor Behind Our Digital Infrastructure, a great technical report published for the Ford Foundation in 2016. You may also have caught her excellent keynote at LCA 2017, entitled Consider the Maintainer. Her latest book, Working in Public: The Making and Maintenance of Open Source Software, published by Stripe Press a few months ago, is a great read and if this topic interests you, I highly recommend it. The book itself is simply gorgeous; bright orange, textured hardcover binding, thick paper, wonderful typesetting it has everything to please. Well, nearly everything. Sadly, it is only available on Amazon, exclusively in the United States. A real let down for a book on Free and Open Source Software. The book is divided in five chapters, namely:
  1. Github as a Platform
  2. The Structure of an Open Source Project
  3. Roles, Incentives and Relationships
  4. The Work Required by Software
  5. Managing the Costs of Production
A picture of the book cover Contrary to what I was expecting, the book feels more like an extension of the LCA keynote I previously mentioned than Roads and Bridges. Indeed, as made apparent by the following quote, Eghbal doesn't believe funding to be the primary problem of FOSS anymore:
We still don't have a common understanding about who's doing the work, why they do it, and what work needs to be done. Only when we understand the underlying behavioral dynamics of open source today, and how it differs from its early origins, can we figure out where money fits in. Otherwise, we're just flinging wet paper towels at a brick wall, hoping that something sticks. p.184
That is to say, the behavior of maintainers and the challenges they face not the eternal money problem is the real topic of this book. And it feels refreshing. When was the last time you read something on the economics of Free Software without it being mostly about what licences projects should pick and how business models can be tacked on them? I certainly can't. To be clear, I'm not sure I agree with Eghbal on this. Her having worked at Github for a few years and having interviewed mostly people in the Ruby on Rails and Javascript communities certainly shows in the form of a strong selection bias. As she herself admits, this is a book on how software on Github is produced. As much as this choice irks me (the Free Software community certainly cannot be reduced to Github), this exercise had the merit of forcing me to look at my own selection biases. As such, reading Working in Public did to me something I wasn't expecting it to do: it broke my Free Software echo chamber. Although I consider myself very familiar with the world of Free and Open Source Software, I now understand my somewhat ill-advised contempt for certain programming languages mostly JS skewed my understanding of what FOSS in 2020 really is. My Free Software world very much revolves around Debian, a project with a strong and opinionated view of Free Software, rooted in a historical and political understanding of the term. This, Eghbal argues, is not the case for a large swat of developers anymore. They are The Github Generation, people attached to Github as a platform first and foremost, and who feel "Open Source" is just a convenient way to make things. Although I could intellectualise this, before reading the book, I didn't really grok how communities akin to npm have been reshaping the modern FOSS ecosystem and how different they are from Debian itself. To be honest, I am not sure I like this tangent and it is certainly part of the reason why I had a tendency to dismiss it as a fringe movement I could safely ignore. Thanks to Nadia Eghbal, I come out of this reading more humble and certainly reminded that FOSS' heterogeneity is real and should not be idly dismissed. This book is rich in content and although I could go on (my personal notes clock-in at around 2000 words and I certainly disagree with a number of things), I'll stop here for now. Go and grab a copy already!

  1. She insists on using the term open source, but I won't :)

4 November 2020

Christian Kastner: qemu-sbuild-utils 0.1: sbuild with QEMU

qemu-sbuild-utils, which were recently accepted into unstable, are a collection of scripts that wrap standard features of sbuild, autopkgtest-build-qemu and vmdb2 to provide a trivial interface for creating and using QEMU-based environments for package building:
  • qemu-sbuild-create creates VM images
  • qemu-sbuild-update is to VM images what sbuild-update is to chroots
  • qemu-sbuild wraps sbuild, adding all necessary (and some useful) options for autopkgtest mode.
Here's a simple two-line example for creating an image, and then using it to build a package:
$ sudo qemu-sbuild-create -o simple.img unstable http://deb.debian.org/debian

$ qemu-sbuild --image simple.img -d unstable [sbuild-options] FOO.dsc
That's it. Both qemu-sbuild-create and qemu-sbuild automate certain things, but also accept a number of options. For example, qemu-sbuild-create can install additional packages either from one of the APT sources, or .deb packages from the local filesystem. qemu-sbuild will pass on every option it does not consume itself to sbuild, so it should mostly work as a drop-in replacement for it (see the Limitations section below for where it doesn't). The created images can also be used for running autopkgtest itself, of course.
Advantages Excellent isolation. One can go nuts in an environment, change or even break things, and the VM can always simply be reset, or rolled back to an earlier state. Snapshots are just terrific for so many reasons. With KVM acceleration and a fast local APT cache, builds are really fast. There's an overhead of a few seconds for booting the VM on my end, but that overhead is negligible in comparison to the overall build time. On the upside, with everything being memory-backed, even massive dependency installations are lightning fast. With the parameters of the target environment being configurable, it's possible to test builds in various settings (for example: single-core vs. multi-core, or with memory constraints). Technically, it should be possible to emulate, on one host, any other guest architecture (even if emulation might be slow because of missing hardware acceleration). This would present an attractive alternative to (possibly distant and/or slow) porter boxes. However, support for that in qemu-sbuild-utils is not quite there yet.
Limitations The utilities are currently only available on the amd64 architecture, for building packages in amd64 and i386 VMs. There are plans to support arm64 in the near future. qemu-sbuild-create needs root, for the debootstrap stage. I'm looking into ways around this (by extending vmdb2). In any case, image updating and package building do not need privileges. autopkgtest mode does not yet support interactivity, so one cannot drop into a shell with --build-failed-commands, for example. The easy workaround is to connect to the VM with SSH. For this, the image must contain the openssh-server package.
Alternatives I looked at qemubuilder, but had troubles getting it to work. In any case, the autopkgtest chroot mode of sbuild seemed far more powerful and useful to me. vectis looks incredibly promising, but I had already written qemu-sbuild-utils by the time I stumbled over it, and as my current setup works well for me for now and is simple enough to maintain, I decided to polish and publish it. I'm also looking into Docker- and other namespace-based isolation solutions (of which there are many), which I think are the way forward for the majority of packages (those that aren't too close to the kernel and/or hardware). Rather than relying on the kernel for isolation, KVM-based solutions like Amazon's Firecracker and QEMU's microvm machine type provide minimal VMs with almost no boot overhead. Firecracker, for example, claims less than 125ms from launch to /sbin/init. Investigating these is a medium-term project for me.
Why not schroot? I have a strong aversion towards chroot-based build environments. The concept is archaic. Far superior software- and/or hardware-based technologies for process isolation have emerged in the past two decades, and I think it is high time to leave chroot-based solutions behind.
Acknowledgments These utilities are just high-level abstractions. All the heavy lifting is done by sbuild, autopkgtest, and vmdb2.

3 November 2020

Martin-&#201;ric Racine: Adding IPv6 support to my home LAN

A couple of year ago, I moved into a new flat that comes with RJ45 sockets wired for 10 Gigabit (but currently offering 1 Gigabit) Ethernet.This also meant changing the settings on my router box for my new ISP.I took this opportunity to review my router's other settings too. I'll be blogging about these over the next few posts. Adding IPv6 support to my home LAN I have been following the evolution of IPv6 ever since the KAME project produced the first IPv6 implementation. I have also been keeping track of the IPv4 address depletion. Around the time the IPv6 Day was organized in 2011, I started investigating the situation of IPv6 support at local ISPs. Well, never mind all those rumors about Finland being some high-tech mecca. Back then, no ISP went beyond testing their routers for IPv6 compatibility and producing white papers on what their limited test deployments accomplished. Not that it matters much, in practice. Most IPv6 documentation out there, including Debian's own, still focuses on configuring transitional mechanisms, especially how to connect to a public IPv6 tunnel broker. Relocating to a new flat and rethinking my home network to match gave me an opportunity to revisit the topic. Much to my delight, my current ISP offers native IPv6. This prompted me to go back and read up on IPv6 one more time. One important detail: IPv6 hosts are globally reachable. The implications of this don't immediately spring to mind for someone used to IPv4 network address translation (NAT): Any network service running on an IPv6 host can be reached by anyone anywhere. Contrary to IPv4, there is no division between private and public IP addresses. Whereas a device behind an IPv4 NAT essentially is shielded from the outside world, IPv6 breaks this assumption in more than one way. Not only is the host reachable from anywhere, its default IPv6 address is a mathematical conversion (EUI-64) of the network interface's MAC address, which makes every connection forensically traceable to a unique device. Basically, if you hadn't given much thought to firewalls until now, IPv6 should give you enough goose bumps to get around it. Tightening the configuration of every network service is also an absolute must. For instance, I configured sshd to only listen to private IPv4 addresses. What /etc/network/interfaces might look like on an dual-stack (IPv4 + IPv6) host:
allow-hotplug enp9s0
iface enp9s0 inet dhcp
iface enp9s0 inet6 auto
	privext 2
	dhcp 1
The auto method means that IPv6 will be auto-configured using SLAAC; privext 2 enables IPv6 privacy options and specifies that we prefer connecting via the randomly-generated IPv6 address, rather than the EUI-64 calculated MAC specific address; dhcp 1 enables passive DHCPv6 to fetch additional routing information. The above works for most desktop and laptop configurations. Where things got more complicated is on the router. I decided early on to keep NAT to provide an IPv4 route to the outside world. Now how exactly is IPv6 routing done? Every node along the line must have its own IPv6 address... including the router's LAN interface. This is accomplished using the sample script found in Debian's IPv6 prefix delegation wiki page. I modified mine as follows (the rest of the script is omitted for clarity):
#Both LAN interfaces on my private network are bridged via br0
IA_PD_IFACE="br0"
IA_PD_SERVICES="dnsmasq"
IA_PD_IPV6CALC="/usr/bin/ipv6calc"
Just put the script at the suggested location. We'll need to request a prefix on the router's outside interface to utilize it. This gives us the following interfaces file:
allow-hotplug enp2s4 enp2s8 enp2s9
auto br0
iface enp2s4 inet dhcp
iface enp2s4 inet6 auto
	request_prefix 1
	privext 2
	dhcp 1
iface enp2s8 inet manual
iface enp2s8 inet6 manual
iface enp2s9 inet manual
iface enp2s9 inet6 manual
iface br0 inet static
	bridge_ports enp2s8 enp2s9
	address 10.10.10.254
iface br0 inet6 manual
	bridge_ports enp2s8 enp2s9
	# IPv6 from /etc/dhcp/dhclient-exit-hooks.d/prefix_delegation
The IPv4 NAT and IPv6 Bridge script on my router looks as follows:
#!/bin/sh
PATH="/usr/sbin:/sbin:/usr/bin:/bin"
wan=enp2s4
lan=br0
########################################################################
# IPv4 NAT
iptables -F; iptables -t nat -F; iptables -t mangle -F
iptables -X; iptables -t nat -X; iptables -t mangle -X
iptables -Z; iptables -t nat -Z; iptables -t mangle -Z
iptables -t nat -A POSTROUTING -o $wan -j MASQUERADE
echo 1 > /proc/sys/net/ipv4/ip_forward
########################################################################
# IPv6 bridge
ip6tables -F; ip6tables -X; ip6tables -Z
# Default policy DROP
ip6tables -P FORWARD DROP
# Allow ICMPv6 forwarding
ip6tables -A FORWARD -p ipv6-icmp -j ACCEPT
# Allow established connections
ip6tables -I FORWARD -m state --state RELATED,ESTABLISHED -j ACCEPT
# Accept packets FROM LAN to everywhere
ip6tables -I FORWARD -i $lan -j ACCEPT
echo 1 > /proc/sys/net/ipv6/conf/all/forwarding
echo 1 > /proc/sys/net/ipv6/conf/default/forwarding
# IPv6 propagation via /etc/dhcp/dhclient-exit-hooks.d/prefix_delegation
The above already provided enough IPv6 connectivity to pass the IPv6 test on my desktop inside the LAN. To make things more fun, I enabled DHCPv6 support for my LAN on the router's dnsmasq by adding the last 3 lines to the configuration:
dhcp-hostsfile=/etc/dnsmasq-ethersfile
bind-interfaces
interface=br0
except-interface=enp2s4
no-dhcp-interface=enp2s4
dhcp-range=tag:br0,10.10.10.0,static,infinite
dhcp-range=tag:br0,::1,constructor:br0,ra-names,ra-stateless,infinite
enable-ra
dhcp-option=option6:dns-server,[::],[2606:4700:4700::1111],[2001:4860:4860::8888]
The 5 first lines (included here for emphasis) are extremely important: they ensure that dnsmasq won't provide any IPv4 or IPv6 service to the outside interface (enp2s4) and that DHCP will only be provided for LAN hosts whose MAC address is known. Line 6 shows how dnsmasq's DHCP service syntax differs between IPv4 and IPv6. The rest of my configuration was omitted on purpose. Enabling native IPv6 on my LAN has been an interesting experiment. I'm sure that someone could come up with even better ip6tables rules for the router or for my desktop hosts. Feel free to mention them in the blog's comment.

Next.

Previous.