Search Results: "will"

29 January 2013

Julien Danjou: Going to FOSDEM 2013

For the first time, I'll be at FOSDEM 2013 in Brussels on Sunday 2nd February 2013. You'll find me probably hanging out in the cloud devroom where I'll talk about Ceilometer with my fellow developers Nick Barcet and Eoghan Glynn. I also hope I'll find time to take a peek at some other talks, like PostgreSQL's ones that Dimitri Fontaine will handle. See you there!

Michal Čihař: phpMyAdmin 3.5.6 for Ubuntu and Debian

Finally, phpMyAdmin packages for Debian and Ubuntu do not lag much behind upstream. Today, I've prepared packages for yesterday released bug fix release 3.5.6. For Debian users, the package should be soon available in experimental (sorry no uploads to unstable during freeze). Ubuntu users, can use my phpMyAdmin PPA. After dozens of comments and no help offered, I've still decided to be nice to Ubuntu users and adjusted the package so that it should work on Lucid as well. The downside is that, unlike in Debian, the package includes bundled copy of many PHP and javascript libraries. PS: As soon as Debian is not frozen or 4.0 is officially released, I will start uploading 4.0 to experimental. My current bet is that 4.0 release will come earlier.

Filed under: Debian English Phpmyadmin 0 comments Flattr this!
Russ Allbery: Much better

Indeed, two days was enough time to recover from an afternoon of social, despite having an hour and a half of meetings today. But today was a day of catching up, sorting issues in JIRA, doing lots of planning meetings, and doing some debugging, so I don't have anything new code-wise to give to the world. So have a photograph. Dried rivulet The product backlog is now all sorted out for the Account Services project into the new phases that will define the work through pretty much the end of the calendar year, I'm guessing. And everything is now a story, not a bug or enhancement or something else without story points, and a few things are shuffled into a more reasonable order. I'm probably going to find a few hours this week to go play video games or work on personal projects, given that I've been working well over 40 hours a week since the start of the year.

28 January 2013

Russ Allbery: Management and the problem stream

Well, today was another day of sleeping, zoning, and having no brain for programming (and no willpower for that or exercise, which is even more frustrating), so you all get more musing about missions and work. Tomorrow, I will re-engage my normal schedule and turn the television off again, because seriously, two days of recovery should be enough even for a whole afternoon of meetings. Perhaps the best concept in the scrum methodology for agile project management is the concept of the product backlog and the product owner. For those who aren't familiar, a scrum project has, as one of its inputs, a prioritized list of stories that the team will implement. During each planning session (generally between once a week and once a month), the development team estimates and takes from the front of the product backlog the top-priority stories that can be completed during that period of time. The product owner is responsible for building the list of pending development stories based on business needs and keeping them sorted in priority order so that the work of the team follows the goals of the larger organization. But the product owner does not get to say how difficult the stories are; the development team estimates the stories, and the product owner may change order based on those estimates (to do simpler things earlier, for example). We've been doing scrum to some extent or another for quite some time now, and while there are a variety of things that I like about it, I think this is the best part. And I think it has very useful concepts for management in general. The product backlog is effectively a problem stream of the sort that I talked about in my last couple of posts. It's a set of problems that need to be solved, that matter to other people. And, if the team is doing scrum properly, the problems are presented in a form that describe a complete unit of desired functionality with its requirements and constraints, but without assuming any sort of implementation. The problem is the domain of the product owner; the solution is the domain of the development team. I am increasingly convinced that my quality of life at work, and that of many other people doing similar sorts of development and project work, would be drastically improved if managers considered this role the core of their jobs. (Ironically, at least in our initial experiences with scrum, it was quite rare for regular managers to be product owners; instead, individual line staff or project managers act as product owners. I think this speaks to how confused a lot of managers are about their roles in a technical development organization. This seems to be improving.) The core of the sort of work that I do is a combination of ongoing maintenance and solving new problems. Both of those can be viewed as a sequence of (possibly recurring) stories; I know this because that's largely how I do my own time management. Apart from HR and staffing, the core role of a manager is almost exactly what scrum calls "backlog grooming": communicating with everyone who has input into what their group is doing, finding out what their problems are, translating that into a list of things that the organization needs to have done, prioritizing them, breaking them into manageable chunks, ensuring they are fully specified and actionable (read: well-written stories), and communicating their completion back to other stakeholders (and then possibly iterating). This lept out at me when I started thinking about our larger strategic vision. That strategic vision is a sort of product backlog: a set of development stories (or, in this case, epics that would be broken down into a large number of smaller stories). But most strategic plans have glaring flaws if they're evaluated by the standards of scrum product backlogs. They're normally written as marketing statements and aimed at the clients or customers rather than at the staff. From the staff perspective, they're often hopelessly vague, not concrete, actionable epics. Often, they are almost entirely composed of grand, conceptual epics that any scrum team would immediately reject as too large and nebulous to even discuss. And often they're undefined but still scheduled: statements that the organization will definitely complete some underspecified thing within the next year or two. Scrum rightfully rejects any form of scheduling for unspecified stories and epics. Additional vagueness and sketchiness is tolerated the farther the story is from the current iteration, so they can be put into the future backlog, but scrum makes no guarantees about when they'll get done until they've been sized and you can apply a reasonable velocity estimate. If you want to put a date on something, you have to make it concrete. This is exactly the problem that I have with long-range strategic plans. We already know this about technology development: long-range strategic plans are feel-good guesses, half-truths, and lies that we tell other people because we're expected to do so, but which no one really believes. The chance that we can predict anything about the shape of projects and rate of delivery of those projects three years from now is laughable, and certainly none of the work that would be required to make real estimates has normally been done for those sorts of long-term strategic projects. There are a lot of scrum advocates who would go farther than I in asking for a complete revolution of how technical projects are planned. I'm not sure how realistic that is, or how well the whole scrum process would work when rolling up work across dozens, if not hundreds, of scrum-sized teams. But in the specific area of the role of managers in a development organization, I think we could learn a lot from this product backlog concept. Right now, there is a constant tension between managers who feel like they need to provide some sort of visionary leadership and guidance (the cult of Steve Jobs) and line staff who feel like managers don't understand enough about specific technology to lead or guide anything. But if you ask a technical developer whether, instead, it would be useful for managers to provide a well-structured, priority-ordered, and clean problem stream from the larger organization so that the developer can trust the problem stream (and not have to go talk to everyone themselves) but have control over the choice of implementation within the described constraints, I think you would find a great deal of enthusiasm. As a further bonus, scrum has a lot of advice about what that problem stream should look like. I think some of the story structuring is overblown (for example, I can't stand the story phrasing structures, the "AS A... I WANT TO... SO THAT..." shackles), but one thing it does correctly emphasize is the difference between problem and solution. The purpose of the story is to describe the outcome from the perspective of the person who will use the resulting technology. Describing the constraints on the solution, in terms of cost or integrations, is actively encouraged. Describing the implementation is verboten; it's up to the project team to choose the implementation that satisfies the constraints. If managers in general would pick up even that simple distinction, I think it would greatly improve the engagement, excitement, and joy that developers could take in their work. There's very little that's more frustrating than to be given an interesting problem in the guise of a half-designed solution and be told that one is not permitted to apply any of one's expertise in elegance, robustness, or durability to replacing the half-baked partial solution. Or even be allowed to know the actual motivating problem, instead of the half-digested form that the manager is willing to pass on.

John Sullivan: FOSDEM

I'll be at FOSDEM again this year, arriving in Brussels on Thursday 31st and leaving on Tuesday 5th. I'll be speaking on Sunday in the legal issues devroom at 10:00. If you will be there and want to meet up, let me know. I may be trying to watch the Super Bowl from there, a plan that didn't quite work out last year but seems more likely this year. State of the GNUnion FSF licensing policy challenges in 2013 This talk will cover the main challenges facing the Free Software Foundation's Licensing and Compliance lab in 2013, and will invite discussion of the FSF's work and policies in this area. We'll explore:

Russell Coker: My SE Linux Status Report LCA 2013

This morning I gave a status report on SE Linux. The talk initially didn t go too well, I wasn t in the right mental state for it and I moved through the material too fast. Fortunately Casey Schaufler asked some really good questions which helped me to get back on track. The end result seemed reasonably good. Here s a summary of the things I discussed: Transaction hooks for RPM to support SE Linux operations. This supports signing packages to indicate their security status and preventing packages from overwriting other packages or executing scripts in the wrong context. There is also work to incorporate some of the features of that into dpkg for Debian. Some changes to libraries to allow faster booting. Systems with sysvinit and a HDD won t be affected but with systemd and SSD it makes a real difference. Mostly Red Hat s work. Filename transition rules to allow the initial context to be assigned based on file name were created in 2011 but are not starting to get used. When systemd is used for starting/stopping daemons some hacks such as run_init can be avoided. Fedora is making the best progress in this regard due to only supporting systemd while the support for other init systems will limit what we can do for Debian. This improves security by stopping terminal buffer insertion attacks while also improving reliability by giving the daemon the same inherited settings each time it s executed. Labelled NFS has been accepted as part of the NFSv4.2 specification. This is a big deal as labelled NFS work has been going for many years without hitting such a milestone in the past. ZFS and BTRFS support but we still need to consider management issues for such snapshot based filesystems. Filesystem snapshots have the potential to interact badly with relabelling if we don t develop code and sysadmin practices to deal with it properly. The most significant upstream focus of SE Linux development over the last year is SE Android. I hope that will result in more work on the X Access Controls for use on the desktop. During question time I also gave a 3 minute lightning talk description of SE Linux.

27 January 2013

Jose Luis Rivas: Less Swap

My old X61 has 2G in RAM and 3G in Swap. It seems my using-habit for Google Chrome is heavy (more than 20 tabs open most of the time) so my swap is normally being used above the 1.8G-mark. That means, my disk is constantly being written and read, and since this is the original hard-drive scare comes to my mind: will I blow-up my disk if I continue doing this? and the heat this disk-use's generating was absurd. That's not good, at all, I prefer having cache used than swap; in Venezuela is not that easy to get a good sale on hard-drives (you know, is hard to get dollars here, since is illegal to buy them unless the govt gives you permission). So the first thing that comes to my mind is sysctl. If I wanted to cofigure swap it would be with a kernel parameter. So running sysctl -a grep swap throws me vm.swappiness = 60, and a little google search tells me more about it. If the swappiness is close to 0 then it will use the swap only if it is really necessary, if it is close to 100 then it will use the swap aggressively. Mine was at 60, and it was really aggressive. The next steps for me was doing sudo echo 'vm.swappiness = 1' >> /etc/sysctl.conf && sudo sysctl -p. Now my system is really smooth and using Chrome + Terminal + Tmux + Rhythmbox is acceptable.
Russell Coker: LCA 2012

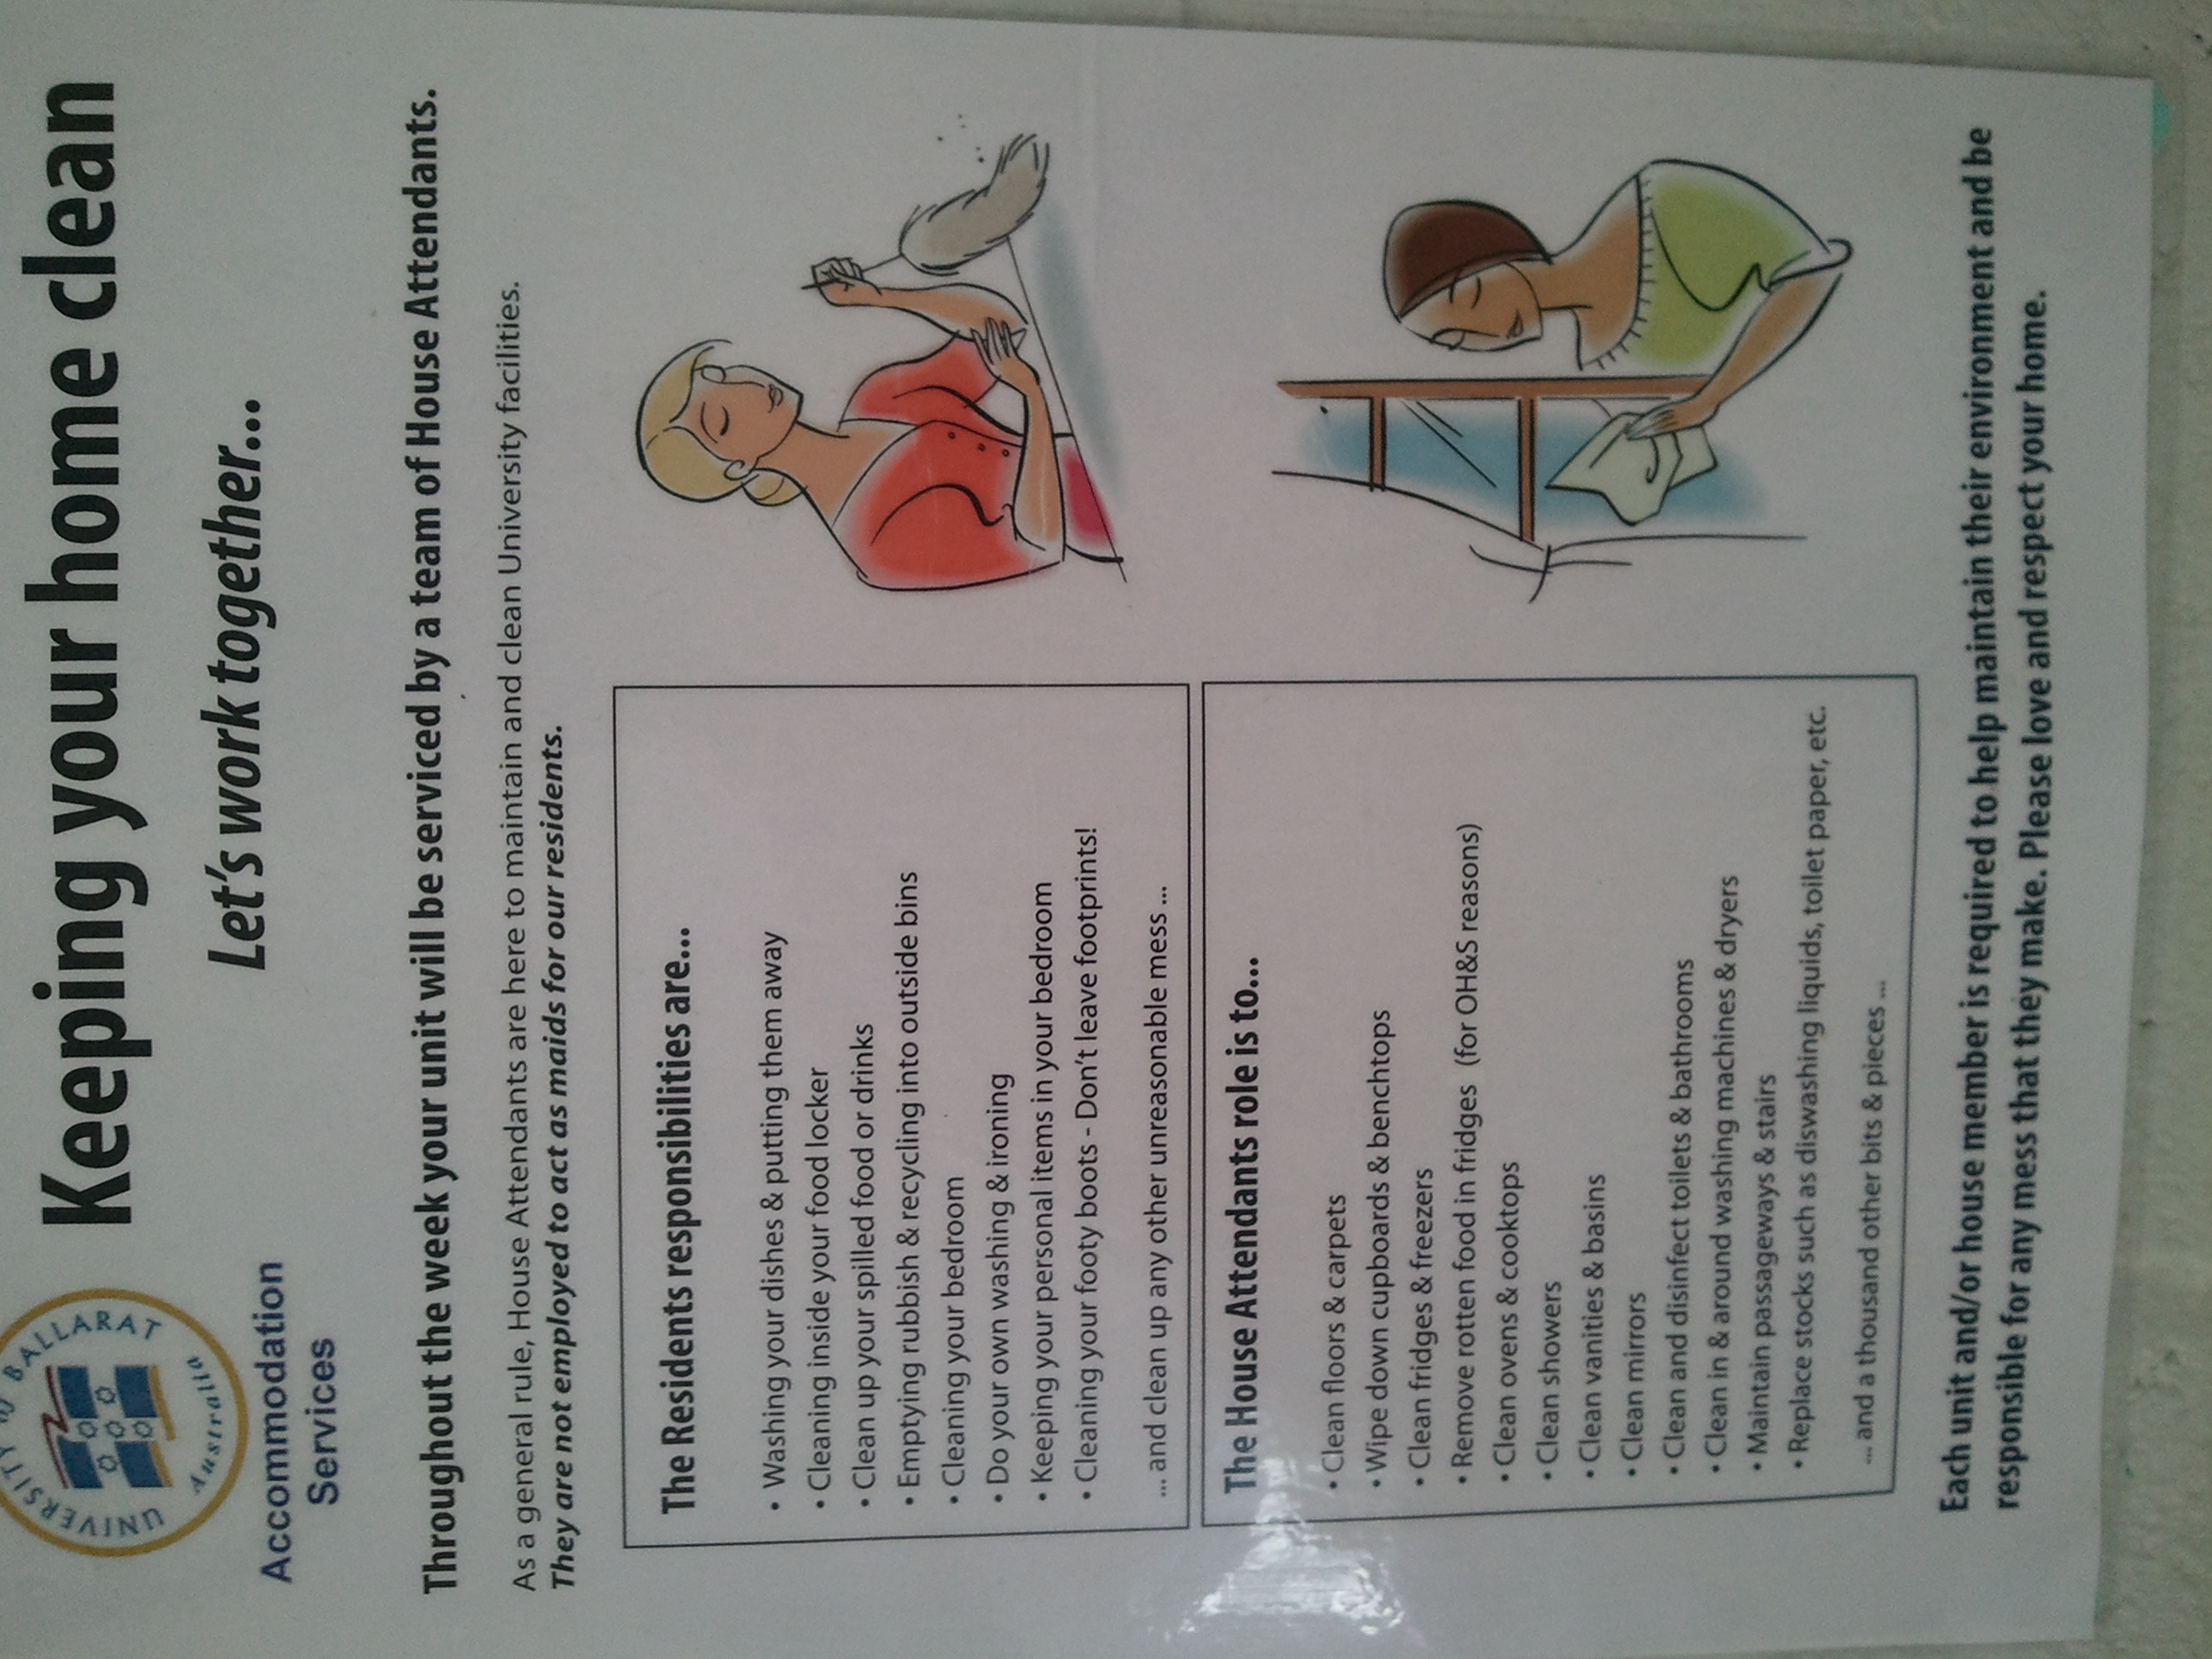
LCA 2013 [1] is starting so it seems like time to finish my write-up of LCA 2012. As usual it was a great conference, although I got sick immediately after getting there which reduced my ability to attend. Android A major unofficial theme of the conference was Android. Most delegates seemed to have Android phones, the Samsung Galaxy S and Galaxy Nexus seemed to be the most popular phones. Many delegates had two or more phones for development purposes. A large portion of the casual conversation at the conference concerned Android. There were a couple of really interesting talks about the Serval mesh networking project [2] which involves Android phones running in ad-hoc Wifi mode for long range communication without any official base station. Serval allows transferring messages, pictures, and voice calls. If you need to get longer range you can mount one phone in a convenient place and other phones will decide to use it as a relay there is no need to have a dedicated relay device (such as a mobile phone tower or Wifi access point). Serval is supposed to work with Wifi access points but due to Java not exposing some networking details to the higher levels of software the code that was available at the time of the conference didn t support networks other than a /24, which meant that the conference Wifi network didn t work with Serval. As an aside most people at the conference who installed Serval were using a development version that was newer than the version on the Android market. I can t remember what the extra features were though. Serval was designed for emergency situations, it can be installed on phones (and pushed to other phones via Wifi) in the field and allow communications when the infrastructure is broken. Also it s designed with some aim of circumventing censorship which among other things means that there are no facilities for tracking use. I think it would be really handy to be able to in some way track viewing of or interest in images that are transported via the mesh (maybe by something similar in concept to Google +1). Then in a crowd sourced environment people who take photos would be encouraged in their work by audience appreciation. One thing that interests me is the possibility of using Serval on a cruise ship. A cruise ship is an environment where mobile phone calls are unreasonably expensive, cabin phones aren t much use (who pays for a cruise and hangs out in their cabin?), and where there is usually a Wifi network installed. If a ship has a single bridged Wifi network that allows connecting to Wifi before authenticating for Internet access (which is probably the common case) then you could transport VOIP over that network without paying and without incurring any expense on the cruise company. One of the Serval developers assured me that this should be possible, of course a cruise ship with 3,000 passengers probably doesn t use a /24 for their Wifi so the current versions of Serval won t work At the geek my dinner event (a party where everyone brought $20 of food/drink which was cooked by volunteers) an artist showed me some art work that she created on her Samsung Galaxy Note (which was the biggest phone on sale at the time), it was very impressive. She recommended Picasso Mirror Draw, Sketch Free, Sketch Book Mobile Express, and Freenote as free graphical programs for Android. Samsung has a Noteworthy Project advertising campaign based on the artistic uses of the Galaxy Note which has some good videos of artists [3]. Chris Neugebauer and Paris Buttfield-Addison gave an informative and amusing talk about Android UI development (this link has the video) [4]. It s a pity that I missed seeing that one live but fortunately the video is of high quality. Accommodation picture of women cleaning As I ve become interested in Sociology I couldn t help but notice the pictures that accompanied the rules about cleaning the dormitory (which were displayed over the kitchen sink), it seems to imply that cleaning is only women s work. I wonder whether the people who created that poster deliberately chose pictures of women or whether they just chose the first available pictures from a collection of stock photos. Someone who was near my dorm room seemed to not realise how their alarm impacts other people. For the first two mornings I was woken repeatedly after 6AM by someone who was pressing the snooze button on their alarm. When sleeping in close proximity to other people the reasonable options involve some combination of having no loud alarm, immediately turning the alarm off and getting up (not pressing snooze to have it go off repeatedly), and setting the alarm for a time when almost everyone wants to get up (EG 1 hour before the first session). Networking Chris Neugebauer organised the Unprofessional Delegates Networking Session which was a great event. It was an event held at the same time as the Professional Delegates Networking Session with the difference being that you had to pay $5 for food and there was no free drink. A lot of great people attended the UPDNS so I m glad I don t pay for the PDNS. It seems that we won t have a UPDNS this year unfortunately. Conclusion LCA is always great fun and very educational. I recommend attending every year.

Russ Allbery: Introversion and mission statements

We had our tech leads retreat on Friday, including the discussion about "why," and I thought it was excellent, although I'm still trying to understand some parts of it. Part of why I'm still working on that is, well, you know that introversion thing? I had five and a half hours of meetings on Friday, and the tail end was an intense four and a half hour retreat, during which I was a major participant the whole time. And tried to say some difficult and intense things, both about the "why" conversation that I posted about and about why the tail end of last year was particularly difficult for me. All that went very well. I was very happy with the overall meeting. Sometimes, I half-convince myself that I'm overstating the degree that introversion or that interpersonal interaction affects me, or that I'm using it as an excuse to duck out of things that aren't really what I want to be working on. Then I do something like this, and find myself completely dead on my feet at the end of the meeting. Not physically tired, but utterly and completely drained. I went home and did something completely right-brain and creative and needed that so desperately that I stayed with it until two in the morning, slept in today until past noon, and still have, despite a couple of minor attempts, absolutely no capability to write code or focus on accomplishing anything. I'm fairly sure I'll still be feeling the after-effects on Monday and Tuesday. I'm a little annoyed at having both missed a day of releasing something to the world (I'd managed to post something every day this year until yesterday) and blowing off exercising yesterday evening for only the second time this year. But I think part of coming to terms with what introversion means is being kind to myself about this. That's something Cain talked a lot about in her book, and it's the advice I'd give to any other introvert, but it's something I'm not applying as well as I could. Being an introvert doesn't mean to not do meetings. It means to pick the ones that are important, do them with all your heart, and then be kind to yourself afterwards just as if you'd put in extreme effort to do something quite energetic and difficult. Because you have. So, I'm trying not to be annoyed at myself. And I think we need to be better about teaching people about this, because apart from Susan Cain, I don't remember many people writing about this, or understanding it. Occasionally there are screeds against meetings, but not a lot of discussion about when it's worth expending the energy, and about how to be kind to oneself and recharge after putting one's energy into the social interactions that are important. I did want to mention that while retreats seem to have a bad reputation in tech circles (and I've heard of a lot of retreats that I would hate), the ones that we do in our group are great. We spent about an hour talking about the things I posted about on Thursday, then a couple of hours talking about the larger organizational roadmap and searching out things that aren't on our upcoming work roadmap that feel like large missing pieces, and then a couple of hours identifying and enumerating our technical debt and deciding what major pieces of technical debt we're going to tackle in the next six months. It's a lot of concrete, specific discussion of what we're going to spend time on and what we're going to defend resources for by pushing back against other priorities. If I had to sum it up in a sentence, I'd say that these retreats are all about listing vaguely equal things that exceed our total capacity and making the decisions about which of them we're going to do and which of them we're not going to do so that we don't have to keep wasting time on revisiting unresolved decisions. The actual mission discussion turned into a discussion by each of us of what we most value in work, stated in terms very similar to what I used in my post, and that was wonderful. I found out things about my co-workers that I didn't know, and which will help me a great deal in improving their enjoyment of their work. I think we came away with a better idea of how to support each other in creating that engagement and excitement, and I think that's the best possible outcome. Since, like I said, I think that's the only real mission statement a group should have. We did, still, talk about having a mission statement anyway. Apparently having a shared statement is really important to people who aren't me. I'm still struggling with this, since it doesn't make sense to me and doesn't feel useful to me. But maybe it's a sort of validation and confirmation that we're allowed to focus on what we care about? But the group mission statement we came away with isn't about any specific technology and focuses on exactly the things that I care about: elegance, robustness, durability, and solving whatever problems the university has. As part of that discussion, we reached a surprising and really satisfying unanimity of opinion about what values we care deeply about. It's a value statement as opposed to a distillation of job descriptions, so if a mission statement is valuable for other people, that's one I'm quite happy with. Even if I don't understand why people want to have one. I'm less satisfied with the roadmap and strategic plan for our larger organization, but I'm starting to realize that's because I'm utterly not the target audience and it's not going to engage or interest me. It's more of a marketing statement that's focused externally, and my proper role in that is to try to help ensure that it reflects the enthusiasms and engagement of the line staff, not to try to turn it into a document that will be inspiring for the line staff. Which ties into what I was writing about previously: in my ideal world, these sorts of focuses flow upwards from the people who will be doing the work, not downward from a high-level manager deciding on an inspirational direction.

26 January 2013

Vipin Nair: Final Project (1/N): Introducing Simple Realtime Notification Service

I am building a realtime notification system as my final semester project. The end product is a simple API that can be used by third party to push real time notification to client applications running on multiple platforms that include browsers and devices. Ideally, if your device can connect to the internet, it should be able to receive notifications. The non functional system requirements are pretty ambitious with scalability, availability and latency guarantees being the most important. Maybe little too ambitious for someone like me but then I will learn a lot in this process and its more fun when its challenging. To address the scalability issues, we ll have to distribute the system. A single system will not scale beyond a point and we need to be able to distribute the load over nodes effectively to be able to serve clients while maintaining the quality of service guarantees. With distribution comes a whole lot of other problems like latency, coordination and handling failures. We have a theorem that officially states that you cannot have the pie and eat it too; its called the CAP theorem. It says that you cannot have have a system that is Consistent, Available and Partition tolerant at the same time (Partition tolerance here refers to the ability of a system to continue operating in the event of partial failures). You can have any two but not all three in varying degrees. In a way this is good because you do not go chasing the holy grail because you know it doesn t exist. CAP Twelve Years Later: How the Rules Have Changed is a good read for some sensible advice when applying CAP theorem to real world scenarios. Reading Notes on Distributed Systems for Young Bloods by Jeff Hodges is highly recommended for anyone starting to work on distributed systems. All the commons assumptions that you may have when you are building a distributed system is wrong, so wrong that it is sort of standardized now under the title Fallacies of Distributed Computing. A more detailed article is available here. I will be using concepts as given in the Amazon Dynamo paper to make the system highly available. This one is big and will a get a blog post of its own. The notification service that I am building at its core is a Publish/Subscribe system with soft real time guarantees. Right now I am clueless about how to deal with latency guarantees but I hope to figure it out soon. Websockets will be the application layer protocol that ll be used to push to browsers and for the trasport layer protocol I hear the MQTT protocol fits to a T. More on this later. I will updating my blog as the project progresses, documenting all the design decisions and the rationale behind them. The code will be available online. This is not something new and I am aware of tools that can do this. While I will try to improve on what already exists, the point is, as mentioned earlier, to learn something new and build what will be considered good software. I have never attended a distributed systems theory class, so I am reading up on that as well. Vector clocks are really cool, if you ask me. If you think this is too big, to be accomplished by a single student programmer in a semester s worth of effort, I wouldn t deny that but then when you pick the right tools for a job, things become a lot more easier and you can afford to be ambitious. Erlang for the win! Feel free to comment on what I am building as I may be potentially unaware of a lot of things I should be knowing. I could use all your suggestions/advice to make things better.

Ben Hutchings: What's in the Linux kernel for Debian 7.0 'wheezy', part 4

The Debian package of the Linux kernel is based on Linux 3.2, but has some additional features. This continues from parts 1, 2 and 3, and covers new and improved hardware support. DRM drivers from Linux 3.4 (proposed) Some recent Intel and AMD graphics chips were not supported well or at all by the DRM (Direct Rendering Manager) drivers in Linux 3.2. Although many bug fixes have been included in 3.2.y stable updates, we are considering updating them to the versions found in Linux 3.4. (We did something similar for Debian 6.0 'squeeze'.) Julien Cristau has been working on this and has prepared binary packages. To install, run as root:
gpg --no-default-keyring --keyring /usr/share/keyrings/debian-keyring.gpg --export 310180050905E40C   apt-key add -
echo deb http://people.debian.org/~jcristau/wheezy-drm34/ ./ > /etc/apt/sources.list.d/jcristau-wheezy-drm34.list
apt-get update
apt-get install linux-image-3.2.0-4.drm-amd64  # or -486, or -686-pae

Please test these and report your results to bug #687442. I would suggest testing suspend/resume (if applicable), use of internal and external displays on laptops, and 3D accelerated graphics (games and compositing window managers such as GNOME Shell). Remember that AMD/ATI graphics chips require the firmware from the firmware-linux-nonfree package for 3D acceleration and many other features. amilo-rfkill driver I wrote a standard rfkill driver for the Fujitsu-Siemens Amilo A1655 and M7440, based on the out-of-tree fsaa1655g and fsam7440 drivers. Unlike those, it should work with the rfkill command, Network Manager, etc. ALPS touchpads Newer touchpads made by ALPS use different protocols for reporting scroll and pinch gestures. Jonathan Nieder backported the changes to support these. Wacom tablets Jonathan Nieder updated the wacom driver to the version in Linux 3.5, adding support for the Intuos5, Bamboo Connect, Bamboo 16FG and various other models. Emulex OneConnect 'Skyhawk' Sarveshwar Bandi at Emulex contributed a backport of the be2net driver from Linux 3.5, adding support for their 'Skyhawk' chip. Marvell Kirkwood Marvell's Kirkwood SoCs have been supported upstream for some time and in Debian since release 6.0 'squeeze'. However new models and boards generally require specific support. Arnaud Patard backported support for the 6282 rev A1 chip found in QNAP TS-x19P II models, and for the Marvell Dreamplug and Iomega Iconnect. Miscellaneous More to come Missing hardware support is an important bug that can be fixed by kernel updates during a freeze and throughout the lifetime of a stable release. If you know that new hardware isn't supported by the Debian kernel, please open a bug report. I can't promise that it will be fixed, but we need to know what's missing. Hardware vendors that maintain their own drivers upstream (not out-of-tree) are especially welcome to contribute tested backports that add support for the latest hardware. Send mail to debian-kernel@lists.debian.org if you have any questions about this.

Eddy Petrișor: (Serial) console flooded with kernel messages?

(If you want to ignore the explanations and see how to stop the Linux kernel from flooding the console with low importance messages, go straight to the bottom of the article, is the small bit at end with larger font.)

After connecting to the serial console on my Linksys WRT160NL router I was faced with the problem that the console was flooded with all sorts of messages such as:
DROP IN=eth1 OUT= SRC=X.Y.Z.W DST=255.255.255.255 PROTO=UDP SPT=58488 DPT=2008 LEN=26
DROP IN=eth1 OUT= SRC=X.Y.Z.U DST=178.156.183.255 PROTO=UDP SPT=137 DPT=137 LEN=58
DROP IN=eth1 OUT= SRC=X.Y.Z.W DST=255.255.255.255 PROTO=UDP SPT=58488 DPT=2008 LEN=26
ACCEPT IN=br0 OUT=eth1 SRC=a.b.c.d DST=69.171.246.16 PROTO=TCP SPT=3651 DPT=443
DROP IN=eth1 OUT= SRC=X.Y.Z.U DST=178.156.183.255 PROTO=UDP SPT=137 DPT=137 LEN=58
DROP IN=eth1 OUT= SRC=X.Y.Z.W DST=255.255.255.255 PROTO=UDP SPT=58488 DPT=2008 LEN=26
DROP IN=eth1 OUT= SRC=178.156.183.146 DST=255.255.255.255 PROTO=UDP SPT=17500 DPT=17500 LEN=120
DROP IN=eth1 OUT= SRC=178.156.183.146 DST=178.156.183.255 PROTO=UDP SPT=17500 DPT=17500 LEN=120
DROP IN=eth1 OUT= SRC=178.156.183.146 DST=255.255.255.255 PROTO=UDP SPT=17500 DPT=17500 LEN=120
DROP IN=eth1 OUT= SRC=X.Y.Z.W DST=255.255.255.255 PROTO=UDP SPT=58488 DPT=2008 LEN=26
DROP IN=eth1 OUT= SRC=178.156.177.142 DST=255.255.255.255 PROTO=UDP SPT=17500 DPT=17500 LEN=153

The serial console was working, but it was impossible to do anything practical in these conditions. I tried looking on the net for 'linux stop console flooding' and similar terms, but didn't get too far, except the fact the problem was the loglevel.

Here is the explanation of what this means (quote from Documentation/kernel-parameters.txt):

        loglevel=       All Kernel Messages with a loglevel smaller than the
                        console loglevel will be printed to the console. It can
                        also be changed with klogd or other programs. The
                        loglevels are defined as follows:
                        0 (KERN_EMERG)          system is unusable
                        1 (KERN_ALERT)          action must be taken immediately
                        2 (KERN_CRIT)           critical conditions
                        3 (KERN_ERR)            error conditions
                        4 (KERN_WARNING)        warning conditions
                        5 (KERN_NOTICE)         normal but significant condition
                        6 (KERN_INFO)           informational
                        7 (KERN_DEBUG)          debug-level messages


This was enough to go through my local git tree of the kernel in the Documentation directory and grep for loglevel. This brought me to this interesting bit from Documentation/sysctl/kernel.txt
==============================================================
printk:
The four values in printk denote: console_loglevel,
default_message_loglevel, minimum_console_loglevel and
default_console_loglevel respectively.
These values influence printk() behavior when printing or
logging error messages. See 'man 2 syslog' for more info on
the different loglevels.
- console_loglevel: messages with a higher priority than
  this will be printed to the console
- default_message_loglevel: messages without an explicit priority
  will be printed with this priority
- minimum_console_loglevel: minimum (highest) value to which
  console_loglevel can be set
- default_console_loglevel: default value for console_loglevel
==============================================================

So I ran 'cat /proc/sys/kernel/printk' and got (I managed to read it through the flood of messages from the firewall):

7       4       1       7
According to the explanations above, that meant that console_loglevel was too, so to fix it I ran:
echo '2 4 1 7' > /proc/sys/kernel/printk
And, behold, the serial console was usable.

25 January 2013

Richard Hartmann: Please don't do this

Update: They got & reported him. Most of you will have seen the news about various private files being hosted on github as this little has taken the Internet by storm yesterday. Obviously most of those files can be found via Google and other means as well, but this exposure is a bit worse inasmuch people will keep on updating their secret information automagically and continuously. Personal favourites that used to work until yesterday include And various other config and history files for AWS, RT, whatnot. Plus, it was really easy to search for certain actions like so. Another fun thing look for were ENV variables setting passwords, hosts, etc. Ironically, having the SSH identity files means anyone is able to change pretty much anything about a person's repositories on github. This includes files like .zshrc which basically allows complete takeover of any account and often machine that file is sourced from. Which reminds me that I still need to add a way for vcsh to only merge commits that have a tag signed with a trusted key and warn for everything else, but I digress. None of this is a problem with github specifically, it's a problem with users who don't think their actions through. And this is non-trivial for github or anyone else to fix as there are potentially endless sources of otherwise secret information. Initially, I sent email to github's quite responsive security team asking them to forbid certain queries and to email users who checked in their private data by accident and left it at that. They got back to me extremely fast, promising to do their best (as of right now, no queries I tried work any more) and after some conversation asked me to link to their help article on removing sensitive data if I were to blog about this. The topic itself has been covered extensively, github did their best to keep user data private, and so the above could have been done without, but... ...I have gotten word of 4chan's /g/ sleuthing their way through various files and at least one incident of people finding direct evidence of child pornography in a Zsh history file. Sadly, this story found its way to me without a link and the person who saw the thread read it on a tablet, preserving neither the URL nor local cache. They saw it on 2013-01-24 at around 2200 UTC. If you, or someone you know, saw anything plainly illegal, immoral, and simply wrong... please report it to the relevant authorities or at least github. As I suspect that there's some overlap between the subscribers of the various planets I am aggregated on and /g/, this may reach the right eyes. Between the account name, a verified email address, access logs with IPs, and possibly a real name, it should be comparatively easy to find anyone you report.

Steve Kemp: Shame there isn't more competition for self-hosted analytics

Today I've been mostly replanting spider-plants, aloe-vera plants, and shuffling trees around inside my flat. Beyond that I've been updating my trivial dashboard skeleton, which was put together as part of this simple introduction article. (So there is a standalone redis&sinatra-using visualization server) After working on the display I was suddenly reminded that I run a cluster now. That means I have four servers each writing a local Apache logfile, and no central way of viewing all my visitor-data. There are several open source analytic packages such as piwik and openwebanalytics - but they require MySQL & PHP at the back-end. Given that node.js is "teh new shiny" it is a surprise there isn't something out there using that, and web sockets perhaps, to collect visitor data. I found a few toy projects, but nothing that seemed to be a clear winner. Adding some javascript to webpages to submit: Is trivial. The hard part is storing that and visualizing it in a neat way. Making data pretty is something I'm notoriously bad at - unless it is turning numbers into graphs using a good library I'm out of luck most of the time. Anyway I will keep digging. Ideally I'll have a scalable node service that'll receive submissions, bung them in redis, and then show real-time activity in a sexy fashion. I can dream?

Josselin Mouette: So(lusOS) I herd U liek mudslingingz?

After this announcement about the future of GNOME in Debian, I received several requests to look at SolusOS and their Consort fork of GNOME. On the paper, this doesn t look like a too bad idea, since they only forked gnome-panel and metacity, the two key components that are no longer maintained upstream. Still, starting a plain fork at the very moment when the former maintainer decided to give the key to anyone who wanted to, looked like a very destructive way of acting. Even if the fork gains momentum (which remains speculative), the amount of effort to rename packages makes you think twice before such a switch. I decided to go talk about it with them on IRC nevertheless. Mind you, they work on a GNOME fork and a Debian derivative, but deliberately use their own IRC server (you ll soon understand why). Just in case you would want to cooperate with SolusOS, you d have to use their infrastructure. It is an euphemism to say that the conversation didn t go well. This could have ended there, but thankfully for your already widening eyes, Ikey (the charming person I had the opportunity to discuss with) made the log public, in an attempt at public shaming that would soon gather his followers, chanting out loud how the revolutionary SolusOS would quickly replace every other Linux distribution. (As a side note, of the hundreds of such claims that were made public in the last 10 years, only one came true, and it was from a billionnaire who hired dozens of developers. Just saying.) Then you can understand why the specific IRC server: it is to K-line people who don t behave with enough deference to Ikey, because kickban is not enough. This log and the claims made in the comments look very ironical, if only for presenting a person working in a team of 10+ on the most popular desktop on one of the most popular desktop distributions, as a beggar. Even more ironical when it is the person who spent the most time on making GNOME Classic available and working nicely for wheezy. So when a dozen kids go chanting that Consort is so much better than GNOME and will replace it, while it just re-does the work I already did, let me at least smile. So what is SolusOS, after all? If you want to see where this story is going, there s a place that tells you: the consortium and consort-panel repositories. Here you will find interesting things: I ve stopped looking there. We re facing an ego issue, but not something that can improve the desktop for our users. In the end, I m sorry for those who genuinely thought we could do better by sharing some maintenance load with SolusOS, but it doesn t look like a big loss anyway.

Johannes Schauer: Bootstrappable Debian - New Milestone

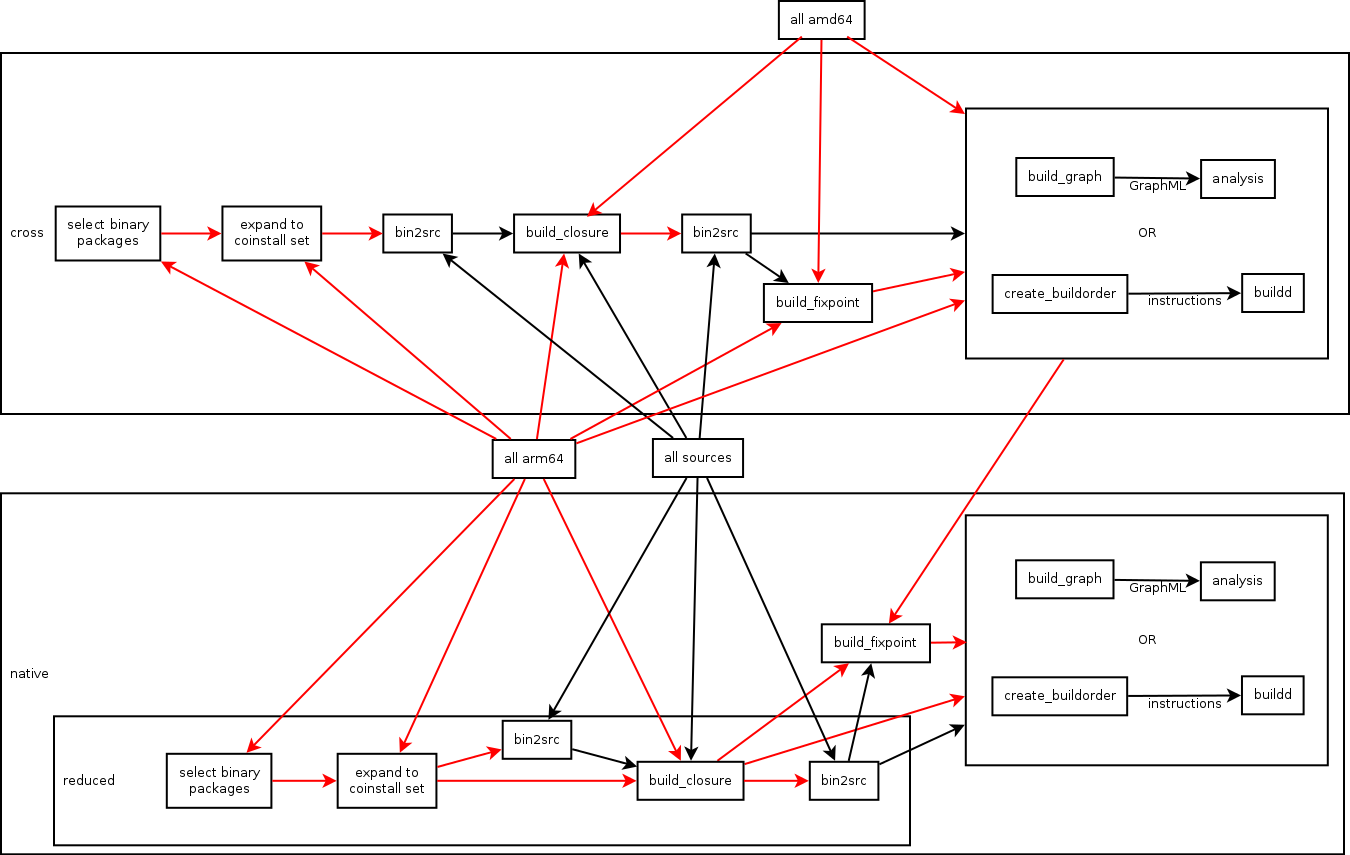
This post is about the port bootstrap build ordering tool (naming suggestions welcome) which was started as a Debian Google Summer of Code project in 2012 and continued to be developed afterwards. Sources are available through gitorious. In the end of November 2012, I managed to put down an approximation algorithm to the feedback arc set problem which allowed to break the dependency graph into a directed acyclic graph with only few removed build dependencies. I wrote about this effort on our mailinglist but didnt mention it here because it was still too much of a proof-of-concept. Later, in January 2013, I mentioned the result of this algorithm in an email wookey and me wrote to debian-devel mailinglist. Many things happened since November 2012:

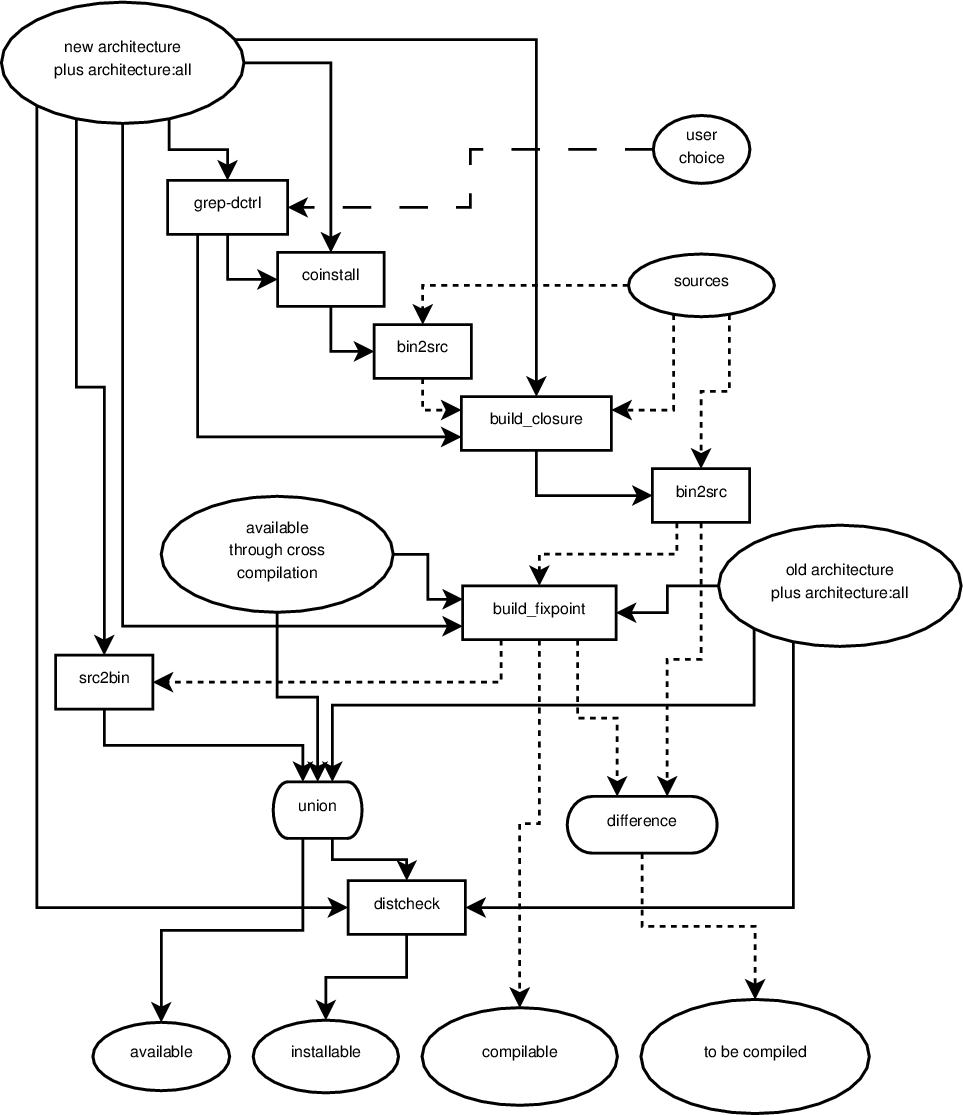
Processing pipeline instead of monolithic tools The tools I developed so far tried to accomplish everything by themselves, reusing functionality implemented in a central library. Therefor, if one wanted to try out even trivial new things, it mostly meant to hack some OCaml code. Pietro Abate suggested to instead develop smaller tools which could work independently of each other, would only execute one algorithm each and could easily be connected together in different ways to achieve different effects. This switch is now done and all functionality from the old tools is moved into a new toolset. The exchange format between the tools is either plain text files in deb822 control format (Packages/Sources files) or a dependency graph. The dependency graph is currently marshalled by OCaml but future versions should work with just passing a GraphML (an XML graph format) representation around. This new way of doing things seems close to the UNIX philosophy (each program does one thing well, data is stored as text, every program is a filter). For example the deb822 control output can easily be manipulated using grep-dctrl(1) and there exist many tools which can read, analyze and manipulate GraphML. It is a big improvement over the old, monolithic tools which did not allow to manipulate any intermediate result by external, existing tools. Currently, a shell script (native.sh) will execute all tools in a meaningful order, connecting them together correctly. The same tools will be used for a future cross.sh but they will be connected differently. I wrote about a first proposal of what the individual tools should do and how they should be connected in this email from which I also linked a confusing overview of the pipeline. This overview has recently been improved to be even more confusing and the current version of the lower half (the native part) now looks like this: native reduced Solid arrows represent a flow of binary packages, dottend arrows represent a flow of source packages, ovals represent a set of packages, boxes with rounded corners represent set operations, rectangular boxes represent filters. There is only one input to a filter, which is the arrow connected to the top of the box. Outgoing arrows from the bottom represent the filtered input. Ingoing arrows to either side are arguments to the filter and control how the filter behaves depending on the algorithm. I will explain this better once the pipeline proved to be less in flux. The pipeline is currently executed like this by native.sh.
Two new ways to break dependency cycles have been discovered So far, we knew of three ways to formally break dependency cycles:
  • remove build dependencies through build profiles
  • find out that the build dependency is only used to build arch:all packages and therefor put it into Build-Depends-Indep
  • cross compile some source packages
Two new methods can be added to the above:

Dependency graph definition changed Back in September when I was visiting irill, Pietro found a flaw in how the dependency graph used to be generated. He supplied a new definition of the dependency graph which does away with the problem he found. After fixing some small issues with his code, I changed all the existing algorithms to use the new graph definition. The old graph is as of today removed from the repository. Thanks to Pietro for supplying the new graph definition - I must still admit that my OCaml foo is not strong enough to have come up with his code.

Added complexity for profile built source packages As mentioned in the introduction, wookey and me addressed the debian-devel list with a proposal on necessary changes for an automated bootstrapping of Debian. During the discussiong, two important things came up which are to be considered by the dependency graph algorithms:
  • profile built source packages may not create all binary packages
  • profile built source packages may need additional build dependencies
Both things make it necessary to alter the dependency graph during the generation of a feedback arc set and feedback vertex set beyond the simple removal of edges. Luckily, the developed approximation algorithms can be extended to support such changes in the graph.

Different feedback arc set algorithms The initially developed feedback arc set algorithm is well suited to discover build dependency edges which should be dropped. It performs far worse when creating the final build order because it only considers edges by itself and not how many edges of a source package can be dropped by profile building it. The adjusted algorithm for generating a build order is more of a feedback vertex set algorithm because instead of greedily finding the edge with most cycles through it, it greedily finds the source package which would break most cycles if it was profile built.

Generating a build order with less profile built source packages After implementing all the features above I now feel more confident to publish the current status of the tools to a wider audience. The following test shows a run of the aforementioned ./native.sh shell script. Its final output is a list of source packages which have to be profile built and a build order. Using the resulting build order, starting from a minimal build system (essential:yes, build-essential and debhelper), all source packages will be compiled which are needed to compile all binary packages in the system. The result will therefor be a list of source and binary packages which fulfill the following property:
  • all binary packages can be built from the available source packages
  • all source packages can be built with the available binary packages
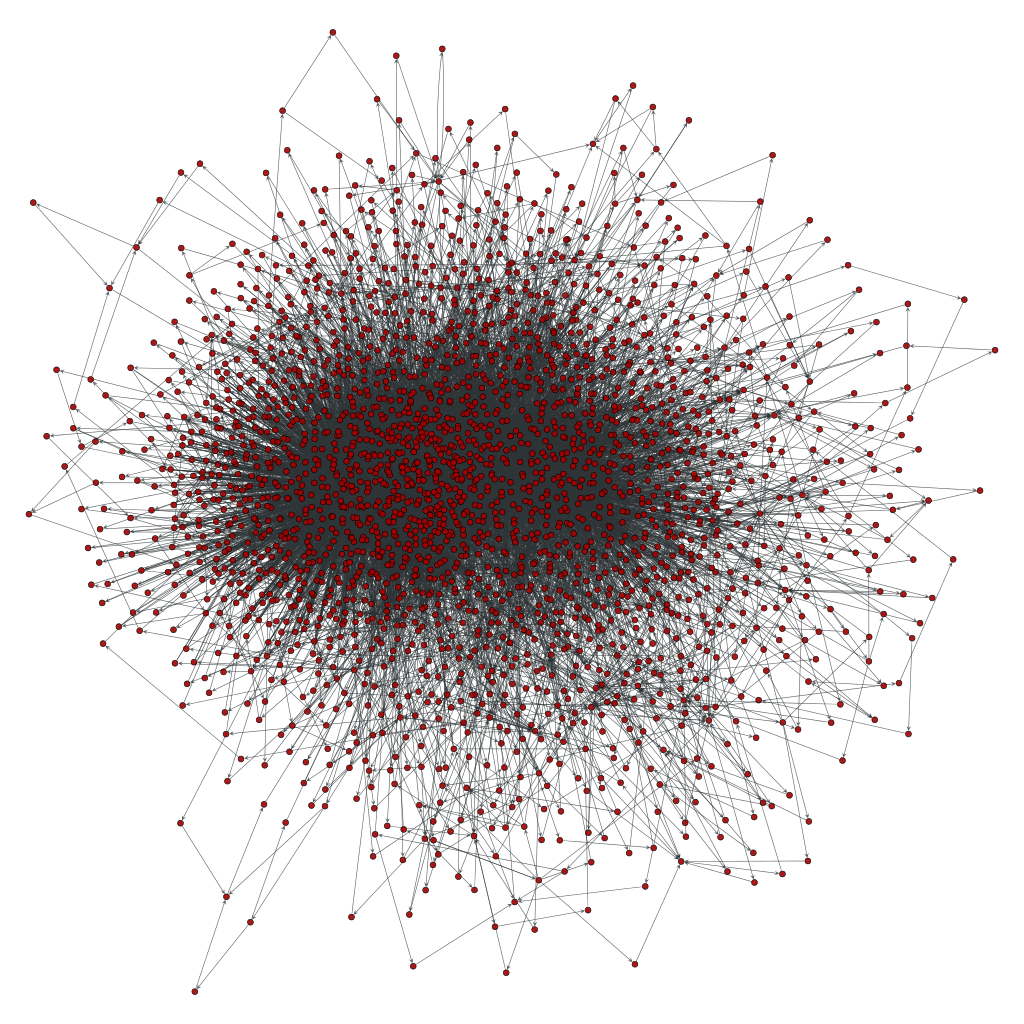
I called this a "reduceded distribution" in earlier posts. The interesting property of this specific selection is, that it contains the biggest problem set of Debian when bootstrapping it: a 900 to 1000 nodes big strongly connected component. Here is a visualization of the problem: hideous mess Source packages do not yet come with build profiles and the cross build situation can not yet be analyzed, so the following assumptions were made: The last point is about 14 build dependencies which were decided to be broken by the feedback arc set algorithm but for which other data sources did not indicate that they are actually breakable. Those 14 are dynamically generated by native.sh. If above assumptions should not be too far from the actual situation, then not more than 73 source packages have to be modified to bootstrap a reduced distribution. This reduced distribution even includes dependency-wise "big" packages like webkit, metacity, iceweasel, network-manager, tracker, gnome-panel, evolution-data-server, kde-runtime, libav and nautilus. By changing one line in native.sh one could easily develop a build order which generates gnome-desktop or really any given (meta-)package selection. All of native.sh takes only 80 seconds to execute on my system (Core i5, 2.5 GHz, singlethreaded). Here is the final build order which creates 2044 binary packages from 613 source packages.
  1. nspr, libio-pty-perl, libmcrypt, unzip, libdbi-perl, cdparanoia, libelf, c-ares, liblocale-gettext-perl, libibverbs, numactl, ilmbase, tbb, check, libogg, libatomic-ops, libnl($), orc($), libaio, tcl8.4, kmod, libgsm, lame, opencore-amr, tcl8.5, exuberant-ctags, mhash, libtext-iconv-perl, libutempter, pciutils, gperf, hspell, recode, tcp-wrappers, fdupes, chrpath, libbsd, zip, procps, wireless-tools, cpufrequtils, ed, libjpeg8, hesiod, pax, less, dietlibc, netkit-telnet, psmisc, docbook-to-man, libhtml-parser-perl, libonig, opensp($), libterm-size-perl, linux86, libxmltok, db-defaults, java-common, sharutils, libgpg-error, hardening-wrapper, cvsps, p11-kit, libyaml, diffstat, m4
  2. openexr, enca, help2man, speex, libvorbis, libid3tag, patch, openjade1.3, openjade, expat, fakeroot, libgcrypt11($), ustr, sysvinit, netcat, libirman, html2text, libmad, pth, clucene-core, libdaemon($), texinfo, popt, net-tools, tar, libsigsegv, gmp, patchutils($), dirac, cunit, bridge-utils, expect, libgc, nettle, elfutils, jade, bison
  3. sed, indent, findutils, fastjar, cpio, chicken, bzip2, aspell, realpath, dctrl-tools, rsync, ctdb, pkg-config($), libarchive, gpgme1.0, exempi, pump, re2c, klibc, gzip, gawk, flex-old, original-awk, mawk, libtasn1-3($), flex($), libtool
  4. libcap2, mksh, readline6, libcdio, libpipeline, libcroco, schroedinger, desktop-file-utils, eina, fribidi, libusb, binfmt-support, silgraphite2.0, atk1.0($), perl, gnutls26($), netcat-openbsd, ossp-uuid, gsl, libnfnetlink, sg3-utils, jbigkit, lua5.1, unixodbc, sqlite, wayland, radvd, open-iscsi, libpcap, linux-atm, gdbm, id3lib3.8.3, vo-aacenc, vo-amrwbenc, fam, faad2, hunspell, dpkg, tslib, libart-lgpl, libidl, dh-exec, giflib, openslp-dfsg, ppl($), xutils-dev, blcr, bc, time, libdatrie, libpthread-stubs, guile-1.8, libev, attr, libsigc++-2.0, pixman, libpng, libssh2, sqlite3, acpica-unix, acl, a52dec
  5. json-c, cloog-ppl, libverto, glibmm2.4, rtmpdump, libdbd-sqlite3-perl, nss, freetds, slang2, libpciaccess, iptables, e2fsprogs, libnetfilter-conntrack, bash, libthai, python2.6($), libice($), libpaper, libfontenc($), libxau, libxdmcp($), openldap($), cyrus-sasl2($), openssl, python2.7($)
  6. psutils, libevent, stunnel4, libnet-ssleay-perl, libffi, readline5, file, libvoikko, gamin, libieee1284, build-essential, libcap-ng($), lcms($), keyutils, libxml2, libxml++2.6, gcc-4.6($), binutils, dbus($), libsm($), libxslt, doxygen($)
  7. liblqr, rarian, xmlto, policykit-1($), libxml-parser-perl, tdb, devscripts, eet, libasyncns, libusbx, icu, linux, libmng, shadow, xmlstarlet, tidy, gavl, flac, dbus-glib($), libxcb, apr, krb5, alsa-lib
  8. usbutils, enchant, neon27, uw-imap, libsndfile, yasm, xcb-util, gconf($), shared-mime-info($), audiofile, ijs($), jbig2dec, libx11($)
  9. esound, freetype, libxkbfile, xvidcore, xcb-util-image, udev($), libxfixes, libxext($), libxt, libxrender
  10. tk8.4, startup-notification, libatasmart, fontconfig, libxp, libdmx, libvdpau, libdrm, libxres, directfb, libxv, libxxf86dga, libxxf86vm, pcsc-lite, libxss, libxcomposite, libxcursor, libxdamage, libxi($), libxinerama, libxrandr, libxmu($), libxpm, libxfont($)
  11. xfonts-utils, libxvmc, xauth, libxtst($), libxaw($)
  12. pmake, corosync, x11-xserver-utils, x11-xkb-utils, coreutils, xft, nas, cairo
  13. libedit, cairomm, tk8.5, openais, pango1.0($)
  14. ocaml, blt, ruby1.8, firebird2.5, heimdal, lvm2($)
  15. cvs($), python-stdlib-extensions, parted, llvm-2.9, ruby1.9.1, findlib, qt4-x11($)
  16. xen, mesa, audit($), avahi($)
  17. x11-utils, xorg-server, freeglut, libva
  18. jasper, tiff3, python3.2($)
  19. openjpeg, qt-assistant-compat, v4l-utils, qca2, jinja2, markupsafe, lcms2, sip4, imlib2, netpbm-free, cracklib2, cups($), postgresql-9.1
  20. py3cairo, pycairo, pam, libgnomecups, gobject-introspection($)
  21. gdk-pixbuf, libgnomeprint, gnome-menus, gsettings-desktop-schemas, pangomm, consolekit, vala-0.16($), colord($), atkmm1.6
  22. libgee, gtk+3.0($), gtk+2.0($)
  23. gtkmm2.4, poppler($), openssh, libglade2, libiodbc2, gcr($), libwmf, systemd($), gcj-4.7, java-atk-wrapper($)
  24. torque, ecj($), vala-0.14, gnome-keyring($), gcc-defaults, gnome-vfs($)
  25. libidn, libgnome-keyring($), openmpi
  26. mpi-defaults, dnsmasq, wget, lynx-cur, ghostscript, curl
  27. fftw3, gnupg, libquvi, xmlrpc-c, raptor, liboauth, groff, fftw, boost1.49, apt
  28. boost-defaults, libsamplerate, cmake, python-apt
  29. qjson, qtzeitgeist, libssh, qimageblitz, pkg-kde-tools, libical, dwarves-dfsg, automoc, attica, yajl, source-highlight, pygobject, pygobject-2, mysql-5.5($)
  30. libdbd-mysql-perl, polkit-qt-1, libdbusmenu-qt, raptor2, dbus-python, apr-util
  31. rasqal, serf, subversion($), apache2
  32. git, redland
  33. xz-utils, util-linux, rpm, man-db, make-dfsg, libvisual, cryptsetup, libgd2, gstreamer0.10
  34. mscgen, texlive-bin
  35. dvipng, luatex
  36. libconfig, transfig, augeas, blas, libcaca, autogen, libdbi, linuxdoc-tools, gdb, gpm
  37. ncurses, python-numpy($), rrdtool, w3m, iproute, gcc-4.7, libtheora($), gcc-4.4
  38. libraw1394, base-passwd, lm-sensors, netcf, eglibc, gst-plugins-base0.10
  39. libiec61883, qtwebkit, libvirt, libdc1394-22, net-snmp, jack-audio-connection-kit($), bluez
  40. redhat-cluster, gvfs($), pulseaudio($)
  41. phonon, libsdl1.2, openjdk-6($)
  42. phonon-backend-gstreamer($), gettext, libbluray, db, swi-prolog, qdbm, swig2.0($)
  43. highlight, libselinux, talloc, libhdate, libftdi, libplist, python-qt4, libprelude, libsemanage, php5
  44. samba, usbmuxd, libvpx, lirc, bsdmainutils, libiptcdata, libgtop2, libgsf, telepathy-glib, libwnck3, libnotify, libunique3, gnome-desktop3, gmime, glib2.0, json-glib, libgnomecanvas, libcanberra, orbit2, udisks, d-conf, libgusb
  45. libgnomeprintui, libimobiledevice, nautilus($), libbonobo, librsvg
  46. evas, wxwidgets2.8, upower, gnome-disk-utility, libgnome
  47. ecore, libbonoboui
  48. libgnomeui
  49. graphviz
  50. exiv2, libexif, lapack, soprano, libnl3, dbus-c++
  51. atlas, libffado, graphicsmagick, libgphoto2, network-manager
  52. pygtk, jackd2, sane-backends, djvulibre
  53. libav($), gpac($), ntrack, python-imaging, imagemagick, dia
  54. x264($), matplotlib, iceweasel
  55. strigi, opencv, libproxy($), ffms2
  56. kde4libs, frei0r, glib-networking
  57. kde-baseapps, kate, libsoup2.4
  58. geoclue, kde-runtime, totem-pl-parser, libgweather, librest, libgdata
  59. webkit
  60. zenity, gnome-online-accounts
  61. metacity, evolution-data-server
  62. gnome-panel
  63. tracker
The final recompilation of profile built source packages is omitted. Source packages marked with a ($) are selected to be profile built. All source packages listed in the same line can be built in parallel as they do not depend upon each other. This order looks convincing as it first compiles a multitude of source packages which have no or only few build dependencies lacking. Later steps allow fewer source packages to be compiled in parallel. The amount of needed build dependencies is highest in the source packages that are built last.

Neil Williams: Hard drive death

My 1Tb laptop drive started misbehaving a few weeks ago, just spending a lot of time spinning when it should have been reading frequently changed files (like the browser cache). I was tempted to blame the browser at that point as no other packages appeared affected.

Wednesday night, a routine package upgrade on unstable brought in a bunch of qt4 updates which I wanted and a virtual box update that I didn't see much point in delaying ... 15 minutes later I couldn't work out why the virtualbox dkms task was still running, spotted it spinning in depmod and found some alarming messages in dmesg about short reads and errors reading from the hard drive. Hmm. The hard drive was out of control at this point, it quickly became apparent that no disc access was going to be possible and I couldn't get to a terminal to kill the current tasks, so I killed the power. The fsck which followed reboot showed more of the errors I'd seen in dmesg and fell back to the manual intervention stage. A few hours of confirming attempts to fix the errors, fsck finally finished. A short amount of usage showed that although fsck had finished, the drive was not happy and was starting to give short reads on other parts of the filesystem, resulting in ~40% of the filesystem appearing to be read-only when the rest was read-write. Somehow, I didn't think this was a welcome feature as the areas affected appeared to be quite random.

The drive in question was a replacement for the original 300Gb drive supplied with the ThinkPad, so a quick bit of switching of drives into a caddy and I could rsync my data off the large drive onto the smaller one. The rsync itself took a lot longer than it should have done because it got lots of short reads too. (Principally in /lib/modules/3.2.0-4/ and in the browser cache directories which had been the original symptom as well as most other places where one could have expected processes to have open files when the drive failed).

Now the 1Tb drive was a pig to fit into the Thinkpad originally because it was too big for the bay but I fitted it anyway. Yes, that was probably a mistake. It certainly meant that in order to fit it I had to not put the drive into the useful caddy provided by Lenovo which makes removal of the drive simple. Indeed the drive was wedged into the bay so tightly that it wasn't going to come out with normal levels of persuasion. This probably contributed to the failure of the drive, so live and learn.

With help from Andy Simpkins (it's always handy to have a hardware engineer on hand at times like this), the keyboard was lifted out, the case was dismantled and just enough room was made to get a screwdriver in behind the sata drive and lever it out of the bay. OK, rebuild laptop, put replacement drive into the caddy (because the smaller capacity drive is also a lot smaller in height than the 1Tb and therefore has plenty of clearance between it and the bay) and move on to the software recovery stage.

Hint: if this happens again, before turning off the broken system for the last time, just remember to download a recent Debian ISO to a USB stick - it saves having to ask someone else or find another machine to do the download. (Thanks Andy...)

OK, so after the usual complaints on reboot that there was no operating system, F12 got the boot order menu up and I was in Debian Installer Rescue Mode. Reinstalling grub failed initially for a few reasons:

  1. I'd deliberately not copied /dev /proc and /sys from the old harddrive but I'd also forgotten to create empty ones on the new drive...
  2. /etc/fstab helpfully referred to / as a UUID which no longer applied, so that had to be edited
  3. grub was confused and couldn't find the root filesystem

A few iterations later, I had a working /dev directory inside the /target chroot, bind mounted from the /dev outside the chroot, I was able to mount proc and sys, so grub was finally happy to reinstall itself and then update the initramfs setup for the new drive.

Reboot, another fsck, all appeared well. I was able to login via the terminal but not in X. Hmmm. Stop xdm, startx manually from the terminal, problems with /tmp/ - permission denied. Oops. Yes, it does help to create /tmp with the right permissions....

The final stage was to complete the dpkg --configure -a from the original failure. I've yet to reinstall the 3.2.0-4 kernel, so I'm back on 3.2.0-3 but that's OK.

So now I'm back on the original drive, albeit temporarily without any swap whatsoever (because I didn't partition the replacement drive to create /dev/sda5 before doing the copy) and now I remember the second reason I wanted to replace the original drive with the 1Tb drive - the original drive is as NOISY as hell. The whole edge of the laptop vibrates constantly, to the point that I can feel the vibration under the keys as I type. It's not that the drive is loose in the bay, it's just a constant vibration.

But, I have kept all my data and I have a usable laptop for the BSP this weekend. I will be looking at an SSD drive to replace this one though and having also found my old Acer laptop with power supply, I can now reference this entry when I transfer the system a second time.

Russ Allbery: The "Why?" of Work

(This is going to be long and rambling. Hopefully at some point I'll be able to distill it into something shorter.) In preparation for a tech leads retreat tomorrow, several of us at work were asked to watch Simon Sinek's TED talk, "How great leaders inspire action". I'll be honest with you: I hated this talk. Sinek lost me right at the start by portraying his idea as the point of commonality among great leaders (don't get me started on survivorship bias; it's a pet peeve) and then compounded the presentation problem with some dubious biology about brain structure. So, after watching it, I ranted a bit about how much I disliked it (to, as it turns out, people who had gotten a lot out of it). (Don't do this, btw. It's nearly always worthwhile to suppress negativity about something someone else enjoyed. I say this to increase the pool of people who can remind me of what I said the next time I forget. Which, if my normal pattern holds, will be about five minutes from now.) Thankfully, I work with tolerant and forgiving people who kindly pointed out the things they saw in the video that I missed, and we ended up having a really good hour and a half discussion, which convinced me that there's an idea under here that's worth talking about. It also helped clarify for me just how much I hate the conventional construction of both leadership and success. This talk is framed around getting other people to do things, which is one of the reasons why I had such a negative reaction to it. It's right there in the title: leaders inspiring action. This feeds into what at least in the United States is an endemic belief that the world consists of leaders and followers, and that the key to success in the world (in business, in politics, in everything else) is to become one of the leaders and accumulate followers (most frequently as customers, since we have a capitalist obsession). This is then defined as success. I think this idea of success is bullshit. Now, that statement requires an immediate qualification. Saying that the societal definition of success is bullshit is a statement from privilege. I have the luxury of saying that because I am successful; I'm in a position where I have a lot of control over my own job, I'm not struggling to make ends meet, and I can spend my time pondering existential questions like how to define success. If I were a little less lucky, success would be whatever put food on the table and kept a roof over my head. I'm making an argument from the top of Maslow's hierarchy. But that is, in a roundabout way, my point: why is defining and constructing success still so hard, and why do we do such a bad job at it, even when we're at the top of the pyramid and able to focus on self-actualization? The context of this talk for my group is pre-work for a discussion about, in Sinek's construction, the "why?" of our group. Why are we here, what is our purpose, and what do we care about? By the mere fact that we are able to ask questions like that, you can correctly surmise that we're already successful. The question, therefore, is what should we do with that success? I normally hear one or more of the following answers, all of which I find unsatisfying or problematic. So, what should I do with success? Or, put another way, since I have the luxury of figuring out a "why?", what's my "why?" This question comes at a good time. As I've mentioned the last couple of days here, I've just come off of two days of the most fun I've had at work in the last several years. I spent about 25 hours total building a log parsing infrastructure that I'm quite fond of, and which may even be useful to other people. And I did that in response to a rather prosaic request: produce a report of user agents by authenticated unique users, rather than by hits, so that we can get an idea of what percentage of our community uses different devices or browsers. This was a problem that I probably could have solved adequately enough for the original request in four hours, maybe less, and then moved on to something else. I spent six times that long on it. That's something I can do because I'm successful: that's the sort of luxury you get when you can define how you want to do your job. So, apparently I have an answer to my question staring me in my face: what I do with success, when I have it, is use that leeway to produce elegant and comprehensive solutions to problems in a way that fully engages me, makes the problem more interesting, and constructs infrastructure that I can reuse for other problems. Huh. That sounds like a "why?" response that's quite common among hackers and software developers. Nothing earth-shattering there... except why is that so rare in a business context? Why isn't it common to answer questions like "what is our group mission statement" with answers like that? This is what I missed in the TED talk, and what the subsequent discussion with my co-workers brought to light for me. I think Sinek was getting at this, but I think he buried the lede. The "why?" should be something that excites you. Something that you're passionate about. Something that you believe in. He says that's because other people will then believe in it too and will buy it from you. I personally don't care about (or, to be honest, have active antipathy towards) that particular outcome, but that's fine; that's not the point. The point is that a "why?" comes from the heart, from something that actually matters, and it creates a motivating and limiting principle. It defines both what you want to do and what you don't want to do. That gives me a personal answer. My "why?" is that I want to build elegant solutions to problems and do work that I find engaging and can be proud of afterwards. I automate common tasks not because I particularly care about being efficient, but because manually doing common tasks is mind-numbing and boring, and I don't like being bored. I write reliable systems not particularly because that helps clients, but primarily because reliable software is more elegant and beautiful and unreliable software offends me. (Being more usable and frustrating for clients is also good; don't get me wrong. It's just not a motive. It's an outcome.) What does that mean for a group mission statement, a group "why?" Usually these exercises produce some sort of distillation of the collective job responsibilities of the people in the group. Our mission is to maintain core infrastructure to let people do their work and to support authentication and authorization services for the university, yadda yadda yadda... this is all true, in its way, but it's also boring. One can work oneself up to caring about things like that, but it requires a lot of effort. But we all have individual "why?" answers, and I bet they look more like my answer than they do like traditional mission statements. If we're in a place where we have the luxury of worrying about self-actualization questions, what gets us up in the morning, what makes it exciting to go into work, is probably some variation on doing interesting and engaging work. But it's probably a different variation for everyone in the group. For example, as you can see from above, I like building things. My happiest moments are when someone gives me a clearly-defined problem statement that fills a real need and then goes away and leaves me in peace to solve it. One thing I've learned is that I'm not very good at coming up with the problem statements myself; I can do it, but usually I end up solving some problem that isn't very important to other people. I love it when my employer can hand me real problems that will make the world better for people, since often they're a lot more interesting (and meaningful) than the problems I come up with on my own. But that's all highly idiosyncratic and is not going to be shared by everyone in my group. I'm an introvert; the "leave me alone" part of that is important. Other people are extroverts; what gets them up in the morning is, in part, engaging with other people. Some people care passionately about UI design. (I also care passionately about UI design, but the UI designs that I'm passionate about are the ones that are natural for my people, who are apparently aliens from another galaxy, so I'm not the person you want doing UI design for things used by humans.) Others might be particularly interested in researching new technology, or coming up with those problem statements, or in smoothly-running production systems, or in metrics and reporting... I don't really know, but I do know that there's no one answer that fits everyone. Which means that none of our individual "why?" responses should become the group "why?". However, I think that leads to an answer, and it's the answer I'm going to advocate for in the meeting tomorrow. I believe the "why?" of our team should be to use the leeway, trust, and credibility that we have because we're successful to try to create an environment in which every individual member of the team can follow their own "why?" responses. In other words, I think the mission of our group should not be about any specific technology, or about any specific set of services, or outcomes. The way we should use our success is to let every member of our team work in a way that lights their fire. That makes them excited to come into work. That lets each of us have as much fun as I had in the past two days. We should have as our goal to create passionate and empowered employees. Nothing more, but nothing less. This is totally not how group mission statements are done. They're always about blending in to some larger overall technological purpose. But I think that's a mistake, and (despite disliking the presentation), I think that's what this TED talk does actually get at. The purpose is the what, or sometimes the how. It's not the why. And the why isn't static; technology is changing fast, and people are using technology in different ways. Any mission statement around technology today is going to be obsolete in short order, and is going to be too narrow. But I think the flip side is that good technological solutions to the problems of the larger organization are outcomes that fall out of having passionate and inspired employees. If people can work in ways that engage and excite them, they will end up solving problems. We're all adults; we know that we're paid to do a job and that job needs to involve solving real problems for the larger organization. All of that is obvious, and therefore none of that belongs in a mission statement. A mission statement should state the inobvious. And while some visionary people can come up with mission statements around technology or around how people use technology that can be a rallying point for a team or organization, I think that's much rarer than people like to think it is. If you stumble across one like that, great, but I think most teams, and certainly our team, would be better served by having the team mission statement be to enable every individual on the team to be passionate about their work. What should our group work on next? Figure out what the university's problems are, line those needs up with the passions of the members of the team, ask the people most excited about each problem how they want to solve that problem, and write down the answers. There's our roadmap and our strategy, all rolled into one.

24 January 2013

Benjamin Mako Hill: Aaron Swartz

I moved to Boston in 2005 at the same time that Aaron Swartz did and we were introduced by a mutual friend. Aaron was one of my first friends in Boston and we became close. When Aaron moved to San Francisco, I moved into his apartment in Somerville where he kept a room for a year or so. Mika and I still live there. His old posters remain on our walls and his old books remain on our shelves. Aaron s brothers Ben and Noah both lived with us and remain close friends. I have spent hours (days?) reading and thinking about Aaron over the last two weeks. It has been disorienting but beautiful to read the descriptions of, and commentaries on, Aaron s life. Although I suspect I may never feel ready, there are several things I want to say about Aaron s death, about Aaron s work, and about what Aaron means to me. 1. Aaron s Death The reaction to Aaron s death has been overwhelming and inspirational. At some point in the near future I plan to join some of the important campaigns already being waged in his name. There are many attempts to understand why Aaron died and many attempts to prevent it from happening to others in the future. Unfortunately, I am familiar with the process of soul-searching and second-guessing that happens when a friend commits suicide. I m sure that every one of his friends has asked themselves, as I have, What could I have done differently? I don t know the answer, but I do know this: Aaron was facing the real risk of losing half his life to prison. But even if one believed that he was only facing the likely loss of ten percent or even one percent of his life I wish that we all, and I wish that I in particular, had reacted with the passion, time, anger, activity, and volume proportional to how we have reacted in the last two weeks when he lost the whole thing. 2. Aaron s Work Of course, Aaron and I worked on related projects and I followed his work. And despite all the incredible things that have been said about Aaron, I feel that Aaron s work was more focused, more ambitious, more transformative, more innovative, and more reckless (in a positive sense) than the outpour online suggests. Although discussion of Aaron has focused his successes, achievements, and victories, the work that inspired me most was not the projects that were most popular or successful. Much of Aaron s work was deeply, and as it turned out overly, ambitious. His best projects were self-conscious attempts to transform knowledge production, organization, and dissemination. Although he moved from project to project, his work was consistently focused on bringing semantic-web concepts and technologies to peer production, to the movement for free culture, and to progressive political activism and on the meta-politics necessary to remove barriers to this work. For example, Aaron created an online collaborative encyclopedia project called the TheInfoNetwork (TIN) several years before Wikipedia was started. I talked to Aaron at length about that project for a research project I am working on. Aaron s work was years ahead of its time; in 2000, TIN embraced more of the Wikimedia Foundation s current goals and principles than Wikipedia did when it was launched. While Wikipedia sought to create a free reference work online, Aaron s effort sought to find out what a reference work online could look like. It turned out to be too ambitious, perhaps, but it taught many, including myself, an enormous amount in that process. When I met Aaron, he was in the process starting a company, Infogami, that was trying to chase many of TIN s goals. Infogami was conceived of as a wiki aware of the structure of data. The model was both simple and profound. Years later, Wikimedia Deutschland s WikiData project is beginning to bring some of these ideas to the mainstream. Infogami merged with Reddit as equal halves of a company with a shared technological foundation based on some of Aaron s other work. But when Reddit took off, Infogami was rarely mentioned, even by Aaron. I think that is too bad. Reddit got traction because it made the most popular stuff more visible; Reddit is popular, fundamentally, because popular things are popular. But popular is not necessary positive. For that reason, Reddit never struck me as either surprising or transformative. But what started as Aaron s half the company, on the other hand, aimed to create a powerful form of democratized information production and dissemination. And although Infogami didn t take off, the ideas and code behind the project found life at the heart of Open Library and will continue to influence and inspire countless other projects. I believe that Infogami s lessons and legacy will undergird a generation of transformative peer production technologies in a way that the Reddit website important as it is will not. 3. What Aaron Means to Me A lot of what has been written about Aaron speaks to his intelligence, his curiosity, his generosity, his ethics and his drive. Although I recognize all these qualities in the Aaron I knew, I ve felt alienated by how abstract some of the discussion of Aaron has been my memories are of particularities.
I remember the time Aaron was hospitalized and I spent two hours on the phone going through my bookshelves arguing with him about the virtues of the books in my library as we tried to decide which books I would bring him. I remember Aaron confronting Peter Singer intellectual founder of the modern animal rights movement at the Boston Vegetarian Food Festival to ask if humans had a moral obligation to stop animals from killing each other. I lurked behind, embarrassed about the question but curious to hear the answer. (Singer sighed and said yes sort of and complemented Aaron on the enormous Marxist commentary he was carrying.) I remember 1-800-INTERNET.com. I remember talking with Aaron about whether being wealthy could be ethical. I argued it could not but Aaron argued uncharacteristically I thought that it could. Aaron told Mika she should slap him if he ever became wealthy. The very next day, it was announced that his company had been acquired and that Aaron was a millionaire. I remember the standing bets I had with Aaron and how he would email me every time news reports favored his claims (but never when they did not). And I remember that I won t hear from him again.
Aaron was a friend and inspiration. I miss him deeply and I am very sad.

Jan Wagner: vsftpd running on IPv4 and IPv6 simultaneous

Today I planed to move my FTP server to a new system running Debian wheezy. Usually I'm running vsftpd, so this was also the plan for the new host. As this system is dual stacked, I wanted to offer the service on IPv6 too.
On the old system I started vsftpd via xinetd, as far as I remember was vsftpd in squeeze not able to bind on the IPv4 and the IPv6. Anyways ... I didn't wanted to use any inetd system ... So I looked if there is any way to solve that. By a quick search I found vsftpd-2.3.4-listen_ipv6.patch, which indicated that just binding to [::] will also accept IPv4 connections. Setting the following in /etc/vsftpd.conf worked out like a charm:
listen=NO
listen_ipv6=YES
I just updated #574837 so hopefully more people can benefit in the future.

Next.

Previous.