Search Results: "will"

21 February 2013

MJ Ray: In Praise of Consensus

The constitution of the debian operating system project says things like consistent with the consensus of the opinions of the Developers at various points but doesn t say how strong a consensus or how the project will test for consensus. I think those were mistakes, breaking a couple of the conditions for consensus. Wikipedia s understanding of consensus is even worse. Wikipedia seems to treat consensus as a synonym for unanimity. Its testing methods allow an infinite loop to form where the casual observer can t differentiate between a controversial proposal and consensus. I think those were mistakes. These famous-but-imperfect implementations frequently lead to misdirected rants which seem to misunderstand consensus as requiring perpetual bikeshedding. Apache s implementation is rather better and it may surprise you to learn that our co-op is mostly run by consensus. There are two key differences which I feel makes consensus work for us: we ve set limits beforehand on some decisions where we need to act fast where not making a decision would usually be the same as making a bad decision and our methods of testing for consensus are better. We test for consensus with secret-at-vote-time-but-published-after straw polls, or using Crowd Wise by email. I summarise Crowd Wise as follows: gather all ideas plus option 0 (do nothing) if possible, carry out a de Borda (preference) voting round 1, merge/amend/consolidate ideas, voting round 2 if needed. It does still work better if participants put their ego aside a little and co-operate, but it does put limits on non-co-operators. Anyway, as described in Xana/ xana2/ bamamba/ Why Russ is wrong, debian isn t exactly using consensus much at the moment, anyway. Should we try to fix its bugs? Do you know other projects where consensus is working?

Joey Hess: Kickstarter rewards wrap-up

I finished delivering all my Kickstarter rewards at the end of the year. This is an overview of how that went, both financially and in general.
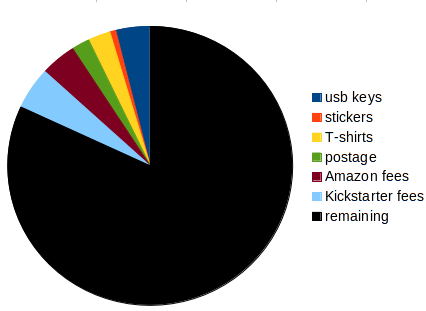
my Kickstarter pie (not including taxes)
While the Kickstarter was under way, several friends warned me that I might end up spending a lot of the money for rewards, or even shipping, and come out a loser. It's happened to some people, but I avoided it. Most of the pie went to its intended purpose.
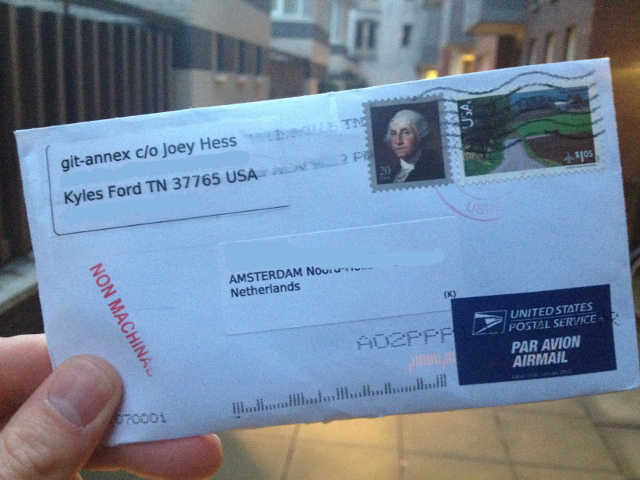
USB key arrives in Amsterdam
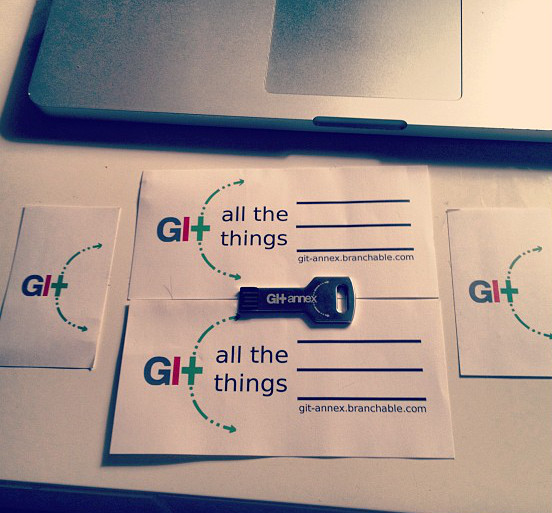
I kept shipping cost low by shipping everything by US postal service, including Air Mail for international shipping. This was particularly important for the stickers (which cost $1.05 to ship internationally). But I also shipped USB keys in regular mail envelopes, protected by bubble wrap, which worked very well and avoided the bother of shipping packages. The USPS will be annoyed at you for a rigid letter and add a non-machinable surcharge, but it's still a nice savings.
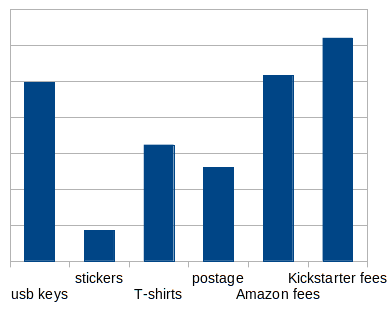
expenses
I spent more on rewards than on transaction fees, but the fees are still pretty large. Being dinged a second time by Amazon is the worst part. I have not been able to work out exactly what formula Kickstarter uses to determine its fee per pledge. It does not seem to be a simple percentage of the pledge. For example, they seem to have charged $0.25 per $10 pledge, but $25 for a $500 pledge. I wanted to solve this, but I'd have to match up all the pledges and fees manually to do it.
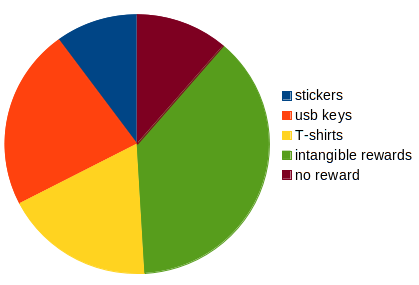
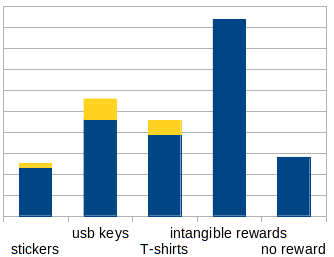
gross income by reward type
This chart is slightly innacurrate, because it puts any money pledged, beyond the amount needed to get a reward, into the "intangibles" category, despite the reward being probably responsible for that money being pledged. (The intangibles also includes people who did not ask for a reward, and several categories of rewards not involving shipping matter around.) But, the surprise for me is how large a peice the T-shirts are responsible for. It was my least favorite reward, and a low volume one, but I made out pretty well on it. However, I'd still try to avoid putting T-shirts on Kickstarter again. It's hard to do a good design (I didn't, really); they're expensive, and were by far the most annoying thing to ship. Also, I was not happy with the countries Cafe Press sourced their shirts from; I've been to Honduras and talked with people who have relatives in las machinas.
gross and net income by reward type (excluding shipping)
In contrast, the stickers had an amazing margin; they're so inexpensive to print that I printed up two kinds and included multiple with every other reward I mailed. I still have hundreds left over, too.. All the online print shops I tried have very annoying interfaces to upload artwork though. I had to do quite a bit of math to render TIFF files with appropriate DPI and margins. The USB keys were my favorite reward. I got them from USB Memory Direct, who gave me quite a nice deal. I was very happy that I was able to send them a SVG file of my artwork, so I didn't need to worry about lacking resolution for the laser engraving. And it came out looking great. The best part was when their sales guy Mike actually did a minor alteration of the artwork, to better fit on the key, when I, being overloaded with Kickstarter stuff asked him too. A bit above and beyond. There was an issue with their Chinese manufacturer's quality control of the 16 gb drives, but they were willing to send me replacement for all the ones I found problems with.
All told I spent probably 3 full days stuffing and shipping envelopes, and probably spent a week working on Kickstarter reward fullfillment. As work-related overhead goes, that's not bad. Maybe someone considering a Kickstarter will find this information useful somehow. Oh well, back to work. :)

20 February 2013

Daniel Pocock: Automatically mirroring SVN repositories to git and github

Updated 21 February 2013: the scripts below have now been adapted to run conveniently from cron and mirror multiple repositories. You can find full scripts and documentation on github There are a number of scripts around, including an earlier blog post of my own, for making a once-off conversion of an SVN repository to a Git repository. However, what if the project team is not yet ready for a full move to git? You may want to start benefiting from git (e.g. using the project as a submodule of another git project, or using Travis-CI.org for automated builds) while development officially continues to take place in SVN. If you don't need to make commits into git just now, you can set up a mirror and refresh it periodically from SVN. This process can be used with various SVN repositories, including Sourceforge and Google Code SVN repositories. Process overview
  • An authors.txt file is created manually before the first run.
  • A git-svn clone of the SVN repository is created. This clone needs to be retained between replication runs.
  • On each run, a temporary git repository is created. The svn-clone is rebased and pushed to the fresh git repository.
  • Fixes (e.g. branch renames and tagging) are made in the temporary git repository.
  • The final results are then pushed from the temporary repository to the real git mirror that is being maintained.
  • Finally, the temporary git repository is deleted, but the svn-clone is kept.
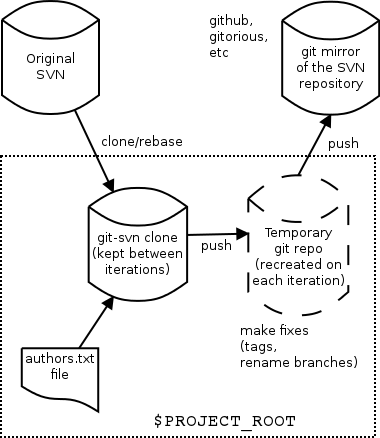
Here is a diagram of the workflow: Config file Here is a sample config file for the script, it mirrors the rather complicated reSIProcate repository with 10,000 commits:
PROJECT_ROOT=/home/daniel/svn-mirror/resiprocate
AUTHORS_FILE=$ PROJECT_ROOT /authors.txt
SVN_REPO=https://svn.resiprocate.org/rep/resiprocate
SVN_LAYOUT="--trunk=main --branches=branches --tags=tags"
GIT_REPO=git@github.com:resiprocate/resiprocate.git
Of particular note here:
  • The $PROJECT_ROOT is where the svn-clone and the temporary repositories will be created
  • $GIT_REPO is the final destination repository. For testing, it could just be a local directory initialised with git init --bare .
  • In this repository, our trunk is actually called main, hence we have the layout argument --trunk=main. Many projects would just use --trunk=trunk
The script The script itself is below. I'd suggest running it manually a few times first and observing how it behaves, disk space requirements, etc.
#!/bin/bash
set -e
if [ ! $# -eq 1 ];
then
  echo "Usage:"
  echo "$0 <config-file>"
  exit 1
fi
CONFIG_FILE="$1"
. "$ CONFIG_FILE "   exit 1
SVN_CLONE="$ PROJECT_ROOT /svn-clone"
GIT_BARE="$ PROJECT_ROOT /git-bare-tmp"
if [ ! -d "$ PROJECT_ROOT " ];
then
  mkdir -p "$ PROJECT_ROOT "
fi
cd "$ PROJECT_ROOT "
if [ ! -d "$ SVN_CLONE " ];
then
  git svn clone \
    "$ SVN_REPO " \
    -A "$ AUTHORS_FILE " \
    $ SVN_LAYOUT  \
    "$ SVN_CLONE "
  cd "$ SVN_CLONE "
else
  cd "$ SVN_CLONE "
  git remote rm bare   echo "failed to delete remote:bare, proceeding anyway"
  git svn rebase \
    --fetch-all \
    -A "$ AUTHORS_FILE "
fi
git remote add bare "$ GIT_BARE "
git config remote.bare.push 'refs/remotes/*:refs/heads/*'
if [ -d "$ GIT_BARE " ];
then
  rm -rf "$ GIT_BARE "
fi
mkdir -p "$ GIT_BARE "
cd "$ GIT_BARE "
git init --bare .
git symbolic-ref HEAD refs/heads/trunk
cd "$ SVN_CLONE "
git push bare
cd "$ GIT_BARE "
git branch -m trunk master
git for-each-ref --format='%(refname)' refs/heads/tags   \
   cut -d / -f 4   \
   while read ref;
   do
      git tag "$ref" "refs/heads/tags/$ref"
      git branch -D "tags/$ref"
   done
git remote add origin "$ GIT_REPO "
git config branch.master.remote origin
git config branch.master.merge refs/heads/master
git push --tags origin master
git push --all
rm -rf "$ GIT_BARE "
</config-file>
AttachmentSize
svn-mirror.png32.65 KB

Daniel Pocock: Automatically mirroring SVN repositories to git and github

Updated 21 February 2013: the scripts below have now been adapted to run conveniently from cron and mirror multiple repositories. You can find full scripts and documentation on github There are a number of scripts around, including an earlier blog post of my own, for making a once-off conversion of an SVN repository to a Git repository. However, what if the project team is not yet ready for a full move to git? You may want to start benefiting from git (e.g. using the project as a submodule of another git project, or using Travis-CI.org for automated builds) while development officially continues to take place in SVN. If you don't need to make commits into git just now, you can set up a mirror and refresh it periodically from SVN. This process can be used with various SVN repositories, including Sourceforge and Google Code SVN repositories. Process overview
  • An authors.txt file is created manually before the first run - see my other blog entry for convenient scripts to help generate authors.txt
  • A git-svn clone of the SVN repository is created. This clone needs to be retained between replication runs.
  • On each run, a temporary git repository is created. The svn-clone is rebased and pushed to the fresh git repository.
  • Fixes (e.g. branch renames and tagging) are made in the temporary git repository.
  • The final results are then pushed from the temporary repository to the real git mirror that is being maintained.
  • Finally, the temporary git repository is deleted, but the svn-clone is kept.
Here is a diagram of the workflow: Config file Here is a sample config file for the script, it mirrors the rather complicated reSIProcate repository with 10,000 commits:
PROJECT_ROOT=/home/daniel/svn-mirror/resiprocate
AUTHORS_FILE=$ PROJECT_ROOT /authors.txt
SVN_REPO=https://svn.resiprocate.org/rep/resiprocate
SVN_LAYOUT="--trunk=main --branches=branches --tags=tags"
GIT_REPO=git@github.com:resiprocate/resiprocate.git
Of particular note here:
  • The $PROJECT_ROOT is where the svn-clone and the temporary repositories will be created
  • $GIT_REPO is the final destination repository. For testing, it could just be a local directory initialised with git init --bare .
  • In this repository, our trunk is actually called main, hence we have the layout argument --trunk=main. Many projects would just use --trunk=trunk
The script The script itself is below. I'd suggest running it manually a few times first and observing how it behaves, disk space requirements, etc.
#!/bin/bash
set -e
if [ ! $# -eq 1 ];
then
  echo "Usage:"
  echo "$0 <config-file>"
  exit 1
fi
CONFIG_FILE="$1"
. "$ CONFIG_FILE "   exit 1
SVN_CLONE="$ PROJECT_ROOT /svn-clone"
GIT_BARE="$ PROJECT_ROOT /git-bare-tmp"
if [ ! -d "$ PROJECT_ROOT " ];
then
  mkdir -p "$ PROJECT_ROOT "
fi
cd "$ PROJECT_ROOT "
if [ ! -d "$ SVN_CLONE " ];
then
  git svn clone \
    "$ SVN_REPO " \
    -A "$ AUTHORS_FILE " \
    $ SVN_LAYOUT  \
    "$ SVN_CLONE "
  cd "$ SVN_CLONE "
else
  cd "$ SVN_CLONE "
  git remote rm bare   echo "failed to delete remote:bare, proceeding anyway"
  git svn rebase \
    --fetch-all \
    -A "$ AUTHORS_FILE "
fi
git remote add bare "$ GIT_BARE "
git config remote.bare.push 'refs/remotes/*:refs/heads/*'
if [ -d "$ GIT_BARE " ];
then
  rm -rf "$ GIT_BARE "
fi
mkdir -p "$ GIT_BARE "
cd "$ GIT_BARE "
git init --bare .
git symbolic-ref HEAD refs/heads/trunk
cd "$ SVN_CLONE "
git push bare
cd "$ GIT_BARE "
git branch -m trunk master
git for-each-ref --format='%(refname)' refs/heads/tags   \
   cut -d / -f 4   \
   while read ref;
   do
      git tag "$ref" "refs/heads/tags/$ref"
      git branch -D "tags/$ref"
   done
git remote add origin "$ GIT_REPO "
git config branch.master.remote origin
git config branch.master.merge refs/heads/master
git push --tags origin master
git push --all
rm -rf "$ GIT_BARE "
</config-file>
AttachmentSize
svn-mirror.png32.65 KB

Martin Pitt: umockdev 0.2: record/replay input devices

I just released umockdev 0.2. The big new feature of this release is support for evdev ioctls. I. e. you can now record what e. g. X.org is doing to touchpads, touch screens, etc.:
  $ umockdev-record /dev/input/event15 > /tmp/touchpad.umockdev
  # umockdev-record -i /tmp/touchpad.ioctl /dev/input/event15 -- Xorg -logfile /dev/null
and load that back into a testbed with X.org using the dummy driver:
  cat <<EOF > xorg-dummy.conf
  Section "Device"
        Identifier "test"
        Driver "dummy"
  EndSection
  EOF
  $ umockdev-run -l /tmp/touchpad.umockdev -i /dev/input/event15=/tmp/touchpad.ioctl -- \
       Xorg -config xorg-dummy.conf -logfile /tmp/X.log :5
Then e. g. DISPLAY=:5 xinput will recognize the simulated device. Note that Xvfb won t work as that does not use udev for device discovery, but only adds the XTest virtual devices and nothing else, so you need to use the real X.org with the dummy driver to run this as a normal user. This enables easier debugging of new kinds of input devices, as well as writing tests for handling multiple touchscreens/monitors, integration tests of Wacom devices, and so on. This release now also works with older automakes and Vala 0.16, so that you can use this from Ubuntu 12.04 LTS. The daily PPA now also has packages for that. Attention: This version does not work any more with recorded ioctl files from version 0.1. More detailled list of changes:

Thorsten Glaser: GNU autotools generated files

On Planet Debian, Vincent Bernat wrote:

The drawback of this approach is that if you rebuild configure from the released tarball, you don t have the git tree and the version will be a date. Just don t do that.

Excuse me This is totally inacceptable. Regenerating files like aclocal.m4 and Makefile.in (for automake), configure (for autoconf), and the likes is one of the absolute duties of a software package. Things will break sooner or later if people do not do that. Additionally, generated files must be remakable from the distfile, so do not break this! May I suggest, constructively, an alternative? (People rightfully, I must admit complain I m just ranting too much.)
When making a release from git, write the git describe output into a file. Then, use that file instead of trying to run the git executable if .git/. is not a directory ( test -d .git/. ). Do not call git, because, in packages, it s either not installed or/and also undesired. Couldn t comment on your blog, but felt strongly enough about this I took the effort of writing a full post of my own. (But thanks for the book recommendation.)

Vincent Bernat: lldpd 0.7.1

A few weeks ago, a new version of lldpd, a 802.1AB (aka LLDP) implementation for various Unices, has been released. LLDP is an industry standard protocol designed to supplant proprietary Link-Layer protocols such as EDP or CDP. The goal of LLDP is to provide an inter-vendor compatible mechanism to deliver Link-Layer notifications to adjacent network devices. In short, LLDP allows you to know exactly on which port is a server (and reciprocally). To illustrate its use, I have made a xkcd-like strip: xkcd-like strip for the use of LLDP If you would like more information about lldpd, please have a look at its new dedicated website. This blog post is an insight of various technical changes that have affected lldpd since its latest major release one year ago. Lots of C stuff ahead!

Version & changelog UPDATED: Guillem Jover told me how he met the same goals for libbsd :
  1. Save the version from git into .dist-version and use this file if it exists. This allows one to rebuild ./configure from the published tarball without losing the version. This also handles Thorsten Glaser s critic.
  2. Include CHANGELOG in DISTCLEANFILES variable.
Since this is a better solution, I have adopted the appropriate line of codes from libbsd. The two following sections are partly technically outdated.

Automated version In configure.ac, I was previously using a static version number that I had to increase when releasing:
AC_INIT([lldpd], [0.5.7], [bernat@luffy.cx])
Since the information is present in the git tree, this seems a bit redundant (and easy to forget). Taking the version from the git tree is easy:
AC_INIT([lldpd],
        [m4_esyscmd_s([git describe --tags --always --match [0-9]* 2> /dev/null   date +%F])],
        [bernat@luffy.cx])
If the head of the git tree is tagged, you get the exact tag (0.7.1 for example). If it is not, you get the nearest one, the number of commits since it and part of the current hash (0.7.1-29-g2909519 for example). The drawback of this approach is that if you rebuild configure from the released tarball, you don t have the git tree and the version will be a date. Just don t do that.

Automated changelog Generating the changelog from git is a common practice. I had some difficulties to make it right. Here is my attempt (I am using automake):
dist_doc_DATA = README.md NEWS ChangeLog
.PHONY: $(distdir)/ChangeLog
dist-hook: $(distdir)/ChangeLog
$(distdir)/ChangeLog:
        $(AM_V_GEN)if test -d $(top_srcdir)/.git; then \
          prev=$$(git describe --tags --always --match [0-9]* 2> /dev/null) ; \
          for tag in $$(git tag   grep -E '^[0-9]+(\.[0-9]+) 1, $$'   sort -rn); do \
            if [ x"$$prev" = x ]; then prev=$$tag ; fi ; \
            if [ x"$$prev" = x"$$tag" ]; then continue; fi ; \
            echo "$$prev [$$(git log $$prev -1 --pretty=format:'%ai')]:" ; \
            echo "" ; \
            git log --pretty=' - [%h] %s (%an)' $$tag..$$prev ; \
            echo "" ; \
            prev=$$tag ; \
          done > $@ ; \
        else \
          touch $@ ; \
        fi
ChangeLog:
        touch $@
Changelog entries are grouped by version. Since it is a bit verbose, I still maintain a NEWS file with important changes.

Core

C99 I have recently read 21st Century C which has some good bits and also handles the ecosystem around C. I have definitively adopted designated initializers in my coding style. Being a GCC extension since a long time, this is not a major compatibility problem. Without designated initializers:
struct netlink_req req;
struct iovec iov;
struct sockaddr_nl peer;
struct msghdr rtnl_msg;
memset(&req, 0, sizeof(req));
memset(&iov, 0, sizeof(iov));
memset(&peer, 0, sizeof(peer));
memset(&rtnl_msg, 0, sizeof(rtnl_msg));
req.hdr.nlmsg_len = NLMSG_LENGTH(sizeof(struct rtgenmsg));
req.hdr.nlmsg_type = RTM_GETLINK;
req.hdr.nlmsg_flags = NLM_F_REQUEST   NLM_F_DUMP;
req.hdr.nlmsg_seq = 1;
req.hdr.nlmsg_pid = getpid();
req.gen.rtgen_family = AF_PACKET;
iov.iov_base = &req;
iov.iov_len = req.hdr.nlmsg_len;
peer.nl_family = AF_NETLINK;
rtnl_msg.msg_iov = &iov;
rtnl_msg.msg_iovlen = 1;
rtnl_msg.msg_name = &peer;
rtnl_msg.msg_namelen = sizeof(struct sockaddr_nl);
With designated initializers:
struct netlink_req req =  
    .hdr =  
        .nlmsg_len = NLMSG_LENGTH(sizeof(struct rtgenmsg)),
        .nlmsg_type = RTM_GETLINK,
        .nlmsg_flags = NLM_F_REQUEST   NLM_F_DUMP,
        .nlmsg_seq = 1,
        .nlmsg_pid = getpid()  ,
    .gen =   .rtgen_family = AF_PACKET  
 ;
struct iovec iov =  
    .iov_base = &req,
    .iov_len = req.hdr.nlmsg_len
 ;
struct sockaddr_nl peer =   .nl_family = AF_NETLINK  ;
struct msghdr rtnl_msg =  
    .msg_iov = &iov,
    .msg_iovlen = 1,
    .msg_name = &peer,
    .msg_namelen = sizeof(struct sockaddr_nl)
 ;

Logging Logging in lldpd was not extensive. Usually, when receiving a bug report, I asked the reporter to add some additional printf() calls to determine where the problem was. This was clearly suboptimal. Therefore, I have added many log_debug() calls with the ability to filter out some of them. For example, to debug interface discovery, one can run lldpd with lldpd -ddd -D interface. Moreover, I have added colors when logging to a terminal. This may seem pointless but it is now far easier to spot warning messages from debug ones. logging output of lldpd

libevent In lldpd 0.5.7, I was using my own select()-based event loop. It worked but I didn t want to grow a full-featured event loop inside lldpd. Therefore, I switched to libevent. The minimal required version of libevent is 2.0.5. A convenient way to check the changes in API is to use Upstream Tracker, a website tracking API and ABI changes for various libraries. This version of libevent is not available in many stable distributions. For example, Debian Squeeze or Ubuntu Lucid only have 1.4.13. I am also trying to keep compatibility with very old distributions, like RHEL 2, which does not have a packaged libevent at all. For some users, it may be a burden to compile additional libraries. Therefore, I have included libevent source code in lldpd source tree (as a git submodule) and I am only using it if no suitable system libevent is available. Have a look at m4/libevent.m4 and src/daemon/Makefile.am to see how this is done.

Client

Serialization lldpctl is a client querying lldpd to display discovered neighbors. The communication is done through an Unix socket. Each structure to be serialized over this socket should be described with a string. For example:
#define STRUCT_LLDPD_DOT3_MACPHY "(bbww)"
struct lldpd_dot3_macphy  
        u_int8_t                 autoneg_support;
        u_int8_t                 autoneg_enabled;
        u_int16_t                autoneg_advertised;
        u_int16_t                mau_type;
 ;
I did not want to use stuff like Protocol Buffers because I didn t want to copy the existing structures to other structures before serialization (and the other way after deserialization). However, the serializer in lldpd did not allow to handle reference to other structures, lists or circular references. I have written another one which works by annotating a structure with some macros:
struct lldpd_chassis  
    TAILQ_ENTRY(lldpd_chassis) c_entries;
    u_int16_t        c_index;
    u_int8_t         c_protocol;
    u_int8_t         c_id_subtype;
    char            *c_id;
    int              c_id_len;
    char            *c_name;
    char            *c_descr;
    u_int16_t        c_cap_available;
    u_int16_t        c_cap_enabled;
    u_int16_t        c_ttl;
    TAILQ_HEAD(, lldpd_mgmt) c_mgmt;
 ;
MARSHAL_BEGIN(lldpd_chassis)
MARSHAL_TQE  (lldpd_chassis, c_entries)
MARSHAL_FSTR (lldpd_chassis, c_id, c_id_len)
MARSHAL_STR  (lldpd_chassis, c_name)
MARSHAL_STR  (lldpd_chassis, c_descr)
MARSHAL_SUBTQ(lldpd_chassis, lldpd_mgmt, c_mgmt)
MARSHAL_END;
Only pointers need to be annotated. The remaining of the structure can be serialized with just memcpy()1. I think there is still room for improvement. It should be possible to add annotations inside the structure and avoid some duplication. Or maybe, using a C parser? Or using the AST output from LLVM?

Library In lldpd 0.5.7, there are two possible entry points to interact with the daemon:
  1. Through SNMP support. Only information available in LLDP-MIB are exported. Therefore, implementation-specific values are not available. Moreover, SNMP support is currently read-only.
  2. Through lldpctl. Thanks to a contribution from Andreas Hofmeister, the output can be requested to be formatted as an XML document.
Integration of lldpd into a network stack was therefore limited to one of those two channels. As an exemple, you can have a look at how Vyatta made the integration using the second solution. To provide a more robust solution, I have added a shared library, liblldpctl, with a stable and well-defined API. lldpctl is now using it. I have followed those directions2:
  • Consistent naming (all exported symbols are prefixed by lldpctl_). No pollution of the global namespace.
  • Consistent return codes (on errors, all functions returning pointers are returning NULL, all functions returning integers are returning -1).
  • Reentrant and thread-safe. No global variables.
  • One well-documented include file.
  • Reduce the use of boilerplate code. Don t segfault on NULL, accept integer input as string, provide easy iterators,
  • Asynchronous API for input/output. The library delegates reading and writing by calling user-provided functions. Those functions can yield their effects. In this case, the user has to callback the library when data is available for reading or writing. It is therefore possible to integrate the library with any existing event-loop. A thin synchronous layer is provided on top of this API.
  • Opaque types with accessor functions.
Accessing bits of information is done through atoms which are opaque containers of type lldpctl_atom_t. From an atom, you can extract some properties as integers, strings, buffers or other atoms. The list of ports is an atom. A port in this list is also an atom. The list of VLAN present on this port is an atom, as well as each VLAN in this list. The VLAN name is a NULL-terminated string living in the scope of an atom. Accessing a property is done by a handful of functions, like lldpctl_atom_get_str(), using a specific key. For example, here is how to display the list of VLAN assuming you have one port as an atom:
vlans = lldpctl_atom_get(port, lldpctl_k_port_vlans);
lldpctl_atom_foreach(vlans, vlan)  
    vid = lldpctl_atom_get_int(vlan,
                               lldpctl_k_vlan_id));
    name = lldpctl_atom_get_str(vlan,
                                lldpctl_k_vlan_name));
    if (vid && name)
        printf("VLAN %d: %s\n", vid, name);
 
lldpctl_atom_dec_ref(vlans);
Internally, an atom is typed and reference counted. The size of the API is greatly limited thanks to this concept. There are currently more than one hundred pieces of information that can be retrieved from lldpd. Ultimately, the library will also enable the full configuration of lldpd. Currently, many aspects can only be configured through command-line flags. The use of the library does not replace lldpctl which will still be available and be the primary client of the library.

CLI Having a configuration file was requested since a long time. I didn t want to include a parser in lldpd: I am trying to keep it small. It was already possible to configure lldpd through lldpctl. Locations, network policies and power policies were the three items that could be configured this way. So, the next step was to enable lldpctl to read a configuration file, parse it and send the result to lldpd. As a bonus, why not provide a full CLI accepting the same statements with inline help and completion?

Parsing & completion Because of completion, it is difficult to use a YACC generated parser. Instead, I define a tree where each node accepts a word. A node is defined with this function:
struct cmd_node *commands_new(
    struct cmd_node *,
    const char *,
    const char *,
    int(*validate)(struct cmd_env*, void *),
    int(*execute)(struct lldpctl_conn_t*, struct writer*,
        struct cmd_env*, void *),
    void *);
A node is defined by:
  • its parent,
  • an optional accepted static token,
  • an help string,
  • an optional validation function and
  • an optional function to execute if the current token is accepted.
When walking the tree, we maintain an environment which is both a key-value store and a stack of positions in the tree. The validation function can check the environment to see if we are in the right context (we want to accept the keyword foo only once, for example). The execution function can add the current token as a value in the environment but it can also pop the current position in the tree to resume walk from a previous node. As an example, see how nodes for configuration of a coordinate-based location are registered:
/* Our root node */
struct cmd_node *configure_medloc_coord = commands_new(
    configure_medlocation,
    "coordinate", "MED location coordinate configuration",
    NULL, NULL, NULL);
/* The exit node.
   The validate function will check if we have both
   latitude and longitude. */
commands_new(configure_medloc_coord,
    NEWLINE, "Configure MED location coordinates",
    cmd_check_env, cmd_medlocation_coordinate,
    "latitude,longitude");
/* Store latitude. Once stored, we pop two positions
   to go back to the "root" node. The user can only
   enter latitude once. */
commands_new(
    commands_new(
        configure_medloc_coord,
        "latitude", "Specify latitude",
        cmd_check_no_env, NULL, "latitude"),
    NULL, "Latitude as xx.yyyyN or xx.yyyyS",
    NULL, cmd_store_env_value_and_pop2, "latitude");
/* Same thing for longitude */
commands_new(
    commands_new(
        configure_medloc_coord,
        "longitude", "Specify longitude",
        cmd_check_no_env, NULL, "longitude"),
    NULL, "Longitude as xx.yyyyE or xx.yyyyW",
    NULL, cmd_store_env_value_and_pop2, "longitude");
The definition of all commands is still a bit verbose but the system is simple enough yet powerful enough to cover all needed cases.

Readline When faced with a CLI, we usually expect some perks like completion, history handling and help. The most used library to provide such features is the GNU Readline Library. Because this is a GPL library, I have first searched an alternative. There are several of them: From an API point of view, the first three libraries support the GNU Readline API. They also have a common native API. Moreover, this native API also handles tokenization. Therefore, I have developed the first version of the CLI with this API3. Unfortunately, I noticed later this library is not very common in the Linux world and is not available in RHEL. Since I have used the native API, it was not possible to fallback to the GNU Readline library. So, let s switch! Thanks to the appropriate macro from the Autoconf Archive (with small modifications), the compilation and linking differences between the libraries are taken care of. Because GNU Readline library does not come with a tokenizer, I had to write one myself. The API is also badly documented and it is difficult to know which symbol is available in which version. I have limited myself to:
  • readline(), addhistory(),
  • rl_insert_text(),
  • rl_forced_update_display(),
  • rl_bind_key()
  • rl_line_buffer and rl_point.
Unfortunately, the various libedit libraries have a noop for rl_bind_key(). Therefore, completion and online help is not available with them. I have noticed that most BSD come with GNU Readline library preinstalled, so it could be considered as a system library. Nonetheless, linking with libedit to avoid licensing issues is possible and help can be obtained by prefixing the command with help.

OS specific support

BSD support Until version 0.7, lldpd was Linux-only. The rewrite to use Netlink was the occasion to abstract interfaces and to port to other OS. The first port was for Debian GNU/kFreeBSD, then for FreeBSD, OpenBSD and NetBSD. They all share the same source code:
  • getifaddrs() to get the list of interfaces,
  • bpf(4) to attach to an interface to receive and send packets,
  • PF_ROUTE socket to be notified when a change happens.
Each BSD has its own ioctl() to retrieve VLAN, bridging and bonding bits but they are quite similar. The code was usually adapted from ifconfig.c. The BSD ports have the same functionalities than the Linux port, except for NetBSD which lacks support for LLDP-MED inventory since I didn t find a simple way to retrieve DMI related information. They also offer greater security by filtering packets sent. Moreover, OpenBSD allows to lock the filters set on the socket:
/* Install write filter (optional) */
if (ioctl(fd, BIOCSETWF, (caddr_t)&fprog) < 0)  
    rc = errno;
    log_info("privsep", "unable to setup write BPF filter for %s",
        name);
    goto end;
 
/* Lock interface */
if (ioctl(fd, BIOCLOCK, (caddr_t)&enable) < 0)  
    rc = errno;
    log_info("privsep", "unable to lock BPF interface %s",
        name);
    goto end;
 
This is a very nice feature. lldpd is using a privileged process to open the raw socket. The socket is then transmitted to an unprivileged process. Without this feature, the unprivileged process can remove the BPF filters. I have ported the ability to lock a socket filter program to Linux. However, I still have to add a write filter.

OS X support Once FreeBSD was supported, supporting OS X seemed easy. I got sponsored by xcloud.me which provided a virtual Mac server. Making lldpd work with OS X took only two days, including a full hour to guess how to get Apple Xcode without providing a credit card. To help people installing lldpd on OS X, I have also written a lldpd formula for Homebrew which seems to be the most popular package manager for OS X.

Upstart and systemd support Many distributions propose upstart and systemd as a replacement or an alternative for the classic SysV init. Like most daemons, lldpd detaches itself from the terminal and run in the background, by forking twice, once it is ready (for lldpd, this just means we have setup the control socket). While both upstart and systemd can accommodate daemons that behave like this, it is recommended to not fork. How to advertise readiness in this case? With upstart, lldpd will send itself the SIGSTOP signal. upstart will detect this, resume lldpd with SIGCONT and assume it is ready. The code to support upstart is therefore quite simple. Instead of calling daemon(), do this:
const char *upstartjob = getenv("UPSTART_JOB");
if (!(upstartjob && !strcmp(upstartjob, "lldpd")))
    return 0;
log_debug("main", "running with upstart, don't fork but stop");
raise(SIGSTOP);
The job configuration file looks like this:
# lldpd - LLDP daemon
description "LLDP daemon"
start on net-device-up IFACE=lo
stop on runlevel [06]
expect stop
respawn
script
  . /etc/default/lldpd
  exec lldpd $DAEMON_ARGS
end script
systemd provides a socket to achieve the same goal. An application is expected to write READY=1 to the socket when it is ready. With the provided library, this is just a matter of calling sd_notify("READY=1\n"). Since sd_notify() has less than 30 lines of code, I have rewritten it to avoid an external dependency. The appropriate unit file is:
[Unit]
Description=LLDP daemon
Documentation=man:lldpd(8)
[Service]
Type=notify
NotifyAccess=main
EnvironmentFile=-/etc/default/lldpd
ExecStart=/usr/sbin/lldpd $DAEMON_ARGS
Restart=on-failure
[Install]
WantedBy=multi-user.target

OS include files Linux-specific include files were a major pain in previous versions of lldpd. The problems range from missing header files (like linux/if_bonding.h) to the use of kernel-only types. Those headers have a difficult history. They were first shipped with the C library but were rarely synced and almost always outdated. They were then extracted from kernel version with almost no change and lagged behind the kernel version used by the released distribution4. Today, the problem is acknowledged and is being solved by both the distributions which extract the headers from the packaged kernel and by kernel developers with a separation of kernel-only headers from user-space API headers. However, we still need to handle legacy. A good case is linux/ethtool.h:
  • It can just be absent.
  • It can use u8, u16 types which are kernel-only types. To work around this issue, type munging can be setup.
  • It can miss some definition, like SPEED_10000. In this case, you either define the missing bits and find yourself with a long copy of the original header interleaved with #ifdef or conditionally use each symbol. The latest solution is a burden by itself but it also hinders some functionalities that can be available in the running kernel.
The easy solution to all this mess is to just include the appropriate kernel headers into the source tree of the project. Thanks to Google ripping them for its Bionic C library, we know that copying kernel headers into a program does not create a derivative work.

  1. Therefore, the use of u_int16_t and u_int8_t types is a left-over of the previous serializer where the size of all members was important.
  2. For more comprehensive guidelines, be sure to check Writing a C library.
  3. Tokenization is not the only advantage of libedit native API. The API is also cleaner, does not have a global state and has a better documentation. All the implementations are also BSD licensed.
  4. For example, in Debian Sarge, the Linux kernel was a 2.6.8 (2004) while the kernel headers were extracted from some pre-2.6 kernel.

Keith Packard: DRI3000

DRI3000 Even Better Direct Rendering This all started with the presentation that Eric Anholt and I did at the 2012 X developers conference, and subsequently wrote about in my DRI-Next posting. That discussion sketched out the goals of changing the existing DRI2-based direct rendering infrastructure. Last month, I gave a more detailed presentation at Linux.conf.au 2013 (the best free software conference in the world). That presentation was recorded, so you can watch it online. Or, you can read Nathan Willis summary at lwn.net. That presentation contained a lot more details about the specific techniques that will be used to implement the new system, in particular it included some initial indications of what kind of performance benefits the overall system might be able to produce. I sat down today and wrote down an initial protocol definition for two new extensions (because two extensions are always better than one). Together, these are designed to provide complete support for direct rendering APIs like OpenGL and offer a better alternative to DRI2. The DRI3 extension Dave Airlie and Eric Anholt refused to let me call either actual extension DRI3000, so the new direct rendering extension is called DRI3. It uses POSIX file descriptor passing to share kernel objects between the X server and the application. DRI3 is a very small extension in three requests:
  1. Open. Returns a file descriptor for a direct rendering device along with the name of the driver for a particular API (OpenGL, Video, etc).
  2. PixmapFromBuffer. Takes a kernel buffer object (Linux uses DMA-BUF) and creates a pixmap that references it. Any place a Pixmap can be used in the X protocol, you can now talk about a DMA-BUF object. This allows an application to do direct rendering, and then pass a reference to those results directly to the X server.
  3. BufferFromPixmap. This takes an existing pixmap and returns a file descriptor for the underlying kernel buffer object. This is needed for the GL Texture from Pixmap extension.
For OpenGL, the plan is to create all of the buffer objects on the client side, then pass the back buffer to the X server for display on the screen. By creating pixmaps, we avoid needing new object types in the X server and can use existing X apis that take pixmaps for these objects. The Swap extension Once you ve got direct rendered content in a Pixmap, you ll want to display it on the screen. You could simply use CopyArea from the pixmap to a window, but that isn t synchronzied to the vertical retrace signal. And, the semantics of the CopyArea operation precludes us from swapping the underlying buffers around, making it more expensive than strictly necessary. The Swap extension fills those needs. Because the DRI3 extension provides an X pixmap reference to the direct rendered content, the Swap extension doesn t need any new object types for its operation. Instead, it talks strictly about core X objects, using X pixmaps as the source of the new data and X drawables as the destination. The core of the Swap extension is one request SwapRegion. This request moves pixels from a pixmap to a drawable. It uses an X fixes Region object to specify the area of the destination being painted, and an offset within the source pixmap to align the two areas. A bunch of data are included in the reply from the SwapRegion request. First, you get a 64-bit sequence number identifying the swap itself. Then, you get a suggested geometry for the next source pixmap. Using the suggested geometry may result in performance improvements from the techniques described in the LCA talk above. The last bit of data included in the SwapRegion reply is a list of pixmaps which were used as source operands to earlier SwapRegion requests to the same drawable. Each pixmap is listed along with the 64-bit sequence number associated with an earlier SwapRegion operation which resulted in the contents which the pixmap now contains. Ok, so that sounds really confusing. Some examples are probably necessary. I m hoping you ll be able to tell that in both cases, the idle swap count tries to name the swap sequence at which time the destination drawable contained the contents currently in the pixmap. Note that even if the SwapRegion is implemented as a Copy operation, the provided source pixmap may not be included in the idle list as the copy may be delayed to meet the synchronization requirements specfied by the client. Finally, if you want to throttle rendering based upon when frames appear on the screen, Swap offers an event that can be delivered to the drawable after the operation actually takes place. Because the Swap extension needs to supply all of the OpenGL SwapBuffers semantics (including a multiplicity of OpenGL extensions related to that), I ve stolen a handful of DRI2 requests to provide the necessary bits for that:
  1. SwapGetMSC
  2. SwapWaitMSC
  3. SwapWaitSBC
These work just like the DRI2 requests of the same names. Current State of the Extensions Both of these extensions have an initial protocol specification written down and stored in git:
  1. DRI3 protocol
  2. Swap protocol

19 February 2013

Daniel Pocock: dynalogin 1.0.0 released

dynalogin 1.0.0 has finally been released. It is available now from the dynalogin web site Packages for Debian GNU/Linux are already in the experimental catalog. It will be made available in Debian unstable and backports as soon as the freeze is lifted for the wheezy release. dynalogin is a distributed solution for one-time-password/token based two-factor authentication on Linux/UNIX based operating systems. It supports PAM (pam_dynalogin) and also has native client code for C/C++ and PHP applications. It is free, open source software, so users can ascertain for themselves that it is genuinely secure and reliable for their needs. dynalogin is licensed under GPL terms. dynalogin works with various soft-tokens, including the dynalogin token for Android and the Google Authenticator for various mobile devices. HOTP and TOTP-based hardware tokens can also be used. Many thanks to Simon Josefsson and the OATH toolkit project which provides the underlying authentication algorithms for dynalogin dynalogin can be integrated with the SimpleID OpenID provider to provide a turn-key solution for web-based single-sign-on, intranets and extranets. All the necessary components are conveniently packaged in Debian and Ubuntu.

Daniel Pocock: dynalogin 1.0.0 released

dynalogin 1.0.0 has finally been released. It is available now from the dynalogin web site Packages for Debian GNU/Linux are already in the experimental catalog. It will be made available in Debian unstable and backports as soon as the freeze is lifted for the wheezy release. dynalogin is a distributed solution for one-time-password/token based two-factor authentication on Linux/UNIX based operating systems. It supports PAM (pam_dynalogin) and also has native client code for C/C++ and PHP applications. It is free, open source software, so users can ascertain for themselves that it is genuinely secure and reliable for their needs. dynalogin is licensed under GPL terms. dynalogin works with various soft-tokens, including the dynalogin token for Android and the Google Authenticator for various mobile devices. HOTP and TOTP-based hardware tokens can also be used. Many thanks to Simon Josefsson and the OATH toolkit project which provides the underlying authentication algorithms for dynalogin dynalogin can be integrated with the SimpleID OpenID provider to provide a turn-key solution for web-based single-sign-on, intranets and extranets. All the necessary components are conveniently packaged in Debian and Ubuntu.

Robert Collins: First experience implementing StreamResult

My last two blog posts were largely about the needs of subunit, but a key result of any protocol is how easy working with it in a high level language is. In the weekend and evenings I ve done an implementation of a new set of classes StreamResult and friends that provides: So far the code has been uniformly simple to write. I started with an API that included an estimate function, which I ve since removed I don t believe the complexity is justified; enumeration is not significantly more expensive than counting, and runners that want to be efficient can either not enumerate or remember the enumeration from prior runs. The documentation in the linked pull request is a good place to start to get a handle on the API; I d love feedback. Next steps for me are to do a subunit protocol revision that maps to the Python API, both parser and generator and see how it feels. One wrinkle there is that the reason for doing this is to fix intrinsic limits in the existing protocol so doing forward and backward wire protocol compatibility would defeat the point. However we can make the output side explicitly choose a protocol version, and if we can autodetect the protocol version in the parser, even if we cannot handle mixed streams we can get the benefits of the new protocol once data has been detected. That said, I think we can start without autodetection during prototyping, and add it later. Without autodetection, programs like TestRepository will need configuration options to control what protocol variant to expect. This could be done by requiring this new protocol and providing a stream filter that can be deployed when needed.

18 February 2013

Dirk Eddelbuettel: New Rcpp master class scheduled for New York

A new Rcpp master class is scheduled for March 9 in New York. The format will an updated version of the one-day workshops I have given at the University of Rochester in 2010, in San Franciso in 2011 (organised by Revolution Analytics) and at the UseR! conference in 2012. The style will be hands-on, with numerous concrete examples and solid coverage of most aspects of Rcpp and related packages. As before, about six hours of instruction, split into four sessions of around ninety minutes focussing (loosely) on motivation/intro, core parts, extensions and applications. This should leave ample time for informal discussions and Q+A---as well as for lunch and coffee breaks---for a total of eight hours in the classroom. This is being put together in New York with the help of Jared Lander, and we will have some technical assistance from RStudio in order to use their EC2 farm for exercises with Rcpp. Registrations details are available here; information about other Rcpp events is also available. Feel free to contact me or Jared at our usual email addresses with questions.

Jan Wagner: Airprint support broken in Debian wheezy?

Some of our customers are using central CUPS systems for managing their printer infrastructure. In the last years the demand for support printing (called Airprint) from mobile apple products increased. This worked well for us on Debian squeeze as documented here (updated scrips). I tried this on a fresh installed Debian wheezy amd64, but no printer was found on any IOS device. Hmm .... let's see if the printer is announces via avahi:
$ avahi-browse -a   grep -i print
+   eth0 IPv6 Kyocera FS-1020D @ service                    Internet Printer     local
+   eth0 IPv6 AirPrint Kyocera @ service                    Internet Printer     local
+   eth0 IPv4 Kyocera FS-1020D @ service                    Internet Printer     local
+   eth0 IPv4 AirPrint Kyocera @ service                    Internet Printer     local
WTF?!? Fortunately we have an Ubuntu 12.04 running in our office and printing from IOS devices works without problems (without copying any files to /etc/avahi/services/):
$ avahi-browse -a   grep -i print
+   eth2 IPv6 Ricoh Aficio MP C2800 @ printing              Internet Printer     local
+   eth2 IPv6 Ricoh Aficio MP 171 @ printing                Internet Printer     local
+   eth2 IPv4 Ricoh Aficio MP 171 @ printing                Internet Printer     local
+   eth2 IPv4 Ricoh Aficio MP C2800 @ printing              Internet Printer     local
I just copied the whole configuration over to my wheezy system, but it didn't worked out. I tried this all on a kfreebsd-i386 system again without success. Sorry, but I don't understand the source of this issue. Cups on wheezy has the same upstream version as on precise. Avahi-daemon on wheezy is just one minor version ahead off precise. Is this a bug/incompatibility in cups and/or avahi? A missing patch compared to the packages of precise? Is this a configuration problem? Update: Looking into LP #1054495 and the debdiff of cups 1.5.3-0ubuntu6 indicates, that there seems modifications beside simple changes of mime configurations files. Update: The fix for LP #1054495 does really fix the problem on wheezy too. With the help of Didier Raboud I was able test a binary package with this fixapplied on our test setup. The good news is, there are no extra modifications needed beside just configuring cups to export it's printers for enabling support for iOS devices. I opened #700961 and hopefully release managment will accept this fix for wheezy. Hints, rants and comments could be send to 'blog - at - waja - dot - info' or via @blogwajainfo.

Paul Tagliamonte: GSoC Project Idea: Debian Android app

Hello, World! There are details coming out soon with regards to GSoC:2013, so all this is without any official hat of any sort on. However, I had an idea, and I was wondering if there were people interested in mentoring it. For a long time, I ve wanted a Debian android application one that will use API calls to fetch PTS info, BTS info, and intercept bug URLs to display Debian related information on the native interface. It d also be neat to set a profile (e.g. my emails) and get notifications when things happen that I care about. Anyone know how to code for android and interested in GSoC?

Aigars Mahinovs: Istabai.lv installation

So, the price of heating my apartment has gone up significantly since last year and a lot of people have noticed the same trend. As a geek, I want not just any solutions, but geekiest solutions possible to that enter a Smart Home system. The heating in my apartment is separated from all other apartments with a separate heat meter that measures both heating water flow and the temperature difference on the incoming and outgoing pipes, so if I reduce the heating consumption I will immediately see that in lower heating bills. This particular smart home system is very simple and made in Latvia and also relatively cheap, so I decided to give this a try. The start was very simple I filled out a form on their home page and got a call the next day to verify the specifics. They already knew my building and had experience installing there, so they offered me two options: I could have two thermal sensors and a radiator controller on each of the 3 radiators in my apartment or (seeing how my apartment is relatively small and well ventilated thus reducing the efficiency of per-room control) one thermal sensor and one radiator controller installed on a new valve that they would build into the heating pipe just outside my apartment. I chose the second option as that was cheaper, simpler and involved less installation for me. Also they offered a nice discount. A plumber of my building installed the valve at some point during the day, I did not even have to be there or arrange anything special, it was all included in the main bill. Then the next day a friendly guy came by to my office and gave me three very cute boxes. The packaging was very, very Apple-like. The three devices were named mother , spy and puller basically that is a base station, a temperature sensor and a radiator regulator a wireless stepper motor. The installation was straight forward I connected the base station (something very similar to this thin in size and looks) to Ethernet and power, went to the web address specified on the sticker on the base station, completed a registration process there, entered a code from the base of the base station into the website and it just found it. After that I pressed a button on the temperature sensor (a Zippo lighter sized box with a built-in Li-Ion battery rechargeable via microUSB once a year or so) and put that on a shelf. I secured it with some double-sided tape after the cat got to it once and played some hockey while I was away. The temperature sensor immediately showed up in the Web UI and I could assign it to a room. The regulator installation was the most complex bit, but it was trivial as well all I had to do was insert some AA batteries (helpfully included in the box, should last a couple years by their estimates), then go outside to the newly installed inlet valve, put this thing on, screw the thread with my hands and then push and hold a button for 10 seconds. After that the controller came to life, connected with the base station and started spinning the valve, testing its operational range I presume. The range is very good you can see 13% signal in the screenshots that is across the whole of the apartment, trough 3 solid walls and another 5 meters out in the hallway inside another wall. As soon as that was done, the Web UI showed the controller and asked my to assign it to a room. So now I have 1 room defined with 1 temperature sensor and one controller. That is all that is needed. Temperature From the charts I have already found out that at current inside/outside temperatures my apartment cools down at around 0.3 degrees C per hour and with current radiator settings it heats up by around 1 degree C per hour. I should turn the radiators up a bit thus increasing the rate at which the system is able to heat things up. Also I should try to re-inspect all possible cold spots to see why the cooldown speed is so high. I expected it to be lower. At least now I have real data to compare things. Temperature chart At this point you can either fire up your web browser or a Android/iOS client on you mobile device to monitor and control the temperature of the apartment. But that was not enough for me I opted for the PRO upgrade which includes the ability to program a weekly cycle of desired temperatures. The programming is limited and thus simple to do there are three temperature modes: day, night and eco. The idea is that you have the night mode every night, then at some time during the day, you have the day mode (to wake up), then you switch to eco mode (when noone is home) and then in the evening you go back to day mode and later to night mode. There are separate sliders for each day of the week and temperature settings for each of the modes for every programmed room. Time zones Temperatures in zones Devices Total investment so far 210 Ls (or around 3 months worth of just heating bills). The experience of other users tells of 30-50% heating bill reduction, so this should pay for itself in 2-3 years. In addition I get a more stable and predictable temperature at home and some more geeky stuff to brag about yay! These guys have their work cut out for them I have no idea how/of they do international orders, I would definately like to see more information in the web site about how my system is working (more temperature history, valve state history, wireless signal and battery history, mobile apps are a bit wonky it feels like the mobile app does not respect the temperature set over the web and tries to reassert itself when opened and it often shows out-of-date temperature data with no indication that it is out-of-date + the mobile apps are missing charts. All in all this is a great start: easy, quite cheap and stylish home heating automation. Good work! P.S. I am pretty sure they use Linux, but it is so packaged, that there is basically no way to confirm or deny that. P.P.S. Also check out this overnight chart, there is definitely some mode switch anticipation going on :)
Overnight temperatures

John Sullivan: SCALE

I will be speaking at the Southern California Linux Expo (and yes, given the topics covered, it's missing a GNU). My talk, "Four Freedoms for Freedom," is on Sunday, February 24, 2013 from 16:30 to 17:30.
The most obvious people affected by all four of the freedoms that define free software are the programmers. They are the ones who will likely want to -- and are able to -- modify software running on their computers. But free software is a movement to advance and defend freedom for anyone and everyone using any computing device, not just programmers. In many countries now, given the ubiquity of tablets, phones, laptops and desktops, "anyone and everyone using any computing device" means nearly all citizens. But new technological innovations in these areas keep coming with new restrictions, frustrating and controlling users even while creating a perception of empowerment. The Free Software Foundation wants to gain the support and protect the interests of everyone, not just programmers. How do we reach people who have no intention of ever modifying a program, and how do we help them?
Other presentations on my list to check out (in chronological order, some conflicting): If you will be there and want to meet up, drop me a line.

17 February 2013

Guido G nther: GTK+3 CSS for touch screens

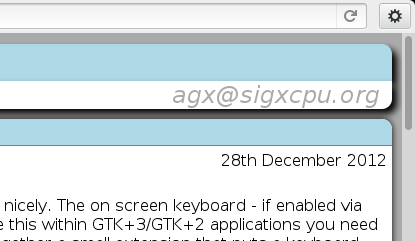
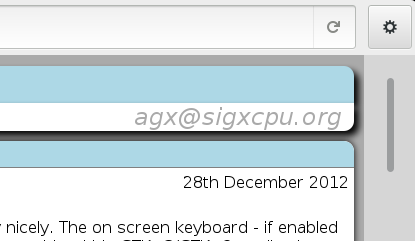
Following up on using Debian on the WeTab with GNOME Shell I've put together a bit of GTK+3 CSS to make it more touch friendly. It's in the same git repo as the OSK extension. If you put the gtk.css into ~/.config/gtk-3.0/gtk.css scrollbars will be a bit larger and the padding between widgets will be increased over the default theme: Larger scroll bar Larger scroll bar This will need more work since some of the sliders look a bit a awkward now so any enhancements will be greatly appreciated. The docs for GTK3's CSS are here. This blog is flattr enabled.

16 February 2013

Christian Perrier: DPL game or why I'm not your man

I am in some way flattered (en_FR?) that some people think that I should stand as DPL candidate (here, or there, or there). Thank you, ladies and gentlemen, for your confidence, it's appreciated. Still, I won't stand and I feel like I should explain why. Yes, I now have some experience in the Debian Project after more than 11 years as DD. Yes, I like to represent the project and I think I don't do that so badly when I do it (which is not as often as one might imagine). Yes, I feel like I have some experience in acting as a "leader" though I often have doubts about this, probably just like many people who have management duties in their professional life. Yes, I often define myself as a non-technical person which helps in dealing with problems and projects with different perspectives. Still, this is often not so true and that extends to my professionnal activity. I *am* indeed a technical person but I'm more a "specialist of everything and nothing" in this aspect. That's probably good for a DPL. But, still I won't stand. There are indeed many reasons for this and I'll try to give them here. First of all, Debian has always been a hobby for me. A hobby that sometimes ate several hours a day and still eats part of my time. But still a hobby. It can't become the major part of my life. And I think that someone spending one year as DPL "has" to do it as the major part of her his life. I can't free time from my work schedule. My work, though being in IT, has few to relate with Free Software, and I can't divert part of it with Debian duties...or merge it with Debian duties. For about 3 years, I compensate the loss of two people in my team by working hard and VERY fast, in a constant stress....connecting with Onera nearly all time long and maintaining the level of services our users deserve as high as I can. And I like it. I can't free time from my family schedule. Of course, my children don't request much attention right now, they all live their own lives. Jean-Baptiste is now having a full-time paid job and does great things in a geeky style I recognize very well. Sophie will soon be a great graduated social worker and will start working in next Summer. And Magali is studying physical therapy so that she can later help me recovering after too hard running races..:-). However, last and definitely not least, I have a wonderful wife who I want to share as much as I can with. And I can't share Debian with her. Indeed, Elizabeth is the very first reason for my reasoning.....because she is the center of my life for more than 30 years now. You also know that I happen to run a little bit..:-)...and that requires time too. Something I won't sacrifice as it brought more equilibrium in my life (and a great health, at an age where one has to care about one's health, now). All this doesn't leave much room. And I indeed noticed that my involvement in Debian has reduced noticeably in the past months. That is indeed the most important point: I'm "slowing down" in Debian...or, at least, I'm trying to find an equilibrium where it represents only a part of my hobbies....and not an ever-growing one. Last...maybe not least, I'm somehow pessimistic about the future of the project. You may have read that subtly in my writings, here or there. I feel like we are slowing down in innovation and are slowly feeling short of resources. Renewal in project members doesn't come as fast as it used to. You are free to disagree with me and I hope you'll be right to. But, still, that won't remove my pessimism. And, well, it's hard to lead a project when you're partly pessimistic about it, isn't it? In short, all in all, I'm currently "fighting" in some way to keep motivation for something I deeply love being involved in. And that's really important. And that's why I can't stand: it wouldn't be a good service to the project. It would be good for my ego, certainly (yes, I have one....and sometimes not a small one)....but it wouldn't be a good service to the project, and I also feel it could very well lead me to burnout. And, if you "nominated" me...or think I would candidate for DPL, you don't want me to burnout and vanish from Debian, right? So, this is why I won't stand. And this is why you'll continue to have great Cheese and Wine parties at Debconfs....or boring l10n reports....or, here or there, some broken uploads in the archive..:-)....but not another French DPL, at least not /me. PS: by the way, I have my own list of preferred candidates. Not sure I want it to be public, though...:-)...you'll see soon if I change my mind!

Daniel Pocock: Adapting the Swisscom Piccolo (Motorola 7640-47) Router for bridging and other ISPs

Background The Piccolo is actually quite a powerful router. Unfortunately, Swisscom has crippled it, removing fundamental configuration options from the web management interface, and even worse, breaking some of the (undocumented) command line configuration options. At a bare minimum, the router can be turned into a bridge/modem, enabling more powerful functionality to be implemented using a wifi router with OpenWRT or a similar solution. Documentation for the Motorola generic version of this device provides some helpful clues about the configuration and may be a useful resource for anybody adapting it. The undocumented telnet interface The username and password for the web interface also allow telnet access to administer the router. The telnet interface actually has quite a lot of features, many more than the web interface. The normal username is admin. If the admin password is not known it can be reset to 1234 using the factory reset button on the back of the router.
$ telnet 192.168.1.1
Trying 192.168.1.1...
Connected to 192.168.1.1.
Escape character is '^]'.
login: admin
Password: (default 1234)
Terminal shell v1.0
Copyright (C) 2011 Motorola, Inc. All rights reserved.
Motorola Netopia Model 7640-47 Annex A VDSL2 IAD
Running Netopia SOC OS version 9.0.10 (build h2d8)
ADSL/VDSL capable
(admin completed login: Admin account with read/write access.)
Removing the Swisscom backdoor The first step for any Piccolo owner is to remove the backdoor from Swisscom. Swisscom links the routers to a management platform that allows them to change configuration remotely, or even push out firmware updates. Allowing an external party such as your ISP to push updates to your router is a major risk. Just imagine if Swisscom decides to update firmware while you are making an online purchase or checking in to a flight - your router reboots itself and your transaction is hosed. Let's have a look at the default configuration of the router, notice these cwmp settings:
Centro_piccolo> show conf
.
.
.
set management cwmp enable on
set management cwmp acs-url "https://rms.bluewin.ch/cwmpWeb/WGCPEMgt"
set management cwmp acs-username "bluewincustomer"
set management cwmp acs-password "***************"
.
.
.
If you didn't already know that was there, you might be quite unpleasantly surprised right now. Removing it is easy:
Centro_piccolo> conf
Config Mode v1.3
Centro_piccolo (top)>> management
Centro_piccolo (management)>> cwmp enable
Centro_piccolo (management cwmp enable)>> set
      enable (on) [ off   on ]: off
Centro_piccolo (management cwmp enable)>> up
Centro_piccolo (management cwmp)>> up
Centro_piccolo (management)>> up
Centro_piccolo (top)>> save
Configuration data saved.
Centro_piccolo (top)>> exit
Notice that after you make a change, you must type the save command to persist the change. Disable the Piccolo's DHCP server If using a more powerful router (e.g. a TP-Link or Buffalo running OpenWRT) then the DHCP server in the Piccolo is not needed. Furthermore, if bridging from a provider that uses the DHCP (as opposed to PPPoE) mechanism to give you your real-world IP address, then the Piccolo's DHCP server will answer the DHCP requests from your other router, and it will never get the proper IP address from the ISP. This scenario must be avoided by disabling the DHCP server in the Piccolo.
Centro_piccolo (top)>> conn name LAN
Centro_piccolo (conn name "LAN")>> dhcp-server-enable
Centro_piccolo (conn name "LAN" dhcp-server-enable)>> set off
Centro_piccolo (conn name "LAN" dhcp-server-enable)>> save
Now, when you want to administer the Piccolo, you need to manually configure an IP address (e.g. 192.168.1.2/24) on the PC that is connecting to the Piccolo. Putting the router into bridge mode When I purchased the router, I was using it with Swisscom. Their own network operates ethernet over ATM and the router obtains an IP address using DHCP. I subsequently changed my ISP to Init7, an independent ISP. Init7, like most third-party ISPs in Switzerland, uses PPPoE rather than the bridged mode. For either mode of operation, the router can bridge the DHCP or PPPoE packets to a more flexible router, such as a TP Link WR-1043ND running OpenWRT or even a Linux server. In the normal configuration, I discovered two bridges in the router:
Centro_piccolo> show bridge interfaces
Bridge interfaces:
bridge name     bridge id               STP enabled     interfaces
br1             8000.0024c94dfcf0       no              eth0.16
                                                        eth1.16
br2             8000.0024c94dfcf1       no              ptm0
                                                        atm1
Clearly, bridging is possible. The Motorola/Netopia manuals refer to various bridge configuration options that just don't seem to exist on this unit. Nonetheless, it is possible to join those two bridges into one:
Centro_piccolo> conf
Config Mode v1.3
Centro_piccolo (top)>> link name LAN
Centro_piccolo (link name "LAN")>> port-vlan
Centro_piccolo (link name "LAN" port-vlan)>> ports
Centro_piccolo (link name "LAN" port-vlan ports)>> set
        ports ("lan-1 lan-2") [ lan-1, lan-2, ptm, vc-1 ]: "lan-1 lan-2 ptm vc-1"
Centro_piccolo (link name "LAN" port-vlan ports)>> up
Centro_piccolo (link name "LAN" port-vlan)>> up
Centro_piccolo (link name "LAN")>> up
Centro_piccolo (link)>> name WAN
Centro_piccolo (link name "WAN")>> port
Centro_piccolo (link name "WAN" port-vlan)>> view
      port-vlan
        ports "ptm vc-1"
        priority 0
Centro_piccolo (link name "WAN" port-vlan)>> ports
Centro_piccolo (link name "WAN" port-vlan ports)>> set
        ports ("ptm vc-1") [ lan-1, lan-2, ptm, vc-1 ]: ""
Centro_piccolo (link name "WAN" port-vlan ports)>> view
        ports ""
Centro_piccolo (link name "WAN" port-vlan ports)>> up
Centro_piccolo (link name "WAN" port-vlan)>> up
Centro_piccolo (link name "WAN")>> up
Centro_piccolo (link)>> save
Configuration data saved.
Centro_piccolo (conn name "WAN" link-oid)>> exit
and now let's check the results:
Centro_piccolo> show bridge interfaces
 Bridge interfaces:
bridge name     bridge id               STP enabled     interfaces
br1             8000.0024c94dfcf0       no              eth0.16
                                                        eth1.16
                                                        ptm0
                                                        atm1
Any WAN connection parameters (PPPoE or DHCP) should now be ignored by the router, and it should just be bridging PPPoE or DHCP traffic from the ISP to the other router. The Piccolo is now behaving like a modem/bridge.

15 February 2013

Iustin Pop: Garmin Montana

Garmin Montana notes Sometimes, I get waaay too excited about gadgets, and I have to share it. So, sorry, here it goes :) For some reason that is not very important, I was looking for a better solution for GPSes with maps. Side-note: if you ask why Android is not good enough , here's the story: last year, knowing that Google Maps supports caching (finally), I upgraded Maps, preloaded London, and went on a trip. Only to exit the Victoria underground station and to stare ~20 minutes in light rain at my phone, wondering why it doesn't get a fix. I gave up in the end, and used the cached maps for getting around. Later I learned the reason: Maps was not broken, but without data, Android can't get a lock easily; and more-over, the recent Maps update without GPS active even once afterwards, to do whatever it needed, meant I couldn't get a lock until back in Switzerland. Or, alternatively: while on a trip to Japan, it turns out that Google Maps caching is not supported there, probably because of rights over mapping data. So I had location, but only temporary cached maps (from the wifi in the hotels). Due to this kind of problems makes I consider Android maps a toy, so I wanted a GPS device with proper maps (on the device, not in the cloud), and with good GPS capabilities (no fancy A-GPS or anything, just plain good standalone GPS). Having had good experiences with the sport line of Garmin (but which doesn't have maps, so it's out of the question), I looked at Garmin. Many people complained about some things (same all over the place): The latter is something that jumped at me from many of the blogs/fora that I read; I like customisable power tools , not one-button mice. The other thing that I didn't really like was that most devices are very focused on a niche: the n vi line on automotive, the Zumo line on motorbikes, and the hand-held lines with some blurring of hiking/geocaching/etc. So no one-size fits all device Features! Customisation! That is, until I found out the Montana series. My my, I was blown. Both by the price (I couldn't believe how expensive it was, without maps!) and by the features. As it turns out, the Montana has different profiles , and it can act: That is for flexibility. As for performance/features: Now for the downsides. Being a multi-functional device, it's not as good as a dedicated one: But the small (for me) draw-backs aside, it's definitely not a dumbed-down device. It's the first device that I have which I feel it a bit too customisable . From completely changeable menus, to profiles that remember their maps selection, to many dashboards, to almost-programmable shortcuts (e.g. a shortcut to change profile, set destination to a given way point, reset the trip log, and turn track logging on) a bit overwhelming at first. Add the 3-axis compass, barometric altimeter, ANT+ support and you get a very powerful device. Software As to the software, yes it has some bugs - mainly that the device crashes sometimes (abruptly) if you play too much with the routes (didn't happen to me yet on the road , only when testing it at home). On the PC-side, Garmin's BaseCamp is nice, but doesn't hold a candle to Google Maps, for example, in terms of UI; I don't mean shininess, but simply how well the UI works. The most annoying thing is how it doesn't scale detail appropriately with the zoom level. But it works, and I can plan hikes offline, and upload both tracks and routes to it (this is important: it seems other recent Garmins can't replay tracks, only routes). And I can load many maps, and toggle them at will, etc. The many maps feature is not to be overlooked. I could have, for example, standard Garmin maps loaded, but just in case they're insuficiently detailed or out of date (hey, Navteq is slow ), I can also have Open Street Maps from two days ago. The routing is then done on the currently active maps, so you are not restricted to a single mapping provider. And of course you can also have custom POIs (Point of interest) on it. Bycicle use The bicycle mount is solid enough, so that on a rough roads it's held firmly. From my ~20 minute test this morning, a few things to note: Voice output By default, the unit can only beep, but if coupled via a 3.5" jack to headphones or via the automotive mount, it can properly speak; quality varies with voice, and whether it is TTS or not. I managed to find one voice (non-TTS) that sounds really well, but of course with less information, and one TTS voice that sounds OK-ish but gives full info. By full info , I mean the following: the behaviour of the various TTS voices is not consistent. For example, on a simulated route, various voices were saying the following: I don't know why these differences, or if they are consistent across routes. But I'll keep with voice E for now :) Summary So, sorry again for sounding like an ad (I don't have any relation with Garmin the company), but I find this device awesome - powerful, rugged, and working (so far) very well. I'm glad that there still exist companies who don't believe they know better than their customers, and instead offer you with a tool that you can make it work just like you want. Or almost ;-) Garmin's tag line: Big and Tough Goes anywhere, everywhere . I tend to agree :)

Next.

Previous.