Search Results: "cas"

1 March 2009

Sven Mueller: Rescueing files from lost+found

Oh well, I tried to search for it but failed miserably, so I m blogging about it hoping the original author might read my post on planet.debian.org (where I read the original post): A friend of mine might need exactly the sort of scripts someone posted here:
  1. Creating a list of file checksum+pathname/filename
  2. Reading files from lost+found and moving them to their original filename by identifying from the list in (1)
However, I can t recall who posted about this, and don t want to do the same work again. Please, Dear Lazyweb, help me ;-)

Frans Pop: The case of the self-perpetuating DNS errors

Ingredients: The last couple of days I've been plagued by some DNS errors that kept showing up in the logcheck mails for my home server which I was busy migrating from one box to another, doing an upgrade from etch/i386 to lenny/amd64 at the same time. So, plenty of stuff going on to confuse the issue. I kept getting the following messages every hour (anonymized):
named: connection refused resolving 'somedomain.org/NS/IN': xxx.yyy.zzz.nnn#53
named: connection refused resolving 'somedomain.org/NS/IN': xxx.yyy.zzz.mmm#53
named: connection refused resolving 'ns1.somedomain.org/AAAA/IN': xxx.yyy.zzz.mmm#53
named: connection refused resolving 'ns2.somedomain.org/AAAA/IN': xxx.yyy.zzz.mmm#53
named: connection refused resolving 'ns1.somedomain.org/AAAA/IN': xxx.yyy.zzz.nnn#53
named: connection refused resolving 'ns2.somedomain.org/AAAA/IN': xxx.yyy.zzz.nnn#53
The times were fairly regular: once just before the hour, most 2 minutes after. I fetch mail at around that time, but also at other times, so possible but unlikely. The 2 minutes after was the first real clue: some cron job maybe? After disabling logcheck the messages no longer appeared in the log. Enable it again, and they were back. Additional confusion was caused by the fact that the domain had "debian" in its name, but it was somewhere obscure. So why was logcheck causing a lookup for that domain? This did confuse me enough to waste some time looking for some silly weird (default) configuration problem in some package. Enter spamassassin. Apparently that was parsing the message body, recognized "somedomain.org" as a host name, and proceded to do a DNS lookup as validity check. So we have the following loop, started off by something causing an initial DNS lookup for the domain, which fails and gets logged: Duh. I remember struggling with probably the same problem a couple of years ago, but then it was a lot more severe: masses of repeating DNS errors for obscure domains. At that time I failed to get to the bottom of it and ended up just ignoring the errors by adding the following option in my bind9 configuration:
logging  
    category lame-servers   null;  ;
 ;
Anyway, now I just no longer pass logcheck mails through spamassassin. (Although filtering out these DNS errors in bind9 can be perfectly valid.)

Joost Yervante Damad: glibc 2.9 - maradns

As Debian has been released my "unstable" box recently upgraded to glibc 2.9.
This caused DNS resolving to mysteriously fail in some applications.

Turns out that only IPv6 enabled applications suffer.

Apparently libc now fires both an IPv4 and IPv6 DNS resolving request in parallel. It looks like some DNS servers don't handle that correctly and answer an error on the IPv6 request before the IPv4 request even has time to resolve further in the internet.

In my case it was my local NSLU2 running Debian lenny causing the trouble, more specific the maradns local DNS server and DNS proxy running on it.

I manually upgraded maradns to the latest version (> 1.3.10) and things are "back" to normal.

Another solution is to disable IPv6 systemwide but I prefer not to do that as I use IPv6 occationally for testing.

I fear that this will cause more trouble for alot of people with routers doing DNS proxying.

Frans Pop: The case of the self-perpetuating DNS-errors

Ingredients: The last couple of days I've been plagued by some DNS errors that kept showing up in the logcheck mails for my home server which I was busy migrating from one box to another, doing an upgrade from etch/i386 to lenny/amd64 at the same time. So, plenty of stuff going on to confuse the issue. I kept getting the following messages every hour (anonymized):
named: connection refused resolving 'somedomain.org/NS/IN': xxx.yyy.zzz.nnn#53
named: connection refused resolving 'somedomain.org/NS/IN': xxx.yyy.zzz.mmm#53
named: connection refused resolving 'ns1.somedomain.org/AAAA/IN': xxx.yyy.zzz.mmm#53
named: connection refused resolving 'ns2.somedomain.org/AAAA/IN': xxx.yyy.zzz.mmm#53
named: connection refused resolving 'ns1.somedomain.org/AAAA/IN': xxx.yyy.zzz.nnn#53
named: connection refused resolving 'ns2.somedomain.org/AAAA/IN': xxx.yyy.zzz.nnn#53
The times were fairly regular: once just before the hour, most 2 minutes after. I fetch mail at around that time, but also at other times, so possible but unlikely. The 2 minutes after was the first real clue: some cron job maybe? After disabling logcheck the messages no longer appeared in the log. Enable it again, and they were back. Additional confusion was caused by the fact that the domain had "debian" in its name, but it was somewhere obscure. So why was logcheck causing a lookup for that domain? This did confuse me enough to waste some time looking for some silly weird (default) configuration problem in some package. Enter spamassassin. Apparently that was parsing the message body, recognized "somedomain.org" as a host name, and proceded to do a DNS lookup as validity check. So we have the following loop, started off by something causing an initial DNS lookup for the domain, which fails and gets logged: Duh. I remember struggling with probably the same problem a couple of years ago, but then it was a lot more severe: masses of repeating DNS errors for obscure domains. At that time I failed to get to the bottom of it and ended up just ignoring the errors by adding the following option in my bind9 configuration:
logging  
    category lame-servers   null;  ;
 ;
Anyway, now I just no longer pass logcheck mails through spamassassin. (Although filtering out these DNS errors in bind9 can be perfectly valid.)

28 February 2009

Pierre Habouzit: How to not make a function safe

This code comes from the actual sources of the last PHP release (ext/sockets/sockets.c). It's probable that this code has been here like, forever: First, yes, this is for real a static variable in the C module, those guys don't know about either of the const or static keyword.
   /* inet_ntop should be used instead of inet_ntoa */                                                       
   int inet_ntoa_lock = 0;
   /* ... */
Then they wrap getpeername:
   PHP_FUNCTION(socket_getpeername)
    
       /* ... */
       if (getpeername(php_sock->bsd_socket, sa, &salen) < 0)  
           PHP_SOCKET_ERROR(php_sock, "unable to retrieve peer name", errno);
           RETURN_FALSE;
        
so far so good. Or maybe not so good.
       switch (sa->sa_family)  
           case AF_INET:
               sin = (struct sockaddr_in *) sa;
               while (inet_ntoa_lock == 1);
               inet_ntoa_lock = 1;
Riiiiiight, locks 101, you fail.
               addr_string = inet_ntoa(sin->sin_addr);
               inet_ntoa_lock = 0;
QUICK ! let's release the lock before we actually use addr_string !
               zval_dtor(arg2);
               ZVAL_STRING(arg2, addr_string, 1);
               /*... */
And you know the best of it ? Of course that code is totally useless since[1]:
   $ grep -wc inet_ntoa **/*.[hc] grep -v :0
   ext/sockets/sockets.c:4
   ext/standard/basic_functions.c:1
   ext/standard/dns.c:2
   main/network.c:1
   sapi/cgi/fastcgi.c:1
   sapi/tux/php_tux.c:1
Those guys are priceless. Especially when you consider the number of 50-liners to implement inet_ntop that lie around.
Notes [1] update: this grep means that inet_ntoa isn't wrapped in the code at all, and that this "locking" code, in addition to be pitiful, is just worthless

Uwe Hermann: Teeworlds - a fun, fast-paced, open-source, online multiplayer shooter

Teeworlds CTF screenshot I have no idea how such a great open-source game as Teeworlds has been able to exist without me hearing about it until recently. Teeworlds is a fast-paced realtime multiplayer shooter. You control a small "Tee" which can hold various weapons (hammer, gun, shotgun, laser-rifle, rocket launcher, ninja-sword) while running and jumping around frantically on the map, trying to frag as many other Tees as you can before you're killed by some other guy. Easy, eh? Teeworlds server list screenshot There's are many game servers to choose from, as well as various game modes (death match, team death match, capfure the flag and some unofficial "mods"). You can join servers on the Internet, or create your own server, be it a public one or a LAN server. Installation Usually I would suggest apt-get install teeworlds, but for now the packages in unstable are an older 0.4.x version, whereas upstream released a much-improved 0.5.1 version. I have already filed a bug and I'm optimistic there'll be a new version in unstable soon. In the mean-time however, you can manually build the game from source via:
 $ apt-get install zlib-dev libsdl1.2-dev
   (maybe also libgl, libglu, and python, if not already installed)
 $ wget 'http://teeworlds.com/trac/bam/browser/releases/bam-0.2.0.zip?format=raw' -O bam-0.2.0.zip
 $ wget http://teeworlds.com/files/teeworlds-0.5.1-src.zip
 $ unzip bam-0.2.0.zip
 $ unzip teeworlds-0.5.1-src.zip
 $ cd bam-0.2.0
 $ ./make_unix.sh
 $ cd ../teeworlds-0.5.1-src
 $ ../bam-0.2.0/src/bam release
Teeworlds stats screenshot Running the game
 $ ./teeworlds
You'll obviously need a working OpenGL/DRI setup (check if "glxinfo grep direct" says "Yes"), otherwise the game will be way too slow. In case you experience graphics glitches and distortions, first exit the game, then:
 $ vi ~/.teeworlds/settings.cfg
Change the "gfx_noclip 0" option there to "gfx_noclip 1" and restart the game. Teeworlds DM screenshot Firewalls If you use a local firewall as I do, you need to open at least ports 8300-8303 (UDP), even better 8300-8310 for more choice in game servers:
 $ iptables -A OUTPUT -m state --state NEW -p udp --dport 8300:8310 -j ACCEPT
Further resources Have fun!

27 February 2009

Jordi Mallach: natura upgraded to lenny

natura.oskuro.net, the home server which still serves this blog, has been suffering hardware problems for some weeks. Apparently the hard drive is failing intermittently, so every now the kernel starts spewing out noisy errors about its main disk dying. If I notice this quickly, it can be rebooted and that normally fixes it for a few more days. But if I don't, it'll end up giving nasty bus errors which will make remote logins a challenge. Most processes still work, but the filesystem appears to be gone. It's easy to know what's going on if you visit the blog's url and get some 404, and in that case I can only phone my father and tell him to press the reset button (I've tried sysrqd, but I need to open the port in the router and haven't had chance to do that yet). So it was time to do something about it, and the other day I installed a dirty 40GB drive on the second IDE controller, in case I could find the time to do somethng about it. Being with an endless pharyngitis that doesn't seem to get cured entirely, I've had some time today to look at it. This evening, I was about to transfer all the system to the new disk (it's half the size as the broken one, and probably slower, but it hopefully has no bad sectors), but I decided to upgrade the system first. natura was first installed in late 1997 or at the beginning of 1998, using the Debian bo install media on a Pentium 150MHz, and has gone through seven dist-upgrades which, as far as I can remember, have always worked out without major problems. The upgrade to lenny hasn't been an exception. The server has gradually lost many of the services it once hosted, so there aren't too many services to take care of anymore. All the mail services I setup for my father ended up being deprecated as they started to get used to Hotmail, GMail and so on, and the frequent hardware crashes made me switch them to the Linksys based DHCP server. In the end, the problems I saw after the upgrade were very similar to what I faced when I upgraded to etch: Such an ancient install will clearly have old, obsolete packages. I installed apt-show-versions to find out what didn't match my package sources. I found I had every single version of cpp, gcc and g++ from 2.95 to 4.3, and a myriad of obsolete libs. But there were also real gems:
defrag 0.73pjm1-7 installed: No available version in archive
figlet 2.2.1-3 installed: No available version in archive
ipmasqadm 0.4.2-2 installed: No available version in archive
isapnptools 1.26-5 installed: No available version in archive
ms-sys 2.1.0-1 installed: No available version in archive
queso 0.980922b-3 installed: No available version in archive
update 2.11-4 installed: No available version in archive
Spaniards will remember queso because it was written by Jordi Murg and became a classic tool to find out what OS was running on a remote host. update was apparently needed to flush your filesystems prior to Linux 2.2.8, and defrag is obvious, although leaves me wondering why it was needed at the time. With the upgrade done successfully, next step is trying to get the system transfered to the spare hard drive. For this, I first partitioned it creating a primary partition using up more or less half of the available space, and setup a LVM volume, leaving some free PE's in the volume group just in case I want to do snapshots in the future, and formatted it using ext3. I then transfered the system to the new disk and now face the boot challenge. I haven't created a boot partition and that should be a double problem: the BIOS is buggy and will only boot from the first 1024 cylinders, and my root is on LVM and GRUB legacy might not like it (but I'm not sure). However, I've become a big fan of GRUB2, and know I will be able to boot no matter what my BIOS thinks of my disks and regardless the complex root partition setup I throw at it. The plan is to install GRUB onto the new drive's MBR, and set it up using the ata module, which should allow to ignore what the BIOS says, and read beyond cylinder 1024 or even boot from CD-ROM. However, this isn't a setup I haven't tried before, and a single failure will result in me taking a train to fix it on-site. So, GRUB experts out there, any suggestions? Of course, for now I guess I can install GRUB in the current drive's MBR and make it boot the old kernel using the new system as root, but that's dirty and would just postpone the problem.

Daniel Kahn Gillmor: redundant DHCP service for a sprawling LAN?

I'm supporting a medium-sized (~70 regular clients and a half-dozen servers) LAN. It's a single logical ethernet segment, but it's built as a tree of cascaded switches. DHCP service is provided by a single host running ISC's DHCPD (via dhcp3-server). DHCP itself is one of the single points of failure in the network layout. i'd really like to make this DHCP server redundant (so that i can take that host down for service if needed and leave the rest of the network intact). However, reading dhcpd.conf(5) makes me pretty worried that the failover stuff is not well-tested or widely deployed. I've read Paul Heinlein's Failover with ISC DHCP, which makes it look not unreasonable, but i was wondering if people have other preferred mechanisms for providing DHCP redundancy. Do you have failover DHCP set up for any LAN that you manage? If so, what do you use? Are there any gotchas to watch out for? I'm also concerned about the security implications. On a network that's not using IPSEC, i don't see any mechanism for the two DHCP servers to properly mutually authenticate. Is it really just by IP address? Could someone spoofing the IP address of one host corrupt the state of the other DHCP server? (i'm less concerned about them keeping network traffic private, since most of what they communicate is likely to go out in the clear on the wire anyway). Am i missing some clever authentication technique? From a security point of view, i understand that there are more severe security problems with DHCP itself, of course (the protocol requires that the client trust the (unauthenticated) server), but that doesn't seem likes a good reason to introduce an opportunity to compromise any given server directly. Your thoughts on DHCP redundancy?Tags: dhcp, failover, redundancy

Bastian Venthur: git-svn branch

Dear Lazyweb, how do I push a local git branch to a new svn branch? The other way round is quite easy and well documented but I didn t find a single document describing what I want to do. I m working with an svn repository with standard layout. I use git-svn to be able to use git locally. Until now I ve always had my master branch reflect the svn s trunk. For every new feature, I created a local git branch, merged with the master branch when I was done and dcommit ed it to the svn s trunk. But now I need to publish an experimental feature which should not yet go into the trunk so I have to publish my local git branch to an svn branch. I tried git-svn branch foo in the local git branch and it created a svn branch/foo for me but not from the current git branch but from the current master (remote/trunk). That s of course not what I wanted, I wanted to push the current branch where I m in and have it linked to the remote svn branch. Neither the manpage of git-svn nor some documentation in the web helped me. I even found a pretty detailed document which describes each and every aspect of git-svn but unfortunately not mine. Is this use case so unusual that no one else uses git-svn this way or is it my weak git-FU?

26 February 2009

Theodore Ts'o: Fast ext4 fsck times, revisited

Last night I managed to finish up a rather satisfying improvement to ext4 s inode and block allocators. The ext4 s original allocator was actually a bit more simple-minded than ext3 s, in that it didn t implement the Orlov algorithm to spread out top-level directories for better filesystem aging. It also was buggy in certain ways, where it would return ENOSPC even when there were still plenty of inodes in the file system. So I had been working on extending ext3 s original Orlov allocator so it would work well with ext4. While I was at it, it occurred to me that one of the tricks I could play with ext4 s flex groups (which are higher-order collection of block groups), was to bias the block allocation algorithms such that the first block group in a flexgroup would be preferred for use by directories, and biased against data blocks for regular files. This meant that directory blocks would get clustered together, which cut a third off the time needed for e2fsck pass2:
Comparison of e2fsck times on an 32GB partition
Pass ext4 old allocator ext4 new allocator
time (s) I/O time (s) I/O
real user system MB read MB/s real user system MB read MB/s
1 6.69 4.06 0.90 82 12.25 6.70 3.63 1.58 82 12.23
2 13.34 2.30 3.78 133 9.97 4.24 1.27 2.46 133 31.36
3 0.02 0.01 0 1 63.85 0.01 0.01 0.01 1 82.69
4 0.28 0.27 0 0 0 0.23 0.22 0 0 0
5 2.60 2.31 0.03 1 0.38 2.42 2.15 0.07 1 0.41
Total 23.06 9.03 4.74 216 9.37 13.78 7.33 4.19 216 15.68

As you may recall from my previous observations on this blog, although we hadn t been explicitly engineering for this, a file system consistency check on an ext4 file system tends to be a factor of 6-8 faster than the e2fsck times on an equivalent ext3 file system, mainly due to the elimination of indirect blocks and the uninit_bg feature reducing the amount of disk reads necessary in e2fsck s pass 1. However, the ext4 layout optimizations didn t do much for e2fsck s pass 2. Well, the optimization of the block and inode allocators is complementary to the original ext4 fsck improvements, since it focuses on what we hadn t optimized the first time around: e2fsck pass 2 times have been cut by a third, and the overall fsck time has been cut by 40%. Not too shabby! Of course, we need to do more testing to make sure we haven t caused other file system benchmarks to degrade, although I m cautiously optimistic that this will end up being a net win. I suspect that some benchmarks will go up by a little, and others will go down a little, depending on how heavily the benchmark exercises directory operations versus sequential I/O patterns. If people want to test this new allocator, it is in the ext4 patch queue. If all goes well, I will hopefully be pushing it to Linus after 2.6.29 is released, at the next merge window.

horizontal separator For comparison s sake, here is a comparison of the fsck time of the same collection of files and directories, comparing ext3 and the original ext4 block and inode allocator. The file system in question is a 32GB install of Ubuntu Jaunty, with a personal home directory, a rather large Maildir directory, some linux kernel trees, and an e2fsprogs tree. It s basically the emergency environment I set up on my Netbook at FOSDEM. In all cases the file systems were freshly copied from the original root directory using the command rsync -axH / /mnt. It s actually a bit surprising to me that ext3 s pass 2 e2fsck times was that much better than e2fsck time under the old ext4 allocator. My previous experience has shown that the two are normally about the same, with a write throughput of around 9-10 MB/s on for e2fsck s pass 2 for both ext3 file systems and ext4 file systems with the original inode/block allocators. Hence, I would have expected ext3 s pass2 time to have been 12-13 seconds, and not 6. I m not sure how that happened, unless it was the luck of draw in terms of how things ended up getting allocated on disk. So I m not too sure what happened there, but overall things look quite good for ext4 and fsck times!
Comparison of e2fsck times on an 32GB partition
Pass ext3 ext4 old allocator
time (s) I/O time (s) I/O
real user system MB read MB/s real user system MB read MB/s
1 108.40 13.74 11.53 583 5.38 6.69 4.06 0.90 82 12.25
2 5.91 1.74 2.56 133 22.51 13.34 2.30 3.78 133 9.97
3 0.03 0.01 0 1 31.21 0.02 0.01 0 1 63.85
4 0.28 0.27 0 0 0 0.28 0.27 0 0 0
5 3.17 0.92 0.13 2 0.63 2.60 2.31 0.03 1 0.38
Total 118.15 16.75 14.25 718 6.08 23.06 9.03 4.74 216 9.37
Vital Statistics of the 32GB partition
312214 inodes used (14.89%)
263 non-contiguous files (0.1%)
198 non-contiguous directories (0.1%)
# of inodes with ind/dind/tind blocks: 0/0/0
Extent depth histogram: 292698/40
4388697 blocks used (52.32%)
0 bad blocks
1 large file
263549 regular files
28022 directories
5 character device files
1 block device file
5 fifos
615 links
20618 symbolic links (19450 fast symbolic links)
5 sockets
312820 files
Related posts (automatically generated):

  1. Fast ext4 fsck times This wasn t one of the things we were explicitly engineering...
  2. Wanted: Incremental Backup Solutions that Use a Database Dear Lazyweb, I m looking for recommendations for Open Source backup...
  3. Ext4 is now the primary filesystem on my laptop Over the weekend, I converted my laptop to use the...

Theodore Ts'o: Fast ext4 fsck times, revisited

Last night I managed to finish up a rather satisfying improvement to ext4 s inode and block allocators. The ext4 s original allocator was actually a bit more simple-minded than ext3 s, in that it didn t implement the Orlov algorithm to spread out top-level directories for better filesystem aging. It also was buggy in certain ways, where it would return ENOSPC even when there were still plenty of inodes in the file system. So I had been working on extending ext3 s original Orlov allocator so it would work well with ext4. While I was at it, it occurred to me that one of the tricks I could play with ext4 s flex groups (which are higher-order collection of block groups), was to bias the block allocation algorithms such that the first block group in a flexgroup would be preferred for use by directories, and biased against data blocks for regular files. This meant that directory blocks would get clustered together, which cut a third off the time needed for e2fsck pass2:
Comparison of e2fsck times on an 32GB partition
Pass ext4 old allocator ext4 new allocator
time (s) I/O time (s) I/O
real user system MB read MB/s real user system MB read MB/s
1 6.69 4.06 0.90 82 12.25 6.70 3.63 1.58 82 12.23
2 13.34 2.30 3.78 133 9.97 4.24 1.27 2.46 133 31.36
3 0.02 0.01 0 1 63.85 0.01 0.01 0.01 1 82.69
4 0.28 0.27 0 0 0 0.23 0.22 0 0 0
5 2.60 2.31 0.03 1 0.38 2.42 2.15 0.07 1 0.41
Total 23.06 9.03 4.74 216 9.37 13.78 7.33 4.19 216 15.68

As you may recall from my previous observations on this blog, although we hadn t been explicitly engineering for this, a file system consistency check on an ext4 file system tends to be a factor of 6-8 faster than the e2fsck times on an equivalent ext3 file system, mainly due to the elimination of indirect blocks and the uninit_bg feature reducing the amount of disk reads necessary in e2fsck s pass 1. However, the ext4 layout optimizations didn t do much for e2fsck s pass 2. Well, the optimization of the block and inode allocators is complementary to the original ext4 fsck improvements, since it focuses on what we hadn t optimized the first time around: e2fsck pass 2 times have been cut by a third, and the overall fsck time has been cut by 40%. Not too shabby! Of course, we need to do more testing to make sure we haven t caused other file system benchmarks to degrade, although I m cautiously optimistic that this will end up being a net win. I suspect that some benchmarks will go up by a little, and others will go down a little, depending on how heavily the benchmark exercises directory operations versus sequential I/O patterns. If people want to test this new allocator, it is in the ext4 patch queue. If all goes well, I will hopefully be pushing it to Linus after 2.6.29 is released, at the next merge window.

horizontal separator For comparison s sake, here is a comparison of the fsck time of the same collection of files and directories, comparing ext3 and the original ext4 block and inode allocator. The file system in question is a 32GB install of Ubuntu Jaunty, with a personal home directory, a rather large Maildir directory, some linux kernel trees, and an e2fsprogs tree. It s basically the emergency environment I set up on my Netbook at FOSDEM. In all cases the file systems were freshly copied from the original root directory using the command rsync -axH / /mnt. It s actually a bit surprising to me that ext3 s pass 2 e2fsck times was that much better than e2fsck time under the old ext4 allocator. My previous experience has shown that the two are normally about the same, with a write throughput of around 9-10 MB/s on for e2fsck s pass 2 for both ext3 file systems and ext4 file systems with the original inode/block allocators. Hence, I would have expected ext3 s pass2 time to have been 12-13 seconds, and not 6. I m not sure how that happened, unless it was the luck of draw in terms of how things ended up getting allocated on disk. So I m not too sure what happened there, but overall things look quite good for ext4 and fsck times!
Comparison of e2fsck times on an 32GB partition
Pass ext3 ext4 old allocator
time (s) I/O time (s) I/O
real user system MB read MB/s real user system MB read MB/s
1 108.40 13.74 11.53 583 5.38 6.69 4.06 0.90 82 12.25
2 5.91 1.74 2.56 133 22.51 13.34 2.30 3.78 133 9.97
3 0.03 0.01 0 1 31.21 0.02 0.01 0 1 63.85
4 0.28 0.27 0 0 0 0.28 0.27 0 0 0
5 3.17 0.92 0.13 2 0.63 2.60 2.31 0.03 1 0.38
Total 118.15 16.75 14.25 718 6.08 23.06 9.03 4.74 216 9.37
Vital Statistics of the 32GB partition
312214 inodes used (14.89%)
263 non-contiguous files (0.1%)
198 non-contiguous directories (0.1%)
# of inodes with ind/dind/tind blocks: 0/0/0
Extent depth histogram: 292698/40
4388697 blocks used (52.32%)
0 bad blocks
1 large file
263549 regular files
28022 directories
5 character device files
1 block device file
5 fifos
615 links
20618 symbolic links (19450 fast symbolic links)
5 sockets
312820 files
Related posts (automatically generated):

  1. Fast ext4 fsck times This wasn t one of the things we were explicitly engineering...
  2. Wanted: Incremental Backup Solutions that Use a Database Dear Lazyweb, I m looking for recommendations for Open Source backup...
  3. Ext4 is now the primary filesystem on my laptop Over the weekend, I converted my laptop to use the...

Joerg Jaspert: DebConf10 in NYC

If you haven t already read about it, DebConf 10 will be in the USA. More information about the bid can, currently, be found in our DebConf wiki. I myself are not happy with this decision, I would have preferred a non-US bid to win. No matter which, but unfortunately in the end we only had one non-US bid in the final meeting (which I was chairing together with Marga), and while this was a pretty good one, it still lost in comparision The whole meeting was very long, it took us 3.5 hours to get the decision. And if the three bids (the possible fourth dropped out before the meeting started) wouldn t have prepared as well as they did this year, it could have easily been 5 or 6 hours. I think it also helped a lot that we forbid everyone, besides few global orga team members and 2 people from each bid, to speak during the meeting. For the chatter and all stuff outside the meeting we made an extra channel and had one of the global orga team members forward any meeting relevant questions. Just looking at the amount of traffic the other channel had during the meeting this was certainly a good idea. We went on by having the bid people introduce themself and then gave everyone time to read the prepared pages of the bids, saving us from copy/paste into the channel, just having a few comments from the venue team inside the channel. Faster if people read it from a website. And after each bid described their own weak points, and what they think is good in the other bids, we had a question session. First part was moderated, 5 minutes per bid, questions related only to the bid. And then a free-for-all 10 minute session, where everyone in the channel was able to speak. Those first steps took nearly exactly one hour, which means the following two and a half hour we used entirely for the discussion how to rate the various topics from our priority list. Some of those topics had been pretty easy to decide as everyone agreed, like that the Quito bid wins for accommodation costs. Or Quito losing for network connectivity, while that had been a huge discussion between New York and Boston who would be better there. Same for food stuff, in cities like these it is practically impossible to say that one is better than the other. After some time (about 2 hours) we had all our topics covered and it was clear from it that the Quito bid couldn t win anymore, so they dropped out here. The rest of us had a 5 minute break and then continued the discussion for about 15 minutes, until it was crystal clear we wont be able to find a way out. We changed the discussion mode from Global team together with the bid teams to Global team only to finally get a decision. Took us another 10 minutes before we had the decision.
Now we have a venue for DebConf where a lot of people wont visit because of the country it is in. Some people sure do that out of a general I hate the US behaviour, I don t know (nor do I care), some others share concerns I have. Mine is mostly with their crap border system. Imagine you are going to visit some place as a tourist, and this place has nothing better to do than to mark you as criminal, by taking your fingerprints, a lot of personal (and totally irrelevant) data and storing that for decades (if not more). A border that can steal your laptop (and/or the data it is on). And whatever else. All that to work against terrorism . As if any of this crap would help. Its pure bullshit, but the usual level politicians have, no matter which country on this world. And I see no reason to put up with this. Truth is, I would rather quit my job before traveling there. The DC10 team puts a lot of hope into the new government to remedy some of the crap the US is doing / had setup during the brainless twit Bush. I wish their hope would come true, but I would place a fairly high bet that this won t happen. No government is taking back actions from their predecessor that are claimed to help security, even if they don t. No matter how much change they promised. (Yes, should their hope really come true and the US no longer thinks you are a criminal just because you want to visit this country, I will change my mind about going there. I just don t believe this will be the case). It probably can t hurt to take a year off and do something different. I don t know what I will do, will be quite a change not taking a whole month off to go to conference I do a little work for (2 weeks conference plus 2 weeks tourism in the country DebConf is in, a habit I started in Mexico ). Or to spend months before it doing work to get it running. I can t even imagine doing this stuff of normal holidays I hear others talking off, traveling to one location and bake yourself in the sun somewhere in a hotel, doing nothing. Brrr.
Now, as some may know, im one of the admins for the debconf.org domain and machine park. Just to avoid more people asking: I won t let my work there be affected from my dislike that the NYC bid won. They will get the same service every other DC had. Well, except that they have to do more admin work, as I will not neccessarily do all of it, especially not the local part, but just enable them to do it whenever neccessary and/or possible.

24 February 2009

Lucas Nussbaum: Creating a large file without zeroing it

Dear readers, I d like to use a large file (> 10 GB) as swap space.
The required steps are:
  1. Create a file
  2. mkswap $file
  3. swapon $file
Now, how can I create the file? The obvious and fast solution is to create a file with holes:
dd if=/dev/zero of=foo bs=1M count=1 seek=10239
mkswap works, but swapon complains:
# swapon /tmp/foo
swapon: Skipping file /tmp/foo - it appears to have holes.
Of course, I count just dd if=/dev/zero of=foo bs=1M count=10240, but that takes too long for me. So, question: is there a way to tell the system: create a file that is 10GB big, don t but fill it with zeros?

Jon Dowland: toys for sale

For reasons I will hopefully explain soon, I need to have a bit of a clear out and raise some money. I will be looking to sell my Thecus N2100 NAS box, complete with a soldered-on serial port connector, the relevant adaptor to 9-pin D-SUB and 512M RAM upgrade and possibly a 500GB SATA drive to use with it; plus my Nokia N800 Internet tablet, screen protector, bluetooth keyboard and some SD cards (can't recall the size of those off the top of my head). I won't post adverts on my log for these once I've sorted them out, but I wanted to send out a heads-up in case a fellow Debian person would find them useful.

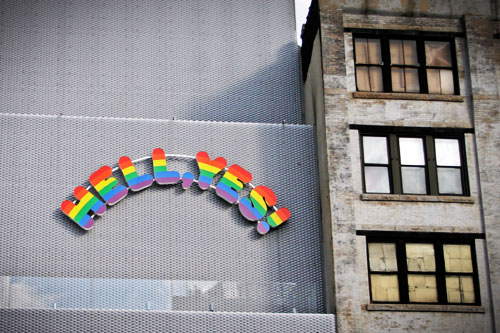
Biella Coleman: hell_yes: debconf nyc 2010


hell_yes, originally uploaded by the biella.
w00t. NYC has been chosen. I was equally excited about Boston so I did not really care about which city won out. But since it is in NYC, I will definitely be helping out and one of the first things I want to do is organize a 1/2 day trip to this sauna/spa mega-facility in Queens

Biella Coleman: hell_yes: debconf nyc 2010


hell_yes, originally uploaded by the biella.
w00t. NYC has been chosen. I was equally excited about Boston so I did not really care about which city won out. But since it is in NYC, I will definitely be helping out and one of the first things I want to do is organize a 1/2 day trip to this sauna/spa mega-facility in Queens

23 February 2009

Matthew Garrett: Misc

Minor Fedora updates - I fixed up the FDI file in the wacom package, so tablet PCs should have a working stylus out of the box in rawhide. The eraser won't work right now - the driver needs some reworking to bind multiple X devices to a single logical input device. I've also added support for brightness control via smartdimmer to nouveau, which should increase the number of machines that have working brightness control. I don't think this has landed in the rawhide kernel yet, but should do soon. There's the potential for some conflict with the mbp_nvidia_bl driver. We may end up dropping that.

HP updates - The button bar on my 2510 got replaced last week. I now have working volume buttons again. However, the machine now reboots whenever the machine is suspended and I close the lid. Diagnosed to either a faulty switch assembly or system board, which will require an engineer visit. An engineer dropped round today to fix the touchpad. Despite the case notes clearly stating that the problem was with the cable assembly, he was sent a replacement top cover unit. Without any cables. So he's coming back at some point. HP's customer support system apparently does not allow these cases to be merged. Which means I now have two visits to look forward to.

Android - I'm gradually working my way through the code, replacing various custom interfaces with standard ones. const char * const LCD_BACKLIGHT = "/sys/class/leds/lcd-backlight/brightness"; is an interesting standout so far.

Michal &#268;iha&#345;: Gammu stable version 1.23.0

After two months of heavy development, new Gammu stable release is out. There are quite a lot of changes and I'm not really convinced it makes sense to include full list of almost 150 lines from ChangeLog, so here are the most important changes (I'm sure I missed something, but I think the list is already too big): You can download from usual place: http://cihar.com/gammu/, Debian users will find packages in unstable soon, SUSE, Fedora and Mandriva users can check repository in OpenSuse Build Service and Ubuntu in my PPA.

Bernd Zeimetz: awesome calendar widget

One of the things I was missing in my favourite windowmanager awesome was a calendar widget. So I spent some minutes and coded it. Moving the mouse over the time widget will show a naughty popup with the current month, use your mouse buttons (and the shift key) to scroll trough the months. The only annoying thing was to figure out how to change the text of an existing notification: notification.box.widgets[2].text = "new test" is neither easy to figure out nor to use. But here's the code for your rc.lua - in case you want to have a license for it - the code is published as public domain or under the ISC license, what ever you prefer.
function displayMonth(month,year,weekStart)
    local t,wkSt=os.time year=year, month=month+1, day=0 ,weekStart or 1
    local d=os.date("*t",t)
    local mthDays,stDay=d.day,(d.wday-d.day-wkSt+1)%7
    local lines =  
    for x=0,6 do
        lines[x+1] = os.date("%a ",os.time year=2006,month=1,day=x+wkSt )
    end
    lines[8] = "    "
    local writeLine = 1
    while writeLine < (stDay + 1) do
        lines[writeLine] = lines[writeLine] .. "   "
        writeLine = writeLine + 1
    end
    for x=1,mthDays do
        if writeLine == 8 then
            writeLine = 1
        end
        if writeLine == 1 or x == 1 then
            lines[8] = lines[8] .. os.date(" %V",os.time year=year,month=month,day=x )
        end
        if (#(tostring(x)) == 1) then
            x = " " .. x
        end
        lines[writeLine] = lines[writeLine] .. " " .. x
        writeLine = writeLine + 1
    end
    local header = os.date("%B %Y\n",os.time year=year,month=month,day=1 )
    header = string.rep(" ", math.floor((#(lines[1]) - #header) / 2 )) .. header
    return header .. table.concat(lines, '\n')
end
local calendar =  
function switchNaughtyMonth(switchMonths)
    if (#calendar < 3) then return end
    local swMonths = switchMonths or 1
    calendar[1] = calendar[1] + swMonths
    calendar[3].box.widgets[2].text = displayMonth(calendar[1], calendar[2], 2)
end
mytextbox.mouse_enter = function ()
    local month, year = os.date('%m'), os.date('%Y')
    calendar =   month, year, 
                naughty.notify( 
                    text = displayMonth(month, year, 2),
                    timeout = 0, hover_timeout = 0.5,
                    width = 200
                 )
                
end 
mytextbox.mouse_leave = function () naughty.destroy(calendar[3]) end
mytextbox:buttons( 
    button(   , 1, function()
        switchNaughtyMonth(-1)
    end),
    button(   , 3, function()
        switchNaughtyMonth(1)
    end),
    button(   , 4, function()
        switchNaughtyMonth(-1)
    end),
    button(   , 5, function()
        switchNaughtyMonth(1)
    end),
    button(  'Shift'  , 1, function()
        switchNaughtyMonth(-12)
    end),
    button(  'Shift'  , 3, function()
        switchNaughtyMonth(12)
    end),
    button(  'Shift'  , 4, function()
        switchNaughtyMonth(-12)
    end),
    button(  'Shift'  , 5, function()
        switchNaughtyMonth(12)
    end)
 )

Bernd Zeimetz: awesome calendar widget

One of the things I was missing in my favourite windowmanager awesome was a calendar widget. So I spent some minutes and coded it. Moving the mouse over the time widget will show a naughty popup with the current month, use your mouse buttons (and the shift key) to scroll trough the months. The only annoying thing was to figure out how to change the text of an existing notification: notification.box.widgets[2].text = "new test" is neither easy to figure out nor to use. But here's the code for your rc.lua - in case you want to have a license for it - the code is published as public domain or under the ISC license, what ever you prefer. Update: With thanks to a hint from madduck, the naughty popup is now aware of the screen your mouse is pointing to.
function displayMonth(month,year,weekStart)
    local t,wkSt=os.time year=year, month=month+1, day=0 ,weekStart or 1
    local d=os.date("*t",t)
    local mthDays,stDay=d.day,(d.wday-d.day-wkSt+1)%7
    local lines =  
    for x=0,6 do
        lines[x+1] = os.date("%a ",os.time year=2006,month=1,day=x+wkSt )
    end
    lines[8] = "    "
    local writeLine = 1
    while writeLine < (stDay + 1) do
        lines[writeLine] = lines[writeLine] .. "   "
        writeLine = writeLine + 1
    end
    for x=1,mthDays do
        if writeLine == 8 then
            writeLine = 1
        end
        if writeLine == 1 or x == 1 then
            lines[8] = lines[8] .. os.date(" %V",os.time year=year,month=month,day=x )
        end
        if (#(tostring(x)) == 1) then
            x = " " .. x
        end
        lines[writeLine] = lines[writeLine] .. " " .. x
        writeLine = writeLine + 1
    end
    local header = os.date("%B %Y\n",os.time year=year,month=month,day=1 )
    header = string.rep(" ", math.floor((#(lines[1]) - #header) / 2 )) .. header
    return header .. table.concat(lines, '\n')
end
local calendar =  
function switchNaughtyMonth(switchMonths)
    if (#calendar < 3) then return end
    local swMonths = switchMonths or 1
    calendar[1] = calendar[1] + swMonths
    calendar[3].box.widgets[2].text = displayMonth(calendar[1], calendar[2], 2)
end
mytextbox.mouse_enter = function ()
    local month, year = os.date('%m'), os.date('%Y')
    calendar =   month, year, 
                naughty.notify( 
                    text = displayMonth(month, year, 2),
                    timeout = 0, hover_timeout = 0.5,
                    width = 200, screen = mouse.screen
                 )
                
end 
mytextbox.mouse_leave = function () naughty.destroy(calendar[3]) end
mytextbox:buttons( 
    button(   , 1, function()
        switchNaughtyMonth(-1)
    end),
    button(   , 3, function()
        switchNaughtyMonth(1)
    end),
    button(   , 4, function()
        switchNaughtyMonth(-1)
    end),
    button(   , 5, function()
        switchNaughtyMonth(1)
    end),
    button(  'Shift'  , 1, function()
        switchNaughtyMonth(-12)
    end),
    button(  'Shift'  , 3, function()
        switchNaughtyMonth(12)
    end),
    button(  'Shift'  , 4, function()
        switchNaughtyMonth(-12)
    end),
    button(  'Shift'  , 5, function()
        switchNaughtyMonth(12)
    end)
 )

Next.

Previous.
