Search Results: "xam"

11 June 2023

Dirk Eddelbuettel: sanitizers 0.1.1 on CRAN: Updated and Expanded

bleach The second release of the sanitizers package is now on CRAN. sanitizers provides true positives for programming errors detected by Address Sanitizers and friends. This permits validation of the setup when chasing such bug reports: it allows us to ascertain that the compiler (and instrumented R version) are correctly set up and the errors we expect to be reported are in fact reported. Almost nine years (!!) since the first release, this update brings an added integer overflow sanitizer contributed by Greg Jeffries so long ago that I had thought it was part of the CRAN releases my bad for delaying this. It also updates programming practices by switching to symbol registration for the compiled functions. And of course several R packaging best practices have improved since the initial release so we updated a few small things throughout. A very good resources for all things sanitizers is the Google repo at GitHub and especially its wiki. The brief NEWS entry follows.

Changes in version 0.1.1 (2023-06-11)
  • Added integer overflow example kindly contributed by Greg Jeffries
  • Added continuous integration and badges
  • Updated package to use symbol registration for compiled code
  • Updated and edited DESCRIPTION, README and help pages for current packaging standards
  • Expanded README with usage example via r-devel-san Rocker container

Courtesy of my CRANberries, there is a diffstat report for this release. See the project page, the github repo, and the package documentation for more details. If you like the open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Michael Prokop: What to expect from Debian/bookworm #newinbookworm

Bookworm Banner, Copyright 2022 Juliette Taka Debian v12 with codename bookworm was released as new stable release on 10th of June 2023. Similar to what we had with #newinbullseye and previous releases, now it s time for #newinbookworm! I was the driving force at several of my customers to be well prepared for bookworm. As usual with major upgrades, there are some things to be aware of, and hereby I m starting my public notes on bookworm that might be worth also for other folks. My focus is primarily on server systems and looking at things from a sysadmin perspective. Further readings As usual start at the official Debian release notes, make sure to especially go through What s new in Debian 12 + Issues to be aware of for bookworm. Package versions As a starting point, let s look at some selected packages and their versions in bullseye vs. bookworm as of 2023-02-10 (mainly having amd64 in mind):
Package bullseye/v11 bookworm/v12
ansible 2.10.7 2.14.3
apache 2.4.56 2.4.57
apt 2.2.4 2.6.1
bash 5.1 5.2.15
ceph 14.2.21 16.2.11
docker 20.10.5 20.10.24
dovecot 2.3.13 2.3.19
dpkg 1.20.12 1.21.22
emacs 27.1 28.2
gcc 10.2.1 12.2.0
git 2.30.2 2.39.2
golang 1.15 1.19
libc 2.31 2.36
linux kernel 5.10 6.1
llvm 11.0 14.0
lxc 4.0.6 5.0.2
mariadb 10.5 10.11
nginx 1.18.0 1.22.1
nodejs 12.22 18.13
openjdk 11.0.18 + 17.0.6 17.0.6
openssh 8.4p1 9.2p1
openssl 1.1.1n 3.0.8-1
perl 5.32.1 5.36.0
php 7.4+76 8.2+93
podman 3.0.1 4.3.1
postfix 3.5.18 3.7.5
postgres 13 15
puppet 5.5.22 7.23.0
python2 2.7.18 (gone!)
python3 3.9.2 3.11.2
qemu/kvm 5.2 7.2
ruby 2.7+2 3.1
rust 1.48.0 1.63.0
samba 4.13.13 4.17.8
systemd 247.3 252.6
unattended-upgrades 2.8 2.9.1
util-linux 2.36.1 2.38.1
vagrant 2.2.14 2.3.4
vim 8.2.2434 9.0.1378
zsh 5.8 5.9
Linux Kernel The bookworm release ships a Linux kernel based on version 6.1, whereas bullseye shipped kernel 5.10. As usual there are plenty of changes in the kernel area, including better hardware support, and this might warrant a separate blog entry, but to highlight some changes: See Kernelnewbies.org for further changes between kernel versions. Configuration management puppet s upstream sadly still doesn t provide packages for bookworm (see PA-4995), though Debian provides puppet-agent and puppetserver packages, and even puppetdb is back again, see release notes for further information. ansible is also available and made it with version 2.14 into bookworm. Prometheus stack Prometheus server was updated from v2.24.1 to v2.42.0 and all the exporters that got shipped with bullseye are still around (in more recent versions of course). Virtualization docker (v20.10.24), ganeti (v3.0.2-3), libvirt (v9.0.0-4), lxc (v5.0.2-1), podman (v4.3.1), openstack (Zed), qemu/kvm (v7.2), xen (v4.17.1) are all still around. Vagrant is available in version 2.3.4, also Vagrant upstream provides their packages for bookworm already. If you re relying on VirtualBox, be aware that upstream doesn t provide packages for bookworm yet (see ticket 21524), but thankfully version 7.0.8-dfsg-2 is available from Debian/unstable (as of 2023-06-10) (VirtualBox isn t shipped with stable releases since quite some time due to lack of cooperation from upstream on security support for older releases, see #794466). rsync rsync was updated from v3.2.3 to v3.2.7, and we got a few new options: OpenSSH OpenSSH was updated from v8.4p1 to v9.2p1, so if you re interested in all the changes, check out the release notes between those version (8.5, 8.6, 8.7, 8.8, 8.9, 9.0, 9.1 + 9.2). Let s highlight some notable new features: One important change you might wanna be aware of is that as of OpenSSH v8.8, RSA signatures using the SHA-1 hash algorithm got disabled by default, but RSA/SHA-256/512 AKA RSA-SHA2 gets used instead. OpenSSH has supported RFC8332 RSA/SHA-256/512 signatures since release 7.2 and existing ssh-rsa keys will automatically use the stronger algorithm where possible. A good overview is also available at SSH: Signature Algorithm ssh-rsa Error. Now tools/libraries not supporting RSA-SHA2 fail to connect to OpenSSH as present in bookworm. For example python3-paramiko v2.7.2-1 as present in bullseye doesn t support RSA-SHA2. It tries to connect using the deprecated RSA-SHA-1, which is no longer offered by default with OpenSSH as present in bookworm, and then fails. Support for RSA/SHA-256/512 signatures in Paramiko was requested e.g. at #1734, and eventually got added to Paramiko and in the end the change made it into Paramiko versions >=2.9.0. Paramiko in bookworm works fine, and a backport by rebuilding the python3-paramiko package from bookworm for bullseye solves the problem (BTDT). Misc unsorted Thanks to everyone involved in the release, happy upgrading to bookworm, and let s continue with working towards Debian/trixie. :)

Petter Reinholdtsen: What did I learn from OpenSnitch this summer?

With yesterdays release of Debian 12 Bookworm, I am happy to know the the interactive application firewall OpenSnitch is available for a wider audience. I have been running it for a few weeks now, and have been surprised about some of the programs connecting to the Internet. Some programs are obviously calling out from my machine, like the NTP network based clock adjusting system and Tor to reach other Tor clients, but others were more dubious. For example, the KDE Window manager try to look up the host name in DNS, for no apparent reason, but if this lookup is blocked the KDE desktop get periodically stuck when I use it. Another surprise was how much Firefox call home directly to mozilla.com, mozilla.net and googleapis.com, to mention a few, when I visit other web pages. This direct connection happen even if I told Firefox to always use a proxy, and the proxy setting is ignored for this traffic. Other surprising connections come from audacity and dirmngr (I do not use Gnome). It took some trial and error to get a good default set of permissions. Without it, I would get popups asking for permissions at any time, also the most inconvenient ones where I am in the middle of a time sensitive gaming session. I suspect some application developers should rethink when then need to use network connections or DNS lookups, and recommend testing OpenSnitch (only apt install opensnitch away in Debian Bookworm) to locate and report any surprising Internet connections on your desktop machine. At the moment the upstream developer and Debian package maintainer is working on making the system more reliable in Debian, by enabling the eBPF kernel module to track processes and connections instead of depending in content in /proc/. This should enter unstable fairly soon. As usual, if you use Bitcoin and want to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

6 June 2023

Shirish Agarwal: Odisha Train Crash and Coverup, Demonetization 2.0 & NHFS-6 Survey

Just a few days back we came to know about the horrific Train Crash that happened in Odisha (Orissa). There are some things that are known and somethings that can be inferred by observance. Sadly, it seems the incident is going to be covered up  . Some of the facts that have not been contested in the public domain are that there were three lines. One loop line on which the Goods Train was standing and there was an up and a down line. So three lines were there. Apparently, the signalling system and the inter-locking system had issues as highlighted by an official about a month back. That letter, thankfully is in the public domain and I have downloaded it as well. It s a letter that goes to 4 pages. The RW is incensed that the letter got leaked and is in public domain. They are blaming everyone and espousing conspiracy theories rather than taking the minister to task. Incidentally, the Minister has three ministries that he currently holds. Ministry of Communication, Ministry of Electronics and Information Technology (MEIT), and Railways Ministry. Each Ministry in itself is important and has revenues of more than 6 lakh crore rupees. How he is able to do justice to all the three ministries is beyond me  The other thing is funds both for safety and relaying of tracks has been either not sanctioned or unutilized. In fact, CAG and the Railway Brass had shared how derailments have increased and unfulfilled vacancies but they were given no importance  In fact, not talking about safety in the recently held Chintan Shivir (brainstorming session) tells you how much the Govt. is serious about safety. In fact, most of the programme was on high speed rail which is a white elephant. I have shared a whitepaper done by RW in the U.S. that tells how high-speed rail doesn t make economic sense. And that is an economy that is 20 times + the Indian Economy. Even the Chinese are stopping with HSR as it doesn t make economic sense. Incidentally, Air Fares again went up 200% yesterday. Somebody shared in the region of 20k + for an Air ticket from their place to Bangalore  Coming back to the story itself. the Goods Train was on the loopline. Some say it was a little bit on the outer, some say otherwise, but it is established that it was on the loopline. This is standard behavior on and around Railway Stations around the world. Whether it was in the Inner or Outer doesn t make much of a difference with what happened next. The first train that collided with the goods train was the 12864 (SMVB-HWH) Yashwantpur Howrah Express and got derailed on to the next track where from the opposite direction 12841 (Shalimar- Bangalore) Coramandel Express was coming. Now they have said that around 300 people have died and that seems to be part of the cover-up. Both the trains are long trains, having between 23 odd coaches each. Even if you have reserved tickets you have 80 odd people in a coach and usually in most of these trains, it is at least double of that. Lot of money goes to TC and then above (Corruption). The Railway fares have gone up enormously but that s a question for perhaps another time  . So at the very least, we could be looking at more than 1000 people having died. The numbers are being under-reported so that nobody has to take responsibility. The Railways itself has told that it is unable to identify 80% of the people who have died. This means that 80% were unreserved ticket holders or a majority of them. There have been disturbing images as how bodies have been flung over on tractors and whatnot to be either buried or cremated without a thought. We are in peak summer season so bodies will start to rot within 24-48 hours  No arrangements made to cool the bodies and take some information and identifying marks or whatever. The whole thing being done in a very callous manner, not giving dignity to even those who have died for no fault of their own. The dissent note also tells that a cover-up is also in the picture. Apparently, India doesn t have nor does it feel to have a need for something like the NTSB that the U.S. used when it hauled both the plane manufacturer (Boeing) and the FAA when the 737 Max went down due to improper data collection and sharing of data with pilots. And with no accountability being fixed to Minister or any of the senior staff, a small junior staff person may be fired. Perhaps the same official that actually told them about the signal failures almost 3 months back  There were and are also some reports that some jugaadu /temporary fixes were applied to signalling and inter-locking just before this incident happened. I do not know nor confirm one way or the other if the above happened. I can however point out that if such a thing happened, then usually a traffic block is announced and all traffic on those lines are stopped. This has been the thing I know for decades. Traveling between Mumbai and Pune multiple times over the years am aware about traffic block. If some repair work was going on and it wasn t able to complete the work within the time-frame then that may well have contributed to the accident. There is also a bit muddying of the waters where it is being said that one of the trains was 4 hours late, which one is conflicting stories. On top of the whole thing, they have put the case to be investigated by CBI and hinting at sabotage. They also tried to paint a religious structure as mosque, later turned out to be a temple. The RW says done by Muslims as it was Friday not taking into account as shared before that most Railway maintenance works are usually done between Friday Monday. This is a practice followed not just in India but world over. There has been also move over a decade to remove wooden sleepers and have concrete sleepers. Unlike the wooden ones they do not expand and contract as much and their life is much more longer than the wooden ones. Funds had been marked (although lower than last few years) but not yet spent. As we know in case of any accident, it is when all the holes in cheese line up it happens. Fukushima is a great example of that, no sea wall even though Japan is no stranger to Tsunamis. External power at the same level as the plant. (10 meters above sea-level), no training for cascading failures scenarios which is what happened. The Days mini-series shares some but not all the faults that happened at Fukushima and the Govt. response to it. There is a difference though, the Japanese Prime Minister resigned on moral grounds. Here, nor the PM, nor the Minister would be resigning on moral grounds or otherwise :(. Zero accountability and that was partly a natural disaster, here it s man-made. In fact, both the Minister and the Prime Minister arrived with their entourages, did a PR blitzkrieg showing how concerned they are. Within 50 hours, the lines were cleared. The part-time Railway Minister shared that he knows the root cause and then few hours later has given the case to CBI. All are saying, wait for the inquiry report. To date, none of the accidents even in this Govt. has produced an investigation report. And even if it did, I am sure it will whitewash as it did in case of Adani as I had shared before in the previous blog post. Incidentally, it is reported that Adani paid off some of its debt, but when questioned as to where they got the money, complete silence on that part :(. As can be seen cover-up after cover-up  FWIW, the Coramandel Express is known as the Migrant train so has a huge number of passengers, the other one which was collided with is known as sick train as huge number of cancer patients use it to travel to Chennai and come back

Demonetization 2.0 Few days back, India announced demonetization 2.0. Surprised, don t be. Apparently, INR 2k/- is being used for corruption and Mr. Modi is unhappy about it. He actually didn t like the INR 2k/- note but was told that it was needed, who told him we are unaware to date. At that time the RBI Governor was Mr. Urjit Patel who didn t say about INR 2k/- he had said that INR 1k/- note redesigned would come in the market. That has yet to happen. What has happened is that just like INR 500/- and INR 1k/- note is concerned, RBI will no longer honor the INR 2k/- note. Obviously, this has made our neighbors angry, namely Nepal, Sri Lanka, Bhutan etc. who do some trading with us. 2 Deccan herald columns share the limelight on it. Apparently, India wants to be the world s currency reserve but doesn t want to play by the rules for everyone else. It was pointed out that both the U.S. and Singapore had retired their currencies but they will honor that promise even today. The Singapore example being a bit closer (as it s in Asia) is perhaps a bit more relevant than the U.S. one. Singapore retired the SGD $10,000 as of 2014 but even in 2022, it remains as legal tender. They also retired the SGD $1,000 in 2020 but still remains legal tender.

So let s have a fictitious example to illustrate what is meant by what Singapore has done. Let s say I go to Singapore, rent a flat, and find a $1000 note in that house somewhere. Both practically and theoretically, I could go down to any of the banks, get the amount transferred to my wallet, bank account etc. and nobody will question. Because they have promised the same. Interestingly, the Singapore Dollar has been pretty resilient against the USD for quite a number of years vis-a-vis other Asian currencies. Most of the INR 2k/- notes were also found and exchanged in Gujarat in just a few days (The PM and HM s state.). I am sure you are looking into the mental gymnastics that the RW indulge in :(. What is sadder that most of the people who try to defend can t make sense one way or the other and start to name-call and get personal as they have nothing else

Disability questions dropped in NHFS-6 Just came to know today that in the upcoming National Family Health Survey-6 disability questions are being dropped. Why is this important. To put it simply, if you don t have numbers, you won t and can t make policies for them. India is one of the worst countries to live if you are disabled. The easiest way to share to draw attention is most Railway platforms are not at level with people. Just as Mick Lynch shares in the UK, the same is pretty much true for India too. Meanwhile in Europe, they do make an effort to be level so even disabled people have some dignity. If your public transport is sorted, then people would want much more and you will be obligated to provide for them as they are citizens. Here, we have had many reports of women being sexually molested when being transferred from platform to coach irrespective of their age or whatnot  The main takeaway is if you do not have their voice, you won t make policies for them. They won t go away but you will make life hell for them. One thing to keep in mind that most people assume that most people are disabled from birth. This may or may not be true. For e.g. in the above triple Railways accidents, there are bound to be disabled people or newly disabled people who were healthy before the accident. The most common accident is road accidents, some involving pedestrians and vehicles or both, the easiest is Ministry of Road Transport data that says 4,00,000 people sustained injuries in 2021 alone in road mishaps. And this is in a country where even accidents are highly under-reported, for more than one reason. The biggest reason especially in 2 and 4 wheeler is the increased premium they would have to pay if in an accident, so they usually compromise with the other and pay off the Traffic Inspector. Sadly, I haven t read a new book, although there are a few books I m looking forward to have. People living in India and neighbors please be careful as more heat waves are expected. Till later.

2 June 2023

Jelmer Vernooij: Porting Python projects to Rust

I ve recently been working on porting some of my Python code to rust, both for performance reasons, and because of the strong typing in the language. As a fan of Haskell, I also just really enjoy using the language. Porting any large project to a new language can be a challenge. There is a temptation to do a rewrite from the ground-up in idiomatic rust and using all new fancy features of the language.
Porting in one go However, this is a bit of a trap:
  • It blocks other work. It can take a long time to finish the rewrite, during which time there is no good place to make other bug fixes/feature changes. If you make the change in the python branch, then you may also have to patch the in-progress rust fork.
  • No immediate return on investment. While the rewrite is happening, all of the investment in it is sunk costs.
  • Throughout the process, you can only run the tests for subsystems that have already been ported. It s common to find subtle bugs later in code ported early.
  • Understanding existing code, porting it and making it idiomatic rust all at the same time takes more time and post-facto debugging.
Iterative porting Instead, we ve found that it works much better to take an iterative approach. One of the hidden gems of rust is the excellent PyO3 crate, which allows creating python bindings for rust code in a way that is several times less verbose and less painful than C or SWIG. Because of rust s strong ownership model, it s also really hard to muck up e.g. reference counts when creating Python bindings for rust code. We port individual functions or classes to rust one at a time, starting with functionality that doesn t have dependencies on other python code and gradually working our way up the call stack. Each subsystem of the code is converted to two matching rust crates: one with a port of the code to pure rust, and one with python bindings for the rust code. Generally multiple python modules end up being a single pair of rust crates. The signature for the pure Rust code follow rust conventions, but the business logic is mostly ported as-is (just in rust syntax) and the signatures of the python bindings match that of the original python code. This then allows running the original python tests to verify that the code still behaves the same way. Changes can also immediately land on the main branch. A subsequent step is usually to refactor the rust code to be more idiomatic - all the while keeping the tests passing. There is also the potential to e.g. switch to using external rust crates (with perhaps subtly different behaviour), or drop functionality altogether. At some point, we will also port the tests from python to rust, and potentially drop the python bindings - once all the caller s have been converted to rust.
Example For example, imagine I have a Python module janitor/mail_filter.py with this function:
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
def parse_plain_text_body(text):
   lines = text.splitlines()
   for i, line in enumerate(lines):
       if line == 'Reply to this email directly or view it on GitHub:':
           return lines[i + 1].split('#')[0]
       if (line == 'For more details, see:'
               and lines[i + 1].startswith('https://code.launchpad.net/')):
           return lines[i + 1]
       try:
           (field, value) = line.split(':', 1)
       except ValueError:
           continue
       if field.lower() == 'merge request url':
           return value.strip()
   return None
Porting this to rust naively (in a crate I ve called mailfilter ) it might look something like this:
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
pub fn parse_plain_text_body(text: &str) -> Option<String>  
     let lines: Vec<&str> = text.lines().collect();
     for (i, line) in lines.iter().enumerate()  
         if line == &"Reply to this email directly or view it on GitHub:"  
             return Some(lines[i + 1].split('#').next().unwrap().to_string());
          
         if line == &"For more details, see:"
             && lines[i + 1].starts_with("https://code.launchpad.net/")
          
             return Some(lines[i + 1].to_string());
          
         if let Some((field, value)) = line.split_once(':')  
             if field.to_lowercase() == "merge request url"  
                 return Some(value.trim().to_string());


     None
  
Bindings are created in a crate called mailfilter-py, which looks like this:
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
use pyo3::prelude::*;
 #[pyfunction]
 fn parse_plain_text_body(text: &str) -> Option<String>  
     janitor_mail_filter::parse_plain_text_body(text)
  
 #[pymodule]
 pub fn _mail_filter(py: Python, m: &PyModule) -> PyResult<()>  
     m.add_function(wrap_pyfunction!(parse_plain_text_body, m)?)?;
     Ok(())
  
The metadata for the crates is what you d expect. mailfilter-py uses PyO3 and depends on mailfilter.
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
[package]
 name = "mailfilter-py"
 version = "0.0.0"
 authors = ["Jelmer Vernoo  <jelmer@jelmer.uk>"]
 edition = "2018"
 [lib]
 crate-type = ["cdylib"]
 [dependencies]
 janitor-mail-filter =   path = "../mailfilter"  
 pyo3 =   version = ">=0.14", features = ["extension-module"] 
I use python-setuptools-rust to get the python ecosystem to build the python bindings. Here is what setup.py looks like:
1
2
3
4
5
6
7
8
9
#!/usr/bin/python3
from setuptools import setup
from setuptools_rust import RustExtension, Binding
setup(
        rust_extensions=[RustExtension(
        "janitor._mailfilter", "crates/mailfilter-py/Cargo.toml",
        binding=Binding.PyO3)],
)
And of course, setuptools-rust needs to be listed as a setup requirement in pyproject.toml or setup.cfg. After that, we can replace the original python code with a simple import and verify that the tests still run:
1
from ._mailfilter import parse_plain_text_body
Of course, not all bindings are as simple as this. Iterators in particular are more complicated, as is code that has a loose idea of ownership in python. But I ve found that the time investment is usually well worth the ability to land changes on the development head early and often. I d be curious to hear if people have had success with other approaches to porting Python code to Rust. If you do, please leave a comment.

Matt Brown: Calling time on DNSSEC: The costs exceed the benefits

I m calling time on DNSSEC. Last week, prompted by a change in my DNS hosting setup, I began removing it from the few personal zones I had signed. Then this Monday the .nz ccTLD experienced a multi-day availability incident triggered by the annual DNSSEC key rotation process. This incident broke several of my unsigned zones, which led me to say very unkind things about DNSSEC on Mastodon and now I feel compelled to more completely explain my thinking: For almost all domains and use-cases, the costs and risks of deploying DNSSEC outweigh the benefits it provides. Don t bother signing your zones. The .nz incident, while topical, is not the motivation or the trigger for this conclusion. Had it been a novel incident, it would still have been annoying, but novel incidents are how we learn so I have a small tolerance for them. The problem with DNSSEC is precisely that this incident was not novel, just the latest in a long and growing list. It s a clear pattern. DNSSEC is complex and risky to deploy. Choosing to sign your zone will almost inevitably mean that you will experience lower availability for your domain over time than if you leave it unsigned. Even if you have a team of DNS experts maintaining your zone and DNS infrastructure, the risk of routine operational tasks triggering a loss of availability (unrelated to any attempted attacks that DNSSEC may thwart) is very high - almost guaranteed to occur. Worse, because of the nature of DNS and DNSSEC these incidents will tend to be prolonged and out of your control to remediate in a timely fashion. The only benefit you get in return for accepting this almost certain reduction in availability is trust in the integrity of the DNS data a subset of your users (those who validate DNSSEC) receive. Trusted DNS data that is then used to communicate across an untrusted network layer. An untrusted network layer which you are almost certainly protecting with TLS which provides a more comprehensive and trustworthy set of security guarantees than DNSSEC is capable of, and provides those guarantees to all your users regardless of whether they are validating DNSSEC or not. In summary, in our modern world where TLS is ubiquitous, DNSSEC provides only a thin layer of redundant protection on top of the comprehensive guarantees provided by TLS, but adds significant operational complexity, cost and a high likelihood of lowered availability. In an ideal world, where the deployment cost of DNSSEC and the risk of DNSSEC-induced outages were both low, it would absolutely be desirable to have that redundancy in our layers of protection. In the real world, given the DNSSEC protocol we have today, the choice to avoid its complexity and rely on TLS alone is not at all painful or risky to make as the operator of an online service. In fact, it s the prudent choice that will result in better overall security outcomes for your users. Ignore DNSSEC and invest the time and resources you would have spent deploying it improving your TLS key and certificate management. Ironically, the one use-case where I think a valid counter-argument for this position can be made is TLDs (including ccTLDs such as .nz). Despite its many failings, DNSSEC is an Internet Standard, and as infrastructure providers, TLDs have an obligation to enable its use. Unfortunately this means that everyone has to bear the costs, complexities and availability risks that DNSSEC burdens these operators with. We can t avoid that fact, but we can avoid creating further costs, complexities and risks by choosing not to deploy DNSSEC on the rest of our non-TLD zones.

But DNSSEC will save us from the evil CA ecosystem! Historically, the strongest motivation for DNSSEC has not been the direct security benefits themselves (which as explained above are minimal compared to what TLS provides), but in the new capabilities and use-cases that could be enabled if DNS were able to provide integrity and trusted data to applications. Specifically, the promise of DNS-based Authentication of Named Entities (DANE) is that with DNSSEC we can be free of the X.509 certificate authority ecosystem and along with it the expensive certificate issuance racket and dubious trust properties that have long been its most distinguishing features. Ten years ago this was an extremely compelling proposition with significant potential to improve the Internet. That potential has gone unfulfilled. Instead of maturing as deployments progressed and associated operational experience was gained, DNSSEC has been beset by the discovery of issue after issue. Each of these has necessitated further changes and additions to the protocol, increasing complexity and deployment cost. For many zones, including significant zones like google.com (where I led the attempt to evaluate and deploy DNSSEC in the mid 2010s), it is simply infeasible to deploy the protocol at all, let alone in a reliable and dependable manner. While DNSSEC maturation and deployment has been languishing, the TLS ecosystem has been steadily and impressively improving. Thanks to the efforts of many individuals and companies, although still founded on the use of a set of root certificate authorities, the TLS and CA ecosystem today features transparency, validation and multi-party accountability that comprehensively build trust in the ability to depend and rely upon the security guarantees that TLS provides. When you use TLS today, you benefit from:
  • Free/cheap issuance from a number of different certificate authorities.
  • Regular, automated issuance/renewal via the ACME protocol.
  • Visibility into who has issued certificates for your domain and when through Certificate Transparency logs.
  • Confidence that certificates issued without certificate transparency (and therefore lacking an SCT) will not be accepted by the leading modern browsers.
  • The use of modern cryptographic protocols as a baseline, with a plausible and compelling story for how these can be steadily and promptly updated over time.
DNSSEC with DANE can match the TLS ecosystem on the first benefit (up front price) and perhaps makes the second benefit moot, but has no ability to match any of the other transparency and accountability measures that today s TLS ecosystem offers. If your ZSK is stolen, or a parent zone is compromised or coerced, validly signed TLSA records for a forged certificate can be produced and spoofed to users under attack with minimal chances of detection. Finally, in terms of overall trust in the roots of the system, the CA/Browser forum requirements continue to improve the accountability and transparency of TLS certificate authorities, significantly reducing the ability for any single actor (say a nefarious government) to subvert the system. The DNS root has a well established transparent multi-party system for establishing trust in the DNSSEC root itself, but at the TLD level, almost intentionally thanks to the hierarchical nature of DNS, DNSSEC has multiple single points of control (or coercion) which exist outside of any formal system of transparency or accountability. We ve moved from DANE being a potential improvement in security over TLS when it was first proposed, to being a definite regression from what TLS provides today. That s not to say that TLS is perfect, but given where we re at, we ll get a better security return from further investment and improvements in the TLS ecosystem than we will from trying to fix DNSSEC.

But TLS is not ubiquitous for non-HTTP applications The arguments above are most compelling when applied to the web-based HTTP-oriented ecosystem which has driven most of the TLS improvements we ve seen to date. Non-HTTP protocols are lagging in adoption of many of the improvements and best practices TLS has on the web. Some claim this need to provide a solution for non-HTTP, non-web applications provides a motivation to continue pushing DNSSEC deployment. I disagree, I think it provides a motivation to instead double-down on moving those applications to TLS. TLS as the new TCP. The problem is that costs of deploying and operating DNSSEC are largely fixed regardless of how many protocols you are intending to protect with it, and worse, the negative side-effects of DNSSEC deployment can and will easily spill over to affect zones and protocols that don t want or need DNSSEC s protection. To justify continued DNSSEC deployment and operation in this context means using a smaller set of benefits (just for the non-HTTP applications) to justify the already high costs of deploying DNSSEC itself, plus the cost of the risk that DNSSEC poses to the reliability to your websites. I don t see how that equation can ever balance, particularly when you evaluate it against the much lower costs of just turning on TLS for the rest of your non-HTTP protocols instead of deploying DNSSEC. MTA-STS is a worked example of how this can be achieved. If you re still not convinced, consider that even DNS itself is considering moving to TLS (via DoT and DoH) in order to add the confidentiality/privacy attributes the protocol currently lacks. I m not a huge fan of the latency implications of these approaches, but the ongoing discussion shows that clever solutions and mitigations for that may exist. DoT/DoH solve distinct problems from DNSSEC and in principle should be used in combination with it, but in a world where DNS itself is relying on TLS and therefore has eliminated the majority of spoofing and cache poisoning attacks through DoT/DoH deployment the benefit side of the DNSSEC equation gets smaller and smaller still while the costs remain the same.

OK, but better software or more careful operations can reduce DNSSEC s cost Some see the current DNSSEC costs simply as teething problems that will reduce as the software and tooling matures to provide more automation of the risky processes and operational teams learn from their mistakes or opt to simply transfer the risk by outsourcing the management and complexity to larger providers to take care of. I don t find these arguments compelling. We ve already had 15+ years to develop improved software for DNSSEC without success. What s changed that we should expect a better outcome this year or next? Nothing. Even if we did have better software or outsourced operations, the approach is still only hiding the costs behind automation or transferring the risk to another organisation. That may appear to work in the short-term, but eventually when the time comes to upgrade the software, migrate between providers or change registrars the debt will come due and incidents will occur. The problem is the complexity of the protocol itself. No amount of software improvement or outsourcing addresses that. After 15+ years of trying, I think it s worth considering that combining cryptography, caching and distributed consensus, some of the most fundamental and complex computer science problems, into a slow-moving and hard to evolve low-level infrastructure protocol while appropriately balancing security, performance and reliability appears to be beyond our collective ability. That doesn t have to be the end of the world, the improvements achieved in the TLS ecosystem over the same time frame provide a positive counter example - perhaps DNSSEC is simply focusing our attention at the wrong layer of the stack. Ideally secure DNS data would be something we could have, but if the complexity of DNSSEC is the price we have to pay to achieve it, I m out. I would rather opt to remain with the simpler yet insecure DNS protocol and compensate for its short comings at higher transport or application layers where experience shows we are able to more rapidly improve and develop our security capabilities.

Summing up For the vast majority of domains and use-cases there is simply no net benefit to deploying DNSSEC in 2023. I d even go so far as to say that if you ve already signed your zones, you should (carefully) move them back to being unsigned - you ll reduce the complexity of your operating environment and lower your risk of availability loss triggered by DNS. Your users will thank you. The threats that DNSSEC defends against are already amply defended by the now mature and still improving TLS ecosystem at the application layer, and investing in further improvements here carries far more return than deployment of DNSSEC. For TLDs, like .nz whose outage triggered this post, DNSSEC is not going anywhere and investment in mitigating its complexities and risks is an unfortunate burden that must be shouldered. While the full incident report of what went wrong with .nz is not yet available, the interim report already hints at some useful insights. It is important that InternetNZ publishes a full and comprehensive review so that the full set of learnings and improvements this incident can provide can be fully realised by .nz and other TLD operators stuck with the unenviable task of trying to safely operate DNSSEC.

Postscript After taking a few days to draft and edit this post, I ve just stumbled across a presentation from the well respected Geoff Huston at last weeks RIPE86 meeting. I ve only had time to skim the slides (video here) - they don t seem to disagree with my thinking regarding the futility of the current state of DNSSEC, but also contain some interesting ideas for what it might take for DNSSEC to become a compelling proposition. Probably worth a read/watch!

31 May 2023

Russ Allbery: Review: Night Watch

Review: Night Watch, by Terry Pratchett
Series: Discworld #29
Publisher: Harper
Copyright: November 2002
Printing: August 2014
ISBN: 0-06-230740-1
Format: Mass market
Pages: 451
Night Watch is the 29th Discworld novel and the sixth Watch novel. I would really like to tell people they could start here if they wanted to, for reasons that I will get into in a moment, but I think I would be doing you a disservice. The emotional heft added by having read the previous Watch novels and followed Vimes's character evolution is significant. It's the 25th of May. Vimes is about to become a father. He and several of the other members of the Watch are wearing sprigs of lilac for reasons that Sergeant Colon is quite vehemently uninterested in explaining. A serial killer named Carcer the Watch has been after for weeks has just murdered an off-duty sergeant. It's a tense and awkward sort of day and Vimes is feeling weird and wistful, remembering the days when he was a copper and not a manager who has to dress up in ceremonial armor and meet with committees. That may be part of why, when the message comes over the clacks that the Watch have Carcer cornered on the roof of the New Hall of the Unseen University, Vimes responds in person. He's grappling with Carcer on the roof of the University Library in the middle of a magical storm when lightning strikes. When he wakes up, he's in the past, shortly after he joined the Watch and shortly before the events of the 25th of May that the older Watch members so vividly remember and don't talk about. I have been saying recently in Discworld reviews that it felt like Pratchett was on the verge of a breakout book that's head and shoulders above Discworld prior to that point. This is it. This is that book. The setup here is masterful: the sprigs of lilac that slowly tell the reader something is going on, the refusal of any of the older Watch members to talk about it, the scene in the graveyard to establish the stakes, the disconcerting fact that Vetinari is wearing a sprig of lilac as well, and the feeling of building tension that matches the growing electrical storm. And Pratchett never gives into the temptation to explain everything and tip his hand prematurely. We know the 25th is coming and something is going to happen, and the reader can put together hints from Vimes's thoughts, but Pratchett lets us guess and sometimes be right and sometimes be wrong. Vimes is trying to change history, which adds another layer of uncertainty and enjoyment as the reader tries to piece together both the true history and the changes. This is a masterful job at a "what if?" story. And, beneath that, the commentary on policing and government and ethics is astonishingly good. In a review of an earlier Watch novel, I compared Pratchett to Dickens in the way that he focuses on a sort of common-sense morality rather than political theory. That is true here too, but oh that moral analysis is sharp enough to slide into you like a knife. This is not the Vimes that we first met in Guards! Guards!. He has has turned his cynical stubbornness into a working theory of policing, and it's subtle and complicated and full of nuance that he only barely knows how to explain. But he knows how to show it to people.
Keep the peace. That was the thing. People often failed to understand what that meant. You'd go to some life-threatening disturbance like a couple of neighbors scrapping in the street over who owned the hedge between their properties, and they'd both be bursting with aggrieved self-righteousness, both yelling, their wives would either be having a private scrap on the side or would have adjourned to a kitchen for a shared pot of tea and a chat, and they all expected you to sort it out. And they could never understand that it wasn't your job. Sorting it out was a job for a good surveyor and a couple of lawyers, maybe. Your job was to quell the impulse to bang their stupid fat heads together, to ignore the affronted speeches of dodgy self-justification, to get them to stop shouting and to get them off the street. Once that had been achieved, your job was over. You weren't some walking god, dispensing finely tuned natural justice. Your job was simply to bring back peace.
When Vimes is thrown back in time, he has to pick up the role of his own mentor, the person who taught him what policing should be like. His younger self is right there, watching everything he does, and he's desperately afraid he'll screw it up and set a worse example. Make history worse when he's trying to make it better. It's a beautifully well-done bit of tension that uses time travel as the hook to show both how difficult mentorship is and also how irritating one's earlier naive self would be.
He wondered if it was at all possible to give this idiot some lessons in basic politics. That was always the dream, wasn't it? "I wish I'd known then what I know now"? But when you got older you found out that you now wasn't you then. You then was a twerp. You then was what you had to be to start out on the rocky road of becoming you now, and one of the rocky patches on that road was being a twerp.
The backdrop of this story, as advertised by the map at the front of the book, is a revolution of sorts. And the revolution does matter, but not in the obvious way. It creates space and circumstance for some other things to happen that are all about the abuse of policing as a tool of politics rather than Vimes's principle of keeping the peace. I mentioned when reviewing Men at Arms that it was an awkward book to read in the United States in 2020. This book tackles the ethics of policing head-on, in exactly the way that book didn't. It's also a marvelous bit of competence porn. Somehow over the years, Vimes has become extremely good at what he does, and not just in the obvious cop-walking-a-beat sort of ways. He's become a leader. It's not something he thinks about, even when thrown back in time, but it's something Pratchett can show the reader directly, and have the other characters in the book comment on. There is so much more that I'd like to say, but so much would be spoilers, and I think Night Watch is more effective when you have the suspense of slowly puzzling out what's going to happen. Pratchett's pacing is exquisite. It's also one of the rare Discworld novels where Pratchett fully commits to a point of view and lets Vimes tell the story. There are a few interludes with other people, but the only other significant protagonist is, quite fittingly, Vetinari. I won't say anything more about that except to note that the relationship between Vimes and Vetinari is one of the best bits of fascinating subtlety in all of Discworld. I think it's also telling that nothing about Night Watch reads as parody. Sure, there is a nod to Back to the Future in the lightning storm, and it's impossible to write a book about police and street revolutions without making the reader think about Les Miserables, but nothing about this plot matches either of those stories. This is Pratchett telling his own story in his own world, unapologetically, and without trying to wedge it into parody shape, and it is so much the better book for it. The one quibble I have with the book is that the bits with the Time Monks don't really work. Lu-Tze is annoying and flippant given the emotional stakes of this story, the interludes with him are frustrating and out of step with the rest of the book, and the time travel hand-waving doesn't add much. I see structurally why Pratchett put this in: it gives Vimes (and the reader) a time frame and a deadline, it establishes some of the ground rules and stakes, and it provides a couple of important opportunities for exposition so that the reader doesn't get lost. But it's not good story. The rest of the book is so amazingly good, though, that it doesn't matter (and the framing stories for "what if?" explorations almost never make much sense). The other thing I have a bit of a quibble with is outside the book. Night Watch, as you may have guessed by now, is the origin of the May 25th Pratchett memes that you will be familiar with if you've spent much time around SFF fandom. But this book is dramatically different from what I was expecting based on the memes. You will, for example see a lot of people posting "Truth, Justice, Freedom, Reasonably Priced Love, And a Hard-Boiled Egg!", and before reading the book it sounds like a Pratchett-style humorous revolutionary slogan. And I guess it is, sort of, but, well... I have to quote the scene:
"You'd like Freedom, Truth, and Justice, wouldn't you, Comrade Sergeant?" said Reg encouragingly. "I'd like a hard-boiled egg," said Vimes, shaking the match out. There was some nervous laughter, but Reg looked offended. "In the circumstances, Sergeant, I think we should set our sights a little higher " "Well, yes, we could," said Vimes, coming down the steps. He glanced at the sheets of papers in front of Reg. The man cared. He really did. And he was serious. He really was. "But...well, Reg, tomorrow the sun will come up again, and I'm pretty sure that whatever happens we won't have found Freedom, and there won't be a whole lot of Justice, and I'm damn sure we won't have found Truth. But it's just possible that I might get a hard-boiled egg."
I think I'm feeling defensive of the heart of this book because it's such an emotional gut punch and says such complicated and nuanced things about politics and ethics (and such deeply cynical things about revolution). But I think if I were to try to represent this story in a meme, it would be the "angels rise up" song, with all the layers of meaning that it gains in this story. I'm still at the point where the lilac sprigs remind me of Sergeant Colon becoming quietly furious at the overstep of someone who wasn't there. There's one other thing I want to say about that scene: I'm not naturally on Vimes's side of this argument. I think it's important to note that Vimes's attitude throughout this book is profoundly, deeply conservative. The hard-boiled egg captures that perfectly: it's a bit of physical comfort, something you can buy or make, something that's part of the day-to-day wheels of the city that Vimes talks about elsewhere in Night Watch. It's a rejection of revolution, something that Vimes does elsewhere far more explicitly. Vimes is a cop. He is in some profound sense a defender of the status quo. He doesn't believe things are going to fundamentally change, and it's not clear he would want them to if they did. And yet. And yet, this is where Pratchett's Dickensian morality comes out. Vimes is a conservative at heart. He's grumpy and cynical and jaded and he doesn't like change. But if you put him in a situation where people are being hurt, he will break every rule and twist every principle to stop it.
He wanted to go home. He wanted it so much that he trembled at the thought. But if the price of that was selling good men to the night, if the price was filling those graves, if the price was not fighting with every trick he knew... then it was too high. It wasn't a decision that he was making, he knew. It was happening far below the areas of the brain that made decisions. It was something built in. There was no universe, anywhere, where a Sam Vimes would give in on this, because if he did then he wouldn't be Sam Vimes any more.
This is truly exceptional stuff. It is the best Discworld novel I have read, by far. I feel like this was the Watch novel that Pratchett was always trying to write, and he had to write five other novels first to figure out how to write it. And maybe to prepare Discworld readers to read it. There are a lot of Discworld novels that are great on their own merits, but also it is 100% worth reading all the Watch novels just so that you can read this book. Followed in publication order by The Wee Free Men and later, thematically, by Thud!. Rating: 10 out of 10

29 May 2023

Louis-Philippe V ronneau: Python 3.11, pip and (breaking) system packages

As we get closer to Debian Bookworm's release, I thought I'd share one change in Python 3.11 that will surely affect many people. Python 3.11 implements the new PEP 668, Marking Python base environments as externally managed 1. If you use pip regularly on Debian, it's likely you'll eventually hit the externally-managed-environment error:
error: externally-managed-environment
  This environment is externally managed
 > To install Python packages system-wide, try apt install
    python3-xyz, where xyz is the package you are trying to
    install.
    If you wish to install a non-Debian-packaged Python package,
    create a virtual environment using python3 -m venv path/to/venv.
    Then use path/to/venv/bin/python and path/to/venv/bin/pip. Make
    sure you have python3-full installed.
    If you wish to install a non-Debian packaged Python application,
    it may be easiest to use pipx install xyz, which will manage a
    virtual environment for you. Make sure you have pipx installed.
    See /usr/share/doc/python3.11/README.venv for more information.
note: If you believe this is a mistake, please contact your Python installation or OS distribution provider. You can override this, at the risk of breaking your Python installation or OS, by passing --break-system-packages.
hint: See PEP 668 for the detailed specification.
With this PEP, Python tools can now distinguish between packages that have been installed by the user with a tool like pip and ones installed using a distribution's package manager, like apt. This is generally great news: it was previously too easy to break a system by mixing the two types of packages. This PEP will simplify our role as a distribution, as well as improve the overall Python user experience in Debian. Sadly, it's also likely this change will break some of your scripts, especially CI that (legitimately) install packages via pip alongside system packages. For example, I use the following gitlab-ci snippet to make sure my PRs don't break my build process2:
build:flit:
  stage: build
  script:
  - apt-get update && apt-get install -y flit python3-pip
  - FLIT_ROOT_INSTALL=1 flit install
  - metalfinder --help
With Python 3.11, this snippet will error out, as pip will refuse to install packages alongside the system's. The fix is to tell pip it's OK to "break" your system packages, either using the --break-system-packages parameter, or the PIP_BREAK_SYSTEM_PACKAGES=1 environment variable3. This, of course, is not something you should be using in production to restore the old behavior! The "proper" way to fix this issue, as the externally-managed-environment error message aptly (har har) informs you, is to use virtual environments. Happy hacking!

  1. Kudos to our own Matthias Klose, Stefano Rivera and Elana Hashman, who worked on designing and implementing this PEP!
  2. Which is something that bit me before... You push some changes to your git repository, everything seems fine and all the tests pass, so you merge it and make a new git tag. When the time comes to build and upload this tag to PyPi, you find out some minor thing broke your build system (which you weren't testing) and you have to scramble to make a point-release to fix the issue. Sad!
  3. Don't go searching for this environment variable in pip's code though, as you won't find it! All of pip's command line options can be passed as env vars using the PIP_<UPPER_LONG_NAME> format. Useful for tools that use pip indirectly, like flit.

25 May 2023

Dirk Eddelbuettel: qlcal 0.0.6 on CRAN: More updates from QuantLib

The sixth release of the still new-ish qlcal package arrivied at CRAN today. qlcal delivers the calendaring parts of QuantLib. It is provided (for the R package) as a set of included files, so the package is self-contained and does not depend on an external QuantLib library (which can be demanding to build). qlcal covers over sixty country / market calendars and can compute holiday lists, its complement (i.e. business day lists) and much more. This release brings updates to a few calendars which happened since the QuantLib 1.30 release, and also updates a several of the (few) non-calendaring functions.

Changes in version 0.0.6 (2023-05-24)
  • Several calendars (India, Singapore, South Africa, South Korea) updated with post-QuantLib 1.3.0 changes (Sebastian Schmidt in #6)
  • Three now-used scheduled files were removed (Dirk in #7))
  • A number of non-calendaring files used were synchronised with the current QuantLib repo (Dirk in #8)

Last release, we also added a quick little demo using xts to column-bind calendars produced from each of the different US sub-calendars. This is a slightly updated version of the sketch we tooted a few days ago. The output now is
> print(Reduce(cbind, Map(makeHol, cals)))
           LiborImpact NYSE GovernmentBond NERC FederalReserve
2023-01-02        TRUE TRUE           TRUE TRUE           TRUE
2023-01-16        TRUE TRUE           TRUE   NA           TRUE
2023-02-20        TRUE TRUE           TRUE   NA           TRUE
2023-04-07          NA TRUE             NA   NA             NA
2023-05-29        TRUE TRUE           TRUE TRUE           TRUE
2023-06-19        TRUE TRUE           TRUE   NA           TRUE
2023-07-04        TRUE TRUE           TRUE TRUE           TRUE
2023-09-04        TRUE TRUE           TRUE TRUE           TRUE
2023-10-09        TRUE   NA           TRUE   NA           TRUE
2023-11-10        TRUE   NA             NA   NA             NA
2023-11-23        TRUE TRUE           TRUE TRUE           TRUE
2023-12-25        TRUE TRUE           TRUE TRUE           TRUE
> 
Courtesy of my CRANberries, there is a diffstat report for this release. See the project page and package documentation for more details, and more examples. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

24 May 2023

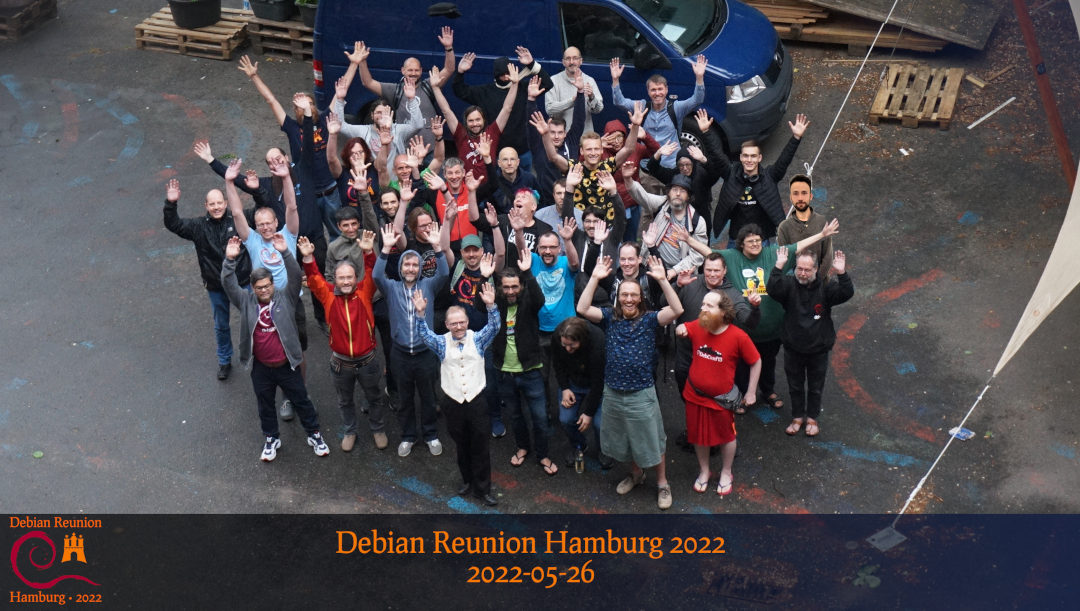
Jonathan Carter: Debian Reunion MiniDebConf 2022

It wouldn t be inaccurate to say that I ve had a lot on my plate in the last few years, and that I have a *huge* backlog of little tasks to finish. Just last week, I finally got to all my keysigning from DebConf22. This week, I m at MiniDebConf Germany in Hamburg. It s the second time I m here! And it s great already. Last year I drafted a blog entry, but never got around to publishing it. So, in order to mentally tick off yet another thing, here follows a somewhat imperfect (I had to delete a lot of short-hand because I didn t know what it means anymore), but at least published post about my activities from a year ago. This week (well, last year) I attended my first ever in-person MiniDebConf and MiniDebCamp in Hamburg, Germany. The last time I was in Germany was 7 years ago for DebConf15 (or at time of publishing, actually, last year for this same event). My focus for the week was to work on Debian live related stuff. In preparation for the week I tried to fix/close as many Calamares bugs as I could, so before the event I closed: Monday to Friday we worked together on various issues, and the weekend was for talks. On Monday morning, I had a nice discussion with Roland Clobus who has been working on making Debian live images reproducible. He s also been working on testing Debian Live on openqa.debian.net. We re planning on integrating his work so that Debian 12 live images will be reproducible. For automated testing on openqa, it will be ongoing work, one blocker has been that snapshots.debian.org limits connections after a while, so builds on there start failing fast.
On Monday afternoon, I went ahead and uploaded the latest Calamares hotfix (Calamares 3.2.58.1-1) release that fixes a UI issue on the partitioning screen where it could get stuck. On 15:00 we had a stand-up meeting where we introduced ourselves and talked a bit about our plans. It was great to see how many people could benefit from each other being there. For example, someone wanting to learn packaging, another wanting to improve packaging documentation, another wanting help with packaging something written in Rust, another wanting to improve Rust packaging in general and lots of overlap when it comes to reproducible builds! I also helped a few people with some of their packaging issues. On Monday evening, someone in videoteam managed to convince me to put together a loopy loop for this MiniDebConf. There s really wasn t enough time to put together something elaborate, but I put something together based on the previous loopy with some experiments that I ve been working on for the upcoming DC22 loopy, and we can use this loop to do a call for content for the DC22 loop. On Tuesday morning had some chats with urbec and Ilu,Tuesday afternoon talked to MIA team about upcoming removals. Did some admin on debian.ch payments for hosting. On Tuesday evening worked on live image stuff (d-i downloader, download module for dmm). On Wednesday morning I slept a bit late, then had to deal with some DPL admin/legal things. Wednesday afternoon, more chats with people. On Thursday: Talked to a bunch more people about a lot of issues, got loopy in a reasonably shape, edited and published the Group photo!
On Friday: prepared my talk slides, learned about Brave (https://github.com/bbc/brave) It initially looked like a great compositor for DebConf video stuff (and possible replacement for OBS, but it turned out it wasn t really maintained upstream). In the evening we had the Cheese and Wine party, where lots of deliciousness was experienced. On Saturday, I learned from Felix s talk that Tensorflow is now in experimental! (and now in 2023 I checked again and that s still the case, although it hasn t made it s way in unstable yet, hopefully that improves over the trixie cycle) I know most of the people who attended quite well, but it was really nice to also see a bunch of new Debianites that I ve only seen online before and to properly put some faces to names. We also had a bunch of enthusiastic new contributors and we did some key signing.

23 May 2023

Craig Small: Devices with cgroup v2

Docker and other container systems by default restrict access to devices on the host. They used to do this with cgroups with the cgroup v1 system, however, the second version of cgroups removed this controller and the man page says:
Cgroup v2 device controller has no interface files and is implemented on top of cgroup BPF.
https://www.kernel.org/doc/Documentation/admin-guide/cgroup-v2.rst
That is just awesome, nothing to see here, go look at the BPF documents if you have cgroup v2. With cgroup v1 if you wanted to know what devices were permitted, you just would cat /sys/fs/cgroup/XX/devices.allow and you were done! The kernel documentation is not very helpful, sure its something in BPF and has something to do with the cgroup BPF specifically, but what does that mean? There doesn t seem to be an easy corresponding method to get the same information. So to see what restrictions a docker container has, we will have to:
  1. Find what cgroup the programs running in the container belong to
  2. Find what is the eBPF program ID that is attached to our container cgroup
  3. Dump the eBPF program to a text file
  4. Try to interpret the eBPF syntax
The last step is by far the most difficult.

Finding a container s cgroup All containers have a short ID and a long ID. When you run the docker ps command, you get the short id. To get the long id you can either use the --no-trunc flag or just guess from the short ID. I usually do the second.
$ docker ps 
CONTAINER ID   IMAGE            COMMAND       CREATED          STATUS          PORTS     NAMES
a3c53d8aaec2   debian:minicom   "/bin/bash"   19 minutes ago   Up 19 minutes             inspiring_shannon
So the short ID is a3c53d8aaec2 and the long ID is a big ugly hex string starting with that. I generally just paste the relevant part in the next step and hit tab. For this container the cgroup is /sys/fs/cgroup/system.slice/docker-a3c53d8aaec23c256124f03d208732484714219c8b5f90dc1c3b4ab00f0b7779.scope/ Notice that the last directory has docker- then the short ID. If you re not sure of the exact path. The /sys/fs/cgroup is the cgroup v2 mount point which can be found with mount -t cgroup2 and then rest is the actual cgroup name. If you know the process running in the container then the cgroup column in ps will show you.
$ ps -o pid,comm,cgroup 140064
    PID COMMAND         CGROUP
 140064 bash            0::/system.slice/docker-a3c53d8aaec23c256124f03d208732484714219c8b5f90dc1c3b4ab00f0b7779.scope
Either way, you will have your cgroup path.

eBPF programs and cgroups Next we will need to get the eBPF program ID that is attached to our recently found cgroup. To do this, we will need to use the bpftool. One thing that threw me for a long time is when the tool talks about a program or a PROG ID they are talking about the eBPF programs, not your processes! With that out of the way, let s find the prog id.
$ sudo bpftool cgroup list /sys/fs/cgroup/system.slice/docker-a3c53d8aaec23c256124f03d208732484714219c8b5f90dc1c3b4ab00f0b7779.scope/
ID       AttachType      AttachFlags     Name
90       cgroup_device   multi
Our cgroup is attached to eBPF prog with ID of 90 and the type of program is cgroup _device.

Dumping the eBPF program Next, we need to get the actual code that is run every time a process running in the cgroup tries to access a device. The program will take some parameters and will return either a 1 for yes you are allowed or a zero for permission denied. Don t use the file option as it dumps the program in binary format. The text version is hard enough to understand.
sudo bpftool prog dump xlated id 90 > myebpf.txt
Congratulations! You now have the eBPF program in a human-readable (?) format.

Interpreting the eBPF program The eBPF format as dumped is not exactly user friendly. It probably helps to first go and look at an example program to see what is going on. You ll see that the program splits type (lower 4 bytes) and access (higher 4 bytes) and then does comparisons on those values. The eBPF has something similar:
   0: (61) r2 = *(u32 *)(r1 +0)
   1: (54) w2 &= 65535
   2: (61) r3 = *(u32 *)(r1 +0)
   3: (74) w3 >>= 16
   4: (61) r4 = *(u32 *)(r1 +4)
   5: (61) r5 = *(u32 *)(r1 +8)
What we find is that once we get past the first few lines filtering the given value that the comparison lines have:
  • r2 is the device type, 1 is block, 2 is character.
  • r3 is the device access, it s used with r1 for comparisons after masking the relevant bits. mknod, read and write are 1,2 and 3 respectively.
  • r4 is the major number
  • r5 is the minor number
For a even pretty simple setup, you are going to have around 60 lines of eBPF code to look at. Luckily, you ll often find the lines for the command options you added will be near the end, which makes it easier. For example:
  63: (55) if r2 != 0x2 goto pc+4
  64: (55) if r4 != 0x64 goto pc+3
  65: (55) if r5 != 0x2a goto pc+2
  66: (b4) w0 = 1
  67: (95) exit
This is a container using the option --device-cgroup-rule='c 100:42 rwm'. It is checking if r2 (device type) is 2 (char) and r4 (major device number) is 0x64 or 100 and r5 (minor device number) is 0x2a or 42. If any of those are not true, move to the next section, otherwise return with 1 (permit). We have all access modes permitted so it doesn t check for it. The previous example has all permissions for our device with id 100:42, what about if we only want write access with the option --device-cgroup-rule='c 100:42 r'. The resulting eBPF is:
  63: (55) if r2 != 0x2 goto pc+7  
  64: (bc) w1 = w3
  65: (54) w1 &= 2
  66: (5d) if r1 != r3 goto pc+4
  67: (55) if r4 != 0x64 goto pc+3
  68: (55) if r5 != 0x2a goto pc+2
  69: (b4) w0 = 1
  70: (95) exit
The code is almost the same but we are checking that w3 only has the second bit set, which is for reading, effectively checking for X==X&2. It s a cautious approach meaning no access still passes but multiple bits set will fail.

The device option docker run allows you to specify files you want to grant access to your containers with the --device flag. This flag actually does two things. The first is to great the device file in the containers /dev directory, effectively doing a mknod command. The second thing is to adjust the eBPF program. If the device file we specified actually did have a major number of 100 and a minor of 42, the eBPF would look exactly like the above snippets.

What about privileged? So we have used the direct cgroup options here, what does the --privileged flag do? This lets the container have full access to all the devices (if the user running the process is allowed). Like the --device flag, it makes the device files as well, but what does the filtering look like? We still have a cgroup but the eBPF program is greatly simplified, here it is in full:
   0: (61) r2 = *(u32 *)(r1 +0)
   1: (54) w2 &= 65535
   2: (61) r3 = *(u32 *)(r1 +0)
   3: (74) w3 >>= 16
   4: (61) r4 = *(u32 *)(r1 +4)
   5: (61) r5 = *(u32 *)(r1 +8)
   6: (b4) w0 = 1
   7: (95) exit
There is the usual setup lines and then, return 1. Everyone is a winner for all devices and access types!

Sergio Durigan Junior: Using WireGuard to host services at home

It s been a while since I had this idea to leverage the power of WireGuard to self-host stuff at home. Even though I pay for a proper server somewhere in the world, there are some services that I don t consider critical to put there, or that I consider too critical to host outside my home.

It s only NATural With today s ISP packages for end users, I find it very annoying the amount of trouble they create when you try to host anything at home. Dynamic IPs, NAT/CGNAT, port-blocking, traffic shapping are only a few examples of methods or limitations that prevent users from making local services reachable in a reliable way from outside.

WireGuard comes to help If you already pay for a VPS or a dedicated server somewhere, why not use its existing infrastructure (and public availability) in your favour? That s what I thought when I started this journey. My initial idea was to use a reverse proxy to redirect external requests to the service running at my home. But how could I make sure that these requests reach my dynamic-IP-behind-a-NAT-behind-another-NAT? Well, let s create a tunnel! WireGuard is the perfect tool for that because of many things: it s stateless, very performant, secure, and requires very little configuration.

Setting up on the server On the server side (i.e., VPS or dedicated server), you will create the first endpoint. Something like the following should do:
[Interface]
PrivateKey = PRIVATE_KEY_HERE
Address = 10.0.0.1/32
ListenPort = 51821
[Peer]
PublicKey = PUBLIC_KEY_HERE
AllowedIps = 10.0.0.2/32
PersistentKeepalive = 10
A few interesting points to note:
  • The Peer section contains information about the home service that will be configured below.
  • I m using PersistentKeepalive because I have a dynamic IP at my home. If you have a static IP, you could get rid of PersistentKeepalive and specify an Endpoint here (don t forget to set a ListenPort below, in the Interface section).
  • Now you have an IP where you can forward requests to. If we re talking about HTTP traffic, Apache and nginx are absolutely capable of doing it. If we re talking about other kind of traffic, you might want to look into other utilities, like HAProxy, Traefik and others.

Setting up at your home At your home, you will configure the peer:
[Interface]
PrivateKey = PRIVATE_KEY_HERE
Address = 10.0.0.2/32
[Peer]
PublicKey = PUBLIC_KEY_HERE
AllowedIps = 10.0.0.1/32
Endpoint = YOUR_SERVER:51821
PersistentKeepalive = 10

A few notes about security I would be remiss if I didn t say anything about security, especially because we re talking about hosting services at home. So, here are a few recommendations:
  • Make sure to put your services in a separate local network. Using VLANs is also a good option.
  • Don t run services on your personal (or work!) computer, even if they ll be running inside a VM.
  • Run a firewall on the WireGuard interface and make sure that you only allow traffic over the required ports.
Have fun!

Russ Allbery: Review: A Half-Built Garden

Review: A Half-Built Garden, by Ruthanna Emrys
Publisher: Tordotcom
Copyright: 2022
ISBN: 1-250-21097-6
Format: Kindle
Pages: 340
The climate apocalypse has happened. Humans woke up to the danger, but a little bit too late. Over one billion people died. But the world on the other side of that apocalypse is not entirely grim. The corporations responsible for so much of the damage have been pushed out of society and isolated on their independent "aislands," traded with only grudgingly for the few commodities the rest of the world has not yet learned how to manufacture without them. Traditional governments have largely collapsed, although they cling to increasingly irrelevant trappings of power. In their place arose the watershed networks: a new way of living with both nature and other humans, built around a mix of anarchic consensus and direct democracy, with conservation and stewardship of the natural environment at its core. Therefore, when the aliens arrive near Bear Island on the Potomac River, they're not detected by powerful telescopes and met by military jets. Instead, their waste sets off water sensors, and they're met by the two women on call for alert duty, carrying a nursing infant and backed by the real-time discussion and consensus technology of the watershed's dandelion network. (Emrys is far from the first person to name something a "dandelion network," so be aware that the usage in this book seems unrelated to the charities or blockchain network.) This is a first contact novel, but it's one that skips over the typical focus of the subgenre. The alien Ringers are completely fluent in English down to subtle nuance of emotion and connotation (supposedly due to observation of our radio and TV signals), have translation devices, and in some cases can make our speech sounds directly. Despite significantly different body shapes, they are immediately comprehensible; differences are limited mostly to family structure, reproduction, and social norms. This is Star Trek first contact, not the type more typical of written science fiction. That feels unrealistic, but it's also obviously an authorial choice to jump directly to the part of the story that Emrys wants to write. The Ringers have come to save humanity. In their experience, technological civilization is inherently incompatible with planets. Technology will destroy the planet, and the planet will in turn destroy the species unless they can escape. They have reached other worlds multiple times before, only to discover that they were too late and everyone is already dead. This is the first time they've arrived in time, and they're eager to help humanity off its dying planet to join them in the Dyson sphere of space habitats they are constructing. Planets, to them, are a nest and a launching pad, something to eventually abandon and break down for spare parts. The small, unexpected wrinkle is that Judy, Carol, and the rest of their watershed network are not interested in leaving Earth. They've finally figured out the most critical pieces of environmental balance. Earth is going to get hotter for a while, but the trend is slowing. What they're doing is working. Humanity would benefit greatly from Ringer technology and the expertise that comes from managing closed habitat ecosystems, but they don't need rescuing. This goes over about as well as a toddler saying that playing in the road is perfectly safe. This is a fantastic hook for a science fiction novel. It does exactly what a great science fiction premise should do: takes current concerns (environmentalism, space boosterism, the debatable primacy of humans as a species, the appropriate role of space colonization, the tension between hopefulness and doomcasting about climate change) and uses the freedom of science fiction to twist them around and come at them from an entirely different angle. The design of the aliens is excellent for this purpose. The Ringers are not one alien species; they are two, evolved on different planets in the same system. The plains dwellers developed space flight first and went to meet the tree dwellers, and while their relationship is not entirely without hierarchy (the plains dwellers clearly lead on most matters), it's extensively symbiotic. They now form mixed families of both species, and have a rich cultural history of stories about first contact, interspecies conflicts and cooperation, and all the perils and misunderstandings that they successfully navigated. It makes their approach to humanity more believable to know that they have done first contact before and are building on a model. Their concern for humanity is credibly sincere. The joining of two species was wildly successful for them and they truly want to add a third. The politics on the human side are satisfyingly complicated. The watershed network may have made first contact, but the US government (in the form of NASA) is close behind, attempting to lean on its widely ignored formal power. The corporations are farther away and therefore slower to arrive, but the alien visitors have a damaged ship and need space to construct a subspace beacon and Asterion is happy to offer a site on one of its New Zealand islands. The corporate representatives are salivating at the chance to escape Earth and its environmental regulation for uncontrolled space construction and a new market of trillions of Ringers. NASA's attitude is more measured, but their representative is easily persuaded that the true future of humanity is in space. The work the watershed networks are doing is difficult, uncertain, and involves a lot of sacrifice, particularly for corporate consumer lifestyles. With such an attractive alien offer on the table, why stay and work so hard for an uncertain future? Maybe the Ringers are right. And then the dandelion networks that the watersheds use as the core of their governance and decision-making system all crash. The setup was great; I was completely invested. The execution was more mixed. There are some things I really liked, some things that I thought were a bit too easy or predictable, and several places where I wish Emrys had dug deeper and provided more detail. I thought the last third of the book fizzled a little, although some of the secondary characters Emrys introduces are delightful and carry the momentum of the story when the politics feel a bit lacking. If you tried to form a mental image of ecofeminist political science fiction with 1970s utopian sensibilities, but updated for the concerns of the 2020s, you would probably come very close to the politics of the watershed networks. There are considerably more breastfeedings and diaper changes than the average SF novel. Two of the primary characters are transgender, but with very different experiences with transition. Pronoun pins are an ubiquitous article of clothing. One of the characters has a prosthetic limb. Another character who becomes important later in the story codes as autistic. None of this felt gratuitous; the characters do come across as obsessed with gender, but in a way that I found believable. The human diversity is well-integrated with the story, shapes the characters, creates practical challenges, and has subtle (and sometimes not so subtle) political ramifications. But, and I say this with love because while these are not quite my people they're closely adjacent to my people, the social politics of this book are a very specific type of white feminist collaborative utopianism. When religion makes an appearance, I was completely unsurprised to find that several of the characters are Jewish. Race never makes a significant appearance at all. It's the sort of book where the throw-away references to other important watershed networks includes African ones, and the characters would doubtless try to be sensitive to racial issues if they came up, but somehow they never do. (If you're wondering if there's polyamory in this book, yes, yes there is, and also I suspect you know exactly what culture I'm talking about.) This is not intended as a criticism, just more of a calibration. All science fiction publishing houses could focus only on this specific political perspective for a year and the results would still be dwarfed by the towering accumulated pile of thoughtless paeans to capitalism. Ecofeminism has a long history in the genre but still doesn't show up in that many books, and we're far from exhausting the space of possibilities for what a consensus-based politics could look like with extensive computer support. But this book has a highly specific point of view, enough so that there won't be many thought-provoking surprises if you're already familiar with this school of political thought. The politics are also very earnest in a way that I admit provoked a bit of eyerolling. Emrys pushes all of the political conflict into the contrasts between the human factions, but I would have liked more internal disagreement within the watershed networks over principles rather than tactics. The degree of ideological agreement within the watershed group felt a bit unrealistic. But, that said, at least politics truly matters and the characters wrestle directly with some tricky questions. I would have liked to see more specifics about the dandelion network and the exact mechanics of the consensus decision process, since that sort of thing is my jam, but we at least get more details than are typical in science fiction. I'll take this over cynical libertarianism any day. Gender plays a huge role in this story, enough so that you should avoid this book if you're not interested in exploring gender conceptions. One of the two alien races is matriarchal and places immense social value on motherhood, and it's culturally expected to bring your children with you for any important negotiation. The watersheds actively embrace this, or at worst find it comfortable to use for their advantage, despite a few hints that the matriarchy of the plains aliens may have a very serious long-term demographic problem. In an interesting twist, it's the mostly-evil corporations that truly challenge gender roles, albeit by turning it into an opportunity to sell more clothing. The Asterion corporate representatives are, as expected, mostly the villains of the plot: flashy, hierarchical, consumerist, greedy, and exploitative. But gender among the corporations is purely a matter of public performance, one of a set of roles that you can put on and off as you choose and signal with clothing. They mostly use neopronouns, change pronouns as frequently as their clothing, and treat any question of body plumbing as intensely private. By comparison, the very 2020 attitudes of the watersheds towards gender felt oddly conservative and essentialist, and the main characters get flustered and annoyed by the ever-fluid corporate gender presentation. I wish Emrys had done more with this. As you can tell, I have a lot of thoughts and a lot of quibbles. Another example: computer security plays an important role in the plot and was sufficiently well-described that I have serious questions about the system architecture and security model of the dandelion networks. But, as with decision-making and gender, the more important takeaway is that Emrys takes enough risks and describes enough interesting ideas that there's a lot of meat here to argue with. That, more than getting everything right, is what a good science fiction novel should do. A Half-Built Garden is written from a very specific political stance that may make it a bit predictable or off-putting, and I thought the tail end of the book had some plot and resolution problems, but arguing with it was one of the more intellectually satisfying science fiction reading experiences I've had recently. You have to be in the right mood, but recommended for when you are. Rating: 7 out of 10

21 May 2023

Russ Allbery: Review: The Stone Canal

Review: The Stone Canal, by Ken MacLeod
Series: Fall Revolution #2
Publisher: Tor
Copyright: 1996
Printing: January 2001
ISBN: 0-8125-6864-8
Format: Mass market
Pages: 339
The Stone Canal is a sort of halfway sequel to The Star Fraction. They both take place in the same universe, but the characters are almost entirely disjoint. Half of The Stone Canal happens (mostly) well before the previous book and the other half happens well after it. This book does contain spoilers for the ending of The Star Fraction if one connects the events of the two books correctly (which was a bit harder than I thought it should be), so I would not read them out of order. At the start of The Stone Canal, Jon Wilde wakes up on New Mars beside the titular canal, in the middle of nowhere, accompanied only by a robot that says it made him. Wilde remembers dying on Earth; this new life is apparently some type of resurrection. It's a long walk to Ship City, the center of civilization of a place the robot tells him is New Mars. In Ship City, an android named Dee Model has escaped from her owner and is hiding in a bar. There, she meets an AI abolitionist named Tamara, who helps her flee out the back and down the canal on a boat when Wilde walks into the bar and immediately recognizes her. The abolitionists provide her protection and legal assistance to argue her case for freedom from her owner, a man named Reid. The third thread of the story, and about half the book, is Jon Wilde's life on Earth, starting in 1975 and leading up to the chaotic wars, political fracturing, and revolutions that formed the background and plot of The Star Fraction. Eventually that story turns into a full-fledged science fiction setting, but not until the last 60 pages of the book. I successfully read two books in a Ken MacLeod series! Sadly, I'm not sure I enjoyed the experience. I commented in my review of The Star Fraction that the appeal for me in MacLeod's writing was his reputation as a writer of political science fiction. Unfortunately that's been a bust. The characters are certainly political, in the sense that they profess to have strong political viewpoints and are usually members of some radical (often Trotskyite) organization. There are libertarian anarchist societies and lots of political conflict. But there is almost no meaningful political discussion in any of these books so far. The politics are all tactical or background, and often seem to be created by authorial fiat. For example, New Mars is a sort of libertarian anarchy that somehow doesn't have corporations or a strongman ruler, even though the history (when we finally learn it) would have naturally given rise to one or the other (and has, in numerous other SF novels with similar plots). There's a half-assed explanation for this towards the end of the book that I didn't find remotely believable. Another part of the book describes the formation of the libertarian microstate in The Star Fraction, but never answers a "why" or "how" question I had in the previous book in a satisfying way. Somehow people stop caring about control or predictability or stability or traditional hierarchy without any significant difficulties except external threats, in situations of chaos and disorder where historically humans turn to anyone promising firm structure. It's common to joke about MacLeod winning multiple libertarian Prometheus Awards for his fiction despite being a Scottish communist. I'm finding that much less surprising now that I've read more of his books. Whether or not he believes in it himself, he's got the cynical libertarian smugness and hand-waving down pat. What his characters do care deeply about is smoking, drinking, and having casual sex. (There's more political fire here around opposition to anti-smoking laws than there is about any of the society-changing political structures that somehow fall into place.) I have no objections to any of those activities from a moral standpoint, but reading about other people doing them is a snoozefest. The flashback scenes sketch out enough imagined history to satisfy some curiosity from the previous book, but they're mostly about the world's least interesting love triangle, involving two completely unlikable men and lots of tedious jealousy and posturing. The characters in The Stone Canal are, in general, a problem. One of those unlikable men is Wilde, the protagonist for most of the book. Not only did I never warm to him, I never figured out what motivates him or what he cares about. He's a supposedly highly political person who seems to engage in politics with all the enthusiasm of someone filling out tax forms, and is entirely uninterested in explaining to the reader any sort of coherent philosophical approach. The most interesting characters in this book are the women (Annette, Dee Model, Tamara, and, very late in the book, Meg), but other than Dee Model they rarely get much focus from the story. By far the best part of this book is the last 60 pages, where MacLeod finally explains the critical bridge events between Wilde's political history on earth and the New Mars society. I thought this was engrossing, fast-moving, and full of interesting ideas (at least for a 1990s book; many of them feel a bit stale now, 25 years later). It was also frustrating, because this was the book I wanted to have been reading for the previous 270 pages, instead of MacLeod playing coy with his invented history or showing us interminable scenes about Wilde's insecure jealousy over his wife. It's also the sort of book where at one point characters (apparently uniformly male as far as one could tell from the text of the book) get assigned sex slaves, and while MacLeod clearly doesn't approve of this, the plot is reminiscent of a Heinlein novel: the protagonist's sex slave becomes a very loyal permanent female companion who seems to have the same upside for the male character in question. This was unfortunately not the book I was hoping for. I did enjoy the last hundred pages, and it's somewhat satisfying to have the history come together after puzzling over what happened for 200 pages. But I found the characters tedious and annoying and the politics weirdly devoid of anything like sociology, philosophy, or political science. There is the core of a decent 1990s AI and singularity novel here, but the technology is now rather dated and a lot of other people have tackled the same idea with fewer irritating ticks. Not recommended, although I'll probably continue to The Cassini Division because the ending was a pretty great hook for another book. Followed by The Cassini Division. Rating: 5 out of 10

15 May 2023

Sven Hoexter: GCP: Private Service Connect Forwarding Rules can not be Updated

PSA for those foolish enough to use Google Cloud and try to use private service connect: If you want to change the serviceAttachment your private service connect forwarding rule points at, you must delete the forwarding rule and create a new one. Updates are not supported. I've done that in the past via terraform, but lately encountered strange errors like this:
Error updating ForwardingRule: googleapi: Error 400: Invalid value for field 'target.target':
'<https://www.googleapis.com/compute/v1/projects/mydumbproject/regions/europe-west1/serviceAttachments/
k8s1-sa-xyz-abc>'. Unexpected resource collection 'serviceAttachments'., invalid
Worked around that with the help of terrraform_data and lifecycle:
resource "terraform_data" "replacement"  
    input = var.gcp_psc_data["target"]
 
resource "google_compute_forwarding_rule" "this"  
    count   = length(var.gcp_psc_data["target"]) > 0 ? 1 : 0
    name    = "$ var.gcp_psc_name -psc"
    region  = var.gcp_region
    project = var.gcp_project
    target                = var.gcp_psc_data["target"]
    load_balancing_scheme = "" # need to override EXTERNAL default when target is a service attachment
    network               = var.gcp_network
    ip_address            = google_compute_address.this.id
    lifecycle  
        replace_triggered_by = [
            terraform_data.replacement
        ]
     
 
See also terraform data for replace_triggered_by.

14 May 2023

C.J. Collier: Early Access: Inserting JSON data to BigQuery from Spark on Dataproc

Hello folks! We recently received a case letting us know that Dataproc 2.1.1 was unable to write to a BigQuery table with a column of type JSON. Although the BigQuery connector for Spark has had support for JSON columns since 0.28.0, the Dataproc images on the 2.1 line still cannot create tables with JSON columns or write to existing tables with JSON columns. The customer has graciously granted permission to share the code we developed to allow this operation. So if you are interested in working with JSON column tables on Dataproc 2.1 please continue reading! Use the following gcloud command to create your single-node dataproc cluster:
IMAGE_VERSION=2.1.1-debian11
REGION=us-west1
ZONE=$ REGION -a
CLUSTER_NAME=pick-a-cluster-name
gcloud dataproc clusters create $ CLUSTER_NAME  \
    --region $ REGION  \
    --zone $ ZONE  \
    --single-node \
    --master-machine-type n1-standard-4 \
    --master-boot-disk-type pd-ssd \
    --master-boot-disk-size 50 \
    --image-version $ IMAGE_VERSION  \
    --max-idle=90m \
    --enable-component-gateway \
    --scopes 'https://www.googleapis.com/auth/cloud-platform'
The following file is the Scala code used to write JSON structured data to a BigQuery table using Spark. The file following this one can be executed from your single-node Dataproc cluster. Main.scala
import org.apache.spark.sql.functions.col
import org.apache.spark.sql.types. Metadata, StringType, StructField, StructType 
import org.apache.spark.sql. Row, SaveMode, SparkSession 
import org.apache.spark.sql.avro
import org.apache.avro.specific
  val env = "x"
  val my_bucket = "cjac-docker-on-yarn"
  val my_table = "dataset.testavro2"
    val spark = env match  
      case "local" =>
        SparkSession
          .builder()
          .config("temporaryGcsBucket", my_bucket)
          .master("local")
          .appName("isssue_115574")
          .getOrCreate()
      case _ =>
        SparkSession
          .builder()
          .config("temporaryGcsBucket", my_bucket)
          .appName("isssue_115574")
          .getOrCreate()
     
  // create DF with some data
  val someData = Seq(
    Row(""" "name":"name1", "age": 10  """, "id1"),
    Row(""" "name":"name2", "age": 20  """, "id2")
  )
  val schema = StructType(
    Seq(
      StructField("user_age", StringType, true),
      StructField("id", StringType, true)
    )
  )
  val avroFileName = s"gs://$ my_bucket /issue_115574/someData.avro"
  
  val someDF = spark.createDataFrame(spark.sparkContext.parallelize(someData), schema)
  someDF.write.format("avro").mode("overwrite").save(avroFileName)
  val avroDF = spark.read.format("avro").load(avroFileName)
  // set metadata
  val dfJSON = avroDF
    .withColumn("user_age_no_metadata", col("user_age"))
    .withMetadata("user_age", Metadata.fromJson(""" "sqlType":"JSON" """))
  dfJSON.show()
  dfJSON.printSchema
  // write to BigQuery
  dfJSON.write.format("bigquery")
    .mode(SaveMode.Overwrite)
    .option("writeMethod", "indirect")
    .option("intermediateFormat", "avro")
    .option("useAvroLogicalTypes", "true")
    .option("table", my_table)
    .save()
repro.sh:
#!/bin/bash
PROJECT_ID=set-yours-here
DATASET_NAME=dataset
TABLE_NAME=testavro2
# We have to remove all of the existing spark bigquery jars from the local
# filesystem, as we will be using the symbols from the
# spark-3.3-bigquery-0.30.0.jar below.  Having existing jar files on the
# local filesystem will result in those symbols having higher precedence
# than the one loaded with the spark-shell.
sudo find /usr -name 'spark*bigquery*jar' -delete
# Remove the table from the bigquery dataset if it exists
bq rm -f -t $PROJECT_ID:$DATASET_NAME.$TABLE_NAME
# Create the table with a JSON type column
bq mk --table $PROJECT_ID:$DATASET_NAME.$TABLE_NAME \
  user_age:JSON,id:STRING,user_age_no_metadata:STRING
# Load the example Main.scala 
spark-shell -i Main.scala \
  --jars /usr/lib/spark/external/spark-avro.jar,gs://spark-lib/bigquery/spark-3.3-bigquery-0.30.0.jar
# Show the table schema when we use  bq mk --table  and then load the avro
bq query --use_legacy_sql=false \
  "SELECT ddl FROM $DATASET_NAME.INFORMATION_SCHEMA.TABLES where table_name='$TABLE_NAME'"
# Remove the table so that we can see that the table is created should it not exist
bq rm -f -t $PROJECT_ID:$DATASET_NAME.$TABLE_NAME
# Dynamically generate a DataFrame, store it to avro, load that avro,
# and write the avro to BigQuery, creating the table if it does not already exist
spark-shell -i Main.scala \
  --jars /usr/lib/spark/external/spark-avro.jar,gs://spark-lib/bigquery/spark-3.3-bigquery-0.30.0.jar
# Show that the table schema does not differ from one created with a bq mk --table
bq query --use_legacy_sql=false \
  "SELECT ddl FROM $DATASET_NAME.INFORMATION_SCHEMA.TABLES where table_name='$TABLE_NAME'"
Google BigQuery has supported JSON data since October of 2022, but until now, it has not been possible, on generally available Dataproc clusters, to interact with these columns using the Spark BigQuery Connector. JSON column type support was introduced in spark-bigquery-connector release 0.28.0.

13 May 2023

Sergio Durigan Junior: Ubuntu debuginfod and source code indexing

You might remember that in my last post about the Ubuntu debuginfod service I talked about wanting to extend it and make it index and serve source code from packages. I m excited to announce that this is now a reality since the Ubuntu Lunar (23.04) release. The feature should work for a lot of packages from the archive, but not all of them. Keep reading to better understand why.

The problem While debugging a package in Ubuntu, one of the first steps you need to take is to install its source code. There are some problems with this:
  • apt-get source required dpkg-dev to be installed, which ends up pulling in a lot of other dependencies.
  • GDB needs to be taught how to find the source code for the package being debugged. This can usually be done by using the dir command, but finding the proper path to be is usually not trivial, and you find yourself having to use more complex commands like set substitute-path, for example.
  • You have to make sure that the version of the source package is the same as the version of the binary package(s) you want to debug.
  • If you want to debug the libraries that the package links against, you will face the same problems described above for each library.
So yeah, not a trivial/pleasant task after all.

The solution Debuginfod can index source code as well as debug symbols. It is smart enough to keep a relationship between the source package and the corresponding binary s Build-ID, which is what GDB will use when making a request for a specific source file. This means that, just like what happens for debug symbol files, the user does not need to keep track of the source package version. While indexing source code, debuginfod will also maintain a record of the relative pathname of each source file. No more fiddling with paths inside the debugger to get things working properly. Last, but not least, if there s a need for a library source file and if it s indexed by debuginfod, then it will get downloaded automatically as well.

but not a perfect one In order to make debuginfod happy when indexing source files, I had to patch dpkg and make it always use -fdebug-prefix-map when compiling stuff. This GCC option is used to remap pathnames inside the DWARF, which is needed because in Debian/Ubuntu we build our packages inside chroots and the build directories end up containing a bunch of random cruft (like /build/ayusd-ASDSEA/something/here). So we need to make sure the path prefix (the /build/ayusd-ASDSEA part) is uniform across all packages, and that s where -fdebug-prefix-map helps. This means that the package must honour dpkg-buildflags during its build process, otherwise the magic flag won t be passed and your DWARF will end up with bogus paths. This should not be a big problem, because most of our packages do honour dpkg-buildflags, and those who don t should be fixed anyway.

especially if you re using LTO Ubuntu enables LTO by default, and unfortunately we are affected by an annoying (and complex) bug that results in those bogus pathnames not being properly remapped. The bug doesn t affect all packages, but if you see GDB having trouble finding a source file whose full path starts without /usr/src/..., that is a good indication that you re being affected by this bug. Hopefully we should see some progress in the following weeks.

Your feedback is important to us If you have any comments, or if you found something strange that looks like a bug in the service, please reach out. You can either send an email to my public inbox (see below) or file a bug against the ubuntu-debuginfod project on Launchpad.

9 May 2023

C.J. Collier: Instructions for installing Proxmox onto the Qotom device

These instructions are for qotom devices Q515P and Q1075GE. You can order one from Amazon or directly from Cherry Ni <export03@qotom.com>. Instructions are for those coming from Windows. Prerequisites: To find your windows network details, run the following command at the command prompt:
netsh interface ip show addresses
Here s my output:
PS C:\Users\cjcol> netsh interface ip show addresses "Wi-Fi"
Configuration for interface "Wi-Fi"
    DHCP enabled:                         Yes
    IP Address:                           172.16.79.53
    Subnet Prefix:                        172.16.79.0/24 (mask 255.255.255.0)
    Default Gateway:                      172.16.79.1
    Gateway Metric:                       0
    InterfaceMetric:                      50
Did you follow the instructions linked above in the prerequisites section? If not, take a moment to do so now.
Open Rufus and select the proxmox iso which you downloaded. You may be warned that Rufus will be acting as dd.
Don t forget to select the USB drive that you want to write the image to. In my example, the device is creatively called NO_LABEL .
You may be warned that re-imaging the USB disk will result in the previous data on the USB disk being lost.
Once the process is complete, the application will indicate that it is complete.
You should now have a USB disk with the Proxmox installer image on it. Place the USB disk into one of the blue, USB-3.0, USB-A slots on the Qotom device so that the system can read the installer image from it at full speed. The Proxmox installer requires a keyboard, video and mouse. Please attach these to the device along with inserting the USB disk you just created. Press the power button on the Qotom device. Press the F11 key repeatedly until you see the AMI BIOS menu. Press F11 a couple more times. You ll be presented with a boot menu. One of the options will launch the Proxmox installer. By trial and error, I found that the correct boot menu option was UEFI OS Once you select the correct option, you will be presented with a menu that looks like this. Select the default option and install. During the install, you will be presented with an option of the block device to install to. I think there s only a single block device in this celeron, but if there are more than one, I prefer the smaller one for the ProxMox OS. I also make a point to limit the size of the root filesystem to 16G. I think it will take up the entire volume group if you don t set a limit. Okay, I ll do another install and select the correct filesystem. If you read this far and want me to add some more screenshots and better instructions, leave a comment.
6 May 2023

Reproducible Builds: Reproducible Builds in April 2023

Welcome to the April 2023 report from the Reproducible Builds project! In these reports we outline the most important things that we have been up to over the past month. And, as always, if you are interested in contributing to the project, please visit our Contribute page on our website.

General news Trisquel is a fully-free operating system building on the work of Ubuntu Linux. This month, Simon Josefsson published an article on his blog titled Trisquel is 42% Reproducible!. Simon wrote:
The absolute number may not be impressive, but what I hope is at least a useful contribution is that there actually is a number on how much of Trisquel is reproducible. Hopefully this will inspire others to help improve the actual metric.
Simon wrote another blog post this month on a new tool to ensure that updates to Linux distribution archive metadata (eg. via apt-get update) will only use files that have been recorded in a globally immutable and tamper-resistant ledger. A similar solution exists for Arch Linux (called pacman-bintrans) which was announced in August 2021 where an archive of all issued signatures is publically accessible.
Joachim Breitner wrote an in-depth blog post on a bootstrap-capable GHC, the primary compiler for the Haskell programming language. As a quick background to what this is trying to solve, in order to generate a fully trustworthy compile chain, trustworthy root binaries are needed and a popular approach to address this problem is called bootstrappable builds where the core idea is to address previously-circular build dependencies by creating a new dependency path using simpler prerequisite versions of software. Joachim takes an somewhat recursive approach to the problem for Haskell, leading to the inadvertently humourous question: Can I turn all of GHC into one module, and compile that? Elsewhere in the world of bootstrapping, Janneke Nieuwenhuizen and Ludovic Court s wrote a blog post on the GNU Guix blog announcing The Full-Source Bootstrap, specifically:
[ ] the third reduction of the Guix bootstrap binaries has now been merged in the main branch of Guix! If you run guix pull today, you get a package graph of more than 22,000 nodes rooted in a 357-byte program something that had never been achieved, to our knowledge, since the birth of Unix.
More info about this change is available on the post itself, including:
The full-source bootstrap was once deemed impossible. Yet, here we are, building the foundations of a GNU/Linux distro entirely from source, a long way towards the ideal that the Guix project has been aiming for from the start. There are still some daunting tasks ahead. For example, what about the Linux kernel? The good news is that the bootstrappable community has grown a lot, from two people six years ago there are now around 100 people in the #bootstrappable IRC channel.

Michael Ablassmeier created a script called pypidiff as they were looking for a way to track differences between packages published on PyPI. According to Micahel, pypidiff uses diffoscope to create reports on the published releases and automatically pushes them to a GitHub repository. This can be seen on the pypi-diff GitHub page (example).
Eleuther AI, a non-profit AI research group, recently unveiled Pythia, a collection of 16 Large Language Model (LLMs) trained on public data in the same order designed specifically to facilitate scientific research. According to a post on MarkTechPost:
Pythia is the only publicly available model suite that includes models that were trained on the same data in the same order [and] all the corresponding data and tools to download and replicate the exact training process are publicly released to facilitate further research.
These properties are intended to allow researchers to understand how gender bias (etc.) can affected by training data and model scale.
Back in February s report we reported on a series of changes to the Sphinx documentation generator that was initiated after attempts to get the alembic Debian package to build reproducibly. Although Chris Lamb was able to identify the source problem and provided a potential patch that might fix it, James Addison has taken the issue in hand, leading to a large amount of activity resulting in a proposed pull request that is waiting to be merged.
WireGuard is a popular Virtual Private Network (VPN) service that aims to be faster, simpler and leaner than other solutions to create secure connections between computing devices. According to a post on the WireGuard developer mailing list, the WireGuard Android app can now be built reproducibly so that its contents can be publicly verified. According to the post by Jason A. Donenfeld, the F-Droid project now does this verification by comparing their build of WireGuard to the build that the WireGuard project publishes. When they match, the new version becomes available. This is very positive news.
Author and public speaker, V. M. Brasseur published a sample chapter from her upcoming book on corporate open source strategy which is the topic of Software Bill of Materials (SBOM):
A software bill of materials (SBOM) is defined as a nested inventory for software, a list of ingredients that make up software components. When you receive a physical delivery of some sort, the bill of materials tells you what s inside the box. Similarly, when you use software created outside of your organisation, the SBOM tells you what s inside that software. The SBOM is a file that declares the software supply chain (SSC) for that specific piece of software. [ ]

Several distributions noticed recent versions of the Linux Kernel are no longer reproducible because the BPF Type Format (BTF) metadata is not generated in a deterministic way. This was discussed on the #reproducible-builds IRC channel, but no solution appears to be in sight for now.

Community news On our mailing list this month: Holger Levsen gave a talk at foss-north 2023 in Gothenburg, Sweden on the topic of Reproducible Builds, the first ten years. Lastly, there were a number of updates to our website, including:
  • Chris Lamb attempted a number of ways to try and fix literal : .lead appearing in the page [ ][ ][ ], made all the Back to who is involved links italics [ ], and corrected the syntax of the _data/sponsors.yml file [ ].
  • Holger Levsen added his recent talk [ ], added Simon Josefsson, Mike Perry and Seth Schoen to the contributors page [ ][ ][ ], reworked the People page a little [ ] [ ], as well as fixed spelling of Arch Linux [ ].
Lastly, Mattia Rizzolo moved some old sponsors to a former section [ ] and Simon Josefsson added Trisquel GNU/Linux. [ ]

Debian
  • Vagrant Cascadian reported on the Debian s build-essential package set, which was inspired by how close we are to making the Debian build-essential set reproducible and how important that set of packages are in general . Vagrant mentioned that: I have some progress, some hope, and I daresay, some fears . [ ]
  • Debian Developer Cyril Brulebois (kibi) filed a bug against snapshot.debian.org after they noticed that there are many missing dinstalls that is to say, the snapshot service is not capturing 100% of all of historical states of the Debian archive. This is relevant to reproducibility because without the availability historical versions, it is becomes impossible to repeat a build at a future date in order to correlate checksums. .
  • 20 reviews of Debian packages were added, 21 were updated and 5 were removed this month adding to our knowledge about identified issues. Chris Lamb added a new build_path_in_line_annotations_added_by_ruby_ragel toolchain issue. [ ]
  • Mattia Rizzolo announced that the data for the stretch archive on tests.reproducible-builds.org has been archived. This matches the archival of stretch within Debian itself. This is of some historical interest, as stretch was the first Debian release regularly tested by the Reproducible Builds project.

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

diffoscope development diffoscope version 241 was uploaded to Debian unstable by Chris Lamb. It included contributions already covered in previous months as well a change by Chris Lamb to add a missing raise statement that was accidentally dropped in a previous commit. [ ]

Testing framework The Reproducible Builds project operates a comprehensive testing framework (available at tests.reproducible-builds.org) in order to check packages and other artifacts for reproducibility. In April, a number of changes were made, including:
  • Holger Levsen:
    • Significant work on a new Documented Jenkins Maintenance (djm) script to support logged maintenance of nodes, etc. [ ][ ][ ][ ][ ][ ]
    • Add the new APT repo url for Jenkins itself with a new signing key. [ ][ ]
    • In the Jenkins shell monitor, allow 40 GiB of files for diffoscope for the Debian experimental distribution as Debian is frozen around the release at the moment. [ ]
    • Updated Arch Linux testing to cleanup leftover files left in /tmp/archlinux-ci/ after three days. [ ][ ][ ]
    • Mark a number of nodes hosted by Oregon State University Open Source Lab (OSUOSL) as online and offline. [ ][ ][ ]
    • Update the node health checks to detect failures to end schroot sessions. [ ]
    • Filter out another duplicate contributor from the contributor statistics. [ ]
  • Mattia Rizzolo:


If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

5 May 2023

Reproducible Builds (diffoscope): diffoscope 242 released

The diffoscope maintainers are pleased to announce the release of diffoscope version 242. This version includes the following changes:
* If the binwalk Python module is not available, ensure the user knows they
  may be missing more differences in, for example, concatenated .cpio
  archives.
* Factor out routine to generate a human-readable comments when
  Python modules are missing.
You find out more by visiting the project homepage.

Next.

Previous.