Search Results: "reg"

13 April 2024

Simon Josefsson: Reproducible and minimal source-only tarballs

With the release of Libntlm version 1.8 the release tarball can be reproduced on several distributions. We also publish a signed minimal source-only tarball, produced by git-archive which is the same format used by Savannah, Codeberg, GitLab, GitHub and others. Reproducibility of both tarballs are tested continuously for regressions on GitLab through a CI/CD pipeline. If that wasn t enough to excite you, the Debian packages of Libntlm are now built from the reproducible minimal source-only tarball. The resulting binaries are reproducible on several architectures. What does that even mean? Why should you care? How you can do the same for your project? What are the open issues? Read on, dear reader This article describes my practical experiments with reproducible release artifacts, following up on my earlier thoughts that lead to discussion on Fosstodon and a patch by Janneke Nieuwenhuizen to make Guix tarballs reproducible that inspired me to some practical work. Let s look at how a maintainer release some software, and how a user can reproduce the released artifacts from the source code. Libntlm provides a shared library written in C and uses GNU Make, GNU Autoconf, GNU Automake, GNU Libtool and gnulib for build management, but these ideas should apply to most project and build system. The following illustrate the steps a maintainer would take to prepare a release:
git clone https://gitlab.com/gsasl/libntlm.git
cd libntlm
git checkout v1.8
./bootstrap
./configure
make distcheck
gpg -b libntlm-1.8.tar.gz
The generated files libntlm-1.8.tar.gz and libntlm-1.8.tar.gz.sig are published, and users download and use them. This is how the GNU project have been doing releases since the late 1980 s. That is a testament to how successful this pattern has been! These tarballs contain source code and some generated files, typically shell scripts generated by autoconf, makefile templates generated by automake, documentation in formats like Info, HTML, or PDF. Rarely do they contain binary object code, but historically that happened. The XZUtils incident illustrate that tarballs with files that are not included in the git archive offer an opportunity to disguise malicious backdoors. I blogged earlier how to mitigate this risk by using signed minimal source-only tarballs. The risk of hiding malware is not the only motivation to publish signed minimal source-only tarballs. With pre-generated content in tarballs, there is a risk that GNU/Linux distributions such as Trisquel, Guix, Debian/Ubuntu or Fedora ship generated files coming from the tarball into the binary *.deb or *.rpm package file. Typically the person packaging the upstream project never realized that some installed artifacts was not re-built through a typical autoconf -fi && ./configure && make install sequence, and never wrote the code to rebuild everything. This can also happen if the build rules are written but are buggy, shipping the old artifact. When a security problem is found, this can lead to time-consuming situations, as it may be that patching the relevant source code and rebuilding the package is not sufficient: the vulnerable generated object from the tarball would be shipped into the binary package instead of a rebuilt artifact. For architecture-specific binaries this rarely happens, since object code is usually not included in tarballs although for 10+ years I shipped the binary Java JAR file in the GNU Libidn release tarball, until I stopped shipping it. For interpreted languages and especially for generated content such as HTML, PDF, shell scripts this happens more than you would like. Publishing minimal source-only tarballs enable easier auditing of a project s code, to avoid the need to read through all generated files looking for malicious content. I have taken care to generate the source-only minimal tarball using git-archive. This is the same format that GitLab, GitHub etc offer for the automated download links on git tags. The minimal source-only tarballs can thus serve as a way to audit GitLab and GitHub download material! Consider if/when hosting sites like GitLab or GitHub has a security incident that cause generated tarballs to include a backdoor that is not present in the git repository. If people rely on the tag download artifact without verifying the maintainer PGP signature using GnuPG, this can lead to similar backdoor scenarios that we had for XZUtils but originated with the hosting provider instead of the release manager. This is even more concerning, since this attack can be mounted for some selected IP address that you want to target and not on everyone, thereby making it harder to discover. With all that discussion and rationale out of the way, let s return to the release process. I have added another step here:
make srcdist
gpg -b libntlm-1.8-src.tar.gz
Now the release is ready. I publish these four files in the Libntlm s Savannah Download area, but they can be uploaded to a GitLab/GitHub release area as well. These are the SHA256 checksums I got after building the tarballs on my Trisquel 11 aramo laptop:
91de864224913b9493c7a6cec2890e6eded3610d34c3d983132823de348ec2ca  libntlm-1.8-src.tar.gz
ce6569a47a21173ba69c990965f73eb82d9a093eb871f935ab64ee13df47fda1  libntlm-1.8.tar.gz
So how can you reproduce my artifacts? Here is how to reproduce them in a Ubuntu 22.04 container:
podman run -it --rm ubuntu:22.04
apt-get update
apt-get install -y --no-install-recommends autoconf automake libtool make git ca-certificates
git clone https://gitlab.com/gsasl/libntlm.git
cd libntlm
git checkout v1.8
./bootstrap
./configure
make dist srcdist
sha256sum libntlm-*.tar.gz
You should see the exact same SHA256 checksum values. Hooray! This works because Trisquel 11 and Ubuntu 22.04 uses the same version of git, autoconf, automake, and libtool. These tools do not guarantee the same output content for all versions, similar to how GNU GCC does not generate the same binary output for all versions. So there is still some delicate version pairing needed. Ideally, the artifacts should be possible to reproduce from the release artifacts themselves, and not only directly from git. It is possible to reproduce the full tarball in a AlmaLinux 8 container replace almalinux:8 with rockylinux:8 if you prefer RockyLinux:
podman run -it --rm almalinux:8
dnf update -y
dnf install -y make wget gcc
wget https://download.savannah.nongnu.org/releases/libntlm/libntlm-1.8.tar.gz
tar xfa libntlm-1.8.tar.gz
cd libntlm-1.8
./configure
make dist
sha256sum libntlm-1.8.tar.gz
The source-only minimal tarball can be regenerated on Debian 11:
podman run -it --rm debian:11
apt-get update
apt-get install -y --no-install-recommends make git ca-certificates
git clone https://gitlab.com/gsasl/libntlm.git
cd libntlm
git checkout v1.8
make -f cfg.mk srcdist
sha256sum libntlm-1.8-src.tar.gz 
As the Magnus Opus or chef-d uvre, let s recreate the full tarball directly from the minimal source-only tarball on Trisquel 11 replace docker.io/kpengboy/trisquel:11.0 with ubuntu:22.04 if you prefer.
podman run -it --rm docker.io/kpengboy/trisquel:11.0
apt-get update
apt-get install -y --no-install-recommends autoconf automake libtool make wget git ca-certificates
wget https://download.savannah.nongnu.org/releases/libntlm/libntlm-1.8-src.tar.gz
tar xfa libntlm-1.8-src.tar.gz
cd libntlm-v1.8
./bootstrap
./configure
make dist
sha256sum libntlm-1.8.tar.gz
Yay! You should now have great confidence in that the release artifacts correspond to what s in version control and also to what the maintainer intended to release. Your remaining job is to audit the source code for vulnerabilities, including the source code of the dependencies used in the build. You no longer have to worry about auditing the release artifacts. I find it somewhat amusing that the build infrastructure for Libntlm is now in a significantly better place than the code itself. Libntlm is written in old C style with plenty of string manipulation and uses broken cryptographic algorithms such as MD4 and single-DES. Remember folks: solving supply chain security issues has no bearing on what kind of code you eventually run. A clean gun can still shoot you in the foot. Side note on naming: GitLab exports tarballs with pathnames libntlm-v1.8/ (i.e.., PROJECT-TAG/) and I ve adopted the same pathnames, which means my libntlm-1.8-src.tar.gz tarballs are bit-by-bit identical to GitLab s exports and you can verify this with tools like diffoscope. GitLab name the tarball libntlm-v1.8.tar.gz (i.e., PROJECT-TAG.ARCHIVE) which I find too similar to the libntlm-1.8.tar.gz that we also publish. GitHub uses the same git archive style, but unfortunately they have logic that removes the v in the pathname so you will get a tarball with pathname libntlm-1.8/ instead of libntlm-v1.8/ that GitLab and I use. The content of the tarball is bit-by-bit identical, but the pathname and archive differs. Codeberg (running Forgejo) uses another approach: the tarball is called libntlm-v1.8.tar.gz (after the tag) just like GitLab, but the pathname inside the archive is libntlm/, otherwise the produced archive is bit-by-bit identical including timestamps. Savannah s CGIT interface uses archive name libntlm-1.8.tar.gz with pathname libntlm-1.8/, but otherwise file content is identical. Savannah s GitWeb interface provides snapshot links that are named after the git commit (e.g., libntlm-a812c2ca.tar.gz with libntlm-a812c2ca/) and I cannot find any tag-based download links at all. Overall, we are so close to get SHA256 checksum to match, but fail on pathname within the archive. I ve chosen to be compatible with GitLab regarding the content of tarballs but not on archive naming. From a simplicity point of view, it would be nice if everyone used PROJECT-TAG.ARCHIVE for the archive filename and PROJECT-TAG/ for the pathname within the archive. This aspect will probably need more discussion. Side note on git archive output: It seems different versions of git archive produce different results for the same repository. The version of git in Debian 11, Trisquel 11 and Ubuntu 22.04 behave the same. The version of git in Debian 12, AlmaLinux/RockyLinux 8/9, Alpine, ArchLinux, macOS homebrew, and upcoming Ubuntu 24.04 behave in another way. Hopefully this will not change that often, but this would invalidate reproducibility of these tarballs in the future, forcing you to use an old git release to reproduce the source-only tarball. Alas, GitLab and most other sites appears to be using modern git so the download tarballs from them would not match my tarballs even though the content would. Side note on ChangeLog: ChangeLog files were traditionally manually curated files with version history for a package. In recent years, several projects moved to dynamically generate them from git history (using tools like git2cl or gitlog-to-changelog). This has consequences for reproducibility of tarballs: you need to have the entire git history available! The gitlog-to-changelog tool also output different outputs depending on the time zone of the person using it, which arguable is a simple bug that can be fixed. However this entire approach is incompatible with rebuilding the full tarball from the minimal source-only tarball. It seems Libntlm s ChangeLog file died on the surgery table here. So how would a distribution build these minimal source-only tarballs? I happen to help on the libntlm package in Debian. It has historically used the generated tarballs as the source code to build from. This means that code coming from gnulib is vendored in the tarball. When a security problem is discovered in gnulib code, the security team needs to patch all packages that include that vendored code and rebuild them, instead of merely patching the gnulib package and rebuild all packages that rely on that particular code. To change this, the Debian libntlm package needs to Build-Depends on Debian s gnulib package. But there was one problem: similar to most projects that use gnulib, Libntlm depend on a particular git commit of gnulib, and Debian only ship one commit. There is no coordination about which commit to use. I have adopted gnulib in Debian, and add a git bundle to the *_all.deb binary package so that projects that rely on gnulib can pick whatever commit they need. This allow an no-network GNULIB_URL and GNULIB_REVISION approach when running Libntlm s ./bootstrap with the Debian gnulib package installed. Otherwise libntlm would pick up whatever latest version of gnulib that Debian happened to have in the gnulib package, which is not what the Libntlm maintainer intended to be used, and can lead to all sorts of version mismatches (and consequently security problems) over time. Libntlm in Debian is developed and tested on Salsa and there is continuous integration testing of it as well, thanks to the Salsa CI team. Side note on git bundles: unfortunately there appears to be no reproducible way to export a git repository into one or more files. So one unfortunate consequence of all this work is that the gnulib *.orig.tar.gz tarball in Debian is not reproducible any more. I have tried to get Git bundles to be reproducible but I never got it to work see my notes in gnulib s debian/README.source on this aspect. Of course, source tarball reproducibility has nothing to do with binary reproducibility of gnulib in Debian itself, fortunately. One open question is how to deal with the increased build dependencies that is triggered by this approach. Some people are surprised by this but I don t see how to get around it: if you depend on source code for tools in another package to build your package, it is a bad idea to hide that dependency. We ve done it for a long time through vendored code in non-minimal tarballs. Libntlm isn t the most critical project from a bootstrapping perspective, so adding git and gnulib as Build-Depends to it will probably be fine. However, consider if this pattern was used for other packages that uses gnulib such as coreutils, gzip, tar, bison etc (all are using gnulib) then they would all Build-Depends on git and gnulib. Cross-building those packages for a new architecture will therefor require git on that architecture first, which gets circular quick. The dependency on gnulib is real so I don t see that going away, and gnulib is a Architecture:all package. However, the dependency on git is merely a consequence of how the Debian gnulib package chose to make all gnulib git commits available to projects: through a git bundle. There are other ways to do this that doesn t require the git tool to extract the necessary files, but none that I found practical ideas welcome! Finally some brief notes on how this was implemented. Enabling bootstrappable source-only minimal tarballs via gnulib s ./bootstrap is achieved by using the GNULIB_REVISION mechanism, locking down the gnulib commit used. I have always disliked git submodules because they add extra steps and has complicated interaction with CI/CD. The reason why I gave up git submodules now is because the particular commit to use is not recorded in the git archive output when git submodules is used. So the particular gnulib commit has to be mentioned explicitly in some source code that goes into the git archive tarball. Colin Watson added the GNULIB_REVISION approach to ./bootstrap back in 2018, and now it no longer made sense to continue to use a gnulib git submodule. One alternative is to use ./bootstrap with --gnulib-srcdir or --gnulib-refdir if there is some practical problem with the GNULIB_URL towards a git bundle the GNULIB_REVISION in bootstrap.conf. The srcdist make rule is simple:
git archive --prefix=libntlm-v1.8/ -o libntlm-1.8-src.tar.gz HEAD
Making the make dist generated tarball reproducible can be more complicated, however for Libntlm it was sufficient to make sure the modification times of all files were set deterministically to the timestamp of the last commit in the git repository. Interestingly there seems to be a couple of different ways to accomplish this, Guix doesn t support minimal source-only tarballs but rely on a .tarball-timestamp file inside the tarball. Paul Eggert explained what TZDB is using some time ago. The approach I m using now is fairly similar to the one I suggested over a year ago. If there are problems because all files in the tarball now use the same modification time, there is a solution by Bruno Haible that could be implemented. Side note on git tags: Some people may wonder why not verify a signed git tag instead of verifying a signed tarball of the git archive. Currently most git repositories uses SHA-1 for git commit identities, but SHA-1 is not a secure hash function. While current SHA-1 attacks can be detected and mitigated, there are fundamental doubts that a git SHA-1 commit identity uniquely refers to the same content that was intended. Verifying a git tag will never offer the same assurance, since a git tag can be moved or re-signed at any time. Verifying a git commit is better but then we need to trust SHA-1. Migrating git to SHA-256 would resolve this aspect, but most hosting sites such as GitLab and GitHub does not support this yet. There are other advantages to using signed tarballs instead of signed git commits or git tags as well, e.g., tar.gz can be a deterministically reproducible persistent stable offline storage format but .git sub-directory trees or git bundles do not offer this property. Doing continous testing of all this is critical to make sure things don t regress. Libntlm s pipeline definition now produce the generated libntlm-*.tar.gz tarballs and a checksum as a build artifact. Then I added the 000-reproducability job which compares the checksums and fails on mismatches. You can read its delicate output in the job for the v1.8 release. Right now we insists that builds on Trisquel 11 match Ubuntu 22.04, that PureOS 10 builds match Debian 11 builds, that AlmaLinux 8 builds match RockyLinux 8 builds, and AlmaLinux 9 builds match RockyLinux 9 builds. As you can see in pipeline job output, not all platforms lead to the same tarballs, but hopefully this state can be improved over time. There is also partial reproducibility, where the full tarball is reproducible across two distributions but not the minimal tarball, or vice versa. If this way of working plays out well, I hope to implement it in other projects too. What do you think? Happy Hacking!

12 April 2024

Freexian Collaborators: Debian Contributions: SSO Authentication for jitsi.debian.social, /usr-move updates, and more! (by Utkarsh Gupta)

Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services. P.S. We ve completed over a year of writing these blogs. If you have any suggestions on how to make them better or what you d like us to cover, or any other opinions/reviews you might have, et al, please let us know by dropping an email to us. We d be happy to hear your thoughts. :)

SSO Authentication for jitsi.debian.social, by Stefano Rivera Debian.social s jitsi instance has been getting some abuse by (non-Debian) people sharing sexually explicit content on the service. After playing whack-a-mole with this for a month, and shutting the instance off for another month, we opened it up again and the abuse immediately re-started. Stefano sat down and wrote an SSO Implementation that hooks into Jitsi s existing JWT SSO support. This requires everyone using jitsi.debian.social to have a Salsa account. With only a little bit of effort, we could change this in future, to only require an account to open a room, and allow guests to join the call.

/usr-move, by Helmut Grohne The biggest task this month was sending mitigation patches for all of the /usr-move issues arising from package renames due to the 2038 transition. As a result, we can now say that every affected package in unstable can either be converted with dh-sequence-movetousr or has an open bug report. The package set relevant to debootstrap except for the set that has to be uploaded concurrently has been moved to /usr and is awaiting migration. The move of coreutils happened to affect piuparts which hard codes the location of /bin/sync and received multiple updates as a result.

Miscellaneous contributions
  • Stefano Rivera uploaded a stable release update to python3.11 for bookworm, fixing a use-after-free crash.
  • Stefano uploaded a new version of python-html2text, and updated python3-defaults to build with it.
  • In support of Python 3.12, Stefano dropped distutils as a Build-Dependency from a few packages, and uploaded a complex set of patches to python-mitogen.
  • Stefano landed some merge requests to clean up dead code in dh-python, removed the flit plugin, and uploaded it.
  • Stefano uploaded new upstream versions of twisted, hatchling, python-flexmock, python-authlib, python mitogen, python-pipx, and xonsh.
  • Stefano requested removal of a few packages supporting the Opsis HDMI2USB hardware that DebConf Video team used to use for HDMI capture, as they are not being maintained upstream. They started to FTBFS, with recent sdcc changes.
  • DebConf 24 is getting ready to open registration, Stefano spent some time fixing bugs in the website, caused by infrastructure updates.
  • Stefano reviewed all the DebConf 23 travel reimbursements, filing requests for more information from SPI where our records mismatched.
  • Stefano spun up a Wafer website for the Berlin 2024 mini DebConf.
  • Roberto C. S nchez worked on facilitating the transfer of upstream maintenance responsibility for the dormant Shorewall project to a new team led by the current maintainer of the Shorewall packages in Debian.
  • Colin Watson fixed build failures in celery-haystack-ng, db1-compat, jsonpickle, libsdl-perl, kali, knews, openssh-ssh1, python-json-log-formatter, python-typing-extensions, trn4, vigor, and wcwidth. Some of these were related to the 64-bit time_t transition, since that involved enabling -Werror=implicit-function-declaration.
  • Colin fixed an off-by-one error in neovim, which was already causing a build failure in Ubuntu and would eventually have caused a build failure in Debian with stricter toolchain settings.
  • Colin added an sshd@.service template to openssh to help newer systemd versions make containers and VMs SSH-accessible over AF_VSOCK sockets.
  • Following the xz-utils backdoor, Colin spent some time testing and discussing OpenSSH upstream s proposed inline systemd notification patch, since the current implementation via libsystemd was part of the attack vector used by that backdoor.
  • Utkarsh reviewed and sponsored some Go packages for Lena Voytek and Rajudev.
  • Utkarsh also helped Mitchell Dzurick with the adoption of pyparted package.
  • Helmut sent 10 patches for cross build failures.
  • Helmut partially fixed architecture cross bootstrap tooling to deal with changes in linux-libc-dev and the recent gcc-for-host changes and also fixed a 64bit-time_t FTBFS in libtextwrap.
  • Thorsten Alteholz uploaded several packages from debian-printing: cjet, lprng, rlpr and epson-inkjet-printer-escpr were affected by the newly enabled compiler switch -Werror=implicit-function-declaration. Besides fixing these serious bugs, Thorsten also worked on other bugs and could fix one or the other.
  • Carles updated simplemonitor and python-ring-doorbell packages with new upstream versions.
  • Santiago is still working on the Salsa CI MRs to adapt the build jobs so they can rely on sbuild. Current work includes adapting the images used by the build job, implementing the basic sbuild support the related jobs, and adjusting the support for experimental and *-backports releases..
    Additionally, Santiago reviewed some MR such as Make timeout action explicit in the logs and the subsequent Implement conditional timeout verbosity, and the batch of MRs included in https://salsa.debian.org/salsa-ci-team/pipeline/-/merge_requests/482.
  • Santiago also reviewed applications for the improving Salsa CI in Debian GSoC 2024 project. We received applications from four very talented candidates. The selection process is currently ongoing. A huge thanks to all of them!
  • As part of the DebConf 24 organization, Santiago has taken part in the Content team discussions.

11 April 2024

Reproducible Builds: Reproducible Builds in March 2024

Welcome to the March 2024 report from the Reproducible Builds project! In our reports, we attempt to outline what we have been up to over the past month, as well as mentioning some of the important things happening more generally in software supply-chain security. As ever, if you are interested in contributing to the project, please visit our Contribute page on our website. Table of contents:
  1. Arch Linux minimal container userland now 100% reproducible
  2. Validating Debian s build infrastructure after the XZ backdoor
  3. Making Fedora Linux (more) reproducible
  4. Increasing Trust in the Open Source Supply Chain with Reproducible Builds and Functional Package Management
  5. Software and source code identification with GNU Guix and reproducible builds
  6. Two new Rust-based tools for post-processing determinism
  7. Distribution work
  8. Mailing list highlights
  9. Website updates
  10. Delta chat clients now reproducible
  11. diffoscope updates
  12. Upstream patches
  13. Reproducibility testing framework

Arch Linux minimal container userland now 100% reproducible In remarkable news, Reproducible builds developer kpcyrd reported that that the Arch Linux minimal container userland is now 100% reproducible after work by developers dvzv and Foxboron on the one remaining package. This represents a real world , widely-used Linux distribution being reproducible. Their post, which kpcyrd suffixed with the question now what? , continues on to outline some potential next steps, including validating whether the container image itself could be reproduced bit-for-bit. The post, which was itself a followup for an Arch Linux update earlier in the month, generated a significant number of replies.

Validating Debian s build infrastructure after the XZ backdoor From our mailing list this month, Vagrant Cascadian wrote about being asked about trying to perform concrete reproducibility checks for recent Debian security updates, in an attempt to gain some confidence about Debian s build infrastructure given that they performed builds in environments running the high-profile XZ vulnerability. Vagrant reports (with some caveats):
So far, I have not found any reproducibility issues; everything I tested I was able to get to build bit-for-bit identical with what is in the Debian archive.
That is to say, reproducibility testing permitted Vagrant and Debian to claim with some confidence that builds performed when this vulnerable version of XZ was installed were not interfered with.

Making Fedora Linux (more) reproducible In March, Davide Cavalca gave a talk at the 2024 Southern California Linux Expo (aka SCALE 21x) about the ongoing effort to make the Fedora Linux distribution reproducible. Documented in more detail on Fedora s website, the talk touched on topics such as the specifics of implementing reproducible builds in Fedora, the challenges encountered, the current status and what s coming next. (YouTube video)

Increasing Trust in the Open Source Supply Chain with Reproducible Builds and Functional Package Management Julien Malka published a brief but interesting paper in the HAL open archive on Increasing Trust in the Open Source Supply Chain with Reproducible Builds and Functional Package Management:
Functional package managers (FPMs) and reproducible builds (R-B) are technologies and methodologies that are conceptually very different from the traditional software deployment model, and that have promising properties for software supply chain security. This thesis aims to evaluate the impact of FPMs and R-B on the security of the software supply chain and propose improvements to the FPM model to further improve trust in the open source supply chain. PDF
Julien s paper poses a number of research questions on how the model of distributions such as GNU Guix and NixOS can be leveraged to further improve the safety of the software supply chain , etc.

Software and source code identification with GNU Guix and reproducible builds In a long line of commendably detailed blog posts, Ludovic Court s, Maxim Cournoyer, Jan Nieuwenhuizen and Simon Tournier have together published two interesting posts on the GNU Guix blog this month. In early March, Ludovic Court s, Maxim Cournoyer, Jan Nieuwenhuizen and Simon Tournier wrote about software and source code identification and how that might be performed using Guix, rhetorically posing the questions: What does it take to identify software ? How can we tell what software is running on a machine to determine, for example, what security vulnerabilities might affect it? Later in the month, Ludovic Court s wrote a solo post describing adventures on the quest for long-term reproducible deployment. Ludovic s post touches on GNU Guix s aim to support time travel , the ability to reliably (and reproducibly) revert to an earlier point in time, employing the iconic image of Harold Lloyd hanging off the clock in Safety Last! (1925) to poetically illustrate both the slapstick nature of current modern technology and the gymnastics required to navigate hazards of our own making.

Two new Rust-based tools for post-processing determinism Zbigniew J drzejewski-Szmek announced add-determinism, a work-in-progress reimplementation of the Reproducible Builds project s own strip-nondeterminism tool in the Rust programming language, intended to be used as a post-processor in RPM-based distributions such as Fedora In addition, Yossi Kreinin published a blog post titled refix: fast, debuggable, reproducible builds that describes a tool that post-processes binaries in such a way that they are still debuggable with gdb, etc.. Yossi post details the motivation and techniques behind the (fast) performance of the tool.

Distribution work In Debian this month, since the testing framework no longer varies the build path, James Addison performed a bulk downgrade of the bug severity for issues filed with a level of normal to a new level of wishlist. In addition, 28 reviews of Debian packages were added, 38 were updated and 23 were removed this month adding to ever-growing knowledge about identified issues. As part of this effort, a number of issue types were updated, including Chris Lamb adding a new ocaml_include_directories toolchain issue [ ] and James Addison adding a new filesystem_order_in_java_jar_manifest_mf_include_resource issue [ ] and updating the random_uuid_in_notebooks_generated_by_nbsphinx to reference a relevant discussion thread [ ]. In addition, Roland Clobus posted his 24th status update of reproducible Debian ISO images. Roland highlights that the images for Debian unstable often cannot be generated due to changes in that distribution related to the 64-bit time_t transition. Lastly, Bernhard M. Wiedemann posted another monthly update for his reproducibility work in openSUSE.

Mailing list highlights Elsewhere on our mailing list this month:

Website updates There were made a number of improvements to our website this month, including:
  • Pol Dellaiera noticed the frequent need to correctly cite the website itself in academic work. To facilitate easier citation across multiple formats, Pol contributed a Citation File Format (CIF) file. As a result, an export in BibTeX format is now available in the Academic Publications section. Pol encourages community contributions to further refine the CITATION.cff file. Pol also added an substantial new section to the buy in page documenting the role of Software Bill of Materials (SBOMs) and ephemeral development environments. [ ][ ]
  • Bernhard M. Wiedemann added a new commandments page to the documentation [ ][ ] and fixed some incorrect YAML elsewhere on the site [ ].
  • Chris Lamb add three recent academic papers to the publications page of the website. [ ]
  • Mattia Rizzolo and Holger Levsen collaborated to add Infomaniak as a sponsor of amd64 virtual machines. [ ][ ][ ]
  • Roland Clobus updated the stable outputs page, dropping version numbers from Python documentation pages [ ] and noting that Python s set data structure is also affected by the PYTHONHASHSEED functionality. [ ]

Delta chat clients now reproducible Delta Chat, an open source messaging application that can work over email, announced this month that the Rust-based core library underlying Delta chat application is now reproducible.

diffoscope diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made a number of changes such as uploading versions 259, 260 and 261 to Debian and made the following additional changes:
  • New features:
    • Add support for the zipdetails tool from the Perl distribution. Thanks to Fay Stegerman and Larry Doolittle et al. for the pointer and thread about this tool. [ ]
  • Bug fixes:
    • Don t identify Redis database dumps as GNU R database files based simply on their filename. [ ]
    • Add a missing call to File.recognizes so we actually perform the filename check for GNU R data files. [ ]
    • Don t crash if we encounter an .rdb file without an equivalent .rdx file. (#1066991)
    • Correctly check for 7z being available and not lz4 when testing 7z. [ ]
    • Prevent a traceback when comparing a contentful .pyc file with an empty one. [ ]
  • Testsuite improvements:
    • Fix .epub tests after supporting the new zipdetails tool. [ ]
    • Don t use parenthesis within test skipping messages, as PyTest adds its own parenthesis. [ ]
    • Factor out Python version checking in test_zip.py. [ ]
    • Skip some Zip-related tests under Python 3.10.14, as a potential regression may have been backported to the 3.10.x series. [ ]
    • Actually test 7z support in the test_7z set of tests, not the lz4 functionality. (Closes: reproducible-builds/diffoscope#359). [ ]
In addition, Fay Stegerman updated diffoscope s monkey patch for supporting the unusual Mozilla ZIP file format after Python s zipfile module changed to detect potentially insecure overlapping entries within .zip files. (#362) Chris Lamb also updated the trydiffoscope command line client, dropping a build-dependency on the deprecated python3-distutils package to fix Debian bug #1065988 [ ], taking a moment to also refresh the packaging to the latest Debian standards [ ]. Finally, Vagrant Cascadian submitted an update for diffoscope version 260 in GNU Guix. [ ]

Upstream patches This month, we wrote a large number of patches, including: Bernhard M. Wiedemann used reproducibility-tooling to detect and fix packages that added changes in their %check section, thus failing when built with the --no-checks option. Only half of all openSUSE packages were tested so far, but a large number of bugs were filed, including ones against caddy, exiv2, gnome-disk-utility, grisbi, gsl, itinerary, kosmindoormap, libQuotient, med-tools, plasma6-disks, pspp, python-pypuppetdb, python-urlextract, rsync, vagrant-libvirt and xsimd. Similarly, Jean-Pierre De Jesus DIAZ employed reproducible builds techniques in order to test a proposed refactor of the ath9k-htc-firmware package. As the change produced bit-for-bit identical binaries to the previously shipped pre-built binaries:
I don t have the hardware to test this firmware, but the build produces the same hashes for the firmware so it s safe to say that the firmware should keep working.

Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In March, an enormous number of changes were made by Holger Levsen:
  • Debian-related changes:
    • Sleep less after a so-called 404 package state has occurred. [ ]
    • Schedule package builds more often. [ ][ ]
    • Regenerate all our HTML indexes every hour, but only every 12h for the released suites. [ ]
    • Create and update unstable and experimental base systems on armhf again. [ ][ ]
    • Don t reschedule so many depwait packages due to the current size of the i386 architecture queue. [ ]
    • Redefine our scheduling thresholds and amounts. [ ]
    • Schedule untested packages with a higher priority, otherwise slow architectures cannot keep up with the experimental distribution growing. [ ]
    • Only create the stats_buildinfo.png graph once per day. [ ][ ]
    • Reproducible Debian dashboard: refactoring, update several more static stats only every 12h. [ ]
    • Document how to use systemctl with new systemd-based services. [ ]
    • Temporarily disable armhf and i386 continuous integration tests in order to get some stability back. [ ]
    • Use the deb.debian.org CDN everywhere. [ ]
    • Remove the rsyslog logging facility on bookworm systems. [ ]
    • Add zst to the list of packages which are false-positive diskspace issues. [ ]
    • Detect failures to bootstrap Debian base systems. [ ]
  • Arch Linux-related changes:
    • Temporarily disable builds because the pacman package manager is broken. [ ][ ]
    • Split reproducible_html_live_status and split the scheduling timing . [ ][ ][ ]
    • Improve handling when database is locked. [ ][ ]
  • Misc changes:
    • Show failed services that require manual cleanup. [ ][ ]
    • Integrate two new Infomaniak nodes. [ ][ ][ ][ ]
    • Improve IRC notifications for artifacts. [ ]
    • Run diffoscope in different systemd slices. [ ]
    • Run the node health check more often, as it can now repair some issues. [ ][ ]
    • Also include the string Bot in the userAgent for Git. (Re: #929013). [ ]
    • Document increased tmpfs size on our OUSL nodes. [ ]
    • Disable memory account for the reproducible_build service. [ ][ ]
    • Allow 10 times as many open files for the Jenkins service. [ ]
    • Set OOMPolicy=continue and OOMScoreAdjust=-1000 for both the Jenkins and the reproducible_build service. [ ]
Mattia Rizzolo also made the following changes:
  • Debian-related changes:
    • Define a systemd slice to group all relevant services. [ ][ ]
    • Add a bunch of quotes in scripts to assuage the shellcheck tool. [ ]
    • Add stats on how many packages have been built today so far. [ ]
    • Instruct systemd-run to handle diffoscope s exit codes specially. [ ]
    • Prefer the pgrep tool over grepping the output of ps. [ ]
    • Re-enable a couple of i386 and armhf architecture builders. [ ][ ]
    • Fix some stylistic issues flagged by the Python flake8 tool. [ ]
    • Cease scheduling Debian unstable and experimental on the armhf architecture due to the time_t transition. [ ]
    • Start a few more i386 & armhf workers. [ ][ ][ ]
    • Temporarly skip pbuilder updates in the unstable distribution, but only on the armhf architecture. [ ]
  • Other changes:
    • Perform some large-scale refactoring on how the systemd service operates. [ ][ ]
    • Move the list of workers into a separate file so it s accessible to a number of scripts. [ ]
    • Refactor the powercycle_x86_nodes.py script to use the new IONOS API and its new Python bindings. [ ]
    • Also fix nph-logwatch after the worker changes. [ ]
    • Do not install the stunnel tool anymore, it shouldn t be needed by anything anymore. [ ]
    • Move temporary directories related to Arch Linux into a single directory for clarity. [ ]
    • Update the arm64 architecture host keys. [ ]
    • Use a common Postfix configuration. [ ]
The following changes were also made by:
  • Jan-Benedict Glaw:
    • Initial work to clean up a messy NetBSD-related script. [ ][ ]
  • Roland Clobus:
    • Show the installer log if the installer fails to build. [ ]
    • Avoid the minus character (i.e. -) in a variable in order to allow for tags in openQA. [ ]
    • Update the schedule of Debian live image builds. [ ]
  • Vagrant Cascadian:
    • Maintenance on the virt* nodes is completed so bring them back online. [ ]
    • Use the fully qualified domain name in configuration. [ ]
Node maintenance was also performed by Holger Levsen, Mattia Rizzolo [ ][ ] and Vagrant Cascadian [ ][ ][ ][ ]

If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Russell Coker: ML Training License

Last year a Debian Developer blogged about writing Haskell code to give a bad result for LLMs that were trained on it. I forgot who wrote the post and I d appreciate the URL if anyone has it. I respect such technical work to enforce one s legal rights when they aren t respected by corporations, but I have a different approach. As an aside the Fosdem lecture Fortify AI against regulation, litigation and lobotomies is interesting on this topic [1], it s what inspired me to write about this. For what I write I am at this time happy to allow it to be used as part of a large training data set (consider this blog post a licence grant that applies until such time as I edit this post to change it). But only if aggregated with so much other data that my content is only a tiny portion of the data set by any metric. So I don t want someone to make a programming LLM that has my code as the only C code or a political data set that has my blog posts as the only left-wing content. If someone wants to train an LLM on only my content to make a Russell-simulator then I don t license my work for that purpose but also as it s small enough that anyone with a bit of skill could do it on a weekend I can t stop it. I would be really interested in seeing the results if someone from the FOSS community wanted to make a Russell-simulator and would probably issue them a license for such work if asked. If my work comprises more than 0.1% of the content in a particular measure (theme, programming language, political position, etc) in a training data set then I don t permit that without prior discussion. Finally if someone wants to make a FOSS training data set to be used for FOSS LLM systems (maybe under the AGPL or some similar license) then I ll allow my writing to be used as part of that.

9 April 2024

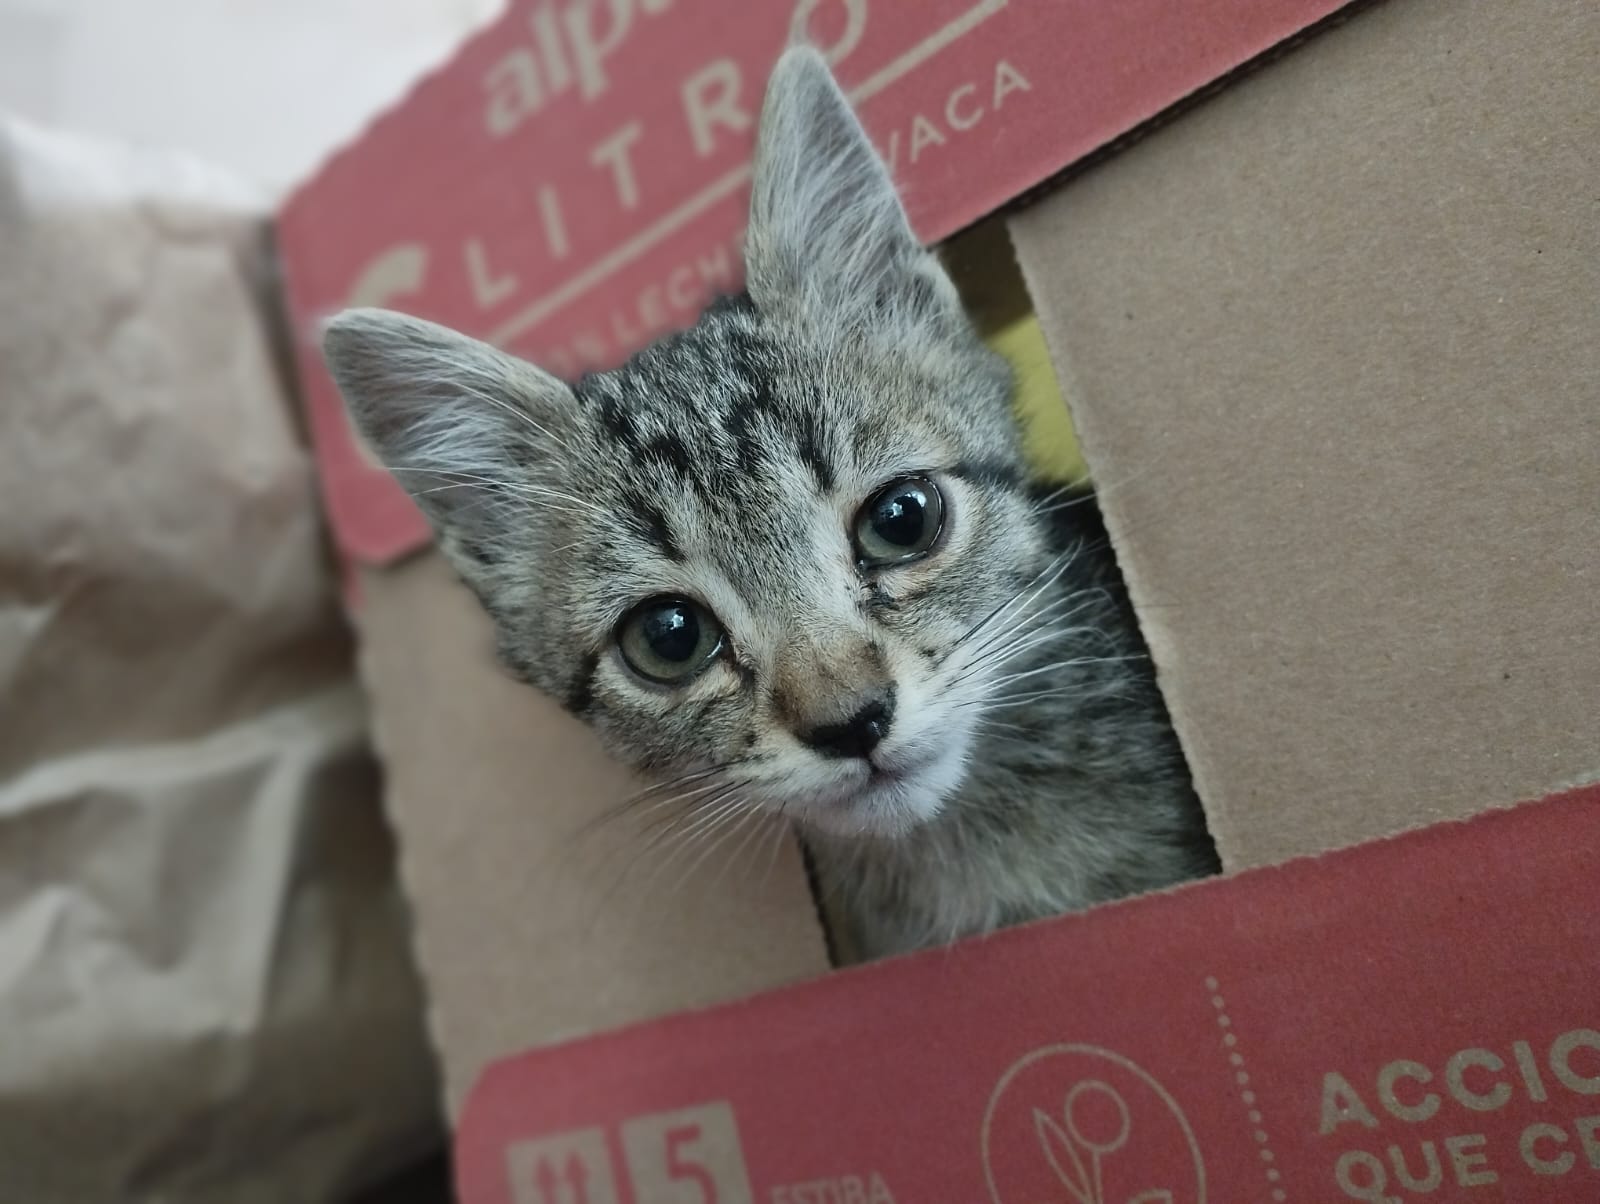
Gunnar Wolf: Think outside the box Welcome Eclipse!

Now that we are back from our six month period in Argentina, we decided to adopt a kitten, to bring more diversity into our lives. Perhaps this little girl will teach us to think outside the box! Yesterday we witnessed a solar eclipse Mexico City was not in the totality range (we reached ~80%), but it was a great experience to go with the kids. A couple dozen thousand people gathered for a massive picnic in las islas, the main area inside our university campus. Afterwards, we went briefly back home, then crossed the city to fetch the little kitten. Of course, the kids were unanimous: Her name is Eclipse.
5 April 2024

Dirk Eddelbuettel: RcppArmadillo 0.12.8.2.0 on CRAN: Upstream Fix

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1136 other packages on CRAN, downloaded 33.5 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 578 times according to Google Scholar. This release brings a new upstream bugfix release Armadillo 12.8.2 prepared by Conrad two days ago. It took the usual day to noodle over 1100+ reverse dependencies and ensure two failures were independent of the upgrade (i.e., no change to worse in CRAN parlance). It took CRAN another because we hit a random network outage for (spurious) NOTE on a remote URL, and were then caught in the shrapnel from another large package ecosystem update spuriously pointing some build failures that were due to a missing rebuild to us. All good, as human intervention comes to the rescue. The set of changes since the last CRAN release follows.

Changes in RcppArmadillo version 0.12.8.2.0 (2024-04-02)
  • Upgraded to Armadillo release 12.8.2 (Cortisol Injector)
    • Workaround for FFTW3 header clash
    • Workaround in testing framework for issue under macOS
    • Minor cleanups to reduce code bloat
    • Improved documentation

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

4 April 2024

John Goerzen: The xz Issue Isn t About Open Source

You ve probably heard of the recent backdoor in xz. There have been a lot of takes on this, most of them boiling down to some version of:
The problem here is with Open Source Software.
I want to say not only is that view so myopic that it pushes towards the incorrect, but also it blinds us to more serious problems. Now, I don t pretend that there are no problems in the FLOSS community. There have been various pieces written about what this issue says about the FLOSS community (usually without actionable solutions). I m not here to say those pieces are wrong. Just that there s a bigger picture. So with this xz issue, it may well be a state actor (aka spy ) that added this malicious code to xz. We also know that proprietary software and systems can be vulnerable. For instance, a Twitter whistleblower revealed that Twitter employed Indian and Chinese spies, some knowingly. A recent report pointed to security lapses at Microsoft, including preventable lapses in security. According to the Wikipedia article on the SolarWinds attack, it was facilitated by various kinds of carelessness, including passwords being posted to Github and weak default passwords. They directly distributed malware-infested updates, encouraged customers to disable anti-malware tools when installing SolarWinds products, and so forth. It would be naive indeed to assume that there aren t black hat actors among the legions of programmers employed by companies that outsource work to low-cost countries some of which have challenges with bribery. So, given all this, we can t really say the problem is Open Source. Maybe it s more broad:
The problem here is with software.
Maybe that inches us closer, but is it really accurate? We have all heard of Boeing s recent issues, which seem to have some element of root causes in corporate carelessness, cost-cutting, and outsourcing. That sounds rather similar to the SolarWinds issue, doesn t it?
Well then, the problem is capitalism.
Maybe it has a role to play, but isn t it a little too easy to just say capitalism and throw up our hands helplessly, just as some do with FLOSS as at the start of this article? After all, capitalism also brought us plenty of products of very high quality over the years. When we can point to successful, non-careless products and I own some of them (for instance, my Framework laptop). We clearly haven t reached the root cause yet. And besides, what would you replace it with? All the major alternatives that have been tried have even stronger downsides. Maybe you replace it with better regulated capitalism , but that s still capitalism.
Then the problem must be with consumers.
As this argument would go, it s consumers buying patterns that drive problems. Buyers individual and corporate seek flashy features and low cost, prizing those over quality and security. No doubt this is true in a lot of cases. Maybe greed or status-conscious societies foster it: Temu promises people to shop like a billionaire , and unloads on them cheap junk, which all but guarantees that shipments from Temu containing products made with forced labor are entering the United States on a regular basis . But consumers are also people, and some fraction of them are quite capable of writing fantastic software, and in fact, do so. So what we need is some way to seize control. Some way to do what is right, despite the pressures of consumers or corporations. Ah yes, dear reader, you have been slogging through all these paragraphs and now realize I have been leading you to this:
Then the solution is Open Source.
Indeed. Faults and all, FLOSS is the most successful movement I know where people are bringing us back to the commons: working and volunteering for the common good, unleashing a thousand creative variants on a theme, iterating in every direction imaginable. We have FLOSS being vital parts of everything from $30 Raspberry Pis to space missions. It is bringing education and communication to impoverished parts of the world. It lets everyone write and release software. And, unlike the SolarWinds and Twitter issues, it exposes both clever solutions and security flaws to the world. If an authentication process in Windows got slower, we would all shrug and mutter Microsoft under our breath. Because, really, what else can we do? We have no agency with Windows. If an authentication process in Linux gets slower, anybody that s interested anybody at all can dive in and ask why and trace it down to root causes. Some look at this and say FLOSS is responsible for this mess. I look at it and say, this would be so much worse if it wasn t FLOSS and experience backs me up on this. FLOSS doesn t prevent security issues itself. What it does do is give capabilities to us all. The ability to investigate. Ability to fix. Yes, even the ability to break and its cousin, the power to learn. And, most rewarding, the ability to contribute.

Lukas M rdian: Netplan v1.0 paves the way to stable, declarative network management

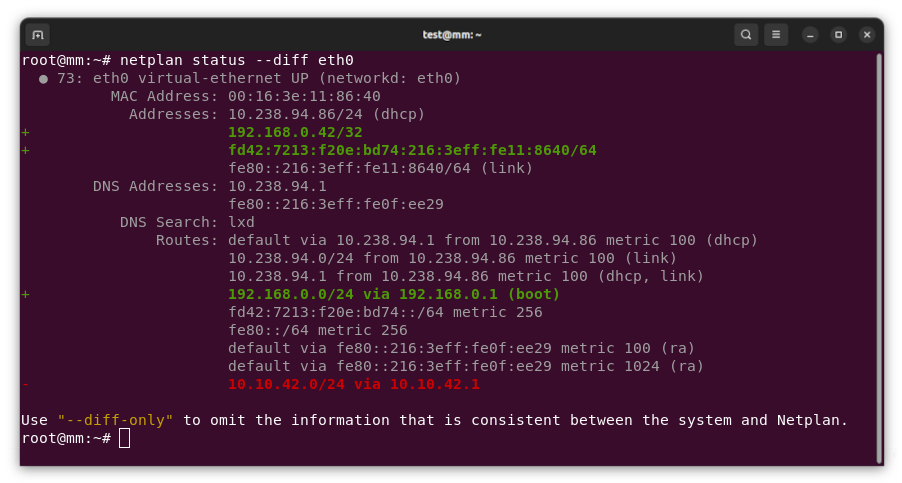
New netplan status diff subcommand, finding differences between configuration and system state As the maintainer and lead developer for Netplan, I m proud to announce the general availability of Netplan v1.0 after more than 7 years of development efforts. Over the years, we ve so far had about 80 individual contributors from around the globe. This includes many contributions from our Netplan core-team at Canonical, but also from other big corporations such as Microsoft or Deutsche Telekom. Those contributions, along with the many we receive from our community of individual contributors, solidify Netplan as a healthy and trusted open source project. In an effort to make Netplan even more dependable, we started shipping upstream patch releases, such as 0.106.1 and 0.107.1, which make it easier to integrate fixes into our users custom workflows. With the release of version 1.0 we primarily focused on stability. However, being a major version upgrade, it allowed us to drop some long-standing legacy code from the libnetplan1 library. Removing this technical debt increases the maintainability of Netplan s codebase going forward. The upcoming Ubuntu 24.04 LTS and Debian 13 releases will ship Netplan v1.0 to millions of users worldwide.

Highlights of version 1.0 In addition to stability and maintainability improvements, it s worth looking at some of the new features that were included in the latest release:
  • Simultaneous WPA2 & WPA3 support.
  • Introduction of a stable libnetplan1 API.
  • Mellanox VF-LAG support for high performance SR-IOV networking.
  • New hairpin and port-mac-learning settings, useful for VXLAN tunnels with FRRouting.
  • New netplan status diff subcommand, finding differences between configuration and system state.
Besides those highlights of the v1.0 release, I d also like to shed some light on new functionality that was integrated within the past two years for those upgrading from the previous Ubuntu 22.04 LTS which used Netplan v0.104:
  • We added support for the management of new network interface types, such as veth, dummy, VXLAN, VRF or InfiniBand (IPoIB).
  • Wireless functionality was improved by integrating Netplan with NetworkManager on desktop systems, adding support for WPA3 and adding the notion of a regulatory-domain, to choose proper frequencies for specific regions.
  • To improve maintainability, we moved to Meson as Netplan s buildsystem, added upstream CI coverage for multiple Linux distributions and integrations (such as Debian testing, NetworkManager, snapd or cloud-init), checks for ABI compatibility, and automatic memory leak detection.
  • We increased consistency between the supported backend renderers (systemd-networkd and NetworkManager), by matching physical network interfaces on permanent MAC address, when the match.macaddress setting is being used, and added new hardware offloading functionality for high performance networking, such as Single-Root IO Virtualisation virtual function link-aggregation (SR-IOV VF-LAG).
The much improved Netplan documentation, that is now hosted on Read the Docs , and new command line subcommands, such as netplan status, make Netplan a well vested tool for declarative network management and troubleshooting.

Integrations Those changes pave the way to integrate Netplan in 3rd party projects, such as system installers or cloud deployment methods. By shipping the new python3-netplan Python bindings to libnetplan, it is now easier than ever to access Netplan functionality and network validation from other projects. We are proud that the Debian Cloud Team chose Netplan to be the default network management tool in their official cloud-images for Debian Bookworm and beyond. Ubuntu s NetworkManager package now uses Netplan as it s default backend on Ubuntu 23.10 Desktop systems and beyond. Further integrations happened with cloud-init and the Calamares installer.
Please check out the Netplan version 1.0 release on GitHub! If you want to learn more, follow our activities on Netplan.io, GitHub, Launchpad, IRC or our Netplan Developer Diaries blog on discourse.

3 April 2024

Arnaud Rebillout: Firefox: Moving from the Debian package to the Flatpak app (long-term?)

First, thanks to Samuel Henrique for giving notice of recent Firefox CVEs in Debian testing/unstable. At the time I didn't want to upgrade my system (Debian Sid) due to the ongoing t64 transition transition, so I decided I could install the Firefox Flatpak app instead, and why not stick to it long-term? This blog post details all the steps, if ever others want to go the same road. Flatpak Installation Disclaimer: this section is hardly anything more than a copy/paste of the official documentation, and with time it will get outdated, so you'd better follow the official doc. First thing first, let's install Flatpak:
$ sudo apt update
$ sudo apt install flatpak
Then the next step is to add the Flathub remote repository, from where we'll get our Flatpak applications:
$ flatpak remote-add --if-not-exists flathub https://dl.flathub.org/repo/flathub.flatpakrepo
And that's all there is to it! Now come the optional steps. For GNOME and KDE users, you might want to install a plugin for the software manager specific to your desktop, so that it can support and manage Flatpak apps:
$ which -s gnome-software  && sudo apt install gnome-software-plugin-flatpak
$ which -s plasma-discover && sudo apt install plasma-discover-backend-flatpak
And here's an additional check you can do, as it's something that did bite me in the past: missing xdg-portal-* packages, that are required for Flatpak applications to communicate with the desktop environment. Just to be sure, you can check the output of apt search '^xdg-desktop-portal' to see what's available, and compare with the output of dpkg -l grep xdg-desktop-portal. As you can see, if you're a GNOME or KDE user, there's a portal backend for you, and it should be installed. For reference, this is what I have on my GNOME desktop at the moment:
$ dpkg -l   grep xdg-desktop-portal   awk ' print $2 '
xdg-desktop-portal
xdg-desktop-portal-gnome
xdg-desktop-portal-gtk
Install the Firefox Flatpak app This is trivial, but still, there's a question I've always asked myself: should I install applications system-wide (aka. flatpak --system, the default) or per-user (aka. flatpak --user)? Turns out, this questions is answered in the Flatpak documentation:
Flatpak commands are run system-wide by default. If you are installing applications for day-to-day usage, it is recommended to stick with this default behavior.
Armed with this new knowledge, let's install the Firefox app:
$ flatpak install flathub org.mozilla.firefox
And that's about it! We can give it a go already:
$ flatpak run org.mozilla.firefox
Data migration At this point, running Firefox via Flatpak gives me an "empty" Firefox. That's not what I want, instead I want my usual Firefox, with a gazillion of tabs already opened, a few extensions, bookmarks and so on. As it turns out, Mozilla provides a brief doc for data migration, and it's as simple as moving Firefox data directory around! To clarify, we'll be copying data: Make sure that all Firefox instances are closed, then proceed:
# BEWARE! Below I'm erasing data!
$ rm -fr ~/.var/app/org.mozilla.firefox/.mozilla/firefox/
$ cp -a ~/.mozilla/firefox/ ~/.var/app/org.mozilla.firefox/.mozilla/
To avoid confusing myself, it's also a good idea to rename the local data directory:
$ mv ~/.mozilla/firefox ~/.mozilla/firefox.old.$(date --iso-8601=date)
At this point, flatpak run org.mozilla.firefox takes me to my "usual" everyday Firefox, with all its tabs opened, pinned, bookmarked, etc. More integration? After following all the steps above, I must say that I'm 99% happy. So far, everything works as before, I didn't hit any issue, and I don't even notice that Firefox is running via Flatpak, it's completely transparent. So where's the 1% of unhappiness? The Run a Command dialog from GNOME, the one that shows up via the keyboard shortcut <Alt+F2>. This is how I start my GUI applications, and I usually run two Firefox instances in parallel (one for work, one for personal), using the firefox -p <profile> command. Given that I ran apt purge firefox before (to avoid confusing myself with two installations of Firefox), now the right (and only) way to start Firefox from a command-line is to type flatpak run org.mozilla.firefox -p <profile>. Typing that every time is way too cumbersome, so I need something quicker. Seems like the most straightforward is to create a wrapper script:
$ cat /usr/local/bin/firefox 
#!/bin/sh
exec flatpak run org.mozilla.firefox "$@"
And now I can just hit <Alt+F2> and type firefox -p <profile> to start Firefox with the profile I want, just as before. Neat! Looking forward: system updates I usually update my system manually every now and then, via the well-known pair of commands:
$ sudo apt update
$ sudo apt full-upgrade
The downside of introducing Flatpak, ie. introducing another package manager, is that I'll need to learn new commands to update the software that comes via this channel. Fortunately, there's really not much to learn. From flatpak-update(1):
flatpak update [OPTION...] [REF...] Updates applications and runtimes. [...] If no REF is given, everything is updated, as well as appstream info for all remotes.
Could it be that simple? Apparently yes, the Flatpak equivalent of the two apt commands above is just:
$ flatpak update
Going forward, my options are:
  1. Teach myself to run flatpak update additionally to apt update, manually, everytime I update my system.
  2. Go crazy: let something automatically update my Flatpak apps, in my back and without my consent.
I'm actually tempted to go for option 2 here, and I wonder if GNOME Software will do that for me, provided that I installed gnome-software-plugin-flatpak, and that I checked Software Updates -> Automatic in the Settings (which I did). However, I didn't find any documentation regarding what this setting really does, so I can't say if it will only download updates, or if it will also install it. I'd be happy if it automatically installs new version of Flatpak apps, but at the same time I'd be very unhappy if it automatically upgrades my Debian system... So we'll see. Enough for today, hope this blog post was useful!

2 April 2024

Dirk Eddelbuettel: ulid 0.3.1 on CRAN: New Maintainer, Some Polish

Happy to share that ulid is now (back) on CRAN. It provides universally unique identifiers that are lexicographically sortable, which improves over the more well-known uuid generators. ulid is a neat little package put together by Bob Rudis a few years ago. It had recently drifted off CRAN so I offered to brush it up and re-submit it. And as tooted earlier today, it took just over an hour to finish that (after the lead up work I had done, including prior email with CRAN in the loop, the repo transfer from Bob s to my ulid repo plus of course a wee bit of actual maintenance; see below for more). The NEWS entry follows.

Changes in version 0.3.1 (2024-04-02)
  • New Maintainer
  • Deleted several repository files no longer used or needed
  • Added .editorconfig, ChangeLog and cleanup
  • Converted NEWS.md to NEWS.Rd
  • Simplified R/ directory to one source file
  • Simplified src/ removing redundant Makevars
  • Added ulid() alias
  • Updated / edited roxygen and README.md documention
  • Removed vignette which was identical to README.md
  • Switched continuous integration to GitHub Actions
  • Placed upstream (header-only) library into src/ulid/
  • Renamed single interface file to src/wrapper

If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Bits from Debian: Bits from the DPL

Dear Debianites This morning I decided to just start writing Bits from DPL and send whatever I have by 18:00 local time. Here it is, barely proof read, along with all it's warts and grammar mistakes! It's slightly long and doesn't contain any critical information, so if you're not in the mood, don't feel compelled to read it! Get ready for a new DPL! Soon, the voting period will start to elect our next DPL, and my time as DPL will come to an end. Reading the questions posted to the new candidates on debian-vote, it takes quite a bit of restraint to not answer all of them myself, I think I can see how that aspect contributed to me being reeled in to running for DPL! In total I've done so 5 times (the first time I ran, Sam was elected!). Good luck to both Andreas and Sruthi, our current DPL candidates! I've already started working on preparing handover, and there's multiple request from teams that have came in recently that will have to wait for the new term, so I hope they're both ready to hit the ground running! Things that I wish could have gone better Communication Recently, I saw a t-shirt that read:
Adulthood is saying, 'But after this week things will slow down a bit' over and over until you die.
I can relate! With every task, crisis or deadline that appears, I think that once this is over, I'll have some more breathing space to get back to non-urgent, but important tasks. "Bits from the DPL" was something I really wanted to get right this last term, and clearly failed spectacularly. I have two long Bits from the DPL drafts that I never finished, I tend to have prioritised problems of the day over communication. With all the hindsight I have, I'm not sure which is better to prioritise, I do rate communication and transparency very highly and this is really the top thing that I wish I could've done better over the last four years. On that note, thanks to people who provided me with some kind words when I've mentioned this to them before. They pointed out that there are many other ways to communicate and be in touch with the community, and they mentioned that they thought that I did a good job with that. Since I'm still on communication, I think we can all learn to be more effective at it, since it's really so important for the project. Every time I publicly spoke about us spending more money, we got more donations. People out there really like to see how we invest funds in to Debian, instead of just making it heap up. DSA just spent a nice chunk on money on hardware, but we don't have very good visibility on it. It's one thing having it on a public line item in SPI's reporting, but it would be much more exciting if DSA could provide a write-up on all the cool hardware they're buying and what impact it would have on developers, and post it somewhere prominent like debian-devel-announce, Planet Debian or Bits from Debian (from the publicity team). I don't want to single out DSA there, it's difficult and affects many other teams. The Salsa CI team also spent a lot of resources (time and money wise) to extend testing on AMD GPUs and other AMD hardware. It's fantastic and interesting work, and really more people within the project and in the outside world should know about it! I'm not going to push my agendas to the next DPL, but I hope that they continue to encourage people to write about their work, and hopefully at some point we'll build enough excitement in doing so that it becomes a more normal part of our daily work. Founding Debian as a standalone entity This was my number one goal for the project this last term, which was a carried over item from my previous terms. I'm tempted to write everything out here, including the problem statement and our current predicaments, what kind of ground work needs to happen, likely constitutional changes that need to happen, and the nature of the GR that would be needed to make such a thing happen, but if I start with that, I might not finish this mail. In short, I 100% believe that this is still a very high ranking issue for Debian, and perhaps after my term I'd be in a better position to spend more time on this (hmm, is this an instance of "The grass is always better on the other side", or "Next week will go better until I die?"). Anyway, I'm willing to work with any future DPL on this, and perhaps it can in itself be a delegation tasked to properly explore all the options, and write up a report for the project that can lead to a GR. Overall, I'd rather have us take another few years and do this properly, rather than rush into something that is again difficult to change afterwards. So while I very much wish this could've been achieved in the last term, I can't say that I have any regrets here either. My terms in a nutshell COVID-19 and Debian 11 era My first term in 2020 started just as the COVID-19 pandemic became known to spread globally. It was a tough year for everyone, and Debian wasn't immune against its effects either. Many of our contributors got sick, some have lost loved ones (my father passed away in March 2020 just after I became DPL), some have lost their jobs (or other earners in their household have) and the effects of social distancing took a mental and even physical health toll on many. In Debian, we tend to do really well when we get together in person to solve problems, and when DebConf20 got cancelled in person, we understood that that was necessary, but it was still more bad news in a year we had too much of it already. I can't remember if there was ever any kind of formal choice or discussion about this at any time, but the DebConf video team just kind of organically and spontaneously became the orga team for an online DebConf, and that lead to our first ever completely online DebConf. This was great on so many levels. We got to see each other's faces again, even though it was on screen. We had some teams talk to each other face to face for the first time in years, even though it was just on a Jitsi call. It had a lasting cultural change in Debian, some teams still have video meetings now, where they didn't do that before, and I think it's a good supplement to our other methods of communication. We also had a few online Mini-DebConfs that was fun, but DebConf21 was also online, and by then we all developed an online conference fatigue, and while it was another good online event overall, it did start to feel a bit like a zombieconf and after that, we had some really nice events from the Brazillians, but no big global online community events again. In my opinion online MiniDebConfs can be a great way to develop our community and we should spend some further energy into this, but hey! This isn't a platform so let me back out of talking about the future as I see it... Despite all the adversity that we faced together, the Debian 11 release ended up being quite good. It happened about a month or so later than what we ideally would've liked, but it was a solid release nonetheless. It turns out that for quite a few people, staying inside for a few months to focus on Debian bugs was quite productive, and Debian 11 ended up being a very polished release. During this time period we also had to deal with a previous Debian Developer that was expelled for his poor behaviour in Debian, who continued to harass members of the Debian project and in other free software communities after his expulsion. This ended up being quite a lot of work since we had to take legal action to protect our community, and eventually also get the police involved. I'm not going to give him the satisfaction by spending too much time talking about him, but you can read our official statement regarding Daniel Pocock here: https://www.debian.org/News/2021/20211117 In late 2021 and early 2022 we also discussed our general resolution process, and had two consequent votes to address some issues that have affected past votes: In my first term I addressed our delegations that were a bit behind, by the end of my last term all delegation requests are up to date. There's still some work to do, but I'm feeling good that I get to hand this over to the next DPL in a very decent state. Delegation updates can be very deceiving, sometimes a delegation is completely re-written and it was just 1 or 2 hours of work. Other times, a delegation updated can contain one line that has changed or a change in one team member that was the result of days worth of discussion and hashing out differences. I also received quite a few requests either to host a service, or to pay a third-party directly for hosting. This was quite an admin nightmare, it either meant we had to manually do monthly reimbursements to someone, or have our TOs create accounts/agreements at the multiple providers that people use. So, after talking to a few people about this, we founded the DebianNet team (we could've admittedly chosen a better name, but that can happen later on) for providing hosting at two different hosting providers that we have agreement with so that people who host things under debian.net have an easy way to host it, and then at the same time Debian also has more control if a site maintainer goes MIA. More info: https://wiki.debian.org/Teams/DebianNet You might notice some Openstack mentioned there, we had some intention to set up a Debian cloud for hosting these things, that could also be used for other additional Debiany things like archive rebuilds, but these have so far fallen through. We still consider it a good idea and hopefully it will work out some other time (if you're a large company who can sponsor few racks and servers, please get in touch!) DebConf22 and Debian 12 era DebConf22 was the first time we returned to an in-person DebConf. It was a bit smaller than our usual DebConf - understandably so, considering that there were still COVID risks and people who were at high risk or who had family with high risk factors did the sensible thing and stayed home. After watching many MiniDebConfs online, I also attended my first ever MiniDebConf in Hamburg. It still feels odd typing that, it feels like I should've been at one before, but my location makes attending them difficult (on a side-note, a few of us are working on bootstrapping a South African Debian community and hopefully we can pull off MiniDebConf in South Africa later this year). While I was at the MiniDebConf, I gave a talk where I covered the evolution of firmware, from the simple e-proms that you'd find in old printers to the complicated firmware in modern GPUs that basically contain complete operating systems- complete with drivers for the device their running on. I also showed my shiny new laptop, and explained that it's impossible to install that laptop without non-free firmware (you'd get a black display on d-i or Debian live). Also that you couldn't even use an accessibility mode with audio since even that depends on non-free firmware these days. Steve, from the image building team, has said for a while that we need to do a GR to vote for this, and after more discussion at DebConf, I kept nudging him to propose the GR, and we ended up voting in favour of it. I do believe that someone out there should be campaigning for more free firmware (unfortunately in Debian we just don't have the resources for this), but, I'm glad that we have the firmware included. In the end, the choice comes down to whether we still want Debian to be installable on mainstream bare-metal hardware. At this point, I'd like to give a special thanks to the ftpmasters, image building team and the installer team who worked really hard to get the changes done that were needed in order to make this happen for Debian 12, and for being really proactive for remaining niggles that was solved by the time Debian 12.1 was released. The included firmware contributed to Debian 12 being a huge success, but it wasn't the only factor. I had a list of personal peeves, and as the hard freeze hit, I lost hope that these would be fixed and made peace with the fact that Debian 12 would release with those bugs. I'm glad that lots of people proved me wrong and also proved that it's never to late to fix bugs, everything on my list got eliminated by the time final freeze hit, which was great! We usually aim to have a release ready about 2 years after the previous release, sometimes there are complications during a freeze and it can take a bit longer. But due to the excellent co-ordination of the release team and heavy lifting from many DDs, the Debian 12 release happened 21 months and 3 weeks after the Debian 11 release. I hope the work from the release team continues to pay off so that we can achieve their goals of having shorter and less painful freezes in the future! Even though many things were going well, the ongoing usr-merge effort highlighted some social problems within our processes. I started typing out the whole history of usrmerge here, but it's going to be too long for the purpose of this mail. Important questions that did come out of this is, should core Debian packages be team maintained? And also about how far the CTTE should really be able to override a maintainer. We had lots of discussion about this at DebConf22, but didn't make much concrete progress. I think that at some point we'll probably have a GR about package maintenance. Also, thank you to Guillem who very patiently explained a few things to me (after probably having have to done so many times to others before already) and to Helmut who have done the same during the MiniDebConf in Hamburg. I think all the technical and social issues here are fixable, it will just take some time and patience and I have lots of confidence in everyone involved. UsrMerge wiki page: https://wiki.debian.org/UsrMerge DebConf 23 and Debian 13 era DebConf23 took place in Kochi, India. At the end of my Bits from the DPL talk there, someone asked me what the most difficult thing I had to do was during my terms as DPL. I answered that nothing particular stood out, and even the most difficult tasks ended up being rewarding to work on. Little did I know that my most difficult period of being DPL was just about to follow. During the day trip, one of our contributors, Abraham Raji, passed away in a tragic accident. There's really not anything anyone could've done to predict or stop it, but it was devastating to many of us, especially the people closest to him. Quite a number of DebConf attendees went to his funeral, wearing the DebConf t-shirts he designed as a tribute. It still haunts me when I saw his mother scream "He was my everything! He was my everything!", this was by a large margin the hardest day I've ever had in Debian, and I really wasn't ok for even a few weeks after that and I think the hurt will be with many of us for some time to come. So, a plea again to everyone, please take care of yourself! There's probably more people that love you than you realise. A special thanks to the DebConf23 team, who did a really good job despite all the uphills they faced (and there were many!). As DPL, I think that planning for a DebConf is near to impossible, all you can do is show up and just jump into things. I planned to work with Enrico to finish up something that will hopefully save future DPLs some time, and that is a web-based DD certificate creator instead of having the DPL do so manually using LaTeX. It already mostly works, you can see the work so far by visiting https://nm.debian.org/person/ACCOUNTNAME/certificate/ and replacing ACCOUNTNAME with your Debian account name, and if you're a DD, you should see your certificate. It still needs a few minor changes and a DPL signature, but at this point I think that will be finished up when the new DPL start. Thanks to Enrico for working on this! Since my first term, I've been trying to find ways to improve all our accounting/finance issues. Tracking what we spend on things, and getting an annual overview is hard, especially over 3 trusted organisations. The reimbursement process can also be really tedious, especially when you have to provide files in a certain order and combine them into a PDF. So, at DebConf22 we had a meeting along with the treasurer team and Stefano Rivera who said that it might be possible for him to work on a new system as part of his Freexian work. It worked out, and Freexian funded the development of the system since then, and after DebConf23 we handled the reimbursements for the conference via the new reimbursements site: https://reimbursements.debian.net/ It's still early days, but over time it should be linked to all our TOs and we'll use the same category codes across the board. So, overall, our reimbursement process becomes a lot simpler, and also we'll be able to get information like how much money we've spent on any category in any period. It will also help us to track how much money we have available or how much we spend on recurring costs. Right now that needs manual polling from our TOs. So I'm really glad that this is a big long-standing problem in the project that is being fixed. For Debian 13, we're waving goodbye to the KFreeBSD and mipsel ports. But we're also gaining riscv64 and loongarch64 as release architectures! I have 3 different RISC-V based machines on my desk here that I haven't had much time to work with yet, you can expect some blog posts about them soon after my DPL term ends! As Debian is a unix-like system, we're affected by the Year 2038 problem, where systems that uses 32 bit time in seconds since 1970 run out of available time and will wrap back to 1970 or have other undefined behaviour. A detailed wiki page explains how this works in Debian, and currently we're going through a rather large transition to make this possible. I believe this is the right time for Debian to be addressing this, we're still a bit more than a year away for the Debian 13 release, and this provides enough time to test the implementation before 2038 rolls along. Of course, big complicated transitions with dependency loops that causes chaos for everyone would still be too easy, so this past weekend (which is a holiday period in most of the west due to Easter weekend) has been filled with dealing with an upstream bug in xz-utils, where a backdoor was placed in this key piece of software. An Ars Technica covers it quite well, so I won't go into all the details here. I mention it because I want to give yet another special thanks to everyone involved in dealing with this on the Debian side. Everyone involved, from the ftpmasters to security team and others involved were super calm and professional and made quick, high quality decisions. This also lead to the archive being frozen on Saturday, this is the first time I've seen this happen since I've been a DD, but I'm sure next week will go better! Looking forward It's really been an honour for me to serve as DPL. It might well be my biggest achievement in my life. Previous DPLs range from prominent software engineers to game developers, or people who have done things like complete Iron Man, run other huge open source projects and are part of big consortiums. Ian Jackson even authored dpkg and is now working on the very interesting tag2upload service! I'm a relative nobody, just someone who grew up as a poor kid in South Africa, who just really cares about Debian a lot. And, above all, I'm really thankful that I didn't do anything major to screw up Debian for good. Not unlike learning how to use Debian, and also becoming a Debian Developer, I've learned a lot from this and it's been a really valuable growth experience for me. I know I can't possible give all the thanks to everyone who deserves it, so here's a big big thanks to everyone who have worked so hard and who have put in many, many hours to making Debian better, I consider you all heroes! -Jonathan

1 April 2024

Colin Watson: Free software activity in March 2024

My Debian contributions this month were all sponsored by Freexian.
Arturo Borrero Gonz lez: Kubecon and CloudNativeCon 2024 Europe summary

Kubecon EU 2024 Paris logo This blog post shares my thoughts on attending Kubecon and CloudNativeCon 2024 Europe in Paris. It was my third time at this conference, and it felt bigger than last year s in Amsterdam. Apparently it had an impact on public transport. I missed part of the opening keynote because of the extremely busy rush hour tram in Paris. On Artificial Intelligence, Machine Learning and GPUs Talks about AI, ML, and GPUs were everywhere this year. While it wasn t my main interest, I did learn about GPU resource sharing and power usage on Kubernetes. There were also ideas about offering Models-as-a-Service, which could be cool for Wikimedia Toolforge in the future. See also: On security, policy and authentication This was probably the main interest for me in the event, given Wikimedia Toolforge was about to migrate away from Pod Security Policy, and we were currently evaluating different alternatives. In contrast to my previous attendances to Kubecon, where there were three policy agents with presence in the program schedule, Kyverno, Kubewarden and OpenPolicyAgent (OPA), this time only OPA had the most relevant sessions. One surprising bit I got from one of the OPA sessions was that it could work to authorize linux PAM sessions. Could this be useful for Wikimedia Toolforge? OPA talk I attended several sessions related to authentication topics. I discovered the keycloak software, which looks very promising. I also attended an Oauth2 session which I had a hard time following, because I clearly missed some additional knowledge about how Oauth2 works internally. I also attended a couple of sessions that ended up being a vendor sales talk. See also: On container image builds, harbor registry, etc This topic was also of interest to me because, again, it is a core part of Wikimedia Toolforge. I attended a couple of sessions regarding container image builds, including topics like general best practices, image minimization, and buildpacks. I learned about kpack, which at first sight felt like a nice simplification of how the Toolforge build service was implemented. I also attended a session by the Harbor project maintainers where they shared some valuable information on things happening soon or in the future , for example: On networking I attended a couple of sessions regarding networking. One session in particular I paid special attention to, ragarding on network policies. They discussed new semantics being added to the Kubernetes API. The different layers of abstractions being added to the API, the different hook points, and override layers clearly resembled (to me at least) the network packet filtering stack of the linux kernel (netfilter), but without the 20 (plus) years of experience building the right semantics and user interfaces. Network talk I very recently missed some semantics for limiting the number of open connections per namespace, see Phabricator T356164: [toolforge] several tools get periods of connection refused (104) when connecting to wikis This functionality should be available in the lower level tools, I mean Netfilter. I may submit a proposal upstream at some point, so they consider adding this to the Kubernetes API. Final notes In general, I believe I learned many things, and perhaps even more importantly I re-learned some stuff I had forgotten because of lack of daily exposure. I m really happy that the cloud native way of thinking was reinforced in me, which I still need because most of my muscle memory to approach systems architecture and engineering is from the old pre-cloud days. That being said, I felt less engaged with the content of the conference schedule compared to last year. I don t know if the schedule itself was less interesting, or that I m losing interest? Finally, not an official track in the conference, but we met a bunch of folks from Wikimedia Deutschland. We had a really nice time talking about how wikibase.cloud uses Kubernetes, whether they could run in Wikimedia Cloud Services, and why structured data is so nice. Group photo
29 March 2024

Ravi Dwivedi: A visit to the Taj Mahal

Note: The currency used in this post is Indian Rupees, which was around 83 INR for 1 US Dollar as that time. I and my friend Badri visited the Taj Mahal this month. Taj Mahal is one of the main tourist destinations in India and does not need an introduction, I guess. It is in Agra, in the state of Uttar Pradesh, 188 km from Delhi by train. So, I am writing a post documenting useful information for people who are planning to visit Taj Mahal. Feel free to ask me questions about visiting the Taj Mahal.
Our retiring room at the Old Delhi Railway Station.
We had booked a train from Delhi to Agra. The name of the train was Taj Express, and its scheduled departure time from Hazrat Nizamuddin station in Delhi is 07:08 hours in the morning, and its arrival time at Agra Cantt station is 09:45. So, we booked a retiring room at the Old Delhi railway station for the previous night. This retiring room was hard to find. We woke up at 05:00 in the morning and took the metro to Hazrat Nizamuddin station. We barely reached the station in time, but anyway, the train was not yet at the station; it was late. We reached Agra at 10:30 and checked into our retiring room, took rest and went out for Taj Mahal at 13:00 in the afternoon. Taj Mahal s outer gate is 5 km away from the Agra Cantt station. As we were going out of the railway station, we were chased by an autorickshaw driver who offered to go to Taj Mahal for 150 INR for both of us. I asked him to bring it down to 60 INR, and after some back and forth, he agreed to drop us off at Taj Mahal for 80 INR. But I said we won t pay anything above 60 INR. He agreed with that amount but said that he would need to fill up with more passengers. When we saw that he wasn t making any effort in bringing more passengers, we walked away. As soon as we got out of the railway station complex, an autorickshaw driver came to us and offered to drop us off at Taj Mahal for 20 INR if we are sharing with other passengers and 100 INR if we reserve the auto for us. We agreed to go with 20 INR per person, but he started the autorickshaw as soon as we hopped in. I thought that the third person in the auto was another passenger sharing a ride with us, but later we got to know he was with the driver. Upon reaching the outer gate of Taj Mahal, I gave him 40 INR (for both of us), and he asked to instead give 100 INR as he said we reserved the auto, even though I clearly stated before taking the auto that we wanted to share the auto, not reserve it. I think this was a scam. We walked away, and he didn t insist further. Taj Mahal entrance was like 500 m from the outer gate. We went there and bought offline tickets just outside the West gate. For Indians, the ticket for going inside the Taj Mahal complex is 50 INR, and a visit to the mausoleum costs 200 INR extra.
Security outside the Taj Mahal complex.
This red colored building is entrance to where you can see the Taj Mahal.
Taj Mahal.
Shoe covers for going inside the mausoleum.
Taj Mahal from side angle.
We came out of the Taj Mahal complex at 18:00 and stopped for some tea and snacks. I also bought a fridge magnet for 30 INR. Then we walked back towards Agra Cantt station, as we had a train for Jaipur at midnight. We were hoping to find a restaurant along the way, but we didn t find any that we found interesting, so we just ate at the railway station. During the return trip, we noticed there was a bus stand near the station, which we didn t know about. It turns out you can catch a bus to Taj Mahal from there. You can click here to check out the location of that bus stand on OpenStreetMap.

Expenses These were our expenses per person Retiring room at Delhi Railway Station for 12 hours 131 Train ticket from Delhi to Agra (Taj Express) 110 Retiring room at Agra Cantt station for 12 hours 450 Auto-rickshaw to Taj Mahal 20 Taj Mahal ticket (including going inside the mausoleum): 250 Food 350

Important information for visitors
  • Taj Mahal is closed on Friday.
  • There are plenty of free-of-cost drinking water taps inside the Taj Mahal complex.
  • Ticket price for Indians is 50, for foreigners and NRIs it is 1100, and for people from SAARC/BIMSTEC is 540. 200 extra for the mausoleum for everyone.
  • A visit inside the mausoleum requires covering your shoes or removing them. Shoe covers costs 10 per person inside the complex, but are probably involved free of charge in foreigner tickets. We could not find a place to keep our shoes, but some people managed to enter barefoot, indicating there must be some place to keep your shoes.
  • Mobile phones and cameras are allowed inside the Taj Mahal, but not eatables.
  • We went there on March 10th, and the weather was pleasant. So, we recommend going around that time.
  • Regarding the timings, I found this written near the ticket counter: Taj Mahal opens 30 minutes before sunrise and closes 30 minutes before sunset during normal operating days, so the timings are vague. But we came out of the complex at 18:00 hours. I would interpret that to mean the Taj Mahal is open from 07:00 to 18:00, and the ticket counter closes at around 17:00. During the winter, the timings might differ.
  • The cheapest way to reach Taj Mahal is by bus, and the bus stop is here
Bye for now. See you in the next post :)

Reproducible Builds (diffoscope): diffoscope 262 released

The diffoscope maintainers are pleased to announce the release of diffoscope version 262. This version includes the following changes:
[ Chris Lamb ]
* Factor out Python version checking in test_zip.py. (Re: #362)
* Also skip some zip tests under 3.10.14 as well; a potential regression may
  have been backported to the 3.10.x series. The underlying cause is still to
  be investigated. (Re: #362)
You find out more by visiting the project homepage.

24 March 2024

Niels Thykier: debputy v0.1.21

Earlier today, I have just released debputy version 0.1.21 to Debian unstable. In the blog post, I will highlight some of the new features.
Package boilerplate reduction with automatic relationship substvar Last month, I started a discussion on rethinking how we do relationship substvars such as the $ misc:Depends . These generally ends up being boilerplate runes in the form of Depends: $ misc:Depends , $ shlibs:Depends where you as the packager has to remember exactly which runes apply to your package. My proposed solution was to automatically apply these substvars and this feature has now been implemented in debputy. It is also combined with the feature where essential packages should use Pre-Depends by default for dpkg-shlibdeps related dependencies. I am quite excited about this feature, because I noticed with libcleri that we are now down to 3-5 fields for defining a simple library package. Especially since most C library packages are trivial enough that debputy can auto-derive them to be Multi-Arch: same. As an example, the libcleric1 package is down to 3 fields (Package, Architecture, Description) with Section and Priority being inherited from the Source stanza. I have submitted a MR to show case the boilerplate reduction at https://salsa.debian.org/siridb-team/libcleri/-/merge_requests/3. The removal of libcleric1 (= $ binary:Version ) in that MR relies on another existing feature where debputy can auto-derive a dependency between an arch:any -dev package and the library package based on the .so symlink for the shared library. The arch:any restriction comes from the fact that arch:all and arch:any packages are not built together, so debputy cannot reliably see across the package boundaries during the build (and therefore refuses to do so at all). Packages that have already migrated to debputy can use debputy migrate-from-dh to detect any unnecessary relationship substitution variables in case you want to clean up. The removal of Multi-Arch: same and intra-source dependencies must be done manually and so only be done so when you have validated that it is safe and sane to do. I was willing to do it for the show-case MR, but I am less confident that would bother with these for existing packages in general. Note: I summarized the discussion of the automatic relationship substvar feature earlier this month in https://lists.debian.org/debian-devel/2024/03/msg00030.html for those who want more details. PS: The automatic relationship substvars feature will also appear in debhelper as a part of compat 14.
Language Server (LSP) and Linting I have long been frustrated by our poor editor support for Debian packaging files. To this end, I started working on a Language Server (LSP) feature in debputy that would cover some of our standard Debian packaging files. This release includes the first version of said language server, which covers the following files:
  • debian/control
  • debian/copyright (the machine readable variant)
  • debian/changelog (mostly just spelling)
  • debian/rules
  • debian/debputy.manifest (syntax checks only; use debputy check-manifest for the full validation for now)
Most of the effort has been spent on the Deb822 based files such as debian/control, which comes with diagnostics, quickfixes, spellchecking (but only for relevant fields!), and completion suggestions. Since not everyone has a LSP capable editor and because sometimes you just want diagnostics without having to open each file in an editor, there is also a batch version for the diagnostics via debputy lint. Please see debputy(1) for how debputy lint compares with lintian if you are curious about which tool to use at what time. To help you getting started, there is a now debputy lsp editor-config command that can provide you with the relevant editor config glue. At the moment, emacs (via eglot) and vim with vim-youcompleteme are supported. For those that followed the previous blog posts on writing the language server, I would like to point out that the command line for running the language server has changed to debputy lsp server and you no longer have to tell which format it is. I have decided to make the language server a "polyglot" server for now, which I will hopefully not regret... Time will tell. :) Anyhow, to get started, you will want:
$ apt satisfy 'dh-debputy (>= 0.1.21~), python3-pygls'
# Optionally, for spellchecking
$ apt install python3-hunspell hunspell-en-us
# For emacs integration
$ apt install elpa-dpkg-dev-el markdown-mode-el
# For vim integration via vim-youcompleteme
$ apt install vim-youcompleteme
Specifically for emacs, I also learned two things after the upload. First, you can auto-activate eglot via eglot-ensure. This badly feature interacts with imenu on debian/changelog for reasons I do not understand (causing a several second start up delay until something times out), but it works fine for the other formats. Oddly enough, opening a changelog file and then activating eglot does not trigger this issue at all. In the next version, editor config for emacs will auto-activate eglot on all files except debian/changelog. The second thing is that if you install elpa-markdown-mode, emacs will accept and process markdown in the hover documentation provided by the language server. Accordingly, the editor config for emacs will also mention this package from the next version on. Finally, on a related note, Jelmer and I have been looking at moving some of this logic into a new package called debpkg-metadata. The point being to support easier reuse of linting and LSP related metadata - like pulling a list of known fields for debian/control or sharing logic between lintian-brush and debputy.
Minimal integration mode for Rules-Requires-Root One of the original motivators for starting debputy was to be able to get rid of fakeroot in our build process. While this is possible, debputy currently does not support most of the complex packaging features such as maintscripts and debconf. Unfortunately, the kind of packages that need fakeroot for static ownership tend to also require very complex packaging features. To bridge this gap, the new version of debputy supports a very minimal integration with dh via the dh-sequence-zz-debputy-rrr. This integration mode keeps the vast majority of debhelper sequence in place meaning most dh add-ons will continue to work with dh-sequence-zz-debputy-rrr. The sequence only replaces the following commands:
  • dh_fixperms
  • dh_gencontrol
  • dh_md5sums
  • dh_builddeb
The installations feature of the manifest will be disabled in this integration mode to avoid feature interactions with debhelper tools that expect debian/<pkg> to contain the materialized package. On a related note, the debputy migrate-from-dh command now supports a --migration-target option, so you can choose the desired level of integration without doing code changes. The command will attempt to auto-detect the desired integration from existing package features such as a build-dependency on a relevant dh sequence, so you do not have to remember this new option every time once the migration has started. :)

Marco d'Itri: CISPE's call for new regulations on VMware

A few days ago CISPE, a trade association of European cloud providers, published a press release complaining about the new VMware licensing scheme and asking for regulators and legislators to intervene. But VMware does not have a monopoly on virtualization software: I think that asking regulators to interfere is unnecessary and unwise, unless, of course, they wish to question the entire foundations of copyright. Which, on the other hand, could be an intriguing position that I would support... I believe that over-reliance on a single supplier is a typical enterprise risk: in the past decade some companies have invested in developing their own virtualization infrastructure using free software, while others have decided to rely entirely on a single proprietary software vendor. My only big concern is that many public sector organizations will continue to use VMware and pay the huge fees designed by Broadcom to extract the maximum amount of money from their customers. However, it is ultimately the citizens who pay these bills, and blaming the evil US corporation is a great way to avoid taking responsibility for these choices.
"Several CISPE members have stated that without the ability to license and use VMware products they will quickly go bankrupt and out of business."
Insert here the Jeremy Clarkson "Oh no! Anyway..." meme.

Jacob Adams: Regular Reboots

Uptime is often considered a measure of system reliability, an indication that the running software is stable and can be counted on. However, this hides the insidious build-up of state throughout the system as it runs, the slow drift from the expected to the strange. As Nolan Lawson highlights in an excellent post entitled Programmers are bad at managing state, state is the most challenging part of programming. It s why did you try turning it off and on again is a classic tech support response to any problem. In addition to the problem of state, installing regular updates periodically requires a reboot, even if the rest of the process is automated through a tool like unattended-upgrades. For my personal homelab, I manage a handful of different machines running various services. I used to just schedule a day to update and reboot all of them, but that got very tedious very quickly. I then moved the reboot to a cronjob, and then recently to a systemd timer and service. I figure that laying out my path to better management of this might help others, and will almost certainly lead to someone telling me a better way to do this. UPDATE: Turns out there s another option for better systemd cron integration. See systemd-cron below.

Stage One: Reboot Cron The first, and easiest approach, is a simple cron job. Just adding the following line to /var/spool/cron/crontabs/root1 is enough to get your machine to reboot once a month2 on the 6th at 8:00 AM3:
0 8 6 * * reboot
I had this configured for many years and it works well. But you have no indication as to whether it succeeds except for checking your uptime regularly yourself.

Stage Two: Reboot systemd Timer The next evolution of this approach for me was to use a systemd timer. I created a regular-reboot.timer with the following contents:
[Unit]
Description=Reboot on a Regular Basis
[Timer]
Unit=regular-reboot.service
OnBootSec=1month
[Install]
WantedBy=timers.target
This timer will trigger the regular-reboot.service systemd unit when the system reaches one month of uptime. I ve seen some guides to creating timer units recommend adding a Wants=regular-reboot.service to the [Unit] section, but this has the consequence of running that service every time it starts the timer. In this case that will just reboot your system on startup which is not what you want. Care needs to be taken to use the OnBootSec directive instead of OnCalendar or any of the other time specifications, as your system could reboot, discover its still within the expected window and reboot again. With OnBootSec your system will not have that problem. Technically, this same problem could have occurred with the cronjob approach, but in practice it never did, as the systems took long enough to come back up that they were no longer within the expected window for the job. I then added the regular-reboot.service:
[Unit]
Description=Reboot on a Regular Basis
Wants=regular-reboot.timer
[Service]
Type=oneshot
ExecStart=shutdown -r 02:45
You ll note that this service is actually scheduling a specific reboot time via the shutdown command instead of just immediately rebooting. This is a bit of a hack needed because I can t control when the timer runs exactly when using OnBootSec. This way different systems have different reboot times so that everything doesn t just reboot and fail all at once. Were something to fail to come back up I would have some time to fix it, as each machine has a few hours between scheduled reboots. One you have both files in place, you ll simply need to reload configuration and then enable and start the timer unit:
systemctl daemon-reload
systemctl enable --now regular-reboot.timer
You can then check when it will fire next:
# systemctl status regular-reboot.timer
  regular-reboot.timer - Reboot on a Regular Basis
     Loaded: loaded (/etc/systemd/system/regular-reboot.timer; enabled; preset: enabled)
     Active: active (waiting) since Wed 2024-03-13 01:54:52 EDT; 1 week 4 days ago
    Trigger: Fri 2024-04-12 12:24:42 EDT; 2 weeks 4 days left
   Triggers:   regular-reboot.service
Mar 13 01:54:52 dorfl systemd[1]: Started regular-reboot.timer - Reboot on a Regular Basis.

Sidenote: Replacing all Cron Jobs with systemd Timers More generally, I ve now replaced all cronjobs on my personal systems with systemd timer units, mostly because I can now actually track failures via prometheus-node-exporter. There are plenty of ways to hack in cron support to the node exporter, but just moving to systemd units provides both support for tracking failure and logging, both of which make system administration much easier when things inevitably go wrong.

systemd-cron An alternative to converting everything by hand, if you happen to have a lot of cronjobs is systemd-cron. It will make each crontab and /etc/cron.* directory into automatic service and timer units. Thanks to Alexandre Detiste for letting me know about this project. I have few enough cron jobs that I ve already converted, but for anyone looking at a large number of jobs to convert you ll want to check it out!

Stage Three: Monitor that it s working The final step here is confirm that these units actually work, beyond just firing regularly. I now have the following rule in my prometheus-alertmanager rules:
  - alert: UptimeTooHigh
    expr: (time() - node_boot_time_seconds job="node" ) / 86400 > 35
    annotations:
      summary: "Instance  Has Been Up Too Long!"
      description: "Instance  Has Been Up Too Long!"
This will trigger an alert anytime that I have a machine up for more than 35 days. This actually helped me track down one machine that I had forgotten to set up this new unit on4.

Not everything needs to scale Is It Worth The Time One of the most common fallacies programmers fall into is that we will jump to automating a solution before we stop and figure out how much time it would even save. In taking a slow improvement route to solve this problem for myself, I ve managed not to invest too much time5 in worrying about this but also achieved a meaningful improvement beyond my first approach of doing it all by hand.
  1. You could also add a line to /etc/crontab or drop a script into /etc/cron.monthly depending on your system.
  2. Why once a month? Mostly to avoid regular disruptions, but still be reasonably timely on updates.
  3. If you re looking to understand the cron time format I recommend crontab guru.
  4. In the long term I really should set up something like ansible to automatically push fleetwide changes like this but with fewer machines than fingers this seems like overkill.
  5. Of course by now writing about it, I ve probably doubled the amount of time I ve spent thinking about this topic but oh well

23 March 2024

Dirk Eddelbuettel: littler 0.3.20 on CRAN: Moar Features!

max-heap image The twentyfirst release of littler as a CRAN package landed on CRAN just now, following in the now eighteen year history (!!) as a package started by Jeff in 2006, and joined by me a few weeks later. littler is the first command-line interface for R as it predates Rscript. It allows for piping as well for shebang scripting via #!, uses command-line arguments more consistently and still starts faster. It also always loaded the methods package which Rscript only began to do in recent years. littler lives on Linux and Unix, has its difficulties on macOS due to yet-another-braindeadedness there (who ever thought case-insensitive filesystems as a default were a good idea?) and simply does not exist on Windows (yet the build system could be extended see RInside for an existence proof, and volunteers are welcome!). See the FAQ vignette on how to add it to your PATH. A few examples are highlighted at the Github repo:, as well as in the examples vignette. This release contains another fair number of small changes and improvements to some of the scripts I use daily to build or test packages, adds a new front-end ciw.r for the recently-released ciw package offering a CRAN Incoming Watcher , a new helper installDeps2.r (extending installDeps.r), a new doi-to-bib converter, allows a different temporary directory setup I find helpful, deals with one corner deployment use, and more. The full change description follows.

Changes in littler version 0.3.20 (2024-03-23)
  • Changes in examples scripts
    • New (dependency-free) helper installDeps2.r to install dependencies
    • Scripts rcc.r, tt.r, tttf.r, tttlr.r use env argument -S to set -t to r
    • tt.r can now fill in inst/tinytest if it is present
    • New script ciw.r wrapping new package ciw
    • tttf.t can now use devtools and its loadall
    • New script doi2bib.r to call the DOI converter REST service (following a skeet by Richard McElreath)
  • Changes in package
    • The CI setup uses checkout@v4 and the r-ci-setup action
    • The Suggests: is a little tighter as we do not list all packages optionally used in the the examples (as R does not check for it either)
    • The package load messag can account for the rare build of R under different architecture (Berwin Turlach in #117 closing #116)
    • In non-vanilla mode, the temporary directory initialization in re-run allowing for a non-standard temp dir via config settings

My CRANberries service provides a comparison to the previous release. Full details for the littler release are provided as usual at the ChangeLog page, and also on the package docs website. The code is available via the GitHub repo, from tarballs and now of course also from its CRAN page and via install.packages("littler"). Binary packages are available directly in Debian as well as (in a day or two) Ubuntu binaries at CRAN thanks to the tireless Michael Rutter. Comments and suggestions are welcome at the GitHub repo. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Valhalla's Things: Forgotten Yeast Bread - Sourdough Edition

Posted on March 23, 2024
Tags: madeof:atoms, craft:cooking, craft:baking, craft:bread
Yesterday I had planned a pan sbagliato for today, but I also had quite a bit of sourdough to deal with, so instead of mixing a bit of of dry yeast at 18:00 and mixing it with some additional flour and water at 21:00, at around maybe 20:00 I substituted:
  • 100 g firm sourdough;
  • 33 g flour;
  • 66 g water.
Then I briefly woke up in the middle of the night and poured the dough on the tray at that time instead of having to wake up before 8:00 in the morning. Everything else was done as in the original recipe. The firm sourdough is feeded regularly with the same weight of flour and half the weight of water. Will. do. again.

Next.

Previous.