Search Results: "xam"

14 December 2005

Jonathan McDowell: It's cool to talk SCMs

It seems everyone is talking SCMs these days, usually touting their favourite option while deriding everyone else's. (I exaggerate for effect.) Years ago we mostly used CVS and were happy. Some people are still happy with it. I still have a bunch of code in it, though migrating it to something else is on my list. Why? Niceties like being able to rename a file. Or atomic changesets. Things that all the new breeds of options can do. For the tress I manage myself distributed working isn't a big issue, so they'll probably just get migrated to Subversion as the easiest option. However I'm not really tied to any SCM. I've used at least Arch (tla), BitKeeper, ClearCase, CVS, Monotone, PVCS and Subversion for both checking out and committing files, and handful more to check out files from things I wanted to look at. The only one that is unusable is PVCS. The rest have all been fine for whatever I've used them for. So, if I don't care about which SCM, why blog about them at all? Because I care about how they get used. I'm a big fan of small granular commits with descriptive commit messages. Not huge big dumps of code with "check in new code" as the comment. Gah. Take, for example, the Linux kernel. Commit messages are fairly descriptive there and if you have enough time you can read through the changelog since the last release and really know what's gone on. This is great. Also the changes are granular enough that if you hit a problem it's likely that you can narrow it down to a single commit that doesn't do a lot other than break things for you. Not all projects I have been part of manage either of these. People often seem to view the SCM as a punishment, using it only under sufferance and as infrequently as possible, leading to large commits of many items at once. Which then means they don't see the advantages of it and are more likely to hit merge problems as the tree has changed under them. Meaning they end up hating it more and avoiding it as much as possible, making it all worse. Not good. Or, you get people who'll commit alright, but without any sanity testing at all. Like, even a compile. What's the point? I know you can roll it back, but if you're not sure it works and haven't even compiled it, what the hell makes you think it's suitable for committing? Bah. I can't see that my desired usage is that unreasonable. Am I missing something?

Aigars Mahinovs: Another idea came to me in shower - I've been read...

Another idea came to me in shower - I've been reading up about MS Office 12 UI changes and I think there are some very nice ideas there, but we can do better.
The main principle of the Ribbon is that all functions are there, but some are smaller then others based on their priority.
It came to me that when you design an UI in, for example, Glade you are basically creating a dynamic structure that can scale up or down. The only two things missing to make it a Ribbonesque interface are: 1. unique priority for each widget to decide which widgets to reduce/increase in size, 2. multiple size versions for each widget - buttons from 128x128px to 16x16px, ...
For situations when 16x16px is not enough for the widget (editbox, for example) one could make a micro button that brings up the rest of the widget as a popover when pressed or simply not show the widget. Less important widgets would simply not be displayed at smaller screen/window sizes (hidden behind a generic "+" icon meaning more functions in a category).
This would allow an application to use those huge screens of the future for bigger and more detailed buttons/widgets and at the same time would increase usability of applications at small screen sizes. Or maybe I am just thinking too far.

13 December 2005

Matthew Palmer: Diversity in Revision Control

Josselin Mouette has thrown down the gauntlet -- Subversion is the One True Revision Control System and we should all just Stop Worrying and Learn To Love The Handcuffs. In particular:
[...] just use subversion, and if you feel it's missing features, please contribute them. By standardizing on subversion, we lower the barrier for people wanting to contribute, instead of increasing it by asking them to install and understand new tools.
Quick thought experiment, Josselin: replace "subversion" with "Java". Or "Perl", or "C", or even "Python" or "Ruby". Or any other language. It doesn't matter which one. Even if the language you substitute is a good one, and one you happen to like, it's still a fairly obviously braindead idea -- that there can possibly be One True Programming Language for all problems, and that there can never be any improvement that can't be bolted into the existing OTPL. Revision control isn't so much different from programming languages. Different systems will provide different advantages and disadvantages. There's also incremental and revolutionary improvement that will take place over time -- machine code to symbolic to procedural to object oriented -- that can never take place within the established framework. I happen to really like the distributed model -- it reduces (though, naturally, cannot eliminate) the division between the Blessed and the Peons in a project (those with direct commit access vs. the rest of us). You can get disconnected operation for (almost) free. Also, despite the assertions contained in your article, the "barrier to entry", ironically, is actually lower with a good distributed RCS than with Subversion. The barrier isn't what you think, though -- sure, using an unfamiliar RCS is troublesome, but it's a lot less hassle than learning a new language, and people do that on occasion to hack on a particularly interesting problem. The real barrier to entry is forcing anyone who isn't blessed with direct access to The One And Only Repository to use inferior development support tools. "An example!" I hear you cry. Gladly. This morning (literally) I got enough of a handle on the internals of Ruby on Rails to actually track down a bug that was irritating the crap out of me. Being a good developer, I wanted to use revision control to track my changes. In the All Subversion, All The Time "utopia", that would involve getting an anonymous checkout, making a copy, hacking on the copy, then (when all was done) running diff -urN between the original and the copy, and sending it all upstream with a manually-created log message (assuming I could remember everything I'd done). You also need to manually remember (or encode it in your directory or something) the source of your tree, so upstream can merge it reliably (and compare it against other equivalent work that may have been done in the meantime). Doing it better, I could do an anonymous checkout, and then import it all into a new Subversion repository (or directory) of my very own, and hack on it in there. Benefit: revision control of my changes. But it's non-trivial to create a new repo and import everything into it, and there's still no automatic record made of the upstream source of my new repo. Wanting to make a second change is even worse -- I either have to make a whole new copy of my source tree (disk is cheap, but this is getting silly) or just keep forging ahead with changing my existing tree -- so this second set of changes can end up being dependent on the first (which is Not So Great if upstream don't merge your first patch). In the "new repo" scenario, you can branch from the root of your new repo and continue hacking on your newly created branch, which is a good start, but it's still icky. And good luck having the system track new commits from upstream while you're working, too. If the project was using a DRCS, in contrast, the problem would reduce to making a branch into your local archive, hacking (committing at will), updating with new upstream commits as you go along, and then publishing your changes to a public place for reintegration (or, in some cases, sending your changeset via e-mail). Oh, and before anyone starts screaming "if anyone can branch, it will encourage forking!", consider which is more likely to result in a permanent fork (rather than a temporary independent line of development): a local set of changes in a tarball or local subversion repo, both of which are hard for anyone else to collaborate on without major pain; or a branch in a simple-to-publish (or push) designed-to-be-shared DRCS archive, which automatically keeps all of your interesting metadata intact and coherent across archives, merges, time, and space (and possibly even dimensions). This utopia doesn't really exist, and is hampered by everybody having their own Pet DRCS, but the problem, I'm fairly sure, is transient, and my main point isn't even so much against the choice of Final Ultimate Solution, or even the problem space, but more about the attitude that everyone should get behind Any One System and stay there. I can't imagine the world of pain we'd be in if Josselin had posted his message a few years ago (but with s/subversion/CVS/i, naturally) and everyone had followed his advice -- can you imagine per-file changesets with no effective merge capability for the rest of eternity? <shudder />
11 December 2005

Thomas Hood: NM clarification

In light of criticisms I would like to confirm that of the twenty-eight months I was in NM, many months were spent by me answering questions. I didn't mean to leave the impression that I have been waiting for actions by Debian for that whole time. In fact I have only been waiting seven months for the latest step, for example. These criticisms have made me realize that what I was seeing as bureaucracy was really just sublimated awareness of my own failings, projected onto a system that any objective observer would agree is fulfilling its mission. I just have to admit not everyone has the right stuff for this job. The title 'Debian Developer' has to stand for something. Something strong. And it's the job of the New Maintainer process to keep Debian strong. Of course this means that some people won't make it. But dammit, Debian is just too important.

Andres Salomon: debian take-out

It amuses me that people are arguing with others about whether Debian “delivers” what it promises its users. Sarge was released on June 6, 2005. Since then, there have been exactly 0 kernel security updates for it. Meanwhile, Ubuntu has managed to release 7 kernel security updates in that timeframe (USN-137-1, USN-143-1, USN-169-1, USN-178-1, USN-187-1, USN-199-1, and USN-219-1). Each one of those fixes at least two or more real vulnerabilities (some fixing as many as ten!). So here we are, 6 months after the release of Sarge, and we’re not fulfilling our promise of a distribution that lacks known security holes. Furthermore, talks with our Security Team (which is, as far as anyone can tell, one active person) have gotten us nowhere; the DPL himself has attempted to do so, and was told that a kernel update is “in progress”. The sad part of this is the fact that the Security Team thinks there is no problem; once a kernel update is complete, everything will be OK. The lack of a kernel updates is merely a symptom of larger problems within Debian; key people do not scale, work in a closed manner, and are not willing to delegate responsibility. Meanwhile, the Testing-Security Team has managed to provide a wonderful example of how a security team could work, in many instances beating the stable Security Team to release fixes. I could go into how much fun it was for me to wait 10 months to get DAM approval in the NM queue, how I’m being forced to run Ubuntu on a server because Debian still hasn’t gotten its act together with respect to AMD64, and other such things, but it all comes down to the same core problem.

10 December 2005

Andrew Pollock: [life/americania] Three weeks

I've been so busy, I haven't had time to blog. Rather than putting it off any longer, I'll just dump what I can remember. Last Wednesday, Sarah arrived after her holiday in Singapore, and from all accounts, had a great time. Photos as well. Sticking with the whirlwind theme, the next day, we had a "building warming" party at work for the new building we'd moved into the week before Michael and I started. The next night we had the work Christmas party, which blew the socks off any work Christmas party I'd ever been to before, and then on Saturday night we went to a party in San Francisco that we'd been invited to. On a life in general front, I'm still waiting for a Social Security number. The lack of one makes life a bit difficult for a lot of things. It also turns out that Sarah's work permit will take about 90 days to approve, so she's going to be a lady of leisure for the next few months. I've finally been issued with a work mobile phone (or "cell phone" as they call them), and so can stop roaming and paying through the nose for the privilege. We've found somewhere to live. We take possession of a 2 bedroom townhouse (split-level) in a complex in Mountain View that is 3 miles from work on the 18th. The rent is $1725 a month, which is a bit better than we were expecting. The complex we're renting in does have shared laundries, which we'd not too keen on before getting over here, but they're quite modern and secure, and there's a laundry block close to our townhouse, so hopefully it won't be too bad. The whole place had been renovated about 5 years ago, so it's all in good condition. We could have rented a 3 bedroom apartment (single level) in the same complex for about $125 a month more, but we're trying to actually make some money while we're over here... Driving on the other side of the road becomes fairly "normal" after about a week of doing it regularly. Sarah's adapted fine. Lane placement is the hardest thing, because your body's used to being in a certain spot on the road, and it's all different sitting on the other side of the car. We've managed to open a rudimentary bank account, even with my lack of Social Security number. Unfortunately I can't get paid until I have an SSN. Upside of that is that if it doesn't happen until next year, I presumably won't have to worry about income tax for this US financial year. Downside is kind of obvious... By far one of the stranger things of everyday life here is the lighting situation in the average residence. Lamps are all the rage, to the point that light switches don't exist in some rooms (notably bedrooms). Take where we're currently living for example. There's a light switch at the bottom of the stairs, there's one at the top. There's a bank of four in the living room, two of which control lights in the kitchen, and one the hallway. The last one controls a lamp in the corner of the living room, which is connected to a power socket (or power point as we'd call it). The bedroom with the attached bathroom (en suite) has two bedside lamps, and that is the sole source of light. The bathroom attached has light switches, and the walk-in robe has a light switch. It's so weird. So walking into a darkened bedroom involves walking all the way in, and fumbling around with a lamp. It's often easier to turn on the light in the wardrobe so you can see what you're doing first. I can't think of any reason for it, except tradition. It's not like they're avoiding wiring the walls or the ceiling, because it's done partially already. The bedroom has a ceiling fan, but where in Australia, there'd be a knob on the wall near the light switch to control it, it has a little chain you yank on. To add to the strangeness, there are two switches on the wall, one of which seems to allow you to turn off the ceiling fan if it's already been switched on by pulling the chain. The townhouse we're renting has a similar lamp dependency, so we're going to be making a trip to Ikea for some lamps it would seem. That's about everything I can recollect right now... Oh, I should point out that I'm really loving it over here.

9 December 2005

Adam Rosi-Kessel: Windows Live Maps

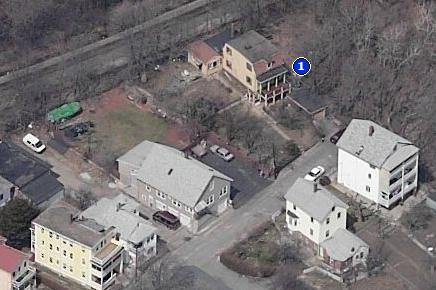
I just checked out the new Windows Live Local—Microsoft’s answer to Google Maps. The interface is a little clunky, but the flyby image quality is amazing. Here’s my house on Windows Live (by the number 1): The same location, at the maximum magnification from Google Maps: Google is going to need to invest in some better images. I think what this proves is that even Google needs some competition. Interestingly, neither of these images shows the 9-unit condominium complex that replaced the duplex across the street from us. The duplex was demolished more than a year ago.

8 December 2005

Lars Wirzenius: Personal life: Programmer survival skills

I have a talk today at the Jyv skyl university about programmer survival skills. My talks page has the original Finnish slides, the link in this log entry is to the quick translation to English I made. Note that when I make slides for a talk, they don't always contain the entire presentation. For example, there is no indication in the slides that I removed my tie after the first non-title slide, or that that slide was presented in a very monotonous voice, because I wanted to create an effect. If the slides don't make sense, it might be because they're missing something important.

7 December 2005

Anthony Towns: On Joey on Permissions

At the end of an interesting piece on permissions, Joey Hess concludes:
I could give many more examples of subsystems in Debian that exist at different point in the spectrum between locked down unix permissions and a wiki. There seems to be a definite pull toward moving away from unix permissions, once ways can be found to do so that are secure or that allow bad changes to be reverted (and blame properly assigned). Cases of moving in the other direction are rare (one case of this is the further locking down of the Debian archive server and BTS server after the server compromise last year).
I think Joey’s focus on “unix permissions” is a bit misleading; you could make the same argument more generally by talking about permissive and restrictive regimes. Permissive systems have the obvious risk of vandalism in various forms, whether deliberate and malicious like adding false information to wikipedia, or well-intentioned contributions that are low quality due to simple ignorance or carelessness. On the other hand restrictive systems have the somewhat subtler risks that good contributions will be turned away because the restrictions are more effort than they’re worth, and that the time it takes to administer the restrictions start detracting from the time to actually do the work in the first place. So obviously there’s a tradeoff. But as well as that, there are ways of easing both risks: the risk of vandalism can be overcome if the stuff isn’t relied upon too heavily and can be changed relatively easily – so problems in unstable aren’t much of an issue since they can be fixed in a day, and don’t affect people running mission-critical systems because they should be using stable or testing or similar. Likewise, managing restrictions can be distributed too: the new-maintainer process is a good example of that, in that a range of people are involved in helping people pass through the qualification round, and in that sponsorship allows people who haven’t passed through the main lot of restrictions to get their contributions in by going through a different process. One interesting approach, to my mind, is worrying less about permissions and more about space – so that different people with different ideas on how to do things can do them independently. That’s part of the idea behind usertags and usercategories: rather than having people try to find an imperfect compromise, let them work on the same stuff in the way they actually prefer. That reduces the risk of carelessness, in that you stop having any reason to bother other people, and also reduces the problem of restrictions, in that if you don’t have permission to work in someone else’s area, you can just setup your own area and work there. Perhaps the worst problem is if the drawbacks feed on each other: a restrictive system turns away contributions, which causes prospective contributors to get frustrated and hence careless, which then reinforces the reasons that the restrictions were put their in the first place and diminishes the chance they’ll be reconsidered. That’s a hard cycle to break, but it’s not one where anyone really wins. I’ll leave the last word to Joey:
Anyway, the point of this is that, if you survey the parts of dealing with the project where Debian developers feel most helpless and unempowered, the parts that are over and over again the subject of heated discussions and complaints, you will find that those are the parts of the project where unix permissions still hold sway. […] The challenge, then is to find ways to open things up to everyone, without throwing security out the window. It has to be done a piece at time, and some of the pieces that are left are the ones most resistant to this change.

Radu Spineanu: Mailman madness

A couple of days ago, a client decided that he wanted one click unsubscribe for all his mailing lists. We used mailman and from what i found googling about it, this is mostly an idea in the minds of the developers. Unfortunately i could not wait until Mailman 3 or 10 appeared. I had to implement it this week.

Actually in the end, the result was pretty simple to do, even though it's rather basic. The idea was that the client did not like the mailman web interface, and wanted to integrate it with his own website (just basic subscribe unsubscribe features).

So i wrote a small patch (3 or so lines) to mailman, that adds a new field to decorate called %(hash) that is the users password crypted.

The interface between the web address in the mail and mailman is done through a directory where requests are placed. For example when a user clicks a link, a php script does some basic checking and places a file in $client_web/list_requests, or a global requests directory. The idea for this part was to be very easy for the user to implement.

Another small python script looks (through cron) in those directories, checks hashes in case of unsubscribing, and procceses the requests.

6 December 2005

Joey Hess: ending the tyranny of unix permissions

In Debian, we work on developing a unix-style operating system, and when the project was getting started, the obvious way to deal with delegating powers to various people was naturaly to use standard unix permmissions on our master server. So the list administrators were the only people who could write to the list configs and archives, the BTS admins were the only ones who could write to the BTS, the archive admins were the only ones who could manipulate the archive, the build daemon admins were the only ones who could modify various bits of that stuff, etc. As time went on, these services were split off to seprate machines and in some cases access to the machine running a service was limited to the maintainers of that service, again in a way that would be familiar to unix admins everywhere. But as time went on and things like revision control systems became available, Debian also began to make some choices that didn't involve unix permission or host based security. The best example of this is the Debian bug tracking system, which allows anyone to manipulate any bug status in any way without any authentication at all. It works because the BTS keeps a record of all changes, and informs interested parties about changes, so vandalism or accidents can be reverted. Aside from spam, vandalism in the BTS is such a rare problem that I cannot think of an example. Thus the Debin BTS partakes somewhat of the WikiNature, although it predates the wiki by a long time. The archive itself only uses unix permissions at its core, while the upper layers do not partake of them: Any maintainer can upload any package and superscede data in the archive automatically, although actual unix write permissions are very limited. The archive administrators use archives of old versions of packages, automated checks, and forced manual review of certian classes of packages (such as NEW) to limit this so that Developers don't make messes. Social norms are used to avoid other problems. The Debian website is in an interesting period in its history. It's been maintained in a way that mostly avoids unix permissions for a long time, by keeping it in CVS and building it automatically. However, for reasons that I suspect have never been adequately explored, not all Debian developers can commit, you have to be in the webwml group. Though gaining access to the webwml groupo is trivial for any Debian developer. But the most interesting thing is that Debian now also has an official wiki, which is open to editing by all, and that increasingly it is used for at least the more fluid and development-based website stuff. For example, the debian-installer home page is a thin stub giving the essential information and links, and mostly linking to the wiki for the rest. The debian-installer project itself occupys another point on the scale between locked down unix permissions and free modification by all. People have to get an alioth account and demonstrate basic competance to get debian-installer write access, but don't need to be Debian developers or spend more than an hour or so to get access. Once you have access, you can change anything in svn (and everything is in svn) we don't limit write access to parts of the project. We avoid malicious commits through patch review. I could give many more examples of subsystems in Debian that exist at different point in the spectrum between locked down unix permissions and a wiki. There seems to be a definite pull toward moving away from unix permissions, once ways can be found to do so that are secure or that allow bad changes to be reverted (and blame properly assigned). Cases of moving in the other direction are rare (one case of this is the further locking down of the Debian archive server and BTS server after the server compromise last year). Anyway, the point of this is that, if you survey the parts of dealing with the project where Debian developers feel most helpless and unempowered, the parts that are over and over again the subject of heated discussions and complaints, you will find that those are the parts of the project where unix permissions still hold sway. This can range from simple cases such as a cron job that only one person can look at and modify[1], to various data files that could perhaps be kept in svn, but aren't, all the way through to stuff like the Debian keyring. I would love to see a full list developed, although many of the things that remain are obscure little corners like certian blacklists in the BTS, bits of the buildd infrastructure that only a half dozen people know about, etc. The challenge, then is to find ways to open things up to everyone, without throwing security out the window. It has to be done a piece at time, and some of the pieces that are left are the ones most resistant to this change. I hope that people can keep this progression away from unix permissions in mind while working on Debian infrastructure. (If I ever ran for Debian Project Leader (which I won't), this would be one of the areas that I would be sure to investigate basing my platform on. Speaking of which, it's nearly election season again, isn't it?)
[1] The best solution I have found to this common problem so far is simply to keep the cron job in svn with everything else, and if someone modifies it, review it and update it via semi-automated means (some simple command). There are probably better ways to do it.

MJ Ray: Safe Cycling Quiz Considered Harmful

The local BUG linked to a safe cycling quiz. I had a few problems with it because it needs javascript as well as the disclosed cookie requirement: PHP could do this without both, so I think it's slightly bad programming; but eventually I went through the questions. I was rather surprised to score only just over 50%. After reviewing the questions, it turns out that it's not because I do things seriously wrong: it's more that the question-setter seems a bit militantly anti-car and assumes that cycle lanes and cycleways won't be built to the national standard. To be fair, most are substandard, but I assumed the examples in the test questions were OK, in the absence of other information. I also disagree about the message sent by moving right on the approach to a narrow. It seems to make some drivers think you're going to make a right turn using the island as a refuge, so they move to undertake, which is really dangerous. They shouldn't overtake too near the island if your normal road position is good.

4 December 2005

Erich Schubert: One more note on firewalls

Most workstations are well-served with firewall rules like this:
*filter
:INPUT DROP
:FORWARD DROP
:OUTPUT ACCEPT
-A INPUT -i lo -j ACCEPT
-A INPUT -m state --state RELATED,ESTABLISHED -j ACCEPT
COMMIT
Yes, this is just two rules. Use iptables-restore to load. No need to fire up a complex firewall builder tool for that. ;-) The first input rule enabled loopback traffic, the second allows data traffic for established and related connections (ftp data channels for example). If you want to allow incoming SSH, add
-A INPUT -p tcp -m tcp --dport 22 -j ACCEPT
Oh, unless of course you want to run filesharing and such. You might want to allow incoming connections on other ports as well.

Enrico Zini: Shell gotcha

Today I was puzzled as I found out that the bash one-liner A=foo echo $A does not print 'foo'. The answer came thanks to Vorlon and Wiggy: A=foo echo sets A in the environment of the echo command, and echo $A passes the value of $A in the shell as an argument to echo. $A is expanded before the line is run and at that time A=foo hasn't been processed yet. One quick fix is doing A=foo; echo $A, but this leaves A set to foo after the execution of the command. To make it so that A is foo only when executing echo, one can use parenthesis: (A=foo ; echo $A):
$ (A=foo; echo $A); echo $A
foo
$
(note: the boring presence of "foo" in these examples should be taken as a reminder of my call for no-op words)

3 December 2005

Uwe Hermann: Some of my photos on flickr

Quake Level
Oldtimer
Escher lookalike architecture
Yes, I finally got a (free) flickr account and uploaded some of my favorite photos from my photoblog to my flickr page. This has several reasons: Note: My photoblog will not die, I will continue posting new stuff there. I'll just use the flickr page for some selected shots. There's an RSS feed for the flickr page, if you want track my photos.

2 December 2005

Steve Kemp: Torrents + Perl

BitTorrent
BitTorrent is one of those applications that most people love. I love it when it works but I find it unnecessarily cumbersome to deal with. One example of what I dislike in the software - you can’t tell when a torrent has finished. Start a download:
btdownload curses headless  foo.torrent
Once the download has finished it doesn’t stop, it just continues to share the files and allow others to download faster. Great 99% of the time. But utterly sucky when you want to download XX files. The natural temptation is to run:
for i in *.torrent; do \
  btdownloadheadless $i
done
That doesn’t work. The first one never finishes. There isn’t even the option of exiting once the download has completed - or running another command, say. (OK my copy has “–at_finish=/bin/foo” - but only because I patched it. This just seems like a basic requirement, right?) Despite that it works well so I can live with it. My other irritation is that there is no functioning Apache mod_bittorrent where files into a directory have their .torrent files created and handled magically. There was a project to do this, but it appears dead now. Shame. Every now and again I get tempted to work on it, then I remember that I have big limits.
ION
Lots of Perl coding today. Simple plugin interfaces, and cleanups of old code. Almost enough to keep me awake.

David Pashley: OOP Strikes Back

Steinar, you missed my point. I explicitly said not to get bogged down in my example. The point is that changing the internal details of your class shouldn't result in your users being forced to change their code. As I said, exposing your implementation tightly couples your code and your users. As Matthew pointed out, you shouldn't have sets and gets for every item in your class. You should have a clearly thought out api that isn't tied to the internal detail. Exposing internal, either through making data public or blindly creating gets and sets for private data members is just bad OO design. An addition to my example that makes things little cleared would be a subclass that validated the words you could use. With a public variable I couldn't enforce that, but I could override my setter to add validation.

1 December 2005

Matthew Palmer: OOP and the Get/Set issue

Steinar, your comments on the limited utility of Get/Set methods both struck a chord and touched a nerve with me. On the one hand, I completely agree that people need to spend more time writing methods that do something useful to an object rather than just exposing public methods. For example, how often have you seen something like this (in faintly python-inspired syntax):
 obj.count += 1
 [...]
 obj.count -= 1
 [...]
 if obj.count == 0:
 	obj.destroy
Instead of the far more descriptive (and well-encapsulated):
 obj.register_user()
 [...]
 obj.unregister_user()
 [...]
 obj.destroy_if_unused()
(or any one of a thousand other similar idioms). This is a contrived example, of course, and a real example would involve doing at least a dozen operations on an object's public attributes from another class (which results in class-associated logic being located in other classes in the system) instead of putting it in a method and calling that (thus keeping all of the logic with the data it's manipulating -- which is the point of OOP). Anyone who writes code like the first example above and calls it OOP is kidding themselves. Of course, you could make the code even more ridiculous with getter/setters:
 obj.setCount(obj.getCount()+1)
 [...]
 obj.setCount(obj.getCount()-1)
 [...]
 if obj.GetCount() == 0:
 	obj.destroy
Incidentally, if you ever see anyone turn the first example into the last example and say they're "improving encapsulation", please do the programming world a favour and kill them. kthx. On the other hand, Steinar, you say "I'm not denying that getters and setters for a few variables might make sense", which clouds the issue immensely. The idea of routing attribute access through a method is immensely useful. It even has it's own name -- the Uniform Access Principle. A few examples are in order (you might already have thought of these, Steinar, but who knows who reads my dribblings!): In my real-life case, there were few enough places to change all of the calls to a method, and since it's all written in Python I could have played __getattr__ games to get back to a method if I'd had to, but it would have been messy. But imagine a system written in a language that doesn't (somehow) support the Uniform Access Principle, and which was widely deployed (possibly even used by programs outside of our direct control) so the users of the class couldn't be adapted easily. Nightmare. Now, the real solution to the problem is to only use languages which support the UAP (Python can be hacked to do it; Ruby is, IMHO, almost a case-study in How To Do It; and there are other good languages out there). But, in ass-backwards languages that can't transparently map attribute accesses to method calls, I'd rather deal with getX()/setX() everywhere than have to try and perform the necessary gymnastics to later support dynamic value generation from what-was-previously-an-attribute. If, on the other hand, your post was primarily targeted at said ass-backwards languages, or programmers who cargo-cult manual getter/setters everywhere, let me join you in your derision. <grin>

David Pashley: Return of Accessors vs. public member variables

Steinar, Imagine a Word class:
class WordA  
   public:
      char * word;
 ;
class WordB  
   private:
      char * word;
   public:
      void setWord(char * w)   word = w;  
      char * getWord()   return word;  
 ;
WordA worda; 
worda.word = "WordA";
WordB wordb;
wordb.setWord("WordB");
printf("%s %s", worda.word, wordb.getWord());
Fine, this works well. Now imagine that you want to change word from a char * to a std::string to stop you dealing with pointers. For the WordBclass you only need to change the getWord function. You don't need to change any of your class's users. For the WordA class, you have a problem because you can't automatically convert from a std::string to a char *, so all your users have to change from object.word to object.word.c_str().
class WordA  
   public:
      std::string word;
 ;
class WordB  
   private:
      std::string word;
   public:
      void setWord(char * w)   word = w;  
      char * getWord()   return word.c_str();  
 ;
WordA worda; 
worda.word = "WordA";
WordB wordb;
wordb.setWord("WordB");
printf("%s %s", worda.word.c_str(), wordb.getWord());
This is the punishment you get for exposing the internal details of your class to your users. Please ignore any specific mistakes in my examples; the principles work the same with different types.

Matthew Palmer: A trace mixin for Python

Although I am by means an expert Python programmer, I do dabble -- at the moment, I'm dabbling fairly heavily in a project for work. I had need, as you do on occasion, for a call trace (I called this method, it returned X, I then called this other method, it returned Y, and so on). Astoundingly, I got no answer when I asked on #python, as I would have expected this sort of thing to be a gimme -- even possibly including it as a core language feature. But nary an answer was forthcoming. Searches for mixins or magic function calls which might solve my problem were similarly fruitless. I resigned myself to manually sticking print wrappers around the function calls of interest, but that got old real fast (especially after I spent about a half-hour chasing my tail because I'd forgotten to return the return value after I printed it). As usual, my subconscious saved the day. On the train home this afternoon, I suddenly had a brainwave, and the code which I've reproduced below appeared almost fully-formed at my fingertips. It's times like this that I really enjoy programming. Now, of course, someone will pop up and say "oh here it is over here", or "you just set the __trace_me_baby__ attribute on your object", but I can console myself with the fact that I know a lot more about grubby Python internals than I did before. The code: (a pre-saved version is also available).
# tracemixin.py
#
# A python mixin to trace the calling of methods.
#
# Copyright (C) 2005 Matthew Palmer 
#
#   This program is free software; you can redistribute it and/or modify
#   it under the terms of the GNU General Public License as published by
#   the Free Software Foundation; either version 2 of the License, or
#   (at your option) any later version.
#
#   This program is distributed in the hope that it will be useful,
#   but WITHOUT ANY WARRANTY; without even the implied warranty of
#   MERCHANTABILITY or FITNESS FOR A PARTICULAR PURPOSE.  See the
#   GNU General Public License for more details.
#
#   You should have received a copy of the GNU General Public License
#   along with this program; if not, write to the Free Software
#   Foundation, Inc., 51 Franklin St, Fifth Floor, Boston, MA  02110-1301 USA
#   or see http://www.gnu.org/licenses/gpl.html
#   
"""
A mixin class to permit the tracing of method calls on an object.
This class, when mixed in, overrides the default operation of method calls
so that requests to call methods which have been listed in the
self._traced_methods list will be printed with their arguments and return
values.  Also included is a simple call depth indication, using indents.
Tracing of particular methods can be turned on and off on a per-object basis
by simply including or removing the method's name in the _traced_methods
list on the particular object.  Whole classes can be traced by setting
the list as a class attribute.
To include this class, simply make it the first class name in the list of
parent classes when defining a new class, like so:
class Something(TraceMixin, RealParentClass):
You could probably leave the TraceMixin in your production code, although
it'll slow execution down by a bit.
Complete usage example:
from tracemixin import TraceMixin
class RandomTask(TraceMixin):
	def x(self):
		print "X!"
	
	def y(self, arg):
		print "%s Y!" % arg
		self.x()
x = RandomTask()
x.x()
x._traced_methods = ['x', 'y']
x.y('why?')
Output:
X!
::y(why?)
why? Y!
  ::x()
X!
  =>None
=>None
"""
class TraceMixin(object):
	_traced_methods = []
	_depth = 0
	def __getattribute__(self, attr):
		if attr in object.__getattribute__(self, '_traced_methods'):
			self.method = attr
			attr = '_trace_proxy'
		return object.__getattribute__(self, attr)
	
	def _trace_proxy(self, *args):
		realmethod = object.__getattribute__(self, self.method)
		if realmethod and realmethod.__class__ == self._trace_proxy.__class__:
			print "%s::%s(%s)" % (self._depth*'  ', self.method, ', '.join(args))
			self._depth += 1
			rv = realmethod(*args)
			self._depth -= 1
			print "%s=>%s" % (self._depth*'  ', rv)
			return rv
		else:
			raise AttributeError

Next.

Previous.