Search Results: "tar"

11 June 2013

Rog rio Brito: Working with CVS via Git

The easiest way of using git locally to commit to a CVS repository is to have both a git clone of the CVS repository and a CVS checkout of your repository. Initial steps that Work for Me (TM)
  1. Create your git clone of the CVS repository:
     git cvsimport -v -a -A /tmp/lame-authors.txt -k -m -d \
         :ext:rbrito@lame.cvs.sourceforge.net:/cvsroot/lame lame
    
    The command above will create your clone of the CVS repository in the current directory which we suppose, for the sake of this discussion, is /tmp/gitified. If want to specify a directory different than what you're in, then you should add the option -C /path/to/git/repository.
  2. Create a checkout of the CVS repository for CVS work stuff (I'm checking out things under /tmp):
     cvs -z3 -d:ext:rbrito@lame.cvs.sourceforge.net:/cvsroot/lame checkout lame
    
    This will create your CVS checkout on the directory /tmp/lame, assuming that you are working under /tmp, as I do.
Doing real work
  1. Go to your git clone (/tmp/gitified) and start hacking, committing, etc.
  2. When it is time to send your patches to the CVS repo, you have to:
     export GIT_DIR=/tmp/gitified/.git
     cd /tmp/lame
     git cherry origin master   sed -n 's/^+ //p'   xargs -l1 git cvsexportcommit -c -p -v
    
    This will automatically check in all the commits that you have made in the previous step.
Continuing your work afterwards
  1. First, discard your commits in your git repository, so that you don't get further problems with git cvsimport.
  2. Update your git repository with the current contents of the CVS repo:
     cd /tmp/gitified
     git cvsimport -v -a -A /tmp/lame-authors.txt -k -m -d \
         :ext:rbrito@lame.cvs.sourceforge.net:/cvsroot/lame lame
    
  3. Update your CVS repository with the current contents of the CVS repo too:
     cd /tmp/lame
     cvs update
    
Conclusion Of course, I would prefer a simpler, leaner workflow. If you happen to have one, please let me know.

9 June 2013

Paul Tagliamonte: Automatically lint your packages with debuild.me

Over my time working with Debian packages, I've always been concerned that I have been missing catchable mistakes by not running all the static checking tools I could run. As a result, I've been interested in writing some code that automates this process, a place where I can push a package and come back a few hours later to check on the results. This is great, since it provides a slightly less scary interface to new packagers, and helps avoid thinking they've just been told off by a Developer. I've spent the time to actually write this code, and I've called it debuild.me. The code itself is in its fourth iteration, and is built up from a few core components. The client / server code (lucy and ethel) are quite interconnected, but firehose works great on it's own, and is a single, unified (and sane!) spec that is easy to hack with (or even on!). Hopefully, this means that our wrappers will be usable outside of debuild.me, which is a win for everyone. Backend Design The backend (lucy) was the first part I wanted to design. I made the decision (very early on) that everything was going to be 100% Python 3.3+. This lets me use some of the (frankly, sweet) tools in the stdlib. Since I've written this type of thing before (i've tried to write this tool many, many, many, many times before), so I had a rough sense of how I wanted to design the backend. Past iterations had suffered from and overly complex server half, so I decided to go ultra minimal with the design of debuild.me. <aside class="left"> You can find the code for the server (lucy) on my GitHub </aside> The backend watches a directory (using a simple inotify script) and processes .changes files as they come in. If the package is a source package, a set of jobs are triggered (such as lintian, build and desktop-file-validate), as well as a different set for binary packages (such as lintian, piuparts and adequite). Only people may upload source packages (without any debs) and only builders can upload binary packages (without source). The client and server talk using XML-RPC with BASIC HTTP auth. I'm going to (eventually) SSL secure the transport layer, but for now, this will work as a proof of concept. Since I tend to like to keep my codebase simple and straightforward, I've used MongoDB as Lucy's DB. This lets me move between documents in Mongo to Python objects without any trouble. In addition, I evaluated some of the queue code out there (ZMQ, etc), and they all seemed like overkill for my problem, and had a hard time keeping track of jobs that (must never!) get lost. As a result, I wrote my own (very simple) job queue in Mongo, which has no sense of scheduling (at all), but can do it's job (and do it well). Jobs describe what's to be built with a link to the package document that the job relates to, and it's arch and suite (don't worry about the rest just yet). Jobs get assigned via natural sort on it's UUID based _id, and assigned to the first builder that can process it's arch / suite. Source packages are considered arch:all / suite:unstable (so they always get the most up-to-date linters on any arch that comes along). Lucy also allows for uploads to be given an X-Lucy-Group tag to manage which set of packages they're a part of. This comes in handy for doing partial archive rebuilds, or eventually using it to manage what jobs should be run on which uploads. This will allow me to run much more time-consuming tools for packages I want to review versus rebuilding to ensure packages don't FTBFS or aren't adequite. Client Design The buildd client (ethel) talks with lucy via XML-RPC to get assigned new jobs, release old jobs, close finished jobs, and upload package report data. When the etheld requests a new job, it also passes along what suites it knows of, which arches it can build, as well as what types it can run (stuff like lintian, build or cppcheck.) Lucy then assigns the builder to that job (so that we don't allocate the same job twice), and what time it was assigned at. <aside class="right"> You can find the code for the client (ethel) on my GitHub </aside> Ethel then takes the result of the job (in the form of a firehose.model tree) and transmits it over the line back to the Lucy server as a report (which also contains information on if the build failed or not), at which point lucy hands back a location (on the lucy host) that the daemon can write the log to. If the job was a binary build, the etheld process will dput the package to the server, with a special X-Lucy-Job tag to signal which job that build relates to, so that future lint runs can fetch the deb files that the build produced. Tooling Ethel runs a set of static checkers on the source code, which are basically fancy wrappers around the tools we all know and love (like lintian, desktop-file-validate, or piuparts) which output Firehose in place of home-grown stdout. This allows us to programmatically deal with the output of these tools in a normal and consistent way. <aside class="left"> You can read more about Firehose over in the Firehose README.rst </aside> Some of the more complex runners are made of 3 parts - a runner, wrapper and command. The server invokes the command routine, which invokes the runner (the command just provides a unified interface to all the runners), who's output gets parsed by the wrapper to turn it into a Firehose model tree. The goal here is that tons of very quick-running tools get run over a distributed network, and machine-readable reports get filed in a central location to aid in reviewing packages. Ricky In addition to the actual code to run builds, I've worked on a few tools to aid with using debuild.me for my DD related life. I have some uncommon use-cases that are nice to support. One such use-case is the ability to rebuild packages from the archive (unmodified) to check that they rebuild OK against the target. This is handy for things like arch:all packages that get uploaded (since they never get rebuilt on the buildd machines, and FTBFSs are sadly common) or packages that have had a Build-Dependency change on them. Ricky is able to create a .dsc url to your friendly local mirror, and fetch that exact version of the package. Ricky can then also use the .dsc (in a monumental hack) to forge a package_version_source.changes file, and sign it with an autobuild key and upload it to the debuild.me instance. Since it can also modify the .changes's target distribution, you can also use this to test if a package will build on stable or testing, unmodified. Fred Fred is a wrapper around Ricky, to help with fetching packages that may not exist yet. Fred also contains an email scraper to read off such lists as debian-devel-changes, and add an entry to fetch that upload when it becomes available on the local mirror, pass it to ricky, and allow debuild.me to rebuild new packages that match a set of criteria. I'm currently playing around with the idea of rebuilding all incoming Python packages to ensure they don't FTBFS in a clean chroot. Loofah Loofah is also another wrapper around Ricky, but for use manually. Loofah is able to sync down the apt Sources list, and place it in Mongo for fast queries. This than allows me to manually run rebuilds on any Source package that fits a set of critera (written in the form of a Mongo query), which get pulled and uploaded by Ricky. An example script to rebuild any packages that Build-Depend on python3-all-dev in Debian unstable / main would look like: <aside class="right"> You can find more queries in the Loofah examples </aside>
[
      "version": "unstable", "suite": "main"  ,
      "Build-Depends": "python3-all-dev"  
]
Or, a script to rebuild any package that depends on CDBS:
[
     ,
     "$or": [ "Build-Depends": "cdbs" ,
              "Build-Depends-Indep": "cdbs" ] 
]
You can use anything that exists in the Sources.gz file to query off of ( including Maintainer!) Future Work The future work on debuild.me will be centered around making it easier for buildd nodes to be added to the network, with more and more automation in that process (likely in the form of debs). I also want to add better control over the jobs, so that packages I upload only go to my personal servers. I'd also very much like to get better EC2 / Virtualization support integrated into the network, so that the buildd count grows with the queue size. This is a slightly hard problem that I'm keen to fix. I'm also considering moving the log parsing code out of the workers, so that the parsing code can be fixed without upgrading all the workers. This would also drop the Firehose dep on the client code, which would be nice. Migration from a debuild.me build into a local reprepro repo is something that would be fairly easy to do as well, likely to be done remotely via the XML-RPC interface, which calls a couple of reprepro commands (such as includedsc and includedeb) and publishes it to the user's repo. This is a nice use of the debs that get built, and could also allow debuild.me to be used like a PPA system, but this allows the user to not migrate packages that may contain piuparts issues.

Gregor Herrmann: RC bugs 2013/23

I know, I'm starting to repeat myself but: this week was again characterized more be RC bug prevention than by actual RC bug fixing. in other words: I was mostly dealing with not-yet release-critical bugs around the perl 5.18 transition. actual RC bugs I've worked on (also mostly pkg-perl related):

8 June 2013

Michael Stapelberg: Survey answers part 1: systemd has too many dependencies, or it is bloated, or it does too many things, or is too complex

This blog post is the first of a series of posts dealing with the results of the Debian systemd survey. I intend to give a presentation at DebConf 2013, too, so you could either read my posts, or watch the talk, or both :-). The top concern shared by most people is:
systemd has too many dependencies, or it is bloated, or it does too many things, or is too complex
Now this concern actually has a lot of different facets, and I am trying to share my opinion on each of them. systemd has too many dependencies First, let s start with too many dependencies , because that is easy to check and reason about. I have created a document which lists all dependencies of the systemd binary itself (pid 1) and all the binaries which are currently shipped by the systemd Debian package. If you don t want to take my word for granted, please read that document. Have you read the document? Very nice! As you can see, the systemd binary itself has 10 dependencies (excluding libc). Now, the question is, what is bad about dependencies? Why do people list dependencies as a top concern?
  1. Cyclic dependencies. When you hear that your init system depends on DBus, you might argue that there is a cyclic dependency here, because DBus needs to be started by the init system. However, systemd does NOT depend on dbus-daemon (!) to boot your machine. Instead of using the system bus, it uses a private UNIX socket. Therefore, systemd uses DBus merely as a serialization format for IPC between its different processes. Only when you want to access systemd via its API as a user (non-root), you actually use the system bus. Since we are talking about DBus: DBus provides a well-tested serialization format and IPC mechanism so that systemd doesn t have to reinvent the wheel and instead benefits from wide support within languages.
  2. Complicated code. I feel like there is the implicit assumption that lots of dependencies correlate with complicated code that is easy to break. I encourage you to have a look at systemd s source code: look for the places where specific libraries are used, e.g. enforce_user which uses libcap. You ll notice that the code is not complex and usage of the libraries is clear.
  3. Software dragging in lots of library packages. The libraries which systemd uses are already in widespread use (e.g. DBus, udev, selinux, libcap, pcre, ). On a typical Debian installation, only very few of them will be dragged in by systemd, if at all. As an example, on a fresh Debian Wheezy installation, less than 10 packages will end up on your machine when running apt-get install systemd .
  4. More memory use. The Linux kernel maps libraries into memory only once, no matter how many processes use them. As stated in the dependency list, on machines where the libraries are not already loaded, systemd brings in about 500 KiB of additional memory-mapped libraries in the worst case. On the machines we have these days, this is a reasonable cost to pay for all the benefits systemd gets us. This holds true on embedded systems with only a few MiB of RAM and especially on typical workstations with 8+ GiB of RAM.
systemd is bloated Now, let s talk about bloat. Again, this is a point which has many facets. I d like to quote the Wikipedia definition of software bloat:
Software bloat is a process whereby successive versions of a computer program become perceptibly slower, use more memory or processing power, or have higher hardware requirements than the previous version whilst making only dubious user-perceptible improvements.
The first part of the definition certainly does not match systemd it is measurably faster than sysvinit. As for memory usage: systemd s RSS is 1.8 MiB, whereas sysvinit uses 0.8 MiB. As I argued on the More memory use point in the dependencies section, I think the additional resource cost is well worth the benefits. Also note that systemd s features are NOT all implemented in the binary which is PID 1. As explained in the dependency list, systemd consists of many cleanly separated binaries. So if a new version of systemd gathers an additional feature, this does not mean that your PID 1 will be bigger. While systemd runs on any hardware, it has an indirect hardware requirement: it requires some Linux kernel features (which are all enabled in Debian kernels). That might rule out usage of systemd on really old embedded hardware where you don t have a chance to update the kernel. While it is sad that those machines cannot profit from systemd, switching to systemd as a default has no downside either: Debian continues to support sysvinit for quite some time, so these machines will continue to work even with upcoming Debian versions. systemd does too many things The Wikipedia definition continues:
[ ] perceived bloat can occur from the software servicing a large, diverse marketplace with many differing requirements. Most end users will feel they only need some limited subset of the available functions and will regard the others as unnecessary bloat, even if people with different requirements do use them.
I think the last part of the Wikipedia definition applies to systemd: it does service a large and diverse marketplace . That marketplace is the entirety of existing software which is started by an init system. Also, systemd can be used on a wide range of hardware (embedded devices, tablets, phones, notebooks, desktops, servers) which requires different features. As an example: on a desktop system you typically don t care strongly about a watchdog feature, but on embedded or servers that feature is very handy. Similarly, on a tablet, forward secure sealing of logfiles is not as important as on a server. Therefore, I can understand if you feel that you don t need many of the features systemd provides. But please think of other users and maintainers who are very happy with systemd s benefits. Also note that while systemd supports many things (in separate binaries!), you don t have to use them all. It still makes sense to ship them all in the same package. Take coreutils as another example in that area. The binaries belong together, even though you most likely haven t used all of them (e.g. od, pr, ptx, :-)). systemd is too complex The remaining concern is that systemd is too complex. In my experience, complexity is often inherent to a specific area and one cannot simply make it go away. Instead, there are different models of how that complexity is represented. Think of the monolithic Linux kernel versus the MINIX microkernel. The latter has a very small amount of lines of source in the kernel, but puts the complexity into userspace. The former uses a different approach with more source in the kernel. The arguments between both camps show that neither is clearly right or clearly wrong. In a way, sysvinit represents the MINIX model: it has a small core (the init binary itself), but a lot of complexity in shell scripts and external programs. The fact that solutions are copied from one init script to another leads to lots of subtle errors and makes code reuse really hard. systemd however has more source code in the binaries, but requires only very simple, descriptive, textual configuration instead of complex init scripts. To me, it seems preferable to have the complexity in a single place instead of distributed across lots of people and projects. Conclusion In a way, you are right. systemd centralizes complexity from tons of init scripts into a single place. However, it therefore makes it very easy for maintainers to write service files (equivalent of an init script) and provides a consistent and reliable interface for service management. Furthermore, it is different than sysvinit, and different solutions often seem complex at first. While systemd consumes more resources than sysvinit, it uses them to make more information available about services; its finer-grained service management requires more state-keeping, but in turn offers you more control over your services.

Daniel Pocock: Rendition link to PRISM

The Guardian is reporting that Britain's GCHQ first started getting produtive with PRISM early 2012. It was about the same time that their buddies down under, ASIO revised their earlier assessment of a refugee, Ranjini, and scooped her up in Australia's domestic rendition program. This may be more than a notable co-incidince, because it adds further support to the hypothesis that Ranjini is a victim of Big Data and PRISM. If ASIO first gained access to PRISM at the same time as GCHQ, then they may have used some tenuous PRISM data to form their revised assessment of her suitability for a visa. Making such inferences, and using them as the basis for a cruel program of indefinite detention is a gross violation of human rights and goes far beyond the claim that PRISM is about catching real terrorists. I've previously mentioned the systematic persecution of coloured people in my own country. Like many honest people, I'm utterly ashamed of it. The Government also has similar programs for indigineous people (they cooked one aboriginal elder alive on our national holiday) and they've also toyed with outlawing homosexuality. Having seen first hand some of the prejudiced, Government-sanctioned evil that exists in Australia, it's not hard to imagine small-minded members of the public service using PRISM data to target these classes of people for an unhealthy dose of bastardisation. Ranjini was ripped away from her husband by the rendition program and dumped in Sydney's Villawood death camp. Twenty-four hours after the gestapo got their hands on her, it was discovered she was pregnant - her child, an Australian citizen, was recently born and confined to the same concentration camp. Ranjini has racked up more than 12 months in captivity now, most of it while pregnant, and the Government has still not made any official charges against this woman. They say they can't comment on her case for fear of revealing their sources: once again, they don't want to talk about programs like PRISM that they share with the US. Maybe she just had one of the wrong people in her facebook friends list? That is not the sort of evidence that can be used to convict somebody in court, especially if the Government wants to avoid public questioning about their access to a close ally's secret database. Various rapists and murderers have made multiple court appearances in the last 12 months, tried and convicted in accordance with the procedures of justice. Ranjini has not been brought into a court room even once because the spooks don't want to reveal their sinister sources like PRISM.
Potential PRISM victim Ranjini
Australia's close ties with the US Australia has had particularly close ties with the US for many years and just as the British GCHQ has been linked to PRISM, it seems Australia's ASIO is also in on the act. For those not familiar with the depth of this alliance, it is worth checking up on Pine Gap, the ECHELON program and the recent exposure (by Wikileaks) of one of our senators with unauthorised US spy connections - he quietly resigned for family reasons'. Pine Gap
Pine Gap, Australia This is not to say that the US is universally bad or that the strategic alliance is undesirable: rather, it is simply to demonstrate the strength of these links and the real risk that data-sharing is used for inappropriate purposes. While many of us in a technical field treat large volumes of data from a very theoretical perspective, it is worth remembering that in the wrong hands, data can be very dangerous and there are real human victims.

Benjamin Mako Hill: London and Michigan

I ll be spending the week after next (June 17-23) in London for the annual meeting of the International Communication Association where I ll be presenting a paper. This will be my first ICA and I m looking forward to connecting with many new colleagues in the discipline. If you re one of them, reading this, and would like to meet up in London, please let me know! Starting June 24th, I ll be in Ann Arbor, Michigan for four weeks of the ICPSR summer program in applied statistics at the Institute for Social Research. I have been wanting to sign up for some of their advanced methods classes for years and am planning to take the opportunity this summer before I start at UW. I ll be living with my friends and fellow Berkman Cooperation Group members Aaron Shaw and Dennis Tennen. I would love to make connections and meet people in both places so, if you would like to meet up, please get in contact.

Thorsten Glaser: Waypoint Statistics

mirabilos  found waypoints I ve finally gotten around to listing all Waypoints (Geocaches, Opencaches, Closedcaches, Earthcaches, Terracaches including Locationless, Navicaches, etc.) I ve found a box, enjoyful, educating, a good place to hide one myself, etc. and putting up a list and, of course, generate my own statpic.

I ll put them up for the other project members, too (already made a picture for gecko2@ but bsiegert@ still needs one; we also need to collect offline lists of found, owned and attended waypoints) A bit of background story: I decided, years ago, to have an offline list of cache finds in case something would happen. Just, I had found way too many already, so this was a huge bit of work. Oh well I of course procrastinated, and then something did happen (Opencaching wanting to force a Restricted Commons licence; me disagreeing and suggesting a change; some trigger-happy person immediately deleting my account without waiting for the discussion or the decision period to end; weeks of forum discussions; Opencaching allowing dual-licencing; them telling me they can t restore my data probably never heard of databa sorry, MySQL backups). And I still didn t have the list. Now I do; recreated even the OC information from what was still accessible and with help from one OC supporter ( mic@ , thanks); merged caches that are co-listed on several platforms, etc. (still need to put in the FTF/STF/TTF/4TF/LTF and voting/favourites information) and a statpic, all in Open Source and Open Data, in cvs(1) with mksh(1) and a frontend for libgd2 I admit, but we had been using that for the MirWebsite for a while already. I suggest every geocacher keep an offline or local record of all their finds (and hides and attended logs) for things like this, in case some platform decides to let s say, put your data into the cloud where it is? I don t know .

Steve Kemp: Migrations and movements

Recently I wanted to cleanup my "main" remote machine. It is a system I've had for many years, which started off as a i386 KVM-guest and was later migrated in place to an AMD64 installation. These days the host runs: The plan was originally to move the "mail stuff" to a new (wheezy) guest. I aborted that after discovering that the mutt-patched package has (IMHO) regressed. So today I spun up a new virtual machine, and configured it to host websites. Thus far I've migrated steve.org.uk, and lumail.org to the new host. Both simple sites that are built via my static-site-generator. Migration mostly involved configuring the proxy and the thttpd instances - then using rsync to migrate the content. I've renamed my current host, which was previously www.steve.org.uk and is now ssh.steve.org.uk, and pushed DNS changes. If all is smooth and happy I'll slowly migrate the rest of the sites. Fingers crossed this will be painless and I'll have a clean split between "login + mail" and "websites".

7 June 2013

Daniel Pocock: "Do as we say, not as we do"

When I was preparing my blog entry about the Gold Standard in Free communications, I had absolutely no idea that The Guardian (another Ganglia user) would be hot on my heels with dramatic revelations about US Government surveillance of dangerous terrorists and maybe sucking up a little bit of data about a few hundred million of their own citizens and another 90% of the world's population for good measure. Some people even thought I've been a bit paranoid with my concerns about excessive surveillance. However, it is just remarkable to see that in the same week that the trial of Bradley Manning is getting under way for inappropriate use of his employer's computer, the US has been exposed plotting cyber attacks and setting a very bad example for all those little script kiddies out there. Practical questions for every one of us Is it time to start blocking email to and from sites like gmail and hotmail? What about the reports that the US Government was engineering back doors in the OpenBSD operating system? Have any open source projects actually been comprised in this way? Will spammers and other criminals take this as a cue that there is nothing morally wrong with hacking? Have certificate authorities been infiltrated too? They may well be the elephant in the room - while everybody was joking about the NSA key hidden in the depths of Microsoft Windows, maybe one or more of the well known trusted root certificates, right under our noses, is also a back door? The danger is real Anybody wondering about the practical implications of all this data gathering doesn't have to look very far to find out what can go wrong. In the same week as all these things were exposed, there have been more dramatic revelations about law enforcement officers selling private data for their own commercial gain. While the vast majority of police are surely good citizens, every organisation has it's bad apples and as Bradley Manning demonstrated so well, it only takes one person to breach security and enormous volumes of data can end up escaping.

Tanguy Ortolo: Looking for an SPF milter

Envelope

For email extensions such as SPF, DKIM and DMARC, I think the most flexible and portable system is the milter protocol. Originally developed for Sendmail, it is now also supported by Postfix, and it allows to plug specific filters in the mail server without the hassle of the previous systems like SMTP proxies.

SPF milters in Debian OpenDKIM provides a good milter for checking DKIM. OpenDMARC provides a similar milter for DMARC. But the situation is more difficult for SPF in Debian which is a requirement for DMARC! :
spf-milter
It was based on the buggy libspf0 and was never updated to libspf2, and was finally removed from Debian;
spf-milter-python
This one seems a bit Sendmail-centric it uses a dbm configuration file for instance and not very documented.
Packaging a new SPF milter? There are other milters for SPF, which have not been packaged for Debian yet, but I am ready to package one. Has anybody tried another SPF milter?
spfmilter
Still in beta test, still to be ported to libspf2 which may never happen since it was not updated since 2005.
smf-spf
Based on libspf2, seems rather neat, with a clean configuration, but inactive since 2007.
milter-spiff
Proprietary.

5 June 2013

Guido G nther: Calendar synchronisation between Nokia N900 and the Calypso CalDAV server

One of the replies to the post about Debian's last groupware meeting was from Patrick Ohly of syncevolution fame pointing out that syncevolution already implements calendar autodetection for CalDAV calendars as described in draft-daboo-srv-caldav-10. While looking at the code I noticed that there's a backend for the N900s calendar by Ove K ven as well. When I tried Ove's latest package on my N900 it lead to an immediate crash when doing a:
syncevolution --print-items target-config@webdav calendar
According to Patrick the bug was supposed to be fixed in recent versions so I set up scratchbox and built a newer git snapshot for maemo (sources). This wouldn't crash but didn't show up any items either. It turned out to be a minor bug in calypso returning no content type for REPORT queries which resulted in libneon discarding the whole reply (now already fixed in calypso upstream). With this out of the way setting up synchronisation is quiet simple:
# Configuration
CALDAV_SERVER=192.168.0.10
syncevolution --configure username=<username> password=<password> \
              calendar/backend=caldav calendar/database=https://$ CALDAV_SERVER :5233/private/my_calendar \
              target-config@webdav calendar
syncevolution --configure --template SyncEvolution_Client sync=none syncURL=local://@webdav username= password= webdav
syncevolution --configure sync=two-way backend=calendar webdav calendar
You should then be able to print the items on the local (N900) and from the remote (CalDAV server) end:
# This lists the current calendar items on the server
syncevolution --print-items target-config@webdav calendar
# This lists the current calendar items on the N900
syncevolution --print-items @default calendar
And from there on sync away:
# initial slow sync
syncevolution --sync slow webdav
# from there on
syncevolution webdav
The syncevolution source code has great documentation about debugging problems (e.g. src/backends/webdav/README). So check that in case you run into problems. The tl;dr version is
SYNCEVOLUTION_DEBUG=1 src/syncevolution loglevel=10 --print-items target-config@webdav calendar
to debug CalDAV related problems. In case you need to run syncevoluton from source be sure to set these beforehand:
export SYNCEVOLUTION_TEMPLATE_DIR=$PWD/src/templates/
export SYNCEVOLUTION_XML_CONFIG_DIR=$PWD/src/syncevo/configs/
On the CalDAV side I used current Calypso git which (with some additional minor fixes) now also interoperates nicely with Iceowl/Icowl-Extension aka Sunbird/Lightning on the desktop side. There's also an ITP for it. So it'll hopefully end up in Debian soon.

Dirk Eddelbuettel: RcppArmadillo 0.3.900.0

A Armadillo release 3.900.0 was provided by Conrad yesterday. It has been rolled into a new RcppArmadillo release 0.3.900.0 which is now on CRAN and in Debian. It has a number of nice changes, mostly on the performance side of things (see below) and a minor cleanup/improvement in our Kalman filter example (which, as I just realized, I forgot to note in the \code NEWS.Rd in the released tarball):
Changes in RcppArmadillo version 0.3.900 (2013-06-04)
  • Upgraded to Armadillo release Version 3.900.0 (Bavarian Sunflower)
    • added automatic SSE2 vectorisation of elementary expressions (eg. matrix addition) when using GCC 4.7+ with -O3 optimisation
    • added support for saving & loading of cubes in HDF5 format, contributed by Szabolcs Horvat
    • faster median(), contributed by Ruslan Shestopalyuk
    • faster handling of compound expressions with transposes of submatrix rows
    • faster handling of compound expressions with transposes of complex vectors
  • Kalman filter example switched from inline to \code sourceCpp , which simplifies / streamlines the C++ side a little
Courtesy of CRANberries, there is also a diffstat report for the most recent release As always, more detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

Johannes Schauer: Reliable IMAP synchronization with IDLE support

The task: reliably synchronize my local MailDir with several remote IMAP mailboxes with IDLE support so that there is no need to poll with small time intervals to get new email immediately. Most graphical mail clients like icedove/thunderbird or evolution have IDLE support which means that their users get notified about new email as soon as it arrives. I prefer to handle email fetching/reading/sending using separate programs so after having used icedove for a long time, I switched to a offlineimap/mutt based setup a few years ago. Some while after that I discovered sup and later notmuch/alot which made me switch again. Now my only remaining problem is the synchronization between my local email and several remote IMAP servers. Using offlineimap worked fine in the beginning but soon I discovered some of its shortcomings. It would for example sometimes lock up or simply crash when I switched between different wireless networks or switched to ethernet or UMTS. Crashing was not a big problem as I just put it into a script which re-executed it every time it crashed. The problem was it locking up for one of its synchronizing email accounts while the others were kept in sync as usual. This once let to me missing five days of email because offlineimap was not crashing and I believed everything was fine (new messages from the other accounts were scrolling by as usual) while people were sending me worried emails whether I was okay or if something bad had happened. I nearly missed a paper submission deadline and another administrative deadline due to this. This was insanely annoying. It turned out that other mail synchronization programs suffered from the same lockup problem so I stuck with offlineimap and instead executed it as:
while true; do
timeout --signal=KILL 1m offlineimap
notmuch new
sleep 5m
done
Which would synchronize my email every five minutes and kill offlineimap if a synchronization took more than one minute. While I would've liked an email synchronizer which would not need this measure, this worked fine over the months. After some while it bugged me that icedove (which my girlfriend is using) was receiving email nearly instantaneously after they arrived and I couldnt have this feature with my setup. This instantaneous arrival of email works by using the IMAP IDLE command which allows the server to notify the client once new email arrives instead of the client having to poll for new email in small intervals. Unfortunately offlineimap (and any other email synchronizer I found) would not support the IDLE command. There is a fork of it which supports IDLE by using a newer python imap library but this is of little use to me as there is no possibility of a hook which executes when new email arrives so that I can execute notmuch new on the new email. At this point I could've used inotify to execute notmuch new upon arrival of new email but I went another way. Here is a short python script idle.py which connects to my IMAP servers and sends the IDLE command:
import imaplib
import select
import sys

class mysock():
def __init__(self, name, server, user, passwd, directory):
self.name = name
self.directory = directory
self.M = imaplib.IMAP4(server)
self.M.login(user, passwd)
self.M.select(self.directory)
self.M.send("%s IDLE\r\n"%(self.M._new_tag()))
if not self.M.readline().startswith('+'): # expect continuation response
exit(1)

def fileno(self):
return self.M.socket().fileno()

if __name__ == '__main__':
sockets = [
mysock("Name1", "imap.foo.bar", "user1", "pass1", "folder1"),
mysock("Name1", "imap.foo.bar", "user1", "pass1", "folder2"),
mysock("Name2", "imap.blub.bla", "user2", "pass2", "folder3")
]
readable, _, _ = select.select(sockets, [], [], 1980) # 33 mins timeout

found = False
for sock in readable:
if sock.M.readline().startswith('* BYE '): continue
print "-u basic -o -q -f %s -a %s"%(sock.directory, sock.name)
found = True
break

if not found:
print "-u basic -o"
It would create a connection to every directory I want to watch on every email account I want to synchronize. The select call will expire after 33 minutes as most email servers would drop the connection if nothing happens at around 30 minutes. If something happened within that time though, the script would output the arguments to offlineimap to do a quick check on just that mailbox on that account. If nothing happened, the script would output the arguments to offlineimap to do a full check on all my mailboxes.
while true; do
args= timeout --signal=KILL 35m python idle.py
echo "idle timed out" >&2;
args="-u basic -o";

echo "call offlineimap with: $args" >&2
timeout --signal=KILL 1m offlineimap $args
echo "offlineimap timed out" >&2;
continue;

notmuch new
done
Every call which interacts with the network is wrapped in a timeout command to avoid any funny effects. Should the python script timeout, a full synchronization with offlineimap is triggered. Should offlineimap timeout, an error message is written to stderr and the script continues. The above naturally has the disadvantage of not immediately responding to new email which arrives during the time that idle.py is not running. But as this email will be fetched once the next message arrives on the same account, there is no much waiting time and so far, this problem didnt bite me. Is there a better way to synchronize my email and at a same time make use of IDLE? I'm surprised I didnt find software which would offer this feature.

4 June 2013

Keith Packard: dri3 extension

Completing the DRI3 Extension This week marks a pretty significant milestone for the glorious DRI3000 future. The first of the two new extensions is complete and running both full Gnome and KDE desktops. DRI3 Extension Overview The DRI3 extension provides facilities for building direct rendering libraries to work with the X window system. DRI3 provides three basic mechanisms:
  1. Open a DRM device.
  2. Share kernel objects associated with X pixmaps. The direct rendering client may allocate kernel objects itself and ask the X server to construct a pixmap referencing them, or the client may take an existing X pixmap and discover the underlying kernel object for it.
  3. Synchronize access to the kernel objects. Within the X server, Sync Fences are used to serialize access to objects. These Sync Fences are exposed via file descriptors which the underlying driver can use to implement synchronization. The current Intel DRM driver passes a shared page containing a Linux Futex.
Opening the DRM Device Ideally, the DRM application would be able to just open the graphics device and start drawing, sending the resulting buffers to the X server for display. There s work going on to make this possible, but the current situation has the X server in charge of blessing the file descriptors used by DRM clients. DRI2 does this by having the DRM client fetch a magic cookie from the kernel and pass that to the X server. The cookie is then passed to the kernel which matches it up with the DRM client and turns on rendering access for that application. For DRI3, things are much simpler the DRM client asks the X server to pass back a file descriptor for the device. The X server opens the device, does the magic cookie dance all by itself (at least for now), and then passes the file descriptor back to the application.
 
    DRI3Open
    drawable: DRAWABLE
    driverType: DRI3DRIVER
    provider: PROVIDER
       
    nfd: CARD8
    driver: STRING
    device: FD
 
    Errors: Drawable, Value, Match
    This requests that the X server open the direct rendering
    device associated with drawable, driverType and RandR
    provider. The provider must support SourceOutput or SourceOffload.
    The direct rendering library used to implement the specified
    'driverType' is returned in 'driver'. The file
    descriptor for the device is returned in 'device'. 'nfd' will
    be set to one (this is strictly a convenience for XCB which
    otherwise would need request-specific information about how
    many file descriptors were associated with this reply).
Sharing Kernel Pixel Buffers An explicit non-goal of DRI3 is support for sharing buffers that don t map directly to regular X pixmaps. So, GL ancillary buffers like depth and stencil just don t apply here. The shared buffers in DRI3 are regular X pixmaps in the X server. This provides a few obvious benefits over the DRI2 scheme: In the kernel, the buffers are referenced by DMA-BUF handles, which provides a nice driver-independent mechanism.
  1. Lifetimes are easily managed. Without being associated with a separate drawable, it s easy to know when to free the Pixmap.
  2. Regular X requests apply directly. For instance, copying between buffers can use the core CopyArea request.
To create back- and fake-front- buffers for Windows, the application creates a kernel buffer, associates a DMA-BUF file descriptor with that and then sends the fd to the X server with a pixmap ID to create the associated pixmap. Doing it in this direction avoids a round trip.
 
    DRI3PixmapFromBuffer
    pixmap: PIXMAP
    drawable: DRAWABLE
    size: CARD32
    width, height, stride: CARD16
    depth, bpp: CARD8
    buffer: FD
 
    Errors: Alloc, Drawable, IDChoice, Value, Match
    Creates a pixmap for the direct rendering object associated
    with 'buffer'. Changes to pixmap will be visible in that
    direct rendered object and changes to the direct rendered
    object will be visible in the pixmap.
    'size' specifies the total size of the buffer bytes. 'width',
    'height' describe the geometry (in pixels) of the underlying
    buffer. 'stride' specifies the number of bytes per scanline in
    the buffer. The pixels within the buffer may not be arranged
    in a simple linear fashion, but 'size' will be at least
    'height' * 'stride'.
    Precisely how any additional information about the buffer is
    shared is outside the scope of this extension.
    If buffer cannot be used with the screen associated with
    drawable, a Match error is returned.
    If depth or bpp are not supported by the screen, a Value error
    is returned.
To provide for texture-from-pixmap, the application takes the pixmap ID and passes that to the X server which returns the a file descriptor for a DMA-BUF which is associated with the underlying kernel buffer.
 
    DRI3BufferFromPixmap
    pixmap: PIXMAP
       
    depth: CARD8
    size: CARD32
    width, height, stride: CARD16
    depth, bpp: CARD8
    buffer: FD
 
    Errors: Pixmap, Match
    Pass back a direct rendering object associated with
    pixmap. Changes to pixmap will be visible in that
    direct rendered object and changes to the direct rendered
    object will be visible in the pixmap.
    'size' specifies the total size of the buffer bytes. 'width',
    'height' describe the geometry (in pixels) of the underlying
    buffer. 'stride' specifies the number of bytes per scanline in
    the buffer. The pixels within the buffer may not be arranged
    in a simple linear fashion, but 'size' will be at least
    'height' * 'stride'.
    Precisely how any additional information about the buffer is
    shared is outside the scope of this extension.
    If buffer cannot be used with the screen associated with
    drawable, a Match error is returned.
Tracking Window Size Changes When Eric Anholt and I first started discussing DRI3, we hoped to avoid needing to learn about the window size from the X server. The thought was that the union of all of the viewports specified by the application would form the bounds of the drawing area. When the window size changed, we expected the application would change the viewport. Alas, this simple plan isn t sufficient here a few GL functions are not limited to the viewport. So, we need to track the actual window size and monitor changes to it. DRI2 does this by delivering invalidate events to the application whenever the current buffer isn t valid; the application discovers that this event has been delivered and goes to as the X server for the new buffers. There are a couple of problems with this approach:
  1. Any outstanding DRM rendering requests will still draw to the old buffers.
  2. The Invalidate events must be captured before the application sees the related ConfigureNotify event so that the GL library can react appropriately.
The first problem is pretty intractable within DRI2 the application has no way of knowing whether a frame that it has drawn was delivered to the correct buffer as the underlying buffer object can change at any time. DRI3 fixes this by having the application in control of buffer management; it can easily copy data from the previous back buffer to the new back buffer synchronized to its own direct rendering. The second problem was solved in DRI2 by using the existing Xlib event hooks; the GL library directly implements the Xlib side of the DRI2 extension and captures the InvalidateBuffers events within that code, delivering those to the driver code. The problem with this solution is that Xlib holds the Display structure mutex across this whole mess, and Mesa must be very careful not to make any Xlib calls during the invalidate call. For DRI3, I considered placing the geometry data in a shared memory buffer, but my future plans for the Present extension led me to want an X event instead (more about the Present extension in a future posting). An X ConfigureNotify event is sufficient for the current requirements to track window sizes accurately. However, there s no easy way for the GL library to ensure that ConfigureNotify events will be delivered to the application other application code may (and probably will) adjust the window event mask for its own uses. I considered adding the necessary event mask tracking code within XCB, but again, knowing that the Present extension would probably need additional information anyhow, decided to create a new event instead. Using an event requires that XCB provide some mechanism to capture those events, keep them from the regular X event stream, and deliver them to the GL library. A further requirement is that the GL library be absolutely assured of receiving notification about these events before the regular event processing within the application will see a core ConfigureNotify event. The method I came up with for XCB is fairly specific to my requirements. The events are always XGE events, and are tagged with a special event context ID , an XID allocated for this purpose. The combination of the extension op-code, the event type and this event context ID are used to split off these events to custom event queues using the following APIs:
/**
 * @brief Listen for a special event
 */
xcb_special_event_t *xcb_register_for_special_event(xcb_connection_t *c,
                                                    uint8_t extension,
                                                    uint16_t evtype,
                                                    uint32_t eid,
                                                    uint32_t *stamp);
This creates a special event queue which will contain only events matching the specified extension/type/event-id triplet.
/**
 * @brief Returns the next event from a special queue
 */
xcb_generic_event_t *xcb_check_for_special_event(xcb_connection_t *c,
                                                 xcb_special_event_t *se);
This pulls an event from a special event queue. These events will not appear in the regular X event queue and so applications will never see them. There s one more piece of magic here the stamp value passed to xcbregisterforspecialevent. This pointer refers to a location in memory which will be incremented every time an event is placed in the special event queue. The application can cheaply monitor this memory location for changes and known when to check the queue for events. Within GL, the value used is the existing dri2 stamp value. That is checked at the top of the rendering operation; if it has changed, the drawing buffers will be re-acquired. Part of the buffer acquisition process is a check for special events related to the window. For now, I ve placed these events in the DRI3 extension. However, they will move to the Present extension once that is working.
 
    DRI3SelectInput
    eventContext: DRI3EVENTID
    window: WINDOW
    eventMask: SETofDRI3EVENT
 
    Errors: Window, Value, Match, IDchoice
    Selects the set of DRI3 events to be delivered for the
    specified window and event context. DRI3SelectInput can
    create, modify or delete event contexts. An event context is
    associated with a specific window; using an existing event
    context with a different window generates a Match error.
    If eventContext specifies an existing event context, then if
    eventMask is empty, DRI3SelectInput deletes the specified
    context, otherwise the specified event context is changed to
    select a different set of events.
    If eventContext is an unused XID, then if eventMask is empty
    no operation is performed. Otherwise, a new event context is
    created selecting the specified events.
The events themselves look a lot like a configure notify event:
 
    DRI3ConfigureNotify
    type: CARD8         XGE event type (35)
    extension: CARD8        DRI3 extension request number
    length: CARD16          2
    evtype: CARD16          DRI3_ConfigureNotify
    eventID: DRI3EVENTID
    window: WINDOW
    x: INT16
    y: INT16
    width: CARD16
    height: CARD16
    off_x: INT16
    off_y: INT16
    pixmap_width: CARD16
    pixmap_height: CARD16
    pixmap_flags: CARD32
 
    'x' and 'y' are the parent-relative location of 'window'.
Note that there are a couple of odd additional fields offx, offy, pixmapwidth, pixmapheight and pixmap_flags are all place-holders for what I expect to end up in the Present extension. For now, in DRI3, they should be ignored. Synchronization The DRM application needs to know when various X requests related to its buffers have finished. In particular, when performing a buffer swap, the client wants to know when that completes, and be able to block until it has. DRI2 does this by having the application make a synchronous request from the X server to get the names of the new back buffer for drawing the next frame. This has two problems:
  1. The synchronous round trip to the X server isn t free. Other running applications may cause fairly arbitrary delays in getting the reply back from the X server.
  2. Synchronizing with the X server doesn t ensure that GPU operations are necessarily serialized between the application and the X server.
What we want is a serialization guarantee between the X server and the DRM application that operates at the GPU level. I ve written a couple of times (dri3k first steps and Shared Memory Fences) about using X Sync extension Fences (created by James Jones and Aaron Plattner) for this synchronization and wanted to get a bit more specific here. With the X server, a Sync extension Fence is essentially driver-specific, allowing the hardware design to control how the actual synchronization is performed. DRI3 creates a way to share the underlying operating system object by passing a file descriptor from application to the X server which somehow references that device object. Both sides of the protocol need to tacitly agree on what it means.
 
    DRI3FenceFromFD
    drawable: DRAWABLE
    fence: FENCE
    initially-triggered: BOOL
    fd: FD
 
    Errors: IDchoice, Drawable
    Creates a Sync extension Fence that provides the regular Sync
    extension semantics along with a file descriptor that provides
    a device-specific mechanism to manipulate the fence directly.
    Details about the mechanism used with this file descriptor are
    outside the scope of the DRI3 extension.
For the current GEM kernel interface, because all GPU access is serialized at the kernel API, it s sufficient to serialize access to the kernel itself to ensure operations are serialized on the GPU. So, for GEM, I m using a shared memory futex for the DRI3 synchronization primitive. That does not mean that all GPUs will share this same mechanism. Eliminate the kernel serialization guarantee and some more GPU-centric design will be required. What about Swap Buffers? None of the above stuff actually gets bits onto the screen. For now, the GL implementation is simply taking the X pixmap and copying it to the window at SwapBuffers time. This is sufficient to run applications, but doesn t provide for all of the fancy swap options, like limiting to frame rate or optimizing full-screen swaps. I ve decided to relegate all of that functionality to the as-yet-unspecified Present extension. Because the whole goal of DRI3 was to get direct rendered application contents into X pixmaps, the Present extension will operate on those X objects directly. This means it will also be usable with non-DRM applications that use simple X pixmap based double buffering, a class which includes most existing non-GL based Gtk+ and Qt applications. So, I get to reduce the size of the DRI3 extension while providing additional functionality for non direct-rendered applications. Current Status As I said above, all of the above functionality is running on my systems and has booted both complete KDE and Gnome sessions. There have been some recent DMA-BUF related fixes in the kernel, so you ll need to run the latest 3.9.x stable release or a 3.10 release candidate. Here s references to all of the appropriate git repositories: DRI3 protocol and spec:
git://people.freedesktop.org/~keithp/dri3proto      master
XCB protocol
git://people.freedesktop.org/~keithp/xcb/proto.git  dri3
XCB library
git://people.freedesktop.org/~keithp/xcb/libxcb.git dri3
xshmfence library:
git://people.freedesktop.org/~keithp/libxshmfence.git   master
X server:
git://people.freedesktop.org/~keithp/xserver.git    dri3
Mesa:
git://people.freedesktop.org/~keithp/mesa.git       dri3
Next Steps Now it s time to go write the Present extension and get that working. I ll start coding and should have another posting here next week.

Ingo Juergensmann: Problems with DaviCal after Wheezy Upgrade

It's been a while since Wheezy was released, but the problems with DaviCal started with that upgrade. I don't know whether this is a DaviCal bug or not, maybe partly. This is just a informational note, before I'll file a bug report (or not). First problem was that I couldn't add any contacts anymore (CardDAV) from OS X. A friend of mine has the same issue as he's using my server for that. He mailed that he's getting the following error of the Contacts app under OS X:
[NSInvalidArgumentException] -[CoreDAVNullParser rootElement]:
unrecognized selector sent to instance 0x7f91bad6b1d0
When I looked at the webfrontend I discovered that the database of DaviCal didn't get updated. I don't know whether this is a general problem or it just happened to me. Anyway. Executing the proper database upgrade script delivered by DaviCal was no problem at all. Adding new contacts worked again. But then I discovered somewhen later that my calendars on the iPhone didn't update anymore. That was a bigger problem to solve, because it appears that it's an IOS 6.x problem and not a DaviCal issue. Finally I found on Google this mail on the DaviCal mailing list:
As I started using DAViCal, I created calenders with "named" paths, not these
long names, like you stated in your message. With iOS 6 this was not a good
idea. I created every calender new with the iOS 6 device and copied all
calender-items to the new calendars. Was a work auf 15 minutes for me. I
described it in a blog-post (german):
http://tech.blog.rana.at/2012/10/24/davical-caldav-mit-ios-6/ Not a real solution for the problem, but a workaround.
So, as linked page is in German, I'll rephrase the "solution" here: The problem seems to be that the old principal path names like user/calendar or user/home do not work anymore under iOS 6. Instead you'll need to create a new calender from your iPhone. So, just configure your calendar account as usually. You'll end with an empyt calendar. Now create a new event in your calendar on the iPhone. This new calendar should show up under OS X (or other clients). There you can export your existing appointments to an *.ics file which you can import in DaviCal webfrontend to the new prinicipal collection. Your dates should now show up on your iPhone again. But you'll end up with duplicate entries in iCal app under OS X. You need to define your new principal as default calendar to be able to delete your old default calendar, if that's not possible. If everything went well, you can share your dates between OS X and your iPhone via DaviCal again. At least this worked for me. :-) It's late over here, so I'll postpone writing the bugreport for now...
Kategorie:

Daniel Pocock: Using reSIProcate to connect Asterisk with WebRTC

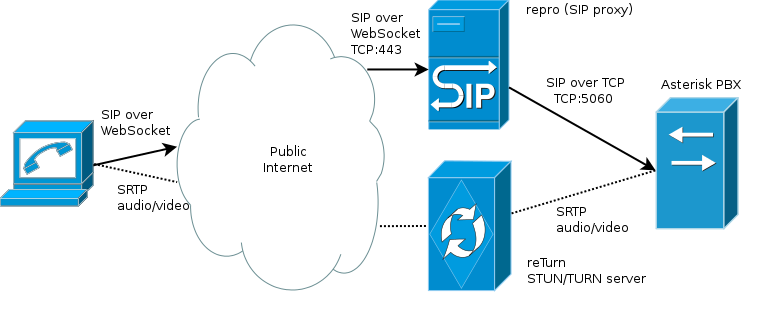
In my previous blog entry about how to get WebRTC going fast I looked at the basics of setting up a SIP proxy (also known as a SIP router) to accept connections from WebRTC clients. As in a traditional, non-WebRTC world, the SIP proxy simply facilitates calling between all the clients it knows. In practice, deployments usually want to add additional functionality in the form of a PBX with queues, voicemail, menus and conferencing. The recent Asterisk 11 release includes support for WebRTC although it is still evolving and I don't currently recomend connecting Asterisk directly to the public Internet. In particular, Asterisk doesn't support features like mutual TLS authentication with the WSS (secure WebSocket) transport. Here, we look at how repro can accept connections from Internet/web users and relay them to an internal Asterisk server. Here is an architecture diagram: Notice that the SIP messages are accepted over repro's WebSocket transport and relayed to Asterisk over a regular SIP TCP transport. This means that we benefit from repro's TLS support too, so the WebSocket client has a much higher chance of escaping their client-side firewall if port 443 is used (repro pretending to be a HTTPS server) and clients can be authenticated with certificates in their browser. Here are the steps to get it running: repro and reTurn setup Set up repro and reTurn server on a Debian server as per my previous blog post. Verify that the clients can talk to repro. Asterisk source build Digium, the creators of Asterisk, are not currently supporting Debian packages, but they do provide RPM packages in their Asterisk package repository However, the pre-built binary packages for Asterisk 11.4 don't include SRTP support. SRTP is a mandatory part of WebRTC. Therefore, we take the Source RPM (SRPM) and build it manually. First, it is recommended that you start with a completely fresh CentOS 6 or RHEL6 server. I built a fresh virtual machine in my XCP environment using a procedure similar to that documented by Grant. After installing and setting a root password, configure yum to access EPEL6 Make sure SELinux and firewall are disabled on the box (they are often enabled by default). A quick way to do this:
# sed -i s/SELINUX=enforcing/SELINUX=disabled/g /etc/selinux/config
# reboot
...
# iptables -I INPUT -j ACCEPT
Next you can tell yum about the Digium repository and install all the necessary dependencies for building Asterisk:
# rpm -Uvh http://packages.asterisk.org/centos/6/current/x86_64/RPMS/asterisknow-version-3.0.0-1_centos6.noarch.rpm
# yum update
# yum install rpm-build libsrtp-devel
In your home directory, set up a work tree for rpmbuild:
$ mkdir ~/rpmbuild
$ cd ~/rpmbuild
$ mkdir BUILD BUILDROOT RPMS SOURCES SPECS SRPMS
$ cd SPECS
$ wget http://danielpocock.com/sites/danielpocock.com/files/asterisk.spec
$ cd ../SRPMS
$ wget http://packages.asterisk.org/centos/6/asterisk-11/SRPMS/asterisk-11.4.0-1_centos6.src.rpm
$ rpmbuild --rebuild asterisk-11.4.0-1_centos6.src.rpm
At this stage, you will have some errors, but it has successfully extracted the tarball into the SOURCES directory:
$ ls -l ../SOURCES
-rw-r--r--   1 daniel daniel 11573400 May 20 23:07 asterisk-sources-11.4.0.tar.gz
$
It will also complain about missing dependencies, you install them using yum:
# yum install make gcc gcc-c++ ....
Notice that you have downloaded a slightly modified version of the asterisk.spec file, the reasons for this are explained in this mailing list discussion. The following should now trigger a successful build:
$ rpmbuild -bb \
  --without tds \
    --without misdn \
    --without odbc \
   ~/rpmbuild/SOURCES/asterisk.spec
Hopefully, Digium will add the SRTP support in the 11.4.1 packages so that source build won't be necessary for every future release. Asterisk configuration: demo application Here we just have to install the RPMs and make a quick configuration change:
$ cd ~/rpmbuild/RPMS/x86_64
$ su -
# rpm -i asterisk*rpm
# yum install asterisk-sounds-core-en-ulaw asterisk-sounds-extra-en-ulaw --enablerepo=asterisk-11
# ln -s /usr/share/asterisk/sounds/demo-* /var/lib/asterisk/sounds/en/
To enable connections from the proxy, we must set a few non-default settings. It is essential to use the TCP transport as the SIP messages from WebSocket clients are usually too big for UDP packets. It is also necessary to enable SRTP and AVPF, as these are mandatory in WebRTC. Here is a diff against the default /etc/asterisk/sip.conf:
--- /etc/asterisk.orig/sip.conf	2013-06-04 10:57:49.428617785 +0200
+++ /etc/asterisk/sip.conf	2013-06-04 11:18:17.825604261 +0200
@@ -207,7 +207,7 @@
 ; subject to change in any release.  If they are changed, the changes will
 ; be reflected in this sample configuration file, as well as in the UPGRADE.txt file.
 ;
-tcpenable=no                    ; Enable server for incoming TCP connections (default is no)
+tcpenable=yes                    ; Enable server for incoming TCP connections (default is no)
 tcpbindaddr=0.0.0.0             ; IP address for TCP server to bind to (0.0.0.0 binds to all interfaces)
                                 ; Optionally add a port number, 192.168.1.1:5062 (default is port 5060)
 
@@ -1371,6 +1371,13 @@
 ; ...
 ;
 
+[1001](public-phone,ulaw-phone)
+avpf = yes
+encryption = yes
+context = public
+icesupport = yes
+
+
 ; Standard configurations not using templates look like this:
 ;
 ;[grandstream1]
This assumes that the SIP user ID of your WebSocket user is 1001 Now you can start Asterisk:
# service asterisk start
Configuring the repro SIP proxy to send calls to Asterisk This is a relatively simple demonstration. The goal is to send calls for the number 1000 to the demo application in Asterisk In repro's web interface, click ADD ROUTE in the menu. Use the following parameters and leave all other options blank:
  • URI: ^sip:1000@
  • Destination: sip:$1@pbx.example.org?transport=tcp
Note: replace pbx.example.org with the hostname or IP address of the box running Asterisk Go to the ADD USER menu link and add a user called 1001. The user ID and password have to be placed in the custom.js file for JsSIP Testing from JsSIP I assume JsSIP was set up following the instructions from my previous blog post Asterisk doesn't support the video codec from a WebRTC client. To work around this, in the custom.js file for JsSIP, make sure video is disabled by default. In the WebRTC client, dial 1000. You should hear the demo greeting from Asterisk. Troubleshooting
  • Check the JavaScript log in the browser
  • Check the logs on the repro proxy and increase the verbosity of the logs if necessary. If the level is set to STACK, you will see full copies of each SIP message sent and received.
  • Connect to the Asterisk console (UNIX command: asterisk -r -vvv) and enable SIP message display: sip set debug on.

Hideki Yamane: upsteram-downstream eco-cycle

happy: get report via BTS (thanks!)

unhappy: silently updated as "u1" or something with just "Merge from Debian unstable. Remaining changes:" changelog.

If their changes are valuable for users, surely I want to include it, however, should I dig into downstream to check every update for all packages? (but I can't...)

I don't want to just blame them, probably something is necessary for them motivated to report/share it with upstream (including Debian), but I cannot find it now...

Rapha&#235;l Hertzog: My Free Software Activities in May 2013

This is my monthly summary of my free software related activities. If you re among the people who made a donation to support my work (70 , thanks everybody!), then you can learn how I spent your money. Otherwise it s just an interesting status update on my various projects. The Debian Administrator s Handbook Spanish translation completed. The Spanish team finished the translation of the book. The PDF build process was not yet ready to build translations so I had to fix this. At the same time, I also improved the mobipocket build script to make use of Amazon s kindlegen when available (since Amazon now requires the use of this tool to generate Mobipocket files that can be distributed on their platform). Once those issues were sorted I made some promotion of this first completed translation because they really deserve some big kudos ! Plans for the French translation. You know that the Debian Administrator s Handbook came to life as a translation of the French book Cahier de l Admin Debian (published by Eyrolles). This means that we currently have a free translation of a proprietary book. It s a bid of an odd situation that I always wanted to fix. I discussed with Eyrolles to find out how we could publish the original book under the same licenses that we picked for the English book and the result is that we setup a new crowdfunding campaign to liberate the French book and then make it an official French translation of the Debian Administrator s Handbook. Read the rest and support us on the ulule project page (a kickstarter like for people who are not based in the US). Liberate the Debian Handbook Debian France I updated our membership management application (galette) to version 0.7.4.1 with numerous bug fixes but the true highlight this month was Solutions Libres et Opensource , a tradeshow in Paris where Tanguy Ortolo, me, and other volunteers (C dric Boutillier, Arnaud G., and some that I have forgotten, thanks to them!), held a Debian booth for two consecutive days (May 28-29). For once we had lots of goodies to sell (buffs, mouse pad, polos, stickers, etc.) and the booth was very well attended. The Debian Booth (Tanguy on the left, Rapha l on the right) Google s Summer of Code Last month I was rater overwhelmed with queries from students who were interested in applying for the Package Tracking System Rewrite project that I offered to mentor as part of Google s Summer of Code. In the end, I got 6 good student applications that Stefano and me evaluated. We selected Marko Lalic. The Community Bonding Period is just starting and we re fleshing out details on how we will organize the work. We ll try to use the IRC channel #debian-qa on OFTC for questions and answers and weekly meetings. Misc Debian packaging I packaged zim 0.60 and with the release of Wheezy, I uploaded to unstable all the packages that I staged in experimental (cpputest, publican). I sponsored the upload of libmicrohttpd 0.9.27-1. I filed a couple of bug reports that I experienced with the upcoming dpkg 1.17.0 (#709172, #709009). In both cases, the package was using a wrongly hardcoded path to dpkg-divert (the binary moved from /usr/sbin/ to /usr/bin/ a while ago and the compatibility symlink is dropped now). I also dealt with #709064 where the user reported upgrade issues related to multiarch. I also filed an upstream bug report on publican to request some way to avoid so much duplication of files (actually I filed it as a response to the Debian bug #708705 that I received). Kali work I had to update OpenVAS for Kali but some parts failed to build in a Debian 7 environment. I diagnosed the problem and submitted a patch upstream. I also got in touch with the Debian OpenVAS maintainer as I wanted to contribute the package back to Debian, but timing issues have pushed this back for a little longer. Thanks See you next month for a new summary of my activities.
One comment Liked this article? Click here. My blog is Flattr-enabled.

3 June 2013

John Goerzen: Two boys, shrimp, and stars

I recently made a routine analysis of my kitchen. (Of course I make a routine analysis of my kitchen; don t you?) In it, I discovered these items, still usable, but approaching that magic throw it out date: So, I thought, what can I make that would use all of these? And I realized I had some shrimp in the freezer, so: a shrimp boil! I tossed it all, plus some various seasonings and a few other veggies, into the Dutch oven, and boiled. Jacob and Oliver watched the activity with interest. Well, except for the potato-peeling part. For that, they went and played with their toy school buses. But the rest was good. They carefully observed me adding some spices, some vegetables, the shrimp, and watched it all simmer. Then it was time to eat. Excitement! Of course, it did take a few minutes to boil, so Jacob got down his whiteboard while Oliver looked on. They enjoyed learning how to peel the shell from the shrimp and devoured their food. And another night recently, Jacob unexpectedly showed up in the kitchen at 10PM. He said he was thirsty, so I got him some water. He asked, Dad, did you make ice cream? Earlier that day, I had prepared ice cream with Oliver, but it was a kind that had to be cooked (lemon with pureed strawberries and peaches) and it wasn t cool enough to finish before their bedtime. I did let them help add the ice and salt to the ice cream freezer just before they went to bed. So I told Jacob that yes, the ice cream was done. He stood there, tiredly, considering, with this oh he ll never say yes to ice cream at 10PM look on his face. So I said, would you like one bite right now? The look of delight on his face was amazing; a broad smile, a twinkle in his eyes, and a clap. So I got out the big bowl of ice cream and scooped up one big spoonful. He loved it. Then I said, should we go look at the stars? I carried Jacob outside to the porch. We stood there, looking up. I used to do this with him periodically, but it had been about a year. So he was thrilled. It was a partially overcast night, but there were still some stars visible. He had no idea there were some stars missing. To him, it was amazing and wonderful and infinite. Oh dad, there are way too many stars to count! He stayed there, arms around my neck, for a minute or two, then was ready to go back inside. I set him down, gave him a hug, said Goodnight, Jacob. And off he trotted, back upstairs, wearing a contented smile, and he fell asleep almost immediately. All it takes to delight children is a bit a shrimp or some stars. And those things delight me, too.

2 June 2013

Thomas Goirand: dtc-xentop: monitoring of CPU, I/O and network for your Xen VMs

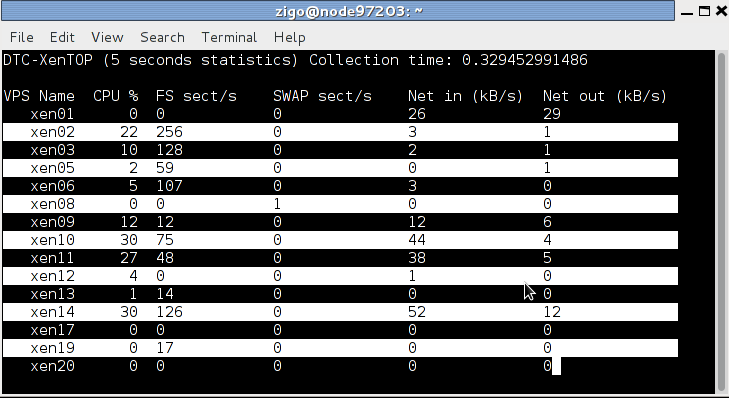
What has always been annoying me with Xen, is that xentop is well a piece of shit! It just displays the current numbers of sectors or network bytes read / write. But as an administrator, what you care about, is to know which of your VM is taking all the resources, making your whole server starve. The number of sectors read/write since the VM has started is of very low importance. What you care about is to have an idea of the current transfer rate. And the same apply for networking. So, tonight, within few hours, I hacked a small python shell script using ncurses to do what I needed, which tells how much resources have been used over the last 5 seconds (and not since the VM started). This way, it is easy to know which VM is killing your server. dtc-xentop The script is adapted to my own needs only. Which means that it works only for DTC-Xen VMs of GPLHost. In my case, VM uses exactly 2 partitions, one for the filesystem, and one for the swap, which means that I display exactly that. I m sure it wouldn t be hard to adapt it so that it would work for all cases (which would mean finding out what device uses a VM and getting the statistics from /sys using that information, instead of determining it using the name of the VM). But I don t need it, so the script will stay this way. Before writing this tonight, I didn t know ncurses. Well, it s really not hard, especially in Python! It took me about 2 hours to write^Whack the script (cheating on the dtc-xen soap server which I already had available).
Next.

Previous.


