Search Results: "ron"

20 November 2024

Russell Coker: Solving Spam and Phishing for Corporations

Centralisation and Corporations An advantage of a medium to large company is that it permits specialisation. For example I m currently working in the IT department of a medium sized company and because we have standardised hardware (Dell Latitude and Precision laptops, Dell Precision Tower workstations, and Dell PowerEdge servers) and I am involved in fixing all Linux compatibility issues on that I can fix most problems in a small fraction of the time that I would take to fix on a random computer. There is scope for a lot of debate about the extent to which companies should standardise and centralise things. But for computer problems which can escalate quickly from minor to serious if not approached in the correct manner it s clear that a good deal of centralisation is appropriate. For people doing technical computer work such as programming there s a large portion of the employees who are computer hobbyists who like to fiddle with computers. But if the support system is run well even they will appreciate having computers just work most of the time and for a large portion of the failures having someone immediately recognise the problem, like the issues with NVidia drivers that I have documented so that first line support can implement workarounds without the need for a lengthy investigation. A big problem with email in the modern Internet is the prevalence of Phishing scams. The current corporate approach to this is to send out test Phishing email to people and then force computer security training on everyone who clicks on them. One problem with this is that attackers only need to fool one person on one occasion and when you have hundreds of people doing something on rare occasions that s not part of their core work they will periodically get it wrong. When every test Phishing run finds several people who need extra training it seems obvious to me that this isn t a solution that s working well. I will concede that the majority of people who click on the test Phishing email would probably realise their mistake if asked to enter the password for the corporate email system, but I think it s still clear that this isn t a great solution. Let s imagine for the sake of discussion that everyone in a company was 100% accurate at identifying Phishing email and other scam email, if that was the case would the problem be solved? I believe that even in that hypothetical case it would not be a solved problem due to the wasted time and concentration. People can spend minutes determining if a single email is legitimate. On many occasions I have had relatives and clients forward me email because they are unsure if it s valid, it s great that they seek expert advice when they are unsure about things but it would be better if they didn t have to go to that effort. What we ideally want to do is centralise the anti-Phishing and anti-spam work to a small group of people who are actually good at it and who can recognise patterns by seeing larger quantities of spam. When a spam or Phishing message is sent to 600 people in a company you don t want 600 people to individually consider it, you want one person to recognise it and delete/block all 600. If 600 people each spend one minute considering the matter then that s 10 work hours wasted! The Rationale for Human Filtering For personal email human filtering usually isn t viable because people want privacy. But corporate email isn t private, it s expected that the company can read it under certain circumstances (in most jurisdictions) and having email open in public areas of the office where colleagues might see it is expected. You can visit gmail.com on your lunch break to read personal email but every company policy (and common sense) says to not have actually private correspondence on company systems. The amount of time spent by reception staff in sorting out such email would be less than that taken by individuals. When someone sends a spam to everyone in the company instead of 500 people each spending a couple of minutes working out whether it s legit you have one person who s good at recognising spam (because it s their job) who clicks on a remove mail from this sender from all mailboxes button and 500 messages are deleted and the sender is blocked. Delaying email would be a concern. It s standard practice for CEOs (and C*Os at larger companies) to have a PA receive their email and forward the ones that need their attention. So human vetting of email can work without unreasonable delays. If we had someone checking all email for the entire company probably email to the senior people would never get noticeably delayed and while people like me would get their mail delayed on occasion people doing technical work generally don t have notifications turned on for email because it s a distraction and a fast response isn t needed. There are a few senders where fast response is required, which is mostly corporations sending a click this link within 10 minutes to confirm your password change email. Setting up rules for all such senders that are relevant to work wouldn t be difficult to do. How to Solve This Spam and Phishing became serious problems over 20 years ago and we have had 20 years of evolution of email filtering which still hasn t solved the problem. The vast majority of email addresses in use are run by major managed service providers and they haven t managed to filter out spam/phishing mail effectively so I think we should assume that it s not going to be solved by filtering. There is talk about what AI technology might do for filtering spam/phishing but that same technology can product better crafted hostile email to avoid filters. An additional complication for corporate email filtering is that some criteria that are used to filter personal email don t apply to corporate mail. If someone sends email to me personally about millions of dollars then it s obviously not legit. If someone sends email to a company then it could be legit. Companies routinely have people emailing potential clients about how their products can save millions of dollars and make purchases over a million dollars. This is not a problem that s impossible to solve, it s just an extra difficulty that reduces the efficiency of filters. It seems to me that the best solution to the problem involves having all mail filtered by a human. A company could configure their mail server to not accept direct external mail for any employee s address. Then people could email files to colleagues etc without any restriction but spam and phishing wouldn t be a problem. The issue is how to manage inbound mail. One possibility is to have addresses of the form it+russell.coker@example.com (for me as an employee in the IT department) and you would have a team of people who would read those mailboxes and forward mail to the right people if it seemed legit. Having addresses like it+russell.coker means that all mail to the IT department would be received into folders of the same account and they could be filtered by someone with suitable security level and not require any special configuration of the mail server. So the person who read the is mailbox would have a folder named russell.coker receiving mail addressed to me. The system could be configured to automate the processing of mail from known good addresses (and even domains), so they could just put in a rule saying that when Dell sends DMARC authenticated mail to is+$USER it gets immediately directed to $USER. This is the sort of thing that can be automated in the email client (mail filtering is becoming a common feature in MUAs). For a FOSS implementation of such things the server side of it (including extracting account data from a directory to determine which department a user is in) would be about a day s work and then an option would be to modify a webmail program to have extra functionality for approving senders and sending change requests to the server to automatically direct future mail from the same sender. As an aside I have previously worked on a project that had a modified version of the Horde webmail system to do this sort of thing for challenge-response email and adding certain automated messages to the allow-list. The Change One of the first things to do is configuring the system to add every recipient of an outbound message to the allow list for receiving a reply. Having a script go through the sent-mail folders of all accounts and adding the recipients to the allow lists would be easy and catch the common cases. But even with processing the sent mail folders going from a working system without such things to a system like this will take some time for the initial work of adding addresses to the allow lists, particularly for domain wide additions of all the sites that send password confirmation messages. You would need rules to direct inbound mail to the old addresses to the new style and then address a huge amount of mail that needs to be categorised. If you have 600 employees and the average amount of time taken on the first day is 10 minutes per user then that s 100 hours of work, 12 work days. If you had everyone from the IT department, reception, and executive assistants working on it that would be viable. After about a week there wouldn t be much work involved in maintaining it. Then after that it would be a net win for the company. The Benefits If the average employee spends one minute a day dealing with spam and phishing email then with 600 employees that s 10 hours of wasted time per day. Effectively wasting one employee s work! I m sure that s the low end of the range, 5 minutes average per day doesn t seem unreasonable especially when people are unsure about phishing email and send it to Slack so multiple employees spend time analysing it. So you could have 5 employees being wasted by hostile email and avoiding that would take a fraction of the time of a few people adding up to less than an hour of total work per day. Then there s the training time for phishing mail. Instead of having every employee spend half an hour doing email security training every few months (that s 300 hours or 7.5 working weeks every time you do it) you just train the few experts. In addition to saving time there are significant security benefits to having experts deal with possibly hostile email. Someone who deals with a lot of phishing email is much less likely to be tricked. Will They Do It? They probably won t do it any time soon. I don t think it s expensive enough for companies yet. Maybe government agencies already have equivalent measures in place, but for regular corporations it s probably regarded as too difficult to change anything and the costs aren t obvious. I have been unsuccessful in suggesting that managers spend slightly more on computer hardware to save significant amounts of worker time for 30 years.

Arnaud Rebillout: Installing an older Ansible version via pipx

Latest Ansible requires Python 3.8 on the remote hosts ... and therefore, hosts running Debian Buster are now unsupported. Monday, I updated the system on my laptop (Debian Sid), and I got the latest version of ansible-core, 2.18:
$ ansible --version   head -1
ansible [core 2.18.0]
To my surprise, Ansible started to fail with some remote hosts:
ansible-core requires a minimum of Python version 3.8. Current version: 3.7.3 (default, Mar 23 2024, 16:12:05) [GCC 8.3.0]
Yep, I do have to work with hosts running Debian Buster (aka. oldoldstable). While Buster is old, it's still out there, and it's still supported via Freexian s Extended LTS. How are we going to keep managing those machines? Obviously, we'll need an older version of Ansible. Pipx to the rescue TL;DR
pipx install --include-deps ansible==10.6.0
pipx inject ansible dnspython    # for community.general.dig
Installing Ansible via pipx Lately I discovered pipx and it's incredibly simple, so I thought I'd give it a try for this use-case. Reminder: pipx allows users to install Python applications in isolated environments. In other words, it doesn't make a mess with your system like pip does, and it doesn't require you to learn how to setup Python virtual environments by yourself. It doesn't ask for root privileges either, as it installs everything under ~/.local/. First thing to know: pipx install ansible won't cut it, it doesn't install the whole Ansible suite. Instead we need to use the --include-deps flag in order to install all the Ansible commands. The output should look something like that:
$ pipx install --include-deps ansible==10.6.0
  installed package ansible 10.6.0, installed using Python 3.12.7
  These apps are now globally available
    - ansible
    - ansible-community
    - ansible-config
    - ansible-connection
    - ansible-console
    - ansible-doc
    - ansible-galaxy
    - ansible-inventory
    - ansible-playbook
    - ansible-pull
    - ansible-test
    - ansible-vault
done!      
Note: at the moment 10.6.0 is the latest release of the 10.x branch, but make sure to check https://pypi.org/project/ansible/#history and install whatever is the latest on this branch. The 11.x branch doesn't work for us, as it's the branch that comes with ansible-core 2.18, and we don't want that. Next: do NOT run pipx ensurepath, even though pipx might suggest that. This is not needed. Instead, check your ~/.profile, it should contain these lines:
# set PATH so it includes user's private bin if it exists
if [ -d "$HOME/.local/bin" ] ; then
    PATH="$HOME/.local/bin:$PATH"
fi
Meaning: ~/.local/bin/ should already be in your path, unless it's the first time you installed a program via pipx and the directory ~/.local/bin/ was just created. If that's the case, you have to log out and log back in. Now, let's open a new terminal and check if we're good:
$ which ansible
/home/me/.local/bin/ansible
$ ansible --version   head -1
ansible [core 2.17.6]
Yep! And that's working already, I can use Ansible with Buster hosts again. What's cool is that we can run ansible to use this specific Ansible version, but we can also run /usr/bin/ansible to run the latest version that is installed via APT. Injecting Python dependencies needed by collections Quickly enough, I realized something odd, apparently the plugin community.general.dig didn't work anymore. After some research, I found a one-liner to test that:
# Works with APT-installed Ansible? Yes!
$ /usr/bin/ansible all -i localhost, -m debug -a msg="  lookup('dig', 'debian.org./A')  "
localhost   SUCCESS =>  
    "msg": "151.101.66.132,151.101.2.132,151.101.194.132,151.101.130.132"
 
# Works with pipx-installed Ansible? No!
$ ansible all -i localhost, -m debug -a msg="  lookup('dig', 'debian.org./A')  "
localhost   FAILED! =>  
  "msg": "An unhandled exception occurred while running the lookup plugin 'dig'.
  Error was a <class 'ansible.errors.AnsibleError'>, original message: The dig
  lookup requires the python 'dnspython' library and it is not installed."
 
The issue here is that we need python3-dnspython, which is installed on my system, but is not installed within the pipx virtual environment. It seems that the way to go is to inject the required dependencies in the venv, which is (again) super easy:
$ pipx inject ansible dnspython
  injected package dnspython into venv ansible
done!      
Problem fixed! Of course you'll have to iterate to install other missing dependencies, depending on which Ansible external plugins are used in your playbooks. Closing thoughts Hopefully there's nothing left to discover and I can get back to work! If there's more quirks and rough edges, drop me an email so that I can update this blog post. Let me also credit another useful blog post on the matter: https://unfriendlygrinch.info/posts/effortless-ansible-installation/

19 November 2024

Aurelien Jarno: AI crawlers should be smarter

It would be fantastic if all those AI companies dedicated some time to make their web crawlers smarter (what about using AI?). Noawadays most of them still stupidly follow every link on a Git frontend. Hint: Changing the display options does not provide more training data!
Melissa Wen: Display/KMS Meeting at XDC 2024: Detailed Report

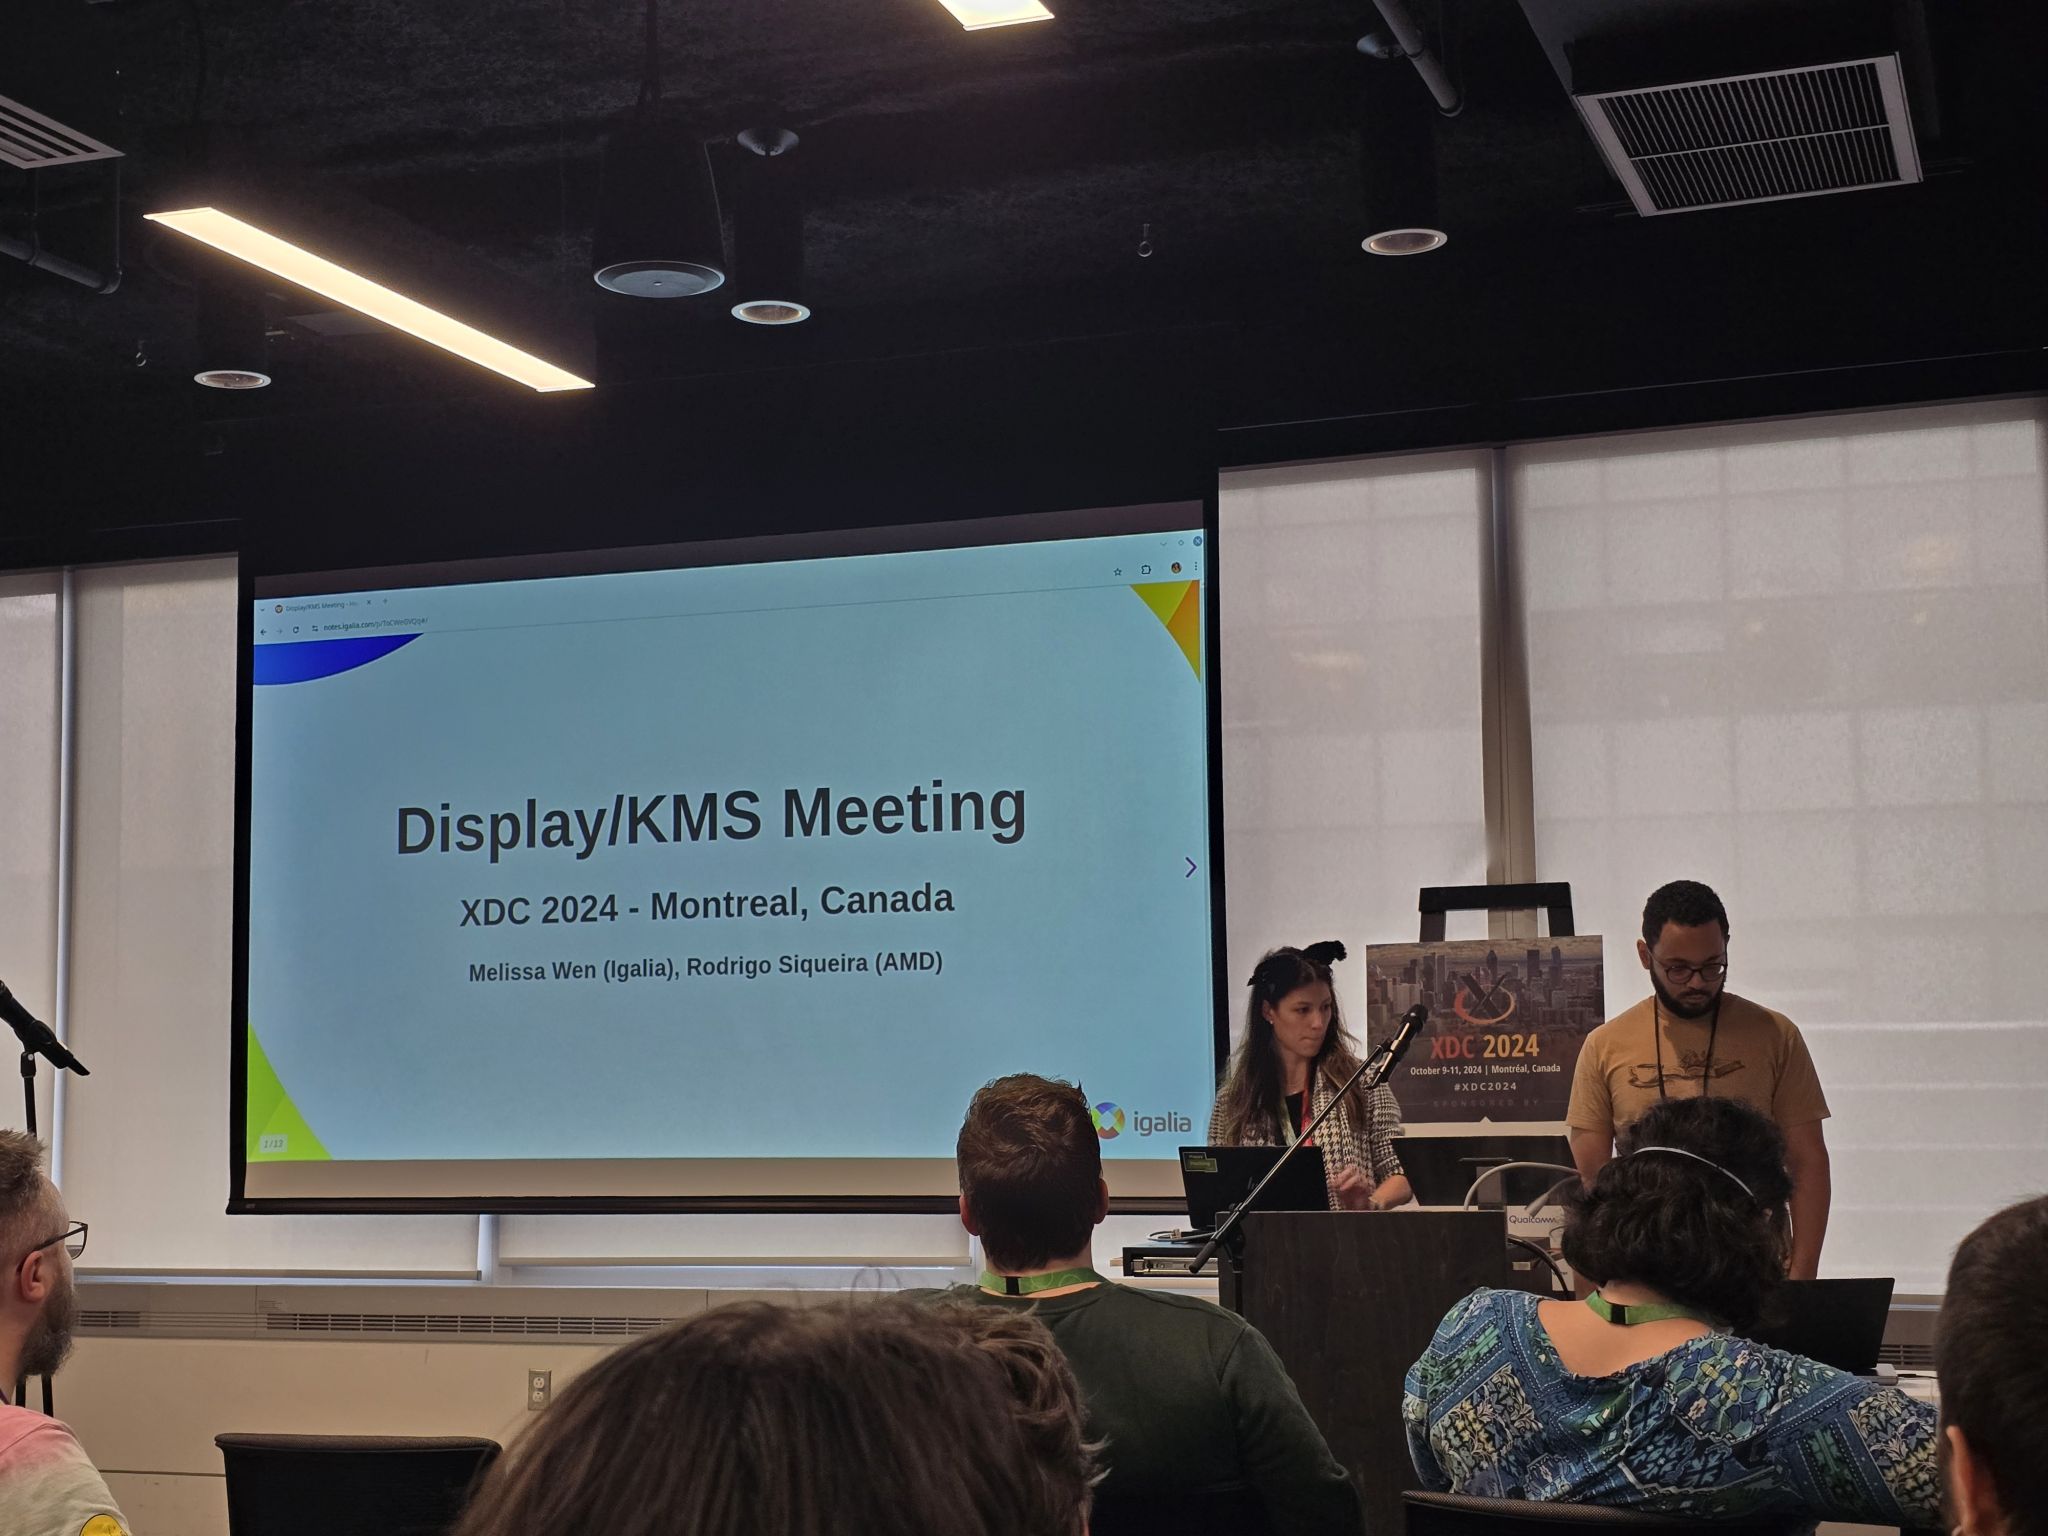
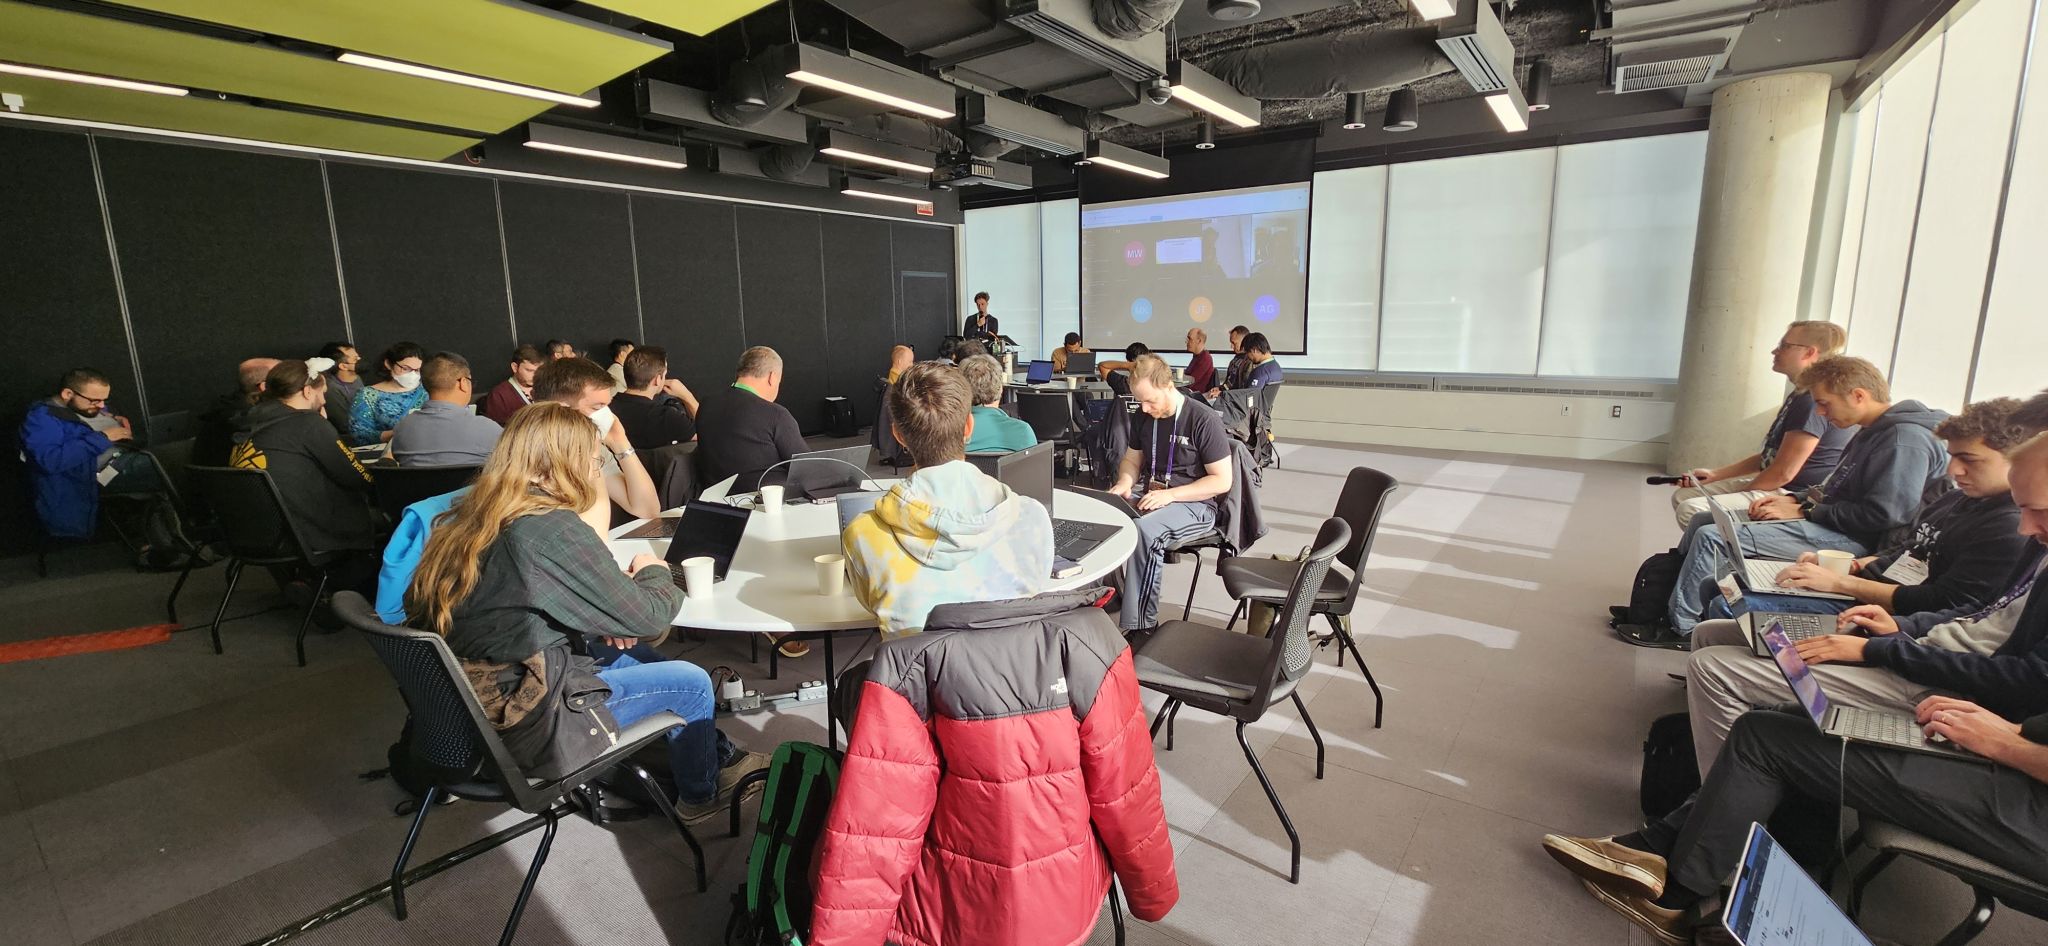
XDC 2024 in Montreal was another fantastic gathering for the Linux Graphics community. It was again a great time to immerse in the world of graphics development, engage in stimulating conversations, and learn from inspiring developers. Many Igalia colleagues and I participated in the conference again, delivering multiple talks about our work on the Linux Graphics stack and also organizing the Display/KMS meeting. This blog post is a detailed report on the Display/KMS meeting held during this XDC edition. Short on Time?
  1. Catch the lightning talk summarizing the meeting here (you can even speed up 2x):
  1. For a quick written summary, scroll down to the TL;DR section.

TL;DR This meeting took 3 hours and tackled a variety of topics related to DRM/KMS (Linux/DRM Kernel Modesetting):
  • Sharing Drivers Between V4L2 and KMS: Brainstorming solutions for using a single driver for devices used in both camera capture and display pipelines.
  • Real-Time Scheduling: Addressing issues with non-blocking page flips encountering sigkills under real-time scheduling.
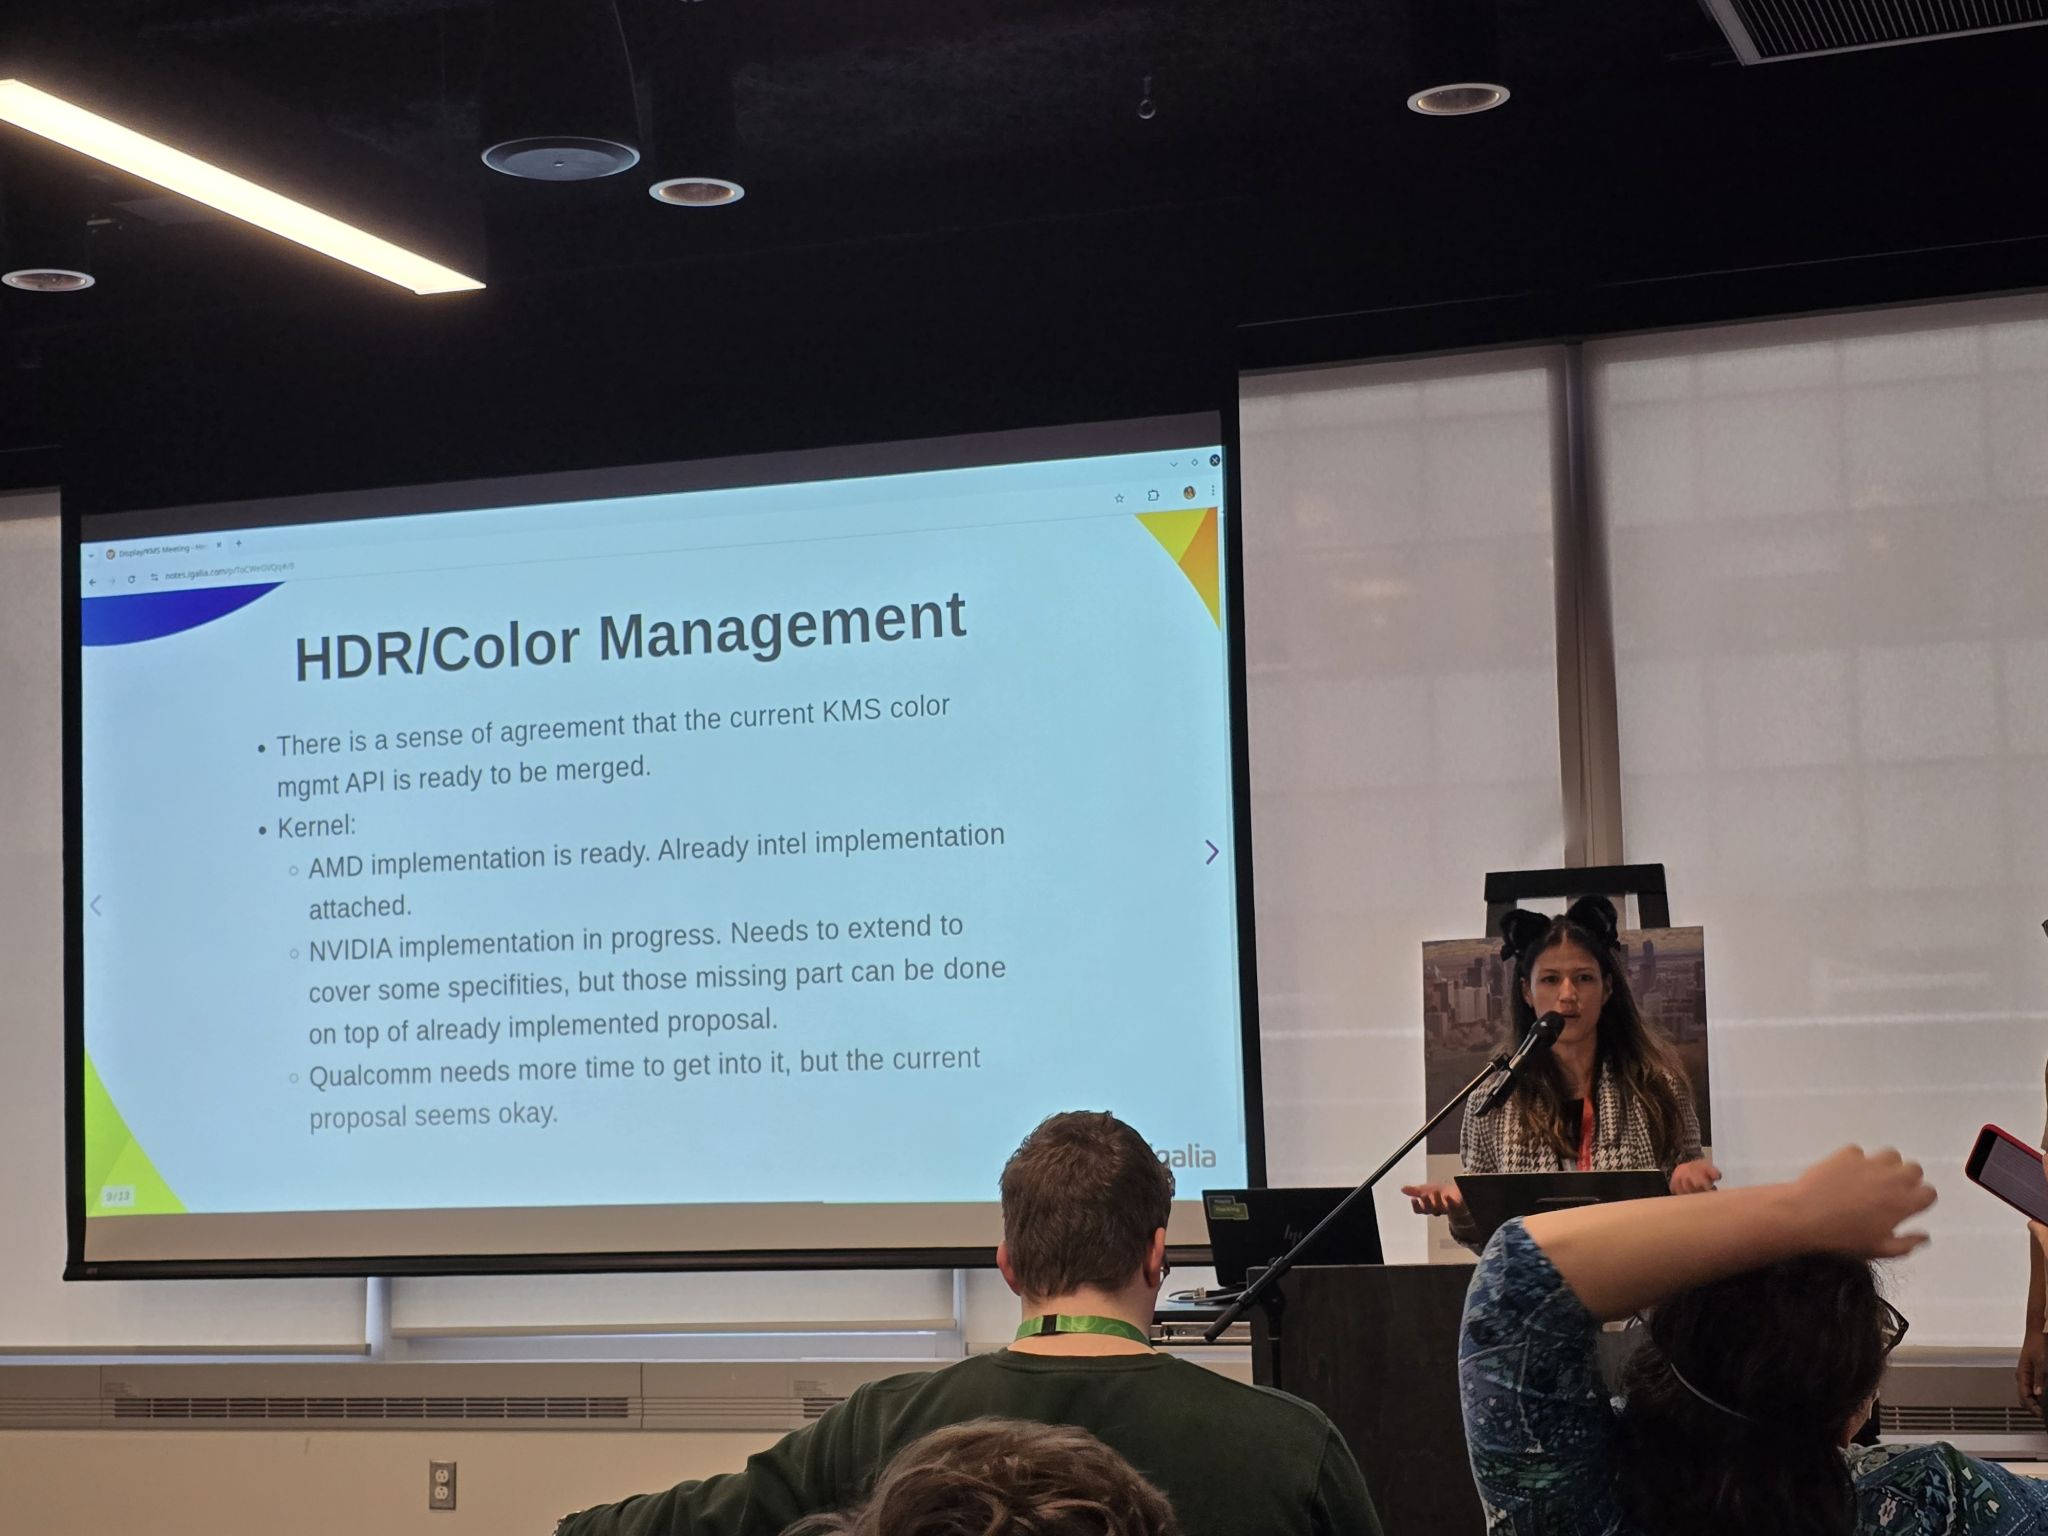
  • HDR/Color Management: Agreement on merging the current proposal, with NVIDIA implementing its special cases on VKMS and adding missing parts on top of Harry Wentland s (AMD) changes.
  • Display Mux: Collaborative design discussions focusing on compositor control and cross-sync considerations.
  • Better Commit Failure Feedback: Exploring ways to equip compositors with more detailed information for failure analysis.

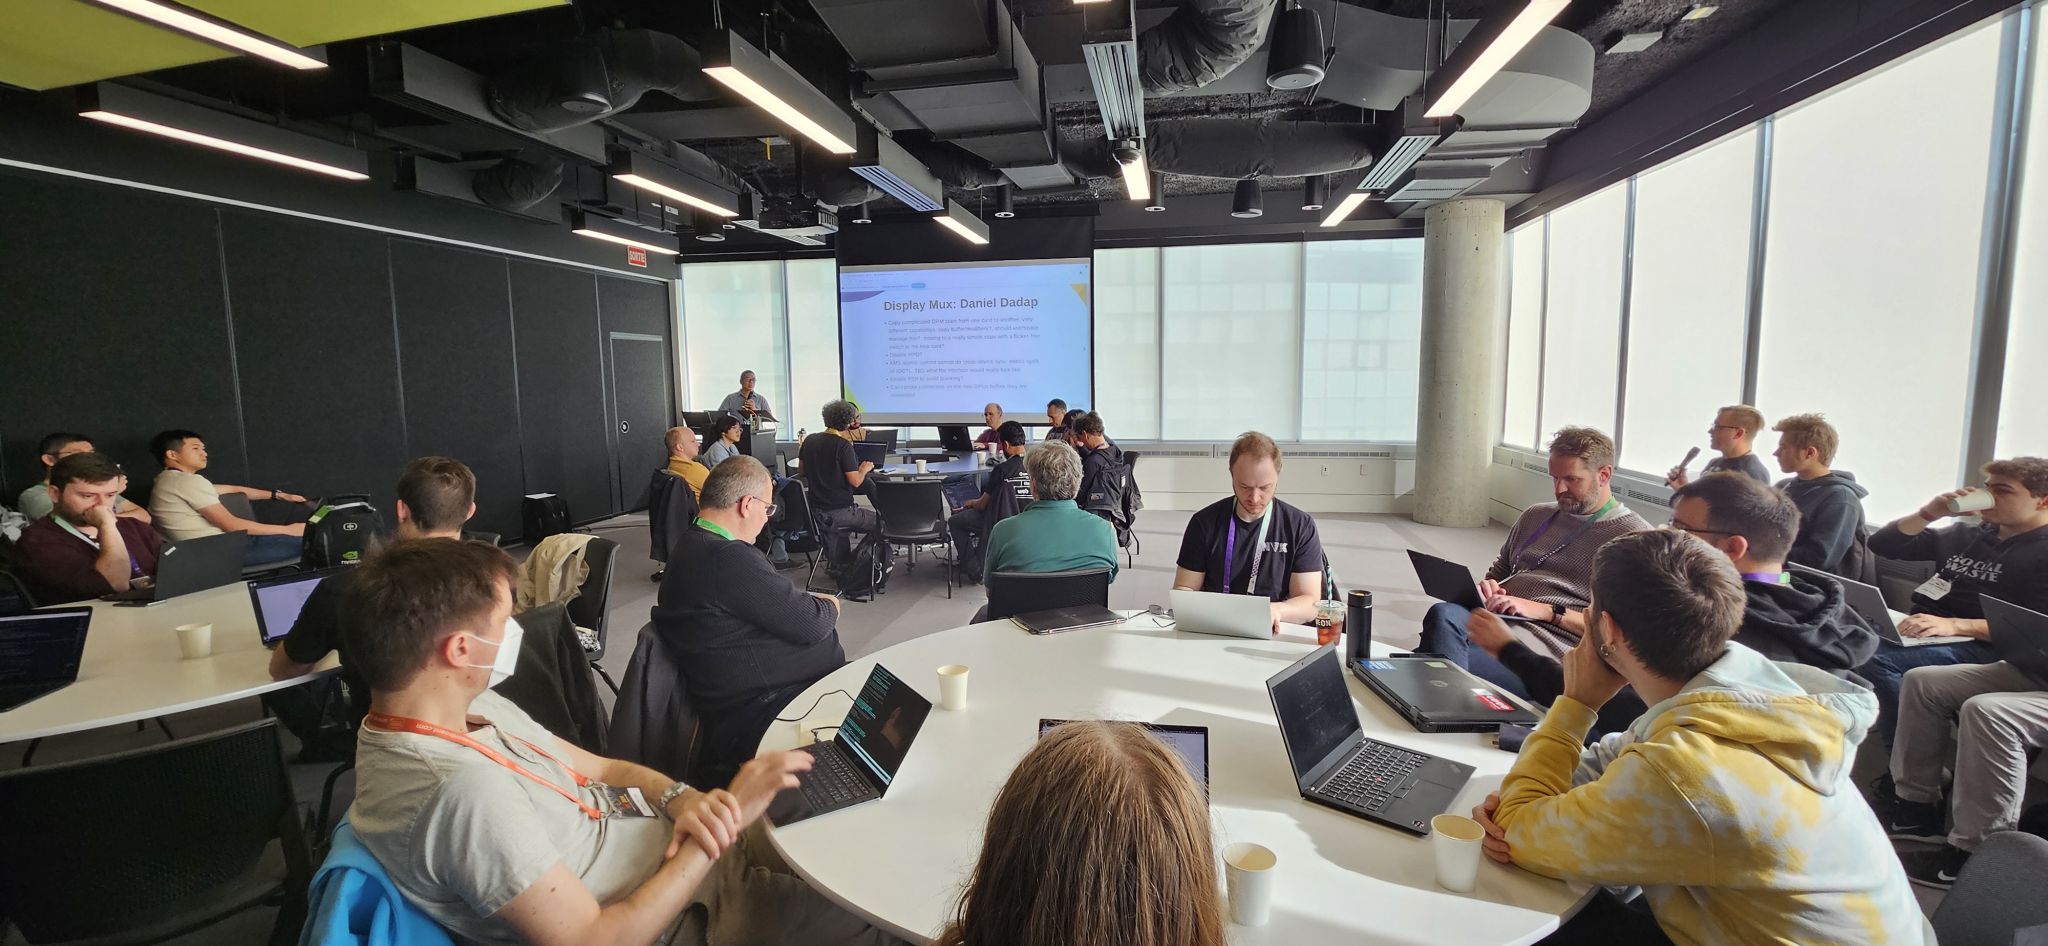
Bringing together Linux display developers in the XDC 2024 While I didn t present a talk this year, I co-organized a Display/KMS meeting (with Rodrigo Siqueira of AMD) to build upon the momentum from the 2024 Linux Display Next hackfest. The meeting was attended by around 30 people in person and 4 remote participants. Speakers: Melissa Wen (Igalia) and Rodrigo Siqueira (AMD) Link: https://indico.freedesktop.org/event/6/contributions/383/ Topics: Similar to the hackfest, the meeting agenda was built over the first two days of the conference and mixed talks follow-up with new ideas and ongoing community efforts. The final agenda covered five topics in the scheduled order:
  1. How to share drivers between V4L2 and DRM for bridge-like components (new topic);
  2. Real-time Scheduling (problems encountered after the Display Next hackfest);
  3. HDR/Color Management (ofc);
  4. Display Mux (from Display hackfest and XDC 2024 talk, bringing AMD and NVIDIA together);
  5. (Better) Commit Failure Feedback (continuing the last minute topic of the Display Next hackfest).

Unpacking the Topics Similar to the hackfest, the meeting agenda evolved over the conference. During the 3 hours of meeting, I coordinated the room and discussion rounds, and Rodrigo Siqueira took notes and also contacted key developers to provide a detailed report of the many topics discussed. From his notes, let s dive into the key discussions!

How to share drivers between V4L2 and KMS for bridge-like components. Led by Laurent Pinchart, we delved into the challenge of creating a unified driver for hardware devices (like scalers) that are used in both camera capture pipelines and display pipelines.
  • Problem Statement: How can we design a single kernel driver to handle devices that serve dual purposes in both V4L2 and DRM subsystems?
  • Potential Solutions:
    1. Multiple Compatible Strings: We could assign different compatible strings to the device tree node based on its usage in either the camera or display pipeline. However, this approach might raise concerns from device tree maintainers as it could be seen as a layer violation.
    2. Separate Abstractions: A single driver could expose the device to both DRM and V4L2 through separate abstractions: drm-bridge for DRM and V4L2 subdev for video. While simple, this approach requires maintaining two different abstractions for the same underlying device.
    3. Unified Kernel Abstraction: We could create a new, unified kernel abstraction that combines the best aspects of drm-bridge and V4L2 subdev. This approach offers a more elegant solution but requires significant design effort and potential migration challenges for existing hardware.

Real-Time Scheduling Challenges We have discussed real-time scheduling during this year Linux Display Next hackfest and, during the XDC 2024, Jonas Adahl brought up issues uncovered while progressing on this front.
  • Context: Non-blocking page-flips can, on rare occasions, take a long time and, for that reason, get a sigkill if the thread doing the atomic commit is a real-time schedule.
  • Action items:
    • Explore alternative backtraces during the busy wait (e.g., ftrace).
    • Investigate the maximum thread time in busy wait to reproduce issues faced by compositors. Tools like RTKit (mutter) can be used for better control (Michel D nzer can help with this setup).

HDR/Color Management This is a well-known topic with ongoing effort on all layers of the Linux Display stack and has been discussed online and in-person in conferences and meetings over the last years. Here s a breakdown of the key points raised at this meeting:
  • Talk: Color operations for Linux color pipeline on AMD devices: In the previous day, Alex Hung (AMD) presented the implementation of this API on AMD display driver.
  • NVIDIA Integration: While they agree with the overall proposal, NVIDIA needs to add some missing parts. Importantly, they will implement these on top of Harry Wentland s (AMD) proposal. Their specific requirements will be implemented on VKMS (Virtual Kernel Mode Setting driver) for further discussion. This VKMS implementation can benefit compositor developers by providing insights into NVIDIA s specific needs.
  • Other vendors: There is a version of the KMS API applied on Intel color pipeline. Apart from that, other vendors appear to be comfortable with the current proposal but lacks the bandwidth to implement it right now.
  • Upstream Patches: The relevant upstream patches were can be found here. [As humorously notes, this series is eagerly awaiting your Acked-by (approval)]
  • Compositor Side: The compositor developers have also made significant progress.
    • KDE has already implemented and validated the API through an experimental implementation in Kwin.
    • Gamescope currently uses a driver-specific implementation but has a draft that utilizes the generic version. However, some work is still required to fully transition away from the driver-specific approach. AP: work on porting gamescope to KMS generic API
    • Weston has also begun exploring implementation, and we might see something from them by the end of the year.
  • Kernel and Testing: The kernel API proposal is well-refined and meets the DRM subsystem requirements. Thanks to Harry Wentland effort, we already have the API attached to two hardware vendors and IGT tests, and, thanks to Xaver Hugl, a compositor implementation in place.
Finally, there was a strong sense of agreement that the current proposal for HDR/Color Management is ready to be merged. In simpler terms, everything seems to be working well on the technical side - all signs point to merging and shipping the DRM/KMS plane color management API!

Display Mux During the meeting, Daniel Dadap led a brainstorming session on the design of the display mux switching sequence, in which the compositor would arm the switch via sysfs, then send a modeset to the outgoing driver, followed by a modeset to the incoming driver.
  • Context:
  • Key Considerations:
    • HPD Handling: There was a general consensus that disabling HPD can be part of the sequence for internal panels and we don t need to focus on it here.
    • Cross-Sync: Ensuring synchronization between the compositor and the drivers is crucial. The compositor should act as the drm-master to coordinate the entire sequence, but how can this be ensured?
    • Future-Proofing: The design should not assume the presence of a mux. In future scenarios, direct sharing over DP might be possible.
  • Action points:
    • Sharing DP AUX: Explore the idea of sharing DP AUX and its implications.
    • Backlight: The backlight definition represents a problem in the mux switch context, so we should explore some of the current specs available for that.

Towards Better Commit Failure Feedback In the last part of the meeting, Xaver Hugl asked for better commit failure feedback.
  • Problem description: Compositors currently face challenges in collecting detailed information from the kernel about commit failures. This lack of granular data hinders their ability to understand and address the root causes of these failures.
To address this issue, we discussed several potential improvements:
  • Direct Kernel Log Access: One idea is to directly load relevant kernel logs into the compositor. This would provide more detailed information about the failure and potentially aid in debugging.
  • Finer-Grained Failure Reporting: We also explored the possibility of separating atomic failures into more specific categories. Not all failures are critical, and understanding the nature of the failure can help compositors take appropriate action.
  • Enhanced Logging: Currently, the dmesg log doesn t provide enough information for user-space validation. Raising the log level to capture more detailed information during failures could be a viable solution.
By implementing these improvements, we aim to equip compositors with the necessary tools to better understand and resolve commit failures, leading to a more robust and stable display system.

A Big Thank You! Huge thanks to Rodrigo Siqueira for these detailed meeting notes. Also, Laurent Pinchart, Jonas Adahl, Daniel Dadap, Xaver Hugl, and Harry Wentland for bringing up interesting topics and leading discussions. Finally, thanks to all the participants who enriched the discussions with their experience, ideas, and inputs, especially Alex Goins, Antonino Maniscalco, Austin Shafer, Daniel Stone, Demi Obenour, Jessica Zhang, Joan Torres, Leo Li, Liviu Dudau, Mario Limonciello, Michel D nzer, Rob Clark, Simon Ser and Teddy Li. This collaborative effort will undoubtedly contribute to the continued development of the Linux display stack. Stay tuned for future updates!

18 November 2024

Dirk Eddelbuettel: RcppArmadillo 14.2.0-1 on CRAN: New Upstream Minor

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1191 other packages on CRAN, downloaded 37.2 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 603 times according to Google Scholar. Conrad released a minor version 14.2.0 a few days ago after we spent about two weeks with several runs of reverse-dependency checks covering corner cases. After a short delay at CRAN due to a false positive on a test, a package failing tests we also failed under the previous version, and some concern over new deprecation warnings _whem using the headers directly as _e.g. mlpack R package does we are now on CRAN. I noticed a missing feature under large 64bit word (for large floating-point matrices) and added an exporter for icube going to double to support the 64-bit integer range (as we already did, of course, for vectors and matrices). Changes since the last CRAN release are summarised below.

Changes in RcppArmadillo version 14.2.0-1 (2024-11-16)
  • Upgraded to Armadillo release 14.2.0 (Smooth Caffeine)
    • Faster handling of symmetric matrices by inv() and rcond()
    • Faster handling of hermitian matrices by inv(), rcond(), cond(), pinv(), rank()
    • Added solve_opts::force_sym option to solve() to force the use of the symmetric solver
    • More efficient handling of compound expressions by solve()
  • Added exporter specialisation for icube for the ARMA_64BIT_WORD case

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

C.J. Collier: Managing HPE SAS Controllers

Notes to self. And anyone else who might find them useful. Following are some ssacli commands which I use infrequently enough that they fall out of cache. This may repeat information in other blogs, but since I search my posts first when commands slip my mind, I thought I d include them here, too. hpacucli is the wrong command. Use ssacli instead.
$ KR='/usr/share/keyrings/hpe.gpg'
$ for fingerprint in \
  882F7199B20F94BD7E3E690EFADD8D64B1275EA3 \
  57446EFDE098E5C934B69C7DC208ADDE26C2B797 \
  476DADAC9E647EE27453F2A3B070680A5CE2D476 ; do \
    curl "https://keyserver.ubuntu.com/pks/lookup?op=get&search=0x$ fingerprint " \
        gpg --no-default-keyring --keyring "$ KR " --import ; \
  done
$ gpg --list-keys --no-default-keyring --keyring "$ KR " 
/usr/share/keyrings/hpe.gpg
---------------------------
pub   rsa2048 2012-12-04 [SC] [expired: 2022-12-02]
      476DADAC9E647EE27453F2A3B070680A5CE2D476
uid           [ expired] Hewlett-Packard Company RSA (HP Codesigning Service)
pub   rsa2048 2014-11-19 [SC] [expired: 2024-11-16]
      882F7199B20F94BD7E3E690EFADD8D64B1275EA3
uid           [ expired] Hewlett-Packard Company RSA (HP Codesigning Service) - 1
pub   rsa2048 2015-12-10 [SCEA] [expires: 2025-12-07]
      57446EFDE098E5C934B69C7DC208ADDE26C2B797
uid           [ unknown] Hewlett Packard Enterprise Company RSA-2048-25 
$ echo "deb [signed-by=$ KR ] http://downloads.linux.hpe.com/SDR/repo/mcp bookworm/current non-free" \
    sudo dd of=/etc/apt/sources.list.d status=none
$ sudo apt-get update
$ sudo apt-get install -y -qq ssacli > /dev/null 2>&1
$ sudo ssacli ctrl all show status
HPE Smart Array P408i-p SR Gen10 in Slot 3
   Controller Status: OK
   Cache Status: OK
   Battery/Capacitor Status: OK
$ sudo ssacli ctrl all show detail
HPE Smart Array P408i-p SR Gen10 in Slot 3
   Bus Interface: PCI
   Slot: 3
   Serial Number: PFJHD0ARCCR1QM
   RAID 6 Status: Enabled
   Controller Status: OK
   Hardware Revision: B
   Firmware Version: 2.65
   Firmware Supports Online Firmware Activation: True
   Driver Supports Online Firmware Activation: True
   Rebuild Priority: High
   Expand Priority: Medium
   Surface Scan Delay: 3 secs
   Surface Scan Mode: Idle
   Parallel Surface Scan Supported: Yes
   Current Parallel Surface Scan Count: 1
   Max Parallel Surface Scan Count: 16
   Queue Depth: Automatic
   Monitor and Performance Delay: 60  min
   Elevator Sort: Enabled
   Degraded Performance Optimization: Disabled
   Inconsistency Repair Policy: Disabled
   Write Cache Bypass Threshold Size: 1040 KiB
   Wait for Cache Room: Disabled
   Surface Analysis Inconsistency Notification: Disabled
   Post Prompt Timeout: 15 secs
   Cache Board Present: True
   Cache Status: OK
   Cache Ratio: 10% Read / 90% Write
   Configured Drive Write Cache Policy: Disable
   Unconfigured Drive Write Cache Policy: Default
   Total Cache Size: 2.0
   Total Cache Memory Available: 1.8
   Battery Backed Cache Size: 1.8
   No-Battery Write Cache: Disabled
   SSD Caching RAID5 WriteBack Enabled: True
   SSD Caching Version: 2
   Cache Backup Power Source: Batteries
   Battery/Capacitor Count: 1
   Battery/Capacitor Status: OK
   SATA NCQ Supported: True
   Spare Activation Mode: Activate on physical drive failure (default)
   Controller Temperature (C): 53
   Cache Module Temperature (C): 43
   Capacitor Temperature  (C): 40
   Number of Ports: 2 Internal only
   Encryption: Not Set
   Express Local Encryption: False
   Driver Name: smartpqi
   Driver Version: Linux 2.1.18-045
   PCI Address (Domain:Bus:Device.Function): 0000:11:00.0
   Negotiated PCIe Data Rate: PCIe 3.0 x8 (7880 MB/s)
   Controller Mode: Mixed
   Port Max Phy Rate Limiting Supported: False
   Latency Scheduler Setting: Disabled
   Current Power Mode: MaxPerformance
   Survival Mode: Enabled
   Host Serial Number: 2M20040D1Q
   Sanitize Erase Supported: True
   Sanitize Lock: None
   Sensor ID: 0
      Location: Capacitor
      Current Value (C): 40
      Max Value Since Power On: 42
   Sensor ID: 1
      Location: ASIC
      Current Value (C): 53
      Max Value Since Power On: 55
   Sensor ID: 2
      Location: Unknown
      Current Value (C): 43
      Max Value Since Power On: 45
   Sensor ID: 3
      Location: Cache
      Current Value (C): 43
      Max Value Since Power On: 44
   Primary Boot Volume: None
   Secondary Boot Volume: None
$ sudo ssacli ctrl all show config
HPE Smart Array P408i-p SR Gen10 in Slot 3  (sn: PFJHD0ARCCR1QM)
   Internal Drive Cage at Port 1I, Box 2, OK
   Internal Drive Cage at Port 2I, Box 2, OK
   Port Name: 1I (Mixed)
   Port Name: 2I (Mixed)
   Array A (SAS, Unused Space: 0  MB)
      logicaldrive 1 (1.64 TB, RAID 6, OK)
      physicaldrive 1I:2:1 (port 1I:box 2:bay 1, SAS HDD, 300 GB, OK)
      physicaldrive 1I:2:2 (port 1I:box 2:bay 2, SAS HDD, 1.2 TB, OK)
      physicaldrive 1I:2:3 (port 1I:box 2:bay 3, SAS HDD, 300 GB, OK)
      physicaldrive 1I:2:4 (port 1I:box 2:bay 4, SAS HDD, 1.2 TB, OK)
      physicaldrive 2I:2:5 (port 2I:box 2:bay 5, SAS HDD, 300 GB, OK)
      physicaldrive 2I:2:6 (port 2I:box 2:bay 6, SAS HDD, 300 GB, OK)
      physicaldrive 2I:2:7 (port 2I:box 2:bay 7, SAS HDD, 1.2 TB, OK)
      physicaldrive 2I:2:8 (port 2I:box 2:bay 8, SAS HDD, 1.2 TB, OK)
   SEP (Vendor ID HPE, Model Smart Adapter) 379  (WWID: 51402EC013705E88, Port: Unknown)
$ sudo ssacli ctrl slot=3 pd 2I:2:7 show detail
HPE Smart Array P408i-p SR Gen10 in Slot 3
   Array A
      physicaldrive 2I:2:7
         Port: 2I
         Box: 2
         Bay: 7
         Status: OK
         Drive Type: Data Drive
         Interface Type: SAS
         Size: 1.2 TB
         Drive exposed to OS: False
         Logical/Physical Block Size: 512/512
         Rotational Speed: 10000
         Firmware Revision: U850
         Serial Number: KZGN1BDE
         WWID: 5000CCA01D247239
         Model: HGST    HUC101212CSS600
         Current Temperature (C): 46
         Maximum Temperature (C): 51
         PHY Count: 2
         PHY Transfer Rate: 6.0Gbps, Unknown
         PHY Physical Link Rate: 6.0Gbps, Unknown
         PHY Maximum Link Rate: 6.0Gbps, 6.0Gbps
         Drive Authentication Status: OK
         Carrier Application Version: 11
         Carrier Bootloader Version: 6
         Sanitize Erase Supported: False
         Shingled Magnetic Recording Support: None
         Drive Unique ID: 5000CCA01D247238
2024-12-09 update I was experiencing a disk failure or predictive failure when I walked into my office this afternoon. I checked this blog post and found the command I used to check the status of the sas array.
cjac@server0:~$ sudo ssacli ctrl all show config
HPE Smart Array P408i-p SR Gen10 in Slot 3  (sn: PFJHD0ARCCR1QM)
   Internal Drive Cage at Port 1I, Box 2, OK
   Internal Drive Cage at Port 2I, Box 2, OK
   Port Name: 1I (Mixed)
   Port Name: 2I (Mixed)
   Array A (SAS, Unused Space: 0  MB)
      logicaldrive 1 (1.64 TB, RAID 6, OK)
      physicaldrive 1I:2:1 (port 1I:box 2:bay 1, SAS HDD, 300 GB, OK)
      physicaldrive 1I:2:2 (port 1I:box 2:bay 2, SAS HDD, 1.2 TB, Predictive Failure)
      physicaldrive 1I:2:3 (port 1I:box 2:bay 3, SAS HDD, 300 GB, OK)
      physicaldrive 1I:2:4 (port 1I:box 2:bay 4, SAS HDD, 1.2 TB, OK)
      physicaldrive 2I:2:5 (port 2I:box 2:bay 5, SAS HDD, 300 GB, OK)
      physicaldrive 2I:2:6 (port 2I:box 2:bay 6, SAS HDD, 300 GB, OK)
      physicaldrive 2I:2:7 (port 2I:box 2:bay 7, SAS HDD, 1.2 TB, OK)
      physicaldrive 2I:2:8 (port 2I:box 2:bay 8, SAS HDD, 300 GB, OK)
   SEP (Vendor ID HPE, Model Smart Adapter) 379  (WWID: 51402EC013705E88, Port: Unknown)
At this point I engaged the under-study to have the flashing disk replaced
cjac@server0:~$ sudo ssacli ctrl all show config
[sudo] password for cjac: 
HPE Smart Array P408i-p SR Gen10 in Slot 3  (sn: PFJHD0ARCCR1QM)
   Internal Drive Cage at Port 1I, Box 2, OK
   Internal Drive Cage at Port 2I, Box 2, OK
   Port Name: 1I (Mixed)
   Port Name: 2I (Mixed)
   Array A (SAS, Unused Space: 0  MB)
      logicaldrive 1 (1.64 TB, RAID 6, Recovering, 56.43% complete)
      physicaldrive 1I:2:1 (port 1I:box 2:bay 1, SAS HDD, 300 GB, OK)
      physicaldrive 1I:2:2 (port 1I:box 2:bay 2, SAS HDD, 300 GB, Rebuilding)
      physicaldrive 1I:2:3 (port 1I:box 2:bay 3, SAS HDD, 300 GB, OK)
      physicaldrive 1I:2:4 (port 1I:box 2:bay 4, SAS HDD, 1.2 TB, OK)
      physicaldrive 2I:2:5 (port 2I:box 2:bay 5, SAS HDD, 300 GB, OK)
      physicaldrive 2I:2:6 (port 2I:box 2:bay 6, SAS HDD, 300 GB, OK)
      physicaldrive 2I:2:7 (port 2I:box 2:bay 7, SAS HDD, 1.2 TB, OK)
      physicaldrive 2I:2:8 (port 2I:box 2:bay 8, SAS HDD, 300 GB, OK)
   SEP (Vendor ID HPE, Model Smart Adapter) 379  (WWID: 51402EC013705E88, Port: Unknown)
In the next and future output, I will elide duplicate lines
cjac@server0:~$ date ; sudo ssacli ctrl all show config
Mon Dec  9 07:36:44 PM PST 2024 ... logicaldrive 1 (1.64 TB, RAID 6, Recovering, 66.85% complete)...
Mon Dec  9 07:39:25 PM PST 2024 ... logicaldrive 1 (1.64 TB, RAID 6, Recovering, 68.97% complete) ...
cjac@server0:~$ date ; sudo ssacli ctrl all show config   grep Recovering
Mon Dec  9 07:43:05 PM PST 2024 ... logicaldrive 1 (1.64 TB, RAID 6, Recovering, 71.85% complete)
Mon Dec  9 07:43:57 PM PST 2024 ... logicaldrive 1 (1.64 TB, RAID 6, Recovering, 72.55% complete)
cjac@server0:~$ sleep 5m ; date ; sudo ssacli ctrl all show config   grep Recovering
Mon Dec  9 07:49:43 PM PST 2024 ... logicaldrive 1 (1.64 TB, RAID 6, Recovering, 77.00% complete)
cjac@server0:~$ date ; sudo ssacli ctrl all show config   grep -e 1I:2:2 -e logicaldrive
Mon Dec  9 11:36:14 PM PST 2024 ... logicaldrive 1 (1.64 TB, RAID 6, OK)
physicaldrive 1I:2:2 (port 1I:box 2:bay 2, SAS HDD, 300 GB, OK)

Russ Allbery: Review: Delilah Green Doesn't Care

Review: Delilah Green Doesn't Care, by Ashley Herring Blake
Series: Bright Falls #1
Publisher: Jove
Copyright: February 2022
ISBN: 0-593-33641-0
Format: Kindle
Pages: 374
Delilah Green Doesn't Care is a sapphic romance novel. It's the first of a trilogy, although in the normal romance series fashion each book follows a different protagonist and has its own happy ending. It is apparently classified as romantic comedy, which did not occur to me while reading but which I suppose I can see in retrospect. Delilah Green got the hell out of Bright Falls as soon as she could and tried not to look back. After her father died, her step-mother lavished all of her perfectionist attention on her overachiever step-sister, leaving Delilah feeling like an unwanted ghost. She escaped to New York where there was space for a queer woman with an acerbic personality and a burgeoning career in photography. Her estranged step-sister's upcoming wedding was not a good enough reason to return to the stifling small town of her childhood. The pay for photographing the wedding was, since it amounted to three months of rent and trying to sell photographs in galleries was not exactly a steady living. So back to Bright Falls Delilah goes. Claire never left Bright Falls. She got pregnant young and ended up with a different life than she expected, although not a bad one. Now she's raising her daughter as a single mom, running the town bookstore, and dealing with her unreliable ex. She and Iris are Astrid Parker's best friends and have been since fifth grade, which means she wants to be happy for Astrid's upcoming wedding. There's only one problem: the groom. He's a controlling, boorish ass, but worse, Astrid seems to turn into a different person around him. Someone Claire doesn't like. Then, to make life even more complicated, Claire tries to pick up Astrid's estranged step-sister in Bright Falls's bar without recognizing her. I have a lot of things to say about this novel, but here's the core of my review: I started this book at 4pm on a Saturday because I hadn't read anything so far that day and wanted to at least start a book. I finished it at 11pm, having blown off everything else I had intended to do that evening, completely unable to put it down. It turns out there is a specific type of romance novel protagonist that I absolutely adore: the sarcastic, confident, no-bullshit character who is willing to pick the fights and say the things that the other overly polite and anxious characters aren't able to get out. Astrid does not react well to criticism, for reasons that are far more complicated than it may first appear, and Claire and Iris have been dancing around the obvious problems with her surprise engagement. As the title says, Delilah thinks she doesn't care: she's here to do a job and get out, and maybe she'll get to tweak her annoying step-sister a bit in the process. But that also means that she is unwilling to play along with Astrid's obsessively controlling mother or her obnoxious fiance, and thus, to the barely disguised glee of Claire and Iris, is a direct threat to the tidy life that Astrid's mother is trying to shoehorn her daughter into. This book is a great example of why I prefer sapphic romances: I think this character setup would not work, at least for me, in a heterosexual romance. Delilah's role only works if she's a woman; if a male character were the sarcastic conversational bulldozer, it would be almost impossible to avoid falling into the gender stereotype of a male rescuer. If this were a heterosexual romance trying to avoid that trap, the long-time friend who doesn't know how to directly confront Astrid would have to be the male protagonist. That could work, but it would be a tricky book to write without turning it into a story focused primarily on the subversion of gender roles. Making both protagonists women dodges the problem entirely and gives them so much narrative and conceptual space to simply be themselves, rather than characters obscured by the shadows of societal gender rules. This is also, at it's core, a book about friendship. Claire, Astrid, and Iris have the sort of close-knit friend group that looks exclusive and unapproachable from the outside. Delilah was the stereotypical outsider, mocked and excluded when they thought of her at all. This, at least, is how the dynamics look at the start of the book, but Blake did an impressive job of shifting my understanding of those relationships without changing their essential nature. She fleshes out all of the characters, not just the romantic leads, and adds complexity, nuance, and perspective. And, yes, past misunderstanding, but it's mostly not the cheap sort that sometimes drives romance plots. It's the misunderstanding rooted in remembered teenage social dynamics, the sort of misunderstanding that happens because communication is incredibly difficult, even more difficult when one has no practice or life experience, and requires knowing oneself well enough to even know what to communicate. The encounter between Delilah and Claire in the bar near the start of the book is cornerstone of the plot, but the moment that grabbed me and pulled me in was Delilah's first interaction with Claire's daughter Ruby. That was the point when I knew these were characters I could trust, and Blake never let me down. I love how Ruby is handled throughout this book, with all of the messy complexity of a kid of divorced parents with her own life and her own personality and complicated relationships with both parents that are independent of the relationship their parents have with each other. This is not a perfect book. There's one prank scene that I thought was excessively juvenile and should have been counter-productive, and there's one tricky question of (nonsexual) consent that the book raises and then later seems to ignore in a way that bugged me after I finished it. There is a third-act breakup, which is not my favorite plot structure, but I think Blake handles it reasonably well. I would probably find more niggles and nitpicks if I re-read it more slowly. But it was utterly engrossing reading that exactly matched my mood the day that I picked it up, and that was a fantastic reading experience. I'm not much of a romance reader and am not the traditional audience for sapphic romance, so I'm probably not the person you should be looking to for recommendations, but this is the sort of book that got me to immediately buy all of the sequels and start thinking about a re-read. It's also the sort of book that dragged me back in for several chapters when I was fact-checking bits of my review. Take that recommendation for whatever it's worth. Content note: Reviews of Delilah Green Doesn't Care tend to call it steamy or spicy. I have no calibration for this for romance novels. I did not find it very sex-focused (I have read genre fantasy novels with more sex), but there are several on-page sex scenes if that's something you care about one way or the other. Followed by Astrid Parker Doesn't Fail. Rating: 9 out of 10

17 November 2024

Russ Allbery: Review: Dark Deeds

Review: Dark Deeds, by Michelle Diener
Series: Class 5 #2
Publisher: Eclipse
Copyright: January 2016
ISBN: 0-6454658-4-4
Format: Kindle
Pages: 340
Dark Deeds is the second book of the self-published Class 5 science fiction romance series. It is a sequel to Dark Horse and will spoil the plot of that book, but it follows the romance series convention of switching to a new protagonist in the same universe and telling a loosely-connected story. Fiona, like Rose in the previous book, was kidnapped by the Tecran in one of their Class 5 ships, although that's not entirely obvious at the start of the story. The book opens with her working as a slave on a Garmman trading ship while its captain works up the nerve to have her killed. She's spared this fate when the ship is raided by Krik pirates. Some brave fast-talking, and a touch of honor among thieves, lets her survive the raid and be rescued by a pursuing Grih battleship, with a useful electronic gadget as a bonus. The author uses the nickname "Fee" for Fiona throughout this book and it was like nails on a chalkboard every time. I had to complain about that before getting into the review. If you've read Dark Horse, you know the formula: lone kidnapped human woman, major violations of the laws against mistreatment of sentient beings that have the Grih furious on her behalf, hunky Grih starship captain who looks like a space elf, all the Grih are fascinated by her musical voice, she makes friends with a secret AI... Diener found a formula that worked well enough that she tried it again, and it would not surprise me if the formula repeated through the series. You should not go into this book expecting to be surprised. That said, the formula did work the first time, and it largely does work again. I thoroughly enjoyed Dark Horse and wanted more, and this is more, delivered on cue. There are worse things, particularly if you're a Kindle Unlimited reader (I am not) and are therefore getting new installments for free. The Tecran fascination with kidnapping human women is explained sufficiently in Fiona's case, but I am mildly curious how Diener will keep justifying it through the rest of the series. (Maybe the formula will change, but I doubt it.) To give Diener credit, this is not a straight repeat of the first book. Fiona is similar to Rose but not identical; Rose had an unshakable ethical calm, and Fiona is more of a scrapper. The Grih are not stupid and, given the amount of chaos Rose unleashed in the previous book, treat the sudden appearance of another human woman with a great deal more caution and suspicion. Unfortunately, this also means far less of my favorite plot element of the first book: the Grih being constantly scandalized and furious at behavior the protagonist finds sadly unsurprising. Instead, this book has quite a bit more action. Dark Horse was mostly character interactions and tense negotiations, with most of the action saved for the end. Dark Deeds replaces a lot of the character work with political plots and infiltrating secret military bases and enemy ships. The AI (named Eazi this time) doesn't show up until well into the book and isn't as much of a presence as Sazo. Instead, there's a lot more of Fiona being drafted into other people's fights, which is entertaining enough while it's happening but which wasn't as delightful or memorable as Rose's story. The writing continues to be serviceable but not great. It's a bit cliched and a bit awkward. Also, Diener uses paragraph breaks for emphasis. It's hard to stop noticing it once you see it. Thankfully, once the story gets going and there's more dialogue, she tones that down, or perhaps I stopped noticing. It's that kind of book (and that kind of series): it's a bit rough to get started, but then there's always something happening, the characters involve a whole lot of wish-fulfillment but are still people I like reading about, and it's the sort of unapologetic "good guys win" type of light science fiction that is just the thing when one simply wants to be entertained. Once I get into the book, it's easy to overlook its shortcomings. I spent Dark Horse knowing roughly what would happen but wondering about the details. I spent Dark Deeds fairly sure of the details and wondering when they would happen. This wasn't as fun of an experience, but the details were still enjoyable and I don't regret reading it. I am hoping that the next book will be more of a twist, or will have a character more like Rose (or at least a character with a better nickname). Sort of recommended if you liked Dark Horse and really want more of the same. Followed by Dark Minds, which I have already purchased. Rating: 6 out of 10

13 November 2024

Russell Coker: Modern Sleep

Julius wrote an insightful blog post about the modern sleep issue with Windows [1]. Basically Microsoft decided that the right way to run laptops is to never entirely sleep, which uses more battery but gives better options for waking up and doing things. I agree with Microsoft in concept and this is something that is a problem that can be solved. A phone can run for 24+ hours without ever fully sleeping, a laptop has a more power hungry CPU and peripherals but also has a much larger battery so it should be able to do the same. Some of the reviews for Snapdragon Windows laptops claim up to 22 hours of actual work without charging! So having suspend not really stop the system should be fine. The ability of a phone to never fully sleep is a change in quality of the usage experience, it means that you can access it and immediately have it respond and it means that all manner of services can be checked for new updates which may require a notification to the user. The XMPP protocol (AKA Jabber) was invented in 1999 which was before laptops were common and Instant Message systems were common long before then. But using Jabber or another IM system on a desktop was a very different experience to using it on a laptop and using it on a phone is different again. The modern sleep allows laptops to act like phones in regard to such messaging services. Currently I have Matrix IM clients running on my Android phone and Linux laptop, if I get a notification that takes much typing for a response then I get out my laptop to respond. If I had an ARM based laptop that never fully shut down I would have much less need for Matrix on a phone. Making modern sleep popular will lead to more development of OS software to work with it. For Linux this will hopefully mean that regular Linux distributions (as opposed to Android which while running a Linux kernel is very different to Debian etc) get better support for such things and therefore become more usable on phones. Debian on a Librem 5 or PinePhonePro isn t very usable due to battery life issues. A laptop with an LTE card can be used for full mobile phone functionality. With modern sleep this is a viable option. I am tempted to make a laptop with LTE card and bluetooth headset a replacement for my phone. Some people will say what if someone tries to call you when it s not convenient to have your laptop with you , my response is what if people learn to not expect me to answer the phone at any time as they managed that in the 90s . Seriously SMS or Matrix me if you want an instant response and if you want a long chat schedule it via SMS or Matrix. Dell has some useful advice about how to use their laptops (and probably most laptops from recent times) in this regard [2]. You can t close the lid before unplugging the power cable you have to unplug first and then close. You shouldn t put a laptop in a sealed bag for travel either. This is a terrible situation, you can put a tablet in a bag and don t need to take any special precautions when unplugging and laptops should work the same. The end result of what Microsoft, Dell, Intel, and others are doing will be good but they are making some silly design choices along the way! I blame Intel mostly for selling laptop CPUs with TDPs >40W! For an amusing take on this Linus Tech Tips has a video about being forced to use MacBooks by Microsoft s implementation of Modern Sleep [3]. I ll try out some ARM laptops in the near future and blog about how well they work on Debian.

Louis-Philippe V ronneau: Montreal's Debian & Stuff - November 2024

Our Debian User Group met on November 2nd after a somewhat longer summer hiatus than normal. It was lovely to see a bunch of people again and to be able to dedicate a whole day to hacking :) Here is what we did: lavamind: pollo: anarcat: LeLutin: tvaz: tassia: Pictures This time around, we went back to Foulab. Thanks for hosting us! As always, the hacklab was full of interesting stuff and I took a few (bad) pictures for this blog post: Two old video cameras and a 'My First Sony' tape recorder An ALP HT-286 machine with a very large 'turbo' button A New Hampshire 'IPROUTE' vanity license plate

12 November 2024

Paul Tagliamonte: Complex for Whom?

In basically every engineering organization I ve ever regarded as particularly high functioning, I ve sat through one specific recurring conversation which is not a conversation about complexity . Things are good or bad because they are or aren t complex, architectures needs to be redone because it s too complex some refactor of whatever it is won t work because it s too complex. You may have even been a part of some of these conversations or even been the one advocating for simple light-weight solutions. I ve done it. Many times. Rarely, if ever, do we talk about complexity within its rightful context complexity for whom. Is a solution complex because it s complex for the end user? Is it complex if it s complex for an API consumer? Is it complex if it s complex for the person maintaining the API service? Is it complex if it s complex for someone outside the team maintaining it to understand? Complexity within a problem domain I ve come to believe, is fairly zero-sum there s a fixed amount of complexity in the problem to be solved, and you can choose to either solve it, or leave it for those downstream of you to solve that problem on their own. That being said, while I believe there is a lower bound in complexity to contend with for a problem, I do not believe there is an upper bound to the complexity of solutions possible. It is always possible, and in fact, very likely that teams create problems for themselves while trying to solve a problem. The rest of this post is talking to the lower bound. When getting feedback on an early draft of this blog post, I ve been informed that Fred Brooks coined a term for what I call lower bound complexity Essential Complexity , in the paper No Silver Bullet Essence and Accident in Software Engineering , which is a better term and can be used interchangeably.

Complexity Culture In a large enough organization, where the team is high functioning enough to have and maintain trust amongst peers, members of the team will specialize. People will begin to engage with subsets of the work to be done, and begin to have their efficacy measured against that part of the organization s problems. Incentives shift, and over time it becomes increasingly likely that two engineers may have two very different priorities when working on the same system together. Someone accountable for uptime and tasked with responding to outages will begin to resist changes. Someone accountable for rapidly delivering features will resist gates between them and their users. Companies (either wittingly or unwittingly) will deal with this by tasking engineers with both production (feature development) and operational tasks (maintenance), so the difference in incentives isn t usually as bad as it could be. When we get a bunch of folks from far-flung corners of an organization in a room, fire up a slide deck and throw up some aspirational to-be architecture diagram in order to get a sign-off to solve some problem (be it someone needs a credible promotion packet, new feature needs to get delivered, or the system has begun to fail and needs fixing), the initial reaction will, more often than I d like, start to devolve into a discussion of how this is going to introduce a bunch of complexity, going to be hard to maintain, why can t you make it less complex? Right around here is when I start to try and contextualize the conversation happening around me understand what complexity is that being discussed, and understand who is taking on that burden. Think about who should be owning that problem, and work through the tradeoffs involved. Is it best solved here, or left to consumers (be them other systems, developers, or users). Should something become an API call s optional param, taking on all the edge-cases and on, or should users have to implement the logic using the data you return (leaving everyone else to take on all the edge-cases and maintenance)? Should you process the data, or require the user to preprocess it for you? Frequently it s right to make an active and explicit decision to simplify and leave problems to be solved downstream, since they may not actually need to be solved or perhaps you expect consumers will want to own the specifics of how the problem is solved, in which case you leave lots of documentation and examples. Many other times, especially when it s something downstream consumers are likely to hit, it s best solved internal to the system, since the only thing that can come of leaving it unsolved are bugs, frustration and half-correct solutions. This is a grey-space of tradeoffs, not a clear decision tree. No one wants the software manifestation of a katamari ball or a junk drawer, nor does anyone want a half-baked service unable to handle the simplest use-case.

Head-in-sand as a Service Popoffs about how complex something is, are, to a first approximation, best understood as meaning complicated for the person making comments . A lot of the #thoughtleadership believe that an AWS hosted EKS k8s cluster running images built by CI talking to an AWS hosted PostgreSQL RDS is not complex. They re right. Mostly right. This is less complex less complex for them. It s not, however, without complexity and its own tradeoffs it s just complexity that they do not have to deal with. Now they don t have to maintain machines that have pesky operating systems or hard drive failures. They don t have to deal with updating the version of k8s, nor ensuring the backups work. No one has to push some artifact to prod manually. Deployments happen unattended. You click a button and get a cluster. On the other hand, developers outside the ops function need to deal with troubleshooting CI, debugging access control rules encoded in turing complete YAML, permissions issues inside the cluster due to whatever the fuck a service mesh is, everyone needs to learn how to use some k8s tools they only actually use during a bad day, likely while doing some x.509 troubleshooting to connect to the cluster (an internal only endpoint; just port forward it) not to mention all sorts of rules to route packets to their project (a single repo s binary being run in 3 containers on a single vm host). Beyond that, there s the invisible complexity complexity on the interior of a service you depend on. I think about the dozens of teams maintaining the EKS service (which is either run on EC2 instances, or alternately, EC2 instances in a trench coat, moustache and even more shell scripts), the RDS service (also EC2 and shell scripts, but this time accounting for redundancy, backups, availability zones), scores of hypervisors pulled off the shelf (xen, kvm) smashed together with the ones built in-house (firecracker, nitro, etc) running on hardware that has to be refreshed and maintained continuously. Every request processed by network ACL rules, AWS IAM rules, security group rules, using IP space announced to the internet wired through IXPs directly into ISPs. I don t even want to begin to think about the complexity inherent in how those switches are designed. Shitloads of complexity to solve problems you may or may not have, or even know you had. What s more complex? An app running in an in-house 4u server racked in the office s telco closet in the back running off the office Verizon line, or an app running four hypervisors deep in an AWS datacenter? Which is more complex to you? What about to your organization? In total? Which is more prone to failure? Which is more secure? Is the complexity good or bad? What type of Complexity can you manage effectively? Which threaten the system? Which threaten your users?

COMPLEXIVIBES This extends beyond Engineering. Decisions regarding what tools are we able to use be them existing contracts with cloud providers, CIO mandated SaaS products, a list of the only permissible open source projects will incur costs in terms of expressed complexity . Pinning open source projects to a fixed set makes SBOM production less complex . Using only one SaaS provider s product suite (even if its terrible, because it has all the types of tools you need) makes accreditation less complex . If all you have is a contract with Pauly T s lowest price technically acceptable artisinal cloudary and haberdashery, the way you pay for your compute is less complex for the CIO shop, though you will find yourself building your own hosted database template, mechanism to spin up a k8s cluster, and all the operational and technical burden that comes with it. Or you won t and make it everyone else s problem in the organization. Nothing you can do will solve for the fact that you must now deal with this problem somewhere because it was less complicated for the business to put the workloads on the existing contract with a cut-rate vendor. Suddenly, the decision to reduce complexity because of an existing contract vehicle has resulted in a huge amount of technical risk and maintenance burden being onboarded. Complexity you would otherwise externalize has now been taken on internally. With a large enough organizations (specifically, in this case, i m talking about you, bureaucracies), this is largely ignored or accepted as normal since the personnel cost is understood to be free to everyone involved. Doing it this way is more expensive, more work, less reliable and less maintainable, and yet, somehow, is, in a lot of ways, less complex to the organization. It s particularly bad with bureaucracies, since screwing up a contract will get you into much more trouble than delivering a broken product, leaving basically no reason for anyone to care to fix this. I can t shake the feeling that for every story of technical mandates gone awry, somewhere just out of sight there s a decisionmaker optimizing for what they believe to be the least amount of complexity least hassle, fewest unique cases, most consistency as they can. They freely offload complexity from their accreditation and risk acceptance functions through mandates. They will never have to deal with it. That does not change the fact that someone does.

TC;DR (TOO COMPLEX; DIDN T REVIEW) We wish to rid ourselves of systemic Complexity after all, complexity is bad, simplicity is good. Removing upper-bound own-goal complexity ( accidental complexity in Brooks s terms) is important, but once you hit the lower bound complexity, the tradeoffs become zero-sum. Removing complexity from one part of the system means that somewhere else maybe outside your organization or in a non-engineering function must grow it back. Sometimes, the opposite is the case, such as when a previously manual business processes is automated. Maybe that s a good idea. Maybe it s not. All I know is that what doesn t help the situation is conflating complexity with everything we don t like legacy code, maintenance burden or toil, cost, delivery velocity.
  • Complexity is not the same as proclivity to failure. The most reliable systems I ve interacted with are unimaginably complex, with layers of internal protection to prevent complete failure. This has its own set of costs which other people have written about extensively.
  • Complexity is not cost. Sometimes the cost of taking all the complexity in-house is less, for whatever value of cost you choose to use.
  • Complexity is not absolute. Something simple from one perspective may be wildly complex from another. The impulse to burn down complex sections of code is helpful to have generally, but sometimes things are complicated for a reason, even if that reason exists outside your codebase or organization.
  • Complexity is not something you can remove without introducing complexity elsewhere. Just as not making a decision is a decision itself; choosing to require someone else to deal with a problem rather than dealing with it internally is a choice that needs to be considered in its full context.
Next time you re sitting through a discussion and someone starts to talk about all the complexity about to be introduced, I want to pop up in the back of your head, politely asking what does complex mean in this context? Is it lower bound complexity? Is this complexity desirable? Is what they re saying mean something along the lines of I don t understand the problems being solved, or does it mean something along the lines of this problem should be solved elsewhere? Do they believe this will result in more work for them in a way that you don t see? Should this not solved at all by changing the bounds of what we should accept or redefine the understood limits of this system? Is the perceived complexity a result of a decision elsewhere? Who s taking this complexity on, or more to the point, is failing to address complexity required by the problem leaving it to others? Does it impact others? How specifically? What are you not seeing? What can change? What should change?

Freexian Collaborators: Monthly report about Debian Long Term Support, October 2024 (by Roberto C. S nchez)

Like each month, have a look at the work funded by Freexian s Debian LTS offering.
Debian LTS contributors In October, 20 contributors have been paid to work on Debian LTS, their reports are available:
  • Abhijith PA did 6.0h (out of 7.0h assigned and 7.0h from previous period), thus carrying over 8.0h to the next month.
  • Adrian Bunk did 15.0h (out of 87.0h assigned and 13.0h from previous period), thus carrying over 85.0h to the next month.
  • Arturo Borrero Gonzalez did 10.0h (out of 10.0h assigned).
  • Bastien Roucari s did 20.0h (out of 20.0h assigned).
  • Ben Hutchings did 4.0h (out of 0.0h assigned and 4.0h from previous period).
  • Chris Lamb did 18.0h (out of 18.0h assigned).
  • Daniel Leidert did 29.0h (out of 26.0h assigned and 3.0h from previous period).
  • Emilio Pozuelo Monfort did 60.0h (out of 23.5h assigned and 36.5h from previous period).
  • Guilhem Moulin did 7.5h (out of 19.75h assigned and 0.25h from previous period), thus carrying over 12.5h to the next month.
  • Lee Garrett did 15.25h (out of 0.0h assigned and 60.0h from previous period), thus carrying over 44.75h to the next month.
  • Lucas Kanashiro did 10.0h (out of 10.0h assigned and 10.0h from previous period), thus carrying over 10.0h to the next month.
  • Markus Koschany did 40.0h (out of 40.0h assigned).
  • Ola Lundqvist did 14.5h (out of 6.5h assigned and 17.5h from previous period), thus carrying over 9.5h to the next month.
  • Roberto C. S nchez did 9.75h (out of 24.0h assigned), thus carrying over 14.25h to the next month.
  • Santiago Ruano Rinc n did 23.5h (out of 25.0h assigned), thus carrying over 1.5h to the next month.
  • Sean Whitton did 6.25h (out of 1.0h assigned and 5.25h from previous period).
  • Stefano Rivera did 1.0h (out of 0.0h assigned and 10.0h from previous period), thus carrying over 9.0h to the next month.
  • Sylvain Beucler did 9.5h (out of 16.0h assigned and 44.0h from previous period), thus carrying over 50.5h to the next month.
  • Thorsten Alteholz did 11.0h (out of 11.0h assigned).
  • Tobias Frost did 10.5h (out of 12.0h assigned), thus carrying over 1.5h to the next month.

Evolution of the situation In October, we have released 35 DLAs. Some notable updates prepared in October include denial of service vulnerability fixes in nss, regression fixes in apache2, multiple fixes in php7.4, and new upstream releases of firefox-esr, openjdk-17, and opendk-11. Additional contributions were made for the stable Debian 12 bookworm release by several LTS contributors. Arturo Borrero Gonzalez prepared a parallel update of nss, Bastien Roucari s prepared a parallel update of apache2, and Santiago Ruano Rinc n prepared updates of activemq for both LTS and Debian stable. LTS contributor Bastien Roucari s undertook a code audit of the cacti package and in the process discovered three new issues in node-dompurity, which were reported upstream and resulted in the assignment of three new CVEs. As always, the LTS team continues to work towards improving the overall sustainability of the free software base upon which Debian LTS is built. We thank our many committed sponsors for their ongoing support.

Thanks to our sponsors Sponsors that joined recently are in bold.

11 November 2024

Dirk Eddelbuettel: RcppSpdlog 0.0.19 on CRAN: New Upstream, New Features

Version 0.0.19 of RcppSpdlog arrived on CRAN early this morning and has been uploaded to Debian. RcppSpdlog bundles spdlog, a wonderful header-only C++ logging library with all the bells and whistles you would want that was written by Gabi Melman, and also includes fmt by Victor Zverovich. You can learn more at the nice package documention site. This releases updates the code to the version 1.15.0 of spdlog which was released on Saturday, and contains fmt 11.0.2. It also contains a contributed PR which allows use std::format under C++20, bypassing fmt (with some post-merge polish too), and another PR correcting a documentation double-entry. The NEWS entry for this release follows.

Changes in RcppSpdlog version 0.0.19 (2024-11-10)
  • Support use of std::format under C++20 via opt-in define instead of fmt (Xanthos Xanthopoulos in #19)
  • An erroneous duplicate log=level documentation level was removed (Contantinos Giachalis in #20)
  • Upgraded to upstream release spdlog 1.15.0 (Dirk in #21)
  • Partially revert / simplify src/formatter.cpp accomodating both #19 and previous state (Dirk in #21)

Courtesy of my CRANberries, there is also a diffstat report. More detailed information is on the RcppSpdlog page, or the package documention site. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

10 November 2024

Reproducible Builds: Reproducible Builds in October 2024

Welcome to the October 2024 report from the Reproducible Builds project. Our reports attempt to outline what we ve been up to over the past month, highlighting news items from elsewhere in tech where they are related. As ever, if you are interested in contributing to the project, please visit our Contribute page on our website. Table of contents:
  1. Beyond bitwise equality for Reproducible Builds?
  2. Two Ways to Trustworthy at SeaGL 2024
  3. Number of cores affected Android compiler output
  4. On our mailing list
  5. diffoscope
  6. IzzyOnDroid passed 25% reproducible apps
  7. Distribution work
  8. Website updates
  9. Reproducibility testing framework
  10. Supply-chain security at Open Source Summit EU
  11. Upstream patches

Beyond bitwise equality for Reproducible Builds? Jens Dietrich, Tim White, of Victoria University of Wellington, New Zealand along with Behnaz Hassanshahi and Paddy Krishnan of Oracle Labs Australia published a paper entitled Levels of Binary Equivalence for the Comparison of Binaries from Alternative Builds :
The availability of multiple binaries built from the same sources creates new challenges and opportunities, and raises questions such as: Does build A confirm the integrity of build B? or Can build A reveal a compromised build B? . To answer such questions requires a notion of equivalence between binaries. We demonstrate that the obvious approach based on bitwise equality has significant shortcomings in practice, and that there is value in opting for alternative notions. We conceptualise this by introducing levels of equivalence, inspired by clone detection types.
A PDF of the paper is freely available.

Two Ways to Trustworthy at SeaGL 2024 On Friday 8th November, Vagrant Cascadian will present a talk entitled Two Ways to Trustworthy at SeaGL in Seattle, WA. Founded in 2013, SeaGL is a free, grassroots technical summit dedicated to spreading awareness and knowledge about free source software, hardware and culture. Vagrant s talk:
[ ] delves into how two project[s] approaches fundamental security features through Reproducible Builds, Bootstrappable Builds, code auditability, etc. to improve trustworthiness, allowing independent verification; trustworthy projects require little to no trust. Exploring the challenges that each project faces due to very different technical architectures, but also contextually relevant social structure, adoption patterns, and organizational history should provide a good backdrop to understand how different approaches to security might evolve, with real-world merits and downsides.

Number of cores affected Android compiler output Fay Stegerman wrote that the cause of the Android toolchain bug from September s report that she reported to the Android issue tracker has been found and the bug has been fixed.
the D8 Java to DEX compiler (part of the Android toolchain) eliminated a redundant field load if running the class s static initialiser was known to be free of side effects, which ended up accidentally depending on the sharding of the input, which is dependent on the number of CPU cores used during the build.
To make it easier to understand the bug and the patch, Fay also made a small example to illustrate when and why the optimisation involved is valid.

On our mailing list On our mailing list this month:

diffoscope diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading versions 279, 280, 281 and 282 to Debian:
  • Ignore errors when listing .ar archives (#1085257). [ ]
  • Don t try and test with systemd-ukify in the Debian stable distribution. [ ]
  • Drop Depends on the deprecated python3-pkg-resources (#1083362). [ ]
In addition, Jelle van der Waa added support for Unified Kernel Image (UKI) files. [ ][ ][ ] Furthermore, Vagrant Cascadian updated diffoscope in GNU Guix to version 282. [ ][ ]

IzzyOnDroid passed 25% reproducible apps The IzzyOnDroid project has reached a good milestone by reaching over 25% of the ~1,200 Android apps provided by their repository (of official APKs built by the original application developers) having been confirmed to be reproducible by a rebuilder.

Distribution work In Debian this month:
  • Holger Levsen uploaded devscripts version 2.24.2, including many changes to the debootsnap, debrebuild and reproducible-check scripts. This is the first time that debrebuild actually works (using sbuild s unshare backend). As part of this, Holger also fixed an issue in the reproducible-check script where a typo in the code led to incorrect results [ ]
  • Recently, a news entry was added to snapshot.debian.org s homepage, describing the recent changes that made the system stable again:
    The new server has no problems keeping up with importing the full archives on every update, as each run finishes comfortably in time before it s time to run again. [While] the new server is the one doing all the importing of updated archives, the HTTP interface is being served by both the new server and one of the VM s at LeaseWeb.
    The entry list a number of specific updates surrounding the API endpoints and rate limiting.
  • Lastly, 12 reviews of Debian packages were added, 3 were updated and 18 were removed this month adding to our knowledge about identified issues.
Elsewhere in distribution news, Zbigniew J drzejewski-Szmek performed another rebuild of Fedora 42 packages, with the headline result being that 91% of the packages are reproducible. Zbigniew also reported a reproducibility problem with QImage. Finally, in openSUSE, Bernhard M. Wiedemann published another report for that distribution.

Website updates There were an enormous number of improvements made to our website this month, including:
  • Alba Herrerias:
    • Improve consistency across distribution-specific guides. [ ]
    • Fix a number of links on the Contribute page. [ ]
  • Chris Lamb:
  • hulkoba
  • James Addison:
    • Huge and significant work on a (as-yet-merged) quickstart guide to be linked from the homepage [ ][ ][ ][ ][ ]
    • On the homepage, link directly to the Projects subpage. [ ]
    • Relocate dependency-drift notes to the Volatile inputs page. [ ]
  • Ninette Adhikari:
    • Add a brand new Success stories page that highlights the success stories of Reproducible Builds, showcasing real-world examples of projects shipping with verifiable, reproducible builds . [ ][ ][ ][ ][ ][ ]
  • Pol Dellaiera:
    • Update the website s README page for building the website under NixOS. [ ][ ][ ][ ][ ]
    • Add a new academic paper citation. [ ]
Lastly, Holger Levsen filed an extensive issue detailing a request to create an overview of recommendations and standards in relation to reproducible builds.

Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In October, a number of changes were made by Holger Levsen, including:
  • Add a basic index.html for rebuilderd. [ ]
  • Update the nginx.conf configuration file for rebuilderd. [ ]
  • Document how to use a rescue system for Infomaniak s OpenStack cloud. [ ]
  • Update usage info for two particular nodes. [ ]
  • Fix up a version skew check to fix the name of the riscv64 architecture. [ ]
  • Update the rebuilderd-related TODO. [ ]
In addition, Mattia Rizzolo added a new IP address for the inos5 node [ ] and Vagrant Cascadian brought 4 virt nodes back online [ ].

Supply-chain security at Open Source Summit EU The Open Source Summit EU took place recently, and covered plenty of topics related to supply-chain security, including:

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Finally, If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Thorsten Alteholz: My Debian Activities in October 2024

FTP master This month I accepted 398 and rejected 22 packages. The overall number of packages that got accepted was 441. In case your RM bug is not closed within a month, you can assume that either the conversion of the subject of the bug email to the corresponding dak command did not work or you still need to take care of reverse dependencies. The dak command related to your removal bug can be found here. Unfortunately the bahavior of some project members caused a decline of motivation of team members to work on these bugs. When I look at these bugs, I just copy and paste the above mentioned dak commands. If they don t work, I don t have the time to debug what is going wrong. So please read the docs and take care of it yourself. Please also keep in mind that you need to close the bug or set a moreinfo tag if you don t want anybody to act on your removal bug. Debian LTS This was my hundred-twenty-fourth month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian. During my allocated time I uploaded or worked on: Last but not least I did a week of FD this month and attended the monthly LTS/ELTS meeting. Debian ELTS This month was the seventy-fifth ELTS month. During my allocated time I uploaded or worked on: I also did a week of FD and attended the monthly LTS/ELTS meeting. Debian Printing Unfortunately I didn t found any time to work on this topic. Debian Matomo Unfortunately I didn t found any time to work on this topic. Debian Astro Unfortunately I didn t found any time to work on this topic. Debian IoT This month I uploaded new upstream or bugfix versions of: Debian Mobcom This month I uploaded new packages or new upstream or bugfix versions of: misc This month I uploaded new upstream or bugfix versions of:

9 November 2024

Jonathan Dowland: Progressively enhancing CGI apps with htmx

I was interested in learning about htmx, so I used it to improve the experience of posting comments on my blog. It seems much of modern web development is structured around having a JavaScript program on the front-end (browser) which exchanges data encoded in JSON asynchronously with the back-end servers. htmx uses a novel (or throwback) approach: it asynchronously fetches snippets of HTML from the back-end, and splices the results into the live page. For example, a htmx-powered button may request a URI on the server, receive HTML in response, and then the button itself would be replaced by the resulting HTML, within the page. I experimented with incorporating it into an existing, old-school CGI web app: IkiWiki, which I became a co-maintainer of this year, and powers my blog. Throughout this project I referred to the excellent book Server-Driven Web Apps with htmx. Comment posting workflow I really value blog comments, but the UX for posting them on my blog was a bit clunky. It went like this:
  1. you load a given page (such as this blog post), which is a static HTML document. There's a link to add a comment to the page.
  2. The link loads a new page which is generated dynamically and served back to you via CGI. This contains a HTML form for you to write your comment.
  3. The form submits to the server via HTTP POST. IkiWiki validates the form content. Various static pages (in particular the one you started on, in Step 1) are regenerated.
  4. the server response to the request in (3) is a HTTP 302 redirect, instructing the browser to go back to the page in Step 1.
First step: fetching a comment form First, I wanted the "add a comment" link to present the edit box in the current page. This step was easiest: add four attributes to the "comment on this page" anchor tag:
hx-get="<CGI ENDPOINT GOES HERE>"
suppresses the normal behaviour of the tag, so clicking on it doesn't load a new page.
issues an asynchronous HTTP GET to the CGI end-point, which returns the full HTML document for the comment edit form
hx-select=".editcomment form"
extract the edit-comment form from within that document
hx-swap=beforeend and hx-target=".addcomment"
append (courtesy of beforeend) the form into the source page after the "add comment" anchor tag (.addcomment)
Now, clicking "comment on this page" loads in the edit-comment box below it without moving you away from the source page. All that without writing any new code! Second step: handling previews
The old Preview Comment page The old Preview Comment page
In the traditional workflow, clicking on "Preview" loaded a new page containing the edit form (but not the original page or any existing comments) with a rendering of the comment-in-progress below it. I wasn't originally interested in supporting the "Preview" feature, but I needed to for reasons I'll explain later. Rather than load new pages, I wanted "Preview" to insert a rendering of the comment-in-progress being inserted into the current page's list of comments, marked up to indicate that it's a preview. IkiWiki provides some templates which you can override to customise your site. I've long overridden page.tmpl, the template used for all pages. I needed to add a new empty div tag in order to have a "hook" to target with the previewed comment. The rest of this was achieved with htmx attributes on the "Preview" button, similar to in the last step: hx-post to define a target URI when you click the button (and specify HTTP POST); hx-select to filter the resulting HTML and extract the comment; hx-target to specify where to insert it. Now, clicking "Preview" does not leave the current page, but fetches a rendering of your comment-in-progress, and splices it into the comment list, appropriately marked up to be clear it's a preview. Third step: handling submitted comments IkiWiki is highly configurable, and many different things could happen once you post a comment. On my personal blog, all comments are held for moderation before they are published. The page you were served after submitting a comment was rather bare-bones, a status message "Your comment will be posted after moderator review", without the original page content or comments. I wanted your comment to appear in the page immediately, albeit marked up to indicate it was awaiting review. Since the traditional workflow didn't render or present your comment to you, I had to cheat. handling moderated comments
Moderation message upon submitting a comment Moderation message upon submitting a comment
One of my goals with this project was not to modify IkiWiki itself. I had to break this rule for moderated comments. When returning the "comment is moderated" page, IkiWiki uses HTTP status code 200, the same as for other scenarios. I wrote a tiny patch to return HTTP 202 (Accepted, but not processed) instead. I now have to write some actual JavaScript. htmx emits the htmx:beforeSwap event after an AJAX call returns, but before the corresponding swap is performed. I wrote a function that is triggered on this event, filters for HTTP 202 responses, triggers the "Preview" button, and then alters the result to indicate a moderated, rather than previewed, comment. (That's why I bothered to implement previews). You can read the full function here: jon.js. Summary I've done barely any front-end web development for years and I found working with htmx to be an enjoyable experience. You can leave a comment on this very blog post if you want to see it in action. I couldn't resist adding an easter egg: Brownie points if you can figure out what it is. Adding htmx to an existing CGI-based website let me improve one of the workflows in a gracefully-degrading way (without JavaScript, the old method will continue to work fine) without modifying the existing application itself (well, almost) and without having to write very much code of my own at all: nearly all of the configuration was declarative.

8 November 2024

Thomas Lange: Using NIS (Network Information Service) in 2024

The topic of this posting already tells you that an old Unix guy tells stories about old techniques. I'm a happy NIS (formerly YP) user since 30+ years. I started using it with SunOS 4.0, later using it with Solaris and with Linux since 1999. In the past, a colleague wasn't happyly using NIS+ when he couldn't log in as root after a short time because of some well known bugs and wrong configs. NIS+ was also much slower than my NIS setup. I know organisations using NIS for more than 80.000 user accounts in 2024. I know the security implications of NIS but I can live with them, because I manage all computers in the network that have access to the NIS maps. And NIS on Linux offers to use shadow maps, which are only accessible to the root account. My users are forced to use very long passwords. Unfortunately NIS support for the PAM modules was removed in Debian in pam 1.4.0-13, which means Debian 12 (bookworm) is lacking NIS support in PAM, but otherwise it is still supported. This only affects changing the NIS password via passwd. You can still authenticate users and use other NIS maps. But yppasswd is deprecated and you should not use it! If you use yppasswd it may generate a new password hash by using the old DES crypt algorithm, which is very weak and only uses the first 8 chars in your password. Do not use yppasswd any more! yppasswd only detects DES, MD5, SHA256 and SHA512 hashes, but for me and some colleagues it only creates weak DES hashes after a password change. yescrypt hashes which are the default in Debian 12 are not supported at all. The solution is to use the plain passwd program. On the NIS master, you should setup your NIS configuration to use /etc/shadow and /etc/passwd even if your other NIS maps are in /var/yp/src or similar. Make sure to have these lines in your /var/yp/Makefile:
PASSWD      = /etc/passwd
SHADOW      = /etc/shadow
Call make once, and it will generate the shadow and passwd map. You may want to set the variable MINUID which defines which entries are not put into the NIS maps. On all NIS clients you still need the entries (for passwd, shadow, group,...) that point to the nis service. E.g.:
passwd:         files nis systemd
group:          files nis systemd
shadow:         files nis
You can remove all occurences of "nis" in your /etc/pam.d/common-password file. Then you can use the plain passwd program to change your password on the NIS master. But this does not call make in /var/yp for updating the NIS shadow map. Let's use inotify(7) for that. First, create a small shell script /usr/local/sbin/shadow-change:
#! /bin/sh
PATH=/usr/sbin:/usr/bin
# only watch the /etc/shadow file
if [ "$2" != "shadow" ]; then
  exit 0
fi
cd /var/yp   exit 3
sleep 2
make
Then install the package incron.
# apt install incron
# echo root >> /etc/incron.allow
# incrontab -e
Add this line:
/etc    IN_MOVED_TO     /usr/local/sbin/shadow-change $@ $# $%
It's not possible to use IN_MODIFY or watch other events on /etc/shadow directly, because the passwd command creates a /etc/nshadow file, deletes /etc/shadow and then moves nshadow to shadow. inotify on a file does not work after the file was removed. You can see the logs from incrond by using:
# journalctl _COMM=incrond
e.g.
Oct 01 12:21:56 kueppers incrond[6588]: starting service (version 0.5.12, built on Jan 27 2023 23:08:49)
Oct 01 13:43:55 kueppers incrond[6589]: table for user root created, loading
Oct 01 13:45:42 kueppers incrond[6589]: PATH (/etc) FILE (shadow) EVENT (IN_MOVED_TO)
Oct 01 13:45:42 kueppers incrond[6589]: (root) CMD ( /usr/local/sbin/shadow-change /etc shadow IN_MOVED_TO)
I've disabled the execution of yppasswd using dpkg-divert
# dpkg-divert --local --rename --divert /usr/bin/yppasswd-disable /usr/bin/yppasswd
chmod a-rwx /usr/bin/yppasswd-disable
Do not forget to limit the access to the shadow.byname map in ypserv.conf and general access to NIS in ypserv.securenets. I've also discovered the package pamtester, which is a nice package for testing your pam configs.

6 November 2024

Bits from Debian: Bits from the DPL

Dear Debian community, this is Bits from DPL for October. In addition to a summary of my recent activities, I aim to include newsworthy developments within Debian that might be of interest to the broader community. I believe this provides valuable insights and foster a sense of connection across our diverse projects. Also, I welcome your feedback on the format and focus of these Bits, as community input helps shape their value. Ada Lovelace Day 2024 As outlined in my platform, I'm committed to increasing the diversity of Debian developers. I hope the recent article celebrating Ada Lovelace Day 2024 featuring interviews with women in Debian will serve as an inspiring motivation for more women to join our community. MiniDebConf Cambridge This was my first time attending the MiniDebConf in Cambridge, hosted at the ARM building. I thoroughly enjoyed the welcoming atmosphere of both MiniDebCamp and MiniDebConf. It was wonderful to reconnect with people who hadn't made it to the last two DebConfs, and, as always, there was plenty of hacking, insightful discussions, and valuable learning. If you missed the recent MiniDebConf, there's a great opportunity to attend the next one in Toulouse. It was recently decided to include a MiniDebCamp beforehand as well. FTPmaster accepts MRs for DAK At the recent MiniDebConf in Cambridge, I discussed potential enhancements for DAK to make life easier for both FTP Team members and developers. For those interested, the document "Hacking on DAK" provides guidance on setting up a local DAK instance and developing patches, which can be submitted as MRs. As a perfectly random example of such improvements some older MR, "Add commands to accept/reject updates from a policy queue" might give you some inspiration. At MiniDebConf, we compiled an initial list of features that could benefit both the FTP Team and the developer community. While I had preliminary discussions with the FTP Team about these items, not all ideas had consensus. I aim to open a detailed, public discussion to gather broader feedback and reach a consensus on which features to prioritize. Sometimes, packages are rejected not because of DFSG-incompatible licenses but due to other issues that could be resolved within an existing package (as discussed in my DebConf23 BoF, "Chatting with ftpmasters"[1]). During the "Meet the ftpteam" BoF (Log/transcription of the BoF can be found here), for the moment until the MR gets accepted, a new option was proposed for FTP Team members reviewing packages in NEW:
Accept + Bug Report This option would allow a package to enter Debian (in unstable or experimental) with an automatically filed RC bug report. The RC bug would prevent the package from migrating to testing until the issues are addressed. To ensure compatibility with the BTS, which only accepts bug reports for existing packages, a delayed job (24 hours post-acceptance) would file the bug.

When binary package names change, currently the package must go through the NEW queue, which can delay the availability of updated libraries. Allowing such packages to bypass the queue could expedite this process. A configuration option to enable this bypass specifically for uploads to experimental may be useful, as it avoids requiring additional technical review for experimental uploads. Previously, I believed the requirement for binary name changes to pass through NEW was due to a missing feature in DAK, possibly addressable via an MR. However, in discussions with the FTP Team, I learned this is a matter of team policy rather than technical limitation. I haven't found this policy documented, so it may be worth having a community discussion to clarify and reach consensus on how we want to handle binary name changes to get the MR sensibly designed. When a developer requests the removal of a package whether entirely or for specific architectures RM bugs must be filed for the package itself as well as for each package depending on it. It would be beneficial if the dependency tree could be automatically resolved, allowing either:
a) the DAK removal tooling to remove the entire dependency tree
   after prompting the bug report author for confirmation, or
b) the system to auto-generate corresponding bug reports for all
   packages in the dependency tree.
The latter option might be better suited for implementation in an MR for reportbug. However, given the possibility of large-scale removals (for example, targeting specific architectures), having appropriate tooling for this would be very beneficial. In my opinion the proposed DAK enhancements aim to support both FTP Team members and uploading developers. I'd be very pleased if these ideas spark constructive discussion and inspire volunteers to start working on them--possibly even preparing to join the FTP Team. On the topic of ftpmasters: an ongoing discussion with SPI lawyers is currently reviewing the non-US agreement established 22 years ago. Ideally, this review will lead to a streamlined workflow for ftpmasters, removing certain hurdles that were originally put in place due to legal requirements, which were updated in 2021. Contacting teams My outreach efforts to Debian teams have slowed somewhat recently. However, I want to emphasize that anyone from a packaging team is more than welcome to reach out to me directly. My outreach emails aren't following any specific orders--just my own somewhat na ve view of Debian, which I'm eager to make more informed. Recently, I received two very informative responses: one from the Qt/KDE Team, which thoughtfully compiled input from several team members into a shared document. The other was from the Rust Team, where I received three quick, helpful replies one of which included an invitation to their upcoming team meeting. Interesting readings on our mailing lists I consider the following threads on our mailing list some interesting reading and would like to add some comments. Sensible languages for younger contributors Though the discussion on debian-devel about programming languages took place in September, I recently caught up with it. I strongly believe Debian must continue evolving to stay relevant for the future. "Everything must change, so that everything can stay the same." -- Giuseppe Tomasi di Lampedusa, The Leopard I encourage constructive discussions on integrating programming languages in our toolchain that support this evolution. Concerns regarding the "Open Source AI Definition" A recent thread on the debian-project list discussed the "Open Source AI Definition". This topic will impact Debian in the future, and we need to reach an informed decision. I'd be glad to see more perspectives in the discussions particularly on finding a sensible consensus, understanding how FTP Team members view their delegated role, and considering whether their delegation might need adjustments for clarity on this issue. Kind regards Andreas.

4 November 2024

Ravi Dwivedi: Asante Kenya for a Good Time

In September of this year, I visited Kenya to attend the State of the Map conference. I spent six nights in the capital Nairobi, two nights in Mombasa, and one night on a train. I was very happy with the visa process being smooth and quick. Furthermore, I stayed at the Nairobi Transit Hotel with other attendees, with Ibtehal from Bangladesh as my roommate. One of the memorable moments was the time I spent at a local coffee shop nearby. We used to go there at midnight, despite the grating in the shops suggesting such adventures were unsafe. Fortunately, nothing bad happened, and we were rewarded with a fun time with the locals.
The coffee shop Ibtehal and me used to visit during the midnight
Grating at a chemist shop in Mombasa, Kenya
The country lies on the equator, which might give the impression of extremely hot temperatures. However, Nairobi was on the cooler side (10 25 degrees Celsius), and I found myself needing a hoodie, which I bought the next day. It also served as a nice souvenir, as it had an outline of the African map printed on it. I also bought a Safaricom SIM card for 100 shillings and recharged it with 1000 shillings for 8 GB internet with 5G speeds and 400 minutes talk time.

A visit to Nairobi s Historic Cricket Ground On this trip, I got a unique souvenir that can t be purchased from the market a cricket jersey worn in an ODI match by a player. The story goes as follows: I was roaming around the market with my friend Benson from Nairobi to buy a Kenyan cricket jersey for myself, but we couldn t find any. So, Benson had the idea of visiting the Nairobi Gymkhana Club, which used to be Kenya s main cricket ground. It has hosted some historic matches, including the 2003 World Cup match in which Kenya beat the mighty Sri Lankans and the record for the fastest ODI century by Shahid Afridi in just 37 balls in 1996. Although entry to the club was exclusively for members, I was warmly welcomed by the staff. Upon reaching the cricket ground, I met some Indian players who played in Kenyan leagues, as well as Lucas Oluoch and Dominic Wesonga, who have represented Kenya in ODIs. When I expressed interest in getting a jersey, Dominic agreed to send me pictures of his jersey. I liked his jersey and collected it from him. I gave him 2000 shillings, an amount suggested by those Indian players.
Me with players at the Nairobi Gymkhana Club
Cricket pitch at the Nairobi Gymkhana Club
A view of the cricket ground inside the Nairobi Gymkhana Club
Scoreboard at the Nairobi Gymkhana cricket ground
Giraffe Center in Nairobi Kenya is known for its safaris and has no shortage of national parks. In fact, Nairobi is the only capital in the world with a national park. I decided not to visit one, as most of them were expensive and offered multi-day tours, and I didn t want to spend that much time in the wildlife. Instead, I went to the Giraffe Center in Nairobi with Pragya and Rabina. The ticket cost 1500 Kenyan shillings (1000 Indian rupees). In Kenya, matatus - shared vans, usually decorated with portraits of famous people and play rap songs - are the most popular means of public transport. Reaching the Giraffe Center from our hotel required taking five matatus, which cost a total of 150 shillings, and a 2 km walk. The journey back was 90 shillings, suggesting that we didn t find the most efficient route to get there. At the Giraffe Center, we fed giraffes and took photos.
A matatu with a Notorious BIG portrait.
Inside the Giraffe Center
Train ride from Nairobi to Mombasa I took a train from Nairobi to Mombasa. The train is known as the SGR Train, where SGR refers to Standard Gauge Railway. The journey was around 500 km. M-Pesa was the only way to make payment for pre-booking the train ticket, and I didn t have an M-Pesa account. Pragya s friend Mary helped facilitate the payment. I booked a second-class ticket, which cost 1500 shillings (1000 Indian rupees). The train was scheduled to depart from Nairobi at 08:00 hours in the morning and arrive in Mombasa at 14:00 hours. The security check at the station required scanning our bags and having them sniffed by sniffer dogs. I also fell victim to a scam by a security official who offered to help me get my ticket printed, only to later ask me to get him some coffee, which I politely declined. Before boarding the train, I was treated to some stunning views at the Nairobi Terminus station. It was a seating train, but I wished it were a sleeper train, as I was sleep-deprived. The train was neat and clean, with good toilets. The train reached Mombasa on time at around 14:00 hours.
SGR train at Nairobi Terminus.
Interior of the SGR train
Arrival in Mombasa
Mombasa Terminus station.
Mombasa was a bit hotter than Nairobi, with temperatures reaching around 30 degrees Celsius. However, that s not too hot for me, as I am used to higher temperatures in India. I had booked a hostel in the Old Town and was searching for a hitchhike from the Mombasa Terminus station. After trying for more than half an hour, I took a matatu that dropped me 3 km from my hostel for 200 shillings (140 Indian rupees). I tried to hitchhike again but couldn t find a ride. I think I know why I couldn t get a ride in both the cases. In the first case, the Mombasa Terminus was in an isolated place, so most of the vehicles were taxis or matatus while any noncommercial cars were there to pick up friends and family. If the station were in the middle of the city, there would be many more car/truck drivers passing by, thus increasing my possibilities of getting a ride. In the second case, my hostel was at the end of the city, and nobody was going towards that side. In fact, many drivers told me they would love to give me a ride, but they were going in some other direction. Finally, I took a tuktuk for 70 shillings to reach my hostel, Tulia Backpackers. It was 11 USD (1400 shillings) for one night. The balcony gave a nice view of the Indian Ocean. The rooms had fans, but there was no air conditioning. Each bed also had mosquito nets. The place was walking distance of the famous Fort Jesus. Mombasa has had more Islamic influence compared to Nairobi and also has many Hindu temples.
The balcony at Tulia Backpackers Hostel had a nice view of the ocean.
A room inside the hostel with fans and mosquito nets on the beds
Visiting White Sandy Beaches and Getting a Hitchhike Visiting Nyali beach marked my first time ever at a white sand beach. It was like 10 km from the hostel. The next day, I visited Diani Beach, which was 30 km from the hostel. Going to Diani Beach required crossing a river, for which there s a free ferry service every few minutes, followed by taking a matatu to Ukunda and then a tuk-tuk. The journey gave me a glimpse of the beautiful countryside of Kenya.
Nyali beach is a white sand beach
This is the ferry service for crossing the river.
During my return from Diani Beach to the hostel, I was successful in hitchhiking. However, it was only a 4 km ride and not sufficient to reach Ukunda, so I tried to get another ride. When a truck stopped for me, I asked for a ride to Ukunda. Later, I learned that they were going in the same direction as me, so I got off within walking distance from my hostel. The ride was around 30 km. I also learned the difference between a truck ride and a matatu or car ride. For instance, matatus and cars are much faster and cooler due to air conditioning, while trucks tend to be warmer because they lack it. Further, the truck was stopped at many checkpoints by the police for inspections as it carried goods, which is not the case with matatus. Anyways, it was a nice experience, and I am grateful for the ride. I had a nice conversation with the truck drivers about Indian movies and my experiences in Kenya.
Diani beach is a popular beach in Kenya. It is a white sand beach.
Selfie with truck drivers who gave me the free ride
Back to Nairobi I took the SGR train from Mombasa back to Nairobi. This time I took the night train, which departs at 22:00 hours, reaching Nairobi at around 04:00 in the morning. I could not sleep comfortably since the train only had seater seats. I had booked the Zarita Hotel in Nairobi and had already confirmed if they allowed early morning check-in. Usually, hotels have a fixed checkout time, say 11:00 in the morning, and you are not allowed to stay beyond that regardless of the time you checked in. But this hotel checked me in for 24 hours. Here, I paid in US dollars, and the cost was 12 USD.

Almost Got Stuck in Kenya Two days before my scheduled flight from Nairobi back to India, I heard the news that the airports in Kenya were closed due to the strikes. Rabina and Pragya had their flight back to Nepal canceled that day, which left them stuck in Nairobi for two additional days. I called Sahil in India and found out during the conversation that the strike was called off in the evening. It was a big relief for me, and I was fortunate to be able to fly back to India without any changes to my plans.
Newspapers at a stand in Kenya covering news on the airport closure
Experience with locals I had no problems communicating with Kenyans, as everyone I met knew English to an extent that could easily surpass that of big cities in India. Additionally, I learned a few words from Kenya s most popular local language, Swahili, such as Asante, meaning thank you, Jambo for hello, and Karibu for welcome. Knowing a few words in the local language went a long way. I am not sure what s up with haggling in Kenya. It wasn t easy to bring the price of souvenirs down. I bought a fridge magnet for 200 shillings, which was the quoted price. On the other hand, it was much easier to bargain with taxis/tuktuks/motorbikes. I stayed at three hotels/hostels in Kenya. None of them had air conditioners. Two of the places were in Nairobi, and they didn t even have fans in the rooms, while the one in Mombasa had only fans. All of them had good Wi-Fi, except Tulia where the internet overall was a bit shaky. My experience with the hotel staff was great. For instance, we requested that the Nairobi Transit Hotel cancel the included breakfast in order to reduce the room costs, but later realized that it was not a good idea. The hotel allowed us to revert and even offered one of our missing breakfasts during dinner. The staff at Tulia Backpackers in Mombasa facilitated the ticket payment for my train from Mombasa to Nairobi. One of the staff members also gave me a lift to the place where I could catch a matatu to Nyali Beach. They even added an extra tea bag to my tea when I requested it to be stronger.

Food At the Nairobi Transit Hotel, a Spanish omelet with tea was served for breakfast. I noticed that Spanish omelette appeared on the menus of many restaurants, suggesting that it is popular in Kenya. This was my first time having this dish. The milk tea in Kenya, referred to by locals as white tea, is lighter than Indian tea (they don t put a lot of tea leaves).
Spanish Omelette served in breakfast at Nairobi Transit Hotel
I also sampled ugali with eggs. In Mombasa, I visited an Indian restaurant called New Chetna and had a buffet thali there twice.
Ugali with eggs.

Tips for Exchanging Money In Kenya, I exchanged my money at forex shops a couple of times. I received good exchange rates for bills larger than 50 USD. For instance, 1 USD on xe.com was 129 shillings, and I got 128.3 shillings per USD (a total of 12,830 shillings) for two 50 USD notes at an exchange in Nairobi, while 127 shillings, which was the highest rate at the banks. On the other hand, for smaller bills such as a one US dollar note, I would have got 125 shillings. A passport was the only document required for the exchange, and they also provided a receipt. A good piece of advice for travelers is to keep 50 USD or larger bills for exchanging into the local currency while saving the smaller US dollar bills for accommodation, as many hotels and hostels accept payment in US dollars (in addition to Kenyan shillings).

Missed Malindi and Lamu There were more places on my to-visit list in Kenya. But I simply didn t have time to cover them, as I don t like rushing through places, especially in a foreign country where there is a chance of me underestimating the amount of time it takes during transit. I would have liked to visit at least one of Kilifi, Watamu or Malindi beaches. Further, Lamu seemed like a unique place to visit as it has no cars or motorized transport; the only options for transport are boats and donkeys. That s it for now. Meet you in the next one :)

2 November 2024

Russell Coker: What is a Workstation?

I recently had someone describe a Mac Mini as a workstation , which I strongly disagree with. The Wikipedia page for Workstation [1] says that it s a type of computer designed for scientific or technical use, for a single user, and would commonly run a multi-user OS. The Mac Mini runs a multi-user OS and is designed for a single user. The issue is whether it is for scientific or technical use . A Mac Mini is a nice little graphical system which could be used for CAD and other engineering work. But I believe that the low capabilities of the system and lack of expansion options make it less of a workstation. The latest versions of the Mac Mini (to be officially launched next week) have up to 64G of RAM and up to 8T of storage. That is quite decent compute power for a small device. For comparison the HP ML 110 Gen9 workstation I m currently using was released in 2021 and has 256G of RAM and has 4 * 3.5 SAS bays so I could easily put a few 4TB NVMe devices and some hard drives larger than 10TB. The HP Z640 workstation I have was released in 2014 and has 128G of RAM and 4*2.5 SATA drive bays and 2*3.5 SATA drive bays. Previously I had a Dell PowerEdge T320 which was released in 2012 and had 96G of RAM and 8*3.5 SAS bays. In CPU and GPU power the recent Mac Minis will compare well to my latest workstations. But they compare poorly to workstations from as much as 12 years ago for RAM and storage. Which is more important depends on the task, if you have to do calculations on 80G of data with lots of scans through the entire data set then a system with 64G of RAM will perform very poorly and a system with 96G and a CPU less than half as fast will perform better. A Dell PowerEdge T320 from 2012 fully loaded with 192G of RAM will outperform a modern Mac Mini on many tasks due to this and the T420 supported up to 384G. Another issue is generic expansion options. I expect a workstation to have a number of PCIe slots free for GPUs and other devices. The T320 I used to use had a PCIe power cable for a power hungry GPU and I think all the T320 and T420 models with high power PSUs supported that. I think that a usable definition of a workstation is a system having a feature set that is typical of servers (ECC RAM, lots of storage for RAID, maybe hot-swap storage devices, maybe redundant PSUs, and lots of expansion options) while also being suitable for running on a desktop or under a desk. The Mac Mini is nice for running on a desk but that s the only workstation criteria it fits. I think that ECC RAM should be a mandatory criteria and any system without it isn t a workstation. That excludes most Apple hardware. The Mac Mini is more of a thin-client than a workstation. My main workstation with ECC RAM could run 3 VMs that each have more RAM than the largest Mac Mini that will be sold next week. If 32G of non-ECC RAM is considered enough for a workstation then you could get an Android phone that counts as a workstation and it will probably cost less than a Mac Mini.

Next.

Previous.