Search Results: "evo"

7 January 2016

Daniel Pocock: Do you own your phone or does it own you?

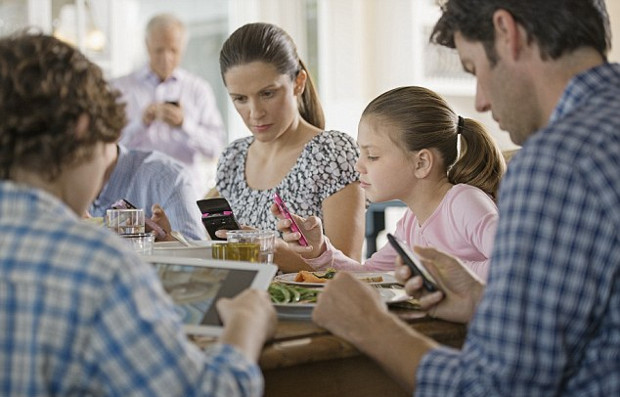
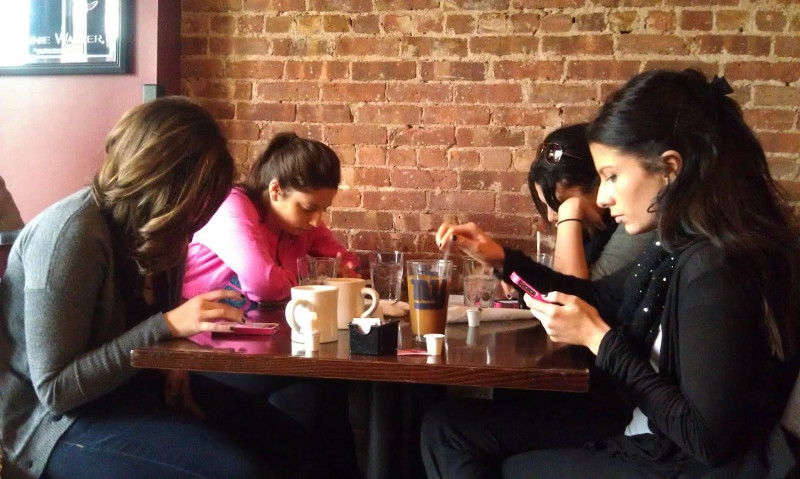
Have you started thinking about new year's resolutions for 2016? Back to the gym or giving up sugary drinks? Many new year's resolutions have a health theme. Unless you have a heroin addiction, there may not be anything else in your life that is more addictive and has potentially more impact on your health and quality of life than your mobile phone. Almost every week there is some new report about the negative impact of phone use on rest or leisure time. Children are particularly at risk and evidence strongly suggests their grades at school are tanking as a consequence. Can you imagine your life changing for the better if you switched off your mobile phone or left it at home for one day per week in 2016? If you have children, can you think of anything more powerful than the example you set yourself to help them stay in control of their phones? Children have a remarkable ability to emulate the bad habits they observe in their parents. Are you in control? Turning it off is a powerful act of showing who is in charge. If you feel you can't live without it, then you are putting your life in the hands of the people who expect an immediate answer of their calls, your phone company and the Silicon Valley executives who make all those apps you can't stop using. As security expert Jacob Appelbaum puts it, cell phones are tracking devices that also happen to make phone calls. Isn't that a chilling thought to reflect on the next time you give one as Christmas gift? For your health, your children and your bank balance Not so long ago we were having lunch in a pizza restaurant in Luzern, a picturesque lakeside town at the base of the Swiss Alps. Luzern is a popular first stop for tourists from all around the world. A Korean family came along and sat at the table next to us. After ordering their food, they all immediately took out their mobile devices and sat there in complete silence, the mother and father, a girl of eight and a boy of five, oblivious to the world around them and even each other, tapping and swiping for the next ten minutes until their food arrived. We wanted to say hello to them, I joked that I should beep first, initiating communication with the sound of a text message notification. Is this how all holidays will be in future? Is it how all families will spend time together? Can you imagine your grandchildren and their children sharing a meal like this in the year 2050 or beyond? Which gadgets does Bond bring to Switzerland? On Her Majesty's Secret Service is one of the more memorable Bond movies for its spectacular setting in the Swiss Alps, the location now transformed into a mountain-top revolving restaurant visited by thousands of tourists every day with a comfortable cable car service and hiking trails with breathtaking views that never become boring. Can you imagine Bond leaving behind his gun and his skis and visiting Switzerland with a smartphone instead? Eating a pizza with one hand while using the fingertips of the other to operate an app for making drone strikes on villains, swiping through Tinder for a new girl to replace the one who died (from boredom) in his previous "adventure" and letting his gelati melt while engrossed in a downhill ski or motorcycle game in all the glory of a 5.7" 24-bit colour display? Of course its absurd. Would you want to live like that yourself? We see more and more of it in people who are supposedly in Switzerland on the trip of a lifetime. Would you tolerate it in a movie? The mobile phone industry has paid big money to have their technology appear on the silver screen but audience feedback shows people are frustrated with movies that plaster the contents of text messages across the screen every few minutes; hopefully Bond movies will continue to plaster bullets and blood across the screen instead. Time for freedom How would you live for a day or a weekend or an entire holiday without your mobile phone? There are many small frustrations you may experience but the biggest one and the indirect cause of many other problems you will experience may be the inability to tell the time. Many people today have stopped wearing a watch, relying instead upon their mobile phone to tell the time. Without either a phone or a watch, frustration is not far away. If you feel apprehension just at the thought of leaving your phone at home, the lack of a watch may be a subconcious factor behind your hesitation. Trying is better than reading Many articles and blogs give opinions about how to buy a watch, how much to spend and what you can wear it with. Don't spend a lot of time reading any of it, if you don't know where to start, simply go down to the local high street or mall and try them. Start with the most glamorous and expensive models from Swiss manufacturers, as these are what everything else is compared to and then perhaps proceed to look more widely. While Swiss brands tend to sell through the stores, vendors on Amazon and eBay now distribute a range of watches from manufacturers in Japan, China and other locations, such as Orient and Invicta, at a fraction of the price of those in the stores. You still need to try a few first to identify your preferred style and case size though. Google can also turn up many options for different budgets.
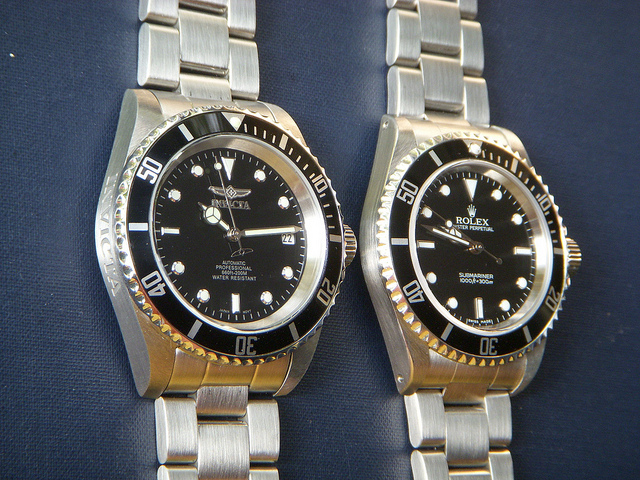
Copying or competition? Similarity of Invicta (from Amazon) and Rolex Submariner You may not know whether you want a watch that is manually wound, automatically wound or battery operated. Buying a low-cost automatic model online could be a good way to familiarize yourself before buying anything serious. Mechanical watches have a smoother and more elegant second-hand movement and will survive the next Carrington event but may come to grief around magnets - a brief encounter with a low-cost de-gausser fixes that. Is it smart to buy a smart watch? If you genuinely want to have the feeling of complete freedom and control over technology, you may want to think twice about buying a smart watch. While it may be interesting to own and experiment with it some of the time, being free from your phone means being free from other electronic technology too. If you do go for a smart watch (and there are many valid reasons for trying one some of the time), maybe make it a second (or third) watch. Smart watches are likely to be controversial for some time to come due to their impact in schools (where mobile phones are usually banned) and various privacy factors. Help those around you achieve phone freedom in 2016 There will be further blogs on this theme during 2016, each looking at the pressures people face when with or without the mobile phone. As a developer of communications technology myself, you may be surprised to see me encouraging people not to use it every waking minute. Working on this technology makes me more conscious of its impact on those around me and society in general. A powerful factor to consider when talking about any communications technology is the presence of peer pressure and the behavior of those around you. Going phone-free may involve helping them to consider taking control too. Helping them out with a new watch as a gift (be careful to seek advice on the style that they are likely to prefer or ensure the purchase can be exchanged) may be an interesting way to help them engage with the idea and every time they look at the time, they may also be reminded of your concern for their freedom.

6 January 2016

Steinar H. Gunderson: IPv6 non-alternatives: DJB's article, 13 years later

With the world passing 10% IPv6 penetration over the weekend, we see the same old debates coming up again; people claiming IPv6 will never happen (despite several years now of exponential growth!), and that if they had only designed it differently, it would have been all over by now. In particular, people like to point to a 2002 3 article by D. J. Bernstein, complete with rants about how Google would never set up useless IPv6 addresses (and then they did that in 2007 I was involved). It's difficult to understand exactly what the article proposes since it's heavy on calling people idiots and light on actual implementation details (as opposed to when DJB's gotten involved in other fields; e.g. thanks to him we now have elliptical curve crypto that doesn't suck, even if the reference implementation was sort of a pain to build), but I will try to go through it nevertheless and show how I cannot find any way it would work well in practice. One thing first, though: Sorry, guys, the ship has sailed. Whatever genius solution DJB may have thought up that I'm missing, and whatever IPv6's shortcomings (they're certainly there), IPv6 is what we have. By now, you can not expect anything else to arise and take over the momentum; we will either live with IPv6 or die with IPv4. So, let's see what DJB says. As far as I can see, his primary call is for a version of IPv6 where the address space is an extension of the IPv4 space. For sake of discussion, let's call that IPv4+ , although it would share a number of properties with IPv6. In particular, his proposal requires changing the OS and other software on every single end host out there, just as IPv6; he readily admits that and outlines how it's done in rough terms (change all structs, change all configuration files, change all databases, change all OS APIs, etc.). From what I can see, he also readily admits that IPv4 and IPv4+ hosts cannot talk to each other, or more clearly, we cannot start using the extended address space before almost everybody has IPv4+ capable software. (E.g., quote: Once these software upgrades have been done on practically every Internet computer, we'll have reached the magic moment: people can start relying on public IPv6 addresses as replacements for public IPv4 addresses. ) So, exactly how does the IPv4 address space fit into the IPv4+ address space? The article doesn't really say anything about this, but I can imagine only two strategies: Build the IPv4+ space around the IPv4 space (ie., the IPv4 space occupies a little corner of the IPv4+ space, similar to how v4-mapped addresses are used within software but not on the wire today, to let applications do unified treatment of IPv4 addresses as a sort of special IPv6 address), or build it as a hierarchical extension. Let's look at the former first; one IPv4 address gives you one IPv4+ addresses. Somehow this seems to give you all the disadvantages of IPv4 and all the disadvantages of IPv6. The ISP is not supposed to give you any more IPv4+ addresses (or at least DJB doesn't want to contact his ISP about more also saying that the fact that automatic address distribution does not change his argument), so if you have one, you're stuck with one. So you still need NAT. (DJB talks about proxies , but I guess that the way things evolved, this either actually means NAT, or it talks about the practice of application-level proxies such as Squid or SOCKS proxies to reach the Internet, which really isn't commonplace anymore, so I'll assume for the sake of discussion it means NAT.) However, we already do NAT. The IPv4 crunch happened despite ubiquitous NAT everywhere; we're actually pretty empty. So we will need to hand out IPv4+ addresses at the very least to new deployments, and also probably reconfigure every site that wants to expand and is out of IPv4 addresses. ( Site here could mean any organizational unit, such as if your neighborhood gets too many new subscribers for your ISP's local addressing scheme to have enough addresses for you.) A much more difficult problem is that we now need to route these addresses on the wire. Ironically, the least clear part of DJB's plan is step 1, saying we will extend the format of IP packets to allow 16-byte addresses ; how exactly will this happen? For this scheme, I can only assume some sort of IPv4 option that says the stuff in the dstaddr field is just the start and doesn't make sense as an IPv4 address on its own; here are the remaining 12 bytes to complete the IPv4+ address . But now your routers need to understand that format, so you cannot do with only upgrading the end hosts; you also need to upgrade every single router out there, not just the end hosts. (Note that many of these do routing in hardware, so you can't just upgrade the software and call it a day.) And until that's done, you're exactly in the same situation as with IPv4/IPv6 today; it's incompatible. I do believe this option is what DJB talks about. However, I fail to see exactly how it is much better than the IPv6 we got ourselves into; you still need to upgrade all software on the planet and all routers on the planet. The benefit is supposedly that a company or user that doesn't care can just keep doing nothing, but they do need to care, since they need to upgrade 100% of their stuff to understand IPv4+ before we can start even deploying it alongside IPv4 (in contrast with IPv6, where we now have lots of experience in running production networks). The single benefit is that they won't have to renumber until they need to grow, at which point they need to anyway. However, let me also discuss the other possible interpretation, namely that of the IPv4+ address space being an extension of IPv4, ie. if you have 1.2.3.4 in IPv4, you have 1.2.3.4.x.x.x.x or similar in IPv4+. (DJB's article mentions 128-bit addresses and not 64-bit, though; we'll get to that in a moment.) People keep bringing this up, too; it's occasionally been called BangIP (probably jokingly, as in this April Fool's joke) due to the similarity with how explicit mail routing would work before SMTP became commonplace. I'll use that name, even though others have been proposed. The main advantage of BangIP is that you can keep your Internet core routing infrastructure. One way or the other, they will keep seeing IPv4 addresses and IPv4 packets; you need no new peering arrangements etc.. The exact details are unclear, though; I've seen people suggest GRE tunneling, ignoring problems they have through NAT, and I've seen suggestions of IPv4 options for source/destination addresses, also ignoring that someting as innocious as setting the ECN bits has been known to break middleboxes left and right. But let's assume you can pull that off, because your middlebox will almost certainly need to be the point that decapsulates BangIP anyway and converts it to IPv4 on the inside, presumably with a 10.0.0.0/8 address space so that your internal routing can keep using IPv4 without an IPv4+ forklift upgrade. (Note that you now lose the supposed security benefit of NAT, by the way, although you could probably encrypt the address.) Of course, your hosts will need to support IPv4+ still, and you will need some way of communicating that you are on the inside of the BangIP boundary. And you will need to know what the inside is, so that when you communicate on this side, you'll send IPv4 and not IPv4+. (For a home network with no routing, you could probably even just do IPv4+ on the inside, although I can imagine complications.) But like I wrote above, experience has shown us that 32 extra bits isn't enough. One layer of NAT isn't doing it, we need two. You could imagine the inter-block routability of BangIP helping a fair bit here (e.g., a company with too many machines for 10.0.0.0/8 could probably easily get more addresses for more external IPv4 addresses, yielding 10.0.0.0/8 blocks), but ultimately, it is a problem that you chop the Internet off in two distinct halves that work very differently. My ISP will probably want to use BangIP for itself, meaning I'm on the outside of the core; how many of those extra bits will they allocate for me? Any at all? Having multiple levels of bang sounds like pain; effectively we're creating a variable-length address. Does anyone ever want that? From experience, when we're creating protocols with variable-length addresses, people just tend to use the maximum level anyway, so why not design it with 128-bit to begin with? (The original IP protocol proposals actually had variable-length addresses, by the way.) So we can create our 32/96 BangIP , where the first 32 bits are for the existing public Internet, and then every IPv4 address gives you a 2^96 addresses to play with. (In a sense, it reminds me of 6to4, which never worked very well and is now thankfully dead.) However, this makes the inside/outside-core problem even worse. I now need two very different wire protocols coexisting on the Internet; IPv4+ (which looks like regular IPv4 to the core) for the core, and a sort of IPv4+-for-the-outside (similar to IPv6) outside it. If I build a company network, I need to make sure all of my routers are IPv4+-for-the-outside and talk that, while if I build the Internet core, I need to make sure all of my connections are IPv4 since I have no guarantee that I will be routable on the Internet otherwise. Furthermore, I have a fixed prefix that I cannot really get out of, defined by my IPv4 address(es). This is called hierarchical routing , and the IPv6 world gave it up relatively early despite it sounding like a great idea at first, because it makes multihoming a complete pain: If I have an address 1.2.3.4 from ISP A and 5.6.7.8 from ISP B, which one do I use as the first 32 bits of my IPv4+ network if I want it routable on the public Internet? You could argue that the solution for me is to get an IPv4 PI netblock (supposedly a /24, since we're not changing the Internet core), but we're already out of those, which is why we started this thing to begin with. Furthermore, if the IPv4/IPv4+ boundary is above my immediate connection to the Internet (say, ISP A doesn't have an IPv4 address, just IPv4+), I'm pretty hosed; I cannot announce an IPv4 netblock in BGP. The fact that the Internet runs on largely the same protocol everywhere is a very nice thing; in contrast, what is described here really would be a mess! So, well. I honestly don't think it's as easy to just do extension instead of alternative when it comes to the address spaces. We'll just need to deal with the pain and realize that upgrading the equipment and software is the larger part of the job anyway, and we'll need to do that no matter what solution we go with. Congrats on reaching 10%! Now get to work with the remaining 90%.

5 January 2016

Daniel Pocock: Promoting free software and free communications on popular social media networks

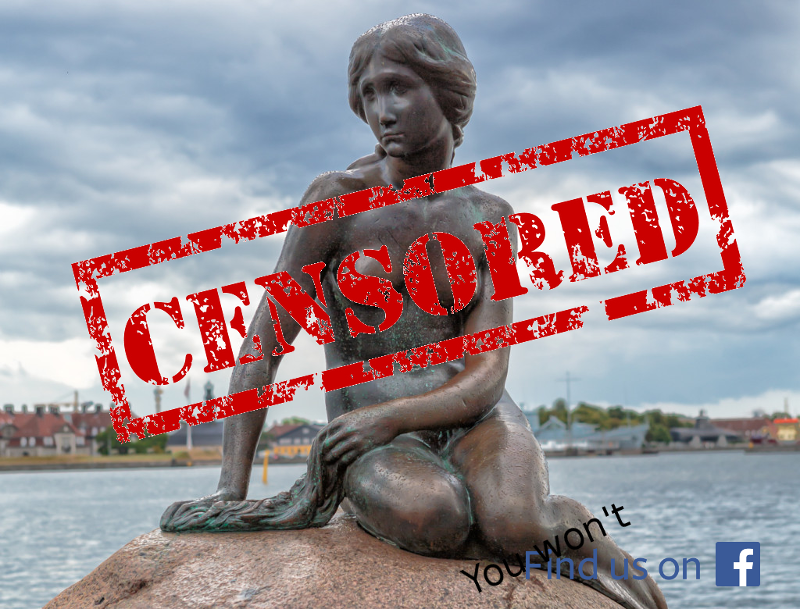
(You can Follow or Tweet about this blog on Twitter) Sites like Twitter and Facebook are not fundamentally free platforms, despite the fact they don't ask their users for money. Look at how Facebook's censors confused Denmark's mermaid statue with pornography or how quickly Twitter can make somebody's account disappear, frustrating public scrutiny of their tweets and potentially denying access to vital information in their "direct message" mailbox. Then there is the fact that users don't get access to the source code, users don't have a full copy of their own data and, potentially worst of all, if most people bothered to read the fine print of the privacy policy they would find it is actually a recipe for downright creepiness. Nonetheless, a significant number of people have accounts in these systems and are to some extent contactable there. Many marketing campaigns that have been successful today, whether they are crowdfunding, political activism or just finding a lost cat claim to have had great success because of Twitter or Facebook. Is this true? In reality, many users of those platforms follow hundreds of different friends and if they only check-in once a day, filtering algorithms show them only a small subset of what all their friends posted. Against these odds, just posting your great idea on Facebook doesn't mean that more than five people are actually going to see it. Those campaigns that have been successful have usually had something else going in their favour, perhaps it was a friend working in the media who gave their campaign a plug on his radio show or maybe they were lucky enough to be slashdotted. Maybe it was having the funds for a professional video production with models who pass off as something spontaneous. The use of Facebook or Twitter alone did not make such campaigns successful, it was just part of a bigger strategy where everything fell into place. Should free software projects, especially those revolving around free communications technology, use such platforms to promote themselves? It is not a simple question. In favour, you could argue that everything we promote through public mailing lists and websites is catalogued by Google anyway, so why not make it easier to access for those who are on Facebook or Twitter? On top of that, many developers don't even want to run their own mail server or web server any more, let alone a self-hosted social-media platform like pump.io. Even running a basic SIP proxy server for the large Debian and Fedora communities involved a lot of discussion about the approach to support it. The argument against using Facebook and Twitter is that you are shooting yourself in the foot, when you participate in those networks, you give them even more credibility and power (which you could quantify using Metcalfe's law). The Metcalfe value of their network, being quadratic rather than linear, shoots ahead of the Metcalfe value of your own solution, putting your alternative even further out of reach. On top of that, the operators of the closed platform are able to evaluate who is responding to your message and how they feel about it and use that intelligence to further undermine you. In some cases, there may be passive censorship, such as WhatsApp silently losing messages that link to rival Telegram. How do you feel about this choice? How and when should free software projects and their developers engage with mainstream social media technology? Please come and share your ideas on the Free-RTC mailing list or perhaps share and Tweet them.

4 January 2016

Alessio Treglia: Enterprise Innovation in a Transformative Society

Recent article by professors Karim Lakhani and Marco Iansiti on the Harvard Business Review, Digital Ubiquity: How Connection, Sensors and Data are Revolutionizing Business , gave me the opportunity for interesting insights and considerations.

Digital technology evolution and the development of modern Internet of Things devices are introducing huge transformative effects within social inter-relationships and its business models. These effects can not be ignored if we want to perceive with the right clarity and meaning the innovation process that inevitably comes with it.
The three fundamental properties of digital technology

<Read More >

30 December 2015

Bits from Debian: Debian lamenta el dec s de l'Ian Murdock

Ian Murdock Amb el cor compungit, Debian lamenta la p rdua d'Ian Murdock, ferm partidari del programari lliure i de codi obert, pare, fill i l'"ian" a Debian. L'Ian va comen ar el projecte Debian l'agost de 1993, i va publicar les primeres versions m s tard el mateix any. Debian es convertiria en el sistema operatiu universal pel m n, que funciona en tot tipus de dispositius, des de sistemes encastats fins a l'estaci especial. L'Ian es va centrar en crear una distribuci i una cultura de comunitat que fessin el correcte, ticament o t cnica. Publicar quan estigui a punt i la ferma posici sobre la llibertat de programari s n les regles d'or en el m n del programari lliure i de codi obert. La seva devoci per fer el correcte va guiar la seva feina, tant a Debian com els seg ents anys, sempre treball per assolir el millor futur possible. El somni de l'Ian est viu, la comunitat de Debian continua incre blement activa, amb milers de desenvolupadors que treballen innumerables hores per proporcionar un sistema operatiu segur i fiable. Els pensaments de la comunitat de Debian s n amb la fam lia de l'Ian en aquests moments tant durs. La seva fam lia ens ha demanat privacitat en aquests moments dif cils i volem respectar-ho. Des de Debian i des de la comunitat de Linux en general podem enviar mostres de condol a in-memoriam-ian@debian.org; seran guardades i arxivades.

Bits from Debian: Debian mourns the passing of Ian Murdock

Ian Murdock With a heavy heart Debian mourns the passing of Ian Murdock, stalwart proponent of Free Open Source Software, Father, Son, and the 'ian' in Debian. Ian started the Debian project in August of 1993, releasing the first versions of Debian later that same year. Debian would go on to become the world's Universal Operating System, running on everything from embedded devices to the space station. Ian's sharp focus was on creating a Distribution and community culture that did the right thing, be it ethically, or technically. Releases went out when they were ready, and the project's staunch stance on Software Freedom are the gold standards in the Free and Open Source world. Ian's devotion to the right thing guided his work, both in Debian and in the subsequent years, always working towards the best possible future. Ian's dream has lived on, the Debian community remains incredibly active, with thousands of developers working untold hours to bring the world a reliable and secure operating system. The thoughts of the Debian Community are with Ian's family in this hard time. His family has asked for privacy during this difficult time and we very much wish to respect that. Within our Debian and the larger Linux community condolences may be sent to in-memoriam-ian@debian.org where they will be kept and archived.

Bits from Debian: Debian lamenta el fallecimiento de Ian Murdock

Ian Murdock Con el coraz n compungido, Debian lamenta el fallecimiento de Ian Murdock, firme partidario del software libre y abierto, padre, hijo y el 'ian' en Debian. Ian empez el proyecto en agosto de 1993, publicando la primera versi n de Debian m s tarde en el mismo a o. Debian se convertir a as en el sistema operativo universal para el mundo, funcionando en cualquier dispositivo, desde sistemas embebidos hasta la estaci n espacial. Ian se centr en crear una distribuci n y una cultura de comunidad que hiciera lo correcto tanto en lo tico como en lo t cnico. Publicar cuando est listo y una postura firme sobre la libertad de software son las reglas de oro en el mundo del software libre y de c digo abierto. La devoci n le gui en su trabajo, tanto en Debian como en los a os posteriores, siempre trabajando hacia un futuro lo mejor posible. El sue o de Debian est vivo, la comunidad permanece incre blemente activa con miles de desarrolladores que trabajan incontables horas para ofrecer un sistema operativo seguro y confiable. La comunidad de Debian da el p same a la familia en este momento tan dif cil. Su familia nos ha pedido discreci n durante estos momentos dif ciles y deseamos respetarlo. Desde dentro de Debian y de la amplia comunidad de Linux podemos expresar nuestras muestras de condolencia a in-memoriam-ian@debian.org, donde ser n guardadas y archivadas.

26 December 2015

Lucas Nussbaum: Debian packages with /outdated/ packaging style

(This is just a copy of this debian-devel@ email) Following my blog post yesterday with graphs about Debian packaging evolution, I prepared lists of packages for each kind of outdatedness. Of course not all practices highlighted below are deprecated, and there are good reasons to continue to do some of them. But still, given that they all represent a clear minority of packages, I thought that it would be useful to list the related packages. (I honestly didn t know if some of my packages would show up in the lists!) The lists are available at https://people.debian.org/~lucas/qa-20151226/ I also pushed them to alioth, so you can either do:
ssh people.debian.org 'grep -A 10 YOURNAME ~lucas/public_html/qa-20151226/*ddlist'
or:
ssh alioth.debian.org 'grep -A 10 YOURNAME ~lucas/qa-20151226/*ddlist' the meaning of the lists is: If you don t understand why your package is listed, you can have a look at allpackages-20151226.yaml that provides more details. If you still don t understand, just ask me. Excluding duplicates, a total of 5469 packages are listed. The dd-list output for the merged list is also available (which isn t very useful, except to know if you are listed).

20 December 2015

Lars Wirzenius: FUUG grant for Obnam development: what happened then

In September, The FUUG Foundation gave me a grant to buy some hardware for Obnam development. I used this money to buy a new desktop-ish machine, see below for details. It's sat in a corner, and I use it as a server: it's not normally connected to a monitor or keyboard. It runs Obnam benchmarks. Before this, I ran Obnam benchmarks and experiments on my laptop, or on BigV virtual servers donated by Bytemark. The hardware The parts: Not to brag, but it's a nice machine. Much more power than my 2012 era laptop. The SSD is the system drive, the HDDs are for running Obnam benchmarks on. The HDDs are not RAIDed. Each drive is a PV for LVM2. All the data on those drives is scratch data: it's not valuable, and I do not care if it is lost. In fact, most of the data gets created and deleted during a benchmark run, and usually the disks are empty. The SSD contains the host operating system, and the virtual disks for all the virtual machines. I assembled the machine myself, with the help of a friend, and installed Debian jessie on it. The Debian installation is pretty bare bones, just enough to run and manage a bunch of virtual machines using libvirt and ansible. All the actual work, including benchmarks, are run in virtual machines. The benchmarks The benchmarks are run by a kludge, called obbench, and the results are published at http://benchmark.obnam.org/. Here's a snapshot of the results so far:
date many files one big file
2015-09-28 2165.0 1381.9
2015-12-06 1461.6 384.0
In a bit over two months, I've made some significant progress, I think. The two benchmarks that I currently run are: These are two extreme cases of what a backup needs to deal with: either the file metadata, or its content. They incur different costs for a backup program. Thus, two benchmarks. In both cases, the benchmark consists of an initial backup, a restore, and a second backup, without changes to the live data. The second backup is an extreme case of what backups usually do: most data usually doesn't change, so keeping that in mind for optimisation is important. The above benchmarks are synthetic: they use data that's generated by a program (genbackupdata), so that they can be reproduced. Synthetic benchmarks are useful, especially for looking at particular aspects of a program's operation for optimisation. However, they do not necessarily reflect how a program behaves in actual use. I also run, by hand, experiments with real data. I have a snapshot of our home file server and my laptop on the benchmark machine. The snapshots are static, and do not get updated. I experiment by running Obnam backups manually, the initial full backup and a no-change incremental one. In early October, I couldn't finish the initial full backups. They took too long, more than a week. Now I can finish them in about a day. This remarkable change is not evident from the synthetic benchmarks. In numbers: 572986 files in the live data, containing 4.5 TiB. Initial backup, about 18.5 hours. Incremental backup, 4m13s. This is from a local disk to a local disk. In addition to these, I've run numerous experiments on the new machine. These would have been much less easy to run on my laptop, and so I probably wouldn't have. Running benchmarks was always painful on my laptop, since it does not have the necessary disk space, and I'd really rather like to use it for other things. The results Thanks to the benchmarks and experiments I've been able to take the in-development version of Obnam from being quite impractical for real use to being in experimental use for real data. I now use the new version as my primary backup of my laptop, with two secondary backups (with the old Obnam version, and rsync) in parallel. This would not have happened this year without the extra hardware. In addition to the Obnam work, I've used the new machine to develop a test suite for vmdebootstrap. My actual development still happens on my laptop, except for things that are heavy enough to be slow on the laptop. I've made sure I can do most development purely on my laptop, while offline, including running a CI system, and testing things on two architecture and three releases of Debian. I do not want my development to be dependent on incidental things such as network access, unless I'm doing things that by their nature depend on the network, such as publishing changes or releases.

15 December 2015

Antoine Beaupr : Using a Yubikey NEO for SSH and OpenPGP on Debian jessie

I recently ordered two Yubikey devices from Yubico, partly because of a special offer from Github. I ordered both a Yubikey NEO and a Yubikey 4, although I am not sure I remember why I ordered two - you can see their Yubikey product comparison if you want to figure that out, but basically, the main difference is that the NEO has support for NFC while the "4" has support for larger RSA key sizes (4096). This article details my experiment on the matter. It is partly based on first hand experience, but also links to various other tutorials that helped me along the way. Especially thanks to folks on various IRC channels that really helped me out in understanding this. My objective in getting a hardware security token like this was three-fold:
  1. use 2FA on important websites like Github, to improve the security of critical infrastructure (like my Borg backup software)
  2. login to remote SSH servers without exposing my password or my private key material on third party computers
  3. store OpenPGP key material on the key securely, so that the private key material can never be compromised
To make a long story short: this article documents step 2 and implicitly step 3 (because I use OpenPGP to login to SSH servers). However it is not possible to use the key on arbitrary third party computers, given how much setup was necessary to make the thing work at all. 2FA on the Github site completely failed, but could be used on other sites, although this is not covered by this article. I have also not experimented in details the other ways the Yubikey can also be used (sorry for the acronym flood) as: Update: OATH works! It is easy to configure and i added a section below.

Not recommended After experimenting with the device and doing a little more research, I am not sure it was the right decision to buy a Yubikey. I would not recommend buying Yubikey devices because they don't allow changing the firmware, making the device basically proprietary, even in the face of an embarrassing security vulnerability on the Yubikey NEO that came out in 2015. A security device, obviously, should be as open as the protocols it uses, otherwise it's basically impossible to trust that the crypto hasn't been backdoored or compromised, or, in this case, is vulnerable to the simplest drive-by attacks. Furthermore, it turns out that the primary use case that Github was promoting is actually not working as advertised: to use the Yubikey on Github, you actually first need to configure 2FA with another tool, either with your phone's text messages (SMS) or with something like Google Authenticator. After contacting Github support, they explained that the Yubikey is seen as a "backup device", which seems really odd to me, especially considering the promotion and the fact that I don't have a "smart" (aka "Google", it seems these days) phone or the desire to share my personal phone number with Github. Finally, as I mentioned before, the fact that those devices are fairly new and the configuration necessary to make them work at all is completely obtuse, non-standardized or at least not available by default on arbitrary computers makes them basically impossible to use on other computers than your own specially crafted gems.

Plugging it in The Yubikey, when inserted into a USB port, seems to be detected properly. It shows up both as a USB keyboard and a generic device.
d c 14 17:23:26 angela kernel: input: Yubico Yubikey NEO OTP+U2F as /devices/pci0000:00/0000:00:12.0/usb3/3-2/3-2:1.0/0003:1050:0114.0016/input/input127
d c 14 17:23:26 angela kernel: hid-generic 0003:1050:0114.0016: input,hidraw3: USB HID v1.10 Keyboard [Yubico Yubikey NEO OTP+U2F] on usb-0000:00:12.0-2/input0
d c 14 17:23:26 angela kernel: hid-generic 0003:1050:0114.0017: hiddev0,hidraw4: USB HID v1.10 Device [Yubico Yubikey NEO OTP+U2F] on usb-0000:00:12.0-2/input1
We'll be changing this now - we want to to support OTP, U2F and CCID. Don't worry about those acronyms now, but U2F is for the web, CCID is for GPG/SSH, and OTP is for the One Time Passwords stuff mentionned earlier. I am using the Yubikey Personalization tool from stretch because the jessie one is too old, according to Gorzen. Indeed, I found out that the jessie version doesn't ship with the proper udev rules. Also, note that we need to run as sudo otherwise we get a permission denied:
$ sudo apt install yubikey-personalization/stretch
$ sudo ykpersonalize -m86
Firmware version 3.4.3 Touch level 1541 Program sequence 1
The USB mode will be set to: 0x86
Commit? (y/n) [n]: y
To understand better what the above does, see the NEO composite device documentation. The next step is to reconnect the key, for the udev rules to kick in. If you were like me, you enthusiastically plugged in the device before installing the yubikey-personalization package, and the udev rules were not present then.

Configuring a PIN Various operations will require you to enter a PIN when talking to the key. The default PIN is 123456 and the default admin PIN is 12345678. You will want to change that, otherwise someone that gets a hold of your key could do any operation without your consent. For this, you need to use:
$ gpg --card-edit
> passwd
> admin
> passwd
Be sure to remember those passwords! Of course, the key material on the Yubikey can be revoked when you loose the key, but only if you still have control of the master key, or if you have a OpenPGP revocation certification (which you should have).

Configuring GPG To do OpenPGP operations (like decryption, signatures and so on), or SSH operations (like authentication on a remote server), you need to talk with GPG. Yes, OpenPGP keys are RSA keys that can be used to authenticate with SSH servers, that's not new and I have already been doing this with Monkeysphere for a while. Now the challenge is how to make GPG talk with the Yubikey. So the next step is to see if gpg can see the key alright, as described in the Yubikey importing keys howto - you will need first to install scdaemon and pcscd (according to this howto) for gpg-agent to be able to talk with the key:
$ sudo apt install scdaemon gnupg-agent pcscd
$ gpg-connect-agent --hex "scd apdu 00 f1 00 00" /bye
ERR 100663404 Card error <SCD>
Well that failed. At this point, touching the key types a bunch of seemingly random characters wherever my cursor is sitting - fun but totally useless still. That was because I failed to reconnect the key: make sure the udev rules are in place and reconnect the key, the above should work:
$ gpg-connect-agent --hex "scd apdu 00 f1 00 00" /bye
D[0000]  01 00 10 90 00                                     .....
OK
This shows it is running the firmware 1.10, which is not vulnerable to the infamous security issue. (Note: I also happened to install opensc and gpgsm because of this suggestion but I am not sure they are required at all.)

Using SSH To make GPG work with SSH, you need somehow to start gpg-agent with ssh support, for example with:
gpg-agent --daemon --enable-ssh-support bash
Of course, this will work better if it's started with your Xsession. Such an agent should already be started, so you just need to add the ssh emulation to its configuration file and restart your X session.
echo 'enable-ssh-support' >> .gnupg/gpg-agent.conf
In Debian Jessie, the ssh-agent wrapper will not start if it detects that you have already one running (for example from gpg-agent) but if that fails, you can try commenting out use-ssh-agent from /etc/X11/Xsession.options to keep it from starting up in your session. (Thanks to stackexchange for that reference.) Here I assume you have already created an authentication subkey on your PGP key. If you haven't, I suggest trying out simply monkeysphere gen-subkey, which will generate an authentication subkey for you. You can also do it by hand by following one of the OpenPGP/SSH tutorials from Yubikey, especially the more complete one. If you are going to generate a completely new OpenPGP key, you may want to follow this simpler tutorial here. Then you need to move your authentication subkey to the Yubikey. For this, you need to edit the key and use the keytocard command:
$ gpg2 --edit-key anarcat@debian.org
> toggle
> key 2
> keytocard
> save
Here, we use toggle to show the OpenPGP private key material. You should see a key marked with A for Authentication. Mine was the second one so I selected it with key 2 which put a star next to it. The keytocard command moved it to the key and save ensure the key was removed from the local keyring. Obviously, backups are essential before doing this, because it's perfectly possible to loose that key in the process, for example if you destroy or lose the key or forget the password. It's probably better to create a completely different authentication subkey for just this purpose, but that may require reconfiguring all remote SSH hosts, and you may not want to do that. Then SSH should magically talk with the GPG agent and ask you for the PIN! That's pretty much all there is to it - if it doesn't, it means that gpg-agent is not your SSH agent, and obviously things will fail... Also, you should be able to see the key being loaded in the agent when it is:
$ ssh-add -l
2048 23:f3:be:bf:1e:da:e8:ad:4b:c7:f6:60:5e:03:c2:a6 cardno:000603647189 (RSA)
.. that's about it! I have yet to cover 2FA and OpenPGP support, but that got me going for a while and I'll stop geeking around with that thing for now. It was fun, for sure, but not sure it's worth it for now.

Using OATH This is pretty neat: it allows you to add two factor authentication to a lot of things. For example, PAM has such a module, which I will configure here to allow myself to login to my server from untrusted machines. While I will expose my main password to keyloggers, the OTP password will prevent that from being reused. This is a simplified version of this OATH tutorial. We install the PAM module with:
sudo apt install libpam-oath
Then, we can hook it into any PAM consumer, for example with sshd:
--- a/pam.d/sshd
+++ b/pam.d/sshd
@@ -1,5 +1,8 @@
 # PAM configuration for the Secure Shell service
+# for the yubikey
+auth required pam_oath.so usersfile=/etc/users.oath window=5 digits=8
+
 # Standard Un*x authentication.
 @include common-auth
We also needed to allow OTP passwords in sshd explicitely, with:
ChallengeResponseAuthentication yes
This will force the user to enter a valid oath token on the server. Unfortunately, this will affect all users, regardless of whether they are present in the users.oath file. I filed bug #807990 regarding this, with a patch. Also, it means the main password is still exposed on the client machine - you can use the sufficient keyword instead of required to workaround that, but then it means anyone with your key can login to your machine, which is something to keep in mind. The /etc/users.oath file needs to be created with something like:
#type   username        pin     start seed
HOTP    anarcat -   00
00 is obviously a fake, and insecure string. Generate a proper one with:
dd if=/dev/random bs=1k count=1   sha1sum # create a random secret
Then the shared secret needs to be added to the Yubikey:
ykpersonalize -1 -o oath-hotp -o oath-hotp8 -o append-cr -a
You simply paste the random secret you created above, when prompted, and that shared secret will be saved in a Yubikey slot for future use. Next time you login to the SSH server, you will be prompted for a OATH password, you just touch the button on the key and it will be pasted there:
$ ssh -o PubkeyAuthentication=no anarc.at
One-time password (OATH) for  anarcat':
Password:
[... logged in!]
Final note: the centralized file approach makes it hard, if not impossible, for users to update their own secret token.. It would be nice if there would be a user-accessible token file, maybe ~/.oath? Filed feature request #807992 about this as well.

14 December 2015

Rapha&#235;l Hertzog: Freexian s report about Debian Long Term Support, November 2015

A Debian LTS logoLike each month, here comes a report about the work of paid contributors to Debian LTS. Individual reports In November, 114.50 work hours have been dispatched among 8 paid contributors. Their reports are available: Evolution of the situation We lost one hour of funding for December due to a sponsor not renewing, and we don t have any new sponsor lined up right now. There s another sponsor who will reduce his sponsorship starting with 2016. While the situation is relatively healthy right now, we should continue the efforts to find new sponsors, both to ensure we can cover more software in wheezy and to better share the costs: having many small sponsors is more resilient than relying on a few big ones. And we still haven t reached our second goal of funding the equivalent of a full-time position. In terms of security updates waiting to be handled, the situation is close to last month: the dla-needed.txt file lists 19 packages awaiting an update (2 less than last month), the list of open vulnerabilities in Squeeze shows about 22 affected packages in total (1 less than last month). Thanks to our sponsors The new sponsors are in bold.

No comment Liked this article? Click here. My blog is Flattr-enabled.

13 December 2015

Robert Edmonds: Works with Debian: Intel SSD 750, AMD FirePro W4100, Dell P2715Q

I recently installed new hardware in my primary computer running Debian unstable. The disk used for the / and /home filesystem was replaced with an Intel SSD 750 series NVM Express card. The graphics card was replaced by an AMD FirePro W4100 card, and two Dell P2715Q monitors were installed. Intel SSD 750 series NVM Express card This is an 800 GB SSD on a PCI-Express x4 card (model number SSDPEDMW800G4X1) using the relatively new NVM Express interface, which appears as a /dev/nvme* device. The stretch alpha 4 Debian installer was able to detect and install onto this device, but grub-installer 1.127 on the installer media was unable to install the boot loader. This was due to a bug recently fixed in 1.128:
grub-installer (1.128) unstable; urgency=high
  * Fix buggy /dev/nvme matching in the case statement to determine
    disc_offered_devfs (Closes: #799119). Thanks, Mario Limonciello!
 -- Cyril Brulebois <kibi@debian.org>  Thu, 03 Dec 2015 00:26:42 +0100
I was able to download and install the updated .udeb by hand in the installer environment and complete the installation. This card was installed on a Supermicro X10SAE motherboard, and the UEFI BIOS was able to boot Debian directly from the NVMe card, although I updated to the latest available BIOS firmware prior to the installation. It appears in lspci like this:
02:00.0 Non-Volatile memory controller: Intel Corporation PCIe Data Center SSD (rev 01)
(prog-if 02 [NVM Express])
    Subsystem: Intel Corporation SSD 750 Series [Add-in Card]
    Flags: bus master, fast devsel, latency 0
    Memory at f7d10000 (64-bit, non-prefetchable) [size=16K]
    Expansion ROM at f7d00000 [disabled] [size=64K]
    Capabilities: [40] Power Management version 3
    Capabilities: [50] MSI-X: Enable+ Count=32 Masked-
    Capabilities: [60] Express Endpoint, MSI 00
    Capabilities: [100] Advanced Error Reporting
    Capabilities: [150] Virtual Channel
    Capabilities: [180] Power Budgeting <?>
    Capabilities: [190] Alternative Routing-ID Interpretation (ARI)
    Capabilities: [270] Device Serial Number 55-cd-2e-41-4c-90-a8-97
    Capabilities: [2a0] #19
    Kernel driver in use: nvme
The card itself appears very large in marketing photos, but this is a visual trick: the photographs are taken with the low-profile PCI bracket installed, rather than the standard height PCI bracket which it ships installed with. smartmontools fails to read SMART data from the drive, although it is still able to retrieve basic device information, including the temperature:
root@chase 0 :~# smartctl -d scsi -a /dev/nvme0n1
smartctl 6.4 2015-06-04 r4109 [x86_64-linux-4.3.0-trunk-amd64] (local build)
Copyright (C) 2002-15, Bruce Allen, Christian Franke, www.smartmontools.org
=== START OF INFORMATION SECTION ===
Vendor:               NVMe
Product:              INTEL SSDPEDMW80
Revision:             0135
Compliance:           SPC-4
User Capacity:        800,166,076,416 bytes [800 GB]
Logical block size:   512 bytes
Rotation Rate:        Solid State Device
Logical Unit id:      8086INTEL SSDPEDMW800G4                     1000CVCQ531500K2800EGN  
Serial number:        CVCQ531500K2800EGN
Device type:          disk
Local Time is:        Sun Dec 13 01:48:37 2015 EST
SMART support is:     Unavailable - device lacks SMART capability.
=== START OF READ SMART DATA SECTION ===
Current Drive Temperature:     31 C
Drive Trip Temperature:        85 C
Error Counter logging not supported
[GLTSD (Global Logging Target Save Disable) set. Enable Save with '-S on']
Device does not support Self Test logging
root@chase 4 :~# 
Simple tests with cat /dev/nvme0n1 >/dev/null and iotop show that the card can read data at about 1 GB/sec, about twice as fast as the SATA-based SSD that it replaced. apt/dpkg now run about as fast on the NVMe SSD as they do on a tmpfs. Hopefully this device doesn't at some point require updated firmware, like some infamous SSDs have. AMD FirePro W4100 graphics card This is a graphics card capable of driving multiple DisplayPort displays at "4K" resolution and at a 60 Hz refresh rate. It has four Mini DisplayPort connectors, although I only use two of them. It was difficult to find a sensible graphics card. Most discrete graphics cards appear to be marketed towards video gamers who apparently must seek out bulky cards that occupy multiple PCI slots and have excessive cooling devices. (To take a random example, the ASUS STRIX R9 390X has three fans and brags about its "Mega Heatpipes".) AMD markets a separate line of "FirePro" graphics cards intended for professionals rather than gamers, although they appear to be based on the same GPUs as their "Radeon" video cards. The AMD FirePro W4100 is a normal half-height PCI-E card that fits into a single PCI slot and has a relatively small cooler with a single fan. It doesn't even require an auxilliary power connection and is about the same dimensions as older video cards that I've successfully used with Debian. It was difficult to determine whether the W4100 card was actually supported by an open source driver before buying it. The word "FirePro" appears nowhere on the webpage for the X.org Radeon driver, but I was able to find a "CAPE VERDE" listed as an engineering name which appears to match the "Cape Verde" code name for the FirePro W4100 given on Wikipedia's List of AMD graphics processing units. This explains the "verde" string that appears in the firmware filenames requested by the kernel (available only in the non-free/firmware-amd-graphics package):
[drm] initializing kernel modesetting (VERDE 0x1002:0x682C 0x1002:0x2B1E).
[drm] Loading verde Microcode
radeon 0000:01:00.0: firmware: direct-loading firmware radeon/verde_pfp.bin
radeon 0000:01:00.0: firmware: direct-loading firmware radeon/verde_me.bin
radeon 0000:01:00.0: firmware: direct-loading firmware radeon/verde_ce.bin
radeon 0000:01:00.0: firmware: direct-loading firmware radeon/verde_rlc.bin
radeon 0000:01:00.0: firmware: direct-loading firmware radeon/verde_mc.bin
radeon 0000:01:00.0: firmware: direct-loading firmware radeon/verde_smc.bin
The card appears in lspci like this:
01:00.0 VGA compatible controller: Advanced Micro Devices, Inc. [AMD/ATI] Cape Verde GL [FirePro W4100]
(prog-if 00 [VGA controller])
    Subsystem: Advanced Micro Devices, Inc. [AMD/ATI] Device 2b1e
    Flags: bus master, fast devsel, latency 0, IRQ 55
    Memory at e0000000 (64-bit, prefetchable) [size=256M]
    Memory at f7e00000 (64-bit, non-prefetchable) [size=256K]
    I/O ports at e000 [size=256]
    Expansion ROM at f7e40000 [disabled] [size=128K]
    Capabilities: [48] Vendor Specific Information: Len=08 <?>
    Capabilities: [50] Power Management version 3
    Capabilities: [58] Express Legacy Endpoint, MSI 00
    Capabilities: [a0] MSI: Enable+ Count=1/1 Maskable- 64bit+
    Capabilities: [100] Vendor Specific Information: ID=0001 Rev=1 Len=010 <?>
    Capabilities: [150] Advanced Error Reporting
    Capabilities: [200] #15
    Capabilities: [270] #19
    Kernel driver in use: radeon
The W4100 appears to work just fine, except for a few bizarre error messages that are printed to the kernel log when the displays are woken from power saving mode:
[Sun Dec 13 00:24:41 2015] [drm:si_dpm_set_power_state [radeon]] *ERROR* si_enable_smc_cac failed
[Sun Dec 13 00:24:41 2015] [drm:si_dpm_set_power_state [radeon]] *ERROR* si_enable_smc_cac failed
[Sun Dec 13 00:24:41 2015] [drm:radeon_dp_link_train [radeon]] *ERROR* displayport link status failed
[Sun Dec 13 00:24:41 2015] [drm:radeon_dp_link_train [radeon]] *ERROR* clock recovery failed
[Sun Dec 13 00:24:41 2015] [drm:radeon_dp_link_train [radeon]] *ERROR* displayport link status failed
[Sun Dec 13 00:24:41 2015] [drm:radeon_dp_link_train [radeon]] *ERROR* clock recovery failed
There don't appear to be any ill effects from these error messages, though. I have the following package versions installed:
 / Name                          Version             Description
+++-=============================-===================-================================================
ii  firmware-amd-graphics         20151207-1          Binary firmware for AMD/ATI graphics chips
ii  linux-image-4.3.0-trunk-amd64 4.3-1~exp2          Linux 4.3 for 64-bit PCs
ii  xserver-xorg-video-radeon     1:7.6.1-1           X.Org X server -- AMD/ATI Radeon display driver
The Supermicro X10SAE motherboard has two PCI-E 3.0 slots, but they're listed as functioning in either "16/NA" or "8/8" mode, which apparently means that putting anything in the second slot (like the Intel 750 SSD, which uses an x4 link) causes the video card to run at a smaller x8 link width. This can be verified by looking at the widths reported in the "LnkCap" and "LnkSta" lines in the lspci -vv output:
root@chase 0 :~# lspci -vv -s 01:00.0   egrep '(LnkCap LnkSta):'
        LnkCap: Port #0, Speed 8GT/s, Width x16, ASPM L0s L1, Exit Latency L0s <64ns, L1 <1us
        LnkSta: Speed 8GT/s, Width x8, TrErr- Train- SlotClk+ DLActive- BWMgmt- ABWMgmt-
root@chase 0 :~# 
I did not notice any visible artifacts or performance degradation because of the smaller link width. The sensors utility from the lm-sensors package is capable of reporting the temperature of the GPU:
root@chase 0 :~# sensors radeon-pci-0100
radeon-pci-0100
Adapter: PCI adapter
temp1:        +55.0 C  (crit = +120.0 C, hyst = +90.0 C)
root@chase 0 :~# 
Dell P2715Q monitors Two new 27" Dell monitors with a native resolution of 3840x2160 were attached to the new graphics card. They replaced two ten year old Dell 2001FP monitors with a native resolution of 1600x1200 that had experienced burn-in, providing 4.32 times as many pixels. (TV and monitor manufacturers now shamelessly refer to the 3840x2160 resolution as "4K" resolution even though neither dimension reaches 4000 pixels.) There was very little to setup beyond plugging the DisplayPort inputs on these monitors into the DisplayPort outputs on the graphics card. Most of the setup involved reconfiguring software to work with the very high resolution. X.org, for tl;dr CLOSED NOTABUG reasons doesn't set the DPI correctly. These monitors have ~163 DPI resolution, so I added -dpi 168 to /etc/X11/xdm/Xservers. (168 is an even 1.75x multiple of 96.) Software like Google Chrome and xfce4-terminal rendered fonts and graphical elements at the right size, but other software like notion, pidgin, and virt-manager did not fully understand the high DPI. E.g., pidgin renders fonts at the correct size, but icons are too small. The default X cursor was also too small. To fix this, I installed the dmz-cursor-theme package, ran update-alternatives --config x-cursor-theme and selected /usr/share/icons/DMZ-Black/cursor.theme as the cursor theme. Overall, these displays are much brighter and more readable than the ones they replaced.

5 December 2015

Gunnar Wolf: Scientific resarch and a moral stand should go hand in hand

During the last few days, I found several references to a beautiful just-published paper, which I hope everybody reads: The Moral Character of Cryptographic Work, by Phillip Rogaway; Cryptology ePrint Report 2015/1162, published on December 1st this year. It is more an academic essay than most crypto-related papers, and a long one at that (46 pages, packed with references and anecdotal notes). But it is surprisingly easy to read. I am sitting in front of my computer while my students work on their final exam, and I have got over half way through the text; earlier today I looked at the quick presentation (as this work was presented by Rogaway at the Asiacrypt 2015 as an invited talk), and just loved it. Now, I know most of the people reading my blog have a moral stand on their work (after all, I expect most of you to be committed to Free Software just as I am, and that is a tremendous political statement). We are also more a practice community than an academic/scientific one. But many of us dwell on several projects and hold more than one hats in life through which we are defined. This paper/essay is really clicking with me, and it deeply resonates with the justification I presented when I joined the Masters on Security Engineering and Information Technologies program which I'm halfway through. Computer security does not exist in a void, and does not exist just for itself. As professionals, we have a mission to fulfill in society, and that will then shape how society evolves. So, I invite everybody to at least take a casual look at this paper. I hope you enjoy it as much as I did, and I hope it changes people's hearts and career decisions.

4 December 2015

Ritesh Raj Sarraf: Freedom, Privacy and Our Choices

When I bought my Lenovo Yoga 2 13, I had great plans. I wanted a device, that I could use both, as a laptop, and also as a tablet. The path hasn't been easy. But then, no path in Free Software against Freedom and Privacy has been easy. The choice is left to us, the users. I had been a long time KDE User. With KDE's decision to have different UIs for different form factors (plasma active, plasma netbook, plasma desktop), it was now time to try something different. I had 2 choices to explore: Unity and GNOME. But given that Unity is not feasible in Debian, the obvious first option to explore was GNOME. And I guess my timing was perfect. I started with 3.14 which showed great promises about touch support, followed by 3.16 and now 3.18. There's still a long way to go, but GNOME definitely is in the right direction and improves impressively with each release. I would like to thank the Debian GNOME Team. You guys just are amazing. The pace at which the packages are prepared and pushed, it is a tough job. So, thank you. Now that I use GNOME, I also follow some GNOME development, file bugs and read User Feedback. While (many of) the design decisions that GNOME makes today is in line with what I desire, there are other users who aren't happy. Many don't like the new UI design GNOME is heading to, i.e. the fusion of the UI such that it is usable on both form factors: Desktop and Tablet. People find the Toolbars bloated. GNOME developer Allan Day has a good blog post showing the facts. But I think there's the other aspect which needs to be emphasized. By improving the same tools, the GNOME devs are making them capable to be used both, on Laptops and Tablets. This is important to me as a user. I still have the freedom of the tools I use.. And those tools don't sniff. By using the same tools in both modes, I also can reliably build a workflow. I remember when I was moving from IceDove to Evolution. It was painful, but once done, I now have an email client I can still use with basic touch workflow. If you take current GNOME out of the picture, what would a user do. Live with a Laptop and a Tablet, 2 separate device. The laptop running Debian and the Tablet ??? In the direction GNOME is in, it allows me to be liberated for both the use cases. My most valuable assets: data and time, both are efficient in use. And not to forget the reason for this blog entry: Freedom and Privacy. Sure you can choose not to buy/use a tablet at all, and live in a world 10yrs behind. By improving the same tools for both use cases, GNOME is also ensuring that they don't throw away learnings from the past. Today Gtk is touch ready and the same libs also are running when on Laptop. A feature addition/enhancement gets leveraged by both. The Search Bar addition into File Dialog is available both, in Laptop and Tablet mode. And the list could go on.... On the other hand, I'm not sure what the KDE User Experience is today. But if I have to log out of my plasma desktop session, to use in Tablet Mode (plasma active), that workflow is already a broken one. I do miss the flexibility KDE used to provide, where in a substantial part of the user flow could be heavily customized. This is one gripe I have with the GNOME Project in general. They just don't balance things at all. Elegance is not about cutting out features. There are simple things you'll miss in GNOME if you come from KDE. Like Ctrl+R in Kwrite. You can't do that in GEdit. Today, with companies like Google, who are developing tools that are cross-platform, stand as good examples as to what GNOME/KDE should do. Don't bloat the UI, but then again don't strip it off either. The Chromium Browser's UI is a great example. The Chromium UI Devs are pretty strict on what new visible field can be added. But under one Wrench button, they provide a world for everyone to be happy. Power Users can run through the option available, and Super Power Users can use things like chrome://settings and chrome://flags I the new world today, where without a proprietary stack running on your mobil device, it is literally useless; Efforts like that of from the GNOME Project, gives some hope.

Categories:

Keywords:

Like:

2 December 2015

Andrea Veri: Three years and counting

It s been a while since my last what s been happening behind the scenes e-mail so I m here to report on what has been happening within the GNOME Infrastructure, its future plans and my personal sensations about a challenge that started around three (3) years ago when Sriram Ramkrishna and Jeff Schroeder proposed my name as a possible candidate for coordinating the team that runs the systems behind the GNOME Project. All this followed by the official hiring achieved by Karen Sandler back in February 2013. The GNOME Infrastructure has finally reached stability both in terms of reliability and uptime, we didn t have any service disruption this and the past year and services have been running smoothly as they were expected to in a project like the one we are managing. As many of you know service disruptions and a total lack of maintenance were very common before I joined back in 2013, I m so glad the situation has dramatically changed and developers, users, passionates are now able to reach our websites, code repositories, build machines without experiencing slowness, downtimes or

unreachability. Additionally all these groups of people now have a reference point they can contact in case they need help when coping with the infrastructure they daily use. The ticketing system allows users to get in touch with the members of the Sysadmin Team and receive support right away within a very short period of time (Also thanks to Pagerduty, service the Foundation is kindly sponsoring) Before moving ahead to the future plans I d like to provide you a summary of what has been done during these roughly three years so you can get an idea of why I define the changes that happened to the infrastructure a complete revamp:
  1. Recycled several ancient machines migrating services off of them while consolidating them by placing all their configuration on our central configuration management platform ran by Puppet. This includes a grand total of 7 machines that were replaced by new hardware and extended warranties the Foundation kindly sponsored.
  2. We strenghten our websites security by introducing SSL certificates everywhere and recently replacing them with SHA2 certificates.
  3. We introduced several services such as Owncloud, the Commits Bot, the Pastebin, the Etherpad, Jabber, the GNOME Github mirror.
  4. We restructured the way we backup our machines also thanks to the Fedora Project sponsoring the disk space on their backup facility. The way we were used to handle backups drastically changed from early years where a magnetic tape facility was in charge of all the burden of archiving our data to today where a NetApp is used together with rdiff-backup.
  5. We upgraded Bugzilla to the latest release, a huge thanks goes to Krzesimir Nowak who kindly helped us building the migration tools.
  6. We introduced the GNOME Apprentice program open-sourcing our internal Puppet repository and cleansing it (shallow clones FTW!) from any sensitive information which now lives on a different repository with restricted access.
  7. We retired Mango and our OpenLDAP instance in favor of FreeIPA which allows users to modify their account information on their own without waiting for the Accounts Team to process the change.
  8. We documented how our internal tools are customized to play together making it easy for future Sysadmin Team members to learn how the infrastructure works and supersede existing members in case they aren t able to keep up their position anymore.
  9. We started providing hosting to the GIMP and GTK projects which now completely rely on the GNOME Infrastructure. (DNS, email, websites and other services infrastructure hosting)
  10. We started providing hosting not only to the GIMP and GTK projects but to localized communities as well such as GNOME Hispano and GNOME Greece
  11. We configured proper monitoring for all the hosted services thanks to Nagios and Check-MK
  12. We migrated the IRC network to a newer ircd with proper IRC services (Nickserv, Chanserv) in place.
  13. We made sure each machine had a configured management (mgmt) and KVM interface for direct remote access to the bare metal machine itself, its hardware status and all the operations related to it. (hard reset, reboot, shutdown etc.)
  14. We upgraded MoinMoin to the latest release and made a substantial cleanup of old accounts, pages marked as spam and trashed pages.
  15. We deployed DNSSEC for several domains we manage including gnome.org, guadec.es, gnomehispano.es, guadec.org, gtk.org and gimp.org
  16. We introduced an account de-activation policy which comes into play when a contributor not committing to any of the hosted repositories at git.gnome.org since two years is caught by the script. The account in question is marked as inactive and the gnomecvs (from the old cvs days) and ftpadmin groups are removed.
  17. We planned mass reboots of all the machines roughly every month for properly applying security and kernel updates.
  18. We introduced Mirrorbrain (MB), the mirroring service serving GNOME and related modules tarballs and software all over the world. Before introducing MB GNOME had several mirrors located in all the main continents and at the same time a very low amount of users making good use of them. Many organizations and companies behind these mirrors decided to not host GNOME sources anymore as the statistics of usage were very poor and preferred providing the same service to projects that really had a demand for these resources. MB solved all this allowing a proper redirect to the closest mirror (through mod_geoip) and making sure the sources checksum matched across all the mirrors and against the original tarball uploaded by a GNOME maintainer and hosted at master.gnome.org.
I can keep the list going for dozens of other accomplished tasks but I m sure many of you are now more interested in what the future plans actually are in terms of where the GNOME Infrastructure should be in the next couple of years. One of the main topics we ve been discussing will be migrating our Git infrastructure away from cgit (which is mainly serving as a code browsing tool) to a more complete platform that is surely going to include a code review tool of some sort. (Gerrit, Gitlab, Phabricator) Another topic would be migrating our mailing lists to Mailman 3 / Hyperkitty. This also means we definitely need a staging infrastructure in place for testing these kind of transitions ideally bound to a separate Puppet / Ansible repository or branch. Having a different repository for testing purposes will also mean helping apprentices to test their changes directly on a live system and not on their personal computer which might be running a different OS / set of tools than the ones we run on the GNOME Infrastructure. What I also aim would be seeing GNOME Accounts being the only authentication resource in use within the whole GNOME Infrastructure. That means one should be able to login to a specific service with the same username / password in use on the other hosted services. That s been on my todo list for a while already and it s probably time to push it forward together with Patrick Uiterwijk, responsible of Ipsilon s development at Red Hat and GNOME Sysadmin. While these are the top priority items we are soon receiving new hardware (plus extended warranty renewals for two out of the three machines that had their warranty renewed a while back) and migrating some of the VMs off from the current set of machines to the new boxes is definitely another task I d be willing to look at in the next couple of months (one machine (ns-master.gnome.org) is being decommissioned giving me a chance to migrate away from BIND into NSD). The GNOME Infrastructure is evolving and it s crucial to have someone maintaining it. On this side I m bringing to your attention the fact the assigned Sysadmin funds are running out as reported on the Board minutes from the 27th of October. On this side Jeff Fortin started looking for possible sponsors and came up with the idea of making a brochure with a set of accomplished tasks that couldn t have been possible without the Sysadmin fundraising campaign launched by Stormy Peters back in June 2010 being a success. The Board is well aware of the importance of having someone looking at the infrastructure that runs the GNOME Project and is making sure the brochure will be properly reviewed and published. And now some stats taken from the Puppet Git Repository:
$ cd /git/GNOME/puppet && git shortlog -ns
3520 Andrea Veri
506 Olav Vitters
338 Owen W. Taylor
239 Patrick Uiterwijk
112 Jeff Schroeder
71 Christer Edwards
4 Daniel Mustieles
4 Matanya Moses
3 Tobias Mueller
2 John Carr
2 Ray Wang
1 Daniel Mustieles Garc a
1 Peter Baumgarten
and from the Request Tracker database (52388 being my assigned ID):
mysql> select count(*) from Tickets where LastUpdatedBy = '52388';
+----------+
  count(*)  
+----------+
  3613  
+----------+
1 row in set (0.01 sec)
mysql> select count(*) from Tickets where LastUpdatedBy = '52388' and Status = 'Resolved';
+----------+
  count(*)  
+----------+
  1596  
+----------+
1 row in set (0.03 sec)
It s been a long run which made me proud, for the things I learnt, for the tasks I ve been able to accomplish, for the great support the GNOME community gave me all the time and most of all for the same fact of being part of the team responsible of the systems hosting the GNOME Project. Thank you GNOME community for your continued and never ending backing, we daily work to improve how the services we host are delivered to you and the support we receive back is fundamental for our passion and enthusiasm to remain high!

30 November 2015

Chris Lamb: Free software activities in November 2015

Here is my monthly update covering a large part of what I have been doing in the free software world (previously):
Debian
  • Presented at MiniDebConf Cambridge 2015 on the current status of Debian's Reproducible Builds effort.
  • Contributed initial Debian support to Red Hat Product Security's repository of certificates shipped by various vendors and Open Source Projects. (#1)
  • Wrote a proof-of-concept version of Guix's challenge command to determine if an installed binary package is reproducible or not. (code)
  • Started initial work on a b2evolution package.
  • Arranged logistics for the Reproducible Builds summit in Athens.
My work in the Reproducible Builds project was also covered in more depth in Lunar's weekly reports (#27, #28, #29, #30).
LTS

This month I have been paid to work 13 hours on Debian Long Term Support (LTS). In that time I did the following:
  • Issued DLA 349-1 for python-django correcting an potential settings leak.
  • Issued DLA 351-1 for redmine fixing a data disclosure vulnerability.
  • Worked on multiple iterations of a fix for CVE-2011-5325 in busybox, not yet complete in order to additionally cover hardlinks.
  • Frontdesk duties.

Uploads
  • redis Addressing CVE-2015-8080, a buffer-overflow security issue.
  • python-django Uploading the latest RC release to experimental.
  • strip-nondeterminism Disable stripping Mono binaries as it is was too aggressive preventing some package installs.
  • gunicorn Correct Python interpreter path references in gunicorn3-debian.
  • python-redis New upstream release.
  • ispell-lt Making the build reproducible.


24 November 2015

Carl Chenet: db2twitter: Twitter out of the browser

You have a database, a tweet pattern and wants to automatically tweet on a regular basis? No need for RSS, fancy tricks, 3rd party website to translate RSS to Twitter or whatever. Just use db2twitter. db2twitter is pretty easy to use! First define your Twitter credentials:
screen_name_of_the_user_to_retweet=journalduhacker
consumer_key=ml9jaiBnf3pmU9uIrKNIxAr3v
consumer_secret=8Cmljklzerkhfer4hlj3ljl2hfvc123rezrfsdctpokaelzerp
access_token=213416590-jgJnrJG5gz132nzerl5zerwi0ahmnwkfJFN9nr3j
access_token_secret=3janlPMqDKlunJ4Hnr90k2bnfk3jfnwkFjeriFZERj32Z
Then your database information:
dbconnector=mysql+mysqlconnector
dbhost=localhost
database=jobboard
dbuser=jobboard
dbpass=V3rYS3cr3t
dbtables=jobs,
jobs_rows=companyname,jobtitle,id
Then the pattern of your tweet, a Python-style formatted string:
tweet=  hires a   https://www.linuxjobs.fr/jobs/ 
Add db2twitter in your crontab:
*/10 * * * * db2witter db2twitter db2twitter.ini
And you re all set! db2twitter will generate and tweet the following tweets:
MyGreatCompany hires a web developer https://www.linuxjobs.fr/jobs/51
CoolStartup hires a devops skilled in Docker https://www.linuxjobs.fr/jobs/52
db2twitter is developed by and run for LinuxJobs.fr, the job board of th french-speaking Free Software and Opensource community. banner-linuxjobs-small db2twitter also has cool options like; db2twitter is coded in Python 3.4, uses SQlAlchemy (see supported database types) and Tweepy. The official documentation is available on readthedocs.

19 November 2015

Miriam Ruiz: Projects, Conflicts and Emotions

The Debian Project includes many people, groups and teams with different goals, priorities and ways of doing things. Diversity is a good thing, and the results of the continuous interaction, cooperation and competition among different points of view and components make up a successful developing framework both in Debian and in other Free / Libre / Open Source Software communities. The cost of this evolutionary paradigm is that sometimes there are subprojects that might have been extremely successful and useful that are surpassed by newer approaches, or that have to compete with alternative approaches that were not there before, and which might pursue different goals or have a different way of doing things that their developers find preferable in terms of modularity, scalability, stability, maintenance, aesthetics or any other reason. Whenever this happens, the emotional impact on the person or group of people that are behind the established component (or process, or organizational structure), that is being questioned and put under test by the newer approach can be important, particularly when they have invested a lot of time and effort and a considerable amount of emotional energy doing a great job for many years. Something they should be thanked for. This might be particularly hard when -for whatever reason- the communication between both teams is not too fluent or constant, and sometimes the author or authors of the solution that was considered mainstream until then might feel left out and their territory stolen. As generally development teams and technical people in the Free / Libre / Open Source world are more focused on results than on relationships, projects are generally not too good at managing this (emotional, relational) situations, even though they (we) are gradually learning and improving. What has happened with the Debian Live Project is indeed a hurtful situation, even though it s probably an unavoidable one. The Debian Live Project has done a great job for many years and it is sad to see it dying abruptly. A new competing approach is on its way with a different set of priorities and different way of doing things, and all that can be done at the moment is to thank Daniel for all his work, as well as everyone who has made the Debian Live Project successful for so many years, also thank the people who are investing their time and effort in developing something that might be even better. Lets wait and see. Source of the image: Conflict Modes and Managerial Styles by Ed Batista

15 November 2015

Manuel A. Fernandez Montecelo: Work on aptitude

Midsummer for me is also known as Noite do Lume Novo (literally New Fire Night ), one of the big calendar events of the year, marking the end of the school year and the beginning of summer. On this day, there are celebrations not very unlike the bonfires in the Guy Fawkes Night in England or Britain [1]. It is a bit different in that it is not a single event for the masses, more of a friends and neighbours thing, and that it lasts for a big chunk of the night (sometimes until morning). Perhaps for some people, or outside bigger towns or cities, Guy Fawkes Night is also celebrated in that way and that's why during the first days of November there are fireworks rocketing and cracking in the neighbourhoods all around. Like many other celebrations around the world involving bonfires, many of them also happening around the summer solstice, it is supposed to be a time of renewal of cycles, purification and keeping the evil spirits away; with rituals to that effect like jumping over the fire when the flames are not high and it is safe enough. So it was fitting that, in the middle of June (almost Midsummer in the northern hemisphere), I learnt that I was about to leave my now-previous job, which is a pretty big signal and precursor for renewal (and it might have something to do with purifying and keeping the evil away as well ;-) ). Whatever... But what does all of this have to do with aptitude or Debian, anyway? For one, it was a question of timing. While looking for a new job (and I am still at it), I had more spare time than usual. DebConf 15 @ Heidelberg was within sight, and for the first time circumstances allowed me to attend this event. It also coincided with the time when I re-gained access to commit to aptitude on the 19th of June. Which means Renewal. End of June was also the time of the announcement of the colossal GCC-5/C++11 ABI transition in Debian, that was scheduled to start on the 1st of August, just before the DebConf. Between 2 and 3 thousand source packages in Debian were affected by this transition, which a few months later is not yet finished (although the most important parts were completed by mid-end September). aptitude itself is written in C++, and depends on several libraries written in C++, like Boost, Xapian and SigC++. All of them had to be compiled with the new C++11 ABI of GCC-5, in unison and in a particular order, for aptitude to continue to work (and for minimal breakage). aptitude and some dependencies did not even compile straight away, so this transition meant that aptitude needed attention just to keep working. Having recently being awarded again with the Aptitude Hat, attending DebConf for the first time and sailing towards the Transition Maelstrom, it was a clear sign that Something Had to Be Done (to avoid the sideways looks and consequent shame at DebConf, if nothing else). Happily (or a bit unhappily for me, but let's pretend...), with the unexpected free time in my hands, I changed the plans that I had before re-gaining the Aptitude Hat (some of them involving Debian, but in other ways maybe I will post about that soon). In July I worked to fix the problems before the transition started, so aptitude would be (mostly) ready, or in the worst case broken only for a few days, while the chain of dependencies was rebuilt. But apart from the changes needed for the new GCC-5, it was decided at the last minute that Boost 1.55 would not be rebuilt with the new ABI, and that the only version with the new ABI would be 1.58 (which caused further breakage in aptitude, was added to experimental only a few days before, and was moved to unstable after the transition had started). Later, in the first days of the transition, aptitude was affected for a few days by breakage in the dependencies, due to not being compiled in sequence according to the transition levels (so with a mix of old and new ABI). With the critical intervention of Axel Beckert (abe / XTaran), things were not so bad as they could have been. He was busy testing and uploading in the critical days when I was enjoying a small holiday on my way to DebConf, with minimal internet access and communicating almost exclusively with him; and he promptly tended the complaints arriving in the Bug Tracking System and asked for rebuilds of the dependencies with the new ABI. He also brought the packaging up to shape, which had decayed a bit in the last few years. Gruesome Challenges But not all was solved yet, more storms were brewing and started to appear in the horizon, in the form of clouds of fire coming from nearby realms. The APT Deities, which had long ago spilled out their secret, inner challenge (just the initial paragraphs), were relentless. Moreover, they were present at Heidelberg in full force, in or close to their home grounds, and they were Marching Decidedly towards Victory: apt BTS Graph, 2015-11-15 In the talk @ DebConf This APT has Super Cow Powers (video available), by David Kalnischkies, they told us about the niceties of apt 1.1 (still in experimental but hopefully coming to unstable soon), and they boasted about getting the lead in our arms race (should I say bugs race?) by a few open bug reports. This act of provocation further escalated the tensions. The fierce competition which had been going on for some time gained new heights. So much so that APT Deities and our team had to sit together in the outdoor areas of the venue and have many a weissbier together, while discussing and fixing bugs. But beneath the calm on the surface, and while pretending to keep good diplomatic relations, I knew that Something Had to Be Done, again. So I could only do one thing jump over the bonfire and Keep the Evil away, be that Keep Evil bugs Away or Keep Evil APT Deities Away from winning the challenge, or both. After returning from DebConf I continued to dedicate time to the project, more than a full time job in some weeks, and this is what happened in the last few months, summarised in another graph, showing the evolution of the BTS for aptitude: aptitude BTS Graph, 2015-11-15 The numbers for apt right now (15th November 2015) are: The numbers for aptitude right now are: The Aftermath As we can see, for the time being I could keep the Evil at bay, both in terms of bugs themselves and re-gaining the lead in the bugs race the Evil APT Deities were thwarted again in their efforts. ... More seriously, as most of you suspected, the graph above is not the whole truth, so I don't want to boast too much. A big part of the reduction in the number of bugs is because of merging duplicates, closing obsolete bugs, applying translations coming from multiple contributors, or simple fixes like typos and useful suggestions needing minor changes. Many of remaining problems are comparatively more difficult or time consuming that the ones addressed so far (except perhaps avoiding the immediate breakage of the transition, that took weeks to solve), and there are many important problems still there, chief among those is aptitude offering very poor solutions to resolve conflicts. Still, even the simplest of the changes takes effort, and triaging hundreds of bugs is not fun at all and mostly a thankless effort althought there is the occasionally kind soul that thanks you for handling a decade-old bug. If being subjected to the rigours of the BTS and reading and solving hundreds of bug reports is not Purification, I don't know what it is. Apart from the triaging, there were 118 bugs closed (or pending) due to changes made in the upstream part or the packaging in the last few months, and there are many changes that are not reflected in bugs closed (like most of the changes needed due to the C++11 ABI transition, bugs and problems fixed that had no report, and general rejuvenation or improvement of some parts of the code). How long this will last, I cannot know. I hope to find a job at some point, which obviously will reduce the time available to work on this. But in the meantime, for all aptitude users: Enjoy the fixes and new features! Notes [1] ^ Some visitors of the recent mini-DebConf @ Cambridge perhaps thought that the fireworks and throngs gathered were in honour of our mighty Universal Operating System, but sadly they were not. They might be, some day. In any case, the reports say that the visitors enjoyed the fireworks.

14 November 2015

Daniel Pocock: Migrating data from Windows phones

Many of the people who have bought Windows phones seek relief sooner or later. Sometimes this comes about due to peer pressure or the feeling of isolation, in other cases it is the frustration of the user interface or the realization that they can't run cool apps like Lumicall. Frequently, the user has been given the phone as a complimentary upgrade when extending a contract without perceiving the time, effort and potential cost involved in getting their data out of the phone, especially if they never owned a smartphone before. When a Windows phone user does decide to cut their losses, they are usually looking to a friend or colleague with technical expertise to help them out. Personally, I'm not sure that anybody I would regard as an IT expert has ever had a Windows phone though, meaning that many experts are probably also going to be scratching their heads when somebody asks them for help. Therefore, I've put together this brief guide to help deal with these phones more expediently when they are encountered. The Windows phones have really bad support for things like CalDAV and WebDAV so don't get your hopes up about using such methods to backup the data to any arbitrary server. Searching online you can find some hacks that involve creating a Google or iCloud account in the phone and then modifying the advanced settings to send the data to an arbitrary server. These techniques vary a lot between specific versions of the Windows Phone OS and so the techniques I've described below are probably easier. Identify the Windows Live / Hotmail account The user may not remember or realize that a Microsoft account was created when they first obtained the phone. It may have been created for them by the phone, a friend or the salesperson in the phone shop. Look in the settings (Accounts) to find the account ID / email address. If the user hasn't been using this account, they may not recognize it and probably won't know the password for it. It is essential to try and obtain (or reset) the password before going any further, so start with the password recovery process. Microsoft may insist on sending a password reset email to some other email address that the user has previously provided or linked to their phone. Extracting data from the phone In many cases, the easiest way to extract the data is to download it from Microsoft live.com rather than extracting it from the phone. Even if the user doesn't realize it, the data is probably all replicated in live.com and so there is no further loss of privacy by logging in there to extract it. Set up an IMAP mail client An IMAP client will be used to download the user's emails (from the live.com account they may never have used) and SMS. Install Mozilla Thunderbird (IceDove on Debian), GNOME Evolution or a similar program on the user's PC. Configure the IMAP mail client to connect to the live.com account. Some clients, like Thunderbird, will automatically set up all the server details when you enter the live.com account ID. For manual account setup, the details here may help. Email backup If the user was not using the live.com account ID for email correspondence, there may not be a lot of mail in it. There may be some billing receipts or other things that are worth keeping though. Create a new folder (or set of folders) in the user's preferred email account and drag and drop the messages from the live.com Inbox to the new folder(s). SMS backup SMS backup can also be done through live.com. It is slightly more complicated than email backup, but similar.
  • In the live.com Outlook email index page, look for the settings button and click Manage Categories.
  • Enable the Contacts and Photos categories with a tick in each of them.
  • Go back to the main Inbox page and look for the categories section on the bottom left-hand side of the screen, under the folder list. Click the Contacts category.
  • The page may now appear blank. That is normal.
  • On the top right-hand corner of the page, click the Arrange menu and choose Conversation.
  • All the SMS messages should now appear on the screen.
  • Under the mail folders list on the left-hand side of the page, click to create a new folder with a name like SMS.
  • Select all the SMS messages and look for the option to move them to a folder. Send them to the SMS folder you created.
  • Now use the IMAP mail client to locate the SMS folder and copy everything from there to a new folder in the user's preferred mail server or local disk.
Contacts backup On the top left-hand corner of the live.com email page, there is a chooser to select other live.com applications. Select People. You should now see a list of all the user's contacts. Look for the option to export them to Outlook and other programs. This will export them as a CSV file. You can now import the CSV file into another application. GNOME Evolution has an import wizard with an option for Outlook file format. To load the contacts into a WebDAV address book, such as DAViCal, configure the address book in Evolution and then select it as the destination when running the CSV import wizard. WARNING: beware of using the Mozilla Thunderbird address book with contact data from mobile devices and other sources. It can't handle more than two email addresses per contact and this can lead to silent data loss if contacts are not fully saved. Calendar backup Now go to the live.com application chooser again and select the calendar application. Microsoft provides instructions to extract the calendar, summarised here:
  • Look for the Share button at the top somewhere and click it.
  • On the left-hand side of the page, click Get a link
  • On the right-hand side, choose Show event details to ensure you get a full calendar and then click Create underneath it.
  • Look for the link with a webcals prefix. If you are downloading with a tool like wget, change the scheme prefix to https. Fetch the file from this link and save it with an ics extension.
  • Inspect the ics calendar file to make sure it looks like real iCalendar data.
You can now import the ics file into another application. GNOME Evolution has an import wizard with an option for iCalendar file format. To load the calendar entries into a CalDAV server, such as DAViCal, configure the calendar server in Evolution and then select it as the destination when running the import wizard. Backup the user's photos, videos and other data files Hopefully you will be able to do this step without going through live.com. Try enabling the MTP or PTP mode in the phone and attach it to the computer using the USB cable. Hopefully the computer will recognize it in at least one of those modes. Use the computer's file manager or another tool to simply backup the entire directory structure. Reset the phone to factory defaults Once the user has their hands on a real phone, it is likely they will never want to look at that Windows phone again. It is time to erase the Windows phone, there is no going back. Go to the Settings and About and tap the factory reset option. It is important to do this before obliterating the live.com account, otherwise there are scenarios where you could be locked out of the phone and unable to erase it. Erasing may take some time. The phone will reboot and then display an animation of some gears spinning around for a few minutes and then reboot again. Wait for it to completely erase. Permanently close the Microsoft live.com account Keeping track of multiple accounts and other services is tedious and frustrating for most people, especially with services that try to force the user to receive email in different places. You can help eliminate user fatigue by helping them permanently close the live.com account so they never have to worry about it again. Follow the instructions on the Microsoft site. At some point it will suggest certain actions you should take before closing the account, most can be ignored. One thing you should do is remove the link between the live.com account ID and the phone. It is a good idea to do this as otherwise you may have problems erasing the device, if you haven't already done so. Before completely closing the account, also verify that the factory reset of the phone completed successfully. Dispose of the Windows phone safely If you can identify any faults with the phone, the user may be able to return it under the terms of the warranty. Some phone companies may allow the user to exchange it for something more desirable when it fails under warranty. It may be tempting to sell the phone to a complete stranger on eBay or install a custom ROM on it. In practice, neither option may be worth the time and effort involved. You may be tempted to put it beyond use so nobody else will suffer with it, but please try to do so in a way that is respectful of the environment. Putting the data into a new phone Prepare the new phone with a suitable ROM such as Replicant or Cyanogenmod. Install the F-Droid app on the new phone. From F-droid, install the DAVdroid app. DAVdroid will allow you to quickly sync the new phone against any arbitrary CalDAV and WebDAV server to populate it with the user's calendar and contact / address book data. Now is a good time to install other interesting apps like Lumicall, Conversations and K-9 Mail.

Next.

Previous.