Search Results: "ed"

8 December 2025

Isoken Ibizugbe: Beginning My Outreachy Journey With Debian

Hello, my name is Isoken, I m a software engineer and product manager from Nigeria. I am excited and grateful to begin this journey as an Outreachy intern working on the project Debian Images Testing with OpenQA . I am particularly drawn to helping solve problems for people; it keeps bugging me till I can find a way to help. This interest in problem-solving and improving quality is what drew me to this project. OpenQA is an automated test tool that simulates a user s interaction by looking at the screen and sending actions like mouse clicks and keyboard inputs. It takes screenshots and compares the image to known reference images to verify if the system is behaving correctly. During the contribution phase (which was 4 weeks), I got to know about Debian software, it s different mode of installation and available different desktop environments, at first I felt intimidated as most of it was new to me, but the setup material and docs for the project made it easy for me, the fact that it looked like a gradual process, getting to know the program, registering the steps in mind and then take notes of every step and visuals, writing it in a way another developer would understand (this is called detail level 3), and then translate it to test code level 1. I contributed to improving the installation documents and a detail level 3 doc for a bug report on the system locale being incorrect. This strengthened my documentation skills and ability to adjust to the writing style of the project. I also started working on app start-stop tests for two desktop environments. I was able to explore, check the applications, and note their differences and similarities. It was really interesting to me; this was where I started writing on coding level 1, and my tests started passing. I will spend the next few weeks continuing on it and hopefully creating a way to synergize the tests and make it easy to maintain later on. I am also grateful for the assistance from other candidates during the contribution stage and the privilege of having the mentors, Tassia Camoes Araujo and Roland Clobus, and Philip Hands, to guide and correct me through the internship period. I will share my progress regularly here on the blog. You can follow the progress of the work here on the main repo. Wish me luck on the rest of this journey

Thorsten Alteholz: My Debian Activities in November 2025

Debian LTS/ELTS This was my hundred-thirty-seventh month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian and my eighty-eighth ELTS month. As the LTS- and ELTS-teams have been merged now, there is only one paragraph left for both activities. During my allocated time I uploaded or worked on: I also attended the monthly LTS/ELTS meeting and did a week of LTS/ELTS frontdesk duties. I also stumbled upon a bug in python3-paramiko, where the parsing of include statements in the ssh_config does not work. Rather annoying but already fixed in the newest version, that only needs to find its way to my old VM. Debian Printing This month I uploaded a new upstream version or a bugfix version of: I also uploaded cups to Trixie, to fix bug #1109471 related to a configuration problem with the admin panel. This work is generously funded by Freexian! Debian Astro This month I uploaded a new upstream version or a bugfix version of: Debian IoT This month I uploaded a new upstream version or a bugfix version of: Debian Mobcom This month I uploaded a new upstream version or a bugfix version of: misc This month I uploaded a new upstream version or a bugfix version of: On my fight against outdated RFPs, I closed 30 of them in November. I started with about 3500 open RFP bugs. and after working six months on this project, I have closed 183 bugs. Of course new bugs appeared, so the overall number of bugs is only down to about 3360. Though I view this as a successful project, I also have to admit that it is a bit boring to work on this daily. Therefore I close this diary again and will add the closed RFP bugs to my bug logbook now. I also try to close some of these bugs by really uploading some software, probably one package per month. FTP master This month I accepted 236 and rejected 16 packages. The overall number of packages that got accepted was 247.

Hellen Chemtai: Debian Images Testing with OpenQA Outreachy Internship

Hello there . I am a software developer and tester. Some of my interests include bash scripting , website full-stack development and also open source software contribution. Outreachy is dedicated to the open source community. The OpenQA community in itself had the right project I wanted to contribute to. It was a really great match for my interests and skills. The project is Debian Images testing with OpenQA. The contribution period was very intense. It was a learning phase at first. I made adjustments to my computer to ensure it would handle the tasks. I also had many trials , failures and problem solving to do. There was a lot of questions asked. My mentors were really helpful. What worked for me in the end was:
  1. Communicating in the social network with fellow contributors and helping out whenever they got stuck.
  2. Writing the small steps I made during the contribution period, from dual booting to all errors encountered and the ways I solved them in a google docs application.
  3. The small steps I made and the word application were then added to the list of contributions I made.
  4. I also wrote and edited the main application in small phases and was detailed on my experiences
  5. Last but not least I did work on my first task. It was speech testing and capturing all audio. I got a lot help from the mentors through out the process.

Every week is a learning phase to me. I encounter newer issues , lets say my latest issue was connecting the Virtual Machine to a newer Wi-Fi network. It took a whole day to get a solution but I eventually solved it. I regularly share my issues and write the solutions so that it would be helpful to anyone in the future. By the end of the internship period, I hope to have contributed to the Debian OpenQA Open Source community.This is by working on the tasks and working with the Opensuse broader community on any issues. I want to build a network with my mentors: Philip, Tassia, Roland and other mentors in the community in order to create future opportunities for contributions, mentoring and just general communication.

Fran ois Marier: Learning a new programming language with an LLM

I started learning Go this year. First, I picked a Perl project I wanted to rewrite, got a good book and ignored AI tools since I thought they would do nothing but interfere with learning. Eventually though, I decided to experiment a bit and ended up finding a few ways to use AI assistants effectively even when learning something new.

Searching more efficiently The first use case that worked for me was search. Instead of searching on a traditional search engine and then ending up on Stack Overflow, I could get the answer I was looking for directly in an AI side-window in my editor. Of course, that's bad news for Stack Overflow. I was however skeptical from the beginning since LLMs make mistakes, sometimes they making up function signatures or APIs that don't exist. Therefore I got into the habit of going to the official standard library documentation to double-check suggestions. For example, if the LLM suggests using strings.SplitN, I verify the function signature and behaviour carefully before using it. Basically, "don't trust and do verify." I stuck to the standard library in my project, but if an LLM recommends third-party dependencies for you, make sure they exist and that Socket doesn't flag them as malicious. Research has found that 5-20% of packages suggested by LLMs don't actually exist, making this a real attack vector (dubbed "slopsquatting").

Autocomplete is too distracting A step I took early on was to disable AI autocomplete in my editor. When learning a new language, you need to develop muscle memory for the syntax. Also, Go is no Java. There's not that much boilerplate to write in general. I found it quite distracting to see some almost correct code replace my thinking about the next step. I can see how one could go faster with these suggestions, but being a developer is not just about cranking out lines of code as fast as possible, it's also about constantly learning new things (and retaining them).

Asking about idiomatic code One of the most useful prompts when learning a new language is "Is this the most idiomatic way to do this in Go?". Large language models are good at recognizing patterns and can point out when you're writing code that works but doesn't follow the conventions of the language. This is especially valuable early on when you don't yet have a feel for what "good" code looks like in that language. It's usually pretty easy (at least for an experience developer) to tell when the LLM suggestion is actually counter productive or wrong. If it increases complexity or is harder to read/decode, it's probably not a good idea to do it.

Reviews One way a new dev gets better is through code review. If you have access to a friend who's an expert in the language you're learning, then you can definitely gain a lot by asking for feedback on your code. If you don't have access to such a valuable resource, or as a first step before you consult your friend, I found that AI-assisted code reviews can be useful:
  1. Get the model to write the review prompt for you. Describe what you want reviewed and let it generate a detailed prompt.
  2. Feed that prompt to multiple models. They each have different answers and will detect different problems.
  3. Be prepared to ignore 50% of what they recommend. Some suggestions will be stylistic preferences, others will be wrong, or irrelevant.
The value is in the other 50%: the suggestions that make you think about your code differently or catch genuine problems. Similarly for security reviews:
  • A lot of what they flag will need to be ignored (false positives, or things that don't apply to your threat model).
  • Some of it may highlight areas for improvement that you hadn't considered.
  • Occasionally, they will point out real vulnerabilities.
But always keep in mind that AI chatbots are trained to be people-pleasers and often feel the need to suggest something when nothing was needed

An unexpected benefit One side effect of using AI assistants was that having them write the scaffolding for unit tests motivated me to increase my code coverage. Trimming unnecessary test cases and adding missing ones is pretty quick when the grunt work is already done, and I ended up testing more of my code (being a personal project written in my own time) than I might have otherwise.

Learning In the end, I continue to believe in the value of learning from quality books (I find reading paper-based most effective). In addition, I like to create Anki questions for common mistakes or things I find I have to look up often. Remembering something will always be faster than asking an AI tool. So my experience this year tells me that LLMs can supplement traditional time-tested learning techniques, but I don't believe it obsoletes them. P.S. I experimented with getting an LLM to ghost-write this post for me from an outline (+ a detailed style guide) and I ended up having to rewrite at least 75% of it. It was largely a waste of time.

Freexian Collaborators: Debian's /usr-move transition has been completed (by Helmut Grohne)

By now, the /usr-merge is an old transition. Effectively, it turns top-level directories such as /bin into symbolic links pointing below /usr. That way the entire operating system can be contained below the /usr hierarchy enabling e.g. image based update mechanisms. It was first supported in Debian 9, which is no longer in active use at this point (except for users of Freexian s ELTS offer). When it became mandatory in Debian 12, it wasn t really done though, because Debian s package manager was not prepared to handle file system objects being referred to via two different paths. With nobody interested in handling the resulting issues, Freexian stepped in and funded a project lead by Helmut Grohne to resolve the remaining issues. While the initial idea was to enhance the package manager, Debian s members disagreed. They preferred an approach where files were simply tracked with their physical location while handling the resulting misbehavior of the package manager using package-specific workarounds. This has been recorded in the DEP17 document. During the Debian 13 release cycle, the plan has been implemented. A tool for detecting possible problems was developed specifically for this transition. Since all files are now tracked with their physical location and necessary workarounds have been added, problematic behavior is no longer triggered. An upgrade from Debian 12 to Debian 13 is unlikely to run into aliasing problems as a result. This whole project probably consumed more than 1500 hours of work from Debian contributors, of which 700 were sponsored by Freexian through the work of Helmut Grohne. What remains is eventually removing the workarounds.

7 December 2025

Vincent Bernat: Compressing embedded files in Go

Go s embed feature lets you bundle static assets into an executable, but it stores them uncompressed. This wastes space: a web interface with documentation can bloat your binary by dozens of megabytes. A proposition to optionally enable compression was declined because it is difficult to handle all use cases. One solution? Put all the assets into a ZIP archive!

Code The Go standard library includes a module to read and write ZIP archives. It contains a function that turns a ZIP archive into an io/fs.FS structure that can replace embed.FS in most contexts.1
package embed
import (
  "archive/zip"
  "bytes"
  _ "embed"
  "fmt"
  "io/fs"
  "sync"
)
//go:embed data/embed.zip
var embeddedZip []byte
var dataOnce = sync.OnceValue(func() *zip.Reader  
  r, err := zip.NewReader(bytes.NewReader(embeddedZip), int64(len(embeddedZip)))
  if err != nil  
    panic(fmt.Sprintf("cannot read embedded archive: %s", err))
   
  return r
 )
func Data() fs.FS  
  return dataOnce()
 
We can build the embed.zip archive with a rule in a Makefile. We specify the files to embed as dependencies to ensure changes are detected.
common/embed/data/embed.zip: console/data/frontend console/data/docs
common/embed/data/embed.zip: orchestrator/clickhouse/data/protocols.csv 
common/embed/data/embed.zip: orchestrator/clickhouse/data/icmp.csv
common/embed/data/embed.zip: orchestrator/clickhouse/data/asns.csv
common/embed/data/embed.zip:
    mkdir -p common/embed/data && zip --quiet --recurse-paths --filesync $@ $^
The automatic variable $@ is the rule target, while $^ expands to all the dependencies, modified or not.

Space gain Akvorado, a flow collector written in Go, embeds several static assets:
  • CSV files to translate port numbers, protocols or AS numbers, and
  • HTML, CSS, JS, and image files for the web interface, and
  • the documentation.
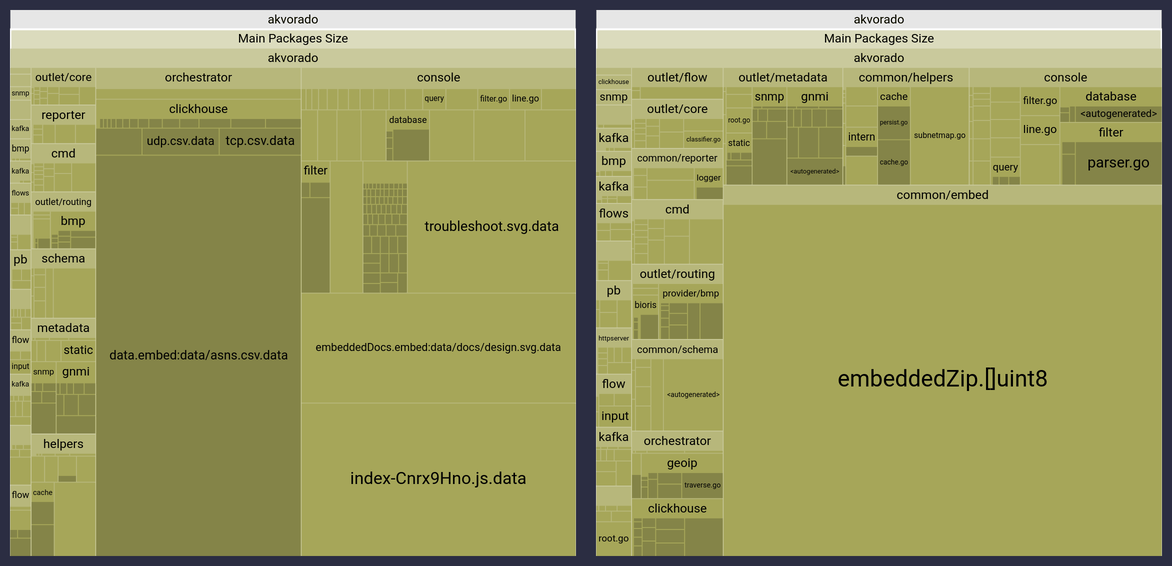
Breakdown of space used by each package before and after introducing embed.zip. It is displayed as a treemap and we can see many embedded files replaced by a bigger one.
Breakdown of the space used by each component before (left) and after (right) the introduction of embed.zip.
Embedding these assets into a ZIP archive reduced the size of the Akvorado executable by more than 4 MiB:
$ unzip -p common/embed/data/embed.zip   wc -c   numfmt --to=iec
7.3M
$ ll common/embed/data/embed.zip
-rw-r--r-- 1 bernat users 2.9M Dec  7 17:17 common/embed/data/embed.zip

Performance loss Reading from a compressed archive is not as fast as reading a flat file. A simple benchmark shows it is more than 4 slower. It also allocates some memory.2
goos: linux
goarch: amd64
pkg: akvorado/common/embed
cpu: AMD Ryzen 5 5600X 6-Core Processor
BenchmarkData/compressed-12     2262   526553 ns/op   610 B/op   10 allocs/op
BenchmarkData/uncompressed-12   9482   123175 ns/op     0 B/op    0 allocs/op
Each access to an asset requires a decompression step, as seen in this flame graph:
🖼 Flame graph when reading data from embed.zip compared to reading data directly
CPU flame graph comparing the time spent on CPU when reading data from embed.zip (left) versus reading data directly (right). Because the Go testing framework executes the benchmark for uncompressed data 4 times more often, it uses the same horizontal space as the benchmark for compressed data. The graph is interactive.
While a ZIP archive has an index to quickly find the requested file, seeking inside a compressed file is currently not possible.3 Therefore, the files from a compressed archive do not implement the io.ReaderAt or io.Seeker interfaces, unlike directly embedded files. This prevents some features, like serving partial files or detecting MIME types when serving files over HTTP.
For Akvorado, this is an acceptable compromise to save a few mebibytes from an executable of almost 100 MiB. Next week, I will continue this futile adventure by explaining how I prevented Go from disabling dead code elimination!

  1. You can safely read multiple files concurrently. However, it does not implement ReadDir() and ReadFile() methods.
  2. You could keep frequently accessed assets in memory. This reduces CPU usage and trades cached memory for resident memory.
  3. SOZip is a profile that enables fast random access in a compressed file. However, Go s archive/zip module does not support it.

Iustin Pop: Yes, still alive!

Yeah, again three months have passed since my last (trivial) post, and I really don t know where the time has flown. I suppose the biggest problem was the long summer vacation, which threw me off-track, and then craziness started. Work work work, no time for anything, which kept me fully busy in August, and then you should travel . So mid-September I went on my first business trip since Covid, again to Kirkland, which in itself was awesome. Flew out Sunday, and as I was concerned I was going to lose too much fitness had a half-marathon planned on the weekend after the return I ran every morning of the four days I was there. And of course, on the last day, I woke up even earlier (05:30 AM), went out to run before sunrise, intending to do a very simple run along the road that borders the lake for 2.5K, then back . And right at the farthest point, a hundred metres before my goal of turning around, I tripped, started falling, and as I was falling, I hit sideways a metal pole. I was in a bus station, it was the pole that has the schedule at the top, and I hit it at relatively full speed, right across my left-side ribs. The crash took the entire air out of my lungs, and I don t remember if I ever felt pain/sensation like that I was seriously not able to breathe for 20 seconds or so, and I was wondering if I m going to pass out at this rate. Only 20 seconds, because my Garmin started howling like a police siren, and the screen was saying something along the lines of: Incident detected; contacting emergency services in 40 35 and I was fumbling to cancel that, since a) I wasn t that bad, b) notifying my wife that I had a crash would have not been a smart idea. My left leg was scraped in a few places, my left hand pretty badly, or more than just scraped, so my focus was on limping back, and finding a fountain to wash my injuries, which I did, so I kept running with blood dripping down my hand. Fun fun, everything was hurting, I took an Uber for the ~1Km to the office, had many meetings, took another Uber and flew back to Zurich. Seattle San Francisco Z rich, I think 14 hours, with my ribs hurting pretty badly. But I got home (Friday afternoon), and was wondering if I can run or not on Saturday. Saturday comes, I feel pretty OK, so I said let s try, will stop if the pain is too great. I pick up my number, I go to the start, of course in the last block and not my normal block, and I start running. After 50 metres, I knew this won t be good enough, but I said, let s make it to the first kilometre. Then to the first fuelling point, then to the first aid point, at which moment I felt good enough to go to the second one. Long story short, I ran the whole half marathon, with pain. Every stop for fuelling was mentally hard, as the pain stopped, and I knew I had to start running again, and the pain would resume. In the end, managed to finish: two and a half hours, instead of just two hours, but alive and very happy. Of course, I didn t know what was waiting for me Sunday I wake up in heavy pain, and despite painkillers, I was not feeling much better. The following night was terrible, Monday morning I went to the doctor, had X-rays, discussion with a radiologist. Not really broken, but more than just bruised. See this angle here? Bones don t have angles normally . Painkillers, chest/abdomen wrapping, no running! So my attempts to not lose fitness put me off running for a couple of weeks. Then October came, and I was getting better, but work was getting even more crazy. I don t know where November passed, honestly, and now we re already in December. I did manage to run, quite well, managed to bike a tiny bit and swim a little, but I m not in a place where I can keep a regular and consistent schedule. On the good side, I managed this year, for the first time since Covid, to not get sick. Hey, a sport injury is 100 better than a sickness, like I had in previous years, taking me out for two weeks. But life was crazy enough that I didn t read some of my email accounts for months, and I m just now starting to catch up to, well, baseline. Of course, the rib the lowest one on the left side is long-healed, or so I thought. After some strength training early this week, I was very sore the next day, and I wanted to test whether my rib is still sore. I touched it at the point , and it hurt so badly I couldn t believe. Two and a half months, and it s not done-done. And now it s just two weeks before Christmas and New Year s, and that time off will ruin my rhythm again. At least ski vacation is booked, ski service is done, and slowly, work is getting in good enough shape to actually enjoy thinking about vacation. So, in the end, a very adventurous last third of the year, and that wasn t even all. As I m writing this, my right wrist is bandaged and for the past 24 hours it hasn t hurt too much, but that s another, and not so interesting, story. I ll close with a yay for always being behind/backlogged, but alive and relatively well. My sport injuries are elective injuries so to speak, and I m very thankful for that. See you in the next post!

6 December 2025

Simon Josefsson: Reproducible Guix Container Images

Around a year ago I wrote about Guix Container Images for GitLab CI/CD and these images have served the community well. Besides continous use in CI/CD, these Guix container images are used to confirm reproducibility of the source tarball artifacts in the releases of Libtasn1 v4.20, InetUtils v2.6, Libidn2 v2.3.8, Libidn v1.43, SASL v2.2.2, Guile-GnuTLS v5.0.1, and OATH Toolkit v2.6.13. See how all those release announcements mention a Guix commit? That s the essential supply-chain information about the Guix build environment that allows the artifacts to be re-created. To make sure this is repeatable, the release tarball artifacts are re-created from source code every week in the verify-reproducible-artifacts project, that I wrote about earlier. Guix s time travelling feature make this sustainable to maintain, and hopefully will continue to be able to reproduce the exact same tarball artifacts for years to come. During the last year, unfortunately Guix was removed from Debian stable. My Guix container images were created from Debian with that Guix package. My setup continued to work since the old stage0 Debian+Guix containers were still available. Such a setup is not sustainable, as there will be bit-rot and we don t want to rely on old containers forever, which (after the removal of Guix in Debian) could not be re-produced any more. Let this be a reminder how user-empowering features such as Guix time-travelling is! I have reworked my Guix container image setup, and this post is an update on the current status of this effort. The first step was to re-engineer Debian container images with Guix, and I realized these were useful on their own, and warrant a separate project. A more narrowly scoped project makes will hopefully make it easier to keep them working. Now instead of apt-get install guix they use the official Guix guix-install.sh approach. Read more about that effort in the announcement of Debian with Guix. The second step was to reconsider my approach to generate the Guix images. The earlier design had several stages. First, Debian+Guix containers were created. Then from those containers, a pure Guix container was created. Finally, using the pure Guix container another pure Guix container was created. The idea behind that GCC-like approach was to get to reproducible images that were created from an image that had no Debian left on it. However, I never managed to finish this. Partially because I hadn t realized that every time you build a Guix container image from Guix, you effectively go back in time. When using Guix version X to build a container with Guix on it, it will not put Guix version X into the container but will put whatever version of Guix is available in its package archive, which will be an earlier version, such as version X-N. I had hope to overcome this somehow (running a guix pull in newly generated images may work), but never finished this before Guix was removed from Debian. So what could a better design look like? For efficiency, I had already started experimenting with generating the final images directly from the Debian+Guix images, and after reproducibility bugs were fixed I was able to get to reproducible images. However, I was still concerned that the Debian container could taint the process somehow, and was also concerned about the implied dependency on non-free software in Debian. I ve been using comparative rebuilds using similar distributions to confirm artifact reproducibility for my software projects, comparing builds on Trisquel 11 with Ubuntu 22.04, and AlmaLinux 9 with RockyLinux 9 for example. This works surprisingly well. Including one freedom-respecting distribution like Trisquel will detect if any non-free software has bearing on artifacts. Using different architectures, such as amd64 vs arm64 also help with deeper supply-chain concerns. My conclusion was that I wanted containers with the same Guix commit for both Trisquel and Ubuntu. Given the similarity with Debian, adapting and launching the Guix on Trisquel/Debian project was straight forward. So we now have Trisquel 11/12 and Ubuntu 22.04/24.04 images with the same Guix on them. Do you see where the debian-with-guix and guix-on-dpkg projects are leading to? We are now ready to look at the modernized Guix Container Images project. The tags are the same as before:
registry.gitlab.com/debdistutils/guix/container:latest
registry.gitlab.com/debdistutils/guix/container:slim
registry.gitlab.com/debdistutils/guix/container:extra
registry.gitlab.com/debdistutils/guix/container:gash
The method to create them is different. Now there is a build job that uses the earlier Guix+Trisquel container (for amd64) or Guix+Debian (for arm64, pending Trisquel arm64 containers). The build job create the final containers directly. Next a Ubuntu reproduce job is launched that runs the same commands, failing if it cannot generate the bit-by-bit identical container. Then single-arch images are tested (installing/building GNU hello and building libksba), and then pushed to the GitLab registry, adding multi-arch images in the process. Then the final multi-arch containers are tested by building Guile-GnuTLS and, on success, uploaded to the Docker Hub. How would you use them? A small way to start the container is like this:
jas@kaka:~$ podman run -it --privileged --entrypoint=/bin/sh registry.gitlab.com/debdistutils/guix/container:latest
sh-5.2# env HOME=/ guix describe # https://issues.guix.gnu.org/74949
  guix 21ce6b3
    repository URL: https://git.guix.gnu.org/guix.git
    branch: master
    commit: 21ce6b392ace4c4d22543abc41bd7c22596cd6d2
sh-5.2# 
The need for --entrypoint=/bin/sh is because Guix s pack command sets up the entry point differently than most other containers. This could probably be fixed if people want that, and there may be open bug reports about this. The need for --privileged is more problematic, but is discussed upstream. The above example works fine without it, but running anything more elaborate with guix-daemon installing packages will trigger a fatal error. Speaking of that, here is a snippet of commands that allow you to install Guix packages in the container.
cp -rL /gnu/store/*profile/etc/* /etc/
echo 'root:x:0:0:root:/:/bin/sh' > /etc/passwd
echo 'root:x:0:' > /etc/group
groupadd --system guixbuild
for i in $(seq -w 1 10); do useradd -g guixbuild -G guixbuild -d /var/empty -s $(command -v nologin) -c "Guix build user $i" --system guixbuilder$i; done
env LANG=C.UTF-8 guix-daemon --build-users-group=guixbuild &
guix archive --authorize < /share/guix/ci.guix.gnu.org.pub
guix archive --authorize < /share/guix/bordeaux.guix.gnu.org.pub
guix install hello
GUIX_PROFILE="/var/guix/profiles/per-user/root/guix-profile"
. "$GUIX_PROFILE/etc/profile"
hello
This could be simplified, but we chose to not hard-code in our containers because some of these are things that probably shouldn t be papered over but fixed properly somehow. In some execution environments, you may need to pass --disable-chroot to guix-daemon. To use the containers to build something in a GitLab pipeline, here is an example snippet:
test-amd64-latest-wget-configure-make-libksba:
  image: registry.gitlab.com/debdistutils/guix/container:latest
  before_script:
  - cp -rL /gnu/store/*profile/etc/* /etc/
  - echo 'root:x:0:0:root:/:/bin/sh' > /etc/passwd
  - echo 'root:x:0:' > /etc/group
  - groupadd --system guixbuild
  - for i in $(seq -w 1 10); do useradd -g guixbuild -G guixbuild -d /var/empty -s $(command -v nologin) -c "Guix build user $i" --system guixbuilder$i; done
  - export HOME=/
  - env LANG=C.UTF-8 guix-daemon --build-users-group=guixbuild &
  - guix archive --authorize < /share/guix/ci.guix.gnu.org.pub
  - guix archive --authorize < /share/guix/bordeaux.guix.gnu.org.pub
  - guix describe
  - guix install libgpg-error
  - GUIX_PROFILE="//.guix-profile"
  - . "$GUIX_PROFILE/etc/profile"
  script:
  - wget https://www.gnupg.org/ftp/gcrypt/libksba/libksba-1.6.7.tar.bz2
  - tar xfa libksba-1.6.7.tar.bz2
  - cd libksba-1.6.7
  - ./configure
  - make V=1
  - make check VERBOSE=t V=1
More help on the project page for the Guix Container Images. That s it for tonight folks, and remember, Happy Hacking!

Jonathan Dowland: thesis

It's done! It's over! I've graduated, I have the scroll, I'm staring at the eye-watering prices for the official photographer snap, I'm adjusting to post-thesis life. My PhD thesis revisions have been accepted and my thesis is now available from Newcastle University Library's eThesis repository. As part of submitting my corrections, I wrote a brief report detailing the changes I made from my thesis at the time of the viva. I also produced a latexdiff marked-up copy of the thesis to visualise the exact changes. In order to shed some light on the post-viva corrections process, at least at my institution, and in the hope that they are some use to someone, I'm sharing those documents:

Kathara Sasikumar: My Journey Through the LFX Linux Kernel Mentorship Program

My Journey Through the LFX Linux Kernel Mentorship Program When I first decided to apply for the Linux Foundation s LFX kernel mentorship program, I knew it would be tough. At the beginning, there were 12 tasks I had to complete to show I understood the basics of kernel development and to get accepted into the program. They helped me understand what I was getting into. Now that the mentorship is almost over, I can say this experience changed how I think about working with the Linux kernel.

Taavi V n nen: How to import a new Wikipedia language edition (in hard mode)

I created the latest Wikipedia language edition, the Toki Pona Wikipedia, last month. Unlike most other wikis which start their lives in the Wikimedia Incubator before the full wiki is created, in this case the community had been using a completely external MediaWiki site to build the wiki before it was approved as a "proper" Wikipedia wiki,1 and now that external wiki needed to be imported to the newly created Wikimedia-hosted wiki. (As far as I'm aware, the last and previously only time an external wiki has been imported to a Wikimedia project was in 2013 when Wikitravel was forked as Wikivoyage.) Creating a Wikimedia wiki these days is actually pretty straightforward, at least when compared to what it used to be like a couple of years ago. Today the process mostly involves using a script to generate two configuration changes, one to add the basic configuration for a wiki to operate and an another to add the wiki to the list of all wikis that exist, and then running a script to create the wiki database in between of deploying those two configuration changes. And then you wait half an hour while the script to tell all Wikidata client wikis about the new wiki runs on one wiki at a time. The primary technical challenge in importing a third-party wiki is that there's no SUL making sure that a single username maps to the same account on both wikis. This means that the usual strategy of using the functionality I wrote in CentralAuth to manually create local accounts can't be used as is, and so we needed to come up with a new way of matching everyone's contributions to their existing Wikimedia accounts. (Side note: While the user-facing interface tries to present a single "global" user account that can be used on all public Wikimedia wikis, in reality the account management layer in CentralAuth is mostly just a glue layer to link together individual "local" accounts on each wiki that the user has ever visited. These local accounts have independent user ID numbers for example I am user #35938993 on the English Wikipedia but #4 on the new Toki Pona Wikipedia and are what most of MediaWiki code interacts with except for a few features specifically designed with cross-wiki usage in mind. This distinction is also still very much present and visible in the various administrative and anti-abuse workflows.) The approach we ended up choosing was to re-write the dump file before importing, so that a hypothetical account called $Name would be turned $Name~wikipesija.org after the import.2 We also created empty user accounts that would take ownership of the edits to be imported so that we could use the standard account management tools on them later on. MediaWiki supports importing contributions without a local account to attribute them to, but it doesn't seem to be possible to convert an imported actor3 to a regular user later on which we wanted to keep as a possibility, even with the minor downside of creating a few hundred users that'll likely never get touched again later. We also made specific decisions to add the username suffix to everyone, not to just those names that'd conflicted with existing SUL accounts, and to deal with renaming users that wanted their contributions linked to an existing SUL account only after the import. This both reduced complexity and thus risk from the import phase, which already had much more unknowns compared to the rest of the process, but also were much better options ethically as well: suffixing all names meant we would not imply that those people chose to be Wikimedians with those specific usernames (when in reality it was us choosing to import those edits to the Wikimedia universe), and doing renames using the standard MediaWiki account management tooling meant that it produced the normal public log entries that all other MediaWiki administrative actions create. With all of the edits imported, the only major thing remaining was doing those merges I mentioned earlier to attribute imported edits to people's existing SUL accounts. Thankfully, the local account -based system makes it actually pretty simple. Usually CentralAuth prevents renaming individual local accounts that are attached to a global account, but that check can be bypassed with a maintenance script or a privileged enough account. Renaming the user automatically detached it from the previous global account, after which an another maintenance script could be used to attach the user to the correct global account.

  1. That external site was a fork of a fork of the original Toki Pona Wikipedia that was closed in 2005. And because cool URIs don't change, we made the the URLs that the old Wikipedia was using work again. Try it: https://art-tokipona.wikipedia.org.
  2. wikipesija.org was the domain where the old third-party wiki was hosted on, and ~ was used as a separator character in usernames during the SUL finalization in the early 2010s so using it here felt appropriate as well.
  3. An actor is a MediaWiki term and a database table referring to anything that can do edits or logged actions. Usually an actor is a user account or an IP address, but an imported user name in a specific format can also be represented as an actor.

4 December 2025

Colin Watson: Free software activity in November 2025

My Debian contributions this month were all sponsored by Freexian. I had a bit less time than usual, because Freexian collaborators gathered in Marseille this month for our yearly sprint, doing some planning for next year. You can also support my work directly via Liberapay or GitHub Sponsors. OpenSSH I began preparing for the second stage of the GSS-API key exchange package split (some details have changed since that message). It seems that we ll need to wait until Ubuntu 26.04 LTS has been released, but that s close enough that it s worth making sure we re ready. This month I just did some packaging cleanups that would otherwise have been annoying to copy, such as removing support for direct upgrades from pre-bookworm. I m considering some other package rearrangements to make the split easier to manage, but haven t made any decisions here yet. This also led me to start on a long-overdue bug triage pass, mainly consisting of applying usertags to lots of our open bugs to sort them by which program they apply to, and also closing a few that have been fixed, since some bugs will eventually need to be reassigned to GSS-API packages and it would be helpful to make them easier to find. At the time of writing, about 30% of the bug list remains to be categorized this way. Python packaging I upgraded these packages to new upstream versions: I packaged django-pgtransaction and backported it to trixie, since we plan to use it in Debusine; and I adopted python-certifi for the Python team. I fixed or helped to fix several other build/test failures: I fixed a couple of other bugs: Other bits and pieces Code reviews

Ben Hutchings: FOSS activity in November 2025

3 December 2025

Reproducible Builds: Reproducible Builds in November 2025

Welcome to the report for November 2025 from the Reproducible Builds project! These monthly reports outline what we ve been up to over the past month, highlighting items of news from elsewhere in the increasingly-important area of software supply-chain security. As always, if you are interested in contributing to the Reproducible Builds project, please see the Contribute page on our website. In this report:

  1. 10 years of Reproducible Build at SeaGL
  2. Distribution work
  3. Tool development
  4. Website updates
  5. Miscellaneous news
  6. Software Supply Chain Security of Web3
  7. Upstream patches

10 years of Reproducible Builds at SeaGL 2025 On Friday 8th November, Chris Lamb gave a talk called 10 years of Reproducible Builds at SeaGL in Seattle, WA. Founded in 2013, SeaGL is a free, grassroots technical summit dedicated to spreading awareness and knowledge about free source software, hardware and culture. Chris talk:
[ ] introduces the concept of reproducible builds, its technical underpinnings and its potentially transformative impact on software security and transparency. It is aimed at developers, security professionals and policy-makers who are concerned with enhancing trust and accountability in our software. It also provides a history of the Reproducible Builds project, which is approximately ten years old. How are we getting on? What have we got left to do? Aren t all the builds reproducible now?

Distribution work In Debian this month, Jochen Sprickerhof created a merge request to replace the use of reprotest in Debian s Salsa Continuous Integration (CI) pipeline with debrebuild. Jochen cites the advantages as being threefold: firstly, that only one extra build needed ; it uses the same sbuild and ccache tooling as the normal build ; and works for any Debian release . The merge request was merged by Emmanuel Arias and is now active. kpcyrd posted to our mailing list announcing the initial release of repro-threshold, which implements an APT transport that defines a threshold of at least X of my N trusted rebuilders need to confirm they reproduced the binary before installing Debian packages. Configuration can be done through a config file, or through a curses-like user interface. Holger then merged two commits by Jochen Sprickerhof in order to address a fakeroot-related reproducibility issue in the debian-installer, and J rg Jaspert deployed a patch by Ivo De Decker for a bug originally filed by Holger in February 2025 related to some Debian packages not being archived on snapshot.debian.org. Elsewhere, Roland Clobus performed some analysis on the live Debian trixie images, which he determined were not reproducible. However, in a follow-up post, Roland happily reports that the issues have been handled. In addition, 145 reviews of Debian packages were added, 12 were updated and 15 were removed this month adding to our knowledge about identified issues. Lastly, Jochen Sprickerhof filed a bug announcing their intention to binary NMU a very large number of the R programming language after a reproducibility-related toolchain bug was fixed.
Bernhard M. Wiedemann posted another openSUSE monthly update for their work there.
Julien Malka and Arnout Engelen launched the new hash collection server for NixOS. Aside from improved reporting to help focus reproducible builds efforts within NixOS, it collects build hashes as individually-signed attestations from independent builders, laying the groundwork for further tooling.

Tool development diffoscope version 307 was uploaded to Debian unstable (as well as version 309). These changes included further attempts to automatically attempt to deploy to PyPI by liaising with the PyPI developers/maintainers (with this experimental feature). [ ][ ][ ] In addition, reprotest versions 0.7.31 and 0.7.32 were uploaded to Debian unstable by Holger Levsen, who also made the following changes:
  • Do not vary the architecture personality if the kernel is not varied. (Thanks to Ra l Cumplido). [ ]
  • Drop the debian/watch file, as Lintian now flags this as error for native Debian packages. [ ][ ]
  • Bump Standards-Version to 4.7.2, with no changes needed. [ ]
  • Drop the Rules-Requires-Root header as it is no longer required.. [ ]
In addition, however, Vagrant Cascadian fixed a build failure by removing some extra whitespace from an older changelog entry. [ ]

Website updates Once again, there were a number of improvements made to our website this month including:

Miscellaneous news

Software Supply Chain Security of Web3 Via our mailing list, Martin Monperrus let us know about their recently-published page on the Software Supply Chain Security of Web3. The abstract of their paper is as follows:
Web3 applications, built on blockchain technology, manage billions of dollars in digital assets through decentralized applications (dApps) and smart contracts. These systems rely on complex, software supply chains that introduce significant security vulnerabilities. This paper examines the software supply chain security challenges unique to the Web3 ecosystem, where traditional Web2 software supply chain problems intersect with the immutable and high-stakes nature of blockchain technology. We analyze the threat landscape and propose mitigation strategies to strengthen the security posture of Web3 systems.
Their paper lists reproducible builds as one of the mitigating strategies. A PDF of the full text is available to download.

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Michael Ablassmeier: libvirt 11.10 VIR_DOMAIN_BACKUP_BEGIN_PRESERVE_SHUTDOWN_DOMAIN

As with libvirt 11.10 a new flag for backup operation has been inroduced: VIR_DOMAIN_BACKUP_BEGIN_PRESERVE_SHUTDOWN_DOMAIN. According to the documentation It instructs libvirt to avoid termination of the VM if the guest OS shuts down while the backup is still running. The VM is in that scenario reset and paused instead of terminated allowing the backup to finish. Once the backup finishes the VM process is terminated. Added support for this in virtnbdbackup 2.40.

2 December 2025

Simon Josefsson: Guix on Trisquel & Ubuntu for Reproducible CI/CD Artifacts

Last week I published Guix on Debian container images that prepared for today s announcement of Guix on Trisquel/Ubuntu container images. I have published images with reasonably modern Guix for Trisquel 11 aramo, Trisquel 12 ecne, Ubuntu 22.04 and Ubuntu 24.04. The Ubuntu images are available for both amd64 and arm64, but unfortunately Trisquel arm64 containers aren t available yet so they are only for amd64. Images for ppc64el and riscv64 are work in progress. The currently supported container names:
registry.gitlab.com/debdistutils/guix/guix-on-dpkg:trisquel11-guix
registry.gitlab.com/debdistutils/guix/guix-on-dpkg:trisquel12-guix
registry.gitlab.com/debdistutils/guix/guix-on-dpkg:ubuntu22.04-guix
registry.gitlab.com/debdistutils/guix/guix-on-dpkg:ubuntu24.04-guix
Or you prefer guix-on-dpkg on Docker Hub:
docker.io/jas4711/guix-on-dpkg:trisquel11-guix
docker.io/jas4711/guix-on-dpkg:trisquel12-guix
docker.io/jas4711/guix-on-dpkg:ubuntu22.04-guix
docker.io/jas4711/guix-on-dpkg:ubuntu24.04-guix
You may use them as follows. See the guix-on-dpkg README for how to start guix-daemon and installing packages.
jas@kaka:~$ podman run -it --hostname guix --rm registry.gitlab.com/debdistutils/guix/guix-on-dpkg:trisquel11-guix
root@guix:/# head -1 /etc/os-release 
NAME="Trisquel GNU/Linux"
root@guix:/# guix describe
  guix 136fc8b
    repository URL: https://gitlab.com/debdistutils/guix/mirror.git
    branch: master
    commit: 136fc8bfe91a64d28b6c54cf8f5930ffe787c16e
root@guix:/# 
You may now be asking yourself: why? Fear not, gentle reader, because having two container images of roughly similar software is a great tool for attempting to build software artifacts reproducible, and comparing the result to spot differences. Obviously. I have been using this pattern to get reproducible tarball artifacts of several software releases for around a year and half, since libntlm 1.8. Let s walk through how to setup a CI/CD pipeline that will build a piece of software, in four different jobs for Trisquel 11/12 and Ubuntu 22.04/24.04. I am in the process of learning Codeberg/Forgejo CI/CD, so I am still using GitLab CI/CD here, but the concepts should be the same regardless of platform. Let s start by defining a job skeleton:
.guile-gnutls: &guile-gnutls
  before_script:
  - /root/.config/guix/current/bin/guix-daemon --version
  - env LC_ALL=C.UTF-8 /root/.config/guix/current/bin/guix-daemon --build-users-group=guixbuild $GUIX_DAEMON_ARGS &
  - GUIX_PROFILE=/root/.config/guix/current; . "$GUIX_PROFILE/etc/profile"
  - type guix
  - guix --version
  - guix describe
  - time guix install --verbosity=0 wget gcc-toolchain autoconf automake libtool gnutls guile pkg-config
  - time apt-get update
  - time apt-get install -y make git texinfo
  - GUIX_PROFILE="/root/.guix-profile"; . "$GUIX_PROFILE/etc/profile"
  script:
  - git clone https://codeberg.org/guile-gnutls/guile-gnutls.git
  - cd guile-gnutls
  - git checkout v5.0.1
  - ./bootstrap
  - ./configure
  - make V=1
  - make V=1 check VERBOSE=t
  - make V=1 dist
  after_script:
  - mkdir -pv out/$CI_JOB_NAME_SLUG/src
  - mv -v guile-gnutls/*-src.tar.* out/$CI_JOB_NAME_SLUG/src/
  - mv -v guile-gnutls/*.tar.* out/$CI_JOB_NAME_SLUG/
  artifacts:
    paths:
    - out/**
This installs some packages, clones guile-gnutls (it could be any project, that s just an example), build it and return tarball artifacts. The artifacts are the git-archive and make dist tarballs. Let s instantiate the skeleton into four jobs, running the Trisquel 11/12 jobs on amd64 and the Ubuntu 22.04/24.04 jobs on arm64 for fun.
guile-gnutls-trisquel11-amd64:
  tags: [ saas-linux-medium-amd64 ]
  image: registry.gitlab.com/debdistutils/guix/guix-on-dpkg:trisquel11-guix
  extends: .guile-gnutls
guile-gnutls-ubuntu22.04-arm64:
  tags: [ saas-linux-medium-arm64 ]
  image: registry.gitlab.com/debdistutils/guix/guix-on-dpkg:ubuntu22.04-guix
  extends: .guile-gnutls
guile-gnutls-trisquel12-amd64:
  tags: [ saas-linux-medium-amd64 ]
  image: registry.gitlab.com/debdistutils/guix/guix-on-dpkg:trisquel12-guix
  extends: .guile-gnutls
guile-gnutls-ubuntu24.04-arm64:
  tags: [ saas-linux-medium-arm64 ]
  image: registry.gitlab.com/debdistutils/guix/guix-on-dpkg:ubuntu24.04-guix
  extends: .guile-gnutls
Running this pipeline will result in artifacts that you want to confirm for reproducibility. Let s add a pipeline job to do the comparison:
guile-gnutls-compare:
  image: alpine:latest
  needs: [ guile-gnutls-trisquel11-amd64,
           guile-gnutls-trisquel12-amd64,
           guile-gnutls-ubuntu22.04-arm64,
           guile-gnutls-ubuntu24.04-arm64 ]
  script:
  - cd out
  - sha256sum */*.tar.* */*/*.tar.*   sort   grep    -- -src.tar.
  - sha256sum */*.tar.* */*/*.tar.*   sort   grep -v -- -src.tar.
  - sha256sum */*.tar.* */*/*.tar.*   sort   uniq -c -w64   sort -rn
  - sha256sum */*.tar.* */*/*.tar.*   grep    -- -src.tar.   sort   uniq -c -w64   grep -v '^      1 '
  - sha256sum */*.tar.* */*/*.tar.*   grep -v -- -src.tar.   sort   uniq -c -w64   grep -v '^      1 '
# Confirm modern git-archive tarball reproducibility
  - cmp guile-gnutls-trisquel12-amd64/src/*.tar.gz guile-gnutls-ubuntu24-04-arm64/src/*.tar.gz
# Confirm old git-archive (export-subst but long git describe) tarball reproducibility
  - cmp guile-gnutls-trisquel11-amd64/src/*.tar.gz guile-gnutls-ubuntu22-04-arm64/src/*.tar.gz
# Confirm 'make dist' generated tarball reproducibility
  - cmp guile-gnutls-trisquel11-amd64/*.tar.gz guile-gnutls-ubuntu22-04-arm64/*.tar.gz
  - cmp guile-gnutls-trisquel12-amd64/*.tar.gz guile-gnutls-ubuntu24-04-arm64/*.tar.gz
  artifacts:
    when: always
    paths:
    - ./out/**
Look how beautiful, almost like ASCII art! The commands print SHA256 checksums of the artifacts, sorted in a couple of ways, and then proceeds to compare relevant artifacts. What would the output of such a run be, you may wonder? You can look for yourself in the guix-on-dpkg pipeline but here is the gist of it:
$ cd out
$ sha256sum */*.tar.* */*/*.tar.*   sort   grep    -- -src.tar.
79bc24143ba083819b36822eacb8f9e15a15a543e1257c53d30204e9ffec7aca  guile-gnutls-trisquel11-amd64/src/guile-gnutls-v5.0.1-src.tar.gz
79bc24143ba083819b36822eacb8f9e15a15a543e1257c53d30204e9ffec7aca  guile-gnutls-ubuntu22-04-arm64/src/guile-gnutls-v5.0.1-src.tar.gz
b190047cee068f6b22a5e8d49ca49a2425ad4593901b9ac8940f8842ba7f164f  guile-gnutls-trisquel12-amd64/src/guile-gnutls-v5.0.1-src.tar.gz
b190047cee068f6b22a5e8d49ca49a2425ad4593901b9ac8940f8842ba7f164f  guile-gnutls-ubuntu24-04-arm64/src/guile-gnutls-v5.0.1-src.tar.gz
$ sha256sum */*.tar.* */*/*.tar.*   sort   grep -v -- -src.tar.
1e8d107ad534b85f30e432d5c98bf599aab5d8db5f996c2530aabe91f203018a  guile-gnutls-trisquel11-amd64/guile-gnutls-5.0.1.tar.gz
1e8d107ad534b85f30e432d5c98bf599aab5d8db5f996c2530aabe91f203018a  guile-gnutls-ubuntu22-04-arm64/guile-gnutls-5.0.1.tar.gz
bc2df2d868f141bca5f3625aa146aa0f24871f6dcf0b48ff497eba3bb5219b84  guile-gnutls-trisquel12-amd64/guile-gnutls-5.0.1.tar.gz
bc2df2d868f141bca5f3625aa146aa0f24871f6dcf0b48ff497eba3bb5219b84  guile-gnutls-ubuntu24-04-arm64/guile-gnutls-5.0.1.tar.gz
$ sha256sum */*.tar.* */*/*.tar.*   sort   uniq -c -w64   sort -rn
      2 bc2df2d868f141bca5f3625aa146aa0f24871f6dcf0b48ff497eba3bb5219b84  guile-gnutls-trisquel12-amd64/guile-gnutls-5.0.1.tar.gz
      2 b190047cee068f6b22a5e8d49ca49a2425ad4593901b9ac8940f8842ba7f164f  guile-gnutls-trisquel12-amd64/src/guile-gnutls-v5.0.1-src.tar.gz
      2 79bc24143ba083819b36822eacb8f9e15a15a543e1257c53d30204e9ffec7aca  guile-gnutls-trisquel11-amd64/src/guile-gnutls-v5.0.1-src.tar.gz
      2 1e8d107ad534b85f30e432d5c98bf599aab5d8db5f996c2530aabe91f203018a  guile-gnutls-trisquel11-amd64/guile-gnutls-5.0.1.tar.gz
$ sha256sum */*.tar.* */*/*.tar.*   grep    -- -src.tar.   sort   uniq -c -w64   grep -v '^      1 '
      2 79bc24143ba083819b36822eacb8f9e15a15a543e1257c53d30204e9ffec7aca  guile-gnutls-trisquel11-amd64/src/guile-gnutls-v5.0.1-src.tar.gz
      2 b190047cee068f6b22a5e8d49ca49a2425ad4593901b9ac8940f8842ba7f164f  guile-gnutls-trisquel12-amd64/src/guile-gnutls-v5.0.1-src.tar.gz
$ sha256sum */*.tar.* */*/*.tar.*   grep -v -- -src.tar.   sort   uniq -c -w64   grep -v '^      1 '
      2 1e8d107ad534b85f30e432d5c98bf599aab5d8db5f996c2530aabe91f203018a  guile-gnutls-trisquel11-amd64/guile-gnutls-5.0.1.tar.gz
      2 bc2df2d868f141bca5f3625aa146aa0f24871f6dcf0b48ff497eba3bb5219b84  guile-gnutls-trisquel12-amd64/guile-gnutls-5.0.1.tar.gz
$ cmp guile-gnutls-trisquel12-amd64/src/*.tar.gz guile-gnutls-ubuntu24-04-arm64/src/*.tar.gz
$ cmp guile-gnutls-trisquel11-amd64/src/*.tar.gz guile-gnutls-ubuntu22-04-arm64/src/*.tar.gz
$ cmp guile-gnutls-trisquel11-amd64/*.tar.gz guile-gnutls-ubuntu22-04-arm64/*.tar.gz
$ cmp guile-gnutls-trisquel12-amd64/*.tar.gz guile-gnutls-ubuntu24-04-arm64/*.tar.gz
That s it for today, but stay tuned for more updates on using Guix in containers, and remember; Happy Hacking!

Dirk Eddelbuettel: duckdb-mlpack 0.0.5: Added kmeans, version helpers, documentation

A new release of the still-recent duckdb extension for mlpack, the C++ header-only library for machine learning, was merged into the duckdb community extensions repo today, and has been updated at its duckdb mlpack extension page. This release 0.0.5 adds one new method: kmeans clustering. We also added two version accessors for both mlpack and armadillo. We found during the work on random forests (added in 0.0.4) that the multithreaded random number generation was not quite right in the respective upstream codes. This has by now been corrected in armadillo 15.2.2 as well as the trunk version of mlpack so if you build with those, and set a seed, then your forests and classification will be stable across reruns. We added a second state variable mlpack_silent that can be used to suppress even the minimal prediction quality summary some methods show, and expanded the documentation. For more details, see the repo for code, issues and more, and the extension page for more about this duckdb community extension.
This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Birger Schacht: Status update, November 2025

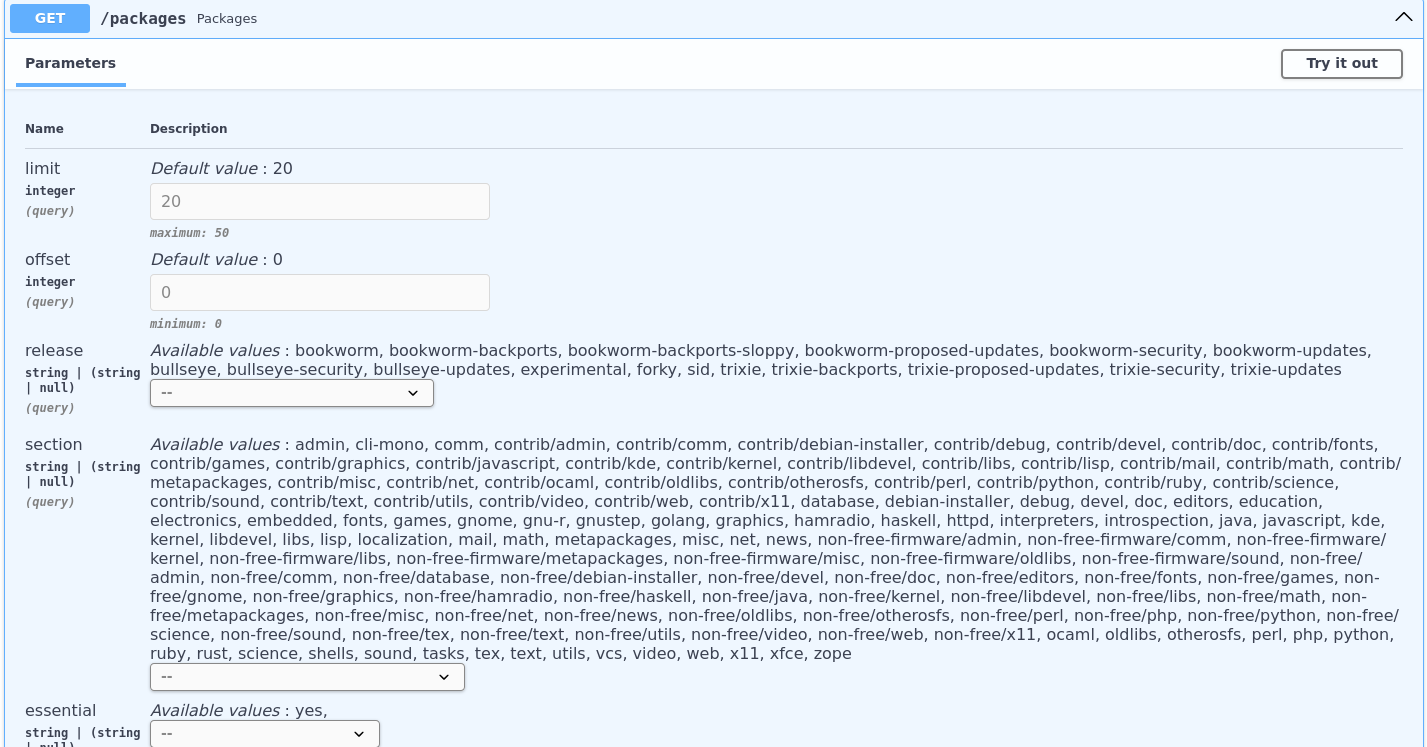
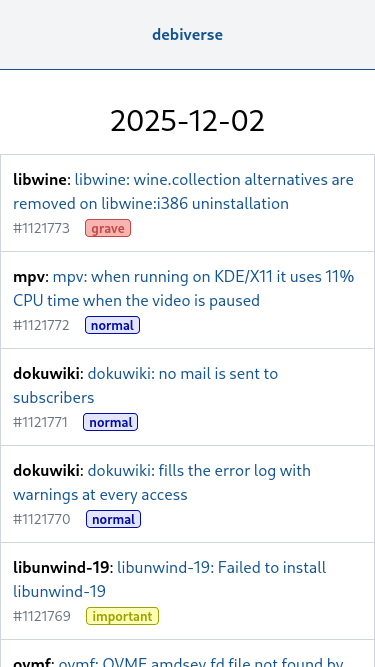
I started this month with a week of vacation which was followed by a small planned surgery and two weeks of sick leave. Nonetheless, I packaged and uploaded new releases of a couple of packages: Besides that I reactivated I project I started in summer 2024: debiverse.org. The idea of that was to have interfaces to Debian bugs and packages that are usable on mobile devices (I know, ludicrous!). Back then I started with Flask and Sqlalchemy, but that soon got out of hand. I now switched the whole stack to FastAPI and SQLModel which makes it a lot easier to manage. And the upside is that it comes with an API and OpenAPI docs. For the rendered HTML pages I use Jinja2 with Tailwind as CSS framework. I am currently using udd-mirror as database backend, which works pretty good (for this single user project). It would be nice to have some of the data in a faster index, like Typesense or Meilisearch. This way it would be possible to have faceted search or more performant full text search. But I haven t found any software that could provide this that is packaged in Debian.
Screenshot of the debiverse bug report list Screenshot of the debiverse swagger API

Fran ois Marier: Recovering from a broken update on the Turris Omnia

The recent Turris OS update from 7.2.3 to 9.0.0 took down my WiFi entirely. The wired network still works fine, but wireless is completely broken.

Factory reset It turns out the Omnia has an extensive (and fast) factory reset / recovery mode via the hardware reset button. Unfortunately, the factory image didn't work for me, possibly because I don't use the stock WiFi radios anymore.

Rolling back with schnapps Thanks to the fact that the Omnia uses a btrfs root filesystem, and the liberal use of snapshots around updates, I was able to rollback to the pre-9.0.0 state. First, I connected to the router using ssh:
ssh root@192.168.1.1
Then I listed the available snapshots:
$ schnapps list
#   Type        Size          Date                          Description
------+-----------+-------------+-----------------------------+------------------------------------
  500   post           15.98MiB   2025-08-09 11:27:48 -0700     Automatic post-update snapshot (TurrisOS 7.2.2 - hbs)
  506   pre            17.92MiB   2025-09-12 03:44:32 -0700     Automatic pre-update snapshot (TurrisOS 7.2.2 - hbs)
  507   post           17.88MiB   2025-09-12 03:45:14 -0700     Automatic post-update snapshot (TurrisOS 7.2.3 - hbs)
  515   time           20.03MiB   2025-11-02 01:05:01 -0700     Snapshot created by cron
  516   time           20.05MiB   2025-11-09 01:05:01 -0800     Snapshot created by cron
  517   time           20.29MiB   2025-11-16 01:05:00 -0800     Snapshot created by cron
  518   time           20.64MiB   2025-11-23 01:05:01 -0800     Snapshot created by cron
  519   time           20.83MiB   2025-11-30 01:05:00 -0800     Snapshot created by cron
  520   pre            87.91MiB   2025-11-30 07:41:10 -0800     Automatic pre-update snapshot (TurrisOS 7.2.3 - hbs)
  521   post          196.32MiB   2025-11-30 07:48:11 -0800     Automatic post-update snapshot (TurrisOS 9.0.0 - hbs)
  523   pre             4.44MiB   2025-11-30 20:47:31 -0800     Automatic pre-update snapshot
  524   post          224.00KiB   2025-11-30 20:47:43 -0800     Automatic post-update snapshot
  525   rollback      224.00KiB   2025-12-01 04:56:32 +0000     Rollback to snapshot factory
  526   pre             4.44MiB   2025-11-30 21:04:19 -0800     Automatic pre-update snapshot
  527   post          272.00KiB   2025-11-30 21:04:31 -0800     Automatic post-update snapshot
  528   rollback      272.00KiB   2025-12-01 05:13:38 +0000     Rollback to snapshot factory
  529   pre             4.52MiB   2025-11-30 21:28:44 -0800     Automatic pre-update snapshot
  530   single        208.00KiB                                 
  531   rollback      224.00KiB   2025-12-01 05:29:47 +0000     Rollback to snapshot factory
Finally, I rolled back to the exact state I was on before the 9.0.0 update:
$ schnapps rollback 520
Current state saved as snapshot number 532
Rolled back to snapshot 520

Full wipe As an aside, it turns out that the factory reset functionality is implemented as a brtfs rollback to a special factory snapshot. This is why is so fast, but it also means that doing a simple factory reset doesn't wipe the data on your router. If you are planning to sell your device or otherwise dispose of it, you also need to delete all btrfs snapshots

Conclusion While this update was very disappointing, especially since it's never happened before with major updates on Turris OS, it made me discover just how great the recovery tools are. It would be pretty tricky to fully brick one of these devices.

1 December 2025

Guido G nther: Free Software Activities November 2025

Another short status update of what happened on my side last month. Hand holding the release machinery for Phosh 0.51.0 but there's more: See below for details on the above and more: phosh phoc phosh-mobile-settings stevia xdg-desktop-portal-phosh pfs Phrog gmobile feedbackd feedbackd-device-themes libcall-ui wirepumber Chatty mobile-broadband-povider-info Debian Mobian wlroots libqrtr-glib libadwaits-rs phosh-site bengalos-debs gtk Reviews This is not code by me but reviews on other peoples code. The list is (as usual) slightly incomplete. Thanks for the contributions! Help Development If you want to support my work see donations. Comments? Join the Fediverse thread

Next.

Previous.