Search Results: "tar"

8 September 2013

Paul Tagliamonte: libolla (src:olla) in experimental

It s been a long time since I last talked about libolla, but it s one of those things I use everywhere and never bothered to
package up and upload. Well. I packaged it. And uploaded it. Finally. Now, let s look at the new quickstart guide: (this assumes you use bash, since I decided to abuse bash_completions to insert an LD_PRELOAD. I know this is gross, but I totally need a better idea) Now, look on in dumbfounded obviousness as I show you what doesn t work:
$ ssh master.d.o
ssh: Could not resolve hostname master.d.o: Name or service not known
Sadsies. Now, let s make it work:
$ ssh master.d.o whoami
ssh: Could not resolve hostname master.d.o: Name or service not known
$ sudo apt-get install -t experimental olla
# (restart your terminal)
$ ssh master.d.o whoami
paultag
Thank you, thank you! I ll be here all week! Anyway. Have fun, kids! Remember, hacks are fun!

7 September 2013

Daniel Pocock: Evacuating Australia

With the news that Australia's 100mbit (and potentially gigabit) fibre to the home is to be abolished and replaced with a cheap 25mbps service using Europe's ADSL hand-me-downs (which will be obsolete in 5 years when the deployment is finished), I've had quite a few emails from people asking just how easy it is to move abroad.
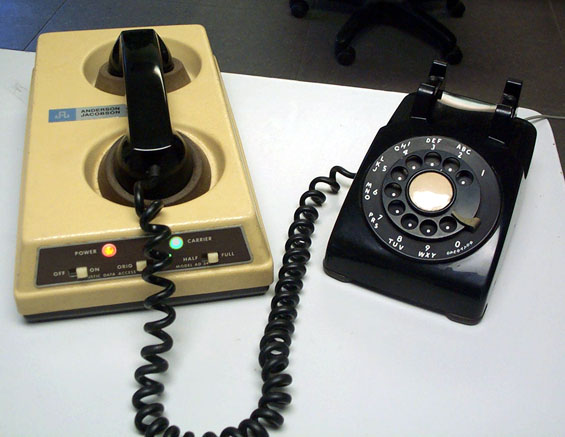
The acoustic modem has a nice retro look Word has got out that I've been spending some time in Switzerland enjoying the world-beating rate of IPv6 deployment. That is not the only reason to leave Australia of course, nor is it the only criteria for people choosing which country will give them a better deal than either of the two non-choices we had in Australia's elections. A free $20,000 for leaving Australia The first good news is that any recent graduate with a big bad ugly HECS bill is only obliged to pay this extra tax when they earn a salary from an Australian employer and file an Australian tax return. Australians who live abroad are not automatically obliged to file tax returns and are not slogged with this extra tax for having attended university. If somebody just graduated and has this hanging over their head, or if they've just started working and seen how much is being deducted on the payslip, moving abroad could make a lot of sense financially. If you have any moral qualms about this, just reflect on the fact that while the Government intimidates students with the feeling that they have to "pay" for fulfilling an education that makes them into a productive member of society, thousands of would-be athletes are given money with no obligation to repay it. The easiest route: a second passport One in four Australians has a parent born abroad. Most of those people qualify for a passport from their parent's country of birth. In some cases this also applies to people with grandparents born abroad. With the European Union now spanning 28 countries and guaranteeing the rights of any citizen from any country to live, work and study in any of the other 27 countries, a passport from any of the EU countries gives a lot of choices, including places where I have lived myself such as the UK, Ireland, France and Switzerland. Europe's citizen-friendly immigration In other words, an Australian with an Italian parent can go up to the Italian embassy in Canberra, collect an Italian passport and immediately fly into London and start working there with no bureaucratic delays, invasive and degrading medical checks or other Government interference in their life.
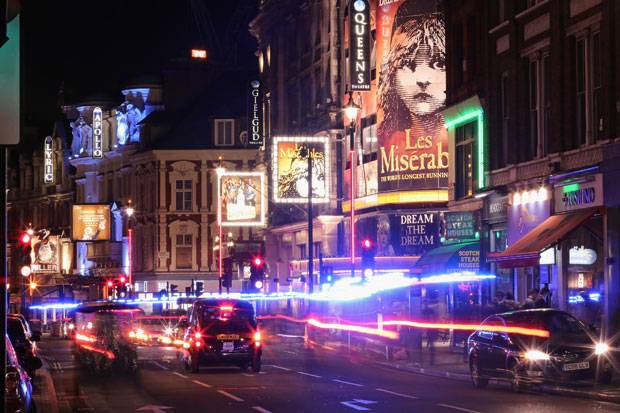
London's nightlife is popular for Australians. The UK started rolling out their high speed 21CN many years before Australia started the NBN. The rights also transfer automatically to all family members (spouse and children) - an Australian with a second passport is not restricted to living in Australia simply because they are married to somebody who does not have a second passport. As long as they arrive together at a European airport, they can simply show a marriage/birth certificate (in any language) and cross the border immediately, enjoy the same rights as a citizen, including work, study, healthcare and better broadband. No paperwork is necessary, no cottage industry for otherwise unemployable immigration agents, these are basic human rights for those living in Europe.
Eiffel tower: potentially part of the wireless network for France's new 4G internet, potentially two to four times the fixed-line speed planned for Australia's crippled broadband Uncle Sam wants more Australians Although it is not widely known, the US has a fast lane for immigration from Australia. The regular programs for skilled visas in the US are usually exhausted every year, whereas 10,000 "E3" class visas for Australians are never fully taken in any year. Surely it's not that easy to go to the US? It is. To qualify, an Australian only needs a university degree and a suitable job offer. Although the visa is for 2 years, it can be renewed and Australians who meet and marry an American have in various cases have gained full residence or citizenship. Anything is possible, you could even end up becoming a NASA Astronaut.
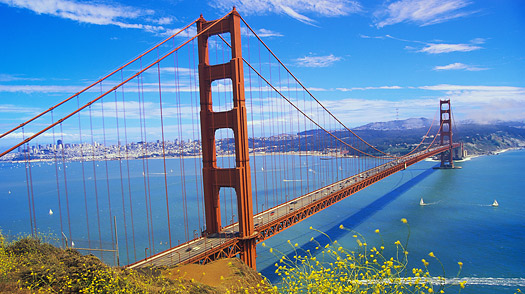
San Francisco, home to leading technology professionals and innovators from many countries. Some US cities such as Austin and Kansas City have let Google install fibre to the home, San Francisco could follow Working holiday schemes are not just for Britain Most Australians know somebody who went to London on a "working holiday" visa. These visas are not just for the UK and Australia has similar reciprocal programs with many other countries too. These rules for these schemes are rooted in the industrial age concept of workers with punch cards. Participants are typically limited to work 20 hours per week. Of particular interest for those in IT, such rules are hard to quantify for freelancers, web designers or creative people who earn their living charging fees per-project or undertaking management work without specified working hours. Although the visas are limited to 4 years, I've heard of Australians benefiting from the open borders of mainland Europe, spending 4 years in one country and then obtaining another 4 year visa for an adjacent country and travelling freely back and forth, building up a business and lifestyle of their own design. Singapore and Hong Kong Singapore and Hong Kong have become enormously popular destinations for Australians, particularly those with special skills in IT, finance, engineering and international business.
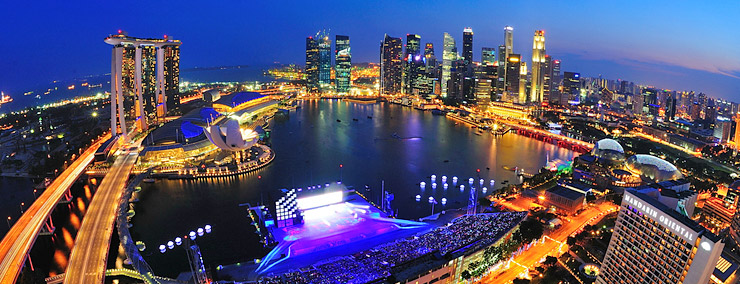
Singapore is respected as one of the cleanest and most orderly cities in Asia while embracing significant diversity in dining, shopping, leisure and lifestyle possibilities. They have recently boosted speeds to help people get a full 100MBit over fibre. A SIM card with high speed broadband charges SGD 7 (about $5) for 1 Gigabyte. These are not necessarily destinations that a graduate can easily move to. People are measured by their salary and the Government simply assumes that anybody earning a high salary is going to make a valuable contribution to society and they are given a visa in 1 or 2 weeks. Usually 3-5 years employment experience is required before making a move to one of these countries. The Not Ordinarily Resident (NOR) scheme gives some hints about the minimum salary level that ex-pats aim for, many earn significantly more with bonuses, stock programs and properly engineered tax-free offshore pension arrangements. These countries offer particularly low taxes (around 10%) and great technology. They have some rough edges too: like Europe, spouses are automatically given a visa too, but in contrast, their visa does not permit them to work unless they also work in a profession that is highly paid. Visas are issued quickly but they are also canceled very quickly if the job is terminated or the company goes bust. There have been various stories of people paying the typical 2-month deposit on an appartment in Singapore and then finding that it is forfeited when their job and visa are canceled and they have 4 weeks to leave. The bottom line is that people moving to these locations usually have a wide professional network and confidence to change their job quickly if necessary. Freestyle immigration and the visa run Not too long ago I was at a house party in Prague, Czech Republic, which is like a Paris of eastern Europe. Somebody introduced me to some Americans who I was told had similar interests in technology. They were operating an offshore web site and living very well. They had spent 10 years in Prague living on tourist visas. Authorities seemed quite happy for them to remain as long as they left every 3 months and spent 1 night abroad, a typical visa run. That could be as simple as a train journey to Vienna, Austria and an overnight stay.
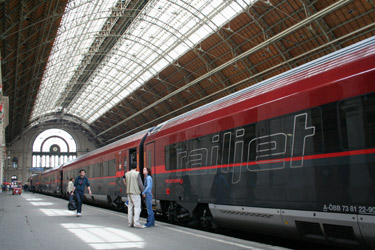
Making a visa run in comfort and style with European railways. The Railjet train pictured includes free wifi, a lot cheaper than the $20 billion Tony Abbott plans to spend rolling out yesterday's technology in Australia When European countries abolished border controls, this system became much more convoluted for those who depend on the visa run. However, it remains common in many Asian and Latin American countries and many ex-pats live this way. Officials in many of these medium sized economies recognise the value of people bringing in money from offshore business (such as web sites) and using it to pay rent, food and local services. To make this effective, the ex-pats typically need to have an international private health insurance policy (high quality offshore policies can be found quickly with a search engine) and not aspire to work in a normal 9-5 job. Conclusion Young Australians might not want to just consider travel, it may even become unavoidable. The reality is, by 2020, one in three Australians will be a retired baby boomer and one way or another, whichever Government is in office will be unable to avoid taxing those of working age to pay for the health care and pension promises made to older generations. Serious expenditure on public infrastructure such as broadband or high speed rail appears to remain a pipe dream. Moving abroad, however, is just so much fun. Look at the way multinational companies make countries compete to attract their new factories and other projects: why should any individual citizen be any less demanding in choosing where they work, play and get the best value for whatever taxes they have to pay? Some people raise questions of patriotism or responsibility to the nation. Think again. The 200,000 Australians who live abroad or travel extensively make a significant contribution to Australia's international profile, engage in new trade initiatives, bring skills back to Australia and generally represent what our country is really about much better than some of those who are paid to do so.

Ben Armstrong: Wifi roaming on the move redux

It has been nearly six years with a netbook and five since I last wrote about wifi roaming from the bus to stay on irc without a costly celluar link during the daily commute. Since then, some readers have asked me to share my refinements to the method in a followup post. So here it is. The software On the server: On the client: Putting it together: on the client Make sure if you have a wireless manager installed (such as NetworkManager) it is configured to skip your wireless interface, disabled entirely, or if possible, removed. Set up /etc/wpa_supplicant/wpa_supplicant.conf and /etc/network/interfaces for roaming, as per the instructions in /usr/share/doc/wpasupplicant/README.modes.gz. Don t forget to add yourself to the netdev group if you are not in it already. In /etc/wpa_supplicant/wpa_supplicant.conf, list common names of open networks. Normally the catch-all network that associates with any essid, i.e. the first stanza below, works well. However, occasionally the strongest signal is neither one of the common networks nor an easily accessible network (e.g. web portals), so having a list of common open networks helps to quickly select from among those instead. The more you travel, the more of these will discover and add. Just use reconfigure from wpa_cli to reload your edited list each time you add a new one.
ctrl_interface=DIR=/var/run/wpa_supplicant GROUP=netdev
network= 
        key_mgmt=NONE
 
network= 
        ssid="default"
        key_mgmt=NONE
 
network= 
        ssid="linksys"
        key_mgmt=NONE
 
...
Since you ll be using ssh repeatedly to connect and it has to be fast, make sure your server is set up to accept your key and use ssh-add so that you only have to enter your ssh key password once. You can tweak isc-dhcp-client to make connections faster. In /etc/dhcp/dhclient.conf, use:
backoff-cutoff 1;
initial-interval 1;
Here are a few scripts I wrote to facilitate quick roaming from one open AP to another and reconnect to irssi running in screen, to break a connection and try the next one, and to recover from occasional lockups (more about that later). ~/bin/screen_reconnect This is a script to reconnect continuously via ssh to a screen session:
#!/bin/sh
reset
while ! ssh -t 10.9.8.7 'screen -UDr' 2>/dev/null ; do echo -n "." ; sleep .1 ; done
Just substitute the IP of your own server here. Using an IP instead of domain name makes the connection faster because a DNS lookup is not required. ~/bin/wifi_reassociate This script closes any open ssh sessions and informs wpa_supplicant to attempt to connect again.
#/bin/sh
/sbin/wpa_cli rea
killall ssh >/dev/null 2>&1
~/bin/wifi_killall This optional, somewhat ugly script addresses an issue I hope you never have. On my ASUS Eee PC 1001PX, occasionally scanning stops. When this happens, and I have never figured out why, apparently ACPI events are blocked. At this point wifi becomes unusable and ACPI sleep is inhibited. By trial and error I found that if you bring down the interface, kill all network-related processes, and bring it up again, ACPI events are unblocked and wifi is usable once more (and any pending request to sleep will finally happen). The script requires sudo, and to use the openbox key binding, gksudo.
#/bin/sh
sudo ifdown wlan0
# in case any of these are hung
sudo killall dhclient3
sudo killall wpa_cli
sudo killall wpa_action
sudo killall wpa_supplicant
# in case any of these are *really* hung
sleep 1
sudo killall -9 dhclient3
sudo killall -9 wpa_cli
sudo killall -9 wpa_action
sudo killall -9 wpa_supplicant
sudo dhclient -r
sudo ifup wlan0
Openbox Since certain actions need to be performed repeatedly and quickly, it is useful to have hotkeys bound in your window manager to the scripts. In ~/.config/openbox/rc.xml, key bindings for <alt>-r to reassociate and <alt>-d to disconnect a hung connection would look like:
  
<keyboard>
  <!-- My keybindings -->
  <keybind key="A-R">
    <action name="Execute">
        <execute>/home/synrg/bin/wifi_reassociate</execute>
    </action>
  </keybind>
  <keybind key="A-D">
    <action name="Execute">
        <execute>gksudo /home/synrg/bin/wifi_killall</execute>
    </action>
  </keybind>
</keyboard>
Putting it together: on the server There is very little to do here. Just start screen, and start irssi in screen. Running screen on the client as well as the server means you should either bind the screen meta keys to a different key sequence on each system, or else learn to press meta twice to pass through meta to the server screen as needed. I use the latter approach. Alternatively, you could use a tabbed terminal on the client, or separate terminals per client process instead of screen. This is a matter of personal taste. Ready to roam Here is a typical setup for roaming on the bus: In a terminal (I use urxvt), first ssh-add, then start screen with these three processes running in separate virtual terminals: March of the dots Most of the commute, just enjoy watching the dots march by, waiting for a new connection. If you estimate a connection is unusable, press <alt>-r to reassociate immediately, giving the next network a chance. If the connection is already firmly established, this might not work on the first try. If the dots don t resume immediately, wait a bit and press it again. This might take a few tries. Changing selected networks on the fly Use wpa_cli when you need to do some fine-tuning of network selections on the fly. While normally you can just watch the march of the dots until a connection is acquired, sometimes you can improve your chances of connecting to a good network by manually controlling the selected candidate networks here. For example, by watching the speed of the bus relative to known good APs, you can predict which networks are more likely to succeed. Rather than connect to any arbitrary network, you might select a specific one by id, and then later when it goes out of range, revert to the original configuration, e.g.
> select_network 5
...
> reconfigure
You can use tab-completion in wpa_cli to type these commands quickly or else just abbreviate the commands. Another common scenario is when you pass through a business area with many captive portal hotspots. These rarely make good choices because they either require a password not known to you or else you can t click through I agree in time before the bus moves on. In this case, you might just disable the catch-all stanza and let the common open network stanzas you listed ( default , linksys , etc.) do the work:
> disable_network 1
Become a type ahead wizard While running, a continuous stream of periods fills the screen, which provides you with a highly visible cue that no available APs are in range. When the movement stops, you know a connection is being attempted. While waiting to connect, you can type ahead any comments you want to make in the current irssi window (taking care to remember which one you are in!) While having periods interspersed in what you type may be disorienting at first, you get used to it. There is a point when a connection is first established and ssh is accepting input, but anything you type can no longer be seen while you re typing. Depending on whether the connection was completely successful or not, what you type now may or may not finally be sent. For best results, only type ahead before the dots stop moving. Eventually you can become skilled enough at this to type ahead a comment in one channel, switch channels with /win # and continue typing ahead in the new channel, all buffered until the next few seconds (or even fraction of a second) of connection time. Fine-tune antenna direction with wavemon When the bus has come to a standstill, you may find wavemon useful to pull in a weak signal. Because wavemon has continuously updated signal level and link quality bars, you can use it to fine-tune the antenna position. Just turn your laptop until the bars are at their maximum. Captive portals I have not figured out how to do any automation for this, so it really is a crapshoot, as it is likely the bus has moved on by the time you ve managed to manually navigate the login through a captive portal. But in rush hour, you may have the luxury of time to connect to these as you pass them. I have recently learned about the CoovaFX Firefox plugin which automates logins to captive portals. I m going to give it a try to see if it helps. Update: I can t recommend this plugin, as it is not compatible with Iceweasel >= 23.0. Also, the standard it is based on, WISPr, appears to have an uncertain future. That, coupled with the fact that the plugin appears to not be open source means I m still looking for alternatives. Summary If all of this sounds a bit nuts to you, well, it probably is. But after half a decade enjoying free access to irc from the bus, it all seems perfectly natural to me! If you try this method and like it, please let me know in the comments. Likewise, if you have any improvements to the process or scripts, please share them!

6 September 2013

Sylvain Le Gall: OUnit 2.0 progress, August 2013

After a long pause, I have resumed my work on OUnit2. It is going quite well. The basic features: I still need to do the following: There is still a lot of work, but the current results are already quite good. The speed improvement of the processes runner is a good thing to shorten test timing (HINT: tester needed!). Focus on: the new bracket. In OUnit 1, a bracket was very functional:
 bracket 
    (fun () -> "foo")  (* setup *)
    (fun foo -> ())
    (fun foo -> ())  (* tear down *)
So for common bracket, like bracket_tmpfile
   bracket_tmpfile
       (fun (fn, chn) ->
             (* Do something with chn and fn *)
The problem is that if you were using 2 or 3 temporary files, the level of indentation was high. I have decide to switch to a more imperative approach, registering the tear down function inside the test context:
   let (fn1, chn1) = bracket_tmpfile ctxt in
   let (fn2, chn2) = bracket_tmpfile ctxt in
      ....
This is shorter and clearer (albeit less functional). Focus on: non fatal section Sometimes, you want to verify a set of properties but to have a clear vision of what is going wrong, you need to do more than one assert. In OUnit1, you can do:
 assert_equal exp1 v1;
 assert_equal exp2 v2
But if exp1 <> v1, you quit immediately and you'll never know for exp2 and v2. In OUnit2, you can do:
 non_fatal ctxt (fun ctxt -> assert_equal exp1 v1);
 non_fatal ctxt (fun ctxt -> assert_equal exp2 v2)
In this new version, you will test both equality and the result of the test will be the worst failure you get (or success if both of them succeed). Help wanted If you have a long standing issue with OUnit, this is the time to submit a bug. OUnit BTS If you want to try the dev version of OUnit:
 $> darcs get http://forge.ocamlcore.org/anonscm/darcs/ounit/ounit
Patches always welcome. Special thanks to Thomas Wickham who has entirely written OUnitRunnerThreads and kickstarted the processes runner.

Justus Winter: cgroupfs keeps track of processes

Tl;dr!!elfel1 Screenshot (slightly edited and annotated shell trace):
+ settrans -ca /cgroup /hurd/cgroupfs
+ mkdir /cgroup/init /cgroup/rootfs
+ echo $$ >> /cgroup/init/tasks  # $$ is 6
+ echo 3 >> /cgroup/rootfs/tasks # pid 3 is the root filesystem
+ sleep 1m & echo sleep has pid $!
sleep has pid 16
+ cat /proc/cmdline > /dev/null
+ tail /cgroup/init/tasks /cgroup/rootfs/tasks
==> /cgroup/init/tasks <==
6
16
20
==> /cgroup/rootfs/tasks <==
3
19
17
+ pstree -p
init(1)-+-auth(5)
         -cgroupfs(14)
         -ext2fs(3)-+-exec(4)
                     -null(17)
                     -pflocal(8)
                     -procfs(19)
                     -term(7)
         -mach-defpager(10)
         -root=device:hd0s1(2)
         -sh(6)-+-pstree(21)
                 -sleep(16)
Isn't she a beauty? So we bind the cgroupfs translator to /cgroup, create two cgroups, init and rootfs, move the currently executing shell script (that later execs sysvinit) into the former and the root filesystem translator into the latter cgroup. We then spawn a sleep process and cat the content of /proc/cmdline into /dev/null which will make the root filesystem start the /hurd/procfs and the /hurd/null translator. We then inspect /cgroup/ init,rootfs /tasks and find indeed all the newly spawned processes in the cgroup their parent process was in. This is accomplished by: I also filed a bug report containing my patches for the sysvinit package (#721917). This is the second bug report I filed during my gsoc, the first one was for the ifupdown package (#720531) which Andrew Shadura improved and merged on the very next day, thanks Andrew! Next week I'll continue to improve the cgroupfs translator, work on the notification prototype (hopefully fixing non-root subhurds in the process, this requires a similar notification mechanism for newly created tasks and making /hurd/proc just a little subhurd aware) and trying to get my gnumach patch into a working shape (currently the parental relation of processes is a Hurd-only concept and relies upon processes telling the /hurd/proc server that a newly created process is their child. This is automatically done if the process uses fork(2) of course, but not if it uses task_create to start a new Mach task).

Vincent Bernat: High availability with ExaBGP

When it comes to provide redundant services, several options are available: A common setup is a combination of those solutions: web servers are behind a couple of load-balancers achieving both redundancy and load-balancing. The load-balancers use VRRP to ensure redundancy. The whole setup is replicated to another datacenter and round-robin DNS is used to ensure both redundancy and load-balacing of the datacenters. There is a fourth option which is similar to VRRP but relies on dynamic routing and therefore is not limited to nodes in the same subnet: We will explore how to implement this fourth option using ExaBGP, the BGP swiss army knife of networking, in a small lab based on KVM. You can grab the complete lab from GitHub. ExaBGP 3.2.5 is needed to run this lab.

Environment We will be working in the following (IPv6-only) environment: Lab with three web nodes

BGP configuration BGP is enabled on ER2 and ER3 to exchange routes with peers and transits (only R1 for this lab). BIRD is used as a BGP daemon. Its configuration is pretty basic. Here is a fragment:
router id 1.1.1.2;
protocol static NETS   #  
  import all;
  export none;
  route 2001:db8::/40 reject;
 
protocol bgp R1   #  
  import all;
  export where proto = "NETS";
  local as 64496;
  neighbor 2001:db8:1000::1 as 64511;
 
protocol bgp ER3   #  
  import all;
  export all;
  next hop self;
  local as 64496;
  neighbor 2001:db8:1::3 as 64496;
 
First, in , we declare the routes that we want to export to our peers. We don t try to summarize them from the IGP. We just unconditonnaly export the networks that we own. Then, in , R1 is defined as a neighbor and we export the static route we declared previously. We import any route that R1 is willing to send us. In , we share everything we know with our pal, ER3, using internal BGP.

OSPF configuration OSPF will distribute routes inside the AS. It is enabled on ER2, ER3, DR6, DR7 and DR8. For example, here is the relevant part of the configuration of DR6:
router id 1.1.1.6;
protocol kernel  
   persist;
   import none;
   export all;
 
protocol ospf INTERNAL  
  import all;
  export none;
  area 0.0.0.0  
    networks  
      2001:db8:1::/64;
      2001:db8:6::/64;
     ;
    interface "eth0";
    interface "eth1"   stub yes;  ;
   ;
 
ER2 and ER3 inject a default route into OSPF:
protocol static DEFAULT  
  import all;
  export none;
  route ::/0 via 2001:db8:1000::1;
 
filter default_route  
  if proto = "DEFAULT" then accept;
  reject;
 
protocol ospf INTERNAL  
  import all;
  export filter default_route;
  area 0.0.0.0  
    networks  
      2001:db8:1::/64;
     ;
    interface "eth1";
   ;
 

Web nodes The web nodes are pretty basic. They have a default static route to the nearest router and that s all. The interesting thing here is that they are each on a separate IP subnet: we cannot share an IP using VRRP2. Why are those web servers on different subnets? Maybe they are not in the same datacenter or maybe your network architecture is using a routed access layer. Let s see how to use BGP to enable redundancy of those web nodes.

Redundancy with ExaBGP ExaBGP is a convenient tool to plug scripts into BGP. They can then receive and advertise routes. ExaBGP does the hard work of speaking BGP with your routers. The scripts just have to read routes from standard input or advertise them on standard output.

The big picture Here is the big picture: Using ExaBGP to advertise web services Let s explain it step by step:
  1. Three IP addresses will be allocated for our web service: 2001:db8:30::1, 2001:db8:30::2 and 2001:db8:30::3. Those are distinct from the real IP addresses of W1, W2 and W3.
  2. Each web node will advertise all of them to the route servers we added in the network. I will talk more about those route servers later.
  3. Each route comes with a metric to help the route server choose where it should be routed. We choose the metrics such that each IP address will be routed to a distinct web node (unless there is a problem).
  4. The route servers (which are not routers) will then advertise the best routes they learned to all the routers in our network. This is still done using BGP.
  5. Now, for a given IP address, each router knows to which web node the traffic should be directed.
Here are the respective metrics announced routes for W1, W2 and W3 when everything works as expected:
Route W1 W2 W3 Best Backup
2001:db8:30::1 102 101 100 W3 W2
2001:db8:30::2 101 100 102 W2 W1
2001:db8:30::3 100 102 101 W1 W3

ExaBGP configuration The configuration of ExaBGP is quite simple:
group rs  
  neighbor 2001:db8:1::4  
    router-id 1.1.1.11;
    local-address 2001:db8:6::11;
    local-as 65001;
    peer-as 65002;
   
  neighbor 2001:db8:8::5  
    router-id 1.1.1.11;
    local-address 2001:db8:6::11;
    local-as 65001;
    peer-as 65002;
   
  process watch-nginx  
      run /usr/bin/python /lab/healthcheck.py -s --config /lab/healthcheck-nginx.conf --start-ip 0;
   
 
A script is entailed to check if the service (an nginx web server) is up and running and advertise the appropriate IP addresses to the two declared route servers. If we run the script manually, we can see the advertised routes:
$ python /lab/healthcheck.py --config /lab/healthcheck-nginx.conf --start-ip 0
INFO[healthcheck] send announces for UP state to ExaBGP
announce route 2001:db8:30::3/128 next-hop self med 100
announce route 2001:db8:30::2/128 next-hop self med 101
announce route 2001:db8:30::1/128 next-hop self med 102
[...]
WARNING[healthcheck] Check command was unsuccessful: 7
INFO[healthcheck] Output of check command:  curl: (7) Failed connect to ip6-localhost:80; Connection refused
WARNING[healthcheck] Check command was unsuccessful: 7
INFO[healthcheck] Output of check command:  curl: (7) Failed connect to ip6-localhost:80; Connection refused
WARNING[healthcheck] Check command was unsuccessful: 7
INFO[healthcheck] Output of check command:  curl: (7) Failed connect to ip6-localhost:80; Connection refused
INFO[healthcheck] send announces for DOWN state to ExaBGP
announce route 2001:db8:30::3/128 next-hop self med 1000
announce route 2001:db8:30::2/128 next-hop self med 1001
announce route 2001:db8:30::1/128 next-hop self med 1002
When the service becomes unresponsive, the healthcheck script detect the situation and retry several times before acknowledging that the service is dead. Then, the IP addresses are advertised with higher metrics and the service will be routed to another node (the one advertising 2001:db8:30::3/128 with metric 101). This healthcheck script is now part of ExaBGP.

Route servers We could have connected our ExaBGP servers directly to each router. However, if you have 20 routers and 10 web servers, you now have to manage a mesh of 200 sessions. The route servers are here for three purposes:
  1. Reduce the number of BGP sessions (from 200 to 60) between equipments (less configuration, less errors).
  2. Avoid modifying the configuration on routers each time a new service is added.
  3. Separate the routing decision (the route servers) from the routing process (the routers).
You may also ask yourself: why not use OSPF? . Good question!
  • OSPF could be enabled on each web node and the IP addresses advertised using this protocol. However, OSPF has several drawbacks: it does not scale, there are restrictions on the allowed topologies, it is difficult to filter routes inside OSPF and a misconfiguration will likely impact the whole network. Therefore, it is considered a good practice to limit OSPF to network equipments.
  • The routes learned by the route servers could be injected into OSPF. On paper, OSPF has a next-hop field to provide an explicit next-hop. This would be handy as we wouldn t have to configure adjacencies with each router. However, I have absolutely no idea how to inject BGP next-hop into OSPF next-hop. What happens is that BGP next-hop is resolved locally using OSPF routes. For example, if we inject BGP routes into OSPF from RS4, RS4 will know the appropriate next-hop but other routers will route the traffic to RS4.
Let s look at how to configure our route servers. RS4 will use BIRD while RS5 will use Quagga. Using two different implementations will help with resiliency by avoiding a bug to hit the two route servers at the same time.

Bird configuration There are two sides for BGP configuration: the BGP sessions with the ExaBGP nodes and the ones with the routers. Here is the configuration for the later:
template bgp INFRABGP  
  export all;
  import none;
  local as 65002;
  rs client;
 
protocol bgp ER2 from INFRABGP  
  neighbor 2001:db8:1::2 as 65003;
 
protocol bgp ER3 from INFRABGP  
  neighbor 2001:db8:1::3 as 65003;
 
protocol bgp DR6 from INFRABGP  
  neighbor 2001:db8:1::6 as 65003;
 
protocol bgp DR7 from INFRABGP  
  neighbor 2001:db8:1::7 as 65003;
 
protocol bgp DR8 from INFRABGP  
  neighbor 2001:db8:1::8 as 65003;
 
The AS number used by our route server is 65002 while the AS number used for routers is 65003 (the AS numbers for web nodes will be 65001). They are reserved for private use by RFC 6996. All routes known by the route server are exported to the routers but no routes are accepted from them. Let s have a look at the other side:
# Only import loopback IPs
filter only_loopbacks   #  
  if net ~ [ 2001:db8:30::/64 128,128  ] then accept;
  reject;
 
# General template for an EXABGP node
template bgp EXABGP  
  local as 65002;
  import filter only_loopbacks; #  
  export none;
  route limit 10; #  
  rs client;
  hold time 6; #  
  multihop 10;
  igp table internal;
 
protocol bgp W1 from EXABGP  
  neighbor 2001:db8:6::11 as 65001;
 
protocol bgp W2 from EXABGP  
  neighbor 2001:db8:7::12 as 65001;
 
protocol bgp W3 from EXABGP  
  neighbor 2001:db8:8::13 as 65001;
 
To ensure separation of concerns, we are being a bit more picky. With and , we only accept loopback addresses and only if they are contained in the subnet that we reserved for this use. No server should be able to inject arbitrary addresses into our network. With , we also limit the number of routes that a server can advertise. With , we reduce the hold time from 240 to 6. It means that after 6 seconds, the peer is considered dead. This is quite important to be able to recover quickly from a dead machine. The minimal value is 3. We could have use a similar setting with the session with the routers.

Quagga configuration Quagga s configuration is a bit more verbose but should be strictly equivalent:
router bgp 65002 view EXABGP
 bgp router-id 1.1.1.5
 bgp log-neighbor-changes
 no bgp default ipv4-unicast
 neighbor R peer-group
 neighbor R remote-as 65003
 neighbor R ebgp-multihop 10
 neighbor EXABGP peer-group
 neighbor EXABGP remote-as 65001
 neighbor EXABGP ebgp-multihop 10
 neighbor EXABGP timers 2 6
!
 address-family ipv6
 neighbor R activate
 neighbor R soft-reconfiguration inbound
 neighbor R route-server-client
 neighbor R route-map R-IMPORT import
 neighbor R route-map R-EXPORT export
 neighbor 2001:db8:1::2 peer-group R
 neighbor 2001:db8:1::3 peer-group R
 neighbor 2001:db8:1::6 peer-group R
 neighbor 2001:db8:1::7 peer-group R
 neighbor 2001:db8:1::8 peer-group R
 neighbor EXABGP activate
 neighbor EXABGP soft-reconfiguration inbound
 neighbor EXABGP maximum-prefix 10
 neighbor EXABGP route-server-client
 neighbor EXABGP route-map RSCLIENT-IMPORT import
 neighbor EXABGP route-map RSCLIENT-EXPORT export
 neighbor 2001:db8:6::11 peer-group EXABGP
 neighbor 2001:db8:7::12 peer-group EXABGP
 neighbor 2001:db8:8::13 peer-group EXABGP
 exit-address-family
!
ipv6 prefix-list LOOPBACKS seq 5 permit 2001:db8:30::/64 ge 128 le 128
ipv6 prefix-list LOOPBACKS seq 10 deny any
!
route-map RSCLIENT-IMPORT deny 10
!
route-map RSCLIENT-EXPORT permit 10
  match ipv6 address prefix-list LOOPBACKS
!
route-map R-IMPORT permit 10
!
route-map R-EXPORT deny 10
!
The view is here to not install routes in the kernel3.

Routers Configuring BIRD to receive routes from route servers is straightforward:
# BGP with route servers
protocol bgp RS4  
  import all;
  export none;
  local as 65003;
  neighbor 2001:db8:1::4 as 65002;
  gateway recursive;
 
protocol bgp RS5  
  import all;
  export none;
  local as 65003;
  neighbor 2001:db8:8::5 as 65002;
  multihop 4;
  gateway recursive;
 
It is important to set gateway recursive because most of the time, the next-hop is not reachable directly. In this case, by default, BIRD will use the IP address of the advertising router (the route servers).

Testing Let s check that everything works as expected. Here is the view from RS5:
# show ipv6  bgp  
BGP table version is 0, local router ID is 1.1.1.5
Status codes: s suppressed, d damped, h history, * valid, > best, i - internal,
              r RIB-failure, S Stale, R Removed
Origin codes: i - IGP, e - EGP, ? - incomplete
   Network          Next Hop            Metric LocPrf Weight Path
*  2001:db8:30::1/128
                    2001:db8:6::11         102             0 65001 i
*>                  2001:db8:8::13         100             0 65001 i
*                   2001:db8:7::12         101             0 65001 i
*  2001:db8:30::2/128
                    2001:db8:6::11         101             0 65001 i
*                   2001:db8:8::13         102             0 65001 i
*>                  2001:db8:7::12         100             0 65001 i
*> 2001:db8:30::3/128
                    2001:db8:6::11         100             0 65001 i
*                   2001:db8:8::13         101             0 65001 i
*                   2001:db8:7::12         102             0 65001 i
Total number of prefixes 3
For example, traffic to 2001:db8:30::2 should be routed through 2001:db8:7::12 (which is W2). Other IP are affected to W1 and W3. RS4 should see the same thing4:
$ birdc6 show route 
BIRD 1.3.11 ready.
2001:db8:30::1/128 [W3 22:07 from 2001:db8:8::13] * (100/20) [AS65001i]
                   [W1 23:34 from 2001:db8:6::11] (100/20) [AS65001i]
                   [W2 22:07 from 2001:db8:7::12] (100/20) [AS65001i]
2001:db8:30::2/128 [W2 22:07 from 2001:db8:7::12] * (100/20) [AS65001i]
                   [W1 23:34 from 2001:db8:6::11] (100/20) [AS65001i]
                   [W3 22:07 from 2001:db8:8::13] (100/20) [AS65001i]
2001:db8:30::3/128 [W1 23:34 from 2001:db8:6::11] * (100/20) [AS65001i]
                   [W3 22:07 from 2001:db8:8::13] (100/20) [AS65001i]
                   [W2 22:07 from 2001:db8:7::12] (100/20) [AS65001i]
Let s have a look at DR6:
$ birdc6 show route
2001:db8:30::1/128 via fe80::5054:56ff:fe6e:98a6 on eth0 * (100/20) [AS65001i]
                   via fe80::5054:56ff:fe6e:98a6 on eth0 (100/20) [AS65001i]
2001:db8:30::2/128 via fe80::5054:60ff:fe02:3681 on eth0 * (100/20) [AS65001i]
                   via fe80::5054:60ff:fe02:3681 on eth0 (100/20) [AS65001i]
2001:db8:30::3/128 via 2001:db8:6::11 on eth1 * (100/10) [AS65001i]
                   via 2001:db8:6::11 on eth1 (100/10) [AS65001i]
So, 2001:db8:30::3 is owned by W1 which is behind DR6 while the two others are in another part of the network and will be reached through the appropriate link-local addresses learned by OSPF. Let s kill W1 by stopping nginx. A few seconds later, DR6 learns the new routes:
$ birdc6 show route
2001:db8:30::1/128 via fe80::5054:56ff:fe6e:98a6 on eth0 * (100/20) [AS65001i]
                   via fe80::5054:56ff:fe6e:98a6 on eth0 (100/20) [AS65001i]
2001:db8:30::2/128 via fe80::5054:60ff:fe02:3681 on eth0 * (100/20) [AS65001i]
                   via fe80::5054:60ff:fe02:3681 on eth0 (100/20) [AS65001i]
2001:db8:30::3/128 via fe80::5054:56ff:fe6e:98a6 on eth0 * (100/20) [AS65001i]
                   via fe80::5054:56ff:fe6e:98a6 on eth0 (100/20) [AS65001i]

Demo For a demo, have a look at the following video (it is also available as an Ogg Theora video).

  1. The primary target of VRRP is to make a default gateway for an IP network highly available by exposing a virtual router which is an abstract representation of multiple routers. The virtual IP address is held by the master router and any backup router can be promoted to master in case of a failure. In practice, VRRP can be used to achieve high availability of services too.
  2. However, you could deploy an L2 overlay network using, for example, VXLAN and use VRRP on it.
  3. I have been told on the Quagga mailing-list that such a setup is quite uncommon and that it would be better to not use views but use --no_kernel flag for bgpd instead. You may want to look at the whole thread for more details.
  4. The output of birdc6 shows both the next-hop as advertised in BGP and the resolved next-hop if the route have to be exported into another protocol. I have simplified the output to avoid confusion.

Marko Lalic: PTS User Accounts

PTS User AccountsDuring the last iteration, the PTS rewrite has grown user accounts! This is a major addition, which moves the GSoC project beyond a simple "rewrite".

As always, this feature is available to be tested at the running PTS demo instance found at http://pts.debian.net.

For the moment the features related to user accounts allow for Web-oriented package subscription management. This means that the user can achieve the same functionality as what is offered by the control commands accessible over the control mail interface (control@pts.debian.net).

This includes subscribing to a package directly from the package page by clicking a single button; no confirmation mail required. Users are able to see a list of all their subscriptions and associated keywords, modify their default keywords and subscription-specific keywords all through a single profile page.

Eventually, a user is going to be able to associate multiple email addresses with his account and manage subscriptions for each of them from the same central panel. Actually, all currently existing functionality has already been implemented with this in mind and is backed by extensive Selenium-driven functional tests. This story is found in the backlog and is to be worked on in the last week of GSoC.

Another interesting, albeit Debian-specific, feature that is in the pipeline is allowing Debian Developers to authenticate via sso.debian.org: no PTS-specific registration/passwords required!

Besides package subscription management, introducing user accounts to the PTS opens up interesting possibilities for future development. Perhaps things like personalized package pages, a private stream of notifications in the user's profile... Hopefully, there are members of the community interested in exploring some of them.

PTS Rename?As the scope of the project begins to encompass more and more previously nonexisting functionality and in doing so even starts engulfing some other existing services (an example is that the PTS can now automatically extract and serve some source package files, e.g. debian/copyright)., an idea has been floating around to rename it. The question becomes: what would a good name be? No decision has been made as of yet, so suggestions and opinions are welcome.

5 September 2013

Vincent Sanders: Strive for continuous improvement, instead of perfection.


Kim Collins was perhaps thinking more about physical improvement but his advice holds well for software.

A lot has been written about the problems around software engineers wanting to rewrite a codebase because of "legacy" issues. Experience has taught me that refactoring is a generally better solution than rewriting because you always have something that works and can be released if necessary.

Although that observation applies to the whole of a project, sometimes the technical debt in component modules means they need reimplementing. Within NetSurf we have historically had problems when such a change was done because of the large number of supported platforms and configurations.
HistoryA year ago I implemented a Continuous Integration (CI) solution for NetSurf which, combined with our switch to GIT for revision control, has transformed our process. Making several important refactor and rewrites possible while being confident about the overall project stability.

I know it has been a year because the VPS hosting bill from Mythic turned up and we are still a very happy customer. We have taken the opportunity to extend the infrastructure to add additional build systems which is still within the NetSurf projects means.

Over the last twelve months the CI system has attempted over 100,000 builds including the projects libraries and browser. Each commit causes an attempt to build for eight platforms, in multiple configurations with multiple compilers. Because of this the response time to a commit is dependant on the slowest build slave (the mac mini OS X leopard system).

Currently this means a browser build, not including the support libraries, completes in around 450 seconds. The eleven support libraries range from 30 to 330 seconds each. This gives a reasonable response time for most operations. The worst case involves changing the core buildsystem which causes everything to be rebuilt from scratch taking some 40 minutes.

The CI system has gained capability since it was first set up, there are now jobs that:
DownsidesIt has not all been positive though, the administration required to keep the builds running has been more than expected and it has highlighted just how costly supporting all our platforms is. When I say costly I do not just refer to the physical requirements of providing build slaves but more importantly the time required.

Some examples include:
  • Procuring the hardware, installing the operating system and configuring the build environment for the OS X slaves
  • Getting the toolchain built and installed for cross compilation
  • Dealing with software upgrades and updates on the systems
  • Solving version issues with interacting parts, especially limiting is the lack of JAVA 1.6 on PPC OS X preventing jenkins updates
This administration is not interesting to me and consumes time which could otherwise be spent improving the browser. Though the benefits of having the system are considered by the development team to outweigh the disadvantages.

The highlighting of the costs of supporting so many platforms has lead us to reevaluate their future viability. Certainly the PPC mac os X port is in gravest danger of being imminently dropped and was only saved when the build slaves drive failed because there were actual users.

There is also the question of the BeOS platform which we are currently unable to even build with the CI system at all as it cannot be targeted for cross compilation and cannot run a sufficiently complete JAVA implementation to run a jenkins slave.

An unexpected side effect of publishing every CI build has been that many non developer user are directly downloading and using these builds. In some cases we get messages to the mailing list about a specific build while the rest of the job is still ongoing.

Despite the prominent warning on the download area and clear explanation on the mailing lists we still get complaints and opinions about what we should be "allowing" in terms of stability and features with these builds. For anyone else considering allowing general access to CI builds I would recommend a very clear statement of intent and to have a policy prepared for when when users ignore the statement.
Tools
Using jenkins has also been a learning experience. It is generally great but there are some issues I have which, while not insurmountable, are troubling:
Configuration and history cannot easily be stored in a revision control system.
This means our system has to be restored from a backup in case of failure and I cannot simply redeploy it from scratch.

Job filtering, especially for matrix jobs with many combinations, is unnecessarily complicated.
This requires the use of a single text line "combination filter" which is a java expression limiting which combinations are built. An interface allowing the user to graphically select from a grid similar to the output tables showing success would be preferable. Such a tool could even generate the textural combination filter if thats easier.

This is especially problematic of the main browser job which has options for label (platform that can compile the build), javascript enablement, compiler and frontend (the windowing toolkit if you prefer e.g. linux label can build both gtk and framebuffer). The filter for this job is several kilobytes of text which due to the first issue has to be cut and pasted by hand.

Handling of simple makefile based projects is rudimentary.
This has been worked around mainly by creating shell scripts to perform the builds. These scripts are checked into the repositories so they are readily modified. Initially we had the text in each job but that quickly became unmanageable.

Output parsing is limited.
Fortunately several plugins are available which mitigate this issue but I cannot help feeling that they ought to be integrated by default.

Website output is not readily modifiable.
Instead of perhaps providing a default css file and all generated content using that styling someone with knowledge of JAVA must write a plugin to change any of the look and feel of the jenkins tool. I understand this helps all jenkins instances look like the same program but it means integrating jenkins into the rest of our projects web site is not straightforward.
ConclusionIn conclusion I think the CI system is an invaluable tool for almost any non trivial software project but the implementation costs with current tools should not be underestimated.

Gergely Nagy: What's cooking in syslog-ng 3.5?

The first alpha of syslog-ng 3.4 was released more than a year ago, and the first stable release earlier this year, development on syslog-ng 3.5 has been going on steadlily since then, with a lot of interesting features and changes pouring in. While the 3.5 release will not bring as many overwhelming changes as the previous two releases did, the sheer number of improvements is still substantial. Our focus was on smaller developments all over the place this time, instead of big sweeping changes. In this post, we will go over most of these features, with use-cases, examples and a few words about why they are so useful and awesome.Multi-line support, new destinations, new template functions, type hinting, unit suffixes, and other things. Read on, and be amazed!These are only bigger features, there has been a lot of small tweaking going on, and of course, all of the fixes that went into prior versions will also be in 3.5 too, and there's still a chance that something else may find its way in before the feature freeze.Multi-line supportOne of the major new features in the 3.5 release will be support for multi-line messages, a feature that has been available in syslog-ng PE for a good while, and which has been ported to and improved upon to the open source edition. Two variants of multi-line are supported, which will be detailed below. Both of them are available for the file() and pipe() sources only.Indented multi-lineThe easiest variant is indented multi-line, where each line can be followed by others, indented by whitespace, and the message continues until the first non-indented line. This is the format used by the Linux kernel too, from version 3.5, for /dev/log. This type of multi-line can be used as follows:
source s_multiline   file("/path/to/file" multi-line-mode(indented));  ;
Consider that /path/to/file has the following content:
First line
 Continuation 1;
 Continuation 2;
Second line
With the indented multi-line-mode() setting, this would turn into two log messages:
First line\n Continuation 1;\n Continuation 2;
Second line
Regexp-based multilineIf multi-line input is not based on indentation, one can use the regexp multi-line-mode() instead, which makes two new settings available: multi-line-prefix() and multi-line-garbage(). These can be used to define the start and the end of a log message: any string between a the beginning matching prefix and a matching garbage will be considered a single message. That is, the prefix will be included, the garbage will not be: it will be discarded.To illustrate:
source s_multiline  
 file("/path/to/file" multi-line-mode(regexp)
                      multi-line-prefix("^prefix")
                      multi-line-garbage(" garbage$"));
 ;
If the source contains these lines:
prefix message
continuing garbage
This will turn into the following log message:
prefix message\ncontinuing
New destinationsIt would be pretty hard to do a syslog-ng release without new destinations, and with 3.5, we will have three of them!STOMPWhile we had AMQP before, we now have a STOMP destination too, so we can stream logs to any STOMP server, with a few simple lines:
stomp(
 host("localhost")
 port(61613)
 destination("/topic/syslog")
 routing_key("")
 persistent(yes)
 ack(no)
 username("someone")
 password("something")
 body("This is the body! YAY! Here's a message: $MESSAGE!\n")
 value-pairs(scope(nv-pairs, syslog-proto, selected-macros))
)
Of course, none of these settings need to be set, you can just use the defaults, and it will just work!RiemannDid you know that syslog-ng is far more than a log collector and processor? No? You do now. When you have access to a lot of logs, and a tremendous amount of power in parsing them, you can use these tools for monitoring easily! And when we're talking monitoring, riemann is a great asset in our toolbox, and with the new destination, we can easily forward metrics to it:
riemann(
 server("localhost")
 port(5555)
 host("$HOST")
 service("$PROGRAM")
 description("$PROGRAM pids")
 metric(int("$PID"))
 ttl(300)
);
Of course, the above is a very silly example, it would make much more sense to extract data from a log message instead, but this will serve as an example.New template functions
$(upper-case TEXT...), $(lower-case TEXT...)
To turn some text into *upper-* or *lower-case*, these two template functions come in handy. They simply turn all their arguments into the respecitve case.
$(delimit DELIMITERS NEW-DELIMITER TEXT)
Sometimes one has a delimited string, where one wishes to replace the delimiters. This function does just that: give it a list of delimiters (you may need to quote it, if it contains whitespace), a replacement, and a text to replace delimiters in, and it does the rest. For example, to replace tabs and spaces with a vertical bar, one could write a template like this:
template("$(delimit \"\t \" \" \" $MESSAGE)\n")
$(env VARIABLE...)
Have you ever felt the need to check an environment variable from within syslog-ng? I did, and now I can.
Type hintingWhile syslog-ng supported sending log messages into various data stores and message queues for a while (SQL at first, MongoDB, JSON and AMQP later), even when those supported different types of data than strings, we could not do anything else. Until now. It is now possible - at places where it makes sense - to annotate templates with type hints, which the destination driver can optionally use. Type hinting is implemented for the mongodb() destination and the $(format-json) template function for now. When no type hint is specified, syslog-ng defaults to string.To add type hints, simply wrap the respective template with the hinted type, like this:
mongodb(
 value-pairs(pair("date", datetime("$UNIXDATE"))
             pair("pid", int64("$PID")))
);
Currently the following type hints exist: boolean (anything that begins with a t or 1 is true, anything that begins with f or 0 is false, everything else is an error), string, literal (same as string, but not quoted if it would be quoted otherwise), int32 (int is an alias for this), int64, and datetime. Only UNIX timestamps can be type-hinted to datetime, anything else will likely result in a casting error.It is also possible to control what happens when type casting fails: syslog-ng can drop the whole message, drop the property, or fall back to string. It can also do all of these silently:
options  
 typecast(on-error(silently-drop-property));
 ;
Using this feature with $(format-json) is very similary too:
$(format-json date=datetime("$UNIXDATE") pid=int64("$PID"))
With this feature in place, you can now store your non-string values with their proper types!Unit suffixesUnit suffixes make it considerably easier to set limits and describe numbers within the syslog-ng configuration. We no longer need to spell out sizes to the byte precious, it is now enough to write: log-fifo-size(200MiB). Now, syslog-ng will understand suffixes for kilo-, mega-, and giga-bytes, (K, M, G, respectively) either in base-10 or base-2 (with an extra i after the suffix). One can also omit the trailing b from the end.So, to set the log-fifo-size() to 2097152 bytes, one can simply use 2MiB. Or, to set it to 2000000, 2Mb. That's a whole lot easier, isn't it? No more counting zeros, no more silly typos in a ten-digit number, no more pain, but easily readable units!Miscellaneous featuresApart from the features above, there have been a lot of other changes and improvements in the code base:

Tanguy Ortolo: PluXml, a file-based, database-free blog

The blog engine PluXml is now available as a Debian package:
Package: pluxml
Version: 5.2-2
Description-en: Light blog engine using XML files
 PluXml is a light and simple blog and CMS engine that uses simple XML
 files to store its data and requires no database. It has all the usual
 features (static pages, comments, categories, tags, medias, RSS
 feed...) and supports multiple users, customizable themes and plugins.
Homepage: http://www.pluxml.org/
Section: web
Priority: extra
PluXml logo: a leaf with its petiole used as one bar of the word  Xml
PluXml is a French blog engine that uses XML files to store its data, thus avoiding the need for an external database system as most blogs do. The name PluXml is a French portmanteau between plume (feather, evoking something light) and XML. Apart from that, although it was started in French only and its official website is still in French, it was internationalized about a year ago. It is designed to be easy enough to use, targeting regular users, but not too fancy: for instance, it provides a web-based administration interface, but content editing uses HTML code unless you install a graphical content editor plugin. That package may be of interest to people like me, that consider the almost systematic use of relational database systems in many web applications as a disease, and more generally to self-hosted people that would rather avoid running an additional database server on their small home servers. The package includes an interactive configuration, that allows to choose the blog language, title, description, admin login and password. Unless debconf was configured not to ask questions, in which case nothing is asked and the blog is left in an barely unusable state, of course.

Daniel Pocock: Will Baby Boomers strangle Australia's Internet?

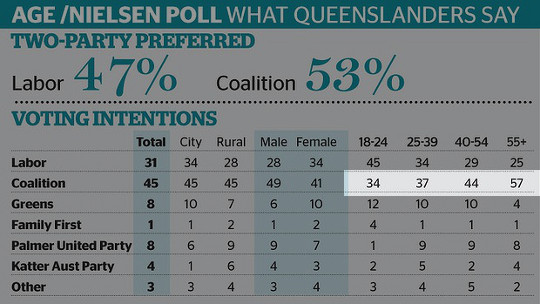
When Labor's Communications Minister Stephen Conroy won the title Internet villain of the year most educated people realised it wasn't something to celebrate. So it might be surprising for some that the title could potentially be returning to Australia so soon... Australia's main opposition party, the deceptively named Liberals (who actually lurk at the Marine Le Pen grade of conservatism) have just announced plans to resurrect the plan by implanting filtering technology in all modems, routers and smartphones. Whether they do or don't, there are serious concerns that they have described Australia's still-under-construction national broadband network as a wasteful project (which is potentially true) but failed to provide any credible alternative: who really thinks the conservative's proposed 25MBps will be a serious technology when they finish deploying it in 2019?. It is interesting to look at the bigger picture to see where this stupidity comes from. A political poll released early this week gives us half the story: Big bad baby boomers It is obvious that older voters prefer the conservative "coalition" parties, 57% of over-55s in particular. It is a huge jump from the 44% of voters in the age group below them. What this table doesn't tell us is that Australia's population is top-heavy with Baby Boomers. In other words, there are actually quite a lot of those over-55-year-old voters. In fact, it is estimated that close to 1 in 3 Australians will be in this category within the next 10 years. People who want the world to be the way it was in the 60s: many have already paid off a mortgage on a home in the suburbs with no access to things like public transport. They grew up under the white Australia policy and are frustrated at the presence of educated hard working foreigners from countries like India and China. Retired, no longer working, expecting the state to provide roads to their poorly located McMansions and free health care but little concern for broadband or anything that smells new. As they are no longer working, many have no commercial demand for broadband but will happily vote for a policy to censor it even if they don't use it themselves, simply because they want to see a Government that is blocking change. Sadly, they are shooting themselves in the foot: younger generations of Australians need to work and pay tax if there is to be any hope of keeping the dream alive for older Australians. However, with the conservatives cutting education to fund an over-dramatised response to immigration that costs billions of dollars every year, cutting corners and dumbing-down essential technology like the Internet, it seems that working-age Australians will struggle to compete in the global marketplace.

4 September 2013

Mike Gabriel: Python X2Go now has support for passphrase-protected SSH keys

Yesterday, I (with my X2Go upstream hat on) have added a new (long waited for) feature to PyHoca-GUI / Python X2Go. So far, in PyHoca-GUI (python-x2go) it was only possible to use passphrase-protected / encrypted SSH keys via an ssh-agent process that unlocks those keys when being added to the agent's keyring previous to logging into an X2Go Server. Unlocking those keys natively in PyHoca-GUI was not possible so far.
-> Now it is!!! This feature will be available with PyHoca-GUI 0.4.0.9 / Python X2Go 0.4.0.9 (and PyHoca-CLI 0.4.0.3). read more

Russell Coker: Ownership of a Club

Last night at the Annual General Meeting we had a motion to disincorporate The Linux Users of Victoria (LUV) [1]. The proposal was for LUV to cease being an incorporated society on condition that Linux Australia (LA) [2] accepts us as a sub-committee. As a sub-committee of LA we would elect our own committee to run things locally but have LA hold the finances, deal with all the paperwork that the government demands, and generally do as many of the non-core tasks associated with running a users group as possible. When we discussed this at the LUV committee meetings it didn t seem like a big deal. But as is often the case with political discussions it turned out to be difficult. There was a lot of discussion about LUV supposedly ceasing to exist, people seem to think that LUV is defined by having an incorporated society. My impression was always that it was defined by a mailing list and having meetings and I was involved in both before there was an incorporated society. Lurkers and Ownership During the discussion we had some input from members who were typically lurkers who seemed to feel that their property rights towards LUV were being infringed, this annoys me. I think that if someone chooses not to be involved in running an organisation then they should choose not to concern themselves with the details of how the organisation is to be run. People who attend the meetings should have a say in how the meetings are run and have reason to be concerned about anything that might affect them and the opinions of speakers also matter. People who are involved with mailing list discussions should have a say in how the lists are run. But people who have never volunteered for a position on the committee shouldn t be greatly concerned about the internal issues of how things are run. Finance Some concern was expressed about the financial situation of LUV and whether we would still get enough donations to keep it running when combined with LA. There was even some FUD suggesting that LA would just take our money (they had assured us that all funds and donations would be ear-marked for us). The current LUV financial situation is that Red Hat pays for the venue for the monthly meetings and the rent for the venue comprises about 2/3 of all donations. The remaining 1/3 comes from one company. So in the current situation if Red Hat ceased donating then we would have 18 months to find another donor or cease holding meetings before our bank balance became unreasonably low. If the company which gives the other significant annual donation was to cease doing so then we could operate for a few years on savings but we would need to find some other source of funding. It seems to me that joining LA would give us more financial security. Then if Red Hat ceased paying for the venue then LA could keep things running until we found another donor, I m confident that LA wouldn t allow LUV to just shut down because of a shortage of donations. If people are really concerned about the financial situation of LUV then they should urgently seek further donations such that if any one donor decided to stop giving then we could still operate as normal. To achieve that goal I think we need at least another $1,000 per annum. This issue of redundancy in donations is something I raise every time that LUV finances are discussed. My conclusion is that people aren t really bothered about the financial security of LUV except when they are looking for reasons to avoid change. Doing New Things During the course of discussion about the future of LUV there were a number of requests for improvement. One significant request was for more support for regional Linux users. Some years ago we held a mini-conference in Ballarat which went well. I think it would be good to do such things again, the cost is not particularly great and I m sure it would be accepted by LA for funding, but we need to organise it. Organising such events is something that anyone can do. Any LUV member can plan an event, get costs for everything that is needed (food, accommodation, travel, etc) and then pitch it to the LUV committee in terms of which things should be paid by LUV and which by the members concerned. We could then work on getting additional funding from LA if necessary. But planning an event takes some effort and it s often effort that can only be done by a local. Finding a suitable venue and getting some assurance that a large enough audience will attend is something that can t be done remotely. I think that the problem for LUV in regard to such things isn t a lack of money or independence. I think that the problem is that the committee spends too much volunteer time on administrative tasks and not enough time directly doing things that benefit members and the community in general. In the past I have declined nomination to the LUV committee because I felt that I could contribute more by giving lectures, finding other speakers, and doing other things to directly improve the group. I was on the committee last year and have now been elected to it again, but I m starting to think that I made a mistake. Maybe I should have declined and let others work on the new model rules and other paperwork. One committee member has claimed that the time taken on administrative tasks isn t taking time away from other LUV related tasks, I invite any committee members who feel that way to address some of the services that members are requesting. Speaking for myself my lack of time directly impacts that I can do for the club. I think that ownership of a club should be related to what people do for the club. If you have a feeling of ownership and lack ideas for how to contribute then you can ask the LUV mailing list, there are lots of people with suggestions for things to do.

3 September 2013

Chris Lamb: Using the Garmin 910XT on Linux

The Garmin 910XT is the premier GPS watch for triathlon training and racing.

  1. You'll probably need a newer version of pyusb:

    $ git clone git://github.com/walac/pyusb
    
    There is no need to install it systemwide - you can simply leave it checked out somewhere.
  2. Get the Garmin-Forerunner-610-Extractor project from GitHub:

    $ git clone git://github.com/Tigge/Garmin-Forerunner-610-Extractor.git
    
  3. Turn your watch on and plug in the USB adaptor.

  4. You can now sync your activities:

    $ sudo env PYTHONPATH=/path/to/pyusb ./garmin.py
    Request basic information...
      ANT version:   AJK1.04RAF
      Capabilities:  array('B', [8, 3, 0, 186, 54, 0])
      Serial number: 3480039
    Starting system...
    Searching...
    Authenticating with Forerunner 910XT (3863343203)
     - Passkey: OK
    Downloading 1 file(s)
    Downloading 2013-09-03_21-09-32-80-19364.fit [..........]
    
    The first time you sync, you will have to authenticate on the watch itself. Downloading the activities will be much slower than you expect.
  5. After the syncing has finished, don't forget to turn the watch off. If you are used to the Garmin Edge 800 (which turns itself off when you insert the USB cable) you will probably not have the habit of turning off the unit.

  6. Rather confusingly, your .FIT files are available in the Xdg configuration folder. For example:

    ls -l ~/.config/garmin-extractor/3863343203/activities/
    -rw-r--r-- 1 root root   2688 Jun  9 15:23 2013-06-08_12-33-24-80-2688.fit
    -rw-r--r-- 1 root root   1171 Jun  9 15:23 2013-06-08_12-37-14-80-1171.fit
    -rw-r--r-- 1 root root   6111 Jun  9 15:23 2013-06-08_22-19-28-80-6111.fit
    -rw-r--r-- 1 root root 170327 Jun  9 15:26 2013-06-09_11-09-44-80-170327.fit
    
  7. Strava supports these .fit files through the From File upload option.

Chris Lamb: Using the Garmin 910XT on Linux

The Garmin 910XT is the premier GPS watch for triathlon training and racing.
  1. You'll probably need a newer version of pyusb:

    $ git clone git://github.com/walac/pyusb
    
    There is no need to install it systemwide - you can simply leave it checked out somewhere.
  2. Get the Garmin-Forerunner-610-Extractor project from GitHub:

    $ git clone git://github.com/Tigge/Garmin-Forerunner-610-Extractor.git
    
  3. Turn your watch on and plug in the USB adaptor.

  4. You can now sync your activities:

    $ sudo env PYTHONPATH=/path/to/pyusb ./garmin.py
    Request basic information...
      ANT version:   AJK1.04RAF
      Capabilities:  array('B', [8, 3, 0, 186, 54, 0])
      Serial number: 3480039
    Starting system...
    Searching...
    Authenticating with Forerunner 910XT (3863343203)
     - Passkey: OK
    Downloading 1 file(s)
    Downloading 2013-09-03_21-09-32-80-19364.fit [..........]
    
    The first time you sync, you will have to authenticate on the watch itself. Downloading the activities will be much slower than you expect.
  5. After the syncing has finished, don't forget to turn the watch off. If you are used to the Garmin Edge 800 (which turns itself off when you insert the USB cable) you will probably not have the habit of turning off the unit.

  6. Rather confusingly, your .FIT files are available in the Xdg configuration folder. For example:

    ls -l ~/.config/garmin-extractor/3863343203/activities/
    -rw-r--r-- 1 root root   2688 Jun  9 15:23 2013-06-08_12-33-24-80-2688.fit
    -rw-r--r-- 1 root root   1171 Jun  9 15:23 2013-06-08_12-37-14-80-1171.fit
    -rw-r--r-- 1 root root   6111 Jun  9 15:23 2013-06-08_22-19-28-80-6111.fit
    -rw-r--r-- 1 root root 170327 Jun  9 15:26 2013-06-09_11-09-44-80-170327.fit
    
  7. Strava supports these .fit files through the From File upload option.

Jan Wagner: nagios-plugins: Call for testing

Some of you might have noticed there is a new nagios-plugins version in the row. To support upstream in evaluating bugs and bringing the code to a wider audience, I uploaded the latest development version into Debian unstable. Since this package version contrib/ is dropped by upstream. But we stopped shipping the latest plugins of contrib/ with Debian wheezy. We also removed perlmods/ from the upstream tarball, as this was never used by our package. The packaging changes are:
* New upstream git snapshot (b15adb7762)
  - Adjust debian/copyright
* Droped the following upstream integrated patches
  - 05_fix_gets_undefined_in_iso_c11.dpatch
  - 10_check_apt_perfdata.dpatch
  - 11_check_nt_npe.dpatch
  - 12_check_smtp_double_threshold.dpatch
* Fix removing empty /usr/include
* Add new check_dbi into nagios-plugins-standard
* Remove whois from Recommands, as check_bgpstate is removed
* Cleanup debian/rules from unused stuff
* Provide information about repackaging
  - Extend debian/README.source
  - Add debian/bin/repack.sh
* Updating standards version to 3.9.4 (no changes needed)
* Add libfreeradius-client-dev to build-deps and remove libradiusclient-ng-dev
  (Closes: #721621)
* Remove traces of contrib/ from debian/copyright
* Remove command.cfg from examples in nagios-plugins-common, it was removed
  upstream
The Debian Nagios Maintainer and Upstream Developer are asking you to try out this new package on non production systems. Not that we think there might be a high risk for damage, but you know .. :) The latest version of the plugins are running on several systems already, but it is nearly impossible to test all scenarios even automated. If you find bugs, please report all packaging bugs into the BTS. Upstream bugs you might consider to report in the upstream bugtracker. If you want to give it a try on Debian wheezy, you could install the packages from our wheezy-backports repository:
    # wget "http://ftp.cyconet.org/debian/sources.list.d/wheezy-backports-cyconet.list" \
        -O /etc/apt/sources.list.d/wheezy-backports-cyconet.list
    # aptitude update
    # aptitude -t wheezy-backports install nagios-plugins
For adding our archive key, you can just install the package "debian-cyconet-archive-keyring"

Rapha&#235;l Hertzog: Finding a new name for the Package Tracking System

The Google Summer of Code rewriting the Package Tracking System is approaching its end and I m starting to think about deploying it on debian.org. Its scope has expanded over the years and the rewritten PTS will continue this trend by bringing some new features for teams (like the possibility to subscribe to all packages of a team). I believe that its current hostname (and name) doesn t reflect properly the role of the PTS. Add to this the fact that there s still some work left to be done to reach feature-parity with the current PTS, I m considering deploying it in parallel to the current PTS under a new name. Package Tracking System is also a bit too long for a name, and sounds more like a description than a name But if I get rid of packages.qa.debian.org and Package Tracking System , how should we call the new PTS? :-) The PTS is a sort of central place that brings together information from many parts of Debian. It s currently mainly a consumer/dispatcher of information but I expect to integrate some of the external services that are useful for all Debian derivatives, and it will thus become more and more a producer of first-hand information as well. To replace packages.qa.debian.org, Stefano Zacchiroli suggested me hub.debian.org and I must say I like it, it s short and relatively close to what the PTS actually is (and reminds me of DEP-2 the new PTS will be an asset to make it a reality). My other ideas were devel.debian.org, inside.debian.org, watch.debian.org, track.debian.org, do you have better suggestions? what s your preference? Finding a better name is harder, but there s room to build on the hub concept and similar images. I would like a full name that s not too long and an associated abbreviation/short name for the top-level Python package (currently we use pts for that Python package). Can you come up with something original and satisfactory? My latest thoughts end up with DistroHub as full name and dhub as Python package name. Still boring So, dear lazy web, I heard that we re good at bikeshedding in Debian, so can you come up with something better? Share your suggestions in the comments!

31 comments Liked this article? Click here. My blog is Flattr-enabled.

Julien Danjou: Announcing The Hacker Guide to Python

I've been hacking on Python for a lot of years now, on various project. For the last two years, I've beenheavily involved in OpenStack, which makes an heavy usage of Python. Once you start working with a hundred of hackers, on several software and libraries representing more than half a million source lines of Python, things change. The scalability, testing and deployment problems inherent to a cloud platform meddle with everything in designing components. During these two years working on OpenStack development, I've learned a lot on Python from astounding Python hackers. From general architecture and design principles to various tips and tricks of the language. It seemed to me like a good opportunity to share what I learnt doing so with others so you can benefit from it in other projects. I've started working a book, entitled "The Hacker Guide to Python", where I will try to share what I learnt while working with Python. The book is still a work in progress at this stage, but if you'd like to get in touch and keep updated on its advancement, you can subscribe in the following form or from the book homepage.
The Hacker Guide to Python
A book I'm writing that will be launched soon, talking about designing Python applications, state of the art, and various Python tips. If you want to be the first to hear about the launch, subscribe now.

Miriam Ruiz: pySioGame: Educational activities and games for kids

I discovered pySioGame for the first time in the first half of 2012, and even though it was still in a beta state, I liked it a lot. pySioGame is essentially a set of educational activities and games for kids. pySioGame was initially developed by its author -Ireneusz Imiolek- for his son, but he soon decided to make it Free Software. And I m glad that he did, because it s a very cute application. Even though -in it s author s own words- it s hard to put age range on this kind of games, it is primarily targeted to children from as young as 3 years old, up to about 10 years old. The activities included, many of which are grid based, cover topics like maths, reading, writing, painting, and memory activities, among others. I was finally able to upload pySioGame to Debian during the DebConf, and it has very recently hit the archive. I m convinced that pySioGame is soon going to be one of the references among the free programs for small kids, among titles such as GCompris, ChildsPlay, PySyCache, or Bouncy. Or, even though it s not in the archives, Omnitux. Finally, to whet your appetite, here is the link to a video, and there go some screenshots:

2 September 2013

Daniel Pocock: Australia's Labor Party exposed spying on their own members

Australia's Labor Party claims to represent the little guy, advocating the interests of a wide slice of the population over the interests of those who might supposedly exploit them. In this latest blog I'll look at just how the Victorian state branch of the party is emulating the more sinister elements of monitoring and control that you would typically expect from marketers, spammers and the NSA. It makes you wonder, if they do this to their own members, how can Australia's government ever hope to rein in spammers or other undesirable practices? Europe has tried cookie laws and the right to be forgotten, while the ALP has taken these developments almost as a guide to exploiting their own most valuable resource, their membership. The email version of invisible ink Straight out of an email attempting to recruit party members to the federal election campaign, we find that the ALP's logo itself has been turned into a sinister tracking mechanism. Looking underneath the logo, there is a hidden tracking number attached to every message:
http://gallery.mailchimp.com/3021e68df9a7200135725c633/images/Email_Header_ThisisLabor.jpg
There it is, that big long code 3021e68df9a7200135725c633. On it's own, you may think this number can't do much harm. Think again. After all, as the filename says, "ThisisLabor". Reaching the grass roots by long distance email When a party member sees any of the images in the email or clicks any of the links, their email software or web browser sends a HTTP request to the ALP's outsourced tracking server in the United States. Here is an example of what that request may contain:
TCP Headers:
  SOURCE IP ADDRESS: 198.51.100.56
HTTP headers:
  GET /3021e68df9a7200135725c633/images/Email_Header_ThisisLabor.jpg
  HTTP/1.1
  Host: gallery.mailchimp.com
  User-Agent: Mozilla/5.0 (X11; Linux x86_64; rv:17.0) Gecko/20130515 Firefox/17.0 Iceweasel/17.0.6
  Accept: text/html,application/xhtml+xml,application/xml;q=0.9,*/*;q=0.8
  Accept-Language: en-US,en;q=0.5
  Accept-Encoding: gzip, deflate
  X-Forwarded-For: 192.168.1.54
  Connection: keep-alive
These codes are all transmitted from the recipient of the email back to the ALP. Notice the tracking number is in the very first line of the HTTP request? These codes send many details to the tracking server. Just what is revealed?
  • What time the message was read
  • How many times the message was opened
  • Whether the message was read on multiple computers (perhaps it was forwarded)
  • The IP addresses reveal which network was used.
    • For people reading email at work or on wifi, the IP address reveals the name of the employer, it can be easily looked up in this public database. Here is an example querying one of the ALPs own IP addresses, 203.24.72.2
    • For people using an internet connection at home, the IP address reveals the service provider. There is more to it though: if one party member regularly visits another party member and uses their wifi, they will both appear to be using the same IP address and the party will be able to deduce that there is a connection between these two people.
  • The web browser name and version and the operating system name and version.
  • The language normally used on the computer
Crunching the numbers You may think that nobody would be interested in all that data or that it is even too much data for anybody to easily study. Think again. The ALP has outsourced processing of this data to an offshore firm that specializes in bulk email, MailChimp. After lecturing everybody about the dangers of outsourcing, the ALP has literally sold the farm (their own membership data) - to a foreign marketing company. Here are some of the claims MailChimp make on their web site:
"Dig even deeper with Subscriber Activity Reports, which give you a real time report for every subscriber s email activities: when they opened, what they clicked, and when they came back for more. You can even generate a list of people who didn t open, and send them a modified campaign."
That's right: if ALP members don't read their emails fast enough, they will send even more of them. Just who has access to this data? Well, the scope is quite broad. According to these rules, it is not only the dubious officials in the party's state office, but Labor Party regulations also list a whole lot of other officials who have access to some subset of the data: branch and FEA district committees, policy committees and maybe some trade union officials too. Once you start to contemplate this, it becomes apparent that the probability of somebody profiling members at an individual level is very real. On the other hand, those rules clearly do not permit the state branch to process the member's data offshore. Double whammy In fact, even MailChimp is further outsourcing the data. When receiving an image from the booby-trapped link in the email, we receive a response like this:
HTTP/1.1 200 OK
Content-Type: image/jpeg
Content-Length: 407474
Connection: keep-alive
Date: Wed, 10 Jul 2013 06:25:55 GMT
Last-Modified: Tue,  03 Sep 2013 04:05:37 GMT
ETag: "df9a7200135725c6331369a22"
Accept-Ranges: bytes
Server: AmazonS3
Age: 62097
Via: 1.0 e71fe855f29513f54a41e213fe653fb1.cloudfront.net (CloudFront)
X-Cache: Hit from cloudfront
X-Amz-Cf-Id: S2V2aW4gUnVkZCBpcyBhIGJhZCBib3kuCg==
which contains more tracking numbers and clearly indicates that the data is being processed in the massive AmazonS3 (a.k.a Amazon online bookstore) cloud platform. Thanks to cloud computing, there is considerable scope for cross-referencing records across other web sites. The IP address becomes a magic key, allowing a range of sinister forces to join the dots at the click of a button and profile the whole private and professional identity of any individual ALP member. Googling ALP members It doesn't stop there however, after following these links a victim will eventually end up on one of the ALP's own web pages. Looking through the HTML code underneath http://www.viclabor.com.au is very easy, in most web browsers, you can just press Control-U to see what is hidden away in the shadows. Buried in the code, I found this little gem:
  var _gaq = _gaq   [];
  _gaq.push(['_setAccount', 'UA-35325645-1']);
  _gaq.push(['_trackPageview']);
  (function()  
    var ga = document.createElement('script'); ga.type = 'text/javascript'; ga.async = true;
    ga.src = ('https:' == document.location.protocol ? 'https://ssl' : 'http://www') + '.google-analytics.com/ga.js';
    var s = document.getElementsByTagName('script')[0]; s.parentNode.insertBefore(ga, s);
   )();
This may be even scarier: it's a JavaScript code that channels all access to the ALP web site into an outsourced tracking system provided by Google. Google can now cross-reference ALP members against their Gmail accounts, their friends and the topics they search for to further profile the type of advertising they should be exposed to. Google, like any private company, has a loyalty to its shareholders and the laws of the country where it is domiciled. Will that coincide with the best interests of ALP members in Victoria? Australia's other parties: samples needed Do you have similar communications from Australia's other political parties? Please send them to me and I'll be happy to examine them for similar shortcomings.

Next.

Previous.