Search Results: "ag"

18 December 2016

Iustin Pop: Printer fun

Had some printer fun this week. It was fun in the sense that failure modes are interesting, not that there was much joy in the process. My current document printer is an HP that I bought back in early 2008; soon 9 years old, that is. When I got the printer I was quite happy: it supports Postscript, it supports memory extension (which allowed me to go from the built-in 64MB to a whopping 320MB), it is networked and has automatic duplex. Not good for much more than document printing, but that it did well. I didn't print a lot on it (averaged it was well below the recommended monthly limit), which might explain the total trouble-free operation, but I did change the toner cartridges a couple of times. The current cartridges were running low for a while, but I didn't need to change them yet. As I printed a user manual at the beginning of the week (~300+ pages in total), I ran out of the black half-way through. Bought a new cartridge, installed it, and the first strange thing was that it still showed Black empty - please replace . I powered the printer off and turned it on again (the miracle cure for all IT-related things), and things seemed OK, so I restarted printing. However, this time, the printer was going through 20-30 pages, and then was getting stuck in "Printing document" with green led blinking. Waited for 20 minutes, nothing. So cancel the job (from the printer), restart printing, all fine. The next day I wanted to print a single page, and didn't manage to. Checked that the PDF is normal, checked an older PDF which I printed successfully before, nothing worked. Changed drivers, unseated & re-seated the extra memory, changed operating systems, nothing. Not even the built-in printer diagnostic pages were printing. The internet was all over with "HP formatter issues"; apparently some HP printers had "green" (i.e. low-quality) soldering, and were failing after a while. But people were complaining about 1-2-4 years, not 9 that my printer worked, and it was very suspicious that all troubles started after my cartridge replacement. Or, more likely, due to the recent sudden increase in printing. Given that formatter board fixes (bake in the oven for N minutes at a specific temperature to reflow the soldering) are temporary and that you can't find replacement parts for this printer, I started looking for a new printer. To my surprise (and dismay at the waste that capitalism produces), a new printer from a higher class was cheaper than replacing all 4 cartridges in my printer. So I had a 90% full black cartridge that I couldn't reuse, but I'd get a new printer for not much more. Interestingly, in 9 years, the development was: I was however happy that one can still get OS-independent (Postscript), networked printers that are small enough for home use and don't (necessarily) come with WiFi. However, one thing still bothered me: did I have such problems because the printer died of overwork at old age, or was it related to the cartridge change? So I start searching again, and I find a post on a forum (oh Google, why did you remove "forum search" and replaced it with "language level"?) that details a hidden procedure to format the internal storage of the printer, exactly for my printer model, exactly for my symptoms. Huh, I will lose page count, but this is worth a try So I do press the required keys, I see the printer booting and saying "erasing ", then asking for language, which makes me happy because it seems the forum post was correct in one regard. I confirm English, the printer reboots once more, and then when it comes up it warns me: "Yellow cartridge is a non-HP original, please confirm". I get confused, and re-seat all cartridges, to no avail. Yellow is non-HP. Sigh, maybe that cartridge had something that confused the printer? When I visit its web page however, all cartridges except the newly installed black one are marked as Non-HP; this only means that I can't see their remaining toner level, but otherwise the printer is restored back to life. I take the opportunity to also perform a firmware upgrade (only five years newer firmware, but still quite old), but this doesn't solve the Non-HP message. The printer works now, and I'm left wondering: was this all a DRM-related failure, something like new cartridge chip which had some new code that confused the printer so bad it needed reformatting, at which point the old cartridge code is no longer supported (for whatever reason)? Was it just a fluke, unrelated to DRM? Was the problem that I powered off the printer soon after replacing the cartridge, while it was still doing something (e.g. preparing to do a calibration after the change)? And another, more practical question: I have 3 cartridges to replace still; they were at 10% before this entire saga, and I'm not able to see their level anymore, but they'll get down to empty soon. The black cartridge in the printer is already at 77%, which is surprising as I didn't print that much. So should I replace the cartridges on what is a possibly fully functional, but also possibly a dying printer? Or buy a new one for slightly more, throwing out possibly good hardware? Even though I understand the business reason behind it, I hate the whole concept of "the printer is free, you pay for the ink". Though in my case "free" didn't mean bad, as a lifetime of 9 years is good enough for a printer.

Daniel Stender: How to cheat setuptools-scm (Debian diary)

[2016-12-19: some additions] This is another little issue from Python packaging for Debian which I came across lately packaging the compressed NumPy based data container Bcolz. Upstream uses setuptools-scm to determine the software s version during build time from the source code management environment the code is in. This method is convenient for the upstream development because with that the version number doesn t need to be hard-coded, and often people just forget to update that (and other version carrying files like doc/conf.py) when a new version of a project is released. python-setuptools just needs to be added to the setup.py to do its job, and in Bcolz the code goes like this:
setup(
    name="bcolz",
    use_scm_version= 
        'version_scheme': 'guess-next-dev',
        'local_scheme': 'dirty-tag',
        'write_to': 'bcolz/version.py'
The file the version number is written to is bcolz/version.py. This file isn t in the upstream code revision nor in the tarball which was released by the upstream developers, it s always generated during build time. In Debian there is an error if you try to build a package from a source tree which contains files which aren t to be found in the corresponding tarball, like cruft from a previous build, or if any files have changed therefore every new package should be test build also twice in a row in a non-chroot environment. Generally there a two ways to solve this, either you add cruft to debian/clean, or you add the file resp. a matching file pattern to extend-diff-ignore in debian/source/options. Which method is the better one could be discussed, I m generally using the clean option if something isn t in the upstream tarball, and the source/options solution if something is already in the upstream tarball, but gets changed during a build. This is related to your preferred Git procedures, if you remove a file which is in the upstream tarball these removals have to be checked in separately, and that means everytime a new upstream tarball is released that is not very convenient. Another option which is available is to strip certain files from the upstream tarball by putting them on the Files-Excluded in deb/copyright. By the way, the same complex applies to egg-info/: that folder is shipped or is not shipped in the upstream tarball, and files in that folder get changed during build. When the source code is put into a Git environment for Debian packaging, there could be problems with the version number setuptools-scm comes up with. This setuptools extension gets the recent version from the latest Git tag when there is a version number to be found, and that s all right. In Git environments for Debian packaging (like e.g. of the Debian Science group, the Python groups and the others) that is available, like the commonly used upstream tags have that1. The problem is, sometimes the upstream version which Debian has2 doesn t match the original upstream version number which is wanted for version in bcolz/version.py. For example, the suffix +ds is used if the upstream tarball has been stripped from prebuild files or embedded convenience shipments (like it s the case with the Bcolz package where c-blosc/ has been stripped because that s build for another package), of the suffix +dfsg shows that non-DFSG free software has been removed (which can t be distributed through the main archive section). For example, the version string for Bcolz which is found after the build currently (1.1.0+ds1-1) is 1.1.0+ds1:
# coding: utf-8
# file generated by setuptools_scm
# don't change, don't track in version control
version = '1.1.0+ds1'
But that s not wanted because this version never has been released, but appears everywhere:
$ pip list   grep bcolz
bcolz (1.1.0+ds1)
$ python3 -c 'import bcolz; bcolz.print_versions()'
-=-=-=-=-=-=-=-=-=-=-=-=-=-=-=-=-=-=-=-=-=-=-=-=-=-
bcolz version:     1.1.0+ds1
There are several different ways how to fix this. The one with the crowbar (like said in German) is to patch use_scm_version out from setup.py, but if you don t provide any version in exchange the version number which is used by Setuptools then is 0.0.0. The upstream version could be hard-coded into the patch, but then again it has not to be forgotten to update it manually by the maintainer, which is not very convenient. Plus, setup.py could change and the patch then might need to be unfuzzed, thus more work. Bad. A patch could be spared by manipulating and exporting the SETUPTOOLS_SCM_PRETEND_VERSION environment variable for setuptools-scm in debian/rules, which is sometimes used when I see the returns for that string on Debian Code Search. But how to prevent to hard code the version number, here? The dpkg-dev package (pulled by build-essential) ships a Makefile snippet /usr/share/dpkg/pkg-info.mk which could be included into debian/rules. It defines several variables which are useful for packaging, like DEB_SOURCE contains the source package name, they are extracted from debian/changelog. But, DEB_VERSION_UPSTREAM which is available through that puts out the upstream version without epoch and Debian revision, but it s not getting any finer grained out of the box. For a custom fix, a regular expression which removes the +... extensions (if present) from the bare upstream version string would be s/\+[^+]*//:
$ echo "1.1.0+ds1"   sed -e 's/\+[^+]*//'
1.1.0
$ echo "1.1.0"   sed -e 's/\+[^+]*//'
1.1.0
$ echo "1.1.0+dfsg12"   sed -e 's/\+[^+]*//'
1.1.0
With that, a custom variable VERSION_UPSTREAM could be set on the top of DEB_VERSION_UPSTREAM (from pkg-info.mk) in debian/rules:
include /usr/share/dpkg/pkg-info.mk
VERSION_UPSTREAM = $(shell echo '$(DEB_VERSION_UPSTREAM)'   sed -e 's/\+[^+]*//')
export SETUPTOOLS_SCM_PRETEND_VERSION = $(VERSION_UPSTREAM)
Bam, that works (see the commit here):
# coding: utf-8
# file generated by setuptools_scm
# don't change, don't track in version control
version = '1.1.0'
An addition, I ve seen that dh-python also takes care of SETUPTOOLS_SCM_PRETEND_VERSION since 2.20160609. The environment variable is set by the Debhelper build system if python 3, -setuptools-scm is among the build-dependencies in debian/control. The Perl code for that is in dh/pybuild.pm. I think the version number string above comes from dh-python s pretended version, and not from any of the Git tags (which are currently debian/1.1.0+ds1-1 and upstream/1.1.0+ds1).

  1. For Git in Debian packaging, e.g. see the DEP-14 proposal (Recommended layout for Git packaging repositories): http://dep.debian.net/deps/dep14/ [return]
  2. Following the scheme for package versions [epoch:]upstream_version[-debian-revision] [return]

Sean Whitton: progpoking

Programming by poking: why MIT stopped teaching SICP Perhaps there is a case for CS programs keeping pace with workplace technological changes (in addition to developments in the academic field of CS), but it seems sad to deprive undergrads of deeper knowledge about language design.

Dirk Eddelbuettel: RcppArmadillo 0.7.600.1.0

armadillo image Earlier this week, Conrad released Armadillo 7.600.1. The corresponding RcppArmadillo release 0.7.600.1.0 is now on CRAN and in Debian. This follows several of rounds testing at our end with a full reverse-dependency of a pre-release version followed by another full reverse-depency check. Which was of course followed by CRAN testing for two more days. Armadillo is a powerful and expressive C++ template library for linear algebra aiming towards a good balance between speed and ease of use with a syntax deliberately close to a Matlab. RcppArmadillo integrates this library with the R environment and language--and is widely used by (currently) 298 other packages on CRAN -- an increase of 24 just since the last CRAN release of 0.7.500.0.0 in October! Changes in this release relative to the previous CRAN release 0.7.500.0.0 are as follows:

Changes in RcppArmadillo version 0.7.600.1.0 (2016-12-16)
  • Upgraded to Armadillo release 7.600.1 (Coup d'Etat Deluxe)
    • more accurate eigs_sym() and eigs_gen()
    • expanded floor(), ceil(), round(), trunc(), sign() to handle sparse matrices
    • added arg(), atan2(), hypot()

Changes in RcppArmadillo version 0.7.500.1.0 (2016-11-11)
  • Upgraded to Armadillo release 7.500.1
  • Small improvement to return value treatment
  • The sample.h extension was updated to the newer Armadillo interface. (Closes #111)

Courtesy of CRANberries, there is a diffstat report. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Mike Gabriel: Free Your Phone, Free Yourself, Get Sponsored for your Work

TL;DR; This is a call to every FLOSS developer interested in working towards Free Software driven mobile phones, esp. targetting the Fairphone 2. If your only show stopper is lack of development hardware or lack of financial support, please go on reading below. As I see it, the Fairphone 2 will be (or already is) the FLOSS community platform on the mobile devices market. Regularly, I get new notice about people working on this or that OS port to the FP2 hardware platform. The combination of a hardware-wise sustainably maintained mobile phone platform and a Free (or sort-of-Free) operating system being ported to it, makes the Fairphone 2 a really attractive device. Personally, I run Sailfish OS on my Fairphone 2. Some weeks ago, I got contacted by one of my sponsors letting me know that he got involved in setting up an initiative that works on porting the Ubuntu Table/Phone OS to FP2. That very project is in need of more developers. Possibly, it needs exactly YOU!!! So, if you are a developer that meets one or more of the below requirements and are interested in working in a highly motivated team, please get in touch with the UT4FP [1] project (skill requirements taken from the UT4FP website): My sponsor offers to send out FP2 devices to (seriously) interested developers and if needed, he can also back up developers financially. If you are interested, please get in touch with me (and I'll channel you through...) via IRC (on the OFTC or Freenode network). light+love
Mike (aka sunweaver on IRC) [1] https://www.ut4fp.org/

B lint R czey: Hardening Debian Stretch with PIE is ready but bindnow will be missing

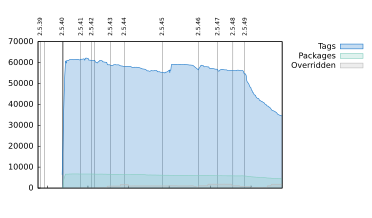
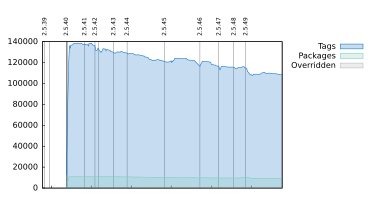
pie-bindnow-notnow-debianHardening all executables by making them position independent by default is basically ready with a few packages to fix (bugs). On the other hand bindnow is not enabled globally (#835146) and it seems it will not be for the next stable release despite my plan :-(. If you are a maintainer you can still have your packages hardened in Stretch by enabling bindnow per package before 25 January, 2017. It could be a nice present for your users! update: It is nice to see how enabling PIE in GCC increased PIE coverage while bindnow coverage is improving slowly with maintainers enabling it package by package:
lintian-pie

From https://lintian.debian.org/tags/hardening-no-pie.html

lintian-no-bindnow

From: https://lintian.debian.org/tags/hardening-no-bindnow.html

update 2: Changed the deadline of enabling bindnow per package to align with the start of the full freeze, not the soft freeze.

Johannes Schauer: Looking for self-hosted filesharing software

The owncloud package was removed from Debian unstable and testing. I am thus now looking for an alternative. Unfortunately, finding such replacement seems to be harder than I initially thought, even though I only use a very small subset of what owncloud provides. What I require is some software which allows me to:
  1. upload a directory of files of any type to my server (no "distributed" filesharing where I have to stay online with my laptop)
  2. share the content of that directory via HTTP (no requirement to install any additional software other than a web browser)
  3. let the share-links be private (no possibility to infer the location of other shares)
  4. allow users to browse that directory (image thumbnails or a photo gallery would be nice)
  5. allow me to allow anonymous users to upload their own content into that directory (also only requiring their web browser)
  6. already in Debian or easy to package and maintain due to low complexity (I don't have enough time to become the next "owncloud maintainer")
I thought this was a pretty simple task to solve but I am unable to find any software that fits above criteria. The below table shows the result of my research of what's currently available. The columns mark whether the respective software fulfills one of the six criteria from above.
Software 123456
owncloud
sparkleshare
dvcs-autosync
git annex assistant
syncthing
pydio
seafile
sandstorm.io
ipfs
bozon
droppy
Pydio, seafile and sandstorm.io look promising but they seem to be beasts similar in complexity to owncloud as they bring features like version tracking, office integration, wikis, synchronization across multiple devices or online editing of files which are features that I do not need. I would already be very happy if there was a script which would make it easy to create a hard-to-guess symlink to a directory with data tracked by git annex under my www-root and then generate some static HTML to provide a thumbnails view or a photo gallery. Unfortunately, even that solution would not be sufficient as it would still disallow public upload by anybody whom I would give the link to... If you know some software that meets my criteria or would like to submit corrections to above table, please shoot an email to josch@debian.org. Thanks!

17 December 2016

Shirish Agarwal: Demonetisation, Indian state and world

Queues get longer, patience runs out- Copyright Indian Express Group.

Queues get longer, patience runs out- Copyright Indian Express Group.

I dunno if people heard or didn t hear about the demonetisation of INR 500 and INR 1000 which happened in India on 8th November 2016 with new currency designed in India of INR 2000 and INR 500. What they did was from that moment onwards, paper currency of INR 500 and INR 1000 notes were declared invalid except few places (Government Hospitals, Petrol Pumps, Booking of Air and Train tickets) . The reasons given were as a. End of corruption There is/was suspicion that there are people who have loads of unaccounted wealth which they keep in the form of Cash in hand, b. Charge against fake/duplicate currency There is/was suspicion that quite a bit of the money esp, high value notes such as INR 500 and INR 1000, so having made them illegal, people had to hand over cash to banks and fake money would go outside the system. c. Terror funding This is related with the above point. There is a popular theory/myth/fact that terrorists use fake money to buy people, arms and ammunition while further devaluing the value of INR against dollar and basket of other high-value currencies that Indian currency follows/bases itself on. Each of these theories/myths/facts has been contested. Every day we are seeing and reading reports of people being caught with new currency in absurd numbers while RBI , our central bank and Lender of Last Resort has had to play multiple roles such as policing along with the country s Income Tax Department as well as pumping in new notes of the NEW INR 2000/- and INR 500/- into ATM s and Bank branches around the country. Now while the above may seem to be reasonable, there have been multiple factors which has made the whole exercise less effective while implementing a. Banking reach While India does and can boast of somewhat good indicators of banking reach . But Quarter of these accounts were opened only in the last couple of years under the Pradhan Mantri Jan Dhana Yojana . There are quite a few limitations of such accounts. It is a good scheme as if you develop a good rapport with a bank and show good credit/debit understanding then there is possibility to move to normal full-fledged bank account. Almost all of these accounts had zero-balances till the demonetization move. Many of these accounts are suspected to have been conduits to convert black money to white as the Govt. had said it will not scrutinize small savings bank accounts. Also many bank accounts historically have laid dormant over the years. One of my first jobs was of a data entry operator in a bank and I used to see hundreds of bank accounts lying dormant for years together. This was in bank digitization in early 90s. Small Savings accounts would not be scrutinized if they bring upto INR 250000 while Jan Dhan accounts have an upper limit of only INR 50000 . Even then, it has lead to a huge surge in balances specifically in Zero balances account. What begs the question is if it is their hard-earned money why hadn t they deposited money before 8th November 2016. While I can t speak about them, I can certainly speak about myself. I hardly keep at the most INR INR 5/10K for medical emergencies in-house for number of years. Unless you are a businessman who has need of cash or have some function, nobody that I know would keep such amounts in their homes, simply for the possibility of theft in homes. So how did such people who are not able to open a full-fledged saving account get access to such large amounts? In most public sector banks, to have a full-fledged savings account the only requirements are a. Have INR 500 to 1000 as balance at all times.
b. Have permanent identity and residential proof
c. Two photographs
d. 2-3 people who are account holders who can act as guarantor. Of the above, b. and d. are probably sticking points for most migrants, while d. may be a sticking point for labourers, craftsman etc. hence the need for that specific scheme. Which leads to the natural suspicion that they may have been white-washing somebody s untaxed, unaccounted money which is being put into bank and made into legitimate white money. People do not have to file an Income Tax Return (ITR) unless they earn more than 250,000 in a single financial year. One good off-shot of the scheme though is the transparency gained about Bank Mitras b. Number of banks, quality of Bank services, number of people per bank at least in Nationalized Banks leaves much to be desired. We can t even try to compare with other BRIC countries, leave alone Germany.
Mobile ATM - Copyright - PTI

Mobile ATM Copyright PTI

One another positive off-shoot has been the introduction of Mobile ATM Vans around the country. I had experienced such vans in Mumbai since ages, but not anywhere else. I do hope that both Bank Mitras as well as such Van Mobile ATMs happen more. There are huge swathes of people who are currently unbanked. Getting them into the banking infrastructure, getting them to *think* about taking rational financial decisions, i.e. saving and spending, different types of saving etc. should not make citizens and the banking systems more productive and efficient, but hopefully improves our GDP and make it more resilient to any outside financial shocks. c. Many bank websites have everything in English. That norm needs to change. I do have few queries though, one of the countries who is supposed to be a prominent supporter and user of cashless society is supposed to be Canada. Could any Canadians (also because debconf is going to happen in Canada in 2017) share how and if they had seen the Canadian banking system evolve in their country ? Also how much of Canada s economy is cashless i.e used to Electronic Money Transfer and other means (but not cash) and how much is cash, more in day-to-day usage and transactions. I am trying to get people s perspective rather than some website which may serve only raw numbers, although even that would be appreciable. Also what, if any charges/commission are paid to a Canadian bank for paying via card/electronic money transfer. I ask as India has reduced charges overall to 1% from 2% for making transactions upto INR 2000 in a day. There has also been recent talk of plastic notes instead of paper currency. Plastic notes are supposed to be more copy-proof and also will work for much longer time. They will not soil as paper notes do. How have countries been looking at Plastic currencies. I do suspect there would be issues while destroying plastic money vis-a-vis paper currencies. A sort of interesting discussion that I had with Bernelle before venturing into South Africa was asking her about monetary transactions in SA. She had replied that the highest denomination notes was 200 ZAR which is roughly equal to ( ZAR 200 x 5 = INR 1000) . What is/was interesting that Bernelle told me to be careful and as far as possible not to show 200 ZAR note, whereas in India, even the cheapest worker I have met, they have seen and used INR 1000 note. The context of the discussion was being safe in South Africa and doing transactions with people around as to what works. It would be curiouser to know how things work in Canada for instance ? Also has Canada or any other country have experimented with plastic notes. If yes, how has the experience been ? I would have to say this is in no way a definitive guide of the different impressions and repercussion that the decision and the way it s playing out even now. Another thing, while researching for the article there were lots of interesting knowledge, for e.g. the Big Mac Index and it s limitations which I didn t know how to integrate into the decision and Policy taken. I also came to know/saw that lots of Policy initiatives being taken by the current (NDA)Government is similar to initiatives taken elsewhere in the world.. Whether the Policy would be fruitful in getting the desired outcome or would it lead to more chaos and down-turn will know in next quarter only. It would be nice and interesting if people have observed something similar in their country s economic policies as well.
Filed under: Miscellenous Tagged: #Bank Mitra, #Bank reach, #blackmoney, #debconf17, #Demonetisation, #fake currencies, #full-fledged savings account, #Jan Dhan scheme, #Moile ATM Van, #Plastic money, #Public Sector Banks (PSB), #Reserve Bank of India, Big Mac Index

Russ Allbery: INN 2.6.1

(As usual, Julien finished this release a bit back, and then I got busy with life stuff and haven't gotten the announcement out.) This is a bug-fix and minor feature release over INN 2.6.0. The biggest change is adding support for the new COMPRESS extension. It also fixes various bugs around state changes when negotiating various compression or integrity layers and fixes some issues with nnrpd's validation of newly-posted messages. (Messages with Received and Posted headers are no longer rejected; messages with all-whitespace headers now are.) This release also supports OpenSSL 1.1.0 and fixes an nntpsend bug under systemd. As always, thanks to Julien LIE for preparing this release and doing most of the maintenance work on INN! You can get the latest version from the official ISC download page or from my personal INN pages. The latter also has links to the full changelog and the other INN documentation.

16 December 2016

Dimitri John Ledkov: Swapfiles by default in Ubuntu

4MB RAM card
By default, in Ubuntu, we usually create a swap partition.

Back in the day of 4MB RAM cards this made total sense, as the ration of RAM to disk space, was still very low. Things have changed since. Server, desktop, embedded systems have migrated to newer generations of both RAM and persistent storage. On the high performance side of things we see machines with faster storage in the form of NVMe and SSD drives. Reserving space for swap on such storage, can be seen as expensive and wasteful. This is also true for recent enough laptops and desktops too. Mobile phones have substantial amounts of RAM these days, and at times, coupled with eMMC storage - it is flash storage of lower performance, which have limited number of write cycles, hence should not be overused for volatile swap data. And there are also unicorns in a form of high performance computing of high memory (shared memory) systems with little or no disk space.

Today, carving a partition and reserving twice the RAM size for swap makes little sense. For a common, general, machine most of the time this swap will not be used at all. Or if said swap space is in use but is of inappropriate size, changing it in-place in retrospect is painful.

Starting from 17.04 Zesty Zapus release, instead of creating swap partitions, swapfiles will be used by default for non-lvm based installations.

Secondly, the sizing of swapfiles is very different. It is no more than 5% of free disk space or 2GiB, whichever is lower.

For preseeding, there are two toggles that control this behavior:
  • d-i partman-swapfile/percentage string 5
  • d-i partman-swapfile/size string 2048
Setting either of those to zero, will result in system without any swap at all. And one can tweak relative integer percentage points and absolute limits in integer percentage points or MiB.

On LVM based installations, swap logical volumes are used, since unfortunately LVM snapshots do not exclude swapfile changes. However, I would like to move partman-auto to respect the above proposed 5%-or-2GB limits.

Ps. 4MB RAM card picture is by Bub's (Photo) [GFDL or CC-BY-SA-3.0], via Wikimedia Commons

Dirk Eddelbuettel: nanotime 0.0.1: New package for Nanosecond Resolution Time for R

R has excellent tools for dates and times. The Date and POSIXct classes (as well as the 'wide' representation in POSIXlt) are versatile, and a lot of useful tooling has been built around them. However, POSIXct is implemented as a double with fractional seconds since the epoch. Given the 53 bits accuracy, it leaves just a bit less than microsecond resolution. Which is good enough for most things. But more and more performance measurements, latency statistics, ... are now measured more finely, and we need nanosecond resolution. For which commonly an integer64 is used to represent nanoseconds since the epoch. And while R does not a native type for this, the bit64 package by Jens Oehlschl gel offers a performant one implemented as a lightweight S3 class. So this package uses this integer64 class, along with two helper functions for parsing and formatting, respectively, at nano-second resolution from the RcppCCTZ package which wraps the CCTZ library from Google. CCTZ is a modern C++11 library extending the (C++11-native) chrono type.

Examples

Simple Parsing and Arithmetic
R> x <- nanotime("1970-01-01T00:00:00.000000001+00:00")
R> print(x)
integer64
[1] 1
R> format(x)
[1] "1970-01-01T00:00:00.000000001+00:00"
R> cat("x+1 is: ")
x+1 is: R> x <- x + 1
R> print(x)
integer64
[1] 2
R> format(x)
[1] "1970-01-01T00:00:00.000000002+00:00"
R>

Vectorised
R> options("width"=60)
R> v <- nanotime(Sys.time()) + 1:5
R> v
integer64
[1] 1481505724483583001 1481505724483583002
[3] 1481505724483583003 1481505724483583004
[5] 1481505724483583005
R> format(v)
[1] "2016-12-12T01:22:04.483583001+00:00"
[2] "2016-12-12T01:22:04.483583002+00:00"
[3] "2016-12-12T01:22:04.483583003+00:00"
[4] "2016-12-12T01:22:04.483583004+00:00"
[5] "2016-12-12T01:22:04.483583005+00:00"
R> 

Use with zoo
R> z <- zoo(cbind(A=1:5, B=5:1), v)
R> options("nanotimeFormat"="%d %b %H:%M:%E*S")  ## override default
R> z
                          A B
12 Dec 01:47:55.812513001 1 5
12 Dec 01:47:55.812513002 2 4
12 Dec 01:47:55.812513003 3 3
12 Dec 01:47:55.812513004 4 2
12 Dec 01:47:55.812513005 5 1
R> 

Technical Details The bit64 package (by Jens Oehlschl gel) supplies the integer64 type used to store the nanosecond resolution time as (positive or negative) offsets to the epoch of January 1, 1970. The RcppCCTZ package supplies the formatting and parsing routines based on the (modern C++) library CCTZ from Google.

Status Version 0.0.1 has now been released. It works with some other packages, notably zoo and data.table. It (at least currently) requires RcppCCTZ to parse and format nanosecond resolution time objects from / to text --- and this package is on Linux and OS X only due to its use of system time zoneinfo. The requirement could be relaxed in the future by rewriting formating and parsing code. Contributions are welcome.

Installation The package is not yet on CRAN. Until it gets there, or to install the development versions, it can also be installed via a standard
install.packages("RcppCCTZ")   # need 0.1.0 or later
remotes::install_github("eddelbuettel/nanotime")  
If you prefer install.packages() (as I do), use the version from the ghrr drat:
install.packages("drat")       # easier repo access + creation
drat:::add("ghrr")             # make it known
install.packages("nanotime")   # install it
If and when it gets to CRAN you will be able to do
install.packages("nanotime")

Contact For questions or comments use the issue tracker off the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Rapha&#235;l Hertzog: Freexian s report about Debian Long Term Support, November 2016

A Debian LTS logoLike each month, here comes a report about the work of paid contributors to Debian LTS. Individual reports In October, about 150 work hours have been dispatched among 14 paid contributors. Their reports are available: Evolution of the situation The number of sponsored hours did not change this month and in fact we haven t had any new sponsor since September. We still need a couple of supplementary sponsors to reach our objective of funding the equivalent of a full time position. The security tracker currently lists 40 packages with a known CVE and the dla-needed.txt file 36. We don t seem to really catch up the small backlog. The reasons are not clear but I noticed that there are a few packages that take a lot of time due to the number of issues found with fuzzers. We also handle many issues that the security team ends up classifying as not worth an update because we add the package to dla-needed.txt before the security team has done its review and nobody checks afterwards. Thanks to our sponsors New sponsors are in bold.

No comment Liked this article? Click here. My blog is Flattr-enabled.

Michal &#268;iha&#345;: wlc 0.7

wlc 0.7, a command line utility for Weblate, has been just released. There are several new commands like translation file download or statistics fetching. Full list of changes: wlc is built on API introduced in Weblate 2.6 and still being in development, you need Weblate 2.10 for some feature (already available on our hosting offering). You can find usage examples in the wlc documentation.

Filed under: Debian English phpMyAdmin SUSE Weblate 2 comments

15 December 2016

Steve Kemp: A simple Perl alternative to storing data in Redis

I continue to be a big user of Perl, and for many of my sites I avoid the use of MySQL which means that I largely store data in flat files, SQLite databases, or in memory via Redis. One of my servers was recently struggling with RAM, and the suprising cause was "too much data" in Redis. (Surprising because I'd not been paying attention and seen how popular it was, and also because ASCII text compresses pretty well). Read/Write speed isn't a real concern, so I figured I'd move the data into an SQLite database, but that would require rewriting the application. The client library for Perl is pretty awesome, and simple usage looks like this:
# Connect to localhost.
my $r = Redis->new()
# simple storage
$r->set( "key", "value" );
# Work with sets
$r->sadd( "fruits", "orange" );
$r->sadd( "fruits", "apple" );
$r->sadd( "fruits", "blueberry" );
$r->sadd( "fruits", "banannanananananarama" );
# Show the set-count
print "There are " . $r->scard( "fruits" ) . " known fruits";
# Pick a random one
print "Here is a random one " . $r->srandmember( "fruits" ) . "\n";
I figured, if I ignored the Lua support and the other more complex operations, creating a compatible API implementation wouldn't be too hard. So rather than porting my application to using SQLite directly I could juse use a different client-library. In short I change this:
use Redis;
my $r = Redis->new();
To this:
use Redis::SQLite;
my $r = Redis::SQLite->new();
And everything continues to work. I've implemented all the set-related functions except one, and a random smattering of the other simple operations. The appropriate test-cases in the Redis client library (i.e. removing all references to things I didn't implement) pass, and my own new tests also make me confident. It's obviously not a hard job, but it was a quick solution to a real problem and might be useful to others. My image hosting site, and my markdown sharing site now both use this wrapper and seem to be performing well - but with more free RAM. No doubt I'll add more of the simple primitives as time goes on, but so far I've done enough to be useful.

Reproducible builds folks: Reproducible Builds: week 85 in Stretch cycle

What happened in the Reproducible Builds effort between Sunday December 4 and Saturday December 10 2016: Toolchain development and fixes Anders Kaseorg opened a pull request to asciidoc upstream, to make it generate reproducible documentation. (#782294) Bugs filed Chris Lamb: Clint Adams: Dafydd Harries: Robbie Harwood: Valerie R Young: Reviews of unreproducible packages 47 package reviews have been added, 84 have been updated and 3 have been removed in this week, adding to our knowledge about identified issues. 1 new issue type has been added: lessc_captures_build_path Weekly QA work During our reproducibility testing, some FTBFS bugs have been detected and reported by: diffoscope development Chris Lamb fixed a division-by-zero in the progress bar, split out trydiffoscope into a separate package, and made some performance enhancements. Maria Glukhova fixed build issues with Python 3.4 strip-nondeterminism development Anders Kaseorg added support for .par files, by allowing them to be treated as Zip archives; and Chris Lamb improved some documentation. reprotest development Ximin Luo added the ability to vary the build time using faketime, as well as other code quality improvements and cleanups. He also discovered a little-known fact about faketime - that it also modifies filesystem timestamps by default. He submitted a PR to libfaketime upstream to improve the documentation on this, which was quickly accepted, and also disabled this feature in reprotest's own usage of faketime. buildinfo.debian.net development There was further work on buildinfo.debian.net code. Chris Lamb added support for buildinfo format 0.2 and made rejection notices clearer; and Emanuel Bronshtein fixed some links to use HTTPS. Misc. This week's edition was written by Ximin Luo and reviewed by a bunch of Reproducible Builds folks on IRC and via email.

Jamie McClelland: Should we be pushing OpenPGP?

Bjarni R nar, the author of Mailpile released a blog about recent blogs disparaging OpenPGP. It's a good read. There's one reason to support OpenPGP missing from the blog: OpenPGP protects you if your mail server is hacked. I'm sure that Debbie Wasserman Schultz wishes she had been using OpenPGP. Having said all of this... OpenPGP didn't make my recent list of security tips. That ommission is for two reasons:

Michal &#268;iha&#345;: Weblate 2.10

Quite on the schedule, Weblate 2.10 is out today. This release brings Git exporter module, improves support for machine translation services and adds various CSV exports and API interfaces. Full list of changes: If you are upgrading from older version, please follow our upgrading instructions. You can find more information about Weblate on https://weblate.org, the code is hosted on Github. If you are curious how it looks, you can try it out on demo server. You can login there with demo account using demo password or register your own user. Weblate is also being used on https://hosted.weblate.org/ as official translating service for phpMyAdmin, OsmAnd, Aptoide, FreedomBox, Weblate itself and many other projects. Should you be looking for hosting of translations for your project, I'm happy to host them for you or help with setting it up on your infrastructure. Further development of Weblate would not be possible without people providing donations, thanks to everybody who have helped so far! The roadmap for next release is just being prepared, you can influence this by expressing support for individual issues either by comments or by providing bounty for them.

Filed under: Debian English phpMyAdmin SUSE Weblate 0 comments

14 December 2016

Carl Chenet: Feed2tweet 0.8, tool to post RSS feeds to Twitter, released

Feed2tweet 0.8, a self-hosted Python app to automatically post RSS feeds to the Twitter social network, was released this December, 14th. With this release Feed2tweet now smartly manages the hashtags, adding as much as possible given the size of the tweet. Also 2 new options are available : Feed2tweet 0.8 is already in production for Le Journal du hacker, a French-speaking Hacker News-like website, LinuxJobs.fr, a French-speaking job board and this very blog. fiesta What s the purpose of Feed2tweet? Some online services offer to convert your RSS entries into Twitter posts. Theses services are usually not reliable, slow and don t respect your privacy. Feed2tweet is Python self-hosted app, the source code is easy to read and you can enjoy the official documentation online with lots of examples. Twitter Out Of The Browser Have a look at my Github account for my other Twitter automation tools: What about you? Do you use tools to automate the management of your Twitter account? Feel free to give me feedback in the comments below.

Antoine Beaupr : Debian considering automated upgrades

The Debian project is looking at possibly making automatic minor upgrades to installed packages the default for newly installed systems. While Debian has a reliable and stable package update system that has been an inspiration for multiple operating systems (the venerable APT), upgrades are, usually, a manual process on Debian for most users. The proposal was brought up during the Debian Cloud sprint in November by longtime Debian Developer Steve McIntyre. The rationale was to make sure that users installing Debian in the cloud have a "secure" experience by default, by installing and configuring the unattended-upgrades package within the images. The unattended-upgrades package contains a Python program that automatically performs any pending upgrade and is designed to run unattended. It is roughly the equivalent of doing apt-get update; apt-get upgrade in a cron job, but has special code to handle error conditions, warn about reboots, and selectively upgrade packages. The package was originally written for Ubuntu by Michael Vogt, a longtime Debian developer and Canonical employee. Since there was a concern that Debian cloud images would be different from normal Debian installs, McIntyre suggested installing unattended-upgrades by default on all Debian installs, so that people have a consistent experience inside and outside of the cloud. The discussion that followed was interesting as it brought up key issues one would have when deploying automated upgrade tools, outlining both the benefits and downsides to such systems.

Problems with automated upgrades An issue raised in the following discussion is that automated upgrades may create unscheduled downtime for critical services. For example, certain sites may not be willing to tolerate a master MySQL server rebooting in conditions not controlled by the administrators. The consensus seems to be that experienced administrators will be able to solve this issue on their own, or are already doing so. For example, Noah Meyerhans, a Debian developer, argued that "any reasonably well managed production host is going to be driven by some kind of configuration management system" where competent administrators can override the defaults. Debian, for example, provides the policy-rc.d mechanism to disable service restarts on certain packages out of the box. unattended-upgrades also features a way to disable upgrades on specific packages that administrators would consider too sensitive to restart automatically and will want to schedule during maintenance windows. Reboots were another issue discussed: how and when to deploy kernel upgrades? Automating kernel upgrades may mean data loss if the reboot happens during a critical operation. On Debian systems, the kernel upgrade mechanisms already provide a /var/run/reboot-required flag file that tools can monitor to notify users of the required reboot. For example, some desktop environments will popup a warning prompting users to reboot when the file exists. Debian doesn't currently feature an equivalent warning for command-line operation: Vogt suggested that the warning could be shown along with the usual /etc/motd announcement. The ideal solution here, of course, is reboot-less kernel upgrades, which is also known as "live patching" the kernel. Unfortunately, this area is still in development in the kernel (as was previously discussed here). Canonical deployed the feature for the Ubuntu 16.04 LTS release, but Debian doesn't yet have such capability, since it requires extra infrastructure among other issues. Furthermore, system reboots are only one part of the problem. Currently, upgrading packages only replaces the code and restarts the primary service shipped with a given package. On library upgrades, however, dependent services may not necessarily notice and will keep running with older, possibly vulnerable, libraries. While libc6, in Debian, has special code to restart dependent services, other libraries like libssl do not notify dependent services that they need to restart to benefit from potentially critical security fixes. One solution to this is the needrestart package which inspects all running processes and restarts services as necessary. It also covers interpreted code, specifically Ruby, Python, and Perl. In my experience, however, it can take up to a minute to inspect all processes, which degrades the interactivity of the usually satisfying apt-get install process. Nevertheless, it seems like needrestart is a key component of a properly deployed automated upgrade system.

Benefits of automated upgrades One thing that was less discussed is the actual benefit of automating upgrades. It is merely described as "secure by default" by McIntyre in the proposal, but no one actually expanded on this much. For me, however, it is now obvious that any out-of-date system will be systematically attacked by automated probes and may be taken over to the detriment of the whole internet community, as we are seeing with Internet of Things devices. As Debian Developer Lars Wirzenius said:
The ecosystem-wide security benefits of having Debian systems keep up to date with security updates by default overweigh any inconvenience of having to tweak system configuration on hosts where the automatic updates are problematic.
One could compare automated upgrades with backups: if they are not automated, they do not exist and you will run into trouble without them. (Wirzenius, coincidentally, also works on the Obnam backup software.) Another benefit that may be less obvious is the acceleration of the feedback loop between developers and users: developers like to know quickly when an update creates a regression. Automation does create the risk of a bad update affecting more users, but this issue is already present, to a lesser extent, with manual updates. And the same solution applies: have a staging area for security upgrades, the same way updates to Debian stable are first proposed before shipping a point release. This doesn't have to be limited to stable security updates either: more adventurous users could follow rolling distributions like Debian testing or unstable with unattended upgrades as well, with all the risks and benefits that implies.

Possible non-issues That there was not a backlash against the proposal surprised me: I expected the privacy-sensitive Debian community to react negatively to another "phone home" system as it did with the Django proposal. This, however, is different than a phone home system: it merely leaks package lists and one has to leak that information to get the updated packages. Furthermore, privacy-sensitive administrators can use APT over Tor to fetch packages. In addition, the diversity of the mirror infrastructure makes it difficult for a single entity to profile users. Automated upgrades do imply a culture change, however: administrators approve changes only a posteriori as opposed to deliberately deciding to upgrade parts they chose. I remember a time when I had to maintain proprietary operating systems and was reluctant to enable automated upgrades: such changes could mean degraded functionality or additional spyware. However, this is the free-software world and upgrades generally come with bug fixes and new features, not additional restrictions.

Automating major upgrades? While automating minor upgrades is one part of the solution to the problem of security maintenance, the other is how to deal with major upgrades. Once a release becomes unsupported, security issues may come up and affect older software. While Debian LTS extends releases lifetimes significantly, it merely delays the inevitable major upgrades. In the grand scheme of things, the lifetimes of Linux systems (Debian: 3-5 years, Ubuntu: 1-5 years) versus other operating systems (Solaris: 10-15 years, Windows: 10+ years) is fairly short, which makes major upgrades especially critical. While major upgrades are not currently automated in Debian, they are usually pretty simple: edit sources.list then:
    # apt-get update && apt-get dist-upgrade
But the actual upgrade process is really much more complex. If you run into problems with the above commands, you will quickly learn that you should have followed the release notes, a whopping 20,000-word, ten-section document that outlines all the gory details of the release. This is a real issue for large deployments and for users unfamiliar with the command line. The solutions most administrators seem to use right now is to roll their own automated upgrade process. For example, the Debian.org system administrators have their own process for the "jessie" (8.0) upgrade. I have also written a specification of how major upgrades could be automated that attempts to take into account the wide variety of corner cases that occur during major upgrades, but it is currently at the design stage. Therefore, this problem space is generally unaddressed in Debian: Ubuntu does have a do-release-upgrade command but it is Ubuntu-specific and would need significant changes in order to work in Debian.

Future work Ubuntu currently defaults to "no automation" but, on install, invites users to enable unattended-upgrades or Landscape, a proprietary system-management service from Canonical. According to Vogt, the company supports both projects equally as they differ in scope: unattended-upgrades just upgrades packages while Landscape aims at maintaining thousands of machines and handles user management, release upgrades, statistics, and aggregation. It appears that Debian will enable unattended-upgrades on the images built for the cloud by default. For regular installs, the consensus that has emerged points at the Debian installer prompting users to ask if they want to disable the feature as well. One reason why this was not enabled before is that unattended-upgrades had serious bugs in the past that made it less attractive. For example, it would simply fail to follow security updates, a major bug that was fortunately promptly fixed by the maintainer. In any case, it is important to distribute security and major upgrades on Debian machines in a timely manner. In my long experience in professionally administering Unix server farms, I have found the upgrade work to be a critical but time-consuming part of my work. During that time, I successfully deployed an automated upgrade system all the way back to Debian woody, using the simpler cron-apt. This approach is, unfortunately, a little brittle and non-standard; it doesn't address the need of automating major upgrades, for which I had to revert to tools like cluster-ssh or more specialized configuration management tools like Puppet. I therefore encourage any effort towards improving that process for the whole community. More information about the configuration of unattended-upgrades can be found in the Ubuntu documentation or the Debian wiki.
Note: this article first appeared in the Linux Weekly News.

Antoine Beaupr : Django debates privacy concern

In recent years, privacy issues have become a growing concern among free-software projects and users. As more and more software tasks become web-based, surveillance and tracking of users is also on the rise. While some software may use advertising as a source of revenue, which has the side effect of monitoring users, the Django community recently got into an interesting debate surrounding a proposal to add user tracking actually developer tracking to the popular Python web framework.

Tracking for funding A novel aspect of this debate is that the initiative comes from concerns of the Django Software Foundation (DSF) about funding. The proposal suggests that "relying on the free labor of volunteers is ineffective, unfair, and risky" and states that "the future of Django depends on our ability to fund its development". In fact, the DSF recently hired an engineer to help oversee Django's development, which has been quite successful in helping the project make timely releases with fewer bugs. Various fundraising efforts have resulted in major new Django features, but it is difficult to attract sponsors without some hard data on the usage of Django. The proposed feature tries to count the number of "unique developers" and gather some metrics of their environments by using Google Analytics (GA) in Django. The actual proposal (DEP 8) is done as a pull request, which is part of Django Enhancement Proposal (DEP) process that is similar in spirit to the Python Enhancement Proposal (PEP) process. DEP 8 was brought forward by a longtime Django developer, Jacob Kaplan-Moss. The rationale is that "if we had clear data on the extent of Django's usage, it would be much easier to approach organizations for funding". The proposal is essentially about adding code in Django to send a certain set of metrics when "developer" commands are run. The system would be "opt-out", enabled by default unless turned off, although the developer would be warned the first time the phone-home system is used. The proposal notes that an opt-in system "severely undercounts" and is therefore not considered "substantially better than a community survey" that the DSF is already doing.

Information gathered The pieces of information reported are specifically designed to run only in a developer's environment and not in production. The metrics identified are, at the time of writing:
  • an event category (the developer commands: startproject, startapp, runserver)
  • the HTTP User-Agent string identifying the Django, Python, and OS versions
  • a user-specific unique identifier (a UUID generated on first run)
The proposal mentions the use of the GA aip flag which, according to GA documentation, makes "the IP address of the sender 'anonymized'". It is not quite clear how that is done at Google and, given that it is a proprietary platform, there is no way to verify that claim. The proposal says it means that "we can't see, and Google Analytics doesn't store, your actual IP". But that is not actually what Google does: GA stores IP addresses, the documentation just says they are anonymized, without explaining how. GA is presented as a trade-off, since "Google's track record indicates that they don't value privacy nearly as high" as the DSF does. The alternative, deploying its own analytics software, was presented as making sustainability problems worse. According to the proposal, Google "can't track Django users. [...] The only thing Google could do would be to lie about anonymizing IP addresses, and attempt to match users based on their IPs". The truth is that we don't actually know what Google means when it "anonymizes" data: Jannis Leidel, a Django team member, commented that "Google has previously been subjected to secret US court orders and was required to collaborate in mass surveillance conducted by US intelligence services" that limit even Google's capacity of ensuring its users' anonymity. Leidel also argued that the legal framework of the US may not apply elsewhere in the world: "for example the strict German (and by extension EU) privacy laws would exclude the automatic opt-in as a lawful option". Furthermore, the proposal claims that "if we discovered Google was lying about this, we'd obviously stop using them immediately", but it is unclear exactly how this could be implemented if the software was already deployed. There are also concerns that an implementation could block normal operation, especially in countries (like China) where Google itself may be blocked. Finally, some expressed concerns that the information could constitute a security problem, since it would unduly expose the version number of Django that is running.

In other projects Django is certainly not the first project to consider implementing analytics to get more information about its users. The proposal is largely inspired by a similar system implemented by the OS X Homebrew package manager, which has its own opt-out analytics. Other projects embed GA code directly in their web pages. This is apparently the option chosen by the Oscar Django-based ecommerce solution, but that was seen by the DSF as less useful since it would count Django administrators and wasn't seen as useful as counting developers. Wagtail, a Django-based content-management system, was incorrectly identified as using GA directly, as well. It actually uses referrer information to identify installed domains through the version updates checks, with opt-out. Wagtail didn't use GA because the project wanted only minimal data and it was worried about users' reactions. NPM, the JavaScript package manager, also considered similar tracking extensions. Laurie Voss, the co-founder of NPM, said it decided to completely avoid phoning home, because "users would absolutely hate it". But NPM users are constantly downloading packages to rebuild applications from scratch, so it has more complete usage metrics, which are aggregated and available via a public API. NPM users seem to find this is a "reasonable utility/privacy trade". Some NPM packages do phone home and have seen "very mixed" feedback from users, Voss said. Eric Holscher, co-founder of Read the Docs, said the project is considering using Sentry for centralized reporting, which is a different idea, but interesting considering Sentry is fully open source. So even though it is a commercial service (as opposed to the closed-source Google Analytics), it may be possible to verify any anonymity claims.

Debian's response Since Django is shipped with Debian, one concern was the reaction of the distribution to the change. Indeed, "major distros' positions would be very important for public reception" to the feature, another developer stated. One of the current maintainers of Django in Debian, Rapha l Hertzog, explicitly stated from the start that such a system would "likely be disabled by default in Debian". There were two short discussions on Debian mailing lists where the overall consensus seemed to be that any opt-out tracking code was undesirable in Debian, especially if it was aimed at Google servers. I have done some research to see what, exactly, was acceptable as a phone-home system in the Debian community. My research has revealed ten distinct bug reports against packages that would unexpectedly connect to the network, most of which were not directly about collecting statistics but more often about checking for new versions. In most cases I found, the feature was disabled. In the case of version checks, it seems right for Debian to disable the feature, because the package cannot upgrade itself: that task is delegated to the package manager. One of those issues was the infamous "OK Google" voice activation binary blog controversy that was previously reported here and has since then been fixed (although other issues remain in Chromium). I have also found out that there is no clearly defined policy in Debian regarding tracking software. What I have found, however, is that there seems to be a strong consensus in Debian that any tracking is unacceptable. This is, for example, an extract of a policy that was drafted (but never formally adopted) by Ian Jackson, a longtime Debian developer:
Software in Debian should not communicate over the network except: in order to, and as necessary to, perform their function[...]; or for other purposes with explicit permission from the user.
In other words, opt-in only, period. Jackson explained that "when we originally wrote the core of the policy documents, the DFSG [Debian Free Software Guidelines], the SC [Social Contract], and so on, no-one would have considered this behaviour acceptable", which explains why no explicit formal policy has been adopted yet in the Debian project. One of the concerns with opt-out systems (or even prompts that default to opt-in) was well explained back then by Debian developer Bas Wijnen:
It very much resembles having to click through a license for every package you install. One of the nice things about Debian is that the user doesn't need to worry about such things: Debian makes sure things are fine.
One could argue that Debian has its own tracking systems. For example, by default, Debian will "phone home" through the APT update system (though it only reports the packages requested). However, this is currently not automated by default, although there are plans to do so soon. Furthermore, Debian members do not consider APT as tracking, because it needs to connect to the network to accomplish its primary function. Since there are multiple distributed mirrors (which the user gets to choose when installing), the risk of surveillance and tracking is also greatly reduced. A better parallel could be drawn with Debian's popcon system, which actually tracks Debian installations, including package lists. But as Barry Warsaw pointed out in that discussion, "popcon is 'opt-in' and [...] the overwhelming majority in Debian is in favour of it in contrast to 'opt-out'". It should be noted that popcon, while opt-in, defaults to "yes" if users click through the install process. [Update: As pointed out in the comments, popcon actually defaults to "no" in Debian.] There are around 200,000 submissions at this time, which are tracked with machine-specific unique identifiers that are submitted daily. Ubuntu, which also uses the popcon software, gets around 2.8 million daily submissions, while Canonical estimates there are 40 million desktop users of Ubuntu. This would mean there is about an order of magnitude more installations than what is reported by popcon. Policy aside, Warsaw explained that "Debian has a reputation for taking privacy issues very serious and likes to keep it".

Next steps There are obviously disagreements within the Django project about how to handle this problem. It looks like the phone-home system may end up being implemented as a proxy system "which would allow us to strip IP addresses instead of relying on Google to anonymize them, or to anonymize them ourselves", another Django developer, Aymeric Augustin, said. Augustin also stated that the feature wouldn't "land before Django drops support for Python 2", which is currently estimated to be around 2020. It is unclear, then, how the proposal would resolve the funding issues, considering how long it would take to deploy the change and then collect the information so that it can be used to spur the funding efforts. It also seems the system may explicitly prompt the user, with an opt-out default, instead of just splashing a warning or privacy agreement without a prompt. As Shai Berger, another Django contributor, stated, "you do not get [those] kind of numbers in community surveys". Berger also made the argument that "we trust the community to give back without being forced to do so"; furthermore:
I don't believe the increase we might get in the number of reports by making it harder to opt-out, can be worth the ill-will generated for people who might feel the reporting was "sneaked" upon them, or even those who feel they were nagged into participation rather than choosing to participate.
Other options may also include gathering metrics in pip or PyPI, which was proposed by Donald Stufft. Leidel also proposed that the system could ask to opt-in only after a few times the commands are called. It is encouraging to see that a community can discuss such issues without heating up too much and shows great maturity for the Django project. Every free-software project may be confronted with funding and sustainability issues. Django seems to be trying to address this in a transparent way. The project is willing to engage with the whole spectrum of the community, from the top leaders to downstream distributors, including individual developers. This practice should serve as a model, if not of how to do funding or tracking, at least of how to discuss those issues productively. Everyone seems to agree the point is not to surveil users, but improve the software. As Lars Wirzenius, a Debian developer, commented: "it's a very sad situation if free software projects have to compromise on privacy to get funded". Hopefully, Django will be able to improve its funding without compromising its principles.
Note: this article first appeared in the Linux Weekly News.

Next.

Previous.