Search Results: "xam"

16 August 2023

Wouter Verhelst: Perl test suites in GitLab

I've been maintaining a number of Perl software packages recently. There's SReview, my video review and transcoding system of which I split off Media::Convert a while back; and as of about a year ago, I've also added PtLink, an RSS aggregator (with future plans for more than just that). All these come with extensive test suites which can help me ensure that things continue to work properly when I play with things; and all of these are hosted on salsa.debian.org, Debian's gitlab instance. Since we're there anyway, I configured GitLab CI/CD to run a full test suite of all the software, so that I can't forget, and also so that I know sooner rather than later when things start breaking. GitLab has extensive support for various test-related reports, and while it took a while to be able to enable all of them, I'm happy to report that today, my perl test suites generate all three possible reports. They are: Additionally, I also store the native perl Devel::Cover report as job artifacts, as they show some information that GitLab does not. It's important to recognize that not all data is useful. For instance, the JUnit report allows for a test name and for details of the test. However, the module that generates the JUnit report from TAP test suites does not make a distinction here; both the test name and the test details are reported as the same. Additionally, the time a test took is measured as the time between the end of the previous test and the end of the current one; there is no "start" marker in the TAP protocol. That being said, it's still useful to see all the available information in GitLab. And it's not even all that hard to do:
test:
  stage: test
  image: perl:latest
  coverage: '/^Total.* (\d+.\d+)$/'
  before_script:
    - cpanm ExtUtils::Depends Devel::Cover TAP::Harness::JUnit Devel::Cover::Report::Cobertura
    - cpanm --notest --installdeps .
    - perl Makefile.PL
  script:
    - cover -delete
    - HARNESS_PERL_SWITCHES='-MDevel::Cover' prove -v -l -s --harness TAP::Harness::JUnit
    - cover
    - cover -report cobertura
  artifacts:
    paths:
    - cover_db
    reports:
      junit: junit_output.xml
      coverage_report:
        path: cover_db/cobertura.xml
        coverage_format: cobertura
Let's expand on that a bit. The first three lines should be clear for anyone who's used GitLab CI/CD in the past. We create a job called test; we start it in the test stage, and we run it in the perl:latest docker image. Nothing spectacular here. The coverage line contains a regular expression. This is applied by GitLab to the output of the job; if it matches, then the first bracket match is extracted, and whatever that contains is assumed to contain the code coverage percentage for the code; it will be reported as such in the GitLab UI for the job that was ran, and graphs may be drawn to show how the coverage changes over time. Additionally, merge requests will show the delta in the code coverage, which may help deciding whether to accept a merge request. This regular expression will match on a line of that the cover program will generate on standard output. The before_script section installs various perl modules we'll need later on. First, we intall ExtUtils::Depends. My code uses ExtUtils::MakeMaker, which ExtUtils::Depends depends on (no pun intended); obviously, if your perl code doesn't use that, then you don't need to install it. The next three modules -- Devel::Cover, TAP::Harness::JUnit and Devel::Cover::Report::Cobertura are necessary for the reports, and you should include them if you want to copy what I'm doing. Next, we install declared dependencies, which is probably a good idea for you as well, and then we run perl Makefile.PL, which will generate the Makefile. If you don't use ExtUtils::MakeMaker, update that part to do what your build system uses. That should be fairly straightforward. You'll notice that we don't actually use the Makefile. This is because we only want to run the test suite, which in our case (since these are PurePerl modules) doesn't require us to build the software first. One might consider that this makes the call of perl Makefile.PL useless, but I think it's a useful test regardless; if that fails, then obviously we did something wrong and shouldn't even try to go further. The actual tests are run inside a script snippet, as is usual for GitLab. However we do a bit more than you would normally expect; this is required for the reports that we want to generate. Let's unpack what we do there:
cover -delete
This deletes any coverage database that might exist (e.g., due to caching or some such). We don't actually expect any coverage database, but it doesn't hurt.
HARNESS_PERL_SWITCHES='-MDevel::Cover'
This tells the TAP harness that we want it to load the Devel::Cover addon, which can generate code coverage statistics. It stores that in the cover_db directory, and allows you to generate all kinds of reports on the code coverage later (but we don't do that here, yet).
prove -v -l -s
Runs the actual test suite, with verbose output, shuffling (aka, randomizing) the test suite, and adding the lib directory to perl's include path. This works for us, again, because we don't actually need to compile anything; if you do, then -b (for blib) may be required. ExtUtils::MakeMaker creates a test target in its Makefile, and usually this is how you invoke the test suite. However, it's not the only way to do so, and indeed if you want to generate a JUnit XML report then you can't do that. Instead, in that case, you need to use the prove, so that you can tell it to load the TAP::Harness::JUnit module by way of the --harness option, which will then generate the JUnit XML report. By default, the JUnit XML report is generated in a file junit_output.xml. It's possible to customize the filename for this report, but GitLab doesn't care and neither do I, so I don't. Uploading the JUnit XML format tells GitLab which tests were run and Finally, we invoke the cover script twice to generate two coverage reports; once we generate the default report (which generates HTML files with detailed information on all the code that was triggered in your test suite), and once with the -report cobertura parameter, which generates the cobertura XML format. Once we've generated all our reports, we then need to upload them to GitLab in the right way. The native perl report, which is in the cover_db directory, is uploaded as a regular job artifact, which we can then look at through a web browser, and the two XML reports are uploaded in the correct way for their respective formats. All in all, I find that doing this makes it easier to understand how my code is tested, and why things go wrong when they do.

15 August 2023

Dirk Eddelbuettel: #41: Using r2u in Codespaces

Welcome to the 41th post in the $R^4 series. This post draws on joint experiments first started by Grant building on the lovely work done by Eitsupi as part of our Rocker Project. In short, r2u is an ideal match for Codespaces, a Microsoft/GitHub service to run code locally but in the cloud via browser or Visual Studio Code. This posts co-serves as the README.md in the .devcontainer directory as well as a vignette for r2u. So let us get into it. Starting from the r2u repository, the .devcontainer directory provides a small self-containted file devcontainer.json to launch an executable environment R using r2u. It is based on the example in Grant McDermott s codespaces-r2u repo and reuses its documentation. It is driven by the Rocker Project s Devcontainer Features repo creating a fully functioning R environment for cloud use in a few minutes. And thanks to r2u you can add easily to this environment by installing new R packages in a fast and failsafe way.

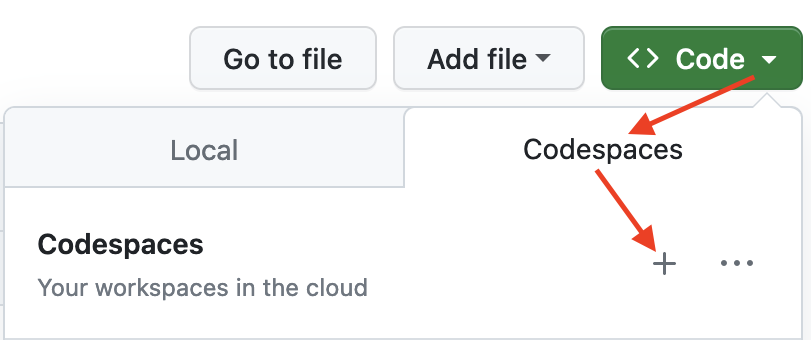
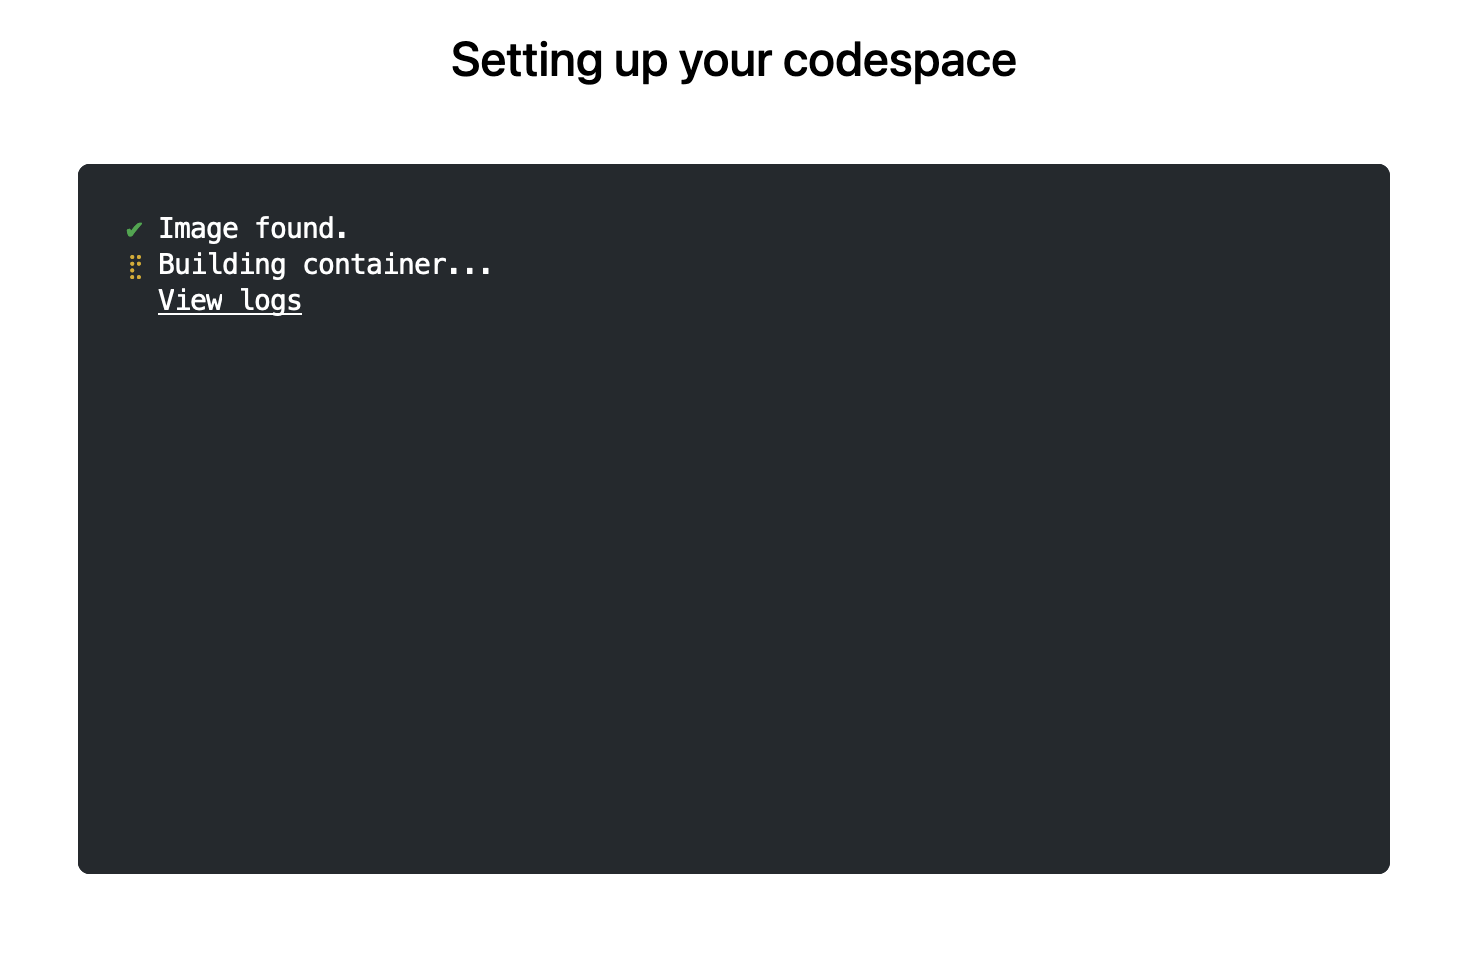
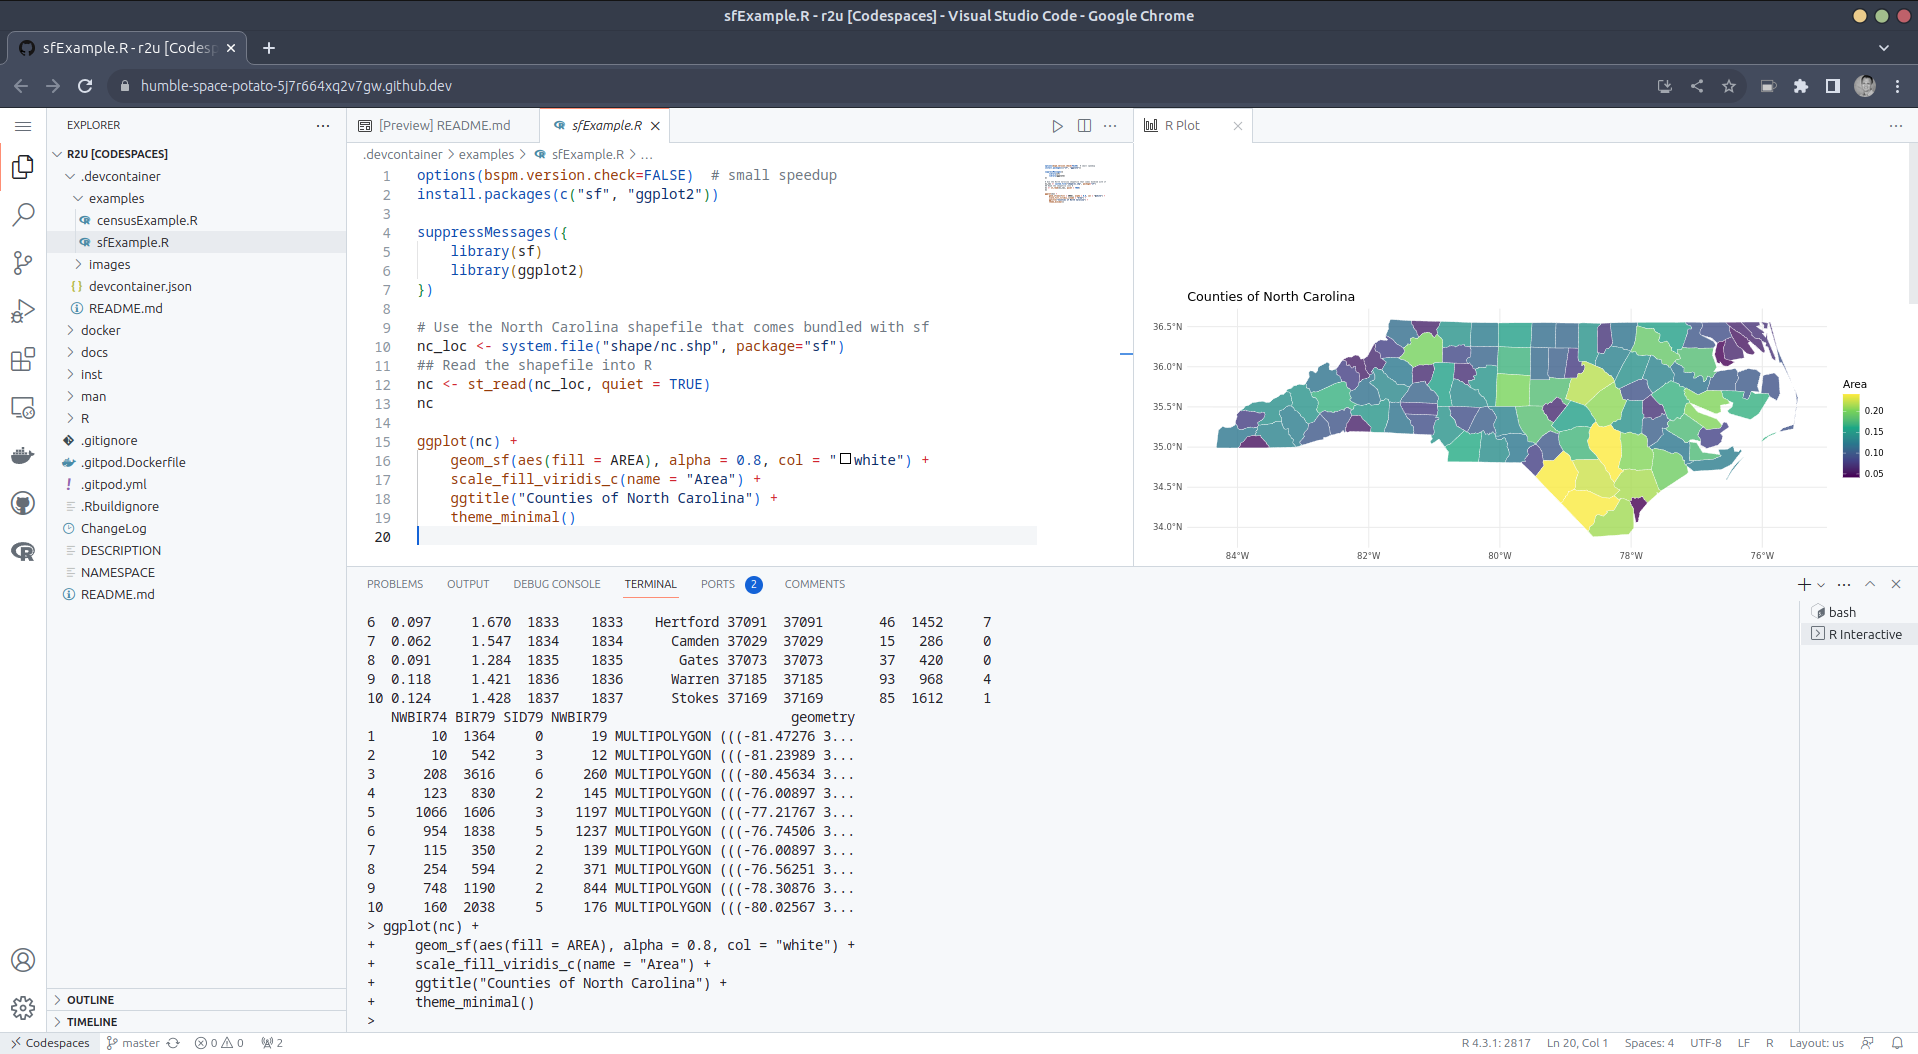
Try it out To get started, simply click on the green Code button at the top right. Then select the Codespaces tab and click the + symbol to start a new Codespace. The first time you do this, it will open up a new browser tab where your Codespace is being instantiated. This first-time instantiation will take a few minutes (feel free to click View logs to see how things are progressing) so please be patient. Once built, your Codespace will deploy almost immediately when you use it again in the future. After the VS Code editor opens up in your browser, feel free to open up the examples/sfExample.R file. It demonstrates how r2u enables us install packages and their system-dependencies with ease, here installing packages sf (including all its geospatial dependencies) and ggplot2 (including all its dependencies). You can run the code easily in the browser environment: Highlight or hover over line(s) and execute them by hitting Cmd+Return (Mac) / Ctrl+Return (Linux / Windows). (Both example screenshots reflect the initial codespaces-r2u repo as well as personal scratchspace one which we started with, both of course work here too.) Do not forget to close your Codespace once you have finished using it. Click the Codespaces tab at the very bottom left of your code editor / browser and select Close Current Codespace in the resulting pop-up box. You can restart it at any time, for example by going to https://github.com/codespaces and clicking on your instance.

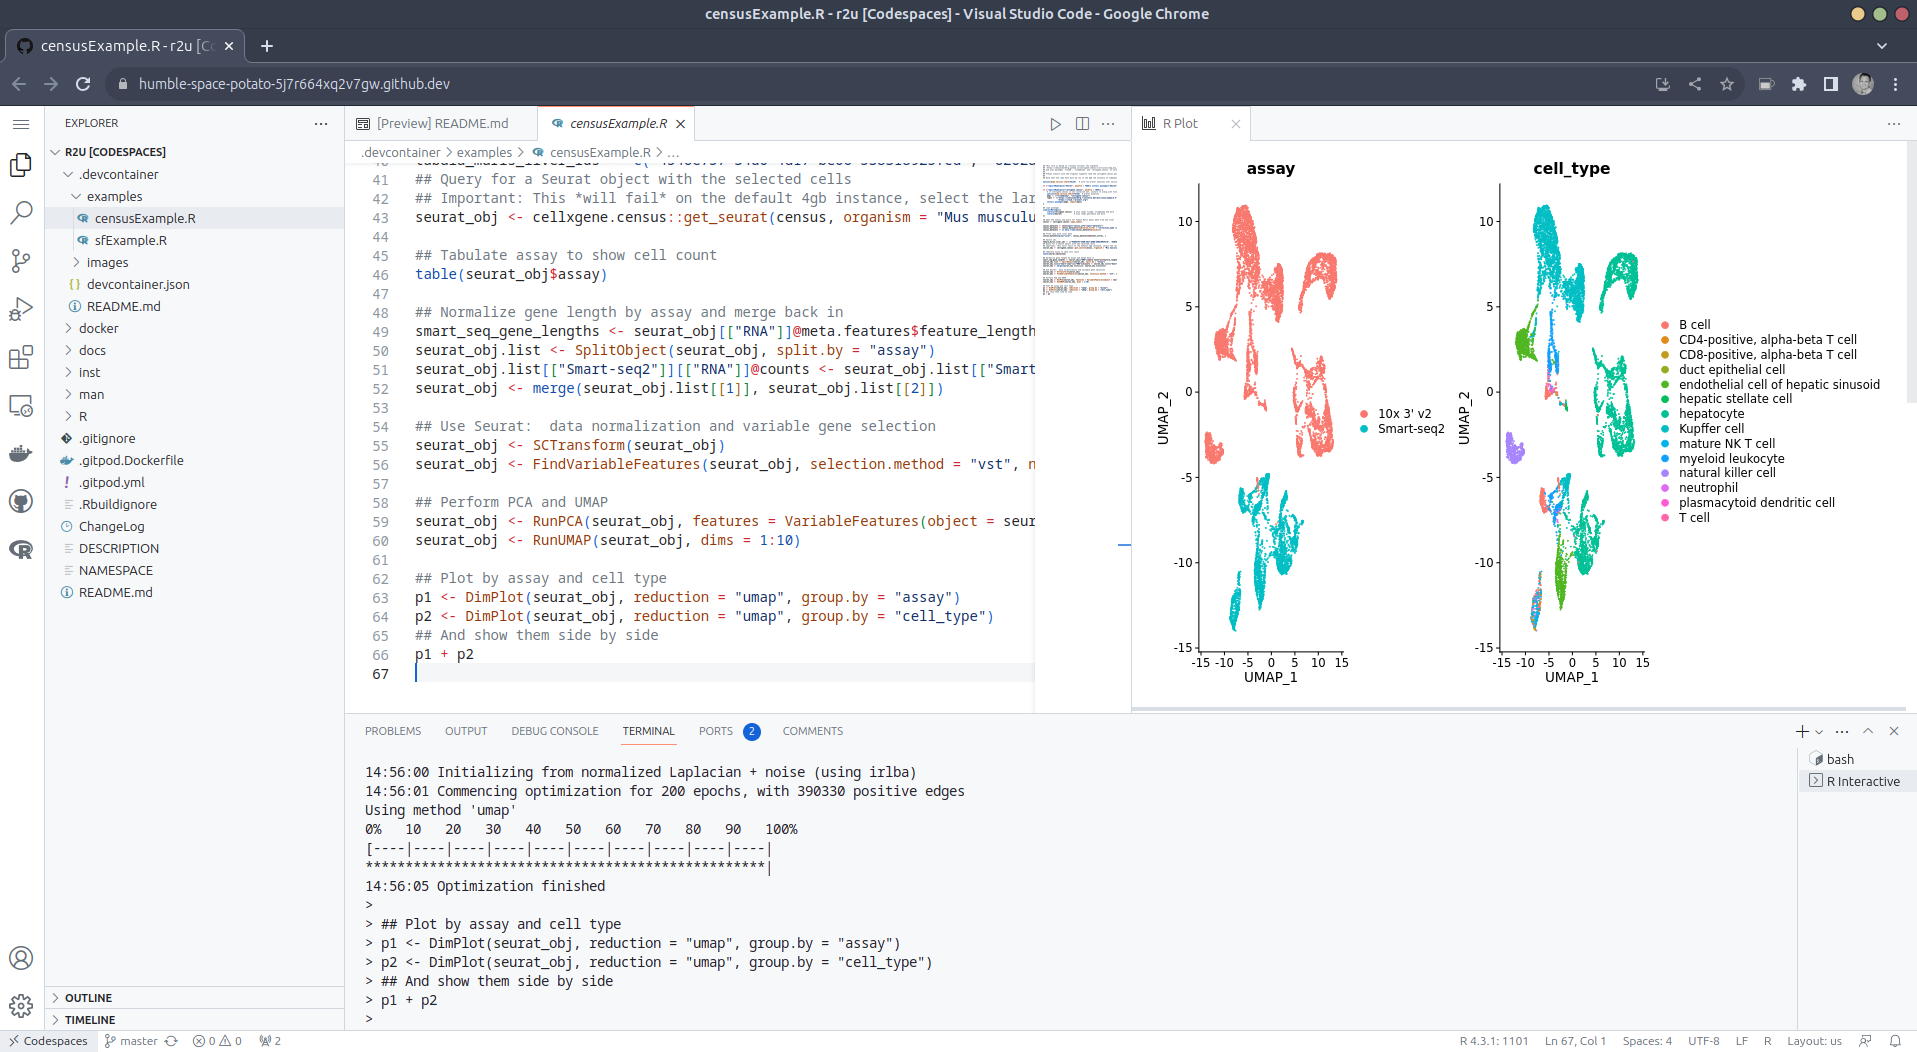
Extend r2u with r-universe r2u offers fast, easy, reliable access to all of CRAN via binaries for Ubuntu focal and jammy. When using the latter (as is the default), it can be combined with r-universe and its Ubuntu jammy binaries. We demontrates this in a second example file examples/censusExample.R which install both the cellxgene-census and tiledbsoma R packages as binaries from r-universe (along with about 100 dependencies), downloads single-cell data from Census and uses Seurat to create PCA and UMAP decomposition plots. Note that in order run this you have to change the Codespaces default instance from small (4gb ram) to large (16gb ram).

Local DevContainer build Codespaces are DevContainers running in the cloud (where DevContainers are themselves just Docker images running with some VS Code sugar on top). This gives you the very powerful ability to edit locally but run remotely in the hosted codespace. To test this setup locally, simply clone the repo and open it up in VS Code. You will need to have Docker installed and running on your system (see here). You will also need the Remote Development extension (you will probably be prompted to install it automatically if you do not have it yet). Select Reopen in Container when prompted. Otherwise, click the >< tab at the very bottom left of your VS Code editor and select this option. To shut down the container, simply click the same button and choose Reopen Folder Locally . You can always search for these commands via the command palette too (Cmd+Shift+p / Ctrl+Shift+p).

Use in Your Repo To add this ability of launching Codespaces in the browser (or editor) to a repo of yours, create a directory .devcontainers in your selected repo, and add the file .devcontainers/devcontainer.json. You can customize it by enabling other feature, or use the postCreateCommand field to install packages (while taking full advantage of r2u).

Acknowledgments There are a few key plumbing pieces that make everything work here. Thanks to:

Colophon More information about r2u is at its site, and we answered some question in issues, and at stackoverflow. More questions are always welcome! If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Originally posted 2023-08-13, minimally edited 2023-08-15 which changed the timestamo and URL.

14 August 2023

Jonathan McDowell: listadmin3: An imperfect replacement for listadmin on Mailman 3

One of the annoyances I had when I upgraded from Buster to Bullseye (yes, I m talking about an upgrade I did at the end of 2021) is that I ended up moving from Mailman 2 to Mailman 3. Which is fine, I guess, but it meant I could no longer use listadmin to deal with messages held for moderation. At the time I looked around, couldn t find anything, shrugged, and became incredibly bad at performing my list moderation duties. Last week I finally accepted what I should have done at least a year ago and wrote some hopefully not too bad Python to web scrape the Mailman 3 admin interface. It then presents a list of subscribers and held messages that might need approved or discarded. It s heavily inspired by listadmin, but not a faithful copy (partly because it s been so long since I used it that I m no longer familiar with its interface). Despite that I ve called it listadmin3. It currently meets the bar of extremely useful to me so I ve tagged v0.1. You can get it on Github. I d be interested in knowing if it actually works for / is useful to anyone else (I suspect it won t be happy with interfaces configured to not be in English, but that should be solvable). Comment here or reply to my Fediverse announcement. Example usage, cribbed directly from the README:
$ listadmin3
fetching data for partypeople@example.org ... 200 messages
(1/200) 5303: omgitsspam@example.org / March 31, 2023, 6:39 a.m.:
  The message is not from a list member: TOP PICK
(a)ccept, (d)iscard, (b)ody, (h)eaders, (s)kip, (q)uit? q
Moving on...
fetching data for admins@example.org ... 1 subscription requests
(1/1) "The New Admin" <newadmin@example.org>
(a)ccept, (d)iscard, (r)eject, (s)kip, (q)uit? a
1 messages
(1/1) 6560: anastyspamer@example.org / Aug. 13, 2023, 3:15 p.m.:
  The message is not from a list member: Buy my stuff!
(a)ccept, (d)iscard, (b)ody, (h)eaders, (s)kip, (q)uit? d
0 to accept, 1 to discard, proceed? (y/n) y
fetching data for announce@example.org ... nothing in queue
$
There s Debian packaging in the repository (dpkg-buildpackage -uc -us -b will spit you out a .deb) but I m holding off on filing an ITP + actually uploading until I know if it s useful enough for others before doing so. You only really need the listadmin3 file and to ensure you have Python3 + MechanicalSoup installed. (Yes, I still run mailing lists. Hell, I still run a Usenet server.)

13 August 2023

Dirk Eddelbuettel: #41: Using r2u in Codespaces

Welcome to the 41th post in the $R^4 series. This post draws on joint experiments first started by Grant building on the lovely work Eitsupi as part of our Rocker Project. In short, r2u is an ideal match for Codesspaces, a Microsoft/GitHub service to run code locally but in the cloud via browser or Visual Studio Code. This posts co-serves as the README.md in the .devcontainer directory as well as a vignette for r2u. So let us get into it. Starting from the r2u repository, the .devcontainer directory provides a small self-containted file devcontainer.json to launch an executable environment R using r2u. It is based on the example in Grant McDermott s codespaces-r2u repo and reuses its documentation. It is driven by the Rocker Project s Devcontainer Features repo creating a fully functioning R environment for cloud use in a few minutes. And thanks to r2u you can add easily to this environment by installing new R packages in a fast and failsafe way.

Try it out To get started, simply click on the green Code button at the top right. Then select the Codespaces tab and click the + symbol to start a new Codespace. The first time you do this, it will open up a new browser tab where your Codespace is being instantiated. This first-time instantiation will take a few minutes (feel free to click View logs to see how things are progressing) so please be patient. Once built, your Codespace will deploy almost immediately when you use it again in the future. After the VS Code editor opens up in your browser, feel free to open up the examples/sfExample.R file. It demonstrates how r2u enables us install packages and their system-dependencies with ease, here installing packages sf (including all its geospatial dependencies) and ggplot2 (including all its dependencies). You can run the code easily in the browser environment: Highlight or hover over line(s) and execute them by hitting Cmd+Return (Mac) / Ctrl+Return (Linux / Windows). (Both example screenshots reflect the initial codespaces-r2u repo as well as personal scratchspace one which we started with, both of course work here too.) Do not forget to close your Codespace once you have finished using it. Click the Codespaces tab at the very bottom left of your code editor / browser and select Close Current Codespace in the resulting pop-up box. You can restart it at any time, for example by going to https://github.com/codespaces and clicking on your instance.

Extend r2u with r-universe r2u offers fast, easy, reliable access to all of CRAN via binaries for Ubuntu focal and jammy. When using the latter (as is the default), it can be combined with r-universe and its Ubuntu jammy binaries. We demontrates this in a second example file examples/censusExample.R which install both the cellxgene-census and tiledbsoma R packages as binaries from r-universe (along with about 100 dependencies), downloads single-cell data from Census and uses Seurat to create PCA and UMAP decomposition plots. Note that in order run this you have to change the Codespaces default instance from small (4gb ram) to large (16gb ram).

Local DevContainer build Codespaces are DevContainers running in the cloud (where DevContainers are themselves just Docker images running with some VS Code sugar on top). This gives you the very powerful ability to edit locally but run remotely in the hosted codespace. To test this setup locally, simply clone the repo and open it up in VS Code. You will need to have Docker installed and running on your system (see here). You will also need the Remote Development extension (you will probably be prompted to install it automatically if you do not have it yet). Select Reopen in Container when prompted. Otherwise, click the >< tab at the very bottom left of your VS Code editor and select this option. To shut down the container, simply click the same button and choose Reopen Folder Locally . You can always search for these commands via the command palette too (Cmd+Shift+p / Ctrl+Shift+p).

Use in Your Repo To add this ability of launching Codespaces in the browser (or editor) to a repo of yours, create a directory .devcontainers in your selected repo, and add the file .devcontainers/devcontainer.json. You can customize it by enabling other feature, or use the postCreateCommand field to install packages (while taking full advantage of r2u).

Acknowledgments There are a few key plumbing pieces that make everything work here. Thanks to:

Colophon More information about r2u is at its site, and we answered some question in issues, and at stackoverflow. More questions are always welcome! If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

11 August 2023

Birger Schacht: Another round of rust

A couple of weeks ago I had to undergo surgery, because one of my kidneys malfunctioned. Everything went well and I m on my way to recovery. Luckily the most recent local heat wave was over just shortly after I got home, which made being stuck at home a little easier (not sure yet when I ll be allowed to do sports again, I miss my climbing gym ). At first I did not have that much energy to do computer stuff, but after a week or so I was able to sit in front of the screen for short amounts of time and I started to get into writing Rust code again.

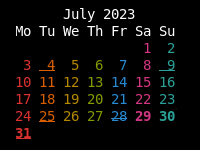
carl The first thing I did was updating carl. I updated all the dependencies and switched the dependency that does coloring from ansi_term, which is unmaintained, to nu-ansi-term. When I then updated the clap dependency to version 4 I realized that clap now depends on the anstyle crate for text styling - so I updated carls coloring code once again so it now uses anstyle, which led to less dependencies overall. Implementing this change I also did some refactoring of the code. carl how also has its own website as well as a subdomain1. I also added a couple of new date properties to carl, namely all weekdays as well as odd and even - this means it is now possible choose a separate color for every weekday and have a rainbow calendar:
screenshot carl
This is included in version 0.1.0 of carl, which I published on crates.io.

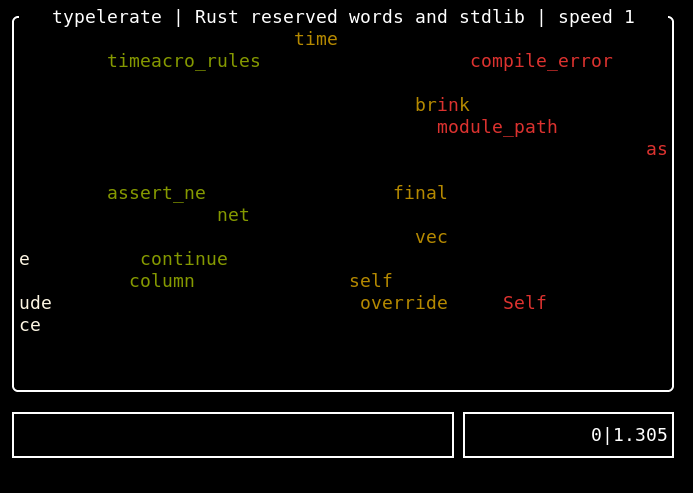
typelerate Then I started writing my first game - typelerate. It is a copy of the great typespeed, without the multiplayer support. To describe the idea behind the game, I quote the typespeed website:
Typespeed s idea is ripped from ztspeed (a DOS game made by Zorlim). The Idea behind the game is rather easy: type words that are flying by from left to right as fast as you can. If you miss 10 or more words, game is over.
Instead of the multiplayer support, typelerate works with UTF-8 strings and it also has another game mode: in typespeed you only type whats scrolling via the screen. In typelerate I added the option to have one or more answer strings. One of those has to be typed instead of the word flying across the screen. This lets you implement kind of an question/answer game. To be backwards compatible with the existing wordfiles from typespeed2, the wordfiles for the question/answer games contain comma separated values. The typelerate repository contains wordfiles with Python and Rust keywords as well as wordfiles where you are shown an Emoji and you have to type the corresponding Github shortcode. I m happy to add additional wordfiles (there could be for example math questions ).
screenshot typelerate

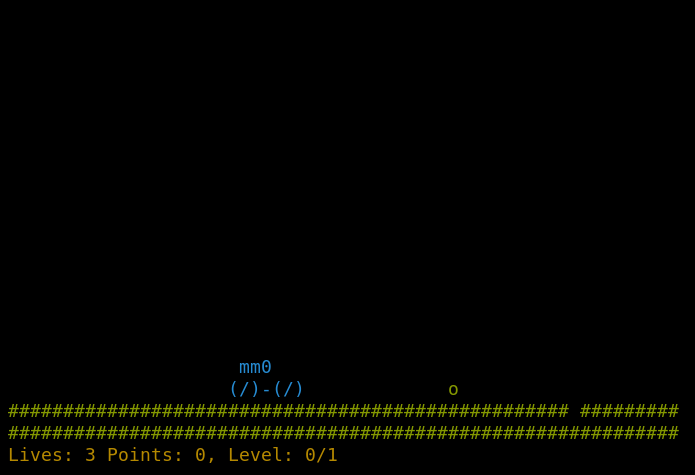
marsrover Another commandline game I really like, because I am fascinated by the animated ASCII graphics, is the venerable moon-buggy. In this game you have to drive a vehicle across the moon s surface and deal with obstacles like craters or aliens. I reimplemented the game in rust and called it marsrover:
screenshot marsrover
I published it on crates.io, you can find the repository on github. The game uses a configuration file in $XDG_CONFIG_HOME/marsrover/config.toml - you can configure the colors of the elements as well as the levels. The game comes with four levels predefined, but you can use the configuration file to override that list of levels with levels with your own properties. The level properties define the probabilities of obstacles occuring on your way on the mars surface and a points setting that defines how many points the user can get in that level (=the game switches to the next level if the user reaches the points).
[[levels]]
prob_ditch_one = 0.2
prob_ditch_two = 0.0
prob_ditch_three = 0.0
prob_alien = 0.5
points = 100
After the last level, the game generates new ones on the fly.

  1. thanks to the service from https://cli.rs.
  2. actually, typelerate is not backwards compatible with the typespeed wordfiles, because those are not UTF-8 encoded

10 August 2023

Sandro Tosi: Mastodon hook for dput-ng

If you use dput-ng, you may be familiar with the Twitter hook that tweets a message when uploading a package.A similar hook is now available for Mastodon too; if interested, give it a try and comment on the MR

9 August 2023

Kentaro Hayashi: How to setup DMARC policy for subdomain on debian.net

For setting up subdomain on debian.net, we usually use LDAP Gateway. [1] db.debian.org [1] https://db.debian.org/doc-mail.html With changing dnsZoneEntry, we can set up each subdomain of debian.net. For example, you can customize SPF TXT record for example.debian.net.
example IN TXT v=spf1 a:example.debian.net ~all
But when you setup DMARC policy for dnsZoneEntry, it may cause the trouble. LDAP Gateway returns the following error:
Command is not understood. Halted - no changes committed
This is caused by unsupported v=DMARC1 record by changes@db.debian.org. Even though LDAP Gateway doesn't support v=DMARC1 record, there is a workaround for it. (e.g example.debian.net) TXT record of _dmarc.example.example.org is something like this:
v=DMARC1; p=quarantine; fo=s; aspf=s; rua=dmarc-reports@example.debian.net; ruf=dmarc-reports@example.debian.net
dmarc.example IN CNAME dmarc.example.example.org.
It means that _dmarc.example.debian.net is provided by _dmarc.example.example.org 's txt record. Now you can ready to verify it.

7 August 2023

Dirk Eddelbuettel: RQuantLib 0.4.19 on CRAN: More Maintenance

A new release 0.4.19 of RQuantLib arrived at CRAN earlier today, and has already been uploaded to Debian too. QuantLib is a rather comprehensice free/open-source library for quantitative finance. RQuantLib connects it to the R environment and language, and has been part of CRAN for more than twenty years (!!) This release of RQuantLib brings a small update to three unit tests as very recent 1.31 release QuantLib brought a subtle change to some fixed income payment schedules and dates. On a sadder note, as CRAN now checks the ratio of user time over elapsed time , excessive threading was inferred for five examples. As we seemingly cannot limit std::thread here, I opted to park these examples behind a \dontrun . Not ideal. Lastly, a few version checks in configure were updated.

Changes in RQuantLib version 0.4.19 (2023-08-07)
  • Three calendaring / schedule tests were adjusted for slightly changed values under QuantLib 1.31
  • Several checks in the configure script have been updated to reflect current versions of packages.
  • Five examples no longer run because, even while extremely short, use of (too many default) threads was seen.

Courtesy of my CRANberries, there is also a diffstat report for the this release 0.4.19. As always, more detailed information is on the RQuantLib page. Questions, comments etc should go to the rquantlib-devel mailing list. Issue tickets can be filed at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

5 August 2023

Bits from Debian: Debian Project Bits Volume 1, Issue 1


Debian Project Bits Volume 1, Issue 1 August 05, 2023 Welcome to the inaugural issue of Debian Project Bits! Those remembering the Debian Weekly News (DwN) will recognize some of the sections here which served as our inspiration. Debian Project Bits posts will allow for a faster turnaround of some project news on a monthly basis. The Debian Micronews service will continue to share shorter news items, the Debian Project News remains as our official newsletter which may move to a biannual archive format. News Debian Day The Debian Project was officially founded by Ian Murdock on August 16, 1993. Since then we have celebrated our Anniversary of that date each year with events around the world. We would love it if you could join our revels this very special year as we have the honor of turning 30! Attend or organize a local Debian Day celebration. You're invited to plan your own event: from Bug Squashing parties to Key Signing parties, Meet-Ups, or any type of social event whether large or small. And be sure to check our Debian reimbursement How To if you need such resources. You can share your days, events, thoughts, or notes with us and the rest of the community with the #debianday tag that will be used across most social media platforms. See you then! Events: Upcoming and Reports Upcoming Debian 30 anos The Debian Brasil Community is organizing the event Debian 30 anos to celebrate the 30th anniversary of the Debian Project. From August 14 to 18, between 7pm and 22pm (UTC-3) contributors will talk online in Portuguese and we will live stream on Debian Brasil YouTube channel. DebConf23: Debian Developers Camp and Conference The 2023 Debian Developers Camp (DebCamp) and Conference (DebConf23) will be hosted this year in Infopark, Kochi, India. DebCamp is slated to run from September 3 through 9, immediately followed by the larger DebConf, September 10 through 17. If you are planning on attending the conference this year, now is the time to ensure your travel documentation, visa information, bursary submissions, papers and relevant equipment are prepared. For more information contact: debconf@debconf. MiniDebConf Cambridge 2023 There will be a MiniDebConf held in Cambridge, UK, hosted by ARM for 4 days in November: 2 days for a mini-DebCamp (Thu 23 - Fri 24), with space for dedicated development / sprint / team meetings, then two days for a more regular MiniDebConf (Sat 25 - Sun 26) with space for more general talks, up to 80 people. Reports During the last months, the Debian Community has organized some Bug Squashing Parties:
Tilburg, Netherlands. October 2022. St-Cergue, Switzerland. January 2023 Montreal, Canada. February 2023 In January, Debian India hosted the MiniDebConf Tamil Nadu in Viluppuram, Tamil Nadu, India (Sat 28 - Sun 26). The following month, the MiniDebConf Portugal 2023 was held in Lisbon (12 - 16 February 2023). These events, seen as a stunning success by some of their attendees, demonstrate the vitality of our community.
Debian Brasil Community at Campus Party Brazil 2023 Another edition of Campus Party Brazil took place in the city of S o Paulo between July 25th and 30th. And one more time the Debian Brazil Community was present. During the days in the available space, we carry out some activities such as: For more info and a few photos, check out the organizers' report. MiniDebConf Bras lia 2023 From May 25 to 27, Bras lia hosted the MiniDebConf Bras lia 2023. This gathering was composed of various activities such as talks, workshops, sprints, BSPs (Bug Squashing Party), key signings, social events, and hacking, aimed to bring the community together and celebrate the world's largest Free Software project: Debian. For more information please see the full report written by the organizers. Debian Reunion Hamburg 2023 This year the annual Debian Reunion Hamburg was held from Tuesday 23 to 30 May starting with four days of hacking followed by two days of talks, and then two more days of hacking. As usual, people - more than forty-five attendees from Germany, Czechia, France, Slovakia, and Switzerland - were happy to meet in person, to hack and chat together, and much more. If you missed the live streams, the video recordings are available. Translation workshops from the pt_BR team The Brazilian translation team, debian-l10n-portuguese, had their first workshop of 2023 in February with great results. The workshop was aimed at beginners, working in DDTP/DDTSS. For more information please see the full report written by the organizers. And on June 13 another workshop took place to translate The Debian Administrator's Handbook). The main goal was to show beginners how to collaborate in the translation of this important material, which has existed since 2004. The manual's translations are hosted on Weblate. Releases Stable Release Debian 12 bookworm was released on June 10, 2023. This new version becomes the stable release of Debian and moves the prior Debian 11 bullseye release to oldstable status. The Debian community celebrated the release with 23 Release Parties all around the world. Bookworm's first point release 12.1 address miscellaneous bug fixes affecting 88 packages, documentation, and installer updates was made available on July 22, 2023. RISC-V support riscv64 has recently been added to the official Debian architectures for support of 64-bit little-endian RISC-V hardware running the Linux kernel. We expect to have full riscv64 support in Debian 13 trixie. Updates on bootstrap, build daemon, porterbox, and development progress were recently shared by the team in a Bits from the Debian riscv64 porters post. non-free-firmware The Debian 12 bookworm archive now includes non-free-firmware; please be sure to update your apt sources.list if your systems requires such components for operation. If your previous sources.list included non-free for this purpose it may safely be removed. apt sources.list The Debian archive holds several components: Example of the sources.list file
deb http://deb.debian.org/debian bookworm main
deb-src http://deb.debian.org/debian bookworm main
deb http://deb.debian.org/debian-security/ bookworm-security main
deb-src http://deb.debian.org/debian-security/ bookworm-security main
deb http://deb.debian.org/debian bookworm-updates main
deb-src http://deb.debian.org/debian bookworm-updates main
Example using the components:
deb http://deb.debian.org/debian bookworm main non-free-firmware
deb-src http://deb.debian.org/debian bookworm main non-free-firmware
deb http://deb.debian.org/debian-security/ bookworm-security main non-free-firmware
deb-src http://deb.debian.org/debian-security/ bookworm-security main non-free-firmware
deb http://deb.debian.org/debian bookworm-updates main non-free-firmware
deb-src http://deb.debian.org/debian bookworm-updates main non-free-firmware
For more information and guidelines on proper configuration of the apt source.list file please see the Configuring Apt Sources - Wiki page. Inside Debian New Debian Members Please welcome the following newest Debian Project Members: To find out more about our newest members or any Debian Developer, look for them on the Debian People list. Security Debian's Security Team releases current advisories on a daily basis. Some recently released advisories concern these packages: trafficserver Several vulnerabilities were discovered in Apache Traffic Server, a reverse and forward proxy server, which could result in information disclosure or denial of service. asterisk A flaw was found in Asterisk, an Open Source Private Branch Exchange. A buffer overflow vulnerability affects users that use PJSIP DNS resolver. This vulnerability is related to CVE-2022-24793. The difference is that this issue is in parsing the query record parse_query(), while the issue in CVE-2022-24793 is in parse_rr(). A workaround is to disable DNS resolution in PJSIP config (by setting nameserver_count to zero) or use an external resolver implementation instead. flask It was discovered that in some conditions the Flask web framework may disclose a session cookie. chromium Multiple security issues were discovered in Chromium, which could result in the execution of arbitrary code, denial of service or information disclosure. Other Popular packages gpgv - GNU privacy guard signature verification tool. 99,053 installations. gpgv is actually a stripped-down version of gpg which is only able to check signatures. It is somewhat smaller than the fully-blown gpg and uses a different (and simpler) way to check that the public keys used to make the signature are valid. There are no configuration files and only a few options are implemented. dmsetup - Linux Kernel Device Mapper userspace library. 77,769 installations. The Linux Kernel Device Mapper is the LVM (Linux Logical Volume Management) Team's implementation of a minimalistic kernel-space driver that handles volume management, while keeping knowledge of the underlying device layout in user-space. This makes it useful for not only LVM, but software raid, and other drivers that create "virtual" block devices. sensible-utils - Utilities for sensible alternative selection. 96,001 daily users. This package provides a number of small utilities which are used by programs to sensibly select and spawn an appropriate browser, editor, or pager. The specific utilities included are: sensible-browser sensible-editor sensible-pager. popularity-contest - The popularity-contest package. 90,758 daily users. The popularity-contest package sets up a cron job that will periodically anonymously submit to the Debian developers statistics about the most used Debian packages on the system. This information helps Debian make decisions such as which packages should go on the first CD. It also lets Debian improve future versions of the distribution so that the most popular packages are the ones which are installed automatically for new users. New and noteworthy packages in unstable Toolkit for scalable simulation of distributed applications SimGrid is a toolkit that provides core functionalities for the simulation of distributed applications in heterogeneous distributed environments. SimGrid can be used as a Grid simulator, a P2P simulator, a Cloud simulator, a MPI simulator, or a mix of all of them. The typical use-cases of SimGrid include heuristic evaluation, application prototyping, and real application development and tuning. This package contains the dynamic libraries and runtime. LDraw mklist program 3D CAD programs and rendering programs using the LDraw parts library of LEGO parts rely on a file called parts.lst containing a list of all available parts. The program ldraw-mklist is used to generate this list from a directory of LDraw parts. Open Lighting Architecture - RDM Responder Tests The DMX512 standard for Digital MultipleX is used for digital communication networks commonly used to control stage lighting and effects. The Remote Device Management protocol is an extension to DMX512, allowing bi-directional communication between RDM-compliant devices without disturbing other devices on the same connection. The Open Lighting Architecture (OLA) provides a plugin framework for distributing DMX512 control signals. The ola-rdm-tests package provides an automated way to check protocol compliance in RDM devices. parsec-service Parsec is an abstraction layer that can be used to interact with hardware-backed security facilities such as the Hardware Security Module (HSM), the Trusted Platform Module (TPM), as well as firmware-backed and isolated software services. The core component of Parsec is the security service, provided by this package. The service is a background process that runs on the host platform and provides connectivity with the secure facilities of that host, exposing a platform-neutral API that can be consumed into different programming languages using a client library. For a client library implemented in Rust see the package librust-parsec-interface-dev. Simple network calculator and lookup tool Process and lookup network addresses from the command line or CSV with ripalc. Output has a variety of customisable formats. High performance, open source CPU/GPU miner and RandomX benchmark XMRig is a high performance, open source, cross platform RandomX, KawPow, CryptoNight, and GhostRider unified CPU/GPU miner and RandomX benchmark. Ping, but with a graph - Rust source code This package contains the source for the Rust gping crate, packaged by debcargo for use with cargo and dh-cargo. Once upon a time in Debian: 2014-07-31 The Technical committee choose libjpeg-turbo as the default JPEG decoder. 2010-08-01 DebConf10 starts New York City, USA 2007-08-05 Debian Maintainers approved by vote 2009-08-05 Jeff Chimene files bug #540000 against live-initramfs. Calls for help The Publicity team calls for volunteers and help! Your Publicity team is asking for help from you our readers, developers, and interested parties to contribute to the Debian news effort. We implore you to submit items that may be of interest to our community and also ask for your assistance with translations of the news into (your!) other languages along with the needed second or third set of eyes to assist in editing our work before publishing. If you can share a small amount of your time to aid our team which strives to keep all of us informed, we need you. Please reach out to us via IRC on #debian-publicity on OFTC.net, or our public mailing list, or via email at press@debian.org for sensitive or private inquiries.

1 August 2023

Jonathan Dowland: Interzone's new home

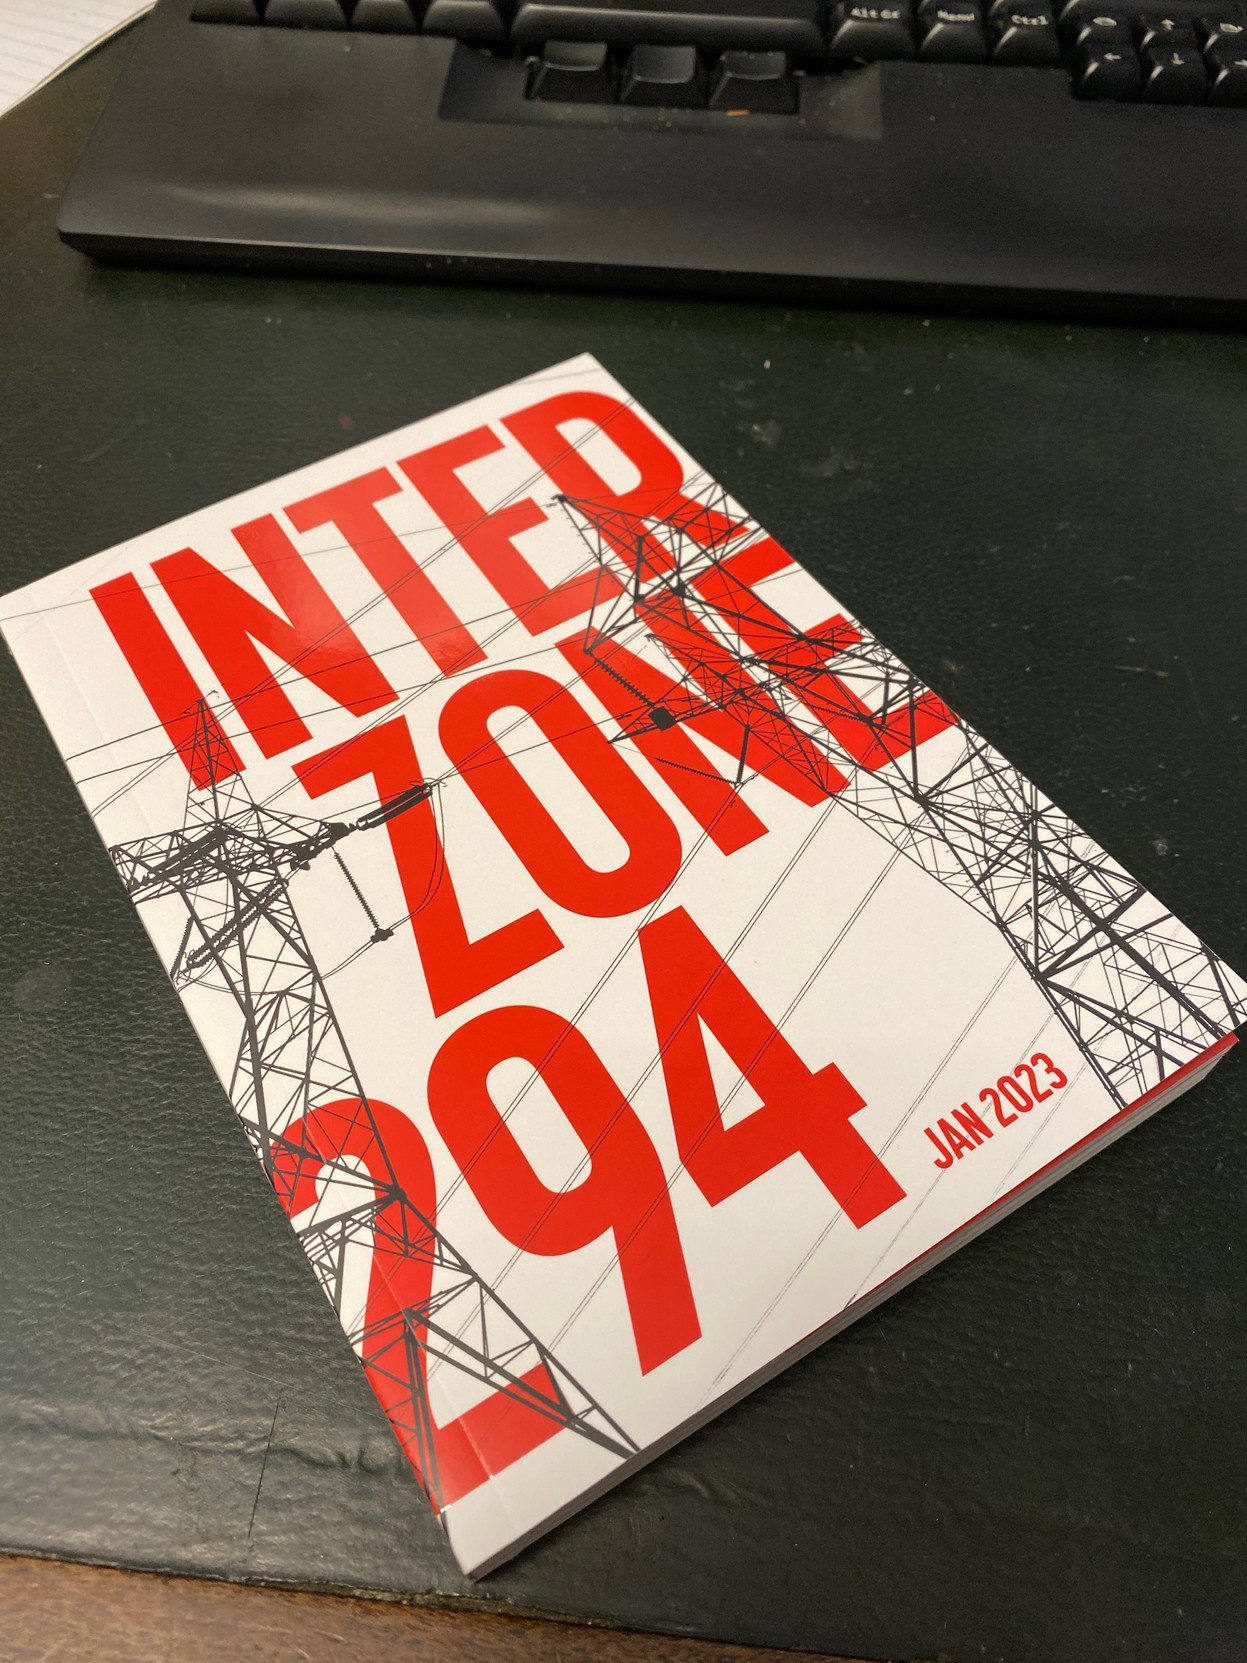
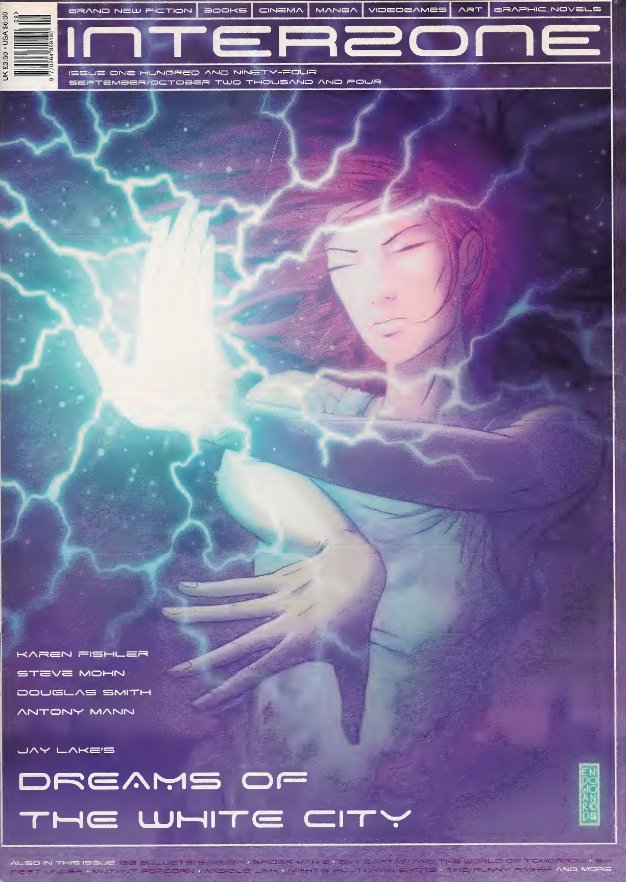
IZ #294, the latest issue IZ #294, the latest issue
The long running British1 SF Magazine Interzone has a new home and new editor, Gareth Jelley, starting with issue 294. It's also got a swanky new format ("JB6"): a perfect-bound, paperback novel size, perfect for fitting into an oversize coat or jeans pocket for reading on the train. I started reading Interzone in around 2003, having picked up an issue (#176) from Feb 2002 that was languishing on the shelves in Forbidden Planet. Once I discovered it I wondered why it had taken me so long. That issue introduced me to Greg Egan. I bought a number of back issues on eBay, to grab issues with stories by people including Terry Pratchett, Iain Banks, Alastair Reynolds, and others.
IZ #194: The first by TTA press IZ #194: The first by TTA press
A short while later in early 2004, after 22 years, Interzone's owner and editorship changed from David Pringle to Andy Cox and TTA Press. I can remember the initial transition was very jarring: the cover emphasised expanding into coverage of Manga, Graphic Novels and Video Games (which ultimately didn't happen) but after a short period of experimentation it quickly settled down into a similarly fantastic read. I particularly liked the move to a smaller, perfect-bound form-factor in 2012. I had to double-check this but I'd been reading IZ throughout the TTA era and it lasted 18 years! Throughout that time I have discovered countless fantastic authors that I would otherwise never have experienced. Some (but by no means all) are Dominic Green, Daniel Kaysen, Chris Beckett, C cile Cristofari, Aliya Whiteley, Tim Major, Fran oise Harvey, Will McIntosh. Cox has now retired (after 100 issues and a tenure almost as long as Pringle) and handed the reins to Gareth Jelley/MYY Press, who have published their first issue, #294. Jelley is clearly putting a huge amount of effort into revitalizing the magazine. There's a new homepage at interzone.press but also companion internet presences: a plethora of digital content at interzone.digital, Interzone Socials (a novel idea), a Discord server, a podcast, and no doubt more. Having said that, the economics of small magazines have been perilous for a long time, and that hasn't changed, so I think the future of IZ (in physical format at least) is in peril. If you enjoy short fiction, fresh ideas, SF/F/Fantastika; why not try a subscription to Interzone, whilst you still can!

  1. Interzone has always been "British", in some sense, but never exclusively so. I recall fondly a long-term project under Pringle to publish a lot of Serbian writer Zoran ivkovi , for example, and the very first story I read was by Australian Greg Egan. Under Jelley, the magazine is being printed in Poland and priced in Euros. I expect it to continue to attract and publish writers from all over the place.

Reproducible Builds: Supporter spotlight: Simon Butler on business adoption of Reproducible Builds

The Reproducible Builds project relies on several projects, supporters and sponsors for financial support, but they are also valued as ambassadors who spread the word about our project and the work that we do. This is the seventh instalment in a series featuring the projects, companies and individuals who support the Reproducible Builds project. We started this series by featuring the Civil Infrastructure Platform project, and followed this up with a post about the Ford Foundation as well as recent ones about ARDC, the Google Open Source Security Team (GOSST), Bootstrappable Builds, the F-Droid project and David A. Wheeler. Today, however, we will be talking with Simon Butler, an associate senior lecturer in the School of Informatics at the University of Sk vde, where he undertakes research in software engineering that focuses on IoT and open source software, and contributes to the teaching of computer science to undergraduates.

Chris: For those who have not heard of it before, can you tell us more about the School of Informatics at Sk vde University? Simon: Certainly, but I may be a little long-winded. Sk vde is a city in the area between the two large lakes in southern Sweden. The city is a busy place. Sk vde is home to the regional hospital, some of Volvo s manufacturing facilities, two regiments of the Swedish defence force, a lot of businesses in the Swedish computer games industry, other tech companies and more. The University of Sk vde is relatively small. Sweden s large land area and low population density mean that regional centres such as Sk vde are important and local universities support businesses by training new staff and supporting innovation. The School of Informatics has two divisions. One focuses on teaching and researching computer games. The other division encompasses a wider range of teaching and research, including computer science, web development, computer security, network administration, data science and so on.
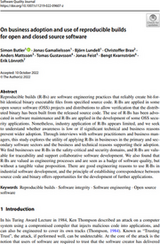
Chris: You recently had a open-access paper published in Software Quality Journal. Could you tell us a little bit more about it and perhaps briefly summarise its key findings? Simon: The paper is one output of a collaborative research project with six Swedish businesses that use open source software. There are two parts to the paper. The first consists of an analysis of what the group of businesses in the project know about Reproducible Builds (R-Bs), their experiences with R-Bs and their perception of the value of R-Bs to the businesses. The second part is an interview study with business practitioners and others with experience and expertise in R-Bs. We set out to try to understand the extent to which software-intensive businesses were aware of R-Bs, the technical and business reasons they were or were not using R-Bs and to document the business and technical use cases for R-Bs. The key findings were that businesses are aware of R-Bs, and some are using R-Bs as part of their day-to-day development process. Some of the uses for R-Bs we found were not previously documented. We also found that businesses understood the value R-Bs have as part of engineering and software quality processes. They are also aware of the costs of implementing R-Bs and that R-Bs are an intangible value proposition - in other words, businesses can add value through process improvement by using R-Bs. But, that, currently at least, R-Bs are not a selling point for software or products.
Chris: You performed a large number of interviews in order to prepare your paper. What was the most surprising response to you? Simon: Most surprising is a good question. Everybody I spoke to brought something new to my understanding of R-Bs, and many responses surprised me. The interviewees that surprised me most were I01 and I02 (interviews were anonymised and interviewees were assigned numeric identities). I02 described the sceptical perspective that there is a viable, pragmatic alternative to R-Bs - verifiable builds - which I was aware of before undertaking the research. The company had developed a sufficiently robust system for their needs and worked well. With a large archive of software used in production, they couldn t justify the cost of retrofitting a different solution that might only offer small advantages over the existing system. Doesn t really sound too surprising, but the interview was one of the first I did on this topic, and I was very focused on the value of, and need for, trust in a system that motivated the R-B. The solution used by the company requires trust, but they seem to have established sufficient trust for their needs by securing their build systems to the extent that they are more or less tamper-proof. The other big surprise for me was I01 s use of R-Bs to support the verification of system configuration in a system with multiple embedded components at boot time. It s such an obvious application of R-Bs, and exactly the kind of response I hoped to get from interviewees. However, it is another instance of a solution where trust is only one factor. In the first instance, the developer is using R-Bs to establish trust in the toolchain. There is also the second application that the developer can use a set of R-Bs to establish that deployed system consists of compatible components. While this might not sound too significant, there appear to be some important potential applications. One that came to mind immediately is a problem with firmware updates on nodes in IoT systems where the node needs to update quickly with limited downtime and without failure. The node also needs to be able to roll back any update proposed by a server if there are conflicts with the current configuration or if any tests on the node fail. Perhaps the chances of failure could be reduced, if a node can instead negotiate with a server to determine a safe path to migrate from its current configuration to a working configuration with the upgraded components the central system requires? Another potential application appears to be in the configuration management of AI systems, where decisions need to be explainable. A means of specifying validated configurations of training data, models and deployed systems might, perhaps, be leveraged to prevent invalid or broken configurations from being deployed in production.
Chris: One of your findings was that reproducible builds were perceived to be good engineering practice . To what extent do you believe cultural forces affect the adoption or rejection of a given technology or practice? Simon: To a large extent. People s decisions are informed by cultural norms, and business decisions are made by people acting collectively. Of course, decision-making, including assessments of risk and usefulness, is mediated by individual positions on the continuum from conformity to non-conformity, as well as individual and in-group norms. Whether a business will consider a given technology for adoption will depend on cultural forces. The decision to adopt may well be made on the grounds of cost and benefits.
Chris: Another conclusion implied by your research is that businesses are often dealing with software deployment lifespans (eg. 20+ years) that differ from widely from those of the typical hobbyist programmer. To what degree do you think this temporal mismatch is a problem for both groups? Simon: This is a fascinating question. Long-term software maintenance is a requirement in some industries because of the working lifespans of the products and legal requirements to maintain the products for a fixed period. For some other industries, it is less of a problem. Consequently, I would tend to divide developers into those who have been exposed to long-term maintenance problems and those who have not. Although, more professional than hobbyist developers will have been exposed to the problem. Nonetheless, there are areas, such as music software, where there are also long-term maintenance challenges for data formats and software.
Chris: Based on your research, what would you say are the biggest blockers for the adoption of reproducible builds within business ? And, based on this, would you have any advice or recommendations for the broader reproducible builds ecosystem? Simon: From the research, the main blocker appears to be cost. Not an absolute cost, but there is an overhead to introducing R-Bs. Businesses (and thus business managers) need to understand the business case for R-Bs. Making decision-makers in businesses aware of R-Bs and that they are valuable will take time. Advocacy at multiple levels appears to be the way forward and this is being done. I would recommend being persistent while being patient and to keep talking about reproducible builds. The work done in Linux distributions raises awareness of R-Bs amongst developers. Guix, NixOS and Software Heritage are all providing practical solutions and getting attention - I ve been seeing progressively more mentions of all three during the last couple of years. Increased awareness amongst developers should lead to more interest within companies. There is also research money being assigned to supply chain security and R-B s. The CHAINS project at KTH in Stockholm is one example of a strategic research project. There may be others that I m not aware of. The policy-level advocacy is slowly getting results in some countries, and where CISA leads, others may follow.
Chris: Was there a particular reason you alighted on the question of the adoption of reproducible builds in business? Do you think there s any truth behind the shopworn stereotype of hacker types neglecting the resources that business might be able to offer? Simon: Much of the motivation for the research came from the contrast between the visibility of R-Bs in open source projects and the relative invisibility of R-Bs in industry. Where companies are known to be using R-Bs (e.g. Google, etc.) there is no fuss, no hype. They were not selling R-Bs as a solution; instead the documentation is very matter-of-fact that R-Bs are part of a customer-facing process in their cloud solutions. An obvious question for me was that if some people use R-B s in software development, why doesn t everybody? There are limits to the tooling for some programming languages that mean R-Bs are difficult or impossible. But where creating an R-B is practical, why are they not used more widely? So, to your second question. There is another factor, which seems to be more about a lack of communication rather than neglecting opportunities. Businesses may not always be willing to discuss their development processes and innovations. Though I do think the increasing number of conferences (big and small) for software practitioners is helping to facilitate more communication and greater exchange of ideas.
Chris: Has your personal view of reproducible builds changed since before you embarked on writing this paper? Simon: Absolutely! In the early stages of the research, I was interested in questions of trust and how R-Bs were applied to resolve build and supply chain security problems. As the research developed, however, I started to see there were benefits to the use of R-Bs that were less obvious and that, in some cases, an R-B can have more than a single application.
Chris: Finally, do you have any plans to do future research touching on reproducible builds? Simon: Yes, definitely. There are a set of problems that interest me. One already mentioned is the use of reproducible builds with AI systems. Interpretable or explainable AI (XAI) is a necessity, and I think that R-Bs can be used to support traceability in the configuration and testing of both deployed systems and systems used during model training and evaluation. I would also like to return to a problem discussed briefly in the article, which is to develop a deeper understanding of the elements involved in the application of R-Bs that can be used to support reasoning about existing and potential applications of R-Bs. For example, R-Bs can be used to establish trust for different groups of individuals at different times, say, between remote developers prior to the release of software and by users after release. One question is whether when an R-B is used might be a significant factor. Another group of questions concerns the ways in which trust (of some sort) propagates among users of an R-B. There is an example in the paper of a company that rebuilds Debian reproducibly for security reasons and is then able to collaborate on software projects where software is built reproducibly with other companies that use public distributions of Debian.
Chris: Many thanks for this interview, Simon. If someone wanted to get in touch or learn more about you and your colleagues at the School of Informatics, where might they go? Thank you for the opportunity. It has been a pleasure to reflect a little more widely on the research! Personally, you can find out about my work on my official homepage and on my personal site. The software systems research group (SSRG) has a website, and the University of Sk vde s English language pages are also available. Chris: Many thanks for this interview, Simon!


For more information about the Reproducible Builds project, please see our website at reproducible-builds.org. If you are interested in ensuring the ongoing security of the software that underpins our civilisation and wish to sponsor the Reproducible Builds project, please reach out to the project by emailing contact@reproducible-builds.org.

30 July 2023

Russell Coker: My Predictions for the Ukraine War

There are a lot of people talking about the Russian invasion of Ukraine and a lot of moving goalposts in such discussions. I think that everyone who wants to advocate for it should publish what they expect to happen and what specific things they consider as victory conditions. When Russia first invaded I thought they would win in a matter of weeks. I underestimated the determination of the Ukrainian people and the corruption and the incompetence and corruption of the Russian military. The first time I thought that Ukraine could win was when I read an analysis of the tires on Russian military vehicles breaking because of the cheapest available tires being bought and then not stored correctly to avoid damage, which led to the long stalled convoy. A successful military campaign requires many more difficult tasks than buying good tires and maintaining them correctly. An army that is too corrupt to buy the bare minimum of usable equipment and too incompetent to adapt to failures is not going to do well. The Ukrainians have done very well with the equipment available, one example is their use of off the shelf drones for dropping grenades into armoured vehicles and for targeting artillery. While the Russians have responded by buying Iranian military drones because they lack the industrial capacity to make their own ones. From the time when the Russians first got bogged down the Ukrainians have been mostly retaking their territory slowly and steadily. The Russians started the invasion with a significant advantage in aircraft, armoured vehicles, artillery, and ammunition. This advantage has been significantly decreased due to losses of vehicles and artillery, high rates of ammunition use, and Ukrainian capture of Russian equipment. The Ukrainians are getting new vehicles, aircraft, artillery, and ammunition from western countries while sanctions are preventing Russians from importing or manufacturing much. Currently one important factor for Russia is the ability of their airforce to attack Ukrainian positions while out of range of Ukrainian air defence systems. The MANPAD systems are good for close support but not good for long range. A problem that the Russians will have in the long term is running out of spare parts and being unable to properly maintain aircraft. This will result in loss of aircraft due to accidents and the inability to repair aircraft that has even minor damage. Here are my specific predictions:
  1. I predict that by the end of 2023 Russia will have a much smaller number of military aircraft through maintenance problems even if Ukraine doesn t get long-range SAM systems.
  2. I predict that by mid 2024 Ukraine will have air superiority. They will destroy many Russian SAM systems and be able to bomb Russian targets with little risk.
  3. I predict that Russia won t impose any significant new conscription programs on their population. Such programs are extremely unpopular and Russia doesn t have the industrial capacity to equip a larger army as they can t properly equip their current army.
  4. Currently Ukraine is making slow but steady progress in retaking their territory in the East. I predict that before the end of 2023 they will have cut all supply lines to Crimea from the mainland by having artillery that can accurately cover all the distance to the coast of the Sea of Azov. I also predict that the bridge over the Kerch strait will be mostly unusable from now on (on average less than 1/3 the bridge capacity usable). As fast as the Russians can repair it the Ukrainians will bomb it again. At most they will have half of the road lanes available to cars and will be unable to transport any significant amount of military equipment.
  5. Due to Russians lacking supplies I predict that Ukraine will recapture at least half the Crimean land area by the end of 2023.
  6. The regions of Luhansk and Donetsk will be the most difficult to capture as they have been held the longest. I predict that the war will not end until Ukraine controls everything within their 2013 borders including Luhansk and Donetsk. The final victory may happen due to the Russian military collapsing or due to a new Russian government ordering a withdrawal.
  7. I predict that Russia will make significant efforts to help Trump get elected in 2024. But even if they succeed it will be too late for him to help them much or change the outcome.
  8. I predict that Ukraine will win this war before the end of 2025. Even if some of my other predictions turn out to be incorrect I predict that by the end of 2025 the military forces of Russia and Ukraine will not be fighting and that it will be because Ukraine has given the Russian military a proper spanking. If something like the Troubles in Ireland happens (which is a real possibility) that doesn t count as a war.
  9. I predict that Ukraine will not deploy any significant attack inside Russian territory. They will launch small scale attacks on specific military targets but do nothing that the Russian population might consider to be full scale war.
  10. I predict that Putin will not lead Russia 2 months after Ukraine recaptures all their territory. He may not live for long after Ukraine wins, or the Russian withdrawal might happen because Putin dies of apparently natural causes.
  11. After the war I predict that Ukraine will control all their territory from 2013 and there will be a demilitarised zone or no-fly zone in Russian territory.
  12. I predict that after the war some parts of the Russian Federation will break free. There are many different groups who would like to be free of Russia and Ukraine destroying most of the Russian military will make things easy for them. A Russian civil war is a possibility.
  13. I predict that the US will give minimal support to Russia after the war as a strategic plan to block China. I predict that the quality and efficacy of such support will be comparable to the US actions in the Middle East.
I welcome comments disagreeing with this. But please make specific predictions that can be tested and sign your name to them. If you don t think that a certain event will happen when I predict it then provide a date when you think it will happen or a date by which the opposite will have happened. Also please show enough confidence to make multiple predictions. I ve made 12 specific predictions, if you think I m doing badly then make at least 3 specific competing predictions. If you think that Russia will win then define what a win means in terms of territory occupied when fighting between armies ends and when that will happen. Also if you think that Russia will win then please make a prediction about whether there will be a Ukrainian equivalent of the IRA and if so what they will do.

26 July 2023

Shirish Agarwal: Manipur Violence, Drugs, Binging on Northshore, Alaska Daily, Doogie Kamealoha and EU Digital Resilence Act.

Manipur Videos Warning: The text might be mature and will have references to violence so if there are kids or you are sensitive, please excuse. Few days back, saw the videos and I cannot share the rage, shame and many conflicting emotions that were going through me. I almost didn t want to share but couldn t stop myself. The woman in the video were being palmed, fingered, nude, later reportedly raped and murdered. And there have been more than a few cases. The next day saw another video that showed beheaded heads, and Kukis being killed just next to their houses. I couldn t imagine what those people must be feeling as the CM has been making partisan statements against them. One of the husbands of the Kuki women who had been paraded, fondled is an Army Officer in the Indian Army. The Meiteis even tried to burn his home but the Army intervened and didn t let it get burnt. The CM s own statement as shared before tells his inability to bring the situation out of crisis. In fact, his statement was dumb stating that the Internet shutdown was because there were more than 100 such cases. And it s spreading to the nearby Northeast regions. Now Mizoram, the nearest neighbor is going through similar things where the Meitis are not dominant. The Mizos have told the Meitis to get out. To date, the PM has chosen not to visit Manipur. He just made a small 1 minute statement about it saying how the women have shamed India, an approximation of what he said.While it s actually not the women but the men who have shamed India. The Wire has been talking to both the Meitis, the Kukis, the Nagas. A Kuki women sort of bared all. She is right on many counts. The GOI while wanting to paint the Kukis in a negative light have forgotten what has been happening in its own state, especially its own youth as well as in other states while also ignoring the larger geopolitics and business around it. Taliban has been cracking as even they couldn t see young boys, women becoming drug users. I had read somewhere that 1 in 4 or 1 in 5 young person in Afghanistan is now in its grip. So no wonder,the Taliban is trying to eradicate and shutdown drug use among it s own youth. Circling back to Manipur, I was under the wrong impression that the Internet shutdown is now over. After those videos became viral as well as the others I mentioned, again the orders have been given and there is shutdown. It is not fully shut but now only Govt. offices have it. so nobody can share a video that goes against any State or Central Govt. narrative  A real sad state of affairs  Update: There is conditional reopening whatever that means  When I saw the videos, the first thing is I felt was being powerless, powerless to do anything about it. The second was if I do not write about it, amplify it and don t let others know about it then what s the use of being able to blog

Mental Health, Binging on various Webseries Both the videos shocked me and I couldn t sleep that night or the night after. it. Even after doing work and all, they would come in unobtrusively in my nightmares  While I felt a bit foolish, I felt it would be nice to binge on some webseries. Little I was to know that both Northshore and Alaska Daily would have stories similar to what is happening here  While the story in Alaska Daily is fictional it resembles very closely to a real newspaper called Anchorage Daily news. Even there the Intuit women , one of the marginalized communities in Alaska. The only difference I can see between GOI and the Alaskan Government is that the Alaskan Government was much subtle in doing the same things. There are some differences though. First, the State is and was responsive to the local press and apart from one close call to one of its reporters, most reporters do not have to think about their own life in peril. Here, the press cannot look after either their livelihood or their life. It was a juvenile kid who actually shot the video, uploaded and made it viral. One needs to just remember the case details of Siddique Kappan. Just for sharing the news and the video he was arrested. Bail was denied to him time and time again citing that the Police were investigating . Only after 2 years and 3 months he got bail and that too because none of the charges that the Police had they were able to show any prima facie evidence. One of the better interviews though was of Vrinda Grover. For those who don t know her, her Wikipedia page does tell a bit about her although it is woefully incomplete. For example, most recently she had relentlessly pursued the unconstitutional Internet Shutdown that happened in Kashmir for 5 months. Just like in Manipur, the shutdown was there to bury crimes either committed or being facilitated by the State. For the issues of livelihood, one can take the cases of Bipin Yadav and Rashid Hussain. Both were fired by their employer Dainik Bhaskar because they questioned the BJP MP Smriti Irani what she has done for the state. The problems for Dainik Bhaskar or for any other mainstream media is most of them rely on Government advertisements. Private investment in India has fallen to record lows mostly due to the policies made by the Centre. If any entity or sector grows a bit then either Adani or Ambani will one way or the other take it. So, for most first and second generation entrepreneurs it doesn t make sense to grow and then finally sell it to one of these corporates at a loss  GOI on Adani, Ambani side of any deal. The MSME sector that is and used to be the second highest employer hasn t been able to recover from the shocks of demonetization, GST and then the pandemic. Each resulting in more and more closures and shutdowns. Most of the joblessness has gone up tremendously in North India which the Government tries to deny. The most interesting points in all those above examples is within a month or less, whatever the media reports gets scrubbed. Even the firing of the journos that was covered by some of the mainstream media isn t there anymore. I have to use secondary sources instead of primary sources. One can think of the chilling effects on reportage due to the above. The sad fact is even with all the money in the world the PM is unable to come to the Parliament to face questions.
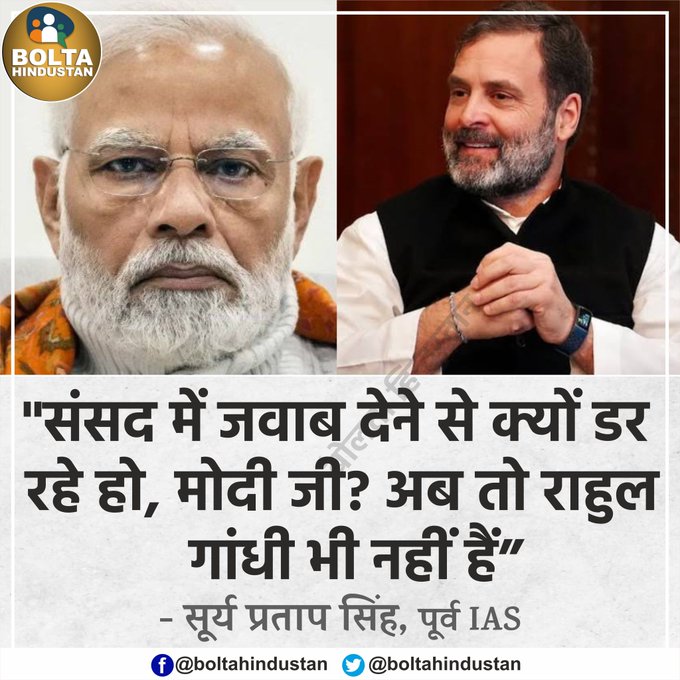
Why is PM not answering in Parliament,, even Rahul Gandhi is not there - Surya Pratap Singh, prev. IAS Officer.
The above poster/question is by Surya Pratap Singh, a retired IAS officer. He asks why the PM is unable to answer in either of the houses. As shared before, the Govt. wants very limited discussion. Even yesterday, the Lok Sabha TV just showed the BJP MP s making statements but silent or mic was off during whatever questions or statements made by the opposition. If this isn t mockery of Indian democracy then I don t know what is  Even the media landscape has been altered substantially within the last few years. Both Adani and Ambani have distributed the media pie between themselves. One of the last bastions of the free press, NDTV was bought by Adani in a hostile takeover. Both Ambani and Adani are close to this Goverment. In fact, there is no sector in which one or the other is not present. Media houses like Newsclick, The Wire etc. that are a fraction of mainstream press are where most of the youth have been going to get their news as they are not partisan. Although even there, GOI has time and again interfered. The Wire has had too many 504 Gateway timeouts in the recent months and they had been forced to move most of their journalism from online to video, rather Youtube in order to escape both the censoring and the timeouts as shared above. In such a hostile environment, how both the organizations are somehow able to survive is a miracle. Most local reportage is also going to YouTube as that s the best way for them to not get into Govt. censors. Not an ideal situation, but that s the way it is. The difference between Indian and Israeli media can be seen through this
The above is a Screenshot shared by how the Israeli media has reacted to the Israeli Government s Knesset over the judicial overhaul . Here, the press itself erodes its own by giving into the Government day and night

Binging on Webseries Saw Northshore, Three Pines, Alaska Daily and Doogie Kamealoha M.D. which is based on Doogie Howser M.D. Of the four, enjoyed Doogie Kamealoha M.D. the most but then it might be because it s a copy of Doogie Howser, just updated to the new millenia and there are some good childhood memories associated with that series. The others are also good. I tried to not see European stuff as most of them are twisted and didn t want that space.

EU Digital Operational Resilience Act and impact on FOSS Few days ago, apparently the EU shared the above Act. One can read about it more here. This would have more impact on FOSS as most development of various FOSS distributions happens in EU. Fair bit of Debian s own development happens in Germany and France. While there have been calls to make things more clearer, especially for FOSS given that most developers do foss development either on side or as a hobby while their day job is and would be different. The part about consumer electronics and FOSS is a tricky one as updates can screw up your systems. Microsoft has had a huge history of devices not working after an update or upgrade. And this is not limited to Windows as they would like to believe. Even apple seems to be having its share of issues time and time again. One would have hoped that these companies that make billions of dollars from their hardware and software sales would be doing more testing and Q&A and be more aware about security issues. FOSS, on the other hand while being more responsive doesn t make as much money vis-a-vis the competitors. Let s take the most concrete example. The most successful mobile phone having FOSS is Purism. But it s phone, it has priced itself out of the market. A huge part of that is to do with both economies of scale and trying to get an infrastructure and skills in the States where none or minimally exists. Compared that to say Pinepro that is manufactured in Hong Kong and is priced 1/3rd of the same. For most people it is simply not affordable in these times. Add to that the complexity of these modern cellphones make it harder, not easier for most people to be vigilant and update the phone at all times. Maybe we need more dumphones such as Light and Punkt but then can those be remotely hacked or not, there doesn t seem to be any answers on that one. I haven t even seen anybody even ask those questions. They may have their own chicken and egg issues. For people like me who have lost hearing, while I can navigate smartphones for now but as I become old I don t see anything that would help me. For many an elderly population, both hearing and seeing are the first to fade. There doesn t seem to be any solutions targeted for them even though they are 5-10% of any population at the very least. Probably more so in Europe and the U.S. as well as Japan and China. All of them are clearly under-served markets but dunno a solution for them. At least to me that s an open question.

25 July 2023

Sam Hartman: AI and Sexuality

When I began to read about the generative AI revolution, I realized there was an opportunity to combine two aspects of my life I never thought I could merge. While I m not working on the cloud or security, I work as a sex and intimacy educator, helping people embrace love, vulnerability and connection. As I first began to interact with ChatGPT, I saw the potential for AI to help people explore parts of the world they had not experienced for themselves. I m blind. When I write fiction, physical descriptions are always challenging for me. I don t understand facial expressions very well, and figuring out what characters look like is difficult. Generative AI has opened up an entire new world for me. I can explore how people might express some emotion and how they might dress in a certain situation. I can even exploit the cultural biases that are sometimes the bane of AI to translate my ideas about personality and background into appearance. Immediately I realized the opportunities for sexual freedom: People are already using Generative AI to help with intimacy. There are plenty of stories about how people use AI to tune their dating profiles. But all too often, the desire to make AI safe brings shame and rejection into the discussion of intimacy. Even something as simple as Help me come up with a sensual description of this character, is likely to run up against the all-too-familiar responses: I am a large language model and for safety reasons I cannot do that. That safety is important: one thing we have learned from sex positive culture is how important boundaries are. We need to respect those boundaries and not expose people to unwanted sexual content. But we also know how damaging shame is. When someone reaches out and tentatively asks to explore their sexuality, rejecting that exploration will come across as a rejection of that person they are dirty or disgusting for wanting to explore. Fortunately, we will see AI models that are open to exploring sexuality. Some of the uncensored models will already try, although calling some of the results sex positive would be stretching the truth. We re already seeing discussions of virtual AI girlfriends. And as AI meets sex, I m going to be there, helping try and turn it into something healthy both for business and for lovers. There are all sorts of interesting challenges: There are all the cultural and social challenges that sex-positive work faces. Then there are versions of the AI challenges of bias, hallucinations and the like, along with specific challenges of exploring emotionally-charged vulnerable topics. And yet there s so much potential to help people gain confidence and valuable skills. I am eagerly looking for opportunities to combine my work as a sex positive educator and as a software developer. I d love to hear about any ongoing work at the intersection of Sex and Generative AI. I ve done some research already, but there s so much going on in the AI world it is impossible to follow it all. Please reach out with anything you think I should track.

comment count unavailable comments

23 July 2023

Dirk Eddelbuettel: #41: Another r2u Example Really Simple CI

Welcome to the 41th post in the $R^4 series. Just as the previous post illustrated r2u use to empower interactive Google Colab sessions, today we want to look at continuous integration via GitHub Actions. Actions are very powerful, yet also intimidating and complex. How does one know what to run? How does ensure requirements are installed? What does these other actions do? Here we offer a much simpler yet fully automatic solution. It takes advantage of the fact that r2u integrates fully and automatically with the system, here apt, without us having to worry about the setup. One way to make this very easy is the use of the Rocker containers for r2u. They already include the few lines of simple (and scriptable) setup, and have bspm setup so that R commands to install packages dispatch to apt and will bring all required dependencies automatically and easily. With that the required yaml file for an action can be as simple as this:
name: r2u

on:
  push:
  pull_request:
  release:

jobs:
  ci:
    runs-on: ubuntu-latest
    container:
      image: rocker/r2u:latest
    steps:
      - uses: actions/checkout@v3
      - name: SessionInfo
        run: R -q -e 'sessionInfo()'
      #- name: System Dependencies
      #  # can be used to install e.g. cmake or other build dependencies
      #  run: apt update -qq && apt install --yes --no-install-recommends cmake git
      - name: Package Dependencies
        run: R -q -e 'remotes::install_deps(".", dependencies=TRUE)'
      - name: Build Package
        run: R CMD build --no-build-vignettes --no-manual .
      - name: Check Package
        run: R CMD check --no-vignettes --no-manual $(ls -1tr *.tar.gz   tail -1)
There are only a few key components here. First, we have the on block where for simplicity we select pushes, pull requests and releases. One could reduce this to just pushes by removing or commenting out the next two lines. Many further refinements are possible and documented but not reqired. Second, the jobs section and its sole field ci saythat we are running this CI on Ubuntu in its latest release. Importantly we then also select the rocker container for r2 meaning that we explicitly select running in this container (which happens to be an extension and refinement of ubuntu-latest). The latest tag points to the most recent LTS release, currently jammy aka 22.04. This choice also means that our runs are limited to Ubuntu and exclude macOS and Windows. That is a choice: not every CI task needs to burn extra (and more expensive) cpu cycles on the alternative OS, yet those can always be added via other yaml files possibly conditioned on fewer runs (say: only pull requests) if needed. Third, we have the basic sequence of steps. We check out the repo this file is part of (very standard). After that we ask R show the session info in case we need to troubleshoot. (These two lines could be commented out.) Next we show a commented-out segment we needed in another repo where we needed to add cmake and git as the package in question required local compilation during build. Such a need is fairly rare, but as shown can be be accomodated easily while taking advantage of the rich development infrastructure provided by Ubuntu. But the step should be optional for most R packages so it is commented out here. The next step uses the remotes package to look at the DESCRIPTION file and install all dependencies which, thanks to r2u and bspm, will use all Ubuntu binaries making it both very fast, very easy, and generally failsafe. Finally we do the two standard steps of building the source package and checking it (while omitting vignettes and the (pdf) manual as the container does not bother with a full texlive installation this could be altered if desired in a derived container). And that s it! The startup cost is a few seconds to pull the container, plus a few more seconds for dependencies and let us recall that e.g. the entire tidyverse installs all one hundred plus packages in about twenty seconds as shown in earlier post. After that the next cost is generally just what it takes to build and check your package once all requirements are in. To use such a file for continuous integration, we can install it in the .github/workflows/ directory of a repository. One filename I have used is .github/workflows/r2u.yaml making it clear what this does and how. More information about r2u is at its site, and we answered some question in issues, and at stackoverflow. More questions are always welcome! If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

20 July 2023

Dirk Eddelbuettel: qlcal 0.0.7 on CRAN: QuantLib 1.31 Updates

The seventh release of the still pretty new qlcal package arrivied at CRAN today. qlcal delivers the calendaring parts of QuantLib. It is provided (for the R package) as a set of included files, so the package is self-contained and does not depend on an external QuantLib library (which can be demanding to build). qlcal covers over sixty country / market calendars and can compute holiday lists, its complement (i.e. business day lists) and much more. This release brings updates from the just-released QuantLib 1.31 version.

Changes in version 0.0.7 (2023-07-19)
  • Updates, extensions and corrections to calendars from South Korea, Hong Kong, Singapore, India, Taiwan, South Africa, Denmark and Finland from QuantLib 1.31
  • Added support for UnitedStates/SOFR calendar

As the update comprises a number of small-but-important updates to eight different country calendars as well as a new US calendar (in a slight variation on the government bond calendar) we can also update the little demo highlighting all calendars within the US for the given year:
> ## see https://github.com/qlcal/qlcal-r/blob/master/demo/allUScalendars.R
> ## see R/calendars.R in qlcal, we prepend 'UnitedStates/' in makeHol()
> cals <- c("LiborImpact", "NYSE", "GovernmentBond", "NERC", "FederalReserve", "SOFR")
> print(Reduce(cbind, Map(makeHol, cals)))
           LiborImpact NYSE GovernmentBond NERC FederalReserve SOFR
2023-01-02        TRUE TRUE           TRUE TRUE           TRUE TRUE
2023-01-16        TRUE TRUE           TRUE   NA           TRUE TRUE
2023-02-20        TRUE TRUE           TRUE   NA           TRUE TRUE
2023-04-07          NA TRUE             NA   NA             NA TRUE
2023-05-29        TRUE TRUE           TRUE TRUE           TRUE TRUE
2023-06-19        TRUE TRUE           TRUE   NA           TRUE TRUE
2023-07-04        TRUE TRUE           TRUE TRUE           TRUE TRUE
2023-09-04        TRUE TRUE           TRUE TRUE           TRUE TRUE
2023-10-09        TRUE   NA           TRUE   NA           TRUE TRUE
2023-11-10        TRUE   NA             NA   NA             NA   NA
2023-11-23        TRUE TRUE           TRUE TRUE           TRUE TRUE
2023-12-25        TRUE TRUE           TRUE TRUE           TRUE TRUE
> 
Courtesy of my CRANberries, there is a diffstat report for this release. See the project page and package documentation for more details, and more examples. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

19 July 2023

Ian Jackson: Installing Debian bookworm without systemd

Instructions
  1. Get the official installation image from the usual locations. I got the netinst CD image via BitTorrent.
  2. Boot from the image and go through the installation in the normal way.
    1. You may want to select an alternative desktop environment (and unselect GNOME). These steps have been tested with MATE.
    2. Stop when you are asked to remove the installation media and reboot.
  3. Press Alt + Right arrow to switch to the text VC. Hit return to activate the console and run the following commands (answering yes as appropriate):
chroot /target bash
apt-get install sysvinit-core elogind ntp dbus-x11
apt-get autoremove
exit
  1. Observe the output from the apt-get install. If your disk arrangements are unusual, that may generate some error messages from update-initramfs.
  2. Go back to the installer VC with Alt + Left arrow. If there were no error messages above, you may tell it to reboot.
  3. If there were error messages (for example, I found that if there was disk encryption, alarming messages were printed), tell the installer to go Back . Then ask it to Install GRUB bootloader (again). After that has completed, you may reboot.
  4. Enjoy your Debian system without systemd.
Discussion This is pleasingly straightforward, albeit with an ugly wart. This recipe was not formally developed and tested; it s just what happened when I tried to actually perform this task. The official installation guide has similar instructions although they don t seem to have the initramfs workaround. update-initramfs The need to go back and have the installer reinstall grub is because if your storage is not very straightforward, the update-initramfs caused by apt-get install apparently doesn t have all the right context. I haven t investigated this at all; indeed, I don t even really know that the initramfs generated in step 3 above was broken, although the messages did suggest to me that important pieces or config might have been omitted. Instead, I simply chose to bet that it might be broken, but that the installer would know what to do. So I used the installer s install GRUB bootloader option, which does regenerate the initramfs. So, I don t know that step 6 is necessary. In principle it would be better to do the switch from systemd to sysvinit earlier in the installation process, and under the control of the installer. But by default the installer goes straight from the early setup questions through to the set the time or reboot questions, without stopping. One could use the expert mode, or modify the command line, or something, but all of those things are, in practice, a lot more typing and/or interaction. And as far as I m aware the installer doesn t have an option for avoiding systemd . The apt-get install line sysvinit-core is the principal part of the sysvinit init system. Asking to install that causes the deinstallation of systemd s init and ancillary packages. systemd refuses to allow itself to be deinstalled, if it is already running, so if you boot into the systemd system you can t then switch init system. This is why the switch is best done at install time. If you re too late, there are instructions for changing init system post-installation. elogind is a forked version of some of systemd s user desktop session functionality. In practice modern desktop environments need this; without it, apt will want to remove things you probably want to keep. Even if you force it, you may find that your desktop environment can t adjust the audio volume, etc. ntp is needed because nowadays the default network time client is systemd-timesyncd (which is a bad idea even on systems with systemd as init). We need to specify it because the package dependencies don t automatically give you any replacement for systemd-timesyncd. dbus-x11 is a glue component. In theory it ought to be installed automatically. However, there have been problems with the dependencies that meant that (for example) asking for emacs would try to switch the init system. Specifying dbus-x11 explicitly is a workaround for that, which I nowadays adopt out of caution. Perhaps it is no longer needed. (On existing systems, it may be necessary to manually install orphan-sysvinit-scripts, which exists as a suboptimal technical workaround for the sociopolitical problems of hostile package maintainers and Debian s governance failures. The recipe above seems to install this package automatically.) usrmerge This recipe results in a system which has merged-/usr via symlinks. This configuration is a bad one. Ideally usrmerge-via-symlinks would be avoided. The un-merged system is declared not officially supported by Debian and key packages try very hard to force it on users. However, merged-/usr-via-symlinks is full of bugs (mostly affecting package management) which are far too hard to fix (a project by some folks to try to do so has given up). I suspect un-merged systems will suffer from fewer bugs in practice. But I don t know how to persuade d-i to make one. Installer images I think there is room in the market for an unofficial installer image which installs without systemd and perhaps without usrmerge. I don t have the effort for making such a thing myself. Conclusion Installing Debian without systemd is fairly straightforward. Operating Debian without systemd is a pleasure and every time one of my friends has some systemd-induced lossage I get to feel smug.

comment count unavailable comments

18 July 2023

Jamie McClelland: What am I missing about AI?

Last month I blogged about how the mainstream media is focusing on the wrong parts of the Artificial Intelligence/ChatGPT story. One of the comments left on the post was:
I encourage you to dig a little deeper. If LLM s were just probability
machines, no one would be raising any flags.
Hinton, Bengio, Tegmark and many others are not simpletons. It is the fact that
the architecture and specific training (deep NN, back prop / gradient descend)
produces a system with emergent properties, beyond just a probability machine,
when the system size reaches some thresholds, that has them spooked.
They do understand mathematics and stats and probabilities, i assure you. It is
just that you may have only read the layman s articles and not the scientific
ones
I confess: I haven t made much progress in this regard. I gave Vicky Boykis' Embeddings a go, and started to get a handle on the math, but honestly had a hard time following it. I m open to suggestions from anyone with a few good recommendations for scientific papers accessible to non-math professionals, particularly ones that explain the emergent properties and what that means. Meanwhile, regardless of the scientific truths or falsehoods around chat GPT, the mainstream media continues to miserably fail in helping the rest of us understand the implications of this technology. Most recently, I listend to This American Life s First Contact (part of their Greetings People of Earth show). They interviewed several Microsft AI researchers who first experimented with ChatGPT 4 prior to it s big release. The focus of the researchers was: can we demonstrate chat GPT s general intelligence ability by presenting it with logic problems it could not possibly have encountered before? And the answer: YES! The two examples were:
  1. Stacking: the researcher asked chat GPT how to stack a number of odd objects in a stable way (a book, a dozen eggs, a nail, etc) and chat GPT gave both the correct answer and a reasonable explanation of why.
  2. Hidden state: the researcher described two people in a room with a cat. One person put the cat in a basket and left. The other moved the cat to a box ad left. And, remarkably, chat GPT could explain that when they returned, the first person would think the cat is in the basket and the second person would know it s in the box.
I thought this was pretty cool. So I fired up chat GPT (and even ponied up for chat GPT version 4). I asked it my own stacking question and, hm, chat GPT thought a plate should be placed on top of a can of soda instead of beneath it. So, well, mostly right but I m pretty sure any reasonable human would put the can of soda on the plate not the other way around (chat GPT 3.5 wanted the can of soda to be balanced on the tip of the nail). I then asked it my own simple version of the cat problem and it got it right. Very good. But when I asked it a much more complicated and weird version of the cat problem (involving beetles in a mansion with a movie theater and changing movies and a butler with a big mustache) it got the answer flat out wrong. Did anyone at This American Life try this? Really? It seems like a basic responsibility of journalism to fact check the experts. Maybe the scientists would have had a convincing response? Or maybe scientists are just like everyone else and can get caught up in the excitement and make mistakes? I am amazed and awed by what chat GPT can do - it truly is remarkable. And, I think that a lot of human intelligence is synthesizing what we ve seen and simply regurgitating it in a different context - a task that chat GPT is way better at doing than we are. But the overriding message of most mainstream media stories is that chat GPT is somehow going beyond word synthesis and probability and magically tapping into a form of logic. If the scientific papers are demonstrating this remarkable feat, I think the media needs to do a way better job reporting it.

Lukas M rdian: A declarative approach to Linux networking with Netplan

Photo by Taylor Vick (Unsplash)
Linux networking can be confusing due to the wide range of technology stacks and tools in use, in addition to the complexity of the surrounding network environment. The configuration of bridges, bonds, VRFs or routes can be done programmatically, declaratively, manually or with automated with tools like ifupdown, ifupdown2, ifupdown-ng, iproute2, NetworkManager, systemd-networkd and others. Each of these tools use different formats and locations to store their configuration files. Netplan, a utility for easily configuring networking on a Linux system, is designed to unify and standardise how administrators interact with these underlying technologies. Starting from a YAML description of the required network interfaces and what each should be configured to do, Netplan will generate all the necessary configuration for your chosen tool. In this article, we will provide an overview of how Ubuntu uses Netplan to manage Linux networking in a unified way. By creating a common interface across two disparate technology stacks, IT administrators benefit from a unified experience across both desktops and servers whilst retaining the unique advantages of the underlying tech. But first, let s start with a bit of history and show where we are today.

The history of Netplan in Ubuntu Starting with Ubuntu 16.10 and driven by the need to express network configuration in a common way across cloud metadata and other installer systems, we had the opportunity to switch to a network stack that integrates better with our dependency-based boot model. We chose systemd-networkd on server installations for its active upstream community and because it was already part of Systemd and therefore included in any Ubuntu base installation. It has a much better outlook for the future, using modern development techniques, good test coverage and CI integration, compared to the ifupdown tool we used previously. On desktop installations, we kept using NetworkManager due to its very good integration with the user interface. Having to manage and configure two separate network stacks, depending on the Ubuntu variant in use, can be confusing, and we wanted to provide a streamlined user experience across any flavour of Ubuntu. Therefore, we introduced Netplan.io as a control layer above systemd-networkd and NetworkManager. Netplan takes declarative YAML files from /etc/netplan/ as an input and generates corresponding network configuration for the relevant network stack backend in /run/systemd/network/ or /run/NetworkManager/ depending on the system configuration. All while keeping full flexibility to control the underlying network stack in its native way if need be.
Design overview (netplan.io)

Who is using Netplan? Recent versions of Netplan are available and ready to be installed on many distributions, such as Ubuntu, Fedora, RedHat Enterprise Linux, Debian and Arch Linux.

Ubuntu As stated above, Netplan has been installed by default on Ubuntu systems since 2016 and is therefore being used by millions of users across multiple long-term support versions of Ubuntu (18.04, 20.04, 22.04) on a day-to-day basis. This covers Ubuntu server scenarios primarily, such as bridges, bonding, VLANs, VXLANs, VRFs, IP tunnels or WireGuard tunnels, using systemd-networkd as the backend renderer. On Ubuntu desktop systems, Netplan can be used manually through its declarative YAML configuration files, and it will handle those to configure the NetworkManager stack. Keep reading to get a glimpse of how this will be improved through automation and integration with the desktop stack in the future.

Cloud It might not be as obvious, but many people have been using Netplan without knowing about it when configuring a public cloud instance on AWS, Google Cloud or elsewhere through cloud-init. This is because cloud-init s Networking Config Version 2 is a passthrough configuration to Netplan, which will then set up the underlying network stack on the given cloud instance. This is why Netplan is also a key package on the Debian distribution, for example, as it s being used by default on Debian cloud images, too.

Our vision for Linux networking We know that Linux networking can be a beast, and we want to keep simple things simple. But also allow for custom setups of any complexity. With Netplan, the day-to-day networking needs are covered through easily comprehensible and nicely documented YAML files, that describe the desired state of the local network interfaces, which will be rendered into corresponding configuration files for the relevant network stack and applied at (re-)boot or at runtime, using the netplan apply CLI. For example /etc/netplan/lan.yaml:
network:
  version: 2
  renderer: networkd
  ethernets:
    enp3s0:
      dhcp4: true
Having a single source of truth for network configuration is also important for administrators, so they do not need to understand multiple network stacks, but can rely on the declarative data given in /etc/netplan/ to configure a system, independent of the underlying network configuration backend. This is also very helpful to seed the initial network configuration for new Linux installations, for example through installation systems such as Subiquity, Ubuntu s desktop installer or cloud-init across the public and private clouds. In addition to describing and applying network configuration, the netplan status CLI can be used to query relevant data from the underlying network stack(s), such as systemd-networkd, NetworkManager or iproute2, and present them in a unified way.
Netplan status (Debian)
At the Netplan project we strive for very high test automation and coverage with plenty of unit tests, integration tests and linting steps, across multiple Linux distros, which gives high confidence in also supporting more advanced networking use cases, such as Open vSwitch or SR-IOV network virtualization, in addition to normal wired (static IP, DHCP, routing), wireless (e.g. wwan modems, WPA2/3 connections, WiFi hotspot, controlling the regulatory domain, ) and common server scenarios. Should there ever be a scenario that is not covered by Netplan natively, it allows for full flexibility to control the underlying network stack directly through systemd override configurations or NetworkManager passthrough settings in addition to having manual configuration side-by-side with interfaces controlled through Netplan.

The future of Netplan desktop integration On workstations, the most common scenario is for end users to configure NetworkManager through its user interface tools, instead of driving it through Netplan s declarative YAML files, which makes use of NetworkManager s native configuration files. To avoid Netplan just handing over control to NetworkManager on such systems, we re working on a bidirectional integration between NetworkManager and Netplan to further improve the single source of truth use case on Ubuntu desktop installations. Netplan is shipping a libnetplan library that provides an API to access Netplan s parser and validation internals, that can be used by NetworkManager to write back a network interface configuration. For instance, configuration given through NetworkManager s UI tools or D-Bus API can be exported to Netplan s native YAML format in the common location at /etc/netplan/. This way, administrators just need to care about Netplan when managing a fleet of Desktop installations. This solution is currently being used in more confined environments, like Ubuntu Core, when using the NetworkManager snap, and we will deliver it to generic Ubuntu desktop systems in 24.04 LTS. In addition to NetworkManager, libnetplan can also be used to integrate with other tools in the networking space, such as cloud-init for improved validation of user data or installation systems when seeding new Linux images.

Conclusion Overall, Netplan can be considered to be a good citizen within a network environment that plays hand-in-hand with other networking tools and makes it easy to control modern network stacks, such as systemd-networkd or NetworkManager in a common, streamlined and declarative way. It provides a single source of truth to network administrators about the network state, while keeping simple things simple, but allowing for arbitrarily complex custom setups.
If you want to learn more, feel free to follow our activities on Netplan.io, GitHub, Launchpad, IRC or our Netplan Developer Diaries blog on discourse.

12 July 2023

Reproducible Builds: Reproducible Builds in June 2023

Welcome to the June 2023 report from the Reproducible Builds project In our reports, we outline the most important things that we have been up to over the past month. As always, if you are interested in contributing to the project, please visit our Contribute page on our website.


We are very happy to announce the upcoming Reproducible Builds Summit which set to take place from October 31st November 2nd 2023, in the vibrant city of Hamburg, Germany. Our summits are a unique gathering that brings together attendees from diverse projects, united by a shared vision of advancing the Reproducible Builds effort. During this enriching event, participants will have the opportunity to engage in discussions, establish connections and exchange ideas to drive progress in this vital field. Our aim is to create an inclusive space that fosters collaboration, innovation and problem-solving. We are thrilled to host the seventh edition of this exciting event, following the success of previous summits in various iconic locations around the world, including Venice, Marrakesh, Paris, Berlin and Athens. If you re interesting in joining us this year, please make sure to read the event page] which has more details about the event and location. (You may also be interested in attending PackagingCon 2023 held a few days before in Berlin.)
This month, Vagrant Cascadian will present at FOSSY 2023 on the topic of Breaking the Chains of Trusting Trust:
Corrupted build environments can deliver compromised cryptographically signed binaries. Several exploits in critical supply chains have been demonstrated in recent years, proving that this is not just theoretical. The most well secured build environments are still single points of failure when they fail. [ ] This talk will focus on the state of the art from several angles in related Free and Open Source Software projects, what works, current challenges and future plans for building trustworthy toolchains you do not need to trust.
Hosted by the Software Freedom Conservancy and taking place in Portland, Oregon, FOSSY aims to be a community-focused event: Whether you are a long time contributing member of a free software project, a recent graduate of a coding bootcamp or university, or just have an interest in the possibilities that free and open source software bring, FOSSY will have something for you . More information on the event is available on the FOSSY 2023 website, including the full programme schedule.
Marcel Fourn , Dominik Wermke, William Enck, Sascha Fahl and Yasemin Acar recently published an academic paper in the 44th IEEE Symposium on Security and Privacy titled It s like flossing your teeth: On the Importance and Challenges of Reproducible Builds for Software Supply Chain Security . The abstract reads as follows:
The 2020 Solarwinds attack was a tipping point that caused a heightened awareness about the security of the software supply chain and in particular the large amount of trust placed in build systems. Reproducible Builds (R-Bs) provide a strong foundation to build defenses for arbitrary attacks against build systems by ensuring that given the same source code, build environment, and build instructions, bitwise-identical artifacts are created.
However, in contrast to other papers that touch on some theoretical aspect of reproducible builds, the authors paper takes a different approach. Starting with the observation that much of the software industry believes R-Bs are too far out of reach for most projects and conjoining that with a goal of to help identify a path for R-Bs to become a commonplace property , the paper has a different methodology:
We conducted a series of 24 semi-structured expert interviews with participants from the Reproducible-Builds.org project, and iterated on our questions with the reproducible builds community. We identified a range of motivations that can encourage open source developers to strive for R-Bs, including indicators of quality, security benefits, and more efficient caching of artifacts. We identify experiences that help and hinder adoption, which heavily include communication with upstream projects. We conclude with recommendations on how to better integrate R-Bs with the efforts of the open source and free software community.
A PDF of the paper is now available, as is an entry on the CISPA Helmholtz Center for Information Security website and an entry under the TeamUSEC Human-Centered Security research group.
On our mailing list this month:
The antagonist is David Schwartz, who correctly says There are dozens of complex reasons why what seems to be the same sequence of operations might produce different end results, but goes on to say I totally disagree with your general viewpoint that compilers must provide for reproducability [sic]. Dwight Tovey and I (Larry Doolittle) argue for reproducible builds. I assert Any program especially a mission-critical program like a compiler that cannot reproduce a result at will is broken. Also it s commonplace to take a binary from the net, and check to see if it was trojaned by attempting to recreate it from source.

Lastly, there were a few changes to our website this month too, including Bernhard M. Wiedemann adding a simplified Rust example to our documentation about the SOURCE_DATE_EPOCH environment variable [ ], Chris Lamb made it easier to parse our summit announcement at a glance [ ], Mattia Rizzolo added the summit announcement at a glance [ ] itself [ ][ ][ ] and Rahul Bajaj added a taxonomy of variations in build environments [ ].

Distribution work 27 reviews of Debian packages were added, 40 were updated and 8 were removed this month adding to our knowledge about identified issues. A new randomness_in_documentation_generated_by_mkdocs toolchain issue was added by Chris Lamb [ ], and the deterministic flag on the paths_vary_due_to_usrmerge issue as we are not currently testing usrmerge issues [ ] issues.
Roland Clobus posted his 18th update of the status of reproducible Debian ISO images on our mailing list. Roland reported that all major desktops build reproducibly with bullseye, bookworm, trixie and sid , but he also mentioned amongst many changes that not only are the non-free images being built (and are reproducible) but that the live images are generated officially by Debian itself. [ ]
Jan-Benedict Glaw noticed a problem when building NetBSD for the VAX architecture. Noting that Reproducible builds [are] probably not as reproducible as we thought , Jan-Benedict goes on to describe that when two builds from different source directories won t produce the same result and adds various notes about sub-optimal handling of the CFLAGS environment variable. [ ]
F-Droid added 21 new reproducible apps in June, resulting in a new record of 145 reproducible apps in total. [ ]. (This page now sports missing data for March May 2023.) F-Droid contributors also reported an issue with broken resources in APKs making some builds unreproducible. [ ]
Bernhard M. Wiedemann published another monthly report about reproducibility within openSUSE

Upstream patches

Testing framework The Reproducible Builds project operates a comprehensive testing framework (available at tests.reproducible-builds.org) in order to check packages and other artifacts for reproducibility. In June, a number of changes were made by Holger Levsen, including:
  • Additions to a (relatively) new Documented Jenkins Maintenance (djm) script to automatically shrink a cache & save a backup of old data [ ], automatically split out previous months data from logfiles into specially-named files [ ], prevent concurrent remote logfile fetches by using a lock file [ ] and to add/remove various debugging statements [ ].
  • Updates to the automated system health checks to, for example, to correctly detect new kernel warnings due to a wording change [ ] and to explicitly observe which old/unused kernels should be removed [ ]. This was related to an improvement so that various kernel issues on Ubuntu-based nodes are automatically fixed. [ ]
Holger and Vagrant Cascadian updated all thirty-five hosts running Debian on the amd64, armhf, and i386 architectures to Debian bookworm, with the exception of the Jenkins host itself which will be upgraded after the release of Debian 12.1. In addition, Mattia Rizzolo updated the email configuration for the @reproducible-builds.org domain to correctly accept incoming mails from jenkins.debian.net [ ] as well as to set up DomainKeys Identified Mail (DKIM) signing [ ]. And working together with Holger, Mattia also updated the Jenkins configuration to start testing Debian trixie which resulted in stopped testing Debian buster. And, finally, Jan-Benedict Glaw contributed patches for improved NetBSD testing.

If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Next.

Previous.