Search Results: "evo"

13 April 2016

Mike Gabriel: IPv6: Broken by Design; Digital Ocean - How are we doing?

Recently, Digital Ocean (which I am a customer of) asked me "how they were doing". Well, yet another survey... Let's ignore this one for now... I thought some days ago. And then yesterday, I added IPv6 support to my main mail server (which runs at Hetzner, Germany). All my hosted/rented/whatever systems report back to this main mailserver. Now that that main mail server finally has its AAAA record and its own IPv6 address, all associated systems try to reach this main mail server via IPv6. Of course. Crippling IPv6 support by adding Port Blocks But, then, I see messages like these in my syslog files on droplets hosted at Digital Ocean:
Apr 13 10:10:59 <do-droplet> postfix/smtp[23469]: connect to mail.<mydomain>[<ipv6-address>]:25: Connection timed out
After some more research [1], I realized that the folks out there at DO really apply some port blockings to IPv6 networks, but not to IPv4 networks. Pardon me? From my DO droplets, I can nmap any port on my mail server (25,80,143,443, 465, 587, etc.) via the IPv4 connection, but not over the IPv6 connection. Wait, not fully true: ports 80 and 443 are not blocked, but the other aforementioned ports are definitely blocked. Is Digital Ocean a professional ISP or a WiFi hotspot provider at my nearest coffee place? (This really makes me scratch my head...). Routing only the first 16 addresses of allocated /64 prefixes The above was the second IPv6 brokeness I learned about DO, recently. An earlier issue with DO's IPv6 support, I encountered while I was deploying an IPv6 capable OpenVPN internet gateway via a droplet hosted at DO. Digital Ocean assigns full IPv6 /64 prefixes to each individual droplet (which is great), but only properly routes the first 16 IP addresses of such a /64 prefix [2]. Urgh? I had to work around this flaw by adding an IPv6-over-IPv4 tunnel and attaching an IPv6 /56 prefix obtained from Hurricane Electrics' tunnel broker service [3] to the OpenVPN server. Thanks, Digital Ocean, for reminding me about giving feedback So, today, I luckily received a reminder mail about DO's yet-another-survey survey. My opportunity!!! Here is the feedback, I gave:
DO service is basically good.
BUT: You as a provider SUCK when it comes to IPv6.
(1) http://pixelschatten.net/blocked-ipv6-ports/
-> SMTP/IMAP traffic blocked over IPv6, but not over IPv4... WTF?). I normally have all my systems report back to my main mail server. I expect this to work as it is the default on all Linux hosts nowadays, and that is: prefer IPv6 over IPv4.
(2) https://digitalocean.uservoice.com/forums/136585-digitalocean/suggestion...
-> Droplets get a full /64 prefix assigned, but only the first 16 addresses (or such) get routed properly. WTF?
Please do your homework on IPv6 and don't cripple your service by offering crippled IPv6 support.
I tell people, DO is great, but their IPv6 support is broken-by-design. Let me know, once this is about to change.
Mike Gabriel (aka sunweaver at debian dot org, Debian Developer)
Apology for the tone of the wording Now reading the feedback given, I realize that my tone has been quite impolite. I am sorry about this. However, the experienced IPv6 issues are indeed annoying. So please excuse me for having expressed my annoyance with such harsh words. And... I am still annoyed about myself paying an ISP for such a crippled IPv6 support. (I need to consider migrating the VMs to another hoster, unless there will be some dynamics observable in the near future). @Digital Ocean: Keep up the good work that you do in the realm of VM hosting. Evolve and grow up in the realm of IPv6 networking. Thank you! light+love
Mike [1] http://pixelschatten.net/blocked-ipv6-ports/
[2] https://digitalocean.uservoice.com/forums/136585-digitalocean/suggestion...
[3] https://tunnelbroker.net/
Mehdi Dogguy: 2016 DPL election

It is time of the year where Debian project members should elect a new project leader. This year, only one candidate has stepped up, yours truly. As a reminder, my platform is published here. The campaign has been quite calm, comparing to past editions, which is not surprising given the number of candidates. There have been some interesting questions though as detailed below:
There are not many questions. It will take little time to read, if you haven't already.

Last but not least, please do vote! You have until 2016-04-16 23:59:59 UTC to vote (as announced here). It is very important to share your opinion and take part in the reflection around the future of the project. That every project member takes part in the evolutions that should be implemented to stay relevant and innovative in what we do.

12 April 2016

Reproducible builds folks: Reproducible builds: week 48 in Stretch cycle

What happened in the reproducible builds effort between March 20th and March 26th: Toolchain fixes Daniel Kahn Gillmor worked on removing build path from build symbols submitting a patch adding -fdebug-prefix-map to clang to match GCC, another patch against gcc-5 to backport the removal of -fdebug-prefix-map from DW_AT_producer, and finally by proposing the addition of a normalizedebugpath to the reproducible feature set of dpkg-buildflags that would use -fdebug-prefix-map to replace the current directory with . using -fdebug-prefix-map. Sergey Poznyakoff merged the --clamp-mtime option so that it will be featured in the next Tar release. This option is likely to be used by dpkg-deb to implement deterministic mtimes for packaged files. Packages fixed The following packages have become reproducible due to changes in their build dependencies: augeas, gmtkbabel, ktikz, octave-control, octave-general, octave-image, octave-ltfat, octave-miscellaneous, octave-mpi, octave-nurbs, octave-octcdf, octave-sockets, octave-strings, openlayers, python-structlog, signond. The following packages became reproducible after getting fixed: Some uploads fixed some reproducibility issues, but not all of them: Patches submitted which have not made their way to the archive yet: tests.reproducible-builds.org i386 build nodes have been setup by converting 2 of the 4 amd64 nodes to i386. (h01ger) Package reviews 92 reviews have been removed, 66 added and 31 updated in the previous week. New issues: timestamps_generated_by_xbean_spring, timestamps_generated_by_mangosdk_spiprocessor. Chris Lamb filed 7 FTBFS bugs. Misc. On March 20th, Chris Lamb gave a talk at FOSSASIA 2016 in Singapore. The very same day, but a few timezones apart, h01ger did a presentation at LibrePlanet 2016 in Cambridge, Massachusetts. Seven GSoC/Outreachy applications were made by potential interns to work on various aspects of the reproducible builds effort. On top of interacting with several applicants, prospective mentors gathered to review the applications.

8 April 2016

Colin Watson: No more Hash Sum Mismatch errors

The Debian repository format was designed a long time ago. The oldest versions of it were produced with the help of tools such as dpkg-scanpackages and consumed by dselect access methods such as dpkg-ftp. The access methods just fetched a Packages file (perhaps compressed) and used it as an index of which packages were available; each package had an MD5 checksum to defend against transport errors, but being from a more innocent age there was no repository signing or other protection against man-in-the-middle attacks. An important and intentional feature of the early format was that, apart from the top-level Packages file, all other files were static in the sense that, once published, their content would never change without also changing the file name. This means that repositories can be efficiently copied around using rsync without having to tell it to re-checksum all files, and it avoids network races when fetching updates: the repository you re updating from might change in the middle of your update, but as long as the repository maintenance software keeps superseded packages around for a suitable grace period, you ll still be able to fetch them. The repository format evolved rather organically over time as different needs arose, by what one might call distributed consensus among the maintainers of the various client tools that consumed it. Of course all sorts of fields were added to the index files themselves, which have an extensible format so that this kind of thing is usually easy to do. At some point a Sources index for source packages was added, which worked pretty much the same way as Packages except for having a different set of fields. But by far the most significant change to the repository structure was the package pools project. The original repository layout put the packages themselves under the dists/ tree along with the index files. The dists/ tree is organised by suite (modern examples of which would be stable , stable-updates , testing , unstable , xenial , xenial-updates , and so on). This meant that making a release of Debian tended to involve copying lots of data around, and implementing the testing suite would have been very costly. Package pools solved this problem by moving individual package files out of dists/ and into a new pool/ tree, allowing those files to be shared between multiple suites with only a negligible cost in disk space and mirror bandwidth. From a database design perspective this is obviously much more sensible. As part of this project, the original Debian dinstall repository maintenance scripts were replaced by da-katie or dak , which among other things used a new apt-ftparchive program to build the index files; this replaced dpkg-scanpackages and dpkg-scansources, and included its own database cache which made a big difference to performance at the scale of a distribution. A few months after the initial implementation of package pools, Release files were added. These formed a sort of meta-index for each suite, telling APT which index files were available (main/binary-i386/Packages, non-free/source/Sources, and so on) and what their checksums were. Detached signatures were added alongside that (Release.gpg) so that it was now possible to fetch packages securely given a public key for the repository, and client-side verification support for this eventually made its way into Debian and Ubuntu. The repository structure stayed more or less like this for several years. At some point along the way, those of us by now involved in repository maintenance realised that an important property had been lost. I mentioned earlier that the original format allowed race-free updates, but this was no longer true with the introduction of the Release file. A client now had to fetch Release and then fetch whichever other index files such as Packages they wanted, typically in separate HTTP transactions. If a client was unlucky, these transactions would fall on either side of a mirror update and they d get a Hash Sum Mismatch error from APT. Worse, if a mirror was unlucky and also didn t go to special lengths to verify index integrity (most don t), its own updates could span an update of its upstream mirror and then all its clients would see mismatches until the next mirror update. This was compounded by using detached signatures, so Release and Release.gpg were fetched separately and could be out of sync. Fixing this has been a long road (the first time I remember talking about this was in late 2007!), and we ve had to take care to maintain client/server compatibility along the way. The first step was to add inline-signed versions of the Release file, called InRelease, so that there would no longer be a race between fetching Release and fetching its signature. APT has had this for a while, Debian s repository supports it as of stretch, and we finally implemented it for Ubuntu six months ago. Dealing with the other index files is more complicated, though; it isn t sensible to inline them, as clients usually only need to fetch a small fraction of all the indexes available for a given suite. The solution we ve ended up with, thanks to Michael Vogt s work implementing it in APT, is called by-hash and should be familiar in concept to people who ve used git: with the exception of the top-level InRelease file, index files for suites that support the by-hash mechanism may now be fetched using a URL based on one of their hashes listed in InRelease. This means that clients can now operate like this: This is now enabled by default in Ubuntu. It s only there as of xenial (16.04), since earlier versions of Ubuntu don t have the necessary support in APT. With this, hash mismatches on updates should be a thing of the past. There will still be some people who won t yet benefit from this. debmirror doesn t support by-hash yet; apt-cacher-ng only supports it as of xenial, although there s an easy configuration workaround. Full archive mirrors must make sure that they put new by-hash files in place before new InRelease files (I just fixed our recommended two-stage sync script to do this; ubumirror still needs some work; Debian s ftpsync is almost correct but needs a tweak for its handling of translation files, which I ve sent to its maintainers). Other mirrors and proxies that have specific handling of the repository format may need similar changes. Please let me know if you see strange things happening as a result of this change. It s useful to check the output of apt -o Debug::Acquire::http=true update to see exactly what requests are being issued.

5 April 2016

Matthew Garrett: There's more than one way to exploit the commons

There's a piece of software called XScreenSaver. It attempts to fill two somewhat disparate roles: XScreenSaver does an excellent job of the second of these[2] and is pretty good at the first, which is to say that it only suffers from a disastrous security flaw once very few years and as such is certainly not appreciably worse than any other piece of software.

Debian ships an operating system that prides itself on stability. The Debian definition of stability is a very specific one - rather than referring to how often the software crashes or misbehaves, it refers to how often the software changes behaviour. Debian is very reluctant to upgrade software that is part of a stable release, to the extent that developers will attempt to backport individual security fixes to the version they shipped rather than upgrading to a release that contains all those security fixes but also adds a new feature. The argument here is that the new release may also introduce new bugs, and Debian's users desire stability (in the "things don't change" sense) more than new features. Backporting security fixes keeps them safe without compromising the reason they're running Debian in the first place.

This all makes plenty of sense at a theoretical level, but reality is sometimes less convenient. The first problem is that security bugs are typically also, well, bugs. They may make your software crash or misbehave in annoying but apparently harmless ways. And when you fix that bug you've also fixed a security bug, but the ability to determine whether a bug is a security bug or not is one that involves deep magic and a fanatical devotion to the cause so given the choice between maybe asking for a CVE and dealing with embargoes and all that crap when perhaps you've actually only fixed a bug that makes the letter "E" appear in places it shouldn't and not one that allows the complete destruction of your intergalactic invasion fleet means people will tend to err on the side of "Eh fuckit" and go drinking instead. So new versions of software will often fix security vulnerabilities without there being any indication that they do so[3], and running old versions probably means you have a bunch of security issues that nobody will ever do anything about.

But that's broadly a technical problem and one we can apply various metrics to, and if somebody wanted to spend enough time performing careful analysis of software we could have actual numbers to figure out whether the better security approach is to upgrade or to backport fixes. Conversations become boring once we introduce too many numbers, so let's ignore that problem and go onto the second, which is far more handwavy and social and so significantly more interesting.

The second problem is that upstream developers remain associated with the software shipped by Debian. Even though Debian includes a tool for reporting bugs against packages included in Debian, some users will ignore that and go straight to the upstream developers. Those upstream developers then have to spend at least 15 or so seconds telling the user that the bug they're seeing has been fixed for some time, and then figure out how to explain that no sorry they can't make Debian include a fixed version because that's not how things work. Worst case, the stable release of Debian ends up including a bug that makes software just basically not work at all and everybody who uses it assumes that the upstream author is brutally incompetent, and they end up quitting the software industry and I don't know running a nightclub or something.

From the Debian side of things, the straightforward solution is to make it more obvious that users should file bugs with Debian and not bother the upstream authors. This doesn't solve the problem of damaged reputation, and nor does it entirely solve the problem of users contacting upstream developers. If a bug is filed with Debian and doesn't get fixed in a timely manner, it's hardly surprising that users will end up going upstream. The Debian bugs list for XScreenSaver does not make terribly attractive reading.

So, coming back to the title for this entry. The most obvious failure of the commons is where a basically malicious actor consumes while giving nothing back, but if an actor with good intentions ends up consuming more than they contribute that may still be a problem. An upstream author releases a piece of software under a free license. Debian distributes this to users. Debian's policies result in the upstream author having to do more work. What does the upstream author get out of this exchange? In an ideal world, plenty. The author's software is made available to more people. A larger set of developers is willing to work on making improvements to the software. In a less ideal world, rather less. The author has to deal with bug mail about already fixed bugs. The author's reputation may be harmed by user exposure to said fixed bugs. The author may get less in the way of useful bug fixes or features because people are running old versions rather than fixing new ones. If the balance tips towards the latter, the author's decision to release their software under a free license has made their life more difficult.

Most discussions about Debian's policies entirely ignore the latter scenario, focusing more on the fact that the author chose to release their software under a free license to begin with. If the author is unwilling to handle the consequences of that, goes the argument, why did they do it in the first place? The unfortunate logical conclusion to that argument is that the author realises that they made a huge mistake and never does so again, and woo uh oops.

The irony here is that one of Debian's foundational documents, the Debian Free Software Guidelines, makes allowances for this. Section 4 allows for distribution of software in Debian even if the author insists that modified versions[4] are renamed. This allows for an author to make a choice - allow themselves to be associated with the Debian version of their work and increase (a) their userbase and (b) their support load, or try to distinguish what Debian ship from their identity. But that document was ratified in 1997 and people haven't really spent much time since then thinking about why it says what it does, and so this tradeoff is rarely considered.

Free software doesn't benefit from distributions antagonising their upstreams, even if said upstream is a cranky nightclub owner. Debian's users are Debian's highest priority, but those users are going to suffer if developers decide that not using free licenses improves their quality of life. Kneejerk reactions around specific instances aren't helpful, but now is probably a good time to start thinking about what value Debian bring to its upstream authors and how that can be increased. Failing to do so doesn't serve users, Debian itself or the free software community as a whole.

[1] The X server has no fundamental concept of a screen lock. This is implemented by an application asking that the X server send all keyboard and mouse input to it rather than to any other application, and then that application creating a window that fills the screen. Due to some hilarious design decisions, opening a pop-up menu in an application prevents any other application from being able to grab input and so it is impossible for the screensaver to activate if you open a menu and then walk away from your computer. This is merely the most obvious problem - there are others that are more subtle and more infuriating. The only fix in this case is to nuke the site from orbit.

[2] There's screenshots here. My favourites are the one that emulate the electrical characteristics of an old CRT in order to present a more realistic depiction of the output of an Apple 2 and the one that includes a complete 6502 emulator.

[3] And obviously new versions of software will often also introduce new security vulnerabilities without there being any indication that they do so, because who would ever put that in their changelog. But the less ethically challenged members of the security community are more likely to be looking at new versions of software than ones released three years ago, so you're probably still tending towards winning overall

[4] There's a perfectly reasonable argument that all packages distributed by Debian are modified in some way

comment count unavailable comments

27 March 2016

Lunar: Reproducible builds: week 48 in Stretch cycle

What happened in the reproducible builds effort between March 20th and March 26th:

Toolchain fixes
  • Sebastian Ramacher uploaded breathe/4.2.0-1 which makes its output deterministic. Original patch by Chris Lamb, merged uptream.
  • Rafael Laboissiere uploaded octave/4.0.1-1 which allows packages to be built in place and avoid unreproducible builds due to temporary build directories appearing in the .oct files.
Daniel Kahn Gillmor worked on removing build path from build symbols submitting a patch adding -fdebug-prefix-map to clang to match GCC, another patch against gcc-5 to backport the removal of -fdebug-prefix-map from DW_AT_producer, and finally by proposing the addition of a normalizedebugpath to the reproducible feature set of dpkg-buildflags that would use -fdebug-prefix-map to replace the current directory with . using -fdebug-prefix-map. As succesful result of lobbying at LibrePlanet 2016, the --clamp-mtime option will be featured in the next Tar release. This option is likely to be used by dpkg-deb to implement deterministic mtimes for packaged files.

Packages fixed The following packages have become reproducible due to changes in their build dependencies: augeas, gmtkbabel, ktikz, octave-control, octave-general, octave-image, octave-ltfat, octave-miscellaneous, octave-mpi, octave-nurbs, octave-octcdf, octave-sockets, octave-strings, openlayers, python-structlog, signond. The following packages became reproducible after getting fixed: Some uploads fixed some reproducibility issues, but not all of them: Patches submitted which have not made their way to the archive yet:
  • #818742 on milkytracker by Reiner Herrmann: sorts the list of source files.
  • #818752 on tcl8.4 by Reiner Herrmann: sort source files using C locale.
  • #818753 on tk8.6 by Reiner Herrmann: sort source files using C locale.
  • #818754 on tk8.5 by Reiner Herrmann: sort source files using C locale.
  • #818755 on tk8.4 by Reiner Herrmann: sort source files using C locale.
  • #818952 on marionnet by ceridwen: dummy out build date and uname to make build reproducible.
  • #819334 on avahi by Reiner Herrmann: ship upstream changelog instead of the one generated by gettextize (although duplicate of #804141 by Santiago Vila).

tests.reproducible-builds.org i386 build nodes have been setup by converting 2 of the 4 amd64 nodes to i386. (h01ger)

Package reviews 92 reviews have been removed, 66 added and 31 updated in the previous week. New issues: timestamps_generated_by_xbean_spring, timestamps_generated_by_mangosdk_spiprocessor. Chris Lamb filed 7 FTBFS bugs.

Misc. On March 20th, Chris Lamb gave a talk at FOSSASIA 2016 in Singapore. The very same day, but a few timezones apart, h01ger did a presentation at LibrePlanet 2016 in Cambridge, Massachusetts. Seven GSoC/Outreachy applications were made by potential interns to work on various aspects of the reproducible builds effort. On top of interacting with several applicants, prospective mentors gathered to review the applications. Huge thanks to Linda Naeun Lee for the new hackergotchi visible on Planet Debian.

13 March 2016

Antoine Beaupr : State of Mapping on the Debian Desktop

TL;DR: Mapbox Studio classic is not as good as Tilemill, Mapbox studio is very promising, but you still need to signup for access, and kosmtik seems to be working right now. Use kosmtik and help getting it in Debian.

The requirement I have been following the development of fascinating tools from the Development seed people, now seemingly all focused on the Mapbox brand. They created what seemed to me a revolutionary desktop tool called Tilemill. Tilemill allowed you to create custom map stylesheets on your desktop to outline specific areas or patterns or "things". My interest was to create outdoor maps - OSM has pretty good biking maps, but no generic outdoor tiles out there (I need stuff for skiing, canoeing, biking)... Mapbox has Mapbox outdoors but that's a paid plan as well. Oh and there's a place to download Garmin data files especially made for outdoors as well, and that could be loaded in Qmapshack, but they don't have coverage in Canada at all. Besides, I would like to print maps, I know, crazy... So I have been looking forward to seeing Tilemill packaged in Debian given how annoying it is to maintain Node apps (period). Unfortunately, by the time Debian people figured out all the Node dependencies, the Tilemill project stopped and has been stalled since 2012. It seems the Mapbox people have now been working on other products, and in the meantime, the community, scratching their heads, just switched to other projects.

Overview of alternatives I wrote this long post to the Debian bugtrackers to try to untangle all of this, but figured this would be interesting to a wider community than the narrow group of people working on Javascript packages, so I figured I would send this on Debian planet. So Here's a summary of what happened so far, after Tilemill development stopped. Hang on to your tiles boys and girls, there's a lot going on!

Mapbox Studio classic Mapbox people have released a new product in September 2014 named Mapbox studio classic. The code is still freely available and seems to be a fork of tilemill. Mapbox classic still has releases on github, last one is from November 2015. It looks like Mapbox studio classic has some sort of Mapbox.com lock-in, and there are certainly new copyright issues, if only with the bundled fonts, but it could probably be packaged after addressing those issues. There is an ITP for Mapbox Studio classic as well.

Mapbox Studio Then there's Mapbox Studio, which is a full rewrite of Mapbox Studio classic. You need to "signup" somehow to get access, even though parts of the code are free, namely the Mapbox GL studio project. It is an interesting project because it aims to make all this stuff happen in a web browser, which means it "should" work everywhere. Unfortunately for us, it means it doesn't work anywhere without a signup form, so that's out for me at least. There is an [ITP for Mapbox-studio][] yet it is unclear to me what that one means because the source code to Mapbox-studio doesn't seem to be available, as far as i can tell (and the ITP doesn't say either). That is actually the ITP for Mapbox studio classic.

Kosmtik The Openstreetmap-carto developers have mostly switched to kosmtik instead of Mapbox. Kosmtik is another Node desktop app that seems fairly lightweight and mostly based on plugins. Ross has an ITP for kosmtik. The package is waiting on other node dependencies to be uploaded (yes, again).

The future of Tilemill And there's still this RFP for tilemill, which should probably be closed now because the project seems dead and plenty of alternatives exist. I wonder if node some dependencies that were packaged for Tilemill actually now need to be removed from Debian, because they have become useless leaf packages... I am leaving the Tilemill RFP open for someone to clean that up.

CartoCSS Oh, and finally one could mention another Mapbox project, Carto, a command line CSS tools that implements some sort of standard CSS language that all those tools end up using to talk to Mapnik, more or less. There are no RFPs for that.

11 March 2016

Rapha&#235;l Hertzog: Freexian s report about Debian Long Term Support, February 2016

A Debian LTS logoLike each month, here comes a report about the work of paid contributors to Debian LTS. Individual reports In February, 112.50 work hours have been dispatched among 11 paid contributors. Their reports are available: Evolution of the situation The number of sponsored hours continued to decrease a little bit. It s not worrisome yet but we should try to get back to a positive slope if we want to be able to do an outstanding job for wheezy LTS. On the positive side, TOSHIBA renewed their platinum sponsorship for another 6 months at least and we have some contacts for new sponsors, though they are far from being concluded yet. We are now in transition between squeeze LTS and wheezy LTS. The paid contributors are helping the security team by fixing packages that were fixed in squeeze already but that are still outstanding in wheezy. They are also taking generic measures to prepare wheezy LTS (for example to ensure all packages work with OpenJDK 7.x since support for 6.x will be dropped in the LTS period). Thanks to our sponsors New sponsors are in bold (none this month).

No comment Liked this article? Click here. My blog is Flattr-enabled.

10 March 2016

Antoine Beaupr : Trying out Keybase

I was privileged enough to get access to the alpha preview of Keybase.io. Last year, the project raised 11M$ in venture capital and they seem to be attacking the hard problems, so it is a serious project, worth considering for any cryptography hacker like me. This was obviously discussed elsewhere previously but since Keybase has evolved a bit since then, I figured it would be worth adding my grain of salt.

The elite alpha problem My first problem with Keybase was of course that I wasn't in the elite club of invited people. Somehow, I finally got in but the problem remains for the everyone else. In my case, it was the Keybase filesystem announcement that brought my attention back to the project, although I have yet to test that itself - yet another invite-only problem (need to email chris@keybase.io to get access, I guess). Still, 10GB of storage might be interesting for some people, but considering the number of hurdles or "friction", as they say, that needs to be jumped over to get access, I am not sure how much traction this will get for now. The project has been in alpha for a while now (more than a year) with no announced public beta just yet, which is way slower than similarly challenging projects with less capital. Let's encrypt, as a comparison, was publicly announced in 2014 and by the end of 2015, the public beta was opened.

Private key leakage My second major concern is that Keybase does worrisome things to private key material. If you tell it to import your regular GPG keys, it will copy them into the keybase keyring, which is already a problem: now you have two places where you store sensitive secrets. But worse, Keybase offers you to upload your private key material on the server, without clearly and explicitely exposing the potential risks that means to the user. The key, presumably, is encrypted (at least that is what I can parse from the Keybase privacy policy). Yet this is still a concern: a determined attacker (e.g. the government or another malicious entity) could force Keybase to give up the encrypted private key material and install sniffers that would reveal the passphrase that would allow decryption and impersonation of the related identity. That is a huge deal. This is what caused Hushmail's demise in 2007: they had similar promises about how they had a "secure" email (in this case) service based on OpenPGP, but since they key was stored on the server, they only had to serve a malicious applet to victims and were able to give cleartext data to the US government (12 CDs!) under a Mutual Legal Assistance Treaty with Canada. In Keybase, When I generate a new key, it asks me if I want to upload the key to their servers, and "Yes" is chosen as a default, so it is clearly a policy that is encouraged. This is presumably to enable browser-based crypto, yet this could be done by storing keys within the browser, not on the server. The mere possibility that the client can meddle with secret key material in such a way is a problem. Even if uploading secret keys to the server is optional, the fact that it is a possibility widens the attack surface on the client significantly. GPG has been working on isolating private key operations to a different process (gpg-agent) or smart cards, SSH has privilege seperation. The idea of uploading secret key material online is so beyond current practices that it should bring the project to a full stop already. My private key material is pretty sensitive. I am a Debian developer: if someone gets access to that key, they can upload arbitrary code for thousands of packages, affecting thousands if not millions of users. That is a huge deal, and I am not ready to give that power to an arbitrary third party that I know little about.

Privacy policy issues Furthermore, the Keybase privacy policy explicitely states that "Logs of this information may persist for an indefinite period", which include, and I quote:
  • Your computer s IP address
  • Your preferences and settings (time zone, language, privacy preferences, application preferences, etc.)
  • The URL of the site that referred you to the Service
  • The buttons and controls you clicked on (if any) within the Service
  • How long you used the Service and which parts and features you used
  • Session times and lengths
For a company working to improve user's privacy, this is a pretty bad policy. It exposes Keybase users to undue surveillance, on a lot of private information that is not necessary to operate the service. I haven't actually read the remaining of the policy, as I was already scared as hell and figure I would just log off for now and try not to add any extra personal information in that already growing pile. Let's mention, while I'm here, that the keybase commandline client has this odd way of working that it forks a daemon in the background all the time, even to run just keybase status. One has to wonder if this thing is included in the surveillance data above, which would make the keybase client an amazing surveillance device in itself. To stop all this, you need:
keybase logout
keybase ctl stop
Not quite obvious...

Usability issues Which brings me to a series of usability issues I have found while working with Keybase. Having worked on usability myself in the Monkeysphere project, I understand how hard those problems can be. But right now, the fact is that keybase is only a commandline client, with some web-based sugar sprinkled on top. I recognize the huge efforts that have been done to make the user experience (UX) as easy as possible through the commandline, but this is definitely not "grand public" material yet. Even as a OpenPGP hacker, Keybase can get confusing. Since it has its own separate keyring from GPG, things that used to be obvious before are suddenly new things to learn. For example, I originally generated a key for anarcat@debian.org in keybase, thinking it would be a separate thing from my current GPG identity. Well, that ended up creating a new key in my GPG keyring, duplicating my existing identity, with no way for me to tell this was a Keybase copy. This could have ended up on the keyservers and confuse anyone looking for my PGP key.

Revoking keys So I revoked that key, which, in itself, is not such an obvious process either. I first had to "drop" the key:
keybase pgp drop '010143572d4e438f457a7447c9758804cc7be44c1ee2b7915c3904567d0a3fb5cf590a'
To find that magic number, I had to go on the website and click through the PGP key to end up on the revoke link which told me which magic string to put. The web UI was telling me I could use keybase status to get that information, but I couldn't find that in the output here:
$ keybase status
Username:      anarcat
Logged in:     no
Device:
    name:      angela
    ID:        070f6a13f2a66afbb463f49dadfd4518
    status:    active
Keybase keys:  unlocked
Session:       anarcat [salt only]
KBFS:
    status:    not running
    version:
    log:       /home/anarcat/.cache/keybase/keybase.kbfs.log
Service:
    status:    running
    version:   1.0.14-1
    log:       /home/anarcat/.cache/keybase/keybase.service.log
Platform Information:
    OS:        linux
    Runtime:   go1.5.3
    Arch:      amd64
Client:
    version:   1.0.14-1
Desktop app:
    status:    not running
    version:
    log:       /home/anarcat/.cache/keybase/Keybase.app.log
Config path:   /home/anarcat/.config/keybase/config.json
Default user:  anarcat
Other users:
command-line client:
    keybase status [pid: 14562, version: 1.0.14-1]
So keybase drop "deletes" the key from the keybase client (and presumably the server). One problem here is that we have three different verbs to mean the same thing: in some places, the website says "deleted" (in the web graph), the commandline client uses "drop" and everyone else using PGP in the world uses "revoke". So what is it? Also note that just dropping that key is not enough to eradicate that key: you still need to generate and import a revocation certificate on GPG's side as well, for that key. This makes sense, because you may have imported that key and you may not want to destroy it when you remove it from keybase, but there could be a little better guessing and UX here as well.

Password usage Then another problem is that, when you signup on the commandline, it asks you to choose a passphrase. It's not clear at all from the UI what that passphrase is for. Is it to protect the private key material? To login the website? Both? It turns out it is actually to login to the website and the Keybase API. It could also be the key to the private key material, but I haven't quite figured that out yet. Similarly, the "paper devices" are a little confusing to me as well. The registration process is fairly insistent that I need to write a series of secret words down on a piece of paper and put it my wallet. This is based on the idea that you can use that key to recover your account and setup new devices. However, it is not made clear at all how those credentials should be protected or used. What if I lose my wallet? What do I do then? Is it okay if i write it on the back of my laptop instead? I know it sounds like stupid questions to crypto geek, but it's definitely stuff people will do, and education, at all levels, is necessary here.

The existing web of trust Finally, I found it surprisingly counter-intuitive to sign keys with keybase. I was assuming the whole point of the thing was to expand the web of trust, but it seems their mission lies somewhere else: there is no facility to sign keys directly in keybase. You sign statements on various social sites (Github, Twitter, Reddit...) but doing traditional key exchanges seems to be off limits. My obvious use case was to sign my existing key material with my newly generated anarcat@keybase.io key, so that keybase would become another way of verifying my identity. Well, this is not possible with keybase directly - you still have to go through the regular:
gpg --sign-key DEADBEEF
Which is really unfortunate, because some craaaazy people like me insist on doing in person, actually secure key exchanges sometimes, and the tools to do this right now (mainly gpg, caff and monkeysign) really need a lot of love and help. Keybase could have helped a lot in pushing those initiatives forward and bring new ways of doing secure key exchanges, instead of only lowering the standards on cryptographic identity.

Usual proprietary startup rant I can't help but finish by noticing that the whole basic problem with Keybase is more fundamental than a few usability issues, which can all be fixed fairly easily. Keybase.IO is a web-based service that is entirely proprietary. The client is freely downloadable and free software - but the server side is not. This makes us rely on a central point of failure and the goodwill of those operators to not only keep the service running (for free?) indefinitely, but to protect us against all attackers, state-run or otherwise. This is definitely against basic free software principles and the open architecture of the internet federation, well embodied in the Franklin street statement. Online services should be decentralized and open like the OpenPGP keyservers have always been, period.

Conclusion I am curious to see where Keybase brings us, as a community. So far, I am concerned about centralization and devaluation of the web of trust as cryptographic system. I do not believe that trusting multiple corporate social networking sites bring much benefit to our security, although it does improve usability significantly and is certainly better than TOFU, so that part of the project is definitely interesting, especially since it allows leveraging classical internet protocols like DNS and HTTPS. Key exchange is a critical problem that still hasn't properly been resolved in the cryptographic community. Most efforts at building communication tools (say like Signal or Telegram) mostly ignore the problem and expect people to read up strings of numbers or rely on synchronous communications (see the Axolotl rachet for Signal's take on it). Keybase's attempts at fixing this are great, but needs much more work to actually resolve the PKI issues in a significant way. More fundamentally, the practice of storing keys on the servers should just stop: it is a definite no go for me, and a classic crypto mistake that has bitten way too many people. In my mind, it discredits the whole project. The point of OpenPGP is end to end encryption across devices: storing the keys on a server breaks that apart, and doesn't improve much on the existing HTTPS security systems already in place on the web. It is especially a problem given the new waves of attacks on cryptography from western governments, from the UK to California... Until those issues are resolved, I can't get myself to recommend Keybase to anyone just yet.

Post-scriptum Note to Keybase developers: I have considered filing issues regarding the above, but unfortunately, I was unable to filter through the gigantic github issues list for duplicates, and didn't have time to file detailed reports for everything. I apologize for bypassing those usual conventions. If you want to try out Keybase to make your own opinion, I do have 4 invites I can give away, but I will do so only if you need to test specific issues. Otherwise, I note that there is a Request For Package for the Debian package to become official, that Debian developers (or Keybase developers!) may be interested in completing.

9 March 2016

Guido G nther: Contatacs, CardDAV, Calypso and the N900

As a follow up to calendar synchronisation with calypso, syncevolution and the N900 running maemo I finally added contacts to the mix: on the phone When you have the calendar sync already running it's as simple as: First start ssh on the n900 to ease typing:
apt-get install dropbear
echo /bin/sh >> /etc/shells
cd /etc/dropbear && ./run
SSH into the phone and configure contacts synchronization:
cat <<EOF > ~/.config/syncevolution/webdav/sources/addressbook/config.ini
backend = CardDAV
database = https://carddav.example.com/contacts/username
EOF
And perform the initial sync:
syncevolution --sync slow webdav addressbook
From there on you can sync contacts and calendars in one go with:
syncevoluton webdav
Looking at the calypso logs on the server it seems that syncevoluton does not always generate an FN entry and so the card gets skipped. This doesn't harm the overall sync, but I need to have a look how to fix this. on the laptop In order to use the contacts im mutt there's pycarddav packaged in Debian. This is basically following upstreams documentation.
sudo apt-get install pycarddav
mkdir -p ~/.config/pycard
cp /usr/share/doc/pycarddav/examples/pycard.conf.sample ~/.config/pycard/pycard.conf
# Edit file as needed
cat ~/.config/pycard/pycard.conf
[Account username]
user: username
resource: https://carddav.example.com/
write_support = YesPleaseIDoHaveABackupOfMyData
[query]
where: vcard
[sqlite]
[default]
debug: False
To use the entries in mutt add the just extend your .muttrc:
cat <<EOF >>~/.muttrc
set query_command="pc_query -m %s"
macro index,pager B "<pipe-message>pycard-import<enter>" "add sender address to pycardsyncer"
EOF
This allows you to query contacts using Q and add new conatcs with CTRL-B in mutt's index and pager. Calypso Changes We recently moved calypso's git repository to alioth and started to merge several out of tree patches. More will happen during this years Debian Groupware Meeting including a new upload to Debian.

1 March 2016

Ritesh Raj Sarraf: Linux Power Savings 2016

Having moved to a new place, now at times, I also have to deal with power outages. As heat increases, the power outages will be much longer and more frequent. So much, that UPS and Power Inverters run out. Such are ideal times to measure idle power consumption for my laptop. Here's what my default (and idle) OS looks like. It should be standard to most "typical" users. Some minor odds could be apport, dnsmasq, and maybe, tor. Also, thanks to systemd, there are some native services which are now converted to socket activation based ones. There's also Laptop Mode Tools for userspace power savings. But huge thanks to Intel's work in making the kernel more power efficient. With things like Runtime PM and Intel P-State, we can now define, default and aggressive power-savings modes, helping conserve more power. We still have challenges with things like binary-only drivers; and also stock GPL drivers but with an external firmware blob. There have been many instances when my previous machines (which had both) ran into severe power drain. The challenge with power savings is that it is not just the job of the kernel. All components, kernel and userspace, need to be made aware of, and work in unison. Otherwise, one ill behaving web browser tab can be the cause of power drain. P-State driver seems to already be doing some scale down of CPU resources. And with CGroups maturing moe I think we'll eventually have all Desktop Environments making use of it.
systemd-+-ModemManager-+- gdbus 
                        - gmain 
         -NetworkManager-+- gdbus 
                          - gmain 
         -accounts-daemon-+- gdbus 
                           - gmain 
         -agetty
         -apport-notifyd
         -atd
         -avahi-daemon---avahi-daemon
         -bluetoothd
         -colord-+- gdbus 
                  - gmain 
         -cron
         -dbus-daemon
         -dnsmasq
         -evolution-+- book-client-dbu 
                     - dconf worker 
                     -7*[ evolution ]
                     - gdbus 
                     - gmain 
         -gdm3-+-gdm-session-wor-+-gdm-x-session-+-Xorg
                                                  -gnome-session-b-+-gnome-settings--+- dconf worker 
                                                                                      - gdbus 
                                                                                      - gmain 
                                                                                      - pool 
                                                                                      - threaded-ml 
                                                                    -gnome-shell-+-ibus-daemon-+-ibus-dconf-+- dconf worker 
                                                                                                             - gdbus 
                                                                                                             - gmain 
                                                                                                -ibus-engine-sim-+- gdbus 
                                                                                                                  - gmain 
                                                                                                - gdbus 
                                                                                                - gmain 
                                                                                  - JS GC Helper 
                                                                                  - JS Sour~ Thread 
                                                                                  - dconf worker 
                                                                                  - gdbus 
                                                                                  - gmain 
                                                                                  - threaded-ml 
                                                                    - dconf worker 
                                                                    - gdbus 
                                                                    - gmain 
                                                  - gdbus 
                                                  - gmain 
                                  - gdbus 
                                  - gmain 
                -gdm-session-wor-+-gdm-x-session-+-Xorg
                                                  -gnome-session-b-+-evolution-alarm-+- cal-client-dbus 
                                                                                      - dconf worker 
                                                                                      - evolution-alarm 
                                                                                      - gdbus 
                                                                                      - gmain 
                                                                    -gnome-settings--+- dconf worker 
                                                                                      - gdbus 
                                                                                      - gmain 
                                                                                      - pool 
                                                                                      - threaded-ml 
                                                                    -gnome-shell-+-2*[redshift-+- gdbus ]
                                                                                                - gmain ]
                                                                                  - JS GC Helper 
                                                                                  - JS Sour~ Thread 
                                                                                  - dconf worker 
                                                                                  - gdbus 
                                                                                  - gmain 
                                                                                  - threaded-ml 
                                                                    -parcimonie
                                                                    -parcimonie-appl-+- gdbus 
                                                                                      - gmain 
                                                                    -python3---libinput-debug-
                                                                    -ssh-agent
                                                                    -tracker-extract-+- dconf worker 
                                                                                      - gdbus 
                                                                                      - gmain 
                                                                                      -10*[ pool ]
                                                                    -tracker-miner-a-+- gdbus 
                                                                                      - gmain 
                                                                    -tracker-miner-f-+- dconf worker 
                                                                                      - gdbus 
                                                                                      - gmain 
                                                                    -tracker-miner-u-+- gdbus 
                                                                                      - gmain 
                                                                    - dconf worker 
                                                                    - gdbus 
                                                                    - gmain 
                                                  - gdbus 
                                                  - gmain 
                                  - gdbus 
                                  - gmain 
                - gdbus 
                - gmain 
         -geoclue-+- gdbus 
                   - gmain 
         -gnome-keyring-d-+- gdbus 
                           - gmain 
                           - timer 
         -gpg-agent
         -gsd-printer-+- gdbus 
                       - gmain 
         -ibus-daemon-+-ibus-dconf-+- dconf worker 
                                    - gdbus 
                                    - gmain 
                       -ibus-engine-sim-+- gdbus 
                                         - gmain 
                       - gdbus 
                       - gmain 
         -ibus-x11-+- gdbus 
                    - gmain 
         -iio-sensor-prox-+- gdbus 
                           - gmain 
         -inetd---leafnode
         -libvirtd---15*[ libvirtd ]
         -lvmetad
         -master-+-pickup
                  -qmgr
                  -tlsmgr
         -mcelog
         -minissdpd
         -mount.ntfs
         -onboard-+- dconf worker 
                   - gdbus 
                   - gmain 
         -packagekitd-+- gdbus 
                       - gmain 
         -polkitd-+- gdbus 
                   - gmain 
         -2*[pulseaudio-+-gconf-helper]
                         - alsa-sink-ALC23 ]
                         - alsa-sink-HDMI  ]
                         - alsa-sink-pcspe ]
                         - alsa-source-ALC ]
         -rtkit-daemon---2*[ rtkit-daemon ]
         -systemd-+-(sd-pam)
                   -at-spi-bus-laun-+-dbus-daemon
                                     - dconf worker 
                                     - gdbus 
                                     - gmain 
                   -at-spi2-registr-+- gdbus 
                                     - gmain 
                   -dbus-daemon
                   -dconf-service-+- gdbus 
                                   - gmain 
                   -goa-daemon-+- dconf worker 
                                - gdbus 
                                - gmain 
                   -goa-identity-se-+- gdbus 
                                     - gmain 
                                     - pool 
                   -gvfs-afc-volume-+- gdbus 
                                     - gmain 
                                     - gvfs-afc-volume 
                   -gvfs-goa-volume-+- gdbus 
                                     - gmain 
                   -gvfs-gphoto2-vo-+- gdbus 
                                     - gmain 
                   -gvfs-mtp-volume-+- gdbus 
                                     - gmain 
                   -gvfs-udisks2-vo-+- gdbus 
                                     - gmain 
                   -gvfsd-+- gdbus 
                           - gmain 
                   -gvfsd-fuse-+- gdbus 
                                - gmain 
                                - gvfs-fuse-sub 
                                -2*[ gvfsd-fuse ]
                   -gvfsd-metadata-+- gdbus 
                                    - gmain 
                   -mission-control-+- dconf worker 
                                     - gdbus 
                                     - gmain 
         -systemd-+-(sd-pam)
                   -at-spi-bus-laun-+-dbus-daemon
                                     - dconf worker 
                                     - gdbus 
                                     - gmain 
                   -at-spi2-registr-+- gdbus 
                                     - gmain 
                   -dbus-daemon
                   -gconfd-2
         -systemd-+-(sd-pam)
                   -at-spi-bus-laun-+-dbus-daemon
                                     - dconf worker 
                                     - gdbus 
                                     - gmain 
                   -at-spi2-registr-+- gdbus 
                                     - gmain 
                   -dbus-daemon
                   -dconf-service-+- gdbus 
                                   - gmain 
                   -evolution-addre-+-2*[evolution-addre-+- dconf worker ]
                                                          - evolution-addre ]
                                                          - gdbus ]
                                                          - gmain ]
                                     - dconf worker 
                                     - evolution-addre 
                                     - gdbus 
                                     - gmain 
                   -evolution-calen-+-evolution-calen-+- dconf worker 
                                                       - evolution-calen 
                                                       - gdbus 
                                                       - gmain 
                                                       -6*[ pool ]
                                     -evolution-calen-+- book-client-dbu 
                                                       - dconf worker 
                                                       - evolution-calen 
                                                       - gdbus 
                                                       - gmain 
                                                       - pool 
                                     -2*[evolution-calen-+- dconf worker ]
                                                          - evolution-calen ]
                                                          - gdbus ]
                                                          - gmain ]
                                     - dconf worker 
                                     - evolution-calen 
                                     - gdbus 
                                     - gmain 
                   -evolution-sourc-+- dconf worker 
                                     - gdbus 
                                     - gmain 
                   -gconfd-2
                   -gnome-shell-cal-+- cal-client-dbus 
                                     - dconf worker 
                                     - gdbus 
                                     - gmain 
                                     - gnome-shell-cal 
                   -gnome-terminal--+-bash---pstree
                                     -bash
                                     - dconf worker 
                                     - gdbus 
                                     - gmain 
                   -goa-daemon-+- dconf worker 
                                - gdbus 
                                - gmain 
                   -goa-identity-se-+- gdbus 
                                     - gmain 
                                     - pool 
                   -gpaste-daemon-+- dconf worker 
                                   - gdbus 
                                   - gmain 
                   -gvfs-afc-volume-+- gdbus 
                                     - gmain 
                                     - gvfs-afc-volume 
                   -gvfs-goa-volume-+- gdbus 
                                     - gmain 
                   -gvfs-gphoto2-vo-+- gdbus 
                                     - gmain 
                   -gvfs-mtp-volume-+- gdbus 
                                     - gmain 
                   -gvfs-udisks2-vo-+- gdbus 
                                     - gmain 
                   -gvfsd-+- gdbus 
                           - gmain 
                   -gvfsd-burn-+- gdbus 
                                - gmain 
                   -gvfsd-dnssd-+- gdbus 
                                 - gmain 
                   -gvfsd-fuse-+- gdbus 
                                - gmain 
                                - gvfs-fuse-sub 
                                -2*[ gvfsd-fuse ]
                   -gvfsd-metadata-+- gdbus 
                                    - gmain 
                   -gvfsd-network-+- dconf worker 
                                   - gdbus 
                                   - gmain 
                   -gvfsd-trash-+- gdbus 
                                 - gmain 
                   -mission-control-+- dconf worker 
                                     - gdbus 
                                     - gmain 
                   -nautilus-+-gedit
                              - dconf worker 
                              - gdbus 
                              - gmain 
                   -tracker-store-+- dconf worker 
                                   - gdbus 
                                   - gmain 
                                   -4*[ pool ]
         -systemd-journal
         -systemd-logind
         -systemd-network
         -systemd-timesyn--- sd-resolve 
         -systemd-udevd
         -thermald--- thermald 
         -tor
         -udisksd-+- cleanup 
                   - gdbus 
                   - gmain 
                   - probing-thread 
         -upowerd-+- gdbus 
                   - gmain 
         -wpa_supplicant
So I used the standard power measurement tool, powertop. Below is a screenshot of PowerTop claiming 9 - 10 hours of possible battery backup. This is idle state. "Idle" would mean when the user is not interacting with the machine. When under basic usage (email, web), the actual battery backup I've sensed is somewhere around 6-7 hrs, which is still good from what we got a couple years ago. There's one oddity in the screenshot though. The estimated power consumption reported is 4.55W, where as, the power consumption of just the wifi card is reported 6.17W. That too, when the wifi was disconnected. This reminded me of the bug report against PowerTop, which is now more than 2 years old. We've still not concluded in that bug report, so if anyone can shed some light on PowerTop's reporting, please do share it in the bug report. Note: Please ignore the terminal's title in the screenshot. That is wrong and I've not bothered to figure out why it is displaying the title name constructed from an outdated session, which is already terminated.

Categories:

Keywords:

Like:

27 February 2016

Joey Hess: documentation first

I write documentation first and code second. I've mentioned this from time to time (previously, previously) but a reader pointed out that I've never really explained why I work that way. It's a way to make my thinking more concrete without diving all the way into the complexities of the code right away. So sometimes, what I write down is design documentation, and sometimes it's notes on a bug report[1], but if what I'm working on is user-visible, I start by writing down the end user documentation. Writing things down lets me interact with them as words on a page, which are more concrete than muddled thoughts in the head, and much easier to edit and reason about. Code constrains to existing structures; a blank page frees you to explore and build up new ideas. It's the essay writing process, applied to software development, with a side effect of making sure everything is documented. Also, end-user documentation is best when it doesn't assume that the user has any prior knowledge. The point in time when I'm closest to perfect lack of knowledge about something is before I've built it[2]. So, that's the best time to document it. I understand what I'm trying to tell you better now that I've written it down than I did when I started. Hopefully you do too.
[1] I'll often write a bug report down even if I have found the bug myself and am going to fix it myself on the same day. (example) This is one place where it's nice to have bug reports as files in the same repository as the code, so that the bug report can be included in the commit fixing it. Often the bug report has lots of details that don't need to go into the commit message, but explain more about my evolving thinking about a problem. [2] Technically I'm even more clueless ten years later when I've totally forgotten whatever, but it's not practical to wait. ;-)

17 February 2016

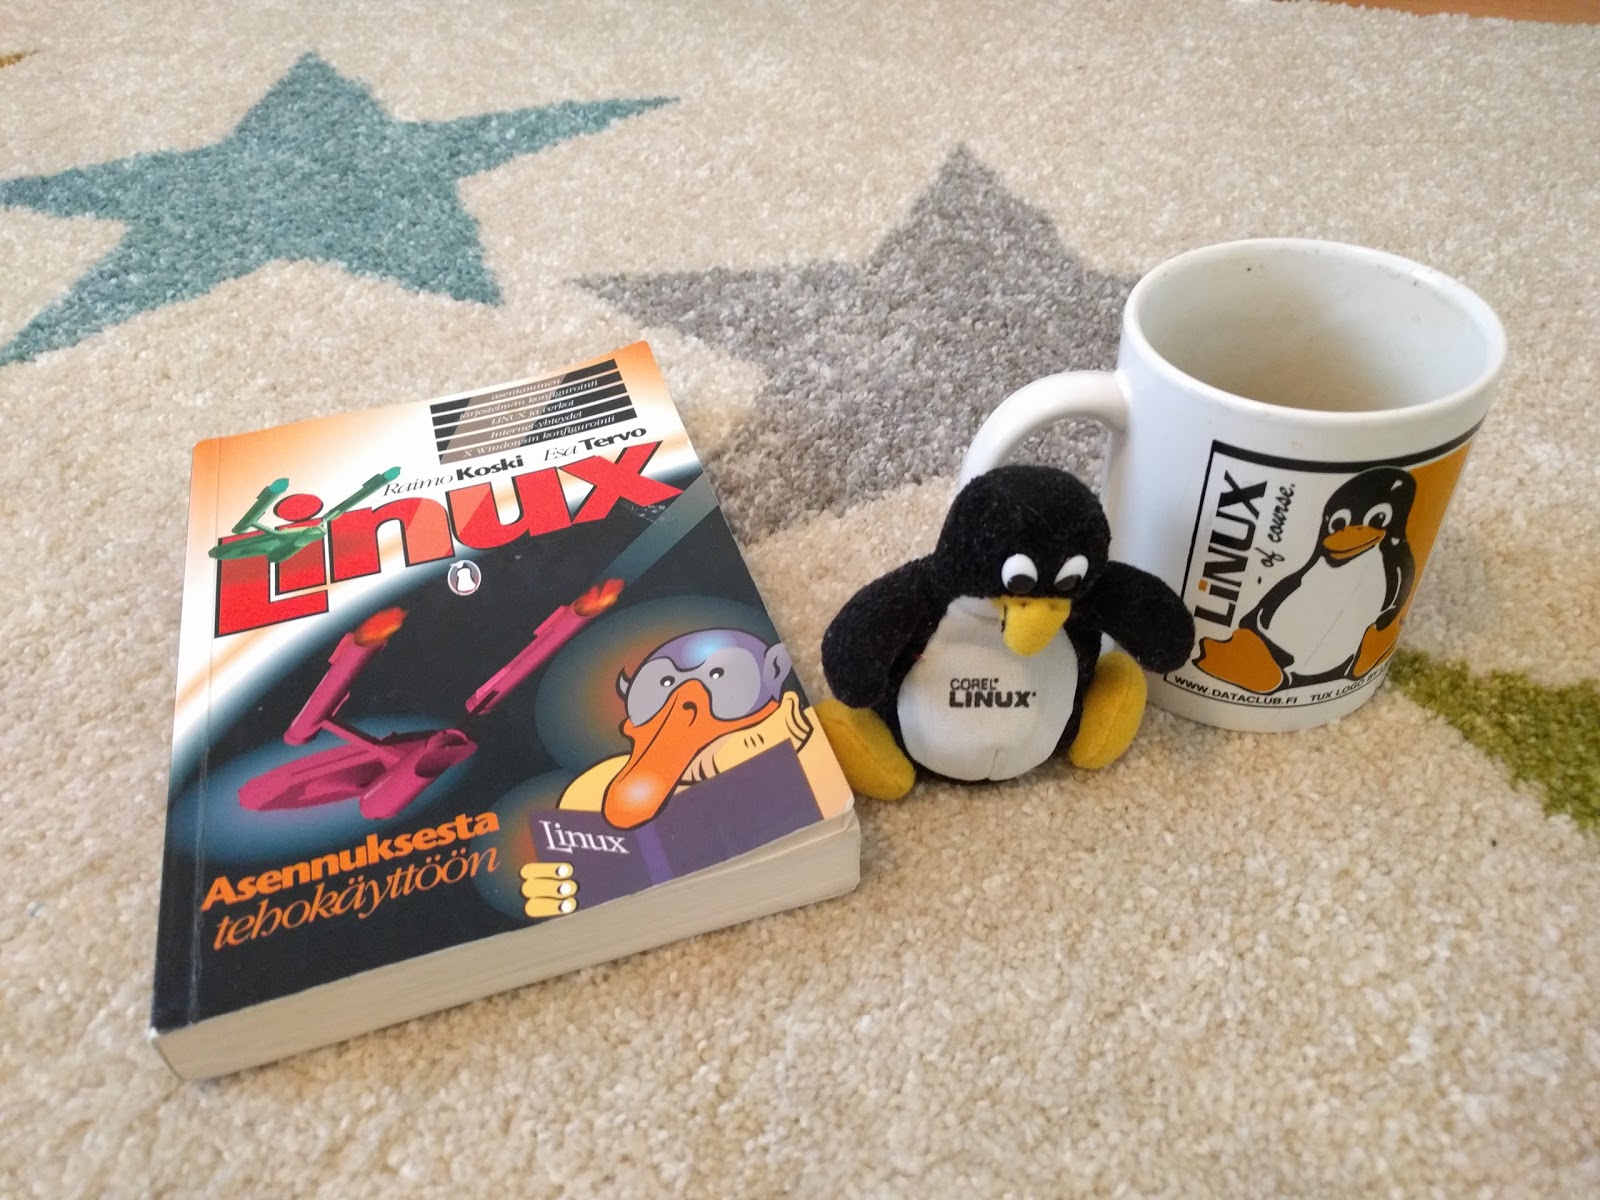
Riku Voipio: Ancient Linux swag

Since I've now been using Linux for 20 years, I've dug up some artifacts from the early journey.
  1. First the book, from late 1995. This from before Tux, so the penguin in the cover is just a co-incidence. The book came with a slackware 3.0 CD, which was my entrance to Linux. Today, almost all of the book is outdated - slackware and lilo install? printing with lpr? mtools and dosemu? ftp, telnet with SLIP dialup? Manually configuring XFree86 and fvwm? How I miss those times!* The only parts of the book are still valid are: shell and vi guides. I didn't read latter, and instead imported my favorite editor from dos FTE.
  2. Fast forward some years, into my first programming job. Ready to advertise the Linux revolution, I bought the mug on right. Nobody else would have a Tux mug, so nobody would accidentally take my mug from the office dishwasher. That only worked for my first work place (a huge and nationally hated IT consultant house). The next workplace, a mobile gaming startup (in 2001, I was there before it was trendy!) - and there was already plenty of Linux mugs when I joined...
  3. While today it may be hard to imagine, those days using Microsoft office tools was mandatory. That leads to the third memorabilia in the picture. Wordperfect for Linux existed for a brief while, and in the box (can you imagine, software came in physical boxes?) came a Tux plush.
* Wait no, I don't miss those times at all

14 February 2016

Rapha&#235;l Hertzog: Freexian s report about Debian Long Term Support, January 2016

A Debian LTS logoLike each month, here comes a report about the work of paid contributors to Debian LTS. Individual reports In December, 113.50 work hours have been dispatched among 9 paid contributors. Their reports are available: Evolution of the situation As expected, we had a small drop in the amount of hours sponsored. New sponsors (re-)joined but others stopped too (Gree this time) mostly balancing the result. We only lost 2 hours of sponsored work. It would be nice if we could invert that curve and actually start again to get closer to our objective of funding the equivalent of a full time position. Let s hope that the switch to wheezy as the version supported by the LTS team will motivate many companies relying on Debian 7 in their IT system. In terms of security updates waiting to be handled, the situation is close to last month(17 packages in dla-needed.txt, 27 in the list of CVE). It looks like that having about 20 packages needing an update is the normal situation and that we can t really get further down given the time required to process some updates (sometimes we wait until the upstream authors provides a patch, and so on). Thanks to our sponsors New sponsors are in bold.

No comment Liked this article? Click here. My blog is Flattr-enabled.

3 February 2016

Sven Hoexter: Moby

Maybe my favourite song of Moby - "That's when I reach for my revolver" - is one of the more unsual ones, slightly more rooted in his Punk years and a cover version. Great artist anyway.

1 February 2016

Ritesh Raj Sarraf: State of Email Clients on Linux Based Platforms

I've been trying to catch up on my reading list (Thanks to rss2email, now I can hold the list longer, than just marking all as read). And one item from last year's end worth spending time was Thunderbird. Thunderbird has been the email client of choice for many users. The main reason for it being popular has been, in my opinion, it being cross platform. Because that allows users an easy migration path across platforms. It also bring persistence, in terms of features and workflows, to the end users. Perhaps that must have been an important reason for many distributions (Ubuntu) and service providers to promote it as the default email client. A Windows/Mac user migrating to Ubuntu will have a lot better experience if they see familiar tools, and their data and workflows being intact. Mozilla must have executed its plan pretty well, to have been able to get it rolling so far. Because other attempts elsewhere (KDE4 Windows) weren't so easy. Part of the reason maybe that any time a new disruptive update is rolled on (KDE4, GNOME3), a lot many frustrated users are born. It is not that people don't want change. Its just that no one likes to see things break. But unfortunately, in Free Software / Open Source world, that is taken lightly. That's one reason why it takes Mozilla so so so long to implement Maildir in TB, when others (Evolution) have had it for so long. So, recently, Mozilla announced its plans to drop Thunderbird development. It is not something new. Anyone using TB knows how long it has been in Maintenance/ESR mode. What was interesting on LWN was the comments. People talked a lot about DE Native Email clients - Kmail, Sylpheed. TUI Clients and these days Browser based clients. Surprisingly, not much was talked about Evolution. My recent move to GNOME has made me look into letting go of old tools/workflows, and try to embrace newer ones. Of them has been GNOME itself. Changing workflows for email was difficult and frustrating. But knowing that TB doesn't have a bright future, it was important to look for alternatives. Just having waited for Maildir and GTK3 port of TB for so long, was enough. On GNOME, Evolution, may give an initial impression of being in Maintenance mode. Especially given that most GNOME apps are now moving to the new UI, which is more touch friendly. And also, because there were other efforts to have another email client on GNOME, I think it is Yorba. But even in its current form, Evolution is a pretty impressive email client Personal Information Management tool. It already is ported to GTK3. Which implies it is capable of responding to Touch events. It sure could have a revised Touch UI, like what is happening with other GNOME Apps. But I'm happy that it has been defered for now. Revising Evolution won't be an easy task, and knowing that GNOME too is understaffed, breaking a perfectly working tool won't be a good idea. My intent with this blog post is to give credit to my favorite GNOME application, i.e. Evolution. So next time you are looking for an email client alternative, give Evolution a try. Today, it already does:
  • Touch UI
  • Maildir
  • Microsoft Exchange
  • GTK3
  • Addressbook, Notes, Tasks, Calendar - Most Standards Based and Google Services compatible
  • RSS Feed Manager
  • And many more that I may not have been using
The only missing piece is being cross-platform. But given the trend, and available resources, I think that path is not worthy of trying. Keep It Simple. Support one platform and support it well.

Categories:

Keywords:

Like:

25 January 2016

Antoine Beaupr : Internet in Cuba

A lot has been written about the Internet in Cuba over the years. I have read a few articles, from New York Times' happy support for Google's invasion of Cuba to RSF's dramatic and fairly outdated report about censorship in Cuba. Having written before about Internet censorship in Tunisia, I was curious to see if I could get a feel of what it is like over there, now that a new Castro is in power and the Obama administration has started restoring diplomatic ties with Cuba. With those political changes coming signifying the end of an embargo that has been called genocidal by the Cuban government, it is surprisingly difficult to get fresh information about the current state of affairs. This article aims to fill that gap in clarifying how the internet works in Cuba, what kind of censorship mechanisms are in place and how to work around them. It also digs more technically into the network architecture and performance. It is published in the hope of providing both Cubans and the rest of the world with a better understanding of their network and, if possible, Cubans ways to access the internet more cheaply or without censorship.

"Censorship" and workarounds Unfortunately, I have been connected to the internet only through the the Varadero airport and the WiFi of a "full included" resort near Jibacoa. I have to come to assume that this network is likely to be on a segregated, uncensored internet while the rest of the country suffers the wrath of the Internet censorship in Cuba I have seen documented elsewhere. Through my research, I couldn't find any sort of direct censorship. The Netalyzr tool couldn't find anything significantly wrong with the connection, other than the obvious performance problems related both to the overloaded uplinks of the Cuban internet. I ran an incomplete OONI probe as well, and it seems there was no obvious censorship detected there as well, at least according to folks in the helpful #ooni IRC channel. Tor also works fine, and could be a great way to avoid the global surveillance system described later in this article. Nevertheless, it still remains to be seen how the internet is censored in the "real" Cuban internet, outside of the tourist designated areas - hopefully future visitors or locals can expand on this using the tools mentioned above, using the regular internet. Usual care should be taken when using any workaround tools, mentioned in this post or not, as different regimes over the world have accused, detained, tortured and killed sometimes for the mere fact of using or distributing circumvention tools. For example, a Russian developer was arrested and detained in 2001 by United States' FBI for exposing vulnerabilities in the Adobe e-books copy protection mechanisms. Similarly, people distributing Tor and other tools have been arrested during the period prior to the revolution in Tunisia.

The Cuban captive portal There is, however, a more pernicious and yet very obvious censorship mechanism at work in Cuba: to get access to the internet, you have to go through what seems to be a state-wide captive portal, which I have seen both at the hotel and the airport. It is presumably deployed at all levels of the internet access points. To get credentials through that portal, you need a username and password which you get by buying a Nauta card. Those cards cost 2$CUC and get you an hour of basically unlimited internet access. That may not seem like a lot for a rich northern hotel party-goer, but for Cubans, it's a lot of money, given that the average monthly salary is around 20$CUC. The system is also pretty annoying to use, because it means you do not get continuous network access: every hour, you need to input a new card, which will obviously make streaming movies and other online activities annoying. It also makes hosting servers basically impossible. So while Cuba does not have, like China or Iran, a "great firewall", there is definitely a big restriction to going online in Cuba. Indeed, it seems to be how the government ensures that Cubans do not foment too much dissent online: keep the internet slow and inaccessible, and you won't get too many Arab spring / blogger revolutions.

Bypassing the Cuban captive portal The good news is that it is perfectly possible for Cubans (or at least for a tourist like me with resources outside of the country) to bypass the captive portal. Like many poorly implemented portals, the portal allows DNS traffic to go through, which makes it possible to access the global network for free by using a tool like iodine which tunnels IP traffic over DNS requests. Of course, the bandwidth and reliability of the connection you get through such a portal is pretty bad. I have regularly seen 80% packet loss and over two minutes of latency:
--- 10.0.0.1 ping statistics ---
163 packets transmitted, 31 received, 80% packet loss, time 162391ms
rtt min/avg/max/mdev = 133.700/2669.535/64188.027/11257.336 ms, pipe 65
Still, it allowed me to login to my home server through SSH using Mosh to workaround the reliability issues. Every once in a while, mosh would get stuck and keep on trying to send packets to probe the server, which would clog the connection even more. So I regularly had to restart the whole stack using these commands:
killall iodine # stop DNS tunnel
nmcli n off # turn off wifi to change MAC address
macchanger -A wlan0 # change MAC address
nmcli n on # turn wifi back on
sleep 3 # wait for wifi to settle
iodine-client-start # restart DNS tunnel
The Koumbit Wiki has good instructions on how to setup a DNS tunnel. I am wondering if such a public service could be of use for Cubans, although I am not sure how it could be deployed only for Cubans, and what kind of traffic it could support... The fact is that iodine does require a server to operate, and that server must be run on the outside of the censored perimeter, something that Cubans may not be able to afford in the first place. Another possible way to save money with the captive portal would be to write something that automates connecting and disconnecting from the portal. You would feed that program a list of credentials and it would connect to the portal only on demand, and disconnect as soon as no traffic goes through. There are details on the implementation of the captive portal below that may help future endeavours in that field.

Private information revealed to the captive portal It should be mentioned, however, that the captive portal has a significant amount of information on clients, which is a direct threat to the online privacy of Cuban internet users. Of course the unique identifiers issued with the Nauta cards can be correlated with your identity, right from the start. For example, I had to give my room number to get a Nauta card issued. Then the central portal also knows which access point you are connected to. For example, the central portal I was connected to Wifi_Memories_Jibacoa which, for anyone that cares to research, will give them a location of about 20 square meters where I was located when connected (there is only one access point in the whole hotel). Finally, the central portal also knows my MAC address, a unique identifier for the computer I am using which also reveals which brand of computer I am using (Mac, Lenovo, etc). While this address can be changed, very few people know that, let alone how. This led me to question whether I would be allowed back in Cuba (or even allowed out!) after publishing this blog post, as it is obvious that I can be easily identified based on the time this article was published, my name and other details. Hopefully the Cuban government will either not notice or not care, but this can be a tricky situation, obviously. I have heard that Cuban prisons are not the best hangout place in Cuba, to say the least...

Network configuration assessment This section is more technical and delves more deeply in the Cuban internet to analyze the quality and topology of the network, along with hints as to which hardware and providers are being used to support the Cuban government.

Line quality The internet is actually not so bad in the hotel. Again, this may be because of the very fact that I am in that hotel, and I get a privileged access to the new fiber line to Venezuela, the ALBA-1 link. The line speed I get is around 1mbps, according to speedtest, which selected a server from LIME in George Town, Cayman Islands:
[1034]anarcat@angela:cuba$ speedtest
Retrieving speedtest.net configuration...
Retrieving speedtest.net server list...
Testing from Empresa de Telecomunicaciones de Cuba (152.206.92.146)...
Selecting best server based on latency...
Hosted by LIME (George Town) [391.78 km]: 317.546 ms
Testing download speed........................................
Download: 1.01 Mbits/s
Testing upload speed..................................................
Upload: 1.00 Mbits/s
Latency to the rest of the world is of couse slow:
--- koumbit.org ping statistics ---
122 packets transmitted, 120 received, 1,64% packet loss, time 18731,6ms
rtt min/avg/max/sdev = 127,457/156,097/725,211/94,688 ms
--- google.com ping statistics ---
122 packets transmitted, 121 received, 0,82% packet loss, time 19371,4ms
rtt min/avg/max/sdev = 132,517/160,095/724,971/93,273 ms
--- redcta.org.ar ping statistics ---
122 packets transmitted, 120 received, 1,64% packet loss, time 40748,6ms
rtt min/avg/max/sdev = 303,035/339,572/965,092/97,503 ms
--- ccc.de ping statistics ---
122 packets transmitted, 72 received, 40,98% packet loss, time 19560,2ms
rtt min/avg/max/sdev = 244,266/271,670/594,104/61,933 ms
Interestingly, Koumbit is actually the closest host in the above test. It could be that Canadian hosts are less affected by bandwidth problems compared to US hosts because of the embargo.

Network topology The various traceroutes show a fairly odd network topology, but that is typical of what I would described as "colonized internet users", which have layers and layers of NAT and obscure routing that keep them from the real internet. Just like large corporations are implementing NAT in a large scale, Cuba seems to have layers and layers of private RFC 1918 IPv4 space. A typical traceroute starts with:
traceroute to koumbit.net (199.58.80.33), 30 hops max, 60 byte packets
 1  10.156.41.1 (10.156.41.1)  9.724 ms  9.472 ms  9.405 ms
 2  192.168.134.137 (192.168.134.137)  16.089 ms  15.612 ms  15.509 ms
 3  172.31.252.113 (172.31.252.113)  15.350 ms  15.805 ms  15.358 ms
 4  pos6-0-0-agu-cr-1.mpls.enet.cu (172.31.253.197)  15.286 ms  14.832 ms  14.405 ms
 5  172.31.252.29 (172.31.252.29)  13.734 ms  13.685 ms  14.485 ms
 6  200.0.16.130 (200.0.16.130)  14.428 ms  11.393 ms  10.977 ms
 7  200.0.16.74 (200.0.16.74)  10.738 ms  10.019 ms  10.326 ms
 8  ix-11-3-1-0.tcore1.TNK-Toronto.as6453.net (64.86.33.45)  108.577 ms  108.449 ms
Let's take this apart line by line:
 1  10.156.41.1 (10.156.41.1)  9.724 ms  9.472 ms  9.405 ms
This is my local gateway, probably the hotel's wifi router.
 2  192.168.134.137 (192.168.134.137)  16.089 ms  15.612 ms  15.509 ms
This is likely not very far from the local gateway, probably still in Cuba. It in one bit away from the captive portal IP address (see below) so it is very likely related to the captive portal implementation.
 3  172.31.252.113 (172.31.252.113)  15.350 ms  15.805 ms  15.358 ms
 4  pos6-0-0-agu-cr-1.mpls.enet.cu (172.31.253.197)  15.286 ms  14.832 ms  14.405 ms
 5  172.31.252.29 (172.31.252.29)  13.734 ms  13.685 ms  14.485 ms
All those are withing RFC 1918 space. Interestingly, the Cuban DNS servers resolve one of those private IPs as within Cuban space, on line #4. That line is interesting because it reveals the potential use of MPLS.
 6  200.0.16.130 (200.0.16.130)  14.428 ms  11.393 ms  10.977 ms
 7  200.0.16.74 (200.0.16.74)  10.738 ms  10.019 ms  10.326 ms
Those two lines are the only ones that actually reveal that the route belongs in Cuba at all. Both IPs are in a tiny (/24, or 256 IP addresses) network allocated to ETECSA, the state telco in Cuba:
inetnum:     200.0.16/24
status:      allocated
aut-num:     N/A
owner:       EMPRESA DE TELECOMUNICACIONES DE CUBA S.A. (IXP CUBA)
ownerid:     CU-CUBA-LACNIC
responsible: Rafael L pez Guerra
address:     Ave. Independencia y 19 Mayo, s/n,
address:     10600 - La Habana - CH
country:     CU
phone:       +53 7 574242 []
owner-c:     JOQ
tech-c:      JOQ
abuse-c:     JEM52
inetrev:     200.0.16/24
nserver:     NS1.NAP.ETECSA.NET
nsstat:      20160123 AA
nslastaa:    20160123
nserver:     NS2.NAP.ETECSA.NET
nsstat:      20160123 AA
nslastaa:    20160123
created:     20030512
changed:     20140610
Then the last hop:
 8  ix-11-3-1-0.tcore1.TNK-Toronto.as6453.net (64.86.33.45)  108.577 ms  108.449 ms  108.257 ms
...interestingly, lands directly in Toronto, in this case going later to Koumbit but that is the first hop that varies according to the destination, hops 1-7 being a common trunk to all external communications. It's also interesting that this shoves a good 90 milliseconds extra in latency, showing that a significant distance and number of equipment crossed. Yet a single hop is crossed, not showing the intermediate step of the Venezuelan link or any other links for that matter. Something obscure is going on there... Also interesting to note is the traceroute to the redirection host, which is only one hop away:
traceroute to 192.168.134.138 (192.168.134.138), 30 hops max, 60 byte packets
 1  192.168.134.138 (192.168.134.138)  6.027 ms  5.698 ms  5.596 ms
Even though it is not the gateway:
$ ip route
default via 10.156.41.1 dev wlan0  proto static  metric 1024
10.156.41.0/24 dev wlan0  proto kernel  scope link  src 10.156.41.4
169.254.0.0/16 dev wlan0  scope link  metric 1000
This means a very close coordination between the different access points and the captive portal system. Finally, note that there seems to be only three peers to the Cuban internet: Teleglobe, formerly Canadian, now owned by the Indian [[!wiki Tata group]], and Telef nica, the Spanish Telco that colonized most of Latin America's internet, all the way down to Argentina. This is confirmed by my traceroutes, which show traffic to Koumbit going through Tata and Google's going through Telef nica.

Captive portal implementation The captive portal is https://www.portal-wifi-temas.nauta.cu/ (not accessible outside of Cuba) and uses a self-signed certificate. The domain name resolves to 190.6.81.230 in the hotel. Accessing http://1.1.1.1/ gives you a status page which allows you to disconnect from the portal. It actually redirects you to https://192.168.134.138/logout.user. That is also a self-signed, but different certificate. That certificate actually reveals the implication of Gemtek which is a "world-leading provider of Wireless Broadband solutions, offering a wide range of solutions from residential to business". It is somewhat unclear if the implication of Gemtek here is deliberate or a misconfiguration on the part of Cuban officials, especially since the certificate is self-signed and was issued in 2002. It could be, however, a trace of the supposed involvement of China in the development of Cuba's networking systems, although Gemtek is based in Taiwan, and not in the China mainland. That IP, in turn, redirects you to the same portal but in a page that shows you the statistics:
https://www.portal-wifi-temas.nauta.cu/?mac=0024D1717D18&script=logout.user&remain_time=00%3A55%3A52&session_time=00%3A04%3A08&username=151003576287&clientip=10.156.41.21&nasid=Wifi_Memories_Jibacoa&r=ac%2Fpopup
Notice how you see the MAC address of the machine in the URL (randomized, this is not my MAC address), along with the remaining time, session time, client IP and the Wifi access point ESSID. There may be some potential in defrauding the session time there, I haven't tested it directly. Hitting Actualizar redirects you back to the IP address, which redirects you to the right URL on the portal. The "real" logout is at:
http://192.168.134.138/logout.user?cmd=logout
The login is performed against https://www.portal-wifi-temas.nauta.cu/index.php?r=ac/login with a referer of:
https://www.portal-wifi-temas.nauta.cu/?&nasid=Wifi_Memories_Jibacoa&nasip=192.168.134.138&clientip=10.156.41.21&mac=EC:55:F9:C5:F2:55&ourl=http%3a%2f%2fgoogle.ca%2f&sslport=443&lang=en-US%2cen%3bq%3d0.8&lanip=10.156.41.1
Again, notice the information revealed to the central portal.

Equipment and providers I ran Nmap probes against both the captive portal and the redirection host, in the hope of finding out how they were built and if they could reveal the source of the equipment used. The complete nmap probes are available in nmap, but it seems that the captive portal is running some embedded device. It is confusing because the probe for the captive portal responds as if it was the gateway, which blurs even more the distinction between the hotel's gateway and the captive portal. This raises the distinct possibility that all access points are actually captive portal that authenticate to another central server. The nmap traces do show three distinct hosts however:
  • the captive portal (www.portal-wifi-temas.nauta.cu, 190.6.81.230)
  • some redirection host (192.168.134.138)
  • the hotel's gateway (10.156.41.1)
They do have distinct signatures so the above may be just me misinterpreting traceroute and nmap results. Your comments may help in clarifying the above. Still, the three devices show up as running Linux, in the two last cases versions between 2.4.21 and 2.4.31. Now, to find out which version of Linux it is running is way more challenging, and it is possible it is just some custom Linux distribution. Indeed, the webserver shows up as G4200.GSI.2.22.0155 and the SSH server is running OpenSSH 3.0.2p1, which is basically prehistoric (2002!) which corroborates the idea that this is some Gemtek embedded device. The fact that those devices are running 14 years old software should be a concern to the people responsible for those networks. There is, for example, a remote root vulnerability that affects that specific version of OpenSSH, among many other vulnerabilities.

A note on Nauta card's security Finally, one can note that it is probably trivial to guess card UIDs. All cards i have here start with the prefix 15100, the following digits being 3576 or 4595, presumably depending on the "batch" that was sent to different hotels, which seems to be batches of 1000 cards. You can also correlate the UID with the date at which the card was issued. For example, 15100357XXX cards are all valid until 19/03/2017, and 151004595XXX cards are all valid until 23/03/2017. Here's the list of UIDs I have seen:
151004595313
151004595974
151003576287
151003576105
151003576097
The passwords, on the other hand, do seem fairly random (although my sample size is small). Interestingly, those passwords are also 12 digits long, which is about as strong as a seven-letter password (mixed uppercase and lowercase). If there are no rate-limiting provisions on that captive portal, it could be possible to guess those passwords, since you have free rein on accessing those routers. Depending on the performance of the routers, you could be lucky and find a working password for free...

Conclusion Clearly, Internet access in Cuba needs to be modernized. We can clearly see that Cuba years behind the rest of the Americas, if only through the percentage of the population with internet access, or download speeds. The existence of a centralized captive portal also enables a huge surveillance potential that should be a concern for any Cuban, or for that matter, anyone wishing to live in a free society. The answer, however, lies not in the liberalization of commerce and opening the doors to the US companies and their own systems of surveillance. It should be possible, and even desirable for Cubans to establish their own neutral network, a proposal I have made in the past even for here in Qu bec. This network could be used and improved by Cubans themselves, prioritizing local communities that would establish their own infrastructure according to their own needs. I have been impressed by this article about the El Paquete system - it shows great innovation and initiative from Cubans which are known for engaging in technology in a creative way. This should be leveraged by letting Cubans do what they want with their networks, not telling them what to do. The best the Googles of this world can do to help Cuba is not to colonize Cuba's technological landscape but to cleanup their own and make their own tools more easily accessible and shareable offline. It is something companies can do right now, something I detailed in a previous article.

24 January 2016

Wouter Verhelst: Playing with Letsencrypt

While I'm not convinced that encrypting everything by default is necessarily a good idea, it is certainly true that encryption has its uses. Unfortunately, for the longest time getting an SSL certificate from a CA was quite a hassle -- and then I'm not even mentioning the fact that it would cost money, too. In that light, the letsencrypt project is a useful alternative: rather than having to dabble with emails or webforms, letsencrypt does everything by way of a few scripts. Also, the letsencrypt CA is free to use, in contrast to many other certificate authorities. Of course, once you start scripting, it's easy to overdo it. When you go to the letsencrypt website and try to install their stuff, they point you to a "letsencrypt-auto" thing, which starts installing a python virtualenv and loads of other crap, just so we can talk to a server and get a certificate properly signed. I'm sure that makes sense for some people, and I'm also sure it makes some things significantly easier, but honestly, I think it's a bit overkill. Luckily, there is also a regular letsencrypt script that doesn't do all the virtualenv stuff, and which is already packaged for Debian, so installing that gets us rid of the overkill bits. It's not in stable, but it is an arch:all package. Unfortunately, not all dependencies are available in Jessie, but backporting it turned out to be not too complicated. Once the client is installed, you need to get it to obtain a certificate, and you need to have the certificate be activated for your webserver. By default, the letsencrypt client will update your server configuration for you, and run a temporary webserver, and do a whole lot of other things that I would rather not see it do. The good news, though, is that you can switch all that off. If you're willing to let it write a few files to your DocumentRoot, it can do the whole thing without any change to your system:
letsencrypt certonly -m <your mailaddress> --accept-tos --webroot -w \
    /path/to/DocumentRoot -d example.com -d www.example.com
In that command, the -m option (with mail address) and the --accept-tos option are only required the first time you ever run letsencrypt. Doing so creates an account for you at letsencrypt.org, without which you cannot get any certificates. The --accept-tos option specifies that you accept their terms of service, which you might want to read first before blindly accepting. If all goes well, letsencrypt will tell you that it wrote your account information and some certificates somewhere under /etc/letsencrypt. All that's left is to update your webserver configuration so that the certificates are actually used. No, I won't tell you how that's done -- if you need that information, it's probably better if you just use the apache or nginx plugin of letsencrypt, which updates your webserver's configuration automatically. But if you already know how to do so, and prefer to maintain your configuration by yourself, then it's good to know that it is at least possible. Since we specified two -d parameters, the certificate you get from the letsencrypt CA will have subjectAlternativeName fields, allowing you to use them for more than one domain name. I specified example.com and www.example.com as the valid names, but there is nothing in letsencrypt requiring that the domain names you specify share a suffix; so yes, it is certainly possible to have multiple domains on a single certificate, if you want that. Finally, you need to ensure that your certificates are renewed before they expire. The easiest way to do that is to add a cronjob, which runs letsencrypt again; only this time, you'll need slightly different options:
letsencrypt certonly --renew-by-default --webroot -w \
    /path/to/DocumentRoot -d domain.name.tld -d www.domain.name.tld
The --renew-by-default option tells letsencrypt that you want to renew your certificates, not create new ones. If you specify this, the old certificate will be revoked, and a new one will be generated, again with three months validity. The symlinks under /etc/letsencrypt/live will be updated, so if your webserver's configuration uses those as the path to your certificates, you don't need to update any configuration files (although you may need to restart your webserver). You'll also notice that the -m and --accept-tos options are not specified this time around; this is because those are only required when you want to create an account -- once that step has been taken, letsencrypt will read the necessary information from its configuration files (and creating a new account for every renewal is just silly). With that, you now have a working, browser-trusted, certificate. Update: fix mistake about installing on Jessie. It's possible (I've done so), but it's been a while and I forgot that I had to recompile several of letsencrypt's dependencies in order for it to be installable.

13 January 2016

Norbert Preining: Ian Buruma: Wages of Guilt

Since moving to Japan, I got more and more interested in history, especially the recent history of the 20th century. The book I just finished, Ian Buruma (Wiki, home page) Wages of Guilt Memories of War in Germany and Japan (Independent, NYRB), has been a revelation for me. As an Austrian living in Japan, I am experiencing the discrepancy between these two countries with respect to their treatment of war legacy practically daily, and many of my blog entries revolve around the topic of Japanese non-reconciliation.
Willy Brandt went down on his knees in the Warsaw ghetto, after a functioning democracy had been established in the Federal Republic of Germany, not before. But Japan, shielded from the evil world, has grown into an Oskar Matzerath: opportunistic, stunted, and haunted by demons, which it tries to ignore by burying them in the sand, like Oskar s drum.
Ian Buruma, Wages of Guilt, Clearing Up the Ruins
Buruma-Wages_of_Guilt The comparison of Germany and Japan with respect to their recent history as laid out in Buruma s book throws a spotlight on various aspects of the psychology of German and Japanese population, while at the same time not falling into the easy trap of explaining everything with difference in the guilt culture. A book of great depth and broad insights everyone having even the slightest interest in these topics should read.
This difference between (West) German and Japanese textbooks is not just a matter of detail; it shows a gap in perception.
Ian Buruma, Wages of Guilt, Romance of the Ruins
Only thinking about giving a halfway full account of this book is something impossible for me. The sheer amount of information, both on the German and Japanese side, is impressive. His incredible background (studies of Chinese literature and Japanese movie!) and long years as journalist, editor, etc, enriches the book with facets normally not available: In particular his knowledge of both the German and Japanese movie history, and the reflection of history in movies, were complete new aspects for me (see my recent post (in Japanese)). The book is comprised of four parts: The first with the chapters War Against the West and Romance of the Ruins; the second with the chapters Auschwitz, Hiroshima, and Nanking; the third with History on Trial, Textbook Resistance, and Memorials, Museums, and Monuments; and the last part with A Normal Country, Two Normal Towns, and Clearing Up the Ruins. Let us look at the chapters in turn: The boook somehow left me with a bleak impression of Japanese post-war times as well as Japanese future. Having read other books about the political ignorance in Japan (Norma Field s In the realm of a dying emperor, or the Chibana history), Buruma s characterization of Japanese politics is striking. He couldn t foresee the recent changes in legislation pushed through by the Abe government actually breaking the constitution, or the rewriting of history currently going on with respect to comfort women and Nanking. But reading his statement about Article Nine of the constitution and looking at the changes in political attitude, I am scared about where Japan is heading to:
The Nanking Massacre, for leftists and many liberals too, is the main symbol of Japanese militarism, supported by the imperial (and imperialist) cult. Which is why it is a keystone of postwar pacifism. Article Nine of the constitution is necessary to avoid another Nanking Massacre. The nationalist right takes the opposite view. To restore the true identity of Japan, the emperor must be reinstated as a religious head of state, and Article Nine must be revised to make Japan a legitimate military power again. For this reason, the Nanking Massacre, or any other example of extreme Japanese aggression, has to be ignored, softened, or denied.
Ian Buruma, Wages of Guilt, Nanking
While there are signs of resistance in the streets of Japan (Okinawa and the Hanako bay, the demonstrations against secrecy law and reversion of the constitution), we are still to see a change influenced by the people in a country ruled and distributed by oligarchs. I don t think there will be another Nanking Massacre in the near future, but Buruma s books shows that we are heading back to a nationalistic regime similar to pre-war times, just covered with a democratic veil to distract critics.
I close with several other quotes from the book that caught my attention: In the preface and introduction:
[ ] mainstream conservatives made a deliberate attempt to distract people s attention from war and politics by concentrating on economic growth.
The curious thing was that much of what attracted Japanese to Germany before the war Prussian authoritarianism, romantic nationalism, pseudo-scientific racialism had lingered in Japan while becoming distinctly unfashionable in Germany.
In Romance of the Ruins:
The point of all this is that Ikeda s promise of riches was the final stage of what came to be known as the reverse course, the turn away from a leftist, pacifist, neutral Japan a Japan that would never again be involved in any wars, that would resist any form of imperialism, that had, in short, turned its back for good on its bloody past. The Double Your Incomes policy was a deliberate ploy to draw public attention away from constitutional issues.
In Hiroshima:
The citizens of Hiroshima were indeed victims, primarily of their own military rulers. But when a local group of peace activists petitioned the city of Hiroshima in 1987 to incorporate the history of Japanese aggression into the Peace Memorial Museum, the request was turned down. The petition for an Aggressors Corner was prompted by junior high school students from Osaka, who had embarrassed Peace Museum officials by asking for an explanation about Japanese responsibility for the war.
The history of the war, or indeed any history, is indeed not what the Hiroshima spirit is about. This is why Auschwitz is the only comparison that is officially condoned. Anything else is too controversial, too much part of the flow of history .
In Nanking, by the governmental pseudo-historian Tanaka:
Unlike in Europe or China, writes Tanaka, you won t find one instance of planned, systematic murder in the entire history of Japan. This is because the Japanese have a different sense of values from the Chinese or the Westerners.
In History on Trial:
In 1950, Becker wrote that few things have done more to hinder true historical self-knowledge in Germany than the war crimes trials. He stuck to this belief. Becker must be taken seriously, for he is not a right-wing apologist for the Nazi past, but an eminent liberal.
There never were any Japanese war crimes trials, nor is there a Japanese Ludwigsburg. This is partly because there was no exact equivalent of the Holocaust. Even though the behavior of Japanese troops was often barbarous, and the psychological consequences of State Shinto and emperor worship were frequently as hysterical as Nazism, Japanese atrocities were part of a military campaign, not a planned genocide of a people that included the country s own citizens. And besides, those aspects of the war that were most revolting and furthest removed from actual combat, such as the medical experiments on human guinea pigs (known as logs ) carried out by Unit 731 in Manchuria, were passed over during the Tokyo trial. The knowledge compiled by the doctors of Unit 731 of freezing experiments, injection of deadly diseases, vivisections, among other things was considered so valuable by the Americans in 1945 that the doctors responsible were allowed to go free in exchange for their data.
Some Japanese have suggested that they should have conducted their own war crimes trials. The historian Hata Ikuhiko thought the Japanese leaders should have been tried according to existing Japanese laws, either in military or in civil courts. The Japanese judges, he believed, might well have been more severe than the Allied tribunal in Tokyo. And the consequences would have been healthier. If found guilty, the spirits of the defendants would not have ended up being enshrined at Yasukuni. The Tokyo trial, he said, purified the crimes of the accused and turned them into martyrs. If they had been tried in domestic courts, there is a good chance the real criminals would have been flushed out.
After it was over, the Nippon Times pointed out the flaws of the trial, but added that the Japanese people must ponder over why it is that there has been such a discrepancy between what they thought and what the rest of the world accepted almost as common knowledge. This is at the root of the tragedy which Japan brought upon herself.
Emperor Hirohito was not Hitler; Hitler was no mere Shrine. But the lethal consequences of the emperor-worshipping system of irresponsibilities did emerge during the Tokyo trial. The savagery of Japanese troops was legitimized, if not driven, by an ideology that did not include a Final Solution but was as racialist as Hider s National Socialism. The Japanese were the Asian Herrenvolk, descended from the gods.
Emperor Hirohito, the shadowy figure who changed after the war from navy uniforms to gray suits, was not personally comparable to Hitler, but his psychological role was remarkably similar.
In fact, MacArthur behaved like a traditional Japanese strongman (and was admired for doing so by many Japanese), using the imperial symbol to enhance his own power. As a result, he hurt the chances of a working Japanese democracy and seriously distorted history. For to keep the emperor in place (he could at least have been made to resign), Hirohito s past had to be freed from any blemish; the symbol had to be, so to speak, cleansed from what had been done in its name.
In Memorials, Museums, and Monuments:
If one disregards, for a moment, the differences in style between Shinto and Christianity, the Yasukuni Shrine, with its relics, its sacred ground, its bronze paeans to noble sacrifice, is not so very different from many European memorials after World War I. By and large, World War II memorials in Europe and the United States (though not the Soviet Union) no longer glorify the sacrifice of the fallen soldier. The sacrificial cult and the romantic elevation of war to a higher spiritual plane no longer seemed appropriate after Auschwitz. The Christian knight, bearing the cross of king and country, was not resurrected. But in Japan, where the war was still truly a war (not a Holocaust), and the symbolism still redolent of religious exultation, such shrines as Yasukuni still carry the torch of nineteenth-century nationalism. Hence the image of the nation owing its restoration to the sacrifice of fallen soldiers.
In A Normal Country:
The mayor received a letter from a Shinto priest in which the priest pointed out that it was un-Japanese to demand any more moral responsibility from the emperor than he had already taken. Had the emperor not demonstrated his deep sorrow every year, on the anniversary of Japan s surrender? Besides, he wrote, it was wrong to have spoken about the emperor in such a manner, even as the entire nation was deeply worried about his health. Then he came to the main point: It is a common error among Christians and people with Western inclinations, including so-called intellectuals, to fail to grasp that Western societies and Japanese society are based on fundamentally different religious concepts . . . Forgetting this premise, they attempt to place a Western structure on a Japanese foundation. I think this kind of mistake explains the demand for the emperor to bear full responsibility.
In Two Normal Towns:
The bust of the man caught my attention, but not because it was in any way unusual; such busts of prominent local figures can be seen everywhere in Japan. This one, however, was particularly grandiose. Smiling across the yard, with a look of deep satisfaction over his many achievements, was Hatazawa Kyoichi. His various functions and titles were inscribed below his bust. He had been an important provincial bureaucrat, a pillar of the sumo wrestling establishment, a member of various Olympic committees, and the recipient of some of the highest honors in Japan. The song engraved on the smooth stone was composed in praise of his rich life. There was just one small gap in Hatazawa s life story as related on his monument: the years from 1941 to 1945 were missing. Yet he had not been idle then, for he was the man in charge of labor at the Hanaoka mines.
In Clearing Up the Ruins:
But the question in American minds was understandable: could one trust a nation whose official spokesmen still refused to admit that their country had been responsible for starting a war? In these Japanese evasions there was something of the petulant child, stamping its foot, shouting that it had done nothing wrong, because everybody did it.
Japan seems at times not so much a nation of twelve-year-olds, to repeat General MacArthur s phrase, as a nation of people longing to be twelve-year-olds, or even younger, to be at that golden age when everything was secure and responsibility and conformity were not yet required.
For General MacArthur was right: in 1945, the Japanese people were political children. Until then, they had been forced into a position of complete submission to a state run by authoritarian bureaucrats and military men, and to a religious cult whose high priest was also formally chief of the armed forces and supreme monarch of the empire.
I saw Jew S ss that same year, at a screening for students of the film academy in Berlin. This showing, too, was followed by a discussion. The students, mostly from western Germany, but some from the east, were in their early twenties. They were dressed in the international uniform of jeans, anoraks, and work shirts. The professor was a man in his forties, a 68er named Karsten Witte. He began the discussion by saying that he wanted the students to concentrate on the aesthetics of the film more than the story. To describe the propaganda, he said, would simply be banal: We all know the what, so let s talk about the how. I thought of my fellow students at the film school in Tokyo more than fifteen years before. How many of them knew the what of the Japanese war in Asia.

Rapha&#235;l Hertzog: Freexian s report about Debian Long Term Support, December 2015

A Debian LTS logoLike each month, here comes a report about the work of paid contributors to Debian LTS. Individual reports In December, 113.50 work hours have been dispatched among 9 paid contributors. Their reports are available: Evolution of the situation We lost our first silver sponsor (Gandi.net, they prefer to give the same amount of money to Debian directly) and another sponsor reduced his sponsorship level. While this won t show in the hours dispatched in January, we will do a small jump backwards in February (unless we get new sponsors replacing those in the next 3 weeks). This is a bit unfortunate as we are rather looking at reinforcing the amount of sponsorship we get as we approach Wheezy LTS and we will need more support to properly support virtualization related packages and other packages that were formerly excluded from Squeeze LTS. Can you convince your company and help us reach our second goal? In terms of security updates waiting to be handled, the situation is close to last month. It looks like that having about 20 packages needing an update is the normal situation and that we can t really get further down given the time required to process some updates (sometimes we wait until the upstream authors provides a patch, and so on). Thanks to our sponsors We got one new bronze sponsor but he s not listed (he did not fill the form where we request their permission to be listed).

2 comments Liked this article? Click here. My blog is Flattr-enabled.

Next.

Previous.