Search Results: "ed"

21 December 2025

Russell Coker: Links December 2025

Russ Allbery wrote an interesting review of Politics on the Edge, by Rory Stewart who sems like one of the few conservative politicians I could respect and possibly even like [1]. It has some good insights about the problems with our current political environment. The NY Times has an amusing article about the attempt to sell the solution to the CIA s encrypted artwork [2]. Wired has an interesting article about computer face recognition systems failing on people with facial disabilities or scars [3]. This is a major accessibility issue potentially violating disability legislation and a demonstration of the problems of fully automating systems when there should be a human in the loop. The October 2025 report from the Debian Reproducible Builds team is particularly interesting [4]. kpcyrd forwarded a fascinating tidbit regarding so-called ninja and samurai build ordering, that uses data structures in which the pointer values returned from malloc are used to determine some order of execution LOL Louis Rossmann made an insightful youtube video about the moral case for piracy of software and media [5]. Louis Rossman made an insightful video about the way that Hyundai is circumventing Right to Repair laws to make repairs needlessly expensive [6]. Korean cars aren t much good nowadays. Their prices keep increasing and the quality doesn t. Brian Krebs wrote an interesting article about how Google is taking legal action against SMS phishing crime groups [7]. We need more of this! Josh Griffiths wrote an informative blog post about how YouTube is awful [8]. I really should investigate Peertube. Louis Rossman made an informative YouTube video about Right to Repair and the US military, if even the US military is getting ripped off by this it s a bigger problem than most people realise [9]. He also asks the rhetorical question of whether politicians are bought or whether it s a subscription model . Brian Krebs wrote an informative article about the US plans to ban TP Link devices, OpenWRT seems like a good option [10]. Brian Krebs wrote an informative article about free streaming Android TV boxes that act as hidden residential VPN proxies [11]. Also the free streaming violates copyright law. Bruce Schneier and Nathan E. Sanders wrote an interesting article about ways that AI is being used to strengthen democracy [12]. Cory Doctorow wrote an insightful article about the incentives for making shitty goods and services and why we need legislation to protect consumers [13]. Linus Tech Tips has an interesting interview with Linus Torvalds [14]. Interesting video about the Kowloon Walled City [15]. It would be nice if a government deliberately created a hive city like that, the only example I know of is the Alaskan town in a single building. David Brin wrote an insightful set of 3 blog posts about a Democratic American deal that could improve the situation there [16].

20 December 2025

Sahil Dhiman: MiniDebConf Navi Mumbai 2025

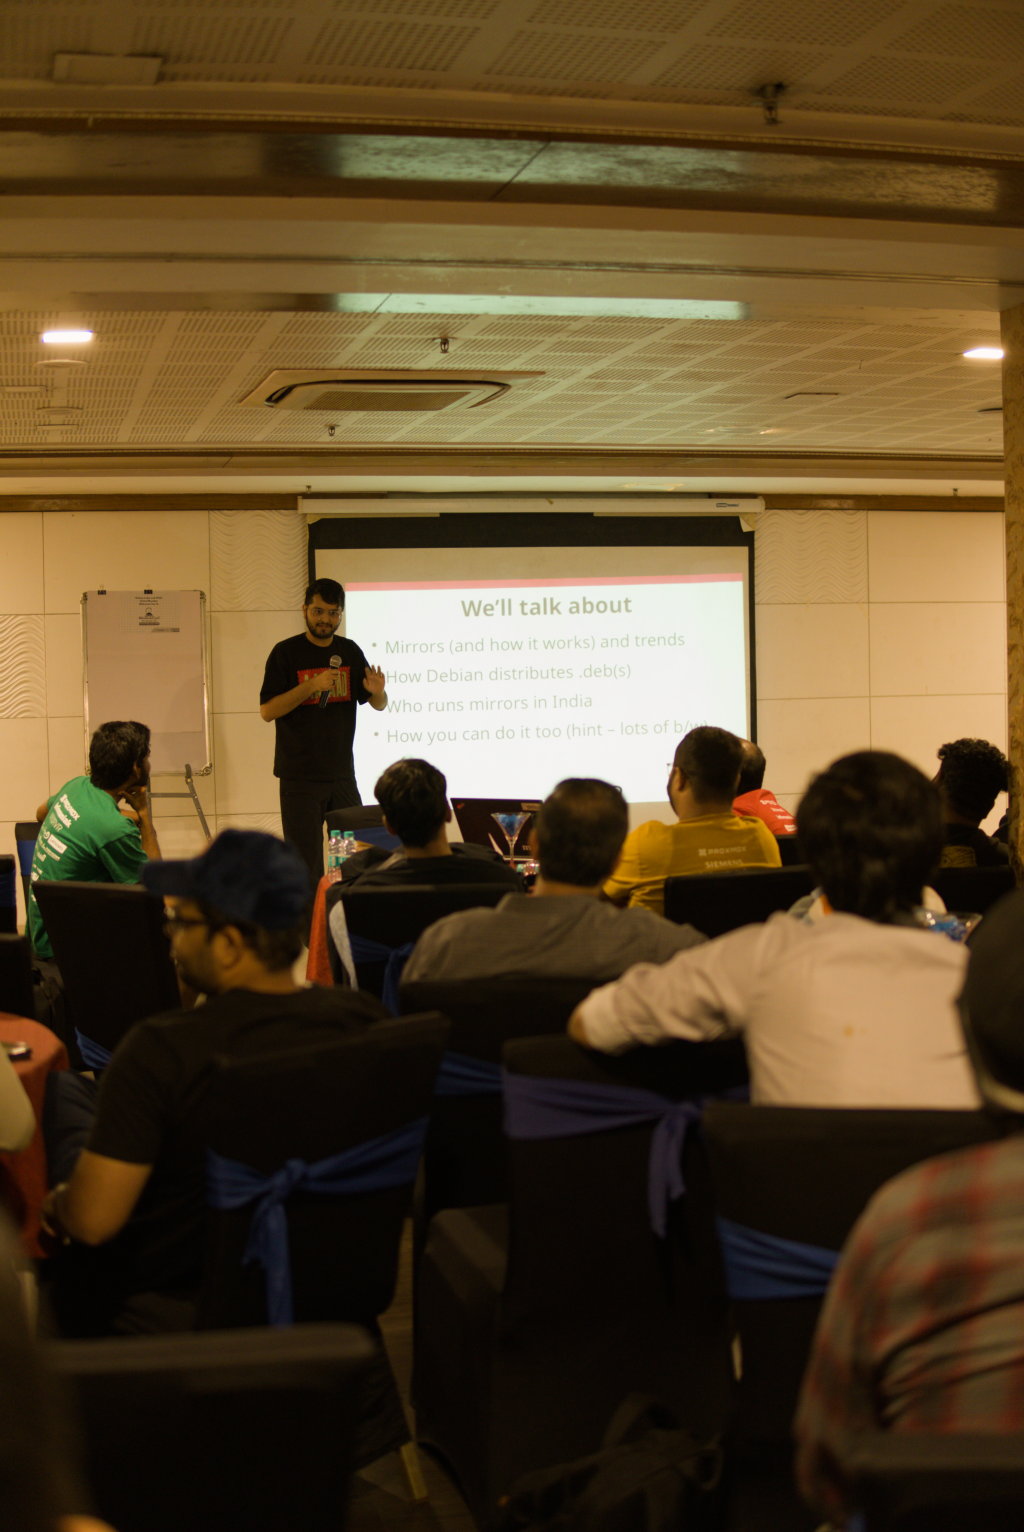
MiniDebConf Navi Mumbai 2025 which was MiniDebConf Mumbai, which in turn was FOSSMumbai x MiniDebian Conference, happened on 13th and 14th December, 2025, with a hotel as Day 1 venue and a college on Day 2. Originally planned for the 8th of November, it got postponed to December due to operational reasons. Most of the on-ground logistics and other heavy lifting was done by Arya, Vidhya, MumbaiFOSS, and the Remigies Technologies team, so we didn t had to worry much. This time, I gave a talk on Basics of a Free Software Mirror (and how Debian does it) (Presentation URL). I had the idea for this talk for a while and gave a KDE version of it during KDE India Conf 2025. The gist was to explain how Free Software is delivered to users and how one can help. For MDC, I focused a bit on Debian mirror network(s) and who else host mirrors in India and trends.
Me during mirror talk
Credits - niyabits. Thanks for the pictures
At the onset someone mentioned my Termux mirror. Termux is a good project to get into mirror hosting with. I got into mirroring with it. It has low traffic (usually less than 20 GB/day) demands with a high request count and can be done on an existing 6 USD Digital Ocean nodes. Q&A time turned out more interesting than I anticipated. Folks touched upon commercial CDNs instead of community mirrors, supply chain security issues, and a bit of other stuff. We had quite a number of interesting talks and I remember when Arya was telling me during CFP time, bro we have too many talks now :D. Now, preparations have already started for MiniDebConf Kanpur 2026, scheduled for March 14th and 15th at the IIT campus. If you want to help, see the following thread. See you in the next one. A group photo
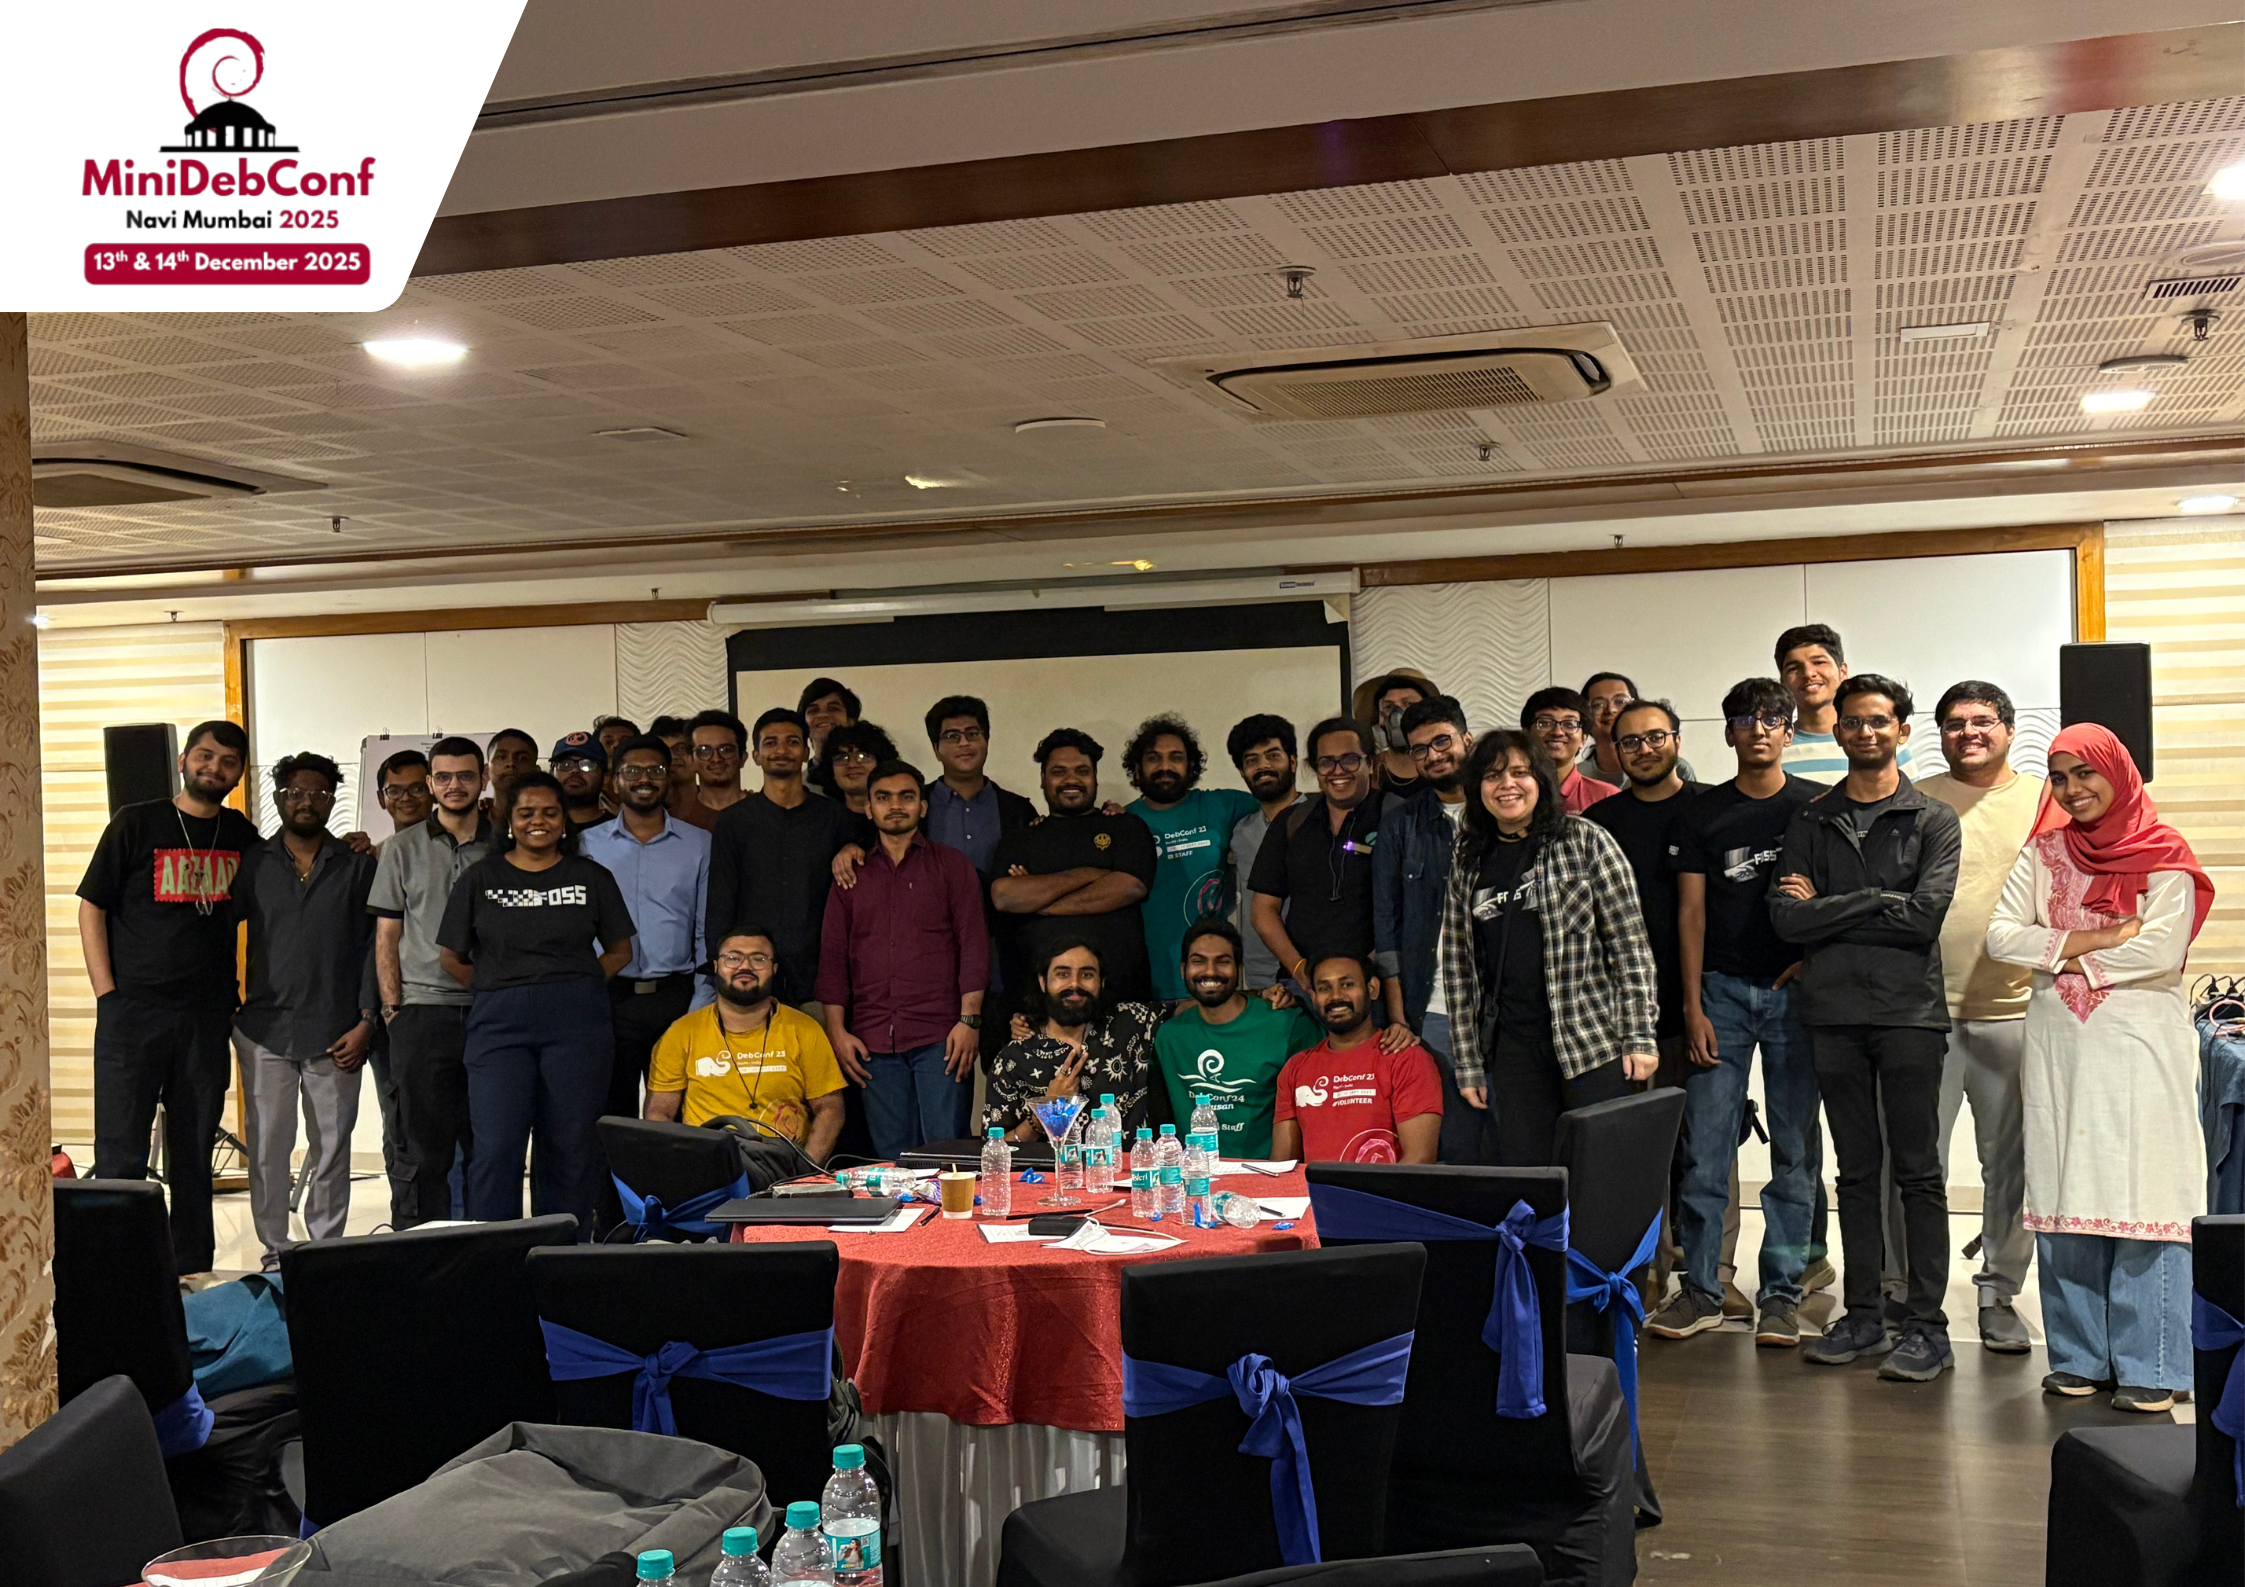
Day 1 group photo. Click to enlarge

A group photo
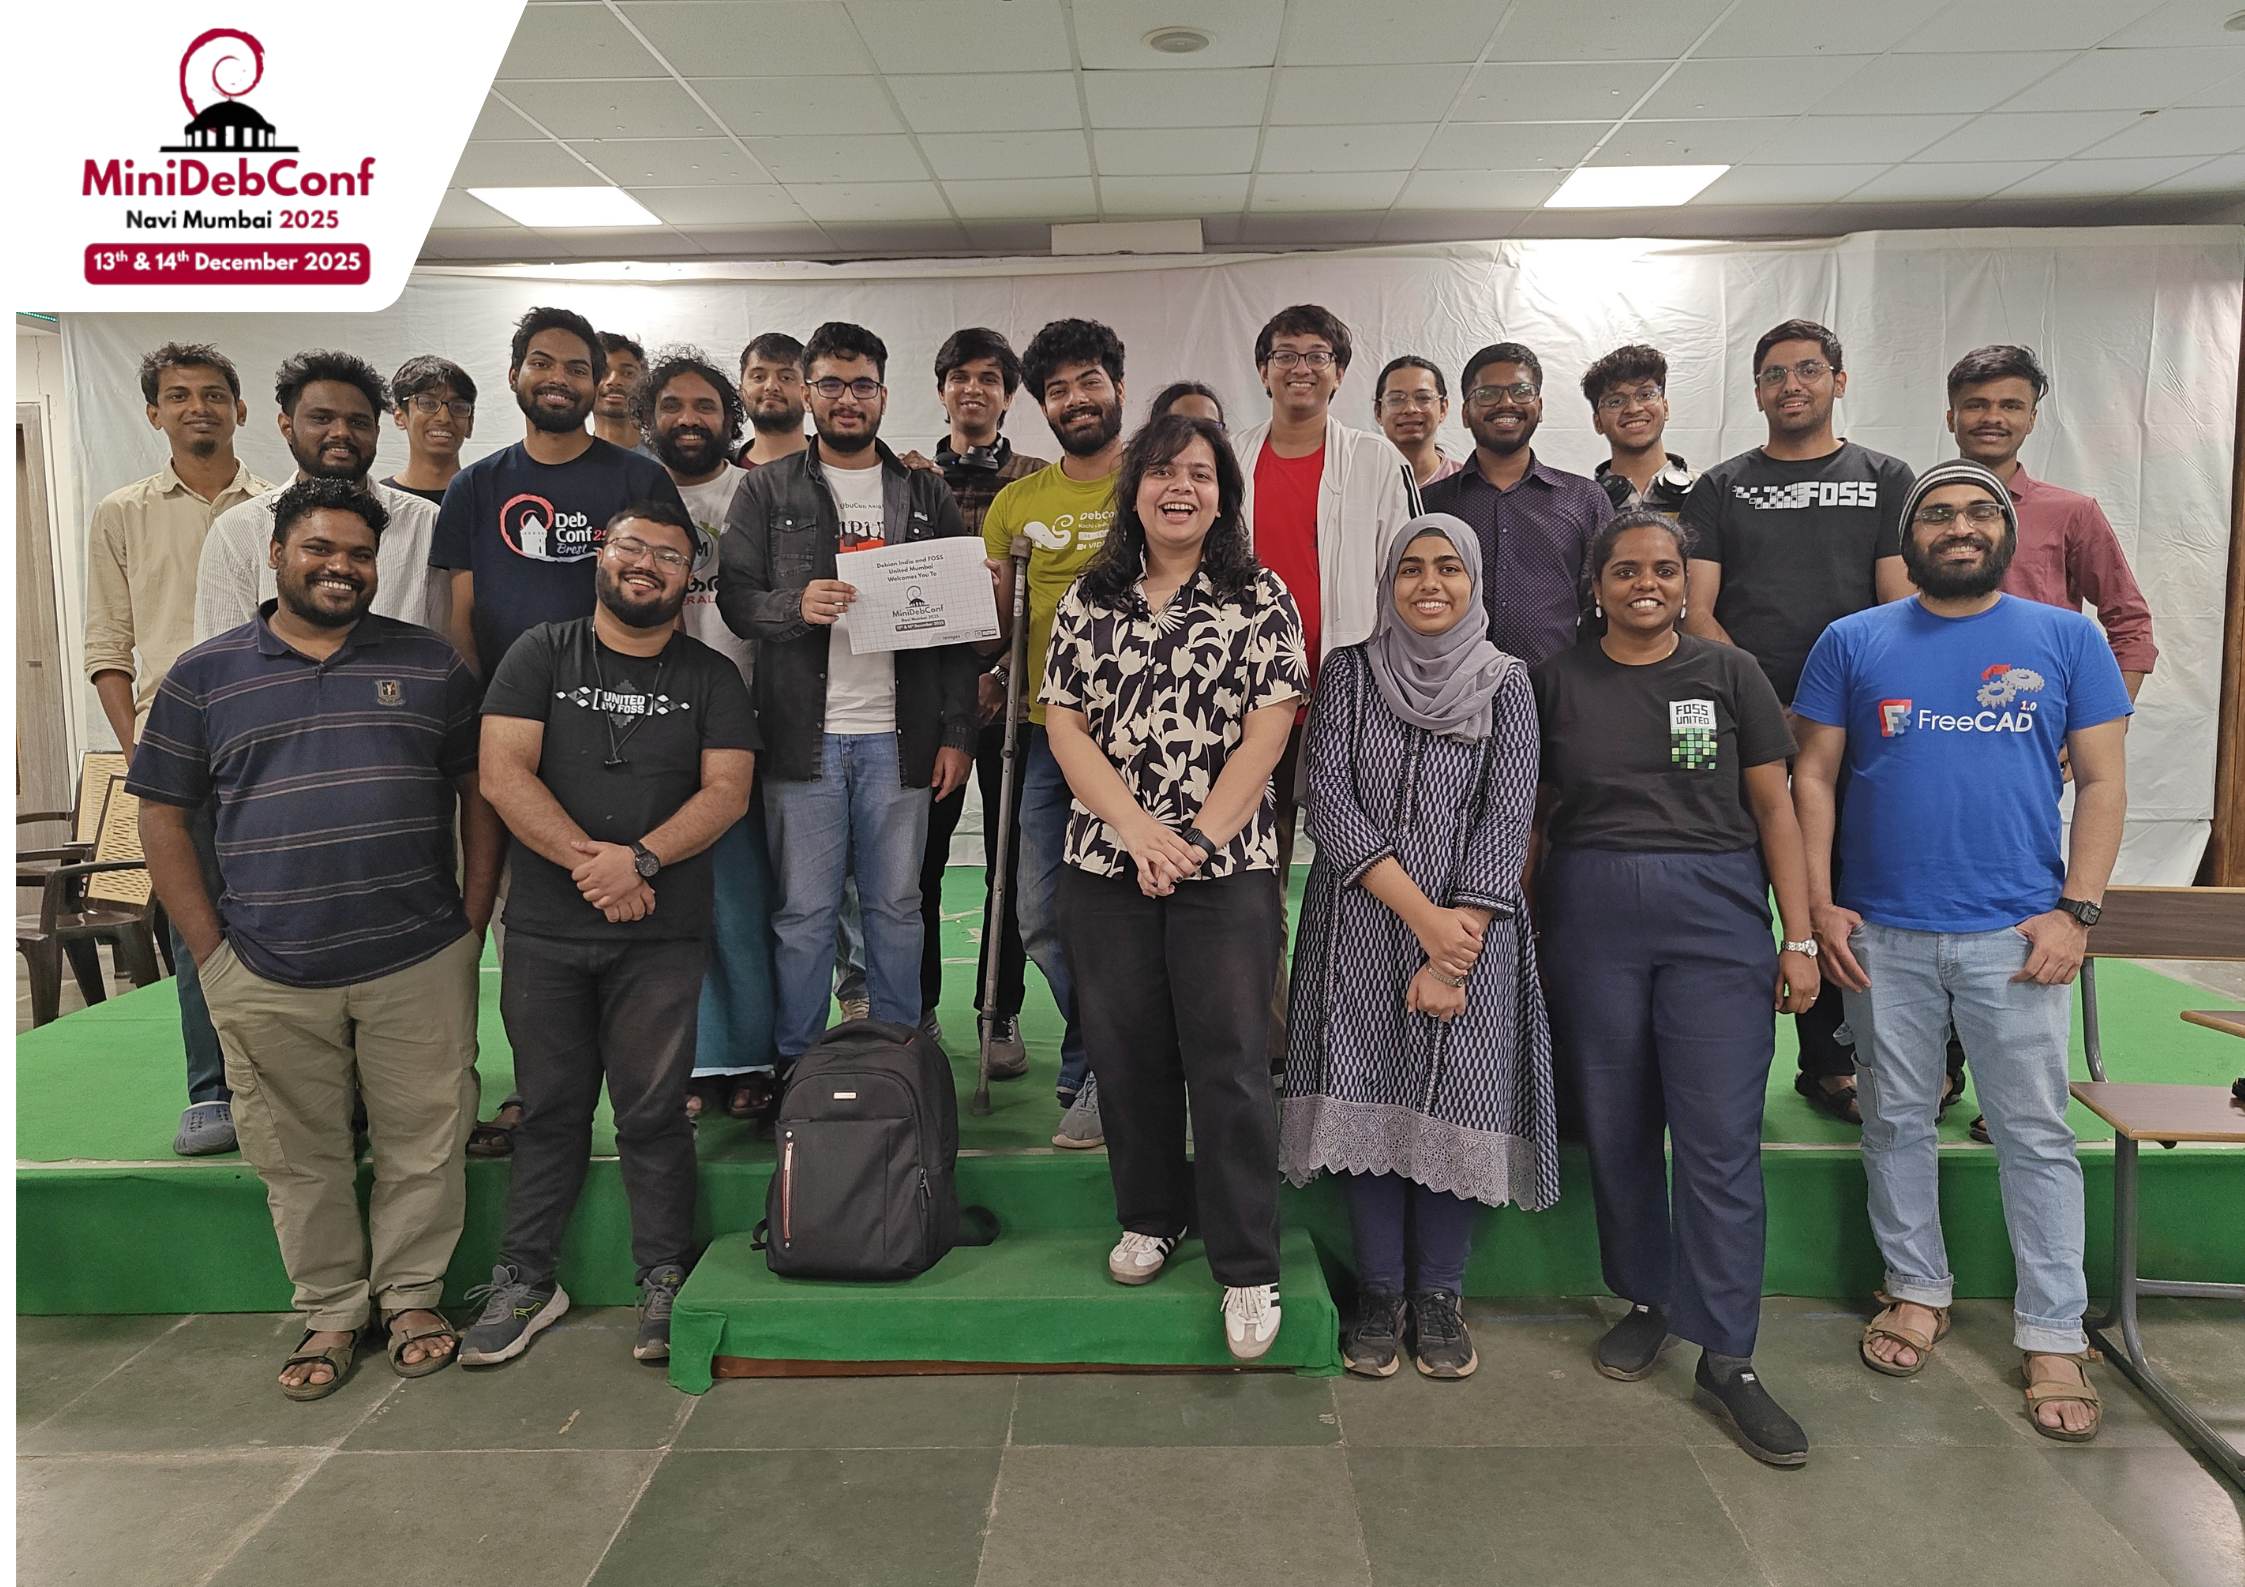
Day 2 group photo. Click to enlarge

19 December 2025

Kartik Mistry: KDE Needs You!

* KDE Randa Meetings and make a donation! I know that my contributions to KDE are minimal at this stage, but hey, I m doing my part this time for sure!

Otto Kek l inen: Backtesting trailing stop-loss strategies with Python and market data

Featured image of post Backtesting trailing stop-loss strategies with Python and market dataIn January 2024 I wrote about the insanity of the Magnificent Seven dominating the MSCI World Index, and I wondered how long the number can continue to go up? It has continued to surge upward at an accelerating pace, which makes me worry that a crash is likely closer. As a software professional, I decided to analyze whether using stop-loss orders could reliably automate avoiding deep drawdowns. As everyone with some savings in the stock market (hopefully) knows, the stock market eventually experiences crashes. It is just a matter of when and how deep the crash will be. Staying on the sidelines for years is not a good investment strategy, as inflation will erode the value of your savings. Assuming the current true inflation rate is around 7%, a restaurant dinner that costs 20 euros today will cost 24.50 euros in three years. Savings of 1000 euros today would drop in purchasing power from 50 dinners to only 40 dinners in three years. Hence, if you intend to retain the value of your hard-earned savings, they need to be invested in something that grows in value. Most people try to beat inflation by buying shares in stable companies, directly or via broad market ETFs. These historically grow faster than inflation during normal years, but likely drop in value during recessions.

What is a trailing stop-loss order? What if you could buy stocks to benefit from their value increasing without having to worry about a potential crash? All modern online stock brokers have a feature called stop-loss, where you can enter a price at which your stocks automatically get sold if they drop down to that price. A trailing stop-loss order is similar, but instead of a fixed price, you enter a margin (e.g. 10%). If the stock price rises, the stop-loss price will trail upwards by that margin. For example, if you buy a share at 100 euros and it has risen to 110 euros, you can set a 10% trailing stop-loss order which automatically sells it if the price drops 10% from the peak of 110 euros, at 99 euros. Thus, no matter what happens, you only lost 1 euro. And if the stock price continues to rise to 150 euros, the trailing stop-loss would automatically readjust to 150 euros minus 10%, which is 135 euros (150-15=135). If the price dropped to 135 euros, you would lock in a gain of 35 euros, which is not the peak price of 150 euros, but still better than whatever the price fell down to as a result of a large crash. In the simple case above, it obviously makes sense in theory, but it might not make sense in practice. Prices constantly oscillate, so you don t want a margin that is too small, otherwise you exit too early. Conversely, having a large margin may result in too large a drawdown before exiting. If markets crash rapidly, it might be that nobody buys your stocks at the stop-loss price, and shares have to be sold at an even lower price. Also, what will you do once the position is sold? The reason you invested in the stock market was to avoid holding cash, so would you buy the same stock back when the crash bottoms? But how will you know when the bottom has been reached?

Backtesting stock market strategies with Python, YFinance, Pandas and Lightweight Charts I am not a professional investor, and nobody should take investment advice from me. However, I know what backtesting is and how to leverage open source software. So, I wrote a Python script to test if the trading strategy of using trailing stop-loss orders with specific margin values would have worked for a particular stock. First you need to have data. YFinance is a handy Python library that can be used to download the historic price data for any stock ticker on Yahoo.com. Then you need to manipulate the data. Pandas is the Python data analysis library with advanced data structures for working with relational or labeled data. Finally, to visualize the results, I used Lightweight Charts, which is a fast, interactive library for rendering financial charts, allowing you to plot the stock price, the trailing stop-loss line, and the points where trades would have occurred. I really like how the zoom is implemented in Lightweight Charts, which makes drilling into the data points feel effortless. The full solution is not polished enough to be published for others to use, but you can piece together your own by reusing some of the key snippets. To avoid re-downloading the same data repeatedly, I implemented a small caching wrapper that saves the data locally (as Parquet files):
python
CACHE_DIR.mkdir(parents=True, exist_ok=True)
end_date = datetime.today().strftime("%Y-%m-%d")
cache_file = CACHE_DIR / f" TICKER - START_DATE -- end_date .parquet"

if cache_file.is_file():
 dataframe = pandas.read_parquet(cache_file)
 print(f"Loaded price data from cache:  cache_file ")
else:
 dataframe = yfinance.download(
 TICKER,
 start=START_DATE,
 end=end_date,
 progress=False,
 auto_adjust=False
 )

 dataframe.to_parquet(cache_file)
 print(f"Fetched new price data from Yahoo Finance and cached to:  cache_file ")
The dataframe is a Pandas object with a powerful API. For example, to print a snippet from the beginning and the end of the dataframe to see what the data looks like, you can use:
python
print("First 5 rows of the raw data:")
print(df.head())
print("Last 5 rows of the raw data:")
print(df.tail())
Example output:
First 5 rows of the raw data
Price Adj Close Close High Low Open Volume
Ticker BNP.PA BNP.PA BNP.PA BNP.PA BNP.PA BNP.PA
Date
2014-01-02 29.956285 55.540001 56.910000 55.349998 56.700001 316552
2014-01-03 30.031801 55.680000 55.990002 55.290001 55.580002 210044
2014-01-06 30.080338 55.770000 56.230000 55.529999 55.560001 185142
2014-01-07 30.943321 57.369999 57.619999 55.790001 55.880001 370397
2014-01-08 31.385597 58.189999 59.209999 57.750000 57.790001 489940
Last 5 rows of the raw data
Price Adj Close Close High Low Open Volume
Ticker BNP.PA BNP.PA BNP.PA BNP.PA BNP.PA BNP.PA
Date
2025-12-11 78.669998 78.669998 78.919998 76.900002 76.919998 357918
2025-12-12 78.089996 78.089996 80.269997 78.089996 79.470001 280477
2025-12-15 79.080002 79.080002 79.449997 78.559998 78.559998 233852
2025-12-16 78.860001 78.860001 79.980003 78.809998 79.430000 283057
2025-12-17 80.080002 80.080002 80.150002 79.080002 79.199997 262818
Adding new columns to the dataframe is easy. For example, I used a custom function to calculate the Relative Strength Index (RSI). To add a new column RSI with a value for every row based on the price from that row, only one line of code is needed, without custom loops:
python
df["RSI"] = compute_rsi(df["price"], period=14)
After manipulating the data, the series can be converted into an array structure and printed as JSON into a placeholder in an HTML template:
python
 baseline_series = [
  "time": ts, "value": val 
 for ts, val in df_plot[["timestamp", BASELINE_LABEL]].itertuples(index=False)
 ]

 baseline_json = json.dumps(baseline_series)
 template = jinja2.Template("template.html")
 rendered_html = template.render(
 title=title,
 heading=heading,
 description=description_html,
 ...
 baseline_json=baseline_json,
 ...
 )

 with open("report.html", "w", encoding="utf-8") as f:
 f.write(rendered_html)
 print("Report generated!")
In the HTML template, the marker variable in Jinja syntax gets replaced with the actual JSON:
html
<!DOCTYPE html>
<html lang="en">
<head>
 <meta charset="UTF-8">
 <title>  title  </title>
 ...
</head>
<body>
 <h1>  heading  </h1>
 <div id="chart"></div>
 <script>
 // Ensure the DOM is ready before we initialise the chart
 document.addEventListener('DOMContentLoaded', () =>  
 // Parse the JSON data passed from Python
 const baselineData =   baseline_json   safe  ;
 const strategyData =   strategy_json   safe  ;
 const markersData =   markers_json   safe  ;

 // Create the chart
 const chart = LightweightCharts.createChart(document.getElementById('chart'),  
 width: document.getElementById('chart').clientWidth,
 height: 500,
 layout:  
 background:   color: "#222"  ,
 textColor: "#ccc"
  ,
 grid:  
 vertLines:   color: "#555"  ,
 horzLines:   color: "#555"  
  
  );

 // Add baseline series
 const baselineSeries = chart.addLineSeries( 
 title: '  baseline_label  ',
 lastValueVisible: false,
 priceLineVisible: false,
 priceLineWidth: 1
  );
 baselineSeries.setData(baselineData);

 baselineSeries.priceScale().applyOptions( 
 entireTextOnly: true
  );

 // Add strategy series
 const strategySeries = chart.addLineSeries( 
 title: '  strategy_label  ',
 lastValueVisible: false,
 priceLineVisible: false,
 color: '#FF6D00'
  );
 strategySeries.setData(strategyData);

 // Add buy/sell markers to the strategy series
 strategySeries.setMarkers(markersData);

 // Fit the chart to show the full data range (full zoom)
 chart.timeScale().fitContent();
  )
 </script>
</body>
</html>
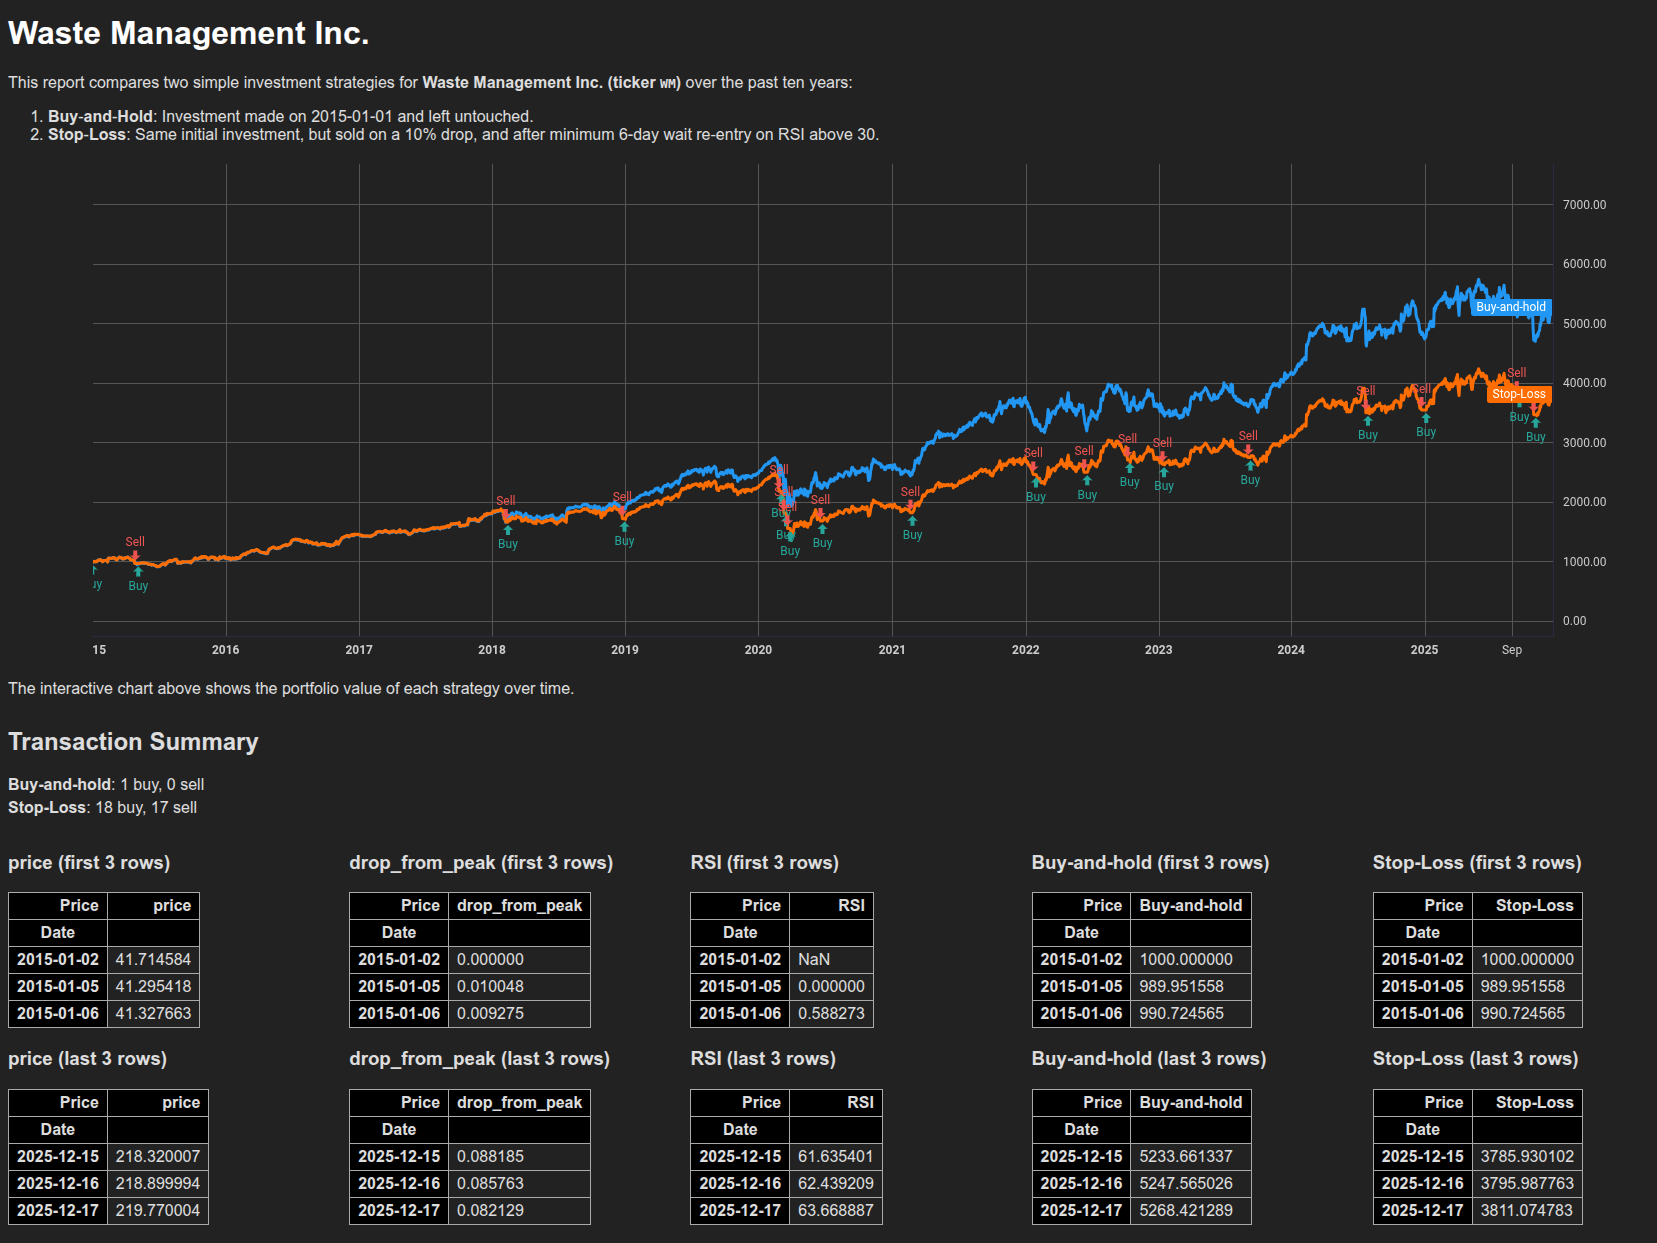
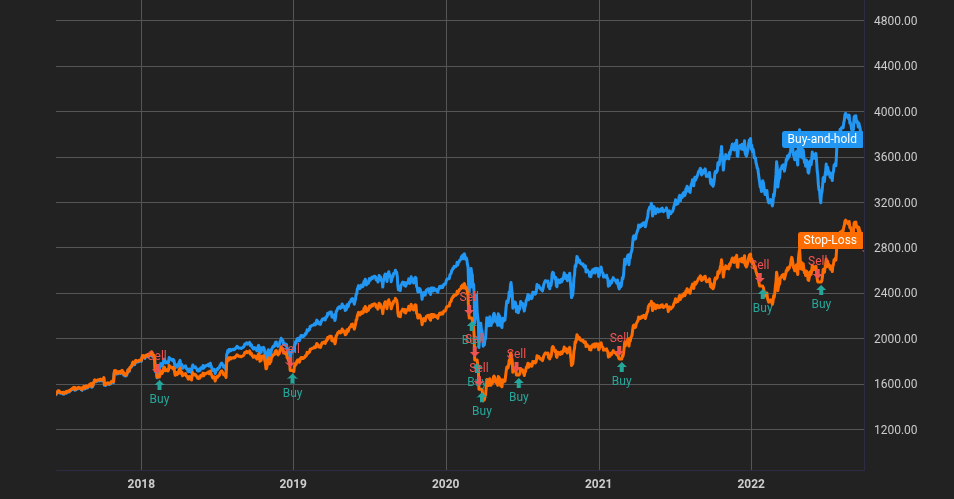
There are also Python libraries built specifically for backtesting investment strategies, such as Backtrader and Zipline, but they do not seem to be actively maintained, and probably have too many features and complexity compared to what I needed for doing this simple test. The screenshot below shows an example of backtesting a strategy on the Waste Management Inc stock from January 2015 to December 2025. The baseline Buy and hold scenario is shown as the blue line and it fully tracks the stock price, while the orange line shows how the strategy would have performed, with markers for the sells and buys along the way. Backtest run example

Results I experimented with multiple strategies and tested them with various parameters, but I don t think I found a strategy that was consistently and clearly better than just buy-and-hold. It basically boils down to the fact that I was not able to find any way to calculate when the crash has bottomed based on historical data. You can only know in hindsight that the price has stopped dropping and is on a steady path to recovery, but at that point it is already too late to buy in. In my testing, most strategies underperformed buy-and-hold because they sold when the crash started, but bought back after it recovered at a slightly higher price. In particular when using narrow margins and selling on a 3-6% drawdown the strategy performed very badly, as those small dips tend to recover in a few days. Essentially, the strategy was repeating the pattern of selling 100 stocks at a 6% discount, then being able to buy back only 94 shares the next day, then again selling 94 shares at a 6% discount, and only being able to buy back maybe 90 shares after recovery, and so forth, never catching up to the buy-and-hold. The strategy worked better in large market crashes as they tended to last longer, and there were higher chances of buying back the shares while the price was still low. For example, in the 2020 crash selling at a 20% drawdown was a good strategy, as the stock I tested dropped nearly 50% and remained low for several weeks; thus, the strategy bought back the stocks while the price was still low and had not yet started to climb significantly. But that was just a lucky incident, as the delta between the trailing stop-loss margin of 20% and total crash of 50% was large enough. If the crash had been only 25%, the strategy would have missed the rebound and ended up buying back the stocks at a slightly higher price. Also, note that the simulation assumes that the trade itself is too small to affect the price formation. We should keep in mind that in reality, if many people have stop-loss orders in place, a large price drop would trigger all of them, creating a flood of sell orders, which in turn would affect the price and drive it lower even faster and deeper. Luckily, it seems that stop-loss orders are generally not a good strategy, and we don t need to fear that too many people will be using them.

Conclusion Even though using a trailing stop-loss strategy does not seem to help in getting consistently higher returns based on my backtesting, I would still say it is useful in protecting from the downside of stock investing. It can act as a kind of insurance policy to considerably decrease the chances of losing big while increasing the chances of losing a little bit. If you are risk-averse, which I think I probably am, this tradeoff can make sense. I d rather miss out on an initial 50% loss and an overall 3% gain on recovery than have to sit through weeks or months with a 50% loss before the price recovers to prior levels. Most notably, the trailing stop-loss strategy works best if used only once. If it is repeated multiple times, the small losses in gains will compound into big losses overall. Thus, I think I might actually put this automation in place at least on the stocks in my portfolio that have had the highest gains. If they keep going up, I will ride along, but once the crash happens, I will be out of those particular stocks permanently. Do you have a favorite open source investment tool or are you aware of any strategy that actually works? Comment below!

18 December 2025

Dirk Eddelbuettel: dang 0.0.17: New Features, Plus Maintenance

dang image A new release of my mixed collection of things package dang package arrived at CRAN earlier today. The dang package regroups a few functions of mine that had no other home as for example lsos() from a StackOverflow question from 2009 (!!), the overbought/oversold price band plotter from an older blog post, the market monitor blogged about as well as the checkCRANStatus() function tweeted about by Tim Taylor. And more so take a look. This release retires two functions: the social media site nobody ever visits anymore shut down its API too, so no way to mute posts by a given handle. Similarly, the (never official) ability by Google to supply financial data is no more, so the function to access data this way is gone too. But we also have two new ones: one that helps with CRAN entries for ORCiD ids, and another little helper to re-order microbenchmark results by summary column (defaulting to the median). Other than the usual updates to continuous integrations, as well as a switch to Authors@R which will result in CRAN nagging me less about this, and another argument update. The detailed NEWS entry follows.

Changes in version 0.0.17 (2025-12-18)
  • Added new funtion reorderMicrobenchmarkResults with alias rmr
  • Use tolower on email argument to checkCRANStatus
  • Added new function cranORCIDs bootstrapped from two emails by Kurt Hornik
  • Switched to using Authors@R in DESCRIPTION and added ORCIDs where available
  • Switched to r-ci action with included bootstrap step; updated updated the checkout action (twice); added (commented-out) log accessor
  • Removed googleFinanceData as the (unofficial) API access point no longer works
  • Removed muteTweeters because the API was turned off

Via my CRANberries, there is a comparison to the previous release. For questions or comments use the the issue tracker at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Colin Watson: Preparing a transition in Debusine

We announced a public beta of Debusine repositories recently (Freexian blog, debian-devel-announce). One thing I m very keen on is being able to use these to prepare transitions : changes to multiple packages that need to be prepared together in order to land in testing. As I said in my DebConf25 talk:
We have distribution-wide CI in unstable, but there s only one of it and it s shared between all of us. As a result it s very possible to get into tangles when multiple people are working on related things at the same time, and we only avoid that as much as we do by careful coordination such as transition bugs. Experimental helps, but again, there s only one of it and setting up another one is far from trivial. So, what we want is a system where you can run experiments on possible Debian changes at a large scale without a high setup cost and without fear of breaking things for other people. And then, if it all works, push the whole lot into Debian.
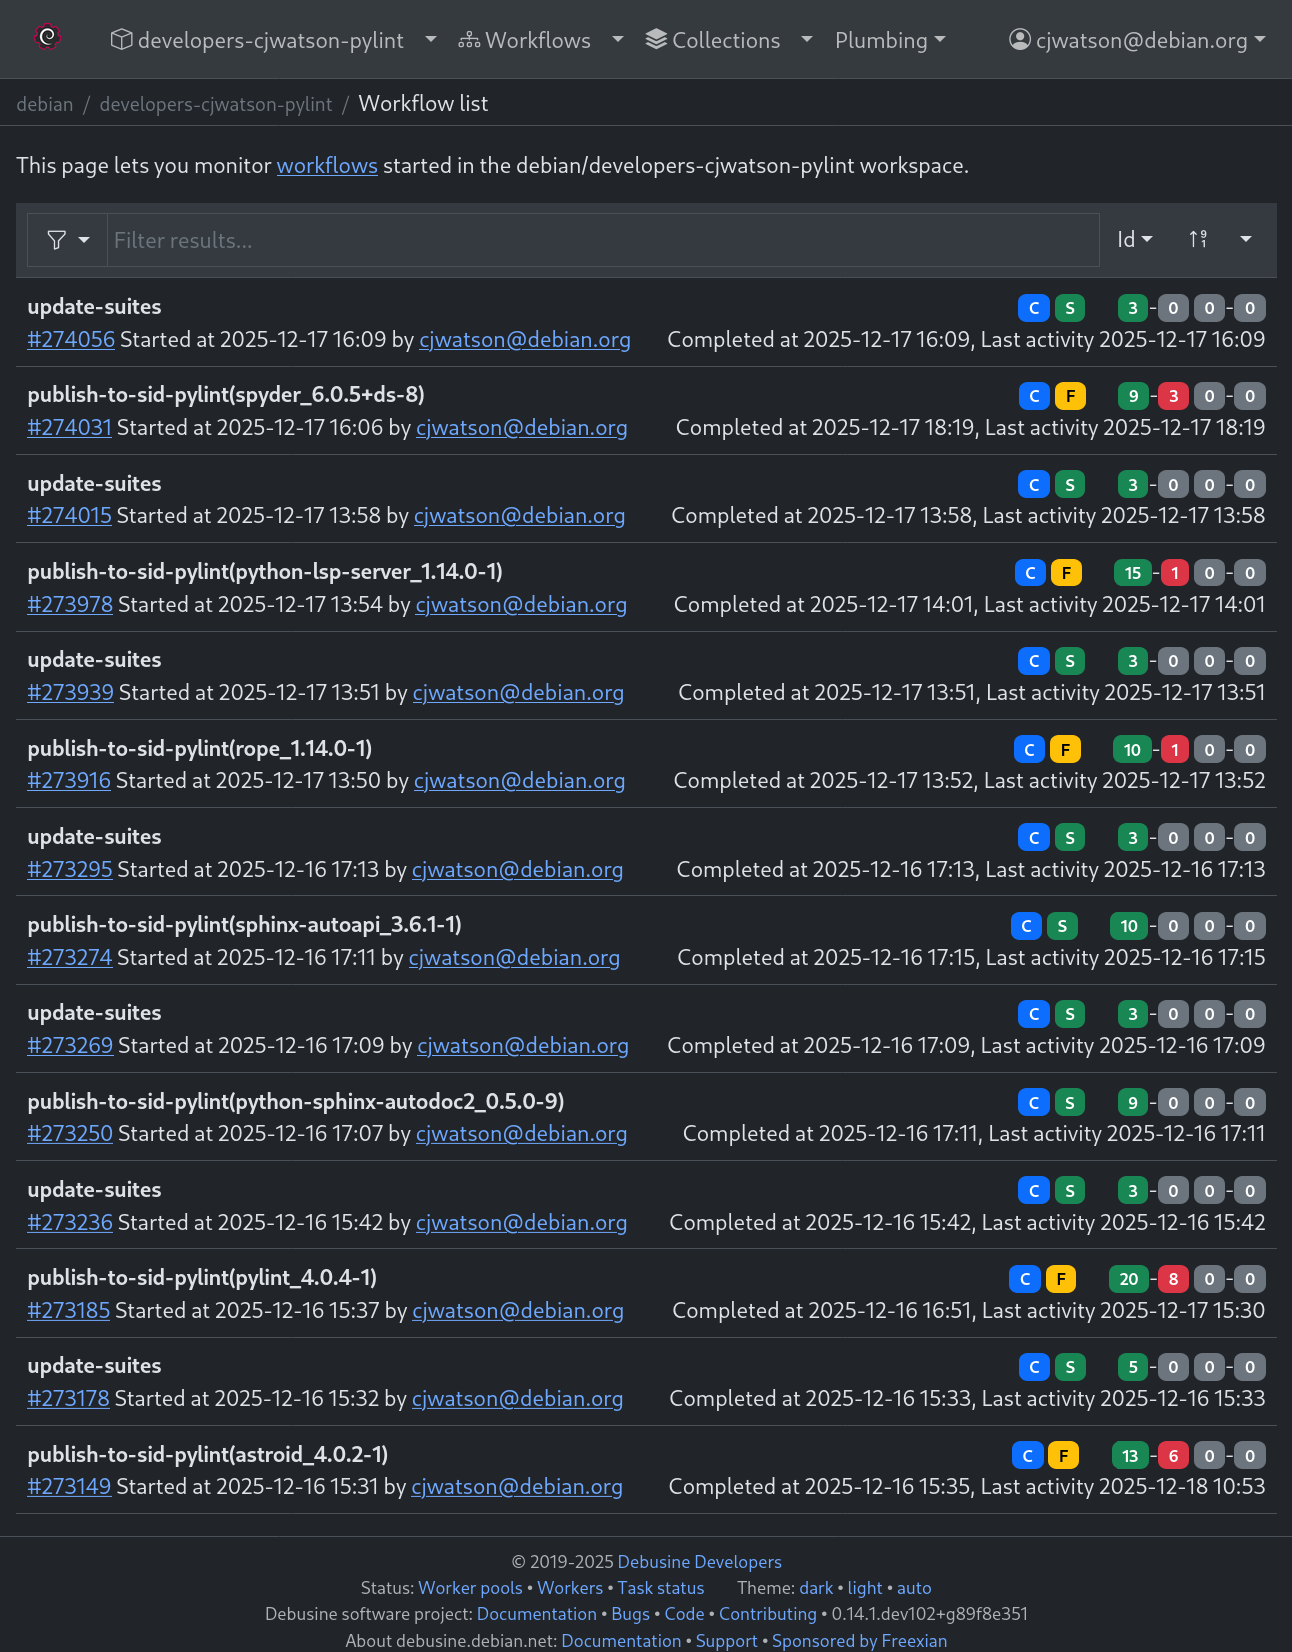
Time to practice what I preach. Setup The setup process is documented on the Debian wiki. You need to decide whether you re working on a short-lived experiment, in which case you ll run the create-experiment workflow and your workspace will expire after 60 days of inactivity, or something that you expect to keep around for longer, in which case you ll run the create-repository workflow. Either one of those will create a new workspace for you. Then, in that workspace, you run debusine archive suite create for whichever suites you want to use. For the case of a transition that you plan to land in unstable, you ll most likely use create-experiment and then create a single suite with the pattern sid-<name>. The situation I was dealing with here was moving to Pylint 4. Tests showed that we needed this as part of adding Python 3.14 as a supported Python version, and I knew that I was going to need newer upstream versions of the astroid and pylint packages. However, I wasn t quite sure what the fallout of a new major version of pylint was going to be. Fortunately, the Debian Python ecosystem has pretty good autopkgtest coverage, so I thought I d see what Debusine said about it. I created an experiment called cjwatson-pylint (resulting in https://debusine.debian.net/debian/developers-cjwatson-pylint/ - I m not making that a proper link since it will expire in a couple of months) and a sid-pylint suite in it. Iteration From this starting point, the basic cycle involved uploading each package like this for each package I d prepared:
$ dput -O debusine_workspace=developers-cjwatson-pylint \
       -O debusine_workflow=publish-to-sid-pylint \
       debusine.debian.net foo.changes
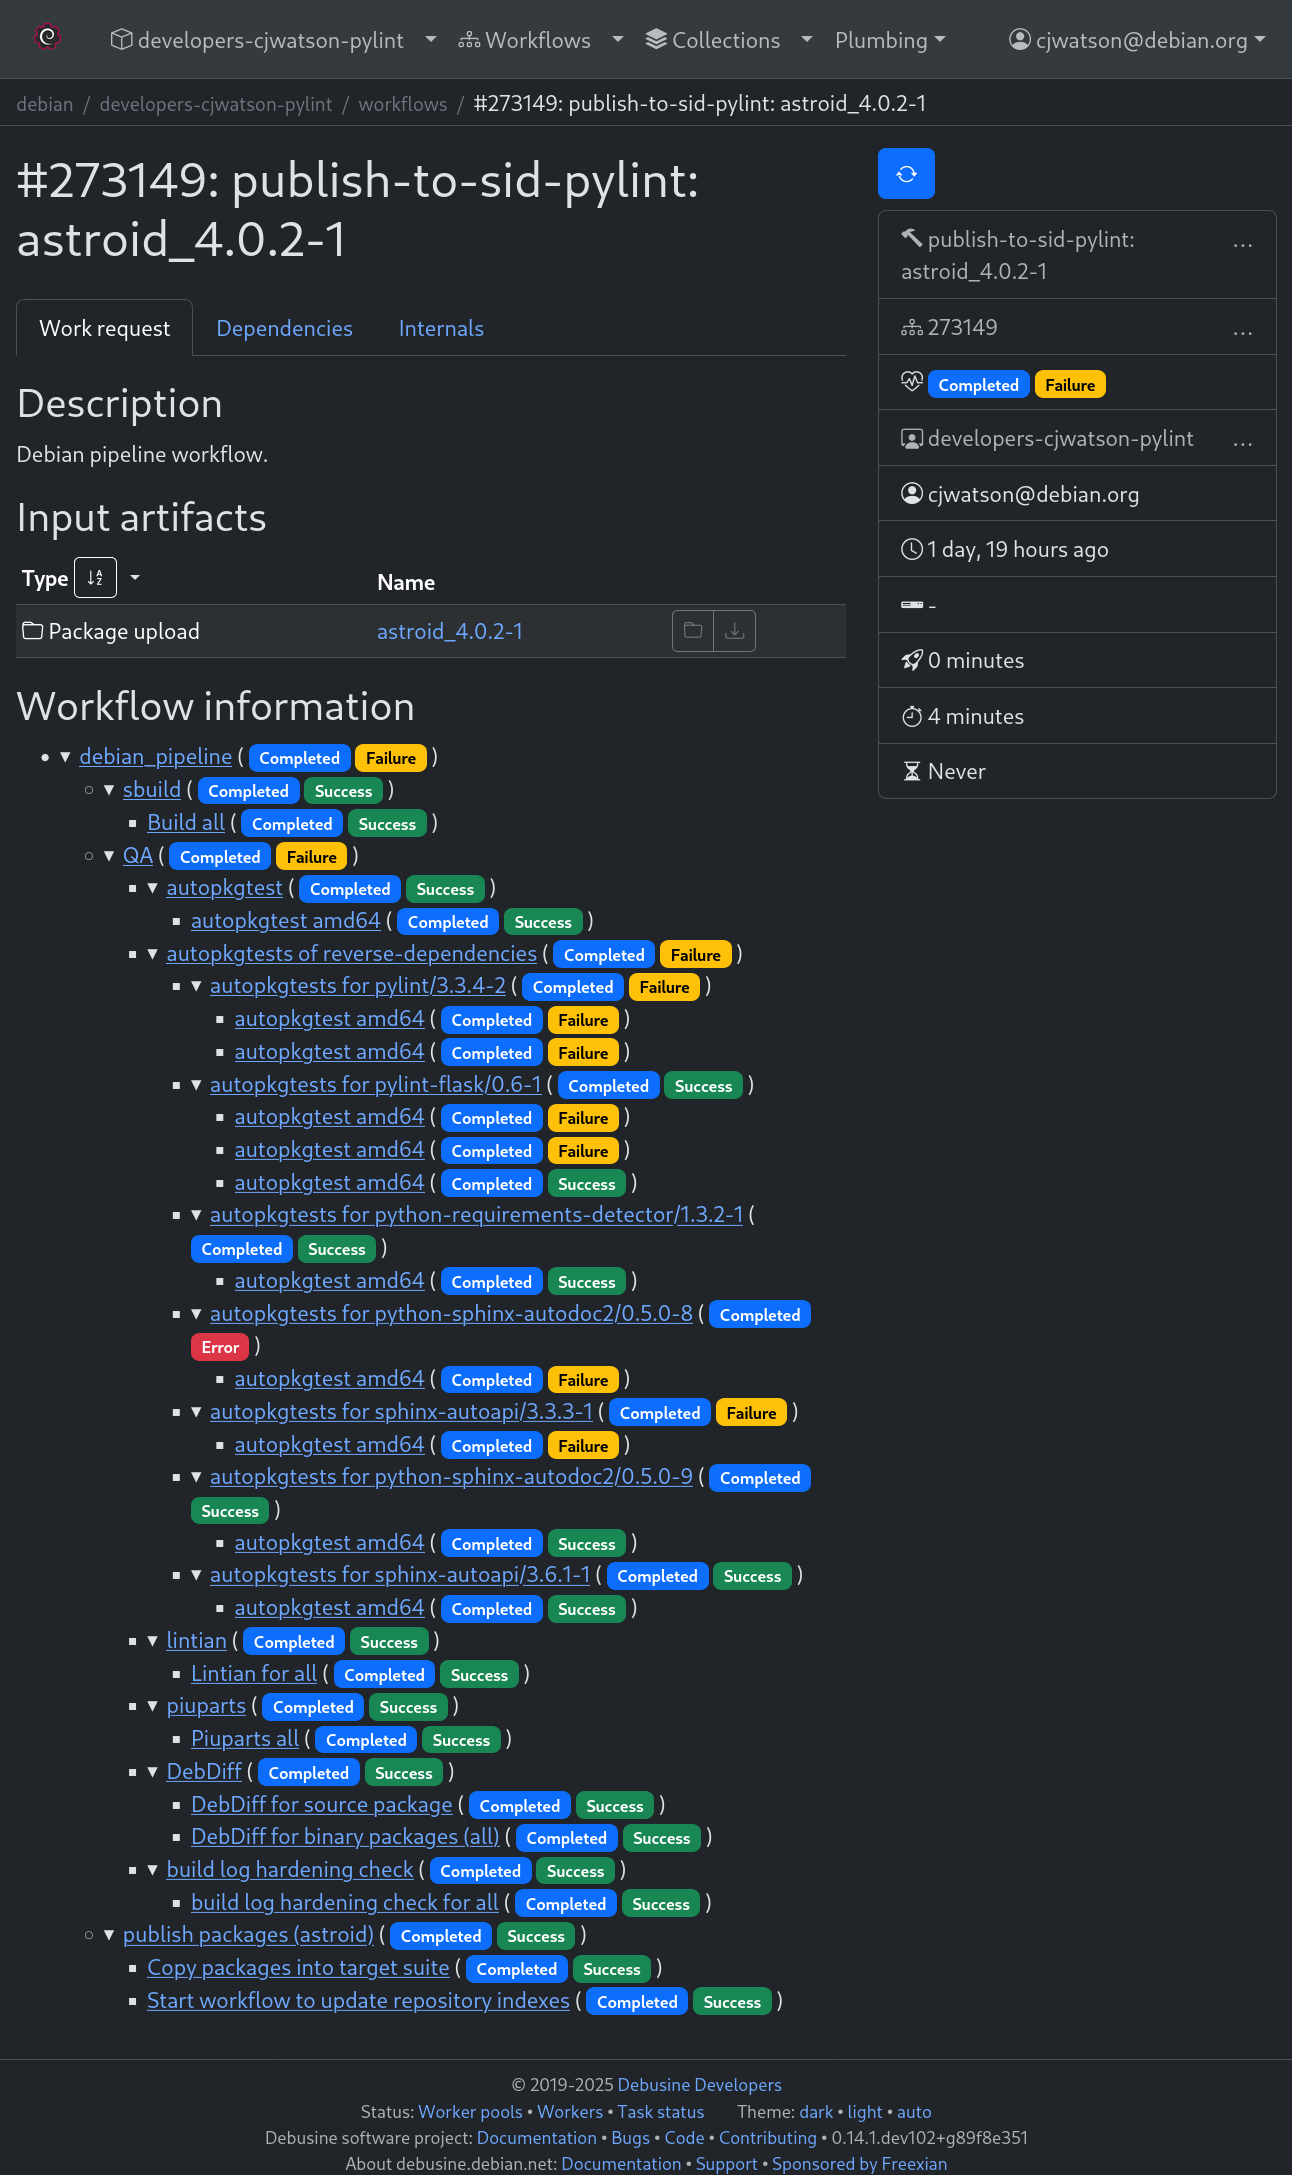
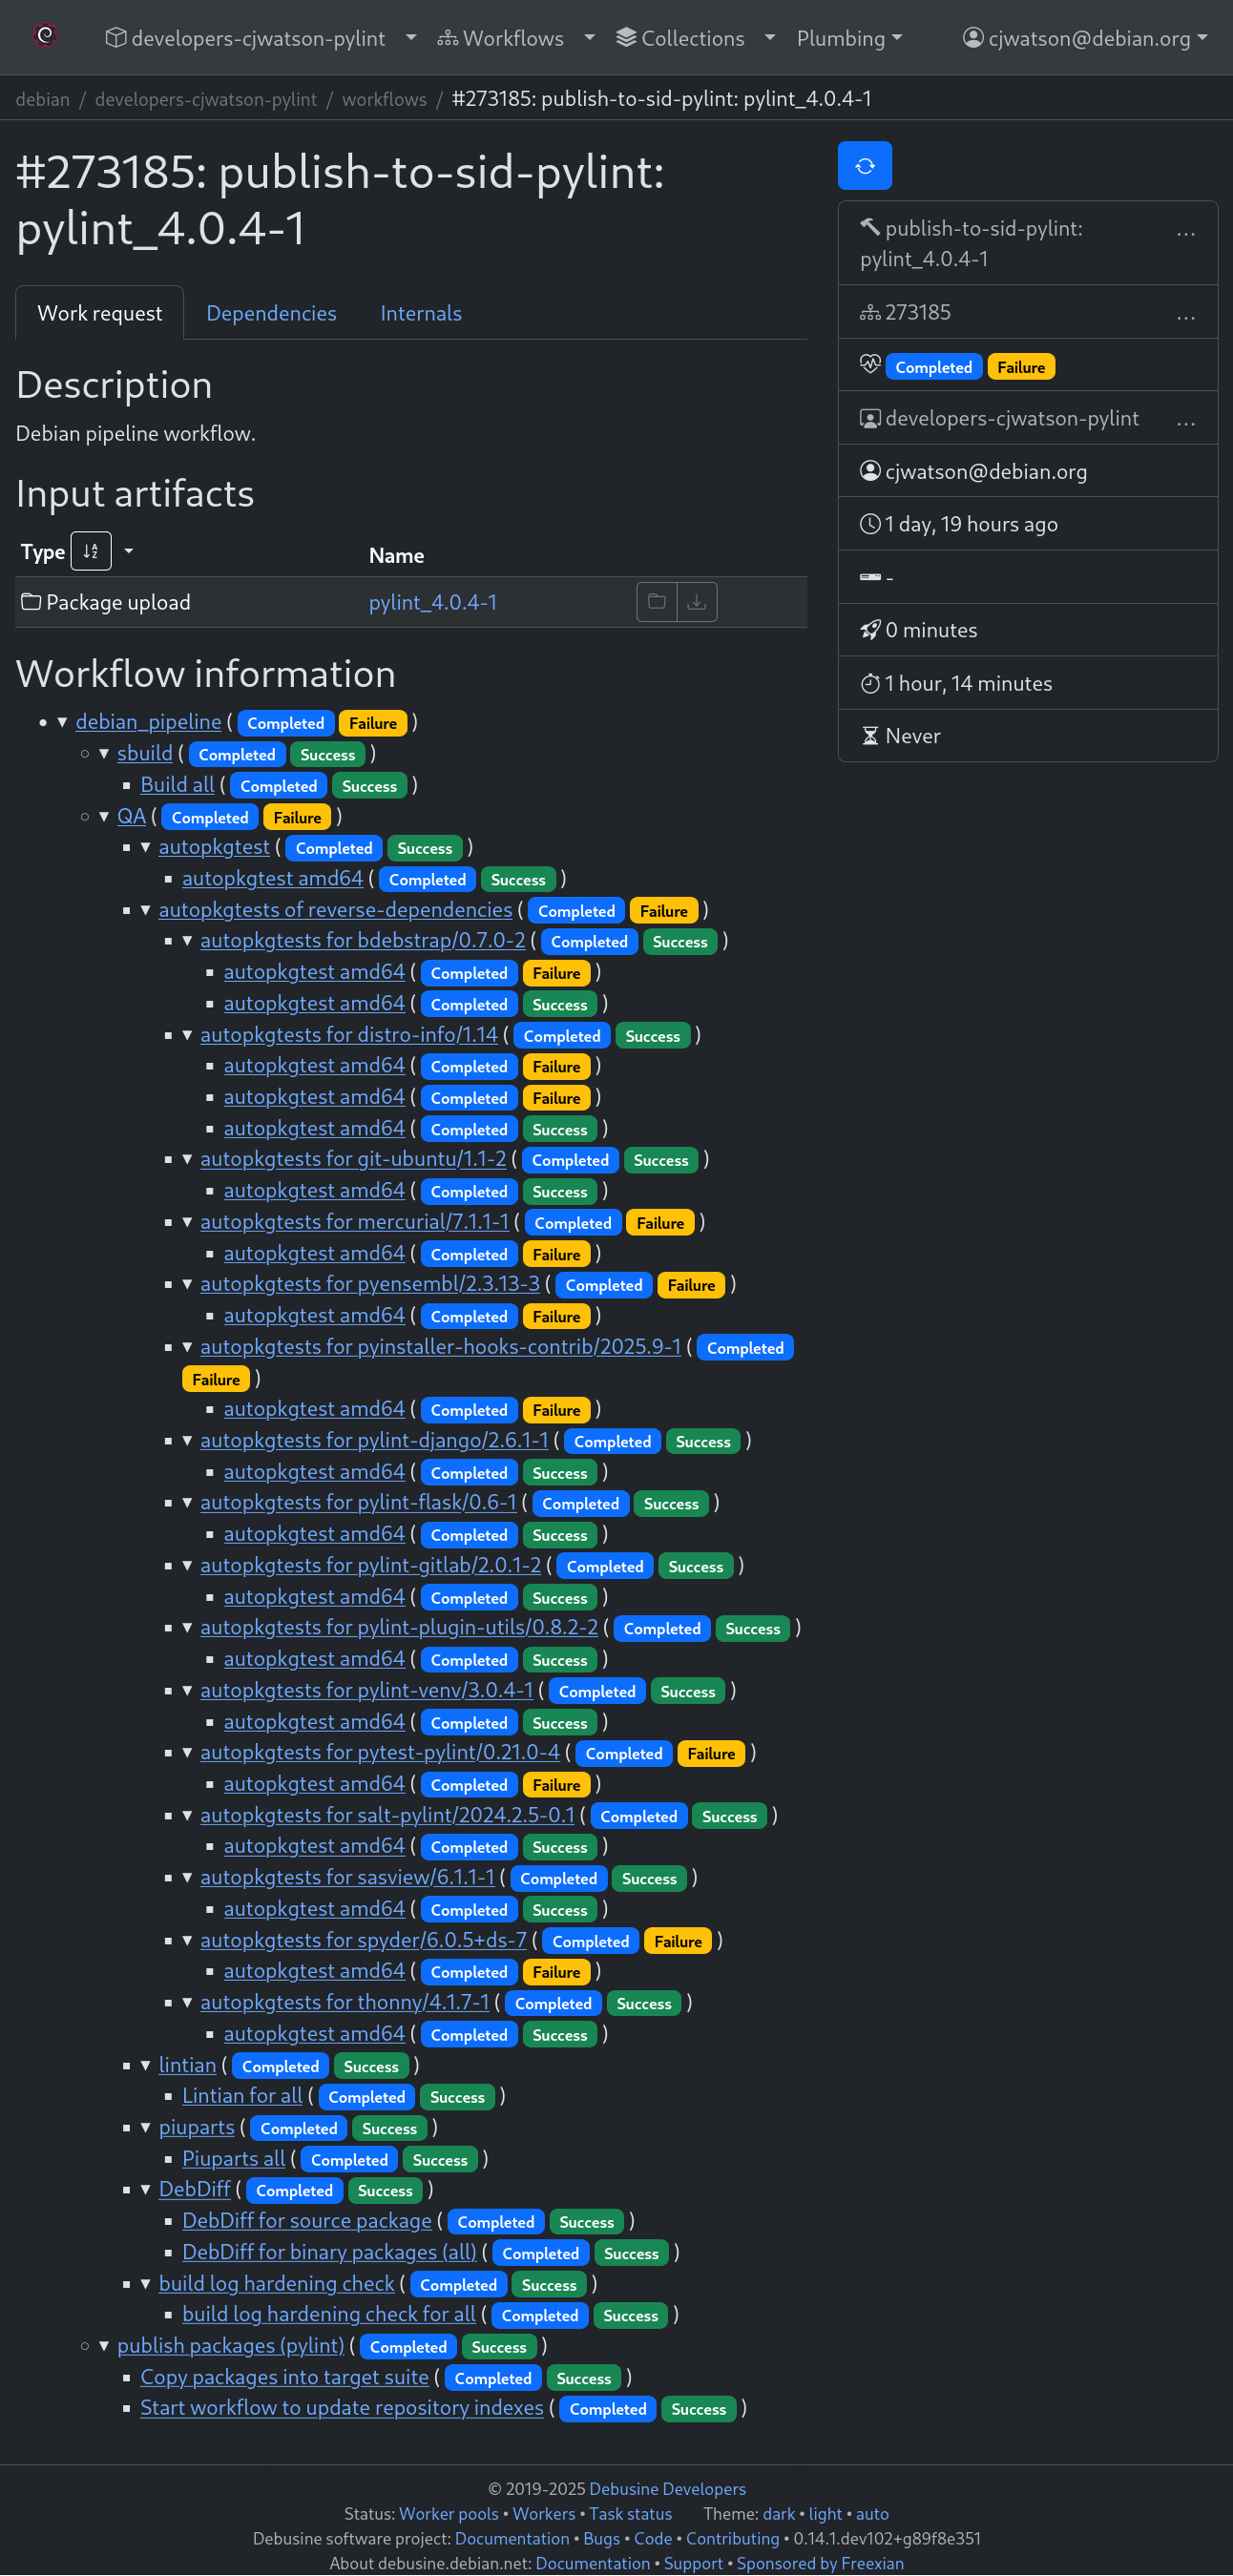
I could have made a new dput-ng profile to cut down on typing, but it wasn t worth it here. Then I looked at the workflow results, figured out which other packages I needed to fix based on those, and repeated until the whole set looked coherent. Debusine automatically built each upload against whatever else was currently in the repository, as you d expect. I should probably have used version numbers with tilde suffixes (e.g. 4.0.2-1~test1) in case I needed to correct anything, but fortunately that was mostly unnecessary. I did at least run initial test-builds locally of just the individual packages I was directly changing to make sure that they weren t too egregiously broken, just because I usually find it quicker to iterate that way. I didn t take screenshots as I was going along, but here s what the list of top-level workflows in my workspace looked like by the end: Workflows You can see that not all of the workflows are successful. This is because we currently just show everything in every workflow; we don t consider whether a task was retried and succeeded on the second try, or whether there s now a newer version of a reverse-dependency so tests of the older version should be disregarded, and so on. More fundamentally, you have to look through each individual workflow, which is a bit of a pain: we plan to add a dashboard that shows you the current state of a suite as a whole rather than the current workflow-oriented view, but we haven t started on that yet. Drilling down into one of these workflows, it looks something like this: astroid workflow This was the first package I uploaded. The first pass of failures told me about pylint (expected), pylint-flask (an obvious consequence), and python-sphinx-autodoc2 and sphinx-autoapi (surprises). The slightly odd pattern of failures and errors is because I retried a few things, and we sometimes report retries in a slightly strange way, especially when there are workflows involved that might not be able to resolve their input parameters any more. The next level was: pylint workflow Again, there were some retries involved here, and also some cases where packages were already failing in unstable so the failures weren t the fault of my change; for now I had to go through and analyze these by hand, but we ll soon have regression tracking to compare with reference runs and show you where things have got better or worse. After excluding those, that left pytest-pylint (not caused by my changes, but I fixed it anyway in unstable to clear out some noise) and spyder. I d seen people talking about spyder on #debian-python recently, so after a bit of conversation there I sponsored a rope upload by Aeliton Silva, upgraded python-lsp-server, and patched spyder. All those went into my repository too, exposing a couple more tests I d forgotten in spyder. Once I was satisfied with the results, I uploaded everything to unstable. The next day, I looked through the tracker as usual starting from astroid, and while there are some test failures showing up right now it looks as though they should all clear out as pieces migrate to testing. Success! Conclusions We still have some way to go before this is a completely smooth experience that I d be prepared to say that every developer can and should be using; there are all sorts of fit-and-finish issues that I can easily see here. Still, I do think we re at the point where a tolerant developer can use this to deal with the common case of a mid-sized transition, and get more out of it than they put in. Without Debusine, either I d have had to put much more effort into searching for and testing reverse-dependencies myself, or (more likely, let s face it) I d have just dumped things into unstable and sorted them out afterwards, resulting in potentially delaying other people s work. This way, everything was done with as little disruption as possible. This works best when the packages likely to be involved have reasonably good autopkgtest coverage (even if the tests themselves are relatively basic). This is an increasingly good bet in Debian, but we have plans to add installability comparisons (similar to how Debian s testing suite works) as well as optional rebuild testing. If this has got you interested, please try it out for yourself and let us know how it goes!

17 December 2025

Jonathan McDowell: 21 years of blogging

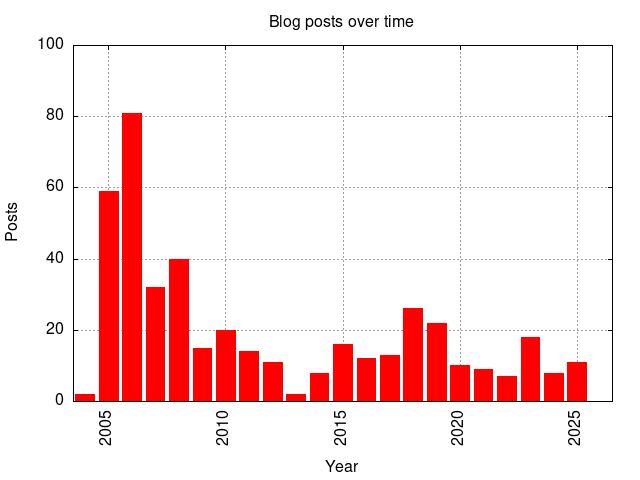
21 years ago today I wrote my first blog post. Did I think I d still be writing all this time later? I ve no idea to be honest. I ve always had the impression my readership is small, and people who mostly know me in some manner, and I post to let them know what I m up to in more detail than snippets of IRC conversation can capture. Or I write to make notes for myself (I frequently refer back to things I ve documented here). I write less about my personal life than I used to, but I still occasionally feel the need to mark some event. From a software PoV I started out with Blosxom, migrated to MovableType in 2008, ditched that, when the Open Source variant disappeared, for Jekyll in 2015 (when I also started putting it all in git). And have stuck there since. The static generator format works well for me, and I outsource comments to Disqus - I don t get a lot, I can t be bothered with the effort of trying to protect against spammers, and folk who don t want to use it can easily email or poke me on the Fediverse. If I ever feel the need to move from Jekyll I ll probably take a look at Hugo, but thankfully at present there s no push factor to switch. It s interesting to look at my writing patterns over time. I obviously started keen, and peaked with 81 posts in 2006 (I ve no idea how on earth that happened), while 2013 had only 2. Generally I write less when I m busy, or stressed, or unhappy, so it s kinda interesting to see how that lines up with various life events. Blog posts over time During that period I ve lived in 10 different places (well, 10 different houses/flats, I think it s only 6 different towns/cities), on 2 different continents, working at 6 different employers, as well as a period where I was doing my Masters in law. I ve travelled around the world, made new friends, lost contact with folk, started a family. In short, I have lived, even if lots of it hasn t made it to these pages. At this point, do I see myself stopping? No, not really. I plan to still be around, like Flameeyes, to the end. Even if my posts are unlikely to hit the frequency from back when I started out.

Sven Hoexter: exfatprogs: Do not try defrag.exfat / mkfs.exfat Windows compatibility in Trixie

exfatprogs 1.3.0 added a new defrag.exfat utility which turned out to be not reliable and cause data loss. exfatprogs 1.3.1 disabled the utility, and I followed that decision with the upload to Debian/unstable yesterday. But as usual it will take some time until it's migrating to testing. Thus if you use testing do not try defag.exfat! At least not without a vetted and current backup. Beside of that there is a compatibility issue with the way mkfs.exfat, as shipped in trixie (exfatprogs 1.2.9), handles drives which have a physical sector size of 4096 bytes but emulate a logical size of 512 bytes. With exfatprogs 1.2.6 a change was implemented to prefer the physical sector size on those devices. That turned out to be not compatible with Windows, and was reverted in exfatprogs 1.3.0. Sadly John Ogness ran into the issue and spent some time to debug it. I've to admit that I missed the relevance of that change. Huge kudos to John for the bug report. Based on that I prepared an update for the next trixie point release. If you hit that issue on trixie with exfatprogs 1.2.9-1 you can work around it by formating with mkfs.exfat -s 512 /dev/sdX to get Windows compatibility. If you use exfatprogs 1.2.9-1+deb13u1 or later, and want the performance gain back, and do not need Windows compatibility, you can format with mkfs.exfat -s 4096 /dev/sdX.

Dirk Eddelbuettel: RcppArmadillo 15.2.3-1 on CRAN: Upstream Update

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1272 other packages on CRAN, downloaded 43.2 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 661 times according to Google Scholar. This versions updates to the 15.2.3 upstream Armadillo release from yesterday. It brings minor changes over the RcppArmadillo 15.2.2 release made last month (and described in this post). As noted previously, and due to both the upstream transition to C++14 coupled with the CRAN move away from C++11, the package offers a transition by allowing packages to remain with the older, pre-15.0.0 legacy Armadillo yet offering the current version as the default. If and when CRAN will have nudged (nearly) all maintainers away from C++11 (and now also C++14 !!) we can remove the fallback. Our offer to help with the C++ modernization still stands, so please get in touch if we can be of assistance. As a reminder, the meta-issue #475 regroups all the resources for the C++11 transition. There were no R-side changes in this release. The detailed changes since the last release follow.

Changes in RcppArmadillo version 15.2.3-1 (2025-12-16)
  • Upgraded to Armadillo release 15.2.3 (Medium Roast Deluxe)
    • Faster .resize() for vectors
    • Faster repcube()

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Matthew Garrett: How did IRC ping timeouts end up in a lawsuit?

I recently won a lawsuit against Roy and Rianne Schestowitz, the authors and publishers of the Techrights and Tuxmachines websites. The short version of events is that they were subject to an online harassment campaign, which they incorrectly blamed me for. They responded with a large number of defamatory online posts about me, which the judge described as unsubstantiated character assassination and consequently awarded me significant damages. That's not what this post is about, as such. It's about the sole meaningful claim made that tied me to the abuse.

In the defendants' defence and counterclaim[1], 15.27 asserts in part The facts linking the Claimant to the sock puppet accounts include, on the IRC network: simultaneous dropped connections to the mjg59_ and elusive_woman accounts. This is so unlikely to be coincidental that the natural inference is that the same person posted under both names. "elusive_woman" here is an account linked to the harassment, and "mjg59_" is me. This is actually a surprisingly interesting claim to make, and it's worth going into in some more detail.

The event in question occurred on the 28th of April, 2023. You can see a line reading *elusive_woman has quit (Ping timeout: 2m30s), followed by one reading *mjg59_ has quit (Ping timeout: 2m30s). The timestamp listed for the first is 09:52, and for the second 09:53. Is that actually simultaneous? We can actually gain some more information - if you hover over the timestamp links on the right hand side you can see that the link is actually accurate to the second even if that's not displayed. The first event took place at 09:52:52, and the second at 09:53:03. That's 11 seconds apart, which is clearly not simultaneous, but maybe it's close enough. Figuring out more requires knowing what a "ping timeout" actually means here.

The IRC server in question is running Ergo (link to source code), and the relevant function is handleIdleTimeout(). The logic here is fairly simple - track the time since activity was last seen from the client. If that time is longer than DefaultIdleTimeout (which defaults to 90 seconds) and a ping hasn't been sent yet, send a ping to the client. If a ping has been sent and the timeout is greater than DefaultTotalTimeout (which defaults to 150 seconds), disconnect the client with a "Ping timeout" message. There's no special logic for handling the ping reply - a pong simply counts as any other client activity and resets the "last activity" value and timeout.

What does this mean? Well, for a start, two clients running on the same system will only have simultaneous ping timeouts if their last activity was simultaneous. Let's imagine a machine with two clients, A and B. A sends a message at 02:22:59. B sends a message 2 seconds later, at 02:23:01. The idle timeout for A will fire at 02:24:29, and for B at 02:24:31. A ping is sent for A at 02:24:29 and is responded to immediately - the idle timeout for A is now reset to 02:25:59, 90 seconds later. The machine hosting A and B has its network cable pulled out at 02:24:30. The ping to B is sent at 02:24:31, but receives no reply. A minute later, at 02:25:31, B quits with a "Ping timeout" message. A ping is sent to A at 02:25:59, but receives no reply. A minute later, at 02:26:59, A quits with a "Ping timeout" message. Despite both clients having their network interrupted simultaneously, the ping timeouts occur 88 seconds apart.

So, two clients disconnecting with ping timeouts 11 seconds apart is not incompatible with the network connection being interrupted simultaneously - depending on activity, simultaneous network interruption may result in disconnections up to 90 seconds apart. But another way of looking at this is that network interruptions may occur up to 90 seconds apart and generate simultaneous disconnections[2]. Without additional information it's impossible to determine which is the case.

This already casts doubt over the assertion that the disconnection was simultaneous, but if this is unusual enough it's still potentially significant. Unfortunately for the Schestowitzes, even looking just at the elusive_woman account, there were several cases where elusive_woman and another user had a ping timeout within 90 seconds of each other - including one case where elusive_woman and schestowitz[TR] disconnect 40 seconds apart. By the Schestowitzes argument, it's also a natural inference that elusive_woman and schestowitz[TR] (one of Roy Schestowitz's accounts) are the same person.

We didn't actually need to make this argument, though. In England it's necessary to file a witness statement describing the evidence that you're going to present in advance of the actual court hearing. Despite being warned of the consequences on multiple occasions the Schestowitzes never provided any witness statements, and as a result weren't allowed to provide any evidence in court, which made for a fairly foregone conclusion.

[1] As well as defending themselves against my claim, the Schestowitzes made a counterclaim on the basis that I had engaged in a campaign of harassment against them. This counterclaim failed.

[2] Client A and client B both send messages at 02:22:59. A falls off the network at 02:23:00, has a ping sent at 02:24:29, and has a ping timeout at 02:25:29. B falls off the network at 02:24:28, has a ping sent at 02:24:29, and has a ping timeout at 02:25:29. Simultaneous disconnects despite over a minute of difference in the network interruption.

comment count unavailable comments

16 December 2025

Christian Kastner: Simple-PPA, a minimalistic PPA implementation

Today, the Debusine developers launched Debusine repositories, a beta implementation of PPAs. In the announcement, Colin remarks that "[d]iscussions about this have been happening for long enough that people started referring to PPAs for Debian as 'bikesheds'"; a characterization that I'm sure most will agree with. So it is with great amusement that on this same day, I launch a second PPA implementation for Debian: Simple-PPA. Simple-PPA was never meant to compete with Debusine, though. In fact, it's entirely the opposite: from discussions at DebConf, I knew that it was only a matter of time until Debusine gained a PPA-like feature, but I needed a stop-gap solution earlier, and with some polish, what was once by Python script already doing APT processing for apt.ai.debian.net, recently became Simple-PPA. Consequently, Simple-PPA lacks (and will always lack) all of the features that Debusine offers: there is no auto-building, no CI, nor any other type of QA. It's the simplest possible type of APT repository: you just upload packages, they get imported into an archive, and the archive is exposed via a web server. Under the hood, reprepro does all the heavy lifting. However, this also means it's trivial to set up. The following is the entire configuration that simple-ppa.debian.net started with:
# simple-ppa.conf
[CORE]
SignWith = 2906D748B7551BC8
ExportDir = /srv/www/simple-ppa
MailFrom: Simple-PPA <admin@simple-ppa.debian.net>
Codenames = sid forky trixie trixie-backports bookworm bookworm-backports
AlsoAllow = forky: unstable
            trixie: unstable
            bookworm: unstable
[simple-ppa-dev]
Label = Simple-PPA's self-hosted development repository
# ckk's key
Uploaders = allow * by key E76004C5CEF0C94C+
[ckk]
Label = Christian Kastner at Simple-PPA
Uploaders = allow * by key E76004C5CEF0C94C+
The CORE section just sets some defaults and sensible rules. Two PPAs are defined, simple-ppa-dev and ckk, which accept packages signed by the key with the ID E76004C5CEF0C94C. These PPAs use the global defaults, but individual PPAs can override Architectures, Suites, and Components, and of course allow an arbitrary number of users. Users upload to this archive using SFTP (e.g.: with dput-ng). Every 15 minutes, uploads get processed, with ACCEPTED or REJECTED mails sent to the Maintainer address. The APT archive of all PPAs is signed with a single global key. I myself intend to use Debusine repositories soon, as the autobuilding and the QA tasks Debusine offers are something I need. However, I do still see a niche use case for Simple-PPA: when you need an APT archive, but don't want to do a deep dive into reprepro (which is extremely powerful). If you'd like to give Simple-PPA a try, head over to simple-ppa.debian.net and follow the instructions for users.

Freexian Collaborators: Monthly report about Debian Long Term Support, November 2025 (by Santiago Ruano Rinc n)

The Debian LTS Team, funded by [Freexian s Debian LTS offering] (https://www.freexian.com/lts/debian/), is pleased to report its activities for November.

Activity summary During the month of November, 18 contributors have been paid to work on Debian LTS (links to individual contributor reports are located below). The team released 33 DLAs fixing 219 CVEs. The LTS Team kept going with the usual cadence of preparing security updates for Debian 11 bullseye , but also for Debian 12 bookworm , Debian 13 trixie and even Debian unstable. As in previous months, we are pleased to say that there have been multiple contributions of LTS uploads by Debian Fellows outside the regular LTS Team. Notable security updates:
  • Guilhem Moulin prepared DLA 4365-1 for unbound, a caching DNS resolver, fixing a cache poisoning vulnerability that could lead to domain hijacking.
  • Another update related to DNS software was made by Andreas Henriksson. Andreas completed the work on bind9, released as DLA 4364-1 to fix cache poisoning and Denial of Service (DoS) vulnerabilities.
  • Chris Lamb released DLA 4374-1 to fix a potential arbitrary code execution vulnerability in pdfminer, a tool for extracting information from PDF documents.
  • Ben Hutchings published a regular security update for the linux 6.1 bullseye backport, as DLA 4379-1.
  • A couple of other important recurrent updates were prepared by Emilio Pozuelo, who handled firefox-esr and thunderbird (in collaboration with Christoph Goehre), published as DLAs DLA 4370-1 and DLA 4372-1, respectively.
Contributions from fellows outside the LTS Team:
  • Thomas Goirand uploaded a bullseye update for keystone and swift
  • Jeremy B cha prepared the bullseye update for gst-plugins-base1.0
  • As mentioned above, Christoph Goehre prepared the bullseye update for thunderbird.
  • Mathias Behrle provided feedback about the tryton-server and tryton-sao vulnerabilities that were disclosed last month, and helped to review the bullseye patches for tryton-server.
Other than the regular LTS updates for bullseye, the LTS Team has also contributed updates to the latest Debian releases:
  • Bastien Roucari s prepared a bookworm update for squid, the web proxy cache server.
  • Carlos Henrique Lima Melara filed a bookworm point update request for gdk-pixbuf to fix CVE-2025-7345, a heap buffer overflow vulnerability that could lead to arbitrary code execution.
  • Daniel Leidert prepared bookworm and trixie updates for r-cran-gh to fix CVE-2025-54956, an issue that may expose user credentials in HTTP responses.
  • Along with the bullseye updates for unbound mentioned above, Guilhem helped to prepare the trixie update for unbound.
  • In collaboration with Lukas M rdian, Tobias Frost prepared trixie and bookworm updates for log4cxx, the C++ port of the logging framework for JAVA.
  • Jochen Sprickerhof prepared a bookworm update for syslog-ng.
  • Utkarsh completed the bookworm update for wordpress, addressing multiple security issues in the popular blogging tool.
Beyond security updates, there has been a significant effort in revamping our documentation, aiming to make the processes more clear and consistent for all the members of the team. This work was mainly carried out by Sylvain, Jochen and Roberto. We would like to express our gratitude to the sponsors for making the Debian LTS project possible. Also, special thanks to the fellows outside the LTS team for their valuable help.

Individual Debian LTS contributor reports

Thanks to our sponsors Sponsors that joined recently are in bold.

Freexian Collaborators: Debusine repositories now in beta (by Colin Watson)

We re happy to announce that Debusine can now be used to maintain APT-compatible add-on package repositories for Debian. This facility is available in public beta to Debian developers and maintainers.

Why? Debian developers typically put most of their effort towards maintaining the main Debian archive. However, it s often useful to have other places to work, for various reasons:
  • Developers working on a set of packages might need to check that changes to several of them all work properly together on a real system.
  • Somebody fixing a bug might need to ask affected users to test the fix before uploading it to Debian.
  • Some projects are difficult to package in a way that meets Debian policy, or are too niche to include in Debian, but it s still useful to distribute them in a packaged form.
  • For some packages, it s useful to provide multiple upstream versions for multiple Debian releases, even though Debian itself would normally want to keep that to a minimum.
The Ubuntu ecosystem has had PPAs for a long time to meet these sorts of needs, but people working directly on Debian have had to make do with putting things together themselves using something like reprepro or aptly. Discussions about this have been happening for long enough that people started referring to PPAs for Debian as bikesheds , and users often find themselves trying to use Ubuntu PPAs on Debian systems and hoping that dependencies will be compatible enough for things to more or less work. This clearly isn t ideal, and solving it is one of Freexian s objectives for Debusine. Developers publishing packages to Debusine repositories can take advantage of all Debusine s existing facilities, including a battery of QA tests and regression tracking (coming soon). Repositories are signed using per-repository keys held in Debusine s signing service, and uploads to repositories are built against the current contents of that repository as well as the corresponding base Debian release. All repositories include automatic built-in snapshot capabilities.

Who can use this service? We ve set up debusine.debian.net to allow using repositories. All Debian Developers and Debian Maintainers can log in there and publish packages to it. The resulting repositories are public by default. debusine.debian.net only allows packages with licences that allow distribution by Debian, and it is intended primarily for work that could reasonably end up in Debian; Freexian reserves the right to remove repositories from it.

How can I use it? If you are a Debian contributor, we d be very excited to have you try this out, especially if you give us feedback. We have published instructions for developers on using this. Since this is a beta service, you can expect things to change, but we ll maintain compatibility where we can. If you re interested in using this in a commercial setting, please contact Freexian to discuss what we can do for you.

15 December 2025

Gunnar Wolf: Unique security and privacy threats of large language models a comprehensive survey

This post is an unpublished review for Unique security and privacy threats of large language models a comprehensive survey
Much has been written about large language models (LLMs) being a risk to user security and privacy, including the issue that, being trained with datasets whose provenance and licensing are not always clear, they can be tricked into producing bits of data that should not be divulgated. I took on reading this article as means to gain a better understanding of this area. The article completely fulfilled my expectations. This is a review article, which is not a common format for me to follow: instead of digging deep into a given topic, including an experiment or some way of proofing the authors claims, a review article will contain a brief explanation and taxonomy of the issues at hand, and a large number of references covering the field. And, at 36 pages and 151 references, that s exactly what we get. The article is roughly split in two parts: The first three sections present the issue of security and privacy threats as seen by the authors, as well as the taxonomy within which the review will be performed, and sections 4 through 7 cover the different moments in the life cycle of a LLM model (at pre-training, during fine-tuning, when deploying systems that will interact with end-users, and when deploying LLM-based agents), detailing their relevant publications. For each of said moments, the authors first explore the nature of the relevant risks, then present relevant attacks, and finally close outlining countermeasures to said attacks. The text is accompanied all throughout its development with tables, pipeline diagrams and attack examples that visually guide the reader. While the examples presented are sometimes a bit simplistic, they are a welcome guide and aid to follow the explanations; the explanations for each of the attack models are necessarily not very deep, and I was often left wondering I correctly understood a given topic, or wanting to dig deeper but being this a review article, it is absolutely understandable. The authors present an easy to read prose, and this article covers an important spot in understanding this large, important, and emerging area of LLM-related study.

Russ Allbery: Review: Brigands & Breadknives

Review: Brigands & Breadknives, by Travis Baldree
Series: Legends & Lattes #3
Publisher: Tor
Copyright: 2025
ISBN: 1-250-33489-6
Format: Kindle
Pages: 325
Brigands & Breadknives is a secondary-world sword-and-sorcery fantasy and a sequel to both Legends & Lattes and Bookshops & Bonedust. It takes place shortly after Legends & Lattes chronologically, but Fern, the protagonist, was introduced in the Bookshops & Bonedust prequel. You may have noticed I didn't describe this as cozy fantasy. That is intentional. When we left Fern at the end of Bookshops & Bonedust, the rattkin was running a bookshop in the town of Murk. As Brigands & Breadknives opens, Fern is moving, for complicated and hard-to-describe personal reasons, to Thune where Viv has her coffee shop. Her plan is to open a new bookstore next door to Legends and Lattes. This is exactly the sort of plot one might expect from this series, and the first few chapters feel like yet another version of the first two novels. Then Fern makes an impulsive and rather inexplicable (even to herself) decision and the plot goes delightfully sideways. Brigands & Breadknives is not, as Baldree puts it in the afterword, a book about fantasy small-business ownership as the answer to all of life's woes. It is, instead, a sword and sorcery story about a possibly immortal elven bounty hunter, her utterly baffling goblin prisoner, and a rattkin bookseller who becomes their unexpected travel companion for reasons she can't explain. It's a story about a mid-life crisis in a world and with supporting characters that I can only describe as inspired by a T. Kingfisher novel. Baldree is not Ursula Vernon, of course. This book does not contain paladins or a romance, possibly to the relief of some readers. It's slower, a bit more introspective, and doesn't have as sharp of edges or the casual eerie unsettlingness. But there is a religious order that worships a tentacled space horror for entirely unexpected reasons, pompous and oleaginous talking swords with verbose opinions about everything, a mischievously chaotic orange-haired goblin who quickly became one of my favorite fantasy characters and then kept getting better, and a whole lot of heart. You may see why Kingfisher was my first thought for a comparison point. Unlike Baldree's previous novels, there is a lot of combat and injury. I think some people will still describe this book as cozy, and I'm not going to argue too strongly because the conflicts are a bit lighter than the sort of rape and murder one would see in a Mercedes Lackey novel. But to me this felt like sword and sorcery in a Dungeons and Dragons universe made more interesting by letting the world-building go feral and a little bit sarcastic. Most of the book is spent traveling, there are a lot of random encounters that build into a connected plot, and some scenes (particularly the defense of the forest village) felt like they could have sold to the Swords and Sorceress anthology series. Also, this was really good! I liked both Legends & Lattes and Bookshops & Bonedust, maybe a bit more than the prevailing opinion among reviewers since the anachronisms never bothered me, but I wasn't sure whether to dive directly into this book because I was expecting more of the same. This is not more of the same. I think it's clearly better writing and world-building than either of the previous books. It helps that Fern is the protagonist; as much as I like Viv, I think Fern is a more interesting character, and I am glad she got a book of her own. Baldree takes a big risk on the emotional arc of this book. Fern starts the story in a bad state and makes some decisions to kick off the plot that are difficult to defend. She beats herself up for those decisions for most of the book, deservedly, and parts of that emotional turmoil are difficult to read. Baldree resists the urge to smooth everything over and instead provides a rather raw sense of depression, avoidance, and social anxiety that some readers are going to have to brace themselves for. I respect the decision to not write the easy series book people probably expected, but I'm not sure Fern's emotional arc quite worked. Baldree is hinting at something that's hard to describe logically, and I'm not sure he was able to draw a clear enough map of Fern's thought process for the reader to understand her catharsis. The "follow your passion" self-help mindset has formed a gravitational singularity in the vicinity of this book's theme, it takes some skillful piloting to avoid being sucked into its event horizon, and I don't think Baldree quite managed to escape it. He made a valiant attempt, though, and it created a far more interesting book than one about safer emotions. I wanted more of an emotional payoff than I got, but the journey, even with the moments of guilt and anxiety, was so worth it. The world-building is funnier and more interesting than the previous books of the series, and the supporting cast is fantastic. If you bailed on the series but you like sword and sorcery and T. Kingfisher novels, consider returning. You do probably need to read Bookshops & Bonedust first, if you haven't already, since it helps to know the start of Fern's story. Recommended, and shortcomings aside, much better than I had expected. Content notes: Bloody sword fights, major injury, some very raw emotions about letting down friends and destroying friendships. Rating: 8 out of 10

14 December 2025

Evgeni Golov: Home Assistant, Govee Lights Local, VLANs, Oh my!

We recently bought some Govee Glide Hexa Light Panels, because they have a local LAN API that is well integrated into Home Assistant. Or so we thought. Our network is not that complicated, but there is a dedicated VLAN for IOT devices. Home Assistant runs in a container (with network=host) on a box in the basement, and that box has a NIC in the IOT VLAN so it can reach devices there easily. So far, this has never been a problem. Enter the Govee LAN API. Or maybe its Python implementation. Not exactly sure who's to blame here. The API involves sending JSON over multicast, which the Govee device will answer to.
No devices found on the network
After turning logging for homeassistant.components.govee_light_local to 11, erm debug, we see:
DEBUG (MainThread) [homeassistant.components.govee_light_local.config_flow] Starting discovery with IP 192.168.42.2
DEBUG (MainThread) [homeassistant.components.govee_light_local.config_flow] No devices found with IP 192.168.42.2
That's not the IP address in the IOT VLAN! Turns out the integration recently got support for multiple NICs, but Home Assistant doesn't just use all the interfaces it sees by default. You need to go to Settings Network Network adapter and deselect "Autoconfigure", which will allow your to select individual interfaces. Once you've done that, you'll see Starting discovery with IP messages for all selected interfaces and adding of Govee Lights Local will work.

Dirk Eddelbuettel: BH 1.90.0-1 on CRAN: New Upstream

Boost Boost is a very large and comprehensive set of (peer-reviewed) libraries for the C++ programming language, containing well over one hundred individual libraries. The BH package provides a sizeable subset of header-only libraries for (easier, no linking required) use by R. It is fairly widely used: the (partial) CRAN mirror logs (aggregated from the cloud mirrors) show over 41.5 million package downloads. Version 1.90.0 of Boost was released a few days ago following the regular Boost release schedule of April, August and December releases. As before, we packaged it almost immediately and started testing following our annual update cycle which strives to balance being close enough to upstream and not stressing CRAN and the user base too much. The reverse depends check revealed only one really minor issue among the over three hundred direct reverse dependencies. And that issue was addressed yesterday within hours by a truly responsove maintainer (and it helped that a related issue had been addressed months earlier with version 1.89.). So big thanks to Jean-Romain Roussel for the prompt fix, and to Andrew Johnson for the earlier test with 1.89.0. As last year with 1.87.0, no new Boost libraries were added to BH so the (considerable) size is more or less unchanged. It lead to CRAN doing a manual inspection but as there were no other issues it sailed through as is now in the CRAN repository. The short NEWS entry follows.

Changes in version 1.90.0-1 (2025-12-13)
  • Upgrade to Boost 1.90.0, patched as usual to comment-out diagnostic suppression messages per the request of CRAN
  • Minor upgrades to continuous integration

Via my CRANberries, there is a diffstat report relative to the previous release. Comments and suggestions about BH are welcome via the issue tracker at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

13 December 2025

Junichi Uekawa: I was wondering if there was some debian thread and noticed maybe something is broken in my mail setup.

I was wondering if there was some debian thread and noticed maybe something is broken in my mail setup. The amount of emails I am receiving seems to be very small.

12 December 2025

Freexian Collaborators: Debian Contributions: Updates about DebConf Video Team Sprint, rebootstrap, SBOM tooling in Debian and more! (by Anupa Ann Joseph)

Debian Contributions: 2025-11 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

DebConf Video Team Sprint The DebConf Video Team records, streams, and publishes talks from DebConf and many miniDebConfs. A lot of the infrastructure development happens during setup for these events, but we also try to organize a sprint once a year to work on infrastructure, when there isn t a DebConf about to happen. Stefano attended the sprint in Herefordshire this year and wrote up a report.

rebootstrap, by Helmut Grohne A number of jobs were stuck in architecture-specific failures. gcc-15 and dpkg still disagree about whether PIE is enabled occasionally and big endian mipsen needed fixes in systemd. Beyond this regular uploads of libxml2 and gcc-15 required fixes and rebasing of pending patches. Earlier, Loongson used rebootstrap to create the initial package set for loong64 and Miao Wang now submitted their changes. Therefore, there is now initial support for suites other than unstable and use with derivatives.

Building the support for Software Bill Of Materials tooling in Debian, by Santiago Ruano Rinc n Vendors of Debian-based products may/should be paying attention to the evolution of different jurisdictions (such as the CRA or updates on CISA s Minimum Elements for a Software Bill of Materials) that require to make available Software Bill of Materials (SBOM) of their products. It is important then to have tools in Debian to make it easier to produce such SBOMs. In this context, Santiago continued the work on packaging libraries related to SBOMs. This includes the packaging of the SPDX python library (python-spdx-tools), and its dependencies rdflib and mkdocs-include-markdown-plugin. System Package Data Exchange (SPDX), defined by ISO/IEC 5962:2021, is an open standard capable of representing systems with software components as SBOMs and other data and security references. SPDX and CycloneDX (whose python library python3-cyclonedx-lib was packaged by prior efforts this year), encompass the two main SBOM standards available today.

Miscellaneous contributions
  • Carles improved po-debconf-manager: added checking status of bug reports automatically via python-debianbts; changed some command line options naming or output based on user feedback; finished refactoring user interaction to rich; codebase is now flake8-compliant; added type safety with mypy.
  • Carles, using po-debconf-manager, created 19 bug reports for translations where the merge requests were pending; reviewed and created merge requests for 4 packages.
  • Carles planned a second version of the tool that detects packages that Recommends or Suggests packages which are not in Debian. He is taking ideas from dumat.
  • Carles submitted a pull request to python-unidiff2 (adapted from the original pull request to python-unidiff). He also started preparing a qnetload update.
  • Stefano did miscellaneous python package updates: mkdocs-macros-plugin, python-confuse, python-pip, python-mitogen.
  • Stefano reviewed a beets upload for a new maintainer who is taking it over.
  • Stefano handled some debian.net infrastructure requests.
  • Stefano updated debian.social infrastructure for the trixie point release.
  • The update broke jitsi.debian.social, Stefano put some time into debugging it and eventually enlisted upstream assistance, who solved the problem!
  • Stefano worked on some patches for Python that help Debian:
    • GH-139914: The main HP PA-RISC support patch for 3.14.
    • GH-141930: We observed an unhelpful error when failing to write a .pyc file during package installation. We may have fixed the problem, and at least made the error better.
    • GH-141011: Ignore missing ifunc support on HP PA-RISC.
  • Stefano spun up a website for hamburg2026.mini.debconf.org.
  • Rapha l reviewed a merge request updating tracker.debian.org to rely on bootstrap
    version 5.
  • Emilio coordinated various transitions.
  • Helmut sent patches for 26 cross build failures.
  • Helmut officially handed over the cleanup of the /usr-move transition.
  • Helmut monitored the transition moving libcrypt-dev out of build-essential and bumped the remaining bugs to rc-severity in coordination with the release team.
  • Helmut updated the Build-Profiles patch for debian-policy incorporating feedback from Sean Whitton with a lot of help from Nattie Mayer-Hutchings and Freexian colleagues.
  • Helmut discovered that the way mmdebstrap deals with start-stop-daemon may result in broken output and sent a patch.
  • As a result of armel being removed from sid , but not from forky , the multiarch hinter broke. Helmut fixed it.
  • Helmut uploaded debvm accepting a patch from Luca Boccassi to fix it for newer
    systemd.
  • Colin began preparing for the second stage of the OpenSSH GSS-API key exchange package split.
  • Colin caught and fixed a devscripts regression due to it breaking part of Debusine.
  • Colin packaged django-pgtransaction and backported it to trixie , since it looks useful for Debusine.
  • Thorsten uploaded the packages lprng, cpdb-backend-cups, cpdb-libs and ippsample to fix some RC bugs as well as other bugs that accumulated over time. He also uploaded cups-filters to all Debian releases to fix three CVEs.

11 December 2025

Dirk Eddelbuettel: #056: Running r-ci with R-devel

Welcome to post 56 in the R4 series. The recent post #54 reviewed a number of earlier posts on r-ci, our small (but very versatile) runner for continunous integration (CI) with R. The post also introduced the notion of using a container in the matrix of jobs defined and running in parallel. The initial motivation was the (still ongoing, and still puzzling) variation in run-times of GitHub Actions. So when running CI and relying on r2u for the fast, easy, reliable: pick all three! provision of CRAN packages as Ubuntu binaries, a small amount of time is spent prepping a basic Ubuntu instance with the necessary setup. This can be as fast as maybe 20 to 30 seconds, but it can also stretch to almost two minutes when GitHub is busier or out of sorts for other reasons. When the CI job itself is short, that is a nuisance. We presented relying on a pre-made r2u4ci container that adds just a few commands to the standard r2u container to be complete for CI. And with that setup CI runs tend to be reliably faster. This situation is still evolving. I have not converted any of my existing CI scripts (apart from a test instance or two), but I keep monitoring the situation. However, this also offered another perspective: why not rely on a different container for a different CI aspect? When discussing the CI approach with Jeff the other day (and helping add CI to his mmap repo), it occurred to me we could also use on of the Rocker containers for R-devel. A minimal change to the underlying run.sh script later, this was accomplished. An example is provided as both a test and an illustration in the repo for package RcppInt64 in its script ci.yaml:
    strategy:
      matrix:
        include:
          -   name: container, os: ubuntu-latest, container: rocker/r2u4ci  
          -   name: r-devel,   os: ubuntu-latest, container: rocker/drd  
          -   name: macos,     os: macos-latest  
          -   name: ubuntu,    os: ubuntu-latest  

    runs-on: $  matrix.os  
    container: $  matrix.container  
This runs both a standard Ubuntu setup (fourth entry) and the alternate just described relying on the container (first entry) along with the (usually commented-out) optional macOS setup (third entry). And line two brings the drd container from Rocker. The CI runner script now checks for a possible Rdevel binary as provided inside drd (along with alias RD) and uses it when present. And that is all that there is: no other change on the user side; tests now run under R-devel. You can see some of the initial runs at the rcppint64 repo actions log. Another example is now also at Jeff s mmap repo. It should be noted that this relies on R-devel running packages made with R-release. Every few years this breaks when R needs to break its binary API. If and when that happens this option will be costlier as the R-devel instance will then have to (re-)install its R package dependencies. This can be accomodated easily as a step in the yaml file. And under normal circumstances it is not needed. Having easy access to recent builds of R-devel (the container refreshes weekly on a schedule) with the convenience of r2u gives another option for package testing. I may continue to test locally with R-devel as my primary option, and most likely keep my CI small and lean (usually just one R-relase run on Ubuntu) but having another option at GitHub Actions is also a good thing.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

Next.

Previous.