Search Results: "cas"

26 September 2024

Melissa Wen: Reflections on 2024 Linux Display Next Hackfest

Hey everyone! The 2024 Linux Display Next hackfest concluded in May, and its outcomes continue to shape the Linux Display stack. Igalia hosted this year s event in A Coru a, Spain, bringing together leading experts in the field. Samuel Iglesias and I organized this year s edition and this blog post summarizes the experience and its fruits. One of the highlights of this year s hackfest was the wide range of backgrounds represented by our 40 participants (both on-site and remotely). Developers and experts from various companies and open-source projects came together to advance the Linux Display ecosystem. You can find the list of participants here. The event covered a broad spectrum of topics affecting the development of Linux projects, user experiences, and the future of display technologies on Linux. From cutting-edge topics to long-term discussions, you can check the event agenda here.
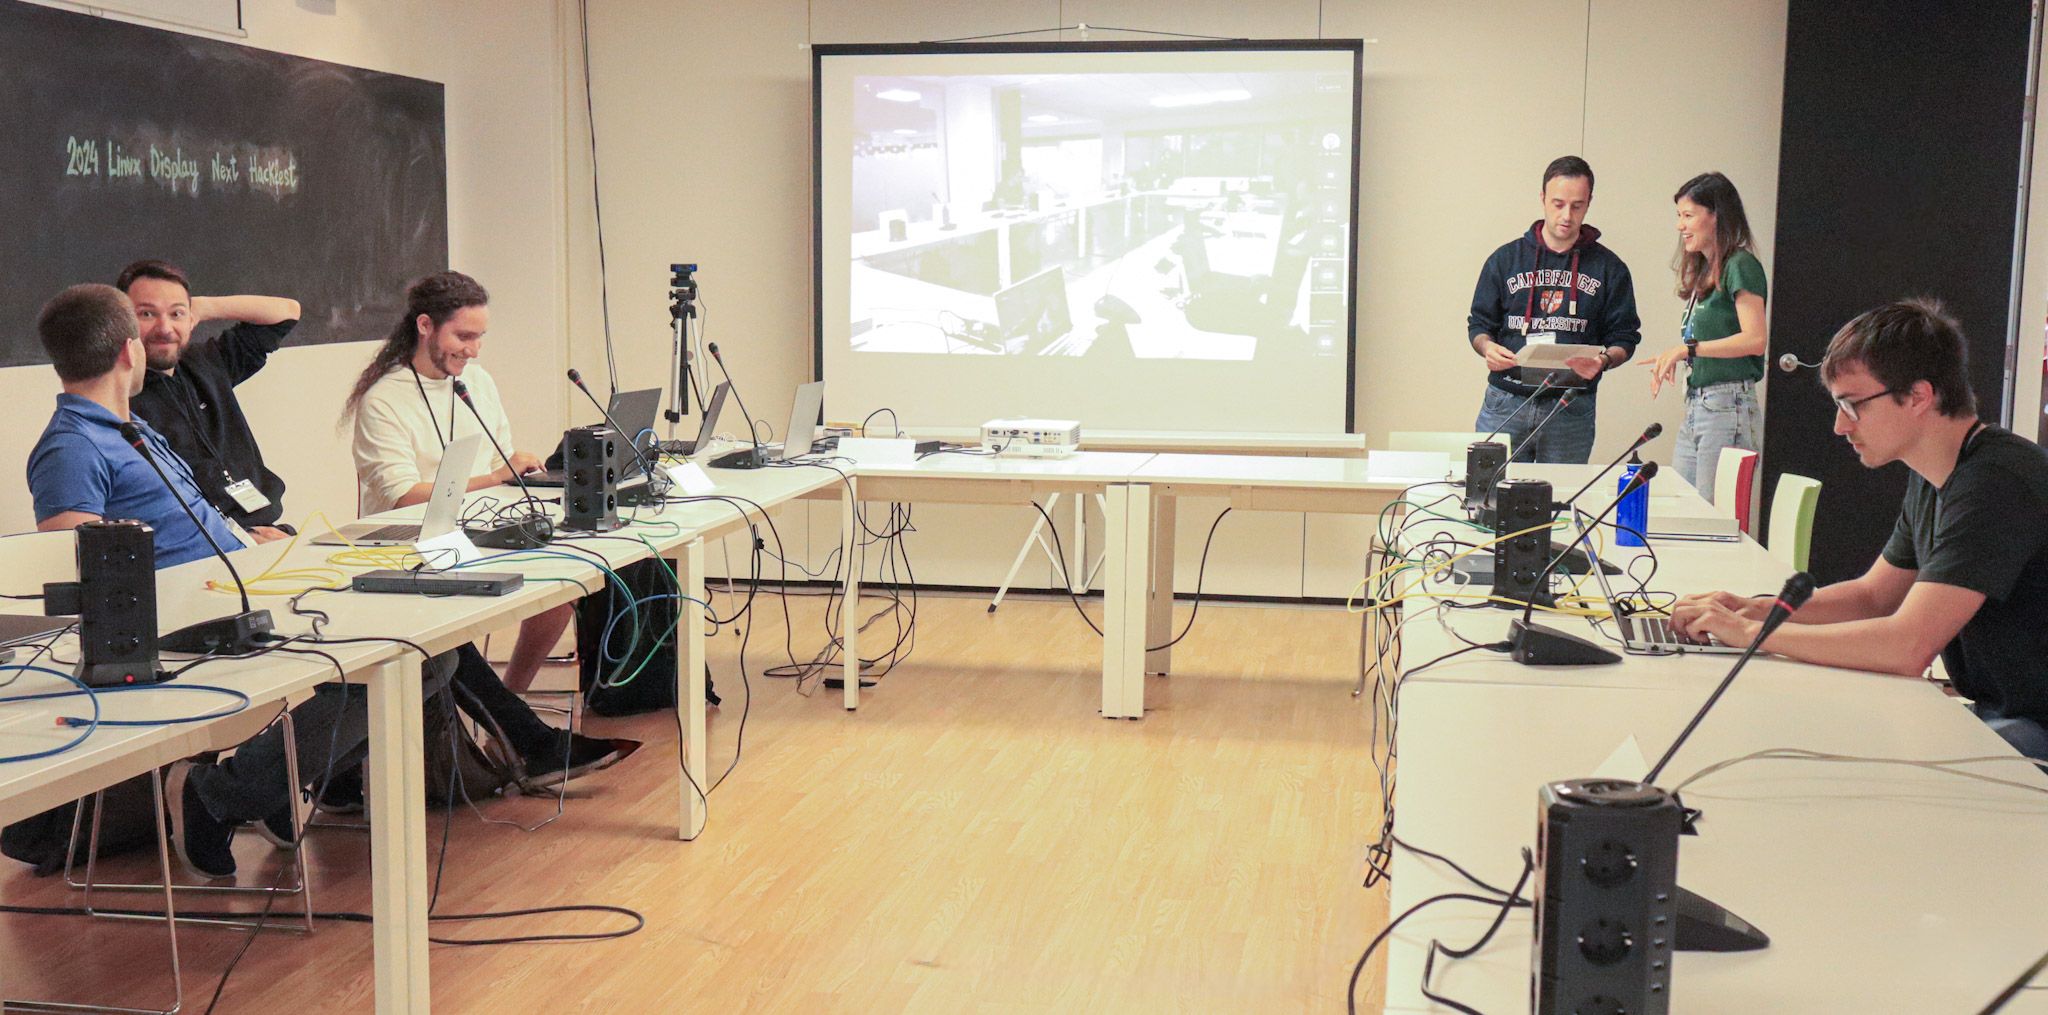
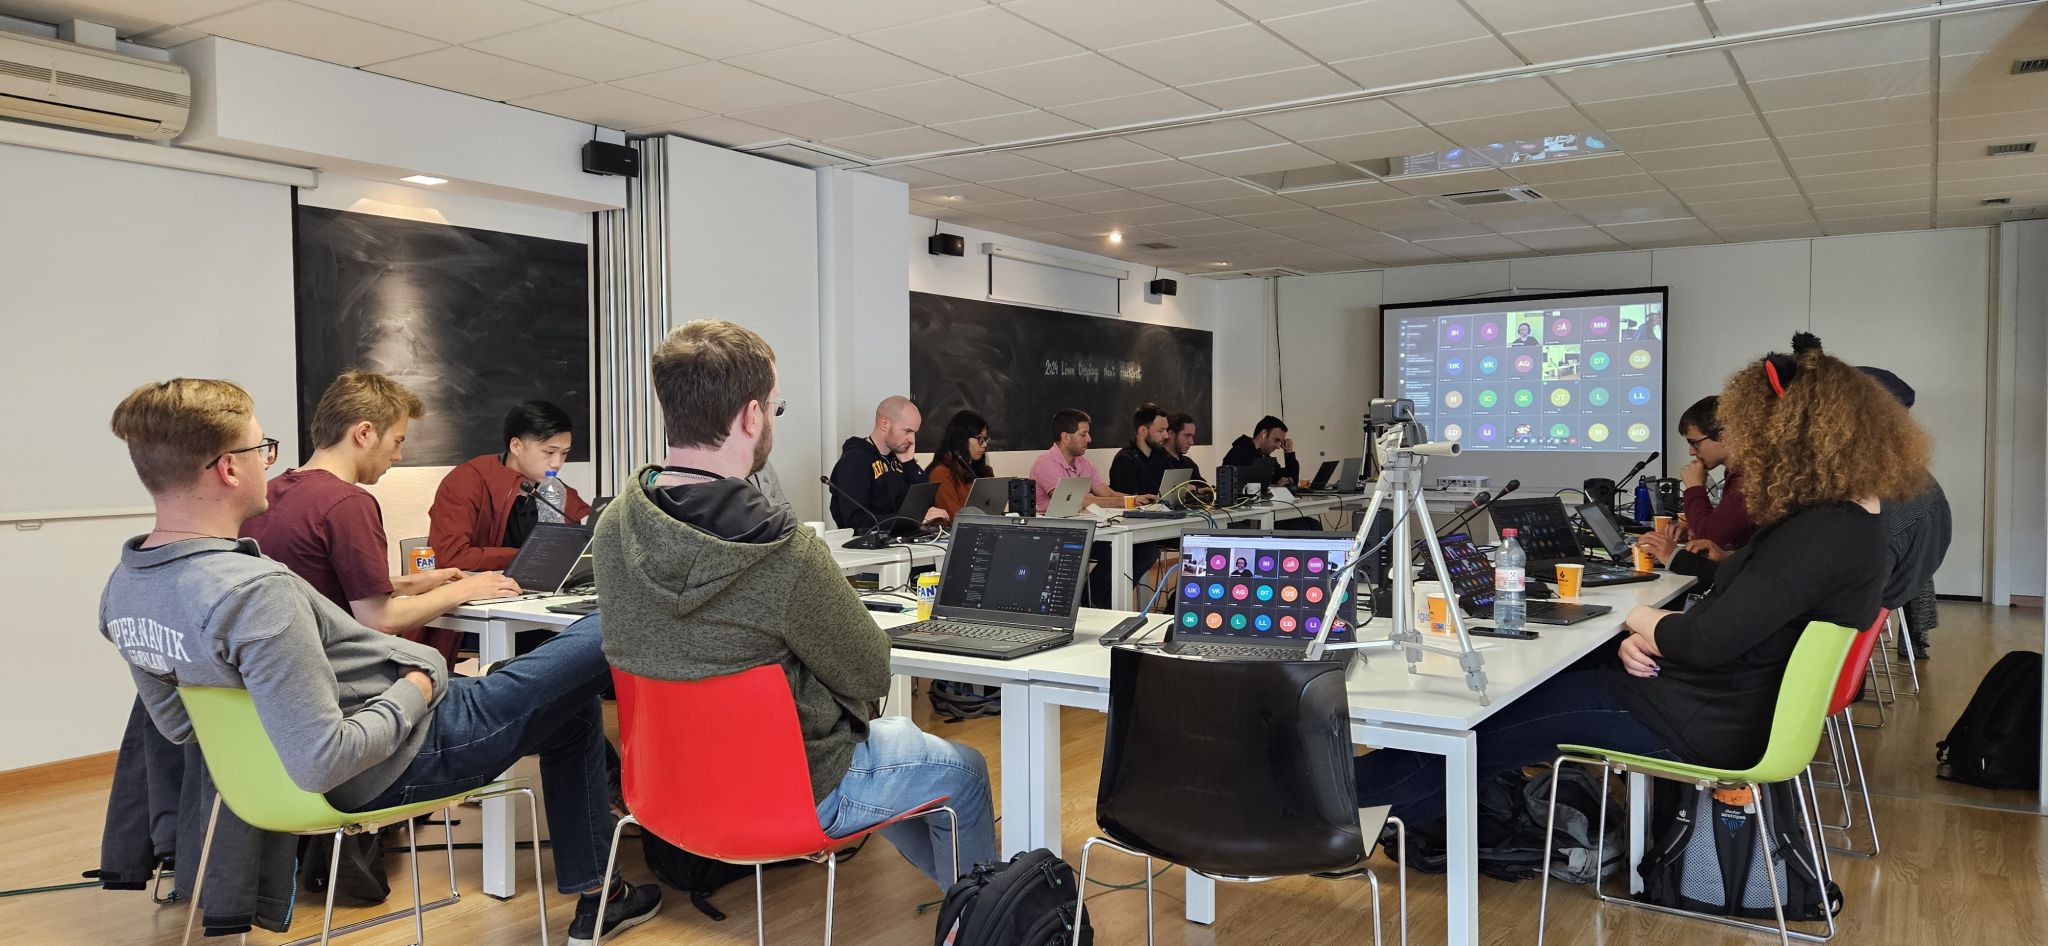
Organization Highlights The hackfest was marked by in-depth discussions and knowledge sharing among Linux contributors, making everyone inspired, informed, and connected to the community. Building on feedback from the previous year, we refined the unconference format to enhance participant preparation and engagement. Structured Agenda and Timeboxes: Each session had a defined scope, time limit (1h20 or 2h10), and began with an introductory talk on the topic.
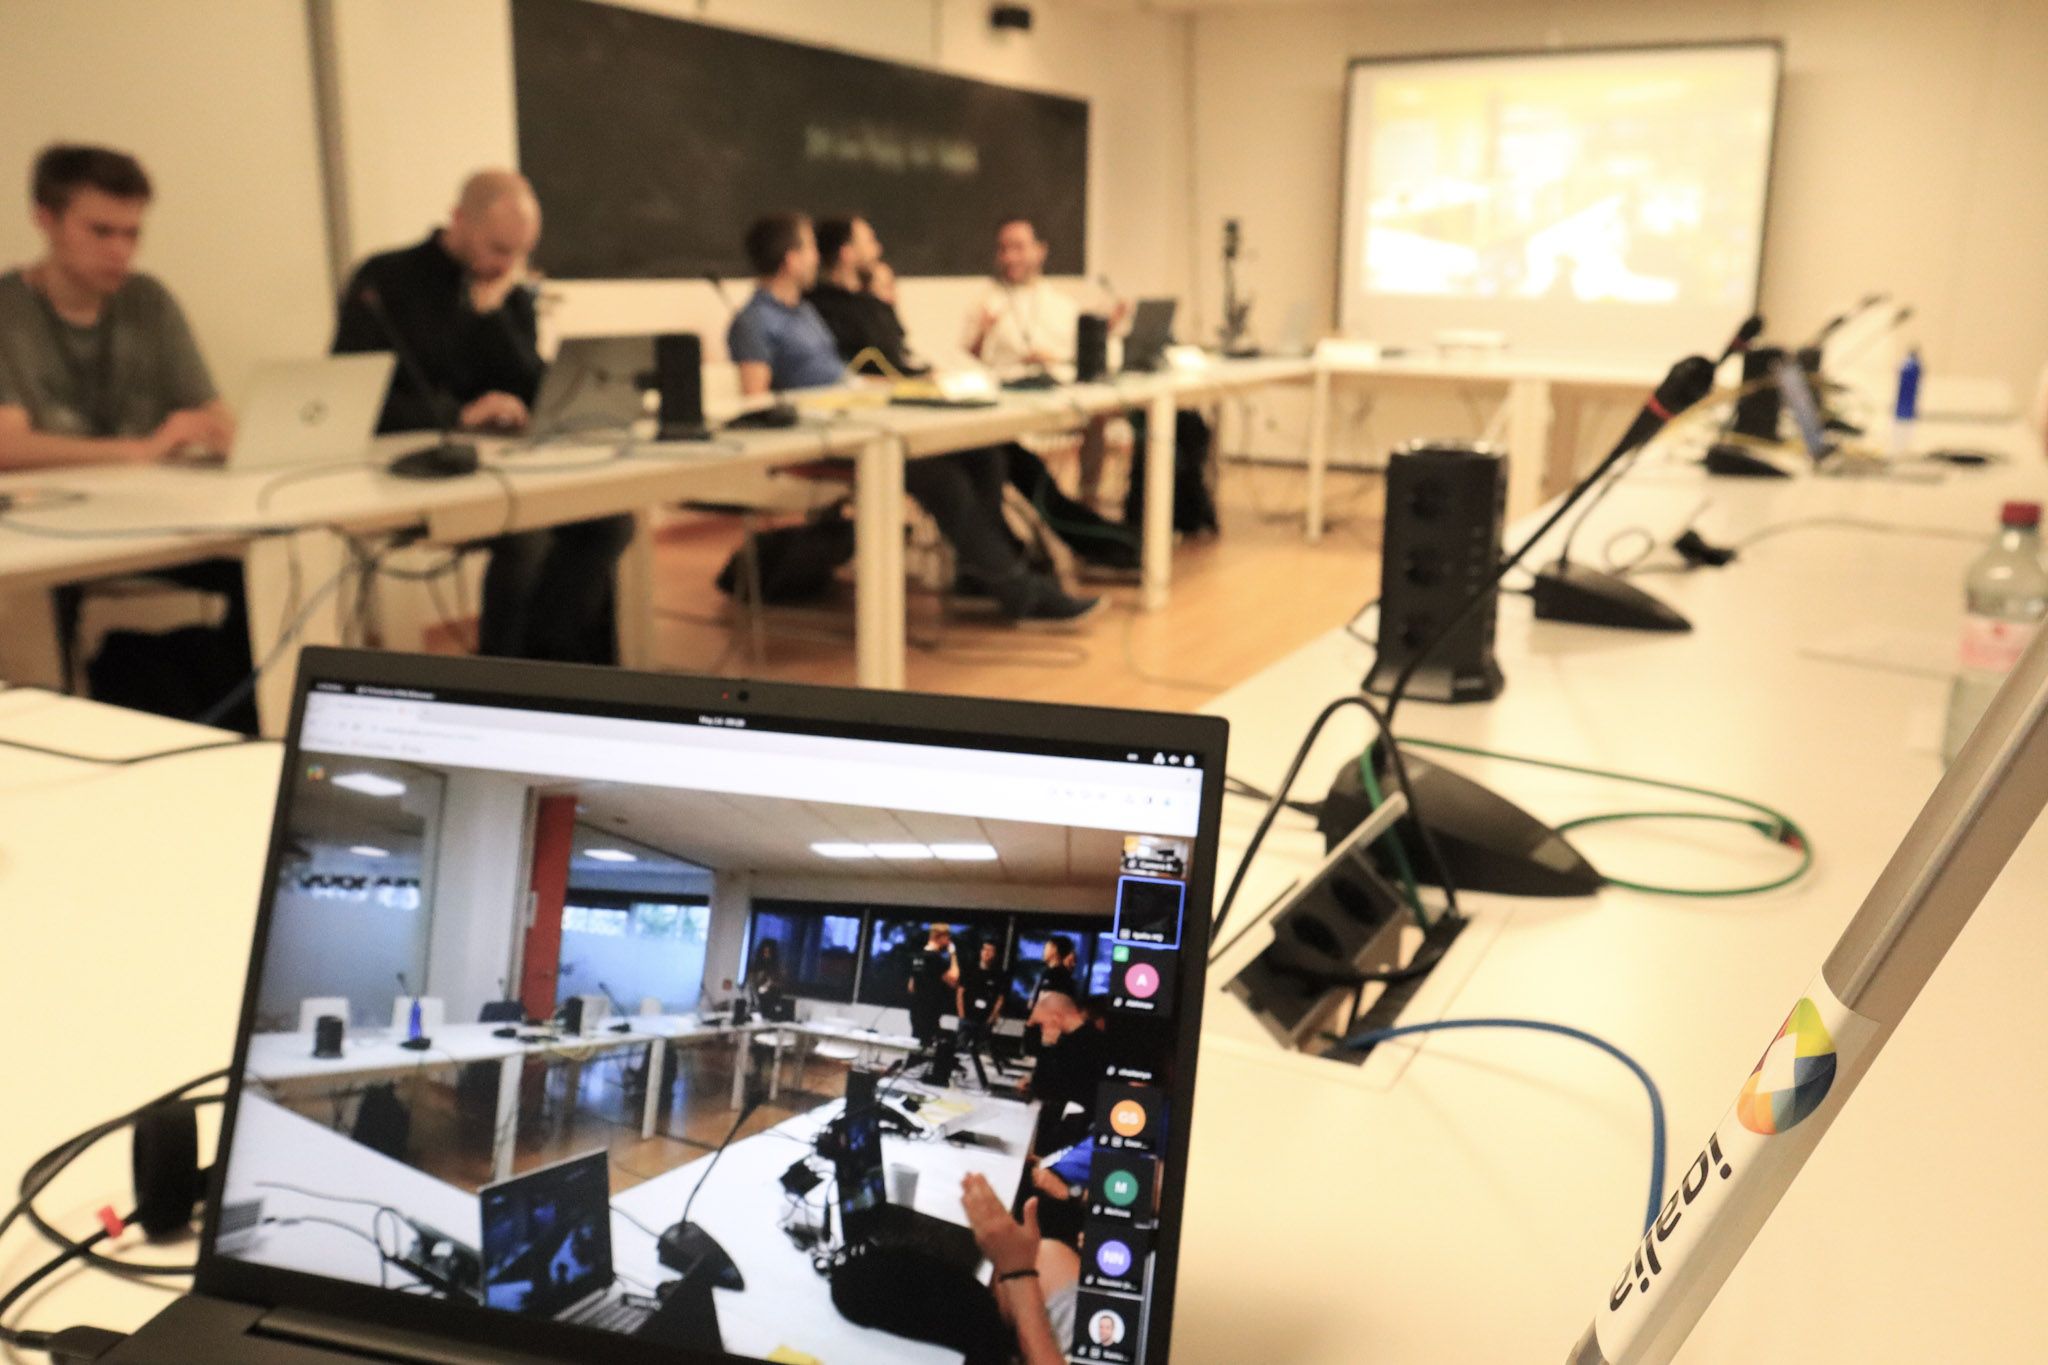
  • Participant-Led Discussions: We pre-selected in-person participants to lead discussions, allowing them to prepare introductions, resources, and scope.
  • Transparent Scheduling: The schedule was shared in advance as GitHub issues, encouraging participants to review and prepare for sessions of interest.
Engaging Sessions: The hackfest featured a variety of topics, including presentations and discussions on how participants were addressing specific subjects within their companies.
  • No Breakout Rooms, No Overlaps: All participants chose to attend all sessions, eliminating the need for separate breakout rooms. We also adapted run-time schedule to keep everybody involved in the same topics.
  • Real-time Updates: We provided notifications and updates through dedicated emails and the event matrix room.
Strengthening Community Connections: The hackfest offered ample opportunities for networking among attendees.
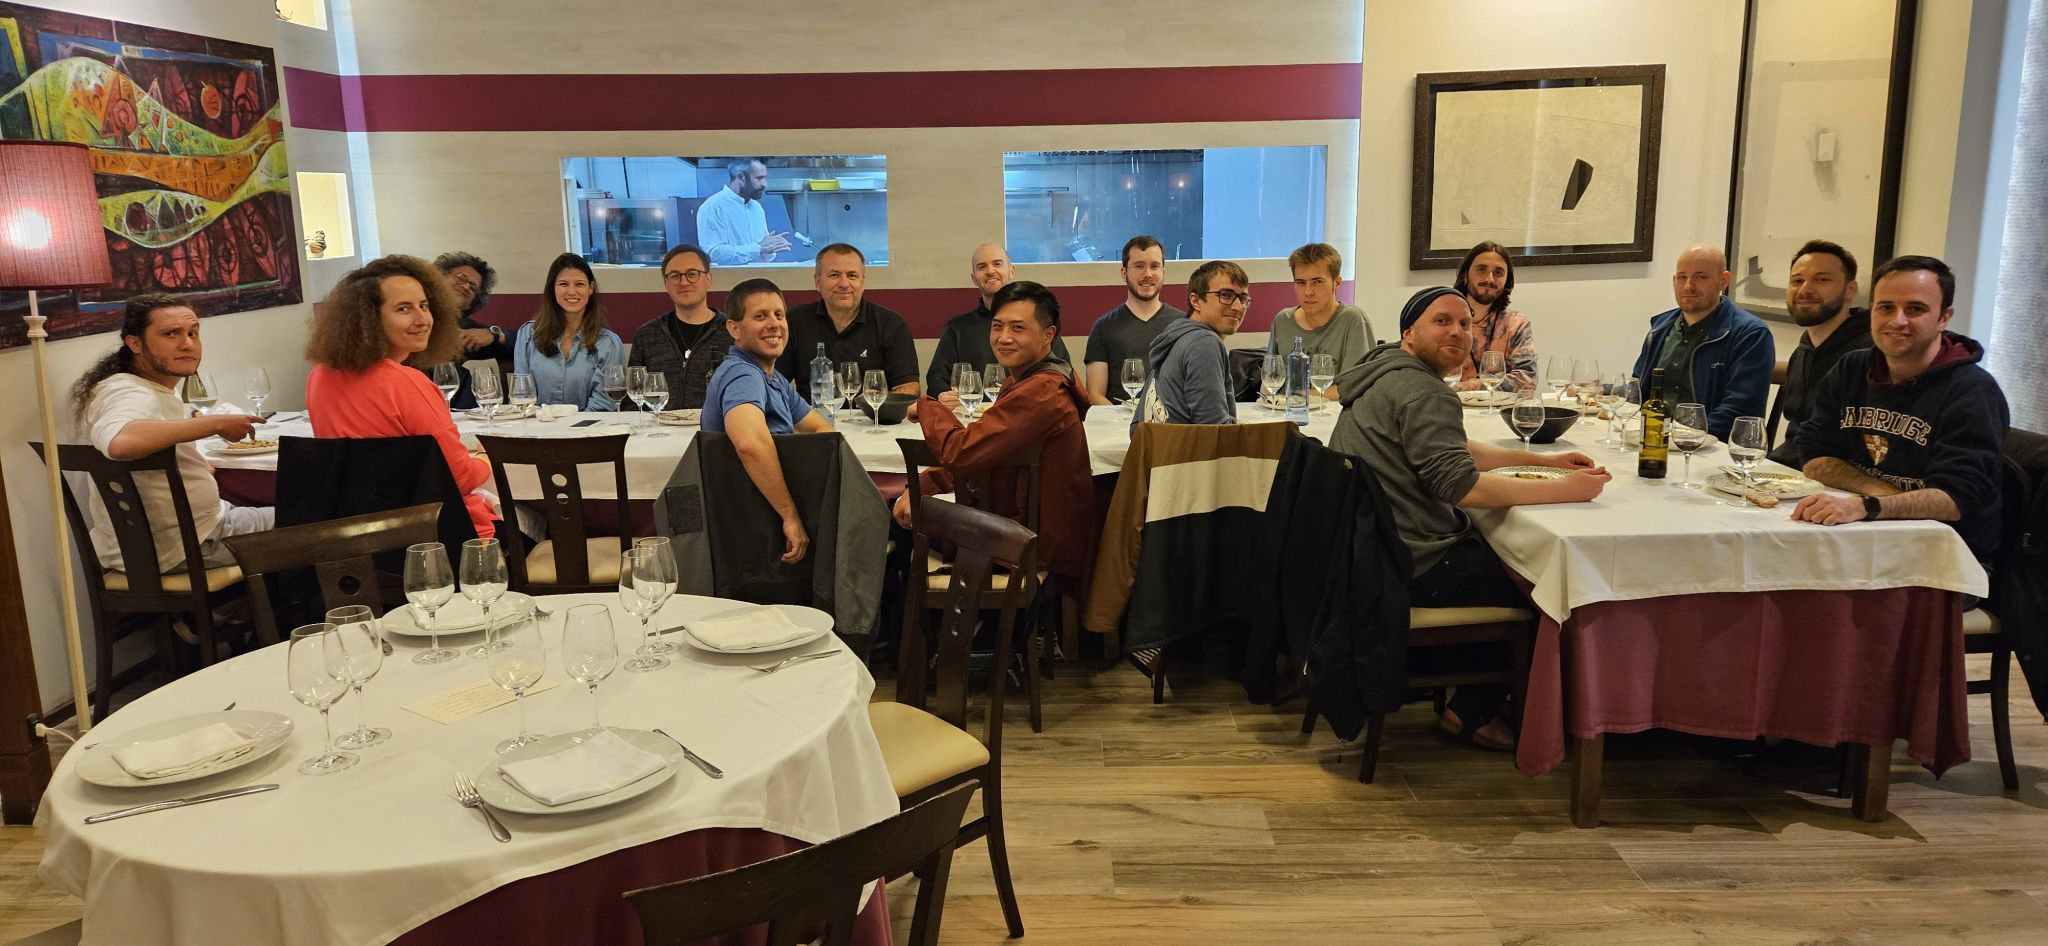
  • Social Events: Igalia sponsored coffee breaks, lunches, and a dinner at a local restaurant.
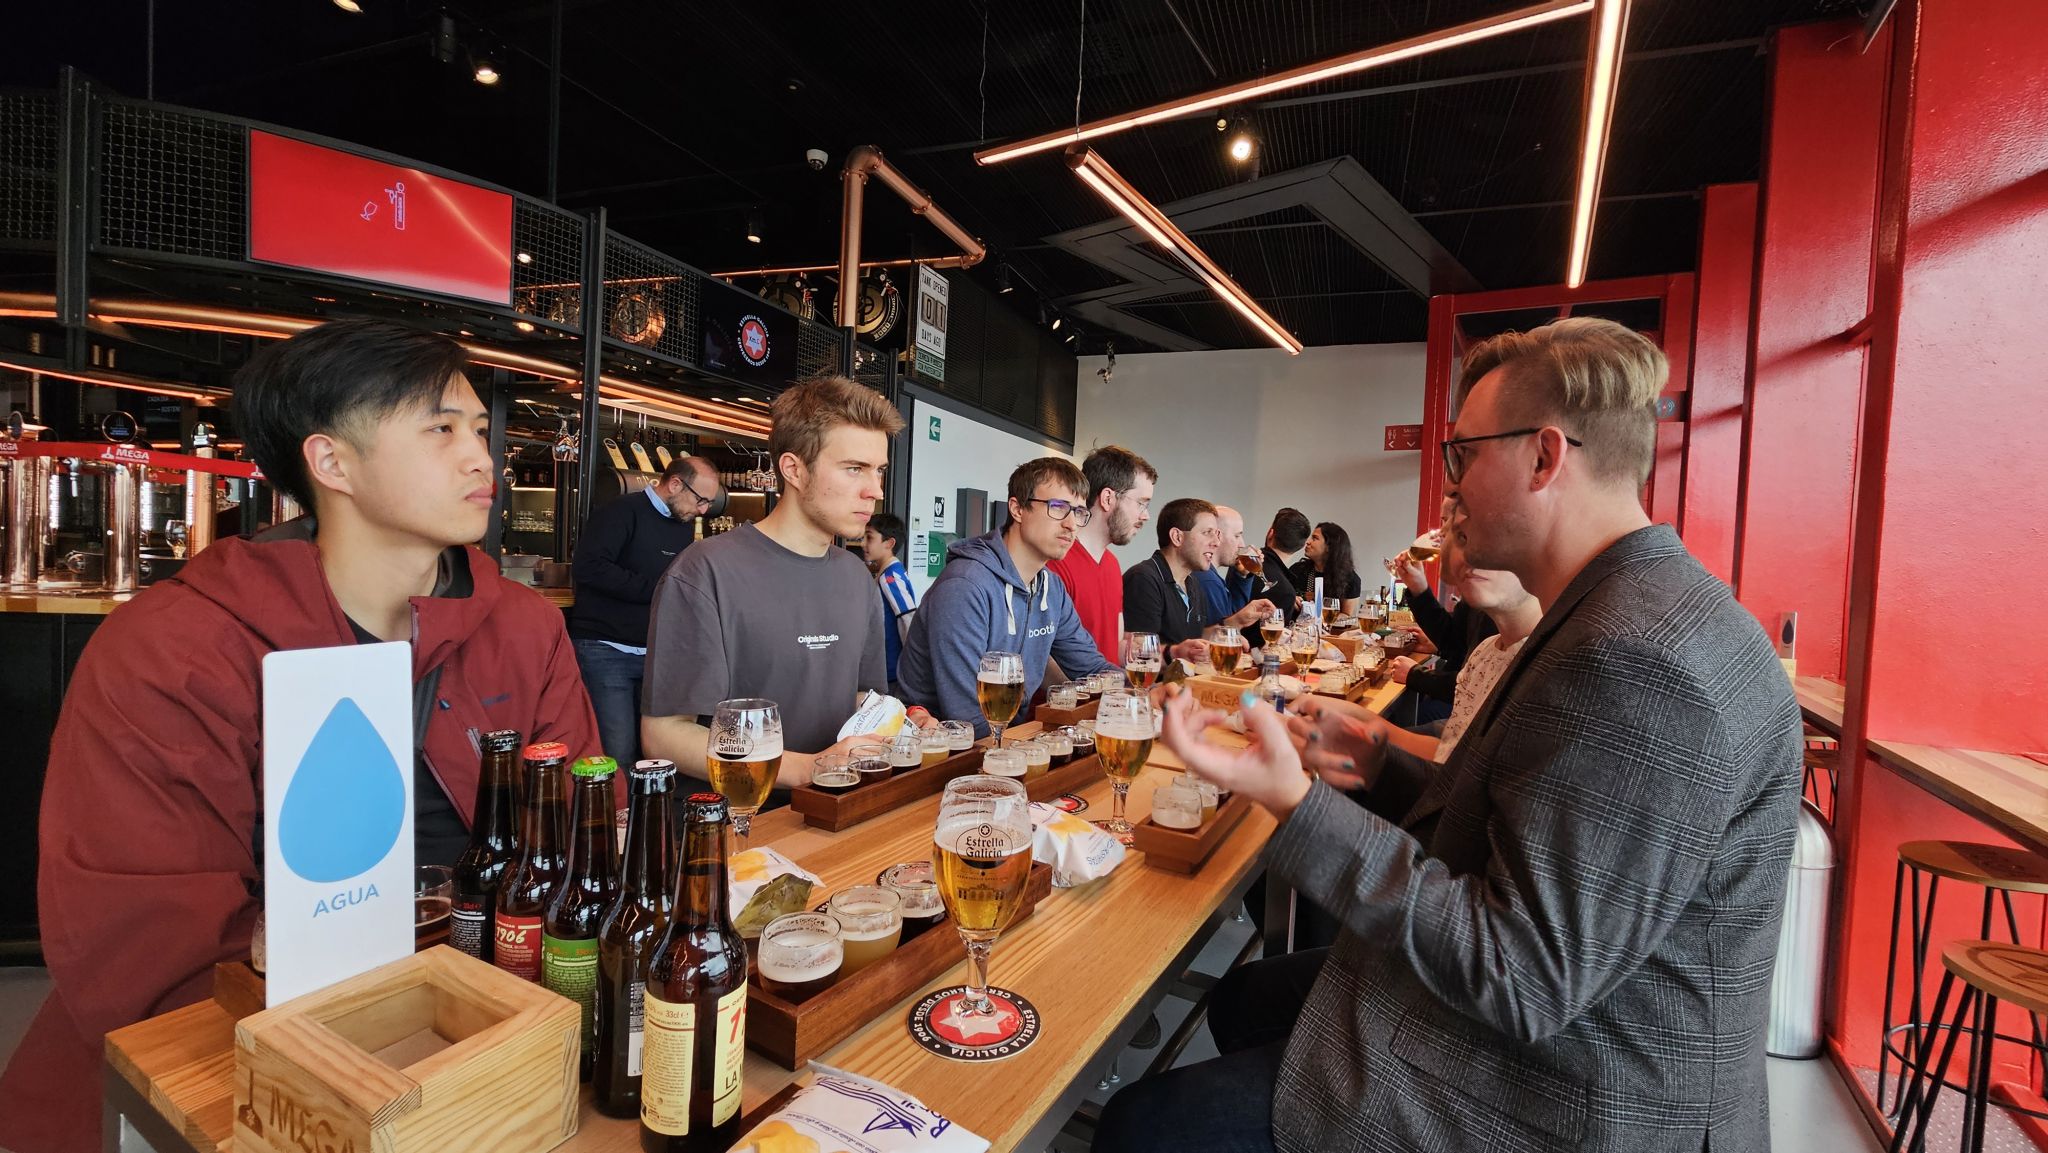
  • Museum Visit: Participants enjoyed a sponsored visit to the Museum of Estrela Galicia Beer (MEGA).
Fruitful Discussions and Follow-up The structured agenda and breaks allowed us to cover multiple topics during the hackfest. These discussions have led to new display feature development and improvements, as evidenced by patches, merge requests, and implementations in project repositories and mailing lists. With the KMS color management API taking shape, we discussed refinements and best approaches to cover the variety of color pipeline from different hardware-vendors. We are also investigating techniques for a performant SDR<->HDR content reproduction and reducing latency and power consumption when using the color blocks of the hardware.
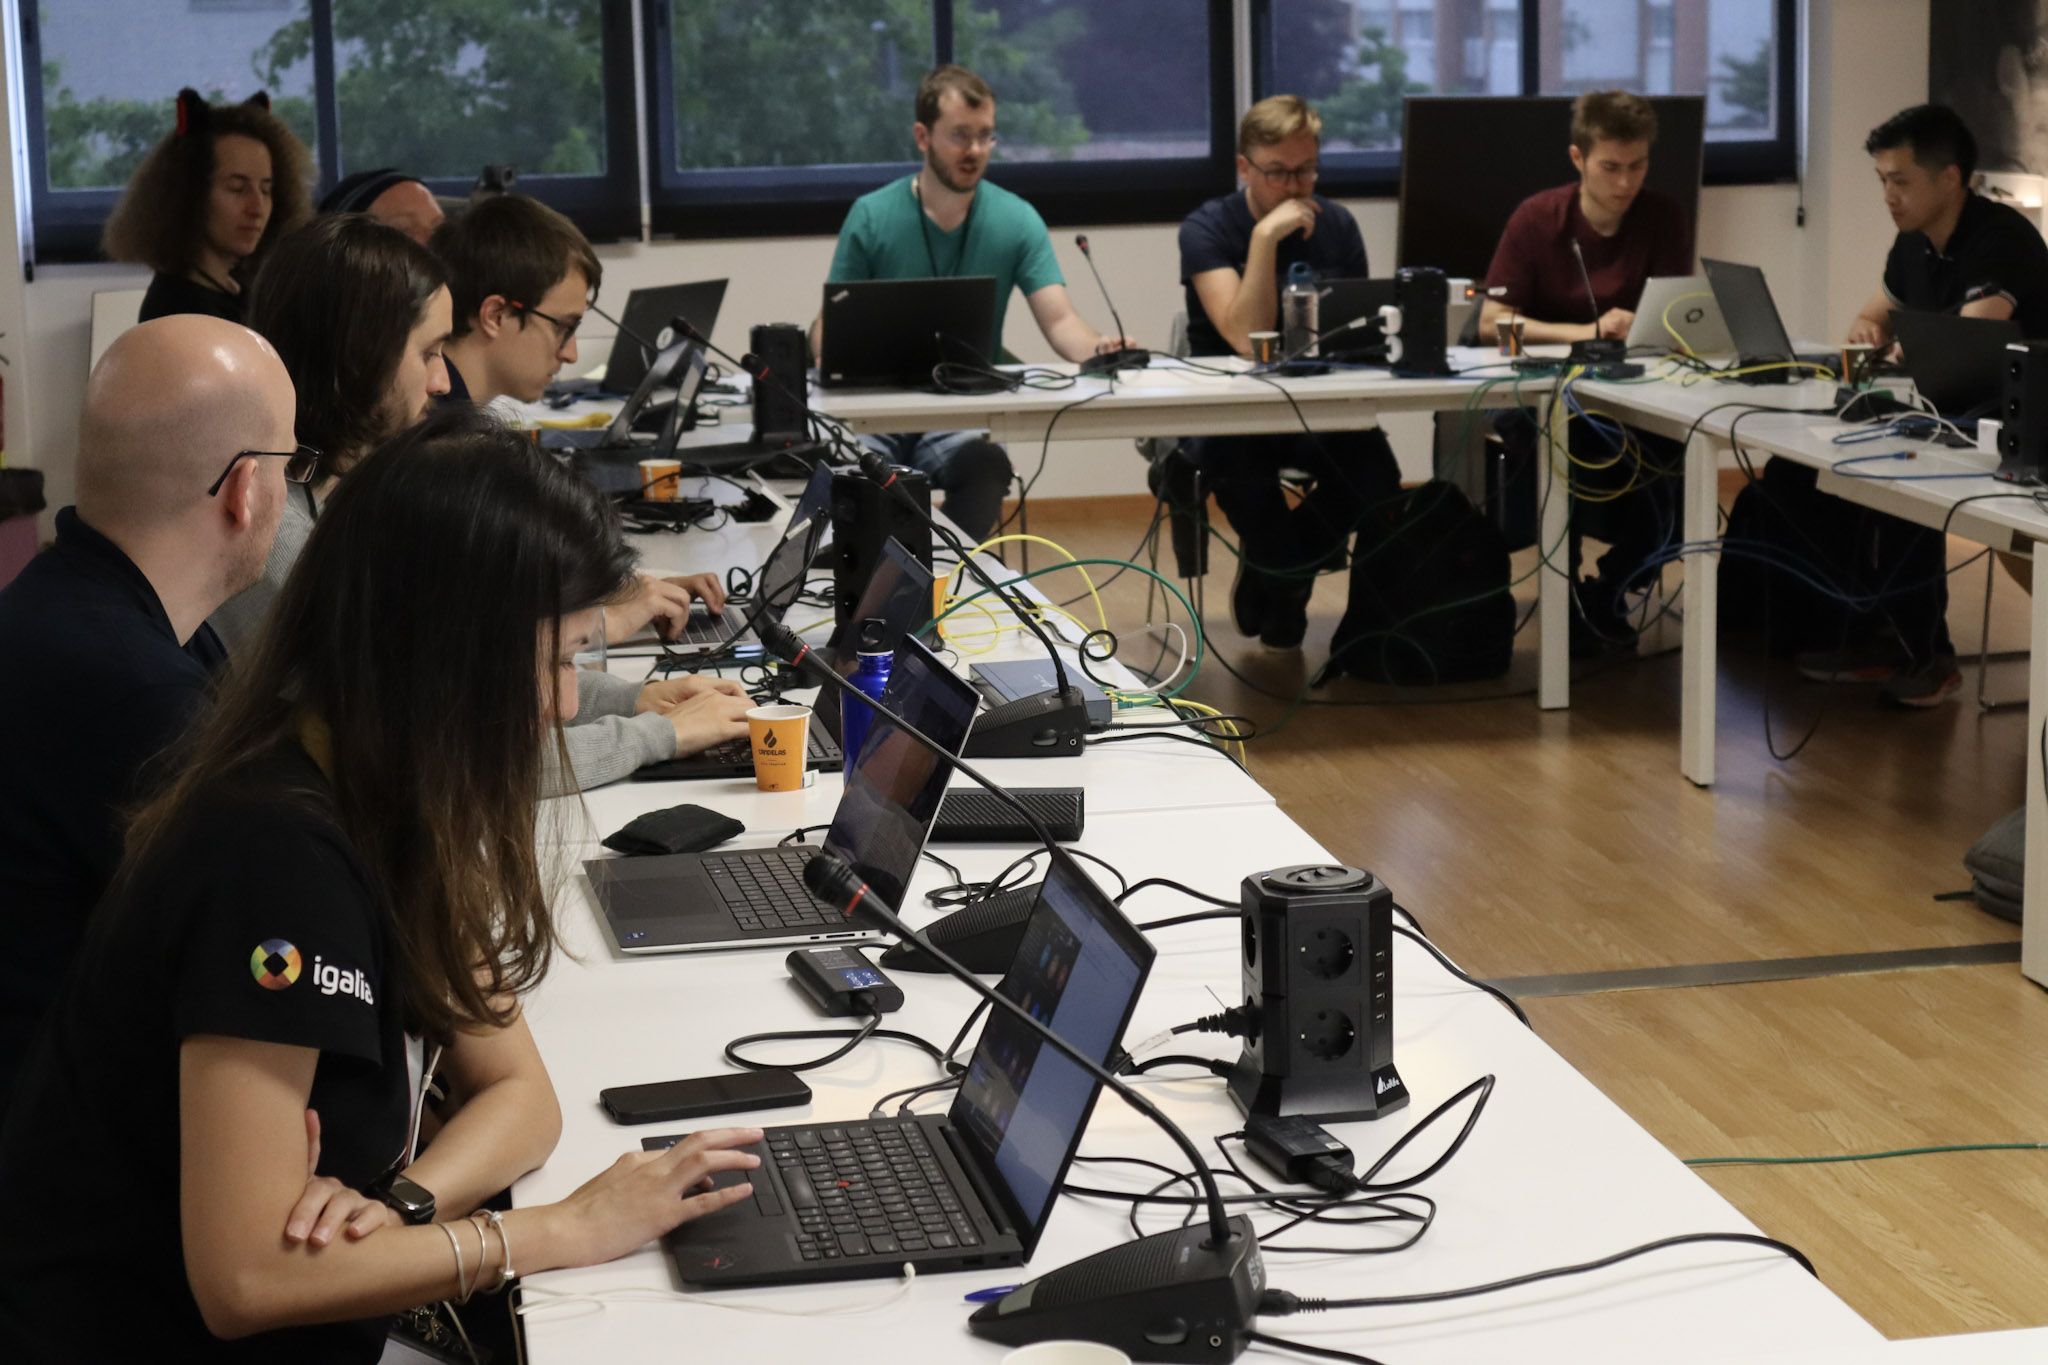
Color Management/HDR Color Management and HDR continued to be the hottest topic of the hackfest. We had three sessions dedicated to discuss Color and HDR across Linux Display stack layers.

Color/HDR (Kernel-Level) Harry Wentland (AMD) led this session. Here, kernel Developers shared the Color Management pipeline of AMD, Intel and NVidia. We counted with diagrams and explanations from HW-vendors developers that discussed differences, constraints and paths to fit them into the KMS generic color management properties such as advertising modeset needs, IN\_FORMAT, segmented LUTs, interpolation types, etc. Developers from Qualcomm and ARM also added information regarding their hardware. Upstream work related to this session:

Color/HDR (Compositor-Level) Sebastian Wick (RedHat) led this session. It started with Sebastian s presentation covering Wayland color protocols and compositor implementation. Also, an explanation of APIs provided by Wayland and how they can be used to achieve better color management for applications and discussions around ICC profiles and color representation metadata. There was also an intensive Q&A about LittleCMS with Marti Maria. Upstream work related to this session:

Color/HDR (Use Cases and Testing) Christopher Cameron (Google) and Melissa Wen (Igalia) led this session. In contrast to the other sessions, here we focused less on implementation and more on brainstorming and reflections of real-world SDR and HDR transformations (use and validation) and gainmaps. Christopher gave a nice presentation explaining HDR gainmap images and how we should think of HDR. This presentation and Q&A were important to put participants at the same page of how to transition between SDR and HDR and somehow emulating HDR. We also discussed on the usage of a kernel background color property. Finally, we discussed a bit about Chamelium and the future of VKMS (future work and maintainership).

Power Savings vs Color/Latency Mario Limonciello (AMD) led this session. Mario gave an introductory presentation about AMD ABM (adaptive backlight management) that is similar to Intel DPST. After some discussions, we agreed on exposing a kernel property for power saving policy. This work was already merged on kernel and the userspace support is under development. Upstream work related to this session:

Strategy for video and gaming use-cases Leo Li (AMD) led this session. Miguel Casas (Google) started this session with a presentation of Overlays in Chrome/OS Video, explaining the main goal of power saving by switching off GPU for accelerated compositing and the challenges of different colorspace/HDR for video on Linux. Then Leo Li presented different strategies for video and gaming and we discussed the userspace need of more detailed feedback mechanisms to understand failures when offloading. Also, creating a debugFS interface came up as a tool for debugging and analysis.

Real-time scheduling and async KMS API Xaver Hugl (KDE/BlueSystems) led this session. Compositor developers have exposed some issues with doing real-time scheduling and async page flips. One is that the Kernel limits the lifetime of realtime threads and if a modeset takes too long, the thread will be killed and thus the compositor as well. Also, simple page flips take longer than expected and drivers should optimize them. Another issue is the lack of feedback to compositors about hardware programming time and commit deadlines (the lastest possible time to commit). This is difficult to predict from drivers, since it varies greatly with the type of properties. For example, color management updates take much longer. In this regard, we discusssed implementing a hw_done callback to timestamp when the hardware programming of the last atomic commit is complete. Also an API to pre-program color pipeline in a kind of A/B scheme. It may not be supported by all drivers, but might be useful in different ways.

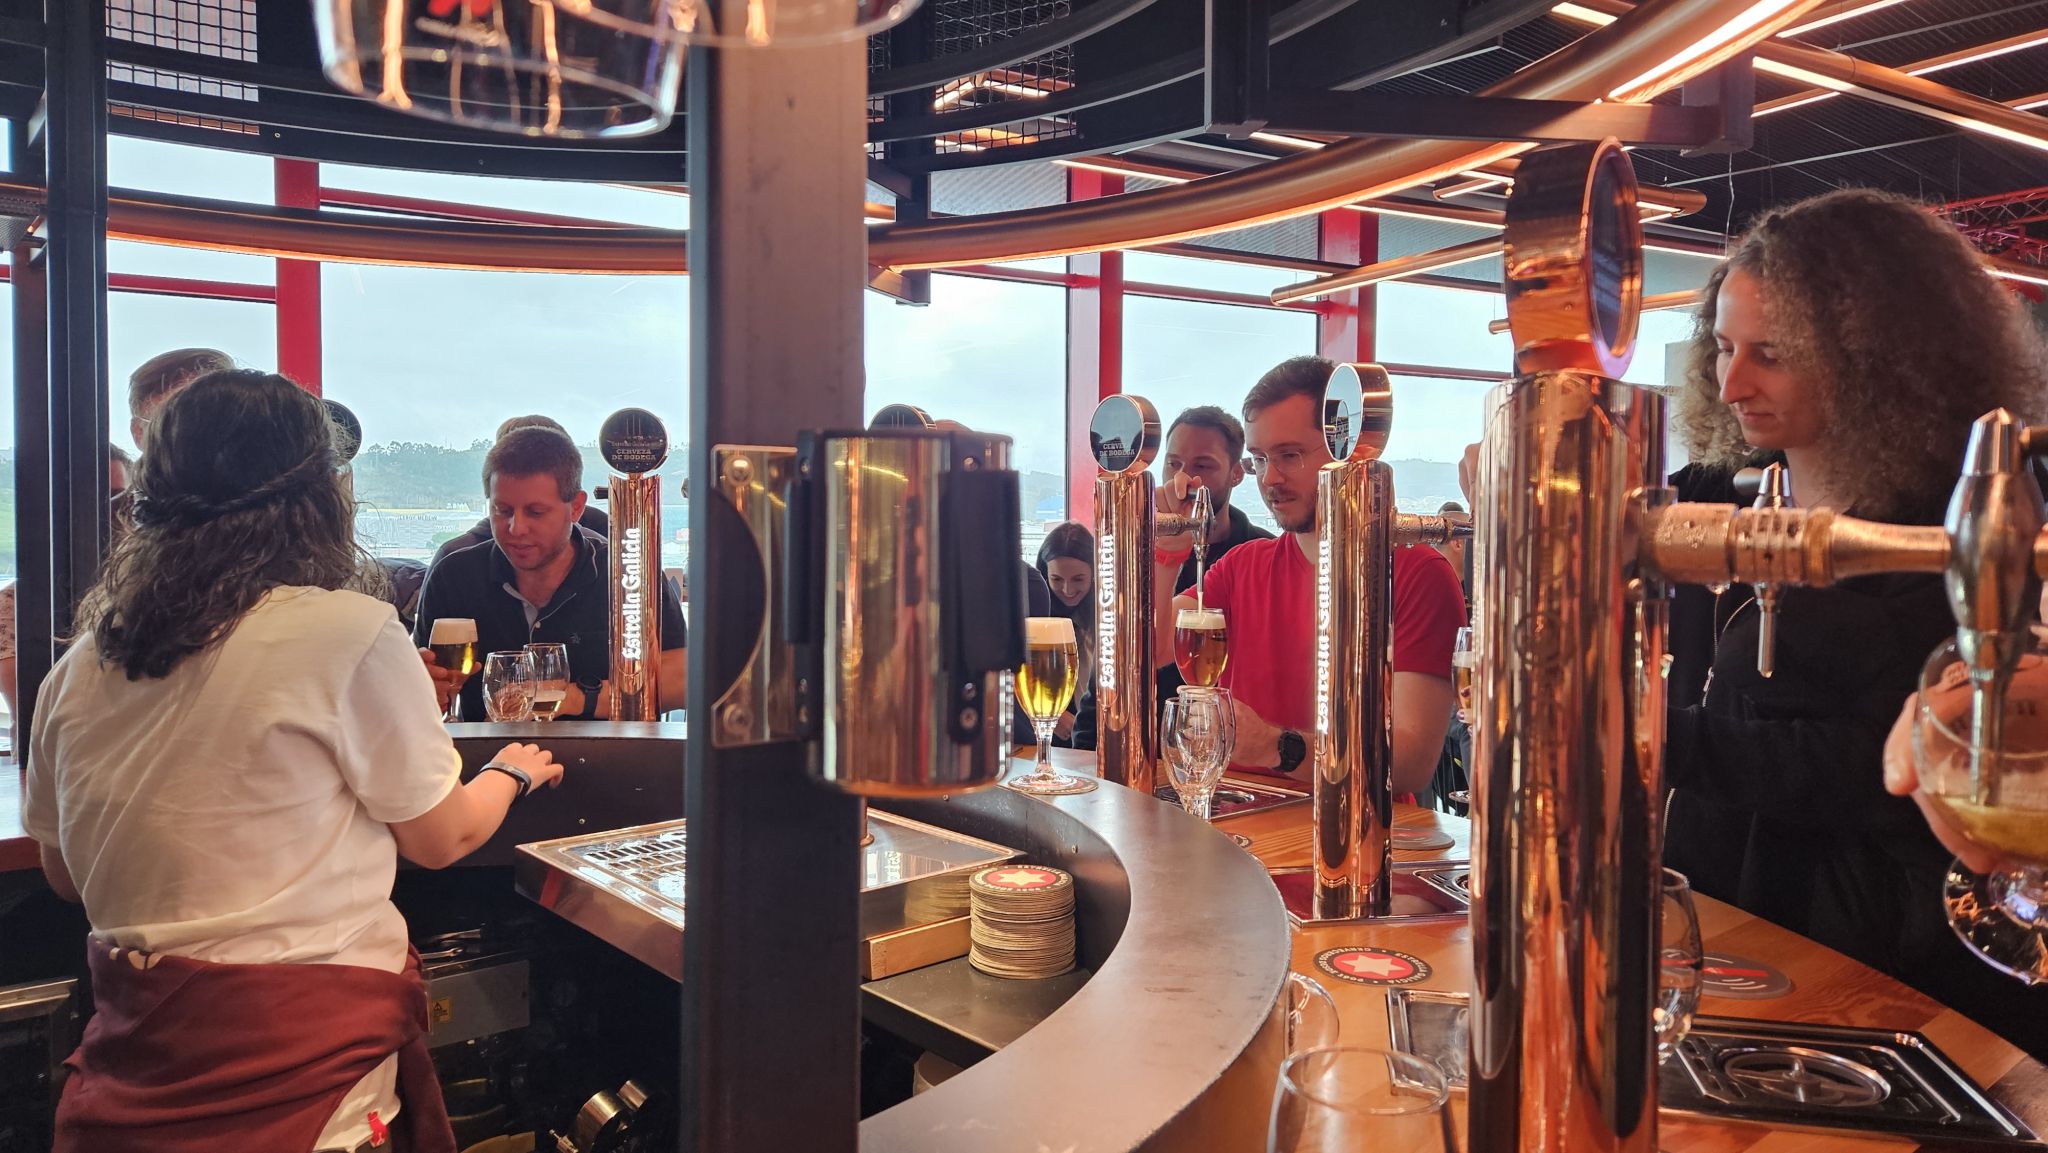
VRR/Frame Limit, Display Mux, Display Control, and more and beer We also had sessions to discuss a new KMS API to mitigate headaches on VRR and Frame Limit as different brightness level at different refresh rates, abrupt changes of refresh rates, low frame rate compensation (LFC) and precise timing in VRR more. On Display Control we discussed features missing in the current KMS interface for HDR mode, atomic backlight settings, source-based tone mapping, etc. We also discussed the need of a place where compositor developers can post TODOs to be developed by KMS people. The Content-adaptive Scaling and Sharpening session focused on sharpening and scaling filters. In the Display Mux session, we discussed proposals to expose the capability of dynamic mux switching display signal between discrete and integrated GPUs. In the last session of the 2024 Display Next Hackfest, participants representing different compositors summarized current and future work and built a Linux Display wish list , which includes: improvements to VTTY and HDR switching, better dmabuf API for multi-GPU support, definition of tone mapping, blending and scaling sematics, and wayland protocols for advertising to clients which colorspaces are supported. We closed this session with a status update on feature development by compositors, including but not limited to: plane offloading (from libcamera to output) / HDR video offloading (dma-heaps) / plane-based scrolling for web pages, color management / HDR / ICC profiles support, addressing issues such as flickering when color primaries don t match, etc. After three days of intensive discussions, all in-person participants went to a guided tour at the Museum of Extrela Galicia beer (MEGA), pouring and tasting the most famous local beer.
Feedback and Future Directions Participants provided valuable feedback on the hackfest, including suggestions for future improvements.
  • Schedule and Break-time Setup: Having a pre-defined agenda and schedule provided a better balance between long discussions and mental refreshments, preventing the fatigue caused by endless discussions.
  • Action Points: Some participants recommended explicitly asking for action points at the end of each session and assigning people to follow-up tasks.
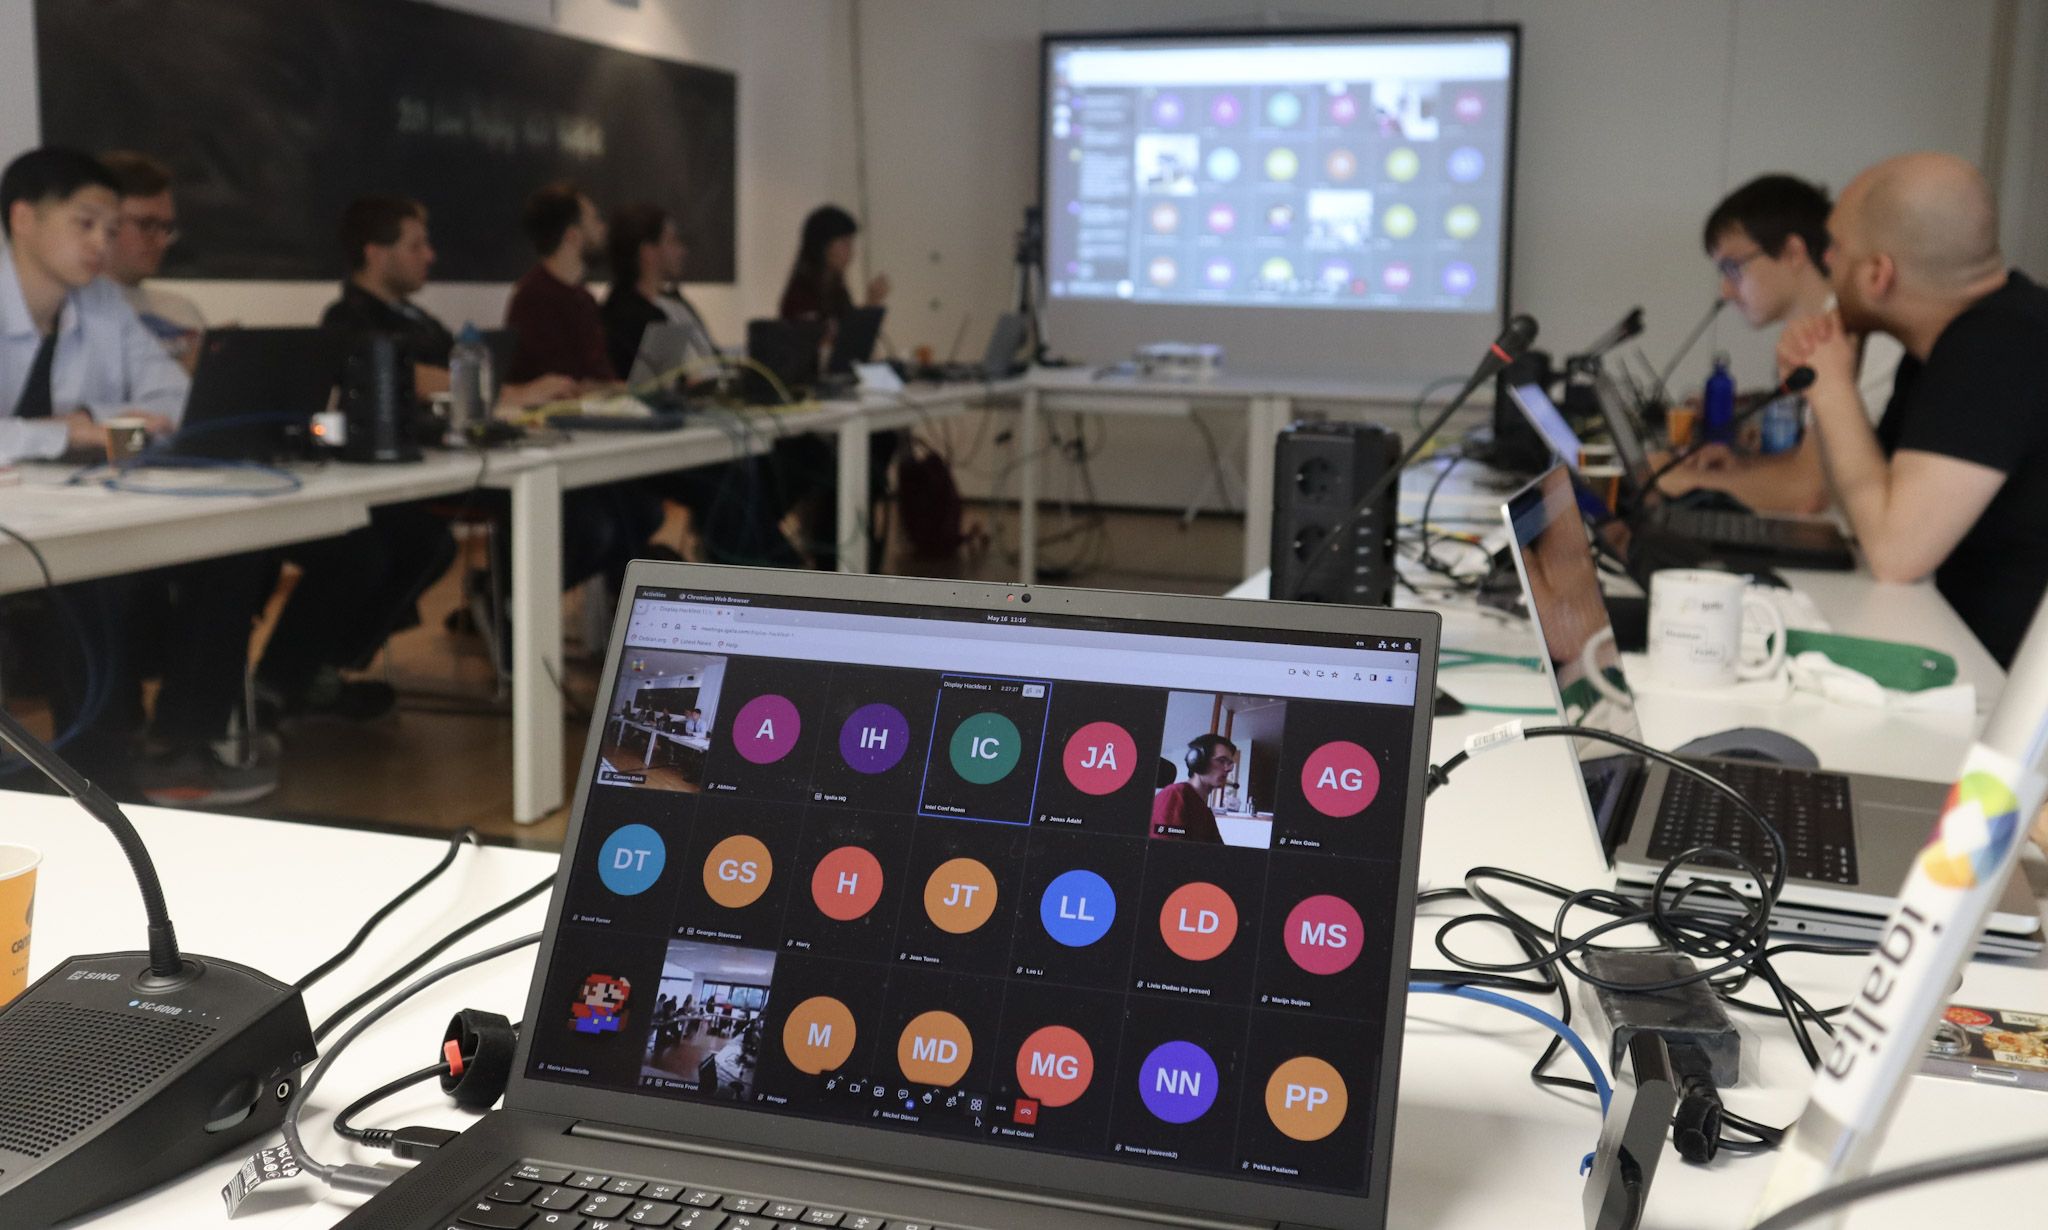
  • Remote Participation: Remote attendees appreciated the inclusive setup and opportunities to actively participate in discussions.
  • Technical Challenges: There were bandwidth and video streaming issues during some sessions due to the large number of participants.
Thank you for joining the 2024 Display Next Hackfest We can t help but thank the 40 participants, who engaged in-person or virtually on relevant discussions, for a collaborative evolution of the Linux display stack and for building an insightful agenda. A big thank you to the leaders and presenters of the nine sessions: Christopher Cameron (Google), Harry Wentland (AMD), Leo Li (AMD), Mario Limoncello (AMD), Sebastian Wick (RedHat) and Xaver Hugl (KDE/BlueSystems) for the effort in preparing the sessions, explaining the topic and guiding discussions. My acknowledge to the others in-person participants that made such an effort to travel to A Coru a: Alex Goins (NVIDIA), David Turner (Raspberry Pi), Georges Stavracas (Igalia), Joan Torres (SUSE), Liviu Dudau (Arm), Louis Chauvet (Bootlin), Robert Mader (Collabora), Tian Mengge (GravityXR), Victor Jaquez (Igalia) and Victoria Brekenfeld (System76). It was and awesome opportunity to meet you and chat face-to-face. Finally, thanks virtual participants who couldn t make it in person but organized their days to actively participate in each discussion, adding different perspectives and valuable inputs even remotely: Abhinav Kumar (Qualcomm), Chaitanya Borah (Intel), Christopher Braga (Qualcomm), Dor Askayo (Red Hat), Jiri Koten (RedHat), Jonas dahl (Red Hat), Leandro Ribeiro (Collabora), Marti Maria (Little CMS), Marijn Suijten, Mario Kleiner, Martin Stransky (Red Hat), Michel D nzer (Red Hat), Miguel Casas-Sanchez (Google), Mitulkumar Golani (Intel), Naveen Kumar (Intel), Niels De Graef (Red Hat), Pekka Paalanen (Collabora), Pichika Uday Kiran (AMD), Shashank Sharma (AMD), Sriharsha PV (AMD), Simon Ser, Uma Shankar (Intel) and Vikas Korjani (AMD). We look forward to another successful Display Next hackfest, continuing to drive innovation and improvement in the Linux display ecosystem!

25 September 2024

Russell Coker: The PiKVM

Hardware I have just setup a PiKVM, here s the Amazon link for the KVM hardware (case and Pi hat etc) and here s an Amazon link for a Pi4 to match. The PiKVM web site has good documentation [1] and they have a YouTube channel with videos showing how to assemble the devices [2]. It s really convenient being able to change the playback speed from low speeds like 1/4 original speed) to double speed when watching such a video. One thing to note is that there are some revisions to the hardware that aren t covered in the videos, the device I received had some improvements that made it easier to assemble which weren t in the video. When you buy the device and Pi you need to also get a SD card of at least 4G in size, a CR1220 battery for real-time clock, and a USB-2/3 to USB-C cable for keyboard/mouse MUST NOT BE USB-C to USB-C! When I first tried using it I used a USB-C to USB-C cable for keyboard and mouse and it didn t work for reasons I don t understand (I welcome comments with theories about this). You also need a micro-HDMI to HDMI cable to get video output if you want to set it up without having to find the IP address and ssh to it. The system has a bright OLED display to show the IP address and some other information which is very handy. The hardware is easy enough for a 12yo to setup. The construction of the parts are solid and well engineered with everything fitting together nicely. It has a PCI/PCIe slot adaptor for controlling power and sending LED status over the connection which I didn t test. I definitely recommend this. Software This is the download link for the RaspberryPi images for the PiKVM [3]. The v3 image matches the hardware from the Amazon link I provided. The default username/password is root/root. Connect it to a HDMI monitor and USB keyboard to change the password etc. If you control the DHCP server you can find the IP address it s using and ssh to it to change the password (it is configured to allow ssh as root with password authentication). If you get the kit to assemble it (as opposed to buying a completed unit already assembled) then you need to run the following commands as root to enable the OLED display. This means that after assembling it you can t get the IP address without plugging in a monitor with a micro-HDMI to HDMI cable or having access to the DHCP server logs.
rw
systemctl enable --now kvmd-oled kvmd-oled-reboot kvmd-oled-shutdown
systemctl enable --now kvmd-fan
ro
The default webadmin username/password is admin/admin. To change the passwords run the following commands:
rw
kvmd-htpasswd set admin
passwd root
ro
It is configured to have the root filesystem mounted read-only which is something I thought had gone out of fashion decades ago. I don t think that modern versions of the Ext3/4 drivers are going to corrupt your filesystem if you have it mounted read-write when you reboot. By default it uses a self-signed SSL certificate so with a Chrome based browser you get an error when you connect where you have to select advanced and then tell it to proceed regardless. I presume you could use the DNS method of Certbot authentication to get a SSL certificate to use on an internal view of your DNS to make it work normally with SSL. The web based software has all the features you expect from a KVM. It shows the screen in any resolution up to 1920*1080 and proxies keyboard and mouse. Strangely lsusb on the machine being managed only reports a single USB device entry for it which covers both keyboard and mouse. Managing Computers For a tower PC disconnect any regular monitor(s) and connect a HDMI port to the HDMI input on the KVM. Connect a regular USB port (not USB-C) to the OTG port on the KVM, then it should all just work. For a laptop connect the HDMI port to the HDMI input on the KVM. Connect a regular USB port (not USB-C) to the OTG port on the KVM. Then boot it up and press Fn-F8 for Dell, Fn-F7 for Lenovo or whatever the vendor code is to switch display output to HDMI during the BIOS initialisation, then Linux will follow the BIOS and send all output to the HDMI port for the early stages of booting. Apparently Lenovo systems have the Fn key mapped in the BIOS so an external keyboard could be used to switch between display outputs, but the PiKVM software doesn t appear to support that. For other systems (probably including the Dell laptops that interest me) the Fn key apparently can t be simulated externally. So for using this to work on laptops in another city I need to have someone local press Fn-F8 at the right time to allow me to change BIOS settings. It is possible to configure the Linux kernel to mirror display to external HDMI and an internal laptop screen. But this doesn t seem useful to me as the use cases for this device don t require that. If you are using it for a server that doesn t have iDRAC/ILO or other management hardware there will be no other monitor and all the output will go through the only connected HDMI device. My main use for it in the near future will be for supporting remote laptops, when Linux has a problem on boot as an easier option than talking someone through Linux commands and for such use it will be a temporary thing and not something that is desired all the time. For the gdm3 login program you can copy the .config/monitors.xml file from a GNOME user session to the gdm home directory to keep the monitor settings. This configuration option is decent for the case where a fixed set of monitors are used but not so great if your requirement is display a login screen on anything that s available . Is there an xdm type program in Debian/Ubuntu that supports this by default or with easy reconfiguration? Conclusion The PiKVM is a well engineered and designed product that does what s expected at a low price. There are lots of minor issues with using it which aren t the fault of the developers but are due to historical decisions in the design of BIOS and Linux software. We need to change the Linux software in question and lobby hardware vendors for BIOS improvements. The feature for connecting to an ATX PSU was unexpected and could be really handy for some people, it s not something I have an immediate use for but is something I could possibly use in future. I like the way they shipped the hardware for it as part of the package giving the user choices about how they use it, many vendors would make it an optional extra that costs another $100. This gives the PiKVM more functionality than many devices that are much more expensive. The web UI wasn t as user friendly as it might have been, but it s a lot better than iDRAC so I don t have a serious complaint about it. It would be nice if there was an option for creating macros for keyboard scancodes so I could try and emulate the Fn options and keys for volume control on systems that support it.

Melissa Wen: Reflections on 2024 Linux Display Next Hackfest

Hey everyone! The 2024 Linux Display Next hackfest concluded in May, and its outcomes continue to shape the Linux Display stack. Igalia hosted this year s event in A Coru a, Spain, bringing together leading experts in the field. Samuel Iglesias and I organized this year s edition and this blog post summarizes the experience and its fruits. One of the highlights of this year s hackfest was the wide range of backgrounds represented by our 40 participants (both on-site and remotely). Developers and experts from various companies and open-source projects came together to advance the Linux Display ecosystem. You can find the list of participants here. The event covered a broad spectrum of topics affecting the development of Linux projects, user experiences, and the future of display technologies on Linux. From cutting-edge topics to long-term discussions, you can check the event agenda here.

Organization Highlights The hackfest was marked by in-depth discussions and knowledge sharing among Linux contributors, making everyone inspired, informed, and connected to the community. Building on feedback from the previous year, we refined the unconference format to enhance participant preparation and engagement. Structured Agenda and Timeboxes: Each session had a defined scope, time limit (1h20 or 2h10), and began with an introductory talk on the topic.
  • Participant-Led Discussions: We pre-selected in-person participants to lead discussions, allowing them to prepare introductions, resources, and scope.
  • Transparent Scheduling: The schedule was shared in advance as GitHub issues, encouraging participants to review and prepare for sessions of interest.
Engaging Sessions: The hackfest featured a variety of topics, including presentations and discussions on how participants were addressing specific subjects within their companies.
  • No Breakout Rooms, No Overlaps: All participants chose to attend all sessions, eliminating the need for separate breakout rooms. We also adapted run-time schedule to keep everybody involved in the same topics.
  • Real-time Updates: We provided notifications and updates through dedicated emails and the event matrix room.
Strengthening Community Connections: The hackfest offered ample opportunities for networking among attendees.
  • Social Events: Igalia sponsored coffee breaks, lunches, and a dinner at a local restaurant.
  • Museum Visit: Participants enjoyed a sponsored visit to the Museum of Estrela Galicia Beer (MEGA).

Fruitful Discussions and Follow-up The structured agenda and breaks allowed us to cover multiple topics during the hackfest. These discussions have led to new display feature development and improvements, as evidenced by patches, merge requests, and implementations in project repositories and mailing lists. With the KMS color management API taking shape, we discussed refinements and best approaches to cover the variety of color pipeline from different hardware-vendors. We are also investigating techniques for a performant SDR<->HDR content reproduction and reducing latency and power consumption when using the color blocks of the hardware.

Color Management/HDR Color Management and HDR continued to be the hottest topic of the hackfest. We had three sessions dedicated to discuss Color and HDR across Linux Display stack layers.

Color/HDR (Kernel-Level) Harry Wentland (AMD) led this session. Here, kernel Developers shared the Color Management pipeline of AMD, Intel and NVidia. We counted with diagrams and explanations from HW-vendors developers that discussed differences, constraints and paths to fit them into the KMS generic color management properties such as advertising modeset needs, IN\_FORMAT, segmented LUTs, interpolation types, etc. Developers from Qualcomm and ARM also added information regarding their hardware. Upstream work related to this session:

Color/HDR (Compositor-Level) Sebastian Wick (RedHat) led this session. It started with Sebastian s presentation covering Wayland color protocols and compositor implementation. Also, an explanation of APIs provided by Wayland and how they can be used to achieve better color management for applications and discussions around ICC profiles and color representation metadata. There was also an intensive Q&A about LittleCMS with Marti Maria. Upstream work related to this session:

Color/HDR (Use Cases and Testing) Christopher Cameron (Google) and Melissa Wen (Igalia) led this session. In contrast to the other sessions, here we focused less on implementation and more on brainstorming and reflections of real-world SDR and HDR transformations (use and validation) and gainmaps. Christopher gave a nice presentation explaining HDR gainmap images and how we should think of HDR. This presentation and Q&A were important to put participants at the same page of how to transition between SDR and HDR and somehow emulating HDR. We also discussed on the usage of a kernel background color property. Finally, we discussed a bit about Chamelium and the future of VKMS (future work and maintainership).

Power Savings vs Color/Latency Mario Limonciello (AMD) led this session. Mario gave an introductory presentation about AMD ABM (adaptive backlight management) that is similar to Intel DPST. After some discussions, we agreed on exposing a kernel property for power saving policy. This work was already merged on kernel and the userspace support is under development. Upstream work related to this session:

Strategy for video and gaming use-cases Leo Li (AMD) led this session. Miguel Casas (Google) started this session with a presentation of Overlays in Chrome/OS Video, explaining the main goal of power saving by switching off GPU for accelerated compositing and the challenges of different colorspace/HDR for video on Linux. Then Leo Li presented different strategies for video and gaming and we discussed the userspace need of more detailed feedback mechanisms to understand failures when offloading. Also, creating a debugFS interface came up as a tool for debugging and analysis.

Real-time scheduling and async KMS API Xaver Hugl (KDE/BlueSystems) led this session. Compositor developers have exposed some issues with doing real-time scheduling and async page flips. One is that the Kernel limits the lifetime of realtime threads and if a modeset takes too long, the thread will be killed and thus the compositor as well. Also, simple page flips take longer than expected and drivers should optimize them. Another issue is the lack of feedback to compositors about hardware programming time and commit deadlines (the lastest possible time to commit). This is difficult to predict from drivers, since it varies greatly with the type of properties. For example, color management updates take much longer. In this regard, we discusssed implementing a hw_done callback to timestamp when the hardware programming of the last atomic commit is complete. Also an API to pre-program color pipeline in a kind of A/B scheme. It may not be supported by all drivers, but might be useful in different ways.

VRR/Frame Limit, Display Mux, Display Control, and more and beer We also had sessions to discuss a new KMS API to mitigate headaches on VRR and Frame Limit as different brightness level at different refresh rates, abrupt changes of refresh rates, low frame rate compensation (LFC) and precise timing in VRR more. On Display Control we discussed features missing in the current KMS interface for HDR mode, atomic backlight settings, source-based tone mapping, etc. We also discussed the need of a place where compositor developers can post TODOs to be developed by KMS people. The Content-adaptive Scaling and Sharpening session focused on sharpening and scaling filters. In the Display Mux session, we discussed proposals to expose the capability of dynamic mux switching display signal between discrete and integrated GPUs. In the last session of the 2024 Display Next Hackfest, participants representing different compositors summarized current and future work and built a Linux Display wish list , which includes: improvements to VTTY and HDR switching, better dmabuf API for multi-GPU support, definition of tone mapping, blending and scaling sematics, and wayland protocols for advertising to clients which colorspaces are supported. We closed this session with a status update on feature development by compositors, including but not limited to: plane offloading (from libcamera to output) / HDR video offloading (dma-heaps) / plane-based scrolling for web pages, color management / HDR / ICC profiles support, addressing issues such as flickering when color primaries don t match, etc. After three days of intensive discussions, all in-person participants went to a guided tour at the Museum of Extrela Galicia beer (MEGA), pouring and tasting the most famous local beer.

Feedback and Future Directions Participants provided valuable feedback on the hackfest, including suggestions for future improvements.
  • Schedule and Break-time Setup: Having a pre-defined agenda and schedule provided a better balance between long discussions and mental refreshments, preventing the fatigue caused by endless discussions.
  • Action Points: Some participants recommended explicitly asking for action points at the end of each session and assigning people to follow-up tasks.
  • Remote Participation: Remote attendees appreciated the inclusive setup and opportunities to actively participate in discussions.
  • Technical Challenges: There were bandwidth and video streaming issues during some sessions due to the large number of participants.

Thank you for joining the 2024 Display Next Hackfest We can t help but thank the 40 participants, who engaged in-person or virtually on relevant discussions, for a collaborative evolution of the Linux display stack and for building an insightful agenda. A big thank you to the leaders and presenters of the nine sessions: Christopher Cameron (Google), Harry Wentland (AMD), Leo Li (AMD), Mario Limoncello (AMD), Sebastian Wick (RedHat) and Xaver Hugl (KDE/BlueSystems) for the effort in preparing the sessions, explaining the topic and guiding discussions. My acknowledge to the others in-person participants that made such an effort to travel to A Coru a: Alex Goins (NVIDIA), David Turner (Raspberry Pi), Georges Stavracas (Igalia), Joan Torres (SUSE), Liviu Dudau (Arm), Louis Chauvet (Bootlin), Robert Mader (Collabora), Tian Mengge (GravityXR), Victor Jaquez (Igalia) and Victoria Brekenfeld (System76). It was and awesome opportunity to meet you and chat face-to-face. Finally, thanks virtual participants who couldn t make it in person but organized their days to actively participate in each discussion, adding different perspectives and valuable inputs even remotely: Abhinav Kumar (Qualcomm), Chaitanya Borah (Intel), Christopher Braga (Qualcomm), Dor Askayo, Jiri Koten (RedHat), Jonas dahl (Red Hat), Leandro Ribeiro (Collabora), Marti Maria (Little CMS), Marijn Suijten, Mario Kleiner, Martin Stransky (Red Hat), Michel D nzer (Red Hat), Miguel Casas-Sanchez (Google), Mitulkumar Golani (Intel), Naveen Kumar (Intel), Niels De Graef (Red Hat), Pekka Paalanen (Collabora), Pichika Uday Kiran (AMD), Shashank Sharma (AMD), Sriharsha PV (AMD), Simon Ser, Uma Shankar (Intel) and Vikas Korjani (AMD). We look forward to another successful Display Next hackfest, continuing to drive innovation and improvement in the Linux display ecosystem!

23 September 2024

Jonathan McDowell: The (lack of a) return-to-office conspiracy

During COVID companies suddenly found themselves able to offer remote working where it hadn t previously been on offer. That s changed over the past 2 or so years, with most places I m aware of moving back from a fully remote situation to either some sort of hybrid, or even full time office attendance. For example last week Amazon announced a full return to office, having already pulled remote-hired workers in for 3 days a week. I ve seen a lot of folk stating they ll never work in an office again, and that RTO is insanity. Despite being lucky enough to work fully remotely (for a role I d been approached about before, but was never prepared to relocate for), I feel the objections from those who are pro-remote often fail to consider the nuances involved. So let s talk about some of the reasons why companies might want to enforce some sort of RTO.

Real estate value Let s clear this one up first. It s not about real estate value, for most companies. City planners and real estate investors might care, but even if your average company owned their building they d close it in an instant all other things being equal. An unoccupied building costs a lot less to maintain. And plenty of companies rent and would save money even if there s a substantial exit fee.

Occupancy levels That said, once you have anyone in the building the equation changes. If you re having to provide power, heating, internet, security/front desk staff etc, you want to make sure you re getting your money s worth. There s no point heating a building that can seat 100 for only 10 people present. One option is to downsize the building, but that leads to not being able to assign everyone a desk, for example. No one I know likes hot desking. There are also scheduling problems about ensuring there are enough desks for everyone who might turn up on a certain day, and you ve ruled out the option of company/office wide events.

Coexistence builds relationships As a remote worker I wish it wasn t true that most people find it easier to form relationships in person, but it is. Some of this can be worked on with specific teambuilding style events, rather than in office working, but I know plenty of folk who hate those as much as they hate the idea of being in the office. I am lucky in that I work with a bunch of folk who are terminally online, so it s much easier to have those casual conversations even being remote, but I also accept I miss out on some things because I m just not in the office regularly enough. You might not care about this ( I just need to put my head down and code, not talk to people ), but don t discount it as a valid reason why companies might want their workers to be in the office. This often matters even more for folk at the start of their career, where having a bunch of experience folk around to help them learn and figure things out ends up working much better in person (my first job offered to let me go mostly remote when I moved to Norwich, but I said no as I knew I wasn t ready for it yet).

Coexistence allows for unexpected interactions People hate the phrase water cooler chat , and I get that, but it covers the idea of casual conversations that just won t happen the same way when people are remote. I experienced this while running Black Cat; every time Simon and I met up in person we had a bunch of useful conversations even though we were on IRC together normally, and had a VoIP setup that meant we regularly talked too. Equally when I was at Nebulon there were conversations I overheard in the office where I was able to correct a misconception or provide extra context. Some of this can be replicated with the right online chat culture, but I ve found many places end up with folk taking conversations to DMs, or they happen in private channels. It happens more naturally in an office environment.

It s easier for bad managers to manage bad performers Again, this falls into the category of things that shouldn t be true, but are. Remote working has increased the ability for people who want to slack off to do so without being easily detected. Ideally what you want is that these folk, if they fail to perform, are then performance managed out of the organisation. That s hard though, there are (rightly) a bunch of rights workers have (I m writing from a UK perspective) around the procedure that needs to be followed. Managers need organisational support in this to make sure they get it right (and folk are given a chance to improve), which is often lacking.

Summary Look, I get there are strong reasons why offering remote is a great thing from the company perspective, but what I ve tried to outline here is that a return-to-office mandate can have some compelling reasons behind it too. Some of those might be things that wouldn t exist in an ideal world, but unfortunately fixing them is a bigger issue than just changing where folk work from. Not acknowledging that just makes any reaction against office work seem ill-informed, to me.

19 September 2024

Vasudev Kamath: Note to Self: Enabling Unified Kernel Image on Debian

Note

These steps may not work on your system if you are using the default Debian installation. This guide assumes that your system is using systemd-boot as the bootloader, which is explained in the post linked below.

A unified kernel image (UKI) is a single executable that can be booted directly from UEFI firmware or automatically sourced by bootloaders with little or no configuration. It combines a UEFI boot stub program like systemd-stub(7), a Linux kernel image, an initrd, and additional resources into a single UEFI PE file. systemd-boot already provides a hook for kernel installation via /etc/kernel/postinst.d/zz-systemd-boot. We just need a couple of additional configurations to generate the UKI image.
Installation and Configuration
  1. Install the systemd-ukify package:

    sudo apt-get install systemd-ukify
    
  2. Create the following configuration in /etc/kernel/install.conf:

    layout=uki
    initrd_generator=dracut
    uki_generator=ukify
    
    This configuration specifies how to generate the UKI image for the installed kernel and which generator to use.
  3. Define the kernel command line for the UKI image. Create /etc/kernel/uki.conf with the following content:

    [UKI]
    Cmdline=@/etc/kernel/cmdline
    
Generating the UKI Image To apply these changes, regenerate the UKI image for the currently running kernel:
sudo dpkg-reconfigure linux-image-$(uname -r)
Verification Use the bootctl list command to verify the presence of a "Type #2" entry for the current kernel. The output should look similar to this:
bootctl list
      type: Boot Loader Specification Type #2 (.efi)
     title: Debian GNU/Linux trixie/sid (2d0080583f1a4127ac0b073b1a9d3e61-6.10.9-amd64.efi) (default) (selected)
        id: 2d0080583f1a4127ac0b073b1a9d3e61-6.10.9-amd64.efi
    source: /boot/efi/EFI/Linux/2d0080583f1a4127ac0b073b1a9d3e61-6.10.9-amd64.efi
  sort-key: debian
     linux: /boot/efi/EFI/Linux/2d0080583f1a4127ac0b073b1a9d3e61-6.10.9-amd64.efi
   options: systemd.gpt_auto=no quiet root=LABEL=root_disk ro systemd.machine_id=2d0080583f1a4127ac0b073b1a9d3e61
      type: Boot Loader Specification Type #2 (.efi)
     title: Debian GNU/Linux trixie/sid (2d0080583f1a4127ac0b073b1a9d3e61-6.10.7-amd64.efi)
        id: 2d0080583f1a4127ac0b073b1a9d3e61-6.10.7-amd64.efi
    source: /boot/efi/EFI/Linux/2d0080583f1a4127ac0b073b1a9d3e61-6.10.7-amd64.efi
  sort-key: debian
     linux: /boot/efi/EFI/Linux/2d0080583f1a4127ac0b073b1a9d3e61-6.10.7-amd64.efi
   options: systemd.gpt_auto=no quiet root=LABEL=root_disk ro systemd.machine_id=2d0080583f1a4127ac0b073b1a9d3e61
      type: Automatic
     title: Reboot Into Firmware Interface
        id: auto-reboot-to-firmware-setup
    source: /sys/firmware/efi/efivars/LoaderEntries-4a67b082-0a4c-41cf-b6c7-440b29bb8c4f
Cleanup and Reboot Once the "Type #2" entries are generated, remove any "Type #1" entries using the bootctl unlink command. After this, reboot your system to boot from the UKI-based image.
Future Considerations The primary use case for a UKI image is secure boot. Signing the UKI image can also be configured in the settings above, but this guide does not cover that process as it requires setting up secure boot on your system.

17 September 2024

Russ Allbery: Review: The Book That Broke the World

Review: The Book That Broke the World, by Mark Lawrence
Series: Library Trilogy #2
Publisher: Ace
Copyright: 2024
ISBN: 0-593-43796-9
Format: Kindle
Pages: 366
The Book That Broke the World is high fantasy and a direct sequel to The Book That Wouldn't Burn. You should not start here. In a delightful break from normal practice, the author provides a useful summary of the previous volume at the start of this book to jog your memory. At the end of The Book That Wouldn't Burn, the characters were scattered and in various states of corporeality after some major revelations about the nature of the Library and the first appearance of the insectile Skeer. The Book That Wouldn't Burn picks up where it left off, and there is a lot more contact with the Skeer, but my guess that they would be the next viewpoint characters does not pan out. Instead, we get a new group and a new protagonist: Celcha, whose sees angels who come to visit her brother. I have complaints, but before I launch into those, I should say that I liked this book apart from the totally unnecessary cannibalism. (I'll get to that.) Livira is a bit sidelined, which is regrettable, but Celcha and her brother are interesting new characters, and both Arpix and Clovis, supporting characters in the first book, get some excellent character development. Similar to the first book, this is a puzzle box story full of world-building tidbits with intellectually-satisfying interactions. Lawrence elaborates and complicates his setting in ways that don't contradict earlier parts of the story but create more room and depth for the characters to be creative. I came away still invested in this world and eager to find out how Lawrence pulls the world-building and narrative threads together. The biggest drawback of this book is that it's not new. My thought after finishing the first book of the series was that if Lawrence had enough world-building ideas to fill three books to that same level of density, this had the potential of being one of my favorite fantasy series of all time. By the end of the second book, I concluded that this is not the case. Instead of showing us new twists and complications the way the first book did throughout, The Book That Broke the World mostly covers the same thematic ground from some new angles. It felt like Lawrence was worried the reader of the first book may not have understood the theme or the world-building, so he spent most of the second book nailing down anything that moved. I found that frustrating. One of the best parts of The Book That Wouldn't Burn was that Lawrence trusted the reader to keep up, which for me hit the glorious but rare sweet spot of pacing where I was figuring out the world at roughly the same pace as the characters. It surprised me in some very enjoyable ways. The Book That Broke the World did not surprise me. There are a few new things, which I enjoyed, and a few elaborations and developments of ideas, which I mostly enjoyed, but I saw the big plot twist coming at least fifty pages before it happened and found the aftermath more annoying than revelatory. It doesn't help that the plot rests on character misunderstandings, one of my least favorite tropes. One of the other disappointments of this book is that the characters stop using the Library as a library. The Library at the center of this series is a truly marvelous piece of world-building with numerous fascinating features that are unrelated to its contents, but Livira used it first and foremost as a repository of books. The first book was full of characters solving problems by finding a relevant book and reading it. In The Book That Broke the World, sadly, this is mostly gone. The Library is mostly reduced to a complicated Big Dumb Object setting. It's still a delightful bit of world-building, and we learn about a few new features, but I only remember two places where the actual books are important to the story. Even the book referenced in the title is mostly important as an artifact with properties unrelated to the words that it contains or to the act of reading it. I think this is a huge lost opportunity and something I hope Lawrence fixes in the last book of the trilogy. This book instead focuses on the politics around the existence of the Library itself. Here I'm cautiously optimistic, although a lot is going to depend on the third book. Lawrence has set up a three-sided argument between groups that I will uncharitably describe as the libertarian techbros, the "burn it all down" reactionaries, and the neoliberal centrist technocrats. All three of those positions suck, and Lawrence had better be setting the stage for Livira to find a different path. Her unwillingness to commit to any of those sides gives me hope, but bringing this plot to a satisfying conclusion is going to be tricky. I hope I like what Lawrence comes up with, but it feels far from certain. It doesn't help that he's started delivering some points with a sledgehammer, and that's where we get to the unnecessary cannibalism. Thankfully this is a fairly small part of the tail end of the book, but it was an unpleasant surprise that I did not want in this novel and that I don't think made the story any better. It's tempting to call the cannibalism gratuitous, but it does fit one of the main themes of this story, namely that humans are depressingly good at using any rule-based object in unexpected and nasty ways that are contrary to the best intentions of the designer. This is the fundamental challenge of the Library as a whole and the question that I suspect the third book will be devoted to addressing, so I understand why Lawrence wanted to emphasize his point. The reason why there is cannibalism here is directly related to a profound misunderstanding of the properties of the library, and I detected an echo of one of C.S. Lewis's arguments in The Last Battle about the nature of Hell. The problem, though, is that this is Satanic baby-killerism, to borrow a term from Fred Clark. There are numerous ways to show this type of perversion of well-intended systems, which I know because Lawrence used other ones in the first book that were more subtle but equally effective. One of the best parts of The Book That Wouldn't Burn is that there were few real villains. The conflict was structural, all sides had valid perspectives, and the ethical points of that story were made with some care and nuance. The problem with cannibalism as it's used here is not merely that it's gross and disgusting and off-putting to the reader, although it is all of those things. If I wanted to read horror, I would read horror novels. I don't appreciate surprise horror used for shock value in regular fantasy. But worse, it's an abandonment of moral nuance. The function of cannibalism in this story is like the function of Satanic baby-killers: it's to signal that these people are wholly and irredeemably evil. They are the Villains, they are Wrong, and they cease to be characters and become symbols of what the protagonists are fighting. This is destructive to the story because it's designed to provoke a visceral short-circuit in the reader and let the author get away with sloppy story-telling. If the author needs to use tactics like this to point out who is the villain, they have failed to set up their moral quandary properly. The worst part is that this was entirely unnecessary because Lawrence's story-telling wasn't sloppy and he set up his moral quandary just fine. No one was confused about the ethical point here. I as the reader was following without difficulty, and had appreciated the subtlety with which Lawrence posed the question. But apparently he thought he was too subtle and decided to come back to the point with a pile-driver. I think that seriously injured the story. The ethical argument here is much more engaging and thought-provoking when it's more finely balanced. That's a lot of complaints, mostly because this is a good book that I badly wanted to be a great book but which kept tripping over its own feet. A lot of trilogies have weak second books. Hopefully this is another example of the mid-story sag, and the finale will be worthy of the start of the story. But I have to admit the moral short-circuiting and the de-emphasis of the actual books in the library has me a bit nervous. I want a lot out of the third book, and I hope I'm not asking this author for too much. If you liked the first book, I think you'll like this one too, with the caveat that it's quite a bit darker and more violent in places, even apart from the surprise cannibalism. But if you've not started this series, you may want to wait for the third book to see if Lawrence can pull off the ending. Followed by The Book That Held Her Heart, currently scheduled for publication in April of 2025. Rating: 7 out of 10

15 September 2024

Russell Coker: Kogan AX1800 Wifi6 Mesh

I previously blogged about the difficulties in getting a good Wifi mesh network setup [1]. I bought the Kogan AX1800 Wifi6 Mesh with 3 nodes for $140, the price has now dropped to $130. It s only Wifi 6 (not 6E which has the extra 6GHz frequency) because all the 6E ones were more expensive than I felt like paying. I ve got it running and it s working really well. One of my laptops has a damaged wire connecting to it s Wifi device which decreased the signal to a degree that I could usually only connect to wifi when in the computer room (and then walk with it to another room once connected). Now I can connect that laptop to wifi in any part of my home. I can now get decent wifi access in my car in front of my home which covers the important corner case of walking to my car and then immediately asking Google maps for directions. Previously my phone would be deciding whether to switch away from wifi due to poor signal and that would delay getting directions, now I get directions quickly on Google Maps. I ve done tests with the Speedtest.net Android app and now get speeds of about 52Mbit/17Mbit in all parts of my home which is limited only by the speed of my NBN connection (one of the many reasons for hating conservatives is giving us expensive slow Internet). As my main reason for buying the devices is for Internet access they have clearly met my reason for purchase and probably meet the requirements for most people as well. Getting that speed is not trivial, my neighbours have lots of Wifi APs and bandwidth is congested. My Kogan 4K Android TV now plays 4K Netflix without pausing even though it only supports 2.4GHz wifi, so having a wifi mesh node next to the TV seems to help it. I did some tests with the Olive Tree FTP server on a Galaxy Note 9 phone running the stock Samsung Android and got over 10MByte (80Mbit) upload and 8Mbyte (64Mbit) download speeds. This might be limited by the Android app or might be limited by the older version of Android. But it still gives higher speeds than my home Internet connection and much higher speeds than I need from an Android device. Running iperf on Linux laptops talking to a Linux workstation that s wired to the main mesh node I get speeds of 27.5Mbit from an old laptop on 2.4GHz wifi, 398Mbit from a new Wifi5 laptop when near the main mesh node, and 91Mbit from the same laptop when at the far end of my home. So not as fast as I d like but still acceptable speeds. The claims about Wifi 6 vs Wifi 5 speeds are that 6 will be about 3* faster. That would be 20% faster than the Gigabit ethernet ports on the wifi nodes. So while 2.5Gbit ethernet on Wifi 6 APs would be a good feature to have it seems that it might provide a 20% benefit at some future time when I have laptops with Wifi 6. At this time all the devices with 2.5Gbit ethernet cost more than I wanted to pay so I m happy with this. It will probably be quite a while before laptops with Wifi 6 are in the price range I feel like paying. For Wifi 6E it seems that anything less than 2.5Gbit ethernet will be a significant bottleneck. But I expect that by the time I buy a Wifi 6E mesh they will all have 2.5Gbit ethernet as standard. The configuration of this device was quite easy via the built in web pages, everything worked pretty much as I expected and I hardly had to look at the manual. The mesh nodes are supposed to connect to each other when you press hardware buttons but that didn t work for me so I used the web admin page to tell them to connect which worked perfectly. The admin of this seemed to be about as good as it gets. Conclusion The performance of this mesh hardware is quite decent. I can t know for sure if it s good or bad because performance really depends on what interference there is. But using this means that for me the Internet connection is now the main bottleneck for all parts of my home and I think it s quite likely that most people in Australia who buy it will find the same result. So for everyone in Australia who doesn t have fiber to their home this seems like an ideal set of mesh hardware. It s cheap, easy to setup, has no cloud stuff to break your configuration, gives quite adequate speed, and generally just does the job.

14 September 2024

Evgeni Golov: Fixing the volume control in an Alesis M1Active 330 USB Speaker System

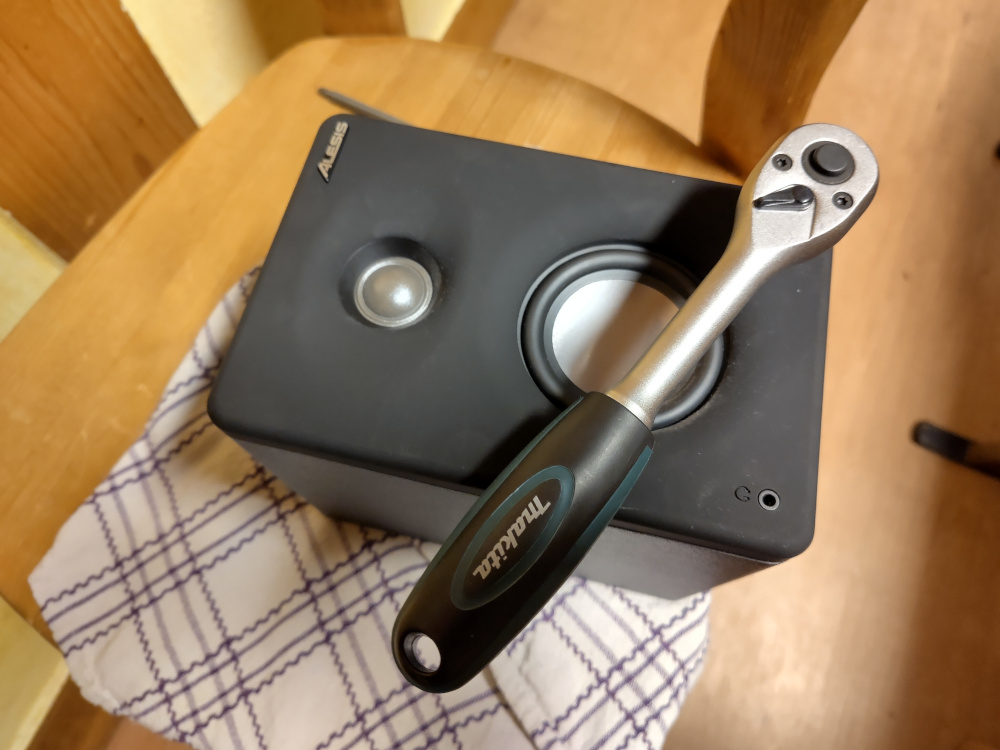
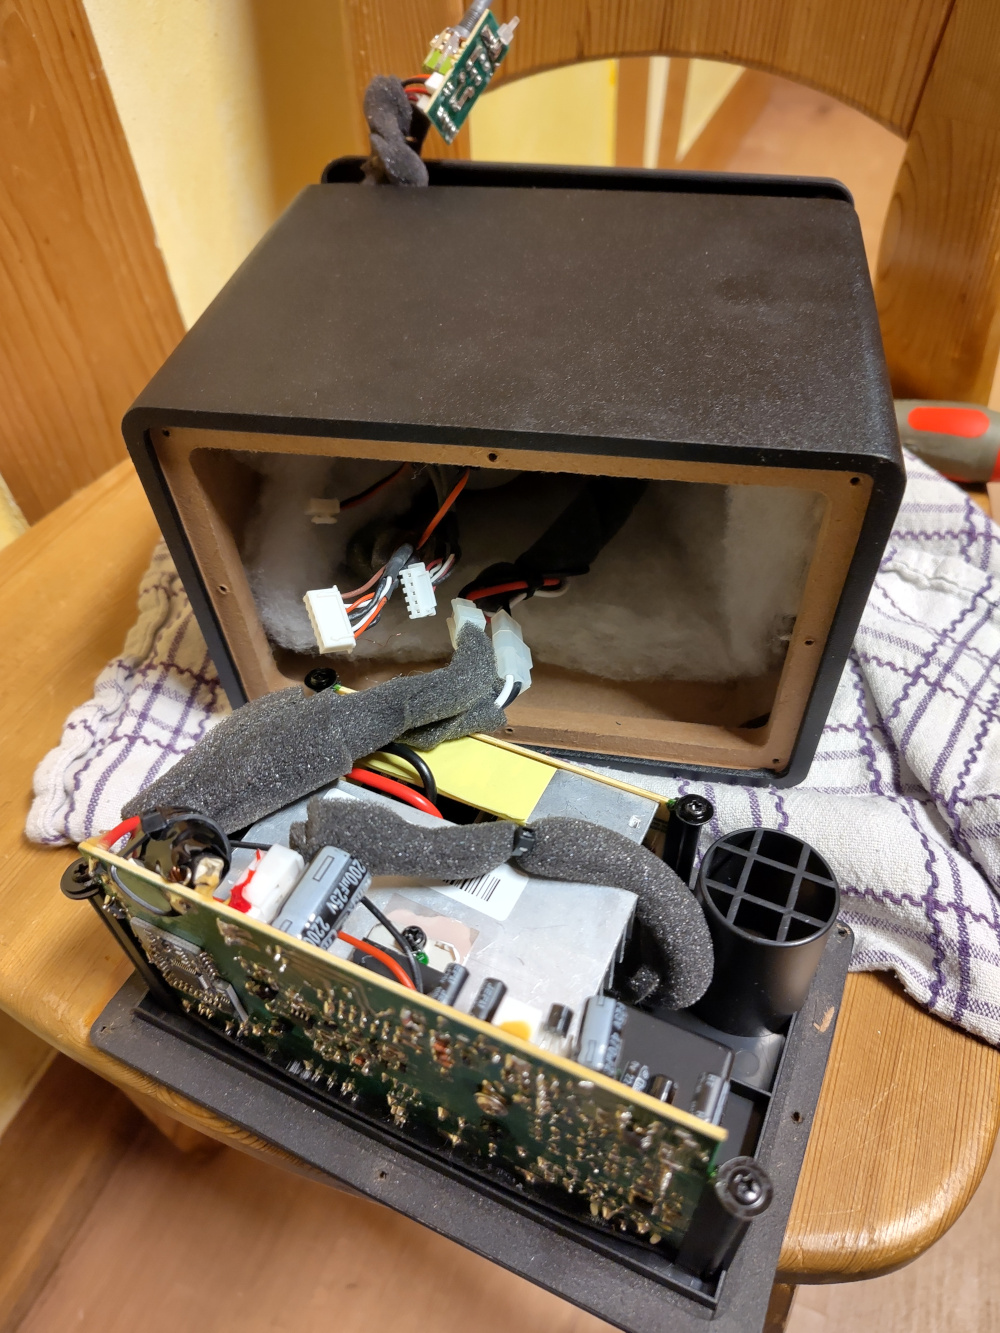
I've a set of Alesis M1Active 330 USB on my desk to listen to music. They were relatively inexpensive (~100 ), have USB and sound pretty good for their size/price. They were also sitting on my desk unused for a while, because the left speaker didn't produce any sound. Well, almost any. If you'd move the volume knob long enough you might have found a position where the left speaker would work a bit, but it'd be quieter than the right one and stop working again after some time. Pretty unacceptable when you want to listen to music. Given the right speaker was working just fine and the left would work a bit when the volume knob is moved, I was quite certain which part was to blame: the potentiometer. So just open the right speaker (it contains all the logic boards, power supply, etc), take out the broken potentiometer, buy a new one, replace, done. Sounds easy? Well, to open the speaker you gotta loosen 8 (!) screws on the back. At least it's not glued, right? Once the screws are removed you can pull out the back plate, which will bring the power supply, USB controller, sound amplifier and cables, lots of cables: two pairs of thick cables, one to each driver, one thin pair for the power switch and two sets of "WTF is this, I am not going to trace pinouts today", one with a 6 pin plug, one with a 5 pin one. Unplug all of these! Yes, they are plugged, nice. Nope, still no friggin' idea how to get to the potentiometer. If you trace the "thin pair" and "WTF1" cables, you see they go inside a small wooden box structure. So we have to pull the thing from the front? Okay, let's remove the plastic part of the knob Right, this looks like a potentiometer. Unscrew it. No, no need for a Makita wrench, I just didn't have anything else in the right size (10mm). right Alesis M1Active 330 USB speaker with a Makita wrench where the volume knob is Still, no movement. Let's look again from the inside! Oh ffs, there are six more screws inside, holding the front. Away with them! Just need a very long PH1 screwdriver. Now you can slowly remove the part of the front where the potentiometer is. Be careful, the top tweeter is mounted to the front, not the main case and so is the headphone jack, without an obvious way to detach it. But you can move away the front far enough to remove the small PCB with the potentiometer and the LED. right Alesis M1Active 330 USB speaker open Great, this was the easy part! The only thing printed on the potentiometer is "A10K". 10K is easy -- 10kOhm. A?! Wikipedia says "A" means "logarithmic", but only if made in the US or Asia. In Europe that'd be "linear". "B" in US/Asia means "linear", in Europe "logarithmic". Do I need to tap the sign again? (The sign is a print of XKCD#927.) My multimeter says in this case it's something like logarithmic. On the right channel anyway, the left one is more like a chopping board. And what's this green box at the end? Oh right, this thing also turns the power on and off. So it's a power switch. Where the fuck do I get a logarithmic 10kOhm stereo potentiometer with a power switch? And then in the exact right size too?! Of course not at any of the big German electronics pharmacies. But AliExpress saves the day, again. It's even the same color! Soldering without pulling out the cable out of the case was a bit challenging, but I've managed it and now have stereo sound again. Yay! PS: Don't operate this thing open to try it out. 230V are dangerous!
12 September 2024

Dirk Eddelbuettel: RcppArmadillo 14.0.2-1 on CRAN: Updates

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1164 other packages on CRAN, downloaded 36.1 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 595 times according to Google Scholar. Conrad released two small incremental releases to version 14.0.0. We did not immediately bring these to CRAN as we have to be mindful of the desired upload cadence of once every one or two months . But as 14.0.2 has been stable for a few weeks, we now decided to bring it to CRAN. Changes since the last CRAN release are summarised below, and overall fairly minimal. On the package side, we reorder what citation() returns, and now follow CRAN requirements via Authors@R.

Changes in RcppArmadillo version 14.0.2-1 (2024-09-11)
  • Upgraded to Armadillo release 14.0.2 (Stochastic Parrot)
    • Optionally use C++20 memory alignment
    • Minor corrections for several corner-cases
  • The order of items displayed by citation() is reversed (Conrad in #449)
  • The DESCRIPTION file now uses an Authors@R field with ORCID IDs

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

11 September 2024

Valhalla's Things: Two Linen Hoods

Posted on September 11, 2024
Tags: madeof:atoms, craft:sewing, FreeSoftWear
A woman wearing a white hood with a deep shoulder covering that ends in a point at about waist height.  The hood is not fitted, has a slight point because of the rectangular construction, and on the torso part one can see the big square gusset that gives it fullness. I ve been influenced again into feeling the need for a garment. It was again a case of multiple sources conspiring in the same direction for unrelated reasons, but I decided I absolutely needed a linen hood, made from the heavy white linen I knew I had in my stash. Why? I don t know. I do like the feeling of wearing a hood, and the white linen should give a decent protection from the sun, but I don t know how often I m going to wear these instead of just a hat. On the other hand the linen was already there and I needed something small to sew. A woman wearing a hood in the same shape, but made in tartan-print flannel.  It looks slightly smaller than the linen one. My first idea was to make a square hood: some time ago I had already made one out of some leftovers of duvet cover, vaguely inspired by the S , because I have a long-term plan of making one a bit more from scratch1. I like the fact that this pattern is completely made out of squares and rectangles, and while the flannel one is quite fitting, as suitable for a warm garment, I felt that by making it just a cm or two wider it would have worked nicely for a warm weather one, and indeed it did. A woman wearing some sort of white veil that covers the head and has two scarf-like appendages, one wrapped around the shoulders and falling on the back, and one falling on the front side, kept in place with one arm. Except, before I even started on the square hood, I started to think that the same square top would also be good for a hood-scarf, one of those long flowy garments that sit on the head, wrap around the neck and fall down, moving with the wind and the movements of the person. Because, let s be honest. worn in a way that look like a veil they feel nice, it s true. But with the help of a couple of pins then you can do this. A woman wearing what looks like a deep hood over some sort of fabric face mask, showing only the eyes, in a way that resembles characters in a video game.  There are again two scarf-like edges that fall on the front and back. And no, I ve never played that game2, and I m not even 100% sure what it is about, other than killing people, climbing buildings and petting cats3, but that s not really an issue when making a bit of casual cosplay of something, right? Anyway, should anybody feel the need to make themselves a hood or ten, the patterns have been released as usual as #FreeSoftWear: square hood and hood scarf.

  1. I m not going to raise the sheep :D I m actually not even going to wash and comb the wool, I ll start from the step just after those :D
  2. because proprietary software, because somewhat underpowered computers and other related reasons that are somewhat incidental to the game itself.
  3. at least two out of three things that make it look like a perfectly enjoyable activity.

10 September 2024

Ben Hutchings: FOSS activity in August 2024

Freexian Collaborators: Debian Contributions: Python 3 patches, OpenSSH GSS-API split, rebootstrap, salsa CI, etc. (by Anupa Ann Joseph)

Debian Contributions: 2024-08 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

Debian Python 3 patch review, by Stefano Rivera Last month, at DebConf, Stefano reviewed the current patch set of Debian s cPython packages with Matthias Klose, the primary maintainer until now. As a result of that review, Stefano re-reviewed the patchset, updating descriptions, etc. A few patches were able to be dropped, and a few others were forwarded upstream. One finds all sorts of skeletons doing reviews like this. One of the patches had been inactive (fortunately, because it was buggy) since the day it was applied, 13 years ago. One is a cleanup that probably only fixes a bug on HPUX, and is a result of copying code from xfree86 into Python 25 years ago. It was fixed in xfree86 a year later. Others support just Debian-specific functionality and probably never seemed worth forwarding. Or good cleanup that only really applies to Debian. A trivial new patch would allow Debian to multiarch co-install Python stable ABI dynamic extensions (like we can with regular dynamic extensions). Performance concerns are stalling it in review, at the moment.

DebConf 24 Organization, by Stefano Rivera Stefano helped organize DebConf 24, which concluded in early August. The event is run by a large entirely volunteer team. The work involved in making this happen is far too varied to describe here. While Freexian provides funding for 20% of collaborator time to spend on Debian-related work, it only covers a small fraction of contributions to time-intensive tasks like this. Since the end of the event, Stefano has been doing some work on the conference finances, and initiated the reimbursement process for travel bursaries.

Archive rebuilds on Debusine, by Stefano Rivera The recent setuptools 73 upload to Debian unstable removed the test subcommand, breaking many packages that were using python3 setup.py test in their Debian packaging. Stefano did a partial archive-rebuild using debusine.debian.net to find the regressions and file bugs. Debusine will be a powerful tool to do QA work like this for Debian in the future, but it doesn t have all the features needed to coordinate rebuild-testing, yet. They are planned to be fleshed out in the next year. In the meantime, Debusine has the building blocks to work through a queue of package building tasks and store the results, it just needs to be driven from outside the system. So, Stefano started working on a set of tools using the Debusine client API to perform archive rebuilds, found and tagged existing bugs, and filed many more.

OpenSSH GSS-API split, by Colin Watson Colin landed the first stage of the planned split of GSS-API authentication and key exchange support in Debian s OpenSSH packaging. In order to allow for smooth upgrades, the second stage will have to wait until after the Debian 13 (trixie) release; but once that s done, as upstream puts it, this substantially reduces the amount of pre-authentication attack surface exposed on your users sshd by default .

OpenSSL vs. cryptography, by Colin Watson Colin facilitated a discussion between Debian s OpenSSL team and the upstream maintainers of Python cryptography about a new incompatibility between Debian s OpenSSL packaging and cryptography s handling of OpenSSL s legacy provider, which was causing a number of build and test failures. While the issue remains open, the Debian OpenSSL maintainers have effectively reverted the change now, so it s no longer a pressing problem.

/usr-move, by Helmut Grohne There are less than 40 source packages left to move files to /usr, so what we re left with is the long tail of the transition. Rather than fix all of them, Helmut started a discussion on removing packages from unstable and filed a first batch. As libvirt is being restructured in experimental, we re handling the fallout in collaboration with its maintainer Andrea Bolognani. Since base-files validates the aliasing symlinks before upgrading, it was discovered that systemd has its own ideas with no solution as of yet. Helmut also proposed that dash checks for ineffective diversions of /bin/sh and that lintian warns about aliased files.

rebootstrap by Helmut Grohne Bootstrapping Debian for a new or existing CPU architecture still is a quite manual process. The rebootstrap project attempts to automate part of the early stage, but it still is very sensitive to changes in unstable. We had a number of fairly intrusive changes this year already. August included a little more fallout from the earlier gcc-for-host work where the C++ include search path would end up being wrong in the generated cross toolchain. A number of packages such as util-linux (twice), libxml2, libcap-ng or systemd had their stage profiles broken. e2fsprogs gained a cycle with libarchive-dev due to having gained support for creating an ext4 filesystem from a tar archive. The restructuring of glib2.0 remains an unsolved problem for now, but libxt and cdebconf should be buildable without glib2.0.

Salsa CI, by Santiago Ruano Rinc n Santiago completed the initial RISC-V support (!523) in the Salsa CI s pipeline. The main work started in July, but it was required to take into account some comments in the review (thanks to Ahmed!) and some final details in [!534]. riscv64 is the most recently supported port in Debian, which will be part of trixie. As its name suggests, the new build-riscv64 job makes it possible to test that a package successfully builds in the riscv64 architecture. The RISC-V runner (salsaci riscv64 runner 01) runs in a couple of machines generously provided by lab.rvperf.org. Debian Developers interested in running this job in their projects should enable the runner (salsaci riscv64 runner 01) in Settings / CI / Runners, and follow the instructions available at https://salsa.debian.org/salsa-ci-team/pipeline/#build-job-on-risc-v. Santiago also took part in discussions about how to optimize the build jobs and reviewed !537 to make the build-source job to only satisfy the Build-Depends and Build-Conflicts fields by Andrea Pappacoda. Thanks a lot to him!

Miscellaneous contributions
  • Stefano submitted patches for BeautifulSoup to support the latest soupsieve and lxml.
  • Stefano uploaded pypy3 7.3.17, upgrading the cPython compatibility from 3.9 to 3.10. Then ran into a GCC-14-related regression, which had to be ignored for now as it s proving hard to fix.
  • Colin released libpipeline 1.5.8 and man-db 2.13.0; the latter included foundations allowing adding an autopkgtest for man-db.
  • Colin upgraded 19 Python packages to new upstream versions (fixing 5 CVEs), fixed several other build failures, fixed a Python 3.12 compatibility issue in zope.security, and made python-nacl build reproducibly.
  • Colin tracked down test failures in python-asyncssh and Ruby resulting from certain odd /etc/hosts configurations.
  • Carles upgraded the packages python-ring-doorbell and simplemonitor to new upstream versions.
  • Carles started discussions and implementation of a tool (still in early days) named po-debconf-manager : a way for translators and reviewers to collaborate using git as a backend instead of mailing list; and submit the translations using salsa MR. More information next month.
  • Carles (dog-fooding po-debconf-manager ) reviewed debconf templates translated by a collaborator.
  • Carles reviewed and submitted the translation of apt .
  • Helmut sent 19 patches for improving cross building.
  • Helmut implemented the cross-exe-wrapper proposed by Simon McVittie for use with glib2.0.
  • Helmut detailed what it takes to make Perl s ExtUtils::PkgConfig suitable for cross building.
  • Helmut made the deletion of the root password work in debvm in all situations and implemented a test case using expect.
  • Anupa attended Debian Publicity team meeting and is moderating and posting on Debian Administrators LinkedIn group.
  • Thorsten uploaded package gutenprint to fix a FTBFS with gcc14 and package ipp-usb to fix a /usr-merge issue.
  • Santiago updated bzip2 to fix a long-standing bug that requested to include a pkg-config file. An important impact of this change is that it makes it possible to use Rust bindings for libbz2 by Sequoia, an implementation of OpenPGP.

9 September 2024

Wouter Verhelst: NBD: Write Zeroes and Rotational

The NBD protocol has grown a number of new features over the years. Unfortunately, some of those features are not (yet?) supported by the Linux kernel. I suggested a few times over the years that the maintainer of the NBD driver in the kernel, Josef Bacik, take a look at these features, but he hasn't done so; presumably he has other priorities. As with anything in the open source world, if you want it done you must do it yourself. I'd been off and on considering to work on the kernel driver so that I could implement these new features, but I never really got anywhere. A few months ago, however, Christoph Hellwig posted a patch set that reworked a number of block device drivers in the Linux kernel to a new type of API. Since the NBD mailinglist is listed in the kernel's MAINTAINERS file, this patch series were crossposted to the NBD mailinglist, too, and when I noticed that it explicitly disabled the "rotational" flag on the NBD device, I suggested to Christoph that perhaps "we" (meaning, "he") might want to vary the decision on whether a device is rotational depending on whether the NBD server signals, through the flag that exists for that very purpose, whether the device is rotational. To which he replied "Can you send a patch". That got me down the rabbit hole, and now, for the first time in the 20+ years of being a C programmer who uses Linux exclusively, I got a patch merged into the Linux kernel... twice. So, what do these things do? The first patch adds support for the ROTATIONAL flag. If the NBD server mentions that the device is rotational, it will be treated as such, and the elevator algorithm will be used to optimize accesses to the device. For the reference implementation, you can do this by adding a line "rotational = true" to the relevant section (relating to the export where you want it to be used) of the config file. It's unlikely that this will be of much benefit in most cases (most nbd-server installations will be exporting a file on a filesystem and have the elevator algorithm implemented server side and then it doesn't matter whether the device has the rotational flag set), but it's there in case you wish to use it. The second set of patches adds support for the WRITE_ZEROES command. Most devices these days allow you to tell them "please write a N zeroes starting at this offset", which is a lot more efficient than sending over a buffer of N zeroes and asking the device to do DMA to copy buffers etc etc for just zeroes. The NBD protocol has supported its own WRITE_ZEROES command for a while now, and hooking it up was reasonably simple in the end. The only problem is that it expects length values in bytes, whereas the kernel uses it in blocks. It took me a few tries to get that right -- and then I also fixed up handling of discard messages, which required the same conversion.

8 September 2024

Thorsten Alteholz: My Debian Activities in August 2024

FTP master This month I accepted 441 and rejected 15 packages. The overall number of packages that got accepted was 442. I am ashamed of some occurrences that happened this month and I apologize for this. Unfortunately I have no idea how to prevent this in the future without becoming a solo entertainer. Debian LTS This was my hundred-twenty-second month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian. Unfortunately Bullseye was not handed over to LTS in August. So I only prepared new packages of asterisk, libvirt and tinyproxy and will upload them next month. Last but not least I did a week of FD this month. Debian ELTS This month was the seventy-third ELTS month. During my allocated time I uploaded or worked on: I also did a week of FD. Debian Printing This month I uploaded This work is generously funded by Freexian! Debian Astro This month I uploaded a new upstream or bugfix version of: Debian Mobcom The following packages have been prepared by the GSoC student Nathan: It was so much fun working with Nathan. Unfortunately GSoC is over now, but Nathan will continue working in Debian and become a Debian Maintainer. misc This month I uploaded new upstream or bugfix versions of: I also filed an RM bug against meep-openmpi. As Adrian made me ware, this package is no longer needed.

Jacob Adams: Linux's Bedtime Routine

How does Linux move from an awake machine to a hibernating one? How does it then manage to restore all state? These questions led me to read way too much C in trying to figure out how this particular hardware/software boundary is navigated. This investigation will be split into a few parts, with the first one going from invocation of hibernation to synchronizing all filesystems to disk. This article has been written using Linux version 6.9.9, the source of which can be found in many places, but can be navigated easily through the Bootlin Elixir Cross-Referencer: https://elixir.bootlin.com/linux/v6.9.9/source Each code snippet will begin with a link to the above giving the file path and the line number of the beginning of the snippet.

A Starting Point for Investigation: /sys/power/state and /sys/power/disk These two system files exist to allow debugging of hibernation, and thus control the exact state used directly. Writing specific values to the state file controls the exact sleep mode used and disk controls the specific hibernation mode1. This is extremely handy as an entry point to understand how these systems work, since we can just follow what happens when they are written to.

Show and Store Functions These two files are defined using the power_attr macro: kernel/power/power.h:80
#define power_attr(_name) \
static struct kobj_attribute _name##_attr =     \
    .attr   =               \
        .name = __stringify(_name), \
        .mode = 0644,           \
     ,                  \
    .show   = _name##_show,         \
    .store  = _name##_store,        \
 
show is called on reads and store on writes. state_show is a little boring for our purposes, as it just prints all the available sleep states. kernel/power/main.c:657
/*
 * state - control system sleep states.
 *
 * show() returns available sleep state labels, which may be "mem", "standby",
 * "freeze" and "disk" (hibernation).
 * See Documentation/admin-guide/pm/sleep-states.rst for a description of
 * what they mean.
 *
 * store() accepts one of those strings, translates it into the proper
 * enumerated value, and initiates a suspend transition.
 */
static ssize_t state_show(struct kobject *kobj, struct kobj_attribute *attr,
			  char *buf)
 
	char *s = buf;
#ifdef CONFIG_SUSPEND
	suspend_state_t i;
	for (i = PM_SUSPEND_MIN; i < PM_SUSPEND_MAX; i++)
		if (pm_states[i])
			s += sprintf(s,"%s ", pm_states[i]);
#endif
	if (hibernation_available())
		s += sprintf(s, "disk ");
	if (s != buf)
		/* convert the last space to a newline */
		*(s-1) = '\n';
	return (s - buf);
 
state_store, however, provides our entry point. If the string disk is written to the state file, it calls hibernate(). This is our entry point. kernel/power/main.c:715
static ssize_t state_store(struct kobject *kobj, struct kobj_attribute *attr,
			   const char *buf, size_t n)
 
	suspend_state_t state;
	int error;
	error = pm_autosleep_lock();
	if (error)
		return error;
	if (pm_autosleep_state() > PM_SUSPEND_ON)  
		error = -EBUSY;
		goto out;
	 
	state = decode_state(buf, n);
	if (state < PM_SUSPEND_MAX)  
		if (state == PM_SUSPEND_MEM)
			state = mem_sleep_current;
		error = pm_suspend(state);
	  else if (state == PM_SUSPEND_MAX)  
		error = hibernate();
	  else  
		error = -EINVAL;
	 
 out:
	pm_autosleep_unlock();
	return error ? error : n;
 
kernel/power/main.c:688
static suspend_state_t decode_state(const char *buf, size_t n)
 
#ifdef CONFIG_SUSPEND
	suspend_state_t state;
#endif
	char *p;
	int len;
	p = memchr(buf, '\n', n);
	len = p ? p - buf : n;
	/* Check hibernation first. */
	if (len == 4 && str_has_prefix(buf, "disk"))
		return PM_SUSPEND_MAX;
#ifdef CONFIG_SUSPEND
	for (state = PM_SUSPEND_MIN; state < PM_SUSPEND_MAX; state++)  
		const char *label = pm_states[state];
		if (label && len == strlen(label) && !strncmp(buf, label, len))
			return state;
	 
#endif
	return PM_SUSPEND_ON;
 
Could we have figured this out just via function names? Sure, but this way we know for sure that nothing else is happening before this function is called.

Autosleep Our first detour is into the autosleep system. When checking the state above, you may notice that the kernel grabs the pm_autosleep_lock before checking the current state. autosleep is a mechanism originally from Android that sends the entire system to either suspend or hibernate whenever it is not actively working on anything. This is not enabled for most desktop configurations, since it s primarily for mobile systems and inverts the standard suspend and hibernate interactions. This system is implemented as a workqueue2 that checks the current number of wakeup events, processes and drivers that need to run3, and if there aren t any, then the system is put into the autosleep state, typically suspend. However, it could be hibernate if configured that way via /sys/power/autosleep in a similar manner to using /sys/power/state to manually enable hibernation. kernel/power/main.c:841
static ssize_t autosleep_store(struct kobject *kobj,
			       struct kobj_attribute *attr,
			       const char *buf, size_t n)
 
	suspend_state_t state = decode_state(buf, n);
	int error;
	if (state == PM_SUSPEND_ON
	    && strcmp(buf, "off") && strcmp(buf, "off\n"))
		return -EINVAL;
	if (state == PM_SUSPEND_MEM)
		state = mem_sleep_current;
	error = pm_autosleep_set_state(state);
	return error ? error : n;
 
power_attr(autosleep);
#endif /* CONFIG_PM_AUTOSLEEP */
kernel/power/autosleep.c:24
static DEFINE_MUTEX(autosleep_lock);
static struct wakeup_source *autosleep_ws;
static void try_to_suspend(struct work_struct *work)
 
	unsigned int initial_count, final_count;
	if (!pm_get_wakeup_count(&initial_count, true))
		goto out;
	mutex_lock(&autosleep_lock);
	if (!pm_save_wakeup_count(initial_count)  
		system_state != SYSTEM_RUNNING)  
		mutex_unlock(&autosleep_lock);
		goto out;
	 
	if (autosleep_state == PM_SUSPEND_ON)  
		mutex_unlock(&autosleep_lock);
		return;
	 
	if (autosleep_state >= PM_SUSPEND_MAX)
		hibernate();
	else
		pm_suspend(autosleep_state);
	mutex_unlock(&autosleep_lock);
	if (!pm_get_wakeup_count(&final_count, false))
		goto out;
	/*
	 * If the wakeup occurred for an unknown reason, wait to prevent the
	 * system from trying to suspend and waking up in a tight loop.
	 */
	if (final_count == initial_count)
		schedule_timeout_uninterruptible(HZ / 2);
 out:
	queue_up_suspend_work();
 
static DECLARE_WORK(suspend_work, try_to_suspend);
void queue_up_suspend_work(void)
 
	if (autosleep_state > PM_SUSPEND_ON)
		queue_work(autosleep_wq, &suspend_work);
 

The Steps of Hibernation

Hibernation Kernel Config It s important to note that most of the hibernate-specific functions below do nothing unless you ve defined CONFIG_HIBERNATION in your Kconfig4. As an example, hibernate itself is defined as the following if CONFIG_HIBERNATE is not set. include/linux/suspend.h:407
static inline int hibernate(void)   return -ENOSYS;  

Check if Hibernation is Available We begin by confirming that we actually can perform hibernation, via the hibernation_available function. kernel/power/hibernate.c:742
if (!hibernation_available())  
	pm_pr_dbg("Hibernation not available.\n");
	return -EPERM;
 
kernel/power/hibernate.c:92
bool hibernation_available(void)
 
	return nohibernate == 0 &&
		!security_locked_down(LOCKDOWN_HIBERNATION) &&
		!secretmem_active() && !cxl_mem_active();
 
nohibernate is controlled by the kernel command line, it s set via either nohibernate or hibernate=no. security_locked_down is a hook for Linux Security Modules to prevent hibernation. This is used to prevent hibernating to an unencrypted storage device, as specified in the manual page kernel_lockdown(7). Interestingly, either level of lockdown, integrity or confidentiality, locks down hibernation because with the ability to hibernate you can extract bascially anything from memory and even reboot into a modified kernel image. secretmem_active checks whether there is any active use of memfd_secret, and if so it prevents hibernation. memfd_secret returns a file descriptor that can be mapped into a process but is specifically unmapped from the kernel s memory space. Hibernating with memory that not even the kernel is supposed to access would expose that memory to whoever could access the hibernation image. This particular feature of secret memory was apparently controversial, though not as controversial as performance concerns around fragmentation when unmapping kernel memory (which did not end up being a real problem). cxl_mem_active just checks whether any CXL memory is active. A full explanation is provided in the commit introducing this check but there s also a shortened explanation from cxl_mem_probe that sets the relevant flag when initializing a CXL memory device. drivers/cxl/mem.c:186
* The kernel may be operating out of CXL memory on this device,
* there is no spec defined way to determine whether this device
* preserves contents over suspend, and there is no simple way
* to arrange for the suspend image to avoid CXL memory which
* would setup a circular dependency between PCI resume and save
* state restoration.

Check Compression The next check is for whether compression support is enabled, and if so whether the requested algorithm is enabled. kernel/power/hibernate.c:747
/*
 * Query for the compression algorithm support if compression is enabled.
 */
if (!nocompress)  
	strscpy(hib_comp_algo, hibernate_compressor, sizeof(hib_comp_algo));
	if (crypto_has_comp(hib_comp_algo, 0, 0) != 1)  
		pr_err("%s compression is not available\n", hib_comp_algo);
		return -EOPNOTSUPP;
	 
 
The nocompress flag is set via the hibernate command line parameter, setting hibernate=nocompress. If compression is enabled, then hibernate_compressor is copied to hib_comp_algo. This synchronizes the current requested compression setting (hibernate_compressor) with the current compression setting (hib_comp_algo). Both values are character arrays of size CRYPTO_MAX_ALG_NAME (128 in this kernel). kernel/power/hibernate.c:50
static char hibernate_compressor[CRYPTO_MAX_ALG_NAME] = CONFIG_HIBERNATION_DEF_COMP;
/*
 * Compression/decompression algorithm to be used while saving/loading
 * image to/from disk. This would later be used in 'kernel/power/swap.c'
 * to allocate comp streams.
 */
char hib_comp_algo[CRYPTO_MAX_ALG_NAME];
hibernate_compressor defaults to lzo if that algorithm is enabled, otherwise to lz4 if enabled5. It can be overwritten using the hibernate.compressor setting to either lzo or lz4. kernel/power/Kconfig:95
choice
	prompt "Default compressor"
	default HIBERNATION_COMP_LZO
	depends on HIBERNATION
config HIBERNATION_COMP_LZO
	bool "lzo"
	depends on CRYPTO_LZO
config HIBERNATION_COMP_LZ4
	bool "lz4"
	depends on CRYPTO_LZ4
endchoice
config HIBERNATION_DEF_COMP
	string
	default "lzo" if HIBERNATION_COMP_LZO
	default "lz4" if HIBERNATION_COMP_LZ4
	help
	  Default compressor to be used for hibernation.
kernel/power/hibernate.c:1425
static const char * const comp_alg_enabled[] =  
#if IS_ENABLED(CONFIG_CRYPTO_LZO)
	COMPRESSION_ALGO_LZO,
#endif
#if IS_ENABLED(CONFIG_CRYPTO_LZ4)
	COMPRESSION_ALGO_LZ4,
#endif
 ;
static int hibernate_compressor_param_set(const char *compressor,
		const struct kernel_param *kp)
 
	unsigned int sleep_flags;
	int index, ret;
	sleep_flags = lock_system_sleep();
	index = sysfs_match_string(comp_alg_enabled, compressor);
	if (index >= 0)  
		ret = param_set_copystring(comp_alg_enabled[index], kp);
		if (!ret)
			strscpy(hib_comp_algo, comp_alg_enabled[index],
				sizeof(hib_comp_algo));
	  else  
		ret = index;
	 
	unlock_system_sleep(sleep_flags);
	if (ret)
		pr_debug("Cannot set specified compressor %s\n",
			 compressor);
	return ret;
 
static const struct kernel_param_ops hibernate_compressor_param_ops =  
	.set    = hibernate_compressor_param_set,
	.get    = param_get_string,
 ;
static struct kparam_string hibernate_compressor_param_string =  
	.maxlen = sizeof(hibernate_compressor),
	.string = hibernate_compressor,
 ;
We then check whether the requested algorithm is supported via crypto_has_comp. If not, we bail out of the whole operation with EOPNOTSUPP. As part of crypto_has_comp we perform any needed initialization of the algorithm, loading kernel modules and running initialization code as needed6.

Grab Locks The next step is to grab the sleep and hibernation locks via lock_system_sleep and hibernate_acquire. kernel/power/hibernate.c:758
sleep_flags = lock_system_sleep();
/* The snapshot device should not be opened while we're running */
if (!hibernate_acquire())  
	error = -EBUSY;
	goto Unlock;
 
First, lock_system_sleep marks the current thread as not freezable, which will be important later7. It then grabs the system_transistion_mutex, which locks taking snapshots or modifying how they are taken, resuming from a hibernation image, entering any suspend state, or rebooting.

The GFP Mask The kernel also issues a warning if the gfp mask is changed via either pm_restore_gfp_mask or pm_restrict_gfp_mask without holding the system_transistion_mutex. GFP flags tell the kernel how it is permitted to handle a request for memory. include/linux/gfp_types.h:12
 * GFP flags are commonly used throughout Linux to indicate how memory
 * should be allocated.  The GFP acronym stands for get_free_pages(),
 * the underlying memory allocation function.  Not every GFP flag is
 * supported by every function which may allocate memory.
In the case of hibernation specifically we care about the IO and FS flags, which are reclaim operators, ways the system is permitted to attempt to free up memory in order to satisfy a specific request for memory. include/linux/gfp_types.h:176
 * Reclaim modifiers
 * -----------------
 * Please note that all the following flags are only applicable to sleepable
 * allocations (e.g. %GFP_NOWAIT and %GFP_ATOMIC will ignore them).
 *
 * %__GFP_IO can start physical IO.
 *
 * %__GFP_FS can call down to the low-level FS. Clearing the flag avoids the
 * allocator recursing into the filesystem which might already be holding
 * locks.
gfp_allowed_mask sets which flags are permitted to be set at the current time. As the comment below outlines, preventing these flags from being set avoids situations where the kernel needs to do I/O to allocate memory (e.g. read/writing swap8) but the devices it needs to read/write to/from are not currently available. kernel/power/main.c:24
/*
 * The following functions are used by the suspend/hibernate code to temporarily
 * change gfp_allowed_mask in order to avoid using I/O during memory allocations
 * while devices are suspended.  To avoid races with the suspend/hibernate code,
 * they should always be called with system_transition_mutex held
 * (gfp_allowed_mask also should only be modified with system_transition_mutex
 * held, unless the suspend/hibernate code is guaranteed not to run in parallel
 * with that modification).
 */
static gfp_t saved_gfp_mask;
void pm_restore_gfp_mask(void)
 
	WARN_ON(!mutex_is_locked(&system_transition_mutex));
	if (saved_gfp_mask)  
		gfp_allowed_mask = saved_gfp_mask;
		saved_gfp_mask = 0;
	 
 
void pm_restrict_gfp_mask(void)
 
	WARN_ON(!mutex_is_locked(&system_transition_mutex));
	WARN_ON(saved_gfp_mask);
	saved_gfp_mask = gfp_allowed_mask;
	gfp_allowed_mask &= ~(__GFP_IO   __GFP_FS);
 

Sleep Flags After grabbing the system_transition_mutex the kernel then returns and captures the previous state of the threads flags in sleep_flags. This is used later to remove PF_NOFREEZE if it wasn t previously set on the current thread. kernel/power/main.c:52
unsigned int lock_system_sleep(void)
 
	unsigned int flags = current->flags;
	current->flags  = PF_NOFREEZE;
	mutex_lock(&system_transition_mutex);
	return flags;
 
EXPORT_SYMBOL_GPL(lock_system_sleep);
include/linux/sched.h:1633
#define PF_NOFREEZE		0x00008000	/* This thread should not be frozen */
Then we grab the hibernate-specific semaphore to ensure no one can open a snapshot or resume from it while we perform hibernation. Additionally this lock is used to prevent hibernate_quiet_exec, which is used by the nvdimm driver to active its firmware with all processes and devices frozen, ensuring it is the only thing running at that time9. kernel/power/hibernate.c:82
bool hibernate_acquire(void)
 
	return atomic_add_unless(&hibernate_atomic, -1, 0);
 

Prepare Console The kernel next calls pm_prepare_console. This function only does anything if CONFIG_VT_CONSOLE_SLEEP has been set. This prepares the virtual terminal for a suspend state, switching away to a console used only for the suspend state if needed. kernel/power/console.c:130
void pm_prepare_console(void)
 
	if (!pm_vt_switch())
		return;
	orig_fgconsole = vt_move_to_console(SUSPEND_CONSOLE, 1);
	if (orig_fgconsole < 0)
		return;
	orig_kmsg = vt_kmsg_redirect(SUSPEND_CONSOLE);
	return;
 
The first thing is to check whether we actually need to switch the VT kernel/power/console.c:94
/*
 * There are three cases when a VT switch on suspend/resume are required:
 *   1) no driver has indicated a requirement one way or another, so preserve
 *      the old behavior
 *   2) console suspend is disabled, we want to see debug messages across
 *      suspend/resume
 *   3) any registered driver indicates it needs a VT switch
 *
 * If none of these conditions is present, meaning we have at least one driver
 * that doesn't need the switch, and none that do, we can avoid it to make
 * resume look a little prettier (and suspend too, but that's usually hidden,
 * e.g. when closing the lid on a laptop).
 */
static bool pm_vt_switch(void)
 
	struct pm_vt_switch *entry;
	bool ret = true;
	mutex_lock(&vt_switch_mutex);
	if (list_empty(&pm_vt_switch_list))
		goto out;
	if (!console_suspend_enabled)
		goto out;
	list_for_each_entry(entry, &pm_vt_switch_list, head)  
		if (entry->required)
			goto out;
	 
	ret = false;
out:
	mutex_unlock(&vt_switch_mutex);
	return ret;
 
There is an explanation of the conditions under which a switch is performed in the comment above the function, but we ll also walk through the steps here. Firstly we grab the vt_switch_mutex to ensure nothing will modify the list while we re looking at it. We then examine the pm_vt_switch_list. This list is used to indicate the drivers that require a switch during suspend. They register this requirement, or the lack thereof, via pm_vt_switch_required. kernel/power/console.c:31
/**
 * pm_vt_switch_required - indicate VT switch at suspend requirements
 * @dev: device
 * @required: if true, caller needs VT switch at suspend/resume time
 *
 * The different console drivers may or may not require VT switches across
 * suspend/resume, depending on how they handle restoring video state and
 * what may be running.
 *
 * Drivers can indicate support for switchless suspend/resume, which can
 * save time and flicker, by using this routine and passing 'false' as
 * the argument.  If any loaded driver needs VT switching, or the
 * no_console_suspend argument has been passed on the command line, VT
 * switches will occur.
 */
void pm_vt_switch_required(struct device *dev, bool required)
Next, we check console_suspend_enabled. This is set to false by the kernel parameter no_console_suspend, but defaults to true. Finally, if there are any entries in the pm_vt_switch_list, then we check to see if any of them require a VT switch. Only if none of these conditions apply, then we return false. If a VT switch is in fact required, then we move first the currently active virtual terminal/console10 (vt_move_to_console) and then the current location of kernel messages (vt_kmsg_redirect) to the SUSPEND_CONSOLE. The SUSPEND_CONSOLE is the last entry in the list of possible consoles, and appears to just be a black hole to throw away messages. kernel/power/console.c:16
#define SUSPEND_CONSOLE	(MAX_NR_CONSOLES-1)
Interestingly, these are separate functions because you can use TIOCL_SETKMSGREDIRECT (an ioctl11) to send kernel messages to a specific virtual terminal, but by default its the same as the currently active console. The locations of the previously active console and the previous kernel messages location are stored in orig_fgconsole and orig_kmsg, to restore the state of the console and kernel messages after the machine wakes up again. Interestingly, this means orig_fgconsole also ends up storing any errors, so has to be checked to ensure it s not less than zero before we try to do anything with the kernel messages on both suspend and resume. drivers/tty/vt/vt_ioctl.c:1268
/* Perform a kernel triggered VT switch for suspend/resume */
static int disable_vt_switch;
int vt_move_to_console(unsigned int vt, int alloc)
 
	int prev;
	console_lock();
	/* Graphics mode - up to X */
	if (disable_vt_switch)  
		console_unlock();
		return 0;
	 
	prev = fg_console;
	if (alloc && vc_allocate(vt))  
		/* we can't have a free VC for now. Too bad,
		 * we don't want to mess the screen for now. */
		console_unlock();
		return -ENOSPC;
	 
	if (set_console(vt))  
		/*
		 * We're unable to switch to the SUSPEND_CONSOLE.
		 * Let the calling function know so it can decide
		 * what to do.
		 */
		console_unlock();
		return -EIO;
	 
	console_unlock();
	if (vt_waitactive(vt + 1))  
		pr_debug("Suspend: Can't switch VCs.");
		return -EINTR;
	 
	return prev;
 
Unlike most other locking functions we ve seen so far, console_lock needs to be careful to ensure nothing else is panicking and needs to dump to the console before grabbing the semaphore for the console and setting a couple flags.

Panics Panics are tracked via an atomic integer set to the id of the processor currently panicking. kernel/printk/printk.c:2649
/**
 * console_lock - block the console subsystem from printing
 *
 * Acquires a lock which guarantees that no consoles will
 * be in or enter their write() callback.
 *
 * Can sleep, returns nothing.
 */
void console_lock(void)
 
	might_sleep();
	/* On panic, the console_lock must be left to the panic cpu. */
	while (other_cpu_in_panic())
		msleep(1000);
	down_console_sem();
	console_locked = 1;
	console_may_schedule = 1;
 
EXPORT_SYMBOL(console_lock);
kernel/printk/printk.c:362
/*
 * Return true if a panic is in progress on a remote CPU.
 *
 * On true, the local CPU should immediately release any printing resources
 * that may be needed by the panic CPU.
 */
bool other_cpu_in_panic(void)
 
	return (panic_in_progress() && !this_cpu_in_panic());
 
kernel/printk/printk.c:345
static bool panic_in_progress(void)
 
	return unlikely(atomic_read(&panic_cpu) != PANIC_CPU_INVALID);
 
kernel/printk/printk.c:350
/* Return true if a panic is in progress on the current CPU. */
bool this_cpu_in_panic(void)
 
	/*
	 * We can use raw_smp_processor_id() here because it is impossible for
	 * the task to be migrated to the panic_cpu, or away from it. If
	 * panic_cpu has already been set, and we're not currently executing on
	 * that CPU, then we never will be.
	 */
	return unlikely(atomic_read(&panic_cpu) == raw_smp_processor_id());
 
console_locked is a debug value, used to indicate that the lock should be held, and our first indication that this whole virtual terminal system is more complex than might initially be expected. kernel/printk/printk.c:373
/*
 * This is used for debugging the mess that is the VT code by
 * keeping track if we have the console semaphore held. It's
 * definitely not the perfect debug tool (we don't know if _WE_
 * hold it and are racing, but it helps tracking those weird code
 * paths in the console code where we end up in places I want
 * locked without the console semaphore held).
 */
static int console_locked;
console_may_schedule is used to see if we are permitted to sleep and schedule other work while we hold this lock. As we ll see later, the virtual terminal subsystem is not re-entrant, so there s all sorts of hacks in here to ensure we don t leave important code sections that can t be safely resumed.

Disable VT Switch As the comment below lays out, when another program is handling graphical display anyway, there s no need to do any of this, so the kernel provides a switch to turn the whole thing off. Interestingly, this appears to only be used by three drivers, so the specific hardware support required must not be particularly common.
drivers/gpu/drm/omapdrm/dss
drivers/video/fbdev/geode
drivers/video/fbdev/omap2
drivers/tty/vt/vt_ioctl.c:1308
/*
 * Normally during a suspend, we allocate a new console and switch to it.
 * When we resume, we switch back to the original console.  This switch
 * can be slow, so on systems where the framebuffer can handle restoration
 * of video registers anyways, there's little point in doing the console
 * switch.  This function allows you to disable it by passing it '0'.
 */
void pm_set_vt_switch(int do_switch)
 
	console_lock();
	disable_vt_switch = !do_switch;
	console_unlock();
 
EXPORT_SYMBOL(pm_set_vt_switch);
The rest of the vt_switch_console function is pretty normal, however, simply allocating space if needed to create the requested virtual terminal and then setting the current virtual terminal via set_console.

Virtual Terminal Set Console With set_console, we begin (as if we haven t been already) to enter the madness that is the virtual terminal subsystem. As mentioned previously, modifications to its state must be made very carefully, as other stuff happening at the same time could create complete messes. All this to say, calling set_console does not actually perform any work to change the state of the current console. Instead it indicates what changes it wants and then schedules that work. drivers/tty/vt/vt.c:3153
int set_console(int nr)
 
	struct vc_data *vc = vc_cons[fg_console].d;
	if (!vc_cons_allocated(nr)   vt_dont_switch  
		(vc->vt_mode.mode == VT_AUTO && vc->vc_mode == KD_GRAPHICS))  
		/*
		 * Console switch will fail in console_callback() or
		 * change_console() so there is no point scheduling
		 * the callback
		 *
		 * Existing set_console() users don't check the return
		 * value so this shouldn't break anything
		 */
		return -EINVAL;
	 
	want_console = nr;
	schedule_console_callback();
	return 0;
 
The check for vc->vc_mode == KD_GRAPHICS is where most end-user graphical desktops will bail out of this change, as they re in graphics mode and don t need to switch away to the suspend console. vt_dont_switch is a flag used by the ioctls11 VT_LOCKSWITCH and VT_UNLOCKSWITCH to prevent the system from switching virtual terminal devices when the user has explicitly locked it. VT_AUTO is a flag indicating that automatic virtual terminal switching is enabled12, and thus deliberate switching to a suspend terminal is not required. However, if you do run your machine from a virtual terminal, then we indicate to the system that we want to change to the requested virtual terminal via the want_console variable and schedule a callback via schedule_console_callback. drivers/tty/vt/vt.c:315
void schedule_console_callback(void)
 
	schedule_work(&console_work);
 
console_work is a workqueue2 that will execute the given task asynchronously.

Console Callback drivers/tty/vt/vt.c:3109
/*
 * This is the console switching callback.
 *
 * Doing console switching in a process context allows
 * us to do the switches asynchronously (needed when we want
 * to switch due to a keyboard interrupt).  Synchronization
 * with other console code and prevention of re-entrancy is
 * ensured with console_lock.
 */
static void console_callback(struct work_struct *ignored)
 
	console_lock();
	if (want_console >= 0)  
		if (want_console != fg_console &&
		    vc_cons_allocated(want_console))  
			hide_cursor(vc_cons[fg_console].d);
			change_console(vc_cons[want_console].d);
			/* we only changed when the console had already
			   been allocated - a new console is not created
			   in an interrupt routine */
		 
		want_console = -1;
	 
...
console_callback first looks to see if there is a console change wanted via want_console and then changes to it if it s not the current console and has been allocated already. We do first remove any cursor state with hide_cursor. drivers/tty/vt/vt.c:841
static void hide_cursor(struct vc_data *vc)
 
	if (vc_is_sel(vc))
		clear_selection();
	vc->vc_sw->con_cursor(vc, false);
	hide_softcursor(vc);
 
A full dive into the tty driver is a task for another time, but this should give a general sense of how this system interacts with hibernation.

Notify Power Management Call Chain kernel/power/hibernate.c:767
pm_notifier_call_chain_robust(PM_HIBERNATION_PREPARE, PM_POST_HIBERNATION)
This will call a chain of power management callbacks, passing first PM_HIBERNATION_PREPARE and then PM_POST_HIBERNATION on startup or on error with another callback. kernel/power/main.c:98
int pm_notifier_call_chain_robust(unsigned long val_up, unsigned long val_down)
 
	int ret;
	ret = blocking_notifier_call_chain_robust(&pm_chain_head, val_up, val_down, NULL);
	return notifier_to_errno(ret);
 
The power management notifier is a blocking notifier chain, which means it has the following properties. include/linux/notifier.h:23
 *	Blocking notifier chains: Chain callbacks run in process context.
 *		Callouts are allowed to block.
The callback chain is a linked list with each entry containing a priority and a function to call. The function technically takes in a data value, but it is always NULL for the power management chain. include/linux/notifier.h:49
struct notifier_block;
typedef	int (*notifier_fn_t)(struct notifier_block *nb,
			unsigned long action, void *data);
struct notifier_block  
	notifier_fn_t notifier_call;
	struct notifier_block __rcu *next;
	int priority;
 ;
The head of the linked list is protected by a read-write semaphore. include/linux/notifier.h:65
struct blocking_notifier_head  
	struct rw_semaphore rwsem;
	struct notifier_block __rcu *head;
 ;
Because it is prioritized, appending to the list requires walking it until an item with lower13 priority is found to insert the current item before. kernel/notifier.c:252
/*
 *	Blocking notifier chain routines.  All access to the chain is
 *	synchronized by an rwsem.
 */
static int __blocking_notifier_chain_register(struct blocking_notifier_head *nh,
					      struct notifier_block *n,
					      bool unique_priority)
 
	int ret;
	/*
	 * This code gets used during boot-up, when task switching is
	 * not yet working and interrupts must remain disabled.  At
	 * such times we must not call down_write().
	 */
	if (unlikely(system_state == SYSTEM_BOOTING))
		return notifier_chain_register(&nh->head, n, unique_priority);
	down_write(&nh->rwsem);
	ret = notifier_chain_register(&nh->head, n, unique_priority);
	up_write(&nh->rwsem);
	return ret;
 
kernel/notifier.c:20
/*
 *	Notifier chain core routines.  The exported routines below
 *	are layered on top of these, with appropriate locking added.
 */
static int notifier_chain_register(struct notifier_block **nl,
				   struct notifier_block *n,
				   bool unique_priority)
 
	while ((*nl) != NULL)  
		if (unlikely((*nl) == n))  
			WARN(1, "notifier callback %ps already registered",
			     n->notifier_call);
			return -EEXIST;
		 
		if (n->priority > (*nl)->priority)
			break;
		if (n->priority == (*nl)->priority && unique_priority)
			return -EBUSY;
		nl = &((*nl)->next);
	 
	n->next = *nl;
	rcu_assign_pointer(*nl, n);
	trace_notifier_register((void *)n->notifier_call);
	return 0;
 
Each callback can return one of a series of options. include/linux/notifier.h:18
#define NOTIFY_DONE		0x0000		/* Don't care */
#define NOTIFY_OK		0x0001		/* Suits me */
#define NOTIFY_STOP_MASK	0x8000		/* Don't call further */
#define NOTIFY_BAD		(NOTIFY_STOP_MASK 0x0002)
						/* Bad/Veto action */
When notifying the chain, if a function returns STOP or BAD then the previous parts of the chain are called again with PM_POST_HIBERNATION14 and an error is returned. kernel/notifier.c:107
/**
 * notifier_call_chain_robust - Inform the registered notifiers about an event
 *                              and rollback on error.
 * @nl:		Pointer to head of the blocking notifier chain
 * @val_up:	Value passed unmodified to the notifier function
 * @val_down:	Value passed unmodified to the notifier function when recovering
 *              from an error on @val_up
 * @v:		Pointer passed unmodified to the notifier function
 *
 * NOTE:	It is important the @nl chain doesn't change between the two
 *		invocations of notifier_call_chain() such that we visit the
 *		exact same notifier callbacks; this rules out any RCU usage.
 *
 * Return:	the return value of the @val_up call.
 */
static int notifier_call_chain_robust(struct notifier_block **nl,
				     unsigned long val_up, unsigned long val_down,
				     void *v)
 
	int ret, nr = 0;
	ret = notifier_call_chain(nl, val_up, v, -1, &nr);
	if (ret & NOTIFY_STOP_MASK)
		notifier_call_chain(nl, val_down, v, nr-1, NULL);
	return ret;
 
Each of these callbacks tends to be quite driver-specific, so we ll cease discussion of this here.

Sync Filesystems The next step is to ensure all filesystems have been synchronized to disk. This is performed via a simple helper function that times how long the full synchronize operation, ksys_sync takes. kernel/power/main.c:69
void ksys_sync_helper(void)
 
	ktime_t start;
	long elapsed_msecs;
	start = ktime_get();
	ksys_sync();
	elapsed_msecs = ktime_to_ms(ktime_sub(ktime_get(), start));
	pr_info("Filesystems sync: %ld.%03ld seconds\n",
		elapsed_msecs / MSEC_PER_SEC, elapsed_msecs % MSEC_PER_SEC);
 
EXPORT_SYMBOL_GPL(ksys_sync_helper);
ksys_sync wakes and instructs a set of flusher threads to write out every filesystem, first their inodes15, then the full filesystem, and then finally all block devices, to ensure all pages are written out to disk. fs/sync.c:87
/*
 * Sync everything. We start by waking flusher threads so that most of
 * writeback runs on all devices in parallel. Then we sync all inodes reliably
 * which effectively also waits for all flusher threads to finish doing
 * writeback. At this point all data is on disk so metadata should be stable
 * and we tell filesystems to sync their metadata via ->sync_fs() calls.
 * Finally, we writeout all block devices because some filesystems (e.g. ext2)
 * just write metadata (such as inodes or bitmaps) to block device page cache
 * and do not sync it on their own in ->sync_fs().
 */
void ksys_sync(void)
 
	int nowait = 0, wait = 1;
	wakeup_flusher_threads(WB_REASON_SYNC);
	iterate_supers(sync_inodes_one_sb, NULL);
	iterate_supers(sync_fs_one_sb, &nowait);
	iterate_supers(sync_fs_one_sb, &wait);
	sync_bdevs(false);
	sync_bdevs(true);
	if (unlikely(laptop_mode))
		laptop_sync_completion();
 
It follows an interesting pattern of using iterate_supers to run both sync_inodes_one_sb and then sync_fs_one_sb on each known filesystem16. It also calls both sync_fs_one_sb and sync_bdevs twice, first without waiting for any operations to complete and then again waiting for completion17. When laptop_mode is enabled the system runs additional filesystem synchronization operations after the specified delay without any writes. mm/page-writeback.c:111
/*
 * Flag that puts the machine in "laptop mode". Doubles as a timeout in jiffies:
 * a full sync is triggered after this time elapses without any disk activity.
 */
int laptop_mode;
EXPORT_SYMBOL(laptop_mode);
However, when running a filesystem synchronization operation, the system will add an additional timer to schedule more writes after the laptop_mode delay. We don t want the state of the system to change at all while performing hibernation, so we cancel those timers. mm/page-writeback.c:2198
/*
 * We're in laptop mode and we've just synced. The sync's writes will have
 * caused another writeback to be scheduled by laptop_io_completion.
 * Nothing needs to be written back anymore, so we unschedule the writeback.
 */
void laptop_sync_completion(void)
 
	struct backing_dev_info *bdi;
	rcu_read_lock();
	list_for_each_entry_rcu(bdi, &bdi_list, bdi_list)
		del_timer(&bdi->laptop_mode_wb_timer);
	rcu_read_unlock();
 
As a side note, the ksys_sync function is simply called when the system call sync is used. fs/sync.c:111
SYSCALL_DEFINE0(sync)
 
	ksys_sync();
	return 0;
 

The End of Preparation With that the system has finished preparations for hibernation. This is a somewhat arbitrary cutoff, but next the system will begin a full freeze of userspace to then dump memory out to an image and finally to perform hibernation. All this will be covered in future articles!
  1. Hibernation modes are outside of scope for this article, see the previous article for a high-level description of the different types of hibernation.
  2. Workqueues are a mechanism for running asynchronous tasks. A full description of them is a task for another time, but the kernel documentation on them is available here: https://www.kernel.org/doc/html/v6.9/core-api/workqueue.html 2
  3. This is a bit of an oversimplification, but since this isn t the main focus of this article this description has been kept to a higher level.
  4. Kconfig is Linux s build configuration system that sets many different macros to enable/disable various features.
  5. Kconfig defaults to the first default found
  6. Including checking whether the algorithm is larval? Which appears to indicate that it requires additional setup, but is an interesting choice of name for such a state.
  7. Specifically when we get to process freezing, which we ll get to in the next article in this series.
  8. Swap space is outside the scope of this article, but in short it is a buffer on disk that the kernel uses to store memory not current in use to free up space for other things. See Swap Management for more details.
  9. The code for this is lengthy and tangential, thus it has not been included here. If you re curious about the details of this, see kernel/power/hibernate.c:858 for the details of hibernate_quiet_exec, and drivers/nvdimm/core.c:451 for how it is used in nvdimm.
  10. Annoyingly this code appears to use the terms console and virtual terminal interchangeably.
  11. ioctls are special device-specific I/O operations that permit performing actions outside of the standard file interactions of read/write/seek/etc. 2
  12. I m not entirely clear on how this flag works, this subsystem is particularly complex.
  13. In this case a higher number is higher priority.
  14. Or whatever the caller passes as val_down, but in this case we re specifically looking at how this is used in hibernation.
  15. An inode refers to a particular file or directory within the filesystem. See Wikipedia for more details.
  16. Each active filesystem is registed with the kernel through a structure known as a superblock, which contains references to all the inodes contained within the filesystem, as well as function pointers to perform the various required operations, like sync.
  17. I m including minimal code in this section, as I m not looking to deep dive into the filesystem code at this time.

4 September 2024

Reproducible Builds: Reproducible Builds in August 2024

Welcome to the August 2024 report from the Reproducible Builds project! Our reports attempt to outline what we ve been up to over the past month, highlighting news items from elsewhere in tech where they are related. As ever, if you are interested in contributing to the project, please visit our Contribute page on our website. Table of contents:
  1. LWN: The history, status, and plans for reproducible builds
  2. Intermediate Autotools build artifacts removed from PostgreSQL distribution tarballs
  3. Distribution news
  4. Mailing list news
  5. diffoscope
  6. Website updates
  7. Upstream patches
  8. Reproducibility testing framework

LWN: The history, status, and plans for reproducible builds The free software newspaper of record, Linux Weekly News, published an in-depth article based on Holger Levsen s talk, Reproducible Builds: The First Eleven Years which was presented at the recent DebConf24 conference in Busan, South Korea. Titled The history, status, and plans for reproducible builds and written by Jake Edge, LWN s article not only summarises Holger s talk and clarifies its message but it links to external information as well. Holger s original talk can also be watched on the DebConf24 webpage (direct .webm link and his HTML slides are available also). There are also a significant number of comments on LWN s page as well. Holger Levsen also headed a scheduled discussion session at DebConf24 on Preserving *other* build artifacts addressing a topic where a number of Debian packages are (or would like to) produce results that are neither the .deb files, the build logs nor the logs of CI tests. This is an issue for reproducible builds as this 4th type of build artifact are typically shipped within the binary .deb packages, and are invariably non-deterministic; thus making the .deb files unreproducible. (A direct .webm link and HTML slides are available).

Intermediate Autotools build artifacts removed from PostgreSQL distribution tarballs Peter Eisentraut wrote a detailed blog post on the subject of The new PostgreSQL 17 make dist . Like many projects, the PostgreSQL database has previously pre-built parts of its GNU Autotools build system: the reason for this is a mix of convenience and traditional practice . Peter astutely notes that this arrangement in the build system is quite tricky as:
You need to carefully maintain the different states of clean source code , partially built source code , and fully built source code , and the commands to transition between them.
However, Peter goes on to mention that:
a lot more attention is nowadays paid to the software supply chain. There are security and legal reasons for this. When users install software, they want to know where it came from, and they want to be sure that they got the right thing, not some fake version or some version of dubious legal provenance.
And cites the XZ Utils backdoor as a reason to care about transparent and reproducible ways of distributing and communicating a source tarball and provenance. Because of this, intermediate build artifacts are now henceforth essentially disallowed from PostgreSQL distribution tarballs.

Distribution news In Debian this month, 30 reviews of Debian packages were added, 17 were updated and 10 were removed this month adding to our knowledge about identified issues. One issue type was added by Chris Lamb, too. [ ] In addition, an issue was filed to update the Salsa CI pipeline (used by 1,000s of Debian packages) to no longer test for reproducibility with reprotest s build_path variation. Holger Levsen provided a rationale for this change in the issue, which has already been made to the tests being performed by tests.reproducible-builds.org.
In Arch Linux this month, Jelle van der Waa published a short blog post on the topic of Investigating creating reproducible images with mkosi, motivated by the desire to make it possible for anyone to re-recreate the official Arch cloud image bit-by-bit identical on their own machine as per [the] reproducible builds definition. In addition, Jelle filed a patch for pacman, the Arch Linux package manager, to respect the SOURCE_DATE_EPOCH environment variable when installing a package.
In openSUSE news, Bernhard M. Wiedemann published another report for that distribution.
In Android news, the IzzyOnDroid project added 49 new rebuilder recipes and now features 256 total reproducible applications representing 21% of the total offerings in the repository. IzzyOnDroid is an F-Droid style repository for Android apps[:] applications in this repository are official binaries built by the original application developers, taken from their resp. repositories (mostly GitHub).

Mailing list news From our mailing list this month:
  • Bernhard M. Wiedemann posted a brief message to the list with some helpful information regarding nondeterminism within Rust binaries, positing the use of the codegen-units = 16 default and resulting in a bug being filed in the Rust issue tracker. [ ]
  • Bernhard also wrote to the list, following up to a thread in November 2023, on attempts to make the LibreOffice suite of office applications build reproducibly. In the thread from this month, Bernhard could announce that the four patches previously mentioned have landed in LibreOffice upstream.
  • Fay Stegerman linked the mailing list to a thread she made on the Signal issue tracker regarding whether device-specific binaries [can] ever be considered meaningfully reproducible . In particular: the whole part about allow[ing] multiple third parties to come to a consensus on a correct result breaks down completely when correct is device-specific and not something everyone can agree on. [ ]
  • Developer kpcyrd posted an update for source code indexing project, whatsrc.org. Announcing that it now importing packages from live-bootstrap ( a usable Linux system [that is] created with only human-auditable, and wherever possible, human-written, source code ) into its database of provenance data.
  • Lastly, Mechtilde Stehmann posted an update to an earlier thread about how Java builds are not reproducible on the armhf architecture, enquiring how they might gain temporary access to such a machine in order to perform some deeper testing. [ ]

diffoscope diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb released versions 274, 275, 276 and 277, uploaded these to Debian, and made the following changes as well:
  • New features:
    • Strip ANSI escapes usually colour codes from the output of the Procyon Java decompiler. [ ]
    • Factor out a method for stripping ANSI escapes. [ ]
    • Append output from dumppdf(1) in more cases, avoiding situations where we fallback to a binary diff. [ ]
    • Add support for versions of Perl s IO::Compress::Zip version 2.212. [ ]
  • Bug fixes:
    • Also catch RuntimeError exceptions when importing the PyPDF library so that it, or, crucially, its transitive dependencies, cannot not cause diffoscope to traceback at runtime and build time. [ ]
    • Do not call marshal.load( ) of precompiled Python bytecode as it, alas, inherently unsafe. Replace for now with a brief summary of the code section of .pyc. [ ][ ]
    • Don t include excessive debug output when calling dumppdf(1). [ ]
  • Testsuite-related changes:
    • Don t bother to check version number in test_python.py: the fixture for this test is fixed. [ ][ ]
    • Update test_zip text fixtures and definitions to support new changes to the Perl IO::Compress library. [ ]
In addition, Mattia Rizzolo updated the available architectures for a number of test dependencies [ ] and Sergei Trofimovich fixed an issue to avoid diffoscope crashing when hashing directory symlinks [ ] and Vagrant Cascadian proposed GNU Guix updates for diffoscope versions 275 and 276 and 277.

Website updates There were a rather substantial number of improvements made to our website this month, including:
  • Alba Herrerias:
    • Substantially extend the guidance on the Contribute page. [ ]
  • Chris Lamb:
    • Set the future: true configuration value so we render all files and documents in the website, regardless of whether they have a date property in the future. After all, we don t re-generate the website on a timer, and have other ways of making unpublished, draft posts. [ ][ ]
  • Fay Stegerman:
  • hulkoba:
  • kpcyrd:
  • Mattia Rizzolo:
  • Pol Dellaiera:

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In August, a number of changes were made by Holger Levsen, including:
  • Temporarily install the openssl-provider-legacy package for the Debian unstable environments for running diffoscope due to Debian bug #1078944. [ ][ ][ ][ ]
  • Mark Debian armhf architecture nodes as being down due to proxy down. [ ][ ]
  • Detect proxy failures. [ ][ ][ ]
  • Run the index-buildinfo for the builtin-pho script with the -q switch. [ ]
  • Disable all Arch Linux reproducible jobs. [ ]
In addition, Mattia Rizzolo updated the website configuration to install the ruby-jekyll-sitemap package as it is now used in the website [ ], Roland Clobus updated the script to build Debian live images to treat openQA issues as warnings [ ], and Vagrant Cascadian marked the cbxi4b node as down [ ].

If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Jonathan Dowland: loading (unintended consequences?)

For their 30th anniversary (ish; the Covid pandemic pushed the date out a bit) British electronic music duo Orbital released the compilation 30 something. The track list mostly looks like a best hits list, which given their prior compilation celebrating 20 years looks much the same would appear superfluous. However, they ve rearranged and re-recorded all their songs for 30, to reflect their live arrangements. The reworkings are sufficiently distinct from the original versions (in some cases I prefer them) and elevate the release. The couple of new tracks are also fun, and many of the remixes on the second disc are worth a listen too.
cover art from Orbital - 30 Something
But what I actually sat down to write about was the cover artwork. They often have designs which riff on the notion of a circle (given their name) and the 30-something art (both for the album and single takes from it) adapts a loading spinner-like device from computing (I suppose it mostly closely resembles the spinner from macOS). A possibly unintended effect of the pattern occurs when you view it on a display which is adjusting its brightness, such as if you re listening to it on a phone, the screen is off, and you pick it up. The brightest part of the spinner is visible first, and the rest fade into visibility in sequence. The first time you see this is unexpected and very cool. (I've tried to recreate it in the picture below, but I don't think it's worked.) Although I've suffixed the titled of this post unintended consequences?, It's quite possible this was deliberate.
screenshot of the artwork displayed on my phone
I ve got the pattern on a t-shirt and my kids love to call out Daddy s loading! In my convalescence it s taken on a special sort of resonance because at times I ve felt I m in a holding state: waiting for an appointment to be made; waiting a polite interval before chasing an appointment; waiting for treatment to start after attending an appointment. Thankfully I m at the end of that now, I hope.

Samuel Henrique: DebConf24 was fun!: Security, curl, wcurl, Debian's quality

A picture of a badger2040w with Samuel's badge and the curl manpage PCB on the side

tl;dr DebConf24 was fun! A playlist of all of my talks, with subtitles (en, pt-br) and chapters is available on YouTube.

Overview DebConf24 was held in Busan, South Korea, between Sunday July 28th to Sunday August 4th 2024. As usual for DebConfs, I had a great time meeting my friends, but also met new people and got to learn a bit about the interesting things they're working on. I ended up getting too excited during the talk submission stage of the conference and as a result I presented 5 different activities (3 talks, 1 BoF and 1 lightning talk). Since I was too busy with the presentations, I did not have a lot of time to actually hang out with folks, or even to go out in the city, I guess I've learned my lesson for next time. The main purpose of this post is to write about all of the things I presented at the conference. I did want to list some of the interesting talks I've watched, but that I would not be able to be fair as I'm sure I would miss some. You can get the schedule and the recordings of any talks from the conference's website: https://debconf24.debconf.org/schedule/

wcurl Lightning Talk The most fun of my presentations, during the second-to-last day of the conference, I've asked for help from Sergio Durigan Junior <sergiodj> to setup an URL containing a whitespace and redirecting that to wcurl's manpage. I then did a little demo to showcase why me (and a lot others) struggle with downloading things with curl, and how wcurl solves that. https://www.youtube.com/watch?v=eM8M5qa4pPM

Fixing CVEs on Debian: Everything you probably know already I've always felt like DebConf was missing security-related talks, so I decided to do something about it and presented a few of the things I've learned when fixing CVEs for Debian. This is an area where we don't get a lot of new contributors, I'm trying to change that, and this talk can be used to introduce newcomers to it. https://www.youtube.com/watch?v=XzNVVILVyUM

The secret sauce of Debian Debian is not very vocal about all of the nice things it has regarding quality-assurance, testing, or CI, even though it's at the state-of-the-art for a lot of things. This talk is an initial step towards making people aware of the cool things happening behind the scenes. Ideally we should have it well-documented somewhere. https://www.youtube.com/watch?v=x_X2IBnpjic

"I use Debian BTW": fzf, tmux, zoxide and friends One of my earliest good memories of Debian was when it started coming with a colored PS1 by default, I still remember the feeling of relief whenever I jumped into a Debian server and didn't have to deal with a black and white PS1. There's still a lot of room for Debian to ship better defaults, and I think some of them can actually happen. This talk is a bit of a silly one where I'm just making people aware of the existence of a few Golang/Rust CLI tools, and also some dotfiles configurations that should probably be the default. https://www.youtube.com/watch?v=tfto3Seokn4

curl The curl project does such a great job with their security advisories that it will likely never receive the amount of praise it deserves, but I did my best at mentioning it throughout my CVEs talk. Maybe I will write more extensively about this someday, but in case I don't:
There's no other project which always consistently mentions the exact range of commits that are affected by a given CVE. Forget about whether the versions are EOL, curl doesn't have LTS releases, yet they do such a great job at clearly documenting their CVEs that I would take that over having LTS releases anytime (that's for curl at least, I acknowledge some types of projects have a different need for LTS releases). Not only that, but they are also always careful about explaining alternative mitigations such as configuration changes, build flags that defuse the exploitation, or parameters that you should not use.
Just like we tend to do every time we meet, me and the other Debian curl maintainers spent the first 2 or 3 days of the conference talking about how we wanted to eventually meet up to discuss the package. It was going to be informal, maybe during the Cheese and Wine party, but then I've realized we should make it part of the official schedule, which would also give us the recordings for later. And so the "curl maintainers BoF" happened, where we spoke about HTTP3, GnutTLS, wcurl and other things. https://www.youtube.com/watch?v=fL7hSypUTdM

wcurl Right after that BoF, Daniel Stenberg asked if we were interested in having wcurl adopted into curl, which we definitely were, so wcurl is now part of the curl project. Daniel was also kind enough to design a logo for the project, which makes me especially happy because I can stop with my own approach at a logo (which I had to redo every few days): A laptop with a curl and a GoHorse sticker, there's a 'w' handwritten with a marker on the right side of the curl sticker, making it 'wcurl' And here is the new logo: 'wcurl' written with the same font and colors as the curl logo, with the 'w' being green instead of blue, and a download icon at the end Much better, I would say :)

curl Swag DebConf24 was my chance at forwarding some curl swag items to the other curl maintainers, so both Sergio Durigan Junior <sergiodj> and Carlos Henrique Lima Melara <charles> got the curl-up t-shirt and the very cool curl PCB coaster, both gifted by Daniel Stenberg. Unfortunately I didn't have any of that for DebConf attendees, but I did drop loads of curl stickers at the stickers table, they were gone very quickly. A table full of different stickers, curl stickers can be seen over the whole table

For the future I used to think the most humbling experience you could have as someone who presented a talk was to have to watch it yourself, you notice a lot of mistakes and you instantly think about things that should be done differently. It turns out the most humbling thing to do is actually to write subtitles for your talks, I noticed every single mistake, often multiple times. So after spending more than 30 hours writing the subtitles for both English and Brazilian Portuguese for my talks, I feel like it's going to be much easier to avoid committing the same mistakes again. After some time you stop feeling shame about those mistakes and you're just left with feelings of annoyance, and at that point it becomes easier to consciously avoid them. I am collecting a list of things I wish I had done differently on all of those talks, so if I end up presenting any one of them again, it will be an improved version. A picture from the top of a group of conference attendees, there's about 150 people in the picture

2 September 2024

Jonathan Carter: Debian Day South Africa 2024

Beer, cake and ISO testing amidst rugby and jazz band chaos On Saturday, the Debian South Africa team got together in Cape Town to celebrate Debian s 31st birthday and to perform ISO testing for the Debian 11.11 and 12.7 point releases.
We ran out of time to organise a fancy printed cake like we had last year, but our improvisation worked out just fine!
We thought that we had allotted plenty of time for all of our activities for the day, and that there would be plenty of time for everything including training, but the day zipped by really fast. We hired a venue at a brewery, which is usually really nice because they have an isolated area with lots of space and a big TV nice for presentations, demos, etc. But on this day, there was a big rugby match between South Africa and New Zealand, and as it got closer to the game, the place just got louder and louder (especially as a band started practicing and doing sound tests for their performance for that evening) and it turned out our space was also double-booked later in the afternoon, so we had to relocate.
Even amidst all the chaos, we ended up having a very productive day and we even managed to have some fun!
Four people from our local team performed ISO testing for the very first time, and in total we covered 44 test cases locally. Most of the other testers were the usual crowd in the UK, we also did a brief video call with them, but it was dinner time for them so we had to keep it short. Next time we ll probably have some party line open that any tester can also join.

Logo
We went through some more iterations of our local team logo that Tammy has been working on. They re turning out very nice and have been in progress for more than a year, I guess like most things Debian, it will be ready when it s ready!

Debian 11.11 and Debian 12.7 released, and looking ahead towards Debian 13 Both point releases tested just fine and was released later in the evening. I m very glad that we managed to be useful and reduce total testing time and that we managed to cover all the test cases in the end. A bunch of things we really wanted to fix by the time Debian 12 launched are now finally fixed in 12.7. There s still a few minor annoyances, but over all, Debian 13 (trixie) is looking even better than Debian 12 was around this time in the release cycle. Freeze dates for trixie has not yet been announced, I hope that the release team announces those sooner rather than later, also KDE Plasma 6 hasn t yet made its way into unstable, I ve seen quite a number of people ask about this online, so hopefully that works out. And by the way, the desktop artwork submissions for trixie ends in two weeks! More information about that is available on the Debian wiki if you re interested in making a contribution. There are already 4 great proposals.

Debian Local Groups Organising local events for Debian is probably easier than you think, and Debian does make funding available for events. So, if you want to grow Debian in your area, feel free to join us at -localgroups on the OFTC IRC network, also plumbed on Matrix at -localgroups:matrix.debian.social where we ll try to answer any questions you might have and guide you through the process! Oh and btw South Africa won the Rugby!

1 September 2024

Bits from Debian: Bits from the DPL

Dear Debian community, this are my bits from DPL for August. Happy Birthday Debian On 16th of August Debian celebrated its 31th birthday. Since I'm unable to write a better text than our great publicity team I'm simply linking to their article for those who might have missed it: https://bits.debian.org/2024/08/debian-turns-31.html Removing more packages from unstable Helmut Grohne argued for more aggressive package removal and sought consensus on a way forward. He provided six examples of processes where packages that are candidates for removal are consuming valuable person-power. I d like to add that the Bug of the Day initiative (see below) also frequently encounters long-unmaintained packages with popcon votes sometimes as low as zero, and often fewer than ten. Helmut's email included a list of packages that would meet the suggested removal criteria. There was some discussion about whether a popcon vote should be included in these criteria, with arguments both for and against it. Although I support including popcon, I acknowledge that Helmut has a valid point in suggesting it be left out. While I ve read several emails in agreement, Scott Kitterman made a valid point "I don't think we need more process. We just need someone to do the work of finding the packages and filing the bugs." I agree that this is crucial to ensure an automated process doesn t lead to unwanted removals. However, I don t see "someone" stepping up to file RM bugs against other maintainers' packages. As long as we have strict ownership of packages, many people are hesitant to touch a package, even for fixing it. Asking for its removal might be even less well-received. Therefore, if an automated procedure were to create RM bugs based on defined criteria, it could help reduce some of the social pressure. In this aspect the opinion of Niels Thykier is interesting: "As much as I want automation, I do not mind the prototype starting as a semi-automatic process if that is what it takes to get started." The urgency of the problem to remove packages was put by CharlesPlessy into the words: "So as of today, it is much less work to keep a package rotting than removing it." My observation when trying to fix the Bug of the Day exactly fits this statement. I would love for this discussion to lead to more aggressive removals that we can agree upon, whether they are automated, semi-automated, or managed by a person processing an automatically generated list (supported by an objective procedure). To use an analogy: I ve found that every image collection improves with aggressive pruning. Similarly, I m convinced that Debian will improve if we remove packages that no longer serve our users well. DEP14 / DEP18 There are two DEPs that affect our workflow for maintaining packages particularly for those who agree on using Git for Debian packages. DEP-14 recommends a standardized layout for Git packaging repositories, which benefits maintainers working across teams and makes it easier for newcomers to learn a consistent repository structure. DEP-14 stalled for various reasons. Sam Hartman suspected it might be because 'it doesn't bring sufficient value.' However, the assumption that git-buildpackage is incompatible with DEP-14 is incorrect, as confirmed by its author, Guido G nther. As one of the two key tools for Debian Git repositories (besides dgit) fully supports DEP-14, though the migration from the previous default is somewhat complex. Some investigation into mass-converting older formats to DEP-14 was conducted by the Perl team, as Gregor Hermann pointed out.. The discussion about DEP-14 resurfaced with the suggestion of DEP-18. Guido G nther proposed the title Encourage Continuous Integration and Merge Request-Based Collaboration for Debian Packages , which more accurately reflects the DEP's technical intent. Otto Kek l inen, who initiated DEP-18 (thank you, Otto), provided a good summary of the current status. He also assembled a very helpful overview of Git and GitLab usage in other Linux distros. More Salsa CI As a result of the DEP-18 discussion, Otto Kek l inen suggested implementing Salsa CI for our top popcon packages. I believe it would be a good idea to enable CI by default across Salsa whenever a new repository is created. Progress in Salsa migration In my campaign, I stated that I aim to reduce the number of packages maintained outside Salsa to below 2,000. As of March 28, 2024, the count was 2,368. Today, it stands at 2,187 (UDD query: SELECT DISTINCT count(*) FROM sources WHERE release = 'sid' and vcs_url not like '%salsa%' ;). After a third of my DPL term (OMG), we've made significant progress, reducing the amount in question (369 packages) by nearly half. I'm pleased with the support from the DDs who moved their packages to Salsa. Some packages were transferred as part of the Bug of the Day initiative (see below). Bug of the Day As announced in my 'Bits from the DPL' talk at DebConf, I started an initiative called Bug of the Day. The goal is to train newcomers in bug triaging by enabling them to tackle small, self-contained QA tasks. We have consistently identified target packages and resolved at least one bug per day, often addressing multiple bugs in a single package. In several cases, we followed the Package Salvaging procedure outlined in the Developers Reference. Most instances were either welcomed by the maintainer or did not elicit a response. Unfortunately, there was one exception where the recipient of the Package Salvage bug expressed significant dissatisfaction. The takeaway is to balance formal procedures with consideration for the recipient s perspective. I'm pleased to confirm that the Matrix channel has seen an increase in active contributors. This aligns with my hope that our efforts would attract individuals interested in QA work. I m particularly pleased that, within just one month, we have had help with both fixing bugs and improving the code that aids in bug selection. As I aim to introduce newcomers to various teams within Debian, I also take the opportunity to learn about each team's specific policies myself. I rely on team members' assistance to adapt to these policies. I find that gaining this practical insight into team dynamics is an effective way to understand the different teams within Debian as DPL. Another finding from this initiative, which aligns with my goal as DPL, is that many of the packages we addressed are already on Salsa but have not been uploaded, meaning their VCS fields are not published. This suggests that maintainers are generally open to managing their packages on Salsa. For packages that were not yet on Salsa, the move was generally welcomed. Publicity team wants you The publicity team has decided to resume regular meetings to coordinate their efforts. Given my high regard for their work, I plan to attend their meetings as frequently as possible, which I began doing with the first IRC meeting. During discussions with some team members, I learned that the team could use additional help. If anyone interested in supporting Debian with non-packaging tasks reads this, please consider introducing yourself to debian-publicity@lists.debian.org. Note that this is a publicly archived mailing list, so it's not the best place for sharing private information. Kind regards Andreas.

Next.

Previous.