Today I had to pleasure of releasing Lintian 2.5.18.1. It is a minor bug fix release on top of Lintian 2.5.18 (which I also released today ). When I was about to deploy the new version of Lintian on lintian.debian.org, I noticed a couple of errors in the log file that smelled of bugs. Indeed, when I investigated them I found two bugs, which were both introduced in Lintian 2.5.17.
Due to another bug in 2.5.17 and the some of the false-positives fixes, we are now doing a full run on lintian.debian.org. After having run for 7 hours, Lintian passed cipux . My rough estimate suggests that it will take 8 days at the current rate. For comparision, when we added amd64, Lintian spent 5 days processing all the new binaries (plus their source and the old binaries built from those source packages).
Of course estimate is rather rough. In particular, I am not sure that the heavy duty groups (e.g. linux and libreoffice) are evenly spread out among the letters of the alphabeth. Anyhow, there will be no updates on lintian.debian.org for the next week or so.
On a regular basis, I find myself the odd-man-out when it comes to talking
about how to work with Python on Debian systems. I'm going to write this and
post it so that I might be able to point people at my thoughts without having
to write the same email in response to each thread that pops up.
Turns out I don't fit in with the Debian hardliners (which is to say, the
mindset that pip sucks and shouldn't exist), nor do I fit in with the Python
hardliners (which is to say apt and dpkg are out of date, and neither have
a place on a Development machine).
I think our discourse on this topic has become petty and stupid in general.
Let's all try to step back and drop a bit of the attitude.
pip doesn't suck, and neither does apt.
The truth is, both sides are wrong. As with any subject, the real
answer here is much more nuanced than either side presents it. I'm going to
try and present my opinion on this, in the way that both my Pythonista self
and my Debianite self see the issue. Hopefully I can keep this short, to
the point, and caked with logic.
The case for dpkg (the Debianite in me)
In defense of dpkg and apt, imagine having to install python-gnome2
on all your systems when you install. It'd be hell on earth.
Imagine having a user try to do this. It's insane to assume that
end-users will be using pip for this purpose.
pip is fun and all, but it's also installing 100% untrusted code to your
system (perhaps as root, if you're using pip with sudo for some reason),
and hasn't been reviewed for software freeness, which is something Debian
(and Debian users) take seriously. This isn't even to mention the hell that
pip wreaks on dpkg controlled files / packages.
Try to remember how much of your system running (yes, right now) is running
because of Python or Python modules. Try to imagine how much of a pain in
the ass it'd be if you couldn't boot into GNOME to use nm-applet to connect
to wifi to pip install something. I'm sure even the most extreme pip'er
understands the need for Operating System level package management.
Debian also has a bigger problem scope - we're not maintaining a library
in Debian for kicks, we're maintaining it so that end user applications may
use the library. When we update something like Django, we have to make sure
that we don't break anything using it (although, to be honest, the fact that we
package webapps is an entire rant for later) before we get to update it to the
newest release.
Hell, with a few coffees, I could automate the process of releasing a .deb
with a new upstream release, 100% unattended. I won't, however, since this is
an insane idea. Let's go over a brief list of things I do before uploading a
new package:
Review the entire codebase for simple mistakes.
Review the entire codebase for license issues.
Review the entire codebase for files without source, and track down
(and include source for) any sourceless files (such as pickle
files, etc).
Get to know the upstream, get to know open bugs, write something using
the lib, in case I need to debug later.
Install the package.
Test the package.
Work out any Debian package issues (this is easy).
Now, a brief list of things I do before I update a package:
Review the changes between the last uploaded version (in diff format, if
it's sane, otherwise get the VCS and review), ensure all the above are still
OK.
Review for Debian-local issues (such as how it will upgrade, using
piuparts, and adequate, etc).
Check to make sure it won't break any reverse dependencies.
Review for bugfixes that I might need to bring back to the stable release.
Figure out if I should (or even can) backport the package, if API is
stable.
Review for bugs (upstream or in Debian) that I need to mention in the
debian/changelog.
Clearly, this isn't a quick-and-dirty task. It's not a matter of getting a
package updated (technically), it's a much more detailed process than that.
This is also why Debian is so highly regarded for its technical virtuosity,
and why the
ISS decided to deploy Debian in space,
despite other commercial distros such as Red Hat, or Ubuntu, and
community distros, such as Fedora or Arch.
It's also not Debian's job to package the world in the archive. This is an
insane task, and it's not Debian's place to do it. We introduce libraries
as things need them, not because we wrote some new library that someone
may find slightly useful at some point in the future. maybe.
Upstream developers and language communities (not only Python here) tend to
lose sight of why we're doing this in the first place, which
is our users. This isn't some sort of technical pissing contest to see who can
distribute the software in the best way. Debian-folk always keep end users
as our highest priority.
I quote the
Debian Social Contract, when I say
that Our priorities are our users and free software. No one's trying to
get developers to use dpkg to create software. In fact, as you'll see
below, I actively discourage using system modules for development.
The case for pip (the Pythonista in me)
In defense of pip, the idea that Debian will keep the latest versions of
packages is insane. The idea that we can keep pace with upstream releases is
nuts, and the idea that every upstream release on pypi is ready to ship is
bananas. b-a-n-a-n-a-annas.
As a developer, I don't want to support every release, and I surely don't want
other people depending on some random snapshot.
Often times, I'll put stuff up on pypi as a preview, or to release often, and
solicit feedback without having to give out instructions on using a git
checkout (it's also easier to have them try a version from pypi so I can
cross-ref the git tag to reproduce issues when they file them)
pypi is easy, ubiquitous and works regardless of the platform, which means
less of my development time is spent packaging stuff up for platforms I don't
really care about (Arch, Fedora, OSX, Windows), even though I value
feedback from users on those systems. The effort it takes to release something
is limited to python setup.py sdist upload, and it's in a place (and in a
shape) that anyone can use it without having 10 sets of platform-local
instructions.
Even ignoring all the above, when I'm writing a new app or bit of code,
I want to be sure I'm targeting the latest version of the code I depend on,
so that future changes to API won't hit me as hard. By following
along with my dependencies' development, I can be sure that my code breaks
early, and breaks in development, not production. Upstreams also tend to not
like bug reports against old branches, so ensuring I have the latest code from
pypi means I can properly file bugs.
Lastly, I prefer virtualenv based setups for development, since I'm usually
working on many things at once. This often means version mismatches in
libraries, which brings in API changes (another whole rant here as well).
I don't want to keep installing and uninstalling packages to switch between
the two projects, and using a chroot(8) means a lot of overhead and that it's
disconnected from my development environment / filesystem, so I resort to
virtualenv to isolate my Development environment.
Final notes
I don't want to keep arguing about this. Just accept that the world's a big
place and that there exist use-cases that both apt and pip need to exist
and work in the way they're working now. At the very least, try and understand
there exist smart people on both sides, and no one is trying to screw anyone
over or keep their own little private club to themselves. Hopefully, going
forward, we can make sure that the integration between these two tools gets
better, not worse.
Help make this dream a reality. Contribute to a productive tone, not a
destructive one. In short:
Use pip without sudo always. Don't tell people to use sudo.
Use apt or dpkg when deploying system-wide.
Understand people are going to package, and they will be more concerned
about software using your library then keeping your library up to date.
Understand Debian Developers and package maintainers have to do a lot of
work when updating or sponsoring an upload.
Understand upstream developers can't be bothered to fix every issue
with every release (release early, release often) with some snapshot
you introduced into unstable.
Use pip and virtualenv in development setups, so we can upgrade your
app when we upgrade the lib.
Well at least he should be according to Sartre though I am not entirely convinced the repercussions of my choice to manufacture another folding chair were entirely thought through.
After my most recent posting the urge to do "just one more iteration" became too great and I succumbed. I therefore present version 4 of my folding chair which corrects all the previously discovered issues.
The popliteal height (420mm) and buttock popliteal length (400mm) are both comfortable for a wide selection of people. The seat slopes a few degrees front to back and the back rest no longer comes further forward than the rear of the seat.
There is a small gap above where the seat folds in when flat but that is only an aesthetic issue when being stored.
Manufacture wise the design is simple to produce although I really will have to teach our CNC router how to use the round over bit to reduce the finishing steps as currently that takes longer than the CNC operation.
In future if I make more of these I will use this design and, once she is less annoyed at me for making another chair, I am going to consult with my wife on adding some cushioning material to the seat and backrest.
And of course that concludes my furniture making for a while...yeah, right!
there have been comments which have complained about my usage of space on sheets and suggested I waste too much material. That is probably true and in my own defence I have not been working with this machine for very long and am not quite used to what I can "get away with" yet.
I was looking at the sheet after removing the last chair design and had a thought, I had not attempted a side X type folding design and perhaps I could squeeze one into the offcuts? I kinda got carried away, it roughly went:
Measure the available offcut space
Measured the remaining 18mm dowel leftover from my dowel hinge experiments
Found the largest width and height area I could get out of the sheet the CNC router ruined.
Sketched a design
Capture design to a DXF
Carefully spread the pieces over the available material in the CAM software
Generate a toolpath.
Cut material
If all of that sounds like and utterly mad way to design a size X stool, you are of course correct, but it worked, and it was a very fast process taking less than four hours from idea to stool.
There are a couple of issues:
the popliteal height is 470mm ( I was aiming at 420 and missed...badly)
It uses a lot of expensive hardwood dowel (1373mm plus cutting width and only way I could get it accurate was to use the disc sander to remove fractions till the length was correct)
I used pockets for the interference seat joints rather than through cuts and discovered that you need to allow tolerance depth (the pegs are 10mm deep and the sockets need to be at least 10.2 not the 10mm I cut)
Dowel joints are great but have a small surface area so friction fit joints work loose.
The seat went together dry fit and Paul tested it for me, however that last issue soon made me realise that this time I was going to have to resort to glue. Yes, sorry, this design needs to be glued to remain stable (I know plywood contains glue...please stop telling me that).
It is pretty simple to put together and aside from needing half the clamps in makespace to hold it in place while the glue dried, I had no trouble.
Though this is definitely not a case of use glue "sparingly" I put generous amounts in all the dowel joints and all the seat slots and got very little ooze so I guess it could have used more.
The final varnished stool is pretty robust but folds up nicely the concept of hooking to its own pivot dowel means it stays closed when flat which makes it very portable.
Total cost was an estimated 10.00 ( 4.25 dowel, 2.50 of 24mm ply, 1.75 for 18mm ply, 0.50 tool wear, 1.00 varnish) though the materials in my case could be argued to have cost nothing.
It has been suggested that I could make an entire picnic table and chairs set this way but if I did I would reduce the stool height by 50mm and examine ways to use less dowel.
Or in this case my final (and yes I am going to do something else next) chair design. It is based on the stool, in fact it is the stool design with the outer legs extended and a back rest added.
The modified design reduces the dowel requirements to 775mm but requires a bit more sheet material (cannot get this one entirely from offcuts).
Total cost was an estimated 10.50 ( 2.50 dowel, 4.50 of 24mm ply, 1.75 for 18mm ply, 0.50 tool wear, 1.25 varnish).
Because it is based on the stool design it suffers from the height issue and in addition the back rest is a bit far back to be completely comfortable.
Neither of the side X designs have flaws that interest me enough to follow the iterative approach again to solve them. Both the designs work well enough and rounded out my adventures with folding chairs and indeed furniture for now.
I have just bought a wireless phone charging system based on the Qi Inductive Power Standard. I bought a charging device which connects to a standard micro-USB cable and receivers for the Samsung Galaxy Note 2 and Samsung Galaxy S3 phones I own. Both those phones have contacts in the back of their case that are designed for wireless charging so you can install a charging device inside them. The charging devices make the case fit a little tight, and the charging device is stuck to the phone battery with contact adhesive, this makes it impractical to change the battery on a phone with such a device and makes it a little more difficult to swap out a battery case. One nice feature of the Nexus 4 is that it has Qi charging built in, that saved me $19 and was also more convenient.
I believe that the main advantage of a wireless charger is to avoid the risk of damage to the phone if it s dropped while connected to a USB charger. This allows the phone to be charged in situations where you might need to quickly or regularly unplug it to go somewhere. One example of how I might use it is when working at an office so I could charge my phone while at my desk and then quickly take it with me if I had to go to a meeting (sadly I have worked in many offices where they have so many meetings). Another example is for sysadmin work where I have to frequently visit devices to fix them.
The wireless charging mat that I bought from Kogan connects to a standard micro-USB plug, the good thing about this is that it s easy to find cables and it can take power from any PC. The bad thing about this is that the resistance of the USB cable is a factor that limits the power that a phone can receive, when using wireless charging you have the limit of the cable resistance as well as some power loss from the wireless transmission. After any extended period of charging the charging mat feels warm to the touch and the phone that s been resting on it feels warmer than usual. The warmth is an indication of energy loss which means longer charging times, a longer charging time isn t necessarily a problem as the convenience of wireless charging can allow longer charging times, but if you want to charge your phone in a hurry before you go somewhere then wireless isn t a good choice.
In the past I ve discovered that the battery in a Samsung Galaxy S3 can t be charged if the phone is at 46C [1]. 46C might seem extremely hot to people in some parts of the world (EG northern Europe and Canada) but the temperature in even southern parts of mainland Australia can get that hot and it can be hotter in central and northern parts, so phone temperature can be a real issue. Currently my house is at 21C according to a digital thermometer, the Galaxy S3 and the Note 2 are being charged from USB and report temperatures of 27C and 23C respectively. While the thermometer in my house and those in the phones probably aren t really accurate it seems reasonable to assume that the battery of a relatively idle smart-phone that s being charged will be a few degrees warmer than the ambient temperature. The Qi charger makes things a lot worse as it even feels warm to the touch. So maybe a phone on a Qi charger would be 8 degrees warmer than the ambient temperature or more. That implies that in Australian summer weather a Qi charger won t be useful outside or in any building that lacks air-conditioning. So I think we can give up on the idea of using Qi devices to charge phones at a BBQ.
The final problem I have is that the Qi device is quite small, I took the above picture with my phone face-down because no part of the charger is visible in normal use. With that size I can t just dump a phone like a Note 2 on top of the charging mat and expect it to work. I have to carefully place it so that it balances and so that the wireless receptor inside the phone matches the transmitter in the mat, if the phone isn t placed correctly then the Qi mat won t detect it and won t supply full power to the transmitter.
Conclusion
I m fairly disappointed in this device. The waste heat makes it unsuitable for Australian summer conditions and slows charging. The difficulty of correctly placing the phone reduces the convenience which is one of the major features.
The price was $19 for each charging card for the Note 2 and the S3 and $29 for the charging mat to give a total of $67. I think it s worth the money for me to cover the risk of one of my phones having it s USB port damaged. Using a Qi charger on occasion will decrease the probability of such damage and allow the phone to be used after receiving certain types of damage.
The prices of those phones nowadays are $389 for a Galaxy S3 (Kogan price), $250 for a Nexus 4 (when it was on sale in the Google store), and probably about $500 for a Galaxy Note 2 (last time Kogan offered them). So by paying $67 for Qi charging I believe that I m getting some degree of damage insurance for just over $1100 worth of phones. It seems likely that the Nexus 5 will ship with Qi charging support and that the Galaxy Note 3 will also support an optional Qi charging card (which will probably also be $19 or some similar price) so the charging mat should be useful for a long time.
While I m disappointed I don t regret buying the device. But I would be hesitant to recommend it to other people and definitely wouldn t recommend it to someone who doesn t have a significant interest and investment in smart phones.
I ve been running several Deb-o-Matic instances on several servers since ages. This service, meant to provide a way to automate the build of Debian source packages, has been the starting point for a lot of Italian developers to start packaging, and eventually become Debian or Ubuntu developers. I can t exactly tell how many packages Deb-o-Matic servers have built so far, but it has been the primary build and test environment for at least three Debian Developers since four years.
This service was hosted for free since the beginning, but the good things always come to an end. My provider decided they cannot keep our servers running (its core business is totally unrelated to hosting servers), and asked me to shut them down. I started with the two kfreebsd-* machines, and soon I will shut down i386 and amd64 as well. When all services will be down, I ll take care of removing the debian.net domains I created for them.
Deb-o-Matic development won t stop, but developers who used Deb-o-Matic daily will have to find a different solution to build and test their packages.
A client has recently asked for my advice on web editing software. There are lots of programs out there for editing web sites and according to a quick Google search there are free Windows programs to do most things that you would want to do.
The first thing I m wondering about is whether the best option is to just get a Linux PC for web editing. PCs capable of running Linux are almost free nowadays (any system which is too slow for the last couple of Windows versions will do nicely). While some time will have to be spent in learning a new OS someone who uses Linux for such tasks will be able to use fully-featured programs such as the GIMP which are installed as part of the OS. While it is possible to configure a Windows system to run rsync to copy a development site to the production server and to have all the useful tools installed it s much easier to run a few apt-get or yum commands to install the software and then copy some scripts to the user s home directory.
The next issue is whether web editing is the best idea. Sites that are manually edited tend to be very simple, inconsistent, or both. Some sort of CMS seems to be the better option. WordPress is a CMS that I m very familiar with so it s easy for me to install it for a client, while I try and resist the temptation to force my favorite software on clients there is the issue that I can install WordPress quickly which therefore saves money for my client. WordPress is a CMS that supports installing different themes (and has a huge repository of free themes). The content that it manages consists of pages and posts , two arbitrary types of document. Supporting two types of document with a common look and feel and common important data in a side-bar seems to describe the core functionality used by most web sites for small businesses.
Does anyone have any other ideas for ways of solving this problem? Note that it should be reasonably easy to use for someone who hasn t had much experience at doing such things, it shouldn t take much sysadmin time to install or cost to run.
While I suspect that professional speakers have separate presentation
laptops that they use only to give talks, I don't do this often enough to
justify the hassle and cost of a separate machine. However, I do use a
separate user account to present from.
It allows me to focus on my presentation and not stress out about running
into configuration problems or exposing private information. But mostly, I
think it's about removing anything that could be distracting for the
audience.
The great thing of having a separate user for this is that you can do whatever
you want in your normal account and still know that the other account is ready
to go and configured for presenting on a big screen.
Basics
The user account I use when giving talks is called presenter and it has
the same password as my main user account, just to keep things
simple. However, it doesn't need to belong to any of the UNIX groups that my
main user account belongs to.
In terms of configuration, it looks like this:
power management and screen saver are turned off
all sound effects are turned off
window manager set to the default one (as opposed to a weird tiling one)
desktop notifications are turned off
Of course, this user account only has the software I need while
presenting. You won't find an instant messaging, IRC or Twitter client
running on there.
The desktop only has the icons I need for the presentation: slides and
backup videos (in case the network is down and/or prevents me from doing a
live demo).
Web browsers
While I usually have my presentations in PDF format (for maximum
compatibility, you never know when you'll have to borrow someone else's
laptop), I use web browsers (different ones to show that my demos work with
all of them) all the time for demos.
Each browser:
clears everything (cookies, history, cache, etc.) at the end of the session
has the site I want to demo as the homepage
only contains add-ons or extensions I need for the demos
has the minimal number of toolbars and doesn't have any bookmarks
has search suggestions turned off
never asks to remember passwords
Terminal and editors
Some of my demos may feature coding demos and running scripts, which is why
I have my terminal and editor set to:
a large font size
a color scheme with lots of contrast
It's all about making sure that the audience can see everything and follow
along easily.
Also, if you have the sl package installed system-wide, you'll
probably want to put the following in your ~/.bashrc:
alias sl="ls"
alias LS="ls"
Rehearsal
It's very important to rehearse the whole presentation using this
account to make sure that you have everything you need and that you are
comfortable with the configuration (for example, the large font size).
If you have access to a projector or a digital TV, try connecting your
laptop to it. This will ensure that you know how to change the resolution
of the external monitor and to turn mirroring ON and OFF ahead of time
(especially important if you never use the default window manager or desktop
environment). I keep a shortcut to the display settings in the sidebar.
Localization
Another thing I like to do is to set my operating system and browser
locales to the one where I am giving a talk, assuming that it is a western
language I can understand to some extent.
It probably doesn't make a big difference, but I think it's a nice touch and
a few people have commented on this in the past. My theory is that it might
be less distracting to the audience if they are shown the browser UI and
menus they see every day. I'd love to have other people's thoughts on this
point though.
Also, pay attention to the timezone since it could be another source of
distraction as audience members try to guess what timezone your computer is
set to.
Anything else?
If you also use a separate account for your presentations, I'd be curious to
know whether there are other things you've customised. If there's anything I
missed, please leave a comment!
I love to say that Python is a nice subset of Lisp, and I discover that it's
getting even more true as time passes. Recently, I've stumbled upon the
PEP 443 that describes a way to
dispatch generic functions, in a way that looks like what CLOS, the Common
Lisp Object System, provides.
What are generic functions
If you come from the Lisp world, this won't be something new to you. The
Lisp object system provides a really good way to define and handle method
dispatching. It's a base of the Common Lisp object system.
For my own pleasure to see Lisp code in a Python post, I'll show you how
generic methods work in Lisp first.
To begin, let's define a few very simple classes.
(defclasssnare-drum() ())
(defclasscymbal() ())
(defclassstick() ())
(defclassbrushes() ())
This defines a few classes: snare-drum, symbal, stick and brushes,
without any parent class nor attribute. These classes compose a drum kit,
and we can combine them to play sound. So we define a play method that
takes two arguments, and returns a sound (as a string).
(defgenericplay(instrumentaccessory) (:documentation"Play sound with instrument and accessory."))
This only defines a generic method: it has no body, and cannot be called
with any instance yet. At this stage, we only inform the object system that
the method is generic and can be then implemented with various type of
arguments. We'll start by implementing versions of this method that knows
how to play with the snare-drum.
Now we just defined concrete methods with code. They also takes two
arguments: instrument which is an instance of snare-drum and accessory
that is an instance of stick or brushes.
At this stage, you should note the first difference with object system as
built into language like Python: the method isn't tied to any class in
particular. The methods are generic, and any class can implement them, or
not.
Let's try it.
As you see, the function called depends on the class of the arguments. The
object systems dispatch the function calls to the right function for us,
depending on the arguments classes. If we call play with instances that
are not know to the object system, an error will be thrown.
Inheritance is also supported and the equivalent (but more powerful and less
error prone) equivalent of Python's super() is available via
(call-next-method).
In this example, we define the stick and brushes classes as subclass of
the accessory class. The play method defined will return the sound
BIIING! regardless of the accessory instance that is used to play the
cymbal. Except in the case where it's a brushes instance; only the most
precise method is always called. The (call-next-method) function is used
to call the closest parent method, in this case that would be the method
returning _"BIIING!".
Note that CLOS is also able to dispatch on object instances themself by
using the eql specializer.
But if you're really curious about all features CLOS provides, I suggest you
read the
brief guide to CLOS by Jeff Dalton
as a starter.
Python implementation
Python implements a simpler equivalence of this workflow with the
singledispatch function. It will be provided with Python 3.4 as part of
the functools module. Here's a rough equivalence of the above Lisp
program.
@functools.singledispatch defplay(instrument,accessory): raiseNotImplementedError("Cannot play these")
@play.register(SnareDrum) def_(instrument,accessory): ifisinstance(accessory,Stick): return"POC!" ifisinstance(accessory,Brushes): return"SHHHH!" raiseNotImplementedError("Cannot play these")
We define our four classes, and a base play function that raises
NotImplementedError, indicating that by default we don't know what to do.
We can then write specialized version of this function with a first
instrument, the SnareDrum. We then check for the accessory type that we
get, and return the appropriate sound or raise NotImplementedError again
if we don't know what to do with it.
If we run it, it works as expected:
The singledispatch module looks through the classes of the first argument
passed to the play function, and calls the right version of it. The first
defined version of the play function is always run for the object class,
so if our instrument is a class that we did not register for, this base
function will be called.
For whose eager to try and use it, the singledispatch function is
provided Python 2.6 to 3.3 through the Python Package Index.
Limitations
First, as you noticed in the Lisp version, CLOS provides a multiple
dispatcher that can dispatch on the type of any of the argument defined
in the method prototype, not only the first one. Unfortunately, Python
dispatcher is named singledispatch for this good reason: it only knows to
dispatch on the first argument. Guido van Rossum wrote a short article about
the subject that he called
multimethod a
few years ago.
Then, there's no way to call the parent function directly. There's no
equivalent of the (call-next-method) from Lisp nor the super() function
that allows to do that in Python class system. This means you will have to
use various trick to bypass this limitation.
So while I am really glad that Python is going toward that direction, as
it's a really powerful way to enhance an object system, it really lacks a
lot of more advanced features that CLOS provides out of the box.
Though, improving this could be an interesting challenge. Especially to
bring more CLOS power to Hy. :-)
A book I'm writing that will be launched soon, talking about
designing Python applications, state of the art, and various
Python tips.
If you want to be the first to hear about the launch, subscribe
now.
After years of waiting, Google has finally enabled IPv6 for their
email service Gmail. And a few weeks ago, they updated their policy,
adding one specific rule: reject email from IP addresses with no reverse
name:
% nc -Cv gmail-smtp-in.l.google.com. smtp
Connection to gmail-smtp-in.l.google.com. 25 port [tcp/smtp] succeeded!
220 mx.google.com ESMTP bz2si13656083wjc.108 - gsmtp
HELO boo.example.com
250 mx.google.com at your service
MAIL FROM: <me@example.com>
250 2.1.0 OK bz2si13656083wjc.108 - gsmtp
RCPT TO: <you@gmail.com>
250 2.1.5 OK bz2si13656083wjc.108 - gsmtp
DATA
354  Go ahead bz2si13656083wjc.108 - gsmtp
Subject: Test
From: Me <me@example.com>
To: You <you@gmail.com>
Test.
.
550-5.7.1 [2001:db8:8e3f:43c7::12      16] Our system has detected that this
550-5.7.1 message does not meet IPv6 sending guidelines regarding PTR records
550-5.7.1 and authentication. Please review
550-5.7.1 https://support.google.com/mail/?p=ipv6_authentication_error for more
550 5.7.1 information. bz2si13656083wjc.108 - gsmtp
That sucks
It is not a sane anti-spam measure, because not having a reverse
name tells absolutely nothing about the email emitter or the
message itself: it only indicates that the email emitter has a lame
access provider. Specifically:
spammers can have perfect reverse names;
regular email emitter can have no reverse name because
their access provider suck, and have no way of fixing it
because all access providers suck the same way.
While IPv6 is the future of the Internet, this measure
discourages its use. Yes, providing no reverse names suck, but it is
by no mean the user's fault, and since IPv6 is more complicated to
implement than IPv4, Internet actors must tolerate youth errors or
people will just keep what works, i.e. IPv4.
By the way, I would love to have a perfect Internet access provider,
but that does not exist where I live, and I do not think it exists at all
anywhere. Google, instead of complaining
about lame access providers, you are welcome to offer me a fibre service
with decent upload rate, static IPv4, static IPv6 /64, customizable
reverse DNS for IPv4 and IPv6, and full respect of the network
neutrality. Until then, I am doing the best I can with the least bad
provider available.
Workaround
As I said, their is an easy workaround. Google does not accept my
mail on IPv6? Fine, I will keep using IPv4. Only for Google of course,
no need to punish the whole Internet for Google's damn restrictions.
With Postfix, you can do that this way (thanks to Christian
Skala for his blog post about this problem). In
/etc/postfix/master.fr, enable an IPv4-only SMTP
client service:
smtp4 unix - - - - - smtp -o inet_protocols=ipv4
Then, in /etc/postfix/main.cf, define a transport
map if you do not already use one:
transport_maps = hash:/etc/postfix/transport
Create that transport map
/etc/postfix/transport or complete it:
gmail.com smtp4:
Finally, hash that transport map and have Postfix reload its
configuration:
# postmap /etc/postfix/transport
# service postfix reload
I seem to be adhering to Beckett's approach recently but for some reason, after my previous stool attempts, despite having a functioning design I felt I had to do just one more iteration.
Going back to a previous concept of having five legs instead of three while this did not improve the rotational problems with the 12mm thick material, it did make the design more stable overall and less prone to tipping.
The five legged solution realised in 18mm plywood resulted in my final design for this concept. As my friend Stephen demonstrates the design is pretty solid even for those of us with a more ample frame. There are now a couple of them in use at the space alongside the three legged earlier versions.
I was finally satisfied with the result and thought I was done with furniture making for a while. My adorable wife then came up with a challenge, she wanted a practical foldable chair her requirements were:
Must be robust enough to cope with guests of all sizes
Use as little storage space as possible.
Not ugly.
Inexpensive enough they can be given as gifts.
Things for individual humans to sit on raised off the floor, or chairs as we call them, have been around for a long time. My previous research for the stool indicated that chairs have a long history with examples still surviving from the ancient egyptians. From this I assumed there would be nothing novel in this project and to quote the song it's all been done before
Given this perspective my research started with an image search for "folding chair". The results immediately showed there were two common shapes. Either the chair base was formed with a pair of linked X shapes with the seat across the top, or an A frame style where the seat is across the centre.
My initial thoughts were to replicate the IKEA style A frame design until I noticed that some designs were made from a single sheet of timber with a small number of profile cuts. I searched for pre-existing design files but found none, perhaps I had found something novel to do after all.
Some quick measurements of chairs in shops (and more weird looks, mainly from my family) suggested 900mm is generally the highest a chair ought to stand. I selected a popliteal height of 420mm as a general use compromise which is a bit less than the 430mm of most mass produced chairs. I also decided there should be a front to rear drop across the seat which ought to improve comfort a little.
Material selection was based upon what I had to hand which consisted of a couple of sheets of structural plywood (1220x606x18mm temperate softwood - probably spruce although not specified) which had not become stools yet. Allowing for edge wastage and tool width this gave me a working area from a sheet of 1196x582mm.
I sketched the side view of the chair numbering the three parts. I decided part 1 would be 1000mm total height with top and bottom cross braces 80mm high, assuming the 900mm tall target, the A frame apex would be at 820mm height.
If we assert that the apex is immediately below the top cross brace on part 1 this gives 920mm at which point we have two sides of a right angled triangle (820 and 920) from which we can calculate the top angle is 26 . This also means part 2 will be 840mm long with the same 820 height this gives an angle of 10 .
I did the maths for the seat triangle using the 36 angle and 420mm popliteal height. Having experienced how flexible 18mm plywood was in the face dimension I decided to make the frame sides 50mm wide leaving, after 6mm tool path widths, enough space for a 358mm wide seat .
Once the dimensions were decided the design went pretty quickly producing something that looked similar to the designs I had seen earlier.
Generating toolpaths for this design proved challenging with the CAM software we had available, mainly because arranging multiple "inner" and "outer" cuts along the same path and having the tabs line up was obviously not an anticipated feature.
Things had been going far too well for me and during the routing operation our machine decided to follow an uncommanded toolpath excursion mid job (it cut a dirty great hole through the middle of my workpiece where I did not want it) ruining the sheet of material.
Fortunately, once factory reset and reconfigured, the machine ran the job correctly the second time although we still do not know why it went wrong. The parts were cut free of their tabs and hinges fitted.
The resulting design worked with a couple of problems:
I had made an error in my maths and added when I should have subtracted, as a result the seat slopes back to front which is not very comfortable.
The chair feels very wide and tall.
The front face (part 1) flexes alarmingly between the seat and the ground when subjected to large loads.
So time for a second iteration, this time I selected a thicker plywood to reduce the bend under large loads (OK already, I mean me). After shopping around for several days I discovered that unlike 12mm and 18mm thick plywood 24mm thick is much harder to find at a sensible price especially if you want it cut into 1220x606 sheets from the full 1220x2440.
I eventually physically went to Ridgeons and looked at what they actually had in the warehouse and got a price on a sheet of brazilian elliotis pine structural plywood for 43.96 which they cut for me while I waited. Being physically present also gave me the opportunity to pick a "less bad" sheet from the stack much to the annoyance of the Ridgeons employee for not just taking the top one.
This time I reduced the apex height by 30mm, the length of part 1 by 80mm. I also reduced the frame width by 10mm relying on the increased thickness of the plywood to maintain the strength. In area terms it is actually an increase in material (50mm*17.7mm = 885 against 40mm*22.80 = 912). I also included rebates for the top hinges within the design allowing them to be mounted flush within the sheet width.
The new design was cut (without incident this time) and the edges rounded off. I also added some simple catches to keep the seat and back inline while being transported.
While this version worked I had made a couple of mistakes again. The first was simply a radius versus diameter error on the handles which meant too much material was removed from a high stress area causing increased bending.
The second error was a stupid mistake that where I had worked the latch holes in the seat to the wrong side of my measure line meaning the apex angle was 35.5 not the expected 33.6 which meant the backrest felt "too far forward"
The third version rectified those two errors and improved the seat front curve a little to further reduce the unneeded material in the back rest.
The fabrication of this design was double sided allowing for the seat hinge to be fully rebated and become flush and also adding some text similar to the stools.
This version still suffers from a backrest that is a bit too far forward and my sons complain it makes them sit up too straight. The problem is that the angle of the front face (23.6 ) means that to move the rest back 20mm means the piece needs to extend another 50mm beyond the frame apex which would probably make the chair feel tall again.
I guess this is a compromise that would take another iteration or two to solve, alas my wife has declared a moratorium on more chairs unless I find somewhere to put the failed prototypes other than her conservatory.
One other addition would be a better form of catch for transport. The ones in version 2 work but are ugly, magnets inset into the frame have been suggested but not actually implemented yet.
In conclusion I think I succeeded with the original brief and am pretty pleased with the result. A neatly folding chair that can be stacked simply by having a pile of them and are easy to move and setup.
The price per chair is a little higher than I would like at 22 ( 11 for timber, 5 for hinges and screws , 5 for varnish and 1 for tool wear) plus about 2 hours labour (two sided routing plus roundover takes ages)
Today I link you to a video narrated by the legendary Carl Sagan The Frontier is Everywhere.
Partial quotes:
We were hunters and foragers. The frontier was everywhere. We were bounded only by the earth, and the ocean, and the sky. The open road still softly calls. Our little terraqueous globe as the madhouse of those hundred thousand millions of worlds. We, who cannot even put our own planetary home in order, riven with rivalries and hatreds; are we to venture out into space?
By the time we are ready to settle even the nearest other planetary systems, we will have changed For all our failings, despite our limitations and fallibilities, we humans are capable of greatness How far will our nomadic species have wandered, by the end of the next century, and the next millennium?
Our remote descendants, safely arrayed on many worlds through the solar system, and beyond, will be unified, by their common heritage, by their regard for their home planet, and by the knowledge that, whatever other life may be, the only humans in all the universe, come from Earth.
They will gaze up and strain to find the blue dot in their skies. They will marvel at how vulnerable the repository of all our potential once was, how perilous our infancy, how humble our beginnings, how many rivers we had to cross, before we found our way.
It s a somewhat strange feeling to spend time fixing things that broke
instead of implementing new things, but it s not like I m a creative
guy anyway
buildd.debian.orgwent down,
but
it s now up again
thanks to the relevant admins. The
CGI part mentioned by Philipp
was fun to debug: the CGI worked when called from a shell, but not
from Apache (with an apparently strange DNS resolution error). I
suggested attaching it with strace, and the result was even
stranger: a connection to nscd s socket was attempted but the DNS
resolution through the network wasn t. A closer look revealed the
nsswitch.conf file was read, and its configuration was OK, so
what? Looking at libnss_dns.so.2, one could see the usual
syscalls for library loading: open, read, fstat, mmap oh
wait, mmap failed with ENOMEM (Cannot allocate memory). Tollef
bumped the rlimits on the Apache side,
and that was it.
Linux kernel ABI bump notifications: they were
acting weird
since kernel people resumed uploading -trunk- kernels to
experimental. That was identified a while ago, but since I like
tested bugfixes,
I actually did wait for it to happen; fixed in
r68876.
Of course, d-i s git repository
was updated
to bump the ABI from 3.10-2-* to 3.10-3-* accordingly.
#722939 was reported against
udev-udeb since depending on a deb library isn t a good thing
when you re an udeb binary.
Trying to look into d-i build failures earlier this month,
I thought I managed to reproduce the issue,
but that was just my misunderstanding the way apt works. Long story
short, *InRelease and *Packages files are checked before
they re put under lists/; modifying the contents isn t expected:
the modification time is used to set the If-Modified-Since header
when trying to fetch a new version from the server, and it s OK to
get a 304 Not Modified in that case. As a side effect, that means
the files can be hand-edited, for example because you need to work
around the dependency bug mentioned above, and one will still get
Hit lines for all those files. If something goes wrong, one can
still rm the files and start over, but that looks like a large
hammer. Let s see if the issue can get reproduced (and debugged!)
later on.
For those last two points, the long term plan is:
To check udeb installability automatically to catch such dependency
issues as early as possible.
To keep many more logs, so that one can still read the whole output
a few weeks after the fact, and so that one can compare some logs
to try and spot difference in a semi-automated fashion.
Hopefully getting this done this week (famous last words, eh?).
One of the things that was added to WebAuth when we added support for multifactor authentication was the
ability to talk to an external user information service. We wanted to
keep the details of the multifactor authentication implementation out of
WebAuth itself and encapsulate them in a service that WebAuth calls so
that we could replace it with something else later and so that each site
could do multifactor authentication in their own way. (It looks like
we're going to be using that capability, so I'm very glad we designed it
that way.)
That, however, also means that the same interface used by WebAuth could be
used for other things. This PAM module is the first non-WebAuth use of
that API. It provides the ability to prompt for an OTP code as part of
the PAM authentication stack and then verify that code against the WebAuth
user information service.
This is only the bare beginnings of a full PAM integration with the user
information service, and it doesn't do lots of things that it could. (For
example, do anything with the list of configured factors, show reasonable
error messages if a user doesn't have the right things configured, or even
support the SMS multifactor method that requires a callout to send the SMS
message in advance of the authentication.) But it works, and for any
multifactor method that doesn't require a user interaction beyond a code
entry, it's fairly clean.
This is the first public release, with documentation and a test suite.
(There was an earlier, undocumented internal 0.1 release.) It's too soon
to say whether we'll keep using this in the long run, but we're using it
right now in production and will continue to do so for a little bit at
least. I suspect this will prove a viable long-term approach, with some
possible changes to the way the user information service abstraction layer
works.
You can get the latest version from the
pam-webauth-otp distribution page.
It seems I'm catching up with the pace of this course I'm following and that is compelling me to go back to posting on my blog, Arte y cultura en circulaci n: crear y compartir en tiempos digitales .
This week's lesson is (again, in Spanish) Las fronteras del remix (the boundaries of remixes). An interesting text, open to everybody (regardless of whether you are signed up for the course or, I hope, whether time has passed since the course took place).
And this week's homework is to find "our favorite" non-original work (I picked one among my favorite works And, yes, this is partly because I am part of the "club" of deniers of true originality: We cannot create anything without being part of a surrounding culture, without a common heritage and language with which we speak to our audience) and to find something about it, anything considered important or significative as to its antecedents. What do I like about this work, what grabs my attention. Do I consider it to be a true new creative work? Why?
I am taking as an example Leo Masliah, an Uruguayan writer and musician (writer and interpreter). I have followed and enjoyed Masliah's work since 1996, and although by far I'm most familiar with his musical works, I have two books (a novel and a series of short stories). Among his facets, I most enjoy the acid, nihilistic/dadaistic streaks. I chose three of his songs to talk about I am linking to anonline resource where possible, but uploading the three songs to this blog to make his work better known, so that people understand what I talk about, and with my best intentions. Of course, if there is any request to remove the material, I will do it right away. I hope this can be seen as fair/academic use, although this blog is somewhat widely read.
This song was in the first Masliah cassette I came across, Although musically it is an original work, the lyrics are a clear, almost line-by-line reply to the ever-repeated Unicornio song, by Silvio Rodr guez. This song (which I'm sure that every Spanish speaker reading this lines knows, like it or not It defines for me a good deal of Rodr guez hyper-sweetness and clicheness) has been analyzed over and over looking for a meaning. Silvio recorded this song in 1981, and by 1987 Masliah published this answer, mocking each of the lines.
So, this song can be seen as an original creation, as it contains no literal copy neither of the music nor of the lyrics of the original, but it cannot be understood without being familiar with Silvio's lost unicornio. It would just be an almost-dadaistic rant. But every person that has tasted Silvio Rodr guez cloying song will surely laugh with this one.
I find this to be a very unique piece. It bonds together Argentinian folklore and USA pop.
Masliah sings the famous Argentinian song Zamba de Balderrama, (Castilla / Leguizam n), a song lamenting that the very popular bar and artist stage Balderrama, in Salta (North-Western corner of Argentina), seemed to be on the brink of closing. Of course, when Mart n, Constanza, Regina and me went to Balderrama in July 2010, the danger of closing this place had long been averted. And basically every Argentinian knows this song by heart.
The interesting part is that Masliah sings this song (as he presents it as the closing piece for one of his concerts) being short on time, and decides to present two acts together: Zamba de Balderrama and We don't need another hero, by Tina Turner, from the Mad Max soundtrack. So, of course, even if it's obvious that Masliah had to stretch bits to make them fit together, he achieved a very funny, interesting and unique blend of two completely unrelated works. He derives from one as well as from the other, but creates something unique and new.
I was thinking what to write for this assignment , and had already chosen the two other songs. Yesterday, we were visiting our friends Octavio and Claudia, in Guanajuato, and I heard for the first time the original(?) version of Donna Lee, by Miles Davis (although often credited to Charlie Parker). That led me to remember Masliah's interpretation, in his Cl sicos album. This album is basically made up with similar excercises: Taking an instrumental piece, with Masliah singing over it. Some of the lyrics follow the story (i.e. the children stories), others just talk nonsense to illustrate a point (i.e. "La voz del medio", "the middle voice") follows the non-protagonist score trying not to grab much attention to the lyrics but to highlight the often ignored melody)... Donna Lee is just a fun excercise on following the melody asking what was in the head of the author that led him to invent such a strange, hard music.
Masliah is a great music performer, although often it seems he tries to hide it (i.e. by abusing the dissonances, ex-profeso singing off-key, etc), and a very funny and crazy author. Most of his works have a deep satirical tone, and it's common to find either simple winks or complete "borrowings" in a clear remix fashion, but nobody will doubt on the originality of his works.
DebConf 13 report (by Andreas Tille)
General impression
I'm beginning my DebConf report in an unofficial
"Scenic Hacklab" right at the edge of the lake in Yverdon. This
is the right place to memorise the last days. When I started from
this place cycling to Le Camp 12 days ago I was full of great
expectations and what should I say - the reality has even beaten
these.
Once it comes about comparing DebConfs even if it is an unfair
comparison due all the differences my secret long term favourite was
Helsinki very closely followed by Argentina and also very closely
followed by all the other great DebConfs I joined (and I joined all in
Europe). Would Le Camp be able to beat it? The short answer is: Yes,
it is now my favourite DebConf while I think I do not suffer from the
last-Debconf-was-the-best-DebConf-syndrome (and I realised there are
others
thinking the same).
As you might probably know I'm a bit addicted to swimming. While
Helsinki had admittedly the better conditions I was at least able to
fix the distance issue using my bicycle. (Hey, those Le Camp
photographers did a great job in hiding the fact that you can not
actually touch the lake right from the meadow of Le Camp.) Being able
to have my bicycle at DebConf scored some extra points. However, the
really great view of the lake, the inspiring "Scenic Hacklab" which
was my favourite place has bumped DebConf13 at first place in my
personal ranking.
So it comes quite natural to say: "Kudos to the great organisation
team!" They did a Swiss-like precise work and perfectly succeeded in
hiding any problems (I assume there were some as always) from the
attendees so everything went smooth, nice and shiny for the attendees.
The local team was even precise in setting up great weather conditions
for DebConf.
While saying thanks to the local team I would like to also explicitly
thank Luca Capello who has quite some share that this DebConf was
possible at all (while I have to decrease my DebConf score one point
because he was not really there - Luca to bad that you were not able to
come full time!) Also thanks to Gunnar and Gannef who helped remotely
(another score down because I were missing them this year as well).
Even if it was my favourite DebConf I was not able to work down my
todo list fully (which was not only uploading one package per day
which I at least statistically fullfilled). But that's probably a
general feature of todo lists anyway. One item was definitely done:
Doing my daily swimming BoF. I actually was able to do the other
parts of the triathlon which was skipped by Christian and have done in
summary about 150km cycling with 3500m elevation and estimated 7-8km
swimming (0m elevation ;-)). Considering the great view at sunrise
over the lake I was not hating my "Senile bed
escape" disease too much (I was every day waking up at sunset) -
it was simply a great experience. I will never forget seeing water
drips glimmering like gold inside the morning sun while seeing the
Alps panorama in the distant. I hope I was able to help all
interested swimmers with the DebConf Beach Map
which was just a by-product of my activities in DebCamp.
Speaking about OSM: I was astonished that the area was way less
covered than I expected. Thanks to several DebConf attendees the
situation became better and the map does not only show random trees in
the wild but also the tracks leading to these. (Remark: It was no
DebConf attendee who is responsible for plastering the map with single
trees.) While I had my mapping focus basically close to the edge of
the lake I was also able to even map my very
own street. :-)
I clearly remember one specific mapping tour when I was invited by the
DPL: He convinced me to join him on a bicycle tour and since I was
afraid to get fired I joined him instead to keep on hacking. Also
Sorina was brave enough to join us on the tour and she did quite well.
(Sorina, do you remember the agreement about your work on the installer?
;-)) Lucas described the tour as: going uphill on only asphalted roads.
Sorina and me were witnessing the mighty DPL powers when we left the
wood around Le Camp to reach the described road: The asphalt was just
put onto the road - no doubt that it was done on the immediate demand of
mighty DPL. :-)
DebCamp time was flying like nose dive and a lot of known (and unknown)
faces arrived at Le Camp. What I really liked a lot this year was that
several really young children has pulled down the average age of DebConf
attendees. I clearly remember all the discussion one year ago what to
do about children. As always the issue was solved in a typical Debian
way: Just do it and bring your children - they had obviously a great
time as well. I think the youngest child was 2 months and the oldest
"child" above 20. ;-) Actually Baptiste Perrier did great in making the
C&W party a success and had obviously a nice time. (I wished my son
would have been able to come as well but he needs to write his
bachelor s thesis in physics. :-()
It was nice to see the kids using all playing facilities and
communicating with geeks. Also I would like to point out that even the
very young attendees had their share at the success of DebConf: Just
think of the three "bell ringing assistants" who helped me ringing the
bells for lunch and dinner. I've got this cool job from Didier in the
beginning of DebCamp. I must say having some real bells ringing is by
far nicer than just the "lunch / dinner starts in 10 minutes" from IRC
bot. The only thing I did not understand was that people did not
considered ringing the bells at 8:00 for breakfast as a good idea.
Regarding the food in general I would also like to send kudos to the
kitchen: It was tasty, freshly prepared, regional food with a good
change rate. I really liked this. Extra points for having the chance
to sit outside when eating.
Talks
But lets have a look into the conference programme. I'd really
recommend watching the videos of the talks Bits
from the DPL (video)
and Debian
Cosmology (video).
I considered both talks as entertaining and interesting. I also
really hope that the effort Enrico Zini started in Debian
Contributors (video)
will be successful.
I had some talks and BoFs myself starting with Why
running a Blend (video)
and I admit that (as usual) the number of attendees was quite low even
if I think there is some proof (see below) that it is interesting for
way more people who should consider working more "blendish" in their
team. Do you know how to recruit one developer per year and relax the
man power problem in your team? Feel free to watch the video.
We have confirmation that ten DDs of our team have considered to join
Debian only because Debian Med exists. Admittedly biology and
medicine are really leaf topics inside the Debian universe. So if
even this topic that has a very tiny share of the Debian users is able
to attract this level of attention - how many more people could we win
for multimedia, games, GIS and others?
So if you feel you are quite overworked with your packaging and you
have no time this is most probably wrong. The amount of time is
basically a matter of priorities you set for your tasks. Try to put
some higher priority onto using the just existing Blends tools I
explained in my talk to attract more users and developers to your team
and by doing so spread the workload over more people. It works, the
prove was given in my
main talk. So before you start working on a specific
package you should wonder who else could have an even stronger
interest to get this work done and provide him with some additional
motivation and help to get the common goal done.
The interesting thing is that my BoF about How
to attract new developers for your team (video)
- which was a simple report about some by-product of the Blends work -
made it into the main talk room and got way more attention. For me
this is the proof that the Blends concept itself is probably badly
perceived as something like "a few outsiders are doing damn specific
stuff which is not really interesting for anybody else" instead of
what is really is: Smoothing the way from specific upstream
applications to the end user via Debian.
Once you see the video
of this BoF you can observe how my friend Asheesh Laroia became
more and more excited about the Blends concept and admitted what I
said above: We should have more Blends for different fields. Funnily
enough Asheesh asked me in his excitement to talk more about Blends.
This would have been a really good suggestion ten years ago. At
DebConf 3 in Oslo I had my very
first talk about Blends (at this time under the name "Debian
Internal Projects"). I continuously kept on talking about this
(MiniDebConf
Peking 2005, DebConf
5, Helsinki (video),
DebConf
7, Edinburgh (video),
DebConf
8, Mar del Plata (video),
DebConf
9, C ceres (video),
MiniDebConf
Berlin 2010 (video
in German),
MiniDebConf
Paris 2010 (not video recorded),
DebConf
11, Banja Luka (video)
... and these are only (Mini)DebConfs my talks page is full
of this topic)
and every new year I try different ways to communicate the idea to my
fellow Debianistas. I'm wondering how I could invent a title +
abstract avoiding the term Blends, put "Git", "release" and "systemd
versus upstart" in and being able to inform about Blends reasonably by
not becoming to off topic with the abstract.
I also registered the Debian
Science round table. I admit we were lacking some input from
remote via IRC which used to be quite helpful in the past. The
attendees agreed upon the handling of citations in debian/upstream
files which was invented by Debian Med team to create even stronger
bounds to our upstream developers by giving their work extra reward
and providing users with even better documentation (see my summary in
Wiki).
As usual I suggested to create some Debian Science offsprings like
"Debian Astronomy", "Debian Electronics", "Debian Mathematics",
"Debian Physics" etc. who could perfectly leave the Debian Science
umbrella to get a more fine grained structure and a more focused team
to enhance the contact to our users. Unfortunately there is nobody
who volunteers to take over the lead for such Blends. I have given a
short summary about this BoF on the Debian
Science mailing list.
In the Debian
Med meeting I have given some status report. No other long term
team members were attending DebConf and so I gave some kind of
introduction for newcomers and interested people. I touched also the
DebiChem topic which maintains some packages that are used by
biologists frequently and so we have a good connection to this team.
Finally I had registered three BoFs in Blends I'm actually not (or not
yet) active part of. My motivation was to turn the ideas I have
explained in my
main talk into specific application inside these teams and helping
them to implement the Blends framework.
In the first BoF about Debian GIS I have shown the usual team metrics
graphs to demonstrate, that the one packaging team Pkg-OSM is in danger
to become MIA. There are only three persons doing actual uploads. Two
of them were at DebConf but did not joined the BoF because they do not
consider their contribution to Pkg-OSM as a major part of their general
Debian work. I will contact the main contributor David Paleino about
his opinion to move the packages step by step into maintenance of Debian
GIS packaging team to try to overcome the split of two teams that are
sharing a good amount of interest. At least if I might become an
Uploader for one of the packages currently maintained by Pkg-OSM I will
move this to pkg-grass-devel (which is the name of the packaging team of
Debian GIS for historical reasons). The attendees of the BoF have
considered this plan as sensible.
Moreover I talked about my experiences with OSGeo Live - an Ubuntu
derivative that tries to provide a full tool chain to work on GIS and
OSM problems ... basically the same goal as Debian GIS has just
provided by the OSGeo project. I'm lurking on OSGeo mailing list when
I asked explicitly I've got the answer that they are working together
with Debian GIS and are using common repository (which is IMHO the
optimal way of cooperation). However, it seems that several
protagonists of OSGeo Live are underestimating the resources provided
by Debian. For instance there was a question about Java packaging
issues but people were not aware about the existence of the
debian-java mailing list. I was able to give an example how the
Debian Med team managed to strengthen its ties to BioLinux that
is also an Ubuntu derivative for biologists. At our first Debian
Med sprint in 2011 we invited developers from BioLinux and reached
a state where they are using the very same VCS on Alioth where we are
maintaining our packages. At DebConf I was able to upload two
packages where BioLinux developers did certain changes for enhancing
the user experience. My "work" was just bumping the version number in
changelog and so we did profit from the work of the BioLinux
developers as well as they are profiting from our work. I plan to
dive a bit more into Debian GIS and try to strengthen the connection
to OSGeo Live a bit.
The next BoF was the Debian Multimedia meeting. It was nice that the
current leader of Ubuntu Studio
Kaj Ailomaa joined the meeting. When I was explaining my ideas about
cooperation with derivatives I repeated my detailed explanation about
the relation with BioLinux. It seems every topic you could cover
inside Debian has its related derivative. So to me it seems to be
quite natural to work together with the developers of the derivative
to join forces. I actually consider a Blend a derivative done the
right way = inside Debian. The final work for the derivers that might
be left for them is doing some shiny customising of backgrounds or
something like this - but all the hard work could and should be done
in common with the relevant Debian team. My dream is to raise such
relevant teams inside Debian ... the Blends.
Finally the last BoF of this series was the Debian Games meeting. As
always I presented the team metrics graphs and the Debian Games team
members who attended the BoF were quite interested. So it seems to be
some unknown fact that team metrics are done
for several teams in side Debian and so I repeat the link to it for
those who are not yet aware of it. As a result of the BoF Debian
Games team members agreed to put some more effort into maintaining
their Blends tasks. Moreover Miriam Ruiz wants to put some effort
into reviving Debian Jr. Regarding Debian Jr. there was an
interesting talk
about DouDouLinux - in case you might want to watch the video I'd
recommend skipping the first 30min and rather watch the nice live
demo. There was also an ad hoc BoF about Debian Jr scheduled to bring
together all people interested into this cute project and Per Anderson
volunteered to take over the lead. I have given a
summary about this specific BoF at the Debian Jr list.
For some other talks that I'd regard as remarkable for some reasons:
I'd regard the talk "Debian-LAN"
by Andreas Mundt as some hidden pearl because it did not got a lot
of attention but after having seen the video I was quite impressed -
specifically because it is also relevant for the Blends topic.
Memories
I also liked "Paths
into Debian" by Moray Allan (and I was only able to enjoy the
latter talks thanks to the great work of the video team!) because it
also scratched the same topic I was concerned about in my
mentoring talk. Related to this was in my opinion also "Women
in Debian 2013" were we tried to find out reasons for the lack of
woman compared to other projects and how to overcome this issue.
Besides the talks I will probably never forget
two specific moments that make DebConf so special. One of these
moments is recorded on an image that clearly needs no words - just
see Geert hovering over the grass.
Another strong moment in my personal record was in the DebConf Newbies
BoF "First
time at DebConf" that unfortunately was not recorded but at least
for this statement it would have been very great if we would have some
reference better than personal memory. Aarsh Shah a GSoC student from
India suddenly raised up and said: "Four months ago I was not even
aware that Free Software exists. Now I'm here with so many people who
are totally equal. If I will tell my mother at home that I was
standing in the same queue where the Debian Project Leader was queuing
up for food she will never believe me." He was totally excited about
things we are regarding as normal. IMHO we should memorise moments
like this that might be part of the key to success in cultures, where
Debian is widely unknown and very rarely in use.
Amongst these not scheduled great moments the scheduled day trip was also
a great thing. I had a really hard time to decide what tour I might
join but ended up in the "long distance walking (or should I say
running) group". Inspired by the "running Bubulle" who was flashing
between the walking groups we went uphill with 5.4km/h which was a nice
exercise. Our destination the large cliff was an exciting landscape and
I guess we all enjoyed the dinner organised by the "Trout cabal". ;-)
So I had a hard time to leave Le Camp and tried hard to
make sure my memories will remain as long as possible. Keeping some
signs attached to my bicycle, conserving the "Scenic Hacklab" sign
for my private "scenic hacklab @ home" was one part. I also have cut
some branches of the Buxus sempervirens in Le Camp and have put them
in my garden at home (where I create some hedgerow from places where
I spent some great time). These will probably build a great part of
the hedgerow ...
Thanks for reading this longish report.
Looking forward to see you all in Germany 2015 (or earlier)
Andreas.
EFI includes support for storing persistent 'variables': it
implements a key-value store where keys are (UUID, string) and
values are arbitrary blobs. (There are also some flags that
restrict when the variables can be accessed.) The physical storage
medium is normally flash. The Linux efivars module
provides access to variable storage, both through a
specific
interface in sysfs and through the somewhat abstracted
pstore
interface.
An EFI implementation reads the boot order and (if applicable)
Secure Boot configuration from specific EFI variables. An operating
system can add arbitrary variables, using its own UUID(s). On
Linux, the efibootmgr utility is used to read and write the
boot order and the pstore interface is used within the kernel to
dump kernel log messages or other information when particular events
occur.
Since efivars is needed to set the boot order on EFI
systems, it's a critical part of installation. But it wasn't being
loaded on Debian systems until efibootmgr was run. This
doesn't work so well when using a rescue system, as the installation
kernel and installed kernel may be different
(Debian bug 703363). In
future (Debian package version 3.2.41-1) this will be loaded
automatically on EFI systems.
But now comes a new problem: bugs in the implementation of variable
storage can prevent a system from booting, and even worse, they may
prevent manual recovery without special equipment (the system is
'bricked'). Matthew
Garrett recently talked about this and mentioned that some
Samsung laptops are bricked if the variable storage becomes more
than 50% full. efivars now has some extra checks to avoid
triggering this (both in mainline and in stable branches). This
isn't the end of the story, unfortunately.
Remember that nothing can be overwritten in flash without erasing a
relatively large block, and that writes may fail after a few
thousand erase cycles (number depending on the type of flash used).
Therefore, deleting a variable usually does not free storage
immediately, and overwriting a variable usually reduces the amount
of free storage. In the case of the Samsung laptops, unused storage
is apparently reclaimed at the next reboot.
However, while testing the backported efivars changes I found that
my EFI-booting system (Asus P8Z68-V LX motherboard) does not reclaim
unused storage until it's very nearly full. Since the firmware
itself increments a counter variable on every boot, using 36 more
bytes of storage, I was able to observe the available space dropping
to under 100 bytes, and then after another boot jumping to about 42K
(out of 64K). This means that well over 50% of storage was unused,
yet efivars would refuse to write any variables because the
firmware didn't reclaim it. This would prevent (re)installation of
Linux, as the boot configuration could not be written.
On the assumption that both behaviours are common, I've settled
on a compromise that I hope minimises overall risk:
Applied pending changes that allow pstore integration to be
disabled at run-time, and made this the default. This means
only efibootmgr is likely to write to variables.
Removed the check that variable writes will not fill storage
more than 50%.
But it's essential that we find a way to identify and work safely
with both behaviours. Not only do I want to eliminate the
possibility of bricking or installaton failure, but I want to make
EFI-backed pstore safe to enable. Crash logs are often hard to
obtain and pstore can help to solve that problem.
Updated 2013-09-15: The free space check has been
revised (in Linux 3.2.48, 3.5.7.17, 3.8.13.5, 3.9.7 and 3.10) based
on advice from Samsung. The kernel leaves at least 5K (rather than
50%) of the EFI variable store free. If it is about to breach this
limit, it attempts to write a dummy variable that is larger than the
free space, which will either fail or trigger garbage collection.
The normal variable can then be written if garbage collection freed
up enough space. This check can be disabled using the kernel
parameter efi_no_storage_paranoia, but there should be no
need to do so.
I recently purchased an LG Optimus L3 ( e400 ) mobile phone. I ve to admit it would be a perfectly fine purchase if it wasn t for the huge amount of time I had to invest in order for this thing to recognize me as its master. Even though I wanted to install CyanogenMod in it, the device blocked my attempts to install it through ROM Manager. Yes, for some awkward reason LG kept on thinking they still owned the device even after they sold it to me.
Anyway, as none of the rooting instructions for LG Optimus L3 I found on the net worked for me, I figured I should try with the recently-discovered master key vulnerability. A bit of research shows there s very extensive documentation on this hole and how to exploit it, as well as proof-of-concept exploits. But unfortunately, I haven t been able to find any complete solution to implement this in easy steps.
On the soulders of giants
After running through the whole manual setup of this exploit (and succesfully rooting my LG Optimus L3), I figured it would be useful if I put the pieces together into a unified script.
So here it is, an exploit for the Android master key vulnerability which will give you root access to almost every Android device in existance:
https://github.com/robertmillan/mkbreak
Enjoy. Oh and btw: fuck you LG.
I have upgraded all of my own computers from Debian 6.0 (squeeze) now.
I no longer use it myself at all. Some of my software already doesn't
work on squeeze (particularly, yarn, which is part of cmdtest). I
do not want to spend my time finding ways to support, say, the
python-markdown library version that is in squeeze: I would rather
make functional improvements than support ancient software versions.
I am hereby ending my support of squeeze in my own software. This
means I will be removing squeeze from my apt repository on
code.liw.fi, and will no longer test that my software works in
squeeze, and will not be making packages for squeeze. (I am removing
squeeze from the apt repository so that people don't wrongly assume it
is being kept up to date.)
This change affects users of Obnam. Obnam was not part of the squeeze
release of Debian, but I have maintained packages of it for squeeze on
code.liw.fi.
If any of my software that is packaged in squeeze has security bugs,
or bugs that would be considered release-critical by Debian, I will
fix those, but only by making the minimal necessary change to the
version in squeeze rather than backporting the current version. Debian
is committed to support squeeze for several more months, and I will
help Debian do that for my packages.
Yesterday, I pushed my first sizable contribution to GHC, the Haskell compiler. The feature solves the problem that newtypes are not always free: If we have newtype Age = MkAge Int, then we have all learned that the Age function has zero run-time cost. But if the Int that we want to convert is inside another type, the conversion is no longer free: Converting a Maybe Int to a Maybe Age using, for example, fmap Age, will cause time and space overhead at runtime, and there was no way around it. Well, there is unsafeCoerce, but really, that ought to be avoided.
So after some discussion with and encouragement of Simon Peyton Jones at RDP in Eindhoven this year I worked on a design (which was developed, as far as I know, by Simon, Roman Cheplyaka, Stephanie Weirich, Richard Eisenberg and me). In GHC 7.8, there will be a function coerce :: Coercible a b => a -> b that works, from the user point of view, like unsafeCoerce (i.e. no run-time cost), but with the big difference that it will only typecheck if the compiler can infer that it indeed is safe to coerce between a and b. So it will derive Coercible Age Int, and Coercible Int Age, and Coercible (Maybe Age) (Maybe Int) and even stuff like Coercible (Int -> Age) (Age -> Int), but not Coercible Int Bool. It will also not coerce between Age and Int if the constructor MkAge is not exported, to respect module boundaries.
Under the hood this relies on the also new feature of roles, which were solved to make the previously unsafeGeneralizedNewtypeDeriving feature safe again, and which also guarantee that coerce is indeed as safe as the name suggests.
The feature will come with 7.8, but not fully advertised , so things might change again for 7.10, and bugs with the feature may not necessarily qualify to be fixed in further 7.8.x releases, so beware. It also does not automatically convert fmap Age into coerce, but it is a step in that direction.
Portslave is a project that was started in the 90 s to listen to a serial port and launch a PPP or SLIP session after a user has been authenticated, I describe it as a project not a program because a large part of it s operation is via a shared object that hooks into pppd, so if you connect to a Portslave terminal server and just start sending PPP data then the pppd will be launched and use the Portslave shared object for authentication. This dual mode of operation makes it a little tricky to develop and maintain, every significant update to pppd requires that Portslave be recompiled at the minimum, and sometimes code changes in Portslave have been required to match changes in pppd. CHAP authentication was broken in a pppd update in 2004 and I never fixed it, as an aside the last significant code change I made was to disable CHAP support, so I haven t been actively working on it for 9 years.
I took over the Portslave project in 2000, at the time there were three separate forks of the project with different version numbering schemes. I used the release date as the only version number for my Portslave releases so that it would be easy for users to determine which version was the latest. Getting the latest version was very important given the ties to pppd.
When I started maintaining Portslave I had a couple of clients that maintained banks of modems for ISP service and for their staff to connect to the Internet. Also multi-port serial devices were quite common and modems where the standard way of connecting to the Internet.
Since that time all my clients have ceased running modems. Most people connect to the Internet via ADSL or Cable, and when people travel they use 3G net access via their phone which is usually cheaper, faster, and more convenient than using a modem. The last code changes I made to Portslave were in 2010, since then I ve made one upload to Debian for the sole purpose of compiling against a new version of pppd.
I have no real interest in maintaining Portslave, it s no longer a fun project for me, I don t have enough spare time for such things, and no-one is paying me to work on it.
Currently Portslave has two Debian bugs, one is from a CMU project to scan programs for crashes that might indicate security flaws, it seems that Portslave crashes if standard input isn t a terminal device [1]. That one shouldn t be difficult to solve.
The other Debian bug is due to Portslave being compiled against an obsolete RADIUS client library [2]. It also shouldn t be that difficult to fix, when I made it use libradius1 that wasn t a difficult task and it should be even easier to convert from one RADIUS library to another.
But the question is whether it s worth bothering. Is anyone using Portslave? Is anyone prepared to maintain it in Debian? Should I just file a bug report requesting that Portslave be removed from Debian?

 On a regular basis, I find myself the odd-man-out when it comes to talking
about how to work with Python on Debian systems. I'm going to write this and
post it so that I might be able to point people at my thoughts without having
to write the same email in response to each thread that pops up.
Turns out I don't fit in with the Debian hardliners (which is to say, the
mindset that


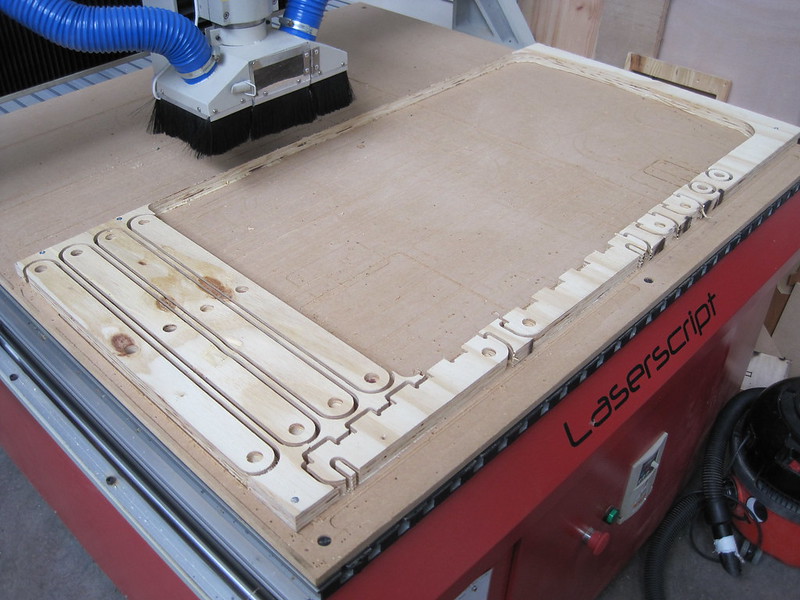
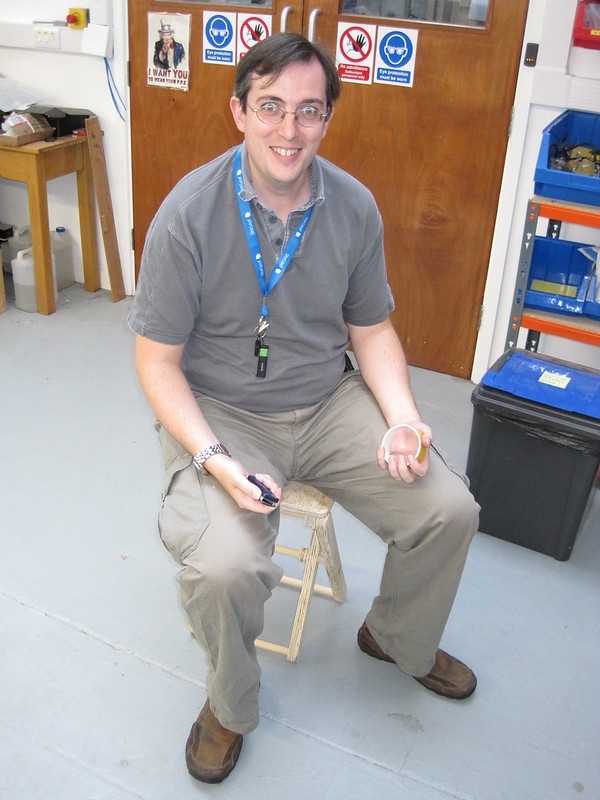

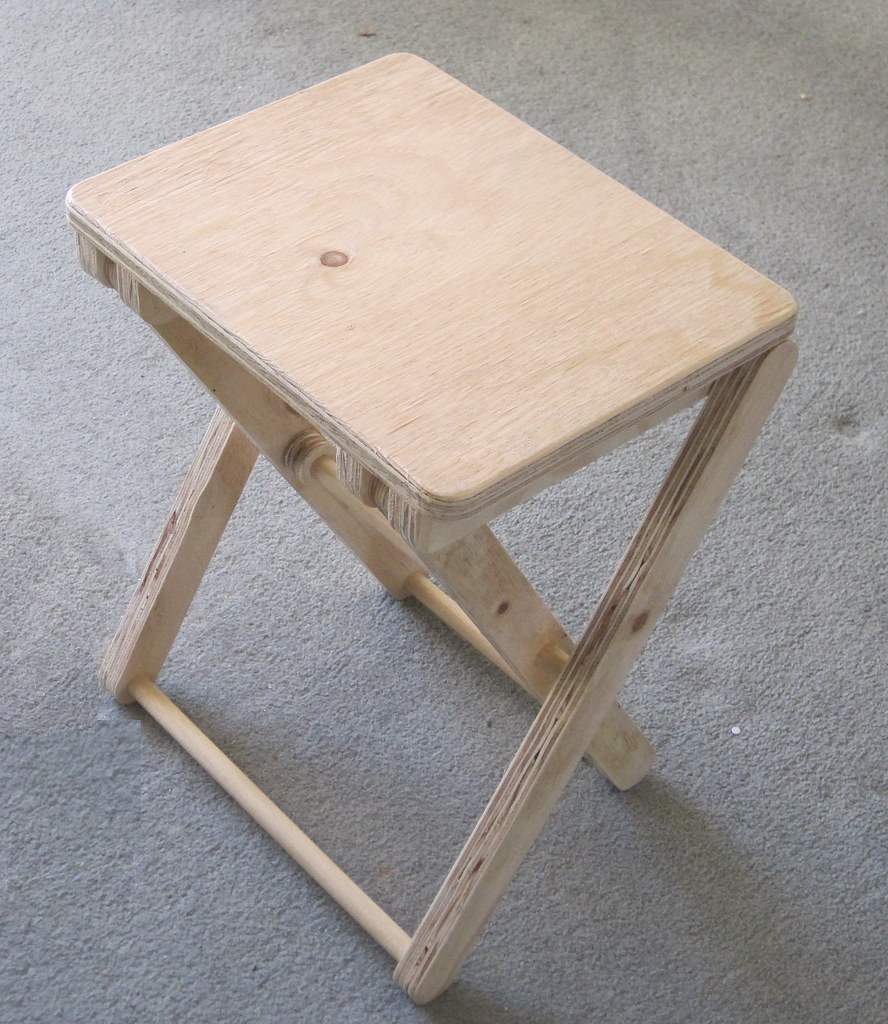
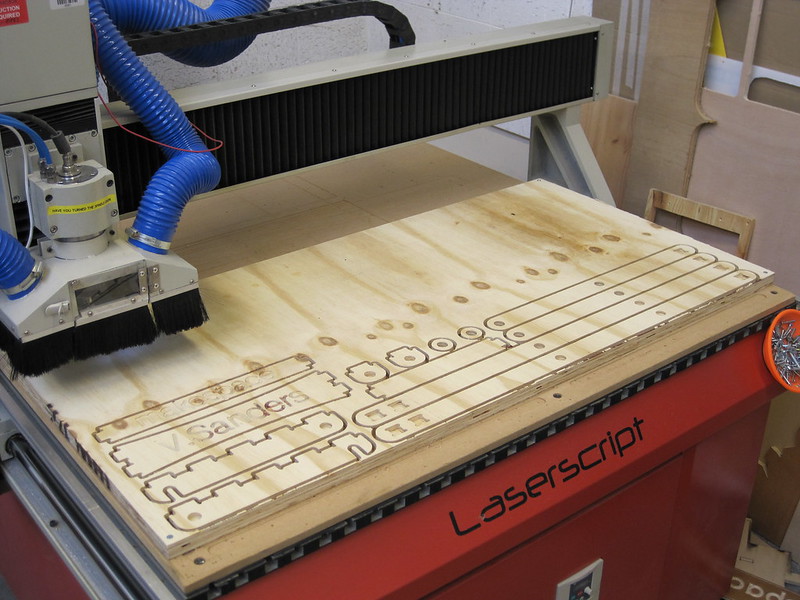
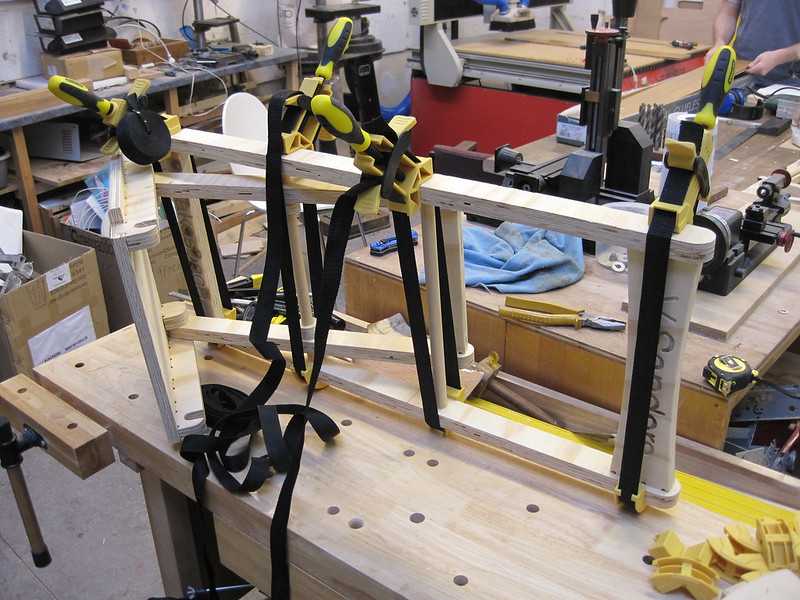
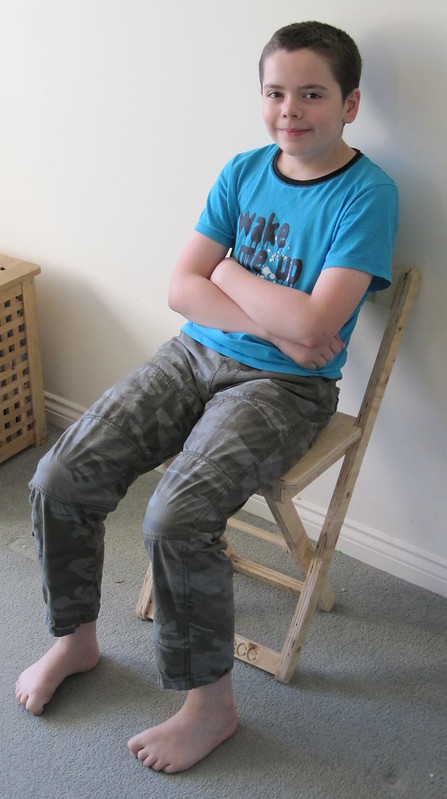
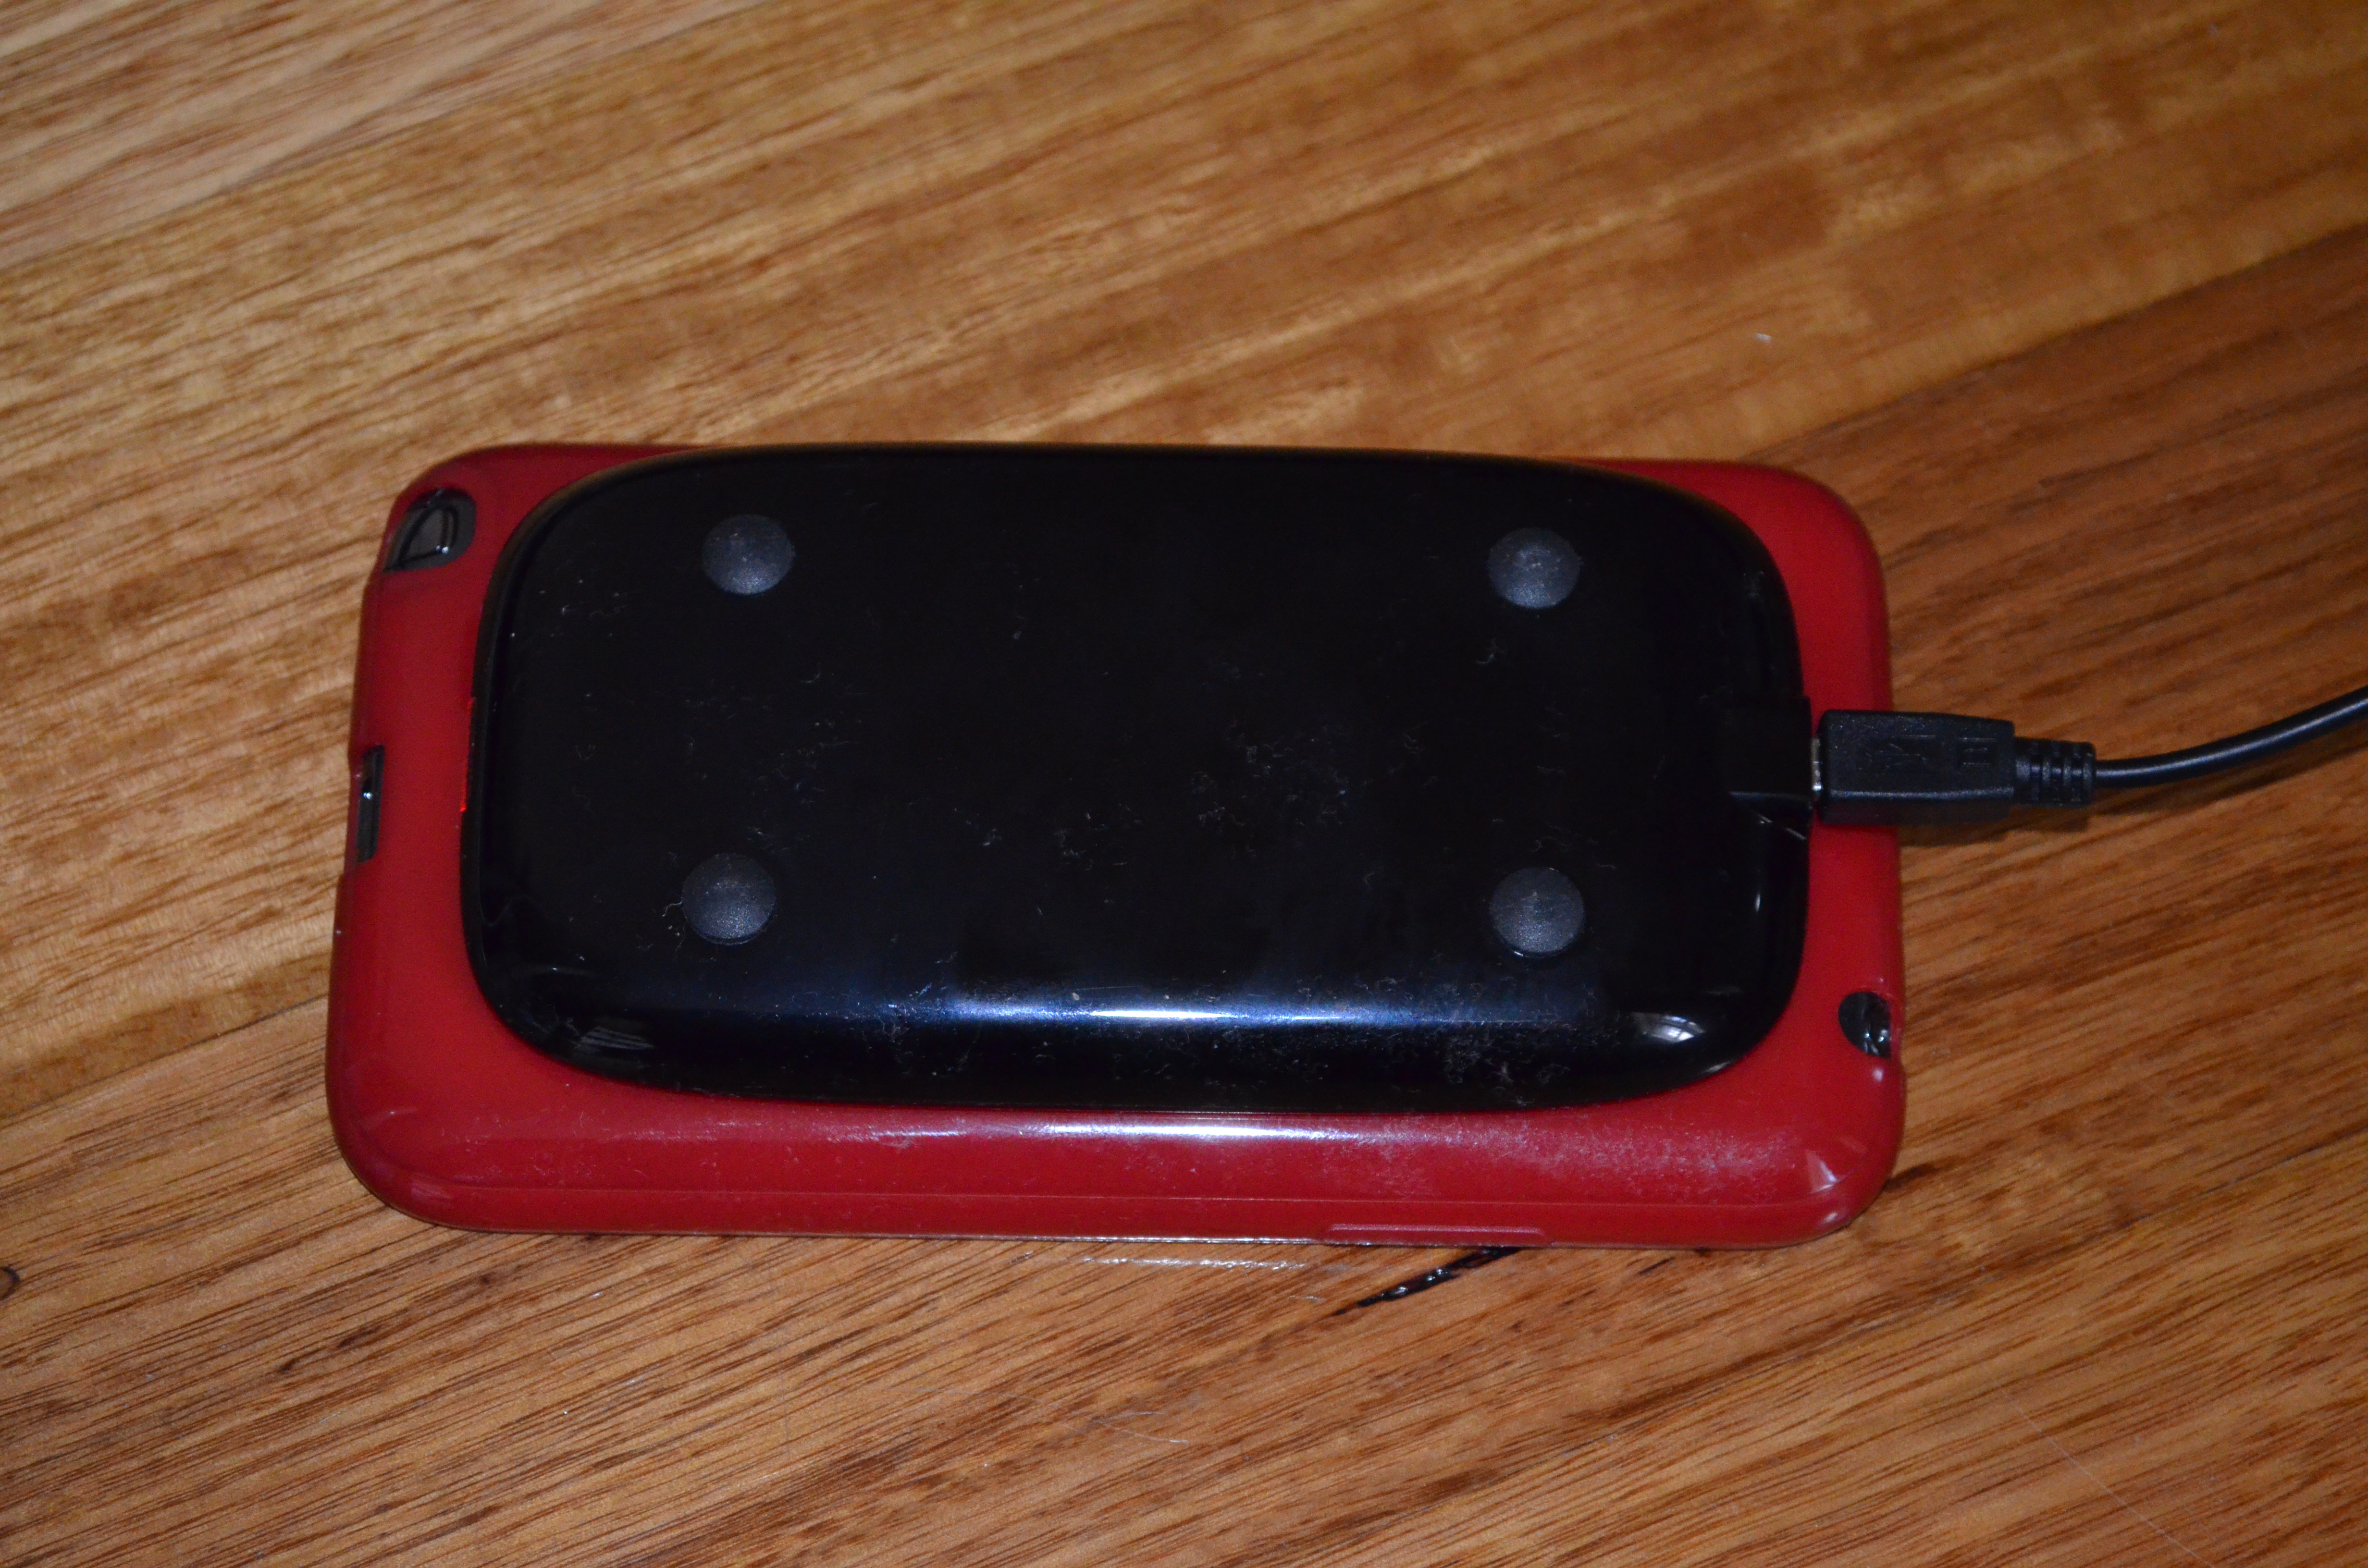
 I ve been running several

 While I suspect that professional speakers have separate presentation
laptops that they use only to give talks, I don't do this often enough to
justify the hassle and cost of a separate machine. However, I do use a
separate user account to present from.
It allows me to focus on my presentation and not stress out about running
into configuration problems or exposing private information. But mostly, I
think it's about removing anything that could be distracting for the
audience.
The great thing of having a separate user for this is that you can do whatever
you want in your normal account and still know that the other account is ready
to go and configured for presenting on a big screen.
 I love to say that Python is a nice subset of Lisp, and I discover that it's
getting even more true as time passes. Recently, I've stumbled upon the

 After years of waiting, Google has finally enabled IPv6 for their
email service Gmail. And a few weeks ago, they updated their policy,
adding one specific rule: reject email from IP addresses with no reverse
name:
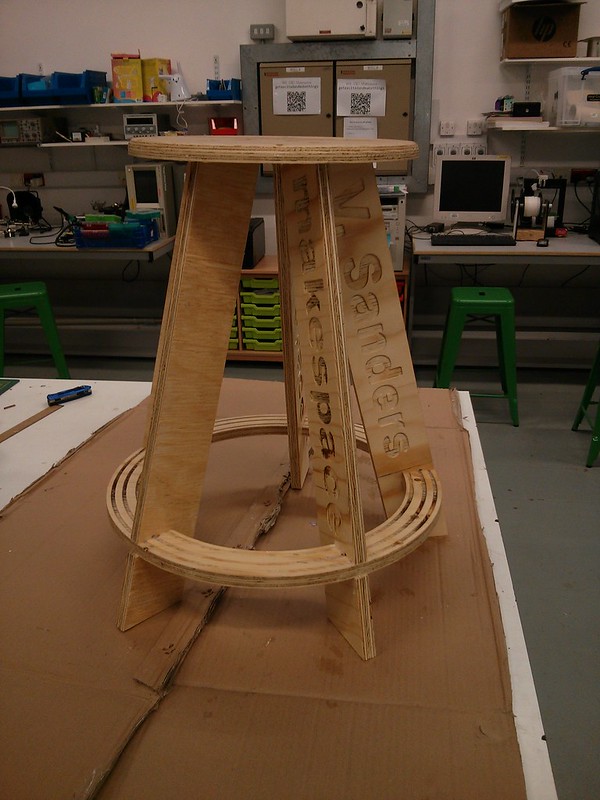



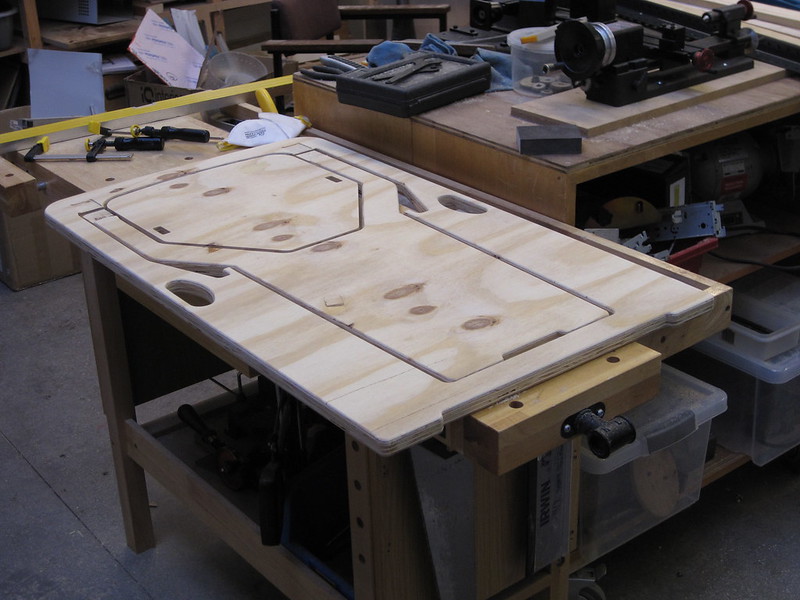

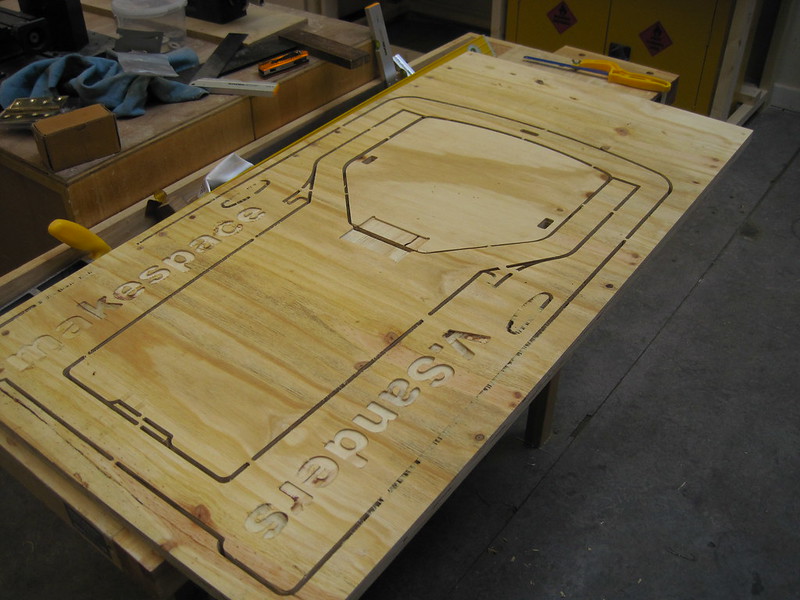
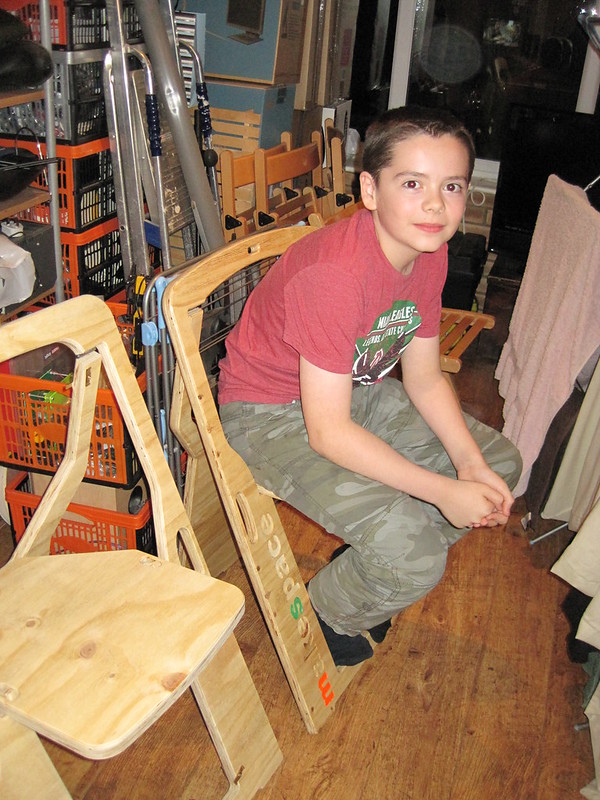
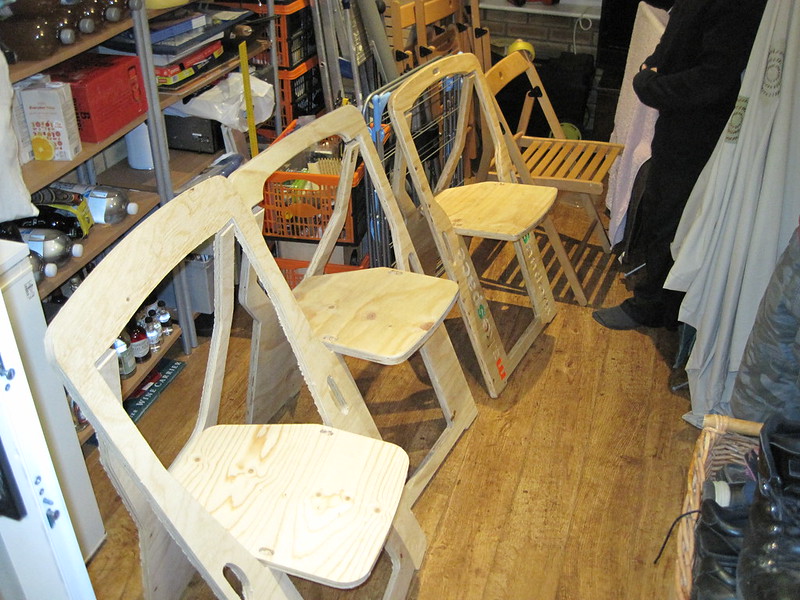
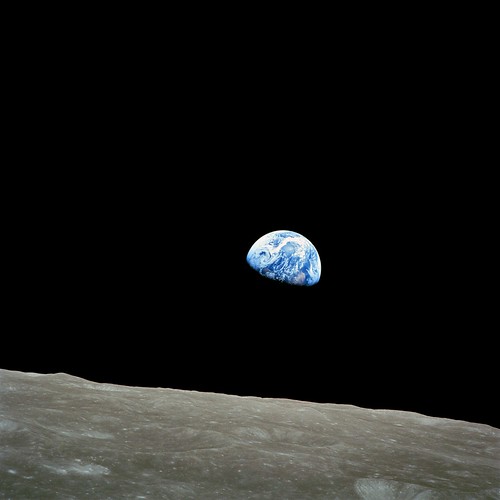
 It seems I'm catching up with the pace of this course I'm following and that is compelling me to go back to posting on my blog,
 EFI includes support for storing persistent 'variables': it
implements a key-value store where keys are (UUID, string) and
values are arbitrary blobs. (There are also some flags that
restrict when the variables can be accessed.) The physical storage
medium is normally flash. The Linux efivars module
provides access to variable storage, both through a
 I recently purchased an LG Optimus L3 ( e400 ) mobile phone. I ve to admit it would be a perfectly fine purchase if it wasn t for the huge amount of time I had to invest in order for this thing to recognize me as its master. Even though I wanted to install

 I have upgraded all of my own computers from Debian 6.0 (squeeze) now.
I no longer use it myself at all. Some of my software already doesn't
work on squeeze (particularly,
 Yesterday, I pushed my first sizable contribution to GHC, the Haskell compiler. The feature solves the problem that newtypes are not always free: If we have newtype Age = MkAge Int, then we have all learned that the Age function has zero run-time cost. But if the Int that we want to convert is inside another type, the conversion is no longer free: Converting a Maybe Int to a Maybe Age using, for example, fmap Age, will cause time and space overhead at runtime, and there was no way around it. Well, there is unsafeCoerce, but really, that ought to be avoided.
So after some discussion with and encouragement of Simon Peyton Jones at