Search Results: "tar"

3 December 2013

Craig Small: procps-ng 3.3.9

Procps version 3.3.9 was released today. As there has been some API changes and fixes which means the library has changed again. There is a fine balance between fixing or enhancing library functions and keeping the API stable, with the added problem it wasn t a terribly good one to start with. Besides the API change, the following changes were made: Tar file is at sourceforge at https://sourceforge.net/projects/procps-ng/files/Production/

Dirk Eddelbuettel: digest 0.6.4

digest version 0.6.4 is now on CRAN and in Debian. This is a pure maintenance release which should help with a build issue affecting users on Solaris. CRANberries provides the usual summary of changes to version 0.6.3. Our package is available via the R-Forge page leading to svn and tarball access, my digest page, the local directory here as well as via Debian and its mirrors.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Daniel Pocock: Ski season starts

The ski season has started again, I went down to Andermatt on Sunday to have some fun. Here is a video made with my camera phone:

Russell Coker: Preferring Not To

I ve just read Bartleby the Scrivener which is a short story about a scrivener who refused to work saying I d prefer not to . It reminded me of some situations in the computer industry. I ve never seen a single case where someone preferred not to work when everyone around them (colleagues and management) wanted them to work. But then the incidence of having an entire team and management wanting to work efficiently isn t nearly as common as one might imagine. In some cases it s desired that someone not work, such as a former colleague who was hired as a sysadmin but did nothing but change backup tapes (a few hours work per week). Not having him login as root improved the general reliability of the servers but it was fortunate that we never needed to restore from backups One time I had a colleague who preferred to spend most of his time in the office searching the Internet for videos of street fights. I have often told colleagues that I would prefer them to work, but in the case of a guy who s only hobby is street-fighting I decided to let it go. Managing people can be difficult, particularly for someone who doesn t like disagreements. Some managers that I ve reported to seemed to prefer not to manage in an apparent attempt to avoid disputes. One time when I complained about a colleague not even having a suitable computer to permit doing any work a manager responded with the rhetorical question what do you expect me to do? . That manager didn t do any annual reviews of staff for over a year, he only eventually did some reviews because he was told that his scheduled promotion was on hold until he got them done. I got the impression that at least two levels of management preferred not to work at that company. Sometimes it just gets weird though, such as the occasion when I was the only member of a team and the manager who was supposedly managing no-one but me never seemed to have time to have a meeting with me. But he didn t want me to bypass him and talk directly to other people in the company, so he preferred not to work and not to have anyone else do his job. Most of the companies that I ve worked for in a full-time capacity didn t seem to have any effective technical interviews (note that I ve mostly worked for financial companies and ISPs not free software companies). So it seems that anyone with minimal computer skills who wants a well paying job could just send out a CV to a bunch of recruiting agencies, get interviewed by enough companies to eventually hit one without a technical interview process and then find a job that doesn t require work. Depression The Wikipedia page about Bartleby the Scrivener [2] suggests that Bartleby was depressed. I wonder how much of the lack of performance I ve witnessed has been due to depression. There appears to be a strong correlation between work environments that cause depression and people preferring not to work. Maybe managers should be considering how to make work less depressing to try and get more effective employees (in terms of quality and quantity of work). One example of this is the sysadmin team death spiral I ve witnessed where no-one can automate solving problems (EG by cron jobs to manage resource usage and analysis tools to find minor problems before they become major problems) because everyone is dedicated to fixing things that break needlessly (EG systems crashing due to lack of disk space). When people start getting control over recurring problems and automating things then the work becomes increasingly about solving problems and less about implementing the same manual processes every day/week and it s more fun and effective for everyone. At the BoF on depression at LCA 2013 one delegate stated that many companies have people in HR who can arrange support for depressed employees. Apparently if you are depressed and you work for a company that s large enough to have a HR department then it can be beneficial to talk to HR about it. That probably works well in the case where an employee is depressed but the company is working well. But in the case where the company isn t working well it seems unlikely to help. David Graeber wrote an interesting article about Bullshit Jobs [3]. He goes a bit far, I don t think that late night pizza delivery is a bullshit job and actuaries are useful to society. But his points about the existence of useless jobs are reasonable. Management Levels I sometimes wonder whether there is some benefit in establishing social norms about working and then having management take little interest in how it happens. If a team works well together then management could just set deadlines (which would be negotiated with employees who know what s possible) and let the team work out how to do it. Then instead of having one manager for each team of ~10 people who theoretically tracks what everyone is doing you could have one manager for a dozen teams who just tracks overall team performance essentially remove a layer of management. Valve is famous for having no formal management structure and for getting things done, unfortunately that apparently allows school-style cliques to block actions [4]. But I think that the Valve experiment is useful and provides some ideas that can be used by other companies. Maybe if instead of requiring consensus of the entire company for hiring decisions they only required consensus of the team things would have worked better. Of course another down-side to such things is that hierarchical management can be good for avoiding discrimination and bullying. The article I cited about Valve compares it to high-school. It could be that Valve employees were all nice people who only hired other nice people. But if similar systems were implemented in many companies then some would surely end up being like a typical high school with all the bullying and mistreatment of minority groups that entails. Michael O. Church wrote an interesting article in which he divides employees into four categories, loser , clueless , psychopaths , and technocrats (note that he didn t invent the first three names) [5]. In his model the clueless category includes most middle-management. I think that there are some problems with Michael s model and I m not arguing for a technocracy (which is how this post might be interpreted in terms of his ideas). But I think he demonstrates some of the real problems in the way companies are managed and in his model the losers prefer not to work as long as they can get paid. Conclusion I don t have any good solutions to these problems to offer. It seems that the best we can hope for is incremental change to make work less depressing, to have the minimal amount of management, and to avoid bullshit jobs .

2 December 2013

Thorsten Glaser: Neo900

I ve did something I surely will (financially) regret, next year, and designated the Neo900 to be the successor to my PocketPC, due to the latter having only 64 MiB RAM and Geocaching applications being quite hungry. It s got a lovely hardware keyboard, a pen display like the PocketPC (as opposed to the wishy-washy displays that Android and iPhone have), not only GPS but also GLONASS, fully free software with mostly free firmware (I m okay with that, mostly), a Ctrl key (useful in ssh and locally and my text editor; ^I is Tab, so it s useful in shell, too), WLAN, UMTS (I don t think I need LTE and would rather it have the more RAM), USB host (OTG), and lots of other nice features. In short, it s a tinkerable device: one I can not only hack at, but also hack on. Since I use a dumbphone for mobile phone anyway (pro: separate battery from the toy PocketPC/Smartphone we re talking two+ weeks of battery time when using it here, and easier use and less bugs, and a reliable fallback when I tinker too much ), this is perfect for me. I m reposting this in the wlog mostly because it s an interesting technical and OSS project, and because if 1000 people want one it will get less expensive for all of us (while here shameless plug any sponsors willing to contribute some EUR so I don t ruin myself with this, in exchange for services of some kind?). I ll probably run Debian on it (unless it goes systemd), maybe in a chroot if the native OS has functionality needed that I can t simply put into packages; they say Maemo has much better power management, but considering most use will have GPS, GLONASS and backlight on, battery isn t going to last long anyway or maybe even native I ve been wanting to know what this freesmartphone stuff my m68k (Atari VM) buildd has been happily compiling, anyway and some sort of Geocaching application (ideally a cross between something online, CacheWolf and an offline OSM (with most of Europe, but uninteresting tags stripped) and possibly access to the GS Live API but nevertheless supporting TC, NC, OC, gpsgames too), and my usual mksh(1), GNU screen, jupp(1), lynx(1), ssh(1) toolchain.) Delivery is expected for mid to end of 2014, but once it s there I ll keep you informed

1 December 2013

Raphaël Hertzog: My Free Software Activities in November 2013

This is my monthly summary of my free software related activities. If you re among the people who made a donation to support my work (44.52 , thanks everybody!), then you can learn how I spent your money. Otherwise it s just an interesting status update on my various projects. The Debian Administrator s Handbook Wheezy update completed. Roland and I completed the update of the Debian Administrator s Handbook for Debian 7 Wheezy. We still have some proofreading work to do but you can already enjoy the result here: http://debian-handbook.info/browse/wheezy/ Feel free to report back any problem that you discover. You can also submit us patches ready to apply if you want to go one step further. Publican contributions. The book is generated with publican and I maintain its Debian package. This month I got a release critical bug because it stopped working it turns out that the problem lied in libxml-treebuilder-perl and I thus reassigned #728885 while providing a tentative patch to the upstream author. After a few days without action from the pkg-perl team, and after having received a FTBFS bug on debian-handbook (of course publican was broken in unstable!), I prepared a fixed package myself and I uploaded it (I m still part of the pkg-perl team although I m inactive). Since I used publican heavily this month, I filed two tickets in its bugzilla. I requested a new feature in #1034836 (the possibility to keep around the former string for fuzzy strings to update), and I reported a problem with the handling of \n in PO files in #1036150. Debian France Galette update. I updated the galette package and its paypal plugin, and I deployed those on france.debian.net. It had some fixes for the reminder mails sent to members. Bylaws update. I also resumed my work on preparing new bylaws for Debian France. Sylvestre Ledru came up with a draft (with the help of a lawyer) a few months ago and I m reviewing/improving them now. The main goal is to clarify that Debian France is meant to be a Trusted Organization for the Debian project. Debian France Shop. We had the idea since a few months already but Sylvestre did the leg work to open a Debian France shop with the help of EnVenteLibre. I asked our members to prepare some CSS that better match the Debian colors and this should be fixed in a few days. The first goodies will also start to appear shortly, just in time for Christmas! Misc Debian work Distro Tracker. In the continuation of the Google Summer of Code, I asked the DSA team to setup a new virtual machine to host tracker.debian.org, an instance of Distro Tracker, the rewritten Package Tracking System. They have done their part of the job (except the mail setup), it s now waiting on me to find some time to complete some cleanups and deploy the thing. WordPress. I packaged wordpress 3.7.1 and sent a call for help on debian-mentors. I got 3 replies, I gave them some initial direction but I haven t heard back anything since. WordPress 3.8 is expected in a few days, hopefully one of the new volunteers will take care of preparing the next update. Dpkg regressions. I haven t done anything for multiple months but at least I keep running the git version of dpkg and I detected two regressions. Good to have them squashed before the upcoming 1.17.2 upload to unstable. PTS fix. I fixed some warnings that the PTS code started generating since the upgrade of its host to wheezy. They were generating some annoying backscatter mails to users of the pts@qa.debian.org bot. Ruby security update. I helped the ruby team to prepare the required security updates of ruby1.8 and ruby1.9.1 (see #730178 and #730189). This work was sponsored by Kali/Offensive Security. Smartcard setup. I bought 2 OpenPGP smartcards with a reader and I moved all my private keys on those devices (one card with the master key for signature/certification to be kept at home, one card for daily/mobile usage with the subkeys for encryption/signature/authentication). My laptop s harddrive doesn t contain any private key anymore. I have kept the required offline backup in a safe place, but in the end, my private keys are much harder to steal. I should write down my findings in another article Thanks See you next month for a new summary of my activities.

2 comments Liked this article? Click here. My blog is Flattr-enabled.

Marco d'Itri: Easily installing Debian on a Cubieboard

I recently bought a Cubieboard to replace my old Sheevaplug which has finally blown a power supply capacitor (this appears to be a common defect of Sheevaplugs), so I am publishing these instructions which show how to install Debian on sunxi systems (i.e. based on the Allwinner A10 SoC or one of its newer versions) with no need for cross compilers, emulators or ugly FAT partitions. This should work on any sunxi system as long as U-Boot is at least version 2012.10. The first step is to erase the beginning of SD card to remove anything in the unpartitioned space which may confuse U-Boot, partition and format it as desired. The first partition must begin at 1MB (1024*1024/512=2048 sectors) because the leading unpartitioned space is used by the boot loaders.
dd if=/dev/zero of=/dev/mmcblk0 bs=1M count=1
parted /dev/mmcblk0
  mklabel msdos
  mkpart primary ext4 2048s 15G
  unit s
  print
  mkpart primary linux-swap ... -1
mkfs.ext4 -L root /dev/mmcblk0p1
mkswap --label swap /dev/mmcblk0p2
Download the boot loaders and an initial kernel and install them:
tar xf cubieboard_hwpack.tar.xz
dd if=bootloader/sunxi-spl.bin of=/dev/mmcblk0 bs=1024 seek=8
dd if=bootloader/u-boot.bin of=/dev/mmcblk0 bs=1024 seek=32
mount /dev/mmcblk0p1 /mnt
mkdir /mnt/boot/
cp kernel/script.bin kernel/uImage /mnt/boot/
script.bin is Allwinner's proprietary equivalent of the device tree: it will be needed until sunxi support will be fully merged in mainline kernels. U-Boot needs to be configured to load the kernel from the ext4 file system (join the lines at \\, this is not a supported syntax!):
cat << END > /mnt/boot/uEnv.txt
# kernel=uImage
root=/dev/mmcblk0p1 rootwait
boot_mmc=ext4load mmc 0:1 0x43000000 boot/script.bin && ext4load mmc 0:1 0x48000000 boot/$ kernel  \\
  && watchdog 0 && bootm 0x48000000
END
Now the system is bootable: add your own root file system or build one with debootstrap. My old Sheevaplug tutorial shows how to do this without a working ARM system or emulator (beware: the other parts are quite obsolete and should not be trusted blindly). If you have an old armel install around it will work as well, and you can easily cross-grade it to armhf as long as it is up to date to at least wheezy (the newer, the better). You can also just use busybox for a quick test:
mkdir /mnt/bin/
dpkg-deb -x .../busybox-static_1.21.0-1_armhf.deb .
cp bin/busybox /mnt/bin/
ln -s busybox /mnt/bin/sh
After booting the busybox root file system you can run busybox --install /bin/ to install links for all the supported commands. Until Debian kernels will support sunxi (do not hold your breath: there are still many parts which are not yet in mainline) I recommend to install one of Roman's kernels:
dpkg -i linux-image-3.4.67-r0-s-rm2+_3.4.67-r0-s-rm2+-10.00.Custom_armhf.deb
mkimage -A arm -O linux -T kernel -C none -a 40008000 -e 40008000 \
  -n uImage -d /boot/vmlinuz-3.4.67-r0-s-rm2+ /boot/uImage-3.4.67-r0-s-rm2+
It is not needed with these kernels for most setups, but an initramfs can be created with:
update-initramfs -c -k 3.4.67-r0-s-rm2+
mkimage -A arm -T ramdisk -C none -n uInitrd \
  -d /boot/initrd.img-3.4.67-r0-s-rm2+ /boot/uInitrd-3.4.67-r0-s-rm2+
/boot/uEnv.txt will have to be updated to load the initramfs. Since the Cubieboard lacks a factory-burned MAC address you should either configure one in script.bin or (much easier) add it to /etc/network/interfaces:
iface eth0 inet dhcp
        hwaddress ether xx:xx:xx:xx:xx:xx
To learn more about the Allwinner SoCs boot process you can consult 1 and 2.

30 November 2013

Dirk Eddelbuettel: RcppCNPy 0.2.2

Right on the heels of release 0.2.1 of RcppCNPy, a new version 0.2.2 is now on CRAN. RcppCNPy uses the CNPY library by Carl Rogers to provide R with easy read and write access to NumPy files. The reason for the new version that I had experimented with a different way to test endianness (as needed for the NumPy file headers) but accidentally sent an interim tarball to CRAN which still wanted to include endian.h promptly breaking Windows builds. So now we do something even simpler and just rely on the (even more complete) test for endianness when R is built, which prevents all sorts of complications for us and builds everywhere (with thanks to Brian Ripley for the suggestion). While we were at it, we also added a new unit test. Full changes are listed below.
Changes in version 0.2.2 (2013-11-29)
  • Switched to using the result from the compile-time configuration for R to determine big or little endian (as needed for the NPy headers)
  • Added a new test (and test validation result file) for a complete save-reload cycle and comparison
CRANberries also provides a diffstat report for 0.2.2 relative to 0.2.1. As always, feedback is welcome and the rcpp-devel mailing list off the R-Forge page for Rcpp is the best place to start a discussion.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Guido G nther: CrystalHD progress

Following up on my port of the crystalhd plugin to the gstreamer 1.0 api I realized that the CrystalHD repo is pretty dormant. After reading slomo's nice article about GStreamer and hardware integration and a short off list mail exchange I decided to split the GStreamer part out of the CrystalHD repo and to try to get the plugin into gst-plugins-bad. Since the kernel part is already in linux kernel's staging area there would not be much left in the repo except for the libcrystalhd library itself and the firmware blobs. So I split them out as well and started to clean them up a bit by moving it to autoconf/automake, dropping the need for a C++ compiler and adding symbol versioning among other things. So up to know video is still smooth with:
gst-launch-1.0 filesrc location=sample.mp4 ! decodebin ! xvimagesink
after jhbuilding up to gst-plugins-bad. There are #ifdefs for macosx and windows but I doubt they're functional but in case anybody is building libcrystalhd on these these platforms it'd be great to know if it still works. Should these efforts lead to the crystalhd plugin being merged into GStreamer getting the kernel driver out of staging would be a great next step. This blog is flattr enabled.

Petter Reinholdtsen: Dugnadsnett for alle, a wireless community network in Oslo, take shape

If you want the ability to electronically communicate directly with your neighbors and friends using a network controlled by your peers in stead of centrally controlled by a few corporations, or would like to experiment with interesting network technology, the Dugnasnett for alle i Oslo might be project for you. 39 mesh nodes are currently being planned, in the freshly started initiative from NUUG and Hackeriet to create a wireless community network. The work is inspired by Freifunk, Athens Wireless Metropolitan Network, Roofnet and other successful mesh networks around the globe. Two days ago we held a workshop to try to get people started on setting up their own mesh node, and there we decided to create a new mailing list dugnadsnett (at) nuug.no and IRC channel #dugnadsnett.no to coordinate the work. See also the NUUG blog post announcing the mailing list and IRC channel.

29 November 2013

Axel Beckert: PDiffs are still useful

probably just not as default. I do agree with Richi and with Michael that disabling PDiffs by default gives the big majority of Debian Testing or Unstable users a speedier package list update. I m though not sure, if disabling PDiffs by default would Additionally I want to remind you that PDiffs per se are nothing bad and should be continued to be supported: So yes, disabling PDiffs by default is probably ok, but the feature must be kept available for those who haven t 100 MBit/s fibre connection into their homes or are sitting just one hop away from the next Debian mirror (like me at work :-). Oh, and btw., for the very same reasons I m also a big fan of debdelta which is approximately the same as PDiffs, just not for package lists but for binary packages. Using debdelta I was able to speed up my download rates over EDGE to up to virtual 100 kB/s, i.e. by factor four (depending on the packages). Just imagine a LibreOffice minor update at 15 kB/s average download rate. ;-) And all these experiences were not made with a high-performance CPU but with the approximately 5 year old Intel Atom processor of my ASUS EeePC 900A. So I used PDiffs and debdelta even despite having a slight performance penalty on applying the diffs and deltas.

28 November 2013

Dirk Eddelbuettel: RcppCNPy 0.2.1

Version 0.2.1 of RcppCNPy is now on CRAN earlier. This version is a minor upgrade with a few small changes as detailed in the NEWS file:
Changes in version 0.2.1 (2013-11-28)
  • Synchronized code with the cnpy repository
  • Added new function to test from R whether integers supported
  • Updated tests for integer support, if available
  • Updated vignette and discussion about need for rebuilding only RcppCNPy with the -std=c++11 flag if integer support is desired
  • Updated tests for integer support, if available
  • Updated THANKS file
  • Ensure that inclusion of Rinternal.h does not affect other headers by adding RF_NO_REMAP
CRANberries also provides a diffstat report for 0.2.1 relative to 0.2.0. As always, feedback is welcome and the rcpp-devel mailing list off the R-Forge page for Rcpp is the best place to start a discussion.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Craig Small: XBMC with MythTv

I have had MythTV running on my server for quite some time. Once I got past the weird problems you often have with the local ABC channel, it has worked very well. One tip, put the recordings into their own partition. MythTV will happily fill it and deleting files only marks them for deletion. This makes perfect sense when it has its own partition but is annoying otherwise. Until recently, the frontend on the television in the living room was a DVD player that spoke DLNA. This worked ok, but was very basic. The recordings were just a list with no graphics or details. Something better had to go here and it has; XBMC. A small (size of a paperback) PC later and we have XBMC running and doesn t it look pretty! The cute thing was it merged my DVD images and my recordings into one, so it didn t matter where the movie came from, it looks the same. It even understands MythTV advertising marks and skips them, all is good. Except, no sound. This is where a combination of my Google skills and XBMC s documentation failed. The documentation either says switch to HDMI output or go through a very long and involved process to get the sound card working. The tests on the command line failed and I thought I was going to be in for that long and involved process fixing alsa. Then in another part of the menus I saw you had Basic, Advanced, Expert levels and wondered what that did? It gave me more things to tweak in the menus. Perhaps that might fix my HDMI sound problem? Going into the System setup and then audio and then switching to a higher level of menu (it s on the left) suddenly I have a screen and a half of options and a few seconds later, sound! So if you are searching for NVIDIA and HDMI and sound, first turn on the advanced menu items and try setting that, it might be all you need (despite what Google and documentation says). One other thing, the C or I button on a remote could be called Guide . It is on mine. Also, SMB shares give a much better result than DLNA ones because SMB all the images and info are done on XBMC and it doesn t do the same for DLNA.

Debian Med: Bits from Debian Med team (by Andreas Tille)

Some of these bits are a bit outdated but there is no point in hiding this information just because it is old. FOSDEM talkAndreas Tille had a talk at FOSDEM which is also Video recorded. A quite similar but updated talk was held at DebConf 13 (see below). Jabber interview by reporter from IndiaThere was an interesting interview between Rajeev Nair and Andreas Tille at So, 17.02.2013 Rajeev Nair is Business head of an health care journal in India held via jabber. Since this might serve as some nice FAQ about Debian Med here is a complete log of this interview (permission to publish it was granted). Article about Debian MedAs a consequence of the interview above the Debian Med team has assembled an article which was originally intended to be published in the Health Cafe journal but somehow this never happened. So we ended up with a nice article targeting at interested readers about Free Software in medicine with not necessarily informatics background. Since the article is considered to be of good quality and has consumed some time of several team members we are seeking for ideas for relevant places where to publish it. It is available as PDFas well as in SVN. Yearly sprint of Debian Med teamThis year we had our third sprint of the Debian Med team and all participants consider it a great success again. The sprint was in end of February and the individual reports are linked from the according wiki page. Since Andreas Tille was able to prove the nice effect of having face to face meetings in Debian teams in the team metrics graphs presented in his talks at DebConf (see below) we will keep on with this good tradition. The next sprint is scheduled for Friday 31st January until Sunday 2nd February in Stonehaven near Aberdeen. If you are interested to meet the people behind Debian Med and want to join us in developing packages which are helpful in health care and bioinformatics you are invited to join us. DebConf 13 in VaumarcusAndreas Tille had two talks with specific influence to Debian Med development(Debian Med as a success story for other Blends, How to attract new developers for your team (MoM, SoB). For those who want to read a full (and lengthy) report about DebConf 13 by Andreas Tille this is online in this blog article. Codefest of the Open Bioinformatics FoundationIvo Maintz and Steffen M ller organised the Codefest of the Open Bioinformatics Foundation in Berlin. About 40 contributors from all over the world attended, connecting the Debian community strongly with upstream. The event triggered a joint paper of participants to Sprints, Codefests and Hackathons alike, presented at the Nettab conference on Semantic, Social, and Mobile Applications for Bioinformatics and Biomedical Laboratories in Venice. Reupload unattended packagesAndreas Tille has mentored the GSoC student Emmanouil Kiagias and as a byproduct some Blends metadata were now kept in UDD. This has inspired some new tools and one of this was an UDD query to return all packages in the interest of the Blend ordered by date when they were uploaded. It has shown that there were packages hanging around in the package pool since five years. So some effort was done to check those packages which were not necessarily "buggy" according to BTS entries and so we were able to fix the following issues in about 20-30 packages: Since it was impressive how many things that deserve fixing are hidden in such long unattended packages it is recommended also to other teams to spend some time into these. The UDD query can be easily tweaked for a team maintainer address. Debian Med Bug Squashing Advent Calendar 2013The Debian Med team will again do the Bug Squashing Advent Calendar. Feel free to join us in our bug squashing effort where we close bugs while other people are opening doors. :-) Kind regards and see you at Debian Med sprint
Andreas.

27 November 2013

Steinar H. Gunderson: Stockfish

The open-source chess program Stockfish recently climbed to the top of the TCEC rating lists. Even though it does not seem likely to win the actual TCEC tournament (it is 15.5 11.5 down in the 48-game superfinal against Komodo, a closed-source commercial program, after winning 4, losing 8 and drawing 15), this is a tremendeous achievement. This is not only because it is highly unusual that the strongest chess program is open-source (it's naturally hard to keep a competitive edge when everybody can see your secrets!), but also because it is a mere 9000 lines of C++ code. (This is without a GUI; it interfaces through a standardized protocol known as UCI.) In comparison, Crafty, a far weaker open-source program, is about four times that, GNU Chess is above 40000, and I seem to recall that the Deep Blue program was something like 65000 lines (in addition to, of course, all the code for the ASIC chess chips it contained, and stood for the majority of its chess strength!). So, the development team is really to be commended. It should also be said that TCEC is testing the latest beta versions of most of these engines and while Stockfish is developed in the open, on GitHub, the latest versions of e.g. Komodo and Houdini are private. (This is probably one of the reasons why Stockfish is slightly lower on e.g. the CCRL list, which also computes chess program rating lists by playing games between them.) Now, why does anyone care? Only a very small handful of players would be able to score even a draw against any of these programs in a 10-game match, so does it really matter which one we choose? Or is this some obscure pissing contest? The answer, of course, is that these engines are not primarily useful for competitive play; they are useful for analysis. Almost any player, right down from beginners to the very top players, can benefit from having someone stronger than them look at their games (or others' games!) and say where things went wrong. (Somehow analyzing losses always seem more instructive than analyzing wins. Nobody ever got better by winning, as the saying goes.) And the better a program is at playing chess, the more likely is its analysis to be correct. Of course, for the weaker players, a chess coach is likely to produce much more understandable guidance ( this creates a weak square on c7 is much more palatable than after these 18 moves here, white is 0.48 pawns stronger than you, so this was a bad move , and engines produce the latter sort of output), but they are always available, incredibly strong, and cost much less than a coach. :-) They also add a lot to the otherwise quite hard-to-comprehend activity of watching high-level human players; while the computers do not understand every kind of position equally well, they at least provide some sort of objective verdict on which player has the upper hand, something which can be really hard to discern unless you have very strong players around for commentary. So, in trying to improve my skills a bit, I've been analyzing my games with engines for a while, and recently I've switched from Rybka to Stockfish. (Rybka, a closed-source program, used to be the clear leader of the pack, but after a huge amount of drama involving accusations of who has copied code from who, it seems no longer to be actively developed, and Stockfish is now somewhat stronger.) This, unfortunately, brings me to the things I don't like too much about Stockfish; it seems to behave more erratically than Rybka did in interactive analysis mode. Its score jumps a lot more around when I move something (worse at remember the analysis from the previous position?), and sometimes, it changes its mind a lot when I move back and forth between moves maybe the huge selectivity that makes chess engines so strong these days also make them behave less usefully when only looking at a move for a few seconds. So, even though Stockfish is a fantastic chess engine, and will only get better in the future, maybe I'll go back to Rybka at some point. But then again, maybe I should then check out Komodo or any of the other engines out there or maybe talk to someone who actually knows chess, that would help a lot, too =)

26 November 2013

Daniel Pocock: Real-time streaming market data with free software

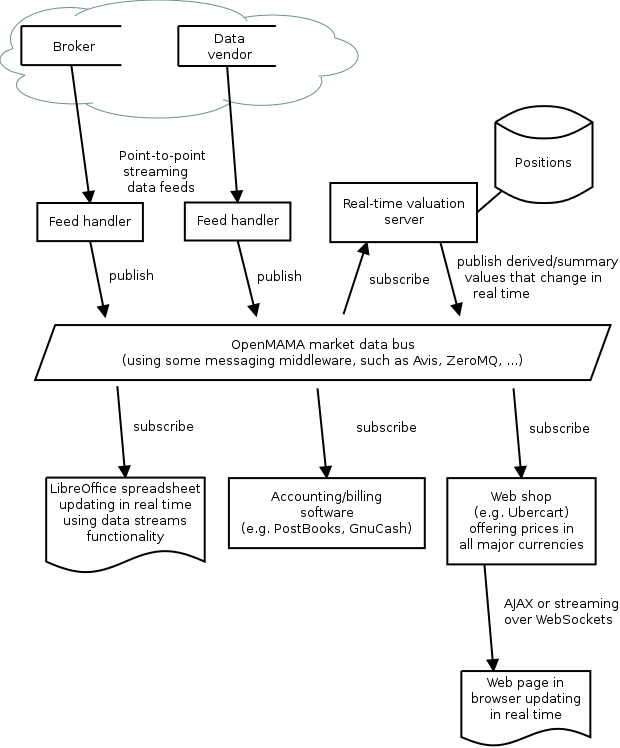
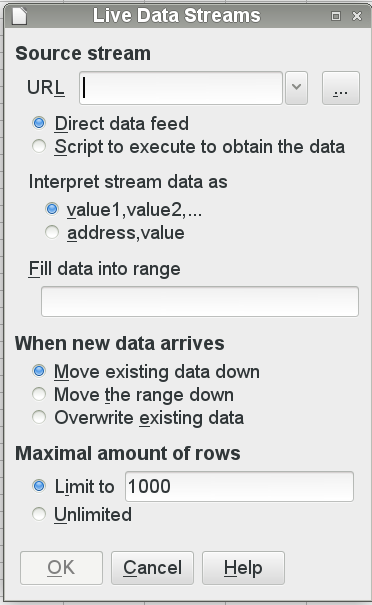
Here is an overview of the real-time market data architecture based on OpenMAMA: All these components may be running on a single host or they may be distributed across different servers and workstations in a LAN. The OpenMAMA market data bus ties them together. External data sources These are external sources of data. These could be currency trading firms, stock brokers, bullion dealers or even Bitcoin exchanges. Some exchanges don't provide data services directly to the general public and they distribute their price data through third-party data vendors such as Reuters and Bloomberg. Feed handlers The feed handlers manage the connections to external data sources. These are typically daemon processes that implement the wire protocols used by the external vendors for transmitting data over the public internet or a leased line. They typically use a point-to-point topology such as TCP connections. The feed handlers publish the data into the market data bus. In practice, the feed handler may be a proprietary application provided by the data vendor or it may simply be a Python script that fetches exchange rates from a URL every five minutes. OpenMAMA The market data bus is a distributed framework that is accessible to all of the local servers and workstations in the LAN. At the lowest level a messaging middleware solution is used to transport the data. The Avis Event Router is a free middleware. There is upcoming support for Apache QPID as well. Some commcercial middleware is supported too - here is the full list OpenMAMA does not provide a daemon or server process of its own. It is a set of libraries that operate on top of the middleware transport. In very general terms, the OpenMAMA libraries let applications publish messages (such as price ticks) or subscribe to receive the messages published by other applications. Spreadsheet application (for example, LibreOffice) LibreOffice is introducing a new data import feature for streaming time series data. This appears to provide a useful integration point for OpenMAMA and discussion is taking place in the development community. The spreadsheet can operate in various ways. A simple application may simply poll the currency prices when the spreadsheet is opened or refreshed. A more demanding application may see the spreadsheet come alive, recalculating all cells on every tick from the data vendor (several times per second). This latter scenario is more common in dealing rooms and hedge funds. Accounting/billing software There are many free accounting applications today, including PostBooks and GnuCash and some more heavyweight solutions like Adempiere and OpenERP. In a world where credit cards and the world wide web have made international trade an everyday activity, many people are using this software to track expenses and accounts in more than one currency. For example, a British business may be paying some suppliers in Euros and a Canadian may be charging some customers in US dollars. A Swiss person may be keeping some of their savings in gold bullion in the vault of one of their world reknowned Swiss banks. A common requirement for all of these users is the balance sheet. Using real-time market data sources, the balance sheet can be refreshed at any time from the live market prices. A home user may just find it convenient that they can open the balance sheet and always see their net worth immediately without having to manually cut and paste the currency prices from a web page. A business user operating in a competitive industry with low margins may be checking the balance sheet several times per day to ensure they remain solvent and profitable. Web shops Many web shops now offer the customers the convenience of viewing prices in their own currency. It is important to make sure these prices are accurate, especially when dealing with volatile currencies or when the products have a low profit margin. The web application server can receive the market data price ticks just like any other application in the network. Using this data, it can insert live prices into the pages as they are generated. If the currencies are particularly volatile, the web application could stream the prices to the browser using WebSockets and a JavaScript client embedded in the page would update the price field in real time. In fact, this web-based streaming price update mechanism is exactly how many online financial trading services offer live market prices to their customers. Real-time valuation server In a large organisation there may be many users looking at the same values. For example, in a trading desk, many users may need to see the desk's overall position in each market. In a busy web shop, many concurrent users may need to see the prices of common products. Rather than recalculating these values for each user in parallel, a common solution involves setting up a server to receive raw values (such as currency prices) from the data feed, calculate values needed by local users and then broadcast those values over the market data bus. How applications can integrate with real-time market data Here are some steps for getting started:
Daniel Pocock: Real-time streaming market data with free software

Here is an overview of the real-time market data architecture based on OpenMAMA: All these components may be running on a single host or they may be distributed across different servers and workstations in a LAN. The OpenMAMA market data bus ties them together. External data sources These are external sources of data. These could be currency trading firms, stock brokers, bullion dealers or even Bitcoin exchanges. Some exchanges don't provide data services directly to the general public and they distribute their price data through third-party data vendors such as Reuters and Bloomberg. Feed handlers The feed handlers manage the connections to external data sources. These are typically daemon processes that implement the wire protocols used by the external vendors for transmitting data over the public internet or a leased line. They typically use a point-to-point topology such as TCP connections. The feed handlers publish the data into the market data bus. In practice, the feed handler may be a proprietary application provided by the data vendor or it may simply be a Python script that fetches exchange rates from a URL every five minutes. OpenMAMA The market data bus is a distributed framework that is accessible to all of the local servers and workstations in the LAN. At the lowest level a messaging middleware solution is used to transport the data. The Avis Event Router is a free middleware. There is upcoming support for Apache QPID as well. Some commcercial middleware is supported too - here is the full list OpenMAMA does not provide a daemon or server process of its own. It is a set of libraries that operate on top of the middleware transport. In very general terms, the OpenMAMA libraries let applications publish messages (such as price ticks) or subscribe to receive the messages published by other applications. Spreadsheet application (for example, LibreOffice) LibreOffice is introducing a new data import feature for streaming time series data. This appears to provide a useful integration point for OpenMAMA and discussion is taking place in the development community. The spreadsheet can operate in various ways. A simple application may simply poll the currency prices when the spreadsheet is opened or refreshed. A more demanding application may see the spreadsheet come alive, recalculating all cells on every tick from the data vendor (several times per second). This latter scenario is more common in dealing rooms and hedge funds. Accounting/billing software There are many free accounting applications today, including PostBooks and GnuCash and some more heavyweight solutions like Adempiere and OpenERP. In a world where credit cards and the world wide web have made international trade an everyday activity, many people are using this software to track expenses and accounts in more than one currency. For example, a British business may be paying some suppliers in Euros and a Canadian may be charging some customers in US dollars. A Swiss person may be keeping some of their savings in gold bullion in the vault of one of their world reknowned Swiss banks. A common requirement for all of these users is the balance sheet. Using real-time market data sources, the balance sheet can be refreshed at any time from the live market prices. A home user may just find it convenient that they can open the balance sheet and always see their net worth immediately without having to manually cut and paste the currency prices from a web page. A business user operating in a competitive industry with low margins may be checking the balance sheet several times per day to ensure they remain solvent and profitable. Web shops Many web shops now offer the customers the convenience of viewing prices in their own currency. It is important to make sure these prices are accurate, especially when dealing with volatile currencies or when the products have a low profit margin. The web application server can receive the market data price ticks just like any other application in the network. Using this data, it can insert live prices into the pages as they are generated. If the currencies are particularly volatile, the web application could stream the prices to the browser using WebSockets and a JavaScript client embedded in the page would update the price field in real time. In fact, this web-based streaming price update mechanism is exactly how many online financial trading services offer live market prices to their customers. Real-time valuation server In a large organisation there may be many users looking at the same values. For example, in a trading desk, many users may need to see the desk's overall position in each market. In a busy web shop, many concurrent users may need to see the prices of common products. Rather than recalculating these values for each user in parallel, a common solution involves setting up a server to receive raw values (such as currency prices) from the data feed, calculate values needed by local users and then broadcast those values over the market data bus. How applications can integrate with real-time market data Here are some steps for getting started:

Axel Beckert: Showing packages newer than in archive with aptitude

I happens quite often that I install a manually built, newer version of some package on a machine. Occassionally I forget to remove it or to downgrade it to the version in the APT repo.
$ apt-show-versions   fgrep newer
easily finds those packages. But usually when doing such a check, I want this list of packages in my aptitude TUI to have a look at the other versions of that package and to take actions. And I don t want to manually search for each of the package manually. This can be done with the following one-liner :
# aptitude -o "Aptitude::Pkg-Display-Limit=(  apt-show-versions   fgrep newer   awk -F '[ :]' ' printf "~n ^"$1"$   " '   sed -e 's/  *$//'  )"
It uses apt-show-version s output, searches for the right packages, takes the first column and transforms it into an aptitude search pattern matching all packages whose name is exactly one of the listed packages. But this solution is quite ugly and slow. So I wondered if this is also doable with pure aptitude search patterns which likely would also be faster. And after some playing around I found the following working aptitude search term:
~i ?any-version(!~O.) !~U !~o
This matches all packages which which are installed and which have a version which has no origin, i.e. no associated APT repository. Since this also matches all hold packages as well as all packages not available in any archive, I use !~U !~o to exclude those packages from that list again. Since nobody can remember that nor wants to type that everytime needed, I added the following alias to my setup:
alias aptitude-newer-than-in-archive='aptitude -o "Aptitude::Pkg-Display-Limit=~i ?any-version(!~O.) !~U !~o"'
Only caveat so far: It seems to also match packages from APT repos which haven t set an Origin . This should not happen with any Debian or Ubuntu APT repository, but seems to happen occasionally with privately run APT repositories. And using ~A instead of ~O, i.e. ~i ?any-version(!~A.), does not work for this case either, despite it matches installed packages of which versions not in any available archive exist. But unfortunately aptitude seems to remember in some way if a package was in some archive in the past, so this only shows packages installed with dpkg -i, but not packages removed from e.g. unstable but with older versions still being available in stable.

Axel Beckert: Next Debian Meetup in Zurich

The first Debian meetup in Zurich last month was quite a success and I look forward to further Debian meetups in Zurich every first Tuesday of the month. The next meetup will be

on Tuesday, 2013-Dec-03 starting at 18:30 CET
at St. Gallerhof, Konradstrasse 2, 8005 Zurich
Please note that this is a different location than last month. Everybody who is interested in Debian is welcome to join us. Registering is not necessary. There was also some interest in Debian meetups in other Swiss cities, namely Bern and somewhere around Lac Leman. In case you want a Debian meetup elsewhere in Switzerland, too, or if you re interested in any Debian meetup in Switzerland, feel free to join the Swiss Debian Community Mailing List and help organising other Swiss Debian meetups.

Daniel Pocock: The free software country?

Loch Ness Monster, Scotland There is big news in Europe right now, especially the UK, about the Scottish nation's manifesto for independence. I thought this was really amazing, a country that is going to move to free software and protect its citizens from horrors like DRM. I couldn't wait to find out more, for example, will they use Linux or *BSD? After all, how many nations today can really consider themselves independent when they are trapped in the use of complex and opaque systems that require ongoing royalty payments to a foreign corporation, much like ancient villages paying their tithes to Rome? Today it is actually worse: these independent nations are not just sacrificing their cash - the new Rome is also using those same secret, proprietary systems to raid their subjects' privacy. So I went to the manifesto's web site to get the details. I couldn't even find the words "software" or "technology" listed in the policy index on the front page - and software doesn't even appear in the search results. A section on Culture, Communications and Digital only really looks at the issues for the media (BBC after independence). They don't even make any comment about the British Telecom (BT) pension crisis and whether Scotland will abandon BT's services, leaving only those customers south of the border to continue subsidising the deficit through higher phone bills. There is some hope, with the dot scot (.scot) top level domain coming in 2015 regardless of the referendum outcome. Does this mean an independent Scotland is going to be run without technology at all then? That could be an interesting way to avoid the type of infiltration of communications technology that has been taking place in Brussels. Or do the people calling the shots simply fail to realise the impact of software and communications technology on a modern day concept of independence? Party date set For those who just care about gatecrashing the post-independence party, start booking your leave for March 2016.

Next.

Previous.