
Some months ago, I got a phone call from
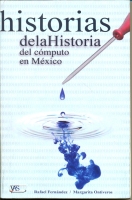
Rafael Fern ndez Flores. He wanted to interview me for a book he was working on regarding the history of computers in Mexico. The first computer in Latin America was installed in 1958 at my University (UNAM), and last year there were several activities conmemorating it. One of said activities is the publication of the book
Historias de la Historia del c mputo en m xico, by Rafael Fern ndez and Margarita Ontiveros.
The book was printed in November, and Rafael gave me my copy in early December. It is quite an entertaining read - I mostly enjoyed the archaeological parts of it, referring to the 1950s and 1960s, and with many people that I know first hand (as my father is one of the founding researchers of the
Centro de Investigaci n en Matem ticas Aplicadas, Sistemas y Servicios, CIMASS, now IIMAS).
I do believe, anyway, the book is focused too heavily on what happened in the large-scale computer world during a fundamental point in time for me (late 1970s, early 1980s) - It shows that the authors were very involved in the important projects the University set foot on, but they overlook fundamental pieces of the history. Very important developments were made in smaller venues (it was shocking for me to find only
one mention, and just as a reference, to
Fundaci n Arturo Rosenblueth and its
great Centros Galileo, where many hundreds of kids (me included) learned to love computers, to program, and had a thriving socialization place. I also missed mentions of the BBS scene in Mexico, for which there are various exponents. And, just to single out one person, I found it absurd to have me interviewed and
not to include
La Mancha de la Calabaza que Ladra.
One of the last chapters -there are over 40 chapters, stemming from over 30 individual interviews- publishes the talk I had with Rafael. I must say there are small errata in its transcription (the first example that comes to my mind: I told him that one of the fruits of the OLPC project was the appearance of the now-popular netbooks, partly due to the appearance of lower cost parts, but I must reiterate
I didn't say the Asus EEE is a part of said project). You can I am attaching my interview (as scanned, low-res images) to this post, in case you are interested.
Anyway - If the topic interests you, you will find many interesting passages, many passages you will surely laugh with and probably remember. The book is very well laid out. And it is a great joy to be part of it!

I've been owning a
Nintendo Wii for quite a while now, but so far only played an occasional game of tennis or the like. Over the holidays I got
The Legend of Zelda: Twilight Princess, which is a really nice game in itself. What is even more interesting though, is that this game allows you to run
homebrew software on your Wii.
What you usually want to do, is to use the so-called
Twilight Hack to install the
Homebrew Channel on your Wii (you'll need an SD card and the Twilight Princess game for this). Once the process has finished you won't need the game anymore though.
So, here's a quick tutorial on how to install the Homebrew Channel. I basically followed the
Setting up your Wii for Homebrew HOWTO from
wiibrew.org.
Requirements
An SD card max. 2GB in size (not an SDHC card!), an SD card reader in your PC or laptop, and the Twilight Princess game (which you must play at least once).
Backup
First, you'll want to backup your Twilight Princess save games (if any). For that, we format the SD card (it needs a FAT16/FAT32) filesystem.
$ mkfs.vfat /dev/mmcblk0p1 (you may need to change "mmcblk0p1" to whatever fits your setup)
Now insert the SD card into the Wii, start the Wii, go to Wii Options --> Data Management --> Save Data --> Wii and copy your Twilight Princess save games onto the SD card. Then, poweroff, remove the SD card, insert it into your laptop/PC and copy the save games to a safe place.
 $ mount -t vfat /dev/mmcblk0p1 /mnt
 $ mv /mnt/private ~/zelda_savegames
Twilight Hack and Homebrew Channel

Next up: download the Twilight Hack and Homebrew Channel, and put the files on the SD card:
 $ wget http://hbc.hackmii.com/dist/twilight-hack-v0.1-beta1.zip
 $ unzip twilight-hack-v0.1-beta1.zip
 $ cp -r private /mnt
 $ wget http://hbc.hackmii.com/dist/the_homebrew_channel-1.0.1.tar.gz
 $ tar xfvz the_homebrew_channel-1.0.1.tar.gz
 $ cp the_homebrew_channel-1.0.1/boot.dol /mnt
 $ umount /mnt
Now remove the SD card, insert it into the Wii and power-up the Wii. Go to Wii Options --> Data Management --> Save Data --> Wii, delete the Wii Twilight Princess save games, then copy the "Twilight Hack" save game from the SD card onto the Wii (you need to select the correct one
for your region).
Quit the menu, start Twilight Princess, load the "Twilight Hack" savegame and finally talk to the person in front of you (do not perform any other actions, or the Wii may crash!). Follow the remaining instructions on the screen and you're done. You now have an additional channel named Homebrew Channel where all your homebrew programs/games (and your own Free Software programs you may write/port) will appear.
Installing homebrew software
So far, there are no real applications in the Homebrew Channel, you need to
put all the homebrew software you want on the SD card. There's a
huuuge list of applications and games to choose from, many of them Free Software with source code, some however are binary-only.
Basically, you put each application in a sub-directory of apps/ on the SD card, the most important file in every sub-directory is always boot.dol. If you have a boot.elf file instead, you'll probably need to convert it using the
ELF to DOL converter.
Restoring Twilight Princess save games
You may now want to restore your Twilight Princess save games onto the Wii, you no longer need the "Twilight Hack" save game. Put your ~/zelda_savegames directory on the SD card and name it private/ again. Insert the SD card into the Wii and copy the save games on the Wii (similar procedure as above).
Have fun with homebrew software on your Wii, or even better
write your own software or port existing Linux applications/games!

I was thrilled to be part of a successful Debian bug squashing party
organized by MIT's
Student Information Processing Board on December
13th.
Greg Price, who helped organize the event, did
a wonderful
write up which he sent to the debian-devel email list.
I though it was worth mentioning the BSP now because I think it's a
wonderful model that I'd love to see replicated in Debian and beyond.
The event was initiated, organized, run, and executed by people with
little or no direct experience with the project. While the organizers
went out of their way to recruit several Debian developers and other
experts to the party, these experts' role was more in answering
questions and helping others. The the majority of the participants --
around 30 of them in total -- had no previous experience doing Debian
development.
While the 11 bugs closed or dealt with are the most visible outcome, I'm
not sure that it is the most important. The event acted as an important
learning experience for everyone involved and, perhaps most centrally,
an important first step for most participants from using free software
to giving back and participating in the community.
You don't need experience, connections, or a @project.org email address
to organize a party like this for Debian or your own free software
project. All you really need is a few people, some technical knowledge,
an Internet connection, and the desire to make it happen.
Other things can help, of course. In particular, the SIPB folks have
packaged up some scripts they used to select bugs to work on and
put
them online.

J r my Bobbio suggested that I should explain how I looked for packages
affected by a compiler bug
(
Debian bug 506713;
gcc bug 38287). I don't claim that
this is a particularly good way to do it, but here it is:
First, I identified a pattern to search for. Unfortunately I don't really
understand the cause or fix for the bug, but I did have the example which
led to this bug report:
Debian bug
490999. The bad code was a stack-pointer-relative load immediately
after a stack allocation (SPARC save instruction) where the offset was not
adjusted for the stack allocation:
save  %sp, -112, %sp
ld  [ %sp + 0x40 ], %i5
I generalised this to:
save  %sp, offset1, sp
...
ld  [ %sp + offset2 ], register
where
offset1 +
offset2 < 0. Of course, this may
be valid if the intervening instructions include a
restore,
branch or store to the effective stack location that the last instruction
loads from. I ended up allowing up to 10 intervening instructions and
examining a disassembly to work out which cases were valid.
I looked up the instruction encoding for these two instructions.
Thankfully SPARC is RISC so they are simple and regular:
save %sp, offset1, sp is encoded as 0x9de3a000 offset1 & 0x1fffld [ %sp + offset2 ], register is encoded as 0xc003a000 reg << 25 offset2 & 0x1fff
I took the dumb but effective approach of scanning entire files for
this pattern rather than only scanning their code sections. This seemed to
work - I got no false hits for non-code - but might not work for other
patterns that could match ASCII text.
I wrote the scanning program in Python, which is my default choice of
language unless I know it's going to be too slow. I was hoping to be able
to read the code files into arrays, but unfortunately the Python array
type only supports the native byte-order (SPARC is big-endian and I was
intending to use an x86 which is little-endian). I tried reading into a
tuple using struct.unpack, which does support explicit byte-ordering, but
this used so much memory for larger files that the program swapped to a
crawl. So finally I resorted to reading the file into a string, doing a
string search for '\x9d\xe3', rejecting matches that weren't appropriately
aligned, then unpacking and comparing the code words from the point of the
string match.
(In Python 3.0 I would have to use the
bytes type for this,
as
str is a Unicode string type.)
So that's how I scanned single files. The next step was to find, unpack
and scan all the SPARC shared libraries in the archive. (This particular
code generation bug is understood to affect only PIC code, and that is
normally only used in shared libraries.) I wrote functions to search
Contents-sparc for shared library files - assumed to match the pattern
([^\s]*/lib[^/\s]+\.so(?:\.[^/\s]*)?) - and to parse
Packages to find the filenames for the packages containing those files.
The latter uses the
debian_bundle.deb822 module from
python-debian.
The last key function downloads and unpacks a package using
wget and
dpkg-deb. I could have used
the
httplib module for downloading but I correctly
anticipated that I'd need to restart the script several times so I
wanted to cache the packages which was easier to do using
wget.
So, that's the explanation. If you really want to see it,
here's
the code.

(or
echo "blosxom hold" sudo dpkg --set-selections)
A few people had pointed out to me that my blog was appearing weirdly in
Google Reader. I myself read my blog via Planet Debian and Planet Linux
Australia, where it appears fine, so I hadn't noticed the problem first
hand.
I did some digging tonight with the
Feed Validator, and I think I've
figured it out.
Funnily enough, it all started with a previous session with the Feed
Validator...
I wanted my blog to be UTF-8, with it being the new hotness and all.
Blosxom was spitting it out as ISO-8859-1.
I've just learned from this evening's debugging, that this is the behaviour
of
CGI.pm's
header() function if not provided with the
-charset
parameter.
I'd previously worked around this by defining my own content_type for the
RSS and HTML flavours. In this file, I just put
text/xml;
charset=utf-8and
text/html; charset=utf-8, respectively.
Unfortunately, this then breaks Blosxom's internal
HTML-escaping-for-RSS-feed code, which is conditional on the content type
being XML:
if ($content_type =~ m \Wxml$ )
# Escape <, >, and &, and to produce valid RSS
my %escape = ('<'=>'<', '>'=>'>', '&'=>'&', '"'=>'"');
my $escape_re = join ' ' => keys %escape;
$title =~ s/($escape_re)/$escape $1 /g;
$body =~ s/($escape_re)/$escape $1 /g;
This block of code was being ignored because the regex was anchored.
"
text/xml; charset=utf-8" didn't match "
\Wxml$". Whenever I
last had an attempt to make my blog's feed pass the Feed Validator, I must
have edited the Blosxom source code to make this regex not be anchored.
Then on November 11, 2008, I updated my Blosxom package to 2.0-14+etch1, to
address CVE-2008-2236 (incidentally, there doesn't appear to be a Debian
Security Advisory for this?), and my local modification got clobbered.
That'll teach me to make local modifications and not put the package on
hold. Blah.
It seems I'm screwed, there's no way to have a well-formed UTF-8 RSS feed
without requiring a source-code modification to Blosxom. I've either got to
change the way the
header() function is being called, or I've got
to change the regex to allow me to specify a charset in the flavour file,
and not disable HTML escaping.
Speaking of screwed, Blosxom seems incapable of making a well-formed RSS
0.91 feed anyway. It wants to put the <pubDate> tag inside an
<item>, which is a violation of
the DTD. There's supposed to
be one for the whole <channel>, not one per item (or "story" in
Blosxom-flavour-speak). You can't just move that from the story flavour file
to the head flavour file, because a pile of variables that you'd otherwise
use seem to only get set on a per-story basis. Double blah.
I'm starting to feel like Blosxom is outliving its usefulness, but I really
do not feel like embarking on a wholesale move to a new blogging platform,
I'm fairly entrenched.
I try to practice
Inbox Zero, and this past year has been brutal far staying on top of my Inbox. When I started pruning the home email a week or so ago (having just gotten my work email box down to zero). It's giving me a pretty good review of 2008. And, umm.. wow:
Spinal tumor, surgery, hating Mountain View (the place, not the job there. My coworkers are pretty uniformly awesome), having a toddler, not being able to lift my toddler, crazy mood altering drugs, visa renewal, a funeral, unexpected pregnancy, weddings, buying a house, mid-term miscarriage, Angie's hospitalisation from that, pneumonia, a move home, having to withdraw from my Master's courses 3 times over the course of the year for medical reasons - eventually causing me to withdraw from the program. Extend it by another 3 months into 2007 (because while I'd love to believe that stress reset at the start of a calendar year...), and we have another wedding, a move to the US and a new job.
I've just gotten to an email where I took notes on what the risks were for the angiogram before I'd told many friends. There's a small pile of emails and such from people wishing me well that I never managed to reply to. I also find myself thinking back to the people I didn't hear from, and the reevaluation of my communities and friendships that came along with that.
The lyrics from Counting Crows come to mind: "It's been a long December and there's reason to believe that maybe this year will be better than the last."
Here's to 2009. =)
Some people consider the
gnome usability
guidelines a nuisance and some consider certain applications
way too simplistic. While it is really hard to get the usability
right, it's well worth it.
We need to keep in mind that as computer oriented people we tend
to see things differently. Things that are simple to us aren't
really that simple to the "normal people". But one of the simple
things we can do the insure that the software we write serve the
people it's designed for is to remove all not needed pop-ups and
questions.
A good way to detect these would be to ask yourself why would a
user choose anything else but the most logical option. It's kind of
hard to explain, so lets pick an example:
Firefox is
updated, the first question it usually asks after upgrade is about
incompatible extensions. The user is presented with choices, check
for updates or cancel. Now, we are dealing with internet browser so
the user should be connected to the internet so there is no problem
with checking for the updates, we can rule out that scenario. The
other scenario that I can come up with is that a developer doesn't
want to update some certain extension.
So at least I can't come up with any reasonable scenario why
someone would want to select anything else but to upgrade the main
option of upgrading the extensions. Why not just leave out the
option and instead do the upgrade automatically. If you wish to be
transparent, you can show the user that you are doing the upgrade.
Or you can do like some applications do and just do it without
bothering the user with the options.
I know I sound like a Google fanboy, but Google generally gets
this right. Their applications skip out all upgrade related notices
and just do the upgrade. Regular user doesn't want to upgrade
because the user has been scared with incompatibility notices and
upgrade checklists for so long. Just going ahead with the upgrade
in complete silence keeps their software up to date as well.
Another example would be from few years back: The
Ubuntu installation. Back in the day
Debian was working on Debian
Installer, which is also used as the main installer in
Ubuntu alternative installation media.
Debian Installer is capable of doing most things silently, but with
Debian it by default asks a
lot of questions. It doesn't matter, since most people who install
Debian can be categorized as
developers. But in my opinion, the thing that made
Ubuntu a success was that it doesn't
ask the questions that can be answered without asking the user.
So, back to usability. There are basically 2 camps, the "normal"
users and the developers. Developers want and need to see a lot of
the backend behaviour, just to debug problems. Currently a lot of
the open source software is focused towards developers while they
are gaining grounds on the "normal" population as well. We should
start focusing on the users for a change.

Christmas holidays in France are not a good season for runners: too much champagne, foie gras, cheese, wine and food in general.
So, while visiting my mom and sister in the region of St-Etienne last week, I wanted to keep my sports pace to a sufficient level as we're now 3 months ahead from this marathon I've been crazy enough to apply for.
That went good:
3 days after my first run over 30km, my brother in law convinced me to enjoy the big snow fall in
Le Bessat, the ski station of my young years, 30 minutes away from the city of St-Etienne.
That was the second time ever I'm doing croos-country skiing in skating technique. But, being supposedly used to skiing in general (20 years of ski are supposed to help), we went on the longest and hardest track: 16km and over 200m positive slope....which I completed in less than 2 hours, so a lot more than the same distance by running. Cross-country skiing in skating technique is awfully hard, particularly when you have no technique at all..:-))
To complete this, I went running for about 12 km on New Year, 3 hours after partying for New Year's Eve. Interesting way to eliminate the weight surplus..:-)
And, finally, today, I went out for a 19km run in the frozen country around my place (-8 degrees) for a wonderful discovery of woods covered with ice and the climbing of the highest "mountain" in the Paris area (280m height, still !) and a great view of the neighbourhood in white, under the sun. These are the joys of running in winter, really.

I really like the
This American Life podcast. It's probably one of my favorite pieces of public radio, and having a full high-quality public feed is fantastic. However, I've been a little grumpy about the long forewords that have been put into the show lately, asking for donations from podcast listeners.
Here's the scoop: apparently
WBEZ (Chicago Public Radio) is spending US$150K just on the bandwidth to keep the podcast on the air (not counting servers, staff, or whatever). This is not just small potatoes for WBEZ; they just laid off a dozen workers. So, podcast listeners should pay their fair share and help out Chicago Public Radio.
Now, I'm a big fan of public radio, and I think everyone should become a member. However, I find the premise of this solicitation kind of faulty. First, there are a lot of technical ways they could cut down on their bandwidth requirements. Providing an alternative
BitTorrent RSS feed, for example, would reduce their bandwidth requirements a lot. They'd need to put a bit of documentation on their site, but is that really harder than getting people to pony up $$? I think not.
Second, they could change the redistribution requirements and let other people or organizations mirror the episodes. A
Creative Commons license would let other people distribute the files, saving WBEZ a lot (possibly all) of the distribution costs.
But that second option is probably not that interesting to WBEZ. Why not? Because they make money selling "This American Life" to other public radio stations. If they put it under a free-redistribution license, they wouldn't be able to get that income.
So, in reality, the service announcements at the beginning of the podcasts aren't really asking listeners to keep the podcasts running. There are lots of ways to do that. What the announcements ask is for listeners to support a particular "business" model. There are even ways (like BitTorrent) to have their cake and eat it too. I'm still going to contribute to WBEZ, since I like the show and I'm glad it's produced the way it is. But I regret the disingenuous guilt-tripping that's going on. It's not a fair way to treat listeners and supporters.
tags:
thisamericanlife wbez publicradio podcast cc bittorrent

I make a lot of Web script processing, whether scraping, webservices, systems administration, etc. Because I sometimes happen to repeat small and useful chunks of code for different projects, I thought that, given making new modules and methods is usually hassleless in Ruby, I should make my own set of methods and goodies I constantly use. Example 1, I sometimes miss Perl s LWP::Simple simplicity where I just pass a URL to a subroutine and get the content on a variable, quick, one-liner. Example 2, extract all links on a given URL on an array that I can then iterate and maybe fetch given the first example. Getting all A links is very easy to do, say with regex or with Hpricot (which should the best way to parse HTML), but most of the time I (and people, I d bet) need absolute URLs which is fairly more complex (relative, absolute URLs, BASE href declarations, etc, the same case as in
Feedbag).
Well, for different cases like that one, I ve started my own set of Ruby goodies. If you don t find them useful, I understand, they are mostly for my needs, I just want to make it public, because maybe, some other people might indeed find them useful.
Simple installation:
sudo gem install damog-goodies -s http://gems.github.com/
As time and needs pass, I will be adding stuff into it. For the time being, here s both above examples in action:
>> require "goodies"
requiring /var/lib/gems/1.8/gems/damog-goodies-0.1/lib/goodies/array.rb
requiring /var/lib/gems/1.8/gems/damog-goodies-0.1/lib/goodies/lwr.rb
requiring /var/lib/gems/1.8/gems/damog-goodies-0.1/lib/goodies/html.rb
=> true
>> pp HTML::Links.find "damog.net"
["mailto:david-YOUKNOWTHEDEAL-axiombox.com",
 "http://log.damog.net/",
 "http://historiasdenuevayork.com",
 "http://axiombox.com/",
 "http://flickr.com/photos/raquelydavid",
 "http://last.fm/user/damog",
 "http://maggit.com.mx",
 "http://twitter.com/damog",
 "http://www.facebook.com/profile.php?id=670490388",
 "http://www.chess.com?ref_id=1380378",
 "http://www.chess.com",
 "http://www.chess.com/members/view/damog?ref_id=1380378",
 "http://www.chess.com/echess/create_game.html?uid=1380378&ref_id=1380378",
 "http://www.chess.com/home/game_archive.html?member=damog&ref_id=1380378"]
=> nil
>> pp HTML::Links.find("http://google.com").first(10)
["http://images.google.com/imghp?hl=en&tab=wi",
 "http://maps.google.com/maps?hl=en&tab=wl",
 "http://news.google.com/nwshp?hl=en&tab=wn",
 "http://www.google.com/prdhp?hl=en&tab=wf",
 "http://mail.google.com/mail/?hl=en&tab=wm",
 "http://www.google.com/intl/en/options/",
 "http://video.google.com/?hl=en&tab=wv",
 "http://groups.google.com/grphp?hl=en&tab=wg",
 "http://books.google.com/bkshp?hl=en&tab=wp",
 "http://scholar.google.com/schhp?hl=en&tab=ws"]
=> nil
>> get "debian.org"
[snip]
>> get("planeta.debian.net")[0, 100]
=> "<!DOCTYPE HTML PUBLIC "-//W3C//DTD HTML 4.01 Transitional//EN" "http://www.w3.org/TR/html4/loose.dtd"
>>
Repository is, as usual, kindly hosted at
GitHub on
damog/goodies.
I ve owned two different GPSs in the past: a Garmin GPS III, and the Garmin eMap. Both are based on similar underlying firmware.
This week, I did some research on more modern GPS units and decided to buy a Garmin nuvi 500. Here s my review.
Overview
The Garmin nuvi 500 is one of only two models in the nuvi line that are waterproof. The nuvi 500 and 550 are both designed as hybrid units: useful both in the car and outdoors. The 500 includes street-level maps (they appear to be the same quality as Google) for the entire United States, detailed topographical maps for the entire United States, and a global basemap. It also includes a microSD slot (or is it miniSD - I forget) for additional maps that you can buy anything from marine maps to other countries.
It also includes a default POI (points of interest) database containing over 5 million points: restaurants, gas stations, parks, hospitals, you name it. Most contain an address and a phone number in additional to the coordinates. Unlike GPS units that you find built in to some cell phones, this is all stored on flash memory on the unit: no Internet connection required. The nuvi 500 is a portable yellow pages, topographical map, and incredibly detailed street atlas all in one.
Car Use
The nuvi 500 comes with a car charger and suction cup windshield mount in the box. (It doesn t come with an AC charger, but it can charge over USB.) It also comes with yay a user-replaceable battery. The windshield mount is very sturdy and I am happy to have one that isn t permanent.
In the car, the device performs admirably. I have read some other reviewers that have compared its routing to other GPSs and found that the nuvi generally picks the same route as Google, and almost always a better route than other GPSs. If you deviate from the selected route, it automatically re-calculates a new route for you. It will show you the next turn coming up, and has either 3D or flat map displays.
There s a one-touch where am I feature. It displays your current coordinates, some sort of street address suitable to read to someone ( 1234 S. Main or I-95 exit 43 type of thing), along with buttons to show you the nearest police stations and hospitals.
The unit also features multi-stop routing. You can either tell it where all you re going in a defined order, or tell it all your stops and let it create an optimal route. This feature works, but it your stops are close by (and involve some of the same roads), it may wind up skipping some stops thinking you ve made your first one.
The speaker announces upcoming maneuvers, though it doesn t have a synthesizer for street names. It s also supposed to work with Bluetooth headsets, though I haven t tested that feature.
I found the map quality to be excellent. It seems to be on par with Google (in fact, I think both use data from Navteq). I was surprised with how many country dirt roads and side roads it knows about and of course, regular city streets are all on there, with one-way indications and the whole lot. In fact, the quality of coverage was so good that I was surprised when it missed roads or got things wrong. Out in rural areas, or small towns, this happens from time to time: it thought that an abandoned railbed was an unnamed road and wanted me to drive on it (it was clearly not drivable), and in some other cases also thought some abandoned roads were still drivable. I don t think this is a device issue though; it s an underlying data issue, and everyone else probably has the same problem.
Its arrival time estimates are quite accurate, and its interface is smooth and easy.
It has some optional accessories I haven t tried, such as real-time traffic reports from wireless sources, boating mode, etc.
Outdoor and Geocaching Mode
Our other main use for the device is outdoor hiking and geocaching. It really shines here. It has special support for the GPX files from geocaching.com. The device supports paperless caching . Not only can it put caches on the map, but if you download the GPX file for your caches, you ll also get the full description, hint (behind a separate button, of course), most recent 5 logs, and the like right there on your screen. You can also log your finds on the device, and upload a file from it to geocaching.com later to log them on the site. This is an incredible time saver over my old method: printing out a bunch of maps, downloading waypoints to the eMap, taking notes, then logging things later.
I found outdoor mode not quite as refined as the auto mode, however. It kept forgetting that I wanted to use an arrow as my current position indicator (the default hiking boots for walking mode didn t provide an accurate enough direction indication for my tastes). Finally realized that saying don t ask me about the configuration was the key to getting it to remember the configuration. It sometimes took a surprisingly long time to realize we weren t standing still any longer.
On the other hand, the quality of the GPS receiver was amazing. It even got a strong signal in my house. And I wasn t even sitting at a window. The topographical maps are a nice addition, and the breadcrumb mode is always helpful when geocaching and hiking, too.
My natural way of holding it meant that I accidentally turned it off a few times, because I had a finger holding it right over the power button. But it powers back up and re-obtains the signal quite rapidly.
The different modes (automobile, outdoor, bicycle, and scooter) are mainly different collections of settings: 3D map or flat, what indicator to use, to navigate off-road or along roadways, to ignore one-way indications or heed them, etc.
PC link
The nuvi 500 has a USB port. Plug it into the PC, and you see its internal flash drive, vfat formatted. You can upload and download GPX files there, store photos if you like. Be careful what you mess with though, because its built-in maps and system data are also on that drive. If you have the SD card inserted, that will also be presented to your computer when you plug the device in. Garmin has some Windows software to make it easier to upload/download stuff, but I haven t tried it.
Annoyances
As you can tell, I really like this GPS, but there are a few things about it that annoy me.
The #1 thing that annoys me isn t actually the GPS itself, but Garmin s website. I went to register the device online, but it wouldn t let me because I don t have the Windows-only browser plugin on my Linux machine, and it wanted to talk to the GPS for some reason. I went to send them a support request about that, only to discover after I had typed in the request that their email us form is broken in Firefox on all platforms. Bad show, Garmin.
The on-screen keyboard (it s a touch-screen device with only one hard button for power) isn t QWERTY layout; it s alphabetical layout, and it makes me inefficient when entering data. I found myself logging my finds on the unit, but taking notes about them on paper because that was faster. Garmin has a feature listed on their website for a toggle between QWERTY and alphabetical layout, which they apparently offer on only their more expensive GPSs. What? There is no reason to not but that in all your firmware.
The device lacks a few features I was used to on my GPS III and eMap. It doesn t support any kind of real-time position indication to the PC; all communications is just accessing stored data on the internal flash drive. I used to think that was a nice feature, but in reality, I haven t used it in years. It also lacks the display of the exact location of each GPS satellite, though the incredible quality of its receiver means that I don t really care any more. (I used to use that information to help figure out which window to put it by if in a car/train or something.)
It also lacks the level of configuration that was present in the settings screens on the older units. There s no battery saver mode (sample every 5 seconds when going at a constant velocity instead of every 1) like the older units had. The sun and moon screen likewise is gone, but added is awareness of timezones; the Nuvi 500 can show you the local time at your present position synced up with the GPS satellites.
The compass is not the most helpful screen, though after some practice, it is functional. The documentation about it is confusing, but really the thing that was more confusing was this: in walking mode, the arrow that indicates what direction you re walking in updates faster than the arrow that indicates what direction you should be walking in. Once I realized what was going on there, it was easier to use.
The compass does tell you what your bearing is, in degrees, but only when you are not seeking a destination. It will not tell you the bearing to the destination, though you can estimate it from the simulated compass face on the display. When seeking a specific point, especially through terrain with obstacles such as trees, it is useful to be able to use a compass for the final approach because a GPS unit can t tell you which direction it s pointed only which direction it s moving, so when you re not moving or moving slowly, it s not helpful.
I did some experimentation today with the compass screen, as well as my real compass, and was able to navigate to my destination rather precisely using the combination of them. That said, a more functional compass screen would still be better.
Conclusion
Overall, I m very happy with the nuvi 500. It s not the same as a top-of-the-line device in either the outdoor or automotive category, but on the other hand, it s cheaper and more convenient than buying two devices with similar features. The geocaching features are excellent, the build quality is excellent as well. The system is stable and performs well. (Some other reviews worried about whether the case is solid enough; it seems quite solid to me.) I wish there were a faster way to toggle between 3D and flat map views, and forgetting about my walking mode icon is annoying, but other than that I have very little to complain about. Garmin s geocaching features (found on this unit and several other in their lineup) is great.

After a rather hectic holiday season, I returned momentarily to pending Geode X.org driver issues. The current status:
- On Debian, 2.10.1 is in Testing and Unstable, while 2.11.0 is in Experimental. For those who need 2.11.0 right away, the experimental package builds as-is using Lenny dependencies. For everyone else, I'll probably get around producing a proper backport once Lenny is released.
- On Ubuntu, 2.9.0-1ubuntu2.5 just entered Hardy-updates with cherry-picked fixes for DCC support on GX2/CS5535 hardware. Meanwhile, Intrepid has 2.10.1 and Jaunty has 2.11.0, with a backport of the later having been requested for Hardy-backports.
I'm especially interested in hearing from users of GX2/CS5535 hardware to see if these recent uploads finally fixed DDC probing for them or not. Just respond to relevant existing bugs or, if necessary, open new bugs to report any regression.

As I
had blogged
a while back, multiseat use broke following the normal upgrade to Ubuntu 8.10.
I had also suggested a fix but it turns out that the fix didn't work.
So we had a clear regression -- multiseat use of a single
Ubuntu workstation with two screens, two keyboards and two mice no longer worked. Consequently, the
kids ended up 'serializing' access to their computer letting the second screen go idle.
Shortly after Christmas, that computer suffered a catastrophic disk failure (and as an aside, I hate LVM when that
happens...). So I reinstalled, this time using the Ubuntu rather Kubuntu variant. This should allow use of
Userful Multiplier
--- a commercial multiseat solution with
free two-seat licenses.
The base package even comes via the Ubuntu repos.
I still had a couple of minor issues. One was possibly related to the Radeon card (as in: don't drive one
monitor in dvi mode and one in analog mode but rather use both in analog mode via a dvi/analog dongle) so the
live cdrom offered by Userful just went into a perpetual 'reconfigure, reboot, reconfigure, reboot, ...' loop.
Another hitch was that their license manager no longer wanted to use the license key I had requested in
November when I tried in vain to use Userful with KDE. And of course I wouldn't a new key as the home ip
address hadn't changed... Now, with a newly requested key from another IP address, things appear to work at
last using the default Gnome setup --- and the kids are back in proper 'parallel' use of their workstation.
All in all, Userful Multiplier is a nice and useful product especially as long as stock XFree does them the
favour of no longer competing in the basic two-seat case.

The other day, I wanted to prepare some videos of my favorite reggae and soul tunes for uploading them to YouTube.. My goal was very simple: prepare a video with a static image and the music I wanted to upload..
After briefly digging for a simple software to do that, which I could not found, I said "hey, why not doing it with
liquidsoap !". Well, that is fairly easy ! Video support in liquidsoap is very young, but the amount of things that can be done is already quite important, so I though this would be an interesting example..
All you have to do is to prepare a PPN version of the picture, using
convert /path/to/image.jpeg /path/to/image.ppn and have the mp3 or ogg file in an other place...
From the scripting point of view, the only difficult thing is to have liquidsoap stop at the end of the song.. As liquidsoap is mainly a streaming language, it is not designed to be able to stop easily. It should be made better soon, but for now I had to use a special trick: compose sequentially the song with a blank source. On the blank source, I add special metadata such that the output file is reopened with a new title when the song has ended. Eventually, the shutdown is triggered when adding the new metadata on the blank source.
Here is the code:
# Log to stdout

set("log.file",false)

set("log.stdout",true)

# Disable real-time processing, to process with the maximun speed

set("root.sync",false)

# Enable video

set("frame.video.channels",1)


# The video source using a static image

s = video.image(width=240,height=240,x=40,"/tmp/bla.ppm")

# The audio song.

audio = single("/tmp/bla.mp3")

# The special metadata function, that

# also triggers the shutdown..

def end_meta(_) =

  shutdown ()

  [("title","prout")]

end

# This is the blank source

bl = map_metadata(insert_missing=true,update=false,end_meta,blank())

# And the final source: the sequence song and blank added

# with the video of the static image..

final = add([sequence([audio,bl]),s])

# Output to a theora file, reopen on new metadata..

output.file.theora(reopen_on_metadata=true,"/tmp/$(title).ogv",

                             final)
The result is just what I wanted (surprisingly !):
The other videos can be found
here.

*.myopenid.com - page security information.
Equifax Secure Global eBusiness CA-1
PKCS #1 MD5 With RSA Encryption
Same for https://www.myopenid.com/signin_password and the same for the myOpenID.com SSL certificates that you actually use with myOpenID.com - all now known to be vulnerable to spoofing. I don't think I'll be using those any more.
SSL spoofing via MD5 certification
CA's using only MD5 to sign the certificate
Oops.
It depends on how you use OpenID I suppose, but if known weak certificates are removed from browsers in order to protect users from possible SSL spoofing, current myOpenID.com certificates will simply stop working.
Not really a surprise considering how Canonical came to exist but, Launchpad OpenID has got it right. Launchpad itself doesn't use a CA that relies solely on the weak MD5. Maybe I'll start using the Launchpad OpenID instead. (Launchpad OpenID still works with the Alioth OpenID support). However, it would be nice if the Launchpad OpenID could provide SSL certificates for users to import into browsers and then I could log into various sites directly. I did like that functionality with myopenid.com but those certificates have had to be revoked now.
Gold stars for Ubuntu and the Alioth admins. A pile of stinky brown stuff for the myopenid.com team.
Update:
Maybe it's time for Alioth to support OpenID more fully? Or there again, maybe not. After a little reading up on the
multiple failings of openid in general, I'm going to leave openid as it is (mostly disabled in my case) and use it only for stuff that really doesn't matter much. Using openid for important stuff just doesn't make any sense.

Recently the
Debian Administration website has been besieged by spammers submitting bogus comments.
I also run a couple of blogs which are constantly having random gibberish submitted to them - although it is less of a problem there because I approve them manually due to the offline nature of my blog, and the
blog compiler I use.
Regardless I figured it was time to do something about it, in part because
Chris Searle suggested that I should be able to query arbitrary text for spammyness due to my experience with
fighting email spam. (As it turns out that is not so useful experience. Comments and emails are not the same. The same header-trickery you see in bogus email, false EHLOs, etc, are not useful concepts to carry accross.)
Anyway we were saying, I was going to do something? So I did. My solution? An XML-RPC server which you submit your comments to. This will return either:
| OK | The comment is clean. |
| SPAM:[reason] | The comment is spam, and the optional reason explains further |
The server itself is very simple, and it comes with a collection of simple plugins which do the job of testing different things. More plugins will almost certainly be added over time - so far I've seen
the lotsaurls plugin capturing most of the SPAM, although
the DNSRBL lookup is also working nicely having captured live spam without my touching it. Huzzah. & etc..
If there is any interest feel free to let me know, although as
the server is open, and the
client side usage is documented I imagine other people could run with it easily enough too - avoiding me becoming a single point of failure.
For reference my initial change to hook this up live on the site was
only a few lines of code - although later I did need to make some additional changes to make it cope with failures, & etc.
ObFilm: Ghostbusters
So the failings of the GR result in just what everyone didn't need - a restarted discussion about the firmware issue without first releasing Lenny. Come on people, leave it alone and get Lenny done.
Anthony,
Thomas and
Theodore (also in
his blog) all seem to be missing the point(s):
- We had the GR and despite all the manifold failings of the GR itself, Further Discussion FAILED as did the option to delay Lenny ad infinitum (Option 1 on the vote).
- Everyone seems hung up on firmware as something that requires source code, when the real point is that firmware isn't necessarily like other content in Debian and in some (many?) situations, there is no, nor can be any, human-readable form - it really can be nothing more than a series of initialisation flags, not instructions that are specific to that chip or would not make any sense to any CPU.
To me, it's more like data for the chips - it's saying "this is who you are, this is what you do and this is how to understand all subsequent instructions". Software is what follows - the instructions themselves.
We have a very good understanding of the separation between software and data in userspace - we all recognise that unless the output of a program consists to a large extent of modified versions of already licensed code (e.g. code generators), then the data created by your free software GPL-3+ text editor (or blogging client) cannot be deemed to be under the GPL-3+ or any other licence until such a statement is made by the copyright holder and that the copyright holder is the user of the software, not the author of the software. I could quite easily put this blog under a Microsoft-style EULA or even NDA if I wanted to be obtuse, despite it being created using a free software stack. The point remains - I am the copyright holder of the content created using the free software on my machines and I am free to publish that data as I see fit. The authors of the software itself have no rights to dictate what I do with the content I create using the software, just as I - as a user - cannot dictate whether the authors of my editor choose to migrate from GPL-2+ to GPL-3+ or even BSD.
Where firmware can have source code, let it have source code - we have such packages in Debian already. Even then, much of the code may be simply calculations or conditionals to select the right combination of binary flags for specific situations. This isn't about Nvidia kernel drivers that do real runtime calculations during the entire runtime of the machine, this is about tiny bits of initialisation data that are set once and not touched again. Can we not accept that some firmware is derived from a process that does not involve source code? How about experimentation and calculation? We know the voltage on pins 5 and 19, we know the state of register A and that for this specific case, it needs to be toggled to match the state of register E because otherwise another chip on the same board gets confused, so setup the chip to do that by setting a firmware datum point to initialise A? Where's the source code in that process? There is none - it is a piece of data, an item in the design notes (or more likely the errata). Yes, maybe the chip should know how to set this datum itself but for whatever reason (probably financial), it doesn't.
Source code could be used to calculate the datum point for a range of chips and chipsets according to a range of data inputs but the creative effort is then in the calculation not the data. The chip doesn't want the calculation, it cannot perform a calculation in this uninitialised state, it needs the datum point. Once it has the registers set, it can then understand subsequent instructions - the software itself. The datum point itself is just a raw piece of initialisation junk for the chip, it has no source code, it is determined by a physical process. It is a reference point - a fixed value that is determined during the design of the chip and/or chipset.
It's like saying you want the source code that determines whether there are one hundred cents in a Euro so that you could modify it to create a thousand or just ten or maybe turn the Euro into a hexadecimal currency. Weird. The fact that the Euro has one hundred sub-divisions is not up for negotiation, it isn't a modifiable value - changing the value unilaterally is not going to magically make everyone use the new value. It is a fixed reference point - a single datum point that initialises all subsequent behaviour of all software utilising such a currency. Even if there was source code (gee, what could that be, do you think? "%.2i" ?) it would be meaningless to insist on being able to modify it.
Few people can make the judgement about whether particular firmware can or cannot have source code - in most cases it comes down to the hardware design of either just the chip or how the chip is utilised for a particular board.
At some point, Debian has to accept that we cannot know if source code was used to create a particular blob. We simply have to ensure that maintainers ask upstream, elucidate as much information as possible about how the firmware was created and document that in debian/copyright. If that information is proved to be incorrect, then we have to deal with it as best we can - on a package-by-package basis. The assumption has to be that firmware does not necessarily have any source code.
In the end, I think the GR came up with the right result, despite all the failings -
Option 5, assume that firmware is compliant with the GPL unless there is evidence to the contrary.
Sometimes, there simply is no source code - sometimes all you have is data.
Debian cannot insist on source code for data that is not generated from source code and it is the difficulty in deciding whether one set of figures is initialisation data or a set of compiled instructions that will defeat all debate on a general solution for the firmware debate. It is comparing apples and oranges - we can insist on source code where source code was used but we also have to accept that some firmware is identified, not programmed. In the end, Debian will have to trust the maintainer and the maintainer will have to trust upstream. Documenting that in debian/copyright seems to be the only sane option.
Now can we all just shut up and release Lenny? Please?