Vincent Bernat: IPv4 route lookup on Linux
 TL;DR: With its implementation of IPv4 routing tables using
LPC-tries, Linux offers good lookup performance (50 ns for a full
view) and low memory usage (64 MiB for a full view).
During the lifetime of an IPv4 datagram inside the Linux kernel, one important step is the route lookup for the destination address through the
fib_lookup() function. From essential
information about the datagram (source and destination IP addresses,
interfaces, firewall mark, ), this function should quickly provide
a decision. Some possible options are:
- local delivery (
RTN_LOCAL), - forwarding to a supplied next hop (
RTN_UNICAST), - silent discard (
RTN_BLACKHOLE).
Route lookup in a trie
Looking up a route in a routing table is to find the most specific
prefix matching the requested destination. Let s assume the
following routing table:
$ ip route show scope global table 100
default via 203.0.113.5 dev out2
192.0.2.0/25
        nexthop via 203.0.113.7  dev out3 weight 1
        nexthop via 203.0.113.9  dev out4 weight 1
192.0.2.47 via 203.0.113.3 dev out1
192.0.2.48 via 203.0.113.3 dev out1
192.0.2.49 via 203.0.113.3 dev out1
192.0.2.50 via 203.0.113.3 dev out1
Here are some examples of lookups and the associated results:
Destination IP
Next hop
192.0.2.49203.0.113.3 via out1
192.0.2.50203.0.113.3 via out1
192.0.2.51203.0.113.7 via out3 or 203.0.113.9 via out4 (ECMP)
192.0.2.200203.0.113.5 via out2
A common structure for route lookup is the trie, a tree structure
where each node has its parent as prefix.
Lookup with a simple trie
The following trie encodes the previous routing table:
 For each node, the prefix is known by its path from the root node and
the prefix length is the current depth.
A lookup in such a trie is quite simple: at each step, fetch the
nth bit of the IP address, where n is the current
depth. If it is 0, continue with the first child. Otherwise, continue
with the second. If a child is missing, backtrack until a routing
entry is found. For example, when looking for
192.0.2.50, we will
find the result in the corresponding leaf (at depth 32). However for
192.0.2.51, we will reach 192.0.2.50/31 but there is no second
child. Therefore, we backtrack until the 192.0.2.0/25 routing entry.
Adding and removing routes is quite easy. From a performance point of
view, the lookup is done in constant time relative to the number of
routes (due to maximum depth being capped to 32).
Quagga is an example of routing software still using
this simple approach.
Lookup with a path-compressed trie
In the previous example, most nodes only have one child. This leads to
a lot of unneeded bitwise comparisons and memory is also wasted on
many nodes. To overcome this problem, we can use path compression:
each node with only one child is removed (except if it also contains a
routing entry). Each remaining node gets a new property telling how
many input bits should be skipped. Such a trie is also known as a
Patricia trie or a radix tree. Here is the path-compressed
version of the previous trie:
 Since some bits have been ignored, on a match, a final check is
executed to ensure all bits from the found entry are matching the
input IP address. If not, we must act as if the entry wasn t found
(and backtrack to find a matching prefix). The following figure shows
two IP addresses matching the same leaf:
 The reduction on the average depth of the tree compensates the
necessity to handle those false positives. The insertion and deletion
of a routing entry is still easy enough.
Many routing systems are using Patricia trees:
Lookup with a level-compressed trie
In addition to path compression, level compression2
detects parts of the trie that are densily populated and replace
them with a single node and an associated vector of 2k
children. This node will handle k input bits instead of just
one. For example, here is a level-compressed version our previous
trie:
 Such a trie is called LC-trie or LPC-trie and offers higher lookup
performances compared to a radix tree.
An heuristic is used to decide how many bits a node should handle. On
Linux, if the ratio of non-empty children to all children would be
above 50% when the node handles an additional bit, the node gets this
additional bit. On the other hand, if the current ratio is below 25%,
the node loses the responsibility of one bit. Those values are not
tunable.
Insertion and deletion becomes more complex but lookup times are
also improved.
Implementation in Linux
The implementation for IPv4 in Linux exists since 2.6.13
(commit 19baf839ff4a) and is enabled by default since 2.6.39
(commit 3630b7c050d9).
Here is the representation of our example routing table in memory3:
 There are several structures involved:
struct fib_table represents a routing table,struct trie represents a complete trie,struct key_vector represents either
an internal node (when bits is not zero) or a leaf,struct fib_info contains the characteristics
shared by several routes (like a next-hop gateway and an output
interface),struct fib_alias is the glue between the
leaves and the fib_info structures.
The trie can be retrieved through /proc/net/fib_trie:
$ cat /proc/net/fib_trie
Id 100:
  +-- 0.0.0.0/0 2 0 2
      -- 0.0.0.0
        /0 universe UNICAST
     +-- 192.0.2.0/26 2 0 1
         -- 192.0.2.0
           /25 universe UNICAST
         -- 192.0.2.47
           /32 universe UNICAST
        +-- 192.0.2.48/30 2 0 1
            -- 192.0.2.48
              /32 universe UNICAST
            -- 192.0.2.49
              /32 universe UNICAST
            -- 192.0.2.50
              /32 universe UNICAST
[...]
For internal nodes, the numbers after the prefix are:
- the number of bits handled by the node,
- the number of full children (they only handle one bit),
- the number of empty children.
Moreover, if the kernel was compiled with CONFIG_IP_FIB_TRIE_STATS,
some interesting statistics are available in /proc/net/fib_triestat4:
$ cat /proc/net/fib_triestat
Basic info: size of leaf: 48 bytes, size of tnode: 40 bytes.
Id 100:
        Aver depth:     2.33
        Max depth:      3
        Leaves:         6
        Prefixes:       6
        Internal nodes: 3
          2: 3
        Pointers: 12
Null ptrs: 4
Total size: 1  kB
[...]
When a routing table is very dense, a node can handle many bits. For
example, a densily populated routing table with 1 million entries
packed in a /12 can have one internal node handling 20 bits. In this
case, route lookup is essentially reduced to a lookup in a vector.
The following graph shows the number of internal nodes used relative
to the number of routes for different scenarios (routes extracted from
an Internet full view, /32 routes spreaded over 4 different subnets
with various densities). When routes are densily packed, the number of
internal nodes are quite limited.

Performance
So how performant is a route lookup? The maximum depth stays low
(about 6 for a full view), so a lookup should be quite fast. With the
help of a small kernel module, we can accurately benchmark5
the fib_lookup() function:
 The lookup time is loosely tied to the maximum depth. When the routing
table is densily populated, the maximum depth is low and the lookup
times are fast.
When forwarding at 10 Gbps, the time budget for a packet would be
about 50 ns. Since this is also the time needed for the route lookup
alone in some cases, we wouldn t be able to forward at line rate with
only one core. Nonetheless, the results are pretty good and they are
expected to scale linearly with the number of cores.
The measurements are done with a Linux kernel 4.11 from Debian
unstable. I have gathered performance metrics accross kernel versions
in Performance progression of IPv4 route lookup on Linux .
Another interesting figure is the time it takes to insert all those
routes into the kernel. Linux is also quite efficient in this area
since you can insert 2 million routes in less than 10 seconds:

Memory usage
The memory usage is available directly in
/proc/net/fib_triestat. The statistic provided doesn t account for
the fib_info structures, but you should only have a handful of them
(one for each possible next-hop). As you can see on the graph below,
the memory use is linear with the number of routes inserted, whatever
the shape of the routes is.
 The results are quite good. With only 256 MiB, about 2 million routes
can be stored!
Routing rules
Unless configured without CONFIG_IP_MULTIPLE_TABLES, Linux
supports several routing tables and has a system of configurable
rules to select the table to use. These rules can be configured with
ip rule. By default, there are three of them:
$ ip rule show
0:      from all lookup local
32766:  from all lookup main
32767:  from all lookup default
Linux will first lookup for a match in the local table. If it
doesn t find one, it will lookup in the main table and at last
resort, the default table.
Builtin tables
The local table contains routes for local delivery:
$ ip route show table local
broadcast 127.0.0.0 dev lo proto kernel scope link src 127.0.0.1
local 127.0.0.0/8 dev lo proto kernel scope host src 127.0.0.1
local 127.0.0.1 dev lo proto kernel scope host src 127.0.0.1
broadcast 127.255.255.255 dev lo proto kernel scope link src 127.0.0.1
broadcast 192.168.117.0 dev eno1 proto kernel scope link src 192.168.117.55
local 192.168.117.55 dev eno1 proto kernel scope host src 192.168.117.55
broadcast 192.168.117.63 dev eno1 proto kernel scope link src 192.168.117.55
This table is populated automatically by the kernel when addresses are
configured. Let s look at the three last lines. When the IP address
192.168.117.55 was configured on the eno1 interface, the kernel
automatically added the appropriate routes:
- a route for
192.168.117.55 for local unicast delivery to the IP address,
- a route for
192.168.117.255 for broadcast delivery to the broadcast address,
- a route for
192.168.117.0 for broadcast delivery to the network address.
When 127.0.0.1 was configured on the loopback interface, the same
kind of routes were added to the local table. However, a loopback
address receives a special treatment and the kernel also adds the
whole subnet to the local table. As a result, you can ping any IP in
127.0.0.0/8:
$ ping -c1 127.42.42.42
PING 127.42.42.42 (127.42.42.42) 56(84) bytes of data.
64 bytes from 127.42.42.42: icmp_seq=1 ttl=64 time=0.039 ms
--- 127.42.42.42 ping statistics ---
1 packets transmitted, 1 received, 0% packet loss, time 0ms
rtt min/avg/max/mdev = 0.039/0.039/0.039/0.000 ms
The main table usually contains all the other routes:
$ ip route show table main
default via 192.168.117.1 dev eno1 proto static metric 100
192.168.117.0/26 dev eno1 proto kernel scope link src 192.168.117.55 metric 100
The default route has been configured by some DHCP daemon. The
connected route (scope link) has been automatically added by the
kernel (proto kernel) when configuring an IP address on the eno1
interface.
The default table is empty and has little use. It has been kept when
the current incarnation of advanced routing has been introduced in
Linux 2.1.68 after a first tentative using classes in Linux 2.1.156.
Performance
Since Linux 4.1 (commit 0ddcf43d5d4a), when the set of rules is
left unmodified, the main and local tables are merged and the
lookup is done with this single table (and the default table if not
empty). Moreover, since Linux 3.0 (commit f4530fa574df), without
specific rules, there is no performance hit when enabling the support
for multiple routing tables. However, as soon as you add new rules,
some CPU cycles will be spent for each datagram to evaluate them. Here
is a couple of graphs demonstrating the impact of routing rules on
lookup times:
 For some reason, the relation is linear when the number of rules is
between 1 and 100 but the slope increases noticeably past this
threshold. The second graph highlights the negative impact of the
first rule (about 30 ns).
A common use of rules is to create virtual routers: interfaces
are segregated into domains and when a datagram enters through an
interface from domain A, it should use routing table A:
# ip rule add iif vlan457 table 10
# ip rule add iif vlan457 blackhole
# ip rule add iif vlan458 table 20
# ip rule add iif vlan458 blackhole
The blackhole rules may be removed if you are sure there is a default
route in each routing table. For example, we add a blackhole default
with a high metric to not override a regular default route:
# ip route add blackhole default metric 9999 table 10
# ip route add blackhole default metric 9999 table 20
# ip rule add iif vlan457 table 10
# ip rule add iif vlan458 table 20
To reduce the impact on performance when many interface-specific rules
are used, interfaces can be attached to VRF instances and a single
rule can be used to select the appropriate table:
# ip link add vrf-A type vrf table 10
# ip link set dev vrf-A up
# ip link add vrf-B type vrf table 20
# ip link set dev vrf-B up
# ip link set dev vlan457 master vrf-A
# ip link set dev vlan458 master vrf-B
# ip rule show
0:      from all lookup local
1000:   from all lookup [l3mdev-table]
32766:  from all lookup main
32767:  from all lookup default
The special l3mdev-table rule was automatically added when
configuring the first VRF interface. This rule will select the routing
table associated to the VRF owning the input (or output) interface.
VRF was introduced in Linux 4.3 (commit 193125dbd8eb), the
performance was greatly enhanced in Linux 4.8
(commit 7889681f4a6c) and the special routing rule was also
introduced in Linux 4.8
(commit 96c63fa7393d, commit 1aa6c4f6b8cd). You can find more
details about it in the kernel documentation.
Conclusion
The takeaways from this article are:
- route lookup times hardly increase with the number of routes,
- densily packed /32 routes lead to amazingly fast route lookups,
- memory use is low (128 MiB par million routes),
- no optimization is done on routing rules.
-
The routing cache was subject to reasonably easy to launch
denial of service attacks. It was also believed to not be
efficient for high volume sites like Google but I have first-hand
experience it was not the case for moderately high volume sites.
-
IP-address lookup using LC-tries , IEEE
Journal on Selected Areas in Communications, 17(6):1083-1092, June 1999.
-
For internal nodes, the
key_vector structure is embedded
into a tnode structure. This structure contains information
rarely used during lookup, notably the reference to the parent
that is usually not needed for backtracking as Linux keeps the
nearest candidate in a variable.
-
One leaf can contain several routes (
struct fib_alias is a
list). The number of prefixes can therefore be greater than the
number of leaves. The system also keeps statistics about the
distribution of the internal nodes relative to the number of bits
they handle. In our example, all the three internal nodes are
handling 2 bits.
-
The measurements are done in a virtual machine with one
vCPU. The host is an Intel Core i5-4670K running at 3.7 GHz
during the experiment (CPU governor was set to performance). The
benchmark is single-threaded. It runs a warm-up phase, then
executes about 100,000 timed iterations and keeps the
median. Timings of individual runs are computed from the TSC.
-
Fun fact: the documentation of this first tentative of
more flexible routing is still available in today s kernel tree
and explains
the usage of the default class .
$ ip route show scope global table 100 default via 203.0.113.5 dev out2 192.0.2.0/25 nexthop via 203.0.113.7 dev out3 weight 1 nexthop via 203.0.113.9 dev out4 weight 1 192.0.2.47 via 203.0.113.3 dev out1 192.0.2.48 via 203.0.113.3 dev out1 192.0.2.49 via 203.0.113.3 dev out1 192.0.2.50 via 203.0.113.3 dev out1
| Destination IP | Next hop |
|---|---|
192.0.2.49 |
203.0.113.3 via out1 |
192.0.2.50 |
203.0.113.3 via out1 |
192.0.2.51 |
203.0.113.7 via out3 or 203.0.113.9 via out4 (ECMP) |
192.0.2.200 |
203.0.113.5 via out2 |
For each node, the prefix is known by its path from the root node and
the prefix length is the current depth.
A lookup in such a trie is quite simple: at each step, fetch the
nth bit of the IP address, where n is the current
depth. If it is 0, continue with the first child. Otherwise, continue
with the second. If a child is missing, backtrack until a routing
entry is found. For example, when looking for 192.0.2.50, we will
find the result in the corresponding leaf (at depth 32). However for
192.0.2.51, we will reach 192.0.2.50/31 but there is no second
child. Therefore, we backtrack until the 192.0.2.0/25 routing entry.
Adding and removing routes is quite easy. From a performance point of
view, the lookup is done in constant time relative to the number of
routes (due to maximum depth being capped to 32).
Quagga is an example of routing software still using
this simple approach.
Lookup with a path-compressed trie
In the previous example, most nodes only have one child. This leads to
a lot of unneeded bitwise comparisons and memory is also wasted on
many nodes. To overcome this problem, we can use path compression:
each node with only one child is removed (except if it also contains a
routing entry). Each remaining node gets a new property telling how
many input bits should be skipped. Such a trie is also known as a
Patricia trie or a radix tree. Here is the path-compressed
version of the previous trie:
Since some bits have been ignored, on a match, a final check is
executed to ensure all bits from the found entry are matching the
input IP address. If not, we must act as if the entry wasn t found
(and backtrack to find a matching prefix). The following figure shows
two IP addresses matching the same leaf:
The reduction on the average depth of the tree compensates the
necessity to handle those false positives. The insertion and deletion
of a routing entry is still easy enough.
Many routing systems are using Patricia trees:
Lookup with a level-compressed trie
In addition to path compression, level compression2
detects parts of the trie that are densily populated and replace
them with a single node and an associated vector of 2k
children. This node will handle k input bits instead of just
one. For example, here is a level-compressed version our previous
trie:
Such a trie is called LC-trie or LPC-trie and offers higher lookup
performances compared to a radix tree.
An heuristic is used to decide how many bits a node should handle. On
Linux, if the ratio of non-empty children to all children would be
above 50% when the node handles an additional bit, the node gets this
additional bit. On the other hand, if the current ratio is below 25%,
the node loses the responsibility of one bit. Those values are not
tunable.
Insertion and deletion becomes more complex but lookup times are
also improved.
Implementation in Linux
The implementation for IPv4 in Linux exists since 2.6.13
(commit 19baf839ff4a) and is enabled by default since 2.6.39
(commit 3630b7c050d9).
Here is the representation of our example routing table in memory3:
There are several structures involved:
struct fib_table represents a routing table,struct trie represents a complete trie,struct key_vector represents either
an internal node (when bits is not zero) or a leaf,struct fib_info contains the characteristics
shared by several routes (like a next-hop gateway and an output
interface),struct fib_alias is the glue between the
leaves and the fib_info structures.
The trie can be retrieved through /proc/net/fib_trie:
$ cat /proc/net/fib_trie
Id 100:
+-- 0.0.0.0/0 2 0 2
-- 0.0.0.0
/0 universe UNICAST
+-- 192.0.2.0/26 2 0 1
-- 192.0.2.0
/25 universe UNICAST
-- 192.0.2.47
/32 universe UNICAST
+-- 192.0.2.48/30 2 0 1
-- 192.0.2.48
/32 universe UNICAST
-- 192.0.2.49
/32 universe UNICAST
-- 192.0.2.50
/32 universe UNICAST
[...]
For internal nodes, the numbers after the prefix are:
- the number of bits handled by the node,
- the number of full children (they only handle one bit),
- the number of empty children.
Moreover, if the kernel was compiled with CONFIG_IP_FIB_TRIE_STATS,
some interesting statistics are available in /proc/net/fib_triestat4:
$ cat /proc/net/fib_triestat
Basic info: size of leaf: 48 bytes, size of tnode: 40 bytes.
Id 100:
Aver depth: 2.33
Max depth: 3
Leaves: 6
Prefixes: 6
Internal nodes: 3
2: 3
Pointers: 12
Null ptrs: 4
Total size: 1 kB
[...]
When a routing table is very dense, a node can handle many bits. For
example, a densily populated routing table with 1 million entries
packed in a /12 can have one internal node handling 20 bits. In this
case, route lookup is essentially reduced to a lookup in a vector.
The following graph shows the number of internal nodes used relative
to the number of routes for different scenarios (routes extracted from
an Internet full view, /32 routes spreaded over 4 different subnets
with various densities). When routes are densily packed, the number of
internal nodes are quite limited.
Performance
So how performant is a route lookup? The maximum depth stays low
(about 6 for a full view), so a lookup should be quite fast. With the
help of a small kernel module, we can accurately benchmark5
the fib_lookup() function:
The lookup time is loosely tied to the maximum depth. When the routing
table is densily populated, the maximum depth is low and the lookup
times are fast.
When forwarding at 10 Gbps, the time budget for a packet would be
about 50 ns. Since this is also the time needed for the route lookup
alone in some cases, we wouldn t be able to forward at line rate with
only one core. Nonetheless, the results are pretty good and they are
expected to scale linearly with the number of cores.
The measurements are done with a Linux kernel 4.11 from Debian
unstable. I have gathered performance metrics accross kernel versions
in Performance progression of IPv4 route lookup on Linux .
Another interesting figure is the time it takes to insert all those
routes into the kernel. Linux is also quite efficient in this area
since you can insert 2 million routes in less than 10 seconds:
Memory usage
The memory usage is available directly in
/proc/net/fib_triestat. The statistic provided doesn t account for
the fib_info structures, but you should only have a handful of them
(one for each possible next-hop). As you can see on the graph below,
the memory use is linear with the number of routes inserted, whatever
the shape of the routes is.
The results are quite good. With only 256 MiB, about 2 million routes
can be stored!
Routing rules
Unless configured without CONFIG_IP_MULTIPLE_TABLES, Linux
supports several routing tables and has a system of configurable
rules to select the table to use. These rules can be configured with
ip rule. By default, there are three of them:
$ ip rule show
0: from all lookup local
32766: from all lookup main
32767: from all lookup default
Linux will first lookup for a match in the local table. If it
doesn t find one, it will lookup in the main table and at last
resort, the default table.
Builtin tables
The local table contains routes for local delivery:
$ ip route show table local
broadcast 127.0.0.0 dev lo proto kernel scope link src 127.0.0.1
local 127.0.0.0/8 dev lo proto kernel scope host src 127.0.0.1
local 127.0.0.1 dev lo proto kernel scope host src 127.0.0.1
broadcast 127.255.255.255 dev lo proto kernel scope link src 127.0.0.1
broadcast 192.168.117.0 dev eno1 proto kernel scope link src 192.168.117.55
local 192.168.117.55 dev eno1 proto kernel scope host src 192.168.117.55
broadcast 192.168.117.63 dev eno1 proto kernel scope link src 192.168.117.55
This table is populated automatically by the kernel when addresses are
configured. Let s look at the three last lines. When the IP address
192.168.117.55 was configured on the eno1 interface, the kernel
automatically added the appropriate routes:
- a route for
192.168.117.55 for local unicast delivery to the IP address,
- a route for
192.168.117.255 for broadcast delivery to the broadcast address,
- a route for
192.168.117.0 for broadcast delivery to the network address.
When 127.0.0.1 was configured on the loopback interface, the same
kind of routes were added to the local table. However, a loopback
address receives a special treatment and the kernel also adds the
whole subnet to the local table. As a result, you can ping any IP in
127.0.0.0/8:
$ ping -c1 127.42.42.42
PING 127.42.42.42 (127.42.42.42) 56(84) bytes of data.
64 bytes from 127.42.42.42: icmp_seq=1 ttl=64 time=0.039 ms
--- 127.42.42.42 ping statistics ---
1 packets transmitted, 1 received, 0% packet loss, time 0ms
rtt min/avg/max/mdev = 0.039/0.039/0.039/0.000 ms
The main table usually contains all the other routes:
$ ip route show table main
default via 192.168.117.1 dev eno1 proto static metric 100
192.168.117.0/26 dev eno1 proto kernel scope link src 192.168.117.55 metric 100
The default route has been configured by some DHCP daemon. The
connected route (scope link) has been automatically added by the
kernel (proto kernel) when configuring an IP address on the eno1
interface.
The default table is empty and has little use. It has been kept when
the current incarnation of advanced routing has been introduced in
Linux 2.1.68 after a first tentative using classes in Linux 2.1.156.
Performance
Since Linux 4.1 (commit 0ddcf43d5d4a), when the set of rules is
left unmodified, the main and local tables are merged and the
lookup is done with this single table (and the default table if not
empty). Moreover, since Linux 3.0 (commit f4530fa574df), without
specific rules, there is no performance hit when enabling the support
for multiple routing tables. However, as soon as you add new rules,
some CPU cycles will be spent for each datagram to evaluate them. Here
is a couple of graphs demonstrating the impact of routing rules on
lookup times:
For some reason, the relation is linear when the number of rules is
between 1 and 100 but the slope increases noticeably past this
threshold. The second graph highlights the negative impact of the
first rule (about 30 ns).
A common use of rules is to create virtual routers: interfaces
are segregated into domains and when a datagram enters through an
interface from domain A, it should use routing table A:
# ip rule add iif vlan457 table 10
# ip rule add iif vlan457 blackhole
# ip rule add iif vlan458 table 20
# ip rule add iif vlan458 blackhole
The blackhole rules may be removed if you are sure there is a default
route in each routing table. For example, we add a blackhole default
with a high metric to not override a regular default route:
# ip route add blackhole default metric 9999 table 10
# ip route add blackhole default metric 9999 table 20
# ip rule add iif vlan457 table 10
# ip rule add iif vlan458 table 20
To reduce the impact on performance when many interface-specific rules
are used, interfaces can be attached to VRF instances and a single
rule can be used to select the appropriate table:
# ip link add vrf-A type vrf table 10
# ip link set dev vrf-A up
# ip link add vrf-B type vrf table 20
# ip link set dev vrf-B up
# ip link set dev vlan457 master vrf-A
# ip link set dev vlan458 master vrf-B
# ip rule show
0: from all lookup local
1000: from all lookup [l3mdev-table]
32766: from all lookup main
32767: from all lookup default
The special l3mdev-table rule was automatically added when
configuring the first VRF interface. This rule will select the routing
table associated to the VRF owning the input (or output) interface.
VRF was introduced in Linux 4.3 (commit 193125dbd8eb), the
performance was greatly enhanced in Linux 4.8
(commit 7889681f4a6c) and the special routing rule was also
introduced in Linux 4.8
(commit 96c63fa7393d, commit 1aa6c4f6b8cd). You can find more
details about it in the kernel documentation.
Conclusion
The takeaways from this article are:
- route lookup times hardly increase with the number of routes,
- densily packed /32 routes lead to amazingly fast route lookups,
- memory use is low (128 MiB par million routes),
- no optimization is done on routing rules.
-
The routing cache was subject to reasonably easy to launch
denial of service attacks. It was also believed to not be
efficient for high volume sites like Google but I have first-hand
experience it was not the case for moderately high volume sites.
-
IP-address lookup using LC-tries , IEEE
Journal on Selected Areas in Communications, 17(6):1083-1092, June 1999.
-
For internal nodes, the
key_vector structure is embedded
into a tnode structure. This structure contains information
rarely used during lookup, notably the reference to the parent
that is usually not needed for backtracking as Linux keeps the
nearest candidate in a variable.
-
One leaf can contain several routes (
struct fib_alias is a
list). The number of prefixes can therefore be greater than the
number of leaves. The system also keeps statistics about the
distribution of the internal nodes relative to the number of bits
they handle. In our example, all the three internal nodes are
handling 2 bits.
-
The measurements are done in a virtual machine with one
vCPU. The host is an Intel Core i5-4670K running at 3.7 GHz
during the experiment (CPU governor was set to performance). The
benchmark is single-threaded. It runs a warm-up phase, then
executes about 100,000 timed iterations and keeps the
median. Timings of individual runs are computed from the TSC.
-
Fun fact: the documentation of this first tentative of
more flexible routing is still available in today s kernel tree
and explains
the usage of the default class .
Such a trie is called LC-trie or LPC-trie and offers higher lookup
performances compared to a radix tree.
An heuristic is used to decide how many bits a node should handle. On
Linux, if the ratio of non-empty children to all children would be
above 50% when the node handles an additional bit, the node gets this
additional bit. On the other hand, if the current ratio is below 25%,
the node loses the responsibility of one bit. Those values are not
tunable.
Insertion and deletion becomes more complex but lookup times are
also improved.
Implementation in Linux
The implementation for IPv4 in Linux exists since 2.6.13
(commit 19baf839ff4a) and is enabled by default since 2.6.39
(commit 3630b7c050d9).
Here is the representation of our example routing table in memory3:
There are several structures involved:
struct fib_table represents a routing table,struct trie represents a complete trie,struct key_vector represents either
an internal node (when bits is not zero) or a leaf,struct fib_info contains the characteristics
shared by several routes (like a next-hop gateway and an output
interface),struct fib_alias is the glue between the
leaves and the fib_info structures.
The trie can be retrieved through /proc/net/fib_trie:
$ cat /proc/net/fib_trie
Id 100:
+-- 0.0.0.0/0 2 0 2
-- 0.0.0.0
/0 universe UNICAST
+-- 192.0.2.0/26 2 0 1
-- 192.0.2.0
/25 universe UNICAST
-- 192.0.2.47
/32 universe UNICAST
+-- 192.0.2.48/30 2 0 1
-- 192.0.2.48
/32 universe UNICAST
-- 192.0.2.49
/32 universe UNICAST
-- 192.0.2.50
/32 universe UNICAST
[...]
For internal nodes, the numbers after the prefix are:
- the number of bits handled by the node,
- the number of full children (they only handle one bit),
- the number of empty children.
Moreover, if the kernel was compiled with CONFIG_IP_FIB_TRIE_STATS,
some interesting statistics are available in /proc/net/fib_triestat4:
$ cat /proc/net/fib_triestat
Basic info: size of leaf: 48 bytes, size of tnode: 40 bytes.
Id 100:
Aver depth: 2.33
Max depth: 3
Leaves: 6
Prefixes: 6
Internal nodes: 3
2: 3
Pointers: 12
Null ptrs: 4
Total size: 1 kB
[...]
When a routing table is very dense, a node can handle many bits. For
example, a densily populated routing table with 1 million entries
packed in a /12 can have one internal node handling 20 bits. In this
case, route lookup is essentially reduced to a lookup in a vector.
The following graph shows the number of internal nodes used relative
to the number of routes for different scenarios (routes extracted from
an Internet full view, /32 routes spreaded over 4 different subnets
with various densities). When routes are densily packed, the number of
internal nodes are quite limited.
Performance
So how performant is a route lookup? The maximum depth stays low
(about 6 for a full view), so a lookup should be quite fast. With the
help of a small kernel module, we can accurately benchmark5
the fib_lookup() function:
The lookup time is loosely tied to the maximum depth. When the routing
table is densily populated, the maximum depth is low and the lookup
times are fast.
When forwarding at 10 Gbps, the time budget for a packet would be
about 50 ns. Since this is also the time needed for the route lookup
alone in some cases, we wouldn t be able to forward at line rate with
only one core. Nonetheless, the results are pretty good and they are
expected to scale linearly with the number of cores.
The measurements are done with a Linux kernel 4.11 from Debian
unstable. I have gathered performance metrics accross kernel versions
in Performance progression of IPv4 route lookup on Linux .
Another interesting figure is the time it takes to insert all those
routes into the kernel. Linux is also quite efficient in this area
since you can insert 2 million routes in less than 10 seconds:
Memory usage
The memory usage is available directly in
/proc/net/fib_triestat. The statistic provided doesn t account for
the fib_info structures, but you should only have a handful of them
(one for each possible next-hop). As you can see on the graph below,
the memory use is linear with the number of routes inserted, whatever
the shape of the routes is.
The results are quite good. With only 256 MiB, about 2 million routes
can be stored!
Routing rules
Unless configured without CONFIG_IP_MULTIPLE_TABLES, Linux
supports several routing tables and has a system of configurable
rules to select the table to use. These rules can be configured with
ip rule. By default, there are three of them:
$ ip rule show
0: from all lookup local
32766: from all lookup main
32767: from all lookup default
Linux will first lookup for a match in the local table. If it
doesn t find one, it will lookup in the main table and at last
resort, the default table.
Builtin tables
The local table contains routes for local delivery:
$ ip route show table local
broadcast 127.0.0.0 dev lo proto kernel scope link src 127.0.0.1
local 127.0.0.0/8 dev lo proto kernel scope host src 127.0.0.1
local 127.0.0.1 dev lo proto kernel scope host src 127.0.0.1
broadcast 127.255.255.255 dev lo proto kernel scope link src 127.0.0.1
broadcast 192.168.117.0 dev eno1 proto kernel scope link src 192.168.117.55
local 192.168.117.55 dev eno1 proto kernel scope host src 192.168.117.55
broadcast 192.168.117.63 dev eno1 proto kernel scope link src 192.168.117.55
This table is populated automatically by the kernel when addresses are
configured. Let s look at the three last lines. When the IP address
192.168.117.55 was configured on the eno1 interface, the kernel
automatically added the appropriate routes:
- a route for
192.168.117.55 for local unicast delivery to the IP address,
- a route for
192.168.117.255 for broadcast delivery to the broadcast address,
- a route for
192.168.117.0 for broadcast delivery to the network address.
When 127.0.0.1 was configured on the loopback interface, the same
kind of routes were added to the local table. However, a loopback
address receives a special treatment and the kernel also adds the
whole subnet to the local table. As a result, you can ping any IP in
127.0.0.0/8:
$ ping -c1 127.42.42.42
PING 127.42.42.42 (127.42.42.42) 56(84) bytes of data.
64 bytes from 127.42.42.42: icmp_seq=1 ttl=64 time=0.039 ms
--- 127.42.42.42 ping statistics ---
1 packets transmitted, 1 received, 0% packet loss, time 0ms
rtt min/avg/max/mdev = 0.039/0.039/0.039/0.000 ms
The main table usually contains all the other routes:
$ ip route show table main
default via 192.168.117.1 dev eno1 proto static metric 100
192.168.117.0/26 dev eno1 proto kernel scope link src 192.168.117.55 metric 100
The default route has been configured by some DHCP daemon. The
connected route (scope link) has been automatically added by the
kernel (proto kernel) when configuring an IP address on the eno1
interface.
The default table is empty and has little use. It has been kept when
the current incarnation of advanced routing has been introduced in
Linux 2.1.68 after a first tentative using classes in Linux 2.1.156.
Performance
Since Linux 4.1 (commit 0ddcf43d5d4a), when the set of rules is
left unmodified, the main and local tables are merged and the
lookup is done with this single table (and the default table if not
empty). Moreover, since Linux 3.0 (commit f4530fa574df), without
specific rules, there is no performance hit when enabling the support
for multiple routing tables. However, as soon as you add new rules,
some CPU cycles will be spent for each datagram to evaluate them. Here
is a couple of graphs demonstrating the impact of routing rules on
lookup times:
For some reason, the relation is linear when the number of rules is
between 1 and 100 but the slope increases noticeably past this
threshold. The second graph highlights the negative impact of the
first rule (about 30 ns).
A common use of rules is to create virtual routers: interfaces
are segregated into domains and when a datagram enters through an
interface from domain A, it should use routing table A:
# ip rule add iif vlan457 table 10
# ip rule add iif vlan457 blackhole
# ip rule add iif vlan458 table 20
# ip rule add iif vlan458 blackhole
The blackhole rules may be removed if you are sure there is a default
route in each routing table. For example, we add a blackhole default
with a high metric to not override a regular default route:
# ip route add blackhole default metric 9999 table 10
# ip route add blackhole default metric 9999 table 20
# ip rule add iif vlan457 table 10
# ip rule add iif vlan458 table 20
To reduce the impact on performance when many interface-specific rules
are used, interfaces can be attached to VRF instances and a single
rule can be used to select the appropriate table:
# ip link add vrf-A type vrf table 10
# ip link set dev vrf-A up
# ip link add vrf-B type vrf table 20
# ip link set dev vrf-B up
# ip link set dev vlan457 master vrf-A
# ip link set dev vlan458 master vrf-B
# ip rule show
0: from all lookup local
1000: from all lookup [l3mdev-table]
32766: from all lookup main
32767: from all lookup default
The special l3mdev-table rule was automatically added when
configuring the first VRF interface. This rule will select the routing
table associated to the VRF owning the input (or output) interface.
VRF was introduced in Linux 4.3 (commit 193125dbd8eb), the
performance was greatly enhanced in Linux 4.8
(commit 7889681f4a6c) and the special routing rule was also
introduced in Linux 4.8
(commit 96c63fa7393d, commit 1aa6c4f6b8cd). You can find more
details about it in the kernel documentation.
Conclusion
The takeaways from this article are:
- route lookup times hardly increase with the number of routes,
- densily packed /32 routes lead to amazingly fast route lookups,
- memory use is low (128 MiB par million routes),
- no optimization is done on routing rules.
-
The routing cache was subject to reasonably easy to launch
denial of service attacks. It was also believed to not be
efficient for high volume sites like Google but I have first-hand
experience it was not the case for moderately high volume sites.
-
IP-address lookup using LC-tries , IEEE
Journal on Selected Areas in Communications, 17(6):1083-1092, June 1999.
-
For internal nodes, the
key_vector structure is embedded
into a tnode structure. This structure contains information
rarely used during lookup, notably the reference to the parent
that is usually not needed for backtracking as Linux keeps the
nearest candidate in a variable.
-
One leaf can contain several routes (
struct fib_alias is a
list). The number of prefixes can therefore be greater than the
number of leaves. The system also keeps statistics about the
distribution of the internal nodes relative to the number of bits
they handle. In our example, all the three internal nodes are
handling 2 bits.
-
The measurements are done in a virtual machine with one
vCPU. The host is an Intel Core i5-4670K running at 3.7 GHz
during the experiment (CPU governor was set to performance). The
benchmark is single-threaded. It runs a warm-up phase, then
executes about 100,000 timed iterations and keeps the
median. Timings of individual runs are computed from the TSC.
-
Fun fact: the documentation of this first tentative of
more flexible routing is still available in today s kernel tree
and explains
the usage of the default class .
struct fib_table represents a routing table,struct trie represents a complete trie,struct key_vector represents either
an internal node (when bits is not zero) or a leaf,struct fib_info contains the characteristics
shared by several routes (like a next-hop gateway and an output
interface),struct fib_alias is the glue between the
leaves and the fib_info structures.$ cat /proc/net/fib_trie Id 100: +-- 0.0.0.0/0 2 0 2 -- 0.0.0.0 /0 universe UNICAST +-- 192.0.2.0/26 2 0 1 -- 192.0.2.0 /25 universe UNICAST -- 192.0.2.47 /32 universe UNICAST +-- 192.0.2.48/30 2 0 1 -- 192.0.2.48 /32 universe UNICAST -- 192.0.2.49 /32 universe UNICAST -- 192.0.2.50 /32 universe UNICAST [...]
$ cat /proc/net/fib_triestat Basic info: size of leaf: 48 bytes, size of tnode: 40 bytes. Id 100: Aver depth: 2.33 Max depth: 3 Leaves: 6 Prefixes: 6 Internal nodes: 3 2: 3 Pointers: 12 Null ptrs: 4 Total size: 1 kB [...]
fib_lookup() function:
The lookup time is loosely tied to the maximum depth. When the routing
table is densily populated, the maximum depth is low and the lookup
times are fast.
When forwarding at 10 Gbps, the time budget for a packet would be
about 50 ns. Since this is also the time needed for the route lookup
alone in some cases, we wouldn t be able to forward at line rate with
only one core. Nonetheless, the results are pretty good and they are
expected to scale linearly with the number of cores.
The measurements are done with a Linux kernel 4.11 from Debian
unstable. I have gathered performance metrics accross kernel versions
in Performance progression of IPv4 route lookup on Linux .
Another interesting figure is the time it takes to insert all those
routes into the kernel. Linux is also quite efficient in this area
since you can insert 2 million routes in less than 10 seconds:
Memory usage
The memory usage is available directly in
/proc/net/fib_triestat. The statistic provided doesn t account for
the fib_info structures, but you should only have a handful of them
(one for each possible next-hop). As you can see on the graph below,
the memory use is linear with the number of routes inserted, whatever
the shape of the routes is.
The results are quite good. With only 256 MiB, about 2 million routes
can be stored!
Routing rules
Unless configured without CONFIG_IP_MULTIPLE_TABLES, Linux
supports several routing tables and has a system of configurable
rules to select the table to use. These rules can be configured with
ip rule. By default, there are three of them:
$ ip rule show
0: from all lookup local
32766: from all lookup main
32767: from all lookup default
Linux will first lookup for a match in the local table. If it
doesn t find one, it will lookup in the main table and at last
resort, the default table.
Builtin tables
The local table contains routes for local delivery:
$ ip route show table local
broadcast 127.0.0.0 dev lo proto kernel scope link src 127.0.0.1
local 127.0.0.0/8 dev lo proto kernel scope host src 127.0.0.1
local 127.0.0.1 dev lo proto kernel scope host src 127.0.0.1
broadcast 127.255.255.255 dev lo proto kernel scope link src 127.0.0.1
broadcast 192.168.117.0 dev eno1 proto kernel scope link src 192.168.117.55
local 192.168.117.55 dev eno1 proto kernel scope host src 192.168.117.55
broadcast 192.168.117.63 dev eno1 proto kernel scope link src 192.168.117.55
This table is populated automatically by the kernel when addresses are
configured. Let s look at the three last lines. When the IP address
192.168.117.55 was configured on the eno1 interface, the kernel
automatically added the appropriate routes:
- a route for
192.168.117.55 for local unicast delivery to the IP address,
- a route for
192.168.117.255 for broadcast delivery to the broadcast address,
- a route for
192.168.117.0 for broadcast delivery to the network address.
When 127.0.0.1 was configured on the loopback interface, the same
kind of routes were added to the local table. However, a loopback
address receives a special treatment and the kernel also adds the
whole subnet to the local table. As a result, you can ping any IP in
127.0.0.0/8:
$ ping -c1 127.42.42.42
PING 127.42.42.42 (127.42.42.42) 56(84) bytes of data.
64 bytes from 127.42.42.42: icmp_seq=1 ttl=64 time=0.039 ms
--- 127.42.42.42 ping statistics ---
1 packets transmitted, 1 received, 0% packet loss, time 0ms
rtt min/avg/max/mdev = 0.039/0.039/0.039/0.000 ms
The main table usually contains all the other routes:
$ ip route show table main
default via 192.168.117.1 dev eno1 proto static metric 100
192.168.117.0/26 dev eno1 proto kernel scope link src 192.168.117.55 metric 100
The default route has been configured by some DHCP daemon. The
connected route (scope link) has been automatically added by the
kernel (proto kernel) when configuring an IP address on the eno1
interface.
The default table is empty and has little use. It has been kept when
the current incarnation of advanced routing has been introduced in
Linux 2.1.68 after a first tentative using classes in Linux 2.1.156.
Performance
Since Linux 4.1 (commit 0ddcf43d5d4a), when the set of rules is
left unmodified, the main and local tables are merged and the
lookup is done with this single table (and the default table if not
empty). Moreover, since Linux 3.0 (commit f4530fa574df), without
specific rules, there is no performance hit when enabling the support
for multiple routing tables. However, as soon as you add new rules,
some CPU cycles will be spent for each datagram to evaluate them. Here
is a couple of graphs demonstrating the impact of routing rules on
lookup times:
For some reason, the relation is linear when the number of rules is
between 1 and 100 but the slope increases noticeably past this
threshold. The second graph highlights the negative impact of the
first rule (about 30 ns).
A common use of rules is to create virtual routers: interfaces
are segregated into domains and when a datagram enters through an
interface from domain A, it should use routing table A:
# ip rule add iif vlan457 table 10
# ip rule add iif vlan457 blackhole
# ip rule add iif vlan458 table 20
# ip rule add iif vlan458 blackhole
The blackhole rules may be removed if you are sure there is a default
route in each routing table. For example, we add a blackhole default
with a high metric to not override a regular default route:
# ip route add blackhole default metric 9999 table 10
# ip route add blackhole default metric 9999 table 20
# ip rule add iif vlan457 table 10
# ip rule add iif vlan458 table 20
To reduce the impact on performance when many interface-specific rules
are used, interfaces can be attached to VRF instances and a single
rule can be used to select the appropriate table:
# ip link add vrf-A type vrf table 10
# ip link set dev vrf-A up
# ip link add vrf-B type vrf table 20
# ip link set dev vrf-B up
# ip link set dev vlan457 master vrf-A
# ip link set dev vlan458 master vrf-B
# ip rule show
0: from all lookup local
1000: from all lookup [l3mdev-table]
32766: from all lookup main
32767: from all lookup default
The special l3mdev-table rule was automatically added when
configuring the first VRF interface. This rule will select the routing
table associated to the VRF owning the input (or output) interface.
VRF was introduced in Linux 4.3 (commit 193125dbd8eb), the
performance was greatly enhanced in Linux 4.8
(commit 7889681f4a6c) and the special routing rule was also
introduced in Linux 4.8
(commit 96c63fa7393d, commit 1aa6c4f6b8cd). You can find more
details about it in the kernel documentation.
Conclusion
The takeaways from this article are:
- route lookup times hardly increase with the number of routes,
- densily packed /32 routes lead to amazingly fast route lookups,
- memory use is low (128 MiB par million routes),
- no optimization is done on routing rules.
-
The routing cache was subject to reasonably easy to launch
denial of service attacks. It was also believed to not be
efficient for high volume sites like Google but I have first-hand
experience it was not the case for moderately high volume sites.
-
IP-address lookup using LC-tries , IEEE
Journal on Selected Areas in Communications, 17(6):1083-1092, June 1999.
-
For internal nodes, the
key_vector structure is embedded
into a tnode structure. This structure contains information
rarely used during lookup, notably the reference to the parent
that is usually not needed for backtracking as Linux keeps the
nearest candidate in a variable.
-
One leaf can contain several routes (
struct fib_alias is a
list). The number of prefixes can therefore be greater than the
number of leaves. The system also keeps statistics about the
distribution of the internal nodes relative to the number of bits
they handle. In our example, all the three internal nodes are
handling 2 bits.
-
The measurements are done in a virtual machine with one
vCPU. The host is an Intel Core i5-4670K running at 3.7 GHz
during the experiment (CPU governor was set to performance). The
benchmark is single-threaded. It runs a warm-up phase, then
executes about 100,000 timed iterations and keeps the
median. Timings of individual runs are computed from the TSC.
-
Fun fact: the documentation of this first tentative of
more flexible routing is still available in today s kernel tree
and explains
the usage of the default class .
CONFIG_IP_MULTIPLE_TABLES, Linux
supports several routing tables and has a system of configurable
rules to select the table to use. These rules can be configured with
ip rule. By default, there are three of them:
$ ip rule show 0: from all lookup local 32766: from all lookup main 32767: from all lookup default
local table. If it
doesn t find one, it will lookup in the main table and at last
resort, the default table.
Builtin tables
The local table contains routes for local delivery:
$ ip route show table local
broadcast 127.0.0.0 dev lo proto kernel scope link src 127.0.0.1
local 127.0.0.0/8 dev lo proto kernel scope host src 127.0.0.1
local 127.0.0.1 dev lo proto kernel scope host src 127.0.0.1
broadcast 127.255.255.255 dev lo proto kernel scope link src 127.0.0.1
broadcast 192.168.117.0 dev eno1 proto kernel scope link src 192.168.117.55
local 192.168.117.55 dev eno1 proto kernel scope host src 192.168.117.55
broadcast 192.168.117.63 dev eno1 proto kernel scope link src 192.168.117.55
This table is populated automatically by the kernel when addresses are
configured. Let s look at the three last lines. When the IP address
192.168.117.55 was configured on the eno1 interface, the kernel
automatically added the appropriate routes:
- a route for
192.168.117.55 for local unicast delivery to the IP address,
- a route for
192.168.117.255 for broadcast delivery to the broadcast address,
- a route for
192.168.117.0 for broadcast delivery to the network address.
When 127.0.0.1 was configured on the loopback interface, the same
kind of routes were added to the local table. However, a loopback
address receives a special treatment and the kernel also adds the
whole subnet to the local table. As a result, you can ping any IP in
127.0.0.0/8:
$ ping -c1 127.42.42.42
PING 127.42.42.42 (127.42.42.42) 56(84) bytes of data.
64 bytes from 127.42.42.42: icmp_seq=1 ttl=64 time=0.039 ms
--- 127.42.42.42 ping statistics ---
1 packets transmitted, 1 received, 0% packet loss, time 0ms
rtt min/avg/max/mdev = 0.039/0.039/0.039/0.000 ms
The main table usually contains all the other routes:
$ ip route show table main
default via 192.168.117.1 dev eno1 proto static metric 100
192.168.117.0/26 dev eno1 proto kernel scope link src 192.168.117.55 metric 100
The default route has been configured by some DHCP daemon. The
connected route (scope link) has been automatically added by the
kernel (proto kernel) when configuring an IP address on the eno1
interface.
The default table is empty and has little use. It has been kept when
the current incarnation of advanced routing has been introduced in
Linux 2.1.68 after a first tentative using classes in Linux 2.1.156.
Performance
Since Linux 4.1 (commit 0ddcf43d5d4a), when the set of rules is
left unmodified, the main and local tables are merged and the
lookup is done with this single table (and the default table if not
empty). Moreover, since Linux 3.0 (commit f4530fa574df), without
specific rules, there is no performance hit when enabling the support
for multiple routing tables. However, as soon as you add new rules,
some CPU cycles will be spent for each datagram to evaluate them. Here
is a couple of graphs demonstrating the impact of routing rules on
lookup times:
For some reason, the relation is linear when the number of rules is
between 1 and 100 but the slope increases noticeably past this
threshold. The second graph highlights the negative impact of the
first rule (about 30 ns).
A common use of rules is to create virtual routers: interfaces
are segregated into domains and when a datagram enters through an
interface from domain A, it should use routing table A:
# ip rule add iif vlan457 table 10
# ip rule add iif vlan457 blackhole
# ip rule add iif vlan458 table 20
# ip rule add iif vlan458 blackhole
The blackhole rules may be removed if you are sure there is a default
route in each routing table. For example, we add a blackhole default
with a high metric to not override a regular default route:
# ip route add blackhole default metric 9999 table 10
# ip route add blackhole default metric 9999 table 20
# ip rule add iif vlan457 table 10
# ip rule add iif vlan458 table 20
To reduce the impact on performance when many interface-specific rules
are used, interfaces can be attached to VRF instances and a single
rule can be used to select the appropriate table:
# ip link add vrf-A type vrf table 10
# ip link set dev vrf-A up
# ip link add vrf-B type vrf table 20
# ip link set dev vrf-B up
# ip link set dev vlan457 master vrf-A
# ip link set dev vlan458 master vrf-B
# ip rule show
0: from all lookup local
1000: from all lookup [l3mdev-table]
32766: from all lookup main
32767: from all lookup default
The special l3mdev-table rule was automatically added when
configuring the first VRF interface. This rule will select the routing
table associated to the VRF owning the input (or output) interface.
VRF was introduced in Linux 4.3 (commit 193125dbd8eb), the
performance was greatly enhanced in Linux 4.8
(commit 7889681f4a6c) and the special routing rule was also
introduced in Linux 4.8
(commit 96c63fa7393d, commit 1aa6c4f6b8cd). You can find more
details about it in the kernel documentation.
Conclusion
The takeaways from this article are:
- route lookup times hardly increase with the number of routes,
- densily packed /32 routes lead to amazingly fast route lookups,
- memory use is low (128 MiB par million routes),
- no optimization is done on routing rules.
-
The routing cache was subject to reasonably easy to launch
denial of service attacks. It was also believed to not be
efficient for high volume sites like Google but I have first-hand
experience it was not the case for moderately high volume sites.
-
IP-address lookup using LC-tries , IEEE
Journal on Selected Areas in Communications, 17(6):1083-1092, June 1999.
-
For internal nodes, the
key_vector structure is embedded
into a tnode structure. This structure contains information
rarely used during lookup, notably the reference to the parent
that is usually not needed for backtracking as Linux keeps the
nearest candidate in a variable.
-
One leaf can contain several routes (
struct fib_alias is a
list). The number of prefixes can therefore be greater than the
number of leaves. The system also keeps statistics about the
distribution of the internal nodes relative to the number of bits
they handle. In our example, all the three internal nodes are
handling 2 bits.
-
The measurements are done in a virtual machine with one
vCPU. The host is an Intel Core i5-4670K running at 3.7 GHz
during the experiment (CPU governor was set to performance). The
benchmark is single-threaded. It runs a warm-up phase, then
executes about 100,000 timed iterations and keeps the
median. Timings of individual runs are computed from the TSC.
-
Fun fact: the documentation of this first tentative of
more flexible routing is still available in today s kernel tree
and explains
the usage of the default class .
$ ip route show table local broadcast 127.0.0.0 dev lo proto kernel scope link src 127.0.0.1 local 127.0.0.0/8 dev lo proto kernel scope host src 127.0.0.1 local 127.0.0.1 dev lo proto kernel scope host src 127.0.0.1 broadcast 127.255.255.255 dev lo proto kernel scope link src 127.0.0.1 broadcast 192.168.117.0 dev eno1 proto kernel scope link src 192.168.117.55 local 192.168.117.55 dev eno1 proto kernel scope host src 192.168.117.55 broadcast 192.168.117.63 dev eno1 proto kernel scope link src 192.168.117.55
192.168.117.55 for local unicast delivery to the IP address,192.168.117.255 for broadcast delivery to the broadcast address,192.168.117.0 for broadcast delivery to the network address.$ ping -c1 127.42.42.42 PING 127.42.42.42 (127.42.42.42) 56(84) bytes of data. 64 bytes from 127.42.42.42: icmp_seq=1 ttl=64 time=0.039 ms --- 127.42.42.42 ping statistics --- 1 packets transmitted, 1 received, 0% packet loss, time 0ms rtt min/avg/max/mdev = 0.039/0.039/0.039/0.000 ms
$ ip route show table main default via 192.168.117.1 dev eno1 proto static metric 100 192.168.117.0/26 dev eno1 proto kernel scope link src 192.168.117.55 metric 100
main and local tables are merged and the
lookup is done with this single table (and the default table if not
empty). Moreover, since Linux 3.0 (commit f4530fa574df), without
specific rules, there is no performance hit when enabling the support
for multiple routing tables. However, as soon as you add new rules,
some CPU cycles will be spent for each datagram to evaluate them. Here
is a couple of graphs demonstrating the impact of routing rules on
lookup times:
For some reason, the relation is linear when the number of rules is
between 1 and 100 but the slope increases noticeably past this
threshold. The second graph highlights the negative impact of the
first rule (about 30 ns).
A common use of rules is to create virtual routers: interfaces
are segregated into domains and when a datagram enters through an
interface from domain A, it should use routing table A:
# ip rule add iif vlan457 table 10 # ip rule add iif vlan457 blackhole # ip rule add iif vlan458 table 20 # ip rule add iif vlan458 blackhole
# ip route add blackhole default metric 9999 table 10 # ip route add blackhole default metric 9999 table 20 # ip rule add iif vlan457 table 10 # ip rule add iif vlan458 table 20
# ip link add vrf-A type vrf table 10 # ip link set dev vrf-A up # ip link add vrf-B type vrf table 20 # ip link set dev vrf-B up # ip link set dev vlan457 master vrf-A # ip link set dev vlan458 master vrf-B # ip rule show 0: from all lookup local 1000: from all lookup [l3mdev-table] 32766: from all lookup main 32767: from all lookup default
l3mdev-table rule was automatically added when
configuring the first VRF interface. This rule will select the routing
table associated to the VRF owning the input (or output) interface.
VRF was introduced in Linux 4.3 (commit 193125dbd8eb), the
performance was greatly enhanced in Linux 4.8
(commit 7889681f4a6c) and the special routing rule was also
introduced in Linux 4.8
(commit 96c63fa7393d, commit 1aa6c4f6b8cd). You can find more
details about it in the kernel documentation.
Conclusion
The takeaways from this article are:
- route lookup times hardly increase with the number of routes,
- densily packed /32 routes lead to amazingly fast route lookups,
- memory use is low (128 MiB par million routes),
- no optimization is done on routing rules.
-
The routing cache was subject to reasonably easy to launch
denial of service attacks. It was also believed to not be
efficient for high volume sites like Google but I have first-hand
experience it was not the case for moderately high volume sites.
-
IP-address lookup using LC-tries , IEEE
Journal on Selected Areas in Communications, 17(6):1083-1092, June 1999.
-
For internal nodes, the
key_vector structure is embedded
into a tnode structure. This structure contains information
rarely used during lookup, notably the reference to the parent
that is usually not needed for backtracking as Linux keeps the
nearest candidate in a variable.
-
One leaf can contain several routes (
struct fib_alias is a
list). The number of prefixes can therefore be greater than the
number of leaves. The system also keeps statistics about the
distribution of the internal nodes relative to the number of bits
they handle. In our example, all the three internal nodes are
handling 2 bits.
-
The measurements are done in a virtual machine with one
vCPU. The host is an Intel Core i5-4670K running at 3.7 GHz
during the experiment (CPU governor was set to performance). The
benchmark is single-threaded. It runs a warm-up phase, then
executes about 100,000 timed iterations and keeps the
median. Timings of individual runs are computed from the TSC.
-
Fun fact: the documentation of this first tentative of
more flexible routing is still available in today s kernel tree
and explains
the usage of the default class .
- The routing cache was subject to reasonably easy to launch denial of service attacks. It was also believed to not be efficient for high volume sites like Google but I have first-hand experience it was not the case for moderately high volume sites.
- IP-address lookup using LC-tries , IEEE Journal on Selected Areas in Communications, 17(6):1083-1092, June 1999.
-
For internal nodes, the
key_vectorstructure is embedded into atnodestructure. This structure contains information rarely used during lookup, notably the reference to the parent that is usually not needed for backtracking as Linux keeps the nearest candidate in a variable. -
One leaf can contain several routes (
struct fib_aliasis a list). The number of prefixes can therefore be greater than the number of leaves. The system also keeps statistics about the distribution of the internal nodes relative to the number of bits they handle. In our example, all the three internal nodes are handling 2 bits. - The measurements are done in a virtual machine with one vCPU. The host is an Intel Core i5-4670K running at 3.7 GHz during the experiment (CPU governor was set to performance). The benchmark is single-threaded. It runs a warm-up phase, then executes about 100,000 timed iterations and keeps the median. Timings of individual runs are computed from the TSC.
- Fun fact: the documentation of this first tentative of more flexible routing is still available in today s kernel tree and explains the usage of the default class .
 Things mostly went very well, and we've released Debian 9 this
weekend past. Many many people worked together to
make this possible, and I'd like to extend my own thanks to all of
them.
As a project, we decided to dedicate Stretch to our late founder
Ian Murdock. He did much of the early work to get Debian going, and
inspired many more to help him. I had the good fortune to meet up with
Ian years ago at a meetup attached to a Usenix conference, and I
remember clearly he was a genuinely nice guy with good ideas. We'll
miss him.
For my part in the release process, again I was responsible for
producing our official installation and live images. Release day
itself went OK, but as is typical the process ran late into Saturday
night / early Sunday morning. We made and tested lots
of different images, although numbers were down from previous releases
as we've stopped making the full CD sets now.
Sunday was the day for the release party in Cambridge. As is
traditional, a group of us met up at a local hostelry for some
revelry! We hid inside the pub to escape from the ridiculouly hot
weather we're having at the moment.
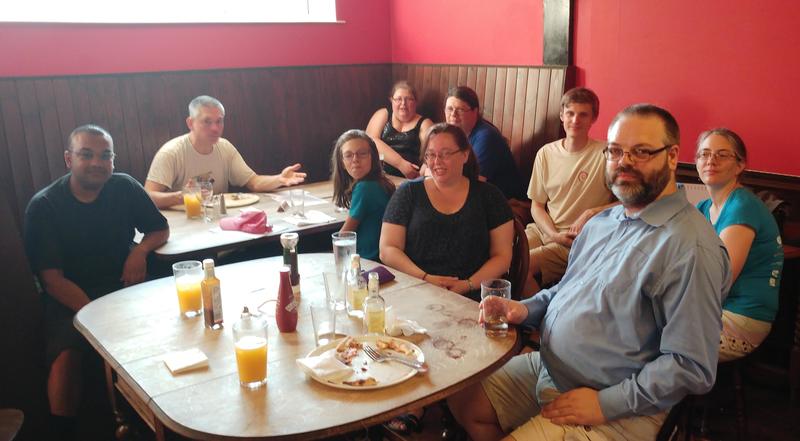 Due to a combination of the lack of sleep and the heat, I nearly
forgot to even take any photos - apologies to the extra folks who'd
been around earlier whom I missed with the camera... :-(

 Yesterday I uploaded the first packages of
 I mentioned already in a
 Dear all, an
 While the above medical device is similar, mine had a cross, the needle was much shorter and is injected into the vein. After that all injections are injected into that including common liquid which is salt,water and something commonly given to patients to stabilize first. I am not remembering the name atm.
I also had a urine bag which was attached to my penis in a non-invasive manner. Both my grandfather and grandma used to cry when things went wrong while I didn t feel any pain but when the urine bag was disattached and attached again, so seems things have improved there.
I was also very conscious of getting bed sores as both my grandpa and grandma had them when in hospital. As I had no strength I had to beg. plead do everything to make sure that every few hours I was turned from one side to other. I also had an air bag which is supposed to alleviate or relief this condition.
Constant physiotherapy every day for a while slowly increased my strength and slowly both the vigo and feeding tube put inside my throat was removed.
I have no remembrance as to when they had put the feeding tube as it was all rubber and felt bad when it came out.
Further physiotherapy helped me crawl till the top of the bed, the bed was around 6 feet in length and and more than enough so I could turn both sides without falling over.
Few days later I found I could also sit up using my legs as a lever and that gave confidence to the doctors to remove the air bed so I could crawl more easily.
Couple of more days later I stood on my feet for the first time and it was like I had lead legs. Each step was painful but the sense and feeling of independence won over whatever pain was there.
I had to endure wet wipes from nurses and ward boys in place of a shower everyday and while they were respectful always it felt humiliating.
The first time I had a bath after 2 weeks or something, every part of my body cried and I felt like a weakling. I had thought I wouldn t be able to do justice to the physiotherapy session which was soon after but after the session was back to feeling normal.
For a while I was doing the penguin waddle which while painful was also had humor in it. I did think of shooting the penguin waddle but decided against it as I was half-naked most of the time ( the hospital clothes never fit me properly)
Cut to today and I was able to climb up and down the stairs on my own and circled my own block, slowly but was able to do it on my own by myself.
While I always had a sense of wonderment for bi-pedal motion as well as all other means of transport, found much more respect of walking. I live near a fast food eating joint so I see lot of youngsters posing in different ways with their legs to show interest to their mates. And this I know happens both on the conscious and sub-conscious levels. To be able to see and discern that also put a sense of wonder in nature s creations.
All in all, I m probabl6y around 40% independent and still 60% interdependent. I know I have to be patient with myself and those around me and explain to others what I m going through.
For e.g. I still tend to spill things and still can t touch-type much.
So, the road is long, I can only pray and hope best wishes for anybody who is my condition and do pray that nobody goes through what I went through, especiallly not children.
I am also hoping that things like


 In my

 It may look that the decision for pagure as alioth replacement is already finalized, but that s not really true. I got a lot of feedback and tips in the last weeks, those made postpone my decision. Several alternative systems were recommended to me, here are a few examples:
 Bem vindo ao Debian Stretch!
Ontem, 17 de junho de 2017, o Debian 9 (Stretch) foi lan ado. Eu gostaria de falar sobre alguns procedimentos b sicos e regras para migrar do Debian 8 (Jessie).
Passos iniciais
 Nos dois casos, recomend vel que voc escolha por instalar a nova vers o do arquivo de configura o. Isso porque o novo arquivo de configura o estar totalmente adaptado aos novos servi os instalados e poder ter muitas op es novas ou diferentes. Mas n o se preocupe, pois as suas configura es n o ser o perdidas. Haver um backup das mesmas. Assim, para shell, escolha a op o "Y" e, no caso de janela, escolha a op o "instalar a vers o do mantenedor do pacote". muito importante anotar o nome de cada arquivo modificado. No caso da janela anterior, trata-se do arquivo /etc/samba/smb.conf. No caso do shell o arquivo foi o /etc/rsyslog.conf.
Depois de completar a migra o, voc poder ver o novo arquivo de configura o e o original. Caso o novo arquivo tenha sido instalado ap s uma escolha via shell, o arquivo original (o que voc tinha anteriormente) ter o mesmo nome com a extens o .dpkg-old. No caso de escolha via janela, o arquivo ser mantido com a extens o .ucf-old. Nos dois casos, voc poder ver as modifica es feitas e reconfigurar o seu novo arquivo de acordo com as necessidades.
Caso voc precise de ajuda para ver as diferen as entre os arquivos, voc poder usar o comando diff para compar -los. Fa a o diff sempre do arquivo novo para o original. como se voc quisesse ver como fazer com o novo arquivo para ficar igual ao original. Exemplo:




 Let yourself be embraced by the purple rubber toy octopus! We're happy to announce
the release of Debian 9.0, codenamed Stretch.
Want to install it?
Choose your favourite