Search Results: "spa"

13 June 2010

Bernd Zeimetz: signs of bad package maintenance

<rant>Recently I've adopted a package, mainly as Merkaartor uses it now. It made me sad to see in which bad condition the package was. Here are just a few things I had to do to bring it into shape: These points were only the larger issues, a lot more were fixed by me or by QA uploads while the package was orphaned. For me it seems that the former maintainer of that package threw some stuff together just to be able to upload the package - or at least run out of spare time to maintain a package properly several years ago. To all the people who maintain packages - and it doesn't matter if you maintain a single package or hundreds of them: Please orphan or at least RFA your packages if you don't have the proper time to maintain (all of) them. Don't open new ITPs if you obviously don't have the time to maintain the packages you have already. Talk with your upstreams, they're usually happy about it. Look at Lintian warnings and errors instead of overriding them. If you take patches from NMUs, say 'thanks' to the poor soul who had to create them for you in debian/changelog instead of taking the work without any notice. Remember - Debian is a community effort, not a run for the highest number of maintained packages on your QA page.</rant>

12 June 2010

Matt Zimmerman: How to decide what to read (and what not to read)?

Like you, dear Internet readers, I have no shortage of reading material. I have ready access to more engaging, high quality, informative and relevant information than I can possibly digest. Every day, I have to choose what to read, and what to pass by. This seems like an important thing to do well, and I wonder if I do a good enough job of it. This is just one example of a larger breadth/depth problem, but I m finding the general problem difficult to stomach, so I m focusing on reading for the moment. These are my primary sources of reading material on a day-to-day basis: How do you decide what to read, and what not to read? How does your experience differ between your primary information sources? How have you tried to improve?

11 June 2010

Petter Reinholdtsen: Automatic upgrade testing from Lenny to Squeeze

The last few days I have done some upgrade testing in Debian, to see if the upgrade from Lenny to Squeeze will go smoothly. A few bugs have been discovered and reported in the process (#585410 in nagios3-cgi, #584879 already fixed in enscript and #584861 in kdebase-workspace-data), and to get a more regular testing going on, I am working on a script to automate the test. The idea is to create a Lenny chroot and use tasksel to install a Gnome or KDE desktop installation inside the chroot before upgrading it. To ensure no services are started in the chroot, a policy-rc.d script is inserted. To make sure tasksel believe it is to install a desktop on a laptop, the tasksel tests are replaced in the chroot (only acceptable because this is a throw-away chroot). A naive upgrade from Lenny to Squeeze using aptitude dist-upgrade currently always fail because udev refuses to upgrade with the kernel in Lenny, so to avoid that problem the file /etc/udev/kernel-upgrade is created. The bug report #566000 make me suspect this problem do not trigger in a chroot, but I touch the file anyway to make sure the upgrade go well. Testing on virtual and real hardware have failed me because of udev so far, and creating this file do the trick in such settings anyway. This is a known issue and the current udev behaviour is intended by the udev maintainer because he lack the resources to rewrite udev to keep working with old kernels or something like that. I really wish the udev upstream would keep udev backwards compatible, to avoid such upgrade problem, but given that they fail to do so, I guess documenting the way out of this mess is the best option we got for Debian Squeeze. Anyway, back to the task at hand, testing upgrades. This test script, which I call upgrade-test for now, is doing the trick:
#!/bin/sh
set -ex
if [ "$1" ] ; then
    desktop=$1
else
    desktop=gnome
fi
from=lenny
to=squeeze
exec < /dev/null
unset LANG
mirror=http://ftp.skolelinux.org/debian
tmpdir=chroot-$from-upgrade-$to-$desktop
fuser -mv .
debootstrap $from $tmpdir $mirror
chroot $tmpdir aptitude update
cat > $tmpdir/usr/sbin/policy-rc.d <<EOF
#!/bin/sh
exit 101
EOF
chmod a+rx $tmpdir/usr/sbin/policy-rc.d
exit_cleanup()  
    umount $tmpdir/proc
 
mount -t proc proc $tmpdir/proc
# Make sure proc is unmounted also on failure
trap exit_cleanup EXIT INT
chroot $tmpdir aptitude -y install debconf-utils
# Make sure tasksel autoselection trigger.  It need the test scripts
# to return the correct answers.
echo tasksel tasksel/desktop multiselect $desktop   \
    chroot $tmpdir debconf-set-selections
# Include the desktop and laptop task
for test in desktop laptop ; do
    echo > $tmpdir/usr/lib/tasksel/tests/$test <<EOF
#!/bin/sh
exit 2
EOF
    chmod a+rx $tmpdir/usr/lib/tasksel/tests/$test
done
DEBIAN_FRONTEND=noninteractive
DEBIAN_PRIORITY=critical
export DEBIAN_FRONTEND DEBIAN_PRIORITY
chroot $tmpdir tasksel --new-install
echo deb $mirror $to main > $tmpdir/etc/apt/sources.list
chroot $tmpdir aptitude update
touch $tmpdir/etc/udev/kernel-upgrade
chroot $tmpdir aptitude -y dist-upgrade
fuser -mv
I suspect it would be useful to test upgrades with both apt-get and with aptitude, but I have not had time to look at how they behave differently so far. I hope to get a cron job running to do the test regularly and post the result on the web. The Gnome upgrade currently work, while the KDE upgrade fail because of the bug in kdebase-workspace-data I am not quite sure what kind of extract from the huge upgrade logs (KDE 167 KiB, Gnome 516 KiB) it make sense to include in this blog post, so I will refrain from trying. I can report that for Gnome, aptitude report 760 packages upgraded, 448 newly installed, 129 to remove and 1 not upgraded and 1024MB need to be downloaded while for KDE the same numbers are 702 packages upgraded, 507 newly installed, 193 to remove and 0 not upgraded and 1117MB need to be downloaded I am very happy to notice that the Gnome desktop + laptop upgrade is able to migrate to dependency based boot sequencing and parallel booting without a hitch. Was unsure if there were still bugs with packages failing to clean up their obsolete init.d script during upgrades, and no such problem seem to affect the Gnome desktop+laptop packages.

Rapha&#235;l Hertzog: About the Debian Community Poll

While I find the idea interesting, several of the questions can t be correctly answered because the proposed choices are not realistic or too limited. On the question of the usage of money, I believe we should spend money to fund important projects but I don t want to fund people having important positions in Debian and doing important work . What should I reply? (Granted, there s the other item but that doesn t help getting a clear picture of the answers) On the question Do you prefer time based releases instead of the it s ready when it s ready releases? , it is putting two concepts in opposition when the release managers recently proposed a third way that combines both: time based freezes and release when it s ready . This is what I want and I can t adequately express it either in the current poll. Partagez cet article / Share This

10 June 2010

David Welton: Ok, first one on the block: leenooks.com

The problem with selling off these sites is that I am a bit attached to them emotionally. Leenooks.com is a cool domain, I think - it's how Linus pronounces Linux, supposedly. It's also one of the first sites I put together: the original version was done in Perl with CGI back in ... '97? The current incarnation runs on DedaWiki a wiki I put together that is built with Ruby on Rails.
The idea behind the site was that, rather than keep track of all the hardware out there that works well with Linux, let's focus on the stuff you really want to avoid as that is a smaller set of things, and hopefully one that, one day, will be empty! It seems to have been fairly popular over the years, and has helped pay for the server it runs on. However, "popular" doesn't necessarily translate into "oodles of money", and especially now that I have a daughter who is a lot of fun to play with, I need to cut back on my "spare time" projects. So this one is the first one up on the auction block. I fervently hope that whoever acquires it can dedicate a bit more time and energy to making it do what it does, only better.

Lior Kaplan: Israeli projects for improvement of government services go open source

In an business open source conference held today (June 10th) in Tel Aviv, Michael Eitan, Minister of Improvement of Government Services, said that projects under his responsibility will go open source to improve transparency. More info at TheMarker (in Hebrew, English version by Google translate). A pilot with a focus group should begin soon for testing the changes.
Filed under: Israeli Community

Dirk Eddelbuettel: RcppArmadillo 0.2.2

Following the Rcpp 0.8.1 release we made yesterday, we released RcppArmadillo release 0.2.2 this morning. RcppArmadillo uses Rcpp (and some 'glue' code) to provide a transparent interface from R to Conrad Sanderson's impressive Armadillo library for linear algebra. This release works well with the most recent inline release 0.3.5. One can now employ inlined R code as we generalized how/which headers are included and how library / linking information is added thanks a plugin mechanism. This is the first RcppArmadillo version to provide such a plugin, We also updated the included Armadillo headers to its most recent release 0.9.10, added some more operators and provide a utility function RcppArmadillo:::CxxFlags() to provide include directory information on the fly. An example of the direct inline approach for the fastLm function:
library(inline)
library(RcppArmadillo)
src <- '
	Rcpp::NumericVector yr(ys);			// creates Rcpp vector from SEXP
	Rcpp::NumericMatrix Xr(Xs);			// creates Rcpp matrix from SEXP
	int n = Xr.nrow(), k = Xr.ncol();

	arma::mat X(Xr.begin(), n, k, false);   	// reuses memory and avoids extra copy
	arma::colvec y(yr.begin(), yr.size(), false);

	arma::colvec coef = arma::solve(X, y);      	// fit model y ~ X
	arma::colvec res = y - X*coef;			// residuals

	double s2 = std::inner_product(res.begin(), res.end(), res.begin(), double())/(n - k);
							// std.errors of coefficients
	arma::colvec std_err = arma::sqrt(s2 * arma::diagvec( arma::inv(arma::trans(X)*X) ));

	return Rcpp::List::create(Rcpp::Named("coefficients") = coef,
				  Rcpp::Named("stderr")       = std_err,
				  Rcpp::Named("df")           = n - k
				  );
'
fun <- cxxfunction(signature(ys="numeric", Xs="numeric"), src, plugin="RcppArmadillo")
This creates a compiled function fun which, by using Armadillo, regresses a vector ys on a matrix Xs (just how the fastLmPure() function in the package does) --- yet is constructed on the fly using cxxfunction from inline. More information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

9 June 2010

David Welton: Some difficult decisions?

I am, by nature, a tinkerer. I love to build things to see how they will work or because I have an idea that I think is fun. I am not so much of a natural business guy. I go build something "because it's there". Or rather, it's there in my mind, and I want to make it. I earn money, however, via consulting work. There are problems with this line of business though, namely that it doesn't scale very well unless, besides being good at a skill, you've also got the skills to build up a consulting business, which is very much about adding and managing people, something I'm not all that passionate about and would rather avoid. So what happens is that you go through slumps with less than full capacity, and then things pick up again, and before you know it, you hit your upper limit and can't take on any new work, putting a ceiling over your potential earnings. Sure, you can raise prices a bit, but that'll only get you so far. For a while now, I've been considering this problem, and I think some sort of product would be an ideal way out. Stories like Balsamiq's are inspirational, and along the lines of what I think might be nice. Don't get me wrong, I like my clients and like to help people solve problems a lot, but it's a stressful job in that you're never very far from having no income. I'm not much of an entrepreneur, though, in the sense of someone with a nose for making money. I tend to think about building something cool first, and not really worrying about making money with it. Predictably, some of the sites I have created are popular, but don't make any money. Sure, they have some ads, but that doesn't really make much unless you get really huge page views or have some sort of content that attracts users who will click on very lucrative advertisements. I've started to think that perhaps I should constrain myself in new initiatives to creating things that have a direct source of revenue: you want to use it, you pay. In my daydream world, I'd probably just hack on open source all day long, but there's no money in that for someone like me who is not the author of some huge, famous piece of software, nor a particularly great hacker in any case (I've met some, like Andrew Tridgell, and it's a really humbling experience). So that brings up the question of what to do with the aforementioned sites. One option would be to sell them off via a site like flippa.com, another would be simply to just let them sit there and stew, but they do take up some resources on my server, and require some maintainance now and then, and they're a bit of a distraction too (I start wondering about things to add or how to fiddle with them). Maybe there's a way to make money from some of them, but I'm too blind to see it. The ones I'm thinking about, are, in no particular order:

Julien Danjou: Desktop notification support for Emacs

This last weeks, I've worked on implementing the Desktop Notification Specification into Emacs. It allows sending desktop notification in a very simple way.

(notifications-notify
    :title "You've got mail!"
    :body "There's 34 mails unread"
    :app-icon "~/.emacs.d/icons/mail.png"
    :urgency 'low)
It supports the protocol signals (NotificationClosed and ActionInvoked) and the two main methods (Notify and CloseNotification). The methods specification are implemented entirely (hints, replaces, actions, icon, etc). The signals are supported via callbacks function provided on the notification creation. It have been merged into Emacs trunk today.
2010-06-09  Julien Danjou  <julien@danjou.info>
        * net/notifications.el: New file.
This also allowed me to discover, raise and fix a bug in the D-Bus binding of Emacs, which will be probably fixed in trunk soon.

8 June 2010

Matt Zimmerman: DevOps and Cloud

DevOps I first heard about DevOps from Lindsay Holmwood at linux.conf.au 2010. Since then, I ve been following the movement with interest. It seems to be about cross-functional involvement in software teams, specifically between software development and system administration (or operations). In many organizations, especially SaaS shops, these two groups are placed in opposition to each other: developers are driven to deliver new features to users, while system administrators are held accountable for the operation of the service. In the best case, they maintain a healthy balance by pushing in opposite directions, but more typically, they resent each other for getting in the way, as a result of this dichotomy:
Development Operations
is responsible for creating products offering services
is measured on delivery of new features high reliability
optimizes by increasing velocity controlling change
and so is perceived as reckless and irresponsible obstructing progress
Of course, both functions are essential to a viable service, and so DevOps aims to replace this opposition with cooperation. By removing this friction from the organization, we hope to improve efficiency, lower costs, and generally get more work done.
So, DevOps promotes the formation of cross-functional teams, where individuals still take on specialist development or operations roles, but work together toward the common goal of delivering a great experience to users. By working as teammates, rather than passing work over the wall , they can both contribute to development, deployment and maintenance according to their skills and expertise. The team becomes a devops team, and is responsible for the entire product life cycle. Particular tasks may be handled by specialists, but when there s a problem, it s the team s problem. Some take it a step further, and feel that what s needed is to combine the two disciplines, so that individuals contribute in both ways. Rather than thinking of themselves as developers or sysadmins , these folks consider themselves devops . They work to become proficient in both roles, and to synthesize new ways of working by drawing on both types of skills and experience. A common crossover activity is the development of sophisticated tools for automating deployment, monitoring, capacity management and failure resolution. DevOps meets Cloud Like DevOps, cloud is not a specific technology or method, but a reorganization of the model (as I ve written previously). It s about breaking down the problem in a different way, splitting and merging its parts, and creating a new representation which doesn t correspond piece-for-piece to the old one. DevOps drives cloud because it offers a richer toolkit for the way they work: fast, flexible, efficient. Tools like Amazon EC2 and Google App Engine solve the right sorts of problems. Cloud also drives DevOps because it calls into question the traditional way of organizing software teams. A development/operations division just doesn t fit cloud as well as a DevOps model. Deployment is a classic duty of system administrators. In many organizations, only the IT department can implement changes in the production environment. Reaping the benefits of an IaaS environment requires deploying through an API, and therefore deployment requires development. While it is already common practice for system administrators to develop tools for automating deployment, and tools like Puppet and Chef are gaining momentum, IaaS makes this a necessity, and raises the bar in terms of sophistication. Doing this well requires skills and knowledge from both sides of the fence between development and operations, and can accelerate development as well as promote stability in production.
This is exemplified by infrastructure service providers like Amazon Web Services, where customers pay by the hour for black box access to computing resources. How those resources are provisioned and maintained is entirely Amazon s problem, while its customers must decide how to deploy and manage their applications within Amazon s IaaS framework. In this scenario, some operations work has been explicitly outsourced to Amazon, but IaaS is not a substitute for system administration. Deployment, monitoring, failure recovery, performance management, OS maintenance, system configuration, and more are still needed. A development team which is lacking the experience or capacity for this type of work cannot simply switch to an IaaS model and expect these needs to be taken care of by their service provider.
With platform service providers, the boundaries are different. Developers, if they build their application on the appropriate platform, can effectively outsource (mostly) the management of the entire production environment to their service provider. The operating system is abstracted away, and its maintenance can be someone else s problem. For applications which can be built with the available facilities, this will be a very attractive option for many organizations. The customers of these services may be traditional developers, who have no need for operations expertise. PaaS providers, though, will require deep expertise in both disciplines in order to build and improve their platform and services, and will likely benefit from a DevOps approach. Technical architecture draws on both development and operations expertise, because design goals like performance and robustness are affected by all layers of the stack, from hardware, power and cooling all the way up to application code. DevOps itself promotes greater collaboration on architecture, by involving experts in both disciplines, but cloud is a great catalyst because cloud architecture can be described in code. Rather than talking to each other about their respective parts of the system, they can work together on the whole system at once. Developers, sysadmins and hybrids can all contribute to a unified source tree, containing both application code and a description of the production environment: how many virtual servers to deploy, their specifications, which components run on which servers, how they are configured, and so on. In this way, system and network architecture can evolve in lockstep with application architecture. Cloudy promises such as dynamic scaling and fault tolerance call for a DevOps approach in order to be realized in a real-world scenario. These systems involve dynamically manipulating production infrastructure in response to changing conditions, and the application must adapt to these changes. Whether this takes the form of an active, intelligent response or a passive crash-only approach, development and operational considerations need to be aligned. So what? DevOps and cloud will continue to reinforce each other and gain momentum. Both individuals and organizations will need to adapt in order to take advantage of the opportunities provided by these new models. Because they re complementary, it makes sense to adopt them together, so those with expertise in both will be at an advantage.

Russell Coker: Is the PC Dying?

I just read an interesting article about the dispute between Microsoft and Apple about types of PC [1]. Steve Jobs predicted a switch from desktop PCs to portable devices, while Steve Ballmer of Microsoft claimed that the iPad is just a new PC. Defining a PC I think that the defining characteristic of the IBM Compatible PC was it s open architecture. Right from the start the PC could have it s hardware expanded by adding new circuit boards into slots on the motherboard (similar to other PC systems of that era such as the Apple 2 and the S-100 bus). The deal with IBM included Intel sharing all it s CPU designs with other manufacturers such as NEC and AMD from the 8086 until the mid-90 s. AMD specialised in chips that were close copies of Intel chips at low prices and higher clock rates while NEC added new instructions. Compaq started the PC clone market as well as the laptop market, and system software for the IBM compatible PCs was primarily available from IBM and Microsoft in the early days, along with less popular variants such as CP/M86, Novell Netware and others. In the late 80 s there was OS/2 as an alternate OS and Windows as one of several optional GUI environments to run on top of MS-DOS or PC-DOS. In the mid 90 s PCs were used for running protected mode OSs such as Linux and Windows/NT. Now if we look at a system such as a Netbook then it clearly misses some of the defining characteristics of the desktop PC. I can t upgrade a Netbook in any meaningful way changing a storage device or adding more RAM does not compare to adding an ISA/MCA/EISA/VL-Bus/PCI/PCIe expansion card. With my EeePC 701 I don t even have an option of replacing the storage as it is soldered to the motherboard! A laptop allows me to add a PCMCIA or PC-Card device to expand it, but with a maximum of two cards and a high price this isn t a great option. What is Best for Home Users? For a while now my parents have been using 3G net access for their home Internet use [2]. So it seems that a laptop provides greater benefits for their use now than it previously did when they used Cable and ADSL net access. My parents have been considering getting a new monitor (1920*1080 resolution monitors are getting insanely cheap nowadays) and driving such a monitor effectively might require a more capable PC. I recently bought myself a nice refurbished Thinkpad for $796 [3], it seems likely that I could find a refurbished Thinkpad at auction which is a little older and slower for a lower price, even buying an old T41p would be a reasonable option. This would give my parents not only the option of using the Internet when on holidays, but also in a different part of their house when they are at home. The Apple iPad would probably be quite a reasonable Internet platform for my parents if it wasn t for the fact that it uses DRM. While it s not a great platform for writing, my parents probably don t do enough that it would be a huge problem for them. So I might look for a less restrictive tablet platform for my parents. At the moment the best resolution for a tablet seems to be 1024*768, but I expect that some tablets (maybe with a hybrid tablet/laptop design like the Always Innovating Smartbook [4]) with a higher resolution will be released soon. I hope that the iPad and other closed devices don t get any serious market share, but it seems likely that OSs such as Android which are only slightly more open will have a significant market share. Ultra-Mobile Design vs PCs Design One significant problem with ultra-mobile devices is that they make significant engineering trade-offs to get the small size. For a desktop system there are lots of ways of doing things inefficiently, running the AMD64 or i386 architecture which is wasteful of energy and having lots of unused space inside the box in case you decide to upgrade it. But for a laptop there are few opportunities for being inefficient, and for a tablet or smart phone everything has to be optimised. When the optimisation of a device starts by choosing a CPU that s unlike most other systems (note that there is a significant range of ARM CPUs that are not fully compatible with each other) it makes it very difficult to produce free software to run it. I can salvage a desktop PC from a rubbish bin and run Linux on it (and I ve done that many times), but I wouldn t even bother trying to run Linux on an old mobile phone. It seems that in the near future my parents (and many other people with similar needs) will be best suited by having a limited device such as a tablet that stores all data on the Internet and not having anything that greatly resembles a PC. In many ways it would be easier for me to support my parents by storing their data in the cloud and then automatically backing it up to removable SATA disks than with my current situation of supporting a fully capable PC and backing it up to a USB device whenever I visit them. I m also considering what to do for some relatives who are about to go on a holiday in Europe, they want to be able to send email etc. It might not be possible just yet, but it seems like an ideal way of doing this would be to provide them with something like an iPad that they can use with a local 3G SIM for the country that they stay in and they could then upload all their best photos to some server that I can backup and send email to everyone they know. An iPad isn t good for this now as you don t want to go on holidays in another country while carrying something that is really desirable to thieves. Ultra Mobile Devices are Killing PCs It seems to me that Google Android and the Apple iPad/iPhone OS are taking over significant parts of the PC market. The people who are doing traditional PC things are increasingly using Laptops and Netbooks, and the number of people who get the freedom that a PC user did in the 80 s and 90 s is decreasing rapidly. I predict that by 2012 the majority of Linux systems will be running Google Android on hardware that doesn t easily allow upgrading to more open software. At the moment probably the majority of Linux systems are wireless routers and other embedded devices that people don t generally think about. But when iPad type devices running a locked-down Linux installation start replacing Ubuntu and Fedora desktop systems people will take notice. I don t think that the death of the PC platform as we know it will kill Linux, but it certainly won t do us any good. If there were smarter people at Microsoft then they would be trying to work with the Linux community on developing innovative new ways of using desktop PCs. Of all the attempts that Microsoft has made to leave the PC platform the only success has been the X-Box which is apparently doing well. Tablet devices such as the iPad could work really well in a corporate environment (where MS makes most of it s money). On many occasions I ve been in a meeting and we had to adjourn due to someone needing to go to their desk to look something up. If everyone had an iPad type device at their desk that used a wired network when it was available and encrypted wireless otherwise then for a meeting everyone could take their tablet without it s keyboard and be able to consult all the usual sources of data without any interruption. Could a high-resolution version of the iPad kill MS-Windows in the corporate environment?

7 June 2010

Chris Lamb: Distributing locking with Python and Redis

This is already possible with Memcache, but if you are already drinking the Koolaid...
import time
class Lock(object):
    def __init__(self, key, expires=60, timeout=10):
        """
        Distributed locking using Redis SETNX and GETSET.
        Usage::
            with Lock('my_lock'):
                print "Critical section"
        :param  expires     We consider any existing lock older than
                             expires  seconds to be invalid in order to
                            detect crashed clients. This value must be higher
                            than it takes the critical section to execute.
        :param  timeout     If another client has already obtained the lock,
                            sleep for a maximum of  timeout  seconds before
                            giving up. A value of 0 means we never wait.
        """
        self.key = key
        self.timeout = timeout
        self.expires = expires
    def __enter__(self):
        timeout = self.timeout
        while timeout >= 0:
            expires = time.time() + self.expires + 1
            if redis.setnx(self.key, expires):
                # We gained the lock; enter critical section
                return
            current_value = redis.get(self.key)
            # We found an expired lock and nobody raced us to replacing it
            if current_value and float(current_value) < time.time() and \
                redis.getset(self.key, expires) == current_value:
                    return
            timeout -= 1
            time.sleep(1)
        raise LockTimeout("Timeout whilst waiting for lock")
    def __exit__(self, exc_type, exc_value, traceback):
        redis.delete(self.key)
class LockTimeout(BaseException):
    pass
One common use case for distributed locks in web applications is to prevent clients dog-piling onto an expensive cache key:
def cache_without_dogpiling(key, cb, cache_expiry=None, *args, **kwargs):
    val = cache.get(key)
    if val is not None:
        return val
    # Cache miss; gain the lock to prevent multiple clients calling cb()
    with Lock(key, *args, **kwargs):
        # Check cache again - another client may have set the cache
        val = cache.get(key)
        if val is None:
            val = cb()
            cache.set(key, val, cache_expiry)
        return val
def slow():
    print "Inside slow()"
    return 1 + 1 # Python is slow
>>> cache_without_dogpiling('my_key', slow, 60 * 10)
Inside slow()
2
>>> cache_without_dogpiling('my_key', slow, 60 * 10)
2
As a bonus, if you don't want your test or development environment to rely on Redis, you can replace it with a no-op lock:
import contextlib
@contextlib.contextmanager
def Lock(*args, **kwargs):
    yield

5 June 2010

Jos? Parrella: Ditching PCI cards in Asterisk for fun and profit

In the past, I ve used PCI cards providing telephony TDM for my Asterisk-based projects. I ve only worked with Digium s FXO/FXS and T1/E1 cards, both in PCI and PCI-x formats, until a client asked for a gateway solution with FXO, FXS and E1, where using the PCI cards in a 1U IPBX was simply out of the question. Using Ethernet gateways has always been a problem in those cases, since entry-to-medium level solutions lack the processing power for massive call handling, and signalling is poor, making the architecture unfit for reporting purposes and specialized apps such as call centers. But hey, that s my experience with gateways. Therefore, I looked into Xorcom s Astribank. They pack FXO, FXS and PRI/BRI ports inside a convenient 19 1U case, which can connect to an Asterisk-based IPBX server via USB and gets recognized as an integral DAHDI device in modern setups. So I ordered a composite 8xFXO, 8xFXS and 1xE1 PRI from Astribank, labelled XR0072. Getting the equipment from Arizona to Florida was easy, and since I worked with DHL, getting it to Guayaquil in Ecuador was a breeze (next-day delivery) but passing customs is, as always in Latin America, a time-consuming operation. After paying 12.5% taxes and then some for DHL operations, and 15 days waiting, I got the equipment in Quito. To my surprise, the Astribank was extremely light and small, slightly near 3 Kg in 1U form factor and under 1/4 depth in the rack. While it had a rack-mounting kit, which I used, it could also rest securely over my IPBX without rack screws. My Astribank uses a single USB cable to connect to the master PBX it could also be connected to a secondary PBX and provide a fault tolerant setup. It also depends on a DC supply, which they included. Since I was using a modern Debian, with a modern Asterisk with already-compiled modern DAHDI (formerly called Zapata/Zaptel) drivers, I just connected the equipment via USB to the IPBX, issued an invoke-rc.d dahdi restart and we were good to go. Note: you do need the fxload package in Debian for firmware loading to the Astribank. And for good to go I mean you can check the registered spans with dahdi_registration and, as soon as you connect the E1 cable that comes from the CPE to the CPE port (which in my XR0072 is the first on the lower row for PRI) you get an OK status with dahdi_tool. Also note that I use an E1/CPE port, which is the default for the Astribank, otherwise I d have to set the XPP_PRI_SETUP variable as indicated on the User Manual. DAHDI insists on configuring a crc4 parameter for the detected spans, which I needed to remove and restart DAHDI so the equipment could sync with the CPE (that is, the box that the telco provided, with the balun and the crossover RJ45 cable) and avoid some nasty noise issues on the line, that also occur with Digium s Wildcard for PRI.
usb:008/005          xpp_usb+     e4e4:1162 Astribank-modular FPGA-firmware
 LABEL=[usb:...]       CONNECTOR=@usb-0000:00:1d.7-1
	XBUS-00/XPD-00: E1       (31)  Span 1  DAHDI-SYNC
	XBUS-00/XPD-10: FXS      (8)   Span 2
	XBUS-00/XPD-20: FXO      (8)   Span 3
Using DAHDI s dahdi_genconf command writes an /etc/asterisk/dahdi-channels.conf file with the group and channel configuration as detected by DAHDI. It should be included by the chan_dahdi.conf file, which, in my case, is not necessary since I only wanted to enable one DAHDI group (DAHDI/g0) with my 31 E1 channels (1-15,17-31)
group=0
context=from-pstn
channel => 1-15,17-31
That means that when I want to use the FXO/FXS ports, it d probably be easier to include the dahdi-channels.conf (FXS ports, for example, belong to a different context, from-internal) so I don t have to type more than my laziness permits. I also found that, in my setup, some Asterisk parameters were superfluous, such as the switchtype (either national or euroisdn work, and the former is the default) or the echo-cancelling stuff, so I assume Astribank s doing a great job in negotiating that with the CPE. Do take note, however, that in my case the CPE needed to be cold-restarted so I could get an Up status in Asterisk (pri show spans) and that my only non-default, channel related configuration in chan_dahdi.conf is signalling=pri_cpe. So far, so good. I m really happy with the Astribank and I can fully understand how useful it is in terms of price (quite competitive in comparison with traditional cards, specially when bought from resellers -like me-), size/weight and functionality/ease of setup and administration. Kudos!

Russell Coker: Bugs in Google Chrome

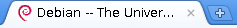
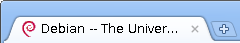
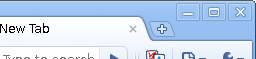
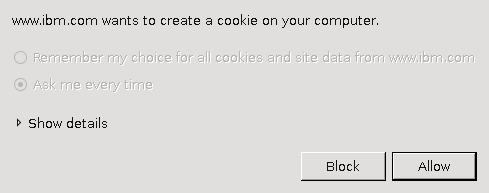
I m currently running google-chrome-beta version 5.0.375.55-r47796 on Debian/Unstable. It s the fastest web browser I ve used in recent times it s the first time that I ve run a browser that feels faster than my recollection of running IBM WebExplorer for OS/2 on a 486-66 system! It has a good feature set, and it s the only browser I ve used that in a typical configuration will make proper use of the screen space by not having a permanent status bar at the bottom of the sceen and by having tabs in the title-bar. But it s not perfect, here is a list of some bugs: Chrome Titlebar when maximisedChrome Titlebar when not maximisedRight of Chrome Titlebar when not maximised Above are three partial screen captures of Chrome, the first is when maximised and the second is when the window isn t maximised. Notice the extra vertical space above the tab in the title bar in the second picture. The third picture shows the right side of the titlebar and you can see a space below the three buttons where you can drag the window around no matter how many tabs you open that space below the three buttons is reserved. If the Chrome developers had removed the extra vertical space in the titlebar and reserved slightly more horizontal space then you would be able to drag the window around. While an anonymous commentator made a good point that the extra vertical space can be used to drag the window around when the maximum number of tabs are open, it seems that there are other ways of achieving that goal without wasting ~18 vertical pixels. Doing so would be a lot less ugly than what they did with finding text in the page. When I visit a web site that uses cookies from an Incognito Window (which means that cookies etc aren t stored) there is no option to say allow all cookies . This is really annoying when you get to a web site such as the IBM one which stores 5 cookies when you first load the page and then at least one new cookie write for every page you visit. Given that cookie data will be discarded as soon as the window is closed it seems like a good idea to have an option to allow all cookies for Incognito Windows even if all cookies aren t allowed for regular windows. Blocking all cookies would be OK too, anything but having to click on Block or Allow multiple times for each page load. The J and K keys don t work in a view of Venus version 0~bzr95-2+lenny1 (the latest version in Debian/Lenny). I once had a situation where I entered a . at the end of a domain name (which is quite legal there is always an implied dot) and Chrome then wouldn t take note of my request to accept all cookies from the domain. I haven t been able to reproduce that bug, but I have noticed that it stores the settings for whether cookies should be stored separately for domains that end in . , so www.cnn.com. is different from www.cnn.com . Iceweasel seems to just quietly strip the trailing dot. Of course this is better than Konqueror which won t even load a URL with a dot at the end. Chrome can be relied on to restore all windows rapidly after a crash, unlike Iceweasel which restores them at it s normal load speed (slow) and Konqueror which doesn t tend to restore windows. This is good as it does seem to crash regularly. In a response to my post about Chrome and SE Linux [1] Ben Hutchings pointed out that the --no-sandbox option to chrome disables the creation of a PID namespace and therefore makes debugging a lot easier, if I get a lot of spare time I ll try and track down some of the Chrome SEGVs. The JavaScript compiler is either buggy or it s not buggy in situations where people expect IE bugs. When using the Dell Australia web site I can t always order all options. When trying to order a Dell R300 1RU server with hot-plug disks in a hardware RAID array it seems impossible to get all the necessary jumpers which is a precondition to completing the order fortunately I only wanted to blog about how cheap Dell servers are so I don t actually need to complete an order. Dell s web site is also difficult in Iceweasel on occasion, so it s obviously more demanding than most sites. It might be a good test site for people who work on browsers as it s both demanding and important. When I select a URL to be opened in a new window (or when JavaScript does this) then the new tab is opened with about:blank listed as the URL. If the URL is for a PDF file (or something else that is to be downloaded) then the URL entry field is never updated to give the real URL. I believe that this is wrong, either the new tab shouldn t be opened or it should have the correct URL on display there is no benefit with a tab open to show nothing but about:blank in the URL entry field. Also if a URL takes some time to load then it may keep about:blank in the URL entry field for some time. This means that if you use the middle mouse button to rapidly open a few new tabs you won t be able to see what is to be loaded in each one. Sometimes I have several tabs loading and I m happy to close some unimportant ones if they are slow but some are worth waiting for. Overall that s not too bad. I can use Dell s site in Iceweasel, so the only critical bug is the cookies issue in Incognito Windows which makes the Incognito feature almost unusable for some sites.

4 June 2010

Marco T&uacute;lio Gontijo e Silva: Summer of Code weekly report #4

My project. I m publishing my report earlier this week, because there was a lot to talk about. This week I started to make changes in the code going in the direction of what I want to do. I haven t started a final implementation, but I m studying about how what I want to do will affect the rest of the Garbage Collection (GC). I noticed the code in rts/sm/Sweep.c was simple and similar to what I m planning to do, so I started changing how it works. Sweep in the Glasgow Haskell Compiler (GHC) is done by a bitmap, which contains a bit for each word in a memory block, and is set to 1 when there s an object starting in the mapped area and 0 otherwise. When there s a block with no objects starting at it, that is, all bits of the bitmap are set to 0, the block is freed.
        if (resid == 0)
         
            freed++;
            gen->n_old_blocks--;
            if (prev == NULL)  
                gen->old_blocks = next;
              else  
                prev->link = next;
             
            freeGroup(bd);
         
The bits are analyzed in a group of BITS_IN(W_), where BITS_IN(W_) is the number of bits in a word.
        for (i = 0; i < BLOCK_SIZE_W / BITS_IN(W_); i++)
         
            if (bd->u.bitmap[i] != 0) resid++;
         
If more than of the groups are completely set to 0, the block is considered fragmented.
            if (resid < (BLOCK_SIZE_W * 3) / (BITS_IN(W_) * 4))  
                fragd++;
                bd->flags  = BF_FRAGMENTED;
             
Immix, the GC algorithm I plan to implement in GHC, divides the blocks of memory in lines. My initial plan was to identify free lines. I decided to consider a the size of a line fixed in BITS_IN(W_) words, because it will map to a word in the bitmap, and the code was already analyzing in groups of BITS_IN(W_) words. This was very easy with the current code.
            if (bd->u.bitmap[i] != 0) resid++;
            else printf("DEBUG: line_found(%p)\n", bd->start + BITS_IN(W_) * i);
This worked, and showed some free lines. I m sure there are other ways of logging in GHC, but printf was the simplest way I could thought of. I measured the occurrence of free lines using the bernouilli program from the NoFib benchmark suite, calling it with 500 +RTS -w, to make it uses sweep. In 782 calls to GarbageCollect(), sweep() was called 171 times, for 41704 blocks to be swept and found 230461 free lines. This gives us about 5.5 free lines per block, from the 8 lines in each block (on 64 bits systems). The problem is that the bitmap is marked only in the start of the objects allocated, so even in a line that all bits are marked with 0 we can t assume that it s completely free, because there may be an object that starts in the previous line that is using the space of the line. Checking only for the previous line doesn t work either, because a big object can span several lines. What we can do here is a variation of conservative marking, as proposed in the Immix paper, checking only the previous line and working only with objects smaller than a line. To make sure I was working only with objects smaller than a line, I had to mark the blocks that contains medium objects and avoid them when seeking free lines. The block flags are defined in includes/rts/storage/Block.h, so I included another flag in this file, BF_MEDIUM.
/* Block contains objects evacuated during this GC */
#define BF_EVACUATED 1
/* Block is a large object */
#define BF_LARGE     2
/* Block is pinned */
#define BF_PINNED    4
/* Block is to be marked, not copied */
#define BF_MARKED    8
/* Block is free, and on the free list  (TODO: is this used?) */
#define BF_FREE      16
/* Block is executable */
#define BF_EXEC	     32
/* Block contains only a small amount of live data */
#define BF_FRAGMENTED 64
/* we know about this block (for finding leaks) */
#define BF_KNOWN     128
/* Block contains objects larger than a line */
#define BF_MEDIUM    256
The GHC GC is generational, there is, objects are allocated in a generation and, after a time, the ones that are still being used are moved the next generation. This idea assumes the death probability of younger objects is higher, so few objects are moved to the next generation. Sweep and Immix work only in the last generation so, to mark blocks with medium objects we have to check the size of the objects that are moved to the next generation. This is done in the copy_tag function of rts/sm/Evac.c. I inserted a code that checks for the object size and marks the block when it s bigger than BITS_IN(W_).
STATIC_INLINE GNUC_ATTR_HOT void
copy_tag(StgClosure **p, const StgInfoTable *info,
         StgClosure *src, nat size, generation *gen, StgWord tag)
 
    StgPtr to, from;
    nat i;
    to = alloc_for_copy(size,gen);
    if(size > 8)  
        Bdescr(to)->flags  = BF_MEDIUM;
     
So I updated the code in rts/sm/Sweep.c to only inspect for free lines in blocks without BF_MEDIUM mark.
            if (bd->u.bitmap[i] != 0) resid++;
            else if(!(bd->flags & BF_MEDIUM))  
                printf("DEBUG: line_found(%p)\n", bd->start + BITS_IN(W_) * i);
             
This also worked. Now, in the 32012 blocks there were 189015 free lines, found in the same number of GCs, making about 5.9 free lines per block. We considered only blocks with small objects, but we didn t ignore the first line of each group of free lines. This can be achieved by checking if the previous line was also free.
            if (bd->u.bitmap[i] != 0) resid++;
            else if(!(bd->flags & BF_MEDIUM) && i > 0 && bd->u.bitmap[i] == 0)  
                printf("DEBUG: line_found(%p)\n", bd->start + BITS_IN(W_) * i);
             
Now, from the 32239 blocks, 165547 free lines were found, giving 5.1 free lines per block. But there are more things to improve. If the whole block is free, we want to free it, instead of marking it s lines as free. So it s better to mark the lines after we know that the blocks are not completely free. So I left the code that checks the bitmap as it was, and included a line check only for blocks that are not completely free. At this point, I also associated the fragmentation test with blocks with medium objects, because in blocks of small objects we plan to allocate in free lines, so fragmentation is not a (big) issue.
            if (resid < (BLOCK_SIZE_W * 3) / (BITS_IN(W_) * 4) &&
                (bd->flags & BF_MEDIUM))  
                fragd++;
                printf("DEBUG: BF_FRAGMENTED\n");
                bd->flags  = BF_FRAGMENTED;
             
            else if(!(bd->flags & BF_MEDIUM))  
                for(i = 1; i < BLOCK_SIZE_W / BITS_IN(W_); i++)
                 
                    if(bd->u.bitmap[i] == 0 && bd->u.bitmap[i - 1] == 0)  
                        printf("DEBUG: line_found(%p)\n", bd->start + BITS_IN(W_) * i);


The total ammount of blocks increased dramatically: the blocks that become fragmented and were not called again in sweep made a huge difference. From the 345143 blocks, 1633268 free lines were found, or about 4.7 free lines per block. 9434 blocks were free, so, from the remaining blocks, we have about 4.9 free lines per block. Something we ll need then is a way to access these lines latter. The simplest way I thought to achieve it is constructing a list of lines, in each the first word of each free line is a pointer to the next free line, and the first word of the last free line is 0. It s useful to keep reporting the lines to stdout, so that we can then follow the list and check if we went to the same lines.
                    if(bd->u.bitmap[i] == 0 && bd->u.bitmap[i - 1] == 0)  
                        StgPtr start = bd->start + BITS_IN(W_) * i;
                        printf("DEBUG: line_found(%p)\n", start);
                        if(line_first == NULL)  
                            line_first = start;
                         
                        if(line_last != NULL)  
                            *line_last = (StgWord) start;
                         
                        line_last = start;
                        *line_last = 0;


    for(line_last = line_first; line_last; line_last = (StgPtr) *line_last)  
        fprintf(stderr, "DEBUG: line_found(%p)\n", line_last);
     
I printed the inclusion of the lines on the list to stdout, and the walking on the list in stderr, so that it d be easy to diff. There was no difference between the lists. There re another improvements that can be made, like using a list of groups of free lines, but I think it ll be better to think about this after studying how the allocation in the free lines will be done. That s where I m going to now.
There are some minor things I learned, and thought they worth blogging. The current GHC uses three strategies for collecting the last generation: copying, mark-compact and mark-sweep. Copying is the default until the memory reaches 30% of the maximum heap size; after that, mark-compact is used. Sweep can be chosen by a Real Time System (RTS) flag, -w. To use mark-compact always, the flag is -c. I ve been submitting small patches to the cvs-ghc mailling list, mostly about outdated comments. Most of them were accepted, except for one which contained a lot of commentary, and that indeed was not completely correct. I corrected it and resend to the list, but the message is waiting for approval because the message header matched a filter rule. I believe this is because I replied the message generated from darcs. There s a very useful ghc option, specially for testing the compiler, because in this case you need to rebuild the source, even when there re no changes in it. It s -fforce-recomp, and it makes only sense when used with --make.

Colin Watson: Hacking on grub2

Various people observed in a long thread on debian-devel that the grub2 package was in a bit of a mess in terms of its release-critical bug count, and Jordi and Stefano both got in touch with me directly to gently point out that I probably ought to be doing something about it as one of the co-maintainers. Actually, I don't think grub2 was in quite as bad a state as its 18 RC bugs suggested. Of course every boot loader failure is critical to the person affected by it, not to mention that GRUB 2 offers more complex functionality than any other boot loader (e.g. LVM and RAID), and so it tends to accumulate RC bugs at rather a high rate. That said, we'd been neglecting its bug list for some time; Robert and Felix have both been taking some time off, Jordi mostly only cared about PowerPC and can't do that any more due to hardware failure, and I hadn't been able to pick up the slack. Most of my projects at work for the next while involve GRUB in one way or another, so I decided it was a perfectly reasonable use of work time to do something about this; I was going to need fully up-to-date snapshots anyway, and practically all the Debian grub2 bugs affect Ubuntu too. Thus, with the exception of some other little things like releasing the first Maverick alpha, I've spent pretty much the last week and a half solidly trying to get the grub2 package back into shape, with four uploads so far. The RC issues that remain are: If we can fix that lot, or even just the ones that are reasonably well-understood, I think we'll be in reasonable shape. I'd also like to make grub-mkconfig a bit more robust in the event that the root filesystem isn't one that GRUB understands (#561855, #562672), and I'd quite like to write some more documentation. On the upside, progress has been good. We have multiple terminal support thanks to a new upstream snapshot (#506707), update-grub runs much faster (#508834, #574088), we have DM-RAID support with a following wind (#579919), the new scheme with symlinks under /dev/mapper/ works (#550704), we have basic support for btrfs / as long as you have something GRUB understands properly on /boot (#540786), we have full info documentation covering all the user-adjustable settings in /etc/default/grub, and a host of other smaller fixes. I'm hoping we can keep this up. If you'd like to help, contact me, especially if there's something particular that isn't being handled that you think you could work on. GRUB 2 is actually quite a pleasant codebase to work on once you get used to its layout; it's certainly much easier to fix bugs in than GRUB Legacy ever was, as far as I'm concerned. Thanks to tools like grub-probe and grub-fstest, it's very often possible to fix problems without needing to reboot for anything other than a final sanity check (although KVM certainly helps), and you can often debug very substantial bits of the boot loader - the bits that actually go wrong - using standard tools such as strace and gdb. Upstream is helpful and I've been able to get many of the problems above fixed directly there. If you have a sound knowledge of C and a decent level of understanding of the environment a boot loader needs to operate in - or for that matter specialist knowledge of interesting device types - then you should be able to find something to do.

Russell Coker: Securely Killing Processes

Joey Hess wrote on Debian-devel about the problem of init scripts not doing adequate checks before using the data from a PID file under /var/run to determine which process to kill [1]. Unfortunately that still doesn t quite solve the problem, there is still the issue of a race condition causing a process to die while you are doing the checks and then be replaced by another process. Below I have included the source code to a little program that will repeatedly fork() until it finds a particular PID and then have it s child call sleep(). So you can run a command such as kill -9 1234 ; ./a.out 1234 and then have this program take over the PID 1234. From testing with this it seems that when you have a shell with it s current working directory as /proc/1234 then once process 1234 is killed the current directory is empty, ls -l returns 0 entries. This isn t surprising, it s the standard Unix behavior when the working directory is removed. So if a program (or even a shell script) changes directory to /proc/1234 it can then verify all attributes of the process (it s CWD, it s root directory, the executable used to run it, it s UID, GID, supplemental groups, it s SE Linux context, and lots of other things all atomically. The only possibility for confusion is that a process might execute a SETUID or SETGID program or a program that has a label which triggers a SE Linux domain transition. It might also change some attributes without executing a new process, for example by using the setuid(), setgid(), setgroups(), or other similar system calls. For the purposes of killing a process I don t think that the possibility of it changing it s own attributes or executing a new program are serious problems, if you want to kill a process then you probably want to kill it after it has called setuid() etc. It seems to me that it would be useful to have a file named /proc/PID/signal (or something similar) to which you could write a number and then have the kernel send the signal in question to that process. So the commands kill -9 1234 and echo 9 > /proc/1234/signal would give the same result. But you could run the command cd /proc/1234 and then some time later you could run echo 9 > signal and know that you would kill the original process 1234 if it was still running and not some other process that replaced it. What do you think? Is this worthy of adding a new feature to the proc filesystem? The Source Run the following program with a single parameter which is the PID that you want it to take. It will keep looping through the PID space until it gets the one you specify, if the one you specify isn t available (EG you give it 1 as a parameter) then it will run forever. It will take some time to get a result on a slower system. On my P3-900MHz test system it took up to 72 seconds to get a result. #include <stdio.h>
#include <unistd.h>
#include <stdlib.h>
#include <sys/types.h>
#include <sys/wait.h> int main(int argc, char **argv)

if(argc != 2)

printf("Specify the desired PID on the command-line\n");
return 1;

pid_t wanted = (pid_t)atoi(argv[1]);
int rc;
int status;
while((rc = fork()) != wanted && rc != 0)

if(rc == -1)

printf("fork error\n");
return 1;

if(wait(&status) == -1)
printf("wait error\n");

if(rc == 0)

if(getpid() == wanted)

printf("Got pid %d, sleeping\n", wanted);
sleep(200);

return 0;

wait(&status);
return 0;

Russ Allbery: NVIDIA, bug handling, and patience

Recently, the long-time maintainer of the NVIDIA packages for Debian stepped down, after having not had much time to work on the packages for some time. I don't really like maintaining non-free packages, but I have some NVIDIA hardware and nouveau isn't quite far enough along yet for me to feel comfortable just switching, so I decided to help, despite having very little spare time. Thankfully, Andreas Beckmann stepped up and has been submitting patches like crazy, so I've not had to do a lot of the work. This is a very difficult package to maintain, since it's completely non-free. Nearly all the code is a binary object, which we cannot change in any way, so it's frustrating because we can't do anything about basically any bugs. Upstream distributes their code in a weird, annoying package format. It's also very complicated, full of random upstream libraries for providing various interfaces to the GPU to do computing, and it conflicts with and replaces various X bits like the GL library. And on top of that, it comes in four different variants, all of which need to be separately packaged, plus a bunch of supporting packages and libraries (some non-free and some free). Oh, and it builds a kernel module. And we historically provided pre-built kernel modules and meta-packages. And the packaging infrastructure hadn't been overhauled in quite some time, so it wasn't using current packaging techniques. Did I mention the RC bugs and the nearly 200 open bugs on just the main non-legacy package (now much lower thanks to Andreas's hard work). We're slowly making progress. nvidia-graphics-drivers migrated to testing for the first time since around the lenny release and now supports DKMS, and Andreas has massively modernized the packaging. We also have just about finished the transition to using the free libvdpao library rather than the one included with the NVIDIA packages. But given that background, you might understand why one might find blog posts like this one (about a bug that was first reported for KDE just one week ago!) just a little demotivating. (The problem had been previously observed with GDM, but it appeared to be fixed somehow in GDM 3.) I'm sure there are better ways that I could have communicated the bug status, and I probably stressed a bit more than I need to the point that the module is completely opaque and non-free and there isn't much that we can do to change its behavior. But reading negative comments about one's work on Planet Debian is really kind of frustrating, particularly when that work is on something that it's hard to get Debian to care about and that's kind of thankless to start with. I'm not trolling for praise here; I have a thick skin. But this does seem like a good opportunity for a reminder that this is a volunteer project, some packages are kind of annoying to maintain, and things take time. If you don't agree with a maintainer's determination of whether or not something is RC (I still don't think this bug is RC), one can certainly have that conversation. But unless the maintainer marks the bug wontfix, please don't jump to the conclusion that no one cares about trying to find a resolution. And one week is a rather short time period to arrive at that conclusion, even if the maintainer is fairly negative about the bug. Sometimes that just means that you caught them on a bad day. For the record, I'm currently pondering asking the people with this bug to try adding nvidia to /etc/modules and see if forcing the module load earlier works around this problem. I think what's happening is that the module is doing some sort of prolonged initialization, and it just needs more lead time before it's expected to respond to the X server.

Christine Spang: Christine Spang: Django form fields with the same name as Python keywords

For work recently I've been doing some Django-related tasks that involve talking to an external API with POSTed forms. Django forms objects are declared by creating a class that inherits from django.forms.Form, with the fields of the form declared by declaring attributes of that class. Which works well and is clean and easy to remember unless the API you're working with requires a field with the same name as a Python keyword, such as return. You can't declare a field like this as an attribute; it will trigger a syntax error. I spent some time scratching my head over this, and came up with this as a workaround after source-diving to find out how Form objects actually work:
from django import forms
class ExampleForm(forms.Form):
    def __init__(self, data=None, files=None, auto_id='id_%s', prefix=None,
            initial=None, errorclass=ErrorList, label_suffix=':', empty_permitted=False, return_url=None):
        forms.Form.__init__(self, data, files, auto_id, prefix, initial,
            errorclass, label_suffix, empty_permitted)
        if return_url is not None:
            self.fields['return'] = forms.CharField(widget=forms.HiddenInput, initial=return_url)
It turns out that the attribute declaration is just syntactic sugar for creating a dictionary of key/value pairs, which is then stored in the fields attribute. So we can monkeypatch in extra values after the translation. Which is somewhat more awkward and ugly, but works in a pinch. Note that I haven't extensively tested what interactions this may cause with other forms code, so use with some caution.

2 June 2010

Axel Beckert: xen-tools back in Debian Unstable

After xen-tools had been removed from Debian Unstable by the upstream developer last December due to no more upstream development, I took over upstream development as well as Debian package maintainership in January. Since then a lot happened: But despite all the things which were to fix after Steve discontinued the xen-tools developement, Steve Kemp did a great job to bring xen-tools so far initially. I m really happy that this software exists and that s the reason why I won t let it die so fast. :-) xen-tools 4.2 beta 1 released Last weekend I released xen-tools 4.2 beta 1 which I also uploaded to Debian Unstable. And thanks to the active ftp-master team, xen-tools went through the NEW queue in less than 12 hours and is now available again in Debian Unstable. 4.2 beta 1 still has some known bugs, the worst ones are in xen-delete-image. But no fear, it doesn t delete more than wanted, just not enough or things which don t exist anyway. :-) There are also some smaller issues to fix for a final 4.2 release. We may also create an PPA for Ubuntu Lucid in the future to work around the lack of xen-tools in Ubuntu Lucid. What about Fedora/RedHat/CentOS support? Since rinse is out of date with regards to current Fedora releases, rpmstrap seems to be out of date for even longer (it has been removed from Debian before the Lenny release) and febootstrap neither seems to work out of the box nor seems to support bootstrapping to mount points (because it wants to delete them first and fails), bootstrapping Fedora ist currently not supported. The copy installation method should work though. rinse still is able to bootstrap CentOS 4 and 5, but the installation seems incomplete. We ll try to work around these issues for the final 4.2 release. We haven t looked at mach and mock so far, but according to Lucas, both are out of date, too. Sure, implementing Lucas howto in form of a script would be a possible way, but we think it would just create yet another not so well supported clone of rinse, rpmstrap, mach, mock or febootstrap. Because of that, Dmitry works on support for the installation of Xen DomUs via kickstart. Fate of xen-shell? Xen-shell has also been removed from Debian Unstable last December because Steve stopped its developement, too. But in comparison to xen-tools itself, we didn t resurrect xen-shell since none of us currently has use for it. So if you are currently using xen-shell and intend to continue to do so, you should hurry up if you want to see it in Debian Squeeze. We can also help you, but we surely can t and won t do it alone nor will we take the majority of the necessary workload.

Next.

Previous.