Search Results: "reg"

5 March 2009

Colin Watson: Bug triage, redux

I've been a bit surprised by the strong positive response to my previous post. People generally seemed to think it was quite non-ranty; maybe I should clean the rust off my flamethrower. :-) My hope was that I'd be able to persuade people to change some practices, so I guess that's a good thing. Of course, there are many very smart people doing bug triage very well, and I don't want to impugn their fine work. Like its medical namesake, bug triage is a skilled discipline. While it's often repetitive, and there are lots of people showing up with similar symptoms, a triage nurse can really make a difference by spotting urgent cases, cleaning up some of the initial blood, and referring the patient quickly to a doctor for attention. Or, if a pattern of cases suddenly appears, a triage nurse might be able to warn of an incipient epidemic. [Note: I have no medical experience, so please excuse me if I'm talking crap here. :-)] The bug triagers who do this well are an absolute godsend; especially when they respond to repetitive tasks with tremendously useful pieces of automation like bughelper. The cases I have trouble with are more like somebody showing up untrained, going through everyone in the waiting room, and telling each of them that they just need to go home, get some rest, and stop complaining so much. Sometimes of course they'll be right, but without taking the time to understand the problem they're probably going to do more harm than good. Ian Jackson reminded me that it's worth mentioning the purpose of bug reports on free software: namely, to improve the software. The GNU Project has some advice to maintainers on this. I think sometimes we stray into regarding bug reports more like support tickets. In that case it would be appropriate to focus on resolving each case as quickly as possible, if necessary by means of a workaround rather than by a software change, and only bother the developers when necessary. This is the wrong way to look at bug reports, though. The reason that we needed to set up a bug triage community in Ubuntu was that we had a relatively low developer-to-package ratio and a very high user-to-developer ratio, and we were getting a lot of bug reports that weren't fleshed out enough for a developer to investigate them without spending a lot of time in back-and-forth with the reporter, so a number of people volunteered to take care of the initial back-and-forth so that good clear bug reports could be handed over to developers. This is all well and good, and indeed I encouraged it because I was personally finding myself unable to keep up with incoming bugs and actually fix anything at the same time. Somewhere along the way, though, some people got the impression that what we wanted was a first-line support firewall to try to defend developers from users, which of course naturally leads to ideas such as closing wishlist bugs containing ideas because obviously those important developers wouldn't want to be bothered by them, and closing old bugs because clearly they must just be getting in developers' way. Let me be clear about this now: I absolutely appreciate help getting bug reports into a state where I can deal with them efficiently, but I do not want to be defended from my users! I don't have a basis from which to state that all developers feel the same way, but my guess is that most do. Antti-Juhani Kaijanaho said he'd experienced most of these problems in Debian. I hadn't actually intended my post to go to Planet Debian - I'd forgotten that the "ubuntu" category on my blog goes there too, which generally I see as a feature, but if I'd remembered that I would have been a little clearer that I was talking about Ubuntu bug triage. If I had been talking about Debian bug triage I'd probably have emphasised different things. Nevertheless, it's interesting that at least one Debian (and non-Ubuntu) developer had experienced similar problems. Justin Dugger mentions a practice of marking duplicate bugs invalid that he has problems with. I agree that this is suboptimal and try not to do it myself. That said, this is not something I object to to the same extent. Given that the purpose of bugs is to improve the software, the real goal is to be able to spend more time fixing bugs, not to get bugs into the ideal state when the underlying problem has already been solved. If it's a choice between somebody having to spend time tracking down the exact duplicate bug number versus fixing another bug, I know which I'd take. Obviously, when doing this, it's worth apologising that you weren't able to find the original bug number, and explaining what the user can do if they believe that you're mistaken (particularly if it's a bug that's believed to be fixed); the stock text people often use for this doesn't seem informative enough to me. Sebastien Bacher commented that preferred bug triage practices differ among teams: for instance, the Ubuntu desktop team deals with packages that are very much to the forefront of users' attention and so get a lot of duplicate bugs. Indeed - and bug triagers who are working closely with the desktop team on this are almost certainly doing things the way the developers on the desktop team prefer, so I have no problem with that. The best advice I can give bug triagers is that their ultimate aim is to help developers, and so they should figure out which developers they need to work with and go and talk to them! That way, rather than duplicating work or being counterproductive, they can tailor their work to be most effective. Everybody wins.

Russell Coker: SE Linux Lenny Status Update

I previously described four levels of SE Linux support on the desktop [1]. Last night I updated my APT repository of SE Linux packages for Lenny (as described on my document about installing SE Linux [2]). I included a new policy package that supports logging in to a graphical session via gdm in either unconfined_t or user_t. This covers all the functionality I described as target 2 (some restricted users). I have tested this to a moderate degree. Target 3 was having all users restricted and no unconfined_t domain (the policy module unconfined.pp not being linked into the running policy). I had previously done a large part of the work towards that goal in preparation for running a SE Linux Play Machine (with public root password) [3] on Lenny - but until last night I had not published it. The combination of the policy needed to run with no unconfined_t domain and the policy to allow logging in as user_t via gdm should mean that a desktop system with gdm for graphical login that has no unconfined_t domain will work - but I have not tested this. So target 3 is likely to have been achieved, if testing reveals any problems in this regard then I ll release another policy update. So now the only remaining target is MLS. Also I have been setting up a mail server with a MySQL database for user account data and using Courier-Maildrop for delivery, so I ve written policy for that and also made some other improvements to the policy regarding complex mail servers.

4 March 2009

Jose Carlos Garcia Sogo: Innovation in netbooks

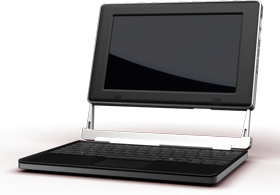
After the release of Asus Eee PC and the discovery of the market that was eager to buy cheap and wearable computers every laptop manufacturer has jumped into the hype and released their own versions of netbooks, with different success.
But somehow it was a cloning phase. Vendors were just cloning what Asus did, with more or less changes, but without innovating. Now, it seems that the path has opened again, from the open source and open hardware front, and it has been released AlwaysInnovating s touchbook. It is a netbook with a detachable keyboard (it is even sold separated) and built upon an ARM processor from Texas Instruments, and a 8GB microSD card. Thus they claim the battery last from 10 to 15h with the keyboard, and 3 to 5h in touchscreen mode.
As is said above, the whole machine is open source based. Software is based upon OpenEmbedded, and hardware schematics of the board are released under GPL on Beagleboard project. They say that you can also install Ubuntu, Android or even Windows CE on it. Update: Just discovered that AlwaysInnovating is a Gr goire Gentil startup. Gr gory is a Civil Engineer from cole des ponts et Chauss es. We know how to build things :-D

3 March 2009

Steve Kemp: Nobody likes a perky goth

Debian project leader elections are coming up soon. My vote will go to the candidate that: Thats all. I guess most people don't really care about being a DPL per-se, instead they stand for election to accomplish a pet project, or two. (Not that there is anything wrong with that. If your platform says "Elect me and I'll do $foo" then you've got implicit support.) A recurring theme in platforms has been communication, and I think that over time it has got a lot better. Regardless, if theres one thing I want to see from the DPL in 2009 it is even more communication. In other news, depending on your timezone, todays date is 3/3/9 - enjoy it while it lasts. The next similar date is 4/4/16 - which is seven years in the future. ObTitle: Blood Ties

Asheesh Laroia: Segmentation grace

Ladies and gentlemen, it seems that Google has finally done it: they shipped Multics for 386 (and compatible). NoiseBridge, this evening: I descended the stairs after teaching my introduction to programming class and found Geoff Schmidt in our San Francisco hacker space. I sat next to Geoff and overheard a lovely conversation with Mike Kan. Geoff told the sad tale of a beautiful, efficient, and dead operating system: Multics. Multics was written in the 1960s as a fast operating system for many users to share an expensive mainframe. It posed design problems never seriously tackled before, and after a decade, it had a practically perfect implementation for each of them. To achieve speed, it expected help from the hardware: registers on the processor split memory into different "segments," creating safe zones for each program to run in. The segment system was powerful and secure enough that a running process could execute code from another without the operating system kernel getting involved. The result was a fantasy come true: protection rings creating legendary security, the flexibility of a multi-user, multi-tasking operating system, and all this at hardly any performance overhead. (Naturally, such perfection is the result of years of work at MIT. So is Geoff.) This perfection came at a price: while Multics was uniquely well-designed and well-integrated, it expected specific support from the hardware it ran on. Geoff's expression deflated, and he pointed out that another operating system arrived on the scene: UNIX. Anyone could study the UNIX source code, and it ran on whatever you gave it. UNIX (a joke on the name Multics) eventually won by being worse: it was slow, unreliable, and worst of all: incorrect. But anyone could read it and make it work on the computer he happened to have. By the mid-1970s, UNIX's dominance over Multics was clear. Geoff skipped forward a decade to the 1980s. Intel had wanted to build a CPU that could be used as a modern computer, and users had shown that the puny memory protection system offered by the 286 wasn't adequate. The chip designers went back to the drawing board, and they brought back features that Multics invented: segmentation registers and protection rings. When shown these powerful, complex features, today's operating systems mostly ignore these Multics tricks and do the least work possible to build a UNIX-like flat memory model. Mike interrupted and howled about how he can't buy a "real Macintosh" anymore; Apple's computers were once based on a simple architecture, but now they are built with the same complex Intel CPUs everyone else uses. But I am writing this because of the release of Google Native Client, a browser extension that allows your computer to securely run machine code written by untrusted people on the Internet. How can it achieve this fantasy? The Wikipedia article summarizes the native client research paper:
Native Client is notable for its novel sandboxing technique which makes use of the x86 architecture's rarely-used segmentation facility.

2 March 2009

Julian Andres Klode: debian-cd, dependencies, debimg, comments


Looking at the amd64 CD images of Lenny, I just saw that there is the package gnome on disk 1, while some of its dependencies are on disk 2. I don t think that this is good. Same also applies to K3B on disk 3, and openoffice.org-kde on KDE-disk 1. In my opinion, all packages which are located on a disk X, should only depend on a disk N (N<X). This means that the package gnome would be moved to disk 2, or its dependencies to disk 1. This is exactly the way debimg works. Debimg uses so-called package groups, which simply represents a set of packages with cyclic dependencies. These package groups are returned in a specific order, so that a group N only requires a group <N. This order is kept when the groups are added to the disk. Furthermore, we treat the groups as one when adding them to the disk, ie. we check whether the whole group fits on the disk (and add it) or not (create a new disk). This way, we ensure that all dependencies can be satisfied. Today, I decided to try it out and therefore wrote a small script reading the debian-cd task files and comparing the file list (of the packages added to the disk) with the file list of the official KDE disk. The results look very good, debimg adds 11 packages and removes 26 which is not that much, and mostly caused by wrong size limits, etc. You can look at the results your self, and regenerate them using: Anyway, debimg still needs real configuration and handling of the debian installer and source packages, but this should give you an idea of how debimg works. And a tarball, for those who don t want to use git all the time. BTW, I have now enabled comment threading here, a new WordPress feature. I hope that it works, as I have not tried it out yet. Posted in Debian, debimg

Theodore Ts'o: SSD s, Journaling, and noatime/relatime

On occasion, you will see the advice that the ext3 file system is not suitable for Solid State Disks (SSD s) due to the extra writes caused by journaling and so Linux users using SSD s should use ext2 instead. However, is this folk wisdom actually true? This weekend, I decided to measure exactly what the write overhead of journaling actually is in actual practice. For this experiment I used ext4, since I recently added a feature to track the amount of writes to the file system over its lifetime (to better gauge the wear and tear on an SSD). Ext4 also has the advantage that (starting in 2.6.29), it can support operations with and without a journal, allowing me to do a controlled experiment where I could manipulate only that one variable. The test workload I chose was a simple one: For the first test, I ran the test using no special mount options, and the only difference being the presence or absence of the has_journal feature. (That is, the first file system was created using mke2fs -t ext4 /dev/closure/testext4, while the second file system was created using mke2fs -t ext4 -O ^has_journal /dev/closure/testext4.)
Amount of data written (in megabytes) on an ext4 filesystem
Operation with journal w/o journal percent change
git clone 367.7 353.0 4.00%
make 231.1 203.4 12.0%
make clean 14.6 7.7 47.3%
What the results show is that metadata-heavy workloads, such as make clean, do result in almost twice the amount data written to disk. This is to be expected, since all changes to metadata blocks are first written to the journal and the journal transaction committed before the metadata is written to their final location on disk. However, for more common workloads where we are writing data as well as modifying filesystem metadata blocks, the difference is much smaller: 4% for the git clone, and 12% for the actual kernel compile. The noatime mount option Can we do better? Yes, if we mount the file system using the noatime mount option:
Amount of data written (in megabytes) on an ext4 filesystem mounted with noatime
Operation with journal w/o journal percent change
git clone 367.0 353.0 3.81%
make 207.6 199.4 3.95%
make clean 6.45 3.73 42.17%
This reduces the extra cost of the journal in the git clone and make steps to be just under 4%. What this shows is that most of the extra meta-data cost without the noatime mount option was caused by update to the last update time for kernel source files and directories. The relatime mount option There is a newer alternative to the noatime mount option, relatime. The relatime mount option updates the last access time of a file only if the last modified or last inode changed time is newer than the last accessed time. This allows programs to be able to determine whether a file has been read size it was last modified. The usual (actually, only) example that is given of such an application is the mutt mail-reader, which uses the last accessed time to determine if new mail has been delivered to Unix mail spool files. Unfortunately, relatime is not free. As you can see below, it has roughly double the overhead of noatime (but roughly half the overhead of using the standard Posix atime semantics):
Amount of data written (in megabytes) on an ext4 filesystem mounted with relatime
Operation with journal w/o journal percent change
git clone 366.6 353.0 3.71%
make 216.8 203.7 6.04%
make clean 13.34 6.97 45.75%
Personally, I don t think relatime is worth it. There are other ways of working around the issue with mutt for example, you can use Maildir-style mailboxes, or you can use mutt s check_mbox_size option. If the goal is to reduce unnecessary disk writes, I would mount my file systems using noatime, and use other workarounds as necessary. Alternatively, you can use chattr +A to set the noatime flag on all files and directories where you don t want noatime semantics, and then clear the flag for the Unix mbox files where you care about the atime updates. Since the noatime flag is inherited by default, you can get this behaviour by setting running chattr +A /mntpt right after the filesystem is first created and mounted; all files and directories created in that file system will have the noatime file inherited. Comparing ext3 and ext2 filesystems
Amount of data written (in megabytes) on an ext3 and ext2 filesystem
Operation ext3 ext2 percent change
git clone 374.6 357.2 4.64%
make 230.9 204.4 11.48%
make clean 14.56 6.54 55.08%
Finally, just to round things out, I tried the same experiment using the ext3 and ext2 file systems. The difference between these results and the ones involving ext4 are the result of the fact that ext2 does not have the directory index feature (aka htree support), and both ext2 and ext3 do not have extents support, but rather use the less efficient indirect block scheme. The ext2 and ext3 allocators are also someone different from each other, and from ext4. Still, the results are substantially similar with the first set of Posix-compliant atime update numbers (I didn t bother to do noatime and relatime benchmark runs with ext2 and ext3, but I expect the results would be similar.) Conclusion So given all of this, where did the common folk wisdom that ext3 was not suitable for SSD s come from? Some of it may have been from people worrying too much about extreme workloads such as make clean ; but while doubling the write load sounds bad, going from 4MB to 7MB worth of writes isn t that much compared to the write load of actually doing the kernel compile or populating the kernel source tree. No, the problem was that first generation SSD s had a very bad problem with what has been called the write amplification effect , where a 4k write might cause a 128k region of the SSD to be erased and rewritten. In addition in order to provide safety against system crashes, ext3 has more synchronous write operations that is where ext3 waits for the write operation to be complete before moving on, and this caused a very pronounced and noticeable stuttering effect which was fairly annoying to users. However, the next generation of SSD s, such as Intel s X25-M SSD, have worked around the write amplification affect. What else have we learned? First of all, for normal workloads that include data writes, the overhead from journaling is actually relatively small (between 4 and 12%, depending on the workload). Further, than much of this overhead can be reduced by enabling the noatime option, with relatime providing some benefit, but ultimately if the goal is to reduce your file system s write load, especially where an SSD is involved, I would strongly recommend the use of noatime over relatime. Related posts (automatically generated):
  1. Should Filesystems Be Optimized for SSD s? In one of the comments to my last blog entry,...
  2. Aligning filesystems to an SSD s erase block size I recently purchased a new toy, an Intel X25-M SSD,...
  3. Fast ext4 fsck times This wasn t one of the things we were explicitly engineering...

1 March 2009

Julian Andres Klode: debimg update - creating images


Much happened since the last time I wrote about debimg. The project is now registered on Alioth and has a mailing list. On the code side, there have also been several changes. First of all, the repository module has been merged into the master branch. This was the first step towards the creation of the image building, which happened today by introducing the image module. The code should be treated as Beta quality, but the project as a whole is Alpha, because the application utilizing debimg.core is still missing. As always, I hereby encourage to try out debimg, have a look at the examples, and help to develop it. Patches should be sent to the mailing list, created with git format-patch, and its usual settings (eg. prefixed with eg. [PATCH 1/2] ). The patches should be inline and validate in pyflakes and using pep8.py. See the README for some more recommendations. Because NEW seems to be really busy at the moment (and doko uploaded python2.6 and python3.1), I m not uploading the current state as 0.1.0~a1 to experimental, but wait until NEW is smaller (maybe it will be 0.1.0~b1 then). What is wanted/planned?
  • Compatibility configuration formats
    • (debimg.config.simple_cdd) A reimplementation of simple-cdd using debimg. This probably needs to wait until there is a module for dealing with the installer, but I want to implement an application to support simple-cdd configuration files.
    • (debimg.config.debian_cd) There could be an implementation of debian-cd s configuration format. This would allow people to easily try out debimg. We can only support a subset, though.
  • New configuration formats
    • (debimg.config.yaml) Debimg s native configuration format. This is the only one supported by the graphical frontends. Where possible, configuration between compatibility formats and this format will be provided.
  • Graphical Frontends:
    • (debimg.frontend.gtk2) The graphical GTK+ frontend for inexperienced users who just want to create their own disk.
    • (debimg.frontend.qt4) The graphical frontend written in QT4.
  • Text frontends
    • (debimg.frontend.text) The basic command-line frontend.
    • (debimg.ubuntu.frontend.text) A script to build Ubuntu images, which could be used to build the official Ubuntu Images. This requires interaction with the germinate tool for dependency resolution, and more. It s also not flexible enough for building custom images.
Requirements for 0.1 Beta
  • Implement at least one configuration format and the build frontend.
  • Have at least one external contributor.
More Changes Julian Andres Klode (6):
  • debimg/core/files: When creating a file object allow filename as source
  • debimg/core/resolver.py: Introduce Package.fullname, Package.component
  • debimg/core/repository.py: Merge the repository module.
  • debimg/core/resolver.py: Improve handling of certain dependency types
  • debimg/core/repository.py: Allow Repository.add_group to take a distro parameter
  • debimg/core/image.py: Introduce the image module.
Posted in Debian, debimg, Ubuntu

Gustavo Noronha Silva: WebKitGTK+ 1.1.1 released

A new version of WebKit s GTK+ port is here, as also announced by Xan! Before I start listing the new features and fixes, let me give you a download link =). For this version we have changed the binary interface slightly, which requires a soversion bump, so rebuilding applications is in order. The API is still stable, though. Another major change worthy of note is that we have made libsoup the only HTTP backend available for WebKitGTK+, removing the CURL related code from our port (the CURL backend remains in the tree, though, as it is used by other ports). This should simplify implementation and allows us to expose Soup objects in the API, reducing the amount of wrapping code that is necessary. We are already exposing the SoupSession we use internally, providing yet more power and flexibility to applications using our API. In this release we finally get to see the official debut of the Web Inspector in the GTK+ port. Can t wait to see releases of our dear browsers featuring the inspector =). Numerous improvements to hading policy decisions regarding navigations and window creation requests to the application have also come with this release. We worked hard on finding and fixing crashes for this release, but also numerous fixes for those pet peeves that bother us just a bit, but enough to add up got landed. There are more of those to kill, but things look promising. We are hoping to release again in two weeks, so expect more fixes soon. So, that s it. Grab the new version, test it, report bugs, and enjoy!

Frans Pop: The case of the self-perpetuating DNS errors

Ingredients: The last couple of days I've been plagued by some DNS errors that kept showing up in the logcheck mails for my home server which I was busy migrating from one box to another, doing an upgrade from etch/i386 to lenny/amd64 at the same time. So, plenty of stuff going on to confuse the issue. I kept getting the following messages every hour (anonymized):
named: connection refused resolving 'somedomain.org/NS/IN': xxx.yyy.zzz.nnn#53
named: connection refused resolving 'somedomain.org/NS/IN': xxx.yyy.zzz.mmm#53
named: connection refused resolving 'ns1.somedomain.org/AAAA/IN': xxx.yyy.zzz.mmm#53
named: connection refused resolving 'ns2.somedomain.org/AAAA/IN': xxx.yyy.zzz.mmm#53
named: connection refused resolving 'ns1.somedomain.org/AAAA/IN': xxx.yyy.zzz.nnn#53
named: connection refused resolving 'ns2.somedomain.org/AAAA/IN': xxx.yyy.zzz.nnn#53
The times were fairly regular: once just before the hour, most 2 minutes after. I fetch mail at around that time, but also at other times, so possible but unlikely. The 2 minutes after was the first real clue: some cron job maybe? After disabling logcheck the messages no longer appeared in the log. Enable it again, and they were back. Additional confusion was caused by the fact that the domain had "debian" in its name, but it was somewhere obscure. So why was logcheck causing a lookup for that domain? This did confuse me enough to waste some time looking for some silly weird (default) configuration problem in some package. Enter spamassassin. Apparently that was parsing the message body, recognized "somedomain.org" as a host name, and proceded to do a DNS lookup as validity check. So we have the following loop, started off by something causing an initial DNS lookup for the domain, which fails and gets logged: Duh. I remember struggling with probably the same problem a couple of years ago, but then it was a lot more severe: masses of repeating DNS errors for obscure domains. At that time I failed to get to the bottom of it and ended up just ignoring the errors by adding the following option in my bind9 configuration:
logging  
    category lame-servers   null;  ;
 ;
Anyway, now I just no longer pass logcheck mails through spamassassin. (Although filtering out these DNS errors in bind9 can be perfectly valid.)

Frans Pop: The case of the self-perpetuating DNS-errors

Ingredients: The last couple of days I've been plagued by some DNS errors that kept showing up in the logcheck mails for my home server which I was busy migrating from one box to another, doing an upgrade from etch/i386 to lenny/amd64 at the same time. So, plenty of stuff going on to confuse the issue. I kept getting the following messages every hour (anonymized):
named: connection refused resolving 'somedomain.org/NS/IN': xxx.yyy.zzz.nnn#53
named: connection refused resolving 'somedomain.org/NS/IN': xxx.yyy.zzz.mmm#53
named: connection refused resolving 'ns1.somedomain.org/AAAA/IN': xxx.yyy.zzz.mmm#53
named: connection refused resolving 'ns2.somedomain.org/AAAA/IN': xxx.yyy.zzz.mmm#53
named: connection refused resolving 'ns1.somedomain.org/AAAA/IN': xxx.yyy.zzz.nnn#53
named: connection refused resolving 'ns2.somedomain.org/AAAA/IN': xxx.yyy.zzz.nnn#53
The times were fairly regular: once just before the hour, most 2 minutes after. I fetch mail at around that time, but also at other times, so possible but unlikely. The 2 minutes after was the first real clue: some cron job maybe? After disabling logcheck the messages no longer appeared in the log. Enable it again, and they were back. Additional confusion was caused by the fact that the domain had "debian" in its name, but it was somewhere obscure. So why was logcheck causing a lookup for that domain? This did confuse me enough to waste some time looking for some silly weird (default) configuration problem in some package. Enter spamassassin. Apparently that was parsing the message body, recognized "somedomain.org" as a host name, and proceded to do a DNS lookup as validity check. So we have the following loop, started off by something causing an initial DNS lookup for the domain, which fails and gets logged: Duh. I remember struggling with probably the same problem a couple of years ago, but then it was a lot more severe: masses of repeating DNS errors for obscure domains. At that time I failed to get to the bottom of it and ended up just ignoring the errors by adding the following option in my bind9 configuration:
logging  
    category lame-servers   null;  ;
 ;
Anyway, now I just no longer pass logcheck mails through spamassassin. (Although filtering out these DNS errors in bind9 can be perfectly valid.)

28 February 2009

Russell Coker: Links February 2009

Michael Anissimov writes about the theft of computers from the Los Alamos nuclear weapons lab [1]. He suggests that this incident (and others like it) pose a great risk to out civilisation. He advocates donating towards The Lifeboat Foundation [2] to try and mitigate risks to humanity. They suggest pledging $1000 per year for 25 years. It s interesting to note that people in Pakistan pay $8 per month for net access that better by most objective metrics than that which most people in first world can get [3]. It seems that we need to remove the cartel for the local loop to get good net access, either deregulate it entirely or make it owned by the local government who are more directly responsive to the residents. Bruce Schneier wrote a post about a proposed US law to force all mobile phones with cameras to make a click sound when taking a picture [4]. The law is largely irrelevant, as it s been law in Japan for a while most phones are already designed in that way. One interesting comment from MarkH was: But if congress REALLY wishes to benefit the public, I suggest that all guns in the U.S. be required, before each discharge, to make loud sounds (with appropriate time sequencing) simulating the flintlock technology that was common at the beginning of U.S. history, including cocking, use of the ramrod, etc. This would give fair warning of an impending discharge, and would limit firing rates to a few per minute. ROFL Brief review of a Google Android phone vs an iPhone [5]. The Android G1 is now on sale in Australia! [6]. LWN has an article about the panel discussion at the LCA Security Mini-conf [7]. Jonathan Corbet has quoted me quite a bit in the article, thanks Jonathan! Peter Ward gave an interesting TED talk about Hydrogen Sulphide and mass extinctions [8]. The best available evidence is that one of the worst extinctions was caused by H2S in the atmosphere which was produced by bacteria. The bacteria in question like a large amount of CO2 in the atmosphere. It s yet another reason for reducing the CO2 production. Michael Anissimov has written a good article summarising some of the dangers of space exploration [9], he suggests colonising the sea, deserts, and Antartica first (all of which are much easier and safer). Until we gain the ability to create huge (miles wide or larger) air bubbles in space enclosed by rapidly self-healing transparent membranes, it will be cramped and overwhelmingly boring. You ll spend even more time on the Internet up there than down here, and your connection will be slow . A confined space and slow net access, that s like being on a plane.

27 February 2009

Jordi Mallach: natura upgraded to lenny

natura.oskuro.net, the home server which still serves this blog, has been suffering hardware problems for some weeks. Apparently the hard drive is failing intermittently, so every now the kernel starts spewing out noisy errors about its main disk dying. If I notice this quickly, it can be rebooted and that normally fixes it for a few more days. But if I don't, it'll end up giving nasty bus errors which will make remote logins a challenge. Most processes still work, but the filesystem appears to be gone. It's easy to know what's going on if you visit the blog's url and get some 404, and in that case I can only phone my father and tell him to press the reset button (I've tried sysrqd, but I need to open the port in the router and haven't had chance to do that yet). So it was time to do something about it, and the other day I installed a dirty 40GB drive on the second IDE controller, in case I could find the time to do somethng about it. Being with an endless pharyngitis that doesn't seem to get cured entirely, I've had some time today to look at it. This evening, I was about to transfer all the system to the new disk (it's half the size as the broken one, and probably slower, but it hopefully has no bad sectors), but I decided to upgrade the system first. natura was first installed in late 1997 or at the beginning of 1998, using the Debian bo install media on a Pentium 150MHz, and has gone through seven dist-upgrades which, as far as I can remember, have always worked out without major problems. The upgrade to lenny hasn't been an exception. The server has gradually lost many of the services it once hosted, so there aren't too many services to take care of anymore. All the mail services I setup for my father ended up being deprecated as they started to get used to Hotmail, GMail and so on, and the frequent hardware crashes made me switch them to the Linksys based DHCP server. In the end, the problems I saw after the upgrade were very similar to what I faced when I upgraded to etch: Such an ancient install will clearly have old, obsolete packages. I installed apt-show-versions to find out what didn't match my package sources. I found I had every single version of cpp, gcc and g++ from 2.95 to 4.3, and a myriad of obsolete libs. But there were also real gems:
defrag 0.73pjm1-7 installed: No available version in archive
figlet 2.2.1-3 installed: No available version in archive
ipmasqadm 0.4.2-2 installed: No available version in archive
isapnptools 1.26-5 installed: No available version in archive
ms-sys 2.1.0-1 installed: No available version in archive
queso 0.980922b-3 installed: No available version in archive
update 2.11-4 installed: No available version in archive
Spaniards will remember queso because it was written by Jordi Murg and became a classic tool to find out what OS was running on a remote host. update was apparently needed to flush your filesystems prior to Linux 2.2.8, and defrag is obvious, although leaves me wondering why it was needed at the time. With the upgrade done successfully, next step is trying to get the system transfered to the spare hard drive. For this, I first partitioned it creating a primary partition using up more or less half of the available space, and setup a LVM volume, leaving some free PE's in the volume group just in case I want to do snapshots in the future, and formatted it using ext3. I then transfered the system to the new disk and now face the boot challenge. I haven't created a boot partition and that should be a double problem: the BIOS is buggy and will only boot from the first 1024 cylinders, and my root is on LVM and GRUB legacy might not like it (but I'm not sure). However, I've become a big fan of GRUB2, and know I will be able to boot no matter what my BIOS thinks of my disks and regardless the complex root partition setup I throw at it. The plan is to install GRUB onto the new drive's MBR, and set it up using the ata module, which should allow to ignore what the BIOS says, and read beyond cylinder 1024 or even boot from CD-ROM. However, this isn't a setup I haven't tried before, and a single failure will result in me taking a train to fix it on-site. So, GRUB experts out there, any suggestions? Of course, for now I guess I can install GRUB in the current drive's MBR and make it boot the old kernel using the new system as root, but that's dirty and would just postpone the problem.

Daniel Kahn Gillmor: redundant DHCP service for a sprawling LAN?

I'm supporting a medium-sized (~70 regular clients and a half-dozen servers) LAN. It's a single logical ethernet segment, but it's built as a tree of cascaded switches. DHCP service is provided by a single host running ISC's DHCPD (via dhcp3-server). DHCP itself is one of the single points of failure in the network layout. i'd really like to make this DHCP server redundant (so that i can take that host down for service if needed and leave the rest of the network intact). However, reading dhcpd.conf(5) makes me pretty worried that the failover stuff is not well-tested or widely deployed. I've read Paul Heinlein's Failover with ISC DHCP, which makes it look not unreasonable, but i was wondering if people have other preferred mechanisms for providing DHCP redundancy. Do you have failover DHCP set up for any LAN that you manage? If so, what do you use? Are there any gotchas to watch out for? I'm also concerned about the security implications. On a network that's not using IPSEC, i don't see any mechanism for the two DHCP servers to properly mutually authenticate. Is it really just by IP address? Could someone spoofing the IP address of one host corrupt the state of the other DHCP server? (i'm less concerned about them keeping network traffic private, since most of what they communicate is likely to go out in the clear on the wire anyway). Am i missing some clever authentication technique? From a security point of view, i understand that there are more severe security problems with DHCP itself, of course (the protocol requires that the client trust the (unauthenticated) server), but that doesn't seem likes a good reason to introduce an opportunity to compromise any given server directly. Your thoughts on DHCP redundancy?Tags: dhcp, failover, redundancy

MJ Ray: New #ukgovOSS Action Plan

Earlier this week, Tom Watson, Cabinet Office Parliamentary Secretary, published the Open Source, Open Standards and Re Use: Government Action Plan. It s had a pretty mixed reaction, with mild scepticism (niq s soapbox: Is gov.uk going open-source?) being the average reaction from what I ve read. I particularly liked the kind offer by Bristol Wireless to debianise Tom Watson s laptop. I think commentators are bang-on that the procurement process needs to change and that this sounds positive. I ll love it if I m wrong, but this looks like the lip service as usual which I ve seen in the last 10 years working on FOSS in the UK. I want to see the action that comes from this plan! When government actually starts buying FOSS from typical FOSS service providers and not just the IBMs of this world, then I ll believe it. My suspicion is re-ignited by some of the activites around this action plan. For example, does anyone know why the Cabinet Office didn t select FOSS to run their special public FOSS Aggregation page? (Actually, what s the best FOSS tag aggregator web service out there? I know we can set them up in Wordpress widgets, but what hosted services are there?) I m also a bit bemused that their page requires users to accept cookies until they expire, yet its privacy policy explicitly says You may suppress cookies after your visit or configure your Internet browser to prevent them. Yes, I can prevent them, but then it does nothing useful! (Based on a comment I made at the OSS Watch team blog and discussions with a few user groups.)

26 February 2009

Theodore Ts'o: Fast ext4 fsck times, revisited

Last night I managed to finish up a rather satisfying improvement to ext4 s inode and block allocators. The ext4 s original allocator was actually a bit more simple-minded than ext3 s, in that it didn t implement the Orlov algorithm to spread out top-level directories for better filesystem aging. It also was buggy in certain ways, where it would return ENOSPC even when there were still plenty of inodes in the file system. So I had been working on extending ext3 s original Orlov allocator so it would work well with ext4. While I was at it, it occurred to me that one of the tricks I could play with ext4 s flex groups (which are higher-order collection of block groups), was to bias the block allocation algorithms such that the first block group in a flexgroup would be preferred for use by directories, and biased against data blocks for regular files. This meant that directory blocks would get clustered together, which cut a third off the time needed for e2fsck pass2:
Comparison of e2fsck times on an 32GB partition
Pass ext4 old allocator ext4 new allocator
time (s) I/O time (s) I/O
real user system MB read MB/s real user system MB read MB/s
1 6.69 4.06 0.90 82 12.25 6.70 3.63 1.58 82 12.23
2 13.34 2.30 3.78 133 9.97 4.24 1.27 2.46 133 31.36
3 0.02 0.01 0 1 63.85 0.01 0.01 0.01 1 82.69
4 0.28 0.27 0 0 0 0.23 0.22 0 0 0
5 2.60 2.31 0.03 1 0.38 2.42 2.15 0.07 1 0.41
Total 23.06 9.03 4.74 216 9.37 13.78 7.33 4.19 216 15.68

As you may recall from my previous observations on this blog, although we hadn t been explicitly engineering for this, a file system consistency check on an ext4 file system tends to be a factor of 6-8 faster than the e2fsck times on an equivalent ext3 file system, mainly due to the elimination of indirect blocks and the uninit_bg feature reducing the amount of disk reads necessary in e2fsck s pass 1. However, the ext4 layout optimizations didn t do much for e2fsck s pass 2. Well, the optimization of the block and inode allocators is complementary to the original ext4 fsck improvements, since it focuses on what we hadn t optimized the first time around: e2fsck pass 2 times have been cut by a third, and the overall fsck time has been cut by 40%. Not too shabby! Of course, we need to do more testing to make sure we haven t caused other file system benchmarks to degrade, although I m cautiously optimistic that this will end up being a net win. I suspect that some benchmarks will go up by a little, and others will go down a little, depending on how heavily the benchmark exercises directory operations versus sequential I/O patterns. If people want to test this new allocator, it is in the ext4 patch queue. If all goes well, I will hopefully be pushing it to Linus after 2.6.29 is released, at the next merge window.

horizontal separator For comparison s sake, here is a comparison of the fsck time of the same collection of files and directories, comparing ext3 and the original ext4 block and inode allocator. The file system in question is a 32GB install of Ubuntu Jaunty, with a personal home directory, a rather large Maildir directory, some linux kernel trees, and an e2fsprogs tree. It s basically the emergency environment I set up on my Netbook at FOSDEM. In all cases the file systems were freshly copied from the original root directory using the command rsync -axH / /mnt. It s actually a bit surprising to me that ext3 s pass 2 e2fsck times was that much better than e2fsck time under the old ext4 allocator. My previous experience has shown that the two are normally about the same, with a write throughput of around 9-10 MB/s on for e2fsck s pass 2 for both ext3 file systems and ext4 file systems with the original inode/block allocators. Hence, I would have expected ext3 s pass2 time to have been 12-13 seconds, and not 6. I m not sure how that happened, unless it was the luck of draw in terms of how things ended up getting allocated on disk. So I m not too sure what happened there, but overall things look quite good for ext4 and fsck times!
Comparison of e2fsck times on an 32GB partition
Pass ext3 ext4 old allocator
time (s) I/O time (s) I/O
real user system MB read MB/s real user system MB read MB/s
1 108.40 13.74 11.53 583 5.38 6.69 4.06 0.90 82 12.25
2 5.91 1.74 2.56 133 22.51 13.34 2.30 3.78 133 9.97
3 0.03 0.01 0 1 31.21 0.02 0.01 0 1 63.85
4 0.28 0.27 0 0 0 0.28 0.27 0 0 0
5 3.17 0.92 0.13 2 0.63 2.60 2.31 0.03 1 0.38
Total 118.15 16.75 14.25 718 6.08 23.06 9.03 4.74 216 9.37
Vital Statistics of the 32GB partition
312214 inodes used (14.89%)
263 non-contiguous files (0.1%)
198 non-contiguous directories (0.1%)
# of inodes with ind/dind/tind blocks: 0/0/0
Extent depth histogram: 292698/40
4388697 blocks used (52.32%)
0 bad blocks
1 large file
263549 regular files
28022 directories
5 character device files
1 block device file
5 fifos
615 links
20618 symbolic links (19450 fast symbolic links)
5 sockets
312820 files
Related posts (automatically generated):

  1. Fast ext4 fsck times This wasn t one of the things we were explicitly engineering...
  2. Wanted: Incremental Backup Solutions that Use a Database Dear Lazyweb, I m looking for recommendations for Open Source backup...
  3. Ext4 is now the primary filesystem on my laptop Over the weekend, I converted my laptop to use the...

Theodore Ts'o: Fast ext4 fsck times, revisited

Last night I managed to finish up a rather satisfying improvement to ext4 s inode and block allocators. The ext4 s original allocator was actually a bit more simple-minded than ext3 s, in that it didn t implement the Orlov algorithm to spread out top-level directories for better filesystem aging. It also was buggy in certain ways, where it would return ENOSPC even when there were still plenty of inodes in the file system. So I had been working on extending ext3 s original Orlov allocator so it would work well with ext4. While I was at it, it occurred to me that one of the tricks I could play with ext4 s flex groups (which are higher-order collection of block groups), was to bias the block allocation algorithms such that the first block group in a flexgroup would be preferred for use by directories, and biased against data blocks for regular files. This meant that directory blocks would get clustered together, which cut a third off the time needed for e2fsck pass2:
Comparison of e2fsck times on an 32GB partition
Pass ext4 old allocator ext4 new allocator
time (s) I/O time (s) I/O
real user system MB read MB/s real user system MB read MB/s
1 6.69 4.06 0.90 82 12.25 6.70 3.63 1.58 82 12.23
2 13.34 2.30 3.78 133 9.97 4.24 1.27 2.46 133 31.36
3 0.02 0.01 0 1 63.85 0.01 0.01 0.01 1 82.69
4 0.28 0.27 0 0 0 0.23 0.22 0 0 0
5 2.60 2.31 0.03 1 0.38 2.42 2.15 0.07 1 0.41
Total 23.06 9.03 4.74 216 9.37 13.78 7.33 4.19 216 15.68

As you may recall from my previous observations on this blog, although we hadn t been explicitly engineering for this, a file system consistency check on an ext4 file system tends to be a factor of 6-8 faster than the e2fsck times on an equivalent ext3 file system, mainly due to the elimination of indirect blocks and the uninit_bg feature reducing the amount of disk reads necessary in e2fsck s pass 1. However, the ext4 layout optimizations didn t do much for e2fsck s pass 2. Well, the optimization of the block and inode allocators is complementary to the original ext4 fsck improvements, since it focuses on what we hadn t optimized the first time around: e2fsck pass 2 times have been cut by a third, and the overall fsck time has been cut by 40%. Not too shabby! Of course, we need to do more testing to make sure we haven t caused other file system benchmarks to degrade, although I m cautiously optimistic that this will end up being a net win. I suspect that some benchmarks will go up by a little, and others will go down a little, depending on how heavily the benchmark exercises directory operations versus sequential I/O patterns. If people want to test this new allocator, it is in the ext4 patch queue. If all goes well, I will hopefully be pushing it to Linus after 2.6.29 is released, at the next merge window.

horizontal separator For comparison s sake, here is a comparison of the fsck time of the same collection of files and directories, comparing ext3 and the original ext4 block and inode allocator. The file system in question is a 32GB install of Ubuntu Jaunty, with a personal home directory, a rather large Maildir directory, some linux kernel trees, and an e2fsprogs tree. It s basically the emergency environment I set up on my Netbook at FOSDEM. In all cases the file systems were freshly copied from the original root directory using the command rsync -axH / /mnt. It s actually a bit surprising to me that ext3 s pass 2 e2fsck times was that much better than e2fsck time under the old ext4 allocator. My previous experience has shown that the two are normally about the same, with a write throughput of around 9-10 MB/s on for e2fsck s pass 2 for both ext3 file systems and ext4 file systems with the original inode/block allocators. Hence, I would have expected ext3 s pass2 time to have been 12-13 seconds, and not 6. I m not sure how that happened, unless it was the luck of draw in terms of how things ended up getting allocated on disk. So I m not too sure what happened there, but overall things look quite good for ext4 and fsck times!
Comparison of e2fsck times on an 32GB partition
Pass ext3 ext4 old allocator
time (s) I/O time (s) I/O
real user system MB read MB/s real user system MB read MB/s
1 108.40 13.74 11.53 583 5.38 6.69 4.06 0.90 82 12.25
2 5.91 1.74 2.56 133 22.51 13.34 2.30 3.78 133 9.97
3 0.03 0.01 0 1 31.21 0.02 0.01 0 1 63.85
4 0.28 0.27 0 0 0 0.28 0.27 0 0 0
5 3.17 0.92 0.13 2 0.63 2.60 2.31 0.03 1 0.38
Total 118.15 16.75 14.25 718 6.08 23.06 9.03 4.74 216 9.37
Vital Statistics of the 32GB partition
312214 inodes used (14.89%)
263 non-contiguous files (0.1%)
198 non-contiguous directories (0.1%)
# of inodes with ind/dind/tind blocks: 0/0/0
Extent depth histogram: 292698/40
4388697 blocks used (52.32%)
0 bad blocks
1 large file
263549 regular files
28022 directories
5 character device files
1 block device file
5 fifos
615 links
20618 symbolic links (19450 fast symbolic links)
5 sockets
312820 files
Related posts (automatically generated):

  1. Fast ext4 fsck times This wasn t one of the things we were explicitly engineering...
  2. Wanted: Incremental Backup Solutions that Use a Database Dear Lazyweb, I m looking for recommendations for Open Source backup...
  3. Ext4 is now the primary filesystem on my laptop Over the weekend, I converted my laptop to use the...

Adrian von Bidder: Tech bits

Two small tricks that I feel should be circulated more widely, because Google only disclosed them to me after a few false starts: To figure out which processes are writing to the disk, I eventually found /proc/sys/vm/block_dump (see also chapter 5 of the Laptop Mode FAQ) which does exactly what I was hoping to find: it shows down to the level of process and file where disk writes are coming from. (Turns out, that kded and PowerDevil are currently appending to the .xsession-errors file regularly, keeping the disk busy on my new toy. Unlimited scrollback in konsole was the other culprit, but that one is switched off easily.) Since I want to start backup on my netbook when it comes online at home, I figured the DHCP server was the likely place to trigger this. But the execute feature to start hook scripts on the DHCP server (see the dhcp-eval man page) was only added quite recently, so google first showed me a huge load of discussions involving tail on syslog and parsing its output. (I also found the simple event correlator which might be useful where run command features are not available.)

Ian Wienand: rdtsc - now even less useful!

An interesting extract from the latest IA32 SDM (18.20.5)
The TSC, IA32_MPERF, and IA32_FIXED_CTR2 operate at the same, maximum-resolved frequency of the platform, which is equal to the product of scalable bus frequency and maximum resolved bus ratio.
For processors based on Intel Core microarchitecture, the scalable bus frequency is encoded in the bit field MSR_FSB_FREQ[2:0] at (0CDH), see Appendix B, "Model-Specific Registers (MSRs)". The maximum resolved bus ratio can be read from the following bit field:
  • If XE operation is disabled, the maximum resolved bus ratio can be read in MSR_PLATFORM_ID[12:8]. It corresponds to the maximum qualified frequency.
  • IF XE operation is enabled, the maximum resolved bus ratio is given in MSR_PERF_STAT[44:40], it corresponds to the maximum XE operation frequency configured by BIOS.
In summary, TSC increment = (scalable bus frequency) * (maximum resolved bus ratio). This implies the TSC is incrementing based on some external bus source (any hardware engineers explain what happened for Core here?), and is a departure from simply assuming that the TSC increments once for each CPU cycle. The interesting bit is that if XE operation is disabled, the bus ratio is assumed to be the maximum qualified frequency. This seems to mean that if you overclock your CPU and your processor is running at higher than the qualified frequency, attempts to measure the CPU speed by counting TSC ticks over a given time may yeild the wrong results (well, will yield the rated result; i.e. the speed of the processor you bought out of the box). While interesting, this divergence is probably has little practical implications because using the TSC for benchmarking is already fraught with danger. You have to be super careful to make sure the compiler and processor don't reschedule things around you and handle other architectural nuances. If you need this level of information, you're much better using the right tools to get it (my favourite is perfmon2).

25 February 2009

Theodore Ts'o: Binary-only device drivers for Linux and the supportability matrix of doom

I came across the following from the ext3-users mailing list. The poor user was stuck on a never-updated RHEL 3 production server and running into kernel panic problems. He was advised to try updating to the latest kernel rpm from Red Hat, but he didn t feel he could do that. In his words:
I m caught between a rock and a hard place due to the EMC PowerPath binary only kernel crack. Which makes it painful to both me and my customers to regularly upgrade the kernel. Not to mention the EMC supportability matrix of doom.
That pretty much sums it all up right there. The good news is that I ve been told that dm-multipath is almost at the point where it has enough functionality to replace PowerPath. Of course, that version isn t yet shipping in distributions, and I m sure it needs more testing, but it ll be good when enterprise users who need this functionality can move to a 100% fully open source storage stack. About the only thing left to do is to work in a mention of the Frying Pan of Doom and the recipe for Quick After-Battle Triple Chocolate Cake into the mix. :-) Related posts (automatically generated):
  1. Tip o the hat, wag o the finger Linux power savings for laptop users It s interesting to see how far, and yet how much...
  2. How active are your local Linux User s Groups? At the Linux Foundation, I recently had been brainstorming with...

Next.

Previous.