Search Results: "ana"

25 May 2010

Matt Zimmerman: The behavioral economics of free software

People who use and promote free software cite various reasons for their choice, but do those reasons tell the whole story? If, as a community, we want free software to continue to grow in popularity, especially in the mainstream, we should understand better the true reasons for choosing it especially our own. Some believe that it offers higher quality, that the availability of source code results in a better product with higher reliability. Although it s difficult to do an apples-to-apples comparison of software, there are certainly instances where free software components have been judged superior to their proprietary counterparts. I m not aware of any comprehensive analysis of the general case, though, and there is plenty of anecdotal evidence on both sides of the debate. Others prefer it for humanitarian reasons, because it s better for society or brings us closer to the world we want to live in. These are more difficult to analyze objectively, as they are closely linked to the individual, their circumstances and their belief system. For developers, a popular reason is the possibility of modifying the software to suit their needs, as enshrined in the Free Software Foundation s freedom 1. This is reasonable enough, though the practical value of this opportunity will vary greatly depending on the software and circumstances. The list goes on: cost savings, educational benefits, universal availability, social rewards, etc. The wealth of evidence of cognitive bias indicates that we should not take these preferences at face value. Not only are human choices seldom rational, they are rarely well understood even by the human themselves. When asked to explain our preferences, we often have a ready answer indeed, we may never run out of reasons but they may not withstand analysis. We have many different ways of fooling ourselves with regard to our own past decisions and held beliefs, as well as those of others. Behavioral economics explores the way in which our irrational behavior affects economies, and the results are curious and subtle. For example, the riddle of experience versus memory (TED video), or the several examples in The Marketplace of Perception (Harvard Magazine article). I think it would be illuminating to examine free software through this lens, and consider that the vagaries of human perception may have a very strong influence on our choices. Some questions for thought: If you re aware of any studies along these lines, I would be interested to read about them.

Russell Coker: Links May 2010

AdRevenge is an interesting concept to pay for Google Adsense adverts about how companies suck [1]. If a suitably large group of people pay to warn you about a company then it s a good signal that the company is actually doing the wrong thing. A guest post by Mili on Charles Stross blog has an interesting analysis of the economcs of Intellectual Property and concludes that content is a public good [2]. New Age Terrorists Develop Homeopathic Bomb [3], an amusing satire of medical fraud and security theatre. The sit has a lot of other good satire too. Mark Shuttleworth wrote an interesting post about new window management changes that will soon go into Ubuntu [4]. He points out that the bottom status bar in applications is a throw-back to Windows 3.1 and notes that a large part of the incentive for removing it (and using the title-bar for the status) is the work on the Netbook version of Ubuntu. This is really ironic given that the resolution of current Netbooks is quite similar to that of desktop systems that were current when Windows 3.1 came out. Omar Ahmad gave an insightful TED talk about the benefit of using a pen and paper to send a letter to a politician [5]. Sebastian Wernicke gave an amusing and informative TED talk about how to give a good TED talk [6]. His talk gives some useful ideas for public speaking that are worth considering. Catherine Mohr gave a brief and interesting TED talk about how to build an energy efficient house with low embodied energy [7]. Her blog at www.301monroe.com has the details. Stephen Wolfram (of Mathematica fame) gave an interesting TED talk [8]. He covers a lot of interesting things that can be done with computers, primarily based on the Wolfram Alpha [9] platform which allows natural language queries of a large data set. He also talks about the search for a Theory of Everything. Esther Duflo gave an interesting TED talk about using social experiments to fight poverty [10]. She describes how scientific tests have been used to determine the effectiveness of various ways of preventing disease and encouraging education in developing countries. One example of the effectiveness of such research is the DeWormTheWorld.org project which was founded after it was discovered that treating intestinal worms was the most cost effective way of getting African children to spend longer at school. David L. Rosenhan wrote an interesting research paper On Being Sane In Insane Places about pseudo-patients admitted to psychiatric hospitals [11]. It seems that psychiatric staff were totally unable to recognise a sane person who was admitted even though other patients could do so. It also documents how psychiatric patients were treated as sub-human. One would hope that things had improved since 1973, but it seems likely that many modern psychiatric hospitals are as bad as was typical in 1973. It s also worth considering the issue of the treatment in society of people who have been diagnosed with a mental illness, it seems likely that the way people are treated in the community would have similar bad results to that which was documented for treatment in psychiatric hospitals even the sanest people will act strangely if treated in an insane manner! Also it seems to me that there could be potential for using a panel of patients assembled via the Delphi Method as part of the psychiatric assessment process as it has been demonstrated that patients can sometimes assess other patients more accurately than psychiatrists! Simon Sinek gave an inspiring TED talk about how great leaders inspire action [12]. Of course the ideas he describes don t just apply to great leaders, they should apply to ordinary people who just want to convince others to adopt their ideas. Stephen Collins write a good article summarising the main reasons why the proposed great firewall of Australia is a bad idea [13]. Lenore Skenazy who is famous for letting her 9yo son catch the metro alone during broad daylight on a pre-planned route home has created a web site about Free Range Kids [14]. She seems to be starting a movement to oppose Helicopter Parenting and has already written a book about her ideas for parenting. The incidence of crime has been steadily increasing, as has the ability of the police to apprehend criminals and recover abducted children. There s no reason for children to be prevented from doing most of the things that children did when I was young!

24 May 2010

Julien Danjou: Making startup-notification XCB native

I'm trying to work on XCB this week. And today I've started to accomplish the second step of a long term goal: making an X11 only library using XCB as its primary interface instead of Xlib. Last year, I had extended the API of startup-notification to support XCB as a back-end. This had been made possible by factorizing some code, duplicating the X11 code and translating it into equivalent XCB. Today, I've accomplished the second step, being dropping the Xlib code inside startup-notification to keep only the XCB one. For this, I used the x11-xcb library, which is available when Xlib is compiled with XCB as its transport, which is nowadays the standard. This library provides the function XGetXCBConnection, which can convert a Display pointer to a xcb_connection_t pointer. Consequently, it's now possible to write and execute XCB based code and being compatible with Xlib. I've made some benchmark of my work for the occasion, in order to measure what the gain is. The first table described 1000 launches of a fake application (a modified version of the startup-notification test suite actually). The X server is local (the latency is very minimal then). The gain is computed between the same back-end type for the total time. Full XCB is the "version" I'm working on.
Version - Back-end User time (seconds) Kernel time (seconds) Total time (seconds) Gain
0.10 - libx11 3.20 7.42 12.989 -
0.10 - libxcb 2.76 7.36 12.414 -
Full XCB - libx11 2.74 7.50 12.380 4.6 %
Full XCB - libxcb 2.72 7.16 12.037 3.0 %
The user time and kernel time are provided but are not really interesting. XCB does not offers a big gain in CPU execution time, but is more about latency. Anyhow, there's always a gain with XCB. This second table describe the same test but running only 100 times over a slow network.
Version - Back-end Total time (seconds) Gain
0.10 - libx11 76 -
0.10 - libxcb 35 -
Full XCB - libx11 72 5.2 %
Full XCB - libxcb 33 5.7%
The gain is relatively small, about 5 %. But anyhow, there's still a gain. Note that the difference between the execution time of the same test written in XCB and Xlib is just huge. I've tried to optimize the Xlib test, but I did not manage to win more seconds. In conclusion, considering that startup-notification is only used when an application launches another application, the perceivable gain might be even smaller. But anyhow, I think it's worth it.

Asheesh Laroia: Kat and Asheesh, on identity

Six months ago, I was talking with Kat. We were talking about talking. On imperfection Kat wrote:
<mindspillage> I think I have to be very very comfortable around someone to be able to be imperfect around them.
<mindspillage> (at least, without feeling horribly embarrassed about it)
<mindspillage> More so if what I'm doing is part of my identity.
It's safe to be bad at dancing, she explained; she doesn't consider herself a good dancer, so nothing's at risk. On flames I had recently written about diversity in free software. Kat showed me a piece she had written, but not yet published, on a similar topic. I thought she should simply publish the piece as-is. Instead, she worried:
<mindspillage> I feel like I have a hard time getting across what I think without coming across as antagonistic.
I've felt the same way. Years ago, I told my friend Venkatesh that had sent a flame to a mailing list we're both on. He retorted that my flames lack flame. So then I thought about why I might feel I've written a flame, even when no one else felt that way. I wrote to Kat:
<paulproteus> Expressing oneself is a frustrating experience.
<paulproteus> It may seem like you're taking this out on other people.
<paulproteus> In fact, you're just frustrated.
<paulproteus> And fighting (successfully) your own urges to just be quiet.
<paulproteus> So at the end you'll feel like you fought a battle, and that seems like you wrote something that others would feel is antagonistic.
Maybe for Kat's writing and my "flames", there was some sort of antagonistic process in which we fought ourselves. That fight doesn't have a lot to do with the resulting text, so it's invisible to the reader. I think this process might leave us vulnerable in another way: if our urges to stay quiet come from a sense of isolation, and we manage to stay quiet about that feeling, no one will sympathize with us. We'll appear to be healthy, active participants in a conversation where we express ourselves. Other people with a similar "process" for self-expression won't get a chance to empathize. (This is why I'm interested in putting together a Debian for Shy People caucus. I hope my Debconf proposal for a Birds of a Feather session is accepted!) On finding a way out We concluded on a happy note:
<mindspillage> I haven't been answering Wikimedia mail for a while. Then I figured out that I don't have to use my real name, so I don't have to answer as someone with responsibility, I can just be some random volunteer.
<mindspillage> Most of it is silly and trivial. But sometimes I am really able to address someone's concern or change someone's mind, and I forget how good that feels.
<mindspillage> (There are some real jerks too.)
<mindspillage> I got someone who was being snarky to apologize for being so rude. That was kind of awesome. Sometimes it doesn't take very much to make me happy.
P.S. A note from the archives Apparently, for me, speaking French is exempt from the above restrictions.

23 May 2010

Marco T&uacute;lio Gontijo e Silva: Playing with criterion

As a part of my Google Summer of Code project, I should take a look at criterion, a benchmark library for Haskell. As I d have to use it, and it seems to be a useful library for a lot of people, I packaged it to Debian, with all its dependencies. The haskell-criterion package is waiting on the NEW queue. Ok, so now I had to test it with something. I came up with a test related to my reading about the Haskell execution model. I noticed that I never have played with multi-threaded Haskell code to achieve better performance, but only to make things that should be in parallel work. So I thought this was a good oportunity to try both. I wrote this code: import Control.Applicative ((<$>), (<*>))
import Control.Concurrent.MVar (newEmptyMVar, putMVar, takeMVar)
import Control.Exception (evaluate)
import Criterion.Main (Benchmark, bench, bgroup, defaultMain, whnf, whnfIO)
import GHC.Conc (forkIO, par)
import System.Environment (getArgs) value :: Int
value = 32 threadsL :: [Int]
threadsL = [1, 2, 3, 4, 8, 16, 32, 64] main :: IO ()
main
= defaultMain
[bgroup "fib" $ [bench "fib" $ whnf fib value]
, bgroup "pfib" $ map pbench threadsL
, bgroup "ifib" $ map ibench threadsL] pbench :: Int -> Benchmark
pbench i = bench (show i) $ whnf (pfib i) value ibench :: Int -> Benchmark
ibench i = bench (show i) $ whnfIO $ ifib i value fib :: Int -> Int
fib n
n < 2 = n
otherwise = fib (n 1) + fib (n 2) pfib :: Int -> Int -> Int
pfib threads n
n < 2 = n
threads < 2 = fib n
otherwise = par n1 $ seq n2 $ n1 + n2
where
n1 = pfib (threads 1) $ n 1
n2 = fib $ n 2 ifib :: Int -> Int -> IO Int
ifib threads n
n < 2 = evaluate n
threads < 2 = evaluate $ fib n
otherwise
= do
f1 <- newEmptyMVar
f2 <- newEmptyMVar
forkIO $ ifib (threads 1) (n 1) >>= putMVar f1
(+) <$> evaluate (fib $ n 2) <*> takeMVar f1 My point is to benchmark the na ve implementation of the Fibonacci function. I ve done three implementations:
fib
which is the simple sequential algorithm
pfib
which call par threads times
ifib
which call forkIO trheads times
I have chosen the value to be found to 32, because it took long enought to make the algorithms show a difference, and short enough to allow me to wait for the benchmarks. I built with:
ghc --make -threaded fib
And runned with:
./fib --summary=fib.csv +RTS -N
The results were surprising for me:
Name,Mean,MeanLB,MeanUB,Stddev,StddevLB,StddevUB
"fib/fib",1.7197746428132055,1.5104790505051613,2.031735854971409,1.2921598378638277,0.9514102096387,1.7188536150257019
"pfib/1",1.246479478704929,1.1805571945786482,1.3496261318802836,0.41570319371618925,0.29446316107198395,0.5823241217769125
"pfib/2",0.709402781355381,0.6850755818963056,0.7553855475068096,0.1650893842889147,0.10136189180677138,0.26853312094492815
"pfib/3",0.6876571162819864,0.6694172366738321,0.7332831247925761,0.136836636420341,5.5142145935712775e-2,0.2581805596992922
"pfib/4",0.6940202649712561,0.6684220250725745,0.746035416948795,0.17779646229098522,9.15862482237111e-2,0.2804203635281818
"pfib/8",0.5887631162285805,0.5625207790017128,0.637939236986637,0.17967127569396815,0.10516397607491562,0.2680488710546616
"pfib/16",0.6578513725876809,0.6107277926087382,0.7372924216866497,0.3070809683902726,0.20679305873839168,0.44571891526087154
"pfib/32",0.8900135167717932,0.8123333438515664,0.9942556460976597,0.45942103747727,0.36818132854060703,0.6233813540278427
"pfib/64",0.6894888337731359,0.6386897596001626,0.7766118057847021,0.33329115700425754,0.22490082647959764,0.5323965317477072
"ifib/1",1.3290104445099833,1.2501559790253634,1.4700443919777875,0.5277373265779313,0.35208278898795436,0.9179652474421286
"ifib/2",0.7626163347840308,0.7239342554688452,0.8381309326767921,0.26785654248385327,0.1679981089775395,0.44853454282169086
"ifib/3",0.7440206035256386,0.6907905062317847,0.8396386941552162,0.3549675945489581,0.22865300516283724,0.536883746220313
"ifib/4",0.6503480085015301,0.6130640967965126,0.711405030119419,0.239522235814317,0.1712396398224678,0.3616636557596486
"ifib/8",0.6300301631569865,0.6085795434594155,0.699028070795536,0.17776228649867923,6.103918021418795e-2,0.39508078831864085
"ifib/16",0.6735970553040505,0.6393461784005164,0.7405966480851172,0.2366561170051713,0.13725890735483465,0.38273830961617655
"ifib/32",0.6162510784745214,0.5983195599198344,0.6736035832047466,0.14678572822644564,5.335959472427259e-2,0.3231734735693349
"ifib/64",0.7217859562516212,0.6820346101403237,0.7857911285042766,0.2534368199920431,0.18073576275895306,0.37636526159654315
I m only analyzing the first column. How come pfib/1 and ifib/1, that is, pfib and ifib called with just one thread, got faster than fib/fib? All they do is calling fib! There s certainly something wrong here. So I reran the tests in a single user environment (recovery-mode on GRUB). And also learned that I should not trust blindly these results in my usual user environment. The new tests were also surprising:
Name,Mean,MeanLB,MeanUB,Stddev,StddevLB,StddevUB
"fib/fib",0.4979443445852824,0.4978961411169597,0.49802434593949996,3.1186229071682967e-4,2.1763919616793833e-4,4.8569259617552764e-4
"pfib/1",0.4980979338339395,0.4980578795126507,0.49816361099992496,2.58930038115918e-4,1.7011790805380493e-4,4.0161943492611696e-4
"pfib/2",0.30187882572923386,0.3018276229551859,0.3019332328489849,2.7088498930449747e-4,2.3482715228451473e-4,3.21989842698397e-4
"pfib/3",0.3025411692312786,0.3024852743795938,0.3026018276861736,2.975260476849551e-4,2.6907713057828055e-4,3.3200184242397705e-4
"pfib/4",0.3045588889769145,0.3024707928350993,0.31463312775407504,2.0236423610294995e-2,3.5108499279216634e-4,4.8255009076253054e-2
"pfib/8",0.27702674538408,0.27158569247041425,0.2846977105787821,3.2790225595837955e-2,2.5215205278321072e-2,4.6554023411818295e-2
"pfib/16",0.26909642369065967,0.2650135436705178,0.2758063927343913,2.615724515115467e-2,1.8039283932648264e-2,4.0956608339390285e-2
"pfib/32",0.2726816359213419,0.26952718407426557,0.27636309534822184,1.7444576031246224e-2,1.4227057669027803e-2,2.2935079362453085e-2
"pfib/64",0.28010295302186694,0.27646669537339885,0.28658743054185587,2.4301648337333875e-2,1.3360828345387364e-2,3.9546300072208655e-2
"ifib/1",0.4984497705153056,0.4984218493155071,0.4984962406805583,1.8040276986757106e-4,1.242720342516858e-4,2.870577387900989e-4
"ifib/2",0.3603615990332194,0.34868544012818997,0.3741170039824078,6.496311767153333e-2,5.652406802832432e-2,7.448312251646773e-2
"ifib/3",0.31676718384538366,0.3109451881102153,0.32481522709642136,3.4887028192202074e-2,2.744363202200484e-2,4.8060797483303504e-2
"ifib/4",0.31541500956330976,0.30635046393190096,0.32643843323503213,5.109215651574664e-2,4.339074296796736e-2,5.995395740457435e-2
"ifib/8",0.32055945069108693,0.3132960501364299,0.3302640953711101,4.2886292109838166e-2,3.422708481199234e-2,5.4196317284934535e-2
"ifib/16",0.32268204123292654,0.31607536703859057,0.33141186625276287,3.858016286486453e-2,3.0959817731033304e-2,4.801572113400926e-2
"ifib/32",0.32020341069017116,0.3151469627073833,0.32664997250352584,2.92266723352992e-2,2.3352577028246314e-2,3.5913110786596904e-2
"ifib/64",0.3183670273474284,0.3136345234564373,0.3248856058767864,2.834147907711714e-2,2.1803978149062524e-2,3.8088053144371074e-2
I didn t thought the improvement in performance on a single-user would be so dramatic. The execution of the program in a single-user environment used 41% of the time to run in my usual environment. About the comparative results, they were more close to what I d expect than the old ones. fib/fib, pfib/1 and ifib/1 had a very similar execution time. What surprised me was that I was expecting to have the best result in the benchmarks with 2 threads, since I ran the tests in a Core 2 Duo T5750 @ 2.00 GHz with 2 cores. But in pfib the execution time has reduced from 4 threads to 8, and in ifib, from 2 to 3. I can t think of where these improvements come from. Unfortunately the creation of charts is currently broken in GHC 6.12, so no graphics by now.

22 May 2010

Clint Adams: Cancelling bash, in command

There is an alternative to using bash, and that is zsh. If you want to defer running a command to the next line, you can invoke the push-line widget, bound by default (in the emacs keymap) to Ctrl-Q and ESC-q.

Marco d'Itri: Less widely known features of iproute

While iproute (AKA ip(8)) nowadays has become the ultimate Linux network configuration tool, it is also poorly documented: many features are not documented in the man page or even in the built-in help. With this post I would like to raise the attention to some of its more recent features which are not getting the attention they deserve. And remember: every time you use ifconfig(8), Cthulhu eats a kitten. Please, think of the kittens. VLANs management
ip link add link eth0 type vlan name eth0.2 id 2
ip link add link eth0 type vlan name myvlan2 id 2 loose_binding on
ip link add foo type vlan help
This replaces the obsolete vconfig(8) program and adds new features. The loose_binding flag stops the VLAN interface from tracking the line protocol status of the underlying device. Creation of dummy interfaces
ip link add mydummy type dummy
The only way to create more dummy interfaces after the dummy module has been loaded used to be loading it again with a different name, and they were all named dummyN. Since module-init-tools does not support anymore loading the same module multiple times, iproute fully replaced this method. Ethernet in GRE tunnels
ip link add mygretun type gretap remote 192.0.2.1
ip link add foo type gretap help
A practical way to remotely bridge two Ethernet networks. The IP MTU is reduced of the expected 20 (IP) + 4 (GRE) + 14 (Ethernet II) bytes. L2TPv3 static tunnels See Documentation/networking/l2tp.txt for details, this requires kernels >= 2.6.34.

Rog rio Brito: Changing Some Configuration from Defaults

Two of my most frequently used tools are, hands down, Emacs and bash. Having a pleasant configuration of one s toolbox is necessary for long-term productivity. However, newer versions of the programs (any programs) don t always have good, comfortable defaults. That is the case with Emacs 23 and bash 4. With Emacs 23, by default, the scratch buffer shows some text that, if you want to quickly enter text to be saved, has to be deleted. This can be tolerated for some invocations of the editor. But at some point, it gets on one s nerves. Luckily, Emacs is so fully customizable that this is not a problem, unless you have to hunt down the right knobs and you are an e-lisp illiterate. That is my case. After reading an admittedly small amount of documentation, some good lines that ought to be put into one s .emacs file are:
(setq inhibit-startup-echo-area-message "rbrito")
(setq initial-scratch-message nil); show an empty scratch buffer
(setq inhibit-startup-message t); remove splash screen
Another line that may make things more comfortable (especially if you, like me, use Emacs s dired as a filemanager to navigate your folders):
(defalias 'yes-or-no-p 'y-or-n-p)
But configuring Emacs is not always that hard. Seeing a change of behaviour with your shell is scarier. When bash 4 was released, one thing that got implemented is the echo of some characters from the terminal to the screen. In practice and with my usage pattern, this meant that whenever I was typing a command line, changed my mind and pressed C-c, I got a ^C printed on the screen, usually overwriting one or two characters of what I had typed. And this prevented me from automatically copying and pasting the command that I had typed. Looking for an answer to that was much harder than to see how to change a parameter on Emacs: every search that I tried on Google with the words bash and Ctrl-C or some variants of that eventually lead me to how do I trap a Ctrl-C on my shell script? . Decided to see what changed, I read the documentation of readline. It didn t help, because I was reading something from version 5. I, then, downloaded the source code and started looking for SIGINT. Then, perusing the code (and the changelog), I saw that with bash 4 and readline 6, a new configuration option was introduced: the echo-control-characters option of readline. Of course, after knowing this, stopping the undesired behaviour was a simple matter of inserting set echo-control-characters off in my .inputrc and think about how much time I spent with that uncomfortable behaviour in some of my preferred tools. As an addendum to the previous paragraphs (written on February of this year, but only now published), the Debian package of Emacs 23.2, the newest version as of this writing, comes with some configuration that makes it ignore the settings that are used with fontconfig. I did not spend any time trying to see the cause of the problem, but adding a simple
Emacs*font:			Mono
to my .Xdefaults file did the trick and restored back the ability to use DejaVu Sans Mono at the right size on my system.

19 May 2010

John Goerzen: Time to learn a new language

I have something of an informal goal of learning a new programming language every few years. It s not so much a goal as it is something of a discomfort. There are so many programming languages out there, with so many niches and approaches to problems, that I get uncomfortable with my lack of knowledge of some of them after awhile. This tends to happen every few years. The last major language I learned was Haskell, which I started working with in 2004. I still enjoy Haskell and don t see anything displacing it as my primary day-to-day workhorse. Yet there are some languages that I d like to learn. I have an interest in cross-platform languages; one of my few annoyances with Haskell is that it can t (at least with production quality) be compiled into something like Java bytecode or something else that isn t architecture-dependent. I have long had a soft spot for functional languages. I haven t had such a soft spot for static type checking, but Haskell s type inference changed that for me. Also I have an interest in writing Android apps, which means some sort of Java tie-in would be needed. Here are my current candidates: Of some particular interest to me is that Haskell has interpreters for Scheme, Lua, and JavaScript as well as code generators for some of these languages (though not generic Haskell-to-foo compilers). Languages not in the running because I already know them include: OCaml, POSIX shell, Python, Perl, Java, C, C++, Pascal, BASIC, Common Lisp, Prolog, SQL. Languages I have no interest in learning right now include Ruby (not different enough from what I already know plus bad experiences with it), any assembly, anything steeped in the Microsoft monoculture (C#, VB, etc.), or anything that is hard to work with outside of an Emacs or vim environment. (If your language requires or strongly encourages me to use your IDE or proprietary compiler, I m not interested that means you, flash.) Brief Reivews of Languages I Have Used To give you a bit of an idea of where I m coming from:

18 May 2010

Wouter Verhelst: Can I have my Debian back?

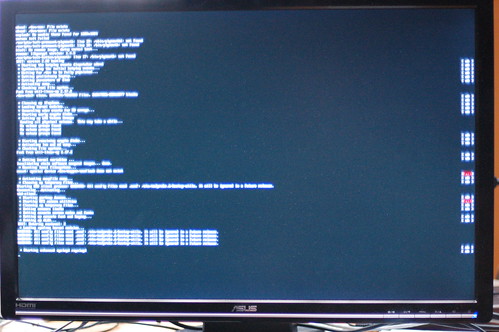
So someone thought it might be a good idea to switch the default from the time-honoured Debian style ("booting foo... ok") to the RedHat style ("<left-align>booting foo... <right-align>[ok]"). I don't think the switch adds any value (it's not like it looked bad or anything in the past); in fact, I think it's a bad idea. And I even have a technical reason. On my 26" 1920x1200 screen (when the i950 driver detects it properly and actually sets the framebuffer to that resolution), the output looks like this: bootscreen Now imagine you get to see that screen for about two to five seconds. Please tell me which two initscripts failed. And no, you cannot use a ruler. Bonus points for if you manage to do so while the text is also moving upwards, which tends to happen when systems boot. Also note that because kernel mode-settings has become the default, a lot more people are going to be using framebuffers. Am I the only one who thinks this is a bad idea?
Sune Vuorela: The Debian-KDE specific things II

I wrote a bit ago a blog post about what debian kde is missing of distribution specific things Some of the more important things includes: Installer

I don t think it is the most important thing. Wether or not the graphical installer is using gtk or qt is not that important. I would love to see it happen, but it is not something I feel like putting my time in. Others are most welcome.
It will give the advantage of giving the installer the possibility to use the framebuffer directly. Modules and firmwares and such
Someone is saying that ubuntu has something called jockey that does this exact thing, with a KDE and a Gnome frontend. Unfortunately, it is python, so it is something I will really avoid. I m hoping that me mentioning it here will make someone into python&debian pick it up and bring it to debian.
It is apparantly some nice magic around discover-data. Debconf frontend that fits
A lot of work has been put into proper perl-qt bindings and they will hopefully be ready for kde4.5, which is unfortunately a series too late for Squeeze :/. But when that has happened, we just need some perl guy to adapt the old frontend to debconf. Reportbug interface
There is already a tool called reportbug-ng that is a qt interface to reporting bugs. All in all, it looks like we are quite far already. We just need to get the last bits put together. Someone: pickup jockey. And note that the comment field isn t a place to report bugs. They will be removed.

Sam Hartman: Moonshot: Federated Authentication Beyond the Web

Recently, I ve been working on an exciting project with JaNet(UK) on a project to bring federated authentication to non-web applications. I ve worked on authentication projects a lot, although this is the first federation project I ve worked on. The big difference appears to be an emphasis on credential independence: the subject (person trying to authenticate) and service will not share a common credential type. Within their organization, the subject and their identity provider share a credential. Then, the federation has some credential mechanism such that the user s organization and the service share some (probably completely different) type of credential. The other emphasis is on providing personalization. For web applications, there are a lot of options to achieve this: Information Card, Open ID, SAML, and OAuth all provide solutions in this space. However there are not good options for non-web applications. If you out-source your mail and chat infrastructure but want to use your own chat client or IMAP client, then you will not get the same federation benefits you can get with the web. If you re using usernames and passwords and don t mind the potential problems with your out-sourcing provider being able to impersonate all your users, you can simply synchronize usernames and passwords. Within an enterprise, you can do better using Kerberos. JaNet(UK) runs the UK Access Federation, which is a SAML-based web single-sign-on federation. In order to better meet the needs of their customers they d like to expand this offering to non-web applications. This demand is apparently shared across the European academic community. I suspect there is also some demand in the US academic community and in enterprise situations. With the web, it turns out that you have a convenient platform for interactions with the identity provider: you can simply direct a web browser to the identity provider and need not specify the user interaction with the web browser at all. This is seen as a significant branding and usability advantage. With other environments, it becomes necessary to specify the interaction with the identity provider. Consider an automated client that wishes to examine a mail box and provide advanced mail sorting or aggregation. That automated client cannot directly use a web browser. OAuth solves this issue with an enrollment step that does typically involve a web browser that produces a consumer key and an authentication step that does not. However for non-web clients it seems like avoiding reliance on the browser authentication will be important. It turns out we already have widely used technologies that do this: the Extensible Authentication Protocol (EAP) mediates the interaction between a subject and identity provider for obtaining network access. It also turns out that we have fairly good technologies for abstract security services within non-web applications: thanks to Kerberos and Active Director, many application protocols and a fair number of applications support GSS-API. JaNet(UK) proposes to combine these technologies with SAML in order to produce a solution for federation beyond the web. I prepared a feasibility analysis of this proposal. At a technical level, the proposal is sound. There s a lot of standardization and implementation work, but there appears to be sufficient motivation to form the seeds of a standards activity and put together a proof-of-concept implementation. However, the big question is Will anyone use it? In particular, to be useful beyond fairly small communities, support from client vendors and application framework vendors will be needed. It s taken massive money and around 20 years to get Kerberos support to a point where it is effective within an enterprise. Moonshot can leverage that work to a large extent, but moonshot may also have greater usability and penetration goals. It s interesting that I m advocating EAP for application layer authentication. When I was a Security AD, I made a strong statement that EAP must only be used for network access. I ve been fairly consistent about that since then. I think there are two huge problems with using EAP for application authentication. The first is that EAP only authenticates the home realm; it does not authenticate what service you re going to. So you might try to connect to your e-mail and end up giving something access to your stored files and pictures instead. That is, EAP has a phishing exposure in the federated context. If the only thing you can get by using EAP is network access, that exposure is only moderate. However in a fully federated environment that is a huge exposure. Moonshot will address this problem by using EAP channel binding and by doing the necessary work to make that a viable solution. The second concern is that interoperability is reduced when you have multiple authentication approaches for the same problem. If EAP is going to be used for application authentication, we need to understand how it relates to the rest of the application authentication metasystem. Moonshot proposes such a relationship, addressing my objection. Moonshot is designed to work well with the objectives of the Identity Metasystem and its laws of identity. It uses a different technology, but does have an approach for dealing with claims-based identity and hopefully will have a user experience very similar to the identity metasystem. It uses a different underlying technology. However one of the main beliefs behind the identity metasystem is that is the user experience and universal interoperability that is important, not any specific technology. In its domain, the technologies Moonshot selects will be a better fit than a web services stack. It s strange not to be working on Kerberos; Moonshot uses some Kerberos technology, but its core is definitely not today s Kerberos. In some ways it is fun to be working on something new. There s one aspect of Kerberos I really miss: Moonshot has nothing like tickets. There s no place to remember state or exchange to directly involve the client in what the server learns. My analysis talks about ways to make Moonshot more like Kerberos; there are some potential advantages, but so far, the tradeoffs do not justify changes. We re hoping to have a bar BOF at IETF 77 and a BOF in the summer at IETF 78.

Erich Schubert: Apple announces new iPad

In a surprise move Apple today announced a new product closely related to the behyped iPad. This move went completely unexpected with technology analysts, who were expecting a new iPhone dubbed "iPhone 4G" to be released next.The new product is called iPad mini, and features most of the iPad functionality in a lot smaller form factor, with extended battery life and without the overheating issues. It will focus on gamers, instead of the deprecated community of newspaper readers. The smaller form factor allows the users to bring the device along at any time.Get all the specifications of the new iPad mini here [www.apple.com]. There is also a special edition with voice-over-3G functionality [www.apple.com].Yes, I'm referring to the iPod touch and the iPhone. Just goofing around.

17 May 2010

Kees Cook: yay for barriers

I find it surreal to have people guessing at my motivations when they could just ask me. On top of all that, I find it weird that people spend so much time with in-fighting. I just want my system not to suck. Some time ago (during in the Ubuntu Karmic development cycle maybe in September 2009), I started having giant problems with my build system. All I/O would start to stall, wait times would surge, and usually my entire system would just go unresponsive with the disk light on solid. This scared the crap out of me, and it wasn t entirely obvious what was triggering it. No one else seemed to be seeing it. I managed to start tracking things using latencytop , and saw stuff like liferea going crazy. As I eliminated more and more things, I eventually settled on it being a problem with umount, and I reported an Ubuntu bug. It seemed to look like an upstream bug that no one else but the reporter could reproduce either. Since no one else was seeing this issue, and it seemed related to LVM snapshots, I migrated off of snapshots, and started using aufs overlays for my builds. For a while, it seemed like things went away. It didn t, and I started hitting it again. I opened a new (now famous) bug in Ubuntu, since now snapshots weren t in the picture, and I didn t want to confuse the earlier history. I managed to find a relatively minimal test-case too. A few other people commenting on the bug were seeing the problem now too, but it was less pronounced for them. As an aside, this wasn t a just wait a few seconds longer kind of issue on my system. A single umount would last 30-40 minutes. And when I m doing parallel builds of security updates, this would turn into my system being unavailable for hours at a stretch. Since none of the kernel developers I was in contact with were able to track down the root cause, I asked Ted Ts o in email if he could just quickly peek in on this for me, since I figured he d be in a good position to confirm or deny it. I didn t want to start wasting upstream time with this if it wasn t reproducible (see earlier upstream kernel bug). To my great relief, Ted found a few minutes to check it, and was able to immediately confirm it and give me a viable work-around ( sync; umount ) for the time being. I confirmed the work-around, and went off to do other things. A while later, Ted came back to deliver a bit of a rant, the purpose of which was not clear to me, but I ultimately ignored it I didn t seem directed at me. I just wanted my system operating normally, and he d done me a favor to check in on it and got me a work-around. More time passes, and I eventually get caught in another I/O-wait melt-down. On investigation, it seemed that the in-kernel work-around in the Ubuntu kernel totally back-fired on me in some cases, rendering even the user-space work-around useless. After investigating the Ubuntu-specific work-around, I re-read Ted s rant in the course of researching what had happened during this bug s triage. It seemed that Ted was basically saying:
this is an upstream problem
RedHat hasn t run into it and he didn t know why I figured I should confirm for myself if Fedora was affected, so downloaded and installed Fedora to double-check there. Since I was able to reproduce it there, I opened an upstream bug, linking back to the original Ubuntu bug, and then went to open a bug in the Fedora tracker, linking back to upstream. And it seems to be these actions that everyone has jumped on. I will now bore you with the reality of my motivations: I wanted to fix the bug so no one would end up experiencing the same pain I d been through over the last 6 months. The bug was, from my perspective, a serious issue. Since I d managed to reproduce it in another distro, it was my duty as a Free Software developer to report it to them. And, in what I felt was an unambiguous gesture, I made sure to include the link to the upstream kernel bug. Reproducing it in Ubuntu, in Fedora, and with a stock kernel had me confident that it was an upstream issue. While Ted did correctly suspect the issue was upstream, I really didn t want to just open an upstream bug and have it be ignored. I wanted some additional proof of reproduction, which I got when I tested it on Fedora. So, I m rather saddened that so many people spent so much time questioning my motivations, making fun of Canonical, or doing anything other than trying to just simply solve this problem. I m totally disinterested in inter-distro fighting. Instead, I continue to assume we re all on the same team, fighting a philosophical battle against close-source software. And in that regard, I think it s still true. If I ignore the rants and jeering, I come away thankful for all the people that spent time trying reproduce the issue at Canonical, at RedHat, and in the larger community. I m hugely thankful that Ted made some time to let me know I wasn t crazy, and there was actually a problem. I m thankful for having some work-arounds, and I m thankful that the root cause was eventually ferreted out, with some possible solutions. I m even thankful that some people on the LWN thread saw that, far from malicious, I was trying to be helpful with the bug. I just wanted my filesystem not to eat my computer. And I was hoping other people could maybe help me, since I m not a filesystem expert. The drama around this bug is pathetic, and now by talking about it for almost 1000 words, I m just as guilty.

Rapha&#235;l Hertzog: Open money and Debian

I recently read an introductory article in an IT magazine on the increased usage of new currencies. It briefly mentioned the work of a researcher called Arthur Brock in using those currencies within open source communities. While I did not find more details on the research, it led me to think again about Debian s relation with money. The reason why we have troubles using money to pay the time spent by our developers is that money is scarce and it s thus next to impossible to be fair in the way money is spent among us. So why not invent a new currency that is not scarce and that would encourage the kind of work that we really value? Apparently there is free software out there to build new currencies: see metacurrency.org or openmoney.org. Let s call the new currency swirly/swirlies for the sake of the examples below. There are then multiple ways to create a small economy within the community and/or even create bridges with the national currencies: I m sure we can come up with many similar ideas. Feel free to share yours in the comments. Partagez cet article / Share This

Matt Zimmerman: Ubuntu 10.10 (Maverick) Developer Summit

I spent last week at the Ubuntu Developer Summit in Belgium, where we kicked off the 10.10 development cycle. Due to our time-boxed release cycle, not everything discussed here will necessarily appear in Ubuntu 10.10, but this should provide a reasonable overview of the direction we re taking. Presentations While most of our time at UDS is spent in small group meetings to discuss specific topics, there are also a handful of presentations to convey key information and stimulate creative thinking. A few of the more memorable ones for me were: The talks were all recorded, though they may not all be online yet. Foundations The Foundations team provides essential infrastructure, tools, packages and processes which are central to the development of all Ubuntu products. They make it possible for the desktop and server teams to focus on their areas of expertise, building on a common base system and development procedures. Highlights from their track: Desktop The desktop team manages both Desktop Edition and Netbook Edition, on a mission to provide a top-notch experience to users across a range of client computing devices. Highlights from their track: Server/Cloud The server team is charging ahead with making Ubuntu the premier server OS for cloud computing environments. Highlights from their track: ARM Kiko Reis gave a talk introducing ARM and the corresponding opportunity for Ubuntu. The ARM team ran a full track during the week on all aspects of their work, from the technical details of the kernel and toolchain, to the assembly of a complete port of Netbook Edition 10.10 for several ARM platforms. Kernel The kernel team provided essential input and support for the above efforts, and also held their own track where they selected 2.6.35 as their target version, agreed on a variety of changes to the Ubuntu kernel configuration, and created a plan for providing backports of newer kernels to LTS releases to support deployment on newer hardware. Security Like the kernel team, the security team provided valuable input into the technical plans being developed by other teams, and also organized a security track to tackle some key security topics such as clarifying the duration of maintenance for various collections of packages, and the ongoing development of AppArmor and Ubuntu s AppArmor profiles. QA The QA team focuses on testing, test automation and bug management throughout the project. While quality is everyone s responsibility, the QA team helps to coordinate these activities across different teams, establish common standards, and maintain shared infrastructure and tools. Highlights from their track include: Design The design team organized a track at UDS for the first time this cycle, and team manager Ivanka Majic gave a presentation to help explain its purpose and scope. Toward the end of the week, I joined in a round table discussion about some of the challenges faced by the team in engaging with the Ubuntu community and building support for their work. This is a landmark effort in mating professional design with free software community, and there is still much to learn about how to do this well. Community The community track discussed the usual line-up of events, outreach and advocacy programs, organizational tools, and governance housekeeping for the 10.10 cycle, as well as goals for improving the translation of Ubuntu and related resources into many languages. One notable project is an initiative to aggressively review patches submitted to the bug tracker, to show our appreciation for these contributions by processing them more quickly and completely.

Francois Marier: List of Open Source Conference Management Systems

Conference Management systems are web applications designed to make the lives of conference organisers easier. They usually include features such as registration, payment, paper submission and review, scheduling and publishing of announcements.

Since Wikipedia is apparently not a place for such a "spammy list," I figured I should at least post this here:
NameUsed byLicenseProgramming Language
A Conference ToolkitYAPC::EuArtistic LicensePerl
ConManUtah Open Source Conference, Texax Linux FestGPLPython (Django)
Open Conference Systemsvarious academic conferencesGPLPHP
OpenConferenceWareOpen Source BridgeMITRuby on Rails
PentabarfDebConf, FOSDEM, CCCGPLRuby on Rails
SCALEregSCALEGPLPython (Django)
Zookeeprlinux.conf.auGPLPython (Pylons)


If you know of any other Open Source systems, please leave a comment!

16 May 2010

Enrico Zini: New apt-xapian-index plugins

New apt-xapian-index plugins Besides a fair bit of refactoring and cleanup, I've recently added two new plugins to apt-xapian-index: app-install If app-install-data is installed, information about .desktop files will now enter the index. This allows, for example, to limit query results to only those packages that contain .desktop files, which is quite useful, for example for building desktop-oriented package managers. aliases It reads term->aliases mapping from files in /etc/apt-xapian-index/aliases/ or /usr/share/apt-xapian-index/aliases/, and feeds them as synonyms in the index. apt-xapian-index ships an example alias file, to give people who know the wrong software names a chance to find the right ones:
# Aliases expanding names of popular applications
excel       XToffice::spreadsheet
powerpoint  XToffice::presentation
photoshop   XTworks-with::image:raster
coreldraw   XTworks-with::image:vector
autocad     XTworks-with::3dmodel
Notice how it is possible to use index terms that happen to be Debtags tags as synonyms, which yields better results, language independence and extra coolness.

Ingo Juergensmann: Slow Import with Digikam

I'm using Digikam to manage my pictures. There are currently more than 32000 pictures to handle. While Digikam 1.2 brought some great performance increases, but the import of new images is driving me crazy. I don't know since when the import ist that slow, but currently a 12 MP image needs 8 seconds to import when it is horizontal. When Digikam needs to rotate it during import because it is a vertically aligned image, then it needs approximately 20 seconds for each image to import.
Funny enough the larger NEF files are imported within a fraction of a second.
I don't know whether this is a Digikam issue or those of a related library or such, but it's really, really annoying when you shot a bunch of fotos and need hours to import them.

UPDATE:
Mark Purcell points at a libexiv2 bugreport: #579835

Thomas Koch: tnt is not topgit

As I've already written, I'm working on an alternative to topgit. I made a first attempt in perl some weeks ago, but gave up after some frustrating hours. Yesterday I started again in python and had a very nice time putting together the groundwork and the first two commands.
It may be noted, that I've no previous programming experience in neither perl nor python!
By now, I can create a patchset branch and add a patch branch to it. There's still a lot to do. For my talk at the Debian Mini Conference in Berlin next month I'd like to be able to update patch branches, export patchsets and give a status summary.
Maybe I can already find somebody who's interested in joining me with this project? The code is in my github account, however the name will most probably change.
One reason that I've been much faster in python is the fantastic python-git library. I can only recommend it!
In other news: I'm searching a couch to surf in Berlin from june 7.-12. I prefer couchsurfing over hotels mostly to get to know nice people around the world. Please contact me, if you'd like to host me for a night or two. (thomas at koch punkt ro)

Next.

Previous.
