Search Results: "ron"

14 March 2011

Kai Wasserb ch: ytplaylistfetcher: new playlist URL format

It seems like YouTube has added a new format for playlist URLs. You'll find it on search result pages. The ID of the playlist comes after:
list=PL
So a complete URL containing this format might look like http://www.youtube.com/watch?v=hzMtVJTxrJw&playnext=1&list=PL00A3D4ABEAF28FA3 I've added support for this format in bcccc0f7 to YTPlaylistFetcher. You can download the latest version by right-clicking on the previous link and select "Save Link as ..." from the context menu.

Colin Watson: Wubi bug 693671

I spent most of last week working on Ubuntu bug 693671 ("wubi install will not boot - phase 2 stops with: Try (hd0,0): NTFS5"), which was quite a challenge to debug since it involved digging into parts of the Wubi boot process I'd never really touched before. Since I don't think much of this is very well-documented, I'd like to spend a bit of time explaining what was involved, in the hope that it will help other developers in the future. Wubi is a system for installing Ubuntu into a file in a Windows filesystem, so that it doesn't require separate partitions and can be uninstalled like any other Windows application. The purpose of this is to make it easy for Windows users to try out Ubuntu without the need to worry about repartitioning, before they commit to a full installation. Wubi started out as an external project, and initially patched the installer on the fly to do all the rather unconventional things it needed to do; we integrated it into Ubuntu 8.04 LTS, which involved turning these patches into proper installer facilities that could be accessed using preseeding, so that Wubi only needs to handle the Windows user interface and other Windows-specific tasks. Anyone familiar with a GNU/Linux system's boot process will immediately see that this isn't as simple as it sounds. Of course, ntfs-3g is a pretty solid piece of software so we can handle the Windows filesystem without too much trouble, and loopback mounts are well-understood so we can just have the initramfs loop-mount the root filesystem. Where are you going to get the kernel and initramfs from, though? Well, we used to copy them out to the NTFS filesystem so that GRUB could read them, but this was overly complicated and error-prone. When we switched to GRUB 2, we could instead use its built-in loopback facilities, and we were able to simplify this. So all was more or less well, except for the elephant in the room. How are you going to load GRUB? In a Wubi installation, NTLDR (or BOOTMGR in Windows Vista and newer) still owns the boot process. Ubuntu is added as a boot menu option using BCDEdit. You might then think that you can just have the Windows boot loader chain-load GRUB. Unfortunately, NTLDR only loads 16 sectors - 8192 bytes - from disk. GRUB won't fit in that: the smallest core.img you can generate at the moment is over 18 kilobytes. Thus, you need something that is small enough to be loaded by NTLDR, but that is intelligent enough to understand NTFS to the point where it can find a particular file in the root directory of a filesystem, load boot loader code from it, and jump to that. The answer for this was GRUB4DOS. Most of GRUB4DOS is based on GRUB Legacy, which is not of much interest to us any more, but it includes an assembly-language program called GRLDR that supports doing this very thing for FAT, NTFS, and ext2. In Wubi, we build GRLDR as wubildr.mbr, and build a specially-configured GRUB core image as wubildr. Now, the messages shown in the bug report suggested a failure either within GRLDR or very early in GRUB. The first thing I did was to remember that GRLDR has been integrated into the grub-extras ntldr-img module suitable for use with GRUB 2, so I tried building wubildr.mbr from that; no change, but this gave me a modern baseline to work on. OK; now to try QEMU (you can use tricks like qemu -hda /dev/sda if you're very careful not to do anything that might involve writing to the host filesystem from within the guest, such as recursively booting your host OS ...). No go; it hung somewhere in the middle of NTLDR. Still, I could at least insert debug statements, copy the built wubildr.mbr over to my test machine, and reboot for each test, although it would be slow and tedious. Couldn't I? Well, yes, I mostly could, but that 8192-byte limit came back to bite me, along with an internal 2048-byte limit that GRLDR allocates for its NTFS bootstrap code. There were only a few spare bytes. Something like this would more or less fit, to print a single mark character at various points so that I could see how far it was getting:
	pushal
	xorw	%bx, %bx	/* video page 0 */
	movw	$0x0e4d, %ax	/* print 'M' */
	int	$0x10
	popal
In a few places, if I removed some code I didn't need on my test machine (say, CHS compatibility), I could even fit in cheap and nasty code to print a single register in hex (as long as you didn't mind 'A' to 'F' actually being ':' to '?' in ASCII; and note that this is real-mode code, so the loop counter is %cx not %ecx):
	/* print %edx in dumbed-down hex */
	pushal
	xorw	%bx, %bx
	movb	$0xe, %ah
	movw	$8, %cx
1:
	roll	$4, %edx
	movb	%dl, %al
	andb	$0xf, %al
	int	$0x10
	loop	1b
	popal
After a considerable amount of work tracking down problems by bisection like this, I also observed that GRLDR's NTFS code bears quite a bit of resemblance in its logical flow to GRUB 2's NTFS module, and indeed the same person wrote much of both. Since I knew that the latter worked, I could use it to relieve my brain of trying to understand assembly code logic directly, and could compare the two to look for discrepancies. I did find a few of these, and corrected a simple one. Testing at this point suggested that the boot process was getting as far as GRUB but still wasn't printing anything. I removed some Ubuntu patches which quieten down GRUB's startup: still nothing - so I switched my attentions to grub-core/kern/i386/pc/startup.S, which contains the first code executed from GRUB's core image. Code before the first call to real_to_prot (which switches the processor into protected mode) succeeded, while code after that point failed. Even more mysteriously, code added to real_to_prot before the actual switch to protected mode failed too. Now I was clearly getting somewhere interesting, but what was going on? What I really wanted was to be able to single-step, or at least see what was at the memory location it was supposed to be jumping to. Around this point I was venting on IRC, and somebody asked if it was reproducible in QEMU. Although I'd tried that already, I went back and tried again. Ubuntu's qemu is actually built from qemu-kvm, and if I used qemu -no-kvm then it worked much better. Excellent! Now I could use GDB:
(gdb) target remote   qemu -gdb stdio -no-kvm -hda /dev/sda
This let me run until the point when NTLDR was about to hand over control, then interrupt and set a breakpoint at 0x8200 (the entry point of startup.S). This revealed that the address that should have been real_to_prot was in fact garbage. I set a breakpoint at 0x7c00 (GRLDR's entry point) and stepped all the way through to ensure it was doing the right thing. In the process it was helpful to know that GDB and QEMU don't handle real mode very well between them. Useful tricks here were: Single-stepping showed that GRLDR was loading the entirety of wubildr correctly and jumping to it. The first instruction it jumped to wasn't in startup.S, though, and then I remembered that we prefix the core image with grub-core/boot/i386/pc/lnxboot.S. Stepping through this required a clear head since it copies itself around and changes segment registers a few times. The interesting part was at real_code_2, where it copies a sector of the kernel to the target load address, and then checks a known offset to find out whether the "kernel" is in fact GRUB rather than a Linux kernel. I checked that offset by hand, and there was the smoking gun. GRUB recently acquired Reed-Solomon error correction on its core image, to allow it to recover from other software writing over sectors in the boot track. This moved the magic number lnxboot.S was checking somewhat further into the core image, after the first sector. lnxboot.S couldn't find it because it hadn't copied it yet! A bit of adjustment and all was well again. The lesson for me from all of this has been to try hard to get an interactive debugger working. Really hard. It's worth quite a bit of up-front effort if it saves you from killing neurons stepping through pages of code by hand. I think the real-mode debugging tricks I picked up should be useful for working on GRUB in the future.

Erich Schubert: Google Circles rumor

The media are spreading a rumor about a social networking platform by Google, called Circles.
So far, these things have been debunked.
I do not believe that Google could succeed with a "Facebook clone". The market is already taken, Facebook is too big and had successfully been taking away international markets from local clones. For example in Germany, the other social networks used to be a lot bigger, but Facebook overtook them in just a few months, and the people I know pretty much quit the other networks then.
And I assume Google is aware that unless they have a strong strategy, the network would go the Wave-Buzz route.
At least here in Germany, people are surprisingly concerned by the amount of data Google might have on them, while at the same time they give it to Facebook for free. This is probably due to the media attention received with StreetView. It's not fair, but that's life.
However, "social network" is a broad term. Just think of what people actually use facebook for:
  • Games (often even not with their social circle!)
  • Microblogging
  • Photo sharing
  • Email
  • Automatic address book
Now, if you look closely at this list, Google pretty much has all of these, if we ignore the browser games (and they are all over the internet by now, Facebook and without!), then there is just one key ingredient missing for Google: the address book thing.
I believe this "Google circles" thing will largely by a "smart address book" that helps people managing their social contacts in a social network style. And obviously, this can be integrated in various products such as Mail, Picasa, Buzz, ...
If Google manages to launch a "contact manager" that makes it really easy for people to manage their social circles, this can be quite a killer. Facebook has "lists" but they are awful to use. It likes to "hide" friends to reduce the amount of information it throws at you. But it doesn't really organize it for you, for example by social circles or topics. These days for example Facebook could split the news feed into "Japan" and "everything else" I guess.

Ian Wienand: Converting DICOM images, part 2

In a previous post I discussed converting medical images. I tried again today and hit another issue which could do with some google help. If you see the following:
$ dcm2pnm --all-frames input.dcm
E: can't change to unencapsulated representation for pixel data
E: can't determine 'PhotometricInterpretation' of decompressed image
E: can't decompress frame 0: Illegal call, perhaps wrong parameters
E: can't convert input pixel data, probably unsupported compression
F: Invalid DICOM image
and dcmdump reports somewhere:
# Dicom-Data-Set
# Used TransferSyntax: JPEG Baseline
Try the dcmj2pnm program, rather than dcm2pnm. The man page does mention this, but that assumes that you know you have a JPEG encoded image :) It works the same, can extract multiple frames and can be converted to a movie as discussed in the previous post. Easy when you know how!

Russell Coker: Effective Computers for Schools

Sam Varghese has written an article that is very skeptical of the educational value of the OLPC project [1].Are Laptops Any Good for Schools?Sam cites an article in the New York Times by Winnie Hu about schools removing laptop programs due to a lack of success [2]. Winnie s article gives an example of a school shutting a program because of getting new teachers who lacked computer skills and some examples of schools which had issues with the repair cost. The solution to that would be computers that are more robust and easier to use by all accounts the OLPC systems are solidly constructed and easy to use!It is claimed that using laptops doesn t increase test scores. Using only test scores to compare educational methods is a way to lose, probably any school which does nothing other than try to increase test scores is worth avoiding. One example from Winnie s article is a report by Mr. Warschauer of students at a middle school in Yarmouth, Me., who used their laptops to create a Spanish book for poor children in Guatemala and debate Supreme Court cases found online . What value can you place on having students develop books for poor children in other countries and debate Supreme Court cases? If this sort of program became popular then it would lead to the countries which do it becoming better places to live in future decades!Mr. Warschauer also claims that If the goal is to get kids up to basic standard levels, then maybe laptops are not the tool. But if the goal is to create the George Lucas and Steve Jobs of the future, then laptops are extremely useful . I would go further than that, I think that providing the educational environment that involves international charity work and analysis of important court cases would lead to students having the skills to become good engineers, designers, and artists who work for people like George Lucas and Steve Jobs. No matter what you might do the vast majority of children will not grow up to be like George Lucas and Steve Jobs, there is a very limited number of positions for such people. But those people employ a huge number of creative people who do interesting and enjoyable work for good pay.I don t think that Winnie s article supports criticism of the OLPC project. I don t think that Winnie s article even contains sufficient evidence to match the headline.Playing GamesSam also cites an article about the misuse of school computers for playing games [3]. Of course there are ways of limiting access to games based on time etc. For a Linux system you could have a root cron job that runs chmod on /usr/games at various times, and preventing users from easily running programs that they install isn t difficult.Not that games are all bad, the flash-based games on www.physicsgames.net do teach kids some things about physics although I admit that much of that could be learned by playing with balls, skate-boards, etc.The Problem with the OLPC ProjectI think that the policy change to make OLPC systems only available to disadvantaged children was a mistake. The give one get one program was a great idea, maybe not the most effective way of getting funding but good for getting developers. While the new Sugar on a Stick project to put the OLPC GUI on a bootable USB device [4] it doesn t compare well to having dedicated hardware IMHO.Minimal Use of ComputersI have previously written about the weight of school bags and how laptops can alleviate the risk of health problems related to carrying heavy text books [5]. Since that time ebook readers and tablets have become incredibly cheap. Ebook readers are really light and the recent tablets are also very light (particularly the smaller ones). It seems to me that every school should at least be moving towards every student having an ebook reader and to use ebooks for all books that are part of the curriculum.At the moment there are a bunch of tablets on sale for about $150, that includes tablets that can access the Internet via Wifi or via 3G and a cheap 3G plan costs less than $150 per annum. If tablets were used for some of the computer tasks related to schools then a lot of the difficulty of repairing hardware would be removed. Tablets don t offer as many options for messing up the software configuration and if the hardware breaks it s easy to transfer the data onto a new tablet from the cloud with a maximum cost of $150 to replace the hardware.Also a cloud-based computing model could permit students to access all the same data from school and home while using desktop computers at both locations.Current SuccessNatalie Craig wrote an interesting article for The Age about The Lab a drop-in computer center for kids on the Autism Spectrum run by Dale Linegar and Stefan Schutt [6]. The fact that kids who have communication difficulties can find it easier to communicate electronically should be fairly obvious to everyone in the free software community, but the creation of an organisation to support such kids is noteworthy I think that such centers should be funded by the government and run in every city.Salman Khan gave an interesting TED talk about his project the Khan Academy [7] which is an online video-based teaching system that evolved from some Youtube videos he produced to tutor his cousins. Salman pointed out that his cousins said that they would rather watch his videos than have him teach them in person, it seems that they liked being able to pause and rewind the talk as well as avoiding the pressure of human interaction. The Khan Academy has videos in Adobe flash format, but conveniently they have download links so those of us who don t have the Flash plugin can still view the content [8].One of the interesting things about the Khan Academy is that in school use the videos are being assigned to kids as homework and the class time is used for teaching children to do worked examples what has traditionally been homework.So it seems that there are real examples of special-needs kids and average kids benefiting from different types of electronic learning.ConclusionI think that almost everything about the education system is broken. I also think that in many ways the education system has reached a local maximum, so there is no small way of improving things, and adding computers without making any of the significant changes needed to fix the big problems probably can t do a lot of good. In spite of this computers can provide some real benefits and I expect that those benefits can be better than the benefits of other potential ways of spending the money (IE it s worth the opportunity cost). I also have no doubt that almost anything can give a negative result if done badly enough, so I don t interpret examples of computer use failing in a school as anything other than evidence of a failing school.While the Khan Academy has some results that seem very positive I think that s only the first step of what needs to be done. It also seems to be based around users who have good Internet access which often isn t the case in places where the OLPC is being deployed. This implies that we need to get systems like the Khan Academy designed to operate in a disconnected manner, maybe with a remote server that s not connected to the Internet. This should be possible if funding is available.Sam suggested that there needs to be a scientific study of the effectiveness of the OLPC. I think that every project which involves significant amounts of public funding should be researched to ensure that it s an effective use of resources. 400,000 laptops is going to cost something more than $40,000,000 so it seems reasonable to devote a few person-years of research to determine how effective they are and which of the possible ways of using an OLPC will give the best results.I am confident that a good study of the effectiveness of the OLPC would demonstrate that it provides real educational benefits when correctly incorporated into an educational program. I also expect that such a study would show some significant differences in the effectiveness of various ways of using them. But we shouldn t be relying on confidence, we need some test results.

13 March 2011

Gregor Herrmann: RC bugs 2011/08 - 2011/10

again, nothing exciting to report. as you can see below, I've only worked on pkg-perl packages. we get a surprising amount of FTBFS bugs at the moment; many of them caused by changes in depended-upon packages, some also by human errors (like not building in a chroot and missing build dependencies upfront). at least the latter could be avoided quite easily ...

Steve Kemp: A few forks.

Although I promised in my previous entry that I'd made my last mention of the redisfs - replication friendly redis-based filesystem I have to disappoint. Ben Sykes informed me that he'd made a fork of redisfs, called shredisfs. I like forks. Forks are good, and this particular one was very welcome - from the README:
Steve's original managed around 250k per second for writes on my test machine, this version does about 15MB a second writes. ... Read speed on the test machine here now is around 180MB/sec..
Needless to say I "stole" the improvements and rolled them into my original release. Thanks all round to those of you that submitted bug reports, suggestions, and codez. I also had a release out briefly which used zLib to compress the values of keys stored in memory. Unfortunately that lead to a net-slowdown for files which were bigger than a single block - due to the overhead of file-system appends which translated to: "fetch", "compress", "append", and "decompress". Finally on the subject of qpsmtpd, my favourite SMTP-server - the exceptionally talented Matt Sergeant released a proof of concept rewrite in Javascript. Using nodejs this new SMTP server is heavily asynchronous and you can find it online under the name Haraka. Although my javascript-fu is weak I'm very impressed by the codebase out there so far, and I'd expect good things of it in the future. Even if it does use Javascript and not my beloved Perl. Finally I'm a year older. But birthdays aren't important. ObQuote: "Do you wanna know what makes all my candy taste so special? " - Epic Movie.

David Bremner: Debugging Duplicity Duplication

It seems kind of unfair, given the name, but duplicity really doesn't like to be run in parallel. This means that some naive admin (not me of course, but uh, this guy I know ;) ) who writes a crontab
 @daily  duplicity incr $ARGS $SRC $DEST
 @weekly duplicity full $ARGS $SRC $DEST 
is in for a nasty surprise when both fire at the same time. In particular one of them will terminate with the not very helpful.
 AttributeError: BackupChain instance has no attribute 'archive_dir'
After some preliminary reading of mailing list archives, I decided to delete ~/.cache/duplicity on the client and try again. This was not a good move.
  1. It didn't fix the problem
  2. Resyncing from the server required decrypting some information, which required access to the gpg private key.
Now for me, one of the main motivations for using duplicity was that I could encrypt to a key without having the private key accessible. Luckily the following crazy hack works.
  1. A host where the gpg private key is accessible, delete the ~/.cache/duplicity, and perform some arbitrary duplicity operation. I did duplicity clean $DEST
  2. Now rsync the ./duplicity/cache directory to the backup client.
Now at first you will be depressed, because the problem isn't fixed yet. What you need to do is go onto the backup server (in my case Amazon s3) and delete one of the backups (in my case, the incremental one). Of course, if you are the kind of reader who skips to the end, probably just doing this will fix the problem and you can avoid the hijinks. And, uh, some kind of locking would probably be a good plan... For now I just stagger the cron jobs.

Francois Marier: Setting up RAID on an existing Debian/Ubuntu installation

I run RAID1 on all of the machines I support. While such hard disk mirroring is not a replacement for having good working backups, it means that a single drive failure is not going to force me to have to spend lots of time rebuilding a machine.

The best possible time to set this up is of course when you first install the operating system. The Debian installer will set everything up for you if you choose that option and Ubuntu has alternate installation CDs which allow you to do the same.

This post documents the steps I followed to retrofit RAID1 into an existing Debian squeeze installation. Getting a mirrored setup after the fact.

OverviewBefore you start, make sure the following packages are installed:
apt-get install mdadm rsync initramfs-tools
Then go through these steps:
  1. Partition the new drive.
  2. Create new degraded RAID arrays.
  3. Install GRUB2 on both drives.
  4. Copy existing data onto the new drive.
  5. Reboot using the RAIDed drive and test system.
  6. Wipe the original drive by adding it to the RAID array.
  7. Test booting off of the original drive.
  8. Resync drives.
  9. Test booting off of the new drive.
  10. Reboot with the two drives and resync the array.
(My instructions are mostly based on this old tutorial but also on this more recent one.)

1- Partition the new driveOnce you have connected the new drive (/dev/sdb), boot into your system and use one of cfdisk or fdisk to display the partition information for the existing drive (/dev/sda on my system).

The idea is to create partitions of the same size on the new drive. (If the new drive is bigger, leave the rest of the drive unpartitioned.)

Partition types should all be: fd (or "linux raid autodetect").

2- Create new degraded RAID arraysThe newly partioned drive, consisting of a root and a swap partition, can be added to new RAID1 arrays using mdadm:
mdadm --create /dev/md0 --level=1 --raid-devices=2 missing /dev/sdb1
mdadm --create /dev/md1 --level=1 --raid-devices=2 missing /dev/sdb2
and formatted like this:
mkswap /dev/md1
mkfs.ext4 /dev/md0
Specify these devices explicitly in /etc/mdadm/mdadm.conf:
DEVICE /dev/sda* /dev/sdb*
and append the RAID arrays to the end of that file:
mdadm --detail --scan >> /etc/mdadm/mdadm.conf
dpkg-reconfigure mdadm
You can check the status of your RAID arrays at any time by running this command:
cat /proc/mdstat

3- Install GRUB2 on both drivesThe best way to ensure that GRUB2, the default bootloader in Debian and Ubuntu, is installed on both drives is to reconfigure its package:
dpkg-reconfigure grub-pc
and select both /dev/sda and /dev/sdb (but not /dev/md0) as installation targets.

This should cause the init ramdisk (/boot/initrd.img-2.6.32-5-amd64) and the grub menu (/boot/grub/grub.cfg) to be rebuilt with RAID support.

4- Copy existing data onto the new driveCopy everything that's on the existing drive onto the new one using rsync:
mkdir /tmp/mntroot
mount /dev/md0 /tmp/mntroot
rsync -auHxv --exclude=/proc/* --exclude=/sys/* --exclude=/tmp/* /* /tmp/mntroot/

5- Reboot using the RAIDed drive and test systemBefore rebooting, open /tmp/mntroot/etc/fstab, and change /dev/sda1 and /dev/sda2 to /dev/md0 and /dev/md1 respectively.

Then reboot and from within the GRUB menu, hit "e" to enter edit mode and make sure that you will be booting off of the new disk:
set root='(md/0)'
linux /boot/vmlinuz-2.6.32-5-amd64 root=/dev/md0 ro quiet
Once the system is up, you can check that the root partition is indeed using the RAID array by running mount and looking for something like:
/dev/md0 on / type ext4 (rw,noatime,errors=remount-ro)

6- Wipe the original drive by adding it to the RAID arrayOnce you have verified that everything is working on /dev/sdb, it's time to change the partition types on /dev/sda to fd and to add the original drive to the degraded RAID array:
mdadm /dev/md0 -a /dev/sda1
mdadm /dev/md1 -a /dev/sda2
You'll have to wait until the two partitions are fully synchronized but you can check the sync status using:
watch -n1 cat /proc/mdstat

7- Test booting off of the original driveOnce the sync is finished, update the boot loader menu:
update-grub
and shut the system down:
shutdown -h now
before physically disconnecting /dev/sdb and turning the machine back on to test booting with only /dev/sda present.

After a successful boot, shut the machine down and plug the second drive back in before powering it up again.

8- Resync drivesIf everything works, you should see the following after running cat /proc/mdstat:
md0 : active raid1 sda1[1]
280567040 blocks [2/1] [_U]
indicating that the RAID array is incomplete and that the second drive is not part of it.

To add the second drive back in and start the sync again:
mdadm /dev/md0 -a /dev/sdb1

9- Test booting off of the new driveTo complete the testing, shut the machine down, pull /dev/sda out and try booting with /dev/sdb only.

10- Reboot with the two drives and resync the arrayOnce you are satisfied that it works, reboot with both drives plugged in and re-add the first drive to the array:
mdadm /dev/md0 -a /dev/sda1
Your setup is now complete and fully tested.

Ongoing maintenanceI recommend making sure the two RAIDed drives stay in sync by enabling periodic RAID checks. The easiest way is to enable the checks that are built into the Debian package:
dpkg-reconfigure mdadm
but you can also create a weekly or monthly cronjob which does the following:
echo "check" > /sys/block/md0/md/sync_action
Something else you should seriously consider is to install the smartmontools package and run weekly SMART checks by putting something like this in your /etc/smartd.conf:
/dev/sda -a -d ata -o on -S on -s (S/../.././02 L/../../6/03)
/dev/sdb -a -d ata -o on -S on -s (S/../.././02 L/../../6/03)
These checks, performed by the hard disk controllers directly, could warn you of imminent failures ahead of time. Personally, when I start seeing errors in the SMART log (smartctl -a /dev/sda), I order a new drive straight away.

12 March 2011

Joey Hess: JEST results

Four months ago I opted out of daylight savings time. How did it work out? Tomorrow I will be in sync with everyone else. That might take some getting used to. I plan to keep my timezone setting, and will be doing this again next winter.

Russell Coker: Climate Action Now Rally Melbourne 12th March

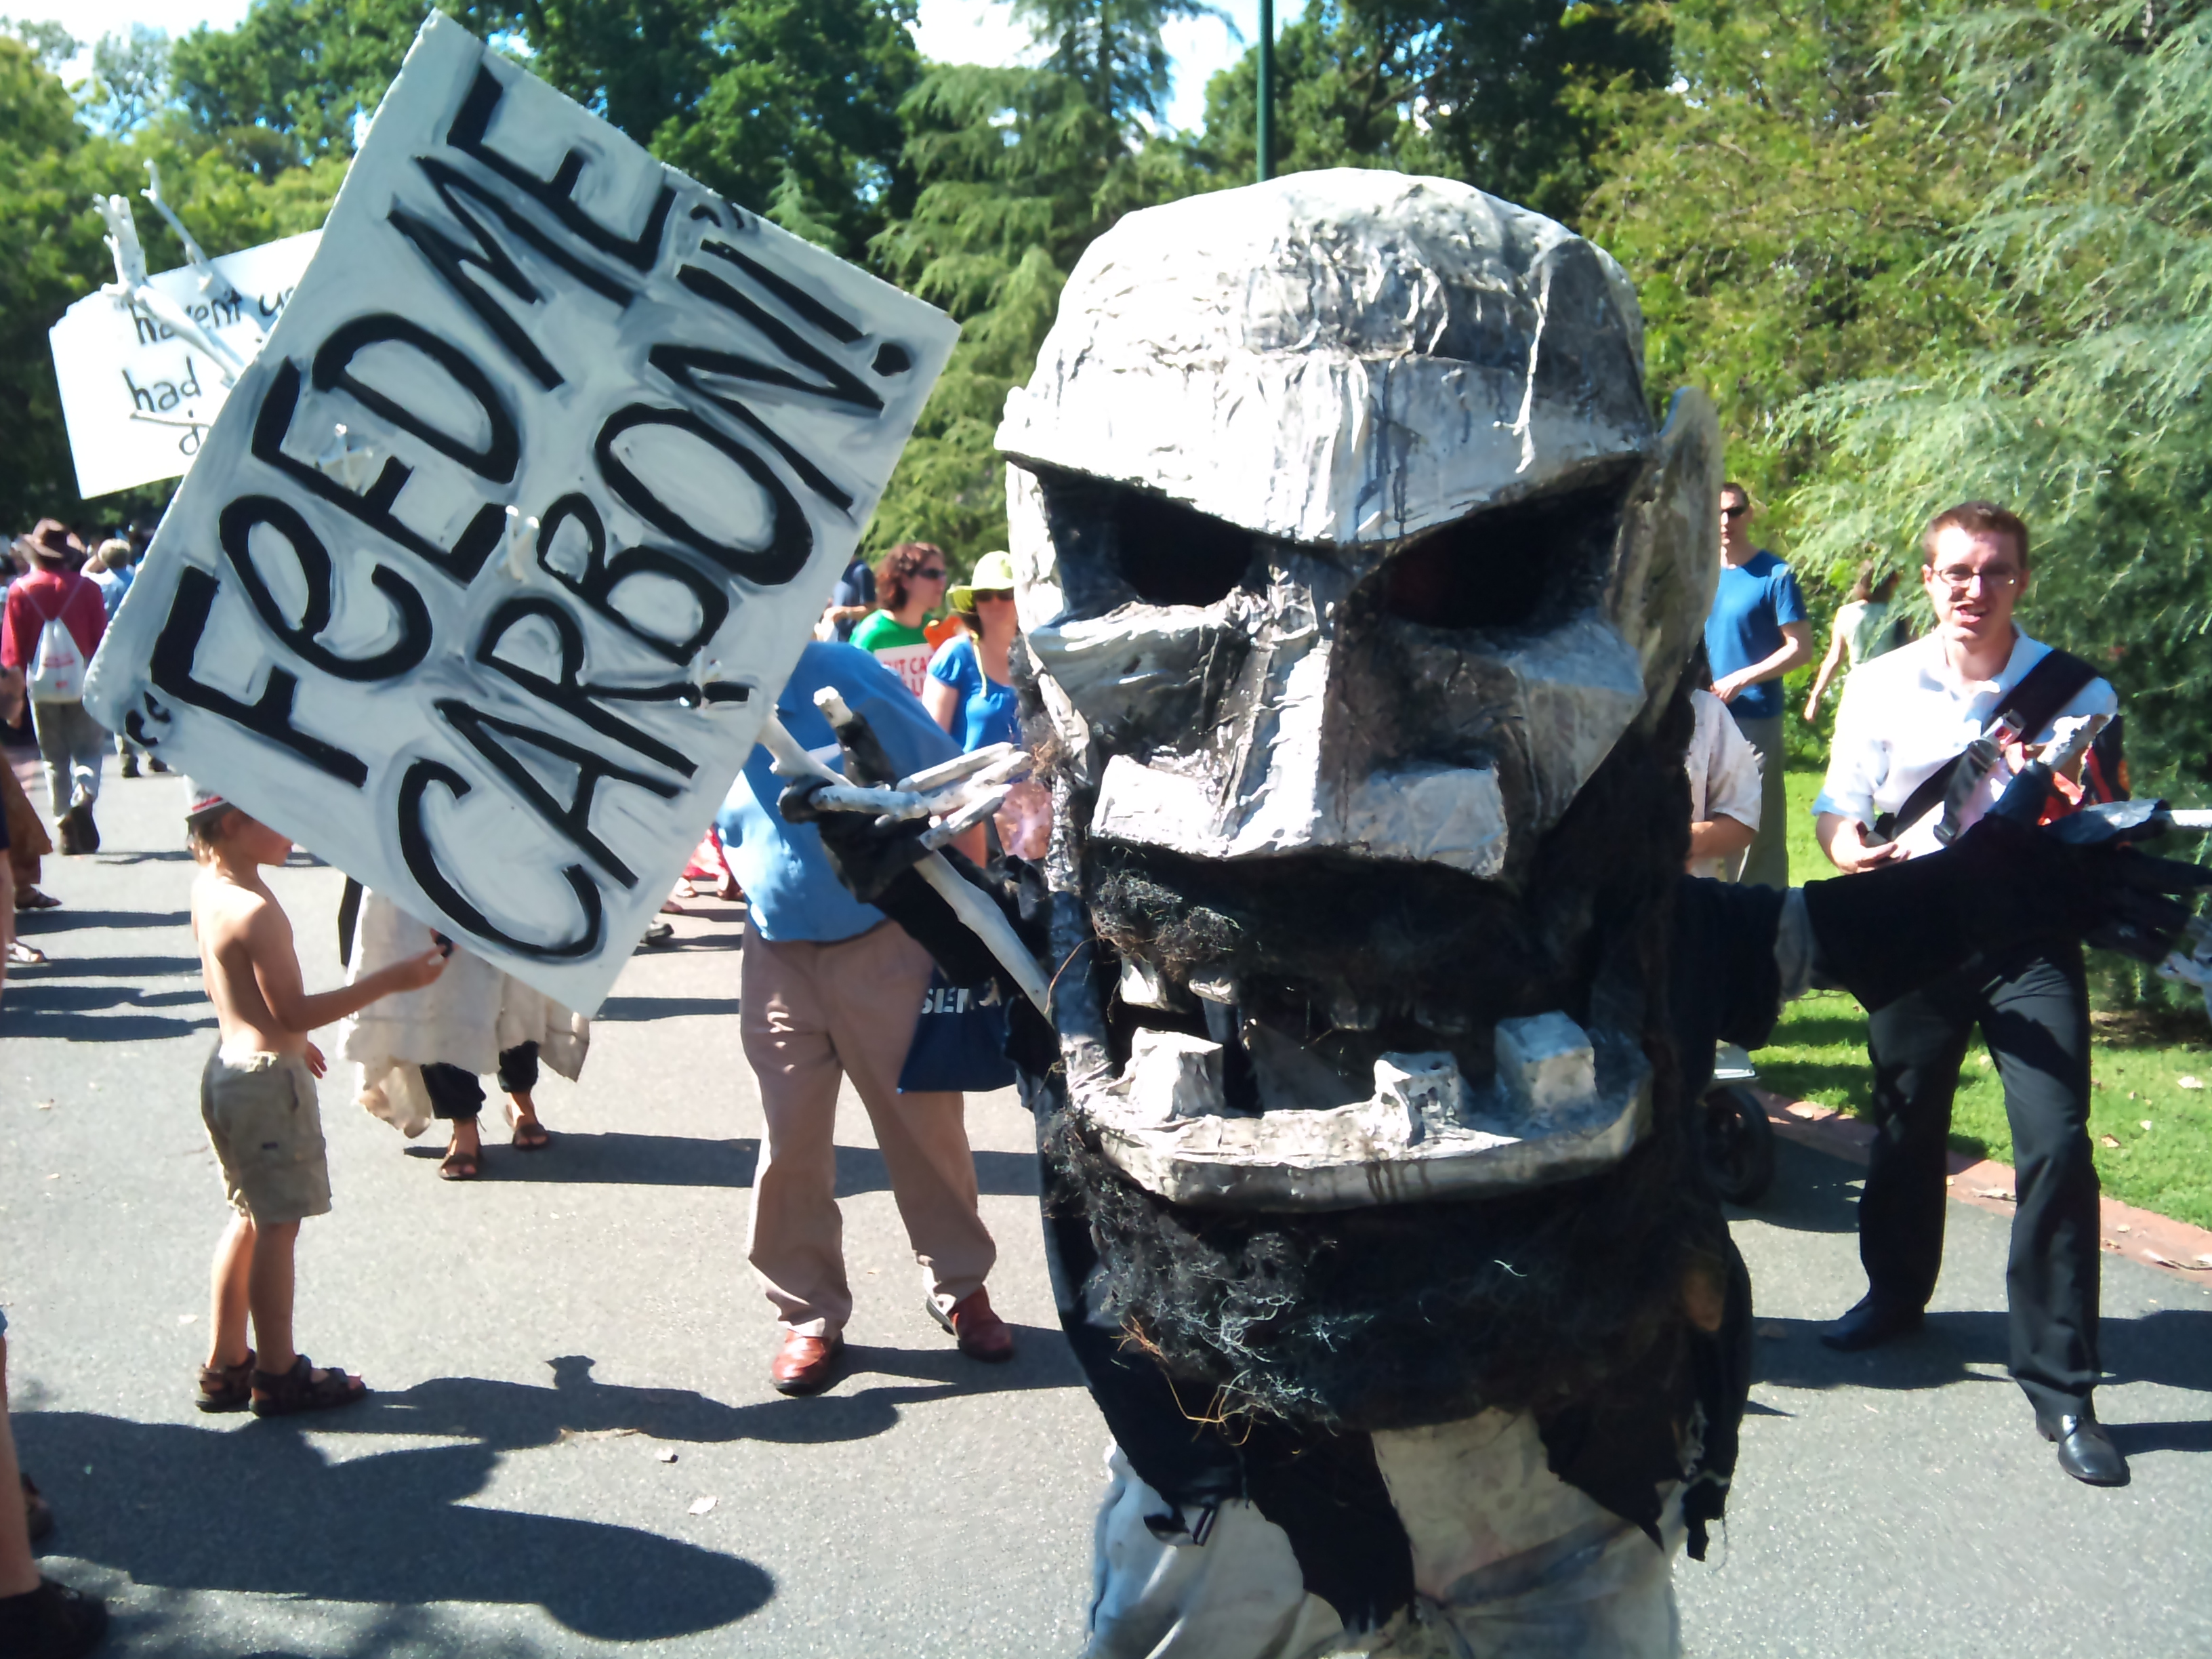
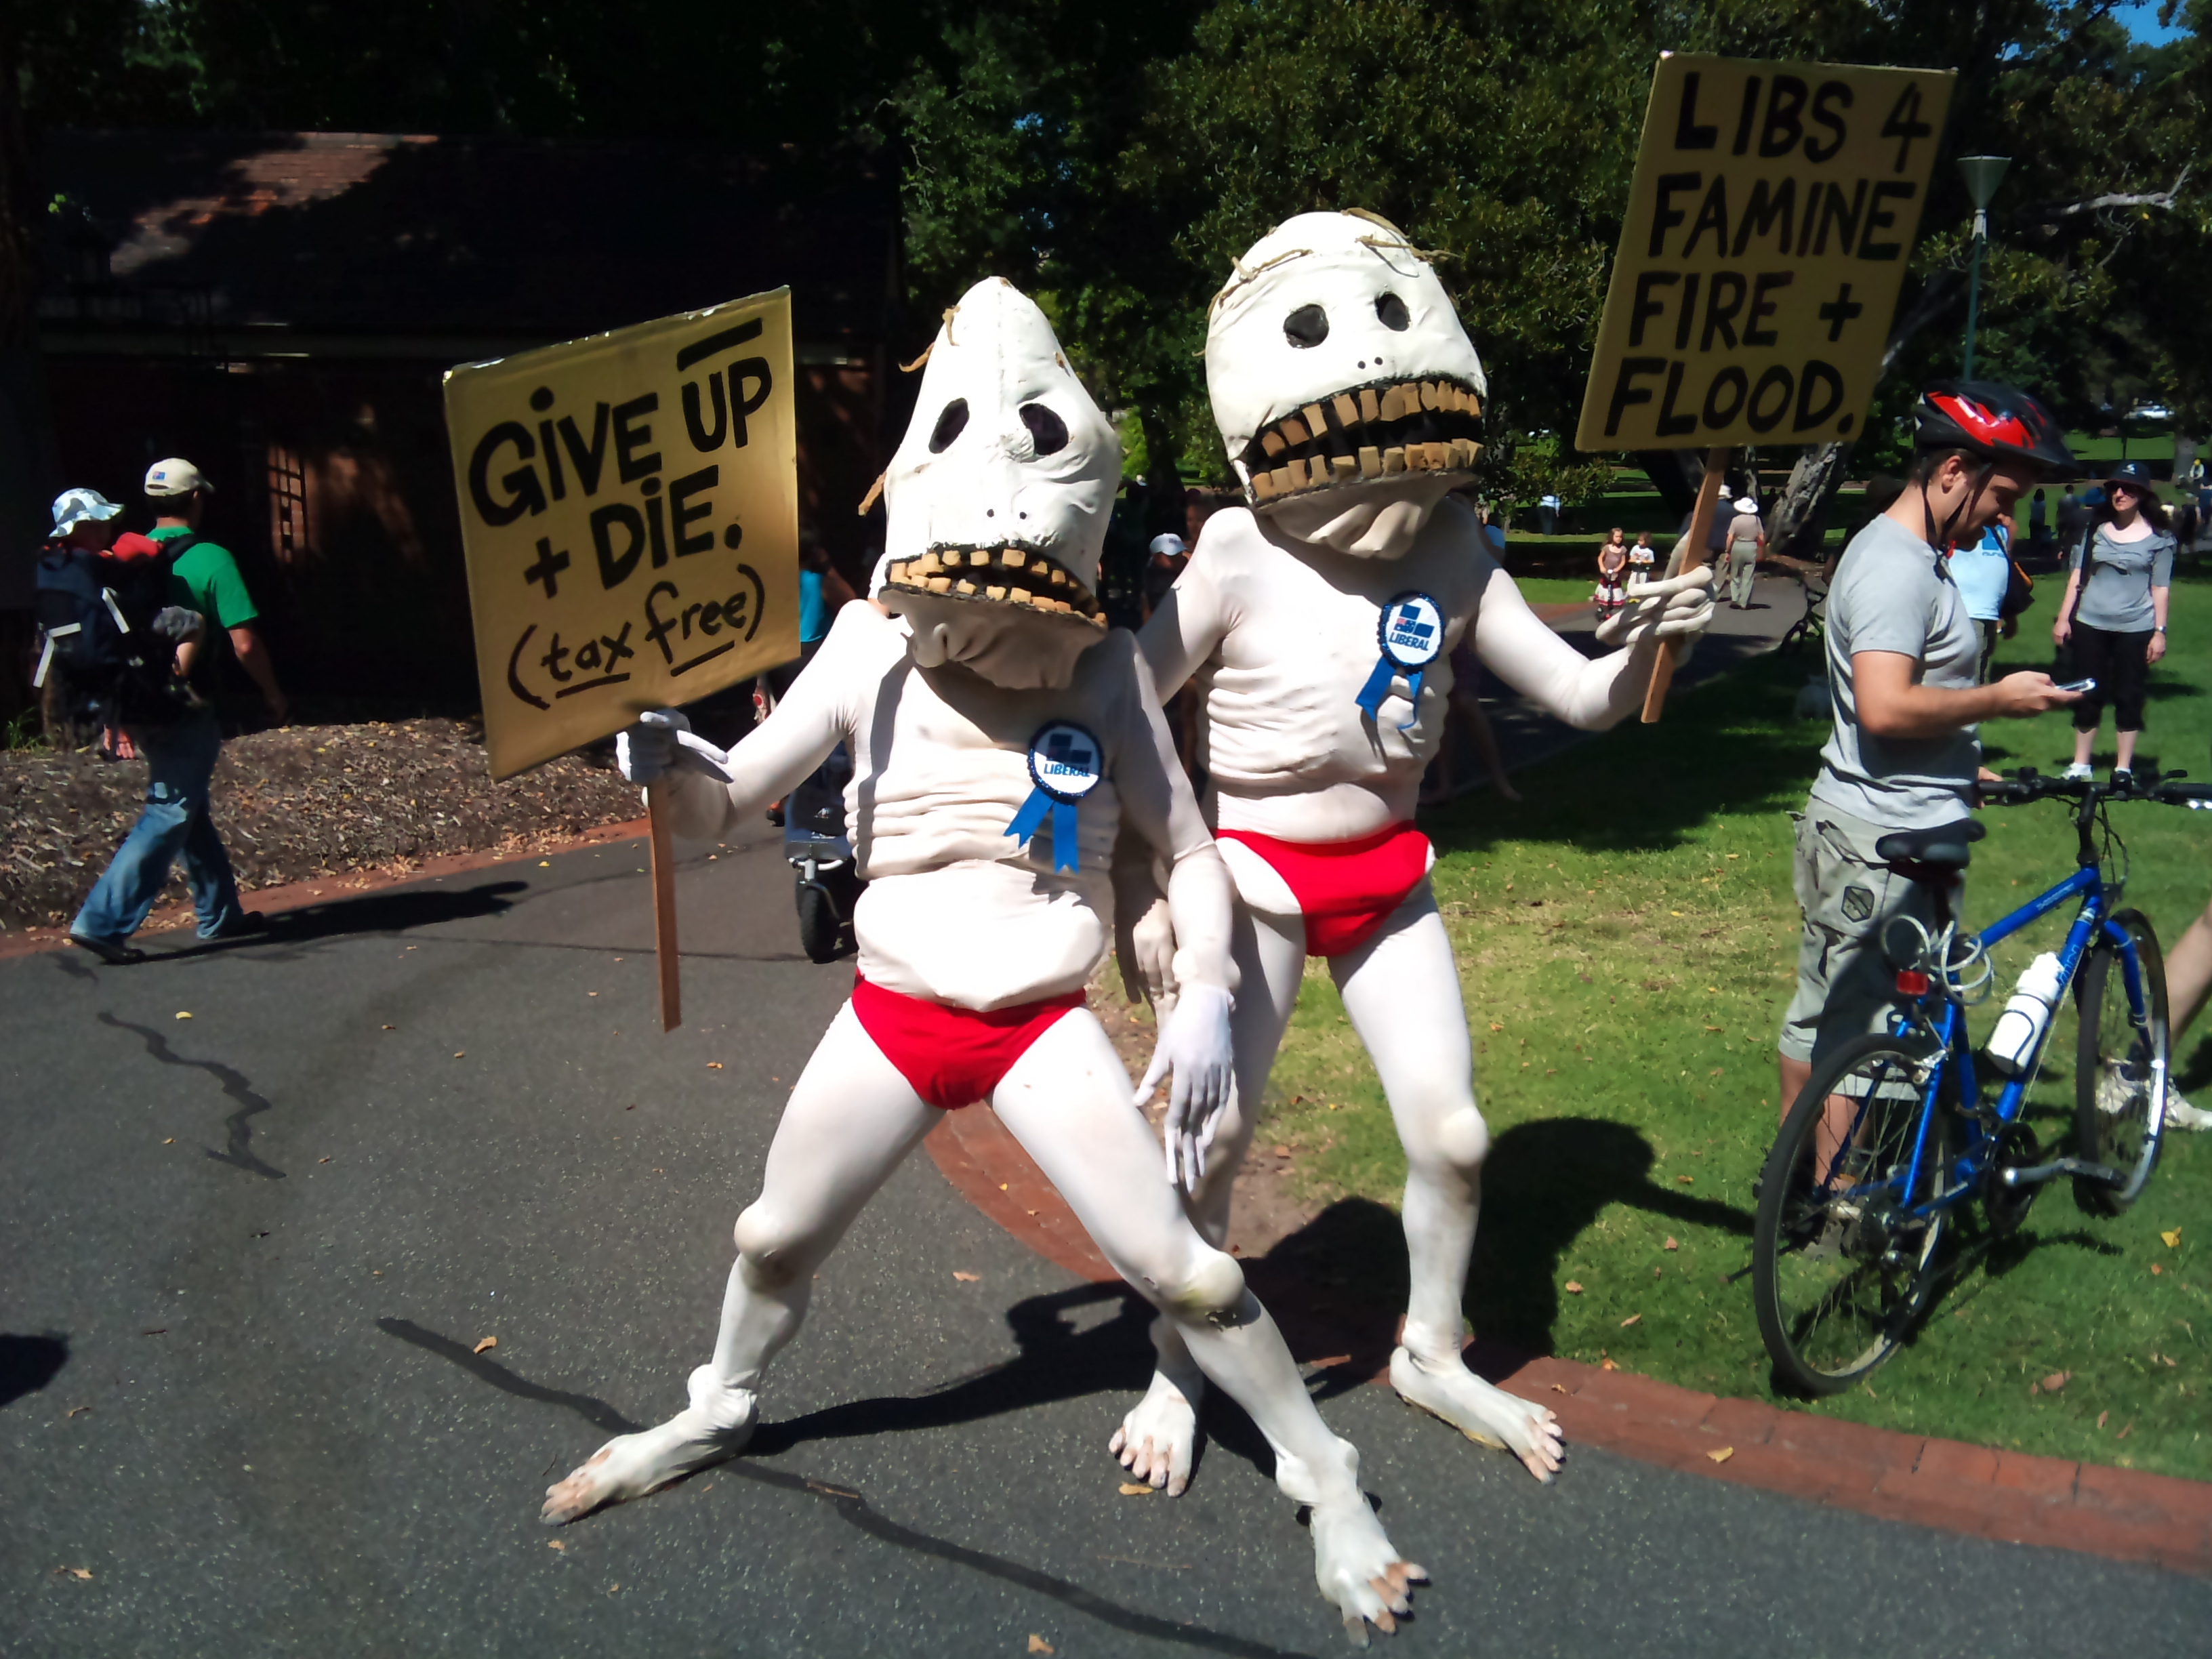
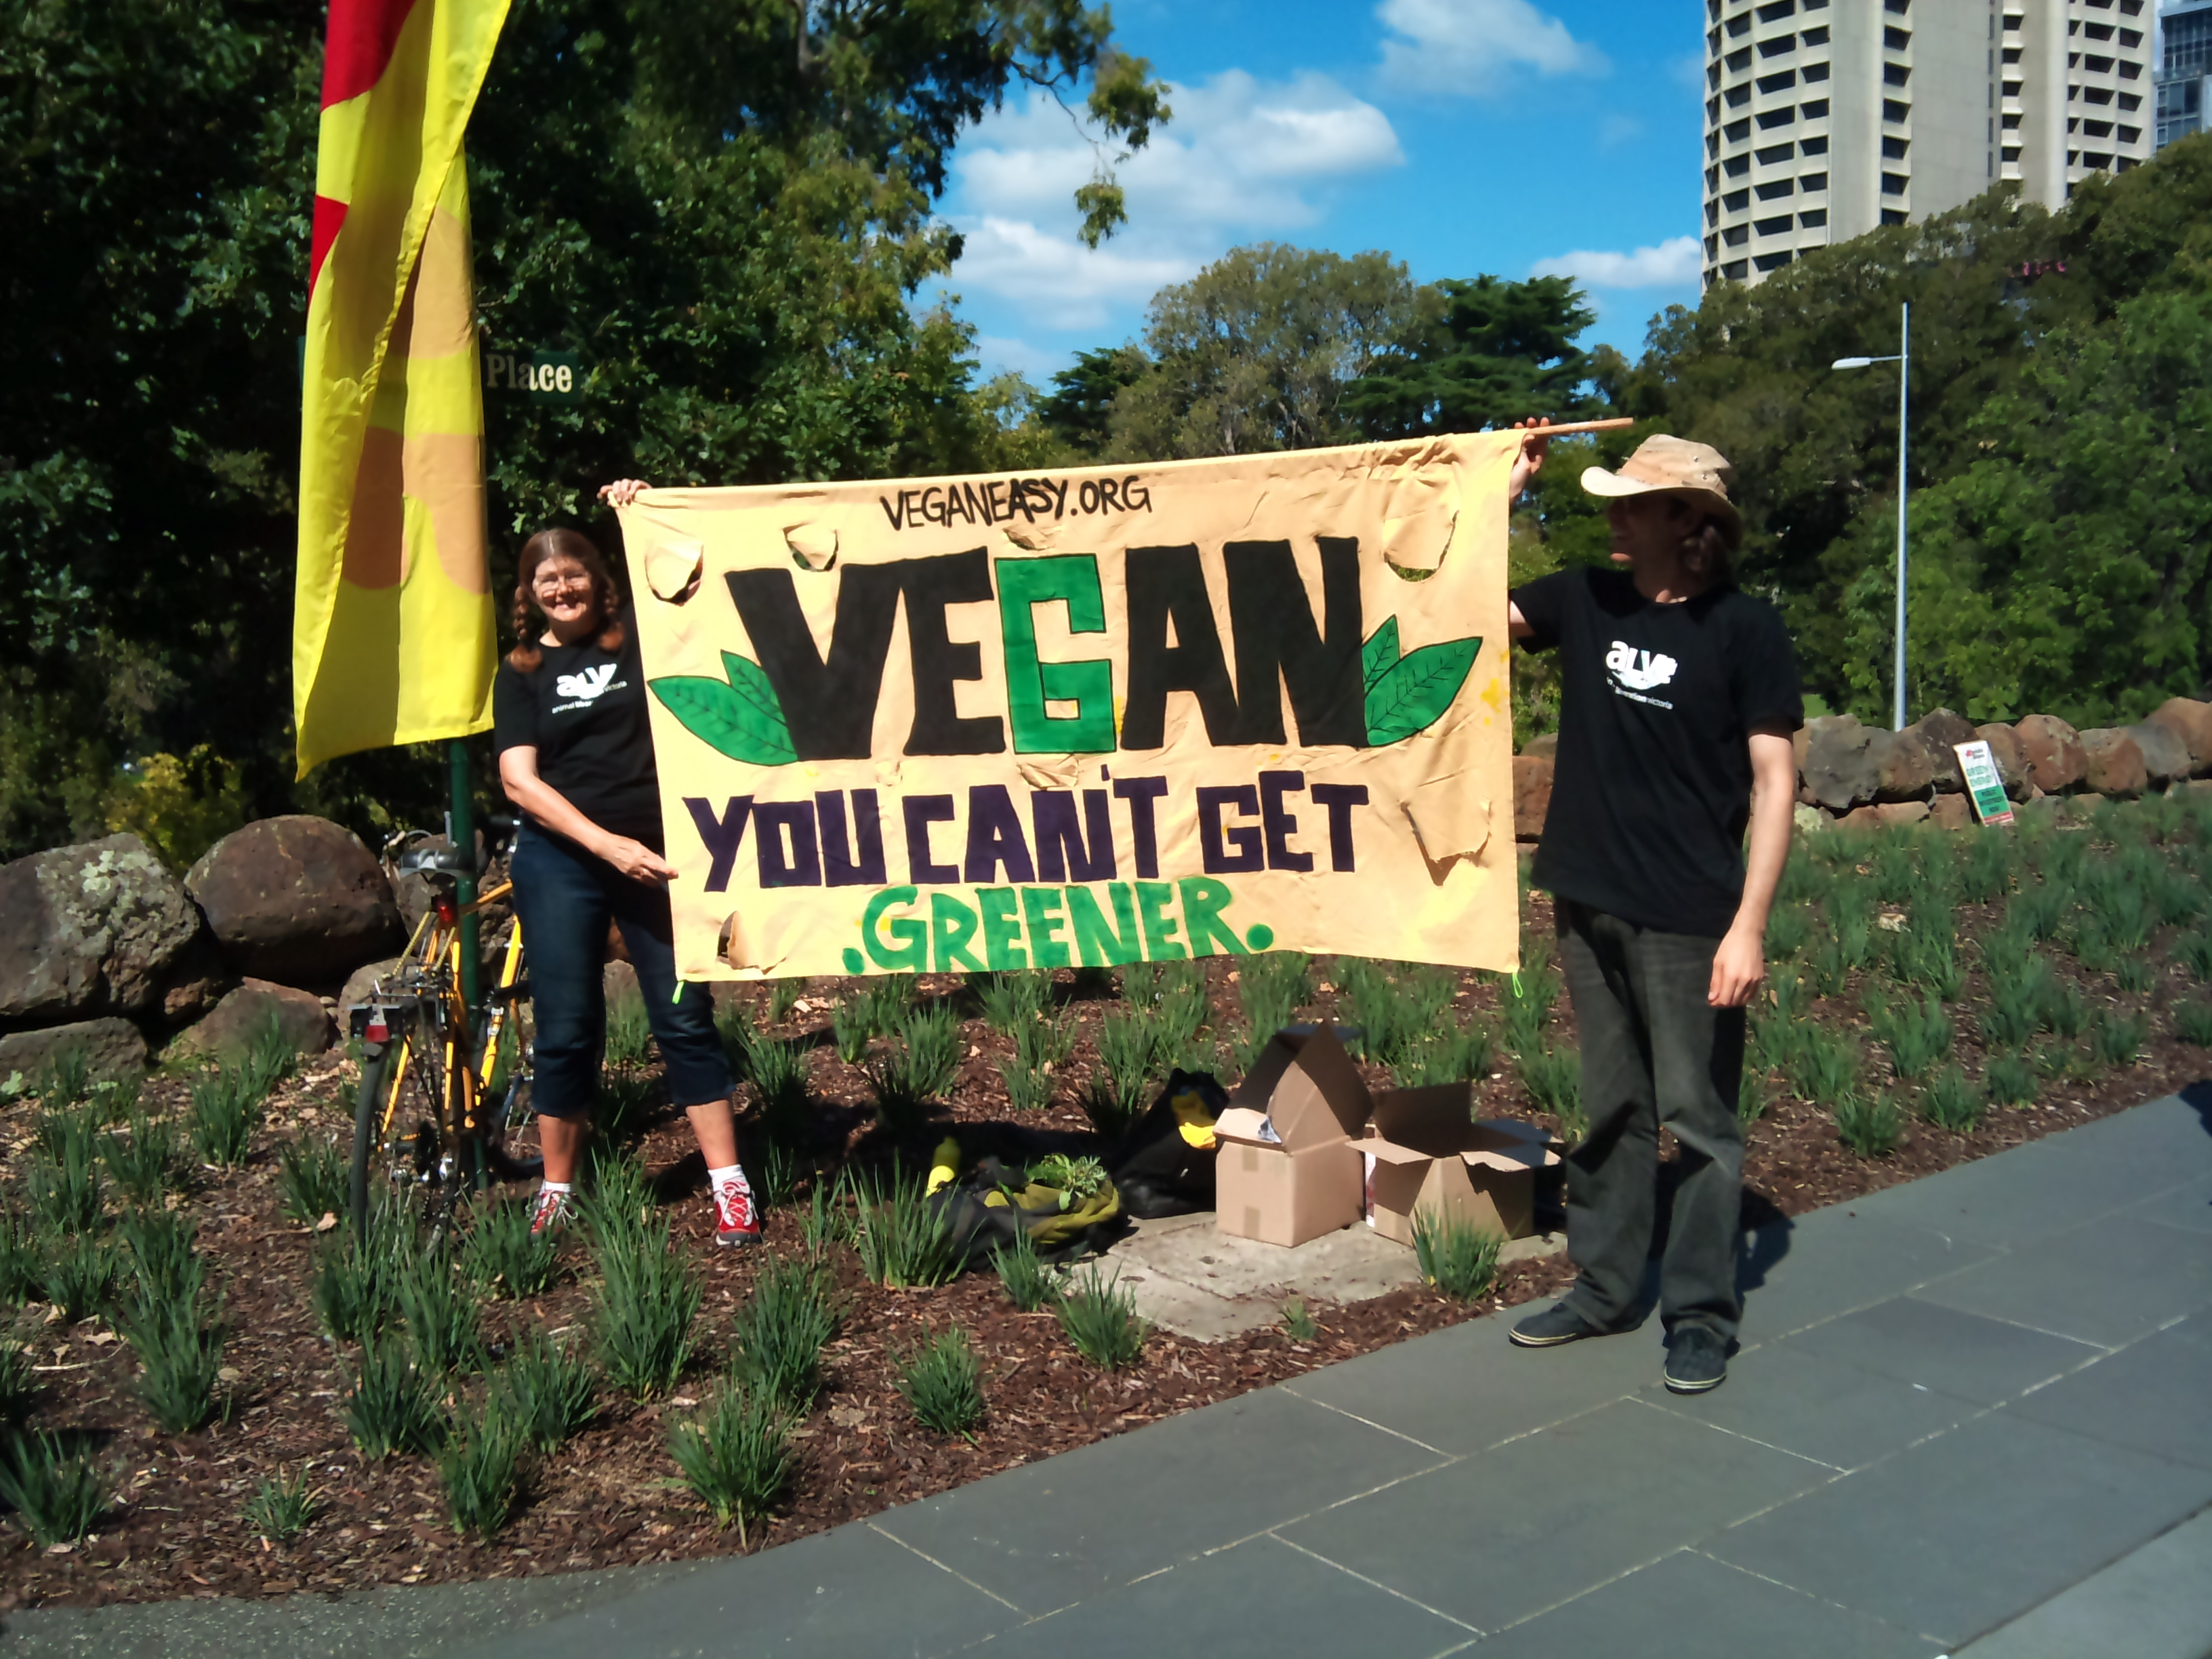
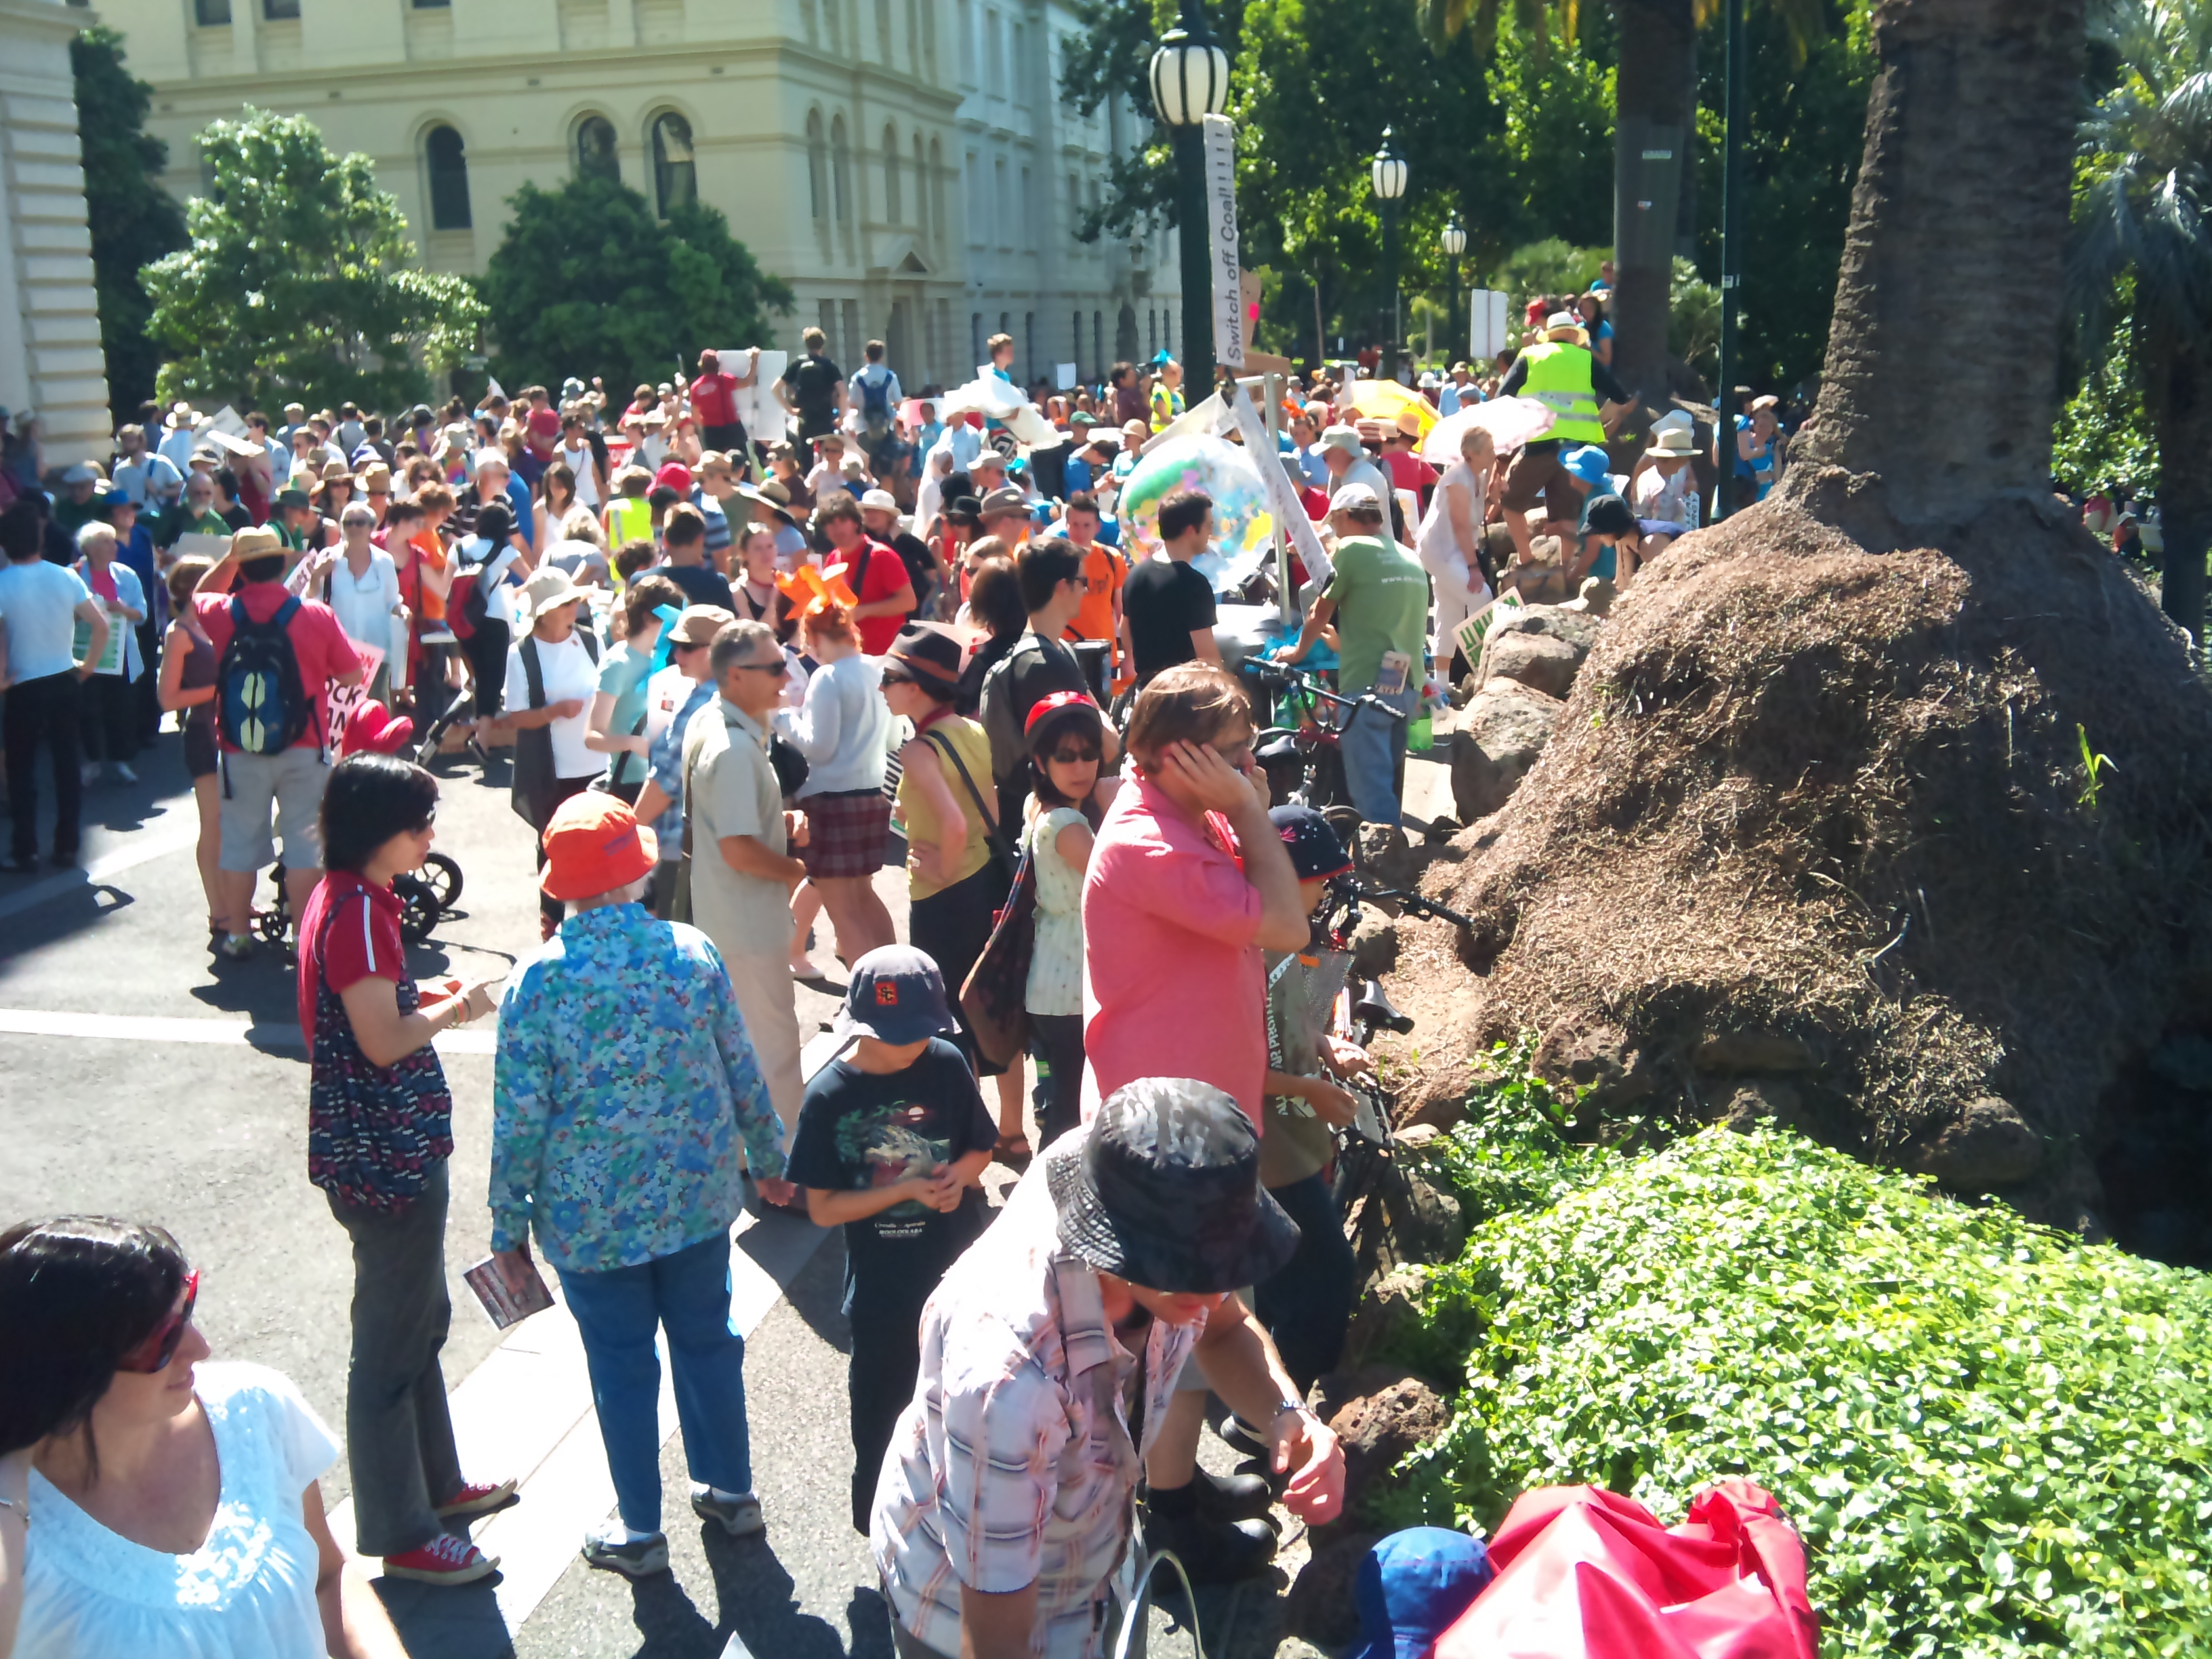
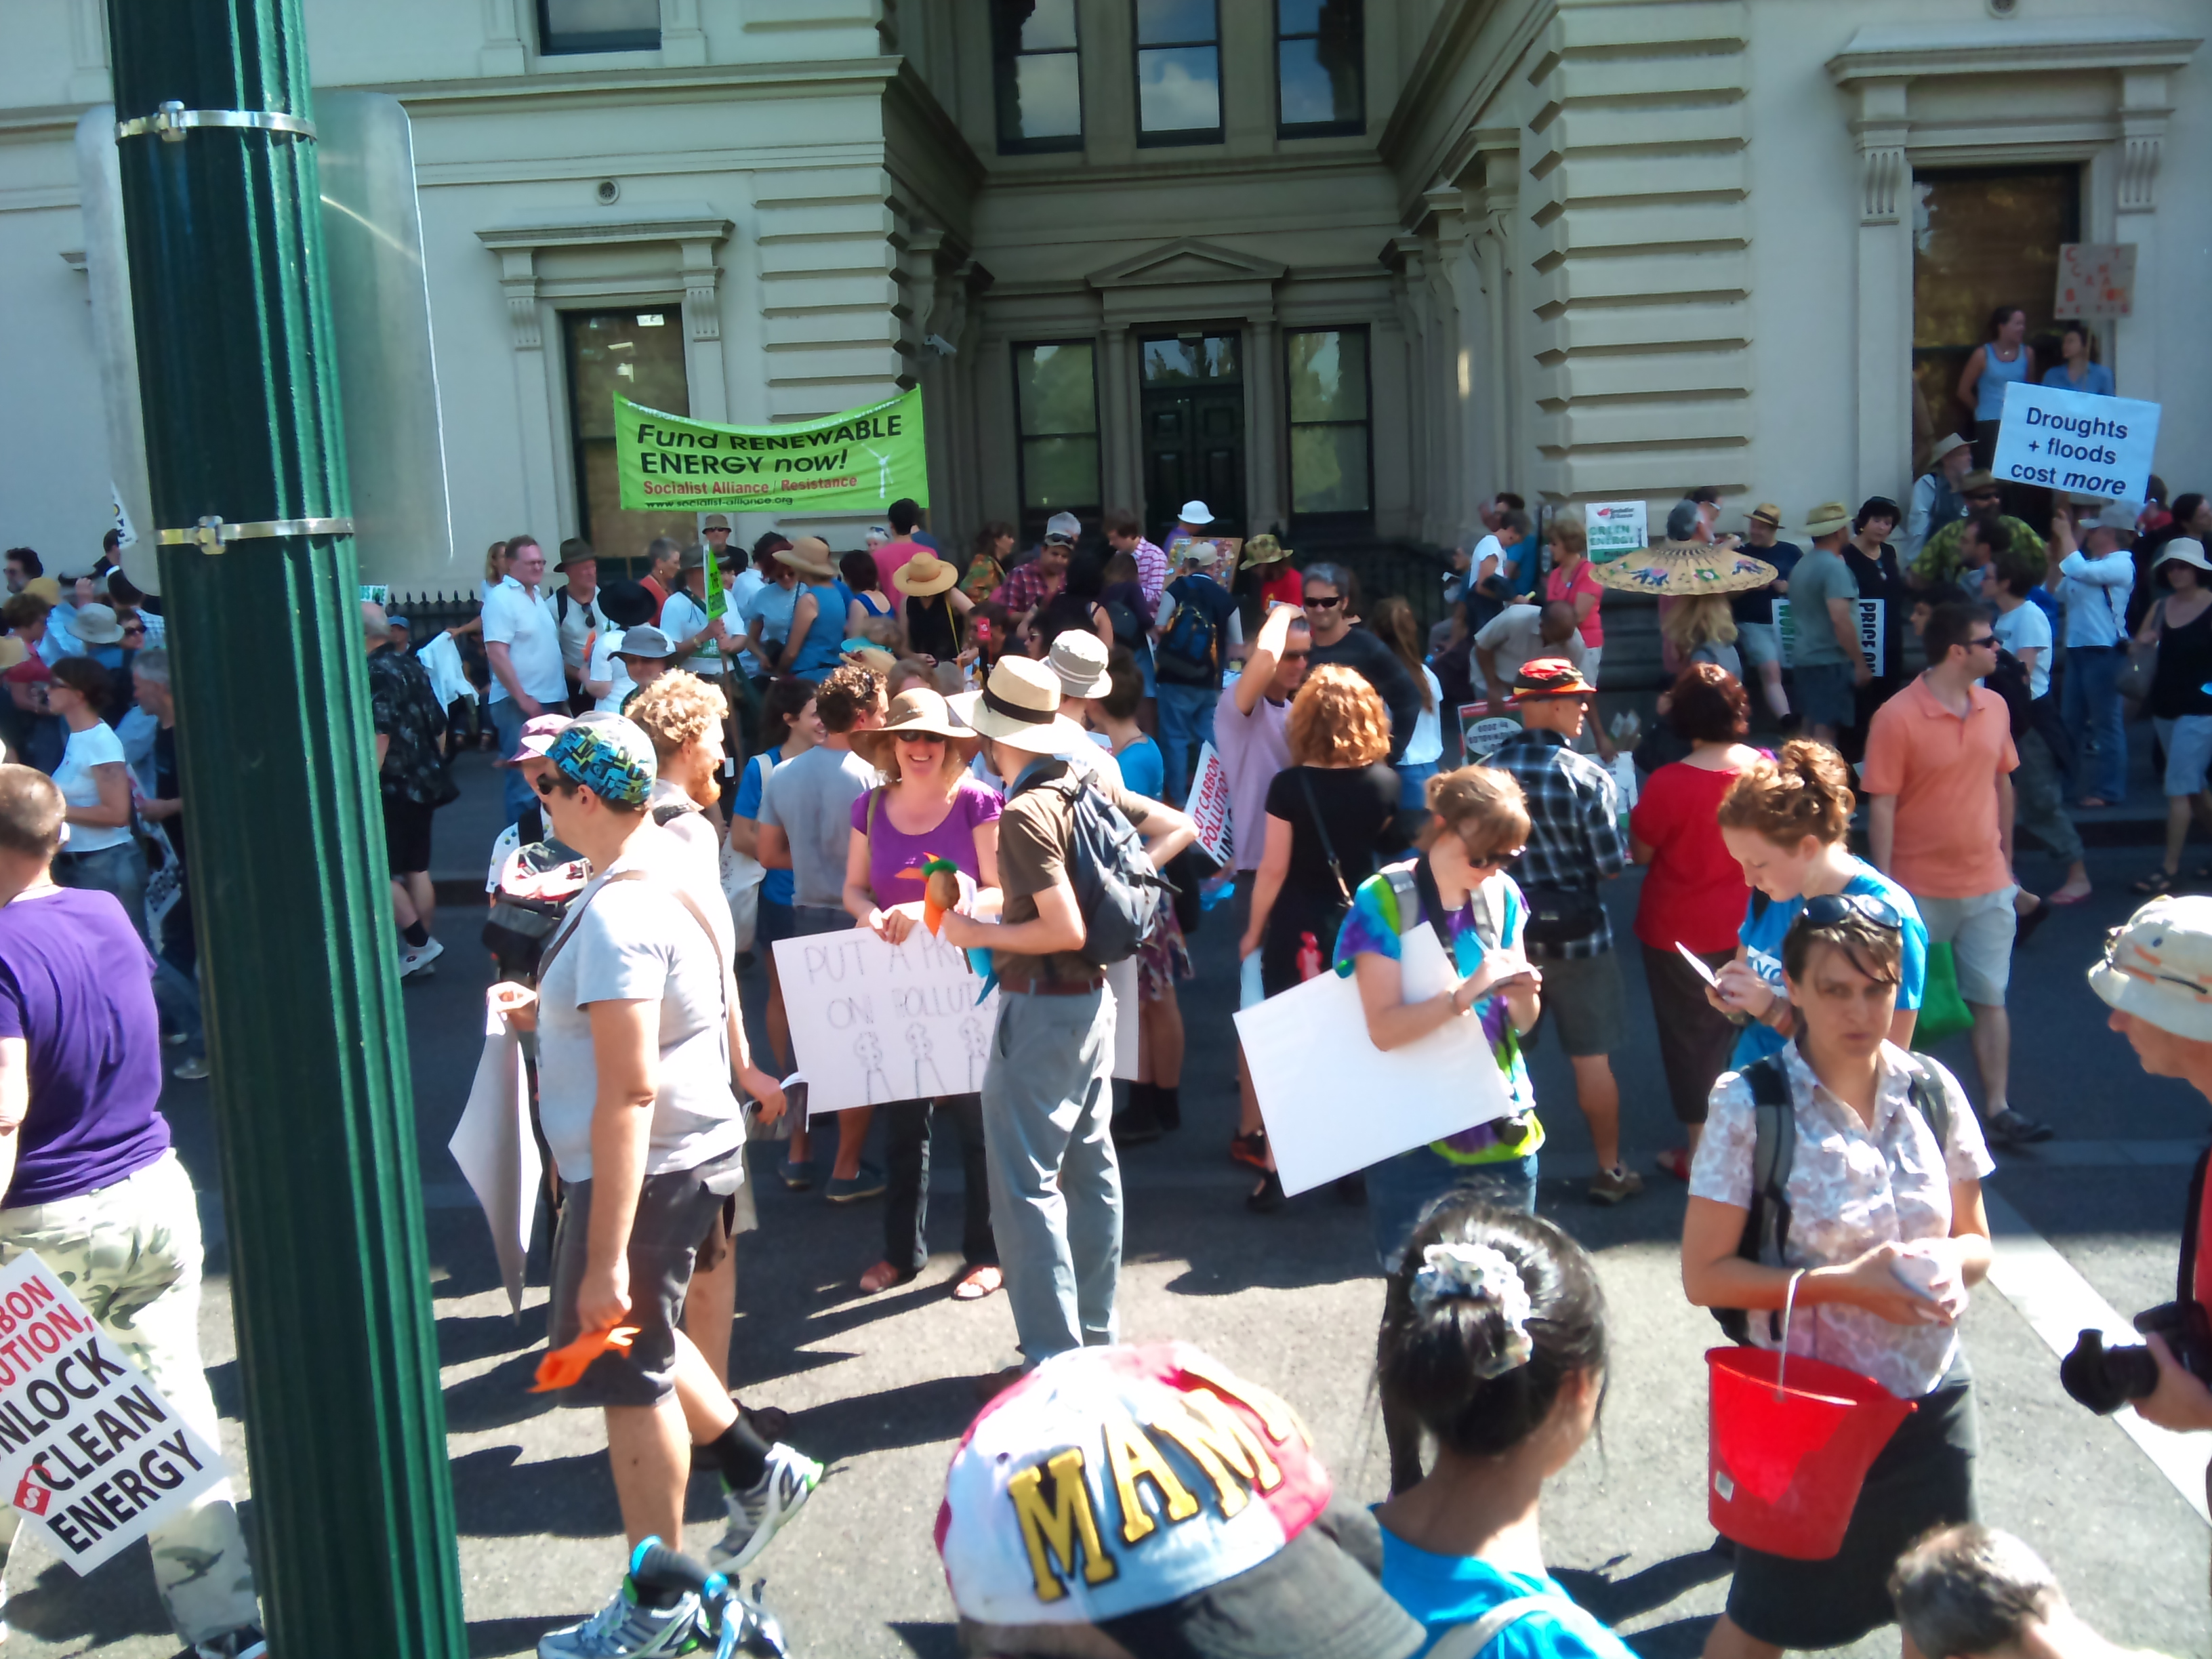
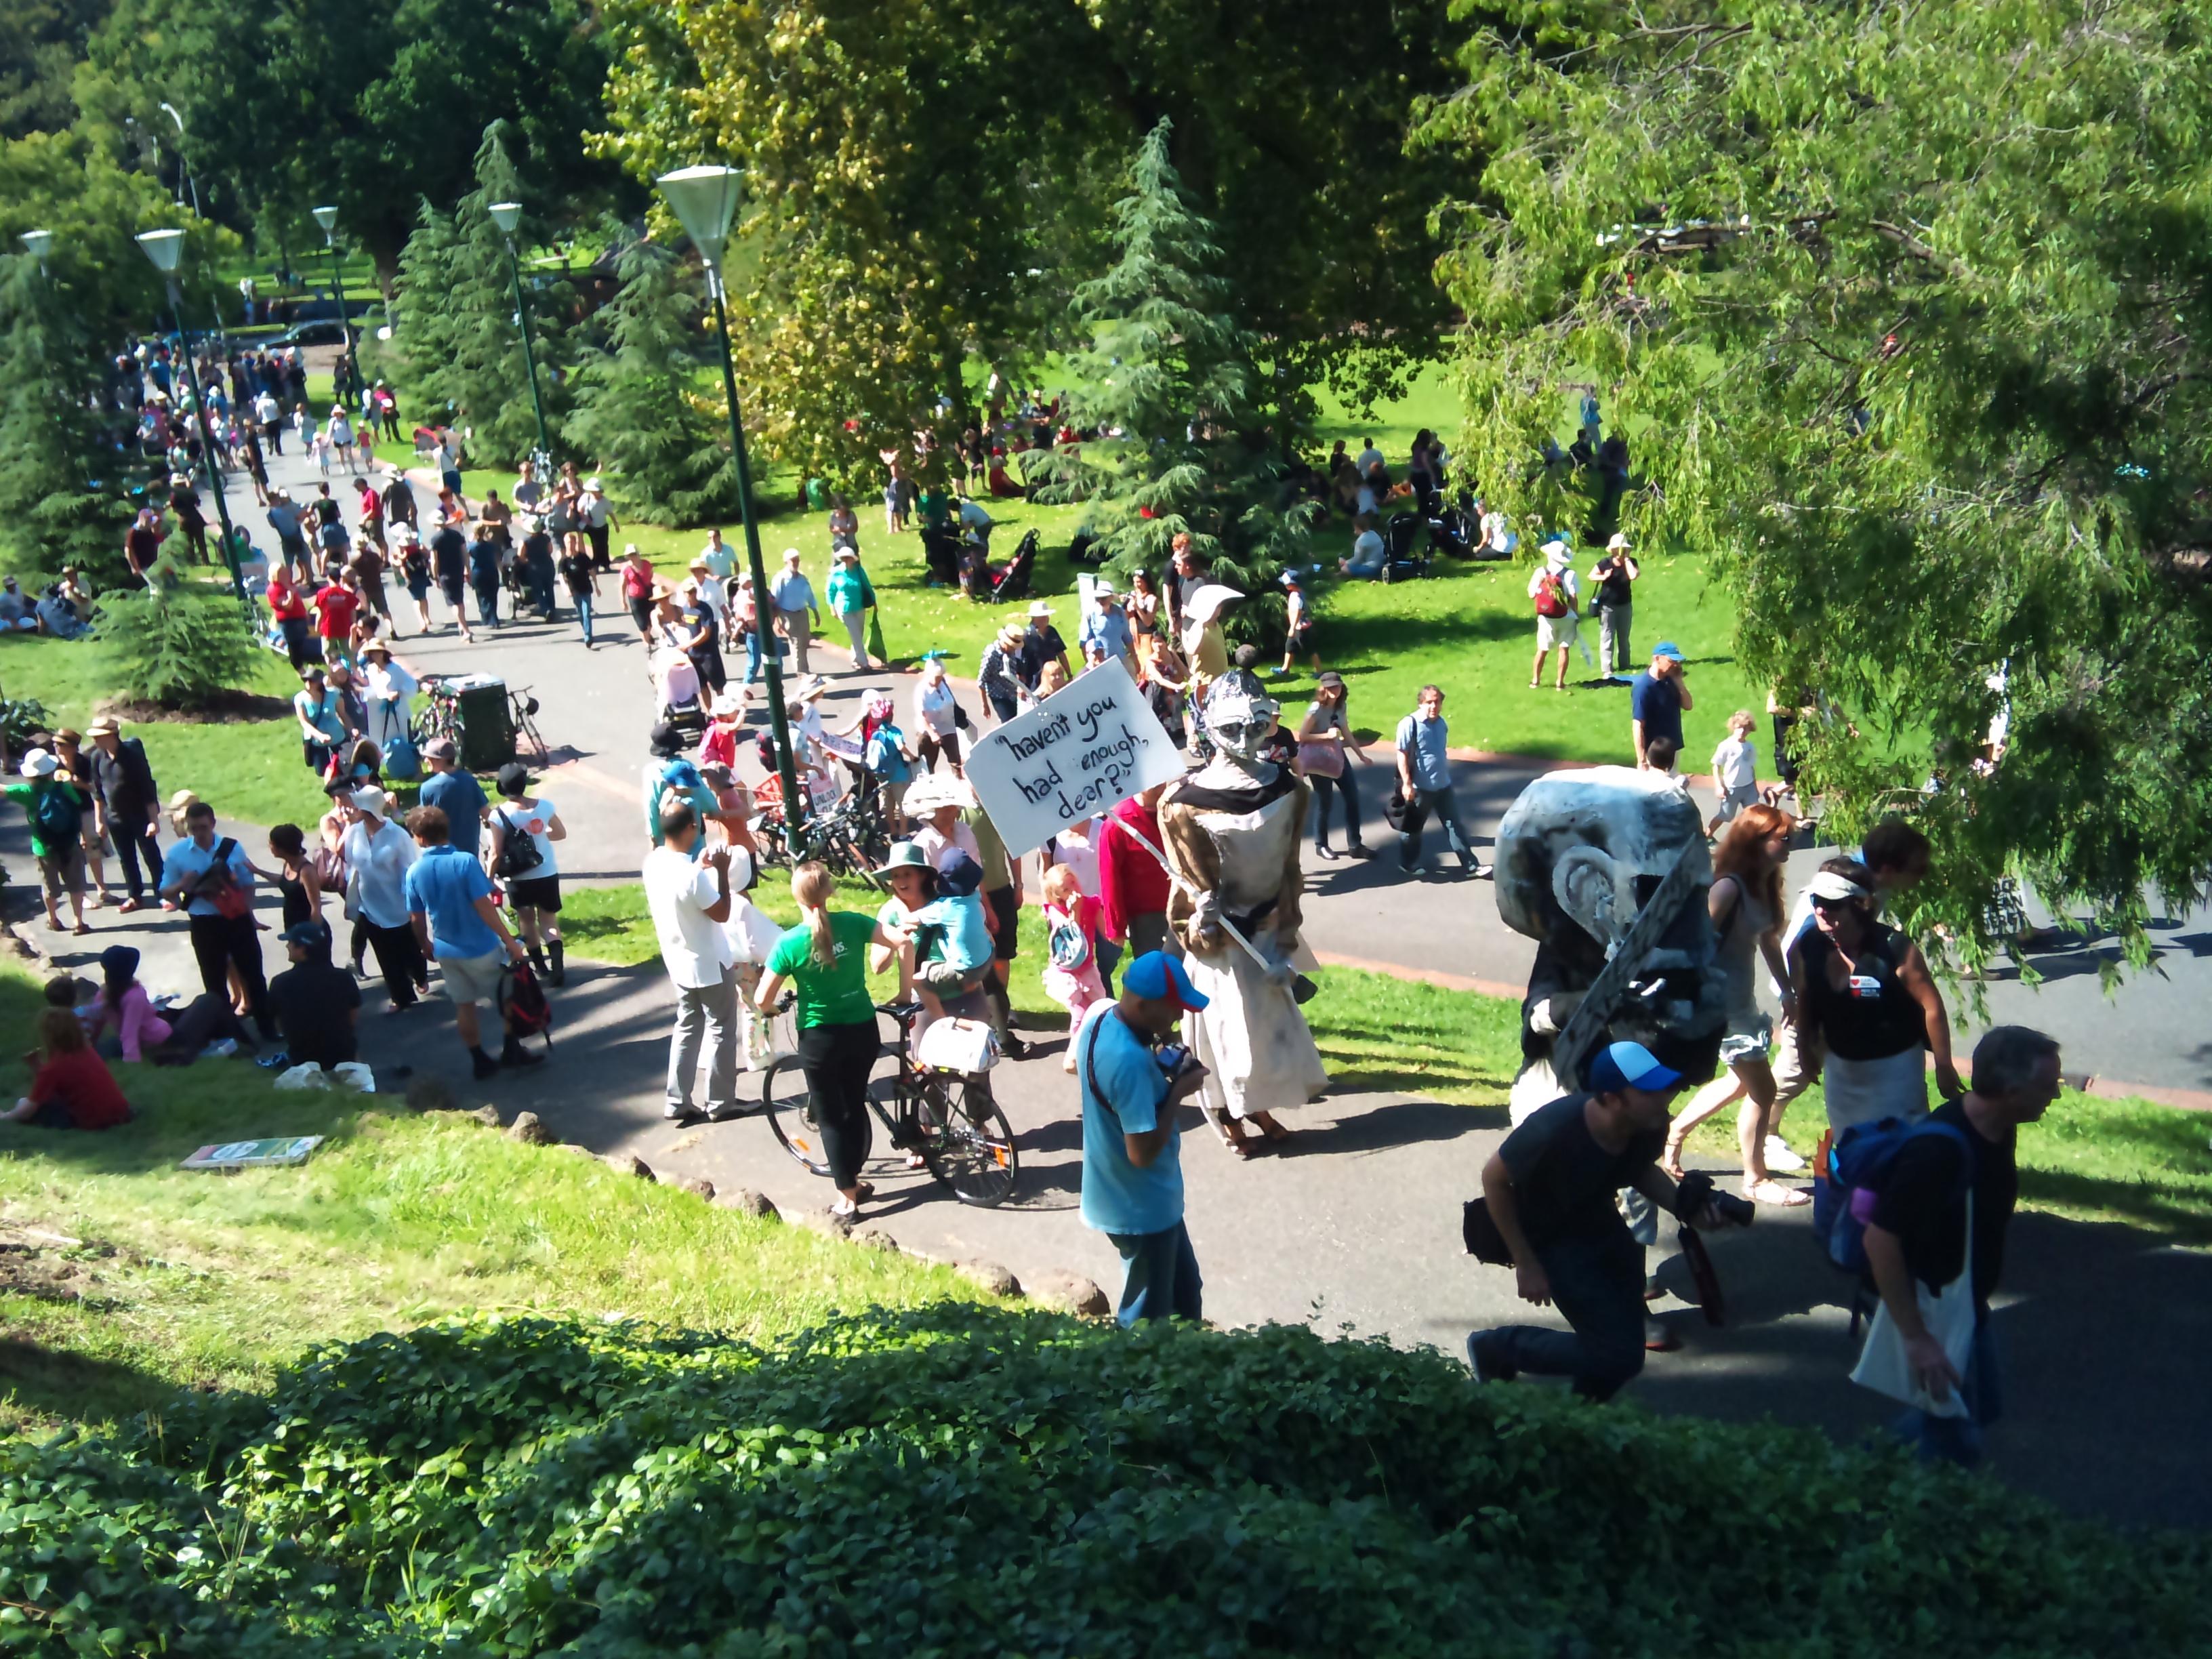
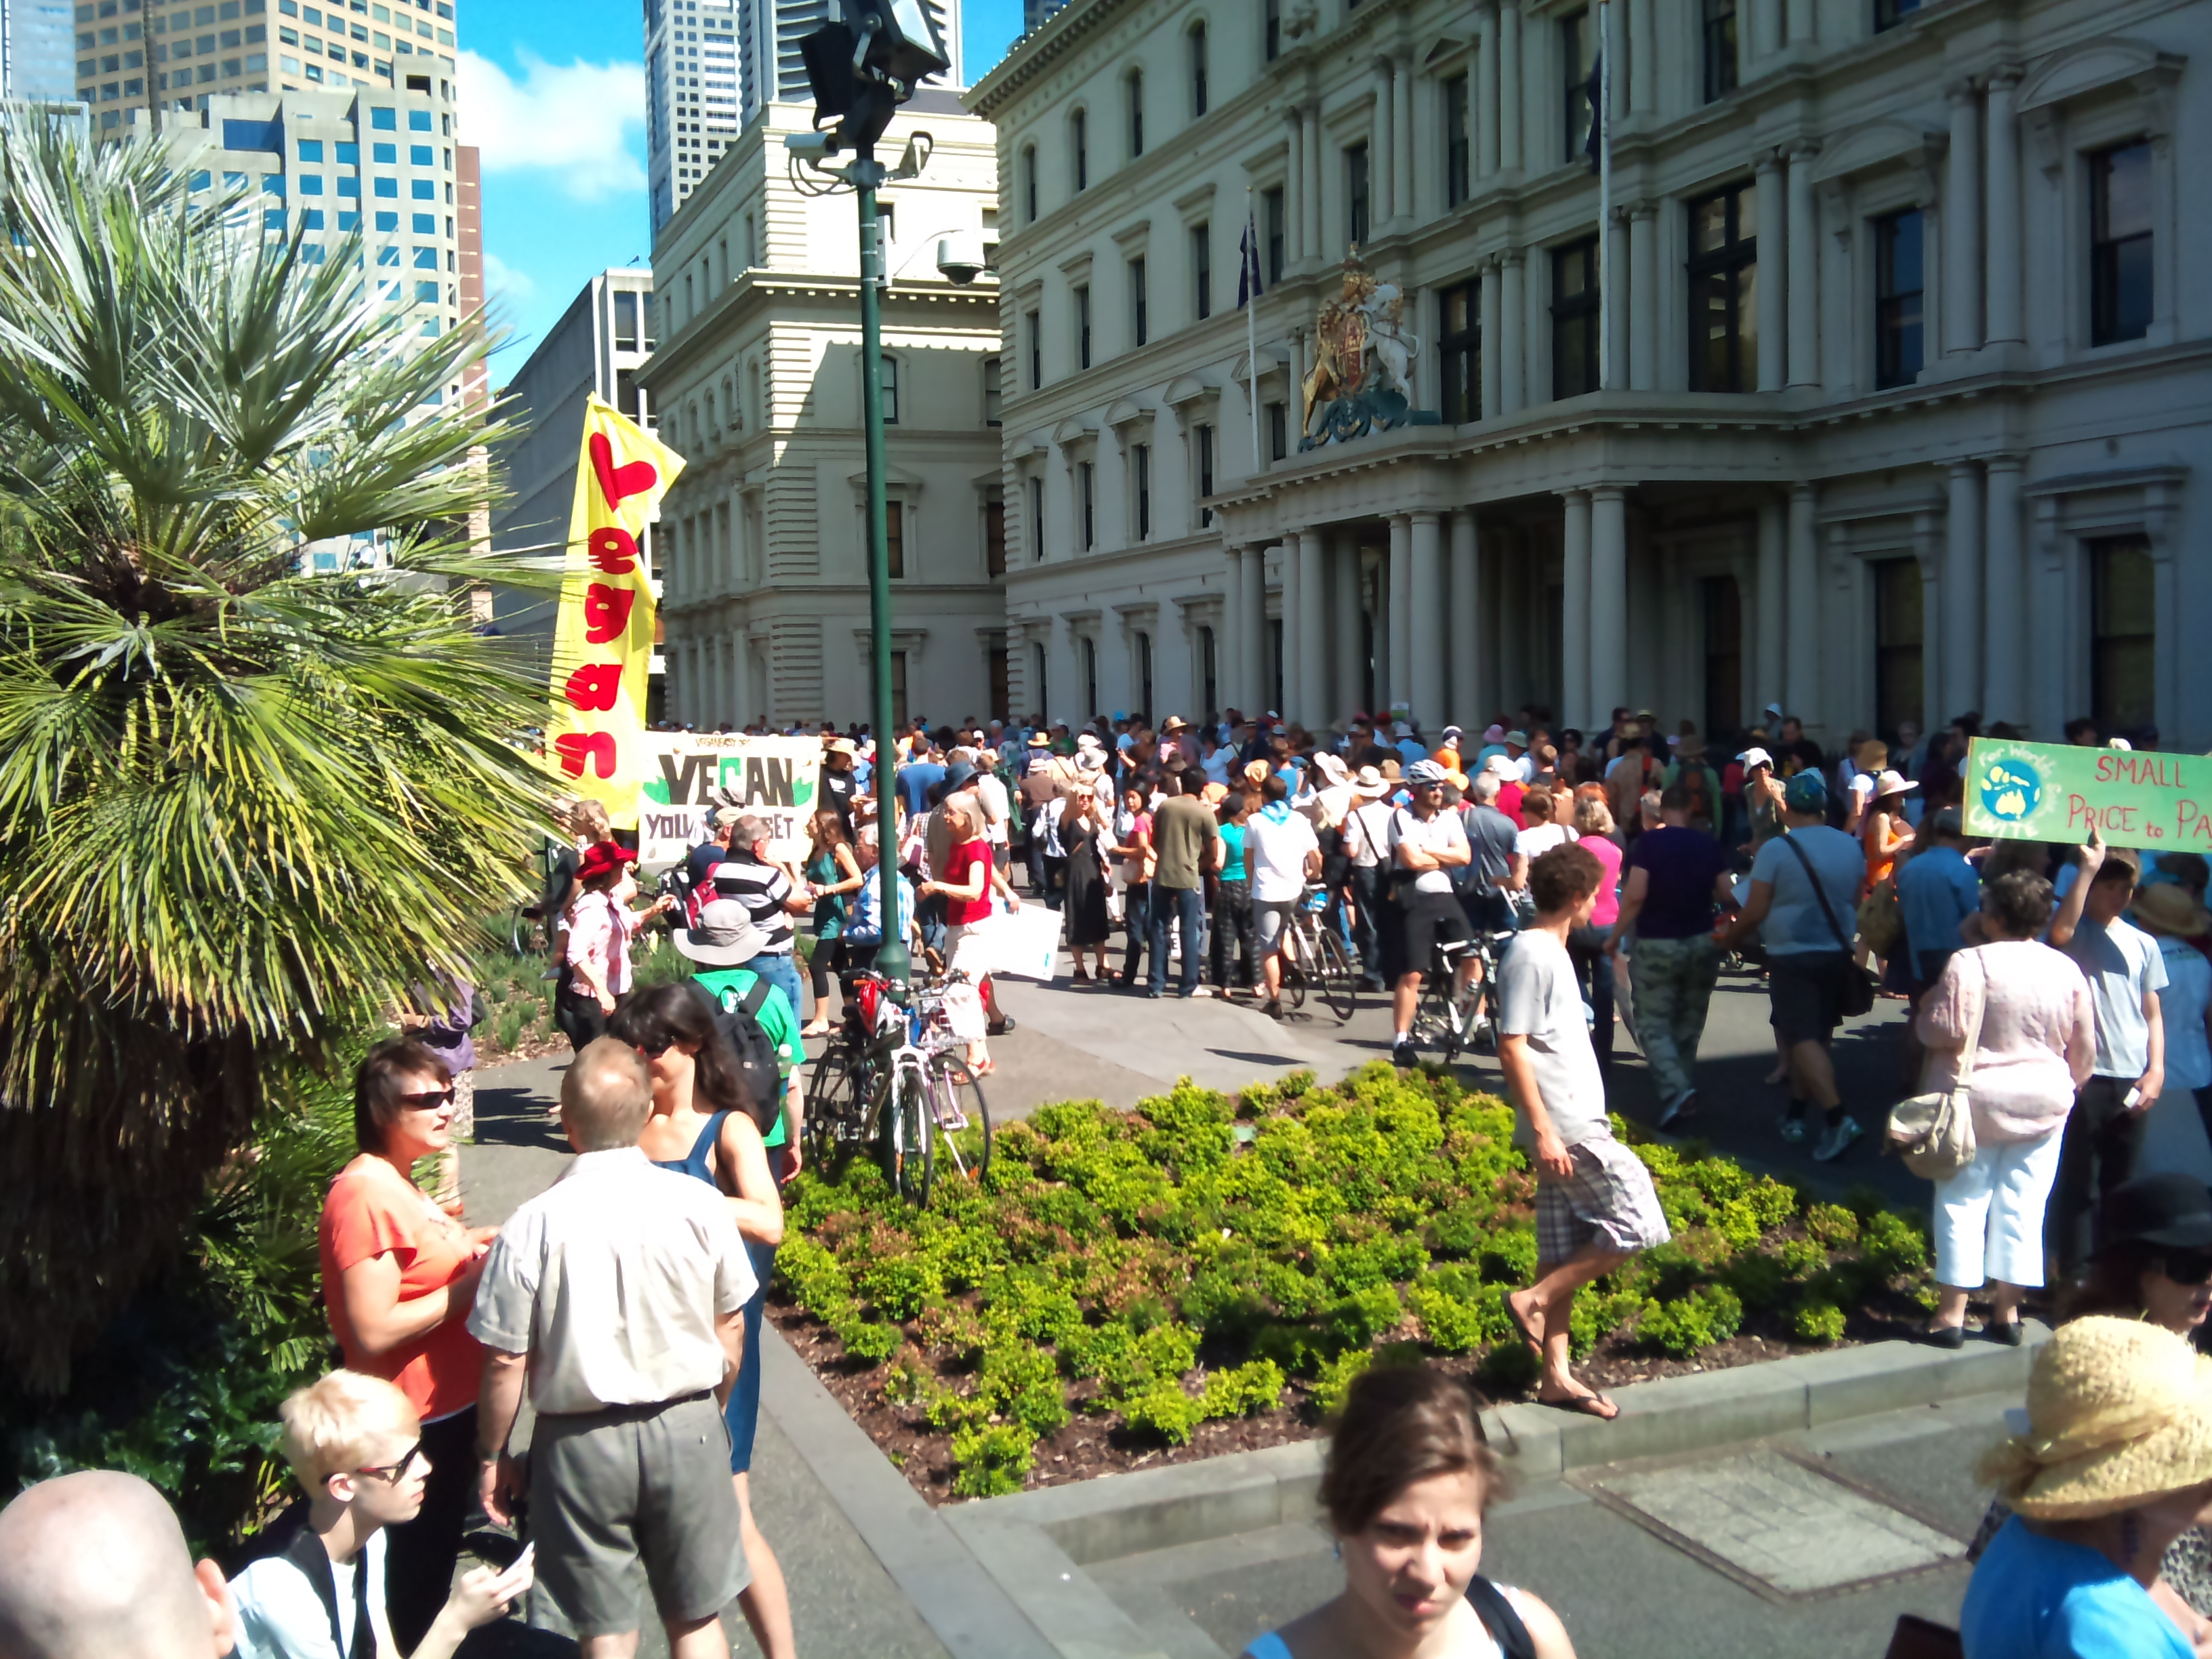
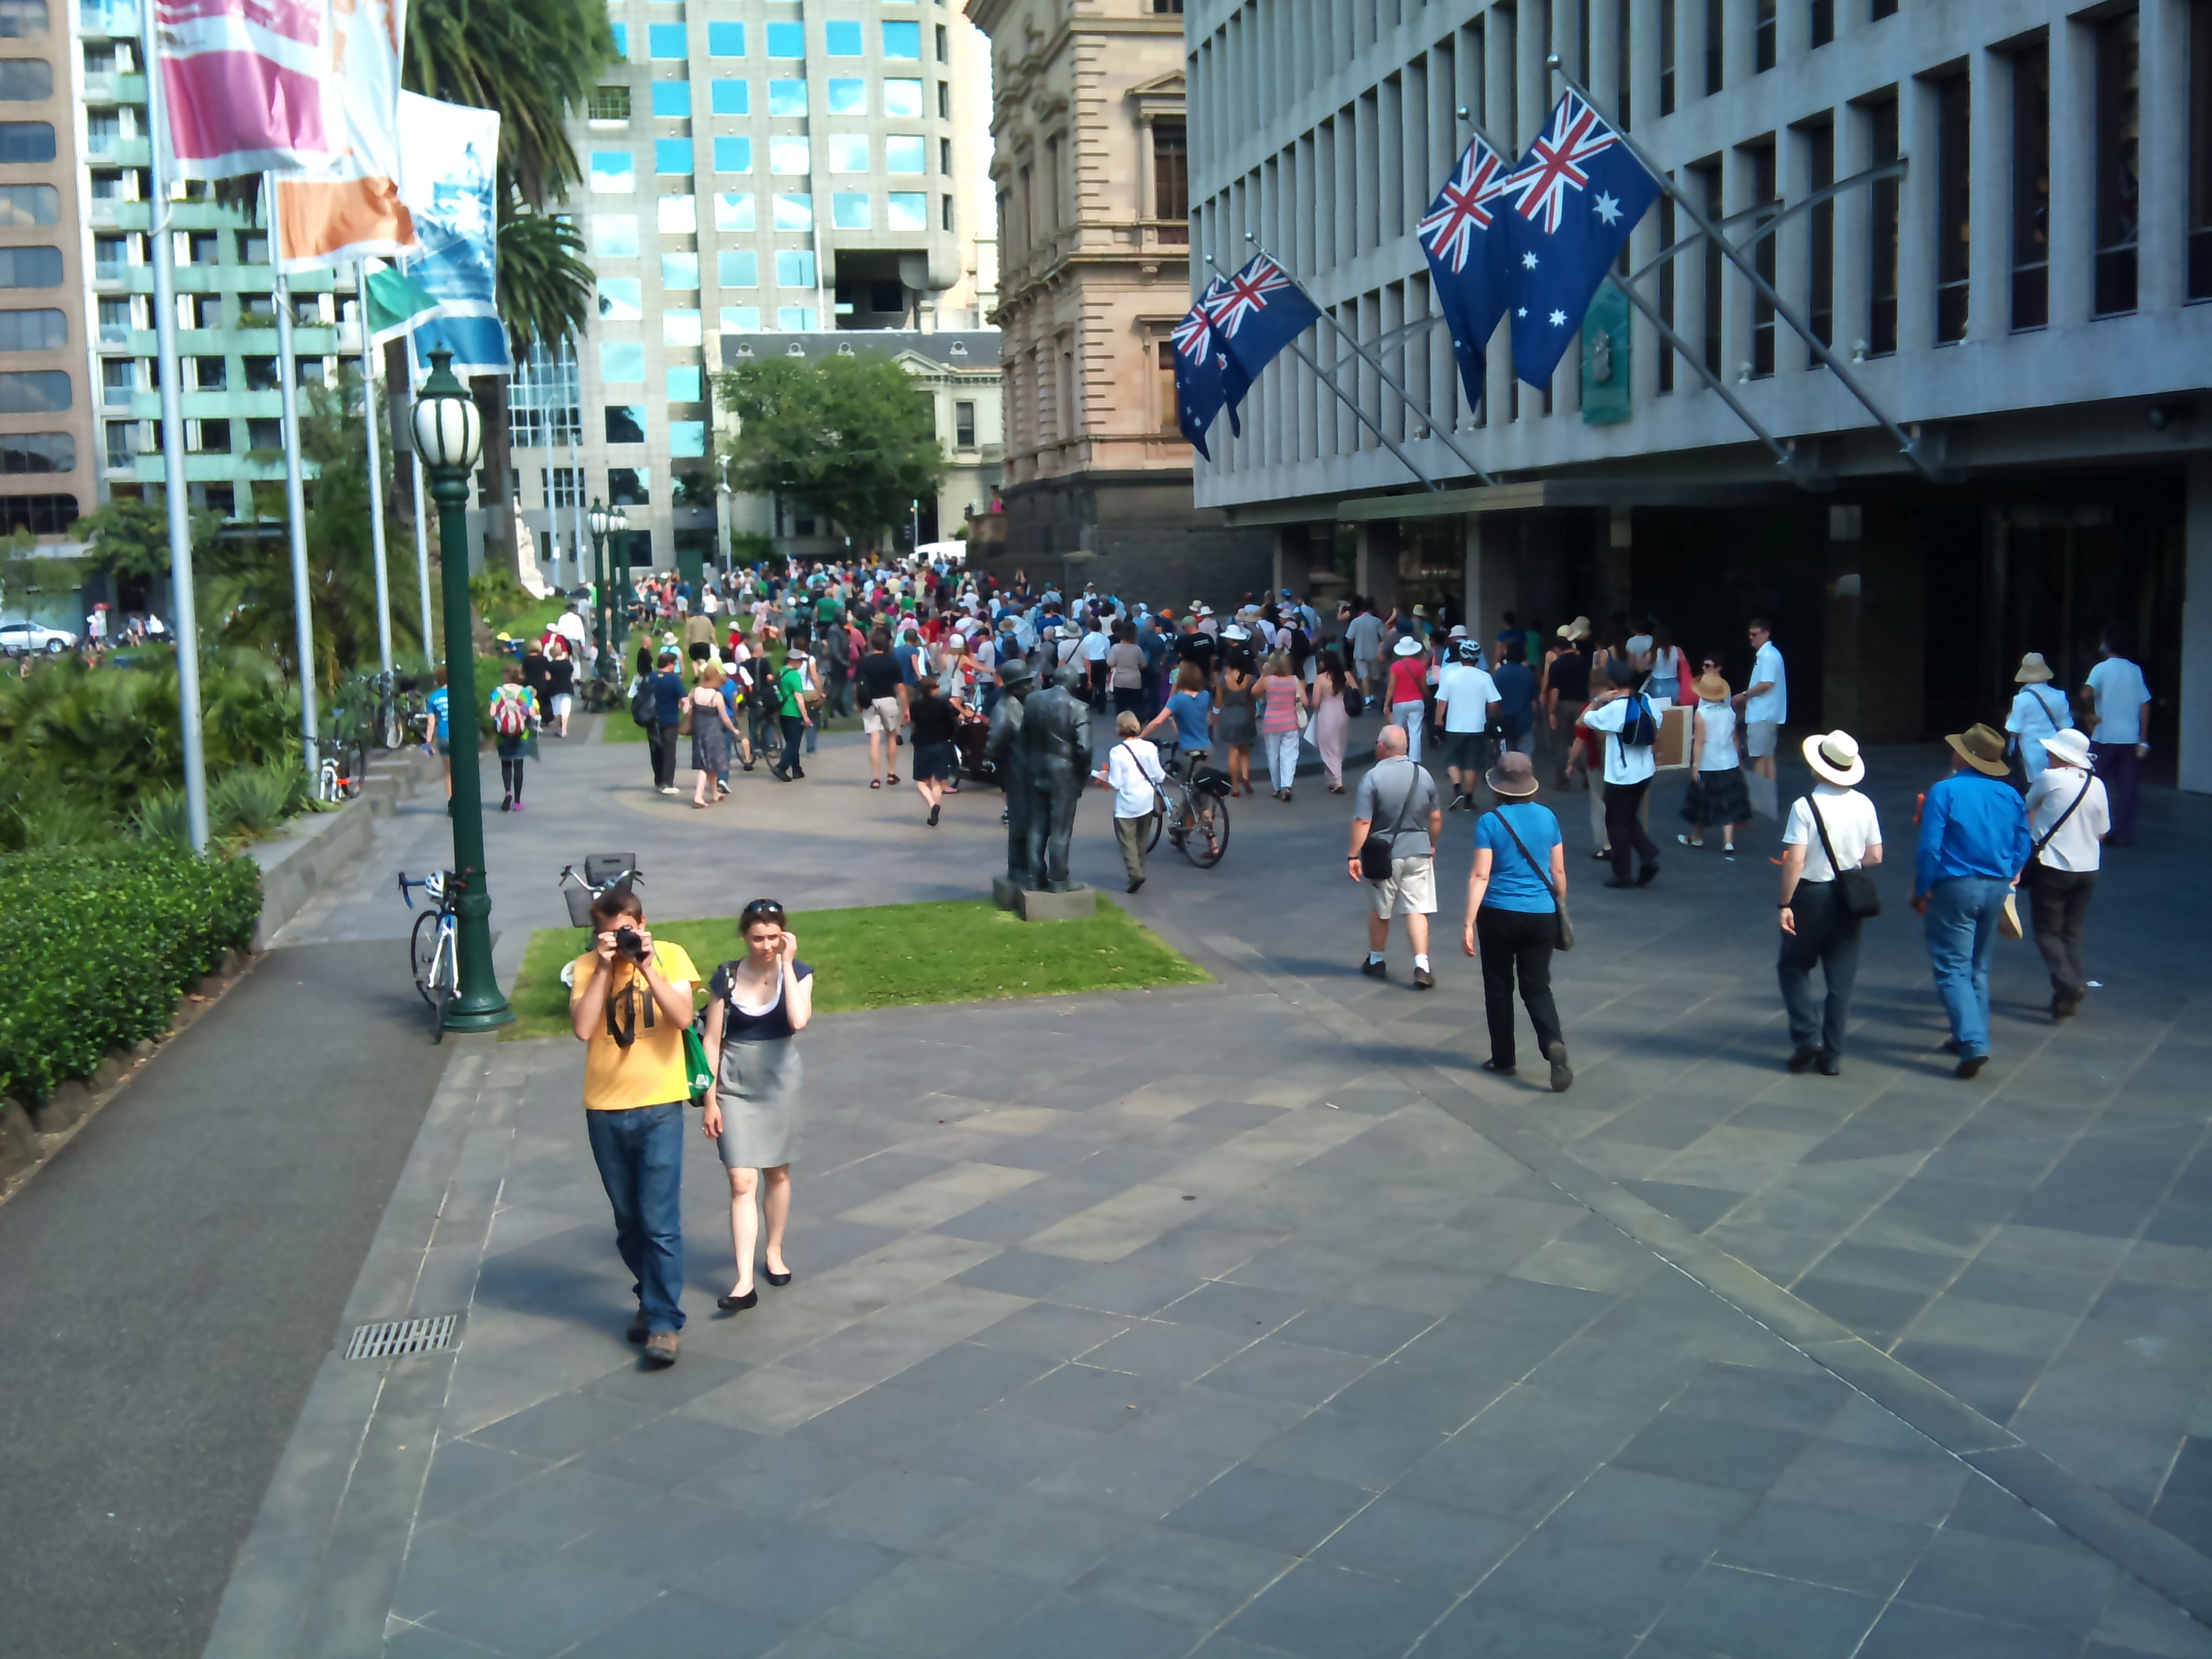
This morning I attended the Climate Action Now rally to support a pollution tax [1]. The event was well attended, my personal estimate of the number of people there was there there was definitely more than 3,000 people, and maybe as many as 8,000 or more.I spoke to an employee of the APS who was on guard duty, he described the event as big and said that they don t usually have events that are so well attended. He gave a personal estimate of 5,000 people. While he wasn t speaking on behalf of the APS he was presumably more skillful at making such estimations than most people. I expect that he also gave a conservative estimate, so it could have been a lot more than that.There were some people using comedy to make political points. Below is a picture of the carbon monster, what you can t see is the man who was handing out coal BBQ fuel for people to feed the monster, children appeared to enjoy that! Also there were three people dressed as Gollum representing the Liberal party (the Australian conservative party), I was unable to get all three in one picture.Carbon monster with sign saying feed me carbonTwo people dressed as Gollum with Liberal Party badges advocating that we die tax-free and that the Liberal party is for famine, fire, and floodSome vegans had a banner supporting the VeganEasy.org site [2]. Being vegetarian can make a significant impact on human environmental impact including on the amount of electricity used (from coal or other sources).Vegans waving a banner for VeganEasy.orgHere are pictures taken looking East over the main part of the rally, looking North towards the building at 3 Treasury place from the other side of the road, looking South over the lawns where people who didn t like being crowded gathered, and looking West over part of the main crowd. The picture looking South shows another view of the Carbon Monster and his accomplice with a sign haven t you had enough dear? .Looking East over the main rallyLooking North towards the building across Treasury PlaceLooking south over the lawnLooking west over the crowdWhen I first arrived there were two main sections to the rally. They weren t discrete (there was no empty space between them) but they acted separately because there was no PA system that could make enough noise to be heard in both sections. At one stage the West section was chanting while there were speeches in the East section. Below is a picture looking out over the West section as people had just turned to go home. This area was entirely packed when I first arrived.The rally was really a family event. There were some grey-haired people wearing t-shirts explaining that they wanted to create a better world for their grand-children and there were also some young children. At the end of the event some children used cardboard signs as toboggans to slide down a steep grassy bank near the main rally area recycling!!! I deliberately chose my photos to try and avoid including children, but even so you can see a few in the background of some of them.

11 March 2011

Pietro Abate: On equivalent debian versions

For one of our experiments, we ended up analyzing all versions mentioned in a Debian Packages file if mentioned in a constraint or in a version field of a package. It seems that there are a lot of DDs that like to use strange 'formatting' when writing down a versioned constraint. This is might be not a choice done directly by the debian maintainer, but just a consequence of a particular version schema from upstream. The debian policy is rigorous with relation to the algorithm to compare version .
 The strings are compared from left to right.
 First the initial part of each string consisting entirely of non-digit characters is determined. These two parts 
 (one of    which may be empty) are compared lexically. If a difference is found it is returned. The lexical 
 comparison is a comparison of ASCII values modified so that all the letters sort earlier than all the non-letters 
 and so that a tilde sorts before anything, even the end of a part. For example, the following parts are in sorted 
 order from earliest to latest: ~~, ~~a, ~, the empty part, a.[34]
 Then the initial part of the remainder of each string which consists entirely of digit characters is determined. 
 The numerical values of these two parts are compared, and any difference found is returned as the result of 
 the comparison. For these purposes an empty string (which can only occur at the end of one or both version 
 strings being compared) counts as zero.
 These two steps (comparing and removing initial non-digit strings and initial digit strings) are repeated until a
 difference is found or both strings are exhausted.
I think the important part is about the numerical comparison The numerical values of these two parts are compared, and any difference found is returned as the result of the comparison . Our tool finds a number of examples of equivalent versions : For example version '0.00001-1' is from package libbenchmark-progressbar-perl. I don't know why so many equivalent way of writing a version string are used. Probably they appear in completely unrelated packages I'm pretty sure no harm is intended :) However, to avoid confusion, it might be a good idea to settle on a non-normative canonical representation of versions. Like no '0' in front of dots and hyphen... Maybe we could add a warning in lintian ? If somebody is interested I can generate a full report that associates each version to a package name.

Eddy Petrișor: HOWTO: Making Windows usable and avoiding accidental sending of mails in Microsoft Outlook

I've changed jobs recently and after 5 years of not having to work with a Windows system I am having all sorts of adaptation-to-Windows problems at the new job.

First I just had to have the usual X-mouse behaviour and so I installed True X-Mouse Gizmo for Windows. This provides focus under mouse, middle click paste after select (not perfect, but it works), right click to push to bottom the window.

Second I had to have a virtual desktop, so I installed Microsoft's Virtual Desktop Manager from the PowerToys page. I tried another virtual desktop manager before using MSVDM, but I found it too clumsy so I switched to MSVDM which I knew from way back when I used Windows the last time. Good, now I can have my applications organised the way I am used to.

UPDATE:
I gave up on MSVDM in favour of Virtual Dimension since I wasn't able to send a particular window to the intended desktop unless I had in the taskbar all apps visible (Shared Desktop option). I might try other suggestions (Virtual Dimension does not have a way to send a window directly to a specific desktop, but just to the neighbours of the current one.)


Third, I had to make Caps Lock work as Ctrl. I just can't go back to an inferior setup. I found information on this page and ended up at this page from where I got a zip file with various registry keys which allow the deactivation of caps, or turning it into another Ctrl.

Fourth, I am used to write with diacritics in Romanian with the secondary layout of the standard (SR 13392:2004), so I rushed to Cristian Secar 's page for the keyboard driver since on XP the Romanian layout is retarded (some history in which some arbitrary German guy decided y and z had to be switched on Romanian keyboards and some other similarly weird stuff). Since the installation, my keyboard behaves according to this layout:


Things started to look well, but I soon was reminded that Outlook is an idiotic mailer since it doesn't require a confirmation on send, not even if you didn't set a subject. And this is problematic since sending the mail is done via Alt+S, so if the current layer is NOT Romanian, when I want to type (s with a comma below), a fairly common character in Romanian words, you end up looking like an idiot on the recipient side since they receive an incomplete mail. Remember, no confirmation AND no default spell checking before send. Yay!

At my second such accidental mail sending (of which the last two were sent to the same person), I decided to see if this can't be fixed. I initially looked for changing the short cut, but I couldn't find it (I might be inept at finding things in Windows, remember, I haven't touched Windows systems in the last 5 years) but I found another workaround and decided it's good enough to share with other people that might hit the problem.

Just setup a delay rule following these steps.
1. Go to Tools....Rules Wizard
2. Click 'New' Rule
3. Select "Check messages after sending"
4. Click Next on "Which conditions you want to Check?" dialog.
5. Press yes to "This Rule will be applied to every message" message box
6. In the "What do you want to do with message?" dialog, Select "Defer delivery by a number of minutes"
7. Select your favourite number of minutes.... I usually select 2 mins.
8. Select Finish. and close the Rules Wizard.

Now everytime you send an email it will sit in your outbox
for specified number of minutes. If you ever wanted to change it, delete it etc, You have sufficient time to do it :)


I used 3 minutes for the delay. At least now I can prevent looking retarded in front of people... more than necessary :D .


Oh, and Windows' clock display is retarded. It shows, by default, the hour and minutes, but there's no way to change that in a sane way. If you want the date, you must hover over the clock and it shows it, but the day of week is missing. Great job! You can see that information, too, but you have to drag the toolbar to be 2 or even 3 rows high (here it requires 2, but I've seen people saying they needed 3) to get that information, too. Great! One has to choose between wasting desktop real estate and having access to useful information. Or you could install an independent application for the clock... retarded. I am not making this shit up.

I hope this helped.

7 March 2011

Matt Zimmerman: Listening to users

In the software community, people hold strong opinions on the subject of listening to users. Some feel that users are an essential source of information for making successful products, as evidenced in the customer development methodology, and seek to involve users deeply in product development. Others believe that users don t know what they want, invoking the quote attributed to Henry Ford, If I d asked customers what they wanted, they would have said a faster horse . Some say that user needs are unknowable except through the lens of a marketplace, where people choose in aggregate which products suit them best, and customers vote with their wallets (anything else is anecdata ). Regular readers will not be surprised that I believe they are all right, but only in certain contexts. The right strategy for involving users in product decisions will depend on factors related to the product itself, the market, and the product development method being used. One of the most important is the life cycle stage of the product: is it a new and rapidly evolving concept, or a mature commodity, or somewhere in between? Simon Wardley explains this well over on his blog, so I won t rehash his points here, but will add a few of my own. If what we re looking for is inspiration for a new product, it s here that Henry Ford was right: users generally won t hand you a complete product vision on a silver platter. They ll frame their input in terms of what they know, and the choices already available to them. However, this doesn t mean that users don t have a role to play in this instance: watching users can be a great source of inspiration. It s the combination of domain knowledge and passionate imagination which triggers the creative spark. Henry Ford applied his engineer s interests to a problem which was evident all around him. If our goal is to test whether a new product is a good fit for its users, there is no substitute for user feedback. We can guess at whether there is a fit, and our intuition may be good, but users are the ultimate judges, and we don t know if we re right or wrong until users evaluate it. So ask them! By engaging in dialogue with individual users, we can learn unexpected things which will help to refine the idea. If we don t find what they think until our new product is released, we risk making something that no one wants. Why wait until it s too late? It can be challenging to extract useful feedback for a product which doesn t yet exist, but this effort is well worth it to avoid wasting much more effort in software engineering. When our objective is to incrementally improve an existing product, individual anecdotes can mislead us. A given change may be an improvement for one user, but a disaster for another. What we want to know is whether the new version is better for the population as a whole, and in this case, we do well to rely on data. There are pitfalls here as well, of course. We need to choose our questions carefully, and realize that users will often resist any change: not because they re stodgy by nature, but because they have to invest effort in adapting to the change. I think of incremental improvement as a joint investment made between product developers and their users, to improve the whole system of people and technology for the better. By choosing the right tool for the job, we can make better decisions, improve faster, and ultimately solve the right problem for our users.

Daniel Kahn Gillmor: PHP, MySQL, and SSL?

Is there a way to access a MySQL database over the network from PHP and be confident that As far as i can tell, when using the stock MySQL bindings, setting MYSQL_CLIENT_SSL is purely advisory (i.e. it won't fail if the server doesn't advertise SSL support). This means it won't defend against an active network attacker performing the equivalent of sslstrip. Even if MYSQL_CLIENT_SSL was stronger than an advisory flag, i can't seem to come up with a way to tell PHP's basic MySQL bindings the equivalent of the --ssl-ca flag to the mysql client binary. Without being able to configure this, a "man-in-the-middle" should be able to intercept the connection by offering their own certificate on their endpoint, and otherwise relaying the traffic. A client that does not verify the server's identity would be none the wiser. One option to avoid a MITM attack would be for the server to require client-side certs via the REQUIRE option for a GRANT statement, but the basic MySQL bindings for php don't seem to support that either. PHP's mysqli bindings (MySQL Improved, i think) feature a command called ssl_set() which appears to allow client-side certificate support. But its documentation isn't clear on how it handles an invalid/expired/revoked server certificate (let alone a server that announces that it doesn't support SSL), and it also mentions:
This function does nothing unless OpenSSL support is enabled.
Given that debian MySQL packages don't use OpenSSL because of licensing incompatibilities with the GPL, i'm left wondering if packages built against yaSSL support this feature. And i'm more than a little bit leery that i have no way of telling whether my configuration request succeeded, or whether this function just happily did nothing because the interpreter got re-built with the wrong flags. Shouldn't the function fail explicitly if it cannot meet the user's request? Meanwhile, the PDO bindings for MySQL apparently don't support SSL connections at all. What's going on here? Does no one use MySQL over the network via PHP? Given the number of LAMP-driven data centers, this seems pretty unlikely. Do PHP+MySQL users just not care about privacy or integrity of their data? Or (please let this be the case) have i just somehow missed the obvious documentation? Tags: mysql, php, question, security, ssl, tls

6 March 2011

Stefano Zacchiroli: on the influence of Debian and derivatives

Counting derivatives In the news, there's an article by Bruce Byfield discussing the influence of Debian and its (transitive) derivatives on the ecosystem of GNU/Linux distributions: Linux Leaders: Debian and Ubuntu Derivative Distros. The article is a sort of review of what you can find in the vast ecosystem of distributions rooted at Debian: from embedded to supercomputer distro, from netbook to scientific computing distros. The articles cites the Debian derivatives front desk and is a study similar to what we might tackle with the derivatives census by Paul Wise. (By the way: did you check if your favorite Debian derivative is already in? No? Do it!) With this article, Bruce has made me quite a favor in harvesting distrowatch to refresh the figures about the number of derivatives that I often use in speeches. The need of doing that has been polluting my LaTeX "% TODO" comments for a while now Here they are: Update: update figures that Bruce misinterpreted; live data are available, thanks to Loris (see comments) for noticing

Neil Williams: Checking build-dependencies

I've been nagged for a while (by Wookey mainly) about the unhelpfulness of dpkg-checkbuilddeps when it outputs the versions and alternatives alongside the package names which are missing, making it harder to pass the list to the package manager. apt-get build-dep isn't particular helpful either - it doesn't look at the modified package at all.

Of course, once the output is in a suitable format, a new script might as well make it possible to simply pass that output to said package manager. Once it can do that, it can then pass the output to the cross-dependency tools, like xapt.

So, I've refactored the embuilddeps script in the xapt package to do just this.

It's gained a few features in the process:

  1. Support for Build-Conflicts resolution

  2. Support for virtual packages, swapping the virtual for the first package to provide it (borrowed some code from Dpkg::Deps for that one).

  3. Support for Build-Depends alternatives (currently using the buildd default of "first alternative gets first chance")

  4. Reads data from debian/control, not the apt cache - to help with the package you're building instead of the one you've already uploaded.

  5. Handles cross dependencies (which are always assumed to not currently be installed) and native dependencies. This support is transitory until such time as enough packages are Multi-Arch compatible that Cross-Multi-Arch becomes trivial.

  6. Support for being used as a build-dependency resolver in pbuilder, including cross-architecture dependencies with pdebuild-cross.

  7. Can locate a debian/control file in a specified directory without needing to be called from that directory

  8. Checks your apt-cache policy to see if the required version of a package is available from your current apt sources. Fails completely if not. (The pdebuild-cross usage will need that to be extended a touch to look at the apt-cache policy from within the chroot.)

  9. Hector Oron has also been asking me to get embuilddeps working with sbuild, so I'm working on that feature too.

  10. verbose and quiet support (so use -q inside other scripts)

  11. most output is already translated - more translations are welcome, especially for the documentation, but hold on until this version has actually been uploaded.


More testing is needed, particularly that the extensive refactoring hasn't broken the pbuilder resolution support and then looking at what still needs to be done for sbuild support. The new script is in Emdebian SVN.

The first-choice method for virtuals and alternatives may well bear extension to explicit management via command-line options. I'm unsure yet whether it needs to be a configuration file setting. It could simply be a recursive - try one, move on - model.

Yves-Alexis Perez: Update on Xfce 4.8

Since the last post, few things did happen. Basically, it's still not the right time for Debian users to upgrade to Xfce 4.8. We eventually managed to upload the whole desktop part (except the xfce metapackage) to experimental and we did upload some of the goodies too. Licensing issues have been solved so the concerned packages have been uploaded, and we're right now waiting on the three packages sitting in NEW. So you'll need to be a little more patient and kindly wait for our ftp-masters to process the (quite huge) NEW backlog. After that we'll need a bit more time in experimental to test upgrade cases, then we'll do an upload to unstable of the whole desktop part and the whole goodies. Upgrading to xfce4-panel 4.8 means *all* plugins need to be rebuilt too, so that means a huge upgrade and a quite large transition to handle for the release team, so we'll have to schedule the unstable upload with them in order not to break all their plans (yes, we try to be good Debian citizens) So please be patient, but you'll see Xfce 4.8 in unstable in a not too distant future. I'll put an update here when we'll need brave volunteers willing to break their systems by doing upgrade tests. [UPDATE]: garcon, thunar-vfs and tumbler were just accepted into experimental, thanks to our ftp-masters. Now we'll synchronize with release team and upload to unstable when possible.

Mike Hommey: A good reason to keep patched source in $VCS

There are a lot of different workflows to maintain Debian packages under a Version Control System. Some people prefer to only keep the debian directory, some the whole source. And in the latter category, some prefer the source tree to be patched with Debian changes, while others prefer to keep it unpatched and exclusively use debian/patches. It turns out the former and the latter don t work so well in one specific case that any package may hit some day ; and that day, you realize how wrong you were not tracking the entire patched source. That happened to me recently, though instead of actually going forward and switch to tracking the patched source, I cheated and simply ditched the patch, because I didn t strictly need it. In all fairness, this is not only a case against not tracking patched source, but also a case of the 3.0 (quilt) source format being cumbersome. In my specific case, I cherry picked an upstream patch modifying and adding some test cases related to a cherry-picked fix. One of the added test cases was a UTF-16 file. UTF-16 files can t be diff ed nor patch ed except in the git patch format, but quilt doesn t use nor support that. The solution around this limitation of 3.0 (quilt) format is to include the plain modified file in the Debian tarball, and add its path to debian/source/include-binaries. On the VCS side of things, it means you have to modify the file in the source directory, and fill debian/source/include-binaries accordingly. Wait. Modify the file in the source directory ? But the other files aren t ! They re tracked by patches ! So here you are, with all of your modifications exclusively in debian/patches except one.

5 March 2011

John Goerzen: Visiting Purdue

Terah went to college at Purdue University, and always enjoyed basketball games there. I ve not been much of a sports fan, but have enjoyed watching Purdue games with her on TV. Terah has been wanting to see a game in person for awhile, so a couple of weeks ago, we went. It was a really fun weekend! When we planed the trip, we had no idea that the Purdue-Ohio State game was going to be such a big one. We walked over from the Union Club Hotel where we were staying on the Purdue campus. People were streaming towards Mackey Arena from all directions. Once inside, it was already loud and buzzing people cheering, the band playing. I ve never experienced anything quite so loud. The game started out badly for Purdue; they were down a few points up front. The entire game was a close one, and the crowd sometimes got so loud that nothing else could be heard not even the band or the announcer. When it became clear at the end that Purdue won the game, the people behind me and apparently 12,000 others began screaming at the top of their lungs. My hearing did eventually return to normal. So did my throat, which had gotten rather sore from from cheering myself. This was our first road trip since I got my amateur radio license. I had a lot of fun visiting with people as we drove. I talked to a retired railroad engineer that used to take an amateur radio with him in his locomotive. As he went through a certain town where he had friends he liked to talk with on the radio, he d get their attention by blowing CQ in Morse code with the train s whistle. Some people in Kansas City had us laughing as we passed through. In Missouri, I talked with some farmers and a World War II vet. In Champaign, IL, I visited with a retired Unix systems administrator that had spent decades working with Unix operating systems. Our hotel was connected to the Purdue Memorial Union, a large and historic building. Besides having some ice cream at the Sweet Shop one evening, we also spent a bit of time exploring it. I noticed that the Purdue Amateur Radio Club was having a testing session in there. We walked past once it was underway, and one of the students was not very busy. I introduced myself and asked if we could see their shack. It was neat to see all the equipment some of it quite old in the room that they must have been using for decades. Terah, of course, had ideas for visiting a number of her favorite places while we were there. We visited Arni s and Bruno s, both pizza places. Bruno s happens to be a Swiss pizza place, so much to my surprise, I had Wienerschnitzel there, which was excellent. We ate a (week late) Valentine s dinner at Bistro 501. On our way back, we also chatted with various people on the radio, though not quite as much. We got helpful suggestions for which route to take, and stopped at the excellent Bobby D s Merchant St. BBQ in Emporia, KS for supper. The boys had also enjoyed their weekend with grandparents, but were glad to see us back. They were particularly interested to see a lot of train videos from Youtube with me the next day.

Next.

Previous.