Search Results: "ana"

24 July 2010

Andrew Pollock: [geek] Cleaning up from 20 years ago

I'm a terrible hoarder. I hang onto old stuff because I think it might be fun to have a look at again later, when I've got nothing to do. The problem is, I never have nothing to do, or when I do, I never think to go through the stuff I've hoarded. As time goes by, the technology becomes more and more obsolete to the point where it becomes impractical to look at it. Today's example: the 3.5" floppy disk. I've got a disk holder thingy with floppies in it dating back to the mid-nineties and earlier. Stuff from high school, which I thought might be a good for a giggle to look at again some time. In the spirit of recording stuff before I throw it out, I present the floppy disks I'm immediately tossing out.
MS-DOS 6.2 and 6.22
Ah the DOS days. I remember excitedly looking forward to new versions of MS-DOS to see what new features they brought. I remember DOS 5.0 being the revolutionary one. The dir command grew a ton of options.
XTreeGold
More from the DOS days, when file management was such a pain in the arse that there was a business model to do it better. ytree seems like a fairly good looking clone of it for Linux.
WinZip for Windows 95, Windows NT and Windows 3.1
Ha. I actually paid money for an official WinZip floppy disk.
Nissan Maxima Electronic Brochure
I'm amazed this fit on a floppy disk
Turbo Pascal 6.0
Excluding GW-BASIC, this was the first "real" language I dabbled in. I learned it in Information Processing & Technology in grades 11 and 12. I never got into the OO stuff that version 6.0 was particularly geared towards.
Where in the World is Carmen Sandiego?
Awesome educational game. I was first introduced to this on the Apple ][, and loved it. This deserves being resurrected for a console.
Captain Comic II
Good sequel to the original, but I never found a version that worked properly (I could never convince it to let me finish it)
HDM IV
Ah, Hard Disk Menu. A necessity from the DOS days when booting up to a C:\> prompt just really didn't cut it. I used to love customising this thing.
ARJ, LHA, PK-ZIP
Of course, you needed a bazillion different decompression programs back in the days of file trading. I guess things haven't changed much with Linux. There's gzip, bzip2, 7zip, etc.
Zeliard
I wasted so many hours playing this. The ending was so hard.
MicroSQL
This was some locally produced software from Brisbane, written in Turbo Pascal (I think). It was a good introduction to SQL, I used it in high school and my first stab at University.
DOOM and DOOM II
Classics. I don't seem to have media for it any more, but I also enjoyed playing Heretic and Hexen. Oooh, Hexen has been ported to Linux? Must check that out...
SimCity 2000
I wasn't a big fan of this game, but I liked the isometric view that 2000 had, compared to the previous version.

23 July 2010

Alexander Reichle-Schmehl: Release Critical Bug report for Week 29

The unofficial rc bug tracker currently knows about the following bugs:
In Total:446
Affecting Squeeze:348
Squeeze only:62
Remaining to be fixed in Squeeze:286
Of these 286 bugs, the following tags are set:
Pending in Squeeze:18
Patched in Squeeze:48
Duplicates in Squeeze:36
Contrib or non-free in Squeeze:12
Claimed in Squeeze:2
Delayed in Squeeze:7
Can fixed in a security Update:23
Otherwise fixed in Squeeze:36
Ignoring all the above (multiple tags possible), 152 bugs need to be fixed by Debian Contributers to get Debian 6.0 Squeeze released. However, with the view of the Release Managers, 250 need to be dealt with for the release to happen. Please see my older post for an explanation of the different numbers.

21 July 2010

Maximilian Attems: Solid bases in Theoretical Physics

Landau, L. D.; Lifshitz, E. M. (1976). Course of Theoretical Physics is still the most interesting and solid base that is to be considered as a reference and inspiration in Theoretical Physics. The reference for "Classical Electrodynamics" is the book by J.D. Jackson. "Advanced Quantum Mechanics" by J.J. Sakurai is a popular student choice. Compendium of Relations contains various formulas and relations of the Standard Model. The Lecture Notes on General Relativity by S. Carroll are a solid introduction for an initiate relativist. "Quantum Field Theory in a Nutshell" by A. Zee is amazing. Quantum electrodynamics can be explored in the books by "The Quantum Theory of Fields" by S. Weinberg or "Quantum field theory" by L.H. Ryder or Quantum Chromodynamics in M.E. Peskin & D.V. Schroeder "An Introduction to Quantum Field Theory". The lecture notes on Quantum Chromodynamics (QCD) might be interesting for people diving into the particle physics standard model. "Finite-temperature field theory: Principles and Application" discusses systems in equilibrium but at finite temperatures and chemical potentials and thus connects to cosmology of the early universe. The field of Statistical Field Theory has the classic "Quantum Many-Particle Systems" by J.W. Negele and H. Orland or the more recent "Quantum Field Theory of Many-Body Systems" by X-G. Wen or "Ultracold Quantum Fields" by H.T.C Stoof, D.B.M. Dickerscheid, K. Gubbels. String Theory is so diverse that you'll find lots of different approaches, recommendations are Graduate Course in String Theory by A. Uranga, Applied Conformal Field Theory by P. Ginsparg, Lectures on String Theory by D. Tong or more introductory the book "A First Course in String Theory " by B. Zwiebach or the dense "Superstring Theory" by M. Green, J. Schwarz and E. Witten, "String Theory" by J. Polchinski. "Quantum Field Theory of Point Particles and Strings" by B. Hatfield assumes no previous stringy background and is known for excellent explanation of the path integral formalism. M. Nakahara wrote the wonderfull bridge to maths: "Geometry, Topology and Physics". So please when looking for "references" in theoretical physics venture on solid grounds and don't get distracted by sketchy notes. Update: Peter West pointed out that the The Feynman Lectures on Physics are missing as a timeless reference.

20 July 2010

Russell Coker: Digital Video Cameras

I ve just done some quick research on Digital Video Cameras for some relatives. It seems to me that the main feature that is necessary is Full HD (1920*1080) resolution as everyone seems to be getting 1920*1080 resolution monitors (getting smaller doesn t save enough money to be worth-while). Resolutions higher than 1920*1080 will probably available in affordable monitors in the next few years, so the ability of programs like mplayer to zoom videos will probably be required even for Full HD video soon. Saving maybe $300 on a video camera while getting a lower resolution doesn t seem like a good idea. The next feature is optical zoom, most cameras are advertised with features such as advanced zoom to try and trick customers, cameras which advertise 60* or better zoom often turn out to only have 20* zoom. I think that about 20* optical zoom should be considered the minimum, not that there is anything special about 20* zoom, it s just that there is a good range of cameras with better zoom capacity. Image stabilisation is a required feature, no-one can keep their hand perfectly steady and the typically a DVC only gets hand-held use most people who own them don t even own a tripod! Digital image stabilisation is apparently not nearly as good as optical image stabilisation, and image stabilisation that involves moving the CCD is apparently somewhere in between. Finally it s good to have the ability to take quality photos as few people will want to carry a Digital Camera and a Digital Video Camera. I did a search for DVCs on the web site of Ted s Camera store (a chain of camera stores in Australia that generally provide good service at a competitive price but not the cheapest price). The best of the Ted s options seems to be the Panasonic SD60 HD Video [1] which does 25* optical zoom, 1920*1080i video, 5 megapixel still photography, and optical image stabilisation it costs $750 from Ted s. The next best option seems to be the Sony Handycam HDR-CX110 HD [2] which does 25* optical zoom, 1920*1080i video, 3.1 megapixel 2048*1536 still photography, and digital image stabilisation. The Panasonic seems to be a better option due to having optical image stabilisation and a higher resolution for still photographs. It is also $750 from Ted s. Now there s the issue of how well the cameras work on Linux. A quick Google search indicated that the Sony cameras present themselves as USB card readers and can be mounted on a Linux system, I couldn t discover anything about the Panasonic. If I was going to buy one I would take my Netbook to the store and do a quick test. I don t have enough information to recommend either of those cameras, they may have some awful defects that are only apparent when you use them. But in terms of features they seem pretty good. The Panasonic SD60 HD Video should be a good benchmark when comparing cameras in the store. If nothing else the camera store staff seem to not be very helpful if asked generic questions such as which camera is best , but if asked questions such as how is this other camera better than the one I m looking at they can usually give good answers. If anyone has any other advice for purchasing a DVC then please let me know. Either generic advice or specific examples of Linux-friendly DVCs that have been purchased recently.

19 July 2010

Christian Perrier: Taking care of my pet geneweb package

This week-end, I didn't work a lot on Debian stuff (mostly running and gardeing...) but still managed to finally take care of my pet package, the one I maintain since 2001, namely geneweb. The package suffered from a very longstanding RC bug that made it unusable on amd64 machines. I had to call for help Ocaml gurus and R mi Vanicat kindly provided a working patch. So, now, geneweb can be released and I won't have to ask for my pet package to be removed from testing. I even switched it to dh7 and "minimal" debian/rules file (something I planned to do at DC10 but finally turned out to be easy to do. That will be my last week-end of activity in Debian until DebConf10 as I'll be away for the upcoming week-end. So, for those of you who attend DC10, see you in NYC. I'll arrive on Wed 28th evening for part of Debcamp and I'll have the great pleasure to introduce my son Jean-Baptiste to the Debian world.

18 July 2010

Steve McIntyre: Poulsbong redux

I wrote a while back about the "fun" Jo and I were having with her Acer Aspire One 751 netbook, a machine that was "blessed" with Intel's integrated GMA500 graphics. It was a PITA to set the machine up and the final installation of Ubuntu Jaunty was anything but reliable, locking up frequently. Well, there's more to the story. In the comments on that blog entry, Ben Armstrong pointed me at some very useful information from the Debian EeePC team: http://wiki.debian.org/DebianEeePC/Model/1101HA, specifically notes on how to use grub2 and the fbdev X driver to get native resolution on a 1366x768 screen. A couple of weeks back I finally managed to steal the laptop from Jo for a few minutes and try that setup. The results are very promising - X performance is perfectly acceptable and the X lockups have totally gone away. So (shock!) it looks like the crappy binary drivers were to blame. Jo is over the moon that finally her Linux laptop is happy and she has specifically asked me to blog again and thank Ben for his help. Thanks! I'm also hoping that this post will help other people searching for useful information on this nasty hardware and how to make it work as well as possible.

17 July 2010

Joachim Breitner: How forky may one maintain a Debian package?

I maintain most of my Debian packages because I use them myself. Sometimes, I have some needs that go slightly beyond what is currently offered by the software. This is not a problem: Debian ships Free Software and I can program, therefore I can patch the software to also do what I want it to do. Trying to be a good member of the Free Software community, I then submit the patch to the upstream author. If he accepts the patch (which is usually the case), everything is fine. But what if he does not reply to the report or rejects it because he does not want this feature (although the patch is technically fine)? I see two options:
  1. I could continue to use a privately patched and built version of the package, while separately building packages for Debian. This way, Debian ships the software as intended by the upstream maintainer while I can use the features I need. On the other hand, I would not be using the version that I upload to Debian, which is not good, and it causes double work when a a new version is released.
  2. I could upload a package to Debian that contains my patch. The technical infrastructure to add patch in Debian packages has always been there... I would actually use the package as it is in Debian and only manage one line of versions. But would I be abusing my powers as a Debian maintainer? If I were not the maintainer, I could not make this decision by myself (this happend with my patch to nagstamon). Plus it could have a negative effect on the Debian-upstream relationship.
How do other Debian Developers handle such issues? The actual case I m considering is a feature enhancement for link-monitor-applet (but I only just wrote the patch, so it does not yet fall in the category upstream does not reply ).

John Goerzen: KD0MJT

Wow tonight was thrilling. It s hard to explain why, but it s pretty exciting to have a radio setup that is all wrong in so many ways work well enough for me to sit in my kitchen in Kansas and talk to someone in Indianapolis using only two-way HF radios. I recently passed my technician and general amateur radio exams. I ve been talking to some very nice people locally on the 2m band, which permits local (say, 100-200mi radius) communication. It s been fun, but Kansas is sparsely populated enough that sometimes there just isn t any activity. At all. Earlier this week, my Yaesu FT-857D and two antennas arrived. I tried it first on VHF, and had a nice chat with Kent (KB0RWI) a few miles away. But tonight was the big experiment. I bought a 20m dipole antenna. This is basically a 30-foot-long wire, connected to a balun and a coax feed line in the middle. You re supposed to put it at least 30 feet off the ground, and away from trees, houses, etc. You re supposed to have a nice RF ground for your transmitter, power supply, antenna tuner, and all that stuff. You re not supposed to just run the coax under that (until today, annoying) small hole in the seal under the kitchen storm door. You re supposed to have to have the correct connectors on your coax, instead of soldering an RG-8 PL-259 onto some RG-8X because you re new at this and didn t realize that you need to buy an adapter. And, I m really pretty sure that you re not supposed to have an aggressive outdoor cat complete with a full set of claws and teeth attack the coax RG-8X cable as it s being pulled through the grass. Fail to do any of these things, and the thing might not work well, or might not work at all, or for people that use old equipment, might burn out your radio or something. So anyway I got out the ladder today, and I got the antenna maybe 10-15 feet in the air. I have three trees in a row with the perfect separation to hang each end and the center balun from. So while Jacob went around playing with water and trying out the ladder on occasion (with my help), I used some string to hang the antenna. In the trees, not far from them. Near the house. Not 30ft off the ground. I strung the feed line into the house, set up all my equipment on our kitchen table, flipped the switch. And nothing. Just the occasional familiar whine while tuning. I tried the 20m band, then the 40m, then even 15, 12, and 10. No activity anywhere. So what was wrong? I improvised some grounding extracted the ground conductor from an old strip of AC house wiring, shoved it into the ground, and grounded the tuner and transmitter. No difference. I unplugged the coax, and tested it with my multimeter. It tested out OK. I plugged it back in and wiggled the connector. Turns out the connector isn t in great shape, but it had been working. I tried transmitting. The tuner made a whole bunch of alarming-sounding clicking noises (sounded like a symphony of relays), indicated SWR over 3, and the ammeter on my power supply went a bit nuts. Later I realized that I just wasn t giving the tuner enough time to tune up; with a few more seconds, it tuned up just fine on every frequency. (So yes, it was supposed to do that.) And, it turns out, that all I needed to do was wait a little while longer to hear some signals. Pretty soon I was finding stuff all over the 40m band. I heard a discussion from Chicago, another from Oklahoma City, some apparent broadcasters from Africa. I decided I would try and transmit. I was hearing one side of a discussion very clearly and decided I would wait for an opportunity to try to contact that person. I heard his callsign, K9RM. I looked it up, and realized he was near Indianapolis, where I had lived for awhile. Eventually he invited a station trying to get in to participate. And: KD0MJT (I announced my callsign, as a request to join the conversation) He said he only made out the 0, but eventually we were talking quite well. It was a brief conversation, but interesting; the person he was talking to was in Portland, and couldn t hear me (and I could barely hear him, but not loud enough to make out). That with no phone lines, no Internet provider needed, etc. And with a rig that is far from being at peak efficiency. I had no idea what to expect tonight and was surprised that just tossing an antenna up in a tree let me talk to someone in Indiana. That s 650 miles away. I wonder what I ll be able to do once I get things done the right way. This hobby is going to be fun. Many thanks to Mike_W for equipment suggestions, Kent and Dan from Newton ARC for encouragement and coming out to the house to test things, Kent for being my first ham radio contact ever (on 2m while I was using an old 1981 radio), Chuck (K9RM) for taking a few minutes to be my first HF contact, and my dad for helping plan out exterior wall penetration methods that will eliminate this coax under the kitchen door and lack of grounding business. Jacob, by the way, still loves his radios and is starting to take an interest in mine. It wouldn t shock me at all of he s one of these kids that gets his technician license in the 2nd grade or something. I think he and I can do this together for a long time.

16 July 2010

Mark Brown: LPC 2010 submit your papers now!

As Lennart just posted the Call for Papers for the 2010 Linux Plumbers Conference (LPC)closes this Monday (the 19th of July). The goal of LPC is to get people working on the various projects that make up the key Linux infrastructure where the kernel and application layers meet together so that everyone understands everyone else s needs and all the components of the system can be made to work together as well as possible. This is the third year the conference has been run, with the previous two years having been very productive, and we hope that the event this year will be equally successful. This year I ll be joining Lennart Poettering in helping to organize the audio track, with my particular focus being on the needs of embedded systems. Embedded audio is currently undergoing a rapid evolution, especially for mobile phones, so there s a lot of exciting work to be done to make sure that the software stack can readily meet the needs of practical applications. Things like the move from analogue to digital audio routing within devices and the increasingly rich audio feature sets provided by systems like smartphones are driving rapid development in this area that has an impact over the full software stack from device drivers up to the application layer. If you are involved with implementing or deploying the Linux audio infrastructure please join us there to discuss the work that needs doing and help improve the Linux audio experience even further, and please also submit a proposal.

Alexander Reichle-Schmehl: Release Critical Bug report for Week 28

The unofficial rc bug tracker currently knows about the following bugs:
In Total:476
Affecting Squeeze:377
Squeeze only:71
Remaining to be fixed in Squeeze:306
Of these 306 bugs, the following tags are set:
Pending in Squeeze:16
Patched in Squeeze:46
Duplicates in Squeeze:37
Contrib or non-free in Squeeze:13
Claimed in Squeeze:3
Delayed in Squeeze:7
Can fixed in a security Update:29
Otherwise fixed in Squeeze:27
Ignoring all the above (multiple tags possible), 171 bugs need to be fixed by Debian Contributers to get Debian 6.0 Squeeze released. However, with the view of the Release Managers, 279 need to be dealt with for the release to happen. Please see my older post for an explanation of the different numbers.

15 July 2010

Jordi Mallach: Hiking through the Pyrenean GR 11

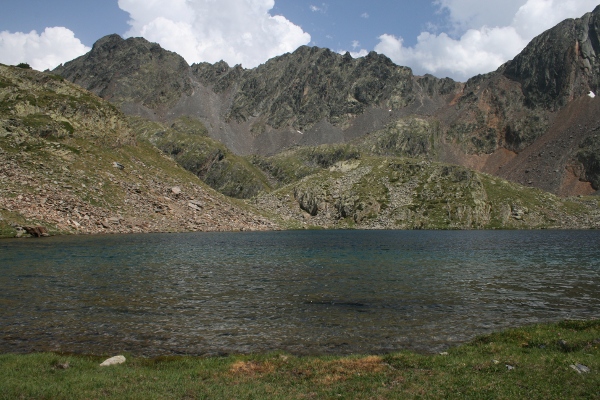
Tomorrow, at this time, I'll probably be unsuccessfully trying to find a comfortable position on a seat of the Bilmanbus to Irun. Very early on Saturday, as soon as we get off the bus, Maria and I will quickly head to Hondarribia's beach in Cape Higer to symbolically wet our feet in the waters of the Cantabrian Sea. We won't have much time to enjoy the cold waters of the ocean, though. Soon after that, we'll have to take a deep breath, look East, and start walking if we want to achieve our utmost objective: take a bath in the beautiful beaches of the Cap de Creus, in the Mediterranean sea. In between, 30 days and 840 kilometres of thick woods, deep valleys, high peaks and cold waters, all of which shape incredible landscapes.


The Portella de Baiau, during our 2008 trip For a whole month, we'll be mostly disconnected from everything else that isn't our knee ache, our blisters, the Sun over our heads or where to get food. It's the first time I leave on a hiking trip as long and tough as this one, and I feel both uncertainty and eagerness. We've been so busy during the last few months that we've been unable to train at all for this, and I'm probably in the worst physical condition in a decade. It's too late to take care of that now, so we'll try to take good care of our legs and spine. In order to get back home in the Mediterranean, we'll have to be fast, some days joining two stages and skipping a few that we know are not that interesting (sections over asphalt, etc.). It's hard to make it in just one month, but we'll try our best. The plan is going to sleep not long after sunset, getting up at dawn, to be able to walk for a decent time before the heat starts being a handicap and just resting at midday, when the Sun is <strongest.> Of course, this means that I'm missing, yet again, this year's edition of DebConf in New York City, which is really sad because I was looking forward hanging around with Mako, Mika, Biella, micah, Clint and the rest of the NYC/ Boston gang, but when the idea of doing a long trip this summer popped up around January, it was clear DebConf seemed unlikely this year. I hope all of you have a lot of fun, and see you in a few weeks!

Enrico Zini: Released cfget 0.15

Released cfget 0.15 I have released version 0.15 of cfget. cfget is a tool to extract values from ini-style config files. A trivial thing, really. It is also simple to install: it is a single python executable and it has no dependencies besides the python standard library. It is trivial and simple, but because of the complex requirements (and sponsorship) of ISAC - CNR it has recently accumulated quite a set of features, and it manages to get a remarkable lot of things done. There are several news since 0.8, worth a rather major announcement: Added --dump=pickle Now all the contents of the configuration files, plus all the contents generated by cfget plugins, can be dumped in pickle format. This provides a quick and dirty way to load all cfget-generated data into a python dict:
data = pickle.loads(
    subprocess.Popen(
        ["cfget", "--dump=pickle"],
        stdout=subprocess.PIPE).communicate()[0])
It sounds like a rather complicated way to read a configuration file, but if you have various plugins that compute nontrivial derived configuration values, that quick&dirty hack could be quite useful. Curly brace expansion Suppose that you have a config file like this:
[general]
mode = show
[show]
command = display
[edit]
command = gimp
And you want to get the command from the section indicated by general/mode. Now you can, very easily: cfget ' general/mode /command' When it notices curly braces, cfget will literally replace them with the result of querying their contents, then parse the expression again. Simple expression support ISAC - CNR are using cfget to configure the run of a rather complicated physical model, and use plugins to derive all sorts of values form the base configuration. This works, but there are times when adding a function to a plugin sounds like overkill: for example, sometimes one needs foo/bar + 1, or just the hour of a timestamp. For those simple cases, I've added support for simple expressions: So to compute a middle point one can now do this:
cfget "round((pos/start + pos/end) / 2)"
It needs a space around arithmetic operators to avoid conflicts with characters used to refer to configuration values, but with the space the expressions look nicer, so the result is that it generally does the right thing. Just as a scary thought, curly braces work with and in expressions:
cfget "values/val round((pos/end - pos/start) / 2)  + 1"
Although if someone ends up having a hairy thing like that, it is worth considering to replace it with a dynamic value computed using a plugin.

14 July 2010

Biella Coleman: Annual Review of Anthropology on Digital Media

I don t remember how but I remember when I first stumbled on an Annual Review of Anthropology. Reading the first one was like stumbling accidentally into a pirate chest of gold doubloons. I was simultaneously flabbergasted, elated, and somewhat annoyed. I could not believe how helpful of a resource the articles were, how interesting it was to learn about the state of the field (since each review covers one topic) and what a time saver it was in terms of research. I was annoyed only because no one had really properly clued me into its existence and felt like it was one of the things that every graduate student should know about like before they even entered their program. When I got asked to write one a few years ago, a mix of conflicting emotions welled up. I was honored and horrified at the same time for I knew that it would require some of the heaviest lifting I have ever engaged in, which turned out to be the case. I almost quit twice but managed to turn in the first draft on time, before the deadline (thanks to a scheduled trip to NZ). After a parade of months of reading, drafting, and rethinking, the uncorrected proofs are now online on the ARA wesbite (you need library access to fetch it and the link is tiny and on the right hand corner). The corrected proofs will be there in a few months but all the mistakes at this point are typos, although I would check back to get the final copy for the purposes of citation. There is a lot more I want to say about the piece and the process of writing it but I will leave such ruminations for future posts. For now, it suffices to say that with a piece like this, you become a dart board, as my friend cleverly put it the other night. I am sure I have overlooked folks (I was working within very thrifty parameters, 6000 words, 150 citations though I managed to get a bit more) and I could have pushed everything further than I did, though this again was very hard to do given the constraints. I decided in the end to be as inclusive as I could, which meant sacrificing a few lines of thought, which I hope to pick up in the future. The part I like the most is the last bit, where I conclude by with the help of systems administrators and spam.

Biella Coleman: Annual Review of Anthropology on Digital Media

I don t remember how but I remember when I first stumbled on an Annual Review of Anthropology. Reading the first one was like stumbling accidentally into a pirate chest of gold doubloons. I was simultaneously flabbergasted, elated, and somewhat annoyed. I could not believe how helpful of a resource the articles were, how interesting it was to learn about the state of the field (since each review covers one topic) and what a time saver it was in terms of research. I was annoyed only because no one had really properly clued me into its existence and felt like it was one of the things that every graduate student should know about like before they even entered their program. When I got asked to write one a few years ago, a mix of conflicting emotions welled up. I was honored and horrified at the same time for I knew that it would require some of the heaviest lifting I have ever engaged in, which turned out to be the case. I almost quit twice but managed to turn in the first draft on time, before the deadline (thanks to a scheduled trip to NZ). After a parade of months of reading, drafting, and rethinking, the uncorrected proofs are now online on the ARA wesbite (you need library access to fetch it and the link is tiny and on the right hand corner). The corrected proofs will be there in a few months but all the mistakes at this point are typos, although I would check back to get the final copy for the purposes of citation. There is a lot more I want to say about the piece and the process of writing it but I will leave such ruminations for future posts. For now, it suffices to say that with a piece like this, you become a dart board, as my friend cleverly put it the other night. I am sure I have overlooked folks (I was working within very thrifty parameters, 6000 words, 150 citations though I managed to get a bit more) and I could have pushed everything further than I did, though this again was very hard to do given the constraints. I decided in the end to be as inclusive as I could, which meant sacrificing a few lines of thought, which I hope to pick up in the future. The part I like the most is the last bit, where I conclude by with the help of systems administrators and spam.

Mike Hommey: I/O patterns on ELF binary initialization

[ I meant to finish this article much earlier, but i had to leave it in a half-written draft state for quite some time due to other activities ] One particular issue that arises with big binary files is that of I/O patterns. It looks like it is not something under the usual scope for both ld.so and programs/libraries, but it can have a dramatic influence on startup times. My analysis is far from complete, would need to be improved by actually investigating ld.so code further, and so far has been limited to libxul.so built from mozilla-central, with the help of icegrind, on x86-64 linux. As I wrote recently, icegrind allows to track memory accesses within mmap()ed memory ranges. As ld.so does mmap() the program and library binaries, tracking the memory accesses within these mmap()s allows to get a better idea at I/O patterns when an ELF binary is initialized. I only focused on local accesses within a single given binary file (libxul.so) because the case of Firefox loading many files at startup is already being scrutinized, and because most of the non-Firefox files being read at Firefox startup (system and GNOME libraries) are most likely already in the page cache. I also focused on that because it was an interesting case that could be helpful to understand how big (and maybe less big) binaries may be affected by the toolchain (compiler, linker and dynamic linker) and possibly by some coding practices. For the record, what I did to get these results is to use icegrind and elflog, with further additions to the sections file with some output from objdump -h : I added sections that elflog wouldn t give (such as .plt, .hash, .dynsym, etc.), and even down to the entry level for the .rela.dyn section. The latter is particularly interesting because icegrind only outputs the first access for any given section. To see sequential accesses within that section, you need to split it in smaller pieces, which I did for .rela.dyn entries (each one being 24 bytes on x86-64). Uncommenting some parts of the icegrind code was also useful to track where some accesses were made from, code-wise. Now, the interesting data: One of the first accesses is a nullification of a few variables within the .bss section. The .bss section is usually an anonymous piece of memory, that is, a range of mmap()ed memory that is not backed by a file, and filled with zeroes by the kernel (I think it even does that lazily). It is used for e.g. variables that are initialized with zeroes in the code, and obviously, any code accessing these variables would be addressing at some offset of the .bss section. It means the section needs to start in memory at the offset it has been assigned by the linker at build time. This is actually where problems begin. When the .bss section offset as assigned by the linker doesn t align on a page (usually 4KB), the mmap()ed .bss can t be at that location, and really starts on the next page. The remainder is still mmap()ed from the binary file, and ld.so will itself fill that part. As the .bss section doesn t start on a page boundary, any write at this location will trigger the kernel reading the entire page. This means one of the first set of data being read from the file is the end of the section preceding .bss, and the beginning of the following one. Most likely, respectively the .data and .comment sections. While this probably doesn t matter much when the binary file is small, when it is big enough, reading in a non sequential manner will trigger hard disk seeks, and we all know how they can hurt performance. Although thankfully, cheap SSDs should be coming some day, in the meanwhile, we still need to cope with the bad performance. The interesting part is, the .bss section is really empty in the binary file, so its virtual memory address could be anywhere. Why the linker wouldn t align it at a page boundary without having to resort to a linker script is beyond me. The next accesses go back and forth between .dynamic, .gnu.hash, .dynstr, .gnu.version_r, .gnu.version and .dynsym. These are probably all related to symbol version resolution and DT_NEEDED library loading. While most of these sections are at the beginning of the file (not necessarily in the order they are read from), the .dynamic section is much nearer to the end, but way before .data, so that it won t even have been loaded as a by-product of the .bss section loading. After that, the .rela.dyn section is read, and for each relocation entry it contains, the relocations are being applied. Relocations is one of the mechanisms by which position independent code (PIC) is made possible. When a library is loaded in memory, it is not necessarily loaded at the same address every time. The code and data contained in the library thus need to cope with that constraint. Fortunately, while the base address where the library is mmap()ed in memory is not necessary constant, the offsets of the various sections are still as codified in the binary. The library code can thus directly access data at the right offset if it knows the base offset of the library (which is what is done on the x86 ABI), or if it knows where the current instruction is located (which is what is done on the x86-64 ABI). Static data (initialized in e.g. a const or a global variable, or, in C++ case, vtables), on the other hand, may contain pointers to other locations. This is where relocation enters the scene. The .rela.dyn section contains a set of rules describing where in the binary some pointers need to be adjusted depending on the base library offset (or some other information), and how they should be updated. ld.so thus reads all .rela.dyn entries, and applies each relocation, which means that while .rela.dyn is being read sequentially, reads and writes are also performed at various places of the binary, depending on the content of the .rela.dyn entries. This is where this gets ugly for Firefox: there are near 200000 such relocations. On x86-64 an entry is 24 bytes (12 on x86), and each of these is going to read/write a pointer (8 bytes on x86-64, 4 on x86) at some random (though mostly ordered) location. The whole .rela.dyn section not being read ahead, what actually happens is that it is read in small batches, with seeks and reads of other data at various locations in between. In libxul.so case, this spreads over .ctors, .data.rel.ro, .got, and .data. The relocation entries are somehow ordered by address to be rewritten, though they occasionally jump backwards. Some of these relocations also appear to be touching to .gnu.version, .dynsym and .dynstr, because their type involves a symbol resolution. Once .rela.dyn relocation have been dealt with comes .rela.plt s turn. The principle is the same for this section: entries describe what kind of relocation must be done where, and how the result must be calculated. The scope of this section, though, is apparently limited to .got.plt. But before explaining these relocations, I ll explain what happens with the PLT. The PLT (Procedure Linkage Table) is used when calling functions from external libraries. For example, in a Hello World example, the PLT would be used for calls to the puts function. The function making the call would in fact call the corresponding PLT location. The PLT itself, on x86 and x86-64, at least, consists of 3 instructions (I ll skip the gory details, especially for x86, where the caller needs to also set some register before calling the PLT). The first instruction is the only one to be called most of the time: it reads the final destination in the .got.plt section, and jumps there. That final destination, obviously, is not fixed in the library file, since it needs to be resolved by its symbol. This is why the two subsequent instructions exist : originally, the destination stored in the .got.plt section points back to the second instruction ; the first instruction will effectively be a nop (no operation), and the following instructions will be executed. They will jump into code responsible for symbol resolution, update of the .got.plt entry for the next call, and call of the real function. But pointing back to the second instruction is like the pointers in static data we saw above : it s not possible in position independent code. So, the .rela.plt relocations are actually filling the .got.plt section with these pointers back to the PLT. There are a tad more than 3000 such relocations. All these relocations should be going away when prelinking the binaries, but from my several experimentations, it looks like prelinking only avoids relative relocations, and not the others, while it technically could skip all of them. prelink even properly applies all the relocations in the binary, but executing the binary rewrites the same information at startup for all but relative relocations. That could well be a bug in either ld.so not skipping enough relocations or prelink not marking enough relocations to be skipped. I haven t dug deep enough in the code to know how prelinking works exactly. Anyways, prelinking is not a perfect solution, as it also breaks ASLR. Sure, prelink can randomize library locations, but it relies on the user or a cron job doing so at arbitrary times, but that s far from satisfying. An interesting thing to note, though, is that a good part of the relocations prelinking doesn t rid us of in libxul.so (more than 25000) are due to the __cxa_pure_virtual symbol, which is used for, well, pure virtual methods. In other words, virtual methods that don t have an implementation in a given class. The __cxa_pure_virtual function is set as method in the corresponding field(s) of the class VTABLE in the .data.rel.ro section. This function is provided by libstdc++, and as such, is dynamically linked. But this function is just a dummy function, doing nothing. Defining an empty __cxa_pure_virtual function to be included in libxul.so makes these relocations become relative, thus taken care of by prelinking. After all relocations occur, the library initialization itself can begin, and the content of the .init section is executed. That section, indirectly, executes all functions stored in the .ctors section. This includes static initializers, which are unfortunately called backwards, as Taras pointed out already. Each of these static initializers are also accessing various locations in the .data or .bss sections, which may or may not have already been loaded during the relocation phase. The execution of these initializers will also (obviously) read various pieces of the .text section (despite its name, it contains executable sections, i.e. functions code). The initialization of the library ends there, and no access should happen until a function from the library is called. In libxul.so case, XRE_main is first called, then many other functions, but that s another story. All that needs to be remembered about the startup process past this point is that the .text section will be read heavily, as well as the various data, got, plt and dynamic symbol sections, in a very scattered way. While most of these sections may have been retrieved in memory already, as a byproduct of the various initialization processes described above, some may have not, increasing even more the need to seek at all places in the binary file. Now the main problem with all these I/O patterns at startup, is that it seems the only way reorganizing the binary layout may have a visible impact is by considering all the above, and not only a part of it, because only addressing a part of it is very likely to only move part of the problem to a different layer. All in all, making sure the relevant sections of libxul.so are read by the kernel before ld.so enters the game is a good short-term solution to avoid many seeks at startup.

12 July 2010

Clint Adams: No raffle ticket winner

Things not to do if you want to be a good person: One of my readers writes in that ve thinks that an egomaniac I may have mentioned previously would get upset about a perceived lack of proper attribution because ve views vis bit of code like vis offspring. This causes me to immediately have flashbacks of poor parenting in public. Many times I have seen adults pay no attention to their children who are misbehaving, perhaps smearing chocolate on a stranger's dress or gnawing on a stranger's leg, and if such a victim either attempts surrogate parenting by kicking ver in the teeth or petitioning the parent to do something about ver, said parent will become very angry and indignant that anyone would impugn vis skills or dedication. So when I see some coder not patch vis buggy code for over three years, yet still find enough time to be a sanctimonious prick and think that ve has the right to tell people how ve should be treated and how the code should be modified by others, I think there are better ways to view that metaphor. On the other hand, I don't know any parents who neglect their kid for 3 years and then still want to actively direct childrearing, unless perhaps they're paying a governess.

Matthew Garrett: Power management at Plumbers

I'm running a power management track at the Linux Plumbers Conference again this November. Unlike most conferences which focus on presenting completed work, Plumbers is an opportunity to focus on unsolved problems and throw around as many half-baked solutions as you want in order to try to find one that seems to stick. The suspend/resume problem in Linux is mostly solved[1], which means that it's time for us to focus on runtime power management and quality of service.

This has been an especially interesting year in the field. We've landed the infrastructure for generic runtime power management, glued that into PCI and started implementing that at the driver level. pm_qos is being reworked to improve performance and scalability as we start seeing more drivers that need to express their own constraints. And, of course, we had the wakelock/suspend blockers conversation that didn't end in a terribly satisfactory manner, although Rafael is now working on an implementation that presents equivalent functionality with a different userspace API. Runtime full-system suspend isn't solved yet either - the current cpuidle-based solution doesn't work well on multicore systems. And maybe we could be more aggressive still by looking at reclocking more system components on the fly even if the existing interfaces don't allow that. Do we have all the hooks we need to identify which system resources are being used? Are we doing the best we can in terms of avoiding trading off performance for power savings?

So if you'd like to talk about any of these things, or if there's any other problems that you don't think have been solved yet, head on over to the call for submissions and help make sure that we can make Linux the most power-efficient OS possible.

[1] Yes, some machines are broken, but those tend to be individual weird bugs which we're gradually tracking down rather than fundamental issues in our core code, so they're not really in the scope of Plumbers

Matt Zimmerman: Read, listen, or comprehend: choose two

I have noticed that when I am reading, I cannot simultaneously understand spoken words. If someone speaks to me while I am reading, I can pay attention to their voice, or to the text, but not both. It s as if these two functions share the same cognitive facility, and this facility can only handle one task at a time. If someone is talking on the phone nearby, I find it very difficult to focus on reading (or writing). If I m having a conversation with someone about a document, I sometimes have to ask them to pause the conversation for a moment while I read. This phenomenon isn t unique to me. In Richard Feynman s What Do You Care what Other People Think?, there is a chapter entitled It s as Simple as One, Two, Three where he describes his experiments with keeping time in his head. He practiced counting at a steady rate while simultaneously performing various actions, such as running up and down the stairs, reading, writing, even counting objects. He discovered that he could do anything while counting to [himself] except talk out loud . What s interesting is that the pattern varies from person to person. Feynman shared his discovery with a group of people, one of whom (John Tukey) had a curiously different experience: while counting steadily, he could easily speak aloud, but could not read. Through experimenting and comparing their experiences, it seemed to them that they were using different cognitive processes to accomplish the task of counting time. Feynman was hearing the numbers in his head, while Tukey was seeing the numbers go by. Analogously, I ve met people who seem to be able to read and listen to speech at the same time. I attributed this to a similar cognitive effect: presumably some people speak the words to themselves, while others watch them. Feynman found that, although he could write and count at the same time, his counting would be interrupted when he had to stop and search for the right word. Perhaps he used a different mental faculty for that. Some people seem to be able to listen to more than one person talking at the same time, and I wonder if that s related. I was reminded of this years later, when I came across this video on speed reading. In it, the speaker explains that most people read by silently voicing words, which they can do at a rate of only 120-250 words per minute. However, people can learn to read visually instead, and thereby read much more quickly. He describes a training technique which involves reading while continuously voicing arbitrary sounds, like the vowels A-E-I-O-U. The interesting part, for me, was the possibility of learning. I realized that different people read in different ways, but hadn t thought much about whether one could change this. Having learned a cognitive skill, like reading or counting time, apparently one can re-learn it a different way. Visual reading would seem, at first glance, to be superior: not only is it faster, but I have to use my eyes to read anyway, so why tie up my listening facility as well? Perhaps I could use it for something else at the same time. So, I tried the simple technique in the video, and it had a definite effect. I could feel that I wasn t reading in the same way that I had been before. I didn t measure whether I was going any faster or slower, because I quickly noticed something more significant: my reading comprehension was completely shot. I couldn t remember what I had read, as the memory of it faded within seconds. Before reaching the end of a paragraph, I would forget the beginning. It was as if my ability to comprehend the meaning of the text was linked to my reading technique. I found this very unsettling, and it ruined my enjoyment of the book I was reading. I ll probably need to separate this practice from my pleasure reading in order to stick with it. Presumably, over time, my comprehension will improve. I m curious about what net effect this will have, though. Will I still comprehend it in the same way? Will it mean the same thing to me? Will I still feel the same way about it? The many levels of meaning are connected to our senses as well, and the same idea, depending on whether it was read or heard, may not have the same meaning to an individual. Even our tactile senses can influence our judgments and decisions. I also wonder whether, if I learn to read visually, I ll lose the ability to read any other way. When I retrained myself to type using a Dvorak keyboard layout, rather than QWERTY, I lost the ability to type on QWERTY at high speed. I think this has been a good tradeoff for me, but raises interesting questions about how my mind works: Why did this happen? What else changed in the process that might have been less obvious? Have you tried re-training yourself in this way? What kind of cognitive side effects did you notice, if any? If you lost something, do you still miss it? (As a sidenote, I am impressed by Feynman s exuberance and persistence in his personal experiments, as described in his books for laypeople. Although I consider myself a very curious person, I rarely invest that kind of physical and intellectual energy in first-hand experiments. I m much more likely to research what other people have done, and skim the surface of the subject.)

9 July 2010

Alexander Reichle-Schmehl: Release Critical Bug report for Week 27

The unofficial rc bug tracker currently knows about the following bugs:
In Total:501
Affecting Squeeze:401
Squeeze only:95
Remaining to be fixed in Squeeze:306
Of these 306 bugs, the following tags are set:
Pending in Squeeze:16
Patched in Squeeze:49
Duplicates in Squeeze:38
Contrib or non-free in Squeeze:12
Claimed in Squeeze:5
Delayed in Squeeze:6
Can fixed in a security Update:35
Otherwise fixed in Squeeze:33
Ignoring all the above (multiple tags possible), 163 bugs need to be fixed by Debian Contributers to get Debian 6.0 Squeeze released. However, the with the view of the Release Managers, 310 need to be dealt with for the release to happen. Please see my older post for an explanation of the different numbers.

8 July 2010

Biella Coleman: Debian in the World: Buidling an Institution vs Managing a Crowd

So there are times that I think of course anyone remotely interested in Free Software, virtual projects, and similar endeavors knows about Debian and its strange rituals. I am pretty mistaken, actually. Recently I have attended various events where it has been made clear to me that there are hordes of folks interested in the politics of openness, access, and free software who have heard about Debian but don t really know what it takes, socially and politically, to manage such a project. Luckily I had the chance to spread some of the esoteric knowledge during a talk at MIT for the Knight News Challenge winners and I have received many emails, excited and some surprised about the governance structures of Debian. If interested, here is a video of my talk, which is quite short, so I don t go into as much detail as I would like. There is a great audio quote from a Debian developer, taken from this class visit for which there is a podcast and which I recommend as well. If you can t play flash, you can download the a video of the talk here (look at the right hand side of the page for download link). update: Interesting blog post on Why the open source way trumps the crowdsourcing way that explores some of the issues I raise in the panel talk. I don t think it always trumps open source but it is certainly a niche form of production that is useful in some cases but all too often confused with expert peer production in quite unproductive and empirically wrong ways.

Next.

Previous.