Search Results: "tar"

28 February 2014

Daniel Pocock: Google Summer of Code opportunities in data science and machine learning with Ganglia

As mentioned in my blog on Monday, the Ganglia Project is proud to be part of Google Summer of Code in 2014 The Ganglia team are offering various types of projects and different parts of Ganglia would welcome students with different skills, for example:
Component Skills
gmond agent C
gmond modules C or Python
JMXetric Java
gmetad and rrdtool for storing time series data C
Ganglia web interface JavaScript and jQuery
Ganglia integration (e.g. ganglia-nagios-bridge) Python
Big data right under your nose I have had many queries from students about how to get into data science. Very few students will be lucky enough to get an internship where they can study time-series from the financial markets and experiment making their own trading algorithms. On the other hand, network performance data is everywhere. It is real-time. It is surprisingly similar in some ways to processing financial data and it provides excellent opportunities for students to practice data science skills and make a meaningful contribution to solving real problems. Finding public Ganglia data with Google Many large organizations, including universities, governments and corporations are using Ganglia to gather metrics from all the hosts in their networks. Some of them even expose this data to the public. Here are two Google searches you can use to find them:
Courtesy of Universit Montpellier 2, France Some sites may even expose their data as an XML feed, you can try and extract it by connecting to the Ganglia server on one of these ports
Port Comments
8649 gmond: sends an XML snapshot to anybody who connects
8651 gmetad: sends an XML snapshot to anybody who connects
8651 gmetad: works a little bit like HTTP, returns a subset of the XML snapshot when you make a GET request
You can discover a Ganglia environment in your campus by looking for a gmond process on your machine and the gmond.conf file, often in /etc/gmond.conf or /etc/ganglia/gmond.conf. That file may contain a clue about the name of the host where Ganglia data is aggregated:
udp_send_channel  
  host = ganglia-reports.example.edu
  port = 8649
  ttl = 1
 
This tells you that the host ganglia-reports.example.edu is collecting the data - you could try the URL http://ganglia-reports.example.edu/ganglia/ in a web browser or try connecting to one of the TCP ports 8649, 8651 or 8652 on that host. Here is an example with netcat:
$ nc ganglia-reports.example.edu 8649   grep ^.H
It will return a list of all hosts that Ganglia knows about. Once you have a data feed, you can then configure a gmetad process on your own system to poll the remote system and generate local RRDs for you to study. Install your own Ganglia It is very easy to get your own Ganglia setup. On a Debian or Ubuntu system, just do:
# apt-get update
# apt-get install ganglia-monitor ganglia-webfrontend
On Fedora and RPM-based systems (such as CentOS or RHEL with EPEL) you can do:
# yum install ganglia-gmond ganglia-web
Everything should be autoconfigured. You can then browse to http://localhost/ganglia to see the charts. If you have several hosts with the gmond agent (just the ganglia-monitor.deb or ganglia-gmond.rpm) on the same LAN, they will automatically find each other using multicast and you will see an aggregated report on the machine with the web server. The data is real-time It is important to keep in mind that the data is real-time. This means you can often detect problems in real-time. If this blog appears on slashdot, for example, then that image from Universit Montpellier 2 will be hit many times. The image actually shows the network load on the web server producing the image, so you will see the slashdot effect graphically in the image itself. Processing real-time data is often the most advanced step in any data science exercise. Initially, you may simply log a few days of data to RRD files to start studying a static data set with your tool of choice, whether it is the R project, Weka or Hadoop Once you have a a hypothesis (for example, an algorithm that understands the normal characteristics of each metric) you may then take each new real-time value from the gmetad XML and test it with the algorithm. The algorithm would then raise an alert if any metric on any host deviates from its normal behavior. Mixing in other sources of data Depending upon the computing environment in your campus or organization, you may also be able to get other data sources, such as a list of people logged in to different machines at different times and the processes that each user starts and stops. This might help to make more accurate predictions about when network or computing resources will be under stress. For example, if users bob, alice and eve all appear on the same host, your algorithm might conclude that the load average will reach an excessive level within 15 minutes and send those three users a suggestion to each try other machines. Making a successful application for GSoC 2014 Here are some tips
  • For all organizations/projects
  • For Ganglia and the data science project in particular
    • Join the ganglia-general mailing list and send an email to introduce yourself
    • Try Ganglia on your own Linux system. Use the packages, it is really easy. Send an email to the list with any questions.
    • Explore the source code in github - ask us questions about it. For the data science project, you may also need to look at RRDtool source code and documentation about making a plugin for R (using C)
    • You don't have to do it our way: if you prefer to work with another tool instead of R, please tell us your idea
    • Write some skeleton code or make a diagram to explain what you want to do. While you do this, do you think of any new questions or problems? Make a list of them.
    • We want to give every student a small coding task as a test. Please tell us which language you prefer (e.g. C, Java, Python) so we can give you a suitable test. If you are really keen, follow the link to bugs I reported in Debian, look for one that is easy and try to write a small patch for it - helping fix bugs that annoy your mentor is likely to be a good way to get on the short-list for selection.

Michael Prokop: State of the art Debian/wheezy deployments with GRUB and LVM/SW-RAID/Crypto

Moving from Lilo to GRUB, using LVM as default, etc throughout the last years it was time to evaluate how well LVM works without a separate boot partition, possibly also on top of Software RAID. Big disks are asking for partitioning with GPT, just UEFI isn t my default yet, so I m still defaulting to Legacy BIOS for Debian/wheezy (I expect this to change for Debian/jessie and according hardware approaching at my customers). So what we have and want in this demonstration setup: System used for installation:
root@grml ~ # grml-version
grml64-full 2013.09 Release Codename Hefeknuddler [2013-09-27]
Partition setup:
root@grml ~ # parted /dev/sda
GNU Parted 2.3
Using /dev/sda
Welcome to GNU Parted! Type 'help' to view a list of commands.
(parted) mklabel gpt
(parted) mkpart primary 2048s 4095s
(parted) set 1 bios_grub on
(parted) name 1 "BIOS Boot Partition"
(parted) mkpart primary 4096s 100%
(parted) set 2 raid on
(parted) name 2 "SW-RAID / Linux"
(parted) quit
Information: You may need to update /etc/fstab.
Clone partition layout from sda to all the other disks:
root@grml ~ # for f in  b,c,d  ; sgdisk -R=/dev/sd$f /dev/sda
The operation has completed successfully.
Make sure each disk has its unique UUID:
root@grml ~ # for f in  b,c,d  ; sgdisk -G /dev/sd$f
The operation has completed successfully.
SW-RAID setup:
root@grml ~ # mdadm --create /dev/md0 --verbose --level=raid5 --raid-devices=4 /dev/sd a,b,c,d 2
mdadm: layout defaults to left-symmetric
mdadm: chunk size defaults to 512K
mdadm: size set to 1465004544K
mdadm: Defaulting to version 1.2 metadata
mdadm: array /dev/md0 started.
root@grml ~ #
SW-RAID speedup (system dependent, YMMV):
root@grml ~ # cat /sys/block/md0/md/stripe_cache_size
256
root@grml ~ # echo 16384 > /sys/block/md0/md/stripe_cache_size # 16MB
root@grml ~ # blockdev --getra /dev/md0
6144
root@grml ~ # blockdev --setra 65536 /dev/md0 # 32 MB
root@grml ~ # sysctl dev.raid.speed_limit_max
dev.raid.speed_limit_max = 200000
root@grml ~ # sysctl -w dev.raid.speed_limit_max=9999999999
dev.raid.speed_limit_max = 9999999999
root@grml ~ # sysctl dev.raid.speed_limit_min
dev.raid.speed_limit_min = 1000
root@grml ~ # sysctl -w dev.raid.speed_limit_min=100000
dev.raid.speed_limit_min = 100000
LVM setup:
root@grml ~ # pvcreate /dev/md0
  Physical volume "/dev/md0" successfully created
root@grml ~ # vgcreate homesrv /dev/md0
  Volume group "homesrv" successfully created
root@grml ~ # lvcreate -n rootfs -L4G homesrv
  Logical volume "rootfs" created
root@grml ~ # lvcreate -n bootfs -L1G homesrv
  Logical volume "bootfs" created
Check partition setup + alignment:
root@grml ~ # parted -s /dev/sda print
Model: ATA WDC WD15EADS-00P (scsi)
Disk /dev/sda: 1500GB
Sector size (logical/physical): 512B/512B
Partition Table: gpt
Number  Start   End     Size    File system  Name                 Flags
 1      1049kB  2097kB  1049kB               BIOS Boot Partition  bios_grub
 2      2097kB  1500GB  1500GB               SW-RAID / Linux      raid
root@grml ~ # parted -s /dev/sda unit s print
Model: ATA WDC WD15EADS-00P (scsi)
Disk /dev/sda: 2930277168s
Sector size (logical/physical): 512B/512B
Partition Table: gpt
Number  Start  End          Size         File system  Name                 Flags
 1      2048s  4095s        2048s                     BIOS Boot Partition  bios_grub
 2      4096s  2930276351s  2930272256s               SW-RAID / Linux      raid
root@grml ~ # gdisk -l /dev/sda
GPT fdisk (gdisk) version 0.8.5
Partition table scan:
  MBR: protective
  BSD: not present
  APM: not present
  GPT: present
Found valid GPT with protective MBR; using GPT.
Disk /dev/sda: 2930277168 sectors, 1.4 TiB
Logical sector size: 512 bytes
Disk identifier (GUID): 212E463A-A4E3-428B-B7E5-8D5785141564
Partition table holds up to 128 entries
First usable sector is 34, last usable sector is 2930277134
Partitions will be aligned on 2048-sector boundaries
Total free space is 2797 sectors (1.4 MiB)
Number  Start (sector)    End (sector)  Size       Code  Name
   1            2048            4095   1024.0 KiB  EF02  BIOS Boot Partition
   2            4096      2930276351   1.4 TiB     FD00  SW-RAID / Linux
root@grml ~ # mdadm -E /dev/sda2
/dev/sda3:
          Magic : a92b4efc
        Version : 1.2
    Feature Map : 0x0
     Array UUID : 7ed3b741:0774d529:d5a71c1f:cf942f0a
           Name : grml:0  (local to host grml)
  Creation Time : Fri Jan 31 15:26:12 2014
     Raid Level : raid5
   Raid Devices : 4
 Avail Dev Size : 2928060416 (1396.21 GiB 1499.17 GB)
     Array Size : 4392089088 (4188.62 GiB 4497.50 GB)
  Used Dev Size : 2928059392 (1396.21 GiB 1499.17 GB)
    Data Offset : 262144 sectors
   Super Offset : 8 sectors
          State : clean
    Device UUID : c1e4213b:81822fd1:260df456:2c9926fb
    Update Time : Mon Feb  3 09:41:48 2014
       Checksum : b8af8f6 - correct
         Events : 72
         Layout : left-symmetric
     chunk size : 512k
   Device Role : Active device 0
   Array State : AAAA ('A' == active, '.' == missing)
root@grml ~ # pvs -o +pe_start
  PV         VG      Fmt  Attr PSize PFree 1st PE
  /dev/md0   homesrv lvm2 a--  4.09t 4.09t   1.50m
root@grml ~ # pvs --units s -o +pe_start
  PV         VG      Fmt  Attr PSize       PFree       1st PE
  /dev/md0   homesrv lvm2 a--  8784175104S 8773689344S   3072S
root@grml ~ # pvs -o +pe_start
  PV         VG      Fmt  Attr PSize PFree 1st PE
  /dev/md0   homesrv lvm2 a--  4.09t 4.09t   1.50m
root@grml ~ # pvs --units s -o +pe_start
  PV         VG      Fmt  Attr PSize       PFree       1st PE
  /dev/md0   homesrv lvm2 a--  8784175104S 8773689344S   3072S
root@grml ~ # vgs -o +pe_start
  VG      #PV #LV #SN Attr   VSize VFree 1st PE
  homesrv   1   2   0 wz--n- 4.09t 4.09t   1.50m
root@grml ~ # vgs --units s -o +pe_start
  VG      #PV #LV #SN Attr   VSize       VFree       1st PE
  homesrv   1   2   0 wz--n- 8784175104S 8773689344S   3072S
Cryptsetup:
root@grml ~ # echo cryptsetup >> /etc/debootstrap/packages
root@grml ~ # cryptsetup luksFormat -c aes-xts-plain64 -s 256 /dev/mapper/homesrv-rootfs
WARNING!
========
This will overwrite data on /dev/mapper/homesrv-rootfs irrevocably.
Are you sure? (Type uppercase yes): YES
Enter passphrase:
Verify passphrase:
root@grml ~ # cryptsetup luksOpen /dev/mapper/homesrv-rootfs cryptorootfs
Enter passphrase for /dev/mapper/homesrv-rootfs:
Filesystems:
root@grml ~ # mkfs.ext4 /dev/mapper/cryptorootfs
mke2fs 1.42.8 (20-Jun-2013)
Filesystem label=
OS type: Linux
Block size=4096 (log=2)
Fragment size=4096 (log=2)
Stride=128 blocks, Stripe width=384 blocks
262144 inodes, 1048192 blocks
52409 blocks (5.00%) reserved for the super user
First data block=0
Maximum filesystem blocks=1073741824
32 block groups
32768 blocks per group, 32768 fragments per group
8192 inodes per group
Superblock backups stored on blocks:
        32768, 98304, 163840, 229376, 294912, 819200, 884736
Allocating group tables: done
Writing inode tables: done
Creating journal (16384 blocks): done
Writing superblocks and filesystem accounting information: done
root@grml ~ # mkfs.ext4 /dev/mapper/homesrv-bootfs
mke2fs 1.42.8 (20-Jun-2013)
Filesystem label=
OS type: Linux
Block size=4096 (log=2)
Fragment size=4096 (log=2)
Stride=128 blocks, Stripe width=384 blocks
65536 inodes, 262144 blocks
13107 blocks (5.00%) reserved for the super user
First data block=0
Maximum filesystem blocks=268435456
8 block groups
32768 blocks per group, 32768 fragments per group
8192 inodes per group
Superblock backups stored on blocks:
        32768, 98304, 163840, 229376
Allocating group tables: done
Writing inode tables: done
Creating journal (8192 blocks): done
Writing superblocks and filesystem accounting information: done
Install Debian/wheezy:
root@grml ~ # mount /dev/mapper/cryptorootfs /media
root@grml ~ # mkdir /media/boot
root@grml ~ # mount /dev/mapper/homesrv-bootfs /media/boot
root@grml ~ # grml-debootstrap --target /media --password YOUR_PASSWORD --hostname YOUR_HOSTNAME
 * grml-debootstrap [0.57] - Please recheck configuration before execution:
   Target:          /media
   Install grub:    no
   Using release:   wheezy
   Using hostname:  YOUR_HOSTNAME
   Using mirror:    http://http.debian.net/debian
   Using arch:      amd64
   Important! Continuing will delete all data from /media!
 * Is this ok for you? [y/N] y
[...]
Enable grml-rescueboot (to have easy access to rescue ISO via GRUB):
root@grml ~ # mkdir /media/boot/grml
root@grml ~ # wget -O /media/boot/grml/grml64-full_$(date +%Y.%m.%d).iso http://daily.grml.org/grml64-full_testing/latest/grml64-full_testing_latest.iso
root@grml ~ # grml-chroot /media apt-get -y install grml-rescueboot
[NOTE: We're installing a daily ISO for grml-rescueboot here because the 2013.09 Grml release doesn't work for this LVM/SW-RAID setup while newer ISOs are working fine already. The upcoming Grml stable release is supposed to work just fine, so you will be able to choose http://download.grml.org/grml64-full_2014.XX.iso by then. :)] Install GRUB on all disks and adjust crypttab, fstab + initramfs:
root@grml ~ # grml-chroot /media /bin/bash
(grml)root@grml:/# for f in  a,b,c,d  ; do grub-install /dev/sd$f ; done
(grml)root@grml:/# update-grub
(grml)root@grml:/# echo "cryptorootfs /dev/mapper/homesrv-rootfs none luks" > /etc/crypttab
(grml)root@grml:/# echo "/dev/mapper/cryptorootfs / auto defaults,errors=remount-ro 0   1" > /etc/fstab
(grml)root@grml:/# echo "/dev/mapper/homesrv-bootfs /boot auto defaults 0 0" >> /etc/fstab
(grml)root@grml:/# update-initramfs -k all -u
(grml)root@grml:/# exit
Clean unmounted/removal for reboot:
root@grml ~ # umount /media/boot
root@grml ~ # umount /media/
root@grml ~ # cryptsetup luksClose cryptorootfs
root@grml ~ # dmsetup remove homesrv-bootfs
root@grml ~ # dmsetup remove homesrv-rootfs
NOTE: On a previous hardware installation I had to install GRUB 2.00-22 from Debian/unstable to get GRUB working.
Some metadata from different mdadm and LVM experiments seems to have been left and confused GRUB 1.99-27+deb7u2 from Debian/wheezy (I wasn t able to reproduce this issue in my VM demo/test setup).
Just in cause you might experience the following error message, try GRUB >=2.00-22:
  # grub-install --recheck /dev/sda
  error: unknown LVM metadata header.
  error: unknown LVM metadata header.
  /usr/sbin/grub-probe: error: cannot find a GRUB drive for /dev/mapper/cryptorootfs.  Check your device.map.
  Auto-detection of a filesystem of /dev/mapper/cryptorootfs failed.
  Try with --recheck.
  If the problem persists please report this together with the output of "/usr/sbin/grub-probe --device-map="/boot/grub/device.map"
  --target=fs -v /boot/grub" to <bug-grub@gnu.org>

Rog rio Brito: Paco de Lucia

I was super sad to know that Paco de Lucia passed a few days ago. It was shocking to know that he was so young (only 66 year old, if I am not mistaken). To share some of his fine work with his frequent collaborators John McLaughlin and Al Di Meola to people that may not otherwise know him or his work, I offered on a Facebook post to upload a bootleg of a show of the Guitar Trio (John McLaughlin, Paco De Lucia and Al Di Meola) with the entire performance (possibly out of order, as that is a bootleg, after all) ripped from a broadcast to Dutch TV station. This performance includes the exceptional Paco de Lucia prominently and the show has many songs from the "Friday Night in San Francisco" record, including the magnificent (IMVHO) "Mediterranean Sundance". The credits of the video are, of course, of the musicians. I only ripped, deinterlaced (remember, analog TV it was interlaced), denoised, encoded, and uploaded the video to youtube.

27 February 2014

Stefano Zacchiroli: moar stats for sources.debian.net

Debian: watch your stats! Over the past few weeks, myself and Matthieu Caneill have worked quite a bit on Debsources. As we have now deployed most of the new features on http://sources.debian.net, it's time for another "What's new with Debsources?" blog post. Here is what's new: Want more? Sure, we'll be happy to! But it'll happen faster if you help. Speaking of which: we've got Debsources into the new contributors game (see announcement) and we're looking forward to mentor new contributors.

Lucas Nussbaum: self-hosting my calendar, follow-up

Following my blog post on the topic, I played a bit with various options. But let s explain my use case (which might be quite specific). I need to deal with three main sources of events: Additionally, I follow some ICS feeds for some colleagues and other events.
I tend to access my calendar mostly on my computer, and sometimes on my N900 phone. None of the web interfaces I looked at enabled me to (1) manage different calendars hosted on different CalDav servers; (2) subscribe to ICS feeds; (3) provide a CalDav interface to synchronize my phone. I ended up using a radicale instance for my personal calendar, which was extremely easy to set up. It s unfortunately a bit slow when there are many events (1600 since 2010 in my case), so I ended up importing only future events, and I will probably have to cleanup from time to time. I switched to using IceDove with the Lightning add-on to manage all my calendars and ICS feeds. It s unfortunately slower and less user-friendly than Google Calendar, but I ll live with it. On my N900, I used syncevolution to synchronize my various CalDav calendars. It works fine, but understanding how to configure it is rather tricky due to the number of concepts involved (templates, databases, servers, contexts, ). The synchronization is quite slow (several minutes for the 400-events Zimbra calendar), but works. I also wanted a way to export my calendars to colleagues (both in a free/busy version, and in a full information version). I quickly hacked something using ruby-agcaldav (which is not packaged in Debian, and required quite a few dependencies, but it was easy to generate packages for all of them using gem2deb the situation with other languages did not look better).
The resulting script is:
require 'agcaldav'
require 'date'
cal = AgCalDAV::Client.new(:uri => 'LABCALDAVSERVER', :user => 'xx', :password => "xx")
ev = cal.find_events(:start => '2014-02-01', :end => '2200-01-01') cal = AgCalDAV::Client.new(:uri => 'RADICALESERVER', :user => 'xx', :password => "xx")
ev2 = cal.find_events(:start => '2014-02-01', :end => '2200-01-01') limit = (Time::now - 7*86400).to_datetime # create new empty calendars
ncpriv = Icalendar::Calendar.new
ncpub = Icalendar::Calendar.new (ev + ev2).each do e
next if e.end < limit # drop old events to keep the calendar small # build event for the free/busy calendar
pe = Icalendar::Event.new
pe.start = e.start
pe.end = e.end
pe.klass = "PRIVATE"
pe.transp = e.transp
ncpriv.add(pe) # build event for the calendar with event information
pube = Icalendar::Event.new
pube.start = e.start
pube.end = e.end
pube.transp = e.transp
if not e.klass == "PRIVATE"
pube.summary = e.summary
pube.location = e.location
end
ncpub.add(pube)
end # export free/busy calendar
fd = File::new('xx.ics', 'w')
fd.puts ncpriv.to_ical
fd.close
# export calendar with event information
fd = File::new('yy-Zeeh9bie.ics', 'w')
fd.puts ncpub.to_ical
fd.close
So, mostly everything works. The only thing that doesn't is that I haven't found a way to subscribe to an ICS feed on my N900. Any ideas?

Simon Josefsson: Replicant 4.2 on Samsung S3

Since November 2013 I have been using Replicant on my Samsung S3 as an alternative OS. The experience has been good for everyday use. The limits (due to non-free software components) compared to a normal S3 (running vendor ROM or CyanogenMod) is lack of GPS/wifi/bluetooth/NFC/frontcamera functionality although it is easy to get some of that working again, including GPS, which is nice for my geocaching hobby. The Replicant software is stable for being an Android platform; better than my Nexus 7 (2nd generation) tablet which I got around the same time that runs an unmodified version of Android. The S3 has crashed around ten times in these four months. I ve lost track of the number of N7 crashes, especially after the upgrade to Android 4.4. I use the N7 significantly less than the S3, reinforcing my impression that Replicant is a stable Android. I have not had any other problem that I couldn t explain, and have rarely had to reboot the device. The Replicant project recently released version 4.2 and while I don t expect the release to resolve any problem for me, I decided it was time to upgrade and learn something new. I initially tried the official ROM images, and later migrated to using my own build of the software (for no particular reason other than that I could). Before the installation, I wanted to have a full backup of the phone to avoid losing data. I use SMS Backup+ to keep a backup of my call log, SMS and MMS on my own IMAP server. I use oandbackup to take a backup of all software and settings on the phone. I use DAVDroid for my contacts and calendar (using a Radicale server), and reluctantly still use aCal in order to access my Google Calendar (because Google does not implement RFC 5397 properly so it doesn t work with DAVDroid). Alas all that software is not sufficient for backup purposes, for example photos are still not copied elsewhere. In order to have a complete backup of the phone, I m using rsync over the android debug bridge (adb). More precisely, I connect the phone using a USB cable, push a rsyncd configuration file, start the rsync daemon on the phone, forward the TCP/IP port, and then launch rsync locally. The following commands are used: jas@latte:~$ cat rsyncd.conf
address 127.0.0.1
uid = root
gid = root
[root]
path = /
jas@latte:~$ adb push rsyncd.conf /extSdCard/rsyncd.conf
* daemon not running. starting it now on port 5037 *
* daemon started successfully *
0 KB/s (57 bytes in 0.059s)
jas@latte:~$ adb root
jas@latte:~$ adb shell rsync --daemon --no-detach --config=/extSdCard/rsyncd.conf &
jas@latte:~$ adb forward tcp:6010 tcp:873
jas@latte:~$ sudo rsync -av --delete --exclude /dev --exclude /acct --exclude /sys --exclude /proc rsync://localhost:6010/root/ /root/s3-bup/
...
Now feeling safe that I would not lose any data, I remove the SIM card from my phone (to avoid having calls, SMS or cell data interrupt during the installation) and follow the Replicant Samsung S3 installation documentation. Installation was straightforward. I booted up the newly installed ROM and familiarized myself with it. My first reaction was that the graphics felt a bit slower compared to Replicant 4.0, but it is hard to tell for certain. After installation, I took a quick rsync backup of the freshly installed phone, to have a starting point for future backups. Since my IMAP and CardDav/CalDav servers use certificates signed by CACert I first had to install the CACert trust anchors, to get SMS Backup+ and DAVDroid to connect. For some reason it was not sufficient to add only the root CACert certificate, so I had to add the intermediate CA cert as well. To load the certs, I invoke the following commands, selecting Install from SD Card when the menu is invoked (twice). adb push root.crt /sdcard/
adb shell am start -n "com.android.settings/.Settings\"\$\"SecuritySettingsActivity"
adb push class3.crt /sdcard/
adb shell am start -n "com.android.settings/.Settings\"\$\"SecuritySettingsActivity"
I restore apps with oandbackup, and I select a set of important apps that I want restored with settings preserved, including aCal, K9, Xabber, c:geo, OsmAnd~, NewsBlur, Google Authenticator. I install SMS Backup+ from FDroid separately and configure it, SMS Backup+ doesn t seem to want to restore anything if the app was restored with settings using oandbackup. I install and configure the DAVdroid account with the server URL, and watch it populate my address book and calendar with information. After organizing the icons on the launcher screen, and changing the wallpaper, I m up and running with Replicant 4.2. This upgrade effort took me around two evenings to complete, with around half of the time consumed by exploring different ways to do the rsync backup before I settled on the rsync daemon approach. Compared to the last time, when I spent almost two weeks researching various options and preparing for the install, this felt like a swift process.
I spent some time researching how to get the various non-free components running. This is of course sub-optimal, and the Replicant project does not endorse non-free software. Alas there aren t any devices out there that meets my requirements and use only free software. Personally, I feel using a free core OS like Replicant and then adding some non-free components back is a better approach than using CyanogenMod directly, or (horror) the stock ROM. Even better is of course to not add these components back, but you have to decide for yourselves which trade-offs you want to make. The Replicant wiki has a somewhat outdated page on Samsung S3 firmware. Below are my notes for each component, which applies to Replicant 4.2 0001. You need to first prepare your device a bit using these commands, and it is a good idea to reboot the device after installing the files. adb root
adb shell mount -o rw,remount /system
adb shell mkdir /system/vendor/firmware
adb shell chmod 755 /system/vendor/firmware
GPS: The required files are the same as for Replicant 4.0, and using the files from CyanogenMod 10.1.3 works fine. The following commands load them onto the device. Note that this will load code that will execute on your main CPU which is particularly bothersome. There seems to exist a number of different versions of these files, CyanogenMod have the same gpsd and gps.exynos4.so in version 10.1.3 and 10.2 but the libsecril-client.so differs between 10.1.3 and 10.2. All files differ from the files I got with my stock Samsung ROM on this device (MD5 checksums in my previous blog). I have not investigated how these versions differs or which of them should be recommended. I use the files from CyanogenMod 10.1.3 because it matches the Android version and because the files are easily available. adb push cm-10.1.3-i9300/system/bin/gpsd /system/bin/gpsd
adb shell chmod 755 /system/bin/gpsd
adb push cm-10.1.3-i9300/system/lib/hw/gps.exynos4.so /system/lib/hw/gps.exynos4.so
adb push cm-10.1.3-i9300/system/lib/libsecril-client.so /system/lib/libsecril-client.so
adb shell chmod 644 /system/lib/hw/gps.exynos4.so /system/lib/libsecril-client.so
Bluetooth: Only one file has to be installed, apparently firmware loaded onto the Bluetooth chip. Cyanogenmod 10.1.3 and 10.2 contains identical files, which has a string in it BCM4334B0 37.4MHz Class1.5 Samsung D2 . The file I got with my stock ROM has a string in it BCM4334B0 37.4MHz Class1.5 Samsung M0 . I don t know the difference, although I have seen that D2 sometimes refers to the US version of a Samsung device. My device is the international version, but it seems to work anyway. adb push cm-10.1.3-i9300/system/bin/bcm4334.hcd /system/vendor/firmware/bcm4334.hcd
adb shell chmod 644 /system/vendor/firmware/bcm4334.hcd
Front Camera: Two files has to be installed, apparently firmware loaded onto the Camera chip. CyanogenMod 10.1.3 and 10.2 contains identical files, which has a string in it [E4412 520-2012/08/30 17:35:56]OABH30 . The file I got with my stock ROM has a string in it [E4412 533-2012/10/06 14:38:46]OABJ06 . I don t know the difference. adb push cm-10.1.3-i9300/system/vendor/firmware/fimc_is_fw.bin /system/vendor/firmware/fimc_is_fw.bin
adb push cm-10.1.3-i9300/system/vendor/firmware/setfile.bin /system/vendor/firmware/setfile.bin
adb shell chmod 644 /system/vendor/firmware/fimc_is_fw.bin /system/vendor/firmware/setfile.bin
NFC: I m happy that I got NFC to work, this was one of my main issues with Replicant 4.0 (see my earlier blog post). Only one file is needed, however CyanogenMod does not seem to distribute it so you have to get it from your stock ROM or elsewhere. The md5 of the file I have is b9364ba59de1947d4588f588229bae20 (and no I will not send it to you). I have tested it with the YubiKey NEO and the Yubico Authenticator app. adb push clockworkmod/blobs/ee6/7188ca465cf01dd355a92685a42361e113f886ef44e96d371fdaebf57acae /system/vendor/firmware/libpn544_fw.so
adb shell chmod 644 /system/vendor/firmware/libpn544_fw.so
Wifi: I haven t gotten wifi to work, although I have not tried very hard. Loading the CyanogenMod firmwares makes my device find wireless networks, but when I try to authenticate (WPA-PSK2), I get failures. Possibly some other files has to be loaded as well. Update: This blog post has been updated since initial posting to use rsync over adb instead of USB tethering, and to mention that I got the ROM building to work. flattr this!

Andrew Pollock: [life] Day 30, A full day on Coochie

Last night went pretty well. Once I got Zoe to sleep, she slept well, with only a brief wake up around 2am. Any mosquito bites she sustained didn't seem to give her any grief. She woke this morning at 6am. It makes me think the blackout curtains at home aren't really contributing to her sleeping in. We had a lazy start to the day. Zoe watched some TV after breakfast, and after I had a shower, fed some bread crusts to the chickens and then we played with the box of dress up costumes for a little while. After that, we jumped on the bike and went down to check out the trademark of Quirky Cottages, a bunch of converted rail cars and "zoo". There were chickens, geese, guinea pigs, a sheep and a donkey. The rail cars weren't anything much to phone home about (much like the Cow House). In fact the whole affair looked a bit dilapidated. Then we continued on the bike down to the local playground, where Zoe had a swing for a bit. We walked over to the jetty and watched the passenger ferry arrive, and then bought a loaf of bread at the store and biked back to the house. It was too early to have lunch, so we just pottered around in the yard. We inspected the chicken coop, and Zoe played on the swings and swung from the rope swing. We tried and failed to catch a chicken, because Zoe wanted me to pick one up. We had lunch, and then Zoe had some fabulous self-directed imaginative play indoors with the various props the house had to offer, while I put my feet up. Then she declared she wanted to take a nap anyway. After her nap, I wanted to go back to the beach. I'd gotten myself all organised so that we could try and jump on the bike as soon as possible once Zoe woke up, but there was the requisite amount of stuffing around. I'd put Zoe's water shoes on, so she could ride in the trailer in her swim gear ready to go, but she had a mosquito bite on her foot that was giving her grief, so I cut my losses, and took the water shoes off and put her sandals back on, and promptly left the water shoes behind. We got all the way to the beach before I realised, and so we had to go back and get them. Once we finally made it back to the beach, I chose a different location than yesterday, just so we would not have any memories of the mud crab incident to deal with. It turned out to be a good choice, because we had a fabulous time exploring. The tide was even lower than yesterday, and the water was a bit silty, so we didn't do much paddling around in it, instead we explored the rock pools. We found some tiny (1 centimetre and smaller) hermit crabs. These didn't seem to freak Zoe out, and she was even prepared to hold them. We saw some really small mud crabs. Once we were still for a little while heaps of soldier crabs started coming out, right near us. That was pretty cool. On the walk back to the bike, I found a crab claw on the beach, so Zoe got to take that as souvenir. I showed her how the claw opened and closed. I think we'll have to eat a crab in the near future, just so she can get a good look at one up close. I most liked how as the excursion progressed, Zoe became more and more confident with the rocks and the tide pools. Initially she was apprehensive of everything, but starting with the soldier crabs, she'd become more and more comfortable with everything. I'd poke at stuff, she'd poke at stuff. It finished with her being comfortable wandering off to explore on her own. We got home, Zoe had a shower and then I made dinner while she watched TV. We read some stories and so far bedtime appears to have gone pretty smoothly, which is good. I'm feeling quite exhausted. Tomorrow morning we have to pack everything up and be on the 9am barge out of here so we can race home, and repack to fly down to Melbourne for the weekend.

26 February 2014

Vincent Sanders: There are only two hard things in Computer Science: cache invalidation and naming things.

It is the first of these which I have recently been attempting and I think Phil Karlton might have a good point.
What are we talking about?Web browsers are pretty complex beasties but the basic concept is pretty easy to understand. They fetch a bunch of files that make up a web page and render those source files into something suitable for human consumption.

It is also intuitive that fetching all the files that make up a web page, every time you browse to a new page, might be wasteful, especially if most of the files had not changed from the previous page.

In order to address this browsers hang onto copies of these files in case your browsing needs them again, this is known as a source file cache. Caches are a widely used technique throughout many aspects of computer technology but the basic idea is that they trade one resource for another.

In this case we are trading local storage space (memory or disc) for access time. This type of trade may give large benefits due to the large differences in access times (sometimes known as latency) between local and network resources.

For example, if the source files that make up a web page are a Megabyte in size accessed with a 2013 era PC with a 10Mbit connection to the Internet:
From this example it becomes startlingly obvious why a source cache is so desirable. I have greatly simplified the browsers operation here as they usually implement many layers of additional caching in other areas to make the browsing experience subjectively smoother.

And before the observant reader suggests that we could just make the network faster it ought to be mentioned that due to fundamental physical constraints, like the speed of light, it would be unlikely that the average practical network reply will ever drop much below 150,000 s [1] or some 40 times slower than disc. Still a worthwhile gain.
Knowing the cost of everything and the value of nothingHaving shown the benefits it might be nice to think there are no downsides to caching, this is not the case, as I mentioned we are trading storage for time and as in any trade one must expect there to be overheads.

In the case of a browser we face several obstacles. Firstly not every file that goes to make up a web page can be cached. The HTTP specification contains an entire section on caching which contains numerous rules and operations to ensure that only objects that should be cached are and determines for how long they can be kept before going "stale".

A great deal of this complexity comes from just how desirable caching is to network providers. Many ISPs will have web proxy servers to cache requests for all users to reduce their bandwidth usage, or increasingly, to implement content filtering according to the local government censorship rules. The browsers cache must know how to interact with these proxies without getting erroneous results.

Then comes the problem alluded to in the section title. A browsers cache cannot grow indefinitely. Eventually a system would run out of memory and disc if a browser kept every file. To deal with this the cache is limited sometimes by the number of files it holds, but more commonly by size both in memory and on disc.

The caching structure used by a web browser is hierarchical in that it will first evict (move) files from memory to a backing store (disc) and when the disc cache size limit is exceeded files are evicted to the next tier. Which in this case, will involve deleting the local copy (invalidating) and requiring performing a fetch from the network if the file is needed again.

Tardis at the Beeb by Sarah G from flikrWhen the cache size is exceeded the decision is made about what to remove from the cache using a cache strategy or algorithm. The aim of this decision is to discard the data that will not be required again for the longest time.

If we had a blue box with a madman inside, who we could persuade to bring our browsing history back from the future, implementing b l dy's algorithm might be possible. Failing a perfect solution we are reduced to making a judgement based on the information available to us.

This involves computing a cost for replacing each entry in the cache and evicting those with the lowest values. The selected algorithm has a large impact on the effectiveness of the cache and often needs fine tuning for the task at hand.
Never has so little been measured so muchHaving established that caching is useful and that we need to make decisions on what to keep it follows that those decisions must be based on information. This information consists of two main groups:
Maintaining all of this information is a significant part of the overheads involved with caching and a compromise must be struck between having the necessary information to make good caching choices and the cost maintaining that data.
Cache metricsMost cache implementations maintain at least some basic metrics, at the very least how much storage is being used so a decision on if evicting entries from the cache to reclaim space is necessary.

It is also common to keep a record of how well the cache is performing. The cache efficiency (the hit rate) is usually measured as the ratio of successful accesses provided from the cache (a cache hit) to the total number of requests to the cache.

A perfect cache would have all hits and no misses (a hit rate of 1) while using as little storage as possible (but as already noted that requires a special madman). The hit rate can be used to automatically change the behaviour of the eviction algorithm, perhaps using more storage if the hit rate drops too low or changing the eviction frequency.
MetadataEach object must carry with it the data necessary to regain its state when retrieved from the cache. This information is essential for the correct operation of the cache but in of itself provides no direct value.

In the case of browser source data this includes all the headers sent in the original network fetch. These headers are themselves just metadata sent along with the object by the web server which must be preserved.

Two particularly useful value for making a good eviction decision are how long it has been since the object was last used and how many times it has been used. This is because an object that was cached a long time ago and then never used again is much less valuable than one that has recently been repeatedly used.
An ImplementationIt is all very well talking about the general solution but a full understanding can only be gained by examining a real implementation. The NetSurf cache was chosen as it is a suitably small amount of code but still demonstrates all the major design features.
InterfaceThe cache deals with all source data and provides the browser with a single unified object request interface regardless of if the source data can be cached or not. This is useful to hide the implementation details allowing for changes without affecting the rest of the browsers code.

The implementation effectively consists of two lists of objects, those that can be cached and those that cannot. Each object on these lists is reference counted against one or more users and while there is at least one user the source data is maintained in memory.

Objects determined to be non cached are always directly fetched from their source and are immediately released once they have no users remaining.

For cacheable objects an attempt is made to fulfil the request in descending order:
  1. from objects already in memory.
  2. from the backing store.
  3. from a network fetch.
Irrespective of the source of the data the remaining operations on the object (determining freshness etc.) are exactly as if the request had been fulfilled from the network. This approach means the use of the cache is transparent to the object users.
WriteoutObjects are placed in the backing store asynchronously to any other operations. When an object has been fetched from the network a background task is scheduled for when the browser is otherwise idle.

This writeout task constructs a list of all cacheable objects not yet in the backing store, associates a cost value with each object and then proceeds to write those objects to the backing store in highest to lowest value order.
CleaningA periodically scheduled task deals with ensuring the cache is cleaned. This consists of destroying stale objects and arranging fresh objects are not using more memory than the configuration permits.

Memory usage is reduced within the cleaning task by discarding the source data for objects already held in the backing store (where the data can be retrieved relatively cheaply)

Additional memory may be recovered by simply discarding unused objects held only in memory. These objects are usually those which have only recently become unused otherwise the writeout task would have committed them to the backing store.

The most recently used objects are statistically likely to be used again soon, because of this there is a high risk of a cache miss associated with discarding these objects. In order to mitigate this undesirable effect the cleaning heuristic favours using more memory than configured for short periods rather than discarding from memory.
Backing storeThe backing store is a simple key-value database. Each source data object and its metadata (its headers etc.) is associated with a unique key (the URL used to fetch it). The backing store is simply required to store and retrieve the object data associated with the given URL.

The backing store implementation in NetSurf is pluggable, this flexibility is required for dealing with the greatly varying capabilities and limits of the various systems the browser is required to execute on.

A novel aspect of this backing store interface is that if an implementation returns the wrong object it is not considered an error and is simply treated as a cache miss. This is possible because the metadata contains the URL of the stored object enabling object verification.

This behaviour is permitted because techniques which significantly improve key-value store performance (principally key hashing) become available if they are not required to always give the correct answer.

The backing store is also required to manage its size within the configured limits and deal with any filesystem behaviour details.

The reference backing store is trivial in that it performs a hash operation on the input URL, encodes the result with base64url encoding and uses that as the object filename. The length of the hash can be configured allowing use of the reference implementation in any situation where using the filesystem as a database is acceptable.

The reference backing store default hash is SHA-1 yielding almost unique [2] 160 bit key values stored in much the same way as the git DVCS. Note we are not using this hash for its cryptographic properties and at worst a collision will result in the cache being a tiny amount less efficient.
ConclusionHopefully this has shown what a browser source file cache is, why it is useful and a basic understanding of how they are implemented.

I will admit I have glossed over some of the more challenging aspects especially in relation to actually implementing the cache strategy but I hope that the reader will forgive those omissions of detail in a quest for a little more clarity of the general principles.

I would like to thank John-Mark Bell for implementing the NetSurf cache and to Melodie Parry for proof reading and providing feedback.

[1] Speed of light is 3x10^8m/s earth circumference is 4x10^7m, divide circumference by speed gives 133,000 s which gives longest round trip time from anywhere on surface of earth to point furthest from. So assuming a whole megabyte can be transferred in one round trip and allowing for some overhead the lower bound estimate of 150,000 s looks reasonable.

[2] Mathematically speaking this hash would allow us to say that with the current estimated 1x10^11 URLs on the internet the likelihood of a collision is still vanishingly small (at least 1x10^-15)

Daniel Pocock: Free communications software takes another big jump

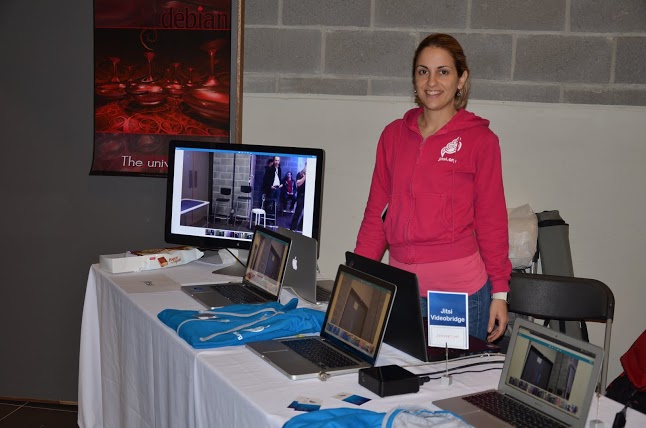
One of the most exciting demonstrations at FOSDEM this year was the new JitMeet web application from the Jitsi team. JitMeet takes the power of the traditional Jitsi Videobridge and makes it accessible to anyone, anywhere (with a modern web browser) using WebRTC. Yana from the Jitsi team with a table full of devices running different operating systems and browsers connecting to a JitMeet video conference. The demo also extended to the Debian table which was immediately underneath (ground floor) and within range of the real-time lounge private WLAN. What makes this so exciting? The thing that stands out for me is that you can run it on any web server under your own control. This gives people real choice in an era when people are starting to realize the risk of using "free" cloud services. Any Linux web server - big or small, running your preferred distribution - can run a JitMeet conference. Here it is running on a very small Intel i3-based NUC with Debian For those who want to know more, you can watch Emil's lightning talk about JitMeet or ask on the Jitsi user mailing list. Emil's lightning talk about JitMeet

Andrew Pollock: [life] Day 29, Coochiemudlo Island and The Cow House

I thought it might be a good idea for Zoe to do something out of the ordinary while Sarah was away, to help pass the time, so I booked The Cow House, one of the Quirky Cottages on Coochiemudlo Island for a couple of nights. I'm thinking it'll be a fun goal to work our way around all of the islands in Moreton Bay eventually, and Coochie is an easy 20 minute barge journey from Victoria Point, so it seemed like as good a starting point as any. So I packed the car up this morning, and after my 8am chiropractic adjustment, we set out. I'd initially thought the barge left at 9:40am, but I was relieved discover it was 10:40am. That extra hour up my sleeve made things much less hectic. It was a 40 minute drive from home to Victoria Point, and we arrived with enough time for Zoe to have a quick play in a nearby playground before we had to drive onto the barge. The house is nothing to phone home about. In fact the mobile coverage is so patchy, phoning home would be rather difficult. It's an old two bedroom fibro shack, with a painted concrete floor. It's been nicely painted in cow print and themed extremely bovinely. Zoe loved it. There were stuffed cows everywhere. She even found some cow slippers. There's chickens running around loose outside. My biggest beef with the place is the fly screens aren't intact, and there are plenty of mosquitoes about. I'm going to have keep Zoe lathered in mosquito repellent or we're going to have a bad time. There is a good supply of kids' dress up costumes, and Zoe's been prancing around the house in a pink princess dress any time she gets the opportunity. I brought the bike and bike trailer with me (which ended up making packing the car more of a challenge). After Zoe's nap, we went for an explore around the island by bike. There was no road around the outside of the island, so we followed the main road along the width of the island, and reached the other side in about 5 minutes. The tide was out, so we decided to return back to the house to get our swim gear and come back and have a bit of a splash around in the water. We biked back in our swim gear. I'd bought Zoe a pair of water shoes so we didn't have to worry about what we were walking on, and I wore my snorkeling boots. The tide was out, but it looked like it was coming back in. We walked out to a big pole that was in the water marking some rocks and then started walking back again. Zoe was a bit standoffish about rocks in the water, and generally a bit apprehensive of anything strange along the way. I spotted a mud crab in really shallow water by the shore, and brought Zoe over to see it. It had half buried itself in the sand, so I nudged it with my boot and it came out with its claws out, and Zoe completely freaked out when it started walking in her direction and she gave the most bloodcurdling scream I've ever heard her make (way worse than when she had her last vaccinations) and she climbed up my leg like a rat up a rope. That was the end of that. She wasn't very interested in walking along the beach lest we run into any more crabs, so we biked back to our side of the island, had an ice cream and returned to the house so Zoe could have a shower and I could start dinner. Zoe's sleeping in a king sized bed tonight, so we'll see how that works out. Bedtime has been a little bit interesting because of the change of surroundings, and there's been a lot of pining for Mummy. Hard to say if it's because of the nap today or the different sleeping arrangements.

25 February 2014

Steve Kemp: What do you pay for, and what would you pay for?

There are times when I consider launching my own company again, most often when it is late at night and the inpetitude of so many other companies gets me too worked up. Then I sit back and think about details and write it off. I've worked for myself in the past a couple of times, and each time it was both more fun and more difficult than expected. Getting a couple of clients is usually easy, getting a ten more is common, but getting "many" is hard and getting "lots" is something I've never done - lots of users for free sites though, along with the associated support burdon! So the though dies away once I sit down and work out the net profit I'd need to live. My expenses are low, so let us pretend I can easily live on 1000 a month. So the "company" has to make more than that, to cover costs, but perhaps not much. Pretend you were offering DNS hosting you'd probably be able to implement that easily on, say 10, virtual machines, net of 150 a month. Imagine clients pay 5 for an unlimited number of domains that means you need to have 1000+150/5 = 230 clients. Not impossible, but also not easy. Pretend instead you're offering backup space, and the numbers get bigger because disk is expensive. Again getting some users would be easy, but getting lots would be hard because your competition is dropbox, skydrive, etc, etc. Once you start thinking of "ideas" they come easily, but the hard part is being realistic about what people would pay for. As always the idea is the easy part, the execution is the hardest part. Realistically if I were to be desperate to work for myself at short notic I'd do the obvious thing - I'd buy a pair of ladders, a bucket, and clean windows. Low overheads, reasonable demand, and I'd be both "fit" and "outdoors". When it comes to paying for online services off the top of my head I personally pay for maybe two things, both of them niche (although profitable for their providers I'm sure), and I know many people who live on the internet but pay for nothing.
For example I'm a VIP member of an online modeling community, which in theory allows me a higher chance of persuading interesting people to pose for me. In practice the turnover on those sites is immense. Lots of cute boys and girls hear constantly "You're so pretty, you should be a model", which is true in perhaps 1% of cases, and the net result is you have a few hard working people who do good things day in day out, and many flighty teenagers who'll pose for two-three people, and then never do it again because they realise it is neither glamourous nor easy money.
Two things I've semi-serously considered recently where hosted "status pages", and hosted "domain parking", but both have many competitors and both I can see a) some people would pay for but b) not very many. I suspect there is no universal "I'd pay for this" online service hwich is both competition free and genuinely trivial to setup, but I'd be curious to see what people are missing, and even more curious to see what people do pay for.

Bits from Debian: Call for participants in the Google Summer of Code for Debian

GSoC 2014 logo The Google Summer of Code is a program that allows post-secondary students aged 18 and older to earn a stipend writing code for Free and Open Source Software projects during the summer. Debian has just been accepted as a mentoring organization for this year's program! We're looking for students and mentors to make this GSoC in Debian the best ever! Eligible students, now is the time to take a look at our project ideas list, engage with the mentors for the projects you find interesting, and start working on your application! For more information, please read the FAQ and the Program Timeline on Google's website. Mentors for prospective projects can still submit proposals on the project ideas list. You also need to send an email to the mailing list linked below to present your project in a few words. Feel also free to propose yourself as a co-mentor for one of the listed projects, more help is always welcome! If you are interested, we encourage you to come and chat with us on irc (#debian-soc on irc.oftc.net), or to send an email to the SoC coordination mailing-list (subscribe). Most of the Debian-specific GSoC information can be found on our wiki pages, but don't be afraid to ask us directly on irc or via email. We're looking forward to work with an amazing team of students and mentors again this summer!

Christoph Berg: Trusty and Saucy on apt.postgresql.org

Over the past few weeks, new distributions have been added on apt.postgresql.org: Ubuntu 13.10 codenamed "saucy" and the upcoming Ubuntu LTS release 14.04 codenamed "trusty". Adding non-LTS releases for the benefit of developers using PostgreSQL on their notebooks and desktop machines has been a frequently requested item since we created the repository. I had some qualms about targeting a new Ubuntu release every 6 months, but with having automated more and more parts of the repository infrastructure, and the bootstrapping process now being painless, the distributions are now available for use. Technically, trusty started as empty, so it hasn't all packages yet, but of course all the PostgreSQL server packages are there, along with pgAdmin. Saucy started as a copy of precise (12.04) so it has all packages. Not all packages have been rebuilt for saucy, but the precise packages included (you can tell by the version number ending in .pgdg12.4+12 or .pgdg13.10+1) will work, unless apt complains about dependency problems. I have rebuilt the packages needing it I was aware about (most notably the postgresql-plperl packages) - if you spot problems, please let us know on the mailing list. Needless to say, last week's PostgreSQL server updates are already included in the repository.

Andrew Pollock: [life] Day 28, Kindergarten, Taxes and a smattering of appointments

Today was yet another busy day. Zoe seems to have taken to waking up at around 5:30am instead of her normal 6:00am (or a bit later when I'm really lucky). Not sure what that's all about. I did get her to go back to bed until about 6:55am, and then she was happy to just come and snuggle in bed with me for a bit instead of play games on her Nexus 7. After that we had a leisurely start to day, making porridge with strawberries in the Thermomix, and then biked to Kindergarten. Somehow it still managed to be 8:45am by the time we got there. I was expecting it would be closer to 8:30am. Drop off looked like it was going to be clingy, but then she just waved me off, so that was nice. I had an appointment at the podiatrist at 11:40am, and that was back near Kindergarten, but further away from home, so I had this grand plan of cycling over there, and then twiddling my thumbs for a bit before Kindergarten pickup. That left me with only a couple of hours at home to work on my taxes before I had to leave again. I managed to make those couple of hours productive though, so that was good. I biked to the podiatrist, had my appointment, and then it was 1pm and I still needed lunch, so I decided to grab some at a cafe near the Kindergarten. I chilled out there for a while catching up on social media on my phone, and then headed over to the Kindergarten, but was still quite early, so I just hung out on one of the couches they have out by the front door, out of sight of the kids. The Kindergarten has an A-frame whiteboard out the front that they use to broadcast messages to parents at drop off and pick up time. One of the teachers came out to write something on it while I was sitting out there, and another parent reacted rather negatively to it as it was being written, so I had to go see it for myself. Apparently a child had a suspected gastro bug (he'd thrown up a couple of times). It was interesting observing the reactions of a few mothers as they trickled in for pick up. It's been a while since a gastro bug has gone through the household, so I guess the news didn't evoke a particularly powerful reaction in me. I'm going with the "suspected" and that hopefully Zoe didn't come into contact with patient zero. I guess time will tell. I certainly hope she doesn't come down with anything between now and Sunday, with all the travel we're doing. I had an accident report to sign today. Apparently a large wooden block hit Zoe in the head while they were packing up a tower they'd made. She had a bit of a lump on her head, but otherwise seemed fine. Zoe had a nap today, of unknown length, but woke up naturally as I entered the room. She took a fair while to get going though, and was grumpy and uncooperative getting on the bike. I ended up having to do it the "hard way" and we had a fabulous ride back with her doing a tired cry all the way. All the way until we passed a playground, when she snapped out of it and declared she wanted to have a play. I'd booked myself in for a haircut at 3pm, and a make up swim class at 4:45pm (to cover our absence this Saturday due to our Melbourne trip) so playing in the playground seemed like the perfect way to fill the gap. It was even on the way to swim class. So after I had my haircut, we popped home, grabbed her swim gear, and biked back to the playground for a bit. Then we went to swim class. This was her third one at her new level, and her progress continues to go very well. It's really exciting watching her. Zoe took her time leaving the pool, so we didn't get home until after 5:30pm and I hadn't started dinner yet. I whipped it up while Zoe watched some TV, and I managed to recoup all of the lost time after dinner and still get Zoe to bed at a reasonable hour. Bedtime itself went nice and smoothly. I used the canned goodnight video I asked Sarah to make for the first time tonight, and it was well received and I think defused any potential issues. I'm hoping she'll sleep well tonight, as her mosquito bites don't seem to be actively giving her trouble any more.

24 February 2014

Daniel Pocock: GSoC Organisations announced, Ganglia selected for 2014

Google has just published the list of organisations for Google Summer of Code 2014 It is no surprise that big projects like Debian and Fedora are all back again. On the other hand, I am delighted to announce that the Ganglia project is participating this year. We have started publishing a list of project ideas and we are keen to start having discussion with potential students and anybody who would like to participate in our mentoring team. We have also invited the RRDtool community to be part of this big adventure because RRDtool is such a critical element of Ganglia's success. My Debian project ideas I've also published a couple of project ideas on the Debian wiki before the organisations were confirmed: As I am part of the admin team for Ganglia, these Debian projects can only go ahead if there are some additional mentors willing to participate in them. Please contact me if either of these projects is interesting for you. You don't have to be a Debian Developer to be a mentor for Debian. Given the highly generic nature of these projects, particularly the Java one, they could also be mentored under the umbrella of another organisation. The Java project is particularly suitable for any Linux distribution or project relying on many JARs and all distributions and Java users are likely to extract some benefit from it. Deadlines approaching GSoC works on a strict calendar, please see the dates here if you would like to participate as a mentor, co-mentor or student.

Vincent Bernat: Coping with the TCP TIME-WAIT state on busy Linux servers

TL;DR: Do not enable net.ipv4.tcp_tw_recycle. The Linux kernel documentation is not very helpful about what net.ipv4.tcp_tw_recycle does:
Enable fast recycling TIME-WAIT sockets. Default value is 0. It should not be changed without advice/request of technical experts.
Its sibling, net.ipv4.tcp_tw_reuse is a little bit more documented but the language is about the same:
Allow to reuse TIME-WAIT sockets for new connections when it is safe from protocol viewpoint. Default value is 0. It should not be changed without advice/request of technical experts.
The mere result of this lack of documentation is that we find numerous tuning guides advising to set both these settings to 1 to reduce the number of entries in the TIME-WAIT state. However, as stated by tcp(7) manual page, the net.ipv4.tcp_tw_recycle option is quite problematic for public-facing servers as it won t handle connections from two different computers behind the same NAT device, which is a problem hard to detect and waiting to bite you:
Enable fast recycling of TIME-WAIT sockets. Enabling this option is not recommended since this causes problems when working with NAT (Network Address Translation).
I will provide here a more detailed explanation in the hope to teach people who are wrong on the Internet. xkcd illustration As a sidenote, despite the use of ipv4 in its name, the net.ipv4.tcp_tw_recycle control also applies to IPv6. Also, keep in mind we are looking at the TCP stack of Linux. This is completely unrelated to Netfilter connection tracking which may be tweaked in other ways1.

About TIME-WAIT state Let s rewind a bit and have a close look at this TIME-WAIT state. What is it? See the TCP state diagram below2: TCP state diagram Only the end closing the connection first will reach the TIME-WAIT state. The other end will follow a path which usually permits to quickly get rid of the connection. You can have a look at the current state of connections with ss -tan:
$ ss -tan   head -5
LISTEN     0  511             *:80              *:*     
SYN-RECV   0  0     192.0.2.145:80    203.0.113.5:35449
SYN-RECV   0  0     192.0.2.145:80   203.0.113.27:53599
ESTAB      0  0     192.0.2.145:80   203.0.113.27:33605
TIME-WAIT  0  0     192.0.2.145:80   203.0.113.47:50685

Purpose There are two purposes for the TIME-WAIT state:
  • The most known one is to prevent delayed segments from one connection being accepted by a later connection relying on the same quadruplet (source address, source port, destination address, destination port). The sequence number also needs to be in a certain range to be accepted. This narrows a bit the problem but it still exists, especially on fast connections with large receive windows. RFC 1337 explains in details what happens when the TIME-WAIT state is deficient3. Here is an example of what could be avoided if the TIME-WAIT state wasn t shortened:
Duplicate segments accepted in another connection
  • The other purpose is to ensure the remote end has closed the connection. When the last ACK is lost, the remote end stays in the LAST-ACK state4. Without the TIME-WAIT state, a connection could be reopened while the remote end still thinks the previous connection is valid. When it receives a SYN segment (and the sequence number matches), it will answer with a RST as it is not expecting such a segment. The new connection will be aborted with an error:
Last ACK lost RFC 793 requires the TIME-WAIT state to last twice the time of the MSL. On Linux, this duration is not tunable and is defined in include/net/tcp.h as one minute:
#define TCP_TIMEWAIT_LEN (60*HZ) /* how long to wait to destroy TIME-WAIT
                                  * state, about 60 seconds     */
There have been propositions to turn this into a tunable value but it has been refused on the ground the TIME-WAIT state is a good thing.

Problems Now, let s see why this state can be annoying on a server handling a lot of connections. There are three aspects of the problem:
  • the slot taken in the connection table preventing new connections of the same kind,
  • the memory occupied by the socket structure in the kernel, and
  • the additional CPU usage.
The result of ss -tan state time-wait wc -l is not a problem per se!

Connection table slot A connection in the TIME-WAIT state is kept for one minute in the connection table. This means, another connection with the same quadruplet (source address, source port, destination address, destination port) cannot exist. For a web server, the destination address and the destination port are likely to be constant. If your web server is behind a L7 load-balancer, the source address will also be constant. On Linux, the client port is by default allocated in a port range of about 30,000 ports (this can be changed by tuning net.ipv4.ip_local_port_range). This means that only 30,000 connections can be established between the web server and the load-balancer every minute, so about 500 connections per second. If the TIME-WAIT sockets are on the client side, such a situation is easy to detect. The call to connect() will return EADDRNOTAVAIL and the application will log some error message about that. On the server side, this is more complex as there is no log and no counter to rely on. In doubt, you should just try to come with something sensible to list the number of used quadruplets:
$ ss -tan 'sport = :80'   awk ' print $(NF)" "$(NF-1) '   \
>     sed 's/:[^ ]*//g'   sort   uniq -c
    696 10.24.2.30 10.33.1.64
   1881 10.24.2.30 10.33.1.65
   5314 10.24.2.30 10.33.1.66
   5293 10.24.2.30 10.33.1.67
   3387 10.24.2.30 10.33.1.68
   2663 10.24.2.30 10.33.1.69
   1129 10.24.2.30 10.33.1.70
  10536 10.24.2.30 10.33.1.73
The solution is more quadruplets5. This can be done in several ways (in the order of difficulty to setup):
  • use more client ports by setting net.ipv4.ip_local_port_range to a wider range,
  • use more server ports by asking the web server to listen to several additional ports (81, 82, 83, ),
  • use more client IP by configuring additional IP on the load balancer and use them in a round-robin fashion,
  • use more server IP by configuring additional IP on the web server6.
Of course, a last solution is to tweak net.ipv4.tcp_tw_reuse and net.ipv4.tcp_tw_recycle. Don t do that yet, we will cover those settings later.

Memory With many connections to handle, leaving a socket open for one additional minute may cost your server some memory. For example, if you want to handle about 10,000 new connections per second, you will have about 600,000 sockets in the TIME-WAIT state. How much memory does it represent? Not that much! First, from the application point of view, a TIME-WAIT socket does not consume any memory: the socket has been closed. In the kernel, a TIME-WAIT socket is present in three structures (for three different purposes):
  1. A hash table of connections, named the TCP established hash table (despite containing connections in other states) is used to locate an existing connection, for example when receiving a new segment. Each bucket of this hash table contains both a list of connections in the TIME-WAIT state and a list of regular active connections. The size of the hash table depends on the system memory and is printed at boot:
    $ dmesg   grep "TCP established hash table"
    [    0.169348] TCP established hash table entries: 65536 (order: 8, 1048576 bytes)
    
    It is possible to override it by specifying the number of entries on the kernel command line with the thash_entries parameter. Each element of the list of connections in the TIME-WAIT state is a struct tcp_timewait_sock, while the type for other states is struct tcp_sock7:
    struct tcp_timewait_sock  
        struct inet_timewait_sock tw_sk;
        u32    tw_rcv_nxt;
        u32    tw_snd_nxt;
        u32    tw_rcv_wnd;
        u32    tw_ts_offset;
        u32    tw_ts_recent;
        long   tw_ts_recent_stamp;
     ;
    struct inet_timewait_sock  
        struct sock_common  __tw_common;
        int                     tw_timeout;
        volatile unsigned char  tw_substate;
        unsigned char           tw_rcv_wscale;
        __be16 tw_sport;
        unsigned int tw_ipv6only     : 1,
                     tw_transparent  : 1,
                     tw_pad          : 6,
                     tw_tos          : 8,
                     tw_ipv6_offset  : 16;
        unsigned long            tw_ttd;
        struct inet_bind_bucket *tw_tb;
        struct hlist_node        tw_death_node;
     ;
    
  2. A set of lists of connections, called the death row , is used to expire the connections in the TIME-WAIT state. They are ordered by how much time left before expiration. It uses the same memory space as for the entries in the hash table of connections. This is the struct hlist_node tw_death_node member of struct inet_timewait_sock.
  3. A hash table of bound ports, holding the locally bound ports and the associated parameters, is used to determine if it is safe to listen to a given port or to find a free port in the case of dynamic bind. The size of this hash table is the same as the size of the hash table of connections:
    $ dmesg   grep "TCP bind hash table"
    [    0.169962] TCP bind hash table entries: 65536 (order: 8, 1048576 bytes)
    
    Each element is a struct inet_bind_socket. There is one element for each locally bound port. A TIME-WAIT connection to a web server is locally bound to the port 80 and shares the same entry as its sibling TIME-WAIT connections. On the other hand, a connection to a remote service is locally bound to some random port and does not share its entry.
So, we are only concerned by the space occupied by struct tcp_timewait_sock and struct inet_bind_socket. There is one struct tcp_timewait_sock for each connection in the TIME-WAIT state, inbound or outbound. There is one dedicated struct inet_bind_socket for each outbound connection and none for an inbound connection. A struct tcp_timewait_sock is only 168 bytes while a struct inet_bind_socket is 48 bytes:
$ sudo apt-get install linux-image-$(uname -r)-dbg
[...]
$ gdb /usr/lib/debug/boot/vmlinux-$(uname -r)
(gdb) print sizeof(struct tcp_timewait_sock)
 $1 = 168
(gdb) print sizeof(struct tcp_sock)
 $2 = 1776
(gdb) print sizeof(struct inet_bind_bucket)
 $3 = 48
So, if you have about 40,000 inbound connections in the TIME-WAIT state, it should eat less than 10MB of memory. If you have about 40,000 outbound connections in the TIME-WAIT state, you need to account for 2.5MB of additional memory. Let s check that by looking at the output of slabtop. Here is the result on a server with about 50,000 connections in the TIME-WAIT state, 45,000 of which are outbound connections:
$ sudo slabtop -o   grep -E '(^  OBJS tw_sock_TCP tcp_bind_bucket)'
  OBJS ACTIVE  USE OBJ SIZE  SLABS OBJ/SLAB CACHE SIZE NAME                   
 50955  49725  97%    0.25K   3397       15     13588K tw_sock_TCP            
 44840  36556  81%    0.06K    760       59      3040K tcp_bind_bucket
There is nothing to change here: the memory used by TIME-WAIT connections is really small. If your server need to handle thousands of new connections per second, you need far more memory to be able to efficiently push data to clients. The overhead of TIME-WAIT connections is negligible.

CPU On the CPU side, searching for a free local port can be a bit expensive. The work is done by the inet_csk_get_port() function which uses a lock and iterate on locally bound ports until a free port is found. A large number of entries in this hash table is usually not a problem if you have a lot of outbound connections in the TIME-WAIT state (like ephemeral connections to a memcached server): the connections usually share the same profile, the function will quickly find a free port as it iterates on them sequentially.

Other solutions If you still think you have a problem with TIME-WAIT connections after reading the previous section, there are three additional solutions to solve them:
  • disable socket lingering,
  • net.ipv4.tcp_tw_reuse, and
  • net.ipv4.tcp_tw_recycle.

Socket lingering When close() is called, any remaining data in the kernel buffers will be sent in the background and the socket will eventually transition to the TIME-WAIT state. The application can continue to work immediatly and assume that all data will eventually be safely delivered. However, an application can choose to disable this behaviour, known as socket lingering. There are two flavors:
  1. In the first one, any remaining data will be discarded and instead of closing the connection with the normal four-packet connection termination sequence, the connection will be closed with a RST (and therefore, the peer will detect an error) and will be immediatly destroyed. No TIME-WAIT state in this case.
  2. With the second flavor, if there is any data still remaining in the socket send buffer, the process will sleep when calling close() until either all the data is sent and acknowledged by the peer or the configured linger timer expires. It is possible for a process to not sleep by setting the socket as non-blocking. In this case, the same process happens in the background. It permits the remaining data to be sent during a configured timeout but if the data is succesfully sent, the normal close sequence is run and you get a TIME-WAIT state. And on the other case, you ll get the connection close with a RST and the remaining data is discarded.
In both cases, disabling socket lingering is not a one-size-fits-all solution. It may be used by some applications like HAProxy or Nginx when it is safe to use from the upper protocol point of view. There are good reasons to not disable it unconditionnaly.

net.ipv4.tcp_tw_reuse The TIME-WAIT state prevents delayed segments to be accepted in an unrelated connection. However, on certain conditions, it is possible to assume a new connection s segment cannot be misinterpreted with an old connection s segment. RFC 1323 presents a set of TCP extensions to improve performance over high-bandwidth paths. Among other things, it defines a new TCP option carrying two four-byte timestamp fields. The first one is the current value of the timestamp clock of the TCP sending the option while the second one is the most recent timestamp received from the remote host. By enabling net.ipv4.tcp_tw_reuse, Linux will reuse an existing connection in the TIME-WAIT state for a new outgoing connection if the new timestamp is strictly bigger than the most recent timestamp recorded for the previous connection: an outgoing connection in the TIME-WAIT state can be reused after just one second. How is it safe? The first purpose of the TIME-WAIT state was to avoid duplicate segments to be accepted in an unrelated connection. Thanks to the use of timestamps, such a duplicate segments will come with an outdated timestamp and therefore be discarded. The second purpose was to ensure the remote end is not in the LAST-ACK state because of the lost of the last ACK. The remote end will retransmit the FIN segment until:
  1. it gives up (and tear down the connection), or
  2. it receives the ACK it is waiting (and tear down the connection), or
  3. it receives a RST (and tear down the connection).
If the FIN segments are received in a timely manner, the local end socket will still be in the TIME-WAIT state and the expected ACK segments will be sent. Once a new connection replaces the TIME-WAIT entry, the SYN segment of the new connection is ignored (thanks to the timestamps) and won t be answered by a RST but only by a retransmission of the FIN segment. The FIN segment will then be answered with a RST (because the local connection is in the SYN-SENT state) which will allow the transition out of the LAST-ACK state. The initial SYN segment will eventually be resent (after one second) because there was no answer and the connection will be established without apparent error, except a slight delay: Last ACK lost and timewait reuse It should be noted that when a connection is reused, the TWRecycled counter is increased (despite its name).

net.ipv4.tcp_tw_recycle This mechanism also relies on the timestamp option but affects both incoming and outgoing connections which is handy when the server usually closes the connection first8. The TIME-WAIT state is scheduled to expire sooner: it will be removed after the retransmission timeout (RTO) interval which is computed from the RTT and its variance. You can spot the appropriate values for a living connection with the ss command:
$ ss --info  sport = :2112 dport = :4057
State      Recv-Q Send-Q    Local Address:Port        Peer Address:Port   
ESTAB      0      1831936   10.47.0.113:2112          10.65.1.42:4057    
         cubic wscale:7,7 rto:564 rtt:352.5/4 ato:40 cwnd:386 ssthresh:200 send 4.5Mbps rcv_space:5792
To keep the same guarantees the TIME-WAIT state was providing, while reducing the expiration timer, when a connection enters the TIME-WAIT state, the latest timestamp is remembered in a dedicated structure containing various metrics for previous known destinations. Then, Linux will drop any segment from the remote host whose timestamp is not strictly bigger than the latest recorded timestamp, unless the TIME-WAIT state would have expired:
if (tmp_opt.saw_tstamp &&
    tcp_death_row.sysctl_tw_recycle &&
    (dst = inet_csk_route_req(sk, &fl4, req, want_cookie)) != NULL &&
    fl4.daddr == saddr &&
    (peer = rt_get_peer((struct rtable *)dst, fl4.daddr)) != NULL)  
        inet_peer_refcheck(peer);
        if ((u32)get_seconds() - peer->tcp_ts_stamp < TCP_PAWS_MSL &&
            (s32)(peer->tcp_ts - req->ts_recent) >
                                        TCP_PAWS_WINDOW)  
                NET_INC_STATS_BH(sock_net(sk), LINUX_MIB_PAWSPASSIVEREJECTED);
                goto drop_and_release;
         
 
When the remote host is in fact a NAT device, the condition on timestamps will forbid allof the hosts except one behind the NAT device to connect during one minute because they do not share the same timestamp clock. In doubt, this is far better to disable this option since it leads to difficult to detect and difficult to diagnose problems. The LAST-ACK state is handled in the exact same way as for net.ipv4.tcp_tw_recycle.

Summary The universal solution is to increase the number of possible quadruplets by using, for example, more server ports. This will allow you to not exhaust the possible connections with TIME-WAIT entries. On the server side, do not enable net.ipv4.tcp_tw_recycle unless you are pretty sure you will never have NAT devices in the mix. Enabling net.ipv4.tcp_tw_reuse is useless for incoming connections. On the client side, enabling net.ipv4.tcp_tw_reuse is another almost-safe solution. Enabling net.ipv4.tcp_tw_recycle in addition to net.ipv4.tcp_tw_reuse is mostly useless. And a final quote by W. Richard Stevens, in Unix Network Programming:
The TIME_WAIT state is our friend and is there to help us (i.e., to let old duplicate segments expire in the network). Instead of trying to avoid the state, we should understand it.

  1. Notably, fiddling with net.netfilter.nf_conntrack_tcp_timeout_time_wait won t change anything on how the TCP stack will handle the TIME-WAIT state.
  2. This diagram is licensed under the LaTeX Project Public License 1.3. The original file is available on this page.
  3. The first work-around proposed in RFC 1337 is to ignore RST segments in the TIME-WAIT state. This behaviour is controlled by net.ipv4.rfc1337 which is not enabled by default on Linux because this is not a complete solution to the problem described in the RFC.
  4. While in the LAST-ACK state, a connection will retransmit the last FIN segment until it gets the expected ACK segment. Therfore, it is unlikely we stay long in this state.
  5. On the client side, older kernels also have to find a free local tuple (source address and source port) for each outgoing connection. Increasing the number of server ports or IP won t help in this case. Linux 3.2 is recent enough to be able to share the same local tuple for different destinations. Thanks to Willy Tarreau for his insight on this aspect.
  6. This last solution may seem a bit dumb since you could just use more ports but some servers are not able to be configured this way. The before last solution can also be quite cumbersome to setup, depending on the load-balancing software, but uses less IP than the last solution.
  7. The use of a dedicated memory structure for sockets in the TIME-WAIT is here since Linux 2.6.14. The struct sock_common structure is a bit more verbose and I won t copy it here.
  8. When the server closes the connection first, it gets the TIME-WAIT state while the client will consider the corresponding quadruplet free and hence may reuse it for a new connection.

Matthew Garrett: The importance of a community-focused mindset

Piston, an Openstack-in-a-box vendor[1] are a sponsor of the Red Hat[2] Summit this year. Last week they briefly ceased to be for no publicly stated reason, although it's been sugggested that this was in response to Piston winning a contract that Red Hat was also bidding on. This situation didn't last for long - Red Hat's CTO tweeted that this was an error and that Red Hat would pay Piston's sponsorship fee for them.

To Red Hat's credit, having the CTO immediately and publicly accept responsibility and offer reparations seems like the best thing they could possibly do in the situation and demonstrates that there are members of senior management who clearly understand the importance of community collaboration to Red Hat's success. But that leaves open the question of how this happened in the first place.

Red Hat is big on collaboration. Workers get copies of the Red Hat Brand Book, an amazingly well-written description of how Red Hat depends on the wider community. New hire induction sessions stress the importance of open source and collaboration. Red Hat staff are at the heart of many vital free software projects. As far as fundamentally Getting It is concerned, Red Hat are a standard to aspire to.

Which is why something like this is somewhat unexpected. Someone in Red Hat made a deliberate choice to exclude Piston from the Summit. If the suggestion that this was because of commercial concerns is true, it's antithetical to the Red Hat Way. Piston are a contributor to upstream Openstack, just as Red Hat are. If Piston can do a better job of selling that code than Red Hat can, the lesson that Red Hat should take away is that they need to do a better job - not punish someone else for doing so.

However, it's not entirely without precedent. The most obvious example is the change to kernel packaging that happened during the RHEL 6 development cycle. Previous releases had included each individual modification that Red Hat made to the kernel as a separate patch. From RHEL 6 onward, all these patches are merged into one giant patch. This was intended to make it harder for vendors like Oracle to compete with RHEL by taking patches from upcoming RHEL point releases, backporting them to older ones and then selling that to Red Hat customers. It obviously also had the effect of hurting other distributions such as Debian who were shipping 2.6.32-based kernels - bugs that were fixed in RHEL had to be separately fixed in Debian, despite Red Hat continuing to benefit from the work Debian put into the stable 2.6.32 point releases.

It's almost three years since that argument erupted, and by and large the community seems to have accepted that the harm Oracle were doing to Red Hat (while giving almost nothing back in return) justified the change. The parallel argument in the Piston case might be that there's no reason for Red Hat to give advertising space to a company that's doing a better job of selling Red Hat's code than Red Hat are. But the two cases aren't really equal - Oracle are a massively larger vendor who take significantly more from the Linux community than they contribute back. Piston aren't.

Which brings us back to how this could have happened in the first place. The Red Hat company culture is supposed to prevent people from thinking that this kind of thing is acceptable, but in this case someone obviously did. Years of Red Hat already having strong standing in a range of open source communities may have engendered some degree of complacency and allowed some within the company to lose track of how important Red Hat's community interactions are in perpetuating that standing. This specific case may have been resolved without any further fallout, but it should really trigger an examination of whether the reality of the company culture still matches the theory. The alternative is that this kind of event becomes the norm rather than the exception, and it takes far less time to lose community goodwill than it takes to build it in the first place.

[1] And, in the spirit of full disclosure, a competitor to my current employer
[2] Furthering the spirit of full disclosure, a former employer

comment count unavailable comments

Rog rio Brito: Trivial fact #3: Continued fractions via matrices

Note Apparently, it's not Debian planet that has problems to deal with MathJax (which makes posts usingn it appear illegible on Debian planet), but the ikiwiki plugin that I am using which generates garbage in the feeds that get consumed by planet.debian.org. If you it know of a better plugin (which doesn't generate such output) please let me know, especially if it is not super computationally expensive for a Core 2 Duo T7250 (which is my notebook).

The real thing As William Stein is now offering a course on Number Theory and he has been posting recorded videos of his lectures, I started watching some of them (mainly, the ones regarding continued factions). In particular, he shows the usual recursive formula for convergents of a continued fraction and that's super nice. For the curious reader, the recurrence relations for the convergents of !!mathjaxbegin-i!! W2FfMCwgYV8xLCBcbGRvdHMsIGFfbiwgXGxkb3RzXQ== !!mathjaxend-i!! are: !!mathjaxbegin-d!! CnBfbiA9IGFfbiBwX3tuLTF9ICsgcF97bi0yfVxcCnFfbiA9IGFfbiBxX3tuLTF9ICsgcV97bi0y fSwK !!mathjaxend-d!! with initial conditions (!!mathjaxbegin-i!! cF97LTJ9ID0gMA== !!mathjaxend-i!!, !!mathjaxbegin-i!! cF97LTF9ID0gMQ== !!mathjaxend-i!!, !!mathjaxbegin-i!! cF8wID0gYV8w !!mathjaxend-i!!, !!mathjaxbegin-i!! cV97LTJ9ID0gMQ== !!mathjaxend-i!!, !!mathjaxbegin-i!! cV97LTF9ID0gMA== !!mathjaxend-i!!, !!mathjaxbegin-i!! cV8wID0gMQ== !!mathjaxend-i!!). He even motivated the use of continued fractions with the golden ratio, which is super nice, given that I like the subject and have been writing a document collecting facts that I know about the Fibonacci numbers (well, this document is horribly incomplete and not even close to something that I would consider proper for public consumption I plan on publishing them soon). OK, after he discussed the basics of it convergents, he noted that the recurrence relations are like those defining the Fibonacci numbers, just that one of the terms is "weighted" by the coefficients of the continued fraction. I missed one thing, though: neither his book nor wikipedia's article on continued fractions mentions a very neat, alternative way to express the convergents of continued fractions (truth be said, I took a quick peek at wikipedia's article and I found that it doesn't mentionat least explicitly, in a 1 min skim it may well be buried somewhere else). I, then, proposed the following exercise for his students (which he apparently liked, as he +1's the suggestion): Prove that the recurrence relation of the !!mathjaxbegin-i!! cF9p !!mathjaxend-i!!'s and !!mathjaxbegin-i!! cV9p !!mathjaxend-i!!'s that we mentioned before can be obtained via matrix multiplication. More precisely, prove that: !!mathjaxbegin-d!! ClxiZWdpbntibWF0cml4fQphXzAgJmFtcDsgMVxcCjEgJmFtcDsgMApcZW5ke2JtYXRyaXh9Clxi ZWdpbntibWF0cml4fQphXzEgJmFtcDsgMVxcCjEgJmFtcDsgMApcZW5ke2JtYXRyaXh9ClxjZG90 cwpcYmVnaW57Ym1hdHJpeH0KYV9uICZhbXA7IDFcXAoxICZhbXA7IDAKXGVuZHtibWF0cml4fQog PQpcYmVnaW57Ym1hdHJpeH0KcF9uICZhbXA7IHBfe24tMX1cXApxX24gJmFtcDsgcV97bi0xfQpc ZW5ke2JtYXRyaXh9Lgo= !!mathjaxend-d!! As a corollary, derive Cassini's identity for the Fibonacci Numbers.
Please, if you any errors on this, please let me know so that I can fix it. Edit: Thanks "noone" for spotting a typographical error.

23 February 2014

Paul Tagliamonte: Debile + Docker = love

I ve spent a bit of time this saturday Dockerizing Debile s slave / workers (for those who don t know about Debile yet, there are a few posts where I explain it) Many thanks to Tianon Gravi for his work in helping me out :) I created two images to test - the base image for any slave (paultag/debile-slave-base, and a preconfigured image for our test master server. This includes a script to preconfigure the slave worker (OpenPGP keys, username, password) that are passed to it via a tarball generated by debile-remote. Hopefully this makes deploying debile slaves easier :) I was able to do a test build of about 300 packages with the dockerized slave, and I think it s a huge step forward. Onward!

Andrew Pollock: [tech] My thoughts on the Ozobot Kickstarter campaign

I'm not an avid Kickstarter follower (if I were, I'd have gone broke long ago). I tend to wind up backing campaigns that come to my attention via other means (in other words, they're in the process of going viral). That said, I've backed plenty of campaigns over the years, and so I'd like to think I have a little bit of familiarity with how they usually operate. When Ozobot came to my attention, I found it unusual, because they were pre-promoting their Kickstarter campaign before it opened. To me, this looked like a case of them trying to build hype prior to the campaign opening, which was a new one to me. The whole thing seemed incredibly slick, and I was surprised they were "only" seeking $100K. The product looked like it'd be something cool for Zoe to play with, so I decided to back it anyway. Then all the updates started flowing in about how well it was being received at various trade shows and whatnot. Yet the amount of dollars flowing into the Kickstarter campaign didn't seem to be reflecting the external hype. I was watching the campaign's dashboard with great interest, because as time marched on, it was looking more and more likely that it wasn't going to make its funding target. This seemed highly unusual to me, given the slickness of the product and purported external interest in it. And then they pulled the plug on the campaign. Purportedly because they were pursuing equity funding instead. They admitted they'd also read the writing on the wall and it was unlikely they were going to make their funding target. I haven't followed other campaigns to see how much of a last minute funding "pop" they have. Usually I've found they've closed at many multiples of their original target, and hit their target well in advance of their deadline, when they're ridiculously popular. My interpretation of Ozobot's campaign, from a funding perspective, is that Kickstarters gave it a big fat "MEH", which surprised me somewhat. Then the question comes up: was the Kickstarter campaign a ruse all along? Was it just a new way of pitching for venture capital? The videos seemed pretty slick. The product seemed already complete, and $100K didn't seem like enough to take it to manufacturing. It'll be interesting to see what becomes of Ozobot now.

Next.

Previous.