Search Results: "ron"

7 June 2011

Gerfried Fuchs: pal versus wyrd

Whenever someone asked me about a calendar application, especially for the textmode, I always encouraged them to give pal a try. I always loved the looks of it, the interactive mode is helpful, it has HTML output format to inject the calendar into a webpage, mail output format for a daily reminder cronjob, and other useful features. I even created a file with the Austrian holidays for it which got included in the original project for the benefit of all its users.
If you haven't tried it yet and are looking for a calendar tool with support for very flexible recurring events and categories, this might be a good look. I am still happy with pal, though someone recently suggested a different tool on IRC, and that was wyrd. From a quick glance it looked promising, so I started to dig into it. My first task was to convert the former mentioned pal file for the Austrian holidays into remind format. remind is the backend for wyrd, and its definition language seems to be extremely powerful. It though took me a while to figure out how to put in Easter date related events into it, the examples weren't really hinting me in the right direction. This is part of what I am using now:
REM [trigger(easterdate(current())-47)] +6 TAG noweight MSG Faschingsdienstag %b The look and view of wyrd is different to pal in several ways. Where the granularity of pal is a pure day view, wyrd scales in hours (or half, quarter thereof). Also, wyrd offers the possibility to color the days differently by busy level. Of course it's possible to exempt tasks from adding weight to a day. pal on the other hand is able to color events differently by category. Decide yourself what you actually need, test it, and ... enjoy!

/cli permanent link Comments: 0 Flattr this

6 June 2011

Sam Dunne: Declarative Diversions - Design Spec 2

DECLARATIVE DIVERSIONS ====================== Introduction A diversion is when it is possible to have dpkg not overwrite a file when it reinstalls the package it belongs to, and to have it put the file from the package somewhere else instead. Declarative diversions involves a new control file with a declarative syntax which dpkg will parse and process directly as part of the package unpack and removal phases, eliminating the problems resulting from non-atomic handling of diversions. Topics There are a number of topics involved in implementing this kind of project * What syntax do we use for the new control file? * What dpkg does with the control file * How do we handle diversions to a non-existant directory? * How do we order unpacking a new package which adds a diversion? * How do we order unpacking a new package that removes a diversion? * How do we order removing a package which had a diversion? * How do we handle errors? * What happens to dpkg-divert? Details - Control File Syntax - It will conform to RFC2822 style with the following format: * Divert-From: * Divert-To: * Blank lines and lines beginning with # will be comments Divert-To will be optional and if it is ommitted then files being diverted will have their filename changed to file.distrib The above style has it s advantages, one of the main ones being that there is no need to escape whitespace within filenames. It also allows for more commands to be added at a later date. Details - Control File Handling - Within control.tar.gz the file should be named diversions This file is then copied to /var/lib/info/$package.diversions We need to store the control file for the currently-installed package so that we can detect declarative diversions that have been removed from the control file between versions (On-disk version and the to-be-unpacked version). If there is no previous version of a control file then all current diversions within the package are left in place and any new ones declared within the control file are added. If there is a previous version of the control file then the diversions listed within the file are compared with the diversions currently in place. If a diversion exists that is no longer listed in the control file then it is removed. If there is a diversion listed in the control file that doesn t currently exist then it is added. Details - Handling Diversions to non-existant directories - Diverting files to directories that don t exist can cause a number of problems. If the package does not own the directory it may be left orphaned on removal of the package The package is responsible for ensuring the availability of the target directory in the unpack phase. If a declarative diversion attempts to divert a file to a folder that neither exists already on the filesystem at unpack time, nor is shipped within the package, dpkg will return an error at unpack time. Details - Ordering Requirements - =>Unpacking a new package that adds a diversion *1. Check if package has a previous diversion control file *2. Copy control file to tmp directory *3. Calculate diversions to be added *4. Unpack folders *5. Add diversions *6. Unpack files *7. Copy control file to /var/lib/dpkg/info/$package.diversion *Performing diversions this way avoids trouble with creating folders and accidentally overwriting the wrong version of files. *Another major problem would be extracting a new version of the file and overwriting the old one. *This might cause the wrong version of the file to be diverted and the package to break. =>Unpacking a new package that removes a diversion *1. Check if package has a previous diversion control file *2. Copy control file to tmp directory *3. Calculate diversions to be removed *4. Check if dropped diversion results in a file conflict and abort the unpack if it does. *5. Unpack folders *6. Unpack files *7. Remove old files no longer needed in the package *8. Remove diversions *9. Copy control file to /var/lib/dpkg/info/$package.diversion *If a package has no previous diversion control file then no diversions will be removed and existing diversions can only be removed using dpkg-divert. *If removing a diversion results in a file conflict then dpkg will return an error at unpack time before anything is unpacked and the unpack is aborted. =>Removing a package which had a diversion *1. Remove files *2. Remove diversions *3. Remove folders *4. Remove control file at /var/lib/dpkg/info/$package.diversion *This ensures that all files, diversions and folders are removed correctly Details - Error handling Errors in diversions will have to handled with a great deal of care due to the fact that if they are not the package could be broken. This means that a great deal of checks must be done to ensure that all the files can be diverted properly before any actual diverting takes place. If they can t the package installation/update must be stopped and rolled back to avoid the package being installed incorrectly or broken. Details - dpkg-divert - When we impliment the new diversion method we should keep the current dpkg-divert. This allows maintainers to catch up with the new method without breaking their packages. It also allows maintainers to perform some operations that aren t support by the new method. All current functionality of dpkg-divert will be left intact for use by sysadmins and for maintainers to catch up with the new system. The two systems will work together without directly conflicting with each other. Example Usage #1 The file to be diverted is /usr/share/foo It needs to be moved to /usr/share/bar The syntax of the control file would be: #Start File Divert-From: /usr/share/foo Divert-To: /usr/share/bar #End File Example Usage #2 In this example the maintainer doesn t want to move the file to any specific folder The syntax of the control file would be: #Start File Divert-From: /usr/share/foo #End File This would divert the file to /usr/share/foo.distrib Footnotes - RFC2822 Guide: * http://www.faqs.org/rfcs/rfc2822.html First Email Thread on Declarative Diversions (First Message in Thread): * http://lists.debian.org/debian-dpkg/2011/05/msg00102.html Email thread on first design draft (First message in Thread): * http://lists.debian.org/debian-dpkg/2011/06/msg00019.html Declarative Diversions Wiki: * http://wiki.debian.org/SummerOfCode2011/DeclarativeDiversions My Blog for this Project: * http://blog.sam-dunne.com

Thorsten Glaser: synchronise environment between two shells

(First posting to Pl net Commandline! Tag: pcli) Vutral asked in IRC how to synchronise two shells environment while they re running. As you may know, POSIX systems cannot change a process environment vector after it has been started, only the process itself can. Well, the shell can, and we ll use a variety of things for this. This trick assumes you have $HISTFILE set to the same pathname in both shells (obviously, they run under the same user). It uses export -p to render the current list of exported variables, then transforms the list from newline-separated to a single big one-line export statement.
Then it transforms all remaining newlines (which will be part of a single-quoted string, since that s mksh(1) s export format) into the sequence '$'\n'' which means: terminate current single-quoted string, append $'\n' and open up a new single-quoted string immediately; concatenate these three.
Now, $'\n' is just a fancy way of saying newline, and part of mksh because David Korn (yes, the Korn in Korn Shell) strongly suggested to me that this functionality be included but, as we can see here, it pays off.
Finally, the so transformed string is prepended by unset \$(export); which, when executed, will cause the shell to unset (and unexport) all currently exported variables. The shell parameters that are not exported, i.e. not in the environment, are not affected by this code (except for $x and $nl, but whatever).
This string is then passed to read -s (plus -r and clearing IFS to enable raw mode), which means, read into the parameter $REPLY (which we conveniently don t use but it s trashed too, thus) but store into history at the same time. Ah hah! Now, the persistent history feature comes into effect! After running the below statement in the source shell, switch into the terminal running the destination shell, press Enter once on the empty line (Ctrl-U to empty it if it wasn t), then Cursor-Up ( ) to recall voil , an insanely large line with the previously created string sorta expanded and press Enter again to run it. Now your set of exported parameters is the exact same (minus if you exported IFS, nl, x or REPLY) as in the source shell.

I ve added extra spaces and a linewrap below, this is really just one big line:

nl=$'\n'; x=$(export -p); x=$ x//$ nl export/ ; IFS= read -rs <<<"unset \\\$(export);$ x//$nl/\'\$\'\\\\n\'\' "

Of course, this makes a nice function, for your ~/.mkshrc or somesuch.

Steve Kemp: So I chose fabric and reported a bug..

When soliciting for opinions, recently, I discovered that the python-based fabric tool was not dead, and was in fact perfect for my needs. During the process of getting acquainted with it I looked over the source code, it was mostly neat but there was a trivial (low-risk) symlink attack present. I reported that as #629003 & it is now identified more globally as CVE-2011-2185. I guess this goes to show that getting into the habit of looking over source code when you install a new package is a worthwhile thing to do; and probably easier than organising a distribution-wide security audit </irony>. In other news I'm struggling to diagnose a perl segfault, when running a search using the swish-a perl modules. Could it be security worthy? Possibly. Right now I just don't want my scripts to die when I attempt to search 20Gb of syslog data. Meh. ObQuote: "You're scared of mice and spiders, but oh-so-much greater is your fear that one day the two species will cross-breed to form an all-powerful race of mice-spiders who will immobilize human beings in giant webs in order to steal cheese. " - Spaced.

Rapha&#235;l Hertzog: Official Debian/Ubuntu packages for Dropbox

Dropbox is a popular service to synchronize files between multiple computers. The service is entirely proprietary but the company is Linux friendly and provides Linux binaries ready to use. They even provide Ubuntu packages that wrap the dropbox client and provide integration with Nautilus. A bit of story Unfortunately for Debian users, those packages do not work on Debian due to a dependency that can t be satisfied (because Ubuntu introduced an epoch on the version of their nautilus package that Debian doesn t have). This was even reported in a Squeeze review in Linux Weekly News. At some point, Ivan Borzenkov introduced a dropbox package to Debian but it was not based on the above package, instead it packaged directly the proprietary binaries. This was a bad decision because the binaries bundle a set of LGPL libraries and nobody from Debian wanted to do the required work to provide the corresponding source code. So the package got dropped (see bug #610300). More recently several persons filed ITP (Intent To Package) bugs stating their willingness to re-introduce dropbox in Debian, but after many months lingering in the bug tracking system (see #544499, #613788), they have been turned back to RFP (Request For Package) because they changed their minds. What I did Being a dropbox user myself (despite the recent proof that data stored on dropbox is not 100% private), I offered sponsorship to the volunteers who wanted to package dropbox. But it turns out this was not enough to motivate someone to complete the task. In the mean time I was still using the old dropbox package that was removed (it used to be downloadable from snapshot.debian.org). While this was good enough for me, it s clearly not OK in the long term and way too difficult for the majority of users. So this week-end I spent some hours to create a proper package. It s loosely based on the package provided by Dropbox but I upgraded the packaging and changed the way it works. I patched the dropbox wrapper to provide a dropbox update command that downloads and updates the proprietary binaries. They are now stored in /var/lib/dropbox instead of having a copy in each user s home directory (~/.dropbox-dist/). This update command is run by the postinst so that installing the package immediately downloads the proprietary binaries. Get the Dropbox packages for Debian The package nautilus-dropbox has been uploaded to Debian unstable, it s currently in the NEW queue but will shortly reach the mirrors. Then you will be able to You can install the package with a simple apt-get install nautilus-dropbox (provided that you activated the non-free section since that s where the package is hosted, it can t be part of Debian since it requires the proprietary binaries to be useful). In the mean time you can get the packages from the links below: Get the Dropbox packages for Ubuntu I have setup a PPA for nautilus-dropbox. Feel free to use it in place of the upstream packages.
$ sudo add-apt-repository ppa:hertzog/nautilus-dropbox
$ sudo apt-get update
$ sudo apt-get install nautilus-dropbox
It also includes packages for oneiric, but in theory once the package is accepted into Debian, it should appear in oneiric shortly after. Package maintenance I have done the initial packaging work but I don t really want to maintain it in the long term. I have more than enough to do with dpkg and my other packages. So if you are interested in maintaining this package, please get in touch with me. You should know a bit of python since there are Debian-specific patches of the upstream code. The package is maintained in a git repository. Feedback If you have encountered a problem with one of those packages, feel free to leave a comment. If you re an happy user of the above packages, click here to find out how you can thank me. I hope you enjoy the packages!

13 comments Liked this article? Click here. My blog is Flattr-enabled.

5 June 2011

Russell Coker: Rallying for a Carbon Tax 5th June

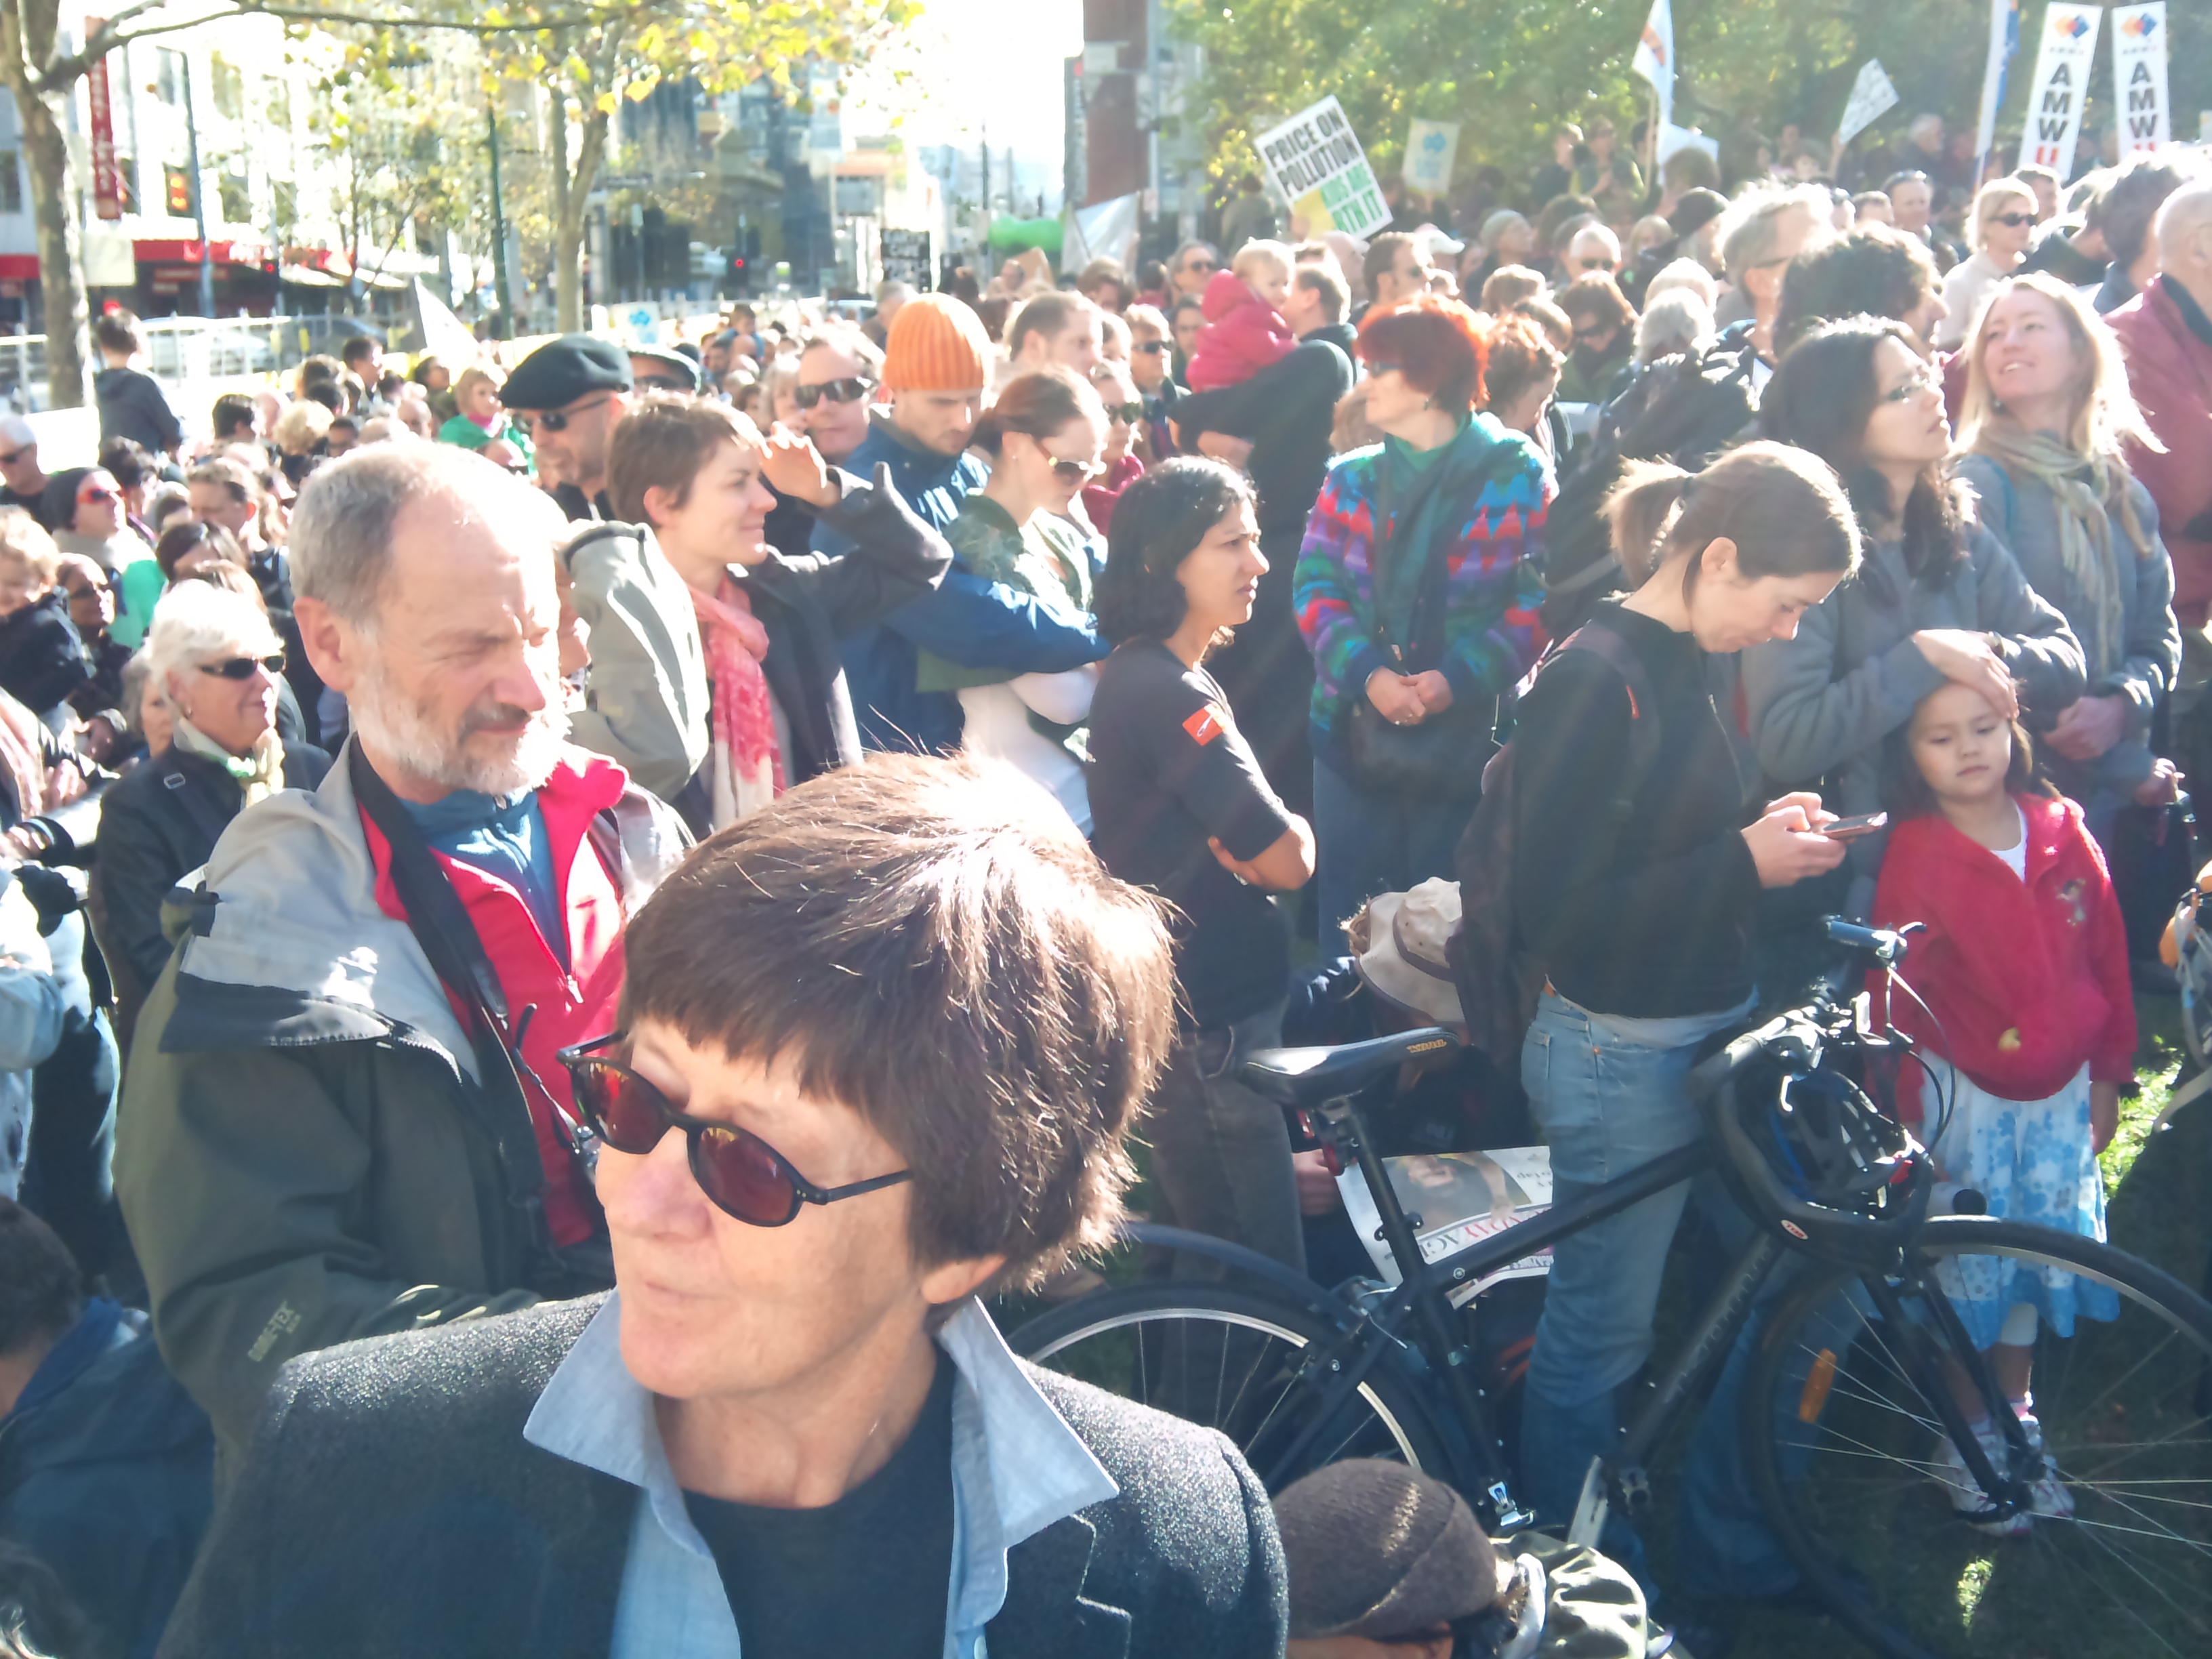
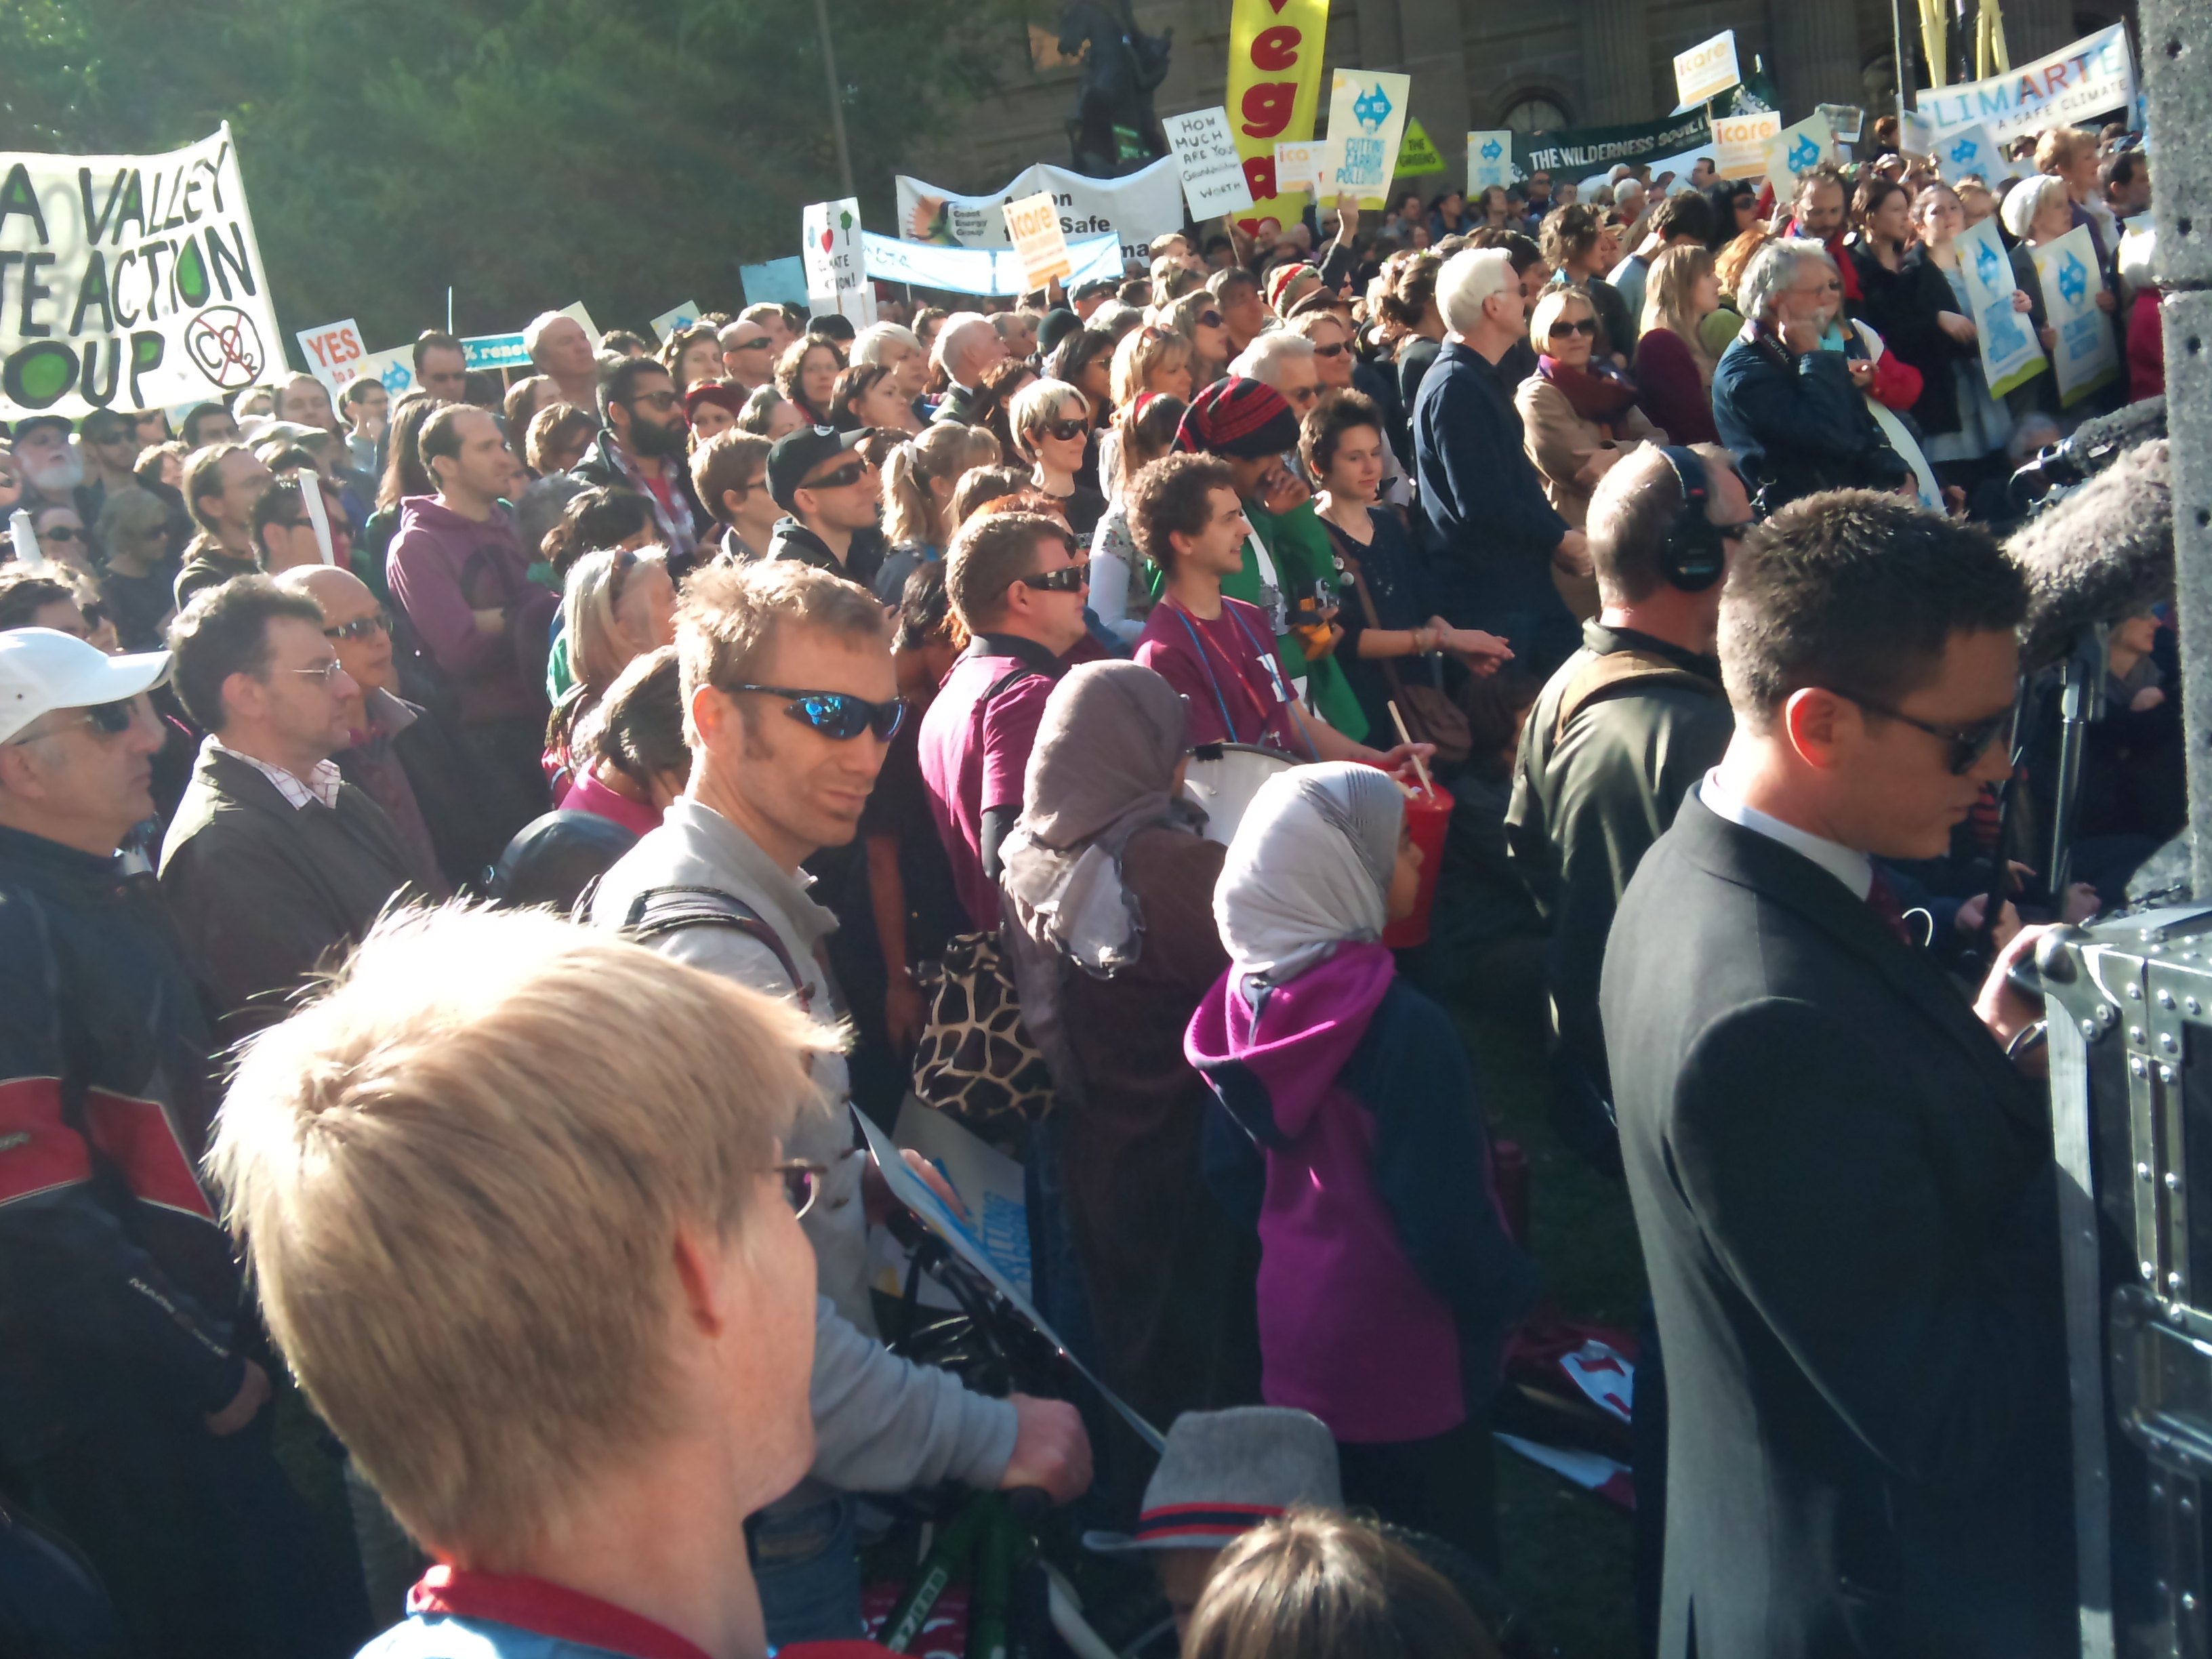
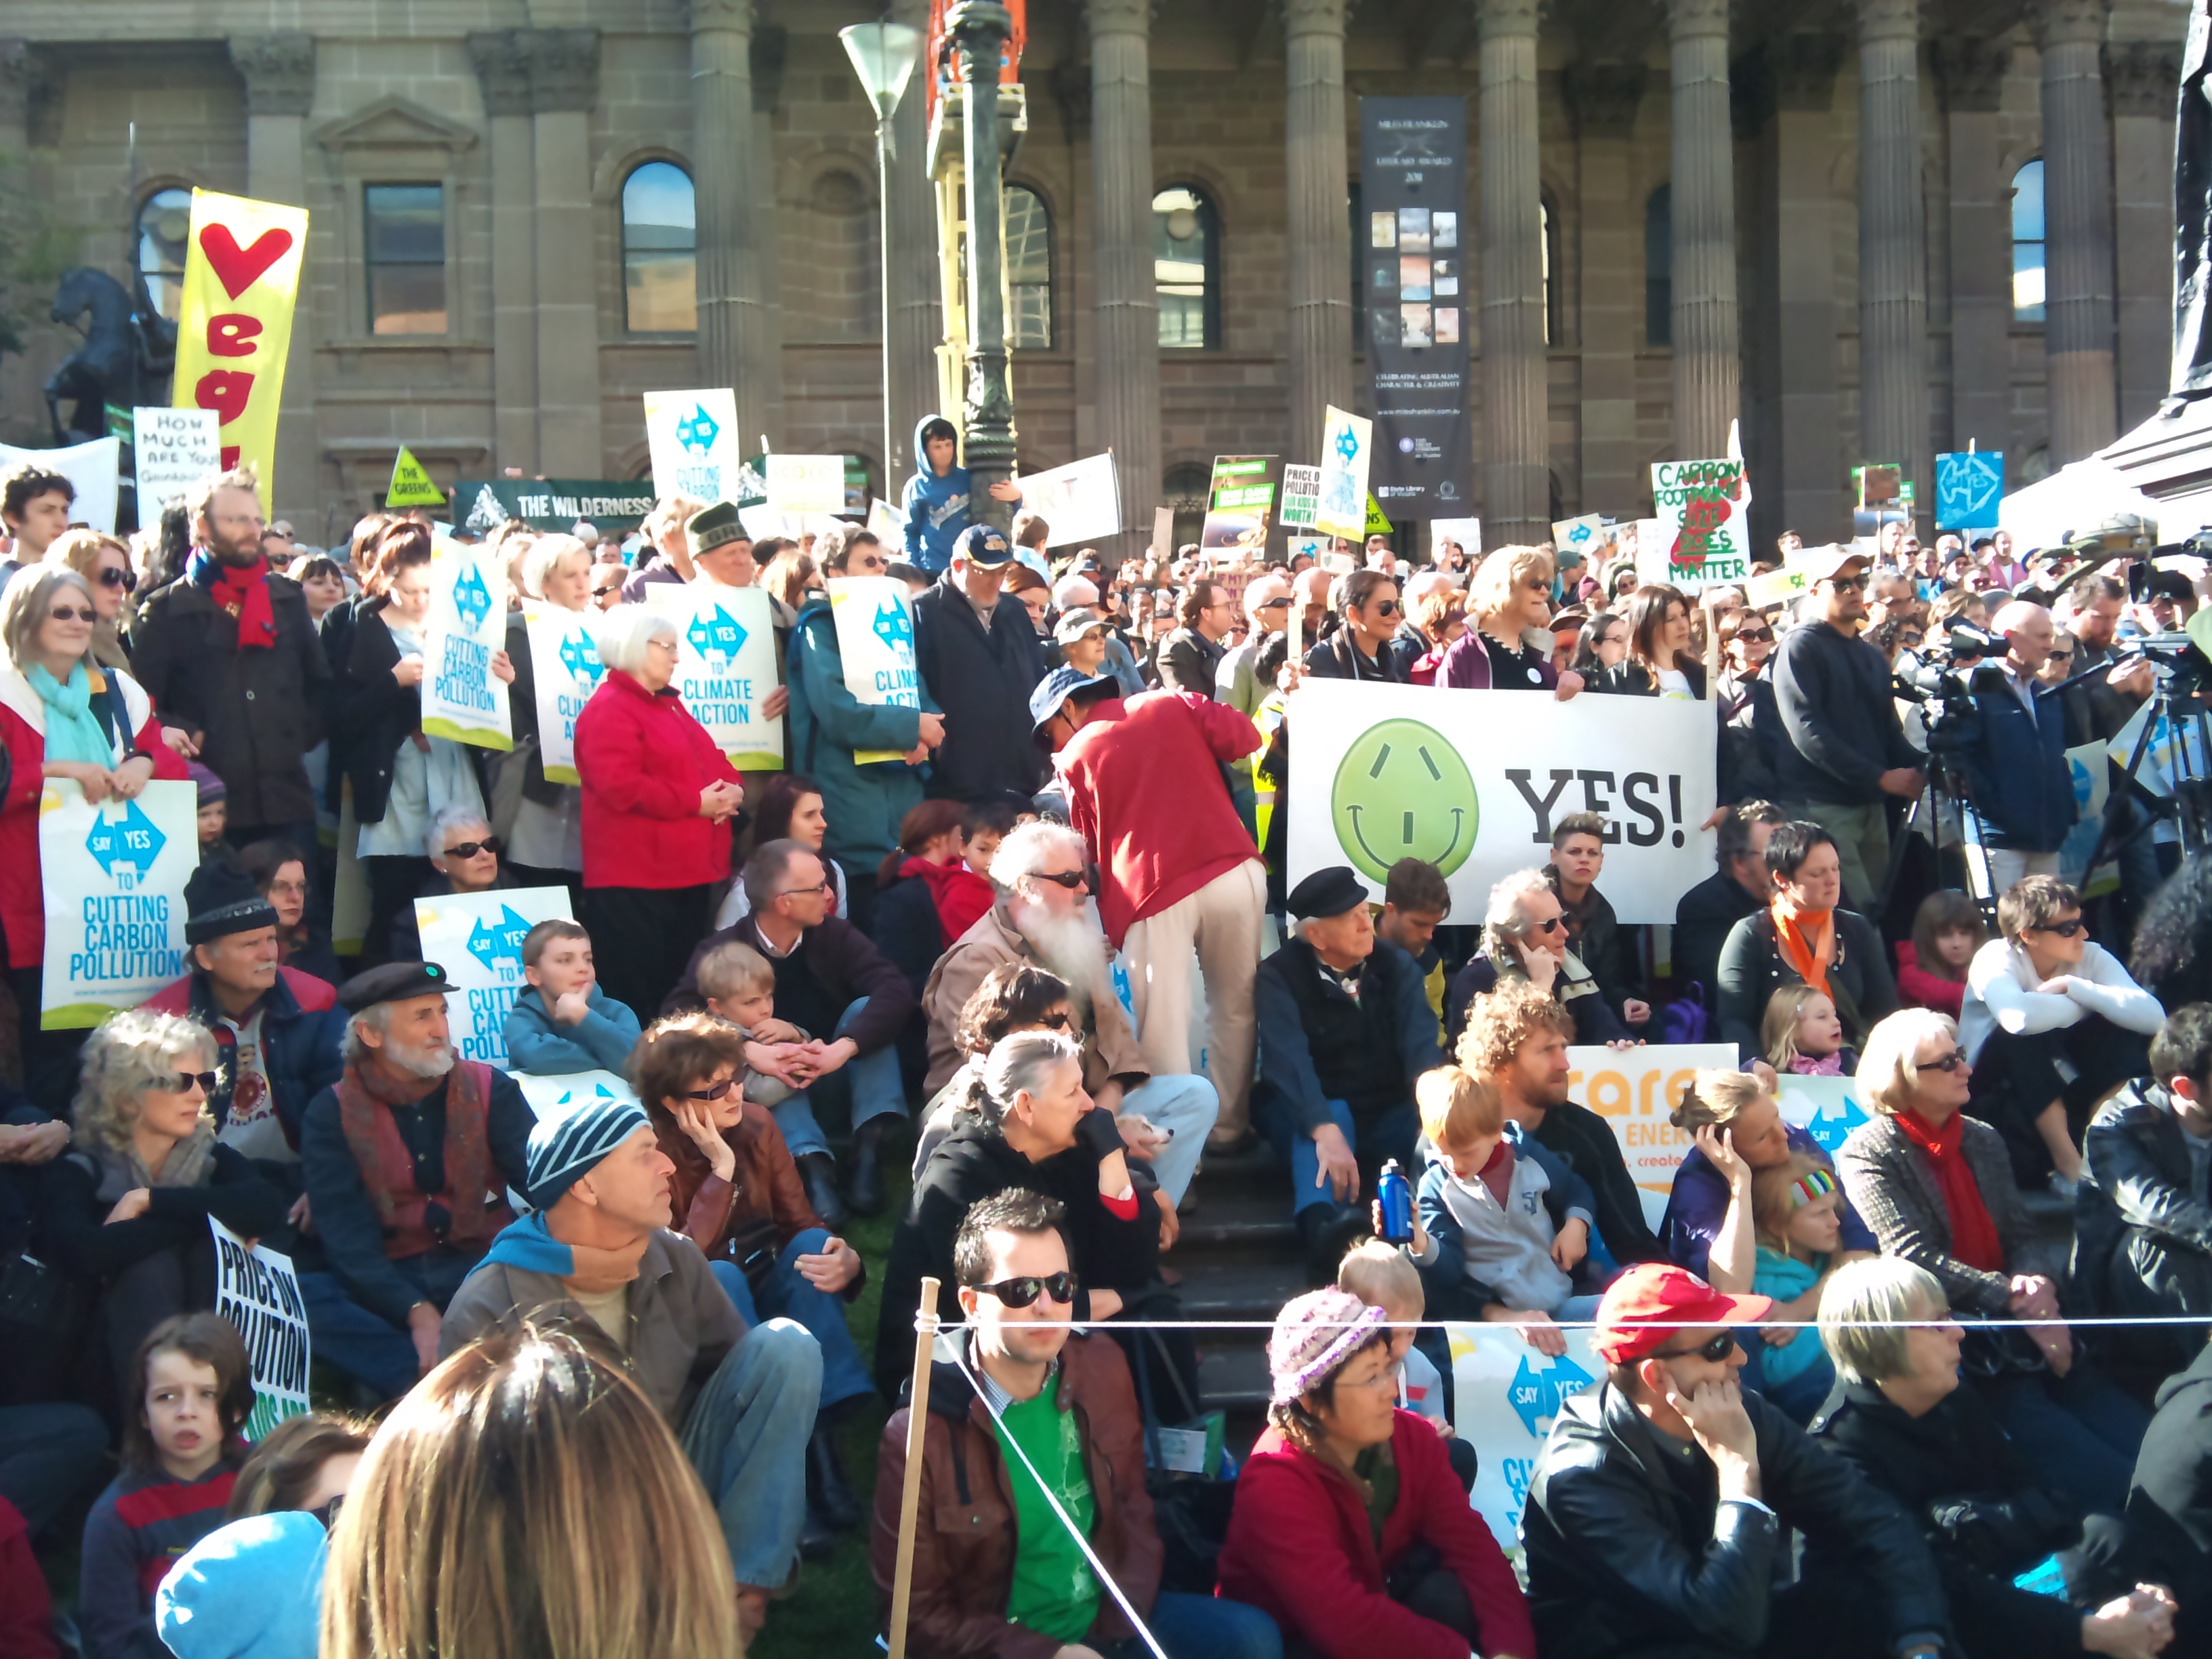
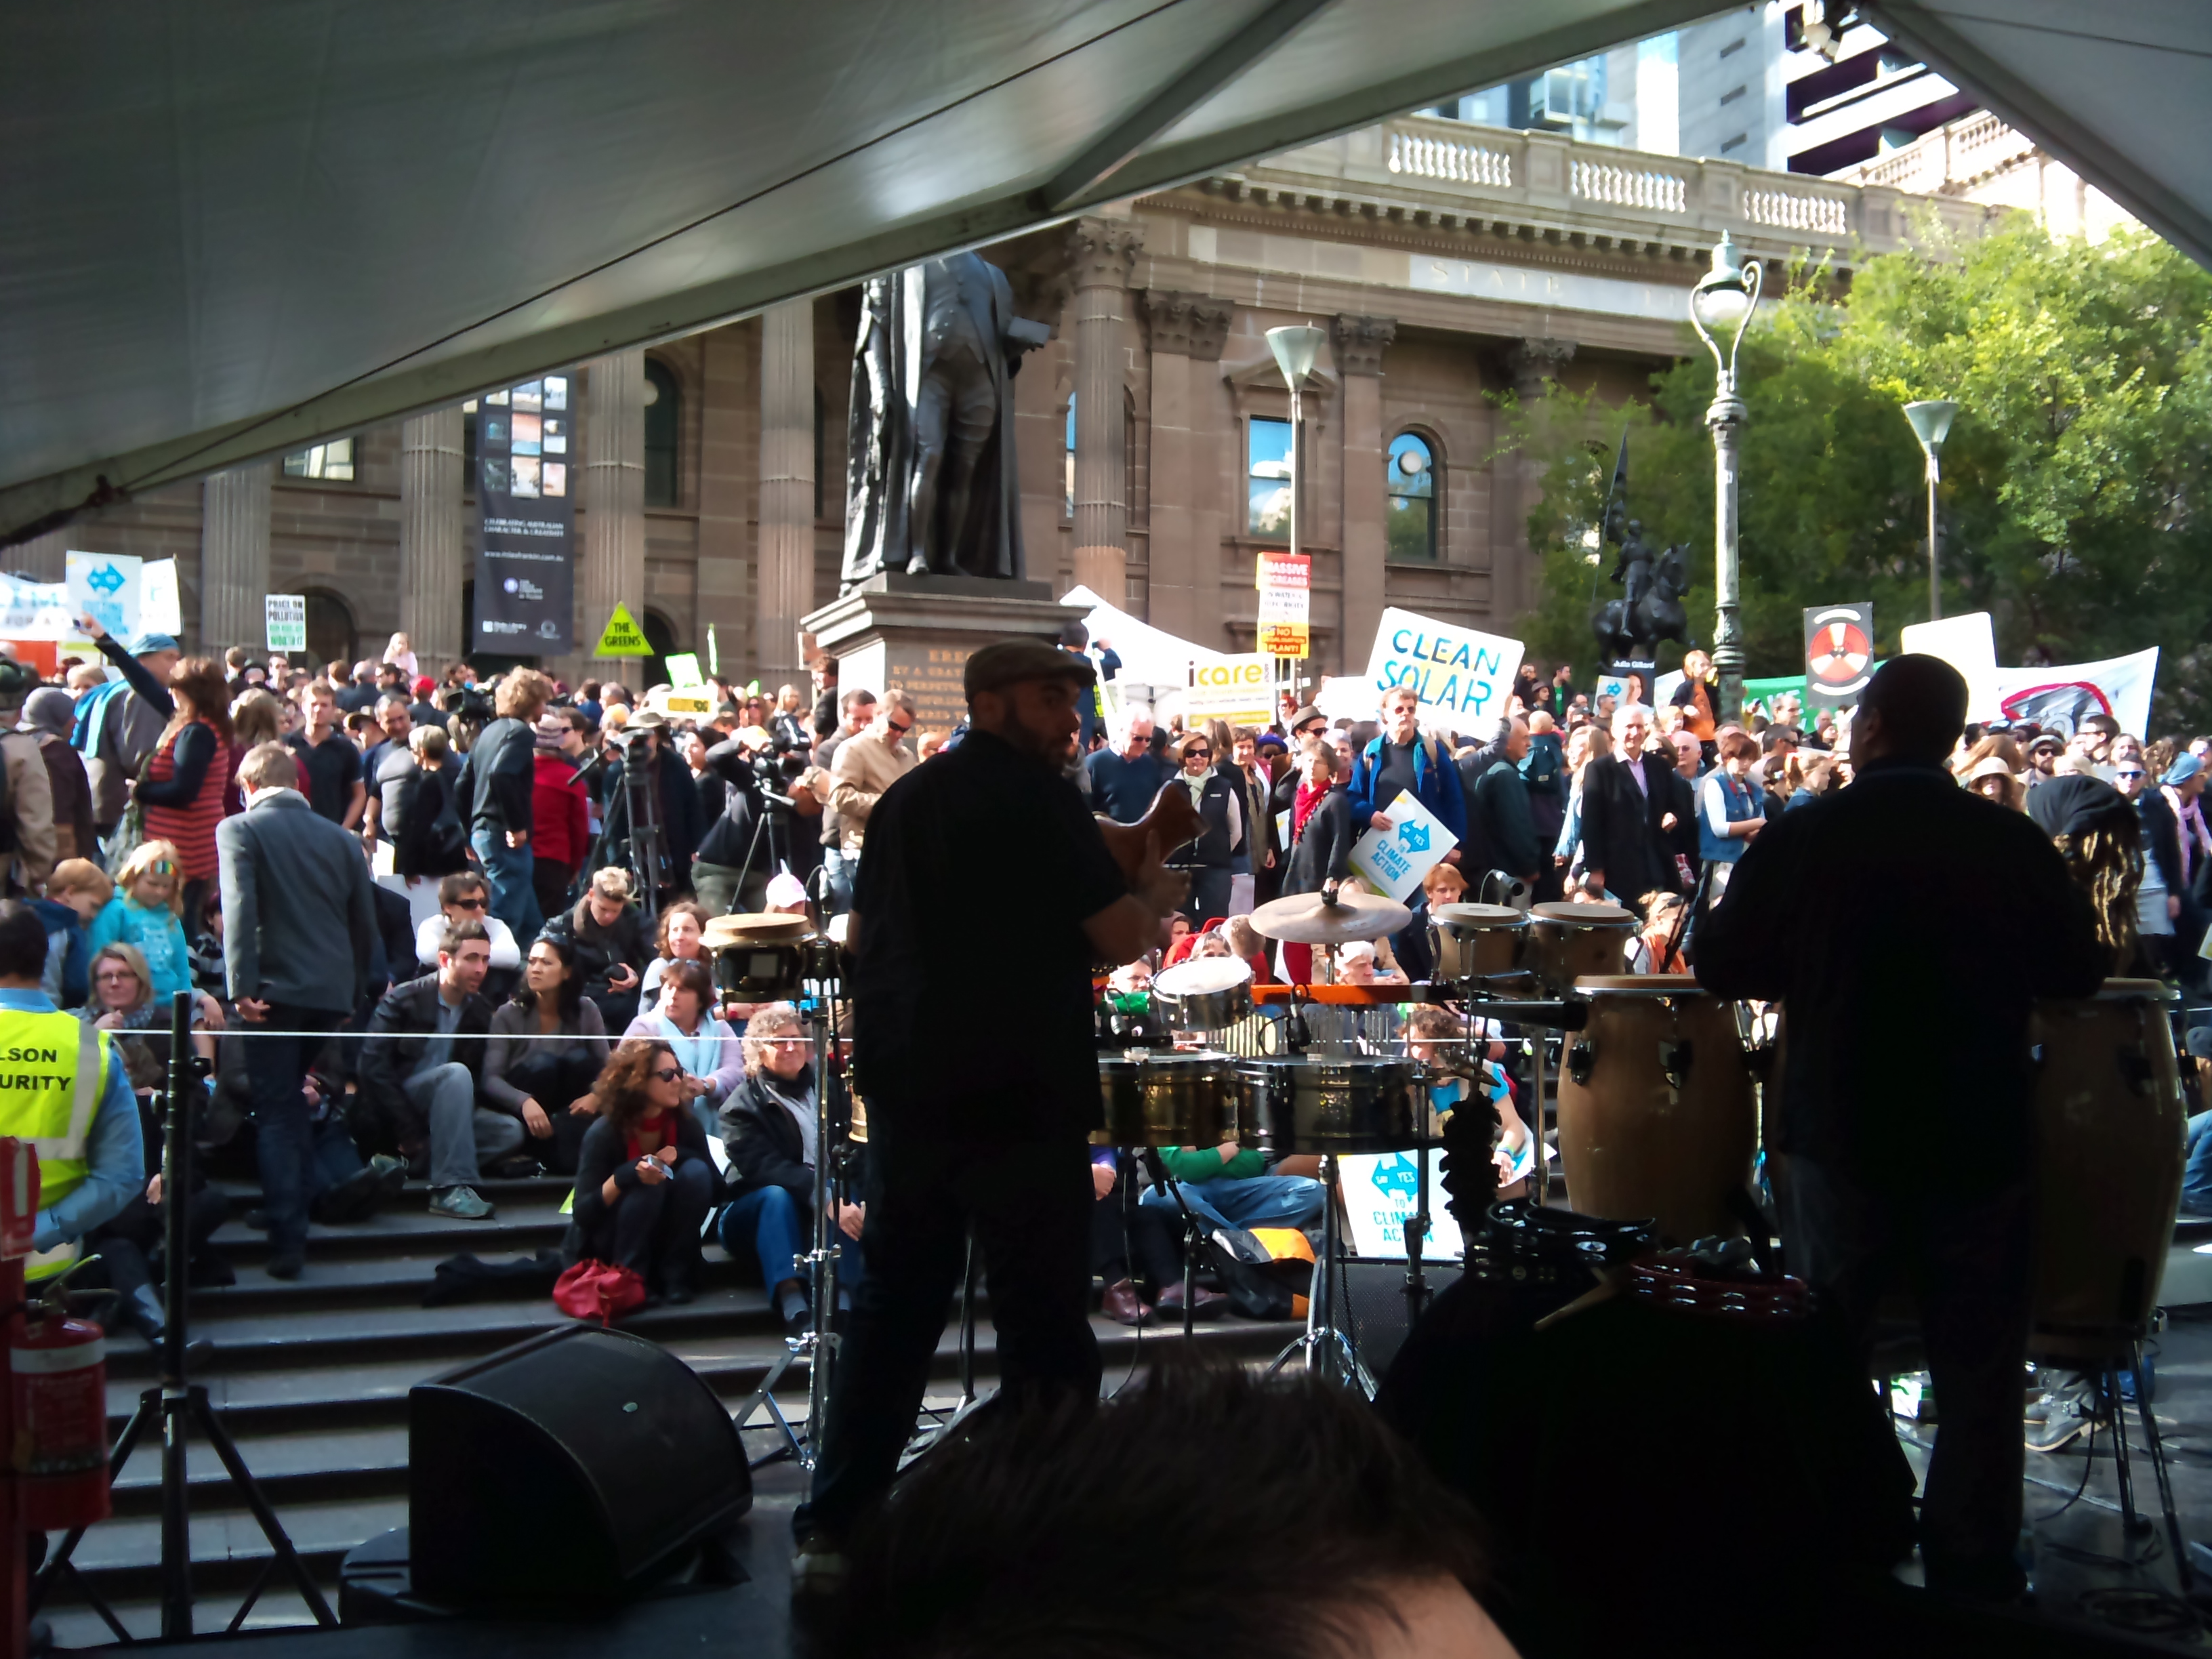
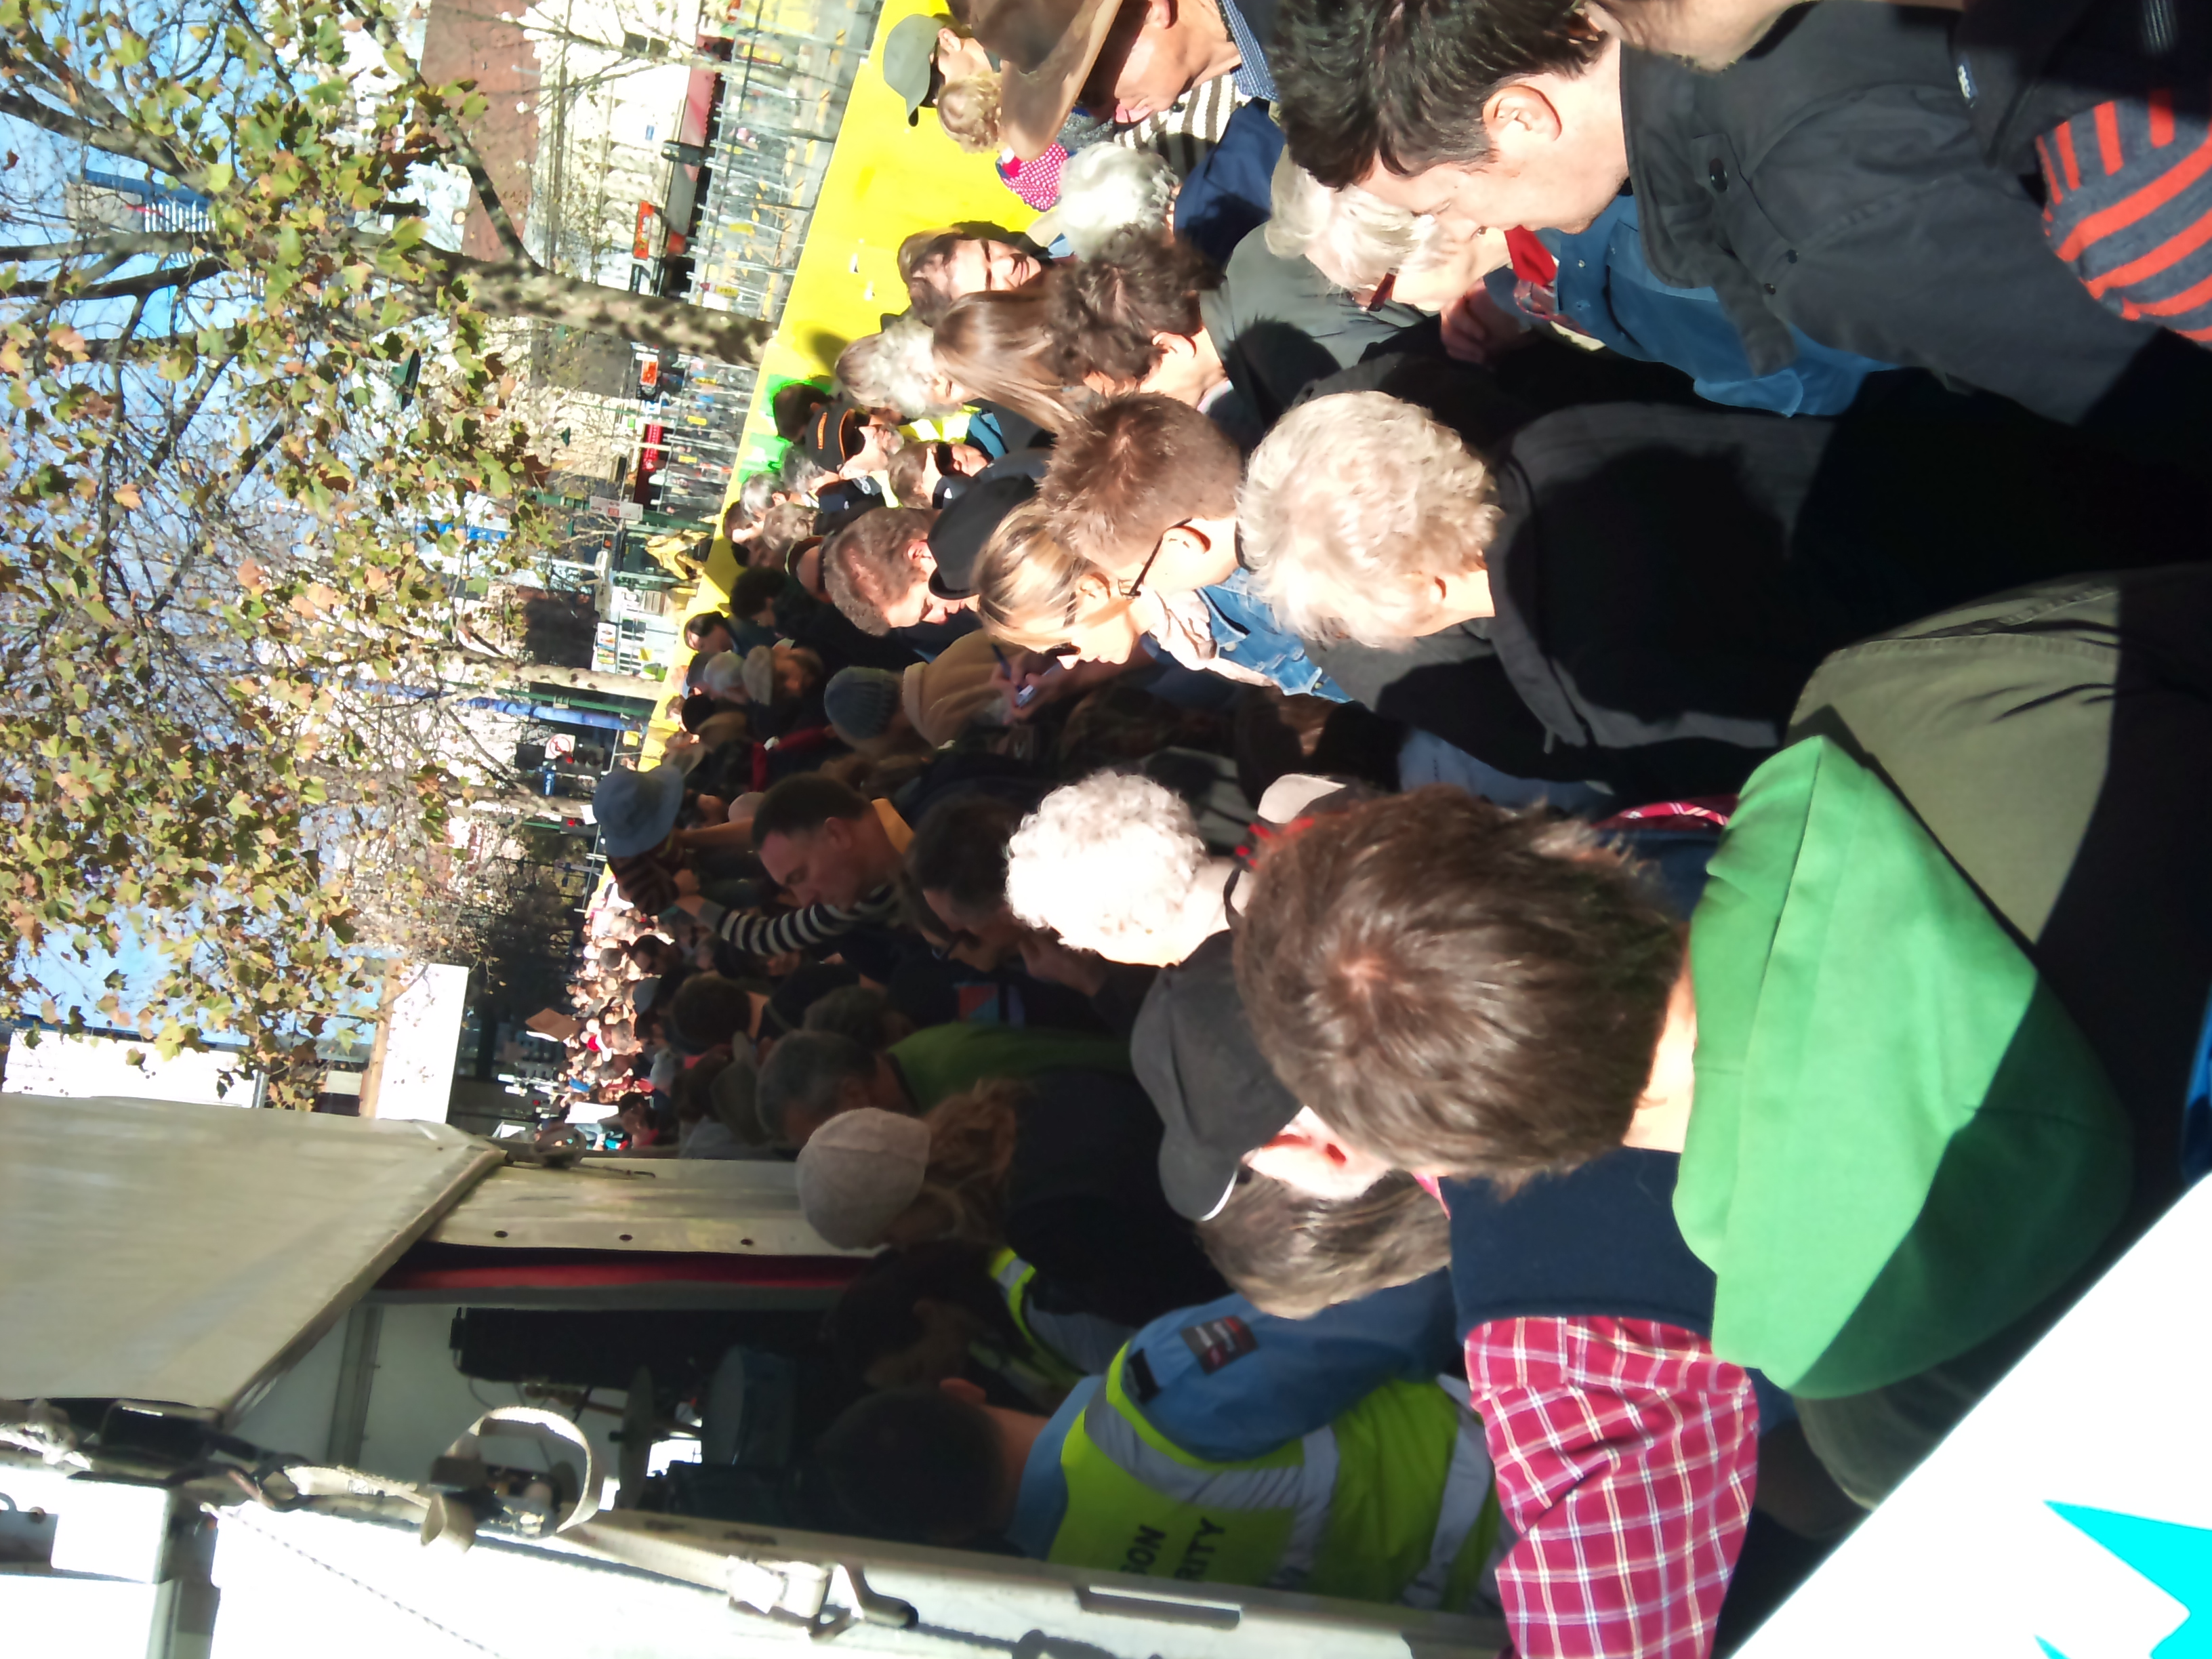
It s not that common to have a rally in favor of creating a new tax, but today I attended the Melbourne rally in favor of a carbon tax [1], it was the second such event this year. The rally was held in front of the state library, there is a reasonable size park there and it s a great place for a few hundred people, and a few thousand can squeeze in there without any problem. But according to the best estimates 10,000 people attended and the venue was obviously a bad choice as all available space was used and the crowd was so great that it wasn t much fun to be there. This was a great contrast to the previous rally in favor of a carbon tax which had maybe about 8,000 people attend and a much larger area [2]. The state library is a great place to hold a small or medium size rally where people can see it, but if you are going to get 10,000 people you need a bigger venue as the exits were partially blocked by road work I m sure that the local government wouldn t have given a permit if so many people were expected. Usually the city center is very quiet on a Sunday afternoon, but this afternoon everything was packed. An extra 10,000 people really makes a difference although admittedly sunny weather would have helped. Australia wide there were apparently about 100,000 people attending similar rallies, that s 0.5% of the population of the country! The aim of the rally was to advocate a large enough tax on coal, oil, and other energy sources that emit CO2 to provide an economic incentive to minimise use and use alternate energy sources where possible. Currently billions of dollars are being given to polluting industries, instead those industries should be taxed and the money raised given to compensate needy people. looking north Looking North towards where I entered. looking east Two pictures from slightly different angles that are roughly East from where I was standing in the center of the crowd. looking east through the bandlooking south Pictures looking east through the band when people were starting to leave and looking south towards the exit I chose while on the way out.

Joey Hess: announcing olduse.net

As I write this, it's the morning of June 5th, 1981. A few people scattered across the US are waking up, going in to work, sitting down at their terminal with a coffee, and reading Usenet. Usenet is only getting a trickle of posts each day -- it's still in that period where it's easy to read every message posted to it. Many things lie in Usenet's future. It's still running A-News, which doesn't even have a real From header yet. Later this year it will switch over to B-News, and volume will begin to increase. In 1987 there will be The great renaming. And of course in 1994, the first spam will be posted to Usenet. But that's all a long way off, here in 1981. Right now, they're talking about 500 mb disk drives that only cost $38000. And rms is inciting flames about nuclear proliferation. And Postel is publishing an RFC for the new Mail Transfer Protocol. Good morning, Usenet. Who knows what will come next in this fledgeling electronic communications medium! a ten year real-time historical exhibit This morning, I'm announcing a new site: Olduse.net It's Usenet, updated in real time as it was thirty years ago. Planned to be available for the next ten years, unless I run out of inodes (again). If you missed it the first time around, this is your chance to follow Usenet's flowering. made possible by 141 magtape usenet archive
PS: You can post to olduse.net, but it won't show up for at least 30 years. :)

Niels Thykier: Status on Lintian and Vendor Profiles

During the past week I finally got around to give the Vendor Profiles branch some attention. I suspect the most exciting change is that I got support for non-overridable tags. Along with making --ftp-master-rejects an alias for the ftp-master profile. This means that you will get the same behavior from Lintian and from the ftp-master auto-reject mechanism. The only issue is that the overrides are silently ignored. We also made dropped the default profile symlink in favor of using dpkg-vendor to find the best profile. This causes a slight conflict with solving #626476. I have asked the dpkg maintainers if that part of the libdpkg-perl API is stable enough for us to use. Finally I fixed an issue where profiles would ignore all display settings (--display-info etc.) and just show all tags (except experimental tags). Beyond the vendor profile branch, there are also a number of interesting changes applied in the master branch. Together with some people from #debian-python (ScottK and jwilk as I recall), I prepared some python related goodies. Particularly we fixed a false-positive missing-python-build-dependency with python3 and marked dh_pycentral and dh_python as deprecated. On a related note, we have also removed the tag uses-dh-python-with-no-pycompat. Based on feedback from Eric Lavarde, we redefined the classpath-contains-relative-path tag. It now only emits the bad parts of the Classpath and relative entries are allowed in they exists or point to /usr/share/java/$file.jar and there is a strong libX-java dependency. While the change breaks overrides, according to lintian.d.o we do not have any yet. The next release will feature a check for non-empty dependency_libs fields in la files and a fix to a flaw in logic for architecture dependent overrides. We will be reducing our dependency of dpkg-dev to a Suggests (#626476). Currently the xz-utils is in the pseudo-essential set, but it may not stay that way. So in the future you may need to explicitly install xz-utils for Lintian to support .xz source packages. Last, but not least, if you have felt that the lintianrc file has been rather useless to you, then you are not alone. I have made a prototype patch to improve the situation and hopefully soon you get to specify default options in your lintianrc.

Sune Vuorela: Five is a four letter word

and it starts with f While looking at the future of the KDE Platform Frameworks here in Randa, Switzerland, a lot of interesting things has been found in kdelibs and kdepimlibs that no one knew what was there for. On the good side, there is also lots of cool stuff, that of course most people knows about and uses And a lot of great larger solutions for solving different real life problems And lots of other cool stuff And we have currently nice things in the required runtime components for every app built using kdelibs

Russ Allbery: git-pbuilder 1.22

I actually released this on May 23rd, but I never posted an announcement here, and I think it's worth at least a brief note (if for no other reason that I can remember what I've been working on). The new version adds support for reading COWBUILDER_BASE from the environment so that you can use a different location for your cowbuilder setups if you'd like. It also removes an extra level of quoting around options in $BASE that caused problems with the shell. The latter is weird, and I still don't completely understand it. I was setting a variable like:
    OPTIONS="$OPTIONS --basepath '$BASE'"
and then using it with:
    pdebuild --pbuilder "$BUILDER" -- $OPTIONS
(with some additional complexity). I expected, since $OPTIONS was not quoted, that this would expand $OPTIONS and then do shell parsing again, which would strip off the other level of quotes. But this doesn't seem to actually work; instead, the quotes are left in, at least for some shells. This is apparently some corner of shell quoting that I don't understand. The chances of the base path containing shell metacharacters is quite low, so I just went with the solution that feels "underquoted." Anyway, you can get the latest version from my scripts page.

4 June 2011

Mike (stew) O'Connor: My Movein Script

Erich Schubert's blog post reminded me that I've been meaning to writeup a post detailing how I'm keeping parts of my $HOME in git repositories. My goal has been to keep my home directory in a version control system effectively. I have a number of constraints however. I want the system to be modular. I don't always need X related config files in my home directory. Sometimes I want just my zsh related files and my emacs related files. I have multiple machines I check email from, and on those want to keep my notmuch/offlineimap files in sync, but I don't need these on every machine I'm on, expecially since those configurations have more sensitive data. I played around with laysvn for a while, but it never really seemed comfortable. I more recently discovered that madduck had started a "vcs-home" website and mailing list, talking about doing what I'm trying to do. I'm now going with madduck's idea of using git with detached work trees, so that I can have multiple git repositories all using $HOME as their $GIT_WORK_TREE. I have a script inspired by his vcsh script that will create a subshell where the GIT_DIR, GIT_WORK_TREE variables are set for me. I can do my git operations related to just one git repository in that shell, while still operating directly on my config files in $HOME, and avoiding any kind of nasty symlinking or hardlinking. Since I am usually using my script to allow me to quickly "move in" to a new host, I named my script "movein". It can be found here. Here's how I'll typically use it:
    stew@guppy:~$ movein init
    git server hostname? git.vireo.org
    path to remote repositories? [~/git] 
    Local repository directory? [~/.movein] 
    Location of .mrconfig file? [~/.mrconfig] 
    stew@guppy:~$ 
This is just run once. It asks me questions about how to setup the 'movein' environment. Now I should have a .moveinrc storing the answers I gave above, I have a stub of a .mrconfig, and an empty .movein directory. Next thing to do is to add some of my repositories. The one I typically add on all machines is my "shell" repository. It has a .bashrc/.zshrc, an .alias that both source and other zsh goodies I'll generally wish to be around:
    stew@guppy:~$ ls .zshrc
    ls: cannot access .zshrc: No such file or directory
    stew@guppy:~$ movein add shell
    Initialized empty Git repository in /home/stew/.movein/shell.git/
    remote: Counting objects: 42, done.
    remote: Compressing objects: 100% (39/39), done.
    remote: Total 42 (delta 18), reused 0 (delta 0)
    Unpacking objects: 100% (42/42), done.
    From ssh://git.vireo.org//home/stew/git/shell
     * [new branch]      master     -> origin/master
    stew@guppy:~$ ls .zshrc
    .zshrc
So what happened here is that the ssh://git.vireo.org/~/git/shell.git repository was cloned with GIT_WORK_TREE=~ and GIT_DIR=.movein/shell.git. My .zshrc (along with a bunch of other files) has appeared. Next perhaps I'll add my emacs config files:
    stew@guppy:~$ movein add emacs       
    Initialized empty Git repository in /home/stew/.movein/emacs.git/
    remote: Counting objects: 77, done.
    remote: Compressing objects: 100% (63/63), done.
    remote: Total 77 (delta 10), reused 0 (delta 0)
    Unpacking objects: 100% (77/77), done.
    From ssh://git.vireo.org//home/stew/git/emacs
     * [new branch]      emacs21    -> origin/emacs21
     * [new branch]      master     -> origin/master
    stew@guppy:~$ ls .emacs
    .emacs
    stew@guppy:~$ 
My remote repositry has a master branch, but also has an emacs21 branch, which I can use when checking out on older machines which don't yet have newer versions of emacs. Let's say I have made changes to my .zshrc file, and I want to check them in. Since we are working with detached work trees, git can't immediately help us:
    stew@guppy:~$ git status
    fatal: Not a git repository (or any of the parent directories): .git
The movein script allows me to "login" to one of the repositories. It will create a subshell with GIT_WORK_TREE and GIT_DIR set. In that subshell, git operations operate as one might expect:
    stew@guppy:~ $ movein login shell
    stew@guppy:~ (shell:master>*) $ echo >> .zshrc
    stew@guppy:~ (shell:master>*) $ git add .zshrc                                       
    stew@guppy:~ (shell:master>*) $ git commit -m "adding a newline to the end of .zshrc"
    [master 81b7311] adding a newline to the end of .zshrc
     1 files changed, 1 insertions(+), 0 deletions(-)
    stew@guppy:~ (shell:master>*) $ git push
    Counting objects: 8, done.
    Delta compression using up to 2 threads.
    Compressing objects: 100% (6/6), done.
    Writing objects: 100% (6/6), 546 bytes, done.
    Total 6 (delta 4), reused 0 (delta 0)
    To ssh://git.vireo.org//home/stew/git/shell.git
       d24bf2d..81b7311  master -> master
    stew@guppy:~ (shell:master*) $ exit
    stew@guppy:~ $ 
If I want to create a brand new repository from files in my home directory. I can:
    stew@guppy:~ $ touch methere
    stew@guppy:~ $ touch mealsothere
    stew@guppy:~ $ movein new oohlala methere mealsothere
    Initialized empty Git repository in /home/stew/git/oohlala.git/
    Initialized empty Git repository in /home/stew/.movein/oohlala.git/
    [master (root-commit) 7abe5ba] initial checkin
     0 files changed, 0 insertions(+), 0 deletions(-)
     create mode 100644 mealsothere
     create mode 100644 methere
    Counting objects: 3, done.
    Delta compression using up to 2 threads.
    Compressing objects: 100% (2/2), done.
    Writing objects: 100% (3/3), 224 bytes, done.
    Total 3 (delta 0), reused 0 (delta 0)
    To ssh://git.vireo.org//home/stew/git/oohlala.git
     * [new branch]      master -> master
Above, the command movein new oohlala methere mealsothere says "create a new repository containing two files: methere, mealsothere". A bare repository is created on the remote machine, a repository is created in the .movein directory, the files are committed, and the new commit is pushed to the remote repository. New on some other machine, I could run movein add oohlala to get these two new files. The movein script maintains a .mrconfig file, so that joeyh's mr tool can be used to manage the repositories in bulk. Commands like "mr update", "mr commit", "mr push" will act on all the known repositories. Here's an example:
    stew@guppy:~ $ cat .mrconfig
    [DEFAULT]
    include = cat /usr/share/mr/git-fake-bare
    [/home/stew/.movein/emacs.git]
    checkout = git_fake_bare_checkout 'ssh://git.vireo.org//home/stew/git/emacs.git' 'emacs.git' '../../'
    [/home/stew/.movein/shell.git]
    checkout = git_fake_bare_checkout 'ssh://git.vireo.org//home/stew/git/shell.git' 'shell.git' '../../'
    [/home/stew/.movein/oohlala.git]
    checkout = git_fake_bare_checkout 'ssh://git.vireo.org//home/stew/git/oohlala.git' 'oohlala.git' '../../'
    stew@guppy:~ $ mr update
    mr update: /home/stew//home/stew/.movein/emacs.git
    From ssh://git.vireo.org//home/stew/git/emacs
     * branch            master     -> FETCH_HEAD
    Already up-to-date.
    mr update: /home/stew//home/stew/.movein/oohlala.git
    From ssh://git.vireo.org//home/stew/git/oohlala
     * branch            master     -> FETCH_HEAD
    Already up-to-date.
    mr update: /home/stew//home/stew/.movein/shell.git
    From ssh://git.vireo.org//home/stew/git/shell
     * branch            master     -> FETCH_HEAD
    Already up-to-date.
    mr update: finished (3 ok)
    stew@guppy:~ $ mr update        
There are still issues I'd like to address. The big one in my mind is that there is no .gitignore. So when you "movein login somerepository" then run "git status", It tells you about hundreds of untracked files in your home directory. Ideally, I just want to know about the files which are already associated with the repository I'm logged into.

Mike (stew) O'Connor: My Movin Script

Erich Schubert's blog post reminded me that I've been meaning to writeup a post detailing how I'm keeping parts of my $HOME in git repositories. My goal has been to keep my home directory in a version control system effectively. I have a number of constraints however. I want the system to be modular. I don't always need X related config files in my home directory. Sometimes I want just my zsh related files and my emacs related files. I have multiple machines I check email from, and on those want to keep my notmuch/offlineimap files in sync, but I don't need these on every machine I'm on, expecially since those configurations have more sensitive data. I played around with laysvn for a while, but it never really seemed comfortable. I more recently discovered that madduck had started a "vcs-home" website and mailing list, talking about doing what I'm trying to do. I'm now going with madduck's idea of using git with detached work trees, so that I can have multiple git repositories all using $HOME as their $GIT_WORK_TREE. I have a script inspired by his vcsh script that will create a subshell where the GIT_DIR, GIT_WORK_TREE variables are set for me. I can do my git operations related to just one git repository in that shell, while still operating directly on my config files in $HOME, and avoiding any kind of nasty symlinking or hardlinking. Since I am usually using my script to allow me to quickly "move in" to a new host, I named my script "movein". It can be found here. Here's how I'll typically use it:
    stew@guppy:~$ movein init
    git server hostname? git.vireo.org
    path to remote repositories? [~/git] 
    Local repository directory? [~/.movein] 
    Location of .mrconfig file? [~/.mrconfig] 
    stew@guppy:~$ 
This is just run once. It asks me questions about how to setup the 'movein' environment. Now I should have a .moveinrc storing the answers I gave above, I have a stub of a .mrconfig, and an empty .movein directory. Next thing to do is to add some of my repositories. The one I typically add on all machines is my "shell" repository. It has a .bashrc/.zshrc, an .alias that both source and other zsh goodies I'll generally wish to be around:
    stew@guppy:~$ ls .zshrc
    ls: cannot access .zshrc: No such file or directory
    stew@guppy:~$ movein add shell
    Initialized empty Git repository in /home/stew/.movein/shell.git/
    remote: Counting objects: 42, done.
    remote: Compressing objects: 100% (39/39), done.
    remote: Total 42 (delta 18), reused 0 (delta 0)
    Unpacking objects: 100% (42/42), done.
    From ssh://git.vireo.org//home/stew/git/shell
     * [new branch]      master     -> origin/master
    stew@guppy:~$ ls .zshrc
    .zshrc
So what happened here is that the ssh://git.vireo.org/~/git/shell.git repository was cloned with GIT_WORK_TREE=~ and GIT_DIR=.movein/shell.git. My .zshrc (along with a bunch of other files) has appeared. Next perhaps I'll add my emacs config files:
    stew@guppy:~$ movein add emacs       
    Initialized empty Git repository in /home/stew/.movein/emacs.git/
    remote: Counting objects: 77, done.
    remote: Compressing objects: 100% (63/63), done.
    remote: Total 77 (delta 10), reused 0 (delta 0)
    Unpacking objects: 100% (77/77), done.
    From ssh://git.vireo.org//home/stew/git/emacs
     * [new branch]      emacs21    -> origin/emacs21
     * [new branch]      master     -> origin/master
    stew@guppy:~$ ls .emacs
    .emacs
    stew@guppy:~$ 
My remote repositry has a master branch, but also has an emacs21 branch, which I can use when checking out on older machines which don't yet have newer versions of emacs. Let's say I have made changes to my .zshrc file, and I want to check them in. Since we are working with detached work trees, git can't immediately help us:
    stew@guppy:~$ git status
    fatal: Not a git repository (or any of the parent directories): .git
The movein script allows me to "login" to one of the repositories. It will create a subshell with GIT_WORK_TREE and GIT_DIR set. In that subshell, git operations operate as one might expect:
    stew@guppy:~ $ movein login shell
    stew@guppy:~ (shell:master>*) $ echo >> .zshrc
    stew@guppy:~ (shell:master>*) $ git add .zshrc                                       
    stew@guppy:~ (shell:master>*) $ git commit -m "adding a newline to the end of .zshrc"
    [master 81b7311] adding a newline to the end of .zshrc
     1 files changed, 1 insertions(+), 0 deletions(-)
    stew@guppy:~ (shell:master>*) $ git push
    Counting objects: 8, done.
    Delta compression using up to 2 threads.
    Compressing objects: 100% (6/6), done.
    Writing objects: 100% (6/6), 546 bytes, done.
    Total 6 (delta 4), reused 0 (delta 0)
    To ssh://git.vireo.org//home/stew/git/shell.git
       d24bf2d..81b7311  master -> master
    stew@guppy:~ (shell:master*) $ exit
    stew@guppy:~ $ 
If I want to create a brand new repository from files in my home directory. I can:
    stew@guppy:~ $ touch methere
    stew@guppy:~ $ touch mealsothere
    stew@guppy:~ $ movein new oohlala methere mealsothere
    Initialized empty Git repository in /home/stew/git/oohlala.git/
    Initialized empty Git repository in /home/stew/.movein/oohlala.git/
    [master (root-commit) 7abe5ba] initial checkin
     0 files changed, 0 insertions(+), 0 deletions(-)
     create mode 100644 mealsothere
     create mode 100644 methere
    Counting objects: 3, done.
    Delta compression using up to 2 threads.
    Compressing objects: 100% (2/2), done.
    Writing objects: 100% (3/3), 224 bytes, done.
    Total 3 (delta 0), reused 0 (delta 0)
    To ssh://git.vireo.org//home/stew/git/oohlala.git
     * [new branch]      master -> master
Above, the command movein new oohlala methere mealsothere says "create a new repository containing two files: methere, mealsothere". A bare repository is created on the remote machine, a repository is created in the .movein directory, the files are committed, and the new commit is pushed to the remote repository. New on some other machine, I could run movein add oohlala to get these two new files. The movein script maintains a .mrconfig file, so that joeyh's mr tool can be used to manage the repositories in bulk. Commands like "mr update", "mr commit", "mr push" will act on all the known repositories. Here's an example:
    stew@guppy:~ $ cat .mrconfig
    [DEFAULT]
    include = cat /usr/share/mr/git-fake-bare
    [/home/stew/.movein/emacs.git]
    checkout = git_fake_bare_checkout 'ssh://git.vireo.org//home/stew/git/emacs.git' 'emacs.git' '../../'
    [/home/stew/.movein/shell.git]
    checkout = git_fake_bare_checkout 'ssh://git.vireo.org//home/stew/git/shell.git' 'shell.git' '../../'
    [/home/stew/.movein/oohlala.git]
    checkout = git_fake_bare_checkout 'ssh://git.vireo.org//home/stew/git/oohlala.git' 'oohlala.git' '../../'
    stew@guppy:~ $ mr update
    mr update: /home/stew//home/stew/.movein/emacs.git
    From ssh://git.vireo.org//home/stew/git/emacs
     * branch            master     -> FETCH_HEAD
    Already up-to-date.
    mr update: /home/stew//home/stew/.movein/oohlala.git
    From ssh://git.vireo.org//home/stew/git/oohlala
     * branch            master     -> FETCH_HEAD
    Already up-to-date.
    mr update: /home/stew//home/stew/.movein/shell.git
    From ssh://git.vireo.org//home/stew/git/shell
     * branch            master     -> FETCH_HEAD
    Already up-to-date.
    mr update: finished (3 ok)
    stew@guppy:~ $ mr update        
There are still issues I'd like to address. The big one in my mind is that there is no .gitignore. So when you "movein login somerepository" then run "git status", It tells you about hundreds of untracked files in your home directory. Ideally, I just want to know about the files which are already associated with the repository I'm logged into.

3 June 2011

Sam Dunne: Declarative Diversions - Report 1

DECLARATIVE DIVERSIONS ====================== Introduction A diversion is when it is possible to have dpkg not overwrite a file when it reinstalls the package it belongs to, and to have it put the file from the package somewhere else instead. Declarative diversions involves a new control file with a declarative syntax which dpkg will parse and process directly as part of the package unpack and removal phases, eliminating the problems resulting from non-atomic handling of diversions. Topics There are a number of topics involved in implementing this kind of project * What syntax do we use for the new control file? * What dpkg does with the control file * How do we handle diversions to a non-existant directory? * How do we order unpacking a new package which adds a diversion? * How do we order unpacking a new package that removes a diversion? * How do we order removing a package which had a diversion? * How do we handle errors? * What happens to dpkg-divert? - Details - Control File Syntax - It will conform to RFC2822 style with the following format: * Divert-From: * Divert-To: * Blank lines and lines beginning with # will be comments Divert-To will be optional and if it is ommitted then files being diverted will have their filename changed to file.distrib The above style has it s advantages, one of the main ones being that there is no need to escape whitespace within filenames. - Details - Control File Handling - Within control.tar.gz the file should be named diversions This file is then copied to /var/lib/info/$package.diversions This is ensuring we have a copy of the control file just in case it is needed. Any input on this subject would be appreciated. - Details - Handling Diversions to non-existant directories - Diverting files to directories that don t exist can cause a number of problems. If the package does not own the directory it may be left orphaned on removal of the package The package is responsible for ensuring the availability of the target directory in the unpack phase. - Details - Ordering Requirements - =>Unpacking a new package that adds a diversion *1. Unpack folders *2. Add diversions *3. Unpack files ==Notes== Performing diversions this way avoids trouble with creating folders and accidentally overwrtiting the wrong version of files. If we don t use this method the problems that can occur include creating folders before the package itself would create them which may cause permission errors. Another major problem would be extracting a new version of the file and overwriting the old one. This might cause the wrong version of the file to be diverted and the package to break. =>Unpacking a new package that removes a diversion *1. Unpack folders *2. Add diversions *3. Unpack files ==Notes== =>Removing a package which had a diversion *1. Remove files *2. Remove diversions *3. Remove folders ==Notes== This ensures that all files, diversions and folders are removed correctly Details - Error handling Errors in diversions will have to handled with a great deal of care due to the fact that if they are not the package could be broken. This means that a great deal of checks must be done to ensure that all the files can be diverted properly before any actual diverting takes place. If they can t the package installation/update must be stopped and rolled back to avoid the package being installed incorrectly or broken. - Details - dpkg-divert - When we impliment the new diversion method we should keep the current dpkg-divert. This allows maintainers to catch up with the new method without breaking their packages. It also allows maintainers to perform some operations that aren t support by the new method. Example Usage #1 The file to be diverted is /usr/share/foo It needs to be moved to /usr/share/bar The syntax of the control file would be: #Start File Divert-From: /usr/share/foo Divert-To: /usr/share/bar #End File Example Usage #2 In this example the maintainer doesn t want to move the file to any specific folder The syntax of the control file would be: #Start File Divert-From: /usr/share/foo #End File This would divert the file to /usr/share/foo.distrib - Footnotes - RFC2822 Guide: * http://www.faqs.org/rfcs/rfc2822.html First Email Thread on Declarative Diversions (First Message in Thread): * http://lists.debian.org/debian-dpkg/2011/05/msg00102.html Declarative Diversions Wiki: * http://wiki.debian.org/SummerOfCode2011/DeclarativeDiversions My Blog for this Project: * http://blog.sam-dunne.com

Guillaume Mazoyer: Status report Jigsaw num. 1 for GSoC 2011

code.pngThe beginning of this Google Summer of Code has been busy and pretty cool. Not a lot of code was produced but I did learn a lot of things.

During this GSoC I will work on the next generation JDK. This means that I will (and I already have) compile the JDK. That s pretty awesome but it requires a lot of power. That s why Tom Marble created me an account on his 8 CPUs machine to help me.
Since I m probably going to sign some packages, I created a new GPG key with a 4096 RSA strength.
My old key was:

pub 1024D/F144A319 2008-10-18

And the new key is:

pub 4096R/EE2BBBC7 2011-05-03

I cross signed my keys using this great tutorial.

I read some documentation about Jigsaw and watched Tom s talk at DebConf 10.
I have spent a little more than a week to understand the current OpenJDK packaging to be able to rebuild it. I have learnt from where do the sources come from. The current packaging is a little hard to understand. There are sources that come from IcedTea, OpenJDK, and more.

After being able to rebuild the OpenJDK 6 package, I have downloaded the source of the OpenJDK 8 and Jigsaw. I used the Mercurial forest to get the sources.

For OpenJDK 8:
hg clone http://hg.openjdk.java.net/jdk8/jdk8 jdk8
cd jdk8 && sh get_sources.sh

For Jigsaw:
hg clone http://hg.openjdk.java.net/jigsaw/jigsaw jigsaw
cd jigsaw && sh get_sources.sh

I have managed to build the sources of OpenJDK 8 and Jigsaw using the same steps:
cd jigsaw
. jigbuild
. jdk/make/jdk_generic_profile.sh
export ALLOW_DOWNLOADS=true
make sanity
make all

Jigsaw specific:
make modules-sanity
make modules

Each build took several minutes. But they were successful. Tom helped me a lot to build OpenJDK 8 and Jigsaw by giving me a solution. For example, after getting the Mercurial forest, there were still missing source files and the build failed. Tom told me that I needed to export a environement variable: ALLOW_DOWNLOADS=true.
After building Jigsaw, I was able to see that the version string is not legal in Debian and that is a real problem.
I have written some simple Hello World examples to compile and run with Jigsaw. To modularize a program, it needs to contain a module-info.java files. This file includes the modules needed to run the program and the main class to run. For a classic hello world, the module-info.java files looks like:

module test.hello @ 1
requires jdk.base @ 7-ea;
class test.hello.Main;


Tom gave me some packages to build: jtharness and jtreg. I succesfully built jtharness using CDBS and its Ant helper but I ll have to repackage it to use javahelper instead of CDBS. I still didn t try to build jtreg because it requires jtharness.

My next plan is to get jtharness and jtreg packaged with javahelper soon and understand what modules does what in Jigsaw. Understaning modules will help me to write some more complex examples. I hope to start working on Jigsaw a little more soon (when I my internship will end [next week]).

Josselin Mouette: Google Apps knows better what browser you can use

So I just read that Google will only support modern browsers starting 2 months from now.
As of August 1st, we will discontinue support for the following browsers and their predecessors: Firefox 3.5, Internet Explorer 7, and Safari 3. In these older browsers you may have trouble using certain features in Gmail, Google Calendar, Google Talk, Google Docs and Google Sites, and eventually these apps may stop working entirely.
Given the importance of Google, the impact is huge. This company has acquired the power to basically dictate what browser you can provide to your users - otherwise they won t be able to access what many of them now consider vital functionality. Such a decision denotes a grave misunderstanding of the workstation ecosystem from the Google people. It means they consider their only target to be nerdy users with home computers they can (and want to) upgrade and break every 3 months with the latest version of Windows or Fedora. What about corporate computers? What about non-techy people who buy a computer and stick with the OS that was sold with it for 4 years? I m afraid they are still the vast majority of web users. You can t decide to deploy a new version of IE of Firefox on a large number of computers for next month. Sometimes, this is not even possible (hello Windows 2000/XP users). For Debian squeeze, this means no more Firefox for you. Epiphany and Konqueror might still work, but Google loves sending JavaScript that make old versions of Webkit struggle. And anyway, this is just the beginning. In a few months they will tell us to upgrade again to Firefox 4.2 and IE 12. One week after their release, yeah! Let s quote a comment which should help understanding the reasoning behind such decisions.
Andy, while I understand staying on LTS, I think it's a little bit silly to use a mission critical machine for web browsing in that way. Also, there is no reason your browser has to be tied in lockstep to your OS. Two simple solutions:
1. Don't use the built-in browser for your main web browsing. Install Chrome, for example. or,
2. Since LTS is designed for servers and other "can't have any chance of downtime" machines, quit using that machine as your web browsing box and use a personal laptop for such things, which you can keep up to date with the current OS release instead of waiting 2 years.
Belief #1: the browser can (and should) be independent from the OS . It s interesting to note that the same people who say this are the ones who also jerk off at the idea of desktops and phones with tight web integration. This integration comes at a cost: this restricts your ability to change everything in the browser from one day to another. Belief #2: long-term OSes are for mission-critical servers only . Yeah sure, that s why Windows has a lifecycle of 3 years. Desktops are no different at all from servers on this matter. You don t upgrade your desktop every 6 months when you do serious work with it; the cost and the risk are just too high. And anyway, this comes again from the same people who want to upgrade every single component of said mission-critical servers every 2 months to install the latest version of their preferred web framework. Belief #3: people can upgrade their browsers or OSes . No really they can t. Many people wouldn t know how to do this, even with a step-by-step documentation. And in enterprise deployments, they are restricted from doing so. Thanks for spreading the clich that web developers are clueless, spotty nerds, incapable of understanding the needs of production environments. Apparently Google is not exempt from this disease.

2 June 2011

Erich Schubert: Managing user configuration files

Dear Lazyweb,
How do you manage your user configuration files? I have around four home directories I frequently use. They are sufficiently well enough in sync, but I have been considering to actually use some file management to synchronize them better. I'm talking about files such as shell config, ssh config, .vimrc etc.
I had some discussions about this before, and the consensus had been that some version control system probably is best. Git seemed to be a good candidate; I remember having read about things like this a dozen years ago when CVS was still common and Subversion was new.
So dear lazyweb, what are your experiences with managing your user configuration? What setup would you recommend?
Update: See vcs-home for various related links and at least five different ways of doing this. mr, a multi-repository VCS wrapper seems particularly well at this.

Craig Small: What happens without software testing

New TurboGears logo

Image via Wikipedia

Well jffnms 0.9.0 was a, well, its a good example of what can go wrong without adequate testing. Having it written in PHP makes it difficult to test, because you can have entire globs of code that are completely wrong but are not activated (because the if statement proves false for example) and you won t get an error. It also had some database migration problems. This is the most difficult and annoying part of releasing versions of JFFNMS. There are so many things to check, like: I ve been looking at sqlalchemy which is part of turbogears. It s a pretty impressive setup and lets you get on with writing your application and not mucking around with the low-level stuff. It s a bit of a steep learning curve learning python AND sqlalchemy AND turbogears but I ve got some rudimentary code running ok and its certainly worth it (python erroring on un-assigned varables but not forcing you to define them is a great compromise). The best thing is that you can develop on a sqlite database but deploy using mysql or postgresql with a minor change. Python and turbogears both emphasise automatic testing. Ideally the testing should cover all the code you write. The authors even suggest you write the test first then implement the feature. After chasing down several bugs, some of which I introduced fixing other bugs, automatic testing would make my life a lot easier and perhaps I wouldn t dread the release cycle so often.

1 June 2011

Vincent Bernat: GNOME Power Manager without GNOME desktop

When I installed my new laptop, I decided to switch from sleepd to GNOME Power Manager (GPM). The rationale behind this decision was to get screen dimming for free while keeping other features because GPM uses UPower which uses pm-suspend and pm-powersave behind the scene. This means that it is easy to execute scripts on suspend or when the AC is unplugged by putting them in /etc/pm. I don t use a full GNOME desktop. My desktop is running FVWM which is just a window manager. However, I already use some parts of the GNOME environment:

What s working It happens that most of the features just do not work. However, suspend when closing the lid works fine. The icon in the systray works fine too (but there is a small bug). The screen dimming feature on idle also works (but there are annoying bugs with it). The visual feedback when pressing brightness keys works too.

What s not working It seems that I am not the only one to have problem with GPM: there are currently 115 bugs opened in the Debian BTS. If you want to get some debug output from gnome-power-manager, run it with --verbose flag. --debug flag does nothing (and supersedes --verbose).

Nothing happens when pressing the power button I have configured GPM to ask me what to do when I press the power button. But when I press the button, nothing happens. Looking at the source, here is the snippet of code that is executed:
1
2
3
4
5
6
7
if (policy == GPM_ACTION_POLICY_INTERACTIVE)  
    GpmSession *session;
    egg_debug ("logout, reason: %s", reason);
    session = gpm_session_new ();
    gpm_session_logout (session);
    g_object_unref (session);
 
In fact, this is not GPM that will ask you the question, but GNOME session manager because GPM triggers logout. If you don t run a full GNOME session, nothing will happen. My workaround is just to set the action to Suspend .

Does not sleep when idle GPM is configured to go to sleep after 2 hours on AC or 30 minutes on battery. This does not work for me because idle detection is delegated to external programs. There are four variables used by GPM to determine if we are idle:
  • session_idle which is the idle hint from ConsoleKit,
  • idle_inhibited which is set when another program asks to disable idle detection (a video player which does not want the screen to be dimmed),
  • suspend_inhibited which means a program do not want we going to sleep (a music player for example)
  • x_idle which tells if X is idle or not (someone is moving the mouse or typing on the keyboard).
To allow GPM to suspend when we are idle, x_idle and session_idle must be true while suspend_inhibited and idle_inhibited must be false. For screen dimming purpose, you just need to have x_idle set to true and idle_inhibited set to false. Currently, only GNOME Screensaver seems to tell ConsoleKit if the session is idle or not. XScreenSaver does not contain anything about this. I am using xautolock with xlock and I am pretty sure they won t tell GPM if I am idle. You can use dbus-send to circumvent this problem:
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
$ dbus-send --system --dest=org.freedesktop.ConsoleKit \
>   --type=method_call --print-reply --reply-timeout=2000 \
>   /org/freedesktop/ConsoleKit/Manager \
>   org.freedesktop.ConsoleKit.Manager.GetCurrentSession
method return sender=:1.6 -> dest=:1.106 reply_serial=2
   object path "/org/freedesktop/ConsoleKit/Session1"
$ dbus-send --system --dest=org.freedesktop.ConsoleKit \
>   --type=method_call --print-reply --reply-timeout=2000 \
>   /org/freedesktop/ConsoleKit/Session1 \
>   org.freedesktop.ConsoleKit.Session.SetIdleHint boolean:true          
method return sender=:1.6 -> dest=:1.108 reply_serial=2
While I understand what is the rationale behind those choices (no code duplicate and allowing external programs to hinder power management), it lacks some fallback in case you don t use GNOME Screensaver (which is the key component here). I first though this was bug #594706 but this is not the case. I have opened (and closed) bug #628755. UPDATED: Jump to the conclusion for an updated solution for this problem.

Brightness is not restored to the previous value after idle When GPM undims the screen, it does not restore the previous value. It seems to be bug #617310 which is marked as fixed in upstream. I did not investigate it.

Wrong number of batteries reported I only have one battery but after one suspend/resume cycle, GPM thinks I have two. Maybe this is a bug of UPower. Maybe this is bug #606434. I did not investigate it. Maybe there is an happy interaction with bug #456280.

Inability to set configure actions when the UPS runs out of battery This is bug #390602. In addition to laptop batteries, UPower also supports UPS. In this case, GPM displays a special icon to tell if the UPS is fully charged. However, there is no possibility to execute special actions when the UPS is unplugged, like hibernate after 10 minutes or something like this. This seems to be a problem with the interface because looking with gconftool-2, we can spot variables like low_ups or critical_ups which allow to set actions when the UPS is almost out of battery. Moreover, the UPS icon only displays after one suspend/resume cycle but I am too lazy to report and debug this issue. Since, the icon disappear if I restart GPM, I am confident that the bug is in GPM.

Conclusion The conclusion is that GPM is not really that buggy but it really needs to be run in a full-blown GNOME desktop. The main problem is not really GPM. New technologies like UPower and ConsoleKit get pushed by freedesktop.org initiative, they get implemented by GNOME (and, I suppose, KDE) because they have tons of people following the appropriate mailing lists and any alternative just gets crushed by all those unpublicized changes. UPDATED: I got several helpful comments about this problem. There are two possible solutions:
  1. Use xfce4-power-manager. It handles brightness control in a better way and don t need an external program to tell when the current session is idle. It still needs a session manager to ask what to do when using the power button. The drawback to this solution is that you start to pull another desktop environment into your environment. You had some parts of GNOME and now you have some parts of XFCE. This solution was proposed by Sylvain Collilieux.
  2. Use gnome-session, gnome-screensaver and keep gnome-power-manager. As pointed by Julien Valroff, gnome-screensaver needs gnome-session to detect idleness. However, gnome-session starts a whole GNOME desktop. Again, there are two solutions. The first one is to replace gnome-session by something lighter implementing the bare minimum to make gnome-screensaver happy. Another suggestion is to configure gnome-session to start your favorite environment.
I start mine from ~/.xsession and here is what I have added at the top of it:
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
# If not done, restart ourself with gnome-session
if [ -z "$SESSION_MANAGER" ]; then
    [ -d ~/.config/autostart ]   mkdir ~/.config/autostart
    rm -f ~/.config/autostart/*
    cat <<EOF > ~/.config/autostart/xsession.desktop
[Desktop Entry]
Name=Xsession
Comment=Start .xsession
Exec=$(readlink -f $0)
Type=Application
X-GNOME-Autostart-enabled=true
EOF
    exec gnome-session --autostart=$HOME/.config/autostart
fi
# Otherwise, keep starting stuff
# [...]
exec fvwm-crystal

31 May 2011

Jordi Mallach: Quinze de maig

Two weeks ago, I was lucky to celebrate my 33th birthday with my closest friends in l'Alqueria. When asked to wish something before blowing the candles on Victor's delicious apple cake, I thought I have basically everything I'd want, but it'd be cool if some real changes happened in this world. Not long after, big demonstrations asking for Real Democracy Now happened throughout the Spanish state, and today, that Sunday seems to be an eternity away. Huge assemblies, thousands of strangers working together, more demonstrations, an election campaign eclipsed by #15m, hundreds of well thought, plausible claims published, the movement crossing the Spanish borders and leaking into France and Greece, the feeling that this is the good one, the basis for a fresh start that can make our lives better, our society a fair one and the possibility to stand in front of the fuckers who have made our lives a lot harder, to tell them it's not going to work like that anymore. All of this in 15 days. Unfortunately, revolution came when I'm in a crucial month to finish my studies and swamped with other little things, so I've been unable to be in the Valencian camp site for more than 3 days. Hopefully when I'm done on the 22nd people will still be taking the square, because Mako and Mika will be visiting then. Yay!

Jamie McClelland: Puppet Without Masters

Puppet labs's use of the term puppetmaster is rather clever (in contrast to other un-necessarily offensive uses of "master" in the software world). While I appreciate the clever name, I'm less impressed with the concept. At May First/People Link we've spent the last several years (including the last couple months in earnest) working to transition management of our 90-some servers from a collection of hand-written bash scripts to puppet. Over the years, we've worked hard to keep our servers as secure as possible. We have a team of about a half dozen people who all have root access on all servers. It's all key-based access. To help mitigate a disaster if one person's keys were compromised, we've implemented monkeysphere on all servers, allowing us to easily revoke access. After spending so much time thinking through our root-access strategy and fully implementing the monkeysphere to reduce our exposure to a single point of vulnerability, I was disappointed by puppet's use of a puppet master. For those less familiar with puppet, it goes something like this: One server (or god forbid multiple servers), run an externally accessible daemon. Each and every server on your network runs a daemon as root that periodically communicates with the puppet master, receives new instructions, and then (again, as root) executes these instructions. In other words, if your puppet master is compromised, I'm not sure exactly what you would need to do, short of rebuilding every server in your network. To make matters worse, it seems as though some users generate and store all server ssh keys (private and public) on the puppet master and then push the private keys to their respective nodes. That means an intruder doesn't need to write to the puppet master, just reading these keys would be enough to compromise all servers in your network. There must be a better way. Puppet without masters After some web-searching, I found a promising thread on the puppet list asking what's lost without a puppet master. This thread lead to a couple other blogs by people who have worked out a system for using puppet without a master. It turns out that there are two distinct points of centralization with puppet. One is the puppet master (as described above). In addition, there is a concept called storeconfigs - which allows each node in the network to store information in a central database. For example, one server can store a request for an account to be setup on a backup server. The next time the backup server runs, it checks the storeconfigs, finds the request, and creates the user. It's possible to run puppet with storeconfigs but without running a puppet master (that avoids the hassle of running the puppet daemons, while providing the convenience of centralization). For our purposes, however, we decided to forego both the puppet master and storeconfigs. We did not want any form of centralization that would provide an additional point of vulnerability. As is common with puppet, we are storing our puppet recipes in a git repository. And, we are publishing to a single, canonical git repository on the Internet. On each node, we have two git repositories - one is a bare repo (that we can push to) and the other is a checked out repo (in /etc/puppet) that is read by puppet. The bare repo has a post-update hook the changes into the /etc/puppet directory, pulls in the changes from the bare repository, and runs puppet against the newly checked out files. Therefore, we can apply new puppet recipes to any server on the network with
git push <server>
No daemons: neither a master daemon nor a puppet daemon running on the node using up memory or providing a potential security hole. The git push happens over an ssh connection - since all system administrators already have root-level ssh access on every server - there is no need to grant any additional access above what we already have. Pushing works great - but with 90 nodes we don't want to have to push to 90 servers everytime we want a change made. That's where the canonical git repository comes in. A cron job runs a script on each node once an hour that runs git remote update from /etc/puppet. The script then checks the time stamp on the most recent gpg-signed tag and compares it with the time stamp of the current commit. If the most recent gpg-signed tag is newer, it verifies that the tag came from a list of authorized gpg keys (the very same gpg keys used by the monkeysphere to grant root level ssh access). If the gpg signature of the tag can be properly verified, then the changes are merged and puppet is run on the new recipes. What about privacy? One of the benefits of a puppet master setup is that nodes get configuration details on a need-to-know basis. The puppet master doesn't share the entire puppet repo - only the compiled manifest for the node with which it's communicating. Our solution to this problem was to go screaming in the other direction. As you might notice from our support wiki and ticket system, we generally favor transparency. Since we are publishing our entire puppet git repo publicly, there seems little point in trying to hide one node's configuration details from another node. That also means each node carries around about 4Mb of extra weight in the form of disk space for the git repo. That seems like a small price to pay for the resource savings of not running a puppetd process all the time. More differences As I've read the puppet lists, faqs and documentation, I've found yet more ways our use of puppet diverges from the norm. The first is a little thing really - most people seem to store all their node configurations in a single nodes.pp file. I'm not sure why. Fortunately, puppet's include syntax allows globbing, so we've created a directory and gave each server it's own .pp file. This arrangement makes it much easier to parse the configuration with tools other than puppet (like, Q. How many servers do we have? A. ls wc -l). Backup and Nagios monitoring without storeconfigs More significantly - there are some things we can't do since we are not using storeconfigs. While many puppet users add a variable, like $nagios = true before including their sshd class (which then causes the sshd class to store a configuration for the nagios server to monitor ssh on the node in question), we were forced to come up with alternatives. My first solution was to simply list all the servers that needed to be monitored in the server node configuration file for the nagios server. Ditto for the backup servers. This approach, however, proved cumbersome and error prone. When adding a new node, I now have to edit three files instead of one. And, how can I easily tell if all nodes have their nagios and/or backup configurations set? The solution was rather simple - there's more than one way to store a config for another node. Our nagios server is called jojobe.mayfirst.org and our backup server is luisa.mayfirst.org. A typical node.pp file looks like this:
node pietri.mayfirst.org  
  # node config goes here
 
if ( $fqdn == "jojobe.mayfirst.org )  
  nagios_montior   "pietri":  
 
if ( $fqdn == "luisa.mayfirst.org )  
  backup_access   "pietri":  
 
This way all configuration related to pietri stays in a single file. Host keys and granting access between servers storeconfigs is commonly used to distribute host ssh keys. Every node that is added to puppet has it's ssh host key stored centrally and then re-distributed to every other node. That way, you can ssh from node to node without ever getting the ssh fingerprint verification. Avoiding that prompt is particularly important when backing up from one server to another via automated scripts. storeconfigs can additionally be used to copy user's public ssh keys - thus granting user access between servers. Our solution to this problem: monkeysphere. Rather than maintaining our own private data store of keys, we publish (and sign) our ssh keys via the web of trust. In addition to server keys, each one of our servers' root user has an ssh-enabled gpg key (also publicly signed by us). By configuring each server to trust our system administrators' gpg keys for verifying other keys, we can both avoid the ssh fingerprint manual verification step and we can grant a root user on one server access to another server by simply dropping root@$server.mayfirst.org into an authorizeduserids file on the target server. There's no question - the setup was rather tedious (we're using runit to maintain an ssh-agent for each root user), however, now that's in place (and configured via puppet), it's a breeze to add new servers. The only extra step we have to take is to confirm and sign each new server's keys. This "extra" step not only allows our servers to verify each other, but also allows our users to verify the servers as well, so it's hardly an extra step at all. Shared modules There's a vibrant community of third party module developers for puppet. Rather than figure out the intricacies of having puppet configure sshd, for example, you can install a contributed sshd module and then you simply add:
include sshd
And you get a default sshd setup. Many of these modules are fairly well developed, offering the ability to easily customize your setup in a number of different ways. Unfortunately, most of the modules assume you are using storeconfigs and if you are not, they will either fail to work right or you will get noisy errors. At first, this seemed like a problem. However, as I built our puppet recipes, I found myself increasingly frustrated with the third party modules that we could use. Configuring servers is hard - and requires constant debugging and trouble shooting. puppet already provides a layer of abstraction between you and the server you are setting up. Given the benefits of puppet, I'm willing to spend the time learning the puppet syntax and asking the rest of our system administrators to do the same. This layer of abstraction is further compounded by our use of git to store the configurations (not a problem if you are git hero - but most of us are already struggling to get a handle on using git). Again, all seems worth it for the pay off. Now enter the puppet module. In addition to learning puppet syntax (and struggling with git) you now need to understand how the third party module works. With software programming, I typically don't need or want to learn how a library or class does what it does - that's the beauty of object-oriented programming: it hides the complexity. But when it comes to configuring the servers that I will be responsible for debugging and maintaining, I really need to know exactly what is happening. To further compound the problem, I found myself wading through third party module code designed to work on Debian, Ubuntu, CentOS, Redhat, gentoo... and more. We run entirely on Debian - we don't need any of this extra code. And, once I got rid of all the other operating systems, I was still left with a complex module that allows you to configure software in ways we'll never need. In the end, we tore out most of these third party modules and replaced them with file and exec puppet resources that did exactly what we needed them to do. Our code base is now much smaller and simpler. Not just a whiner I have a lot more to whine about (like why native resources for things like nagios that are so easily handled with the file resource?). However - the remarkable thing about puppet is that it's flexible. Despite some fairly substantial problems with the "typical" use of puppet, the program provides enough flexibility for us to use it in a way that fully meets our needs. After having built my own bash-based set of configuration scripts and deeply exploring puppet, I have a great appreciation for the difficulty of building system configuration software (we considered and rejected cf-engine and chef as not being any better). And, if you are still not convinced that puppet will work fo you ... you might consider a package I learned about after going down the puppet route: slack.

Next.

Previous.