Search Results: "will"

21 February 2014

Joey Hess: subverting hierarchy with git

Did you ever want to be able to tag your files, and use the tags to query and select the files you want? For many sorts of files we use, this is clearly better than being locked into a single hierarchial view of nested directories. Semantic file systems are a way to do things like this. But that's an entire separate filesystem, often implemented as a FUSE layer. I have never wanted tagging enough to take on that layer of complications. A week ago I realized that there was a way to do this without using an entirely separate filesystem. When we use git, we're used to having different views of our files, called branches, that we switch between. What then, if a git branch were generated from tags and other metadata that meet a query, providing a custom view that meet the user's current needs and could be incrementally refined. Here's a short screencast demoing these views.
And here's a walkthrough for setting it up. To build this, I needed a nice way to store metadata in git, and since git-annex happens to have a very nice way of using git as a database, I naturally built it on top of git-annex. This means that the tags and other metadata are automatically synchronized between different clones of the repository. Multiple users can be tagging and setting other metadata at the same time, and their changes will merge in a consistent way. I have a long list of things to do to fully integrate views into git-annex. However, they're already basically usable, and I'm very pleased with how these dymanic views of the contents of a repository are working out. Today's release of git-annex includes views support, so give them a try!

Vasudev Kamath: Kontalk FLOSS alternative for Whatsapp and Co.

So Whatsapp has been acquired by Facebook and this news is still hot and people are discussing it all over the twitterverse. So I took this opportunity to stop using Whatsapp and removed it from my phone. Possibly I could have deleted my account but who cares. Anyway I've been searching for a secure and FLOSS alternative for Whatsapp for quite some time now, few days ago I found about Telegram but after reading post by Tincho on planet Debian, I decided not to use it. Recently while going through the talk list for fossmeet.in I found link for Kontalk in a privacy awareness talk proposal by Praveen and thought I should give it a try. So below is my first feelings about Kontalk.
Installation and Activation Kontalk can be installed from playstore for verification purpose it requests your phone number and country code and request for verification. This should send a SMS with a code which should be entered in the text box given and app is ready to use. There is also a possibility to use pre-existing verification code (if you got one from developer directly, read below for details). I did see some glitches like I never got the SMS delivered to my phone after 2 attempts and a days wait. Then I went ahead and reported a bug and the main developer was quick to respond. After a discussion it was noticed that SMS was blocked by spam filters. He also mentioned its tough to get SMS delivered to India. He was kind enough to provide me with a verification code and I used the Use existing code option to enter it and get Kontalk activated. The SMS delivery inconsistency is still present for India (and may be other nations too) some people get code immidiately others may be after couple of days and some might not. Upstream is already working on a possible workaround.
User Experience Now coming to usage part, the UI is neat and clean, I won't say super polished as Whatsapp or other popular apps but its really neat and easy to use. Some points which I like are
  • Ability to hide presence, so others won't know you are online or offline. (unlike Whatsapp which advertises last seen)
  • Encrypted messages and ability to optin or optout.
  • Encrypted status messages! Only user with your phone number can see your status. (Cool isn't it).
  • Manually requesting to find contacts who already uses kontalk!. Right it doesn't read your contact list without your permission you need to refresh to check who in your contacts is using Kontalk.
  • Attach and smiley options in the top right corner of Chat window which allows easy accessing unlike keyboard - smiley switching of Whatsapp.
  • No automatic download of media contents which is shared. Yes by default it doesn't download any picture or video automatically if you want to see something click on it and select download.
  • Running your own server for Kontalk! Now thats something which is interesting for people who doesn't want to host their data on some other peoples infrastructure. Code for server is available at xmppserver repo.
But there are some rough edges also but I'm sure this can be improved. But some points which I noticed are
  • Contact name disappears and only number is displayed. This is something which happened with one of my contact so I'm not really sure its a bug.
  • My friend noticed all his existing contacts suddenly vanished when he refreshed contacts list. Again this is possible bugs and we are considering reporting it upstream.
  • No group chats yet. I don't see a option to do that yet.
  • Attachment at the moment is restricted only to pictures (and video? never tried) and uploading takes quite sometime and sometime hangs forever.
So I'm considering forwarding these to upstream and help them by providing enough data so these can be fixed.
Technical Side All code for client server and protocol specs are available under GPL-v3 at the Kontalk project site. Server software is written in Python and I guess uses XMPP (but I've not cross verified). Server also uses MySQL as database. These can be hosted on our own servers but possibly needs more than that like SMS sending options etc.
Conclusion In my views Kontalk can become a great alternative for Whatsapp and co from Free Software world and I encourage every one to give it a try which will be the first step to help improving it.
Disclaimer: I'm not a privacy or security expert so whatever I shared above are what I noticed and experts may see something different than this. In any case I welcome comments and suggestions.

20 February 2014

Francois Marier: Hardening ssh Servers

Basic configuration There are a few basic things that most admins will already know (and that tiger will warn you about if you forget):
  • only allow version 2 of the protocol
  • disable root logins
  • disable password authentication
This is what /etc/ssh/sshd_config should contain:
Protocol 2
PasswordAuthentication no
PermitRootLogin no

Whitelist approach to giving users ssh access To ensure that only a few users have ssh access to the server and that newly created users don't have it enabled by default, create a new group:
addgroup sshuser
and then add the relevant users to it:
adduser francois sshuser
Finally, add this to /etc/ssh/sshd_config:
AllowGroups sshuser

Deterring brute-force (or dictionary) attacks One way to ban attackers who try to brute-force your ssh server is to install the fail2ban package. It keeps an eye on the ssh log file (/var/log/auth.log) and temporarily blocks IP addresses after a number of failed login attempts. Another approach is to hide the ssh service using Single-Packet Authentication. I have fwknop installed on some of my servers and use small wrapper scripts to connect to them.

Using restricted shells For those users who only need an ssh account on the server in order to transfer files (using scp or rsync), it's a good idea to set their shell (via chsh) to a restricted one like rssh. Should they attempt to log into the server, these users will be greeted with the following error message:
This account is restricted by rssh.
Allowed commands: rsync 
If you believe this is in error, please contact your system administrator.
Connection to server.example.com closed.

Restricting authorized keys to certain IP addresses In addition to listing all of the public keys that are allowed to log into a user account, the ~/.ssh/authorized_keys file also allows (as the man page points out) a user to impose a number of restrictions. Perhaps the most useful option is from which allows a user to restrict the IP addresses which can login using a specific key. Here's what one of my authorized_keys looks like:
from="192.0.2.2" ssh-rsa AAAAB3Nz...zvCn bot@example
You may also want to include the following options to each entry: no-X11-forwarding, no-user-rc, no-pty, no-agent-forwarding and no-port-forwarding.

Increasing the amount of logging The first thing I'd recommend is to increase the level of verbosity in /etc/ssh/sshd_config:
LogLevel VERBOSE
which will, amongst other things, log the fingerprints of keys used to login:
sshd: Connection from 192.0.2.2 port 39671
sshd: Found matching RSA key: de:ad:be:ef:ca:fe
sshd: Postponed publickey for francois from 192.0.2.2 port 39671 ssh2 [preauth]
sshd: Accepted publickey for francois from 192.0.2.2 port 39671 ssh2 
Secondly, if you run logcheck and would like to whitelist the "Accepted publickey" messages on your server, you'll have to start by deleting the first line of /etc/logcheck/ignore.d.server/sshd. Then you can add an entry for all of the usernames and IP addresses that you expect to see. Finally, it is also possible to log all commands issued by a specific user over ssh by enabling the pam_tty_audit module in /etc/pam.d/sshd:
session required pam_tty_audit.so enable=francois
However this module is not included in wheezy and has only recently been re-added to Debian.

Identitying stolen keys One thing I'd love to have is a way to identify a stolen public key. Given the IP restrictions described above, if a public key is stolen and used from a different IP, I will see something like this in /var/log/auth.log:
sshd: Connection from 198.51.100.10 port 39492
sshd: Authentication tried for francois with correct key but not from a permitted host (host=198.51.100.10, ip=198.51.100.10).
sshd: Failed publickey for francois from 198.51.100.10 port 39492 ssh2
sshd: Connection closed by 198.51.100.10 [preauth]
So I can get the IP address of the attacker (likely to be a random VPS or a Tor exit node), but unfortunately, the key fingerprints don't appear for failed connections like they do for successful ones. So I don't know which key to revoke. Is there any way to identify which key was used in a failed login attempt or is the solution to only ever have a single public key in each authorized_keys file and create a separate user account for each user?

19 February 2014

Neil McGovern: +++ BREAKING Debian 9.0 codename

A source close to the Debian Project has informed me that the project will break from it s long running tradition of Pixar codenames for their releases.
Going further than this, in what is surely a contentious move, the project will also use multi-worded code names. This is as they feel jealous of the extra exposure that Ubuntu and Fedora have with double barrelled release names.
Thus, the next version of Debian will actually be called Debian 8dot0 phoronoix-will-believe-anything . For those without a satirical radar, this may all be a complete lie

Michael Stapelberg: Using your TPM for SSH authentication

Thomas Habets has blogged about using your TPM (Trusted Platform Module) for SSH authentication a few weeks ago. We worked together to get his package simple-tpm-pk11 into Debian, and it has just arrived in unstable :-). Using simple-tpm-pk11, you can let your TPM generate a key, which you then can use for SSH authentication. This key will never leave the TPM, so it is safer than having your key on the filesystem (e.g. ~/.ssh/id_rsa), since file system access is not enough to steal your key anymore. Instead, you ll need remote code execution. To use this software, first make sure your TPM is enabled in the BIOS. In my ThinkPad X200 from 2008, the TPM is called Security Chip . Afterwards, claim ownership of your TPM using tpm_takeownership -z (from the tpm-tools package) and enter a password. You will not need to enter this password for every SSH authentication later (but you may choose to set a separate password for that). Then, install simple-tpm-pk11, create a key, set it as your PKCS11Provider and install the public key on the host(s) where you want to use it:
mkdir ~/.simple-tpm-pk11
stpm-keygen -o ~/.simple-tpm-pk11/my.key
echo key my.key > ~/.simple-tpm-pk11/config
echo -e "\nHost *\n    PKCS11Provider libsimple-tpm-pk11.so" >> ~/.ssh/config
ssh-keygen -D libsimple-tpm-pk11.so   ssh shell.example.com tee -a .ssh/authorized_keys
You ll now be able to ssh into shell.example.com without having the key for that on your file system :-). In case you have any feedback about/troubles with the software, please feel free to contact Thomas directly.

Andrew Pollock: [life] Day 22, Kindergarten, cleaning and Officeworks outing

Today was my "clean the house" day. I also had a chiropractic adjustment first thing, and a massage before lunch. I biked to Kindergarten to pick up Zoe, and found her holding court with a bunch of her classmates, giving a show and tell session about the Cinderella snow globe and echidna plush toy she'd taken to Kindergarten. The kids were taking turns to raise their hand and ask questions. I was out of earshot, so I couldn't really make out what was being said, but it all looked very cute from where I was standing. She didn't have a nap today. Sarah's going down to Tasmania until early next month, hiking, and so I've got Zoe for the next 12 nights. This is the longest she will have been away from her mother by quite a significant amount. On top of this, she's been doing rather poorly at bedtime with me the last few nights I've had her. I wanted to try and minimise the emotional impact for both of us as much as possible, so I wanted to make an Advent-style calendar to count down the number of sleeps until Mummy got back. After we got home from Kindergarten, we drove over to Officeworks to pick up some bits and pieces. It ended up being quite a long outing because it took a while for me to figure out how to convince the self-service photo printing kiosk to actually print photos. Zoe parked herself in the kid's colouring area, and she was quite happy there while I went looking for a few things, but after a while wandered off to find me and we spent some time looking for each other. I was pretty impressed with how well she went looking for me. She didn't freak out, and was just wandering around the store looking for me. We had a talk about staying put. Then we called grandma from the carpark to wish her a happy birthday before we headed home. That ended up being quite a lengthy outing, and I started dinner as soon as we got home. Bedtime actually went quite smoothly tonight for a change. No idea if the poster or the lack of a nap helped or not.

18 February 2014

Thomas Koch: Waiting for a STATE folder in the XDG basedir spec

The XDG Basedirectory specification proposes default homedir folders for the categories DATA (~/.local/share), CONFIG (~/.config) and CACHE (~/.cache). One category however is missing: STATE. This category has been requested several times but nothing happened.
Examples for state data are:
The missing STATE category is especially annoying if you're managing your dotfiles with a VCS (e.g. via VCSH) and you care to keep your homedir tidy.
If you're as annoyed as me about the missing STATE category, please voice your opinion on the XDG mailing list.
Of course it's a very long way until applications really use such a STATE directory. But without a common standard it will never happen.

Margarita Manterola: MiniDebConf 2014 Barcelona

Debian Women is proud to announce that it will hold a MiniDebConf in Barcelona on 15-16 March 2014, where Debian enthusiasts from far and wide will gather to talk about the latest Debian changes and the Debian community, as well as to meet new and old friends. The MiniDebConf is fast approaching, be sure to make your travel arrangements! It is going to be an exciting event, in a beautiful venue, in one of the most famous European cities! Schedule A draft schedule (still subject to some last minute changes) is already available. The list of talks promises two days packed with great talks! If you have an exciting idea for a talk, but missed the deadline, please get in touch with us, we might still have a slot for you. Crowd-funding We are still raising funds to cover the costs of running the conference and to offer travel sponsorship to people who can't pay for it. Please, consider donating any amount you can, everything helps! Sponsorship If you want to attend the conference, but are unable to cover the costs. Please contact us! We don't have a big budget, but we will make our best to help. Naturally, priority will be given to participants who have an accepted talk. About this MiniDebConf We want to have a MiniDebConf with both talks and social events, to which everyone in Debian is invited but where the speakers in the talks are all people who identify themselves as female. We consider this important to The idea behind the conference is not to talk about women in free software, or women in Debian, but rather to make discussion about Debian subjects more inclusive for women. If you agree with this goal, spread the word. Forward this announcement and help us make this event a great success! About our sponsors This event is possible thanks to the help provided by our generous sponsors. In particular, we'd like to thank our platinum sponsor, Google. We hope to see you in Barcelona! For more information, visit http://bcn2014.mini.debconf.org

Mario Lang: Conntributing on GitHub

I really like to read code written by different people. I've always been the type of learner that can cover a lot of ground by looking at examples. A few of the programming tricks I acquired over time have definitely been learnt by reading programs written by other people. There are of course cases of disagrement with coding style (lets put that very mildly), so not every project is fun to read. But I tend to find projects I like enough to actually look at their source code. Now, if you get into this habit, there is also the occasional spotting of a bug. Many are really cosmetic, like typos in comments or documentation. Others are maybe more serious, who knows what can happen if you read a few lines of code written by someone you have never met in person. This is one of the original arguments of open source and free software. It basically goes like: "People will read your code and report problems." I know that happens, but I also know that there are cases of people finding relatively minor things during a small code review, which they don't report, or which get lost in some developers INBOX. I remember waiting months to see memory corruption fixes for a particular project I submitted by email to actually appear in the development repository. In some cases you really need to track your patches and prod someone to remind them about your contribution if need be. True, some of these issues are probably minor enough to not really hurt if they get lost, but I have a feel that a lot of minor things also sort of add up. This is where GitHub comes into play. We have had project hosting services since at least a decade now, but none of them (to my experience) have ever made it so easy for all involved parties to submit and merge changes into projects. Pull requests are just amazing. Well, at least for me, they are since a few months. I have a sort of mixed hate-love relationship with GitHub when it comes to a topic that is very important to me, Accessibility. The last project hosting site I really liked for their simple web interface (read, still usable with Lynx) was Google Code. That was in the days when Google still seemed to care about such things. These days, their newer services are next to unusable to me (with the tools I prefer). SourceForge was always a catastrophy. Many things were cumbersome to do, because the site is so loaded with links to all sorts of things I never need. However, at the time I was using it, all the things I really needed did work. GitHub is a different beast, in a different era of the internet. While I can read project pages and a few basic things perfectly fine, some parts of the GitHub site are simply unusable for no particular reason. For instance, I can edit (some of my) preferences and even save them. But I can not star a project, nor can I follow other developers. Invoking these links gives me a 404, which seems to indicate that some JavaScript (read, client side code execution) is required which my browser does not perform. However, I really wonder why. Because something like "I want to star this project" will eventually have to end up as a request on the server anyway, so it seems technically unnecessary to rely on Javascript for such an operation to succeed. Luckily, these days, hip projects do have an API. An GitHub is no exception. I want to emphasis that an API alone is not an accessibility fix, since you rarely have the time to implement a clinet for a random API, just to get access to a service you want to use. Sometimes you do, and an API is a great enabler in such situations, but a reference client with a rich feature-set is much better. I have to admit that I haven't evaluated any of the possible alternatives, but one client I found for GitHub's API did really boost my productivity in the last year. I am talking about Hub. It is a simple wrapper around Git that adds a few and enhances some other git commands. Most importantly, hub fork will fork the current checkout on GitHub, and hub pull-request allows you to quickly (and I really mean quickly!) open a pull request for some commits you've just done to your fork of some project. This is very helpful, and very accessible. While it does not solve all my accessibility problems with GitHub, it at least enables me to take part in the GitHub workflow. I can easily fork projects and submit pull reuqests for changes I did. And that is what I did, at least a bit, in roughly the past year. I am not sure exactly, but I think it was spring when someone made me aware of Hub. One approach would be to check my GitHub activity graph, but I probably don't have to mention that it is not accessible. Here is a list of some of my contributions to open source projects on GitHub since I discovered a good client for the GitHub API: To summarize: I love GitHub for what it does to the free software community. I think the simplicity (and transparency) of contributions is to the benefit of free and open source software. However, I also hate GitHub sometimes when I need to ask a friend to do relatively trivial changes for me. What I actually want, is a command-line client like Hub that makes most or even all functionality provided on the website available. True, some things like graphs are not immediately easy to adapt. But I really shouldn't need to use a modern full-fledged web browser to tell GitHub that I am interested in the activities of a certain user. Or delete a fork. Yes, thats right. I can use Hub to fork a project, but there is no way to delete it again. Sort of strange for casual small-scale contributions. I guess the workflow there is: fork, commit, pull-request, wait for merge, delete. I don't want to have all sorts of forks on GitHub that I actually don't actively use/maintain. So once a pull request was merged, and I don't have any other things I am working on right now, I actually want to get rid of the fork again. It is easy enough to do a fork should I ever need it again.

Mario Lang: Contributing on GitHub

I really like to read code written by different people. I've always been the type of learner that can cover a lot of ground by looking at examples. A few of the programming tricks I acquired over time have definitely been learnt by reading programs written by other people. There are of course cases of disagrement with coding style (lets put that very mildly), so not every project is fun to read. But I tend to find projects I like enough to actually look at their source code. Now, if you get into this habit, there is also the occasional spotting of a bug. Many are really cosmetic, like typos in comments or documentation. Others are maybe more serious, who knows what can happen if you read a few lines of code written by someone you have never met in person. This is one of the original arguments of open source and free software. It basically goes like: "People will read your code and report problems." I know that happens, but I also know that there are cases of people finding relatively minor things during a small code review, which they don't report, or which get lost in some developers INBOX. I remember waiting months to see memory corruption fixes for a particular project I submitted by email to actually appear in the development repository. In some cases you really need to track your patches and prod someone to remind them about your contribution if need be. True, some of these issues are probably minor enough to not really hurt if they get lost, but I have a feel that a lot of minor things also sort of add up. This is where GitHub comes into play. We have had project hosting services since at least a decade now, but none of them (to my experience) have ever made it so easy for all involved parties to submit and merge changes into projects. Pull requests are just amazing. Well, at least for me, they are since a few months. I have a sort of mixed hate-love relationship with GitHub when it comes to a topic that is very important to me, Accessibility. The last project hosting site I really liked for their simple web interface (read, still usable with Lynx) was Google Code. That was in the days when Google still seemed to care about such things. These days, their newer services are next to unusable to me (with the tools I prefer). SourceForge was always a catastrophy. Many things were cumbersome to do, because the site is so loaded with links to all sorts of things I never need. However, at the time I was using it, all the things I really needed did work. GitHub is a different beast, in a different era of the internet. While I can read project pages and a few basic things perfectly fine, some parts of the GitHub site are simply unusable for no particular reason. For instance, I can edit (some of my) preferences and even save them. But I can not star a project, nor can I follow other developers. Invoking these links gives me a 404, which seems to indicate that some JavaScript (read, client side code execution) is required which my browser does not perform. However, I really wonder why. Because something like "I want to star this project" will eventually have to end up as a request on the server anyway, so it seems technically unnecessary to rely on Javascript for such an operation to succeed. Luckily, these days, hip projects do have an API. An GitHub is no exception. I want to emphasis that an API alone is not an accessibility fix, since you rarely have the time to implement a clinet for a random API, just to get access to a service you want to use. Sometimes you do, and an API is a great enabler in such situations, but a reference client with a rich feature-set is much better. I have to admit that I haven't evaluated any of the possible alternatives, but one client I found for GitHub's API did really boost my productivity in the last year. I am talking about Hub. It is a simple wrapper around Git that adds a few and enhances some other git commands. Most importantly, hub fork will fork the current checkout on GitHub, and hub pull-request allows you to quickly (and I really mean quickly!) open a pull request for some commits you've just done to your fork of some project. This is very helpful, and very accessible. While it does not solve all my accessibility problems with GitHub, it at least enables me to take part in the GitHub workflow. I can easily fork projects and submit pull reuqests for changes I did. And that is what I did, at least a bit, in roughly the past year. I am not sure exactly, but I think it was spring when someone made me aware of Hub. One approach would be to check my GitHub activity graph, but I probably don't have to mention that it is not accessible. Here is a list of some of my contributions to open source projects on GitHub since I discovered a good client for the GitHub API: To summarize: I love GitHub for what it does to the free software community. I think the simplicity (and transparency) of contributions is to the benefit of free and open source software. However, I also hate GitHub sometimes when I need to ask a friend to do relatively trivial changes for me. What I actually want, is a command-line client like Hub that makes most or even all functionality provided on the website available. True, some things like graphs are not immediately easy to adapt. But I really shouldn't need to use a modern full-fledged web browser to tell GitHub that I am interested in the activities of a certain user. Or delete a fork. Yes, thats right. I can use Hub to fork a project, but there is no way to delete it again. Sort of strange for casual small-scale contributions. I guess the workflow there is: fork, commit, pull-request, wait for merge, delete. I don't want to have all sorts of forks on GitHub that I actually don't actively use/maintain. So once a pull request was merged, and I don't have any other things I am working on right now, I actually want to get rid of the fork again. It is easy enough to do a fork should I ever need it again.

17 February 2014

Chris Lamb: The effect of pedestaling on TT bike position

To "pedestal" an aerobar means to elevate the bars above the basebar using risers instead of using headset spacers:
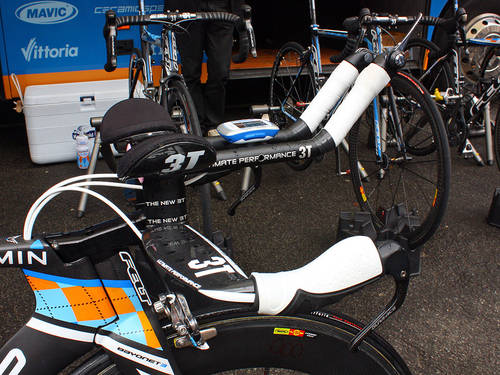
https://chris-lamb.co.uk/wp-content/2014/pedestal1.jpg

David Millar, 2010 Giro d'Italia.

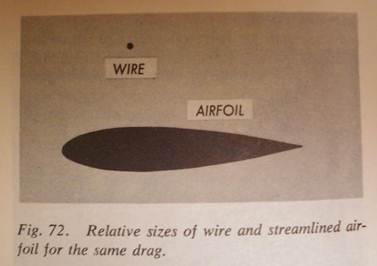
You might do this for a few reasons: https://chris-lamb.co.uk/wp-content/2014/teardrop_vs_cylinder.jpg So, assuming you currently have a bike that uses headset spacers, what would be the effect on your position if you were to replace, say, a 10mm headset spacer with a 10mm armrest riser? First, let us consider the effect of removing the headset spacer. The crucial insight is that removing a 10mm spacer will not lower the stack height ie. the vertical distance relative to the bottom bracket by 10mm. This is because spacers are not oriented perpendicular to the ground; they are stacked along the steerer tube at the head tube angle of the frame. We will assume a head tube angle of 72.5 degrees. We can calculate that removing a 10mm spacer will reduce the stack height by:
sin(72.5 )   10mm = 9.54mm
... and by the same argument it will also increase the effective reach ie. the horizontal distance relative to the bottom bracket by:
cos(72.5 )   10mm = 3.01mm
Next, let us consider the impact of adding the riser. These are oriented perpendicular to the ground, so its addition makes no further change to the reach. However, we can now calculate the overall change in stack height:
  stack = -(sin(72.5 )   10mm) + 10mm = 0.46mm
We can then repeat the calculation for any length of replacement:
Replacement (mm) stack (mm) reach (mm)
10 +0.46 +3.01
20 +0.93 +6.01
30 +1.39 +9.02
40 +1.85 +12.0
50 +2.31 +15.0
60 +2.78 +18.0
From this table, I can discover that if I were to replace 30mm of headset spacers with 30mm of risers it would:
  1. Increase my effective stack height by 1.39mm (likely neglible).
  2. Increase my reach by 9.02mm. This might require me to use a shorter stem to get the same position. If that was undesirable for example, if was already using an extremely short stem I might be forced to abandon the idea altogether.
Three further considerations must be noted:
  1. The resultant low height of the base bar could be quite drastic and prevent you breathing properly whilst climbing.
  2. Having the steerer tube cut down after to removing headset spacers will reduce the resale value of your bike.
  3. You might need to re-cable your brakes as you may have changed the distance the cables must span.
(It may seem odd to provide results for up to 60mm of headset spacers when such a large number of spacers would at the very least void one's warranty. However, I suspect such setups are transiently common within the confines of a fitting studio.)

Rog rio Brito: Some new Youtube-dl functionality

I wrote in a previous post that Youtube changed their way of delivering videos, with the use of Dynamic Adaptive Streaming over HTTP. On top of that, they started serving both the audio and the video in separate streams, which meant trouble for downloader tools like youtube-dl. As I mentioned in that previous post:
What does this mean in practical terms for users of youtube-dl? Well, if you wanted to download videos in resolutions like the 480p (format 35) that I mentioned, then you will probably have to change your way of doing things, until a more automated solution is in place. You will have to download both the audio and the video and, then, "combine" them (that is, multiplex them) to create one "normal" video file with both the audio and the video.
And latter, I wrote:
Otherwise, to download 480p videos (which I do for lectures and so on with other projects of mine, like edx-dl) I have to call youtube-dl twice: once for format 135 and another for format 140, since the old (?) format 35 files are much smaller than the lower resolution 360p files (due to the former being encoded in High profile vs. the latter being encoded in Constrained Baseline profile).

(...) Well, now, we don't have this problem anymore: The new release of youtube-dl brings us many goodies, including that it is possible to automatically combine/merge/multiplex audio and video formats that Youtube now offers separately (See the previous comments about separate audio and video). Now, if you want a 480p video in H.264 format, High profile, with 128kbps AAC audio (this used to be Youtube's format 35), you can specify format -f 135+140 on the command-line and it will download both the audio, the video and multiplex it with ffmpeg (or avconv, depending on what you have installed). Besides being convenient, this automatic downloading and merging makes it unnecessary to write scripts to, say, retrieve all the videos in a playlist that contains a lot of lectures (see one example here, taught by Benedict Gross). Version 2014.02.17 of youtube-dl will be soon in your favorite mirror of the Debian archives.

Steve Kemp: My pastebin will now run under docker.

I've updated my markdown-pastebin site, to be a little cleaner, and to avoid spidering issues. Previously every piece of uploaded text received an incrementing integer to describe it - which meant it was trivially easy for others to see how many pieces of text had been uploaded, and to spider all past uploads (unless the user deleted them). Now each fresh paste receives a random UUID to describe it, and this means spidering is no longer feasible. I've also posted the source code to Gitub so folk can report bugs, fork, etc: That source code now includes a Dockerfile which allows you to quickly and easily build your own container running this wonderful service, and launch it without worrying about trashing your server ;) Anyway other than the user-interface overhaul it is still as functional, or not, as it used to be!

Andrew Pollock: [life] Day 20, Kindergarten, rocket building

Today was another Kindergarten day. Zoe was complaining about being sweaty before we even left the house this morning, so I gave her the choice of going by car or by bike, and she chose car, which was fine by me. It's been stinking hot the last few days. Summer is going out with a bang. Drop off went pretty smoothly. It was another morning where she was happy to have me hang out with her for a little bit, and then I was allowed to leave without any issues. I decided to use this Monday as a Debian day as planned. I mostly ran into a snag with my email setup, but I did manage to do some bug triage and upload one package. It had been hot all day, and I was feeling sapped by it, so I picked up Zoe in the car as well. I was surprised to find she wasn't asleep and hadn't had a nap at all. She seemed in good spirits despite this. Megan's Dad has quit his job, so I don't need to pick her up any more on Mondays and Wednesdays. We dropped by the post office to check my PO box on the way home. Zoe enjoyed peering through the mailbox into the post office. Today's TV diversion was to build a rocket ship out of one of the big moving boxes I've kept aside from the move back. Zoe had great fun blinging up the inside and outside with various craft "gems", and drew a bunch of aliens on the outside. I could have quite easily strung this out until Sarah arrived to pick her up, but I let her watch a little bit of TV right at the end. It was a pretty good afternoon. I liked how Zoe ran with the rocket ship idea and added her own embellishments all by herself. After Sarah picked up Zoe I went for a run. I'd intended to do 10km, but the heat took it out of me, and I lacked the willpower, so I stopped at 5km. After that I had the sweatiest yoga class yet.

16 February 2014

Siri Reiter: Conference Communication Design Building Blocks

As an introvert I like - well, I need to - spend time alone. I get my best ideas on my own. But when I truly thrive is when I am connected with others, cocreating. For the last couple of weeks it's been difficult for me to work on the visual design for the MiniDebConf in Barcelona next month. There have been practical reasons, but the real reason was that I was feeling stuck and overwhelmed. Sharing my uncomfortable feelings with my boyfriend finally made me able to see that I have been feeling alone, and feeling that I had to prove myself with my work. I felt disconnected from the people in Debian I want to cooperate with. I'd really benefit from sharing my thoughts and ideas more with others. The unpleasant feeling of "stuckness" dissolved when I said out loud what they were about, and ideas for changing my state appeared. Now I've started hanging out on the irc-channel more, I've asked for help in finding stuff in the huge pile of info, rules and previous examples and experiences at debian.org and my decision to blog and share more is strengthened. Finally the work has begun. Conferences are about meeting up and getting connected. Listening to somebody trying to enlighten you on a subject. Getting inspired. And so my idea of using speech bubbles as a visual identity koncept for the conference has everything to do with my own experience of connection and disconnection. Release, early, release often, I cannot say that I have done that. We really need the peoposals to be ready now. Thankfully I'll have time in the following days to get feedback and finish. I really hope people will accept the idea, but I'm expecting a debate.

Aurelien Jarno: On configure systems

I will never understand the point of using autotools, cmake or whatever configure system, when later the code uses an hardcoded list of architectures to determine the size of a pointer Unfortunately for porters this pattern is quite common. Update: As people keep asking, the way to check for the size of a given type is explained in the autoconf manual. To check for the size of the pointer, the following entry has to be added to configure.ac: AC_CHECK_SIZEOF(void *) On a 64-bit system, this will lead to the following entry in config.h:

/* The size of void *', as computed by sizeof. */
#define SIZEOF_VOID_P 8

Mark Brown: Human factors

An issue which I always find depressing but sadly unsurprising in discussions of process with software is the frequent disregard for human elements; indeed often the goal people have in creating process is to try to control and eliminate human elements. Little thought is given to what is going to motivate people to do what s asked and if they are going to follow it at all, or in the spirit it was intended. One example I ve seen several times is the idea that some engineers work on irrelevant things and that this can be fixed by requiring every commit to be tied to the project plan or a bug so off project work is obvious. This isn t really attacking the problem so much as putting a roadblock in place to try to avert it; the real problem is normally people not communicating about what they re doing and what s important but those problems are really hard to address. Sadly what tends to happen is that people work around the roadblock and cause some collateral damage; for example devaluing the bug tracker by referencing irrelevant bugs or creating meaningless bugs solely to allow commits, while continuing to behave like they did originally. This is often worse than the original situation. This sort of issue is one of the things I appreciate most about working on Linux there s quite a bit of process but because of the way it has been evolved the incentives are usually right to make sure they are followed in the spirit in which they were intended. For example the patch submission process is essentially just best practices for making sure changes go to people who care in a form which makes it easy for them to work with it; there is a bunch of tooling around it which built on those practices (and in turn influenced the practices) but it all comes back to that basic thing of getting attention for changes and making them easy to work with. As a result people mostly do the right thing (or close enough) so everything runs smoothly. The trick is to remember to standardize and write things down when it s needed notice the good practice and spread its adoption. The key difference here seems to be if process is viewed as something to solve problems for people or if it is viewed as a way to solve problems with people. If the problem is with the people then the view starts off negative and it s perhaps unsurprising that there is little consideration of how they will react. Sometimes it s not so much that a problem is seen with people as that the people doing don t have any real interest in the process (write only timesheets often bear no relation to reality for example) but there is an assumption that they are going to just do what they re asked (but instead they for example don t fill in their time sheets or don t provide accurate information). The end result is the same, their needs don t get considered and their actions end up being counterproductive. Starting to avoid these problems is fairly straightforward take a step back and consider why the people expected to carry out the process are going to want to do so. How does it help them? How will they see it helping others? Generally what s in it for them? If these are difficult questions to answer then there may be a problem it is likely people will ignore the process or do it badly without a lot of active enforcement, but perhaps that s OK for the situation. Beware of using metrics to provide incentives, metrics are gameable and that game can cause problems without care. But do think about people; making software is all about people.

15 February 2014

Gunnar Wolf: Like a Lord and Lady, with my dearest passions...

Like a Lord and Lady, with my dearest passions...
For those of you who didn't yet know it: My mother is a painter. A serious, professional, respected painter. But she sometimes goes to the funny side as well Of course, with all due professionalism! So, she gave us this great gift: She took one of our pictures from DebConf12 (from the "Conference Dinner" night), and painted it. Real size even! So, next time you come to our house, even if we are not around to greet you, we will be glad to welcome you to the Residence!

Thomas Goirand: OpenStack 2013.2.2 uploaded

This is the 2nd point release of OpenStack Havana (this is the name of the current stable release of OpenStack). It was out on Thursday (US time), and I uploaded it on Friday (Chinese time). Unfortunately, I realized that the latest python-keystoneclient didn t support the token and endpoint command line options, effectively breaking Keystone itself, and all automated endpoint registration in all core packages. So after fixing Keystone and openstack-pkg-tools, I had to re-upload a 2nd Debian release. However, after this glitch, the packages passed successfully our CI testing suite: my friends at eNovance and I run the tempest functional test suite each time there s this kind of major update, so that we can validate the packages are working as expected. And all went well after the new keystone command line options were fixed in the postinst scripts. As a side note, I fail to see consistency on deprecating these interfaces. While we still have the old glance index thing in the Glance client (this is really old), keystoneclient just broke backward compatibility, when keystone is quite recent. So, it looks to me that it wasn t a great idea to just remove token and endpoint this way (though I can understand the need of consistency). Hopefully, this will all be fixed anyway, when we move to the unified python-openstackclient command lines instead of per-project clients. I realized today that the pkg-openstack team now maintains more than 100 packages. This of course includes general purpose Python modules, which probably will move to the Python module team if it one day supports Git (life is too short: I do not wish to learn such a deprecated technology as SVN). Though this is still a lot of packages, and some more are coming: as per the OpenStack TODO list wiki page, Ironic (a replacement for nova-baremetal), TripleO (OpenStack on OpenStack), Tuskar (contols where things are deployed with TripleO) and Designate (DNS as a Service) are already packaged, and I am waiting for the Icehouse (this is the name of the next stable release) beta3 to be out to upload them to Experimental. This is scheduled for the 6th of March. I believe I am currently nearly up-to-date with the current global-requirements.txt (eg: python dependencies of OpenStack), pending a few Python module upgrades, so hopefully, packaging OpenStack Icehouse beta3 will smooth.

14 February 2014

Paul Tagliamonte: Introducing: Acid!

I ve been hacking (on and off) on a small bit of code (written in Hy) called Acid. So, all of this is *really* fluid, and I m going to change it s API and code (it s currently just one massive hack), but I think the idea has kinda jelled enough for me to chat a bit about. Acid is a DSL for writing event-driven Hy. Currently it s just using global events (that ll change soon), and it s a monumental hack (not sure how much I can do there), but it works pretty well. It s built on top of tulip / asyncio, which is an amazing new Python 3.4 standard library package for working with async code. Although asyncio is designed around network-based usecases, I ve been trying to shoehorn in an event system on top of it. It s going well so far. A basic Acid script looks something like:
(trip
  (on :startup
    (every 1 second (emit :clock-pulse nil)))
  (on :clock-pulse (print "."))
  (emit :startup nil))
which will print a dot ( . ) every second forever. Something a bit more advanced (fetch the MBTA Red line T information once a minute forever)
(defn get-endpoint-url [line]
  (.format "http://developer.mbta.com/lib/rthr/ 0 .json"
    (get  :red-line  "red"
          :blue-line "blue"  line)))
(trip
  ;; OK. Let's do some work with MBTA feeds.
  (on :update-feed
      ;; let's just update feeds on a cron.
      (print (.json (.get requests (get-endpoint-url event))))
      (emit :feed-updated event))
  (every 1 minute
         (emit :update-feed :red-line)))
Clearly, both of these examples are just as clear as their straight functional counterparts, but I m keen to see what I can do with temporal recursion for long-running daemons. I think my first job will be porting snitch's codebase to Acid. Let me know if you have any ideas!

Next.

Previous.