Search Results: "tar"

10 April 2014

Craig Small: WordPress update needed for stable too

Yesterday I mentioned that wordpress had an important security update to 3.8.2 The particular security bugs also impact the stable Debian version of wordpress, so those patches have been backported. I ve uploaded the changes to the security team so hopefully there will new package soon. The version you are looking for will be 3.6.1+dfsg-1~deb7u2 and will be on the Debian security mirrors.

Christine Spang: a tuturial about search

Today I gave a tutorial at PyCon 2014 entitled Search 101: An Introduction to Information Retrieval. It was an experiment of sorts: the first workshop I've run primarily by myself, my first tutorial at PyCon, my first paid teaching gig. It was an opportunity to take some of the lessons I learned from teaching the Boston Python Workshop and apply them to a new situation. The material itself is a distillation of many hours of frustration with the documentation for various open source search engine libraries, frustration that they didn't tell me where to start or about the big picture, they just jumped straight into the details. Here's what worked: Here's what caused problems: Intermediate students are a different crowd than beginners. There was less of an air of discovery in the room, though I organized the class around open-ended tasks. Since the material allowed for folks to take it in the direction of their interest, I found it a bit difficult to gauge whether people were following or not. Overall though, everyone was attentive and studious. I had fun. Ruben and Stuart, the PyCon tutorial organizers, had logistics running super smoothly, AV, lunch, everything. Thanks for that you guys, you rock. :) And thanks as well to my helpers: Leo, the tutorial host, Eben, my TA, and Roberto, on AV. It's impossible to pay adequate attention to 20+ people as a single person, couldn't have done a decent job without y'all. ;)

9 April 2014

Thorsten Glaser: Heartbleed vs. Startcom / StartSSL

First of all, good news, MirBSD is not vulnerable to The Heartbleed Bug due to my deliberate choice to stick to an older OpenSSL version. My inquiry (in various places) as to what precisely could leak when a vulnerable client connected to a n n-vulnerable server has yet to be answered, though we can assume private key material is safe. Now the bad news: while the CA I use and a CA I don t use offer free rekeying (in general), a CA I also use occasionally refuses to do that. The ugly: they will not even revoke the certificates, so any attacker who gained your key, for example when you have been using a certificate of theirs on a Debian system, will be able to use it (e.g. to MITM your visitors traffic) unless you shell over lots of unreasonable money per certificate. (Someone wrote they got the fee waived, but others don t, nor do I. (There s also a great Twitter discussion-thingy about this involving Zugschlus, but I won t link Twitter because they are not accessible to Lynx users like me and other Planet Debian authors.)
I ve been using GoDaddy privately for a while, paid for a wildcard certificate for *.mirbsd.org, and later also at work. I ve stopped using it privately due to current lack of money. Occasionally, for n n-wildcard gratis SSL certificates for HTTP servers. Startcom s StartSSL certificates are unusable for real SSL as used in SMTP STARTTLS anyway, so usage isn t much.
Now I ve got a dilemma here. I ve created a CA myself, to use with MirBSD infrastructure and things like that X.509 certificates for my hosts (especially so I can use them for SMTP) and possibly personal friends (whose PGP key I ve signed with maximum trust after the usual verification) but am using a StartSSL certificate for www.mirbsd.org as my GoDaddy wildcard certificate expires in a week or so (due to the aforementioned monetary issues), and I d rather not pay for a limited certificate only supporting a single vhost. There is absolutely no issue with that certificate and key (only ever generated and used on MirBSD, only using it in Apache mod_ssl). Then, there s this soon-to-be tax-exempt non-profit society of public utility I m working with, whose server runs Debian, and which is affected, but has been using a StartSSL certificate for a while. Neither the society nor I can afford to pay for revocation, and we do not see any possible justification for this especially in the face of CVE-2014-0160. I expect a rekey keeping the current validity end date, and would accept a revocation even if I were unable to get a new certificate, since even were we to get a certificate for the society s domain from someplace else, an attacker could still MITM us with the previous one from Startcom. The problem here is: I d really love to see (all of!) Startcom dropped from the global list of trustworthy CAs, but then I d not know from where to get a cert for MirBSD; Globalsign is not an option because I will not limit SSL compatibility to a level needed to pass their quality test possibly GoDaddy, ISTR they offer a free year to Open Source projects no idea about one for the society but it would solve the problem of not getting the certificates revoked. For everyone. I am giving Startcom time until Friday after $dayjob (for me); after that, I ll be kicking them off MirBSD s CA bundle and will be lobbying for Debian and Mozilla to do the same. Any other ideas of how to deal with that? I d probably pay 5 for a usable certificate accepted by people (including old systems, such as MSIE 5.0 on Win2k and the likes) without questioning most of the time, I only serve public content anyway and just use SSL to make the NSA s job more difficult (and even when not I m not dealing with any payment information, just the occasional login protected area). By the way, is there any way to access the information that is behind a current-day link to groups.google.com with Lynx or Pine? I can t help but praise GMane for their NNTP interface. ObFunfact: just when I was finished writing this wlog entry, I got a new eMail Special offer just for you. from GoDaddy. Sadly, no offer for a 5 SSL certificate, just the usual 20-35% off coupon code.

Lucas Nussbaum: speedtest.net, or how not to do bandwidth tests

While trying to debug a bandwidth problem on a 3G connection, I tried speedtest.net, which ranks fairly high when one searches for bandwidth test on various search engines. I was getting very strange results, so I started wondering if my ISP might be bandwidth-throttling all traffic except the one from speedtest.net tests. After all, that s on a 3G network, and another french 3G ISP (SFR) apparently uses Citrix ByteMobile to optimize the QoE by minifying HTML pages and recompressing images on-the-fly (amongst other things). So, I fired wireshark, and discovered that no, it s just speedtest being a bit naive. Speedtest uses its own text-based protocol on port 8080. Here is an excerpt of a download speed test:

> HI
< HELLO 2.1 2013-08-14.01
> DOWNLOAD 1000000
< DOWNLOAD JABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFGHIJABCDEFG
Yeah, right: sequences of ABCDEFGHIJ . How course, extremely easy to compress, which apparently happens transparently on 3G (or is it PPP? but I tried to disable PPP compression, and it did not see any change). It s funny how digging into problems that look promising at first sight often results in big disappointments :-(

Craig Small: Important WordPress update

WordPress 3.8.2 was released yesterday which contains some important security fixes. This is an important security release and the Debian packages were uploaded to the ftp-master a few minutes ago. Besides fixing Debian Bug #744018, the release fixes the following two vulnerabilities (as mentioned in the bug report): I recommend if you use the Debian package to upgrade as soon as it is available.

Petter Reinholdtsen: S3QL, a locally mounted cloud file system - nice free software

For a while now, I have been looking for a sensible offsite backup solution for use at home. My requirements are simple, it must be cheap and locally encrypted (in other words, I keep the encryption keys, the storage provider do not have access to my private files). One idea me and my friends had many years ago, before the cloud storage providers showed up, was to use Google mail as storage, writing a Linux block device storing blocks as emails in the mail service provided by Google, and thus get heaps of free space. On top of this one can add encryption, RAID and volume management to have lots of (fairly slow, I admit that) cheap and encrypted storage. But I never found time to implement such system. But the last few weeks I have looked at a system called S3QL, a locally mounted network backed file system with the features I need. S3QL is a fuse file system with a local cache and cloud storage, handling several different storage providers, any with Amazon S3, Google Drive or OpenStack API. There are heaps of such storage providers. S3QL can also use a local directory as storage, which combined with sshfs allow for file storage on any ssh server. S3QL include support for encryption, compression, de-duplication, snapshots and immutable file systems, allowing me to mount the remote storage as a local mount point, look at and use the files as if they were local, while the content is stored in the cloud as well. This allow me to have a backup that should survive fire. The file system can not be shared between several machines at the same time, as only one can mount it at the time, but any machine with the encryption key and access to the storage service can mount it if it is unmounted. It is simple to use. I'm using it on Debian Wheezy, where the package is included already. So to get started, run apt-get install s3ql. Next, pick a storage provider. I ended up picking Greenqloud, after reading their nice recipe on how to use S3QL with their Amazon S3 service, because I trust the laws in Iceland more than those in USA when it come to keeping my personal data safe and private, and thus would rather spend money on a company in Iceland. Another nice recipe is available from the article S3QL Filesystem for HPC Storage by Jeff Layton in the HPC section of Admin magazine. When the provider is picked, figure out how to get the API key needed to connect to the storage API. With Greencloud, the key did not show up until I had added payment details to my account. Armed with the API access details, it is time to create the file system. First, create a new bucket in the cloud. This bucket is the file system storage area. I picked a bucket name reflecting the machine that was going to store data there, but any name will do. I'll refer to it as bucket-name below. In addition, one need the API login and password, and a locally created password. Store it all in ~root/.s3ql/authinfo2 like this:
[s3c]
storage-url: s3c://s.greenqloud.com:443/bucket-name
backend-login: API-login
backend-password: API-password
fs-passphrase: local-password
I create my local passphrase using pwget 50 or similar, but any sensible way to create a fairly random password should do it. Armed with these details, it is now time to run mkfs, entering the API details and password to create it:
# mkdir -m 700 /var/lib/s3ql-cache
# mkfs.s3ql --cachedir /var/lib/s3ql-cache --authfile /root/.s3ql/authinfo2 \
  --ssl s3c://s.greenqloud.com:443/bucket-name
Enter backend login: 
Enter backend password: 
Before using S3QL, make sure to read the user's guide, especially
the 'Important Rules to Avoid Loosing Data' section.
Enter encryption password: 
Confirm encryption password: 
Generating random encryption key...
Creating metadata tables...
Dumping metadata...
..objects..
..blocks..
..inodes..
..inode_blocks..
..symlink_targets..
..names..
..contents..
..ext_attributes..
Compressing and uploading metadata...
Wrote 0.00 MB of compressed metadata.
# 
The next step is mounting the file system to make the storage available.
# mount.s3ql --cachedir /var/lib/s3ql-cache --authfile /root/.s3ql/authinfo2 \
  --ssl --allow-root s3c://s.greenqloud.com:443/bucket-name /s3ql
Using 4 upload threads.
Downloading and decompressing metadata...
Reading metadata...
..objects..
..blocks..
..inodes..
..inode_blocks..
..symlink_targets..
..names..
..contents..
..ext_attributes..
Mounting filesystem...
# df -h /s3ql
Filesystem                              Size  Used Avail Use% Mounted on
s3c://s.greenqloud.com:443/bucket-name  1.0T     0  1.0T   0% /s3ql
#
The file system is now ready for use. I use rsync to store my backups in it, and as the metadata used by rsync is downloaded at mount time, no network traffic (and storage cost) is triggered by running rsync. To unmount, one should not use the normal umount command, as this will not flush the cache to the cloud storage, but instead running the umount.s3ql command like this:
# umount.s3ql /s3ql
# 
There is a fsck command available to check the file system and correct any problems detected. This can be used if the local server crashes while the file system is mounted, to reset the "already mounted" flag. This is what it look like when processing a working file system:
# fsck.s3ql --force --ssl s3c://s.greenqloud.com:443/bucket-name
Using cached metadata.
File system seems clean, checking anyway.
Checking DB integrity...
Creating temporary extra indices...
Checking lost+found...
Checking cached objects...
Checking names (refcounts)...
Checking contents (names)...
Checking contents (inodes)...
Checking contents (parent inodes)...
Checking objects (reference counts)...
Checking objects (backend)...
..processed 5000 objects so far..
..processed 10000 objects so far..
..processed 15000 objects so far..
Checking objects (sizes)...
Checking blocks (referenced objects)...
Checking blocks (refcounts)...
Checking inode-block mapping (blocks)...
Checking inode-block mapping (inodes)...
Checking inodes (refcounts)...
Checking inodes (sizes)...
Checking extended attributes (names)...
Checking extended attributes (inodes)...
Checking symlinks (inodes)...
Checking directory reachability...
Checking unix conventions...
Checking referential integrity...
Dropping temporary indices...
Backing up old metadata...
Dumping metadata...
..objects..
..blocks..
..inodes..
..inode_blocks..
..symlink_targets..
..names..
..contents..
..ext_attributes..
Compressing and uploading metadata...
Wrote 0.89 MB of compressed metadata.
# 
Thanks to the cache, working on files that fit in the cache is very quick, about the same speed as local file access. Uploading large amount of data is to me limited by the bandwidth out of and into my house. Uploading 685 MiB with a 100 MiB cache gave me 305 kiB/s, which is very close to my upload speed, and downloading the same Debian installation ISO gave me 610 kiB/s, close to my download speed. Both were measured using dd. So for me, the bottleneck is my network, not the file system code. I do not know what a good cache size would be, but suspect that the cache should e larger than your working set. I mentioned that only one machine can mount the file system at the time. If another machine try, it is told that the file system is busy:
# mount.s3ql --cachedir /var/lib/s3ql-cache --authfile /root/.s3ql/authinfo2 \
  --ssl --allow-root s3c://s.greenqloud.com:443/bucket-name /s3ql
Using 8 upload threads.
Backend reports that fs is still mounted elsewhere, aborting.
#
The file content is uploaded when the cache is full, while the metadata is uploaded once every 24 hour by default. To ensure the file system content is flushed to the cloud, one can either umount the file system, or ask S3QL to flush the cache and metadata using s3qlctrl:
# s3qlctrl upload-meta /s3ql
# s3qlctrl flushcache /s3ql
# 
If you are curious about how much space your data uses in the cloud, and how much compression and deduplication cut down on the storage usage, you can use s3qlstat on the mounted file system to get a report:
# s3qlstat /s3ql
Directory entries:    9141
Inodes:               9143
Data blocks:          8851
Total data size:      22049.38 MB
After de-duplication: 21955.46 MB (99.57% of total)
After compression:    21877.28 MB (99.22% of total, 99.64% of de-duplicated)
Database size:        2.39 MB (uncompressed)
(some values do not take into account not-yet-uploaded dirty blocks in cache)
#
I mentioned earlier that there are several possible suppliers of storage. I did not try to locate them all, but am aware of at least Greenqloud, Google Drive, Amazon S3 web serivces, Rackspace and Crowncloud. The latter even accept payment in Bitcoin. Pick one that suit your need. Some of them provide several GiB of free storage, but the prize models are quite different and you will have to figure out what suits you best. While researching this blog post, I had a look at research papers and posters discussing the S3QL file system. There are several, which told me that the file system is getting a critical check by the science community and increased my confidence in using it. One nice poster is titled "An Innovative Parallel Cloud Storage System using OpenStack s SwiftObject Store and Transformative Parallel I/O Approach" by Hsing-Bung Chen, Benjamin McClelland, David Sherrill, Alfred Torrez, Parks Fields and Pamela Smith. Please have a look. Given my problems with different file systems earlier, I decided to check out the mounted S3QL file system to see if it would be usable as a home directory (in other word, that it provided POSIX semantics when it come to locking and umask handling etc). Running my test code to check file system semantics, I was happy to discover that no error was found. So the file system can be used for home directories, if one chooses to do so. If you do not want a locally file system, and want something that work without the Linux fuse file system, I would like to mention the Tarsnap service, which also provide locally encrypted backup using a command line client. It have a nicer access control system, where one can split out read and write access, allowing some systems to write to the backup and others to only read from it. As usual, if you use Bitcoin and want to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

Andrew Pollock: [life] Day 71: Tumble Tastics trial, painting and plaster fun

Zoe slept in even later this morning. I'm liking this colder weather. We had nothing particular happening first thing today, so we just snuggled in bed for a bit before we got started. Tumble Tastics were offering free trial classes this week, so I signed Zoe up for one today. She really enjoyed going to Gold Star Gymnastics in the US, and has asked me about finding a gym class over here every now and then. Tumble Tastics is a much smaller affair than Gold Star, but at 300 metres from home on foot, it's awesomely convenient. Zoe scootered there this morning. It seems to be physically part of what I'm guessing used to be the Church of Christ's church hall, so it's not big at all, but the room that Zoe had her class in still had plenty of equipment in it. There were 8 kids in her class, all about her size. I peeked around the door and watched. Most of the class was instructor led and mainly mat work, but then part way through, the parents were invited in, and the teacher walked us all through a course around the room, using the various equipment, and the parents had to spot for their kids. The one thing that cracked me up was when the kids were supposed to be tucking into a ball and rocking on their backs. Zoe instead did a Brazilian Jiu-Jitsu break-fall and fell backwards slapping the mat instead. It was good to see that some of what she learned in those classes has kicked in reflexively. She really enjoyed the rope swing and hanging upside down on the uneven bars. The class ran for 50 minutes (I was only expecting it to last 30 minutes) and Zoe did really well straight off. I think we'll make this her 4th term extra-curricular activity. We scootered home the longer way, because we were in no particular hurry. Zoe did some painting when we got home, and then we had lunch. After lunch we goofed off for a little bit, and then we did quiet time. Zoe napped for about two and a half hours, and then we did some plaster play. I'd picked up a fish ice cube tray from IKEA on the weekend for 99 cents (queue Thrift Shop), and I bought a bag of plaster of Paris a while back, but haven't had a chance to do anything with it yet. I bribed Zoe into doing quiet time by telling her we'd do something new with the ice cube tray I'd bought. We mixed up a few paper cups with plaster of Paris in them and then I squirted some paint in. I'm not sure if the paint caused a reaction, or the plaster was already starting to set by the time the paint got mixed in, but it became quite viscous as soon as the paint was mixed in. We did three different colours and used tongue depressers to jam it into the tray. Zoe seemed to twig that it was the same stuff as the impressions of her baby feet, which I thought was a pretty clever connection to make. After that, there was barely enough time to watch a tiny bit of TV before Sarah arrived to pick Zoe up. I told her that her plaster would be set by the time she got dropped off in the morning. I procrastinated past the point of no return and didn't go for a run. Instead I decided to go out to Officeworks and print out some photos to stick in the photo frame I bought from IKEA on the weekend.

Dirk Eddelbuettel: BH release 1.54.0-1

A new release of the BH package is now on CRAN and its mirrors. BH provides (a sizeable subset of) the Boost library for C++, particularly (large) parts delivered as pure template headers not requiring linking. See the BH page for more details. This release provides our first update relative to the Boost tarballs we started with. It moves us from 1.51.0 (which was getting a little long in the tooth) to 1.54.0. This is just about the first time ever that I didn't package something straight from the current release (now 1.55.0). My aim was to to balance the oh, shiny, new aspect with some stability. Comments welcome--maybe I will go to the bleeding edge next time. As before, the CRAN is created by running bcp over a number of selected components of Boost. If you'd like to see additional ones include, please do get in touch too. Before uploading, I also tested against all of these sixteen CRAN dependents I could quickly test on my server given the installed dependencies there. The complete list changes follows below.
Changes in version 1.54.0-1 (2014-04-07)
  • Upgraded to Boost 1.54.0
  • Adjust build script local/script/CreateBoost.sh accordingly
  • Renamed generation_runge_kutta_cash_karp54_classic.hpp to generation_runge_kutta_cash_karp54_cl.hpp to remain within 100-character limit for tar
Courtesy of CRANberries, there is also a diffstat report for the most recent release. Comments and suggestions are welcome via the mailing list or issue tracker at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

8 April 2014

Tanguy Ortolo: Disable your spammed addresses with Postfix

Using address extension Postfix (and many other mail servers) offers one nice address extension feature: addresses like <user+whaterver@> are implicit aliases to <user@>. This allows users to implement a simple measure to fight spam:
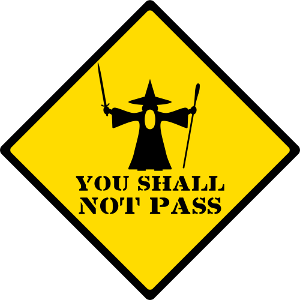
  1. when SomeCompany or whatever asks for your email address, give them <user+somecompany@>;
  2. if you start receiving spam at that address, you know who sold or was stolen your address;
  3. finally, you will be able to disable that address so messages are simply refused with a permanent error code.
Road sign  you shall not pass  with Gandalf
Disabling an extended address So, here is how to implement that last step with Postfix, when you detect that your extended address <user+evilcorp@> is being spammed. In /etc/postfix/main.cf:
smtpd_recipient_restrictions =
    check_recipient_access hash:/etc/postfix/recipients,
    [ ]
Then, create /etc/postfix/recipients containing the addresses to disable:
user+evilcorp@example.com   553 5.7.1 I did not subscribe to receive spam, go away
Of course, the error codes and message can be freely configured, just make sure you are using a permanent error code so senders do not retry. Hash that table, reload Postfix and it is done:
# postmap /etc/postfix/recipients
# service postfix reload
After that, your mail server will reject messages sent to these addresses. And it will do so at the RCPT TO step, saving your bandwidth for more useful things.

Russ Allbery: Review: With Charity for All

Review: With Charity for All, by Ken Stern
Publisher: Anchor
Copyright: November 2013
ISBN: 0-307-74381-0
Format: Trade paperback
Pages: 244
I've been reading a lot lately about how to measure charitable organizations and where best to give your money, which has already prompted a rethinking of which organizations I want to support. Most of that has been shorter, on-line blog posts, but I've been wanting a deeper analysis. This is the first of a couple of books I've found on the topic. (The second, an analysis of microfinance, is waiting for me to have more time to read.) For this kind of book, the background of the author matters a lot. Stern was the former CEO of National Public Radio for eight and a half years, so he has practical experience in the business side of non-profits. He's credited with improving NPR's financial position and management and oversaw an era of rapid growth. In With Charity for All, he speaks frankly about his own personal experiences as well as his research. My impression is that he's typical of competent business managers of non-profits: not particularly radical, focused mostly on business issues, and the sort of person that a non-profit needs to turn a mission or cause into a sustainable organization. It's worth noting in advance that With Charity for All is specifically about the United States charitable sector and US laws and approaches. Some of this may generalize to other countries, but non-profit and charity law is very different between different countries, and the US attitude towards government, non-profits, and the appropriate division of responsibilities between them often doesn't match the prevailing view elsewhere. This book may well be interesting to people outside the US, but only if they're curious about the US charitable sector. The short summary of the message of this book is that we're not getting our money's worth out of charity, either as donors or as taxpayers who are indirectly subsidizing these organizations. This is not (usually) due to any outright fraud, although there certainly is some of that due to the almost total lack of oversight of charitable organizations. Rather, it's the result of a complex combination of history and institutional momentum, focus on the aspects of a charity that play well to potential donors, a concerted effort at feel-good marketing, well-intentioned but misguided donor dictates, adoption of approaches and business practices from the for-profit sector, and, above everything else, the almost complete absence of evidence-based evaluation of charities. Evidence-based evaluation is currently a hot trend among charities. I heard about this book via one of the organizations that is focusing on this (GiveWell). This is not what sites like Charity Navigator do, and indeed Stern talks at some length about the serious limitations of the Charity Navigator approach. All that sites of that type can do is look at spending breakdowns. Stern makes a strong argument that a focus on reducing overhead, as measured by those financial forms, is misguided and leads to very ineffective and unorganized charities. Worse, all Charity Navigator can tell you is if the charity is spending money on something they declare to be in line with their goal, not whether that money did any good whatsoever. The short and depressing news is that most of that money does little or no good, and worse, that most charities have no systematic way of measuring whether it does any good. I'm particularly interested in how to ground charities in more concrete evidence, and Stern's discussion does not disappoint. But one of the things I liked about the book is that he doesn't stop there. Other topics include the dizzying variety of charities and the resulting confusion and dispersion of resources, the non-profits that are practically indistinguishable from for-profit companies except that they get huge tax breaks (sports organizations, as you might expect, are probably the worst offenders, but Stern has harsh commentary on the US hospital system), the mess of compensation in the non-profit sector, and the serious problems created by major donors who want to get directly involved and oversee how their money is spent. All of these topics are fascinating, if a bit depressing in the aggregate. As is typical for a book of this sort, it's a lot easier to see the problems than to describe the solutions. Stern does try to offer his own prescriptions, most of which are variations on more oversight: more regulation, more effort put into measuring results, more concrete standards for success or failure, and a stronger culture of treating tax-exempt status as a privilege, not a right, that has to be defended by showing clear social benefit. I'm convinced those steps would be helpful, although less convinced that we're able to get there from here. One of his ideas I am already using on a small scale: pooling charitable donations with professional evaluators who can take the time to look deeper than financial breakdowns and do some independent measurement of results, or at least survey relevant studies done by others and possibly demand more be done. This model of a mutual fund for charitable giving has some promise, I think (more than a managed mutual fund, in fact), and is very similar to what GiveWell is doing. This is an advocacy book, and one that's primarily focused on concrete, measurable deliverables and on the finances. There are a few places where I have reason to be dubious of the black-and-white conclusions Stern draws. For example, he makes much of the bill collecting practices of charitable hospitals, which I agree is a travesty, but doesn't mention that non-profit hospitals produce better health outcomes. I'm also not sure his analysis is as directly applicable to advocacy organizations, where measuring success is a much more challenging proposition. I think the Southern Poverty Law Center is one of the best charities in the United States (admittedly based largely on gut feeling and presentation), but the nature of their work is not amenable to the style of analysis that Stern is doing here. It's therefore worth taking this book with a grain of salt. But, that said, Stern's conclusions are in line with things I've read elsewhere. I think he's pointing in the right direction, and I would recommend this book to anyone who gives regularly to charity. Hopefully it won't just cause you to stop. There are charities out there that are trying hard to measure their results and ensure they deliver social value for the money that we give them. Our system just doesn't support them very well, yet. Rating: 8 out of 10

7 April 2014

Yves-Alexis Perez: CVE-2014-0160 / heartbleed

Short version: DSA should be in your INBOX in a few moments, and the updates on the mirror a moment later. [UPDATE Tue, 08 Apr 2014 01:06:42 +0200] After the upgrade, you really need to restart all TLS application using libssl1.0.0 to get the fix. Usual suspects are webservers, mailservers etc. Don't forget to restart clients too. Easiest way is to completely reboot the sever, but in case that's not a solution, you can check the process still using the old library with the following snippet:

grep -l 'libssl.*deleted' /proc/*/maps tr -cd 0-9\\n xargs -r ps u Some people seem to indicate that the 64kB leak can enable an attacker to get pretty much anything from the process memory space, including the certificate private key. While we weren't able to confirm that yet, that's not really impossible, so you might also want to regenerate those private keys, although that's not something you should do in a rush either.

Vasudev Kamath: Loading Python modules/plug-ins at runtime

Some times it is desired to load arbitrary python files or pre- installed python modules during application run time.I had encountered 2 such usecases, one is in SILPA application and other is dictionary-bot which I was refactoring recently.
Case 1: Loading installed python module In case of SILPA I need to load pre-installed modules and here is the old code , that is a bit hacky code I copied from Active State Python recipies. I found a bit better way to do it using importlib module as shown below.
from __future__ import print_function
import sys
import importlib
def load_module(modulename):
    mod = None
    try:
        mod = importlib.import_module(modulename)
    except ImportError:
        print("Failed to load  module ".format(module=modulename),
                     file=sys.stderr)
    return mod
Here importlib itself takes care of checking if modulename is already loaded by checking sys.modules[modulename], if loaded it returns that value, otherwise it loads the module and sets it to sys.modules[modulename] before returning module itself.
Case 2: Loading python files from arbitrary location In case of dictionary bot my requirement was bit different, I had some python files lying around in a directory, which I wanted to plug into the bot during run time and use them depending on some conditions. So basic structure which I was looking was as follows.
      pluginloader.py
      plugins
       
       __ aplugin.py
       
       __ bplugin.py
pluginloader.py is the file which needs to load python files under plugins directory. This was again done using importlib module as shown below.
import os
import sys
import re
import importlib
def load_plugins():
    pysearchre = re.compile('.py$', re.IGNORECASE)
    pluginfiles = filter(pysearchre.search,
                           os.listdir(os.path.join(os.path.dirname(__file__),
                                                 'plugins')))
    form_module = lambda fp: '.' + os.path.splitext(fp)[0]
    plugins = map(form_module, pluginfiles)
    # import parent module / namespace
    importlib.import_module('plugins')
    modules = []
    for plugin in plugins:
             if not plugin.startswith('__'):
                 modules.append(importlib.import_module(plugin, package="plugins"))
    return modules
Above code first searches for all python file under specified directory and creates a relative module name from it. For eg. file aplugin.py will become .aplugin. Before loading modules itself we will load the parent module in our case plugins, this is because relative imports in python expects parent module to be already loaded. Finally for relative imports to work with importlib.import_module we need to specify parent module name in package argument. Note that we ignore files begining with __, or specifically we don't want to import __init__.py, this will be done when we import parent module. The above code was inspired from a answer on StackOverflow, which uses imp module, I avoided imp because its been deprecated from Python 3.4 in favor of importlib module.

Olivier Berger: Tagged a first version of the TWiki to FusionForge s MediaWiki converter

As announced previously, I ve been hacking on a migration tool allowing to import into the MediaWiki of a FusionForge project, a conversion of the contents of a TWiki wiki. I ve succesfully imported a first project (from PicoForge to FusionForge) using the tool, so I ve decided to tag a first release and make the Git repo accessible. More details at : https://fusionforge.int-evry.fr/projects/pytwiki2mediawi/ Feel free to ask here in the comments or by email, in case of need. And, yes, my Python is most likely awful, but at least, this works, and much more featureful than existing tools I could test.

Andrew Pollock: [life] Day 69: Walk to King Island, a picnic at Wellington Point, the long slow acquisition of some linseed and a split lip

Today was a really good day, right up until the end, when it wasn't so good, but could have been a whole lot worse, so I'm grateful for that. I've been wanting to walk out to King Island at low tide with Zoe for a while, but it's taken about a month to get the right combination of availability, weather and low tide timing to make it possible. Today, there was a low tide at about 10:27am, which I thought would work out pretty well. I wasn't sure if the tide needed to be dead low to get to King Island, so I thought we could get there a bit early and possibly follow the tide out. I invited Megan and Jason to join us for the day and make a picnic of it. It turned out that we didn't need a really low tide, the sand bar connecting King Island to Wellington Point was well and truly accessible well before low tide was reached, so we headed out as soon as we arrived. I'd brought Zoe's water shoes, but from looking at it, thought it would be walkable in bare feet. We got about 10 metres out on the sand and Zoe started freaking out about crabs. I think that incident with the mud crab on Coochiemudlo Island has left her slightly phobic of crabs. So I went back to Jason's car and got her water shoes. I tried to allay her fears a bit by sticking my finger in some of the small holes in the sand, and even got her to do it too. I'm actually glad that I did get her water shoes, because the shell grit got a bit sharp and spiky towards King Island, so I probably would have needed to carry her more than I did otherwise. Along the way to the island we spotted a tiny baby mud crab, and Zoe was brave enough to hold it briefly, so that was good. We walked all the way out and partially around the island and then across it before heading back. The walk back was much slower because where was a massive headwind. Zoe ran out of steam about half way back. She didn't like the sand getting whipped up and stinging her legs, and the wind was forcing the brim of her hat down, so I gave her a ride on my shoulders for the rest of the way back. We had some lunch after we got back to Wellington Point, and Zoe found her second wind chasing seagulls around the picnic area. After an ice cream, we went over to the playground and the girls had a great time playing. It was a pretty good park. There was this huge tree with a really big, thick, horizontal branch only about a metre or two off the ground. All the kids were climbing on it and then shimmying along the branch to the trunk. Zoe's had a few climbs in trees and seems not afraid of it, so she got up and had a go. She did really well and did a combination of scooting along, straddling the branch and doing a Brazilian Jiu-Jitsu-style "bear crawl" along the branch. It was funny seeing different kids' limits. Zoe was totally unfazed by climbing the tree. Megan was totally freaking out. But when it came to walking in bare feet in an inch of sea water, Zoe wanted to climb up my leg like a rat up a rope, in case there were crabs. Each to their own. Zoe wanted to have a swim in the ocean, so I put her into her swimsuit, but had left the water shoes back in the car. Once again, she freaked out about crabs as soon as we got ankle deep in the water, and was freaking out Megan as well, so the girls elected to go back to playing in the park. After a good play in the park, we headed back home. We'd carpooled in Jason's truck, with both girls in the back. I'd half expected Zoe to fall asleep on the way back, but the girls were very hyped up and had a great time playing games and generally being silly in the back. When we got back to our place, Jason was in need of a coffee, so we walked to the Hawthorne Garage and had coffee and babyccinos, before Megan and Jason went home. It was about 3:30pm at this point, and I wanted to make a start on dinner. I was making a wholemeal pumpkin quiche, which I've made a few times before, and I discovered we were low on linseed. I thought I'd push things and see if Zoe was up for a scooter ride to the health food shop to get some more and kill some time. She was up for it, but ran out of steam part way across Hawthorne Park. Fortunately she was okay with walking and didn't want me to carry her and the scooter. It took us about an hour to get to the health food shop. Zoe immediately remembered the place from the previous week where we'd had to stop for a post-meltdown pit stop and declared she needed to go to the toilet again. We finally made it out of the shop. I wasn't looking forward to the long walk back home, but there were a few people waiting for a bus at the bus stop near the health food shop, and on checking the timetable, the bus was due in a couple of minutes, so we just waited for the bus. That drastically shortened the trip back. Zoe managed to drop the container of linseed on the way home from the bus stop, but miraculously the way it landed didn't result in the loss of too much of the contents, it just split the container. So I carefully carried the container home the rest of the way. By this stage it was quite a bit later than I had really wanted to be starting dinner, but we got it made, and Zoe really liked the pumpkin quiche, and ate a pretty good dinner. It was after dinner when things took a turn for the worse. Zoe was eating an ice block for dessert, and for whatever reason, she'd decided to sit in the corner of the kitchen next to the dishwasher, while I was loading it. I was carrying over one of the plates, and the knife managed to fall off the plate, bounce off the open dishwasher door and hit her in the mouth, splitting her lip. Zoe was understandably upset, and I was appalled that the whole thing had happened. She never sits on the kitchen floor, let alone in the corner where the dishwasher is. And this knife came so close to her eye. Fortunately the lip didn't look too bad. It stopped bleeding quickly, and we kept some ice on it and the swelling went down. I hate it when accidents happen on my watch. I feel like I'm fighting the stigma of the incompetent single Dad, or the abusive single Dad, so when Zoe sustains an injury to the face like a fat lip, which could be misinterpreted, I, well, really hate it. This was such a freak accident, and it could have gone so much worse. I'm just so glad she's okay. Zoe recovered pretty well from it, and I was able to brush her teeth without aggravating her lip. She went to bed well, and I suspect she's going to sleep really well. It's a bit cooler tonight, so I'm half-expecting a sleep in in the morning with any luck.

Russ Allbery: Review: Fantasy & Science Fiction, September/October 2011

Review: Fantasy & Science Fiction, September/October 2011
Editor: Gordon van Gelder
Issue: Volume 121, No. 3 & 4
ISSN: 1095-8258
Pages: 258
Another review of a magazine that I finished quite some time ago. Apologies for any inaccuracies or lack of depth in the reviews. There wasn't much in Charles de Lint's reviews in this issue that interested me, but Michelle West covers a great selection of books. Two of them (The Wise Man's Fear and The Quantum Thief) are already on my to-read list; the third, The Postmortal, sounded interesting and would go on my list to purchase if I didn't already have so many good books I've not read. Otherwise, this issue is short on non-fiction. The only other essay entry is a film review from Kathi Maio, which is the typical whining about all things film that F&SF publishes. "Rutger and Baby Do Jotenheim" by Esther M. Friesner: Baby is a former pole dancer with a toy poodle named Mister Snickers, which warns you right away that this story is going to involve a few over-the-top caricatures and more use of the word "piddle" than one might ideally want. Rutger is a mythology professor who tolerates her for the standard reasons in this sort of pairing. They're travelling across country to Baby's sister's wedding when their car breaks down in Minnesota, prompting an encounter with frost giants. As you might expect, this is a sort of fractured fairy tale, except based on Norse mythology instead of the more typical Grimm fare. The fun is in watching these two apparent incompetents (but with enough knowledge of mythology to clue in the reader) reproduce the confrontation between Thor and Utgard-Loki. The fight with old age is particularly entertaining. If you've read any of Friesner's other stories, you know what to expect: not much in the way of deeper meaning, but lots of fun playing with stereotypes and an optimistic, funny outcome. Good stuff. (7) "The Man Inside Black Betty" by Sarah Langan: This story comes with a mouthful of a subtitle: "Is Nicholas Wellington the World's Best Hope?" It's also a story that purports to be written by a fictional character, in this case one Saurub Ramesh (with Langan credited as having done "research"). It's told in the style of first-person journalism, relating the thoughts and impressions of Ramesh as he interviews Nicholas Wellington. The topic is Black Betty: a black hole above Long Island Sound. Wellington is a scientific genius and iconoclast with radical theories of black holes that contradict how the government has been attempting to deal with Black Betty, unsuccessfully. The structure here was well-handled, reminding me a lot of a Michael Lewis article during the financial collapse. Langan has a good feel for how journalism of this type mixes personalities, politics, and facts. But it's all setup and no story. We get some world building, and then it's over, with no resolution except pessimism. Meh. (4) "A Borrowed Heart" by Deborah J. Ross: Ross starts with the trappings of urban fantasy transplanted into a Victorian world: supernatural creatures about, a protagonist who is a high-class prostitute, and sex and a sucubus by the second page. It evolves from there into a family drama and an investigation, always giving the reader the impression that a vampire will jump out at any moment. But the ending caught me entirely by surprise and was far more effective due to its departure from the expected path. Well done. (7) "Bright Moment" by Daniel Marcus: The conflict between terraforming and appreciation for the universe as we find it is an old story pattern in science fiction, and Marcus doesn't add much here. I think the story would have been stronger if he'd found a way to write the same plot with a pure appeal to environmental beauty without the typical stakes-raising. But he does sprinkle the story with a few interesting bits, including a pod marriage and a futuristic version of extreme sports as a way of communing with nature. (6) "The Corpse Painter's Masterpiece" by M. Rickert: This is typical of my reaction to a Rickert story: shading a bit too much towards horror for me, a bit too cryptic, well-written but not really my thing. It's about a corpse painter who does the work of an informal mortician, improving the appearance of bodies for their funerals, and the sheriff who brings him all the dead bodies. It takes an odd macabre twist, and I have no idea what to make of the ending. (4) "Aisle 1047" by Jon Armstrong: Armstrong is best known for a couple of novels, Grey and Yarn, which entangle their stories in the future of marketing and commerce. One may be unsurprised, then, that this short story is on similar themes, with the intensity turned up to the parody point. Tiffan3 is a department-store saleswoman, spouting corporate slogans and advertising copy while trying to push customers towards particular products. The story follows the escalation into an all-out brand war, fought with the bubbly short-cut propaganda of a thirty-second commercial. For me, it fell awkwardly between two stools: it's a little too over-the-top and in love with its own bizarre alternate world to be effective satire, but the world is more depressing than funny and the advertising copy is grating. More of a curiosity than a successful story, I think. (5) "Anise" by Chris DeVito: Stories that undermine body integrity and focus on the fascinated horror of violation of physical boundaries aren't generally my thing, so take that into account in this review. Anise's husband died, but that's not as much of a problem as it used to be. Medical science can resurrect people via a sort of permanent, full-body life support system, making them more cyborg than human. "Anise" is about the social consequences of this technology in a world where a growing number of people have a much different relationship with their body than the typical living person today. It's a disturbing story that is deeply concerned with the physical: sex, blood, physical intimacy in various different forms, and a twisted type of psychological abuse. I think fans of horror will like this more than I did, although it's not precisely horror. It looks at the way one's perception of self and others can change by passing through a profound physical transformation. (5) "Spider Hill" by Donald Mead: I liked this story a lot better. It's about witchcraft and farm magic, about family secrets, and a sort of coming-of-age story (for a girl rather than a boy, for once). The main character is resourceful, determined, but also empathetic and aware of the impact of her actions, which made her more fun to read about. I doubt I'll remember this for too long, but when skimming through it again for a review, I had fond memories of it. (6) "Where Have All the Young Men Gone?" by Albert E. Cowdrey: Cowdrey in his paranormal investigation mode, which I like better than his horror mode. For once, the protagonist isn't even a lower-class or backwoods character. Instead, he's a military historian travelling in Austria who runs across a local ghost story. This is a fairly straightforward ghost investigation that follows a familiar path (albeit to an unusual final destination), but Cowdrey is a good story-teller and I liked the protagonist. (7) "Overtaken" by Karl Bunker: This is the sort of story that delivers its moral with the force of a hammer. It's not subtle. But if you're in the right mood for that, it's one of the better stories of its type. It's about a long-journey starship, crew in hibernation, that's overtaken by a far newer and faster mechanized ship from Earth that's attempting to re-establish contact with the old ships. The story is a conversation between the ship AIs. Save this one until you're in the mood for an old-fashioned defense of humanity. (8) "Time and Tide" by Alan Peter Ryan: Another pseudo-horror story, although I think it's better classified as a haunting. A wardrobe recalls a traumatic drowning in the childhood of the protagonist. As these things tend to do in stories like this, reality and memory start blurring and the wardrobe takes on a malevolent role. Not my sort of thing. (3) "What We Found" by Geoff Ryman: Any new Geoff Ryman story is something to celebrate. This is a haunting story on the boundaries between the scientific method and tribal superstition, deeply entangled with the question of how one recovers from national and familial trauma. How can we avoid passing the evils and madness of one generation down to the next? Much of the story is about family trauma, told with Ryman's exceptional grasp of character, but the science is entangled in an ingenious way that I won't spoil. As with Air, this is in no way science fiction. The science here would have fascinating and rather scary implications for our world, but clearly is not how science actually works. But as an insight into politics, and into healing, I found it a startlingly effective metaphor. I loved every bit of this. By far the best story of the issue. (9) Rating: 7 out of 10

6 April 2014

Julien Danjou: Doing A/B testing with Apache httpd

When I started to write the landing page for The Hacker's Guide to Python, I wanted to try new things at the same time. I read about A/B testing a while ago, and I figured it was a good opportunity to test it out. A/B testing If you do not know what A/B testing is about, take a quick look at the Wikipedia page on that subject. Long story short, the idea is to serve two different version of a page to your visitors and check which one is getting the most success. When you found which version is better, you can definitely switch to it. In the case of my book, I used that technique on the pre-launch page where people were able to subscribe to the newsletter. I didn't have a lot of things I wanted to test out on that page, so I just used that approach on the subtitle, being either "Learn everything you need to build a successful Python project" or "It's time you make the most out of Python". Statistically, each version would be served half of the time, so both would get the same number of view. I then would build statistics about which page was attracting the most subscribers. With the results I would be able to switch definitively to that version of the landing page. Technical design My Web site, this Web site, is entirely static and served by Apache httpd. I didn't want to use any dynamic page, language or whatever. Mainly because I didn't want to have something else to install and maintain just for that on my server. It turns out that Apache httpd is powerful enough to implement such a feature. There are different ways to build it, and I'm going to describe my choices here. The first thing to pick is a way to balance the display of the page. You need to find a way so that if you get 100 visitors, around 50 will see the version A of your page, and around 50 will see the version B of the page. You could use a random number generator, pick a random number for each visitor, and decides which page he's going to see. But it turns out that I didn't find a way to do that with Apache httpd at first sight. My second thought was to pick the client IP address. But it's not such a good idea, because if you got visitors from, for example, people behind a company firewall, they are all going to be served the same page, so that kind of kills the statistics. Finally, I picked time based balancing: if you visit the page on a second that is even, you get version A of the page, and if you visit the page on a second that is odd, you get version B. Simple, and so far nothing proves there are more visitors on even than odd seconds, or vice-versa. The next thing is to always serve the same page to a returning visitor. I mean that if the visitor comes back later and get a different version, that's cheating. I decided the system should always serve the same page once a visitor "picked" a version. To do that, it's simple enough, you just have to use cookies to store the page the visitor has been attributed, and then use that cookie if he comes back. Implementation To do that in Apache httpd, I used the powerful mod_rewrite that is shipped with it. I put 2 files in the books directory, named either "the-hacker-guide-to-python-a.html" and "the-hacker-guide-to-python-b.html" that got served when you requested "/books/the-hacker-guide-to-python".
RewriteEngine On
RewriteBase /books

# If there's a cookie called thgtp-pre-version set,
# use its value and serve the page
RewriteCond % HTTP_COOKIE thgtp-pre-version=([^;])
RewriteRule ^the-hacker-guide-to-python$ % REQUEST_FILENAME -%1.html [L]

# No cookie yet and
RewriteCond % HTTP_COOKIE !thgtp-pre-version=([^;]+)
# the number of seconds of the time right now is even
RewriteCond % TIME_SEC [02468]$
# Then serve the page A and store "a" in a cookie
RewriteRule ^the-hacker-guide-to-python$ % REQUEST_FILENAME -a.html [cookie=thgtp-pre-version:a:julien.danjou.info,L]

# No cookie yet and
RewriteCond % HTTP_COOKIE !thgtp-pre-version=([^;]+)
# the number of seconds of the time right now is odd
RewriteCond % TIME_SEC [13579]$
# Then serve the page B and store "b" in a cookie
RewriteRule ^the-hacker-guide-to-python$ % REQUEST_FILENAME -b.html [cookie=thgtp-pre-version:b:julien.danjou.info,L]

With that few lines, it worked flawlessly. Results The results were very good, as it worked perfectly. Combined with Google Analytics, I was able to follow the score of each page. It turns out that testing this particular little piece of content of the page was, as expected, really useless. The final score didn't allow to pick any winner. Which also kind of proves that the system worked perfectly.
But it still was an interesting challenge!

Steve Kemp: So that distribution I'm not-building?

The other week I was toying with using GNU stow to build an NFS-share, which would allow remote machines to boot from it. It worked. It worked well. (Standard stuff, PXE booting with an NFS-root.) Then I started wondering about distributions, since in one sense what I'd built was a minimal distribution. On that basis yesterday I started hacking something more minimal: Unfortunately here is where I ran out of patience. Using tcc and the static C library I can compile code. But I can't link it.
$ cat > t.c <>EOF
int main ( int argc, char *argv[] )
 
        printf("OK\n" );
        return 1;
 
EOF
$ /opt/tcc/bin/tcc t.c
tcc: error: file 'crt1.o' not found
tcc: error: file 'crti.o' not found
..
Attempting to fix this up resulted in nothing much better:
$ /opt/tcc/bin/tcc t.c -I/opt/musl/include -L/opt/musl/lib/
And because I don't have a full system I cannot compile t.c to t.o and use ld to link (because I have no ld.) I had a brief flirt with the portable c-compiler, pcc, but didn't get any further with that. I suspect the real solution here is to install gcc onto my host system, with something like --prefix=/opt/gcc, and then rsync that into my (suddenly huge) intramfs image. Then I have all the toys.

Russell Coker: Finding Corrupt Files that cause a Kernel Error

There is a BTRFS bug in kernel 3.13 which is triggered by Kmail and causes Kmail index files to become seriously corrupt. Another bug in BTRFS causes a kernel GPF when an application tries to read such a file, that results in a SEGV being sent to the application. After that the kernel ceases to operate correctly for any files on that filesystem and no command other than reboot -nf (hard reset without flushing write-back caches) can be relied on to work correctly. The second bug should be fixed in Linux 3.14, I m not sure about the first one. In the mean time I have several systems running Kmail on BTRFS which have this problem. (strace tar cf . cat > /dev/null) 2>&1 tail To discover which file is corrupt I run the above command after a reboot. Below is a sample of the typical output of that command which shows that the file named .trash.index is corrupt. After discovering the file name I run reboot -nf and then delete the file (the file can be deleted on a clean system but not after a kernel GPF). Of recent times I ve been doing this about once every 5 days, so on average each Kmail/BTRFS system has been getting disk corruption every two weeks. Fortunately every time the corruption has been on an index file so I don t need to restore from backups. newfstatat(4, ".trash.index", st_mode=S_IFREG 0600, st_size=33, , AT_SYMLINK_NOFOLLOW) = 0
openat(4, ".trash.index", O_RDONLY O_NOCTTY O_NONBLOCK O_NOFOLLOW O_CLOEXEC) = 5
fstat(5, st_mode=S_IFREG 0600, st_size=33, ) = 0
read(5, <unfinished >
+++ killed by SIGSEGV +++

Stefano Zacchiroli: historical overview of debian source code

moar, and moar, and moar debsources stats A while ago I've announced the availability of several stats about Debian source code on http://sources.debian.net. Since then the statistical basis of those stats has increased a lot, and now includes all Debian historical releases, from hamm (July 1998) onward. This allows to appreciate macro-level evolution trends in Free Software, over a period of more than 15 years, through the eyes of a distro that sits at the nice intersection of the eldest, largest, and most reputed distros. To get there I've added support for sticky suites to the plumbing layer of debsources, and then injected historical releases from http://archive.debian.org. The injection process took about a week (without any sort of parallelism, pretty slow disks, and computing sha256 checksums, ctags, and sloccount on all source files) and has been an "interesting" experience. When you go back decades in technology time, bit rot is just around the corner, and I've found my share while injecting archive.d.o into sources.d.n. In both cases the respective maintainers (Guillem and Ganneff, kudos) have been positive about and helpful in improving the situation, despite the low impact of the bugs I've found on the average user. That's quite important for the long-term preservation of digital information in general, and for the perennity of access to Free Software in the specific case of Debian. While we are it, I'm now maintaining a list of bugs affecting sources.d.n but belonging to other packages, in case you fancy helping out but are not a Python hacker. Interestingly enough, quite a bit of those bugs are related to the fact that tools debsources uses (e.g. ctags, sloccount) are also starting to show their age. You might wander why buzz, rex, and bo are still missing from sources.d.n. That's in fact for similar reasons. Before hamm Debian didn't have complete archive coverage in terms of Sources indexes and .dsc files. Given that debsources rely on both to extract source packages, it first needs to grow an additional abstraction layer that can cope with their absence. It's SMOP, and planned. And now let's have fun with ctags bombs. Yours truly,
Stefano Indiana Zacchiroli
(credits: KiBi, #debian-ftp)

Keith Packard: Java-Sound-on-Linux

Java Sound on Linux I m often in the position of having my favorite Java program (AltosUI) unable to make any sounds. Here s a history of the various adventures I ve had. Java and PulseAudio ALSA support When we started playing with Java a few years ago, we discovered that if PulseAudio were enabled, Java wouldn t make any sound. Presumably, that was because the ALSA emulation layer offered by PulseAudio wasn t capable of supporting Java. The fix for that was to make sure pulseaudio would never run. That s harder than it seems; pulseaudio is like the living dead; rising from the grave every time you kill it. As it s nearly impossible to install any desktop applications without gaining a bogus dependency on pulseaudio, the solution that works best is to make sure dpkg never manages to actually install the program with dpkg-divert:
# dpkg-divert --rename /usr/bin/pulseaudio
With this in place, Java was a happy camper for a long time. Java and PulseAudio Native support More recently, Java has apparently gained some native PulseAudio support in some fashion. Of course, I couldn t actually get it to work, even after running the PulseAudio daemon but some kind Debian developer decided that sound should be broken by default for all Java applications and selected the PulseAudio back-end in the Java audio configuration file. Fixing that involved learning about said Java audio configuration file and then applying patch to revert the Debian packaging damage.
$ cat /usr/lib/jvm/java-7-openjdk-amd64/jre/lib/sound.properties
...
#javax.sound.sampled.Clip=org.classpath.icedtea.pulseaudio.PulseAudioMixerProvider
#javax.sound.sampled.Port=org.classpath.icedtea.pulseaudio.PulseAudioMixerProvider
#javax.sound.sampled.SourceDataLine=org.classpath.icedtea.pulseaudio.PulseAudioMixerProvider
#javax.sound.sampled.TargetDataLine=org.classpath.icedtea.pulseaudio.PulseAudioMixerProvider
javax.sound.sampled.Clip=com.sun.media.sound.DirectAudioDeviceProvider
javax.sound.sampled.Port=com.sun.media.sound.PortMixerProvider
javax.sound.sampled.SourceDataLine=com.sun.media.sound.DirectAudioDeviceProvider
javax.sound.sampled.TargetDataLine=com.sun.media.sound.DirectAudioDeviceProvider
You can see the PulseAudio mistakes at the top of that listing, with the corrected native interface settings at the bottom. Java and single-open ALSA drivers It used to be that ALSA drivers could support multiple applications having the device open at the same time. Those with hardware mixing would use that to merge the streams together; those without hardware mixing might do that in the kernel itself. While the latter is probably not a great plan, it did make ALSA a lot more friendly to users. My new laptop is not friendly, and returns EBUSY when you try to open the PCM device more than once. After downloading the jdk and alsa library sources, I figured out that Java was trying to open the PCM device multiple times when using the standard Java sound API in the simplest possible way. I thought I was going to have to fix Java, when I figured out that ALSA provides user-space mixing with the dmix plugin. I enabled that on my machine and now all was well.
$ cat /etc/asound.conf
pcm.!default  
    type plug
    slave.pcm "dmixer"
 
pcm.dmixer   
    type dmix
    ipc_key 1024
    slave  
        pcm "hw:1,0"
        period_time 0
        period_size 1024
        buffer_size 4096
        rate 44100
     
    bindings  
        0 0
        1 1
     
 
ctl.dmixer  
    type hw
    card 1
 
ctl.!default  
    type hw
    card 1
 
As you can see, my sound card is not number 0, it s number 1, so if your card is a different number, you ll have to adapt as necessary.

Next.

Previous.


