Martin Meredith: Ubuntu Global Jam Birmingham (UK)


The Birmingham Bug Jammers at the Last event
The Birmingham Bug Jammers at the Last event
 When your laptop is being repaired (and it s still there, since August 28) you need imaginative ways to be connected.
Here is my Nokia N800 as something near to a desktop computer.
 Just few notices:
 Following zack's suggestions, I've been looking at RC bugs in my sparetime.
In two days (well, two evenings really), I've been able to cope with a good number of bugs:

 Modern daemon implementations can be run in a variety of ways, in a range of contexts. The daemon software itself can be a useful tool in environments where the associated traditional system service is neither needed nor desired. Unfortunately, common debian packaging practice has a tendency to conflate the two ideas, leading to some potentially nasty problems where only the tool itself is needed, but the system service is set up anyway. How would i fix it? i'd suggest that we make a distinction between packages that provide tools and packages that provide system services. A package that provides the system service foo would need to depend on a package that provides the tool foo. But the tool foo should be available through the package manager without setting up a system service automatically. Bad Examples Here are some examples of this class of problem i've seen recently:
Packages that include daemons for system services should place scripts in /etc/init.d to start or stop services at boot time or during a change of runlevel.I feel like this particular conflict must have been hashed out before at some level are there links to definitive discussion that i'm missing? Is there any reason we shouldn't push in general for this kind of distinction in debian daemon packages? Tags: daemons, packaging, policy
 Subscribing to packages on the PTS is really useful to stay informed of everything happening with those packages. Unfortunately, managing your PTS subscriptions is really a challenge. Here is how I proceed to subscribe to packages I forgot to subscribe after uploading them:
/org/packages.qa.debian.org/bin/get-summary-subscribers.pl grep your@emailpsql -A -t service=udd -c "select source from sources
where distribution='debian' and release='sid'
and maintainer_email='your@email'
union select source from uploaders
where distribution='debian' and release='sid'
and email='your@email';"
- You can them use
combine to find the packages you should subscribe to, and mass-subscribe using the email interface.
- Then, you are done, or almost done: mass-confirming PTS subscriptions is a PITA because of #340863.
Some more info:
- The PTS lives on master, in
/org/packages.qa.debian.org.
- The script that handles emails send to pts@ is
bin/control.pl.
- The spool dir for pending requests is
spool/. The files are simple text files.
- You can send multiple commands per email. Sending them in the subject might be broken. (at least it failed for me)
- You don't need to take special care of the From for your emails. It's ignored (unless you subscribe without specifying an email address).
 Email on a desktop Unix system is apparently a hard topic. At least, so far nobody seems to have solved it to my satisfaction... That's where the Pony Express comes in: a sensible /usr/bin/sendmail implementation for desktop sysstems:

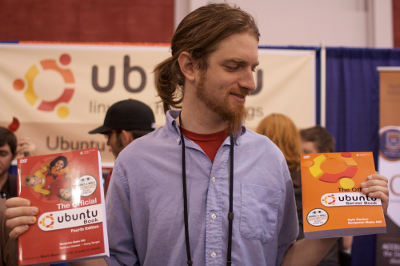 As I am attempting to focus on writing projects that are more scholarly
and academic on the one hand (i.e., work for my day job at MIT) and
more geared toward communicating free software principles toward wider
audiences on the other (e.g., Revealing Errors), I have little
choice but to back away from technical writing.
However, this last month has seen the culmination of a bunch of work
that I've done previously: two book projects that have been ongoing for
the last couple years or more have finally hit the shelves!
The first is the fourth edition (!) of the bestselling Official Ubuntu
Book. Much to my happiness, the book continues to do extremely well
and continues to receive solid reviews. This edition brings the book up
to date for Jaunty/9.04 and adds a few pieces here and there.
Although I was less active in this update than I have been in the past,
Corey Burger continued his great work and Matthew Helmke of Ubuntu
Forums fame stepped up to take a leading role. As I plan to retreat into
a more purely advisory role for the next edition of this book, I'm
thrilled to know that the project will remain in such capable hands.
I'm also thrilled that this edition of the book, like all previous
editions, is released as a free cultural work under CC BY-SA
For years, I have heard people say that although they like the Official
Ubuntu Book, it was a little too focused on desktops and on beginners
for their tastes. The newly released Official Ubuntu Server Book is
designed to address those concerns by providing an expanded guide to
more "advanced" topics and is targeted at system administrators trying
to get to know Ubuntu. Kyle Rankin planned and produced most of this
book but I was thrilled to help poke it in places, chime in during the
planning process, and to contribute a few chapters. Kyle is a
knowledgeable sysadmin and has done wonderful job with the book. I only
wish I could take more credit. The publisher has promised me that, at
the very least, my chapters will be distributed under CC BY-SA.
Many barriers to the adoption of free software are technical and a good
book can, and often does, make a big difference. I enjoy being able to
help address that problem. I also truly enjoy technical writing. I find
it satisfying to share something I know well with others and it is great
to know that I've helped someone with their problems. I'll assure I'll
be able to do things here and there, I'll miss technical writing as I
attempt "cut back."
 The Monad
Reader is a monthly newsletter by Haskellers. From the announcement
email:
This month's issue has a definite introductory theme. It includes republished
book reviews, notes on learning, a look at the differences between functional
and object oriented programming, and distributed computation.
As always, The Monad.Reader invites submissions on Haskell and related
topics. Send a summary or abstract for your article to shae@ScannedInAvian.com
-- Shae Matijs Erisson
Over the last few years, I've been pretty immersed in the world of
wikis. A wiki is like a collaborative web site; it lets several
people view and edit a web page and link to other pages, maybe new
pages that they themselves create.
Wikis let tech-savvy people all over the world collaborate on a
single web page, a single document. That's a pretty powerful idea,
really. The obvious thing to do once an idea like wikis appears is to attempt to cram all of humanity's
knowledge into it. Well that's just crazy enough to work.
Wikipedia is the gold
standard of wikis. It's a collaborative encyclopedia with lots and
lots of articles. As the gold standard, it influences people's
thinking about wikis in ways that might not be quite true.
If Wikipedia were the only wiki you'd ever heard of, you might
think that wikis are used to create encyclopedias. If that were true,
you'd really only need one of them.
If Wikipedia were the only wiki you'd ever heard of, you might be
under the false impression that all wikis everywhere are editable by
anyone. So if you create a wiki page, it's no longer yours. Other
people can scribble on it. Well, some kinds of documents perhaps just
aren't suitable for being edited by anyone, and the good news is that
you can build a wiki for you and your classmates, or you and your
coworkers, and you can decide who gets to edit what.
I want to think about a few distinct uses for wikis in different
contexts. The most common use is of course to create a knowledge
repository; a collection of information written by people who know
what they're talking about. That's what Wikipedia is, mostly. That's
what the Haskell Prime
wiki (which I run) is. And the excellent wiki about the game of Go,
Sensei's Library, is also a
knowledge repository.
But there are other uses for wikis that are pretty cool. I often
have to work on proposals with my coworkers. One (horrible) way to do
this is to write the first draft in MS Word, email it to everyone, who
might edit it and email it back. Of course, only one person can
actually edit it at a time, otherwise I have to figure out what
everyone did and merge their changes by hand. That's what we, in the
computer industry, call teh suck.
A better way to do this is to use a version control system, which lets
multiple people work on a document at one time. Of course, if you're
editing evil document formats like Word, still only one person can
edit it at a time, but at least you cut out email, so things are a bit
better organized.
But wikis are actually a really great way to work on a document
with another person. Two or more people can each collaborate on the
document using the wiki software over the web. What becomes of the
document at that point depends on its ultimate use. Maybe you have to
convert it to MS Word or PDF at the end. That's a bit of a bummer.
So there are two uses of wikis that I've mentioned: building a
knowledge repository, and collaborative writing.
Google started a service for collaborating on documents called Google Docs & Spreadsheets, which is
probably useful for collaborative writing, but not knowledge
repositories. They also acquired
a wiki startup a few days ago, so they are clearly trying to get
all over this space.
There's another very interesting use of wikis that I'll call
situation awareness. You can get a really vivid picture of
this use of wikis if you take a look at the
wikipedia article on the July 2005 London bombings. By the
way, I didn't discover this excellent example of situation awareness
using wikis. I saw it in the slides for a talk, but I don't know the
original source at this point.
If you go to that link, you'll see an excellent and up-to-date
encyclopedia article about the London bombings. It's not a news
article. Go to Google News and
try to find a news article from a major news source which is this
detailed, up-to-date, and well organized. Most articles you'll find
are a snapshot, taken at a particular point in time (when the article
was published) that most likely contains an account of the latest
developments, and usually brief background in case you missed previous
stories.
The wikipedia
article isn't a snapshot, it's an article that explains things in
a logical order, which isn't necessarily chronological.
Each wikipedia article contains a link to its own history. You can
look back over time and see the article evolve. If you look at the
early edit history of that London bombing article, you'll notice
something fascinating. The article was created shortly after the
bombing, with an account of the information that was known at that
time. Within an hour, many people had edited the article, adding
information they know about. If you were refreshing that wikipedia
entry over & over (or if you were subscribed to it using RSS), you'd
see not an account of just the latest developments, but an evolving,
logical understanding of the attacks. The article started evolving
right away, and it continues to evolve to this moment.
That's what I'm calling situation awareness. Don't get me
wrong, the mainstream news media is quite good at situation awareness.
They do it a bit differently, and their articles or TV stories don't
become integrated into a knowledge repository like wikipedia.
I've enumerated three somewhat overlapping uses for wikis that I
think are pretty interesting to examine:
I really enjoy the book The
Pragmatic Programmer. One of the suggestions in this book is to
learn one new programming language every year. Since the new year is
upon us, I though I'd suggest that this year, everyone should learn
Haskell.
So please apt-get install hugs, grab Yet Another
Haskell Tutorial, and get hacking. You'll probably want to have
the Libraries
API bookmarked. You might want to install the Glasgow Haskell Compiler after a
couple of hours.
When you get ready to package your first Haskell library for
Debian, be sure to check out the state of the Haskell Cabal (the Common
Architecture for Building Applications and Libraries).
Here's a basic implementation of cat in Haskell. Compile
With: ghc Cat.hs -o myCat
import System
main = do a <- getArgs
          contents <- sequence (map readFile a)
          putStrLn (concat contents)
I'd be very happy if folks email
me with suggestions on what programming language, API, technique,
paradigm, or whatever I should learn this year. You definitely get
extra points if you can give me a link to a good tutorial and if an
implementation of the language is packaged for Debian.
 Yesterday I received a mail message from a Debian user called Ekrem Erdem
about my previous post, proposing a different
partitioning schema that I found interesting.
The basic idea is to swap the order of the technologies, that is, use LVM on
top of an encrypted partition instead of encrypting logical volumes.
I never thought about this schema because I always use LVM on servers and that
is one of the fist things I setup (just after software RAID-1, if the machine
has two hard drives); when I was evaluating how to setup my system for
encryption I started with the LVM setup and never looked back.
The advantage of this setup is that there is only one pass phrase (the one used
to unlock the encrypted partition,
sda4 in my case), eliminating the need of
derived keys (i. e. my swap setup) or key files (I use them to mount snapshots
of the encrypted partition non interactively).
On the negative side I believe that this setup looses some flexibility:
After my followup to the Tuesday
post I've received some additional comments
and I'm writing this entry to close the subject... ;)
One of the comments was from Gunnar to tell me that the
followup setup was the same provided by the automatic partitioner of the
Debian Installer since 2007.
I was unaware of that because until some weeks ago I never tried to install a
system with encryption support and when I did it on my laptop I used the
manual setup because I wanted to keep the MacOS X partitions.
Anyway my followup blog entry made
sense anyway, as I just wanted to comment my thoughts about the advantages and
disadvantages of each partitioning schema.
I also received a couple of messages proposing the use of three layers to
keep the flexibility of the original setup and the simplicity of the second;
the setup is as follows:
        --- include.orig/linux/time.h   2005-04-21 09:03:16.000000000 +0900
        +++ include/linux/time.h        2005-05-04 15:29:52.266871616 +0900
        @@ -1,6 +1,10 @@
         #ifndef _LINUX_TIME_H
	...
         #ifdef __KERNEL__
=>      @@ -177,5 +181,6 @@ struct      itimerval
         #define TIMER_ABSTIME 0x01
	...
         #endif
        --- include.orig/linux/types.h  2005-04-21 09:03:16.000000000 +0900
        +++ include/linux/types.h       2005-05-04 15:30:14.515900970 +0900
        @@ -1,6 +1,16 @@
         #ifndef _LINUX_TYPES_H
	...
=>      @@ -169,4 +179,6 @@
                char                    f_fpack[6];
          ;
Then, I just exchanged the order of two parts as follows:
        --- include.orig/linux/types.h  2005-04-21 09:03:16.000000000 +0900
        +++ include/linux/types.h       2005-05-04 15:30:14.515900970 +0900
        @@ -1,6 +1,16 @@
         #ifndef _LINUX_TYPES_H
	...
         #include <linux>config.h>
=>      @@ -169,5 +179,7 @@
                char                    f_fpack[6];
          ;
        --- include.orig</linux>linux/time.h   2005-04-21 09:03:16.000000000 +0900
        +++ include/linux/time.h        2005-05-04 15:29:52.266871616 +0900
        @@ -1,6 +1,10 @@
         #ifndef _LINUX_TIME_H
	...
        +
         #ifdef __KERNEL__
=>      @@ -177,6 +181,7 @@ struct      itimerval
         #define TIMER_ABSTIME 0x01
	...
@@ lines are suddenly modified without any editing for patch lines.
This behavior is crazy.
I submitted the bug report to
Bug#201816
and
Bug#307617.
I think either this problem should be fixed or emacs should provide
the variable to stop @@ line modification via "setq" and so on.
slha-io.sh, tries to close that gap. Its description is:
This script is a very simple (and stupid) tool to get or set data in SLHA (SUSY Les Houches Accord) files. It can output complete blocks or individual data lines and replace existing data lines with user given input. It is stupid because it does not check after replacing data lines if the resultant file conforms to the SLHA. So care must be taken when using the set action.But as so often, it is best described by examples. The basic things you can do with
slha-io.sh are (MSSM.in is the SLHA file in these examples):
Here is another example of using$ slha-io.sh MSSM.in get modsel Block MODSEL # Select model 1 0 # MSSM 4 1 # R-parity is violated Block SMINPUTS # Standard Model inputs $ slha-io.sh MSSM.in get sminputs 6 6 1.729000E+02 # m_top(pole) $ slha-io.sh MSSM.in get sminputs 6 awk ' print $2 ' 1.729000E+02 $ slha-io.sh MSSM.in set sminputs 6 \ " 6 1.730000E+02 # m_top(pole)" $ slha-io.sh MSSM.in get sminputs 6 6 1.730000E+02 # m_top(pole)
slha-io.sh to create a batch of files where a parameter is constantly increased from 70 to 80 in steps of 0.5:
for NUM in  seq -f "%.8E" 70 0.5 80 ; do
    FILE = "m0_$NUM.in"
    cp MSSM.in "$FILE"
    slha-io.sh "$FILE" set minpar 1 " 1  $NUM  # m0"
done
Maybe this script is useful for one or two!
By the way, more sophisticated tools for SLHA I/O are SLHALib and SLHAio.
Next.
