Search Results: "sto"

11 June 2025

Freexian Collaborators: Debian Contributions: Updated Austin, DebConf 25 preparations continue and more! (by Anupa Ann Joseph)

Debian Contributions: 2025-05 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

Updated Austin, by Colin Watson and Helmut Grohne Austin is a frame stack sampling profiler for Python. It allows profiling Python applications without instrumenting them while losing some accuracy in the process, and is the only one of its kind presently packaged for Debian. Unfortunately, it hadn t been uploaded in a while and hence the last Python version it worked with was 3.8. We updated it to a current version and also dealt with a number of architecture-specific problems (such as unintended sign promotion, 64bit time_t fallout and strictness due to -Wformat-security ) in cooperation with upstream. With luck, it will migrate in time for trixie.

Preparing for DebConf 25, by Stefano Rivera and Santiago Ruano Rinc n DebConf 25 is quickly approaching, and the organization work doesn t stop. In May, Stefano continued supporting the different teams. Just to give a couple of examples, Stefano made changes in DebConf 25 website to make BoF and sprints submissions public, so interested people can already know if a BoF or sprint for a given subject is planned, allowing coordination with the proposer; or to enhance how statistics are made public to help the work of the local team. Santiago has participated in different tasks, including the logistics of the conference, like preparing more information about the public transportation that will be available. Santiago has also taken part in activities related to fundraising and reviewing more event proposals.

Miscellaneous contributions
  • Lucas fixed security issues in Valkey in unstable.
  • Lucas tried to help with the update of Redis to version 8 in unstable. The package hadn t been updated for a while due to licensing issues, but now upstream maintainers fixed them.
  • Lucas uploaded around 20 ruby-* packages to unstable that weren t updated for some years to make them build reproducible. Thanks to reproducible builds folks to point out those issues. Also some unblock requests (and follow-ups) were needed to make them reach trixie in time for the release.
  • Lucas is organizing a Debian Outreach session for DebConf 25, reaching out to all interns of Google Summer of Code and Outreachy programs from the last year. The session will be presented by in-person interns and also video recordings from the interns interested in participating but did not manage to attend the conference.
  • Lucas continuously works on DebConf Content team tasks. Replying to speakers, sponsors, and communicating internally with the team.
  • Carles improved po-debconf-manager: fixed bugs reported by Catalan translator, added possibility to import packages out of salsa, added using non-default project branches on salsa, polish to get ready for DebCamp.
  • Carles tested new apt in trixie and reported bugs to apt , installation-report , libqt6widget6 .
  • Carles used po-debconf-manager and imported remaining 80 packages, reviewed 20 translations, submitted (MR or bugs) 54 translations.
  • Carles prepared some topics for translation BoF in DebConf (gathered feedback, first pass on topics).
  • Helmut gave an introductory talk about the mechanics of Linux namespaces at MiniDebConf Hamburg.
  • Helmut sent 25 patches for cross compilation failures.
  • Helmut reviewed, refined and applied a patch from Jochen Sprickerhof to make the Multi-Arch hinter emit more hints for pure Python modules.
  • Helmut sat down with Christoph Berg (not affiliated with Freexian) and extended unschroot to support directory-based chroots with overlayfs. This is a feature that was lost in transitioning from sbuild s schroot backend to its unshare backend. unschroot implements the schroot API just enough to be usable with sbuild and otherwise works a lot like the unshare backend. As a result, apt.postgresql.org now performs its builds contained in a user namespace.
  • Helmut looked into a fair number of rebootstrap failures most of which related to musl or gcc-15 and imported patches or workarounds to make those builds proceed.
  • Helmut updated dumat to use sqop fixing earlier PGP verification problems thanks to Justus Winter and Neal Walfield explaining a lot of sequoia at MiniDebConf Hamburg.
  • Helmut got the previous zutils update for /usr-move wrong again and had to send another update.
  • Helmut looked into why debvm s autopkgtests were flaky and with lots of help from Paul Gevers and Michael Tokarev tracked it down to a race condition in qemu. He updated debvm to trigger the problem less often and also fixed a wrong dependency using Luca Boccassi s patch.
  • Santiago continued the switch to sbuild for Salsa CI (that was stopped for some months), and has been mainly testing linux, since it s a complex project that heavily customizes the pipeline. Santiago is preparing the changes for linux to submit a MR soon.
  • In openssh, Colin tracked down some intermittent sshd crashes to a root cause, and issued bookworm and bullseye updates for CVE-2025-32728.
  • Colin spent some time fixing up fail2ban, mainly reverting a patch that caused its tests to fail and would have banned legitimate users in some common cases.
  • Colin backported upstream fixes for CVE-2025-48383 (django-select2) and CVE-2025-47287 (python-tornado) to unstable.
  • Stefano supported video streaming and recording for 2 miniDebConfs in May: Macei and Hamburg. These had overlapping streams for one day, which is a first for us.
  • Stefano packaged the new version of python-virtualenv that includes our patches for not including the wheel for wheel.
  • Stefano got all involved parties to agree (in principle) to meet at DebConf for a mediated discussion on a dispute that was brought to the technical committee.
  • Anupa coordinated the swag purchase for DebConf 25 with Juliana and Nattie.
  • Anupa joined the publicity team meeting for discussing the upcoming events and BoF at DebConf 25.
  • Anupa worked with the publicity team to publish Bits post to welcome GSoc 2025 Interns.
Freexian Collaborators: Monthly report about Debian Long Term Support, May 2025 (by Roberto C. S nchez)

Like each month, have a look at the work funded by Freexian s Debian LTS offering.

Debian LTS contributors In May, 22 contributors have been paid to work on Debian LTS, their reports are available:
  • Abhijith PA did 8.0h (out of 0.0h assigned and 8.0h from previous period).
  • Adrian Bunk did 26.0h (out of 26.0h assigned).
  • Andreas Henriksson did 1.0h (out of 15.0h assigned and 3.0h from previous period), thus carrying over 17.0h to the next month.
  • Andrej Shadura did 3.0h (out of 10.0h assigned), thus carrying over 7.0h to the next month.
  • Bastien Roucari s did 20.0h (out of 20.0h assigned).
  • Ben Hutchings did 8.0h (out of 20.0h assigned and 4.0h from previous period), thus carrying over 16.0h to the next month.
  • Carlos Henrique Lima Melara did 12.0h (out of 11.0h assigned and 1.0h from previous period).
  • Chris Lamb did 15.5h (out of 0.0h assigned and 15.5h from previous period).
  • Daniel Leidert did 25.0h (out of 26.0h assigned), thus carrying over 1.0h to the next month.
  • Emilio Pozuelo Monfort did 21.0h (out of 16.75h assigned and 11.0h from previous period), thus carrying over 6.75h to the next month.
  • Guilhem Moulin did 11.5h (out of 8.5h assigned and 6.5h from previous period), thus carrying over 3.5h to the next month.
  • Jochen Sprickerhof did 3.5h (out of 8.75h assigned and 17.5h from previous period), thus carrying over 22.75h to the next month.
  • Lee Garrett did 26.0h (out of 12.75h assigned and 13.25h from previous period).
  • Lucas Kanashiro did 20.0h (out of 18.0h assigned and 2.0h from previous period).
  • Markus Koschany did 20.0h (out of 26.25h assigned), thus carrying over 6.25h to the next month.
  • Roberto C. S nchez did 20.75h (out of 24.0h assigned), thus carrying over 3.25h to the next month.
  • Santiago Ruano Rinc n did 15.0h (out of 12.5h assigned and 2.5h from previous period).
  • Sean Whitton did 6.25h (out of 6.0h assigned and 2.0h from previous period), thus carrying over 1.75h to the next month.
  • Sylvain Beucler did 26.25h (out of 26.25h assigned).
  • Thorsten Alteholz did 15.0h (out of 15.0h assigned).
  • Tobias Frost did 12.0h (out of 12.0h assigned).
  • Utkarsh Gupta did 1.0h (out of 15.0h assigned), thus carrying over 14.0h to the next month.

Evolution of the situation In May, we released 54 DLAs. The LTS Team was particularly active in May, publishing a higher than normal number of advisories, as well as helping with a wide range of updates to packages in stable and unstable, plus some other interesting work. We are also pleased to welcome several updates from contributors outside the regular team.
  • Notable security updates:
    • containerd, prepared by Andreas Henriksson, fixes a vulnerability that could cause containers launched as non-root users to be run as root
    • libapache2-mod-auth-openidc, prepared by Moritz Schlarb, fixes a vulnerability which could allow an attacker to crash an Apache web server with libapache2-mod-auth-openidc installed
    • request-tracker4, prepared by Andrew Ruthven, fixes multiple vulnerabilities which could result in information disclosure, cross-site scripting and use of weak encryption for S/MIME emails
    • postgresql-13, prepared by Bastien Roucari s, fixes an application crash vulnerability that could affect the server or applications using libpq
    • dropbear, prepared by Guilhem Moulin, fixes a vulnerability which could potentially result in execution of arbitrary shell commands
    • openjdk-17, openjdk-11, prepared by Thorsten Glaser, fixes several vulnerabilities, which include denial of service, information disclosure or bypass of sandbox restrictions
    • glibc, prepared by Sean Whitton, fixes a privilege escalation vulnerability
  • Notable non-security updates:
    • wireless-regdb, prepared by Ben Hutchings, updates information reflecting changes to radio regulations in many countries
This month s contributions from outside the regular team include the libapache2-mod-auth-openidc update mentioned above, prepared by Moritz Schlarb (the maintainer of the package); the update of request-tracker4, prepared by Andrew Ruthven (the maintainer of the package); and the updates of openjdk-17 and openjdk-11, also noted above, prepared by Thorsten Glaser. Additionally, LTS Team members contributed stable updates of the following packages:
  • rubygems and yelp/yelp-xsl, prepared by Lucas Kanashiro
  • simplesamlphp, prepared by Tobias Frost
  • libbson-xs-perl, prepared by Roberto C. S nchez
  • fossil, prepared by Sylvain Beucler
  • setuptools and mydumper, prepared by Lee Garrett
  • redis and webpy, prepared by Adrian Bunk
  • xrdp, prepared by Abhijith PA
  • tcpdf, prepared by Santiago Ruano Rinc n
  • kmail-account-wizard, prepared by Thorsten Alteholz
Other contributions were also made by LTS Team members to packages in unstable:
  • proftpd-dfsg DEP-8 tests (autopkgtests) were provided to the maintainer, prepared by Lucas Kanashiro
  • a regular upload of libsoup2.4, prepared by Sean Whitton
  • a regular upload of setuptools, prepared by Lee Garrett
Freexian, the entity behind the management of the Debian LTS project, has been working for some time now on the development of an advanced CI platform for Debian-based distributions, called Debusine. Recently, Debusine has reached a level of feature implementation that makes it very usable. Some members of the LTS Team have been using Debusine informally, and during May LTS coordinator Santiago Ruano Rinc n has made a call for the team to help with testing of Debusine, and to help evaluate its suitability for the LTS Team to eventually begin using as the primary mechanism for uploading packages into Debian. Team members who have started using Debusine are providing valuable feedback to the Debusine development team, thus helping to improve the platform for all users. Actually, a number of updates, for both bullseye and bookworm, made during the month of May were handled using Debusine, e.g. rubygems s DLA-4163-1. By the way, if you are a Debian Developer, you can easily test Debusine following the instructions found at https://wiki.debian.org/DebusineDebianNet. DebConf, the annual Debian Conference, is coming up in July and, as is customary each year, the week preceding the conference will feature an event called DebCamp. The DebCamp week provides an opportunity for teams and other interested groups/individuals to meet together in person in the same venue as the conference itself, with the purpose of doing focused work, often called sprints . LTS coordinator Roberto C. S nchez has announced that the LTS Team is planning to hold a sprint primarily focused on the Debian security tracker and the associated tooling used by the LTS Team and the Debian Security Team.

Thanks to our sponsors Sponsors that joined recently are in bold.

8 June 2025

Thorsten Alteholz: My Debian Activities in May 2025

Debian LTS This was my hundred-thirty-first month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian. During my allocated time I uploaded or worked on: I also continued my to work on libxmltok and suricata. This month I also had to do some support on seger, for example to inject packages newly needed for builds. Debian ELTS This month was the eighty-second ELTS month. During my allocated time I uploaded or worked on: All packages I worked on have been on the list of longstanding packages. For example espeak-ng has been on this list for more than nine month. I now understood that there is a reason why packages are on this list. Some parts of the software have been almost completely reworked, so that the patches need a reverse rework. For some packages this is easy, but for others this rework needs quite some time. I also continued to work on libxmltok and suricata. Debian Printing Unfortunately I didn t found any time to work on this topic. Debian Astro This month I uploaded bugfix versions of: Debian Mobcom This month I uploaded bugfix versions of: misc This month I uploaded bugfix versions of: Thanks a lot to the Release Team who quickly handled all my unblock bugs! FTP master It is this time of the year when just a few packages arrive in NEW: it is Hard Freeze. So I enjoy this period and basically just take care of kernels or other important packages. As people seem to be more interested in discussions than in fixing RC bugs, my period of rest seems to continue for a while. So thanks for all this valuable discussions and really thanks to the few people who still take care of Trixie. This month I accepted 146 and rejected 10 packages. The overall number of packages that got accepted was 147.

Colin Watson: Free software activity in May 2025

My Debian contributions this month were all sponsored by Freexian. Things were a bit quieter than usual, as for the most part I was sticking to things that seemed urgent for the upcoming trixie release. You can also support my work directly via Liberapay or GitHub Sponsors. OpenSSH After my appeal for help last month to debug intermittent sshd crashes, Michel Casabona helped me put together an environment where I could reproduce it, which allowed me to track it down to a root cause and fix it. (I also found a misuse of strlcpy affecting at least glibc-based systems in passing, though I think that was unrelated.) I worked with Daniel Kahn Gillmor to fix a regression in ssh-agent socket handling. I fixed a reproducibility bug depending on whether passwd is installed on the build system, which would have affected security updates during the lifetime of trixie. I backported openssh 1:10.0p1-5 to bookworm-backports. I issued bookworm and bullseye updates for CVE-2025-32728. groff I backported a fix for incorrect output when formatting multiple documents as PDF/PostScript at once. debmirror I added a simple autopkgtest. Python team I upgraded these packages to new upstream versions: In bookworm-backports, I updated these packages: I fixed problems building these packages reproducibly: I backported fixes for some security vulnerabilities to unstable (since we re in freeze now so it s not always appropriate to upgrade to new upstream versions): I fixed various other build/test failures: I added non-superficial autopkgtests to these packages: I packaged python-django-hashids and python-django-pgbulk, needed for new upstream versions of python-django-pgtrigger. I ported storm to Python 3.14. Science team I fixed a build failure in apertium-oci-fra.
7 June 2025

Evgeni Golov: show your desk - 2025 edition

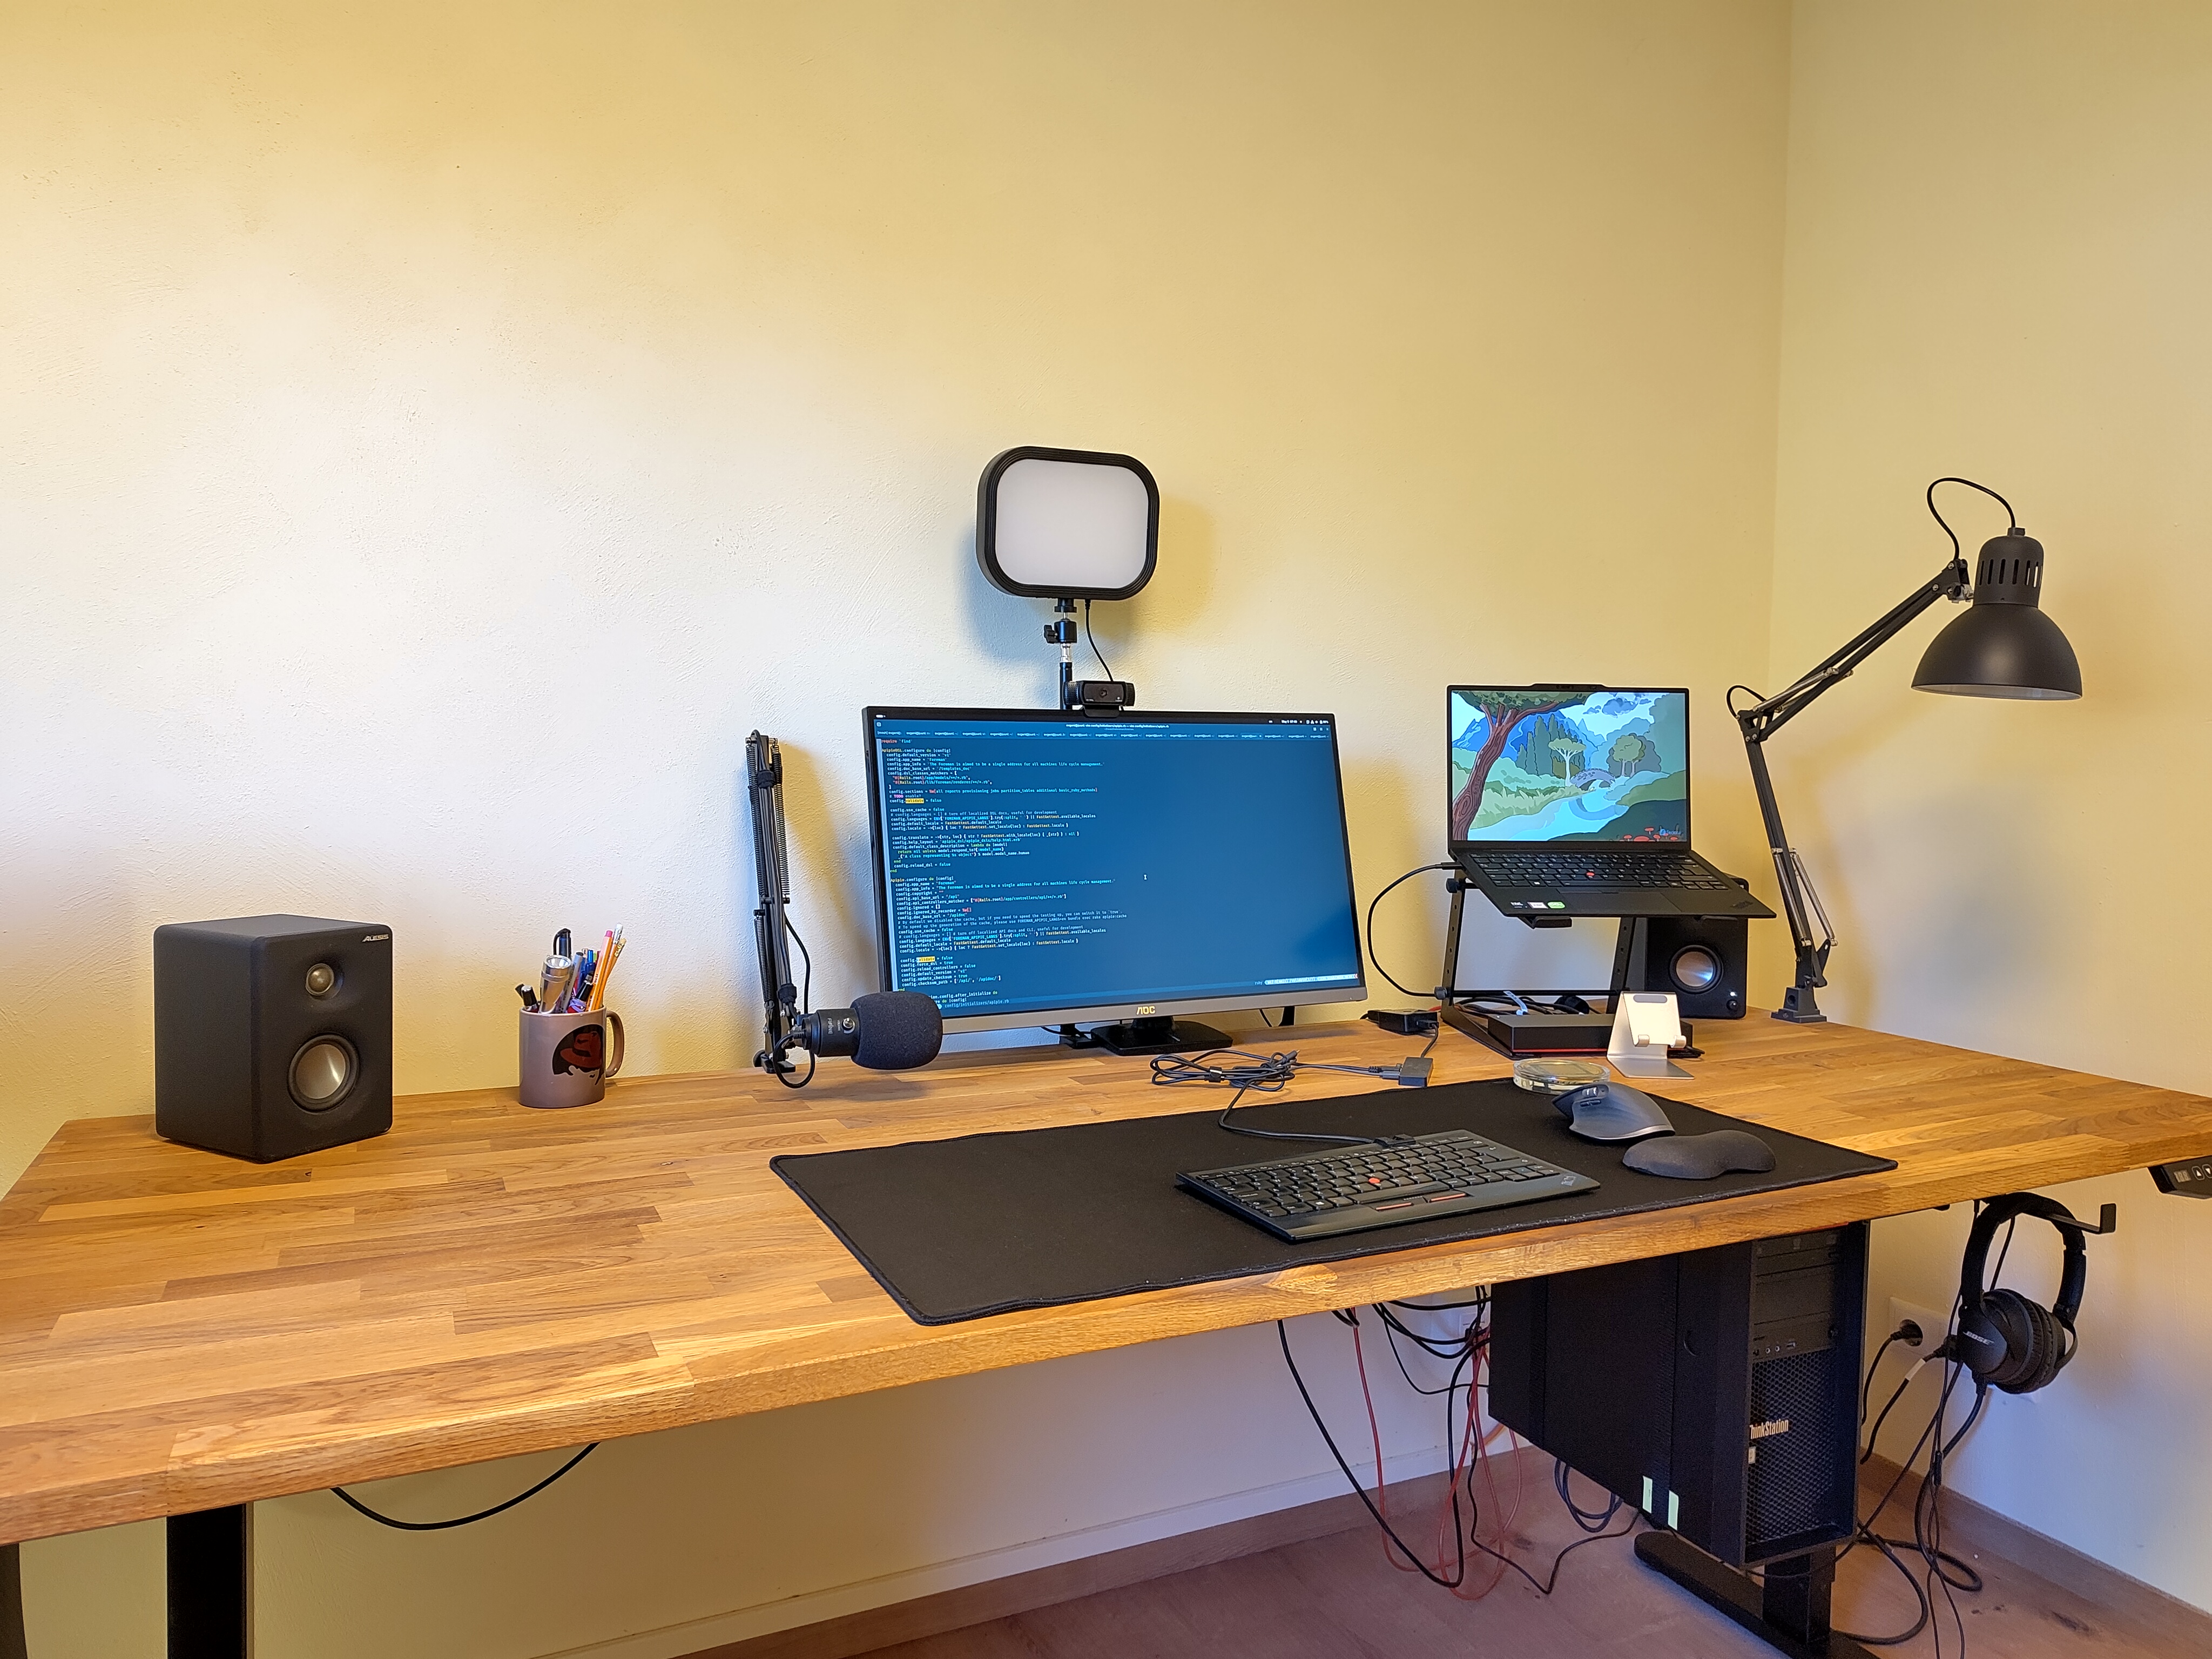
Back in 2020 I posted about my desk setup at home. Recently someone in our #remotees channel at work asked about WFH setups and given quite a few things changed in mine, I thought it's time to post an update. But first, a picture! standing desk with a monitor, laptop etc (Yes, it's cleaner than usual, how could you tell?!) desk It's still the same Flexispot E5B, no change here. After 7 years (I bought mine in 2018) it still works fine. If I'd have to buy a new one, I'd probably get a four-legged one for more stability (they got quite affordable now), but there is no immediate need for that. chair It's still the IKEA Volmar. Again, no complaints here. hardware Now here we finally have some updates! laptop A Lenovo ThinkPad X1 Carbon Gen 12, Intel Core Ultra 7 165U, 32GB RAM, running Fedora (42 at the moment). It's connected to a Lenovo ThinkPad Thunderbolt 4 Dock. It just works . workstation It's still the P410, but mostly unused these days. monitor An AOC U2790PQU 27" 4K. I'm running it at 150% scaling, which works quite decently these days (no comparison to when I got it). speakers As the new monitor didn't want to take the old Dell soundbar, I have upgraded to a pair of Alesis M1Active 330 USB. They sound good and were not too expensive. I had to fix the volume control after some time though. webcam It's still the Logitech C920 Pro. microphone The built in mic of the C920 is really fine, but to do conference-grade talks (and some podcasts ), I decided to get something better. I got a FIFINE K669B, with a nice arm. It's not a Shure, for sure, but does the job well and Christian was quite satisfied with the results when we recorded the Debian and Foreman specials of Focus on Linux. keyboard It's still the ThinkPad Compact USB Keyboard with TrackPoint. I had to print a few fixes and replacement parts for it, but otherwise it's doing great. Seems Lenovo stopped making those, so I really shouldn't break it any further. mouse Logitech MX Master 3S. The surface of the old MX Master 2 got very sticky at some point and it had to be replaced. other notepad I'm still terrible at remembering things, so I still write them down in an A5 notepad. whiteboard I've also added a (small) whiteboard on the wall right of the desk, mostly used for long term todo lists. coaster Turns out Xeon-based coasters are super stable, so it lives on! yubikey Yepp, still a thing. Still USB-A because... reasons. headphones Still the Bose QC25, by now on the third set of ear cushions, but otherwise working great and the odd 15 cushion replacement does not justify buying anything newer (which would have the same problem after some time, I guess). I did add a cheap (~10 ) Bluetooth-to-Headphonejack dongle, so I can use them with my phone too (shakes fist at modern phones). And I do use the headphones more in meetings, as the Alesis speakers fill the room more with sound and thus sometimes produce a bit of an echo. charger The Bose need AAA batteries, and so do some other gadgets in the house, so there is a technoline BC 700 charger for AA and AAA on my desk these days. light Yepp, I've added an IKEA Tertial and an ALDI "face" light. No, I don't use them much. KVM switch I've "built" a KVM switch out of an USB switch, but given I don't use the workstation that often these days, the switch is also mostly unused.
6 June 2025

Reproducible Builds: Reproducible Builds in May 2025

Welcome to our 5th report from the Reproducible Builds project in 2025! Our monthly reports outline what we ve been up to over the past month, and highlight items of news from elsewhere in the increasingly-important area of software supply-chain security. If you are interested in contributing to the Reproducible Builds project, please do visit the Contribute page on our website. In this report:
  1. Security audit of Reproducible Builds tools published
  2. When good pseudorandom numbers go bad
  3. Academic articles
  4. Distribution work
  5. diffoscope and disorderfs
  6. Website updates
  7. Reproducibility testing framework
  8. Upstream patches

Security audit of Reproducible Builds tools published The Open Technology Fund s (OTF) security partner Security Research Labs recently an conducted audit of some specific parts of tools developed by Reproducible Builds. This form of security audit, sometimes called a whitebox audit, is a form testing in which auditors have complete knowledge of the item being tested. They auditors assessed the various codebases for resilience against hacking, with key areas including differential report formats in diffoscope, common client web attacks, command injection, privilege management, hidden modifications in the build process and attack vectors that might enable denials of service. The audit focused on three core Reproducible Builds tools: diffoscope, a Python application that unpacks archives of files and directories and transforms their binary formats into human-readable form in order to compare them; strip-nondeterminism, a Perl program that improves reproducibility by stripping out non-deterministic information such as timestamps or other elements introduced during packaging; and reprotest, a Python application that builds source code multiple times in various environments in order to to test reproducibility. OTF s announcement contains more of an overview of the audit, and the full 24-page report is available in PDF form as well.

When good pseudorandom numbers go bad Danielle Navarro published an interesting and amusing article on their blog on When good pseudorandom numbers go bad. Danielle sets the stage as follows:
[Colleagues] approached me to talk about a reproducibility issue they d been having with some R code. They d been running simulations that rely on generating samples from a multivariate normal distribution, and despite doing the prudent thing and using set.seed() to control the state of the random number generator (RNG), the results were not computationally reproducible. The same code, executed on different machines, would produce different random numbers. The numbers weren t just a little bit different in the way that we ve all wearily learned to expect when you try to force computers to do mathematics. They were painfully, brutally, catastrophically, irreproducible different. Somewhere, somehow, something broke.
Thanks to David Wheeler for posting about this article on our mailing list

Academic articles There were two scholarly articles published this month that related to reproducibility: Daniel Hugenroth and Alastair R. Beresford of the University of Cambridge in the United Kingdom and Mario Lins and Ren Mayrhofer of Johannes Kepler University in Linz, Austria published an article titled Attestable builds: compiling verifiable binaries on untrusted systems using trusted execution environments. In their paper, they:
present attestable builds, a new paradigm to provide strong source-to-binary correspondence in software artifacts. We tackle the challenge of opaque build pipelines that disconnect the trust between source code, which can be understood and audited, and the final binary artifact, which is difficult to inspect. Our system uses modern trusted execution environments (TEEs) and sandboxed build containers to provide strong guarantees that a given artifact was correctly built from a specific source code snapshot. As such it complements existing approaches like reproducible builds which typically require time-intensive modifications to existing build configurations and dependencies, and require independent parties to continuously build and verify artifacts.
The authors compare attestable builds with reproducible builds by noting an attestable build requires only minimal changes to an existing project, and offers nearly instantaneous verification of the correspondence between a given binary and the source code and build pipeline used to construct it , and proceed by determining that t he overhead (42 seconds start-up latency and 14% increase in build duration) is small in comparison to the overall build time.
Timo Pohl, Pavel Nov k, Marc Ohm and Michael Meier have published a paper called Towards Reproducibility for Software Packages in Scripting Language Ecosystems. The authors note that past research into Reproducible Builds has focused primarily on compiled languages and their ecosystems, with a further emphasis on Linux distribution packages:
However, the popular scripting language ecosystems potentially face unique issues given the systematic difference in distributed artifacts. This Systemization of Knowledge (SoK) [paper] provides an overview of existing research, aiming to highlight future directions, as well as chances to transfer existing knowledge from compiled language ecosystems. To that end, we work out key aspects in current research, systematize identified challenges for software reproducibility, and map them between the ecosystems.
Ultimately, the three authors find that the literature is sparse , focusing on few individual problems and ecosystems, and therefore identify space for more critical research.

Distribution work In Debian this month:
Hans-Christoph Steiner of the F-Droid catalogue of open source applications for the Android platform published a blog post on Making reproducible builds visible. Noting that Reproducible builds are essential in order to have trustworthy software , Hans also mentions that F-Droid has been delivering reproducible builds since 2015 . However:
There is now a Reproducibility Status link for each app on f-droid.org, listed on every app s page. Our verification server shows or based on its build results, where means our rebuilder reproduced the same APK file and means it did not. The IzzyOnDroid repository has developed a more elaborate system of badges which displays a for each rebuilder. Additionally, there is a sketch of a five-level graph to represent some aspects about which processes were run.
Hans compares the approach with projects such as Arch Linux and Debian that provide developer-facing tools to give feedback about reproducible builds, but do not display information about reproducible builds in the user-facing interfaces like the package management GUIs.
Arnout Engelen of the NixOS project has been working on reproducing the minimal installation ISO image. This month, Arnout has successfully reproduced the build of the minimal image for the 25.05 release without relying on the binary cache. Work on also reproducing the graphical installer image is ongoing.
In openSUSE news, Bernhard M. Wiedemann posted another monthly update for their work there.
Lastly in Fedora news, Jelle van der Waa opened issues tracking reproducible issues in Haskell documentation, Qt6 recording the host kernel and R packages recording the current date. The R packages can be made reproducible with packaging changes in Fedora.

diffoscope & disorderfs diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading versions 295, 296 and 297 to Debian:
  • Don t rely on zipdetails --walk argument being available, and only add that argument on newer versions after we test for that. [ ]
  • Review and merge support for NuGet packages from Omair Majid. [ ]
  • Update copyright years. [ ]
  • Merge support for an lzma comparator from Will Hollywood. [ ][ ]
Chris also merged an impressive changeset from Siva Mahadevan to make disorderfs more portable, especially on FreeBSD. disorderfs is our FUSE-based filesystem that deliberately introduces non-determinism into directory system calls in order to flush out reproducibility issues [ ]. This was then uploaded to Debian as version 0.6.0-1. Lastly, Vagrant Cascadian updated diffoscope in GNU Guix to version 296 [ ][ ] and 297 [ ][ ], and disorderfs to version 0.6.0 [ ][ ].

Website updates Once again, there were a number of improvements made to our website this month including:

Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. However, Holger Levsen posted to our mailing list this month in order to bring a wider awareness to funding issues faced by the Oregon State University (OSU) Open Source Lab (OSL). As mentioned on OSL s public post, recent changes in university funding makes our current funding model no longer sustainable [and that] unless we secure $250,000 in committed funds, the OSL will shut down later this year . As Holger notes in his post to our mailing list, the Reproducible Builds project relies on hardware nodes hosted there. Nevertheless, Lance Albertson of OSL posted an update to the funding situation later in the month with broadly positive news.
Separate to this, there were various changes to the Jenkins setup this month, which is used as the backend driver of for both tests.reproducible-builds.org and reproduce.debian.net, including:
  • Migrating the central jenkins.debian.net server AMD Opteron to Intel Haswell CPUs. Thanks to IONOS for hosting this server since 2012.
  • After testing it for almost ten years, the i386 architecture has been dropped from tests.reproducible-builds.org. This is because that, with the upcoming release of Debian trixie, i386 is no longer supported as a regular architecture there will be no official kernel and no Debian installer for i386 systems. As a result, a large number of nodes hosted by Infomaniak have been retooled from i386 to amd64.
  • Another node, ionos17-amd64.debian.net, which is used for verifying packages for all.reproduce.debian.net (hosted by IONOS) has had its memory increased from 40 to 64GB, and the number of cores doubled to 32 as well. In addition, two nodes generously hosted by OSUOSL have had their memory doubled to 16GB.
  • Lastly, we have been granted access to more riscv64 architecture boards, so now we have seven such nodes, all with 16GB memory and 4 cores that are verifying packages for riscv64.reproduce.debian.net. Many thanks to PLCT Lab, ISCAS for providing those.

Outside of this, a number of smaller changes were also made by Holger Levsen:
  • reproduce.debian.net-related:
    • Only use two workers for the ppc64el architecture due to RAM size. [ ]
    • Monitor nginx_request and nginx_status with the Munin monitoring system. [ ][ ]
    • Detect various variants of network and memory errors. [ ][ ][ ][ ]
    • Add a prominent link to reproducible-builds.org. [ ]
    • Add a rebuilderd-cache-cleanup.service and run it daily via timer. [ ][ ][ ][ ][ ]
    • Be more verbose what sources are being downloaded. [ ]
    • Correctly deal with packages with an epoch in their version [ ] and deal with binNMUs versions with an epoch as well [ ][ ].
    • Document how to reschedule all other errors on all archs. [ ]
    • Misc documentation improvements. [ ][ ][ ][ ]
    • Include the $HOSTNAME variable in the rebuilderd logfiles. [ ]
    • Install the equivs package on all worker nodes. [ ][ ]
  • Jenkins nodes:
    • Permit the sudo tool to fix up permission issues. [ ][ ]
    • Document how to manage diskspace with OpenStack. [ ]
    • Ignore a number of spurious monitoring errors on riscv64, FreeBSD, etc.. [ ][ ][ ][ ]
    • Install ntpsec-ntpdate (instead of ntpdate) as the former is available on Debian trixie and bookworm. [ ][ ]
    • Use the same SSH ControlPath for all nodes. [ ]
    • Make sure the munin user uses the same SSH config as the jenkins user. [ ]
  • tests.reproducible-builds.org-related:
    • Disable testing of the i386 architecture. [ ][ ][ ][ ][ ]
    • Document the current disk usage. [ ][ ]
    • Address some image placement now that we only test three architectures. [ ]
    • Keep track of build performance. [ ]
  • Misc:
    • Fix a (harmless) typo in the multiarch_versionskew script. [ ]
In addition, Jochen Sprickerhof made a series of changes related to reproduce.debian.net:
  • Add out of memory detection to the statistics page. [ ]
  • Reverse the sorting order on the statistics page. [ ][ ][ ][ ]
  • Improve the spacing between statistics groups. [ ]
  • Update a (hard-coded) line number in error message detection pertaining to a debrebuild line number. [ ]
  • Support Debian unstable in the rebuilder-debian.sh script. [ ] ]
  • Rely on rebuildctl to sync only arch-specific packages. [ ][ ]

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. This month, we wrote a large number of such patches, including:

Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Dirk Eddelbuettel: #49: The Two Cultures of Deploying Statistical Software

Welcome to post 49 in the R4 series. The Two Cultures is a term first used by C.P. Snow in a 1959 speech and monograph focused on the split between humanities and the sciences. Decades later, the term was (quite famously) re-used by Leo Breiman in a (somewhat prophetic) 2001 article about the split between data models and algorithmic models . In this note, we argue that statistical computing practice and deployment can also be described via this Two Cultures moniker. Referring to the term linking these foundational pieces is of course headline bait. Yet when preparing for the discussion of r2u in the invited talk in Mons (video, slides), it occurred to me that there is in fact a wide gulf between two alternative approaches of using R and, specifically, deploying packages. On the one hand we have the approach described by my friend Jeff as you go to the Apple store, buy the nicest machine you can afford, install what you need and then never ever touch it . A computer / workstation / laptop is seen as an immutable object where every attempt at change may lead to breakage, instability, and general chaos and is hence best avoided. If you know Jeff, you know he exaggerates. Maybe only slightly though. Similarly, an entire sub-culture of users striving for reproducibility (and sometimes also replicability ) does the same. This is for example evidenced by the popularity of package renv by Rcpp collaborator and pal Kevin. The expressed hope is that by nailing down a (sub)set of packages, outcomes are constrained to be unchanged. Hope springs eternal, clearly. (Personally, if need be, I do the same with Docker containers and their respective Dockerfile.) On the other hand, rolling is fundamentally different approach. One (well known) example is Google building everything at @HEAD . The entire (ginormous) code base is considered as a mono-repo which at any point in time is expected to be buildable as is. All changes made are pre-tested to be free of side effects to other parts. This sounds hard, and likely is more involved than an alternative of a whatever works approach of independent changes and just hoping for the best. Another example is a rolling (Linux) distribution as for example Debian. Changes are first committed to a staging place (Debian calls this the unstable distribution) and, if no side effects are seen, propagated after a fixed number of days to the rolling distribution (called testing ). With this mechanism, testing should always be installable too. And based on the rolling distribution, at certain times (for Debian roughly every two years) a release is made from testing into stable (following more elaborate testing). The released stable version is then immutable (apart from fixes for seriously grave bugs and of course security updates). So this provides the connection between frequent and rolling updates, and produces immutable fixed set: a release. This Debian approach has been influential for any other projects including CRAN as can be seen in aspects of its system providing a rolling set of curated packages. Instead of a staging area for all packages, extensive tests are made for candidate packages before adding an update. This aims to ensure quality and consistence and has worked remarkably well. We argue that it has clearly contributed to the success and renown of CRAN. Now, when accessing CRAN from R, we fundamentally have two accessor functions. But seemingly only one is widely known and used. In what we may call the Jeff model , everybody is happy to deploy install.packages() for initial installations. That sentiment is clearly expressed by this bsky post:

One of my #rstats coding rituals is that every time I load a @vincentab.bsky.social package I go check for a new version because invariably it s been updated with 18 new major features
And that is why we have two cultures. Because some of us, yours truly included, also use update.packages() at recurring (frequent !!) intervals: daily or near-daily for me. The goodness and, dare I say, gift of packages is not limited to those by my pal Vincent. CRAN updates all the time, and updates are (generally) full of (usually excellent) changes, fixes, or new features. So update frequently! Doing (many but small) updates (frequently) is less invasive than (large, infrequent) waterfall -style changes! But the fear of change, or disruption, is clearly pervasive. One can only speculate why. Is the experience of updating so painful on other operating systems? Is it maybe a lack of exposure / tutorials on best practices? These Two Cultures coexist. When I delivered the talk in Mons, I briefly asked for a show of hands among all the R users in the audience to see who in fact does use update.packages() regularly. And maybe a handful of hands went up: surprisingly few! Now back to the context of installing packages: Clearly only installing has its uses. For continuous integration checks we generally install into ephemeral temporary setups. Some debugging work may be with one-off container or virtual machine setups. But all other uses may well be under maintained setups. So consider calling update.packages() once in while. Or even weekly or daily. The rolling feature of CRAN is a real benefit, and it is there for the taking and enrichment of your statistical computing experience. So to sum up, the real power is to use For both tasks, relying on binary installations accelerates and eases the process. And where available, using binary installation with system-dependency support as r2u does makes it easier still, following the r2u slogan of Fast. Easy. Reliable. Pick All Three. Give it a try!

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

5 June 2025

Matthew Garrett: Twitter's new encrypted DMs aren't better than the old ones

(Edit: Twitter could improve this significantly with very few changes - I wrote about that here. It's unclear why they'd launch without doing that, since it entirely defeats the point of using HSMs)

When Twitter[1] launched encrypted DMs a couple
of years ago, it was the worst kind of end-to-end
encrypted - technically e2ee, but in a way that made it relatively easy for Twitter to inject new encryption keys and get everyone's messages anyway. It was also lacking a whole bunch of features such as "sending pictures", so the entire thing was largely a waste of time. But a couple of days ago, Elon announced the arrival of "XChat", a new encrypted message platform built on Rust with (Bitcoin style) encryption, whole new architecture. Maybe this time they've got it right?

tl;dr - no. Use Signal. Twitter can probably obtain your private keys, and admit that they can MITM you and have full access to your metadata.

The new approach is pretty similar to the old one in that it's based on pretty straightforward and well tested cryptographic primitives, but merely using good cryptography doesn't mean you end up with a good solution. This time they've pivoted away from using the underlying cryptographic primitives directly and into higher level abstractions, which is probably a good thing. They're using Libsodium's boxes for message encryption, which is, well, fine? It doesn't offer forward secrecy (if someone's private key is leaked then all existing messages can be decrypted) so it's a long way from the state of the art for a messaging client (Signal's had forward secrecy for over a decade!), but it's not inherently broken or anything. It is, however, written in C, not Rust[2].

That's about the extent of the good news. Twitter's old implementation involved clients generating keypairs and pushing the public key to Twitter. Each client (a physical device or a browser instance) had its own private key, and messages were simply encrypted to every public key associated with an account. This meant that new devices couldn't decrypt old messages, and also meant there was a maximum number of supported devices and terrible scaling issues and it was pretty bad. The new approach generates a keypair and then stores the private key using the Juicebox protocol. Other devices can then retrieve the private key.

Doesn't this mean Twitter has the private key? Well, no. There's a PIN involved, and the PIN is used to generate an encryption key. The stored copy of the private key is encrypted with that key, so if you don't know the PIN you can't decrypt the key. So we brute force the PIN, right? Juicebox actually protects against that - before the backend will hand over the encrypted key, you have to prove knowledge of the PIN to it (this is done in a clever way that doesn't directly reveal the PIN to the backend). If you ask for the key too many times while providing the wrong PIN, access is locked down.

But this is true only if the Juicebox backend is trustworthy. If the backend is controlled by someone untrustworthy[3] then they're going to be able to obtain the encrypted key material (even if it's in an HSM, they can simply watch what comes out of the HSM when the user authenticates if there's no validation of the HSM's keys). And now all they need is the PIN. Turning the PIN into an encryption key is done using the Argon2id key derivation function, using 32 iterations and a memory cost of 16MB (the Juicebox white paper says 16KB, but (a) that's laughably small and (b) the code says 16 * 1024 in an argument that takes kilobytes), which makes it computationally and moderately memory expensive to generate the encryption key used to decrypt the private key. How expensive? Well, on my (not very fast) laptop, that takes less than 0.2 seconds. How many attempts to I need to crack the PIN? Twitter's chosen to fix that to 4 digits, so a maximum of 10,000. You aren't going to need many machines running in parallel to bring this down to a very small amount of time, at which point private keys can, to a first approximation, be extracted at will.

Juicebox attempts to defend against this by supporting sharding your key over multiple backends, and only requiring a subset of those to recover the original. I can't find any evidence that Twitter's does seem to be making use of this,Twitter uses three backends and requires data from at least two, but all the backends used are under x.com so are presumably under Twitter's direct control. Trusting the keystore without needing to trust whoever's hosting it requires a trustworthy communications mechanism between the client and the keystore. If the device you're talking to can prove that it's an HSM that implements the attempt limiting protocol and has no other mechanism to export the data, this can be made to work. Signal makes use of something along these lines using Intel SGX for contact list and settings storage and recovery, and Google and Apple also have documentation about how they handle this in ways that make it difficult for them to obtain backed up key material. Twitter has no documentation of this, and as far as I can tell does nothing to prove that the backend is in any way trustworthy. (Edit to add: The Juicebox API does support authenticated communication between the client and the HSM, but that relies on you having some way to prove that the public key you're presented with corresponds to a private key that only exists in the HSM. Twitter gives you the public key whenever you communicate with them, so even if they've implemented this properly you can't prove they haven't made up a new key and MITMed you the next time you retrieve your key)

On the plus side, Juicebox is written in Rust, so Elon's not 100% wrong. Just mostly wrong.

But ok, at least you've got viable end-to-end encryption even if someone can put in some (not all that much, really) effort to obtain your private key and render it all pointless? Actually no, since you're still relying on the Twitter server to give you the public key of the other party and there's no out of band mechanism to do that or verify the authenticity of that public key at present. Twitter can simply give you a public key where they control the private key, decrypt the message, and then reencrypt it with the intended recipient's key and pass it on. The support page makes it clear that this is a known shortcoming and that it'll be fixed at some point, but they said that about the original encrypted DM support and it never was, so that's probably dependent on whether Elon gets distracted by something else again. And the server knows who and when you're messaging even if they haven't bothered to break your private key, so there's a lot of metadata leakage.

Signal doesn't have these shortcomings. Use Signal.

[1] I'll respect their name change once Elon respects his daughter

[2] There are implementations written in Rust, but Twitter's using the C one with these JNI bindings

[3] Or someone nominally trustworthy but who's been compelled to act against your interests - even if Elon were absolutely committed to protecting all his users, his overarching goals for Twitter require him to have legal presence in multiple jurisdictions that are not necessarily above placing employees in physical danger if there's a perception that they could obtain someone's encryption keys

comment count unavailable comments

4 June 2025

Gunnar Wolf: The subjective value of privacy Assessing individuals' calculus of costs and benefits in the context of state surveillance

This post is an unpublished review for The subjective value of privacy Assessing individuals' calculus of costs and benefits in the context of state surveillance
Internet users, software developers, academics, entrepreneurs basically everybody is now aware of the importance of considering privacy as a core part of our online experience. User demand, and various national or regional laws, have made privacy a continuously present subject. And privacy is such an all-encompassing, complex topic, the angles from which it can be studied seems never to finish; I recommend computer networking-oriented newcomers to the topic to refer to Brian Kernighan s excellent work [1]. However, how do regular people like ourselves, in our many capacities feel about privacy? Lukas Antoine presents a series of experiments aiming at better understanding how people throughout the world understands privacy, and when is privacy held as more or less important than security in different aspects, Particularly, privacy is often portrayed as a value set at tension against surveillance, and particularly state surveillance, in the name of security: conventional wisdom presents the idea of privacy calculus. This is, it is often assumed that individuals continuously evaluate the costs and benefits of divulging their personal data, sharing data when they expect a positive net outcome, and denying it otherwise. This framework has been accepted for decades, and the author wishes to challenge it. This book is clearly his doctoral thesis on political sciences, and its contents are as thorough as expected in this kind of product. The author presents three empirical studies based on cross-survey analysis. The first experiment explores the security justifications for surveillance and how they influence their support. The second one searches whether the stance on surveillance can be made dependent on personal convenience or financial cost. The third study explores whether privacy attitude is context-dependant or can be seen as a stable personality trait. The studies aim to address the shortcomings of published literature in the field, mainly, (a) the lack of comprehensive research on state surveillance, needed or better understanding privacy appreciation, (b) while several studies have tackled the subjective measure of privacy, there is a lack of cross-national studies to explain wide-ranging phenomena, (c) most studies in this regard are based on population-based surveys, which cannot establish causal relationships, (d) a seemingly blind acceptance of the privacy calculus mentioned above, with no strong evidence that it accurately measures people s motivations for disclosing or withholding their data. The specific take, including the framing of the tension between privacy and surveillance has long been studied, as can be seen in Steven Nock s 1993 book [2], but as Sannon s article in 2022 shows [3], social and technological realities require our undertanding to be continuously kept up to date. The book is full with theoretical references and does a very good job of explaining the path followed by the author. It is, though, a heavy read, and, for people not coming from the social sciences tradition, leads to the occasional feeling of being lost. The conceptual and theoretical frameworks and presented studies are thorough and clear. The author is honest in explaining when the data points at some of his hypotheses being disproven, while others are confirmed. The aim of the book is for people digging deep into this topic. Personally, I have authored several works on different aspects of privacy (such as a book [4] and a magazine number [5]), but this book did get me thinking on many issues I had not previously considered. Looking for comparable works, I find Friedewald et al. s 2017 book [6] chapter organization to follow a similar thought line. My only complaint would be that, for the publication as part of its highly prestigious publisher, little attention has been paid to editorial aspects: sub-subsection depth is often excessive and unclear. Also, when publishing monographs based on doctoral works, it is customary to no longer refer to the work as a thesis and to soften some of the formal requirements such a work often has, with the aim of producing a more gentle and readable book; this book seems just like the mass-production of an (otherwise very interesting and well made) thesis work. References:

Gunnar Wolf: Computational modelling of robot personhood and relationality

This post is an unpublished review for Computational modelling of robot personhood and relationality
If humans and robots were to be able to roam around the same spaces, mutually recognizing each other for what they are, how would interaction be? How can we model such interactions in a way that we can reason about and understand the implications of a given behavior? This book aims at answering this question. The book is split into two very different parts. Chapters 1 through 3 are mostly written with a philosophical angle. It starts by framing the possibility of having sentient androids exist in the same plane as humans, without them trying to pass as us or vice versa. The first chapters look at issues related to personhood, that is, how androids can be treated as valid interaction partners in a society with humans, and how interactions with them can be seen as meaningful. In doing so, several landmarks of the past 40 years in the AI field are reviewed. The issues of the Significant Concerns that make up a society and give it coherence and of Personhood and Relationality , describing how this permeates from a society into each of the individuals that make it up, the relations between them and the social objects that bring individuals closer together (or farther apart) are introduced and explained. The second part of the book is written from a very different angle, and the change in pace took me somewhat by surprise. Each subsequent chapter presents a different angle of the Affinity system, a model that follows some aspects of human behavior over time and in a given space. Chapter 4 introduces the Affinity environment: a 3D simulated environment with simulated physical laws and characteristics, where a number of agents (30-50 is mentioned as usual) interact. Agents have a series of attributes ( value memory ), can adhere to different programs ( narratives ), and gain or lose on some vectors ( economy ). They can sense the world around them with sensors, and can modify the world or signal other agents using effectors. The last two chapters round out the book, as expected: the first presents a set of results from analyzing a given set of value systems, and the second gives readers the conclusions reached by the author. However, I was expecting more either having at least a link to download the Affinity system and continue exploring it or modifying some of the aspects it models to get it to model a set of agents with different stories and narratives, or extend it to yet unforseen behaviors, or at least have the author present a more complete comparison of results than the evaluation of patterns resulting from a given run. The author is a well-known, prolific author in the field, and I was expecting bigger insights from this book. Nevertheless, the book is an interesting and fun read, with important insights in both the first and second parts. There is a certain lack of connection between their respective rhythms, and the second part indeed builds on the concepts introduced in the first one. Overall, I enjoyed reading the book despite expecting more.

1 June 2025

Ben Hutchings: FOSS activity in May 2025

Guido G nther: Free Software Activities May 2025

Another short status update of what happened on my side last month. Larger blocks besides the Phosh 0.47 release are on screen keyboard and cell broadcast improvements, work on separate volume streams, the switch of phoc to wlroots 0.19.0 and effort to make Phosh work on Debian's upcoming stable release (Trixie) out of the box. Trixie will ship with Phosh 0.46, if you want to try out 0.47 you can fetch it from Debian's experimental suite. See below for details on the above and more: phosh phoc phosh-mobile-settings phosh-osk-stub / stevia phosh-tour phosh-osk-data pfs xdg-desktop-portal-phosh phrog phosh-debs meta-phosh feedbackd feedbackd-device-themes gmobile GNOME calls Debian ModemManager osmo-cbc gsm-cell-testing mobile-broadband-provider-info Cellbroadcastd phosh-site pipewire wireplumber python-dbusmock Bugs Reviews This is not code by me but reviews on other peoples code. The list is (as usual) slightly incomplete. Thanks for the contributions! Help Development If you want to support my work see donations. Comments? Join the Fediverse thread
31 May 2025

Russell Coker: Links May 2025

Christopher Biggs gave an informative Evrything Open lecture about voice recognition [1]. We need this on Debian phones. Guido wrote an informative blog post about booting a custom Android kernel on a Pixel 3a [2]. Good work in writing this up, but a pity that Google made the process so difficult. Interesting to read about an expert being a victim of a phishing attack [3]. It can happen to anyone, everyone has moments when they aren t concentrating. Interesting advice on how to leak to a journalist [4]. Brian Krebs wrote an informative article about the ways that Trump is deliberately reducing the cyber security of the US government [5]. Brian Krebs wrote an interesting article about the main smishng groups from China [6]. Louis Rossmann (who is known for high quality YouTube videos about computer repair) made an informative video about a scammy Australian company run by a child sex offender [7]. The Helmover was one of the wildest engineering projects of WW2, an over the horizon guided torpedo that could one-shot a battleship [8]. Interesting blog post about DDoSecrets and the utter failure of the company Telemessages which was used by the US government [9]. Jonathan McDowell wrote an interesting blog post about developing a free software competitor to Alexa etc, the listening hardware costs $13US per node [10]. Noema Magazine published an insightful article about Rewilding the Internet, it has some great ideas [11].

30 May 2025

Russell Coker: Service Setup Difficulties

Marco wrote a blog post opposing hyperscale systems which included We want to use an hyperscaler cloud because our developers do not want to operate a scalable and redundant database just means that you need to hire competent developers and/or system administrators. [1]. I previously wrote a blog post Why Clusters Usually Don t Work [2] and I believe that all the points there are valid today and possibly exacerbated by clusters getting less direct use as clustering is increasingly being done by hyperscale providers. Take a basic need, a MySQL or PostgreSQL database for example. You want it to run and basically do the job and to have good recovery options. You could set it up locally, run backups, test the backups, have a recovery plan for failures, maybe have a hot-spare server if it s really important, have tests for backups and hot-spare server, etc. Then you could have documentation for this so if the person who set it up isn t available when there s a problem they will be able to find out what to do. But the hyperscale option is to just select a database in your provider and have all this just work. If the person who set it up isn t available for recovery in the event of failure the company can just put out a job advert for person with experience on cloud company X and have them just immediately go to work on it. I don t like hyperscale providers as they are all monopolistic companies that do anti-competitive actions. Google should be broken up, Android development and the Play Store should be separated from Gmail etc which should be separated from search and adverts, and all of them should be separated from the GCP cloud service. Amazon should be broken up, running the Amazon store should be separated from selling items on the store, which should be separated from running a video on demand platform, and all of them should be separated from the AWS cloud. Microsoft should be broken up, OS development should be separated from application development all of that should be separated from cloud services (Teams and Office 365), and everything else should be separate from the Azure cloud system. But the cloud providers offer real benefits at small scale. Running a MySQL or PostgreSQL database for local services is easy, it s a simple apt command to install it and then it basically works. Doing backup and recovery isn t so easy. One could say just hire competent people but if you do hire competent people do you want them running MySQL databases etc or have them just click on the create mysql database option on a cloud control panel and then move on to more important things? The FreedomBox project is a great project for installing and managing home/personal services [3]. But it s not about running things like database servers, it s for a high level running mail servers and other things for the user not for the developer. The Debian packaging of Open Stack looks interesting [4], it s a complete setup for running your own hyper scale cloud service. For medium and large organisations running Open Stack could be a good approach. But for small organisations it s cheaper and easier to just use a cloud service to run things. The issue of when to run things in-house and when to put them in the cloud is very complex. I think that if the organisation is going to spend less money on cloud services than on the salary of one sysadmin then it s probably best to have things in the cloud. When cloud costs start to exceed the salary of one person who manages systems then having them spend the extra time and effort to run things locally starts making more sense. There is also an opportunity cost in having a good sysadmin work on the backups for all the different systems instead of letting the cloud provider just do it. Another possibility of course is to run things in-house on low end hardware and just deal with the occasional downtime to save money. Knowingly choosing less reliability to save money can be quite reasonable as long as you have considered the options and all the responsible people are involved in the discussion. The one situation that I strongly oppose is having hyper scale services setup by people who don t understand them. Running a database server on a cloud service because you don t want to spend the time managing it is a reasonable choice in many situations. Running a database server on a cloud service because you don t understand how to setup a database server is never a good choice. While the cloud services are quite resilient there are still ways of breaking the overall system if you don t understand it. Also while it is quite possible for someone to know how to develop for databases including avoiding SQL injection etc but be unable to setup a database server that s probably not going to be common, probably if someone can t set it up (a generally easy task) then they can t do the hard tasks of making it secure.

29 May 2025

Arthur Diniz: Bringing Kubernetes Back to Debian

I ve been part of the Debian Project since 2019, when I attended DebConf held in Curitiba, Brazil. That event sparked my interest in the community, packaging, and how Debian works as a distribution. In the early years of my involvement, I contributed to various teams such as the Python, Golang and Cloud teams, packaging dependencies and maintaining various tools. However, I soon felt the need to focus on packaging software I truly enjoyed, tools I was passionate about using and maintaining. That s when I turned my attention to Kubernetes within Debian.

A Broken Ecosystem The Kubernetes packaging situation in Debian had been problematic for some time. Given its large codebase and complex dependency tree, the initial packaging approach involved vendorizing all dependencies. While this allowed a somewhat functional package to be published, it introduced several long-term issues, especially security concerns. Vendorized packages bundle third-party dependencies directly into the source tarball. When vulnerabilities arise in those dependencies, it becomes difficult for Debian s security team to patch and rebuild affected packages system-wide. This approach broke Debian s best practices, and it eventually led to the abandonment of the Kubernetes source package, which had stalled at version 1.20.5. Due to this abandonment, critical bugs emerged and the package was removed from Debian s testing channel, as we can see in the package tracker.

New Debian Kubernetes Team Around this time, I became a Debian Maintainer (DM), with permissions to upload certain packages. I saw an opportunity to both contribute more deeply to Debian and to fix Kubernetes packaging. In early 2024, just before DebConf Busan in South Korea, I founded the Debian Kubernetes Team. The mission of the team was to repackage Kubernetes in a maintainable, security-conscious, and Debian-compliant way. At DebConf, I shared our progress with the broader community and received great feedback and more visibility, along with people interested in contributing to the team. Our first tasks was to migrate existing Kubernetes-related tools such as kubectx, kubernetes-split-yaml and kubetail into a dedicated namespace on Salsa, Debian s GitLab instance. Many of these tools were stored across different teams (like the Go team), and consolidating them helped us organize development and focus our efforts.

De-vendorizing Kubernetes Our main goal was to un-vendorize Kubernetes and bring it up-to-date with upstream releases. This meant:
  • Removing the vendor directory and all embedded third-party code.
  • Trimming the build scope to focus solely on building kubectl, Kubernetes CLI.
  • Using Files-Excluded in debian/copyright to cleanly drop unneeded files during source imports.
  • Rebuilding the dependency tree, ensuring all Go modules were separately packaged in Debian.
We used uscan, a standard Debian packaging tool that fetches upstream tarballs and prepares them accordingly. The Files-Excluded directive in our debian/copyright file instructed uscan to automatically remove unnecessary files during the repackaging process:
$ uscan
Newest version of kubernetes on remote site is 1.32.3, specified download version is 1.32.3
Successfully repacked ../v1.32.3 as ../kubernetes_1.32.3+ds.orig.tar.gz, deleting 30616 files from it.
The results were dramatic. By comparing the original upstream tarball with our repackaged version, we can see that our approach reduced the tarball size by over 75%:
$ du -h upstream-v1.32.3.tar.gz kubernetes_1.32.3+ds.orig.tar.gz
14M	upstream-v1.32.3.tar.gz
3.2M	kubernetes_1.32.3+ds.orig.tar.gz
This significant reduction wasn t just about saving space. By removing over 30,000 files, we simplified the package, making it more maintainable. Each dependency could now be properly tracked, updated, and patched independently, resolving the security concerns that had plagued the previous packaging approach.

Dependency Graph To give you an idea of the complexity involved in packaging Kubernetes for Debian, the image below is a dependency graph generated with debtree, visualizing all the Go modules and other dependencies required to build the kubectl binary. kubectl-depgraph This web of nodes and edges represents every module and its relationship during the compilation process of kubectl. Each box is a Debian package, and the lines connecting them show how deeply intertwined the ecosystem is. What might look like a mess of blue spaghetti is actually a clear demonstration of the vast and interconnected upstream world that tools like kubectl rely on. But more importantly, this graph is a testament to the effort that went into making kubectl build entirely using Debian-packaged dependencies only, no vendoring, no downloading from the internet, no proprietary blobs.
Upstream Version 1.32.3 and Beyond After nearly two years of work, we successfully uploaded version 1.32.3+ds of kubectl to Debian unstable. kubernetes/-/merge_requests/1 The new package also includes:
  • Zsh, Fish, and Bash completions installed automatically
  • Man pages and metadata for improved discoverability
  • Full integration with kind and docker for testing purposes

Integration Testing with Autopkgtest To ensure the reliability of kubectl in real-world scenarios, we developed a new autopkgtest suite that runs integration tests using real Kubernetes clusters created via Kind. Autopkgtest is a Debian tool used to run automated tests on binary packages. These tests are executed after the package is built but before it s accepted into the Debian archive, helping catch regressions and integration issues early in the packaging pipeline. Our test workflow validates kubectl by performing the following steps:
  • Installing Kind and Docker as test dependencies.
  • Spinning up two local Kubernetes clusters.
  • Switching between cluster contexts to ensure multi-cluster support.
  • Deploying and scaling a sample nginx application using kubectl.
  • Cleaning up the entire test environment to avoid side effects.
  • debian/tests/kubectl.sh

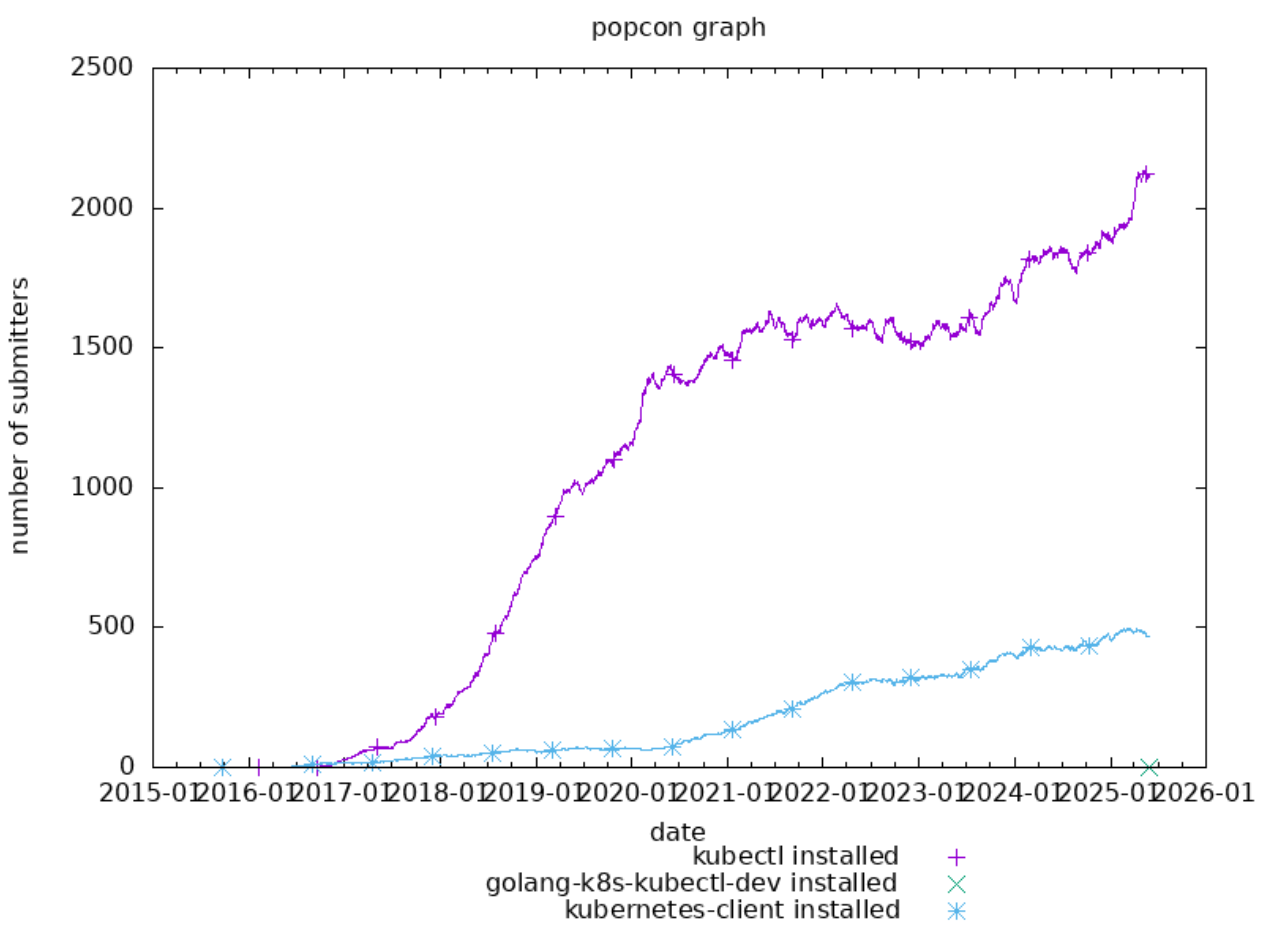
Popcon: Measuring Adoption To measure real-world usage, we rely on data from Debian s popularity contest (popcon), which gives insight into how many users have each binary installed. popcon-graph popcon-table Here s what the data tells us:
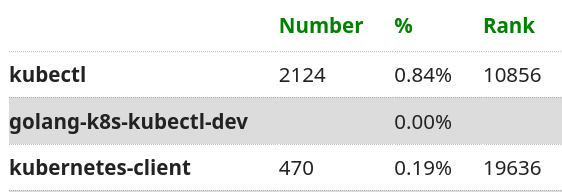
  • kubectl (new binary): Already installed on 2,124 systems.
  • golang-k8s-kubectl-dev: This is the Go development package (a library), useful for other packages and developers who want to interact with Kubernetes programmatically.
  • kubernetes-client: The legacy package that kubectl is replacing. We expect this number to decrease in future releases as more systems transition to the new package.
Although the popcon data shows activity for kubectl before the official Debian upload date, it s important to note that those numbers represent users who had it installed from upstream source-lists, not from the Debian repositories. This distinction underscores a demand that existed even before the package was available in Debian proper, and it validates the importance of bringing it into the archive.
Also worth mentioning: this number is not the real total number of installations, since users can choose not to participate in the popularity contest. So the actual adoption is likely higher than what popcon reflects.

Community and Documentation The team also maintains a dedicated wiki page which documents:
  • Maintained tools and packages
  • Contribution guidelines
  • Our roadmap for the upcoming Debian releases
https://debian-kubernetes.org

Looking Ahead to Debian 13 (Trixie) The next stable release of Debian will ship with kubectl version 1.32.3, built from a clean, de-vendorized source. This version includes nearly all the latest upstream features, and will be the first time in years that Debian users can rely on an up-to-date, policy-compliant kubectl directly from the archive. By comparing with upstream, our Debian package even delivers more out of the box, including shell completions, which the upstream still requires users to generate manually. In 2025, the Debian Kubernetes team will continue expanding our packaging efforts for the Kubernetes ecosystem. Our roadmap includes:
  • kubelet: The primary node agent that runs on each node. This will enable Debian users to create fully functional Kubernetes nodes without relying on external packages.
  • kubeadm: A tool for creating Kubernetes clusters. With kubeadm in Debian, users will then be able to bootstrap minimum viable clusters directly from the official repositories.
  • helm: The package manager for Kubernetes that helps manage applications through Kubernetes YAML files defined as charts.
  • kompose: A conversion tool that helps users familiar with docker-compose move to Kubernetes by translating Docker Compose files into Kubernetes resources.

Final Thoughts This journey was only possible thanks to the amazing support of the debian-devel-br community and the collective effort of contributors who stepped up to package missing dependencies, fix bugs, and test new versions. Special thanks to:
  • Carlos Henrique Melara (@charles)
  • Guilherme Puida (@puida)
  • Jo o Pedro Nobrega (@jnpf)
  • Lucas Kanashiro (@kanashiro)
  • Matheus Polkorny (@polkorny)
  • Samuel Henrique (@samueloph)
  • Sergio Cipriano (@cipriano)
  • Sergio Durigan Junior (@sergiodj)
I look forward to continuing this work, bringing more Kubernetes tools into Debian and improving the developer experience for everyone.

Arthur Diniz: Bringing Kubernetes Back to Debian

I ve been part of the Debian Project since 2019, when I attended DebConf held in Curitiba, Brazil. That event sparked my interest in the community, packaging, and how Debian works as a distribution. In the early years of my involvement, I contributed to various teams such as the Python, Golang and Cloud teams, packaging dependencies and maintaining various tools. However, I soon felt the need to focus on packaging software I truly enjoyed, tools I was passionate about using and maintaining. That s when I turned my attention to Kubernetes within Debian.

A Broken Ecosystem The Kubernetes packaging situation in Debian had been problematic for some time. Given its large codebase and complex dependency tree, the initial packaging approach involved vendorizing all dependencies. While this allowed a somewhat functional package to be published, it introduced several long-term issues, especially security concerns. Vendorized packages bundle third-party dependencies directly into the source tarball. When vulnerabilities arise in those dependencies, it becomes difficult for Debian s security team to patch and rebuild affected packages system-wide. This approach broke Debian s best practices, and it eventually led to the abandonment of the Kubernetes source package, which had stalled at version 1.20.5. Due to this abandonment, critical bugs emerged and the package was removed from Debian s testing channel, as we can see in the package tracker.

New Debian Kubernetes Team Around this time, I became a Debian Maintainer (DM), with permissions to upload certain packages. I saw an opportunity to both contribute more deeply to Debian and to fix Kubernetes packaging. In early 2024, just before DebConf Busan in South Korea, I founded the Debian Kubernetes Team. The mission of the team was to repackage Kubernetes in a maintainable, security-conscious, and Debian-compliant way. At DebConf, I shared our progress with the broader community and received great feedback and more visibility, along with people interested in contributing to the team. Our first tasks was to migrate existing Kubernetes-related tools such as kubectx, kubernetes-split-yaml and kubetail into a dedicated namespace on Salsa, Debian s GitLab instance. Many of these tools were stored across different teams (like the Go team), and consolidating them helped us organize development and focus our efforts.

De-vendorizing Kubernetes Our main goal was to un-vendorize Kubernetes and bring it up-to-date with upstream releases. This meant:
  • Removing the vendor directory and all embedded third-party code.
  • Trimming the build scope to focus solely on building kubectl, Kubernetes CLI.
  • Using Files-Excluded in debian/copyright to cleanly drop unneeded files during source imports.
  • Rebuilding the dependency tree, ensuring all Go modules were separately packaged in Debian.
We used uscan, a standard Debian packaging tool that fetches upstream tarballs and prepares them accordingly. The Files-Excluded directive in our debian/copyright file instructed uscan to automatically remove unnecessary files during the repackaging process:
$ uscan
Newest version of kubernetes on remote site is 1.32.3, specified download version is 1.32.3
Successfully repacked ../v1.32.3 as ../kubernetes_1.32.3+ds.orig.tar.gz, deleting 30616 files from it.
The results were dramatic. By comparing the original upstream tarball with our repackaged version, we can see that our approach reduced the tarball size by over 75%:
$ du -h upstream-v1.32.3.tar.gz kubernetes_1.32.3+ds.orig.tar.gz
14M	upstream-v1.32.3.tar.gz
3.2M	kubernetes_1.32.3+ds.orig.tar.gz
This significant reduction wasn t just about saving space. By removing over 30,000 files, we simplified the package, making it more maintainable. Each dependency could now be properly tracked, updated, and patched independently, resolving the security concerns that had plagued the previous packaging approach.

Dependency Graph To give you an idea of the complexity involved in packaging Kubernetes for Debian, the image below is a dependency graph generated with debtree, visualizing all the Go modules and other dependencies required to build the kubectl binary. kubectl-depgraph This web of nodes and edges represents every module and its relationship during the compilation process of kubectl. Each box is a Debian package, and the lines connecting them show how deeply intertwined the ecosystem is. What might look like a mess of blue spaghetti is actually a clear demonstration of the vast and interconnected upstream world that tools like kubectl rely on. But more importantly, this graph is a testament to the effort that went into making kubectl build entirely using Debian-packaged dependencies only, no vendoring, no downloading from the internet, no proprietary blobs.
Upstream Version 1.32.3 and Beyond After nearly two years of work, we successfully uploaded version 1.32.3+ds of kubectl to Debian unstable. kubernetes/-/merge_requests/1 The new package also includes:
  • Zsh, Fish, and Bash completions installed automatically
  • Man pages and metadata for improved discoverability
  • Full integration with kind and docker for testing purposes

Integration Testing with Autopkgtest To ensure the reliability of kubectl in real-world scenarios, we developed a new autopkgtest suite that runs integration tests using real Kubernetes clusters created via Kind. Autopkgtest is a Debian tool used to run automated tests on binary packages. These tests are executed after the package is built but before it s accepted into the Debian archive, helping catch regressions and integration issues early in the packaging pipeline. Our test workflow validates kubectl by performing the following steps:
  • Installing Kind and Docker as test dependencies.
  • Spinning up two local Kubernetes clusters.
  • Switching between cluster contexts to ensure multi-cluster support.
  • Deploying and scaling a sample nginx application using kubectl.
  • Cleaning up the entire test environment to avoid side effects.
  • debian/tests/kubectl.sh

Popcon: Measuring Adoption To measure real-world usage, we rely on data from Debian s popularity contest (popcon), which gives insight into how many users have each binary installed. popcon-graph popcon-table Here s what the data tells us:
  • kubectl (new binary): Already installed on 2,124 systems.
  • golang-k8s-kubectl-dev: This is the Go development package (a library), useful for other packages and developers who want to interact with Kubernetes programmatically.
  • kubernetes-client: The legacy package that kubectl is replacing. We expect this number to decrease in future releases as more systems transition to the new package.
Although the popcon data shows activity for kubectl before the official Debian upload date, it s important to note that those numbers represent users who had it installed from upstream source-lists, not from the Debian repositories. This distinction underscores a demand that existed even before the package was available in Debian proper, and it validates the importance of bringing it into the archive.
Also worth mentioning: this number is not the real total number of installations, since users can choose not to participate in the popularity contest. So the actual adoption is likely higher than what popcon reflects.

Community and Documentation The team also maintains a dedicated wiki page which documents:
  • Maintained tools and packages
  • Contribution guidelines
  • Our roadmap for the upcoming Debian releases
https://debian-kubernetes.org

Looking Ahead to Debian 13 (Trixie) The next stable release of Debian will ship with kubectl version 1.32.3, built from a clean, de-vendorized source. This version includes nearly all the latest upstream features, and will be the first time in years that Debian users can rely on an up-to-date, policy-compliant kubectl directly from the archive. By comparing with upstream, our Debian package even delivers more out of the box, including shell completions, which the upstream still requires users to generate manually. In 2025, the Debian Kubernetes team will continue expanding our packaging efforts for the Kubernetes ecosystem. Our roadmap includes:
  • kubelet: The primary node agent that runs on each node. This will enable Debian users to create fully functional Kubernetes nodes without relying on external packages.
  • kubeadm: A tool for creating Kubernetes clusters. With kubeadm in Debian, users will then be able to bootstrap minimum viable clusters directly from the official repositories.
  • helm: The package manager for Kubernetes that helps manage applications through Kubernetes YAML files defined as charts.
  • kompose: A conversion tool that helps users familiar with docker-compose move to Kubernetes by translating Docker Compose files into Kubernetes resources.

Final Thoughts This journey was only possible thanks to the amazing support of the debian-devel-br community and the collective effort of contributors who stepped up to package missing dependencies, fix bugs, and test new versions. Special thanks to:
  • Carlos Henrique Melara (@charles)
  • Guilherme Puida (@puida)
  • Jo o Pedro Nobrega (@jnpf)
  • Lucas Kanashiro (@kanashiro)
  • Matheus Polkorny (@polkorny)
  • Samuel Henrique (@samueloph)
  • Sergio Cipriano (@cipriano)
  • Sergio Durigan Junior (@sergiodj)
I look forward to continuing this work, bringing more Kubernetes tools into Debian and improving the developer experience for everyone.

Debian XMPP Team: XMPP/Jabber Debian 13 Trixie News

Debian 13 "Trixie" full freeze has started 2025-05-17, so this is a good time to take a look at some of the features, that this release will bring. Here we will focus on packages related to XMPP, a.k.a. Jabber. XMPP is a universal communication protocol for instant messaging, push notifications, IoT, WebRTC, and social applications. It has existed since 1999, originally called "Jabber", it has a diverse and active developers community. Clients Servers Libraries Gateways/Transports Not in Trixie

28 May 2025

Clint Adams: Potted meat is viewed differently by different cultures

I've been working on a multi-label email classification model. It's been a frustrating slog, fraught with challenges, including a lack of training data. Labeling emails is labor-intensive and error-prone. Also, I habitually delete certain classes of email immediately after its usefulness has been reduced. I use a CRM-114-based spam filtering system (actually I use two different isntances of the same mailreaver config, but that's another story), which is differently frustrating, but I delete spam when it's detected or when it's trained. Fortunately, there's no shortage of incoming spam, so I can collect enough, but for other, arguably more important labels, they arrive infrequently. So, those labels need to be excluded, or the small sample sizes wreck the training feedback loop. Currently, I have ten active labels, and even though the point of this is not to be a spam filter, spam is one of the labels. Out of curiosity, I decided to compare the performance of my three different models, and to do so on a neutral corpus (in other words, emails that none of them had ever been trained on). I grabbed the full TREC 2007 corpus and ran inference. The results were unexpected in many ways. For example, the Pearson correlation coefficient between my older CRM-114 model and my newer CRM-114 was only about 0.78. I was even more surprised by how poorly all three performed. Were they overfit to my email? So, I decided to look at the TREC corpus for the first time, and lo and behold, the first spam-labeled email I checked was something I would definitely train all three models with as non-spam, but ham for CRM-114 and an entirely different label for my experimental model.
Posted on 2025-05-28
Tags:

26 May 2025

Otto Kek l inen: Creating Debian packages from upstream Git

Featured image of post Creating Debian packages from upstream GitIn this post, I demonstrate the optimal workflow for creating new Debian packages in 2025, preserving the upstream git history. The motivation for this is to lower the barrier for sharing improvements to and from upstream, and to improve software provenance and supply-chain security by making it easy to inspect every change at any level using standard git tooling. Key elements of this workflow include: To make the instructions so concrete that anyone can repeat all the steps themselves on a real package, I demonstrate the steps by packaging the command-line tool Entr. It is written in C, has very few dependencies, and its final Debian source package structure is simple, yet exemplifies all the important parts that go into a complete Debian package:
  1. Creating a new packaging repository and publishing it under your personal namespace on salsa.debian.org.
  2. Using dh_make to create the initial Debian packaging.
  3. Posting the first draft of the Debian packaging as a Merge Request (MR) and using Salsa CI to verify Debian packaging quality.
  4. Running local builds efficiently and iterating on the packaging process.

Create new Debian packaging repository from the existing upstream project git repository First, create a new empty directory, then clone the upstream Git repository inside it:
shell
mkdir debian-entr
cd debian-entr
git clone --origin upstreamvcs --branch master \
 --single-branch https://github.com/eradman/entr.git
Using a clean directory makes it easier to inspect the build artifacts of a Debian package, which will be output in the parent directory of the Debian source directory. The extra parameters given to git clone lay the foundation for the Debian packaging git repository structure where the upstream git remote name is upstreamvcs. Only the upstream main branch is tracked to avoid cluttering git history with upstream development branches that are irrelevant for packaging in Debian. Next, enter the git repository directory and list the git tags. Pick the latest upstream release tag as the commit to start the branch upstream/latest. This latest refers to the upstream release, not the upstream development branch. Immediately after, branch off the debian/latest branch, which will have the actual Debian packaging files in the debian/ subdirectory.
shell
cd entr
git tag # shows the latest upstream release tag was '5.6'
git checkout -b upstream/latest 5.6
git checkout -b debian/latest
%% init:   'gitGraph':   'mainBranchName': 'master'      %%
gitGraph:
checkout master
commit id: "Upstream 5.6 release" tag: "5.6"
branch upstream/latest
checkout upstream/latest
commit id: "New upstream version 5.6" tag: "upstream/5.6"
branch debian/latest
checkout debian/latest
commit id: "Initial Debian packaging"
commit id: "Additional change 1"
commit id: "Additional change 2"
commit id: "Additional change 3"
At this point, the repository is structured according to DEP-14 conventions, ensuring a clear separation between upstream and Debian packaging changes, but there are no Debian changes yet. Next, add the Salsa repository as a new remote which called origin, the same as the default remote name in git.
shell
git remote add origin git@salsa.debian.org:otto/entr-demo.git
git push --set-upstream origin debian/latest
This is an important preparation step to later be able to create a Merge Request on Salsa that targets the debian/latest branch, which does not yet have any debian/ directory.

Launch a Debian Sid (unstable) container to run builds in To ensure that all packaging tools are of the latest versions, run everything inside a fresh Sid container. This has two benefits: you are guaranteed to have the most up-to-date toolchain, and your host system stays clean without getting polluted by various extra packages. Additionally, this approach works even if your host system is not Debian/Ubuntu.
shell
cd ..
podman run --interactive --tty --rm --shm-size=1G --cap-add SYS_PTRACE \
 --env='DEB*' --volume=$PWD:/tmp/test --workdir=/tmp/test debian:sid bash
Note that the container should be started from the parent directory of the git repository, not inside it. The --volume parameter will loop-mount the current directory inside the container. Thus all files created and modified are on the host system, and will persist after the container shuts down. Once inside the container, install the basic dependencies:
shell
apt update -q && apt install -q --yes git-buildpackage dpkg-dev dh-make

Automate creating the debian/ files with dh-make To create the files needed for the actual Debian packaging, use dh_make:
shell
# dh_make --packagename entr_5.6 --single --createorig
Maintainer Name : Otto Kek l inen
Email-Address : otto@debian.org
Date : Sat, 15 Feb 2025 01:17:51 +0000
Package Name : entr
Version : 5.6
License : blank
Package Type : single
Are the details correct? [Y/n/q]

Done. Please edit the files in the debian/ subdirectory now.
Due to how dh_make works, the package name and version need to be written as a single underscore separated string. In this case, you should choose --single to specify that the package type is a single binary package. Other options would be --library for library packages (see libgda5 sources as an example) or --indep (see dns-root-data sources as an example). The --createorig will create a mock upstream release tarball (entr_5.6.orig.tar.xz) from the current release directory, which is necessary due to historical reasons and how dh_make worked before git repositories became common and Debian source packages were based off upstream release tarballs (e.g. *.tar.gz). At this stage, a debian/ directory has been created with template files, and you can start modifying the files and iterating towards actual working packaging.
shell
git add debian/
git commit -a -m "Initial Debian packaging"

Review the files The full list of files after the above steps with dh_make would be:
 -- entr
   -- LICENSE
   -- Makefile.bsd
   -- Makefile.linux
   -- Makefile.linux-compat
   -- Makefile.macos
   -- NEWS
   -- README.md
   -- configure
   -- data.h
   -- debian
     -- README.Debian
     -- README.source
     -- changelog
     -- control
     -- copyright
     -- gbp.conf
     -- entr-docs.docs
     -- entr.cron.d.ex
     -- entr.doc-base.ex
     -- manpage.1.ex
     -- manpage.md.ex
     -- manpage.sgml.ex
     -- manpage.xml.ex
     -- postinst.ex
     -- postrm.ex
     -- preinst.ex
     -- prerm.ex
     -- rules
     -- salsa-ci.yml.ex
     -- source
       -- format
     -- upstream
       -- metadata.ex
     -- watch.ex
   -- entr.1
   -- entr.c
   -- missing
     -- compat.h
     -- kqueue_inotify.c
     -- strlcpy.c
     -- sys
     -- event.h
   -- status.c
   -- status.h
   -- system_test.sh
 -- entr_5.6.orig.tar.xz
You can browse these files in the demo repository. The mandatory files in the debian/ directory are:
  • changelog,
  • control,
  • copyright,
  • and rules.
All the other files have been created for convenience so the packager has template files to work from. The files with the suffix .ex are example files that won t have any effect until their content is adjusted and the suffix removed. For detailed explanations of the purpose of each file in the debian/ subdirectory, see the following resources:
  • The Debian Policy Manual: Describes the structure of the operating system, the package archive and requirements for packages to be included in the Debian archive.
  • The Developer s Reference: A collection of best practices and process descriptions Debian packagers are expected to follow while interacting with one another.
  • Debhelper man pages: Detailed information of how the Debian package build system works, and how the contents of the various files in debian/ affect the end result.
As Entr, the package used in this example, is a real package that already exists in the Debian archive, you may want to browse the actual Debian packaging source at https://salsa.debian.org/debian/entr/-/tree/debian/latest/debian for reference. Most of these files have standardized formatting conventions to make collaboration easier. To automatically format the files following the most popular conventions, simply run wrap-and-sort -vast or debputy reformat --style=black.

Identify build dependencies The most common reason for builds to fail is missing dependencies. The easiest way to identify which Debian package ships the required dependency is using apt-file. If, for example, a build fails complaining that pcre2posix.h cannot be found or that libcre2-posix.so is missing, you can use these commands:
shell
$ apt install -q --yes apt-file && apt-file update
$ apt-file search pcre2posix.h
libpcre2-dev: /usr/include/pcre2posix.h
$ apt-file search libpcre2-posix.so
libpcre2-dev: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so
libpcre2-posix3: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so.3
libpcre2-posix3: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so.3.0.6
The output above implies that the debian/control should be extended to define a Build-Depends: libpcre2-dev relationship. There is also dpkg-depcheck that uses strace to trace the files the build process tries to access, and lists what Debian packages those files belong to. Example usage:
shell
dpkg-depcheck -b debian/rules build

Build the Debian sources to generate the .deb package After the first pass of refining the contents of the files in debian/, test the build by running dpkg-buildpackage inside the container:
shell
dpkg-buildpackage -uc -us -b
The options -uc -us will skip signing the resulting Debian source package and other build artifacts. The -b option will skip creating a source package and only build the (binary) *.deb packages. The output is very verbose and gives a large amount of context about what is happening during the build to make debugging build failures easier. In the build log of entr you will see for example the line dh binary --buildsystem=makefile. This and other dh commands can also be run manually if there is a need to quickly repeat only a part of the build while debugging build failures. To see what files were generated or modified by the build simply run git status --ignored:
shell
$ git status --ignored
On branch debian/latest

Untracked files:
 (use "git add <file>..." to include in what will be committed)
 debian/debhelper-build-stamp
 debian/entr.debhelper.log
 debian/entr.substvars
 debian/files

Ignored files:
 (use "git add -f <file>..." to include in what will be committed)
 Makefile
 compat.c
 compat.o
 debian/.debhelper/
 debian/entr/
 entr
 entr.o
 status.o
Re-running dpkg-buildpackage will include running the command dh clean, which assuming it is configured correctly in the debian/rules file will reset the source directory to the original pristine state. The same can of course also be done with regular git commands git reset --hard; git clean -fdx. To avoid accidentally committing unnecessary build artifacts in git, a debian/.gitignore can be useful and it would typically include all four files listed as untracked above. After a successful build you would have the following files:
shell
 -- entr
   -- LICENSE
   -- Makefile -> Makefile.linux
   -- Makefile.bsd
   -- Makefile.linux
   -- Makefile.linux-compat
   -- Makefile.macos
   -- NEWS
   -- README.md
   -- compat.c
   -- compat.o
   -- configure
   -- data.h
   -- debian
     -- README.source.md
     -- changelog
     -- control
     -- copyright
     -- debhelper-build-stamp
     -- docs
     -- entr
       -- DEBIAN
         -- control
         -- md5sums
       -- usr
       -- bin
         -- entr
       -- share
       -- doc
         -- entr
         -- NEWS.gz
         -- README.md
         -- changelog.Debian.gz
         -- copyright
       -- man
       -- man1
       -- entr.1.gz
     -- entr.debhelper.log
     -- entr.substvars
     -- files
     -- gbp.conf
     -- patches
       -- PR149-expand-aliases-in-system-test-script.patch
       -- series
       -- system-test-skip-no-tty.patch
       -- system-test-with-system-binary.patch
     -- rules
     -- salsa-ci.yml
     -- source
       -- format
     -- tests
       -- control
     -- upstream
       -- metadata
       -- signing-key.asc
     -- watch
   -- entr
   -- entr.1
   -- entr.c
   -- entr.o
   -- missing
     -- compat.h
     -- kqueue_inotify.c
     -- strlcpy.c
     -- sys
     -- event.h
   -- status.c
   -- status.h
   -- status.o
   -- system_test.sh
 -- entr-dbgsym_5.6-1_amd64.deb
 -- entr_5.6-1.debian.tar.xz
 -- entr_5.6-1.dsc
 -- entr_5.6-1_amd64.buildinfo
 -- entr_5.6-1_amd64.changes
 -- entr_5.6-1_amd64.deb
 -- entr_5.6.orig.tar.xz
The contents of debian/entr are essentially what goes into the resulting entr_5.6-1_amd64.deb package. Familiarizing yourself with the majority of the files in the original upstream source as well as all the resulting build artifacts is time consuming, but it is a necessary investment to get high-quality Debian packages. There are also tools such as Debcraft that automate generating the build artifacts in separate output directories for each build, thus making it easy to compare the changes to correlate what change in the Debian packaging led to what change in the resulting build artifacts.

Re-run the initial import with git-buildpackage When upstreams publish releases as tarballs, they should also be imported for optimal software supply-chain security, in particular if upstream also publishes cryptographic signatures that can be used to verify the authenticity of the tarballs. To achieve this, the files debian/watch, debian/upstream/signing-key.asc, and debian/gbp.conf need to be present with the correct options. In the gbp.conf file, ensure you have the correct options based on:
  1. Does upstream release tarballs? If so, enforce pristine-tar = True.
  2. Does upstream sign the tarballs? If so, configure explicit signature checking with upstream-signatures = on.
  3. Does upstream have a git repository, and does it have release git tags? If so, configure the release git tag format, e.g. upstream-vcs-tag = %(version%~%.)s.
To validate that the above files are working correctly, run gbp import-orig with the current version explicitly defined:
shell
$ gbp import-orig --uscan --upstream-version 5.6
gbp:info: Launching uscan...
gpgv: Signature made 7. Aug 2024 07.43.27 PDT
gpgv: using RSA key 519151D83E83D40A232B4D615C418B8631BC7C26
gpgv: Good signature from "Eric Radman <ericshane@eradman.com>"
gbp:info: Using uscan downloaded tarball ../entr_5.6.orig.tar.gz
gbp:info: Importing '../entr_5.6.orig.tar.gz' to branch 'upstream/latest'...
gbp:info: Source package is entr
gbp:info: Upstream version is 5.6
gbp:info: Replacing upstream source on 'debian/latest'
gbp:info: Running Postimport hook
gbp:info: Successfully imported version 5.6 of ../entr_5.6.orig.tar.gz
As the original packaging was done based on the upstream release git tag, the above command will fetch the tarball release, create the pristine-tar branch, and store the tarball delta on it. This command will also attempt to create the tag upstream/5.6 on the upstream/latest branch.

Import new upstream versions in the future Forking the upstream git repository, creating the initial packaging, and creating the DEP-14 branch structure are all one-off work needed only when creating the initial packaging. Going forward, to import new upstream releases, one would simply run git fetch upstreamvcs; gbp import-orig --uscan, which fetches the upstream git tags, checks for new upstream tarballs, and automatically downloads, verifies, and imports the new version. See the galera-4-demo example in the Debian source packages in git explained post as a demo you can try running yourself and examine in detail. You can also try running gbp import-orig --uscan without specifying a version. It would fetch it, as it will notice there is now Entr version 5.7 available, and import it.

Build using git-buildpackage From this stage onwards you should build the package using gbp buildpackage, which will do a more comprehensive build.
shell
gbp buildpackage -uc -us
The git-buildpackage build also includes running Lintian to find potential Debian policy violations in the sources or in the resulting .deb binary packages. Many Debian Developers run lintian -EviIL +pedantic after every build to check that there are no new nags, and to validate that changes intended to previous Lintian nags were correct.

Open a Merge Request on Salsa for Debian packaging review Getting everything perfectly right takes a lot of effort, and may require reaching out to an experienced Debian Developers for review and guidance. Thus, you should aim to publish your initial packaging work on Salsa, Debian s GitLab instance, for review and feedback as early as possible. For somebody to be able to easily see what you have done, you should rename your debian/latest branch to another name, for example next/debian/latest, and open a Merge Request that targets the debian/latest branch on your Salsa fork, which still has only the unmodified upstream files. If you have followed the workflow in this post so far, you can simply run:
  1. git checkout -b next/debian/latest
  2. git push --set-upstream origin next/debian/latest
  3. Open in a browser the URL visible in the git remote response
  4. Write the Merge Request description in case the default text from your commit is not enough
  5. Mark the MR as Draft using the checkbox
  6. Publish the MR and request feedback
Once a Merge Request exists, discussion regarding what additional changes are needed can be conducted as MR comments. With an MR, you can easily iterate on the contents of next/debian/latest, rebase, force push, and request re-review as many times as you want. While at it, make sure the Settings > CI/CD page has under CI/CD configuration file the value debian/salsa-ci.yml so that the CI can run and give you immediate automated feedback. For an example of an initial packaging Merge Request, see https://salsa.debian.org/otto/entr-demo/-/merge_requests/1.

Open a Merge Request / Pull Request to fix upstream code Due to the high quality requirements in Debian, it is fairly common that while doing the initial Debian packaging of an open source project, issues are found that stem from the upstream source code. While it is possible to carry extra patches in Debian, it is not good practice to deviate too much from upstream code with custom Debian patches. Instead, the Debian packager should try to get the fixes applied directly upstream. Using git-buildpackage patch queues is the most convenient way to make modifications to the upstream source code so that they automatically convert into Debian patches (stored at debian/patches), and can also easily be submitted upstream as any regular git commit (and rebased and resubmitted many times over). First, decide if you want to work out of the upstream development branch and later cherry-pick to the Debian packaging branch, or work out of the Debian packaging branch and cherry-pick to an upstream branch. The example below starts from the upstream development branch and then cherry-picks the commit into the git-buildpackage patch queue:
shell
git checkout -b bugfix-branch master
nano entr.c
make
./entr # verify change works as expected
git commit -a -m "Commit title" -m "Commit body"
git push # submit upstream
gbp pq import --force --time-machine=10
git cherry-pick <commit id>
git commit --amend # extend commit message with DEP-3 metadata
gbp buildpackage -uc -us -b
./entr # verify change works as expected
gbp pq export --drop --commit
git commit --amend # Write commit message along lines "Add patch to .."
The example below starts by making the fix on a git-buildpackage patch queue branch, and then cherry-picking it onto the upstream development branch:
shell
gbp pq import --force --time-machine=10
nano entr.c
git commit -a -m "Commit title" -m "Commit body"
gbp buildpackage -uc -us -b
./entr # verify change works as expected
gbp pq export --drop --commit
git commit --amend # Write commit message along lines "Add patch to .."
git checkout -b bugfix-branch master
git cherry-pick <commit id>
git commit --amend # prepare commit message for upstream submission
git push # submit upstream
The key git-buildpackage commands to enter and exit the patch-queue mode are:
shell
gbp pq import --force --time-machine=10
gbp pq export --drop --commit
%% init:   'gitGraph':   'mainBranchName': 'debian/latest'      %%
gitGraph
checkout debian/latest
commit id: "Initial packaging"
branch patch-queue/debian/latest
checkout patch-queue/debian/latest
commit id: "Delete debian/patches/..."
commit id: "Patch 1 title"
commit id: "Patch 2 title"
commit id: "Patch 3 title"
These can be run at any time, regardless if any debian/patches existed prior, or if existing patches applied cleanly or not, or if there were old patch queue branches around. Note that the extra -b in gbp buildpackage -uc -us -b instructs to build only binary packages, avoiding any nags from dpkg-source that there are modifications in the upstream sources while building in the patches-applied mode.

Programming-language specific dh-make alternatives As each programming language has its specific way of building the source code, and many other conventions regarding the file layout and more, Debian has multiple custom tools to create new Debian source packages for specific programming languages. Notably, Python does not have its own tool, but there is an dh_make --python option for Python support directly in dh_make itself. The list is not complete and many more tools exist. For some languages, there are even competing options, such as for Go there is in addition to dh-make-golang also Gophian. When learning Debian packaging, there is no need to learn these tools upfront. Being aware that they exist is enough, and one can learn them only if and when one starts to package a project in a new programming language.

The difference between source git repository vs source packages vs binary packages As seen in earlier example, running gbp buildpackage on the Entr packaging repository above will result in several files:
entr_5.6-1_amd64.changes
entr_5.6-1_amd64.deb
entr_5.6-1.debian.tar.xz
entr_5.6-1.dsc
entr_5.6.orig.tar.gz
entr_5.6.orig.tar.gz.asc
The entr_5.6-1_amd64.deb is the binary package, which can be installed on a Debian/Ubuntu system. The rest of the files constitute the source package. To do a source-only build, run gbp buildpackage -S and note the files produced:
entr_5.6-1_source.changes
entr_5.6-1.debian.tar.xz
entr_5.6-1.dsc
entr_5.6.orig.tar.gz
entr_5.6.orig.tar.gz.asc
The source package files can be used to build the binary .deb for amd64, or any architecture that the package supports. It is important to grasp that the Debian source package is the preferred form to be able to build the binary packages on various Debian build systems, and the Debian source package is not the same thing as the Debian packaging git repository contents.
flowchart LR
git[Git repository<br>branch debian/latest] --> gbp buildpackage -S  src[Source Package<br>.dsc + .tar.xz]
src --> dpkg-buildpackage  bin[Binary Packages<br>.deb]
If the package is large and complex, the build could result in multiple binary packages. One set of package definition files in debian/ will however only ever result in a single source package.

Option to repackage source packages with Files-Excluded lists in the debian/copyright file Some upstream projects may include binary files in their release, or other undesirable content that needs to be omitted from the source package in Debian. The easiest way to filter them out is by adding to the debian/copyright file a Files-Excluded field listing the undesired files. The debian/copyright file is read by uscan, which will repackage the upstream sources on-the-fly when importing new upstream releases. For a real-life example, see the debian/copyright files in the Godot package that lists:
debian
Files-Excluded: platform/android/java/gradle/wrapper/gradle-wrapper.jar
The resulting repackaged upstream source tarball, as well as the upstream version component, will have an extra +ds to signify that it is not the true original upstream source but has been modified by Debian:
godot_4.3+ds.orig.tar.xz
godot_4.3+ds-1_amd64.deb

Creating one Debian source package from multiple upstream source packages also possible In some rare cases the upstream project may be split across multiple git repositories or the upstream release may consist of multiple components each in their own separate tarball. Usually these are very large projects that get some benefits from releasing components separately. If in Debian these are deemed to go into a single source package, it is technically possible using the component system in git-buildpackage and uscan. For an example see the gbp.conf and watch files in the node-cacache package. Using this type of structure should be a last resort, as it creates complexity and inter-dependencies that are bound to cause issues later on. It is usually better to work with upstream and champion universal best practices with clear releases and version schemes.

When not to start the Debian packaging repository as a fork of the upstream one Not all upstreams use Git for version control. It is by far the most popular, but there are still some that use e.g. Subversion or Mercurial. Who knows maybe in the future some new version control systems will start to compete with Git. There are also projects that use Git in massive monorepos and with complex submodule setups that invalidate the basic assumptions required to map an upstream Git repository into a Debian packaging repository. In those cases one can t use a debian/latest branch on a clone of the upstream git repository as the starting point for the Debian packaging, but one must revert the traditional way of starting from an upstream release tarball with gbp import-orig package-1.0.tar.gz.

Conclusion Created in August 1993, Debian is one of the oldest Linux distributions. In the 32 years since inception, the .deb packaging format and the tooling to work with it have evolved several generations. In the past 10 years, more and more Debian Developers have converged on certain core practices evidenced by https://trends.debian.net/, but there is still a lot of variance in workflows even for identical tasks. Hopefully, you find this post useful in giving practical guidance on how exactly to do the most common things when packaging software for Debian. Happy packaging!

25 May 2025

Otto Kek l inen: New Debian package creation from upstream git repository

Featured image of post New Debian package creation from upstream git repositoryIn this post, I demonstrate the optimal workflow for creating new Debian packages in 2025, preserving the upstream git history. The motivation for this is to lower the barrier for sharing improvements to and from upstream, and to improve software provenance and supply-chain security by making it easy to inspect every change at any level using standard git tooling. Key elements of this workflow include: To make the instructions so concrete that anyone can repeat all the steps themselves on a real package, I demonstrate the steps by packaging the command-line tool Entr. It is written in C, has very few dependencies, and its final Debian source package structure is simple, yet exemplifies all the important parts that go into a complete Debian package:
  1. Creating a new packaging repository and publishing it under your personal namespace on salsa.debian.org.
  2. Using dh_make to create the initial Debian packaging.
  3. Posting the first draft of the Debian packaging as a Merge Request (MR) and using Salsa CI to verify Debian packaging quality.
  4. Running local builds efficiently and iterating on the packaging process.

Create new Debian packaging repository from the existing upstream project git repository First, create a new empty directory, then clone the upstream Git repository inside it:
shell
mkdir debian-entr
cd debian-entr
git clone --origin upstreamvcs --branch master \
 --single-branch https://github.com/eradman/entr.git
Using a clean directory makes it easier to inspect the build artifacts of a Debian package, which will be output in the parent directory of the Debian source directory. The extra parameters given to git clone lay the foundation for the Debian packaging git repository structure where the upstream git remote name is upstreamvcs. Only the upstream main branch is tracked to avoid cluttering git history with upstream development branches that are irrelevant for packaging in Debian. Next, enter the git repository directory and list the git tags. Pick the latest upstream release tag as the commit to start the branch upstream/latest. This latest refers to the upstream release, not the upstream development branch. Immediately after, branch off the debian/latest branch, which will have the actual Debian packaging files in the debian/ subdirectory.
shell
cd entr
git tag # shows the latest upstream release tag was '5.6'
git checkout -b upstream/latest 5.6
git checkout -b debian/latest
%% init:   'gitGraph':   'mainBranchName': 'master'      %%
gitGraph:
checkout master
commit id: "Upstream 5.6 release" tag: "5.6"
branch upstream/latest
checkout upstream/latest
commit id: "New upstream version 5.6" tag: "upstream/5.6"
branch debian/latest
checkout debian/latest
commit id: "Initial Debian packaging"
commit id: "Additional change 1"
commit id: "Additional change 2"
commit id: "Additional change 3"
At this point, the repository is structured according to DEP-14 conventions, ensuring a clear separation between upstream and Debian packaging changes, but there are no Debian changes yet. Next, add the Salsa repository as a new remote which called origin, the same as the default remote name in git.
shell
git remote add origin git@salsa.debian.org:otto/entr-demo.git
git push --set-upstream origin debian/latest
This is an important preparation step to later be able to create a Merge Request on Salsa that targets the debian/latest branch, which does not yet have any debian/ directory.

Launch a Debian Sid (unstable) container to run builds in To ensure that all packaging tools are of the latest versions, run everything inside a fresh Sid container. This has two benefits: you are guaranteed to have the most up-to-date toolchain, and your host system stays clean without getting polluted by various extra packages. Additionally, this approach works even if your host system is not Debian/Ubuntu.
shell
cd ..
podman run --interactive --tty --rm --shm-size=1G --cap-add SYS_PTRACE \
 --env='DEB*' --volume=$PWD:/tmp/test --workdir=/tmp/test debian:sid bash
Note that the container should be started from the parent directory of the git repository, not inside it. The --volume parameter will loop-mount the current directory inside the container. Thus all files created and modified are on the host system, and will persist after the container shuts down. Once inside the container, install the basic dependencies:
shell
apt update -q && apt install -q --yes git-buildpackage dpkg-dev dh-make

Automate creating the debian/ files with dh-make To create the files needed for the actual Debian packaging, use dh_make:
shell
# dh_make --packagename entr_5.6 --single --createorig
Maintainer Name : Otto Kek l inen
Email-Address : otto@debian.org
Date : Sat, 15 Feb 2025 01:17:51 +0000
Package Name : entr
Version : 5.6
License : blank
Package Type : single
Are the details correct? [Y/n/q]

Done. Please edit the files in the debian/ subdirectory now.
Due to how dh_make works, the package name and version need to be written as a single underscore separated string. In this case, you should choose --single to specify that the package type is a single binary package. Other options would be --library for library packages (see libgda5 sources as an example) or --indep (see dns-root-data sources as an example). The --createorig will create a mock upstream release tarball (entr_5.6.orig.tar.xz) from the current release directory, which is necessary due to historical reasons and how dh_make worked before git repositories became common and Debian source packages were based off upstream release tarballs (e.g. *.tar.gz). At this stage, a debian/ directory has been created with template files, and you can start modifying the files and iterating towards actual working packaging.
shell
git add debian/
git commit -a -m "Initial Debian packaging"

Review the files The full list of files after the above steps with dh_make would be:
 -- entr
   -- LICENSE
   -- Makefile.bsd
   -- Makefile.linux
   -- Makefile.linux-compat
   -- Makefile.macos
   -- NEWS
   -- README.md
   -- configure
   -- data.h
   -- debian
     -- README.Debian
     -- README.source
     -- changelog
     -- control
     -- copyright
     -- gbp.conf
     -- entr-docs.docs
     -- entr.cron.d.ex
     -- entr.doc-base.ex
     -- manpage.1.ex
     -- manpage.md.ex
     -- manpage.sgml.ex
     -- manpage.xml.ex
     -- postinst.ex
     -- postrm.ex
     -- preinst.ex
     -- prerm.ex
     -- rules
     -- salsa-ci.yml.ex
     -- source
       -- format
     -- upstream
       -- metadata.ex
     -- watch.ex
   -- entr.1
   -- entr.c
   -- missing
     -- compat.h
     -- kqueue_inotify.c
     -- strlcpy.c
     -- sys
     -- event.h
   -- status.c
   -- status.h
   -- system_test.sh
 -- entr_5.6.orig.tar.xz
You can browse these files in the demo repository. The mandatory files in the debian/ directory are:
  • changelog,
  • control,
  • copyright,
  • and rules.
All the other files have been created for convenience so the packager has template files to work from. The files with the suffix .ex are example files that won t have any effect until their content is adjusted and the suffix removed. For detailed explanations of the purpose of each file in the debian/ subdirectory, see the following resources:
  • The Debian Policy Manual: Describes the structure of the operating system, the package archive and requirements for packages to be included in the Debian archive.
  • The Developer s Reference: A collection of best practices and process descriptions Debian packagers are expected to follow while interacting with one another.
  • Debhelper man pages: Detailed information of how the Debian package build system works, and how the contents of the various files in debian/ affect the end result.
As Entr, the package used in this example, is a real package that already exists in the Debian archive, you may want to browse the actual Debian packaging source at https://salsa.debian.org/debian/entr/-/tree/debian/latest/debian for reference. Most of these files have standardized formatting conventions to make collaboration easier. To automatically format the files following the most popular conventions, simply run wrap-and-sort -vast or debputy reformat --style=black.

Identify build dependencies The most common reason for builds to fail is missing dependencies. The easiest way to identify which Debian package ships the required dependency is using apt-file. If, for example, a build fails complaining that pcre2posix.h cannot be found or that libcre2-posix.so is missing, you can use these commands:
shell
$ apt install -q --yes apt-file && apt-file update
$ apt-file search pcre2posix.h
libpcre2-dev: /usr/include/pcre2posix.h
$ apt-file search libpcre2-posix.so
libpcre2-dev: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so
libpcre2-posix3: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so.3
libpcre2-posix3: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so.3.0.6
The output above implies that the debian/control should be extended to define a Build-Depends: libpcre2-dev relationship. There is also dpkg-depcheck that uses strace to trace the files the build process tries to access, and lists what Debian packages those files belong to. Example usage:
shell
dpkg-depcheck -b debian/rules build

Build the Debian sources to generate the .deb package After the first pass of refining the contents of the files in debian/, test the build by running dpkg-buildpackage inside the container:
shell
dpkg-buildpackage -uc -us -b
The options -uc -us will skip signing the resulting Debian source package and other build artifacts. The -b option will skip creating a source package and only build the (binary) *.deb packages. The output is very verbose and gives a large amount of context about what is happening during the build to make debugging build failures easier. In the build log of entr you will see for example the line dh binary --buildsystem=makefile. This and other dh commands can also be run manually if there is a need to quickly repeat only a part of the build while debugging build failures. To see what files were generated or modified by the build simply run git status --ignored:
shell
$ git status --ignored
On branch debian/latest

Untracked files:
 (use "git add <file>..." to include in what will be committed)
 debian/debhelper-build-stamp
 debian/entr.debhelper.log
 debian/entr.substvars
 debian/files

Ignored files:
 (use "git add -f <file>..." to include in what will be committed)
 Makefile
 compat.c
 compat.o
 debian/.debhelper/
 debian/entr/
 entr
 entr.o
 status.o
Re-running dpkg-buildpackage will include running the command dh clean, which assuming it is configured correctly in the debian/rules file will reset the source directory to the original pristine state. The same can of course also be done with regular git commands git reset --hard; git clean -fdx. To avoid accidentally committing unnecessary build artifacts in git, a debian/.gitignore can be useful and it would typically include all four files listed as untracked above. After a successful build you would have the following files:
shell
 -- entr
   -- LICENSE
   -- Makefile -> Makefile.linux
   -- Makefile.bsd
   -- Makefile.linux
   -- Makefile.linux-compat
   -- Makefile.macos
   -- NEWS
   -- README.md
   -- compat.c
   -- compat.o
   -- configure
   -- data.h
   -- debian
     -- README.source.md
     -- changelog
     -- control
     -- copyright
     -- debhelper-build-stamp
     -- docs
     -- entr
       -- DEBIAN
         -- control
         -- md5sums
       -- usr
       -- bin
         -- entr
       -- share
       -- doc
         -- entr
         -- NEWS.gz
         -- README.md
         -- changelog.Debian.gz
         -- copyright
       -- man
       -- man1
       -- entr.1.gz
     -- entr.debhelper.log
     -- entr.substvars
     -- files
     -- gbp.conf
     -- patches
       -- PR149-expand-aliases-in-system-test-script.patch
       -- series
       -- system-test-skip-no-tty.patch
       -- system-test-with-system-binary.patch
     -- rules
     -- salsa-ci.yml
     -- source
       -- format
     -- tests
       -- control
     -- upstream
       -- metadata
       -- signing-key.asc
     -- watch
   -- entr
   -- entr.1
   -- entr.c
   -- entr.o
   -- missing
     -- compat.h
     -- kqueue_inotify.c
     -- strlcpy.c
     -- sys
     -- event.h
   -- status.c
   -- status.h
   -- status.o
   -- system_test.sh
 -- entr-dbgsym_5.6-1_amd64.deb
 -- entr_5.6-1.debian.tar.xz
 -- entr_5.6-1.dsc
 -- entr_5.6-1_amd64.buildinfo
 -- entr_5.6-1_amd64.changes
 -- entr_5.6-1_amd64.deb
 -- entr_5.6.orig.tar.xz
The contents of debian/entr are essentially what goes into the resulting entr_5.6-1_amd64.deb package. Familiarizing yourself with the majority of the files in the original upstream source as well as all the resulting build artifacts is time consuming, but it is a necessary investment to get high-quality Debian packages. There are also tools such as Debcraft that automate generating the build artifacts in separate output directories for each build, thus making it easy to compare the changes to correlate what change in the Debian packaging led to what change in the resulting build artifacts.

Re-run the initial import with git-buildpackage When upstreams publish releases as tarballs, they should also be imported for optimal software supply-chain security, in particular if upstream also publishes cryptographic signatures that can be used to verify the authenticity of the tarballs. To achieve this, the files debian/watch, debian/upstream/signing-key.asc, and debian/gbp.conf need to be present with the correct options. In the gbp.conf file, ensure you have the correct options based on:
  1. Does upstream release tarballs? If so, enforce pristine-tar = True.
  2. Does upstream sign the tarballs? If so, configure explicit signature checking with upstream-signatures = on.
  3. Does upstream have a git repository, and does it have release git tags? If so, configure the release git tag format, e.g. upstream-vcs-tag = %(version%~%.)s.
To validate that the above files are working correctly, run gbp import-orig with the current version explicitly defined:
shell
$ gbp import-orig --uscan --upstream-version 5.6
gbp:info: Launching uscan...
gpgv: Signature made 7. Aug 2024 07.43.27 PDT
gpgv: using RSA key 519151D83E83D40A232B4D615C418B8631BC7C26
gpgv: Good signature from "Eric Radman <ericshane@eradman.com>"
gbp:info: Using uscan downloaded tarball ../entr_5.6.orig.tar.gz
gbp:info: Importing '../entr_5.6.orig.tar.gz' to branch 'upstream/latest'...
gbp:info: Source package is entr
gbp:info: Upstream version is 5.6
gbp:info: Replacing upstream source on 'debian/latest'
gbp:info: Running Postimport hook
gbp:info: Successfully imported version 5.6 of ../entr_5.6.orig.tar.gz
As the original packaging was done based on the upstream release git tag, the above command will fetch the tarball release, create the pristine-tar branch, and store the tarball delta on it. This command will also attempt to create the tag upstream/5.6 on the upstream/latest branch.

Import new upstream versions in the future Forking the upstream git repository, creating the initial packaging, and creating the DEP-14 branch structure are all one-off work needed only when creating the initial packaging. Going forward, to import new upstream releases, one would simply run git fetch upstreamvcs; gbp import-orig --uscan, which fetches the upstream git tags, checks for new upstream tarballs, and automatically downloads, verifies, and imports the new version. See the galera-4-demo example in the Debian source packages in git explained post as a demo you can try running yourself and examine in detail. You can also try running gbp import-orig --uscan without specifying a version. It would fetch it, as it will notice there is now Entr version 5.7 available, and import it.

Build using git-buildpackage From this stage onwards you should build the package using gbp buildpackage, which will do a more comprehensive build.
shell
gbp buildpackage -uc -us
The git-buildpackage build also includes running Lintian to find potential Debian policy violations in the sources or in the resulting .deb binary packages. Many Debian Developers run lintian -EviIL +pedantic after every build to check that there are no new nags, and to validate that changes intended to previous Lintian nags were correct.

Open a Merge Request on Salsa for Debian packaging review Getting everything perfectly right takes a lot of effort, and may require reaching out to an experienced Debian Developers for review and guidance. Thus, you should aim to publish your initial packaging work on Salsa, Debian s GitLab instance, for review and feedback as early as possible. For somebody to be able to easily see what you have done, you should rename your debian/latest branch to another name, for example next/debian/latest, and open a Merge Request that targets the debian/latest branch on your Salsa fork, which still has only the unmodified upstream files. If you have followed the workflow in this post so far, you can simply run:
  1. git checkout -b next/debian/latest
  2. git push --set-upstream origin next/debian/latest
  3. Open in a browser the URL visible in the git remote response
  4. Write the Merge Request description in case the default text from your commit is not enough
  5. Mark the MR as Draft using the checkbox
  6. Publish the MR and request feedback
Once a Merge Request exists, discussion regarding what additional changes are needed can be conducted as MR comments. With an MR, you can easily iterate on the contents of next/debian/latest, rebase, force push, and request re-review as many times as you want. While at it, make sure the Settings > CI/CD page has under CI/CD configuration file the value debian/salsa-ci.yml so that the CI can run and give you immediate automated feedback. For an example of an initial packaging Merge Request, see https://salsa.debian.org/otto/entr-demo/-/merge_requests/1.

Open a Merge Request / Pull Request to fix upstream code Due to the high quality requirements in Debian, it is fairly common that while doing the initial Debian packaging of an open source project, issues are found that stem from the upstream source code. While it is possible to carry extra patches in Debian, it is not good practice to deviate too much from upstream code with custom Debian patches. Instead, the Debian packager should try to get the fixes applied directly upstream. Using git-buildpackage patch queues is the most convenient way to make modifications to the upstream source code so that they automatically convert into Debian patches (stored at debian/patches), and can also easily be submitted upstream as any regular git commit (and rebased and resubmitted many times over). First, decide if you want to work out of the upstream development branch and later cherry-pick to the Debian packaging branch, or work out of the Debian packaging branch and cherry-pick to an upstream branch. The example below starts from the upstream development branch and then cherry-picks the commit into the git-buildpackage patch queue:
shell
git checkout -b bugfix-branch master
nano entr.c
make
./entr # verify change works as expected
git commit -a -m "Commit title" -m "Commit body"
git push # submit upstream
gbp pq import --force --time-machine=10
git cherry-pick <commit id>
git commit --amend # extend commit message with DEP-3 metadata
gbp buildpackage -uc -us -b
./entr # verify change works as expected
gbp pq export --drop --commit
git commit --amend # Write commit message along lines "Add patch to .."
The example below starts by making the fix on a git-buildpackage patch queue branch, and then cherry-picking it onto the upstream development branch:
shell
gbp pq import --force --time-machine=10
nano entr.c
git commit -a -m "Commit title" -m "Commit body"
gbp buildpackage -uc -us -b
./entr # verify change works as expected
gbp pq export --drop --commit
git commit --amend # Write commit message along lines "Add patch to .."
git checkout -b bugfix-branch master
git cherry-pick <commit id>
git commit --amend # prepare commit message for upstream submission
git push # submit upstream
The key git-buildpackage commands to enter and exit the patch-queue mode are:
shell
gbp pq import --force --time-machine=10
gbp pq export --drop --commit
%% init:   'gitGraph':   'mainBranchName': 'debian/latest'      %%
gitGraph
checkout debian/latest
commit id: "Initial packaging"
branch patch-queue/debian/latest
checkout patch-queue/debian/latest
commit id: "Delete debian/patches/..."
commit id: "Patch 1 title"
commit id: "Patch 2 title"
commit id: "Patch 3 title"
These can be run at any time, regardless if any debian/patches existed prior, or if existing patches applied cleanly or not, or if there were old patch queue branches around. Note that the extra -b in gbp buildpackage -uc -us -b instructs to build only binary packages, avoiding any nags from dpkg-source that there are modifications in the upstream sources while building in the patches-applied mode.

Programming-language specific dh-make alternatives As each programming language has its specific way of building the source code, and many other conventions regarding the file layout and more, Debian has multiple custom tools to create new Debian source packages for specific programming languages. Notably, Python does not have its own tool, but there is an dh_make --python option for Python support directly in dh_make itself. The list is not complete and many more tools exist. For some languages, there are even competing options, such as for Go there is in addition to dh-make-golang also Gophian. When learning Debian packaging, there is no need to learn these tools upfront. Being aware that they exist is enough, and one can learn them only if and when one starts to package a project in a new programming language.

The difference between source git repository vs source packages vs binary packages As seen in earlier example, running gbp buildpackage on the Entr packaging repository above will result in several files:
entr_5.6-1_amd64.changes
entr_5.6-1_amd64.deb
entr_5.6-1.debian.tar.xz
entr_5.6-1.dsc
entr_5.6.orig.tar.gz
entr_5.6.orig.tar.gz.asc
The entr_5.6-1_amd64.deb is the binary package, which can be installed on a Debian/Ubuntu system. The rest of the files constitute the source package. To do a source-only build, run gbp buildpackage -S and note the files produced:
entr_5.6-1_source.changes
entr_5.6-1.debian.tar.xz
entr_5.6-1.dsc
entr_5.6.orig.tar.gz
entr_5.6.orig.tar.gz.asc
The source package files can be used to build the binary .deb for amd64, or any architecture that the package supports. It is important to grasp that the Debian source package is the preferred form to be able to build the binary packages on various Debian build systems, and the Debian source package is not the same thing as the Debian packaging git repository contents.
flowchart LR
git[Git repository<br>branch debian/latest] --> gbp buildpackage -S  src[Source Package<br>.dsc + .tar.xz]
src --> dpkg-buildpackage  bin[Binary Packages<br>.deb]
If the package is large and complex, the build could result in multiple binary packages. One set of package definition files in debian/ will however only ever result in a single source package.

Option to repackage source packages with Files-Excluded lists in the debian/copyright file Some upstream projects may include binary files in their release, or other undesirable content that needs to be omitted from the source package in Debian. The easiest way to filter them out is by adding to the debian/copyright file a Files-Excluded field listing the undesired files. The debian/copyright file is read by uscan, which will repackage the upstream sources on-the-fly when importing new upstream releases. For a real-life example, see the debian/copyright files in the Godot package that lists:
debian
Files-Excluded: platform/android/java/gradle/wrapper/gradle-wrapper.jar
The resulting repackaged upstream source tarball, as well as the upstream version component, will have an extra +ds to signify that it is not the true original upstream source but has been modified by Debian:
godot_4.3+ds.orig.tar.xz
godot_4.3+ds-1_amd64.deb

Creating one Debian source package from multiple upstream source packages also possible In some rare cases the upstream project may be split across multiple git repositories or the upstream release may consist of multiple components each in their own separate tarball. Usually these are very large projects that get some benefits from releasing components separately. If in Debian these are deemed to go into a single source package, it is technically possible using the component system in git-buildpackage and uscan. For an example see the gbp.conf and watch files in the node-cacache package. Using this type of structure should be a last resort, as it creates complexity and inter-dependencies that are bound to cause issues later on. It is usually better to work with upstream and champion universal best practices with clear releases and version schemes.

When not to start the Debian packaging repository as a fork of the upstream one Not all upstreams use Git for version control. It is by far the most popular, but there are still some that use e.g. Subversion or Mercurial. Who knows maybe in the future some new version control systems will start to compete with Git. There are also projects that use Git in massive monorepos and with complex submodule setups that invalidate the basic assumptions required to map an upstream Git repository into a Debian packaging repository. In those cases one can t use a debian/latest branch on a clone of the upstream git repository as the starting point for the Debian packaging, but one must revert the traditional way of starting from an upstream release tarball with gbp import-orig package-1.0.tar.gz.

Conclusion Created in August 1993, Debian is one of the oldest Linux distributions. In the 32 years since inception, the .deb packaging format and the tooling to work with it have evolved several generations. In the past 10 years, more and more Debian Developers have converged on certain core practices evidenced by https://trends.debian.net/, but there is still a lot of variance in workflows even for identical tasks. Hopefully, you find this post useful in giving practical guidance on how exactly to do the most common things when packaging software for Debian. Happy packaging!

Next.

Previous.