Search Results: "spa"

7 December 2010

John Goerzen: A Switchbox and a Very Happy 4-Year-Old

This all started this summer. My parents have some dimmer switches in their house, which Jacob loves. He also enjoyed turning their lights on an off rapidly to make them flash. Since we have CFLs almost exclusively, we have no dimmer switches, and we don t permit making the lights flash. (This hurts the lifespan of CFLs much more than traditional bulbs.) (I ll just put a few pictures from tonight within the story so you get an idea of what it turned out to be while you read.) IMG_5109.JPG So I had an idea: why not build him a box that has some switches that he can play with? And why not make it a project we can do together? So back in, I think, July, we went to the hardware store. We bought some AC power cord, some electrical boxes, and assorted supplies. I had some other supplies on hand already, so we didn t need to spend much. I asked Jacob today if he remembered that day, and he said, Oh yes! And I got popcorn to eat there! Which was, indeed, quite true. IMG_5111.JPG I had some surplus plywood, so I cut out two squares, one for a front and one for a back. Then, in 10-minute increments every so often over the last few months, Jacob would say, Dad, shall we go work on my switchbox? And by that, he meant that I should work on the switchbox while he pretends that my tape measures are train engines or raids the corner where disused toys are stored. After 10 minutes, he d be done. Which meant that after I gathered up my tools, remembered where I was, and got to work, I made only a few minutes progress each week. But that was fine. This week, I got it all wired up. It doesn t have its sides and back yet, but it was enough for Jacob to try it out. To add to the excitement just that much more, I spent a few dollars at the hardware store today and bought him four light bulbs: 25W red, green, and blue bulbs, and a 7.5W miniature white one. I let him choose two of them to use in the switchbox. IMG_5117.JPG So he started playing with it, and after just a few seconds, said, Dad, I am very very very very excited about my switchbox! And a little while later, he burst into applause, and announced, Dad, my switchbox is so so so so so fun! It is also so so so so so silly the lightbulb is green! I wired up a regular light switch that is a master on/off switch. Then the dimmer switch controls the light bulb socket but not the outlet. The dimmer switch also has a pushbutton on/off circuit, so there are plenty of opportunities for discovery. IMG_5113.JPG This is a play with it only with dad s supervision item for now, but after supper, he insisted in bringing Terah downstairs to show her how to use it too. He happily showed off the red and green lights, how to turn them on, and how to make the red light dimmer. I suggested he also show her what happens when he pushes on the dimmer switch, which he happily did, and also explained to her what it does. He was just amazingly excited. Every so often he d tell me how excited or happy he was, and some fun fact about it all. And, really, that s what I hoped would happen. I didn t accompany it with these words, but I hope that projects like this can serve to remind everyone that toys and gifts don t have to cost hundreds of dollars; they can be made with a few dollars supplies and some surplus materials laying around the house. But not only that, but the best parts of this project were the ones Jacob and I spent together from the time when just the two of us went shopping at the hardware store, through all those 10-minute times where he pretended my tape measures were locomotives and the tape was their track, right to today when he got to try it out. It took a long time, but when I asked him if it was worth the wait, he said Yes! and clapped while jumping up and down. And, I have to admit, as I got into the car with my $4 worth of light bulbs today, I was almost as excited as him, just to see what he would do. That s the best part: I got to experience Jacob s joy right along with him. It s a time when I really enjoy being a dad. IMG_5110.JPG

6 December 2010

Vincent Sanders: New Video Camera

Last week they boys were playing with their remote control car in the snow (which was fun) and Alex wanted to record what his car saw. I immediately dissuaded him from the idea that he can use the family's DV camcorder taped to his car!

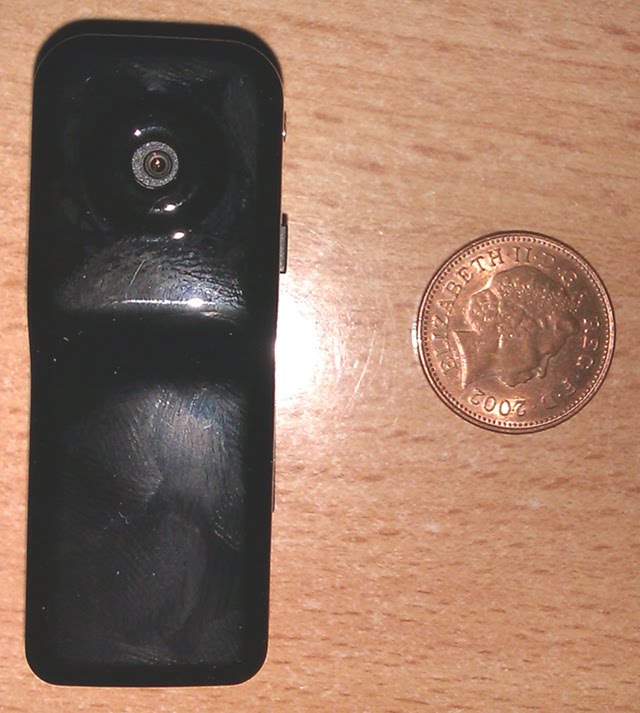
The camera and a UK penny
Later on that day though I saw a rocket project on LMR which used a micro camera and suggested such cameras were available from ebay very cheaply. I did a quick search and ordered on from a UK seller at 15 plus 2.99 pnp and thought no more of it.

This afternoon the camera arrived and it really is tiny and Alex is already scheming of ways to use it in addition to attaching it to his RC car.

The video output is low quality (very blurry in low light) and I have yet to figure out how to disable the time stamp (which is wrong) but it does indeed record video to the storage and can download it via USB and played using VLC.

So if you want a tiny video camera (and an 8Gig micro SD card) which is so cheap you do not care if it gets broken, I can recommend these.

<object class="BLOG_video_class" classid="clsid:D27CDB6E-AE6D-11cf-96B8-444553540000" codebase="http://download.macromedia.com/pub/shockwave/cabs/flash/swflash.cab#version=6,0,40,0" height="266" id="BLOG_video-e10aebbc1dd937ed" width="320"><param name="movie" value="http://www.youtube.com/get_player"><param name="bgcolor" value="#FFFFFF"><param name="allowfullscreen" value="true"><param name="flashvars" value="flvurl=http%3A%2F%2Fv7.nonxt4.googlevideo.com%2Fvideoplayback%3Fid%3De10aebbc1dd937ed%26itag%3D5%26app%3Dblogger%26ip%3D0.0.0.0%26ipbits%3D0%26expire%3D1293804875%26sparams%3Did%252Citag%252Cip%252Cipbits%252Cexpire%26signature%3D4F186A3751631F2931BE78DB408398983676DB8E.2FDDADC2413DD729039774AA440EAB1C95EA068A%26key%3Dck1&amp;iurl=http%3A%2F%2Fvideo.google.com%2FThumbnailServer2%3Fapp%3Dblogger%26contentid%3De10aebbc1dd937ed%26offsetms%3D5000%26itag%3Dw160%26sigh%3Dx99eVmNAybTlHHC3EkTV9GH9eUI&amp;autoplay=0&amp;ps=blogger"><embed allowfullscreen="true" bgcolor="#FFFFFF" flashvars="flvurl=http%3A%2F%2Fv7.nonxt4.googlevideo.com%2Fvideoplayback%3Fid%3De10aebbc1dd937ed%26itag%3D5%26app%3Dblogger%26ip%3D0.0.0.0%26ipbits%3D0%26expire%3D1293804875%26sparams%3Did%252Citag%252Cip%252Cipbits%252Cexpire%26signature%3D4F186A3751631F2931BE78DB408398983676DB8E.2FDDADC2413DD729039774AA440EAB1C95EA068A%26key%3Dck1&amp;iurl=http%3A%2F%2Fvideo.google.com%2FThumbnailServer2%3Fapp%3Dblogger%26contentid%3De10aebbc1dd937ed%26offsetms%3D5000%26itag%3Dw160%26sigh%3Dx99eVmNAybTlHHC3EkTV9GH9eUI&amp;autoplay=0&amp;ps=blogger" height="266" src="http://www.youtube.com/get_player" type="application/x-shockwave-flash" width="320"></object>

Rapha&#235;l Hertzog: State of the Debian-Ubuntu relationship

Debian welcoming contributions from derivativesThe relationship between Debian and Ubuntu has been the subject of many vigorous debates over the years, ever since Ubuntu s launch in 2004. Six years later, the situation has improved and both projects are communicating better. The Natty Narwhal Ubuntu Developer Summit (UDS) featured like all UDS for more than 2 years a Debian Health Check session where current cooperation issues and projects are discussed. A few days after that session, Lucas Nussbaum gave a talk during the mini-Debconf Paris detailing the relationship between both projects, both at the technical and social level. He also shared some concerns for Debian s future and gave his point of view on how Debian should address them. Both events give valuable insights on the current state of the relationship. Lucas Nussbaum s Debian-Ubuntu talk Lucas started by introducing himself. He s an Ubuntu developer since 2006 and a Debian developer since 2007. He has worked to improve the collaboration between both projects, notably by extending the Debian infrastructure to show Ubuntu-related information. He attended conferences for both projects (Debconf, UDS) and has friends in both communities. For all of these reasons, he believes himself to be qualified to speak on this topic. Collaboration at the technical level He then quickly explained the task of a distribution: taking upstream software, integrating it in standardized ways, doing quality assurance on the whole, delivering the result to users, and assuring some support afterward. He pointed out that in the case of Ubuntu, the distribution has one special upstream: Debian. Indeed Ubuntu gets most of its software from Debian (89%), and only 7% are new packages coming from other upstream projects (the remaining 4% are unknown, they are newer upstream releases of software available in Debian but he was not able to find out whether the Debian packaging had been reused or not). From all the packages imported from Debian, 17% have Ubuntu-specific changes. The reasons for those changes are varied: bugfixes, integration with Launchpad/Ubuntu One/etc., or toolchain changes. The above figures are based on Ubuntu Lucid (10.04) while excluding many Ubuntu-specific packages (language-pack-*, language-support-*, kde-l10n-*, *ubuntu*, *launchpad*). The different agendas and the differences in philosophy (Debian often seeking perfect solutions to problems; Ubuntu accepting temporary suboptimal workarounds) also explain why so many packages are modified on the Ubuntu side. It s simply not possible to always do the work in Debian first. But keeping changes in Ubuntu requires a lot of work since they merge with Debian unstable every 6 months. That s why they have a strong incentive to push changes to upstream and/or to Debian. There are 3 channels that Ubuntu uses to push changes to Debian: they file bug reports (between 250 to 400 during each Ubuntu release cycle), they interact directly with Debian maintainers (often the case when there s a maintenance team), or they do nothing and hope that the Debian maintainer will pick up the patch directly from the Debian Package Tracking System (it relays information provided by patches.ubuntu.com). Lucas pointed out that those changes are not the only thing that Debian should take back. Ubuntu has a huge user base resulting in lots of bug reports sitting in Launchpad, often without anyone taking care of them. Debian maintainers who already have enough bugs on their packages are obviously not interested in even more bugs, but those who are maintaining niche packages, with few reports, might be interested by the user feedback available in Launchpad. Even if some of the reports are Ubuntu-specific, many of them are advance warnings of problems that will affect Debian later on, when the toolchain catches up with Ubuntu s aggressive updates. To make this easier for Debian maintainers, Lucas improved the Debian Package Tracking System so that they can easily get Ubuntu bug reports for their packages even without interacting with Launchpad. Human feelings on both sides Lucas witnessed a big evolution in the perception of Ubuntu on the Debian side. The initial climate was rather negative: there were feelings of its work being stolen, claims of giving back that did not match the observations of the Debian maintainers, and problems with specific Canonical employees that reflected badly on Ubuntu as a whole. These days most Debian developers find something positive in Ubuntu: it brings a lot of new users to Linux, it provides something that works for their friends and family, it brings new developers to Debian, and it serves as a technological playground for Debian. On the Ubuntu side, the culture has changed as well. Debian is no longer so scary for Ubuntu contributors and contributing to Debian is The Right Thing to do. More and more Ubuntu developers are getting involved in Debian as well. But at the package level there s not always much to contribute, as many bugfixes are only temporary workarounds. And while Ubuntu s community follows this philosophy, Canonical is a for-profit company that contributes back mainly when it has compelling reasons to do so. Consequences for Debian In Lucas s eyes, the success of Ubuntu creates new problems. For many new users Linux is a synonym for Ubuntu, and since much innovation happens in Ubuntu first, Debian is overshadowed by its most popular derivative. He goes as far as saying that because of that Debian becomes less relevant . He went on to say that Debian needs to be relevant because the project defends important values that Ubuntu does not. And it needs to stay as an independent partner that filters what comes out of Ubuntu, ensuring that quality prevails in the long term. Fixing this problem is difficult, and the answer should not be to undermine Ubuntu. On the contrary, more cooperation is needed. If Debian developers are involved sooner in Ubuntu s projects, Debian will automatically get more credit. And if Ubuntu does more work in Debian, their work can be showcased sooner in the Debian context as well. The other solution that Lucas proposed is that Debian needs to communicate on why it s better than Ubuntu. Debian might not be better for everybody but there are many reasons why one could prefer Debian over Ubuntu. He listed some of them: Debian has better values since it s a volunteer-based project where decisions are made publicly and it has advocated the free software philosophy since 1993. On the other hand, Ubuntu is under control of Canonical where some decisions are imposed, it advocates some proprietary web services (Ubuntu One), the installer recommends adding proprietary software, and copyright assignments are required to contribute to Canonical projects. Debian is also better in terms of quality because every package has a maintainer who is often an expert in the field of the package. As a derivative, Ubuntu does not have the resources to do the same and instead most packages are maintained on a best effort basis by a limited set of developers who can t know everything about all packages. In conclusion, Lucas explained that Debian can neither ignore Ubuntu nor fight it. Instead it should consider Ubuntu as a chance and should leverage it to get back in the center of the FLOSS ecosystem . The Debian health check UDS session While this session has existed for some time, it s only the second time that a Debian Project Leader was present at UDS to discuss collaboration issues. During UDS-M (the previous summit), this increased involvement from Debian was a nice surprise to many. Stefano Zacchiroli the Debian leader collected and shared the feedback of Debian developers and the session ended up being very productive. Six months later is a good time to look back and verify if decisions made during UDS-M (see blueprint) have been followed through. Progress has been made On the Debian side, Stefano set up a Derivatives Front Desk so that derivative distributions (not just Ubuntu) have a clear point of contact when they are trying to cooperate but don t know where to start. It s also a good place to share experiences among the various derivatives. In parallel, a #debian-ubuntu channel has been started on OFTC (the IRC network used by Debian). With more than 50 regulars coming from both distributions, it s a good place for quick queries when you need advice on how to interact with the distribution that you re not familiar with. Ubuntu has updated its documentation to prominently feature how to cooperate with Debian. For example, the sponsorship process documentation explains how to forward patches both to the upstream developers and to Debian. It also recommends ensuring that the patch is not Ubuntu-specific and gives some explanation on how to do it (which includes checking against a list of common packaging changes made by Ubuntu). The Debian Derivative Front Desk is mentioned as a fallback when the Debian maintainer is unresponsive. While organizing Ubuntu Developer Week, Ubuntu now reaches out to Debian developers and tries to have sessions on working with Debian . Launchpad has also been extended to provide a list of bugs with attached patches and that information has been integrated in the Debian Package Tracking system by Lucas Nussbaum. Still some work to do Some of the work items have not been completed yet: many Debian maintainers would like a simpler way to issue a sync request (a process used to inject a package from Debian into Ubuntu). There s a requestsync command line tool provided by the ubuntu-dev-tools package (which is available in Debian) but it s not yet usable because Launchpad doesn t know the GPG keys of Debian maintainers. Another issue concerns packages which are first introduced in Ubuntu. Most of them have no reason to be Ubuntu-specific and should also end up in Debian. It has thus been suggested that people packaging new software for Ubuntu also upload them to Debian. They could however immediately file a request for adoption (RFA) to find another Debian maintainer if they don t plan to maintain it in the long term. If Ubuntu doesn t make this effort, it can take a long time until someone decides to reintegrate the Ubuntu package into Debian just because nobody knows about it. This represents an important shift in the Ubuntu process and it s not certain that it s going to work out. As with any important policy change, it can take several years until people are used to it. Both issues have been rescheduled for this release cycle, so they re still on the agenda. This time the UDS session was probably less interesting than the previous one. Stefano explained once more what Debian considers good collaboration practices: teams with members from both distributions, and forwarding of bugs if they have been well triaged and are known to apply to Debian. He also invited Ubuntu to discuss big changes with Debian before implementing them. An interesting suggestion that came up was that some Ubuntu developers could participate in Debcamp (one week hack-together before Debconf) to work with some Debian developers, go through Ubuntu patches, and merge the interesting bits. This would nicely complement Ubuntu s increased presence at Debconf: for the first time, community management team member Jorge Castro was at DebConf 10 giving a talk on collaboration between Debian and Ubuntu. There was also some brainstorming on how to identify packages where the collaboration is failing. A growing number of Ubuntu revisions (identified for example by a version like 1.0-1ubuntu62) could indicate that no synchronization was made with Debian, but it would also identify packages which are badly maintained on the Debian side. If Ubuntu consistently has a newer upstream version compared to Debian, it can also indicate a problem: maybe the person maintaining the package for Ubuntu would be better off doing the same work in Debian directly since the maintainer is lagging or not doing their work. Unfortunately this doesn t hold true for all packages since many Gnome packages are newer in Ubuntu but are actively maintained on both sides. Few of those discussions led to concrete decisions. It seems most proponents are reasonably satisfied with the current situation. Of course, one can always do better and Jono Bacon is going to ensure that all Canonical teams working on Ubuntu are aware of how to properly cooperate with Debian. The goal is to avoid heavy package modifications without coordination. Conclusion The Debian-Ubuntu relationships used to be a hot topic, but that s no longer the case thanks to regular efforts made on both sides. Conflicts between individuals still happen, but there are multiple places where they can be reported and discussed (#debian-ubuntu channel, Derivatives Front Desk at derivatives@debian.org on the Debian side or debian@ubuntu.com on the Ubuntu side). Documentation and infrastructure are in place to make it easier for volunteers to do the right thing. Despite all those process improvements, the best results still come out when people build personal relationships by discussing what they are doing. It often leads to tight cooperation, up to commit rights to the source repositories. Regular contacts help build a real sense of cooperation that no automated process can ever hope to achieve.

This article was first published in Linux Weekly News. You can get my monthly summary of the Debian/Ubuntu news, all you have to do is to click here to subscribe to my free newsletter.

5 comments Liked this article? Click here. My blog is Flattr-enabled.

5 December 2010

Andrew Pollock: [tech] A cleaner puppet manifest

Jon Downland is tinkering with Puppet, and wrote a class with a package resource to install a bunch of packages, but didn't quite like the way it was written. The way that I'd achieve the same thing, and be slightly cleaner would be something like this:
class jon-desktop  
	$packages_to_install_by_default = [
		'icedove',
		'git-core',
		'vim-gnome',
		'vinagre',
		'build-essential',
		'devscripts',
		'subversion',
		'git-buildpackage',
		'mutt',
		'offlineimap',
		'ascii',
		'gitk',
		'chromium-browser',
	]
	package   $packages_to_install_by_default:
		ensure => installed,
	 
 
This way your actual package resource definition never needs to change. The variable you choose to use to define the list of packages to install can be abstracted away as much as desired.

Jon Dowland: puppet

As a first step on the road to evaluating different configuration management systems, I set up two VMs to test out puppet. Puppet is conveniently packaged within Debian so client and server installation was very simple. By default, puppet clients will look for a host named puppet on the local network, so by naming the server sensibly the two started talking to each other. puppetca --sign [client hostname] on the server started the ball rolling. My first test configuration was to add a user to the sudoers file. With CF Engine 2, I would have achieved this by using editfiles to check for a regular expression and insert a line if necessary. I stumbled across some CF Engine-style definitions for puppet in a Debian Administration article (taken originally from puppet's own wiki, which have since been moved/deleted) and achieved it using

append_if_no_such_line   sudo:
  file => "/etc/sudoers",
  line => "jon ALL=(ALL) ALL"
 
I'm a little concerned that this approach to problem solving is no better than CF Engine 2, and in fact worse than how I'd do it with CF Engine 2: if the host had a line with a different quantity of whitespace, such as jon ALL=(ALL) ALL, it won't match exactly and a duplicate line will be appended, whereas with CF Engine 2 I would have checked for something like ^jon \+ALL=(ALL) \+ALL$. I set up my work laptop as another test node, and used puppet to install some packages that I commonly use:
class jon-desktop  
  package   ['icedove', 'git-core', 'vim-gnome', 'vinagre', 'build-essential',
             'devscripts', 'subversion', 'git-buildpackage', 'mutt',
             'offlineimap', 'ascii', 'gitk', 'chromium-browser'
            ]: ensure => installed  
 
This worked fine, but is a little verbose and the package list is awkward to maintain buried inside the puppet syntax. I spent some time trying to see whether I could populate a puppet list based on the contents of a file: then I could list the packages one-per-line in a separate file. I haven't found a way of doing that yet. Using my laptop as a second node also exposed some interesting puppet client behaviour. Once I went off-site, the laptop tried to look up puppet on foreign networks (such as my home network). I would have assumed that, once the strong SSL association had been made, the client would try to connect to the FQDN of the server. This probably isn't a serious problem in practice, as we probably won't need to rely on nodes off-site talking to the configuration server, but I hope that the client doesn't trust any host that happens to answer to puppet... I fixed this by hacking my hosts file to include an entry for puppet. I could maintain this hack using Puppet itself, which would protect me against stale definitions if any renumbering takes place. I could also have added a line
server = puppet.fqdn.example.org
in /etc/puppet/puppet.conf, which is a more robust way of solving the problem.

Christoph Egger: The erlang experience

This week I had to write a little tool that would collect input on different channels, via socket / netcat, via a http server, .... Calls for a parralel Design -- Maybe a good place to write something real in Erlang. While erlang itself was really nice to write -- I do like Prolog as well as the bunch of functional languages -- doing networking in erlang seems a bit special, the interfaces just aren't thin wrappers around the libc stuff. Getting a Socket Text interface What sounds like a easy challenge to accomplish was actually harder than expected. All I found was some way to pass binaries representing erlang code over a socket and evaluating it remotle. While it's nice that such things are as easy to do as they are it doesn't help me with my task of moving simple strings.
start() ->
     ok, Listen  = gen_tcp:listen(51622, [binary,  packet, 0 ,
                                          reuseaddr, true ,
                                          active, true ]),
    spawn(fun () -> accept_loop(Listen) end).
accept_loop(Listen) ->
     ok, Socket  = gen_tcp:accept(Listen),
    accept_loop(Listen),
    handle(Socket)
handle(Socket) ->
    receive
         tcp, Socket, Bin  ->
            io:format("~p~n", binary_to_list(Bin));
         tcp_closed, Socket  ->
            Buffer
    end.
So the socket is now up and receives text as wanted. However, as we are already runnign a parralel program it would be nice to be hable to handle multiple socket connections in parralel right? For that we just need to add a spawn() at the right place. The right place is not the handle(Socket) but the accept_loop(Listen) because the process that called accept will receive all the tcp messages. This last part was quite obvious after finding the documentation of the active, _ properties for the socket. always here means that you'll receive all data from the socket as erlang Messages, once delivers one package and waits until it is activated again and false requires calling a method -- this would have been possible as well when forking handle(Socket). The web server Ok we also want a webserver. We do not want to run some webapplication inside appache or so, just do some post/get and simple pages. Erlang here provides a built-in httpd with some mod_esi that calls some function depending on the URL used. It doesn't do anything fancy like templating or DB backends or stuff, just taking strings and building the http answers. Unfortunately there are no examples around and basically noone seems to be using this combination (apart from some hacks like mine probably). So as I needed to get some additional information into the handler function (a Pid to connect to some service), I, as a novice, just couldn't find a way. Asking on IRC the solution was rather simple: Just using erlang's process registry. For more complex stuf gproc might prove usefull here. Result I guess I've got a huge step farther in programming erlang now. The manpages are easily found by your search engine -- for python I have to either walk through the (well structured) online documentation or search for the right link in the search results, for erlang they're typically first. Also Joe Armstrong's Books as proven usefull. The most dificult part probably is getting around all the nice extras you can do (transfering functions over sockets et al) and find out how to do the thing you need.

4 December 2010

Richard Darst: Debian-NYC Novice Night was a great success

The first Debian-NYC Novice Night was a great success. We had about 25 people, about fifteen of which we had never seen before. We've been trying hard to reach out to new groups, and it seems to have worked even though we have a lot yet to do. One idea we'll probably use in the future is Novice Nights targeted to specific groups. A group of tech teachers in NYC has already contacted us and we will probably do a night in conjunction with them in the near future.People came for all sorts of reasons. We had a lot of installations, some people came for help configuration or upgrading, and some people came just to talk and learn more. Those who came to help learned a lot, too. Most everyone wants to come back.As with all Debian-NYC's activities, our plans and what we have learned are online so that anyone can adapt and reproduce what we do.We have a social event on December 10th, and will have another workshop, and another Novice Night, early next year.Tags: debian-nyc

3 December 2010

Neil Williams: Documenting Emdebian - components and filters

A continuation of my intermittent series on Emdebian. This time covering how Emdebian changes component behaviourin Emdebian Grip.
Debian divides packages principally between those which comply with the DFSG (main), those which do not (non-free) and those which could but depend on those which do not (contrib). This leads to an enormous bias towards packages in main, which is good in terms of DFSG compliance but not so good for the size of the Packages files which every machine has to download to be able to install new stuff or upgrade existing stuff.
Emdebian is as concerned about the runtime space requirements of the system as much as the install time space requirements. Little point gaining 20Mb by removing stuff from packages if the next apt-get update adds 30Mb of cache data.
Therefore, Emdebian Grip sub-divides main (we don't have contrib or non-free packages at this time). This gives most users the smallest cache data size whilst allowing other users to add the extra components and get the full list of packages provided in Emdebian.
Alongside this division, the aim with emdebian-grip-server is to help others run secondary Emdebian Grip build machines which have a different range of packages. This allows one server to focus on XFCE and one to use other desktops or no desktops.
Components in Grip
Grip subdivides Debian main into main (~60%), dev (~30%), java, debug and doc components. The main emphasis, therefore, is that most Emdebian Grip machines will not be used to actually build other packages. I covered some of the theory on this step on the debian-embedded mailing list in 2009.
Component allocation
Packages are allocated to particular components by three main mechanisms:
  1. Package name suffix - -dev packages into dev, -dbg packages into debug, -doc packages into doc.
  2. Section names - devel goes into dev, java goes into java
  3. Override files which are visible via the emdebian website.

Override files cover situations where a package is in a problematic Section (e.g. dbus is in Section: devel when it is almost impossible to have a netbook or graphical Debian installation without it). Once Squeeze is released, I might take up these overrides with ftpmaster to see if some rationale can be constructed to make things easier.
Sources
The use of components means that an Emdebian Grip device can choose a range of components in the apt sources line. Any permutation as long as main is preserved.

deb http://www.emdebian.org/grip squeeze main dev debug java doc

More on Filtering
I mentioned last time that Emdebian does not carry all packages available in Debian. As well as filtering the files contained within packages, Emdebian Grip filters the list of packages which are allowed into the repository for each server. This is why Emdebian Grip has under 3,000 packages to be released alongside Squeeze. (Emdebian Grip 1.0 based on Lenny had some 1,000 packages.)
Filtering the list of packages means that the maintainer of the server gets to choose their package set in a similar way to how tasksel can be used to select a functionally complete set of packages at installation time. (Indeed, Emdebian Grip provides some bespoke tasks which optimise the combination of tasksel and repository filtering.) Processing packages for Emdebian Grip takes a finite amount of time per package, per architecture and restricting the total number of packages in Grip has several advantages:
  1. Further reductions in cache size - less files in the Packages file, less Packages data to download and cache.
  2. Less processing time which makes it easier to maintain an Emdebian Grip server
  3. Less data to mirror which makes it attractive for admins already running a full Debian mirror to consider squeezing in Emdebian Grip alongside.

Combining component changes and filters needs a little bit of careful handling in the server side code so that packages remain installable. Override files need to be adjusted manually, library transitions mean that once libfoo0 has been replaced by libfoo1, anything depending on libfoo1 is broken in Emdebian Grip until libfoo1 can be added to the repository (which is also a manual task). I'm glad that edos-debcheck is regaining a machine-parseable output format because this will add the chance to make at least some of these transition additions automatic. Other than these tasks, emdebian-grip-server is almost entirely automated and runs as a cron task creating verbose log files each run.
The server task runs edos-debcheck for each supported architecture and for each suite, carefully combining the various Packages files from the available components. As an alternative assessment, Debian Weather runs edos-debcheck over the Packages file for the main component only, for each suite and each architecture in Emdebian Grip. The combination of the two provides invaluable data to spot missing packages.
Equally, there are times when packages disappear from Debian. Currently, the automated scripts don't handle this aggressively but manual support scripts are available, usually for use before a release when the suites are changing less frequently.
I'll cover migrations between suites next time. In the meantime, if you want to prepare your own package set for Emdebian Grip, install emdebian-grip-server from experimental and file bugs to improve the documentation. :-)
Thanks to those who took on the Herculean task of translating the emdebian-grip-server manpages into German and French - more translations are always welcome. POT file contained inside the source package.

Pau Garcia i Quiles: Hello Planet Debian

My name is Pau and I am a software developer at Arisnova, a Spanish company specialized in Linux and Windows software development for the supervision and control (SCADA) of industrial environments. In Debian, I am the maintainer of: I also happen to be a KDE developer. How s this related to Debian? You ll find very soon.

Jos Parrella: Escenarios de uso de Likewise Open

Hace ya alg n tiempo escrib sobre el uso de libpam-ccreds y libnss-db para conseguir la implementaci n de un servicio de cach de credenciales. Sin embargo, hace casi un a o revisit el producto Likewise Open, en un proyecto grande de autenticaci n de Linux contra un Active Directory de Microsoft, o contra un dominio Windows desarrollado con Samba. En realidad Likewise Open elimina la incertidumbre de un setup artesanal de cach de credenciales, siempre y cuando el equipo se est loggeando contra un dominio Windows. Si usted tiene la necesidad de integrar una distribuci n de Linux moderna (una versi n reciente de Debian, Ubuntu, Fedora, por ejemplo) con un dominio Windows servidor por un Active Directory o por Samba, mi recomendaci n es que use Likewise Open. Likewise es libre, abierto y gratuito, y viene en los repositorios de muchas distribuciones, o se baja de la p gina Web de Likewise. Tiene dos versiones (paquetes), likewise-open-gui y likewise-open; el primero instala el segundo y ofrece una interfaz gr fica sencilla para unir el equipo al dominio. Solo se requiere el nombre del dominio, el nombre del equipo (se toma de hostname) y el usuario y la clave de un usuario que pueda agregar equipos al dominio. Como siempre, la resoluci n del dominio se hace consultando al DNS provisto en la configuraci n de red (u otorgado por el DHCP) por ciertos registros SRV, para obtener la IP de uno de los controladores de dominio, y luego ciertas conexiones a algunos puertos del controlador de dominio. Por lo tanto es importante que, si va a probar este escenario en una m quina virtual, la conexi n est en modo puente con la red en la que se encuentra el controlador de dominio. Una vez que el equipo se une al dominio, se crea la cuenta de m quina en el controlador de dominio, y al cerrar la sesi n, ya pueden ingresar a Linux los usuarios del dominio, usando la sintaxis DOMINIO.AD\usuario o DOMINIO\usuario (formas largas y cortas) y la contrase a del dominio. Las pol ticas de inicio de sesi n y contrase as ser n respetadas. Tambi n se puede usar domainjoin-cli para unirse por CLI. Obviamente, Likewise ya ofrece el servicio de cach de credenciales y de cach de usuarios y grupos (importa los grupos del dominio) y lo hace de forma transparente. Por ello, en muchos casos yo recomendar a que si tienes un OpenLDAP y quieres hacer cach con pam-ccreds y nss-db, haz un upgrade de OpenLDAP a un dominio usando Samba y usa Likewise. Ahorra muchos dolores de cabeza. En Likewise Open no hay soporte para GPOs. En ning n caso funcionar n las GPO que se hacen para Windows, pero en versiones pagadas de Likewise hay una funci n que a ade nuevas GPO para GNOME y otras aplicaciones. No he probado estas funcionalidades.

Pietro Abate: distcheck vs edos-debcheck

This is the second post about distcheck. I want to give a quick overview of the differences between edos-distcheck and the new version. First despite using the same sat solver and encoding of the problem, Distcheck has been re-written from scratch. Dose2 has several architectural problems and not very well documented. Adding new features had become too difficult and error-prone, so this was a natural choice (at least for me). Hopefully Dose3 will survive the Mancoosi project and provide a base for dependency reasoning. The framework is well documented and the architecture pretty modular. It's is written in ocaml, so sadly, I don't expect many people to join the development team, but we'll be very open to it. These are the main differences with edos-debcheck .

Performances distcheck is about two times faster than edos-debcheck (from dose2), but it is a "bit" slower then debcheck (say the original debcheck), that is the tool wrote by Jerome Vouillon and that was then superseded in debian by edos-debcheck. The original debcheck was a all-in-one tool that did the parsing, encoding and solving without converting the problem to any intermediate format. distcheck trades a bit of speed for generality. Since it is based on Cudf, it can handle different formats and can be easily adapted in a range of situation just by changing the encoding of the original problem to cudf. Below there are a couple of test I've performed on my machine (debian unstable). The numbers speak alone.
$time cat tmp/squeeze.packages edos-debcheck -failures > /dev/null
Completing conflicts... * 100.0%
Conflicts and dependencies... * 100.0%
Solving * 100.0%

real 0m19.515s
user 0m19.193s
sys 0m0.276s
$time ./distcheck.native -f deb://tmp/squeeze.packages > /dev/null

real 0m10.859s
user 0m10.669s
sys 0m0.172s

Input The second big difference is about different input format. In fact, at the moment, we have two different tools in debian, one edos-debcheck and the other edos-rpmcheck. Despite using the same underlying library these two tools have different code bases. distcheck basically is a multiplexer that convert different inputs to a common format and then uses it (agnostically) to solve the installation problem. It can be called in different ways (via symlinks) to behave similarly to its predecessors. At the moment we are able to handle 5 different formats
  1. deb:// Packages 822 format for debian based distributions
  2. hdlist:// a binary format used by rpm based distribution
  3. synth:// a simplified format to describe rpm based package repositories
  4. eclipse:// a 822 based format that encoded OSGi plugings metadata
  5. cudf:// the native cudf format
distcheck handles gz and bz2 compressed file transparently . However if you care about performances, you should decompress your input file first and the parse it with distcheck and it often takes more time to decompress the file on the fly that run the installability test itself. There is also an experimental database backend that is not compiled by default at them moment.

Output Regarding the output, I've already explained the main differences in an old post. As a quick reminder, the old edos-debcheck had two output options. The first is a human readable - unstructured output - that was a handy source of information when running the tool interactively. The second was a xml based format (without a dtd or a schema, I believe) that was used for batch processing. distcheck has only one output type in the YAML format that aims to be human and machine readable. Hopefully this will cater for both needs. Moreover, just recently I've added the output of distcheck a summary of who is breaking what. The output of edos-debcheck was basically a map of packages to the reasons of the breakage. In addition to this information distcheck gives also a maps between reason (a missing dependency or a conflict) to the list of packages that are broken by this problem.This additional info is off by default, but I think it can be nice to know what is the missing dependency that is responsible for the majority of problems in a distribution... For example, calling distcheck with --summary :
$./distcheck.native --summary deb://tests/sid.packages
backgroud-packages: 29589
foreground-packages: 29589
broken-packages: 143
missing-packages: 138
conflict-packages: 5
unique-missing-packages: 52
unique-conflict-packages: 5
summary:
-
missing:
missingdep: libevas-svn-05-engines-x (>= 0.9.9.063)
packages:
-
package: enna-dbg
version: 0.4.0-4
architecture: amd64
source: enna (= 0.4.0-4)
-
package: enna
version: 0.4.0-4
architecture: amd64
source: enna (= 0.4.0-4)
-
missing:
missingdep: libopenscenegraph56 (>= 2.8.1)
packages:
-
package: libosgal1
version: 0.6.1-2+b3
architecture: amd64
source: osgal (= 0.6.1-2)
-
package: libosgal-dev
version: 0.6.1-2+b3
architecture: amd64
source: osgal (= 0.6.1-2)
Below I give a small example of the edos-debcheck output compared to the new yaml based output.
$cat tests/sid.packages edos-debcheck -failures -explain
Completing conflicts... * 100.0%
Conflicts and dependencies... * 100.0%
Solving * 100.0%
zope-zms (= 1:2.11.1-03-1): FAILED
zope-zms (= 1:2.11.1-03-1) depends on missing:
- zope2.10
- zope2.9
zope-tinytableplus (= 0.9-19): FAILED
zope-tinytableplus (= 0.9-19) depends on missing:
- zope2.11
- zope2.10
- zope2.9
...
And an extract from the distcheck output (the order is different. I cut and pasted parts of the output here...)
$./distcheck.native -f -e deb://tests/sid.packages
report:
-
package: zope-zms
version: 1:2.11.1-03-1
architecture: all
source: zope-zms (= 1:2.11.1-03-1)
status: broken
reasons:
-
missing:
pkg:
package: zope-zms
version: 1:2.11.1-03-1
architecture: all
missingdep: zope2.9 zope2.10
-
package: zope-tinytableplus
version: 0.9-19
architecture: all
source: zope-tinytableplus (= 0.9-19)
status: broken
reasons:
-
missing:
pkg:
package: zope-tinytableplus
version: 0.9-19
architecture: all
missingdep: zope2.9 zope2.10 zope2.11
...

Future The roadmap to release version 1.0 of distcheck is as follows:
  1. add background and foreground package selection. This feature will allow the use to specify a larger universe (background packages), but check only a subset of this universe (foreground packages). This should allow users to select packages using grep-dctrl and then pipe them to discheck . At the moment we can select individual packages on the command line or we can use expression like bash (<= 2.7) to check all version of bash in the universe with version greater than 2.7.
  2. code cleanup and a bit of refactoring between distcheck and buildcheck (that is a frontend for distcheck that allow us to report broken build dependencies)
  3. consider essential packages while performing the installation test. Here there are few things we have to understand, but the idea would be to detect possible problems related the implicit presence of essential packages in the distribution. At the moment, distcheck performs the installation test in the empty universe, while ideally, the universe should contain all essential packages.
  4. finish the documentation. The effort in underway and we hope to finalize shortly to release the debian package in experimental.

2 December 2010

Matt Zimmerman: Breathing information

I ve written previously about my reading habits, online and offline, and the patterns I extrapolate to content consumption in general. I ve been talking with other people about this as well, and am beginning to develop a model to apply to my daily life. There are plenty of unsatisfactory metaphors circulating in this area: we eat the information diet , drink from the fire hose , endure the information explosion , and so on. None of them describe the richness of my experience: the profound variations in style, texture, speed, depth and movement are lost in this kind of dry imagery. Instead, I think of it like respiration. We inhale information, and we also exhale it transformed. We do this, consciously or unconsciously, every moment of our lives. Sometimes we do it quickly, other times slowly, and it can be relaxing or stimulating. We only retain a small amount of what we take in, but it becomes a part of us. We can immerse ourselves deeply, meditatively, in a series of breaths, or fail to notice as we breathe shallowly or pause altogether. One breath may be virtually silent, the next filled with a song or a question or a piercing whistle. We maintain a balance in our breathing, and I aspire to do the same with information: reading and writing, listening and speaking, seeing and being seen. I don t mean this simplistically, that I should do both in equal proportion (imagine trying to write as many words as you read!), but doing both consistently. It is often only when I share an idea that I come to understand it deeply, no matter how much I have read about it. By writing it down, or telling someone about it, I naturally fill in the gaps in my understanding and create mental structures which help me recall and apply what I ve learned. My input and output should be balanced appropriately for my circumstances. Rapid-fire email is like hyperventilation: I can do it for a while, reading and replying in quick succession, and even feel energized by it, but if I go on for too long, I get dizzy. Running might call for a certain breathing ratio, and Yoga quite a different one. Both can be healthy practices, but they are different, and each requires focus and consistency. Another key lesson from breathing is to let go. A friend recently told me about his daily online news routine, which included closing any unread tabs at the end of the session. I will sometimes hang onto an article or a video for days or weeks before I find the opportunity to take it in. I eventually get around to most of them, but meanwhile they are taking up space and causing a continuous low level of anxiety or guilt. This information isn t going anywhere, and if it s truly significant for me, it will most likely turn up again. If it doesn t, that s OK too. Similarly, it s not wise to breathe stale, indoor air for too long. I will try to step outside regularly, and engage with people and media from outside my usual sphere. When the weather is tolerable, I ll open up the house and let plenty of fresh air circulate. This will help me avoid getting stuck in the echo chamber of my own ideas, or in groupthink. Perhaps most significantly, I will try to remember that information exchange, like breathing, is not an end in itself. It is a means to action. This will remind me to get out of my head regularly, and do something significant with what I ve learned. Ready? Breathe.

1 December 2010

Gintautas Miliauskas: Windows (II): User Interface

(This is a part of a series of posts on my recent experience with Windows. See Windows (I) for the first post.)

The Windows user interface is definitely acceptable. The charge that it is too colorful or toy-like is completely unfounded. Rather, perhaps geeks should spend less time looking at their gray Motif boxy controls. In terms of speed, the UI is generally more responsive than on Linux, though maybe less so than previous versions of Windows (that could be because my Intel video IGP is a slouch).

An interesting observation is that apps are almost as heterogeneous in terms of interface as in GNU/Linux, even though the standard controls are ubiquitous. Even apps by Microsoft can be separated into different "generations" of UI (e.g., folder windows, Control Panel, Microsoft Office). Also it is clear that generally more attention is paid to UI and usability by app developers, although perhaps not as much as in Apple products.

The greatest asset and the worst offender at the same time, by far, is the overall GUI orientation of the system. Needless to say, it aids discoverability, but reduces scripting capabilities. Problem is, even if you do not need to write scripts per se, command-line actions are useful because they can be repeated and chained very easily, using shell history. In Windows, I occasionally find myself doing much repetitive clicking that would likely be an "Alt-Tab Up Enter" (or sometimes just one key) sequence in Linux. Moreover, the lack of good standartized scripting is a huge pain during app deployments which tend be repetetive. I did not like Windows on servers before, and I do not like it now.

To be fair, my complaints about scripting capabilities may be partly moot because I have only used vanilla Windows batch files, and have not looked at all into Windows PowerShell, which is a new-generation scripting tool. The examples are fairly impressive. The language has a nice look and is clearly powerful, but also looks somewhat complicated which keeps me away until I find a good reason to learn it.

Initially I missed workspaces. The one app I found that was supposed to emulate workspaces would take several seconds to switch the workspace, so it was completely unusable. I learned to do without them rather quickly though. Actually I'm starting to think that using many workspaces is a sign that you are doing too many things at once and also they are an invitation to distraction (how many of you have a "blog reader" workspace right aside your "work" workspace, ready at your fingertips at a moment's notice?). Workspaces do have one killer feature: you can jump directly to a given workspace instead of cycling through windows. This is very useful when working with more than two apps, in which case without workspaces you are forced to think about the morphing Alt-Tab queue when switching windows.

Speaking about UI generations, I much prefer the ribbon toolbars of the new Office. The still-prevalent toolbars with zillions of old-style 32x32 (or 16x16) toolbar icons are really ugly. Typically only a few of the toolbar buttons are actually useful, and they make the user interface unnecessarily cramped and busy. The move to fewer and larger toolbar buttons is definitely on the right track.

The explorer context menus also tend to grow crazy long. Every app wants to get in there, and in the end you have a context menu that takes up half a screen vertically. Needless to say, most of those items are not used much. Sure, you can opt out during app installation, but at that time it is difficult to say how useful the context menu item will be, and there's no easy way (i.e. easier than just ignoring the cruft) to remove the entries afterwards.

In my coming posts I will cover package management and application development on Windows.

Josselin Mouette: Getting user switching to not suck

We ve come a long way since the times when you needed to configure 2 X servers in XDM just to be able to use 2 X sessions at once. However there was still some way to go until recently. A number of bugs that could be wrongly attributed to bugs in the X server or in the desktop environment were actually caused by the display manager doing crap. GDM up to 2.20 Since the introduction of the flexible X servers feature, GDM hadn t evolved much on the matter of user switching. What it used to do was pretty straightforward: It is interesting to note that VT (console) switching is purely handled by the X server. When starting, the new server switches the current VT to where it is. When exiting, it automatically switches back to the VT from which it was launched. While very simple, this idea fails to work correctly every time you try to do something more complicated than starting a temporary session for a guest and exiting it. For example, if you start two of them, there is a chance that, when the X server switches back to the console it was run from, there is nothing left running in this console, leaving you with the funny Control-Alt-Fn shortcuts to find your way back to a X server. You will also meet interesting race conditions when trying to switch back to an existing session from the login window. GDM 2.28 and above In the process of rewriting the code entirely, the GDM developers tried to address a number of those shortcomings, making use of D-Bus and ConsoleKit. The new design is slightly more complicated, however. Not killing the X server in some cases partly addresses the problems caused by letting it switch back to the original VT when exiting. However in several ways the cure is worse than the disease. Getting it to work The modular architecture of GDM makes it possible to improve the situation. (Possible but not easy because of the millefeuille of classes.) However, it is merely a band-aid unless you fix the root issue: the X server knowing better than you which VT it should switch to when exiting. Fortunately Xorg now features an option to avoid that behavior: -novtswitch. So the first step is to enable it, and let the GDM daemon (or slave) handle VT switching through ConsoleKit. With that, the following changes are possible. The result With all these changes the behavior of the display manager is finally completely consistent. Interestingly enough, this is very similar to what user switching looks like on Vista or MacOS X. So what now? These changes are stabilized for Debian squeeze, but of course it has been long overdue to get them accepted upstream, along with the very large number of Debian-specific changes that still lie in our packages.

Dirk Eddelbuettel: RcppGSL 0.1.0

Earlier in the year, Romain and I did a bunch of initial work on a wrapper from R to the GNU GSL by way of our Rcpp package for seamless R and C++ integration. But other work kept us busy and this fell a little to the side. We have now found some time to finish this work for a first release, together with a nicely detailed eleven page package vignette. As of today, the package is now a CRAN package, and Romain already posted a nice announcement on his blog and on the rcpp-devel list. So what does RcppGSL do? I gave the package its own webpage here as well and listed these points as key features of RcppGSL: Also provided is a simple example which is a simple implementation of a column norm (which we could easily compute directly in R, but we are simply re-using an example from Section 8.4.14 of the GSL manual):
#include <RcppGSL.h>
#include <gsl/gsl_matrix.h>
#include <gsl/gsl_blas.h>
extern "C" SEXP colNorm(SEXP sM)  
  try  
        RcppGSL::matrix<double> M = sM;     // create gsl data structures from SEXP
        int k = M.ncol();
        Rcpp::NumericVector n(k);           // to store results
        for (int j = 0; j < k; j++)  
            RcppGSL::vector_view<double> colview = gsl_matrix_column (M, j);
            n[j] = gsl_blas_dnrm2(colview);
         
        M.free() ;
        return n;                           // return vector
    catch( std::exception &ex )  
        forward_exception_to_r( ex );
    catch(...)  
        ::Rf_error( "c++ exception (unknown reason)" );
   
  return R_NilValue; // -Wall
 
This example function is implemented in an example package contained in the RcppGSL package itself -- so that users have a complete stanza to use in their packages. This will then build a user package on Linux, OS X and Windows provided the GSL is installed (and on Windows you have to do all the extra steps of defining an environment variable pointing to and of course install Rtools to build in the first place---Linux and OS X are so much easier for development). Another complete example is in the package itself and provides a faster (compiled) alternative to the standard lm() function in R; this example is the continuation of the same example I had in several versions of my Intro to HPC with R tutorials and in the Rcpp package itself as an early example. We will try to touch base with CRAN package authors using both GSL and Rcpp to see how this can help them. The API in our package may well be incomplete, but we are always happy to try to respond to requests for additional features brought to our attention, preferably via the rcpp-devel list. More information is on the RcppGSL page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

Gintautas Miliauskas: Windows (I)

I have been helping with an overdue web app project lately, and the project uses ASP.NET MVC, so I have had to use Windows for most of my day. Since I had been using GNU/Linux almost exclusively since 2003, this is quite an adventure (imagine trying out GNU/Linux after a seven year break). It is not nearly as bad as I thought it would be, even though I am using the not-so-well-liked Windows Vista which came pre-installed with my computer.

The first thing that struck me is how much less important the OS is when compared to the situation a few years ago: a lot of the applications I depend on are web-based (GMail, Google Calendar, Google Docs, Springpad), and the ones that are not web-based are multiplatform and installable with a few clicks (GVim comes to mind). In fact, I do not think there is a single piece of software that I really missed in Windows. (An interesting corollary of this observation is that it should be equally easy to migrate to GNU/Linux nowadays.)

The one thing where the operating system matters is hardware support, and I do not think I have to say much here. After years of whack-a-mole GNU/Linux upgrades which would fix support for one component but break another (for things as essential as video and sound), it was absolutely weird having all hardware work properly at the same time (sound after suspend! no video glitches! high quality webcam picture!). There is no point recounting the reasons why hardware support in Linux is as it is, but now I am starting to think that Linux users do tend to suffer from a sort of Stockholm syndrome regarding hardware support; I know I did.

The other important thing that operating systems do is resource management, and I did not have problems here either. In fact, I liked the virtual memory behaviour much better: when Windows ran out of memory (I had filled up the smallish Windows partition and there was no space left for the swap file to grow), it started rejecting malloc calls from applications, but the system was kept alive and responsive, and I could close apps and clean up the mess without much trouble. In Ubuntu, with the default settings, whenever a runaway process ate too much RAM, the system would start thrashing so hard that it would be very difficult to fix. My standard procedure (switch to text console, log in, find and kill app using command line tools) would take minutes and was so annoying that I would sometimes just reset the computer instead. And in the end, even if I did not reset, an important app would possibly be killed anyway. I know there are kernel parameters for tweaking this behaviour (swappiness?), but I never got around to figuring them out as this situation does not arise that frequently, and testing is painful.

I did not like the Windows FS security model. ACLs are much more complicated and thus less transparent that the Unix approach, even though they are more powerful. My main gripe with them is that I do not know a good way to display them easily (as with ls -l in Unix). I have not had to deal with them much though.

I have had no stability issues. It seems that this argument should be put to rest.

Long blog posts are annoying, so I will leave the user interface, the developer experience and my complaints with the system for separate posts (edit: you can now read my next post about the UI).

Pietro Abate: bypassing the apt-get solver

Here at mancoosi we have been working for quite a while to promote and advance solver technology for FOSS distributions. We are almost at the end of the project and it is important to make the mancoosi technology relevant for the community. On goal of the project is to provide a prototype that uses part of the results of mancoosi that can based to install/remove/upgrade packages on a user machine. We certainly don't want to create yet another meta installer. This would be very time consuming and certainly going beyond the scope of the project. The idea is to create a prototype, that can work as an apt-get drop in replacement that will allow everybody to play with different solvers and installation criteria. A very first integration step is a small shell script apt-mancoosi that tries to put together different tools that we have implemented during the project. Roberto wrote extensively about his experience with apt-mancoosi a while ago showing that somehow the mancoosi tools are already usable, as proof of concept, to experiment with all solvers participating to the Misc competition. On notable obstacle we encountered with apt-mancoosi is how to pipe the result of an external solver to apt-get to effectively install the packages proposed as solution. Apt-mancoosi fails to be a drop-in replacement for apt-get exactly for this reason. The "problem" is quite simple : The idea at the beginning was to pass to apt-get, on the command line, a request that effectively represents a complete solution. We expected that, since this was already a locked-down solution, apt-get would have just installed all packages without any further modification to the proposed installation set. Of course, since apt-get is designed to satisfy a user request, and not just to install packages, we quickly realized that our evil plan was doomed to failure. The only option left, was to use libapt directly, but the idea of programming in c++ quickly made me to desist. After a bit of research (not that much after all), I finally found a viable solution to our problems in ''python-apt'' that is a low level and wrapper around libapt. This definitely made my day. Now the juicy details. the problem was to convince apt to completely bypass the solver part and just call the installer. First a small intro. python-apt has an extensive documentation with a couple of tutorials. Using python-apt is actually pretty easy (some snippet from the python-apt doco) :
import apt

# First of all, open the cache
cache = apt.Cache()
# Now, lets update the package list
cache.update()
here we open the cache (apt.Cache is a wrapper around the low level binding in the apt_pkg module), then we update the package list. This is equivalent to apt-get update . Installing a package is equally easy :
import apt
cache = apt.Cache()
pkg = cache['python-apt']

# Mark python-apt for install
pkg.mark_install()

# Now, really install it
cache.commit()
Now, the method mark_install of the module package will effectively run the solver to resolve and mark all the dependencies of the package python-apt. This is the default behavior when apt-get is used on the command line. This method has however three optional arguments that are just what I was looking for, that is autoFix, autoInst and fromUser . The explanation from the python-apt doco is quite clear.
mark_install(*args, **kwds)
Mark a package for install.
If autoFix is True, the resolver will be run, trying to fix broken packages. This is the default.
If autoInst is True, the dependencies of the packages will be installed automatically. This is the default.
If fromUser is True, this package will not be marked as automatically installed. This is the default. Set it to False if you want to be able to automatically remove the package at a later stage when no other package depends on it.
What we want is to set autoFix and autoInst to false to completely bypass the solver. So imagine that an external solver can give use a string of the form : bash+ dash=1.4 baobab- that basically asks to install bash to the newest version, dash at version 1.4 and remove baobab. Suppose also that this is a complete solution, that is, all dependencies are satisfied and there are no conflicts. The work flow of mpm (mancoosi package manager) is as follows : We already have a first prototype on the mancoosi svn. It's not released yet as we are waiting to do more testing, add more options and make it stable enough for testing. Maybe one day, this will be uploaded to debian. This is the trace of a successful installation of a package in a lenny chroot. The solver used here is the p2 solver
dev:~/mpm# ./mpm.py -c apt.conf install baobab
Running p2cudf-paranoid-1.6 solver ...
Validate solution ...
loading CUDF ...
loading solution ...
Summary of proposed changes:
new: 30
removed: 0
replaced: 0
upgraded: 0
downgraded: 0
unsatisfied recommends:: 8
changed: 30
uptodate: 322
notuptodate: 116

New packages: baobab (2.30.0-2) dbus-x11 (1.2.24-3) gconf2 (2.28.1-5)
gconf2-common (2.28.1-5) gnome-utils-common (2.30.0-2)
libatk1.0-0 (1.30.0-1) libcairo2 (1.8.10-6) libdatrie1 (0.2.4-1)
libdbus-glib-1-2 (0.88-2) libgconf2-4 (2.28.1-5) libgtk2.0-0 (2.20.1-2)
libgtk2.0-common (2.20.1-2) libgtop2-7 (2.28.1-1) libgtop2-common (2.28.1-1)
libidl0 (0.8.14-0.1) libjasper1 (1.900.1-7+b1) liborbit2 (1:2.14.18-0.1)
libpango1.0-0 (1.28.3-1) libpango1.0-common (1.28.3-1)
libpixman-1-0 (0.16.4-1) libthai-data (0.1.14-2) libthai0 (0.1.14-2)
libtiff4 (3.9.4-5) libxcb-render-util0 (0.3.6-1) libxcb-render0 (1.6-1)
libxcomposite1 (1:0.4.2-1) libxcursor1 (1:1.1.10-2) libxrandr2 (2:1.3.0-3)
psmisc (22.11-1) shared-mime-info (0.71-3)
Removed packages:
Replaced packages:
Upgraded packages:

Selecting previously deselected package libatk1.0-0.
(Reading database ... 28065 files and directories currently installed.)
Unpacking libatk1.0-0 (from .../libatk1.0-0_1.30.0-1_i386.deb) ...
Selecting previously deselected package libpixman-1-0.
Unpacking libpixman-1-0 (from .../libpixman-1-0_0.16.4-1_i386.deb) ...
Selecting previously deselected package libxcb-render0.
Unpacking libxcb-render0 (from .../libxcb-render0_1.6-1_i386.deb) ...
Selecting previously deselected package libxcb-render-util0.
Unpacking libxcb-render-util0 (from .../libxcb-render-util0_0.3.6-1_i386.deb) ...
Selecting previously deselected package libcairo2.
Unpacking libcairo2 (from .../libcairo2_1.8.10-6_i386.deb) ...
Selecting previously deselected package libdbus-glib-1-2.
Unpacking libdbus-glib-1-2 (from .../libdbus-glib-1-2_0.88-2_i386.deb) ...
Selecting previously deselected package libidl0.
Unpacking libidl0 (from .../libidl0_0.8.14-0.1_i386.deb) ...
Selecting previously deselected package liborbit2.
Unpacking liborbit2 (from .../liborbit2_1%3a2.14.18-0.1_i386.deb) ...
Selecting previously deselected package gconf2-common.
Unpacking gconf2-common (from .../gconf2-common_2.28.1-5_all.deb) ...
Selecting previously deselected package libgconf2-4.
Unpacking libgconf2-4 (from .../libgconf2-4_2.28.1-5_i386.deb) ...
Selecting previously deselected package libgtk2.0-common.
Unpacking libgtk2.0-common (from .../libgtk2.0-common_2.20.1-2_all.deb) ...
Selecting previously deselected package libjasper1.
Unpacking libjasper1 (from .../libjasper1_1.900.1-7+b1_i386.deb) ...
Selecting previously deselected package libpango1.0-common.
Unpacking libpango1.0-common (from .../libpango1.0-common_1.28.3-1_all.deb) ...
Selecting previously deselected package libdatrie1.
Unpacking libdatrie1 (from .../libdatrie1_0.2.4-1_i386.deb) ...
Selecting previously deselected package libthai-data.
Unpacking libthai-data (from .../libthai-data_0.1.14-2_all.deb) ...
Selecting previously deselected package libthai0.
Unpacking libthai0 (from .../libthai0_0.1.14-2_i386.deb) ...
Selecting previously deselected package libpango1.0-0.
Unpacking libpango1.0-0 (from .../libpango1.0-0_1.28.3-1_i386.deb) ...
Selecting previously deselected package libtiff4.
Unpacking libtiff4 (from .../libtiff4_3.9.4-5_i386.deb) ...
Selecting previously deselected package libxcomposite1.
Unpacking libxcomposite1 (from .../libxcomposite1_1%3a0.4.2-1_i386.deb) ...
Selecting previously deselected package libxcursor1.
Selecting previously deselected package libxrandr2.
Unpacking libxrandr2 (from .../libxrandr2_2%3a1.3.0-3_i386.deb) ...
Selecting previously deselected package shared-mime-info.
Unpacking shared-mime-info (from .../shared-mime-info_0.71-3_i386.deb) ...
Selecting previously deselected package libgtk2.0-0.
Unpacking libgtk2.0-0 (from .../libgtk2.0-0_2.20.1-2_i386.deb) ...
Selecting previously deselected package libgtop2-common.
Unpacking libgtop2-common (from .../libgtop2-common_2.28.1-1_all.deb) ...
Selecting previously deselected package libgtop2-7.
Unpacking libgtop2-7 (from .../libgtop2-7_2.28.1-1_i386.deb) ...
Selecting previously deselected package psmisc.
Unpacking psmisc (from .../psmisc_22.11-1_i386.deb) ...
Selecting previously deselected package dbus-x11.
Unpacking dbus-x11 (from .../dbus-x11_1.2.24-3_i386.deb) ...
Selecting previously deselected package gconf2.
Unpacking gconf2 (from .../gconf2_2.28.1-5_i386.deb) ...
Selecting previously deselected package gnome-utils-common.
Unpacking gnome-utils-common (from .../gnome-utils-common_2.30.0-2_all.deb) ...
Selecting previously deselected package baobab.
Unpacking baobab (from .../baobab_2.30.0-2_i386.deb) ...
Processing triggers for man-db ...
Setting up libatk1.0-0 (1.30.0-1) ...
Setting up libpixman-1-0 (0.16.4-1) ...
Setting up libxcb-render0 (1.6-1) ...
Setting up libxcb-render-util0 (0.3.6-1) ...
Setting up libcairo2 (1.8.10-6) ...
Setting up libdbus-glib-1-2 (0.88-2) ...
Setting up libidl0 (0.8.14-0.1) ...
Setting up liborbit2 (1:2.14.18-0.1) ...
Setting up gconf2-common (2.28.1-5) ...

Creating config file /etc/gconf/2/path with new version
Setting up libgconf2-4 (2.28.1-5) ...
Setting up libgtk2.0-common (2.20.1-2) ...
Setting up libjasper1 (1.900.1-7+b1) ...
Setting up libpango1.0-common (1.28.3-1) ...
Cleaning up font configuration of pango...
Updating font configuration of pango...
Cleaning up category xfont..
Updating category xfont..
Setting up libdatrie1 (0.2.4-1) ...
Setting up libthai-data (0.1.14-2) ...
Setting up libthai0 (0.1.14-2) ...
Setting up libpango1.0-0 (1.28.3-1) ...
Setting up libtiff4 (3.9.4-5) ...
Setting up libxcomposite1 (1:0.4.2-1) ...
Setting up libxcursor1 (1:1.1.10-2) ...
Setting up libxrandr2 (2:1.3.0-3) ...
Setting up shared-mime-info (0.71-3) ...
Setting up libgtk2.0-0 (2.20.1-2) ...
Setting up libgtop2-common (2.28.1-1) ...
Setting up libgtop2-7 (2.28.1-1) ...
Setting up psmisc (22.11-1) ...
Setting up dbus-x11 (1.2.24-3) ...
Setting up gconf2 (2.28.1-5) ...
update-alternatives: using /usr/bin/gconftool-2 to provide /usr/bin/gconftool (gconftool) in auto mode.
Setting up gnome-utils-common (2.30.0-2) ...
Setting up baobab (2.30.0-2) ...
Broken: 0
InstCount: 30
DelCount: 0
dev:~/mpm#
I think we'll keep working on this python prototype for a while, but this is not certainly what we want to propose to the community. The mancoosi package manager is probably going to be written in Ocaml and integrated with dose3 and libcudf. This will allow us to gain speed and have a solid language to develop with (nothing against python, but we don't feel that a scripting language is suitable for an essential component as a package manager). Time will tell. For the moment this is just vapor-ware ...

Dirk Eddelbuettel: RQuantLib 0.3.5

The new RQuantLib release 0.3.5 is now on CRAN and in Debian. RQuantLib combines (some of) the quantitative analytics of QuantLib with the R statistical computing environment and language. Most of the changes were made two and four weeks ago: first in response to some warnings triggered by R 2.12.0 on the included manual pages which needed a brush-up, and then again is some consolidation of manual pages and some other minor tweaks. The release was then held back at CRAN as we noticed that manual pages, when collated to a single large document, triggered a segmentation fault in the latex compiler. Oddly enough only in Europe (if the a4paper option was used) and not here (where I use uspaper). Long story short, this turns out to be a bug in the latex toolchain (which we reported as Debian bug report 604754) which is apparently is known but has no known fix yet (a sample file was supplied with the bug report if you want to take a look). With that, special thanks go to Kurt Hornik and Brian Ripley on the R Core team who made a change to how R processes the manual which made it resilient to the latex bug so that normal release of the package could proceed (and the shiny manual is available too). Thanks to CRANberries, there is also a diff to the previous release 0.3.4. Full changelog details, examples and more details about this package are at my RQuantLib page.

30 November 2010

Debian News: Training Session on Python Packaging

As part of the Training Sessions initiative organized by the Debian Women project, this week a lesson about Python packaging will be held. The lesson, which is aimed at an intermediate audience, will focus specifically modules and applications packaging and will be held by Piotr O arowski who is member of Python Applications Packaging Team and Debian Python Modules Team.

The session will take place, as usual, on #debian-women channel on irc.debian.org on Thursday, 2nd December at 20:00 UTC.

Cause of the advanced topic is madatory to have some knowledge about Debian packaging (see, for example Lars Wirzenius tutorial) and about general Python development.

The lesson will consists of a first, theoretical, part in wich Piotr will explain us some basics; and of a Q&A part, entirely dedicated to more advanced problems.

See you on Thursday!

Francesca Ciceri

Tollef Fog Heen: My Varnish is leaking memory

Every so often, we get bug reports about Varnish leaking memory. People have told Varnish to use 20 gigabytes for cache and they discover the process is eating 30 gigabytes of memory and they get confused about what's going on. So, let's take a look. First, a little bit of history. Varnish 2.0 had a fixed per-object workspace which was used for both header manipulations in vcl_fetch as well as for storing the headers of the object when vcl_fetch was done. The default size of this workspace was 8k. If we assume an average object size of 20k, that is almost 1/3 of the store being overhead. With 2.1, this changed. First, vcl_fetch doesn't have obj any longer, it only has beresp which is the backend response. At the end of vcl_fetch, the headers and other relevant bits of the backend response are copied into an object. This means we no longer have a fixed overhead, we use what we need. Of course, we're still subject to malloc's whims when it comes to page sizes and how it actually allocates memory. Less overhead means more objects in the store. More objects in the store, means, everything else being equal, more overhead outside the store (for the hash buckets or critbit tree and other structs). This is where lots of people get confused, since what they see is just Varnish consuming more memory. When moving from 2.0 to 2.1, people should lower their cache size. How much depends on the amount of objects they have, but if they have many and small objects, a significant reduction might be needed. For a machine dedicated to Varnish, we usually recommend making the cache size be 70-75% of the memory of the machine. A reasonable question to ask at this point is what all this overhead is being used for. Part of it is a per-thread overhead. Linux has a 10MB stack size by default, but luckily, most of it isn't allocated, so it only counts against virtual, not resident memory. In addition, we have a hash algorithm which has overhead and the headers from the objects are stored in the object itself and not in the stevedore (object store). Last, but by no means least, we usually see an overhead of around 1k per object, but I have seen up to somewhere above 2k. This doesn't sound like much, but when you're looking at servers with 10 million objects, 1k of overhead means 10 gigabytes of total overhead, leading to the confusion I talked about at the start.

Next.

Previous.