Search Results: "will"

29 April 2014

Andrew Pollock: [life] Day 91: Kindergarten, a successful assault on my to do list, haircuts and venus fly traps

I hate the days when I wake up at odd hours for no good reason. This morning I woke up at 4:30am briefly, with no idea why. It makes me wonder if there was some sort of external noise, and that's what woke Zoe up yesterday morning. I got myself going at a reasonable hour this morning, and decided to walk to the Bulimba post office to collect a package that was waiting for me. It was a nice enough morning for a walk, and I'm glad I decided to do it. Along the way, I observed multiple grandmothers walking their grandchildren to school. I've been thinking a lot about next year lately. I feel very strongly about Zoe not having to go into after school care. It seems that one of the new societal norms is the grandparents have to step in with the school transportation and after school care. That's not going to be particularly practical in our situation though, so I'm currently leaning towards seeking some sort of flexible employment next year that will allow me to be able to be available after Zoe finishes school. I was fairly motivated to get stuck into my to do list after my walk. A long standing item was to cancel one of my remaining US credit cards, and the time difference worked out well to do that, so I finally took care of that. I then realised it was a good time for the US East Coast, so I did a Hangout with one of my best friends in New York. It was great to have a catch up. After that, I finished off my US tax return, and also sorted out some other stuff that needed finishing off. I had to go to the Valley to find a FedEx location, so I drove over there, and on the way back stopped off in Bulimba to get some Mother's Day cards. By that stage it was about time to pick up Zoe from Kindergarten, so I quickly grabbed some lunch and then drove over to pick her up. She didn't nap again today, so that made our departure from Kindergarten nice and easy. I'd booked both of us in for haircuts at 3pm, so we got home with enough time for Zoe to ride her scooter to the hairdresser. We had our haircuts and Zoe had a bit of a play in the play corner, and we headed back home. I'd bought a venus fly trap from Bunnings last week while we were picking up other bits and pieces. I wanted to show Zoe how they worked, so we watched a few YouTube videos. This one was particularly good. After that, we went down to the rubbish skip with our fly trap to see if we could catch any flies in it, but Zoe quickly lost interest. So we headed back upstairs, and triggered one with a toothpick. I probably could have done this on a Friday and called it a Science Friday activity with a botany bent. After that, we just watched some TV together on the couch until Sarah arrived to pick her up.

28 April 2014

Daniel Pocock: SMS logins: an illusion of security

The IT security world is still reeling from the impact of the OpenSSL Heartbleed bug. Thanks to the bug, many experts have been reviewing other technologies to try and find similar risks. While Heartbleed was hidden away in the depths of the OpenSSL code base, another major security risk has been hiding in plain sight: SMS authentication for web site logins. Remarkably, a number of firms have started giving customers the ability to receive single-use passwords over SMS for logging into their secure web sites. Some have even insisted that customers can no longer log in without it, denying customers the right to make an important choice about their own security preferences. Unfortunately, SMS is no substitute to the one-time-passwords generated using proper authentication tokens or the use of other strong authentication schemes such as cryptographic smart cards. Even telephone companies themselves advise that SMS should not be used to secure financial transactions. Ocean's 11 in real life: exploiting the weakest link in the chain To deliver single-use SMS passwords, the SMS must travel through various networks from the firm's headquarters, to a wholesale SMS gateway, international SMS network and finally down the line of the local phone company. In comparison, properly certified token devices generate a code inside the device in the palm of your hand. The code only travels from the screen to your eyes. In a litany of frauds coming in all shapes and sizes, telephone networks have been exploited over and over again because they are almost always the weakest link in the chain. Using the mobile SMS network for authentication is not building on solid ground - some experts even feel it is downright stupidity. One of the most serious examples was the theft of $150,000,000 from a pension fund deposited with JP Morgan: it was described as a real-life case of Ocean's 11. The authentication was meant to be a phone call rather than an SMS: a phone company employee who was in on the scam duly ensured the call never reached the correct place. The insecurity of traditional telephone networks has been on display for all the world to see in the ongoing trial of News Corporation executives for phone hacking. If journalists from a tabloid newspaper can allegedly hack a dozen phones before their first cigarette of the day, is it really wise to use an insecure technology like SMS as the cornerstone of a security system for authorizing transactions? A fraud recently played out on many credit card holders in the UK exploited a low-tech feature of the phone system to trick people to believe they were safe by "calling back" to their bank. A plethora of new attack vectors The staggering reality of the situation is that attackers don't even have to directly hack their victim's phones to access SMS messages. As the Android API documentation demonstrates, SMS reception is notified to all apps in real-time. Apps can process the messages even when the phone is sleeping and the message is not read by the user. Just consider all the apps on a phone that have requested permission to read incoming messages. There was an uproar recently when a new version of the Facebook app started demanding permissions to read incoming SMS. The app can't be installed if the user doesn't agree to these new permissions. WhatsApp, another popular app that has SMS access rights, was recently exposed in a major security scandal which revealed they use a phone's IMEI number as the password. When people install an app like Tinder (which does not yet request SMS access) is the security of their bank account likely to be at the front of their mind? Even if Facebook intends no harm, they have opened the floodgates by further de-sensitizing users to the risks of giving apps un-necessary access to their data. These companies are looking for every piece of data that could give them an edge in their customer profiling and marketing programs. Having real-time access to your SMS is a powerful way for them to understand your activities and feelings at every moment in the day. To facilitate these data analysis techniques, replicating and archiving your messages into their cloud databases (whether you can see them there or not) is par for the course. The cloud, of course, has become a virtual smorgasboard for cyber-criminals, including both hackers and occasionally insiders wanting to peek at private data or harvest it en-masse. Social networking and communication sites are built on a philosophy of sharing data to create interaction and excitement. Unfortunately, this is orthogonal to the needs of security. In this context, the telephone network itself may no longer be the weakest link in the chain. The diligent attacker only needs to look for the cloud operator with an unplugged security hole and use their system as a stepping stone to read any SMS they want, when they want. Would you notice a stray SMS? Maybe you feel that you would notice a stray SMS carrying a login code for your bank account. Would you always be able to react faster than the criminal however? Thanks to social networks, or location data inadvertently leaked by other apps the attacker can easily work out whether you are on holiday, at the gym, at a party or sleeping or in some other situation where you are not likely to check messages immediately. If you receive a flood of SMS spam messages (deliberately sent by an attacker) in the middle of the night and you put your phone into silent mode and ignore it, you may well miss one message that was a login to your bank account. SMS technology was never designed for secure activities. The inconvenience of SMS While security is a headline issue these days, it is also worth reflecting on the inconvenience of SMS in some situations. Travel is at the top of the list: SMS doesn't work universally when abroad. These are usually the times when the only way to access the bank is through the web site. After dealing with the irritations of the hotel or airport wifi registration, do you really need more stress from your bank's systems too? For some networks, SMS can be delayed by hours or days, sometimes never arriving at all. Many people swap their SIM cards when travelling to avoid the excessive roaming charges and there is extra inconvenience in swapping SIM cards back again just to log in to a bank account. Worst of all, if you are tethering with a SIM card from the country you are visiting, then it is impossible for you to receive the SMS message from the bank on your regular SIM card while simultaneously maintaining the SSL connection to their web site over your new SIM card. Other problems like a flat battery, water damage or PIN permanently blocked by children playing with the phone can also leave you without access to your bank account for varying lengths of time. Is there any up-side to SMS authentication? The only potential benefit to SMS authentication is that it weeds out some of the most amateur attempts to compromise your bank account, but this is a false sense of security and it opens up new attack vectors through the cloud as we have just demonstrated. For all other purposes, it smells like a new form of security theater. A more likely reason why it has become popular amongst some firms is that many lenders want to ensure they have mobile phone numbers to contact customers when loan or credit card payments are missed. Making the mobile phone number mandatory for login ensures they almost always have the correct phone number for almost 100% of customers. It is not clear that this benefit justifies the failure to provide proper security and the inconvenience when travelling though. Opting out Next time you log in to a web site, if the firm does try to enrol you in an SMS authentication scheme, it may be a good idea to click the "No thanks" option. If you have already been registered into an SMS authentication scheme, fill out the online complaint form and inform the firm that you will only accept a proper authentication token or cryptographic smart card. These solutions are tried and tested and they are the correct tool for the job.

Martin Pitt: Booting Ubuntu with systemd: Now in Utopic

Hot on the heels of my previous annoucement of my systemd PPA for trusty, I m now happy to announce that the latest systemd 204-10ubuntu1 just landed in Utopic, after sorting out enough of the current uninstallability in -proposed. The other fixes (bluez, resolvconf, lightdm, etc.) already landed a few days ago. Compared to the PPA these have a lot of other fixes and cleanups, due to the excellent hackfest that we held last weekend. So, upgrade today and let us know about problems in bugs tagged systemd-boot . I think systemd in current utopic works well enough to not break a developer s day to day workflow, so we can now start parallelizing the work of identifying packages which only have upstart jobs and provide corresponding systemd units (or SysV script). Also, this hasn t yet been tested on the phone at all, I m sure that it ll require quite some work (e. g. lxc-android-config has a lot of upstart jobs). To clarify, there is nofixed date/plan/deadline when this will be done, in particular it might well last more than one release cycle. So we ll release (i. e. switch to it as a default) when it s ready :-)

27 April 2014

Vincent Bernat: Local corporate APT repositories

Distributing software efficiently accross your platform can be difficult. Every distribution comes with a package manager which is usually suited for this task. APT can be relied upon on when using Debian or a derivative. Unfortunately, the official repositories may not contain everything you need. When you require unpackaged software or more recent versions, it is possible to setup your own local repository. Most of what is presented here was setup for Dailymotion and was greatly inspired by the work done by Rapha l Pinson at Orange.

Setting up your repositories There are three kinds of repositories you may want to setup:
  1. A distribution mirror. Such a mirror will save bandwidth, provide faster downloads and permanent access, even when someone searches Google on Google.
  2. A local repository for your own packages with the ability to have a staging zone to test packages on some servers before putting them in production.
  3. Mirrors for unofficial repositories, like Ubuntu PPA. To avoid unexpected changes, such a repository will also get a staging and a production zone.
Before going further, it is quite important to understand what a repository is. Let s illustrate with the following line from my /etc/apt/sources.list:
deb http://ftp.debian.org/debian/ unstable main contrib non-free
In this example, http://ftp.debian.org/debian/ is the repository and unstable is the distribution. A distribution is subdivided into components. We have three components: main, contrib and non-free. To setup repositories, we will use reprepro. This is not the only solution but it has a good balance between versatility and simplicity. reprepro can only handle one repository. So, the first choice is about how you will split your packages in repositories, distributions and components. Here is what matters:
  • A repository cannot contain two identical packages (same name, same version, same architecture).
  • Inside a component, you can only have one version of a package.
  • Usually, a distribution is a subset of the versions while a component is a subset of the packages. For example, in Debian, with the distribution unstable, you choose to get the most recent versions while with the component main, you choose to get DFSG-free software only.
If you go for several repositories, you will have to handle several reprepro instances and won t be able to easily copy packages from one place to another. At Dailymotion, we put everything in the same repository but it would also be perfectly valid to have three repositories:
  • one to mirror the distribution,
  • one for your local packages, and
  • one to mirror unofficial repositories.
Here is our target setup: Local APT repository

Initial setup First, create a system user to work with the repositories:
$ adduser --system --disabled-password --disabled-login \
>         --home /srv/packages \
>         --group reprepro
All operations should be done with this user only. If you want to setup several repositories, create a directory for each of them. Each repository has those subdirectories:
  • conf/ contains the configuration files,
  • gpg/ contains the GPG stuff to sign the repository1,
  • logs/ contains the logs,
  • www/ contains the repository that should be exported by the web server.
Here is the content of conf/options:
outdir +b/www
logdir +b/logs
gnupghome +b/gpg
Then, you need to create the GPG key to sign the repository:
$ GNUPGHOME=gpg gpg --gen-key
Please select what kind of key you want:
   (1) RSA and RSA (default)
   (2) DSA and Elgamal
   (3) DSA (sign only)
   (4) RSA (sign only)
Your selection? 1
RSA keys may be between 1024 and 4096 bits long.
What keysize do you want? (2048) 4096
Requested keysize is 4096 bits
Please specify how long the key should be valid.
         0 = key does not expire
      <n>  = key expires in n days
      <n>w = key expires in n weeks
      <n>m = key expires in n months
      <n>y = key expires in n years
Key is valid for? (0) 10y
Key expires at mer. 08 nov. 2023 22:30:58 CET
Is this correct? (y/N) y
Real name: Dailymotion Archive Automatic Signing Key
Email address: the-it-operations@dailymotion.com
Comment: 
[...]
By setting an empty password, you allow reprepro to run unattended. You will have to distribute the public key of your new repository to let APT check the archive signature. An easy way is to ship it in some package.

Local mirror of an official distribution Let s start by mirroring a distribution. We want a local mirror of Ubuntu Precise. For this, we need to do two things:
  1. Setup a new distribution in conf/distributions.
  2. Configure the update sources in conf/updates.
Let s add this block to conf/distributions:
# Ubuntu Precise
Origin: Ubuntu
Label: Ubuntu
Suite: precise
Version: 12.04
Codename: precise
Architectures: i386 amd64
Components: main restricted universe multiverse
UDebComponents: main restricted universe multiverse
Description: Ubuntu Precise 12.04 (with updates and security)
Contents: .gz .bz2
UDebIndices: Packages Release . .gz
Tracking: minimal
Update: - ubuntu-precise ubuntu-precise-updates ubuntu-precise-security
SignWith: yes
This defines the precise distribution in our repository. It contains four components: main, restricted, universe and multiverse (like the regular distribution in official repositories). The Update line starts with a dash. This means reprepro will mark everything as deleted before updating with the provided sources. Old packages will not be kept when they are removed from Ubuntu. In conf/updates, we define the sources:
# Ubuntu Precise
Name: ubuntu-precise
Method: http://fr.archive.ubuntu.com/ubuntu
Fallback: http://de.archive.ubuntu.com/ubuntu
Suite: precise
Components: main main multiverse restricted universe
UDebComponents: main restricted universe multiverse
Architectures: amd64 i386
VerifyRelease: 437D05B5
GetInRelease: no
# Ubuntu Precise Updates
Name: ubuntu-precise-updates
Method: http://fr.archive.ubuntu.com/ubuntu
Fallback: http://de.archive.ubuntu.com/ubuntu
Suite: precise-updates
Components: main restricted universe multiverse
UDebComponents: main restricted universe multiverse
Architectures: amd64 i386
VerifyRelease: 437D05B5
GetInRelease: no
# Ubuntu Precise Security
Name: ubuntu-precise-security
Method: http://fr.archive.ubuntu.com/ubuntu
Fallback: http://de.archive.ubuntu.com/ubuntu
Suite: precise-security
Components: main restricted universe multiverse
UDebComponents: main restricted universe multiverse
Architectures: amd64 i386
VerifyRelease: 437D05B5
GetInRelease: no
The VerifyRelease lines are GPG key fingerprint to use to check the remote repository. The key needs to be imported in the local keyring:
$ gpg --keyring /usr/share/keyrings/ubuntu-archive-keyring.gpg \
>     --export 437D05B5   GNUPGHOME=gpg gpg --import
Another important point is that we merge three distributions (precise, precise-updates and precise-security) into a single distribution (precise) in our local repository. This may cause some difficulties with tools expecting the three distributions to be available (like the Debian Installer2). Next, you can run reprepro and ask it to update your local mirror:
$ reprepro update
This will take some time on the first run. You can execute this command every night. reprepro is not the fastest mirror solution but it is easy to setup, flexible and reliable.

Repository for local packages Let s configure the repository to accept local packages. For each official distribution (like precise), we will configure two distributions:
  • precise-staging contains packages that have not been fully tested and not ready to go to production.
  • precise-prod contains production packages copied from precise-staging.
In our workflow, packages are introduced in precise-staging where they can be tested and will be copied to precise-prod when we want them to be available for production. You can adopt a more complex workflow if you need. The reprepro part is quite easy. We add the following blocks into conf/distributions:
# Dailymotion Precise packages (staging)
Origin: Dailymotion #  
Label: dm-staging   #  
Suite: precise-staging
Codename: precise-staging
Architectures: i386 amd64 source
Components: main role/dns role/database role/web #  
Description: Dailymotion Precise staging repository
Contents: .gz .bz2
Tracking: keep
SignWith: yes
NotAutomatic: yes #  
Log: packages.dm-precise-staging.log
 --type=dsc email-changes
# Dailymotion Precise packages (prod)
Origin: Dailymotion #  
Label: dm-prod      #  
Suite: precise-prod
Codename: precise-prod
Architectures: i386 amd64 source
Components: main role/dns role/database role/web #  
Description: Dailymotion Precise prod repository
Contents: .gz .bz2
Tracking: keep
SignWith: yes
Log: packages.dm-precise-prod.log
First notice we use several components (in ):
  • main will contain packages that are not specific to a subset of the platform. If you put a package in main, it should work correctly on any host.
  • role/* are components dedicated to a subset of the platform. For example, in role/dns, we ship a custom version of BIND.
The staging distribution has the NotAutomatic flag (in ) which disallows the package manager to install those packages except if the user explicitely requests it. Just below, when a new dsc file is uploaded, the hook email-changes will be executed. It should be in the conf/ directory. The Origin and Label lines (in ) are quite important to be able to define an explicit policy of which packages should be installed. Let s say we use the following /etc/apt/sources.list file:
# Ubuntu packages
deb http://packages.dm.gg/dailymotion precise main restricted universe multiverse
# Dailymotion packages
deb http://packages.dm.gg/dailymotion precise-prod    main role/dns
deb http://packages.dm.gg/dailymotion precise-staging main role/dns
All servers have the precise-staging distribution. We must ensure we won t install those packages by mistake. The NotAutomatic flag is one possible safe-guard. We also use a tailored /etc/apt/preferences:
Explanation: Dailymotion packages of a specific component should be more preferred
Package: *
Pin: release o=Dailymotion, l=dm-prod, c=role/*
Pin-Priority: 950
Explanation: Dailymotion packages should be preferred
Package: *
Pin: release o=Dailymotion, l=dm-prod
Pin-Priority: 900
Explanation: staging should never be preferred
Package: *
Pin: release o=Dailymotion, l=dm-staging
Pin-Priority: -100
By default, packages will have a priority of 500. By setting a priority of -100 to the staging distribution, we ensure the packages cannot be installed at all. This is stronger than NotAutomatic which sets the priority to 1. When a package exists in Ubuntu and in our local repository, we ensure that, if this is a production package, we will use ours by using a priority of 900 (or 950 if we match a specific role component). Have a look at the How APT Interprets Priorities section of apt_preferences(5) manual page for additional information. Keep in mind that version matters only when the priority is the same. To check if everything works as you expect, use apt-cache policy:
$ apt-cache policy php5-memcache
  Installed: 3.0.8-1~precise2~dm1
  Candidate: 3.0.8-1~precise2~dm1
  Version table:
 *** 3.0.8-1~precise2~dm1 0
        950 http://packages.dm.gg/dailymotion/ precise-prod/role/web amd64 Packages
        100 /var/lib/dpkg/status
     3.0.8-1~precise1~dm4 0
        900 http://packages.dm.gg/dailymotion/ precise-prod/main amd64 Packages
       -100 http://packages.dm.gg/dailymotion/ precise-staging/main amd64 Packages
     3.0.6-1 0
        500 http://packages.dm.gg/dailymotion/ precise/universe amd64 Packages
If we want to install a package from the staging distribution, we can use apt-get with the -t precise-staging option to raise the priority of this distribution to 990. Once you have tested your package, you can copy it from the staging distribution to the production distribution:
$ reprepro -C main copysrc precise-prod precise-staging wackadoodle

Local mirror of third-party repositories Sometimes, you want a software published on some third-party repository without to repackage it yourself. A common example is the repositories edited by hardware vendors. Like for an Ubuntu mirror, there are two steps: defining the distribution and defining the source. We chose to put such mirrors into the same distributions as our local packages but with a dedicated component for each mirror. This way, those third-party packages will share the same workflow as our local packages: they will appear in the staging distribution, we validate them and copy them to the production distribution. The first step is to add the components and an appropriate Update line to conf/distributions:
Origin: Dailymotion
Label: dm-staging
Suite: precise-staging
Components: main role/dns role/database role/web vendor/hp
Update: hp
# [...]
Origin: Dailymotion
Label: dm-prod
Suite: precise-prod
Components: main role/dns role/database role/web vendor/hp
# [...]
We added the vendor/hp component to both the staging and the production distributions. However, only the staging distribution gets an Update line (remember, packages will be copied manually into the production distribution). We declare the source in conf/updates:
# HP repository
Name: hp
Method: http://downloads.linux.hp.com/SDR/downloads/ManagementComponentPack/
Suite: precise/current
Components: non-free>vendor/hp
Architectures: i386 amd64
VerifyRelease: 2689B887
GetInRelease: no
Don t forget to add the GPG key to your local keyring. Notice an interesting feature of reprepro: we copy the remote non-free component to our local vendor/hp component. Then, you can synchronize the mirror with reprepro update. Once the packages have been tested, you will have to copy them in the production distribution.

Building Debian packages Our reprepro setup seems complete, but how do we put packages into the staging distribution? You have several options to build Debian packages for your local repository. It really depends on how much time you want to invest in this activity:
  1. Build packages from source by adding a debian/ directory. This is the classic way of building Debian packages. You can start from scratch or use an existing package as a base. In the latest case, the package can be from the official archive but for a more recent distribution or a backport or from an unofficial repository.
  2. Use a tool that will create a binary package from a directory, like fpm. Such a tool will try to guess a lot of things to minimize your work. It can even download everything for you.
There is no universal solution. If you don t have the time budget for building packages from source, have a look at fpm. I would advise you to use the first approach when possible because you will get those perks for free:
  • You keep the sources in your repository. Whenever you need to rebuild something to fix an emergency bug, you won t have to hunt the sources which may be unavailable when you need them the most. Of course, this only works if you build packages that don t download stuff directly from the Internet.
  • You also keep the recipe3 to build the package in your repository. If someone enables some option and rebuild the package, you won t accidently drop this option on the next build. Those changes can be documented in debian/changelog. Moreover, you can use a version control software for the whole debian/ directory.
  • You can propose your package for inclusion into Debian. This will help many people once the package hits the archive.

Builders We chose pbuilder as a builder4. Its setup is quite straightforward. Here is our /etc/pbuilderrc:
DISTRIBUTION=$DIST
NAME="$DIST-$ARCH"
MIRRORSITE=http://packages.dm.gg/dailymotion
COMPONENTS=("main" "restricted" "universe" "multiverse")
OTHERMIRROR="deb http://packages.dm.gg/dailymotion $ DIST -staging main"
HOOKDIR=/etc/pbuilder/hooks.d
BASE=/var/cache/pbuilder/dailymotion
BASETGZ=$BASE/$NAME/base.tgz
BUILDRESULT=$BASE/$NAME/results/
APTCACHE=$BASE/$NAME/aptcache/
DEBBUILDOPTS="-sa"
KEYRING="/usr/share/keyrings/dailymotion-archive.keyring.gpg"
DEBOOTSTRAPOPTS=("--arch" "$ARCH" "--variant=buildd" "$ DEBOOTSTRAPOPTS[@] " "--keyring=$KEYRING")
APTKEYRINGS=("$KEYRING")
EXTRAPACKAGES=("dailymotion-archive-keyring")
pbuilder is expected to be invoked with DIST, ARCH and optionally ROLE environment variables. Building the initial bases can be done like this:
for ARCH in i386 amd64; do
  for DIST in precise; do
    export ARCH
    export DIST
    pbuilder --create
  done
done
We don t create a base for each role. Instead, we use a D hook to add the appropriate source:
#!/bin/bash
[ -z "$ROLE" ]    
  cat >> /etc/apt/sources.list <<EOF
deb http://packages.dm.gg/dailymotion $ DIST -staging role/$ ROLE 
EOF
 
apt-get update
We ensure packages from our staging distribution are preferred over other packages by adding an /etc/apt/preferences file in a E hook:
#!/bin/bash
cat > /etc/apt/preferences <<EOF
Explanation: Dailymotion packages are of higher priority
Package: *
Pin: release o=Dailymotion
Pin-Priority: 900
EOF
We also use a C hook to get a shell in case there is an error. This is convenient to debug a problem:
#!/bin/bash
apt-get install -y --force-yes vim less
cd /tmp/buildd/*/debian/..
/bin/bash < /dev/tty > /dev/tty 2> /dev/tty
A manual build can be run with:
$ ARCH=amd64 DIST=precise ROLE=web pbuilder \
>         --build somepackage.dsc

Version numbering To avoid to apply complex rules to chose a version number for a package, we chose to treat everything as a backport, even in-house software. We use the following scheme: X-Y~preciseZ+dmW.
  • X is the upstream version5.
  • Y is the Debian version. If there is no Debian version, use 0.
  • Z is the Ubuntu backport version. Again, if such a version doesn t exist, use 0.
  • W is our version of the package. We increment it when we make a change to the packaging. This is the only number we are allowed to control. All the others are set by an upstream entity, unless it doesn t exist and in this case, you use 0.
Let s suppose you need to backport wackadoodle. It is available in a more recent version of Ubuntu as 1.4-3. Your first backport will be 1.4-3~precise0+dm1. After a change to the packaging, the version will be 1.4-3~precise0+dm2. A new upstream version 1.5 is available and you need it. You will use 1.5-0~precise0+dm1. Later, this new upstream version will be available in some version of Ubuntu as 1.5-3ubuntu1. You will rebase your changes on this version and get 1.5-3ubuntu1~precise0+dm1. When using Debian instead of Ubuntu, a compatible convention could be : X-Y~bpo70+Z~dm+W.

Uploading To upload a package, a common setup is the following workflow:
  1. Upload the source package to an incoming directory.
  2. reprepro will notice the source package, check its correctness (signature, distribution) and put it in the archive.
  3. The builder will notice a new package needs to be built and build it.
  4. Once the package is built, the builder will upload the result to the incoming directory.
  5. reprepro will notice again the new binary package and integrate it in the archive.
This workflow has the disadvantage to have many moving pieces and to leave the user in the dark while the compilation is in progress. As an alternative, a simple script can be used to execute each step synchronously. The user can follow on their terminal that everything works as expected. Once we have the .changes file, the build script just issues the appropriate command to include the result in the archive:
$ reprepro -C main include precise-staging \
>      wackadoodle_1.4-3~precise0+dm4_amd64.changes
Happy hacking!

  1. The gpg/ directory could be shared by several repositories.
  2. We teached Debian Installer to work with our setup with an appropriate preseed file.
  3. fpm-cookery is a convenient tool to write recipes for fpm, similar to Homebrew or a BSD port tree. It could be used to achieve the same goal.
  4. sbuild is an alternative to pbuilder and is the official builder for both Debian and Ubuntu. Historically, pbuilder was more focused on developers needs.
  5. For a Git snapshot, we use something like 1.4-git20130905+1-ae42dc1 which is a snapshot made after version 1.4 (use 0.0 if no version has ever been released) at the given date. The following 1 is to be able to package different snapshots at the same date while the hash is here in case you need to retrieve the exact snapshot.

Russell Coker: Swap Breaking SSD

I ve seen many comments about swap space and SSD claiming that swap will inherently destroy SSD through using too many writes. The latest was in the comments of my post about swap space and SSD performance [1]. Note that I m not criticising the person who commented on my blog, everyone has heard lots of reports about possible problems that they avoid without analysing them in detail. The first thing to note is that the quality of flash memory varies a lot, the chips that are used in SSDs for workstation/server use are designed to last while those in USB-flash devices aren t. I ve documented my unsuccessful experiments with using USB-flash for the root filesystem of a gateway server [2] (and the flash device that wasn t used for swap died too). The real issue when determining whether swap will break your SSD is the amount of writes. While swapping can do a lot of writing quickly that usually doesn t happen unless something has gone wrong. The workstation that I m currently using has writes to the root fileystem outnumbering writes to swap by a factor of 130:1 (by volume of data written). On other days I ve seen it as low as 42:1, in either case it s writes to the root filesystem (which is BTRFS and includes /home etc) that will break the SSD if anything. For some other workstations I run I see ratios of 201:1 (that s with 8G of RAM), 57:1, and 23:1. In a quick search I couldn t find a single system I run where even 10% of disk writes were attributed to swap. This really isn t surprising given that adding RAM is a cheap way to improve the performance of most systems. If a SSD didn t do any write leveling (as is rumored to be the case with cheap USB flash devices) then swap use might still cause a problem because of the number of writes in a small area, but if that was the case then filesystem journals and other fixed data structures would be more likely to cause a problem and any swap based breakage would break swap not the root filesystem (although if swap was the first partition then it might also break the MBR). Of the workstations that are convenient to inspect the one with the most writes to the root filesystem and swap space (IE everything on /dev/sda) had 128G written per day for 1.2 days of uptime, but that involved running a filesystem balance and some torrent downloads (not the typical use). Among the two systems which had been running for more than 48 hours with typical use the most writes was 24G in a day. If a SSD can sustain 10,000 writes per block (which is smaller than quoted by most flash manufacturers nowadays) and has perfect wear leveling (which is unlikely) then the system with a 120G SSD and 128G written in a day could continue like that for almost 10,000 days or 27 years much longer than storage is expected to work or be useful. So for workstation use (where even 24G of writes per day probably counts as heavy use) a 120G SSD that can sustain 10,000 writes per block shouldn t be at great risk of wearing out. Conclusion I believe that swap is much less likely to break SSDs than regular file access on every system with a reasonable amount of RAM. For systems which don t have enough RAM you probably want the speed of SSD for swap space anyway in spite of the risks. If wear leveling works as designed and the 10,000+ writes per block claims are accurate then SSDs will massively outlast their useful life. Long before they wear out they should be too small, too slow, and probably not compatible. 26 years ago I had a 5.25 full height ST-506 disk in my desktop PC, it wouldn t physically fit in most systems I own now (unless I removed the DVD drive), there is no possibility of buying a controller (I don t own a system with an ISA bus), and that disk was too slow and small by today s standards. A 27yo SSD isn t going to be useful for anything, even for archive storage it s no good as no-one has tested long term storage and data could decay before then.

26 April 2014

Russell Coker: BTRFS Status April 2014

Since my blog post about BTRFS in March [1] not much has changed for me. Until yesterday I was using 2.13 kernels on all my systems and dealing with the occasional kmail index file corruption problem. Yesterday my main workstation ran out of disk space and went read-only. I started a BTRFS balance which didn t seem to be doing any good because most of the space was actually in use so I deleted a bunch of snapshots. Then my X session aborted (some problem with KDE or the X server I ll never know as logs couldn t be written to disk). I rebooted the system and had kernel threads go into infinite loops with repeated messages about a lack of response for 22 seconds (I should have photographed the screen). When it got into that state the ALT-Fn keys to change a virtual console sometimes worked but nothing else worked the terminal usually didn t respond to input. To try and stop the kernel from entering an infinite loop on every boot that I used rootflags=skip_balance on the kernel command line to stop it from continuing the balance which made the system usable for a little longer, unfortunately the skip_balance mount option doesn t permanently apply, the kernel will keep trying to balance the filesystem on every mount until a btrfs balance cancel operation succeeds. But my attempts to cancel the balance always failed. When I booted my system with skip_balance it would sometimes free some space from the deleted snapshots, after two good runs I got to 17G free. But after that every time I rebooted it would report another Gig or two free (according to btrfs filesystem df ) and then hang without committing the changes to disk. I solved this problem by upgrading my USB rescue image to kernel 3.14 from Debian/Experimental and mounting the filesystem from the rescue image. After letting kernel 3.14 work on the filesystem for a while it was in a stage where I could use it with kernel 3.13 and then boot the system normally to upgrade it to kernel 3.14. I had a minor extra complication due to the fact that I was running apt-get dist-upgrade at the time the filesystem went read-only do the dpkg records of which packages were installed were a bit messed up. But that was easy to fix by running a diff against /var/lib/dpkg/info on a recent snapshot. In retrospect I should have copied from an old snapshot of the root filesystem, but I fixed the problems faster than I could think of better ways to fix them. When running a balance the system had a peak IO rate of about 30MB/s reads and 30MB/s writes. That compares to the maximum contiguous file IO speed of 260MB/s for reads and 320MB/s for writes. During that time it had about 50% CPU time used for my Q8400 quad-core CPU. So far the only tasks that I do regularly which have CPU speed as a significant bottleneck are BTRFS filesystem balancing and recoding MP4 files. Compiling hasn t been an issue because recently I haven t been compiling many programs that are particularly big. Lessons Learned I should photograph the screen regularly when doing things that won t be logged, those kernel error messages might have been useful to me or someone else. The fact that the only kernel that runs BTRFS the way I need comes from the Experimental repository in Debian stands in contrast to the recent kernel patch that stops describing BTRFS as experimental. While I have a high opinion of the people who provide support for the kernel in commercial distributions and their ability to back-port fixes from newer kernels I m concerned about their decision to support BTRFS. I m also dubious about whether we can offer BTRFS support in Debian/Jessie (the next version of Debian) without a significant warning. OTOH if you find yourself with a BTRFS system that isn t working well you could always hire me to fix it. I accept payment via Paypal, bank transfer, or Bitcoin. If you want to pay me in Grange then I assure you I will never forget about it. ;) I thought that I wouldn t have CPU speed issues when I started using the AMD64 architecture, for most tasks that s been the case. But for systems for which storage is important I ll look at getting faster CPUs because of BTRFS. Using faster CPUs for storage isn t that uncommon (I used to work for SGI and dealt with some significant CPU power used for file serving), but needing a fast quad-core CPU to drive a single SSD is a little disappointing. While recovery from file system corner cases isn t going to be particularly common it s something that you want completed quickly, for personal systems you want to be doing something else and for work systems you don t want down-time. The BTRFS problems with running out of disk space are really serious. It seems that even workstations used at home can t survive without monitoring. For any other filesystem used at home you can just let it get full and then delete stuff. Include rootflags=skip_balance in the boot loader configuration for every system with a BTRFS root filesystem and in the /etc/fstab for every non-root BTRFS filesystem. I haven t yet encountered a single situation where continuing the balance did any good or when it didn t do any harm.

DebConf team: Registration is now open for DebConf14 (Posted by Steve Langasek)

Going to DebConf14!
The Debian Project is pleased to announce that registration is now open for DebConf14, taking place in Portland, Oregon, USA from Saturday, August 23 to Sunday, August 31, 2014. To request food, accommodation, or travel sponsorship, you must be registered by Thursday, May 15, 2014. After this date, registrations will still be accepted in any of the basic, professional, and corporate categories, but requests for sponsorship will no longer be accepted. Note that, as for previous years, you will be asked to confirm your registration later once sponsorship has been finalized. If you are not certain you will attend but are considering it, we encourage you to register now. Registration If you want to attend DebConf14, please fill out the registration form. This year, conference registration is integrated with the new Debian SSO system. If you are a Debian developer and have not previously used the Debian SSO system, you will need to configure an SSO password on db.debian.org. If you are not a Debian developer, you will have an opportunity to create an alioth account as part of the registration process. For more information about Debian single sign-on, see the Debian wiki. DebCamp In past years, DebConf has been preceded by a separate DebCamp event, for developers to gather before the conference and collaborate in person on Debian. This year the team is trying a different approach, with a longer conference period allowing for blocks of talks to be mixed with blocks of coding time throughout the week. More information about the schedule will be made available when the Call for Papers is posted in the near future. As mentioned in the last bits from the DPL mail, there is also an opportunity for Debian teams to organize sprints around DebConf. Teams who are interested should follow the documented process. Thank you The DebConf14 team would like to thank all of our sponsors who have made this event possible - a full list of whom can be found here. We are still seeking sponsors to help us make DebConf14 a success. If you or your company would like to give back to Debian, please consider becoming a sponsor. We look forward to seeing you in Portland in August! The DebConf team

25 April 2014

Matthias Klumpp: AppStream 0.6.1 released a quick look at what you can do with the cli tool

Today I released AppStream and libappstream 0.6.1, which feature mostly bugfixes, so nothing incredibly exciting to see there (but this also means no API/ABI breaks). The release clarifies some paragraphs in the spec which people found confusing, and fixes a few issues (like one example in the docs not being valid AppStream metadata). As only spec extension, we introduce a priority property in distro metadata to allow metadata from one repository to override data shipped by another one. This is used (although with a similar syntax) in Fedora already to have placeholder data for non-free stuff, which gets overridden by the real metadata if a new application was added. In general, the property tag was added to make the answer to the question which data is preferred much less magic. The libappstream library got some new API to query component data in different ways, and I also brought back support for Vala (so if you missed the Vapi file: It s back now, although you have to manually enable this feature). The CLI tool also got some extensions to query AppStream data. Here is a brief introduction: First of all, we need to make sure the database is up-to-date, which should be the case already (it is rebuilt automatically):
$ sudo appstream-index --refresh
The database will only be rebuilt when necessary, if you want to force a rebuild anyway, use the force parameter. Now imagine we want to search for an app containing the word media (in description, keywords, summary, ):
$ appstream-index -s media
which will return:
Identifier: gnome-media-player.desktop [desktop-app]
Name: GNOME Media Player
Summary: A simple media player for GNOME
Package: gnome-media-player
----
Identifier: mediaplayer-app.desktop [desktop-app]
Name: Media Player
Summary: Media Player
Package: mediaplayer-app
----
Identifier: kde4__plasma-mediacenter.desktop [desktop-app]
Name: Plasma Media Center
Summary: A mediacenter user interface written with the Plasma framework
Package: plasma-mediacenter
----
etc.
If we already know the name if a .desktop-file or the ID of a component, we can have the tool print out information about the application, including which package it was installed from:
$ appstream-index --get lyx.desktop
If we want to see more details, including e.g. a screenshot URL and a longer description, we can pass details to the tool:
Identifier: lyx.desktop [desktop-app]
Name: LyX
Summary: An advanced document processor with the power of LaTeX.
Package: lyx-common
Homepage: http://www.lyx.org/
Icon: lyx.png
Description: LyX is a document processor that encourages an approach to writing
 based on the structure of your documents (WYSIWYM) and not simply
 their appearance (WYSIWYG).
 
 LyX combines the power and flexibility of TeX/LaTeX[...]
Sample Screenshot URL: http://alt.fedoraproject.org/pub/alt/screenshots/f21/source/lyx-ea535ddf18b5c7328c5e88d2cd2cbd8c.png
License: GPLv2+
(I truncated the results slightly ;-) ) Okay, so far so good. But now it gets really exciting (and this is a feature added with 0.6.1): We can now query a component by the items it provides. For example, I want to know which software provides the library libfoo.2:
appstream-index --what-provides -t lib -v libfoo.so.2
This also works with binaries, or Python modules:
appstream-index --what-provides -t bin -v apper
This stuff works distribution-agnostic, and as long as software ships upstream metadata with a valid <provides/> field, or the distributor adds it while generating AppStream distro metadata.
This means that software can as soon as we have sufficient metadata of this kind declare it s dependencies upstream in form of a simple text file, referencing the needed components to build and run it on any Linux distribution. Users can simply install missing stuff by passing that file to their package manager, which can look up the components->packaging mapping and versions and do the right thing in installing the dependencies. So basically, this allows things pip -r does for Python, but for any application (not only Python stuff), and based on the distributors package database. With the provides-items, we can also scan software to detect it s dependencies automatically (and have it in a distro-agnostic form directly). We can also easily search for missing mimetype-handlers, missing kernel-modules, missing firmware etc. to install it on-demand, making the system much smarter in handling it s dependencies. And users don t need to do search orgies to find the right component for a given task. Also on my todo list for the future, based on this feature: A small tool telling upstream authors which distribution has their application in which version, using just one command (and AppStream data from multiple distros). Also planned: A cross-distro information page showing which distros ship which library versions, Python modules and application versions (and also the support status of the distro), so developers know which library versions (or GCC versions etc.) they should at least support to make their application easily available on most distributions. As always, you can get the releases on Freedesktop, as well es the AppStream specification.

Gerfried Fuchs: Que[e]rbau

I'm moving. Well, not right here, right now. Rather less than two years. But I already know what my flat will look like and was able to influence that decision. And there will be more to influence, like what to do with common rooms in the builing, or what to put in the garden (voting for climbing facilities for my son of course!). It's this kind of co-housing project where you already know your neighbours beforehand and can find common grounds for decisions like that. The co-housing project I'm moving to is called Que[e]rbau. And it will be living up to its name. It is specificly aimed at people who live tolerance and acceptance, and also potentially live an sorta alternative lifestyle, defining their own identity; but not limited to those. There also will be conventional families living there who specificly don't want to raise their kids in a conservative environment. When I told about this plan to someone they asked me if I really want to do that. Their concerns were with respect to my son and if the house wouldn't become a target. I was puzzled at first, given that we have the Rainbow Parade, the Life Ball and most of all the Rosa Lila Villa since several years in Vienna and I'm not aware of any bigger disturbances it causes, rather the opposite. After thinking a while about it it sounded a bit for the wish of a Don't Ask Don't Tell environment. Recently there was this great documentary done by Vice on youtube about Young and Gay in Putin's Russia (watch all five parts of it, it's worth it). In the light of that I don't think hiding does improve the situation, rather the opposite. Not speaking about it doesn't improve acceptance. And actually, I was approached by at least one person during the Debian Women MiniDebconf about how brave I am considered. I'm not sure if it really is brave, I just don't want to lie to myself anymore, and I very rarely had troubles through that. The more open and natural you behave, the less confrontation area you leave left, and people notice that. Not totally unrelated to that, I created myself a new gpg key. It doesn't carry my official name anymore but just the name I prefer to be addressed with: Rhonda. It also carries a last name you might not have heard yet (it was adopted on the Discworld MUD several years ago, even before I wrote Mermaids; actually in connection with the person who partly triggered the poem), that's the reason I added a plain Rhonda UID to it for those who aren't aware of the last name. I will submit that key to keysigning parties from now on, and it of course is up to you if you feel comfortable with signing it.

/personal permanent link Comments: 0 Flattr this

24 April 2014

Daniel Pocock: Android betrays tethering data

When I upgraded an Android device the other day, I found that tethering completely stopped working. The updated CyanogenMod had inherited a new bug from Android, informing the carrier that I was tethering. The carrier, Vodafone Italy, had decided to make my life miserable by blocking that traffic. I had a closer look and managed to find a workaround. There is absolutely no difference, from a technical perspective, between data transmitted from a mobile device on-screen application and data transmitted from tethering. Revealing the use of tethering to the carrier is a massive breach of privacy - yet comments in the Google bug tracker suggest it is a feature rather than a bug. This little table helps put that logic in perspective:
Product Person who carries handset
User Mobile network who wants to discriminate against some types of network traffic to squeeze more money out of the Product
Feature Revealing private information about the way the Product uses his/her Internet so the real User can profit.
It is also bad news for the environment: many people are being tricked into buying un-needed USB dongle modems that will end up in the rubbish in 1-2 years time when their contract expires and the company pushes them to upgrade to the next best thing. Behind the scenes What does it really mean in practice, how does Android tell your carrier which data is from tethering? As my device is rooted and as it is my device and I will do what I want with it, I decided to have a look inside. The ip command revealed that there are now two network devices, rmmnet_usb0 and rmmnet_usb1. The basic ip route command reveals that traffic from different source addresses is handled differently and split over the different network devices:
shell@android:/ # ip route
0.0.0.0/1 dev tun0  scope link
default via 100.66.150.89 dev rmnet_usb0
83.224.66.138 via 100.87.31.214 dev rmnet_usb1
83.224.70.94 via 100.87.31.214 dev rmnet_usb1
100.66.150.88/30 dev rmnet_usb0  proto kernel  scope link  src 100.66.150.90
100.66.150.89 dev rmnet_usb0  scope link
100.87.31.212/30 dev rmnet_usb1  proto kernel  scope link  src 100.87.31.213
100.87.31.214 dev rmnet_usb1  scope link
128.0.0.0/1 dev tun0  scope link
192.168.42.0/24 dev rndis0  proto kernel  scope link  src 192.168.42.129
I then looked more closely and found that there is also an extra routing table, it can be found with ip rule
shell@android:/ # ip rule show
0:      from all lookup local
32765:  from 192.168.42.0/24 lookup 60
32766:  from all lookup main
32767:  from all lookup default
shell@android:/ # ip route show table 60
default via 100.87.51.57 dev rmnet_usb1
100.87.51.57 dev rmnet_usb1
192.168.42.0/24 dev rndis0  scope link
In this routing table, it is obvious that data from the tethering subnet (192.168.42.0/24) is sent over the extra device rmnet_usb1. Manually cleaning it up If the phone is rooted, it is possible to very quickly change the routing table to get all the tethering traffic going through the normal rmnet_usb0 interface again. It is necessary to get rid of that alternative routing table first:
ip rule del pref 32765
and then update the iptables entries that refer to interface names:
iptables -t nat -I natctrl_nat_POSTROUTING -s 192.168.0.0/16 -o rmnet_usb0 -j MASQUERADE
iptables -I natctrl_FORWARD -i rmmnet_usb0 -j RETURN
This immediately resolved the problem for me on the Vodafone network in Italy. Conclusion If Google can be bullied into accepting this kind of discriminatory routing in the stock Android builds and it can even propagate into CyanogenMod, then I'm just glad I'm not running one of those Android builds that has been explicitly "enhanced" by a carrier. It raises big questions about who really is the owner and user of the device and who is receiving the value when a person pays money to "buy" a device.

Martin Pitt: Booting Ubuntu with systemd: Test packages available

On the last UDS we talked about migrating from upstart to systemd to boot Ubuntu, after Mark announced that Ubuntu will follow Debian in that regard. There s a lot of work to do, but it parallelizes well once developers can run systemd on their workstations or in VMs easily and the system boots up enough to still be able to work with it. So today I merged our systemd package with Debian again, dropped the systemd-services split (which wasn t accepted by Debian and will be unnecessary now), and put it into my systemd PPA. Quite surprisingly, this booted a fresh 14.04 VM pretty much right away (of course there s no Plymouth prettiness). The main two things which were missing were NetworkManager and lightdm, as these don t have an init.d script at all (NM) or it isn t enabled (lightdm). Thus the PPA also contains updated packages for these two which provide a proper systemd unit. With that, the desktop is pretty much fully working, except for some details like cron not running. I didn t go through /etc/init/*.conf with a small comb yet to check which upstart jobs need to be ported, that s now part of the TODO list. So, if you want to help with that, or just test and tell us what s wrong, take the plunge. In a 14.04 VM (or real machine if you feel adventurous), do
  sudo add-apt-repository ppa:pitti/systemd
  sudo apt-get update
  sudo apt-get dist-upgrade
This will replace systemd-services with systemd, update network-manager and lightdm, and a few libraries. Up to now, when you reboot you ll still get good old upstart. To actually boot with systemd, press Shift during boot to get the grub menu, edit the Ubuntu stanza, and append this to the linux line: init=/lib/systemd/systemd. For the record, if pressing shift doesn t work for you (too fast, VM, or similar), enable the grub menu with
  sudo sed -i '/GRUB_HIDDEN_TIMEOUT/ s/^/#/' /etc/default/grub
  sudo update-grub
Once you are satisfied that your system boots well enough, you can make this permanent by adding the init= option to /etc/default/grub (and possibly remove the comment sign from the GRUB_HIDDEN_TIMEOUT lines) and run sudo update-grub again. To go back to upstart, just edit the file again, remove the init=sudo update-grub again. I ll be on the Debian systemd/GNOME sprint next weekend, so I feel reasonably well prepared now. :-) Update: As the comments pointed out, this bricked /etc/resolv.conf. I now uploaded a resolvconf package to the PPA which provides the missing unit (counterpart to the /etc/init/resolvconf.conf upstart job) and this now works fine. If you are in that situation, please boot with upstart, and do the following to clean up:
  sudo rm /etc/resolv.conf
  sudo ln -s ../run/resolvconf/resolv.conf /etc/resolv.conf
Then you can boot back to systemd. Update 2: If you want to help testing, please file bugs with a systemd-boot tag. See the list of known bugs when booting with systemd.

23 April 2014

Russ Allbery: On learning, growth, and trust

Here are two separate ideas about programming, Internet security, Internet architecture, and free software. Both of them are fundamental to everything those of us who work on free software are doing.
  1. Writing secure and reliable code is a highly complex and demanding task. It's something that one has to learn, like any other skilled profession. It's not something we're very good at teaching via any mechanism other than apprenticeship and experimentation. The field is changing quickly; if you took ten years off from writing security-critical code, you would expect to have to learn multiple new tools (static analysis, testing techniques, security features), possibly new programming languages, and not infrequently new ways of thinking about threat models and vulnerabilities.
  2. Nearly every computer user trusts tens of thousands of other programmers and millions of lines of code with their day-to-day computer security and reliability, without auditing that code themselves. Even if you have the skill required to audit the code (and very, very few people have the skill to audit all of the code that they use), you do not have the time. Therefore, our computer security is built on trust. We're trusting other programmers not to be malicious, which is obvious, but we're also trusting other programmers to be highly skilled, careful, cautious (but still fast and productive, since we quickly abandon software that isn't "actively developed"), and constantly adopting new techniques and treat models.
I think both of those principles are very widely understood and widely acknowledged. And, as we all know, both of those principles have failure modes, and those failures mean that our computers are nowhere near as secure as we would like them to be. There has been quite a lot of technical discussion about both of these principles in recent days and months, ranging from better code analysis and testing through the flaws in particular programming languages to serious questions about the trust model we use for verifying the code that we're running. I'm going to switch gears away from that discussion for a moment to talk about a social aspect. When a piece of code that one is using has a security vulnerability, it is not unusual to treat that as a trust failure. In other words, technical flaws are very quickly escalated to social flaws. This is less likely among practitioners, since we're all painfully aware of how many bugs we have in our own code, but it's still not unheard of, particularly if the authors of the code do not immediately and publicly show a socially-acceptable level of humility and contrition (in the middle of what is often a horrifically stressful experience). I think this reaction comes largely from fear. Anyone who has given it a moment's thought is painfully aware of just how much code they are running on trust, and just how many ways it could be compromised, accidentally or maliciously. And how frequently that code is compromised. The less control one has over a situation, the more terrifying it is, and the cold reality is that we have very little control over our computer security. There is a natural tendency, when afraid, to look for targets for that fear. Now, go back and think about the first principle. Anyone who has ever worked on or near free software is painfully aware that we have far more good ideas about how to improve computing and security than we have skilled resources to execute on those ideas. My own backlog of things that I've already thought about, know would be good ideas, and simply have to implement is probably longer than my remaining lifespan. I suspect that's the case for nearly all of us. In other words, we have a severe shortage of programmers who care and who have skill. We desperately need more skilled programmers who can write secure and reliable code. We may (and I think do) also need better tools, techniques, languages, protocols, and all the other machinery that we, as technical people, spend most of our time thinking about. But none of that changes the fact that we need more skilled people. In fact, it makes that need more acute: in addition to skilled people to write the code we use, we need skilled people to write the tools. Skilled people are not born. They're made. And in professions where training techniques are still in their infancy and where we don't have a good formal grasp on which techniques work, those skilled people are made primarily through apprenticeship, experimentation, and learning from failure. Worse, people who were skilled do not remain skilled without continually participating in that learning process. See the above point about a fast-changing field with evolving best practices. It's not enough to know how to write secure code to the best known practices today, or even enough to retrofit all of your existing code to current knowledge (which is often so large of an effort as to be practically impossible). You have to constantly, continually learn more, for which there is no reliable formal training. We have to try, fail, try again, and fail better. But failure that leads to a security vulnerability is treated as a loss of trust. We trusted that person to write secure code that we could use. They failed. Now we can't trust them. Based on the trust model of security, we should revoke their ability to try again and instead rely on people who have not failed, since that will make us more secure. Except now we just broke the learning process. And there's no such thing as a programmer who can stop learning. So what does that do to our resource pool? It's sadly ironic, but I believe the free software community writ large has a very serious collaboration problem: we do not tolerate each other's learning processes. This leads to a wide variety of social failures around hostile communities and the failures of meritocracy that other people have talked about at much greater length. But even if you set that all aside, it threatens our security. We need secure code, a lot of it, a lot more than we have right now. To get that code, we need people who can write it. We need to grow, encourage, and support those people and enable their learning processes. Code is written by people. If we rip people apart when they write bad, insecure code, we don't get better, secure code. We get fewer people writing security code. We get far fewer people writing security code in public, since some of the people who haven't been ripped apart will look at that experience and say, "No way am I going near that problem area. It's too scary. I don't want to end up like those programmers." Fewer people writing security code means fewer people learning how to write better security code. Fewer people capable of writing good, secure code is not a solution to any of our problems. If we do not tolerate, support, and encourage the learning process required to become a skilled programmer, or maintain one's skill in programming, we are destroying our future as a community. When you find code that is broken and badly written, you have found a problem that should be reported, analyzed, and corrected. You have also found a programmer who is about to have one of two very different types of experiences. Either they are about to learn how to become a better programmer, or they are about to be publicly shamed, humiliated, and treated as untrustworthy. Which branch they take is partly up to them, but it's also heavily influenced by how all of us react socially to the discovery of bad code. One of those branches leads to more good, secure code being written in the future. The other does not.

Gunnar Wolf: DrupalCamp starting in 5... 4... 3... 2... ( #DrupalCampMX )

Ok, so the day has come: Today begins the much awaited Drupal Camp Mexico City, yay! For those that cannot make it to Mexico City, I understand understood1 we would have live streaming of at least one of the rooms, but anyway, talks will be recorded, and will be put online later on. As for the talks schedule, here you have it. Yes, today my workmate and I will be giving a simple introduction to having a useful basic Drupal install. Today is the tutorials / workshops / BoF / hackathon day, and Thursday and Friday will be the more traditional talks days. Several of the talks on Thursday are grouped under the SymfonyDay track and will refer to the framework that serves as a base for Drupal 8. Anyway, for the Tweetheads among the readers of this post, I understand information will flow under the #DrupalCampMX tag.

Petter Reinholdtsen: Install hardware dependent packages using tasksel (Isenkram 0.7)

It would be nice if it was easier in Debian to get all the hardware related packages relevant for the computer installed automatically. So I implemented one, using my Isenkram package. To use it, install the tasksel and isenkram packages and run tasksel as user root. You should be presented with a new option, "Hardware specific packages (autodetected by isenkram)". When you select it, tasksel will install the packages isenkram claim is fit for the current hardware, hot pluggable or not. The implementation is in two files, one is the tasksel menu entry description, and the other is the script used to extract the list of packages to install. The first part is in /usr/share/tasksel/descs/isenkram.desc and look like this:
Task: isenkram
Section: hardware
Description: Hardware specific packages (autodetected by isenkram)
 Based on the detected hardware various hardware specific packages are
 proposed.
Test-new-install: mark show
Relevance: 8
Packages: for-current-hardware
The second part is in /usr/lib/tasksel/packages/for-current-hardware and look like this:
#!/bin/sh
#
(
    isenkram-lookup
    isenkram-autoinstall-firmware -l
)   sort -u
All in all, a very short and simple implementation making it trivial to install the hardware dependent package we all may want to have installed on our machines. I've not been able to find a way to get tasksel to tell you exactly which packages it plan to install before doing the installation. So if you are curious or careful, check the output from the isenkram-* command line tools first. The information about which packages are handling which hardware is fetched either from the isenkram package itself in /usr/share/isenkram/, from git.debian.org or from the APT package database (using the Modaliases header). The APT package database parsing have caused a nasty resource leak in the isenkram daemon (bugs #719837 and #730704). The cause is in the python-apt code (bug #745487), but using a workaround I was able to get rid of the file descriptor leak and reduce the memory leak from ~30 MiB per hardware detection down to around 2 MiB per hardware detection. It should make the desktop daemon a lot more useful. The fix is in version 0.7 uploaded to unstable today. I believe the current way of mapping hardware to packages in Isenkram is is a good draft, but in the future I expect isenkram to use the AppStream data source for this. A proposal for getting proper AppStream support into Debian is floating around as DEP-11, and GSoC project will take place this summer to improve the situation. I look forward to seeing the result, and welcome patches for isenkram to start using the information when it is ready. If you want your package to map to some specific hardware, either add a "Xb-Modaliases" header to your control file like I did in the pymissile package or submit a bug report with the details to the isenkram package. See also all my blog posts tagged isenkram for details on the notation. I expect the information will be migrated to AppStream eventually, but for the moment I got no better place to store it.

Gergely Nagy: GSoC2014: syslog-ng accepted projects

The Google Summer of Code 2014 programme reached another milestone recently: the accepted proposals were published, and over a thousand students were selected by nearly two hundred mentoring organisations, among them the syslog-ng project. We will be working with four students this year (twice we worked with last year), with more mentors, on a wider selection of projects. It was a tough decision to select the proposals, we received some very strong work this year.We would like to express our gratitude to both Debian, for giving us an extra slot (so we could accept four students instead of three), and Google and Carol Smith in particular, for allowing it, and putting up with our fumbling during the process.The accepted projects and students are: Good luck to all students, we're looking forward to working with you throughout the summer! Happy hacking!

22 April 2014

Steve Kemp: I've not commented on security for a while

Unless you've been living under a rock, or in a tent (which would make me slightly jealous) you'll have heard about the recent heartbleed attack many times by now. The upshot of that attack is that lots of noise was made about hardening things, and there is now a new fork of openssl being developed. Many people have commented about "hardening Debian" in particular, as well as random musing on hardening software. One or two brave souls have even made noises about auditing code. Once upon a time I tried to setup a project to audit Debian software. You can still see the Debian Security Audit Project webpages if you look hard enough for them. What did I learn? There are tons of easy security bugs, but finding the hard ones is hard. (If you get bored some time just pick your favourite Editor, which will be emacs, and look how /tmp is abused during the build-process or in random libraries such as tramp [ tramp-uudecode].) These days I still poke at source code, and I still report bugs, but my enthusiasm has waned considerably. I tend to only commit to auditing a package if it is a new one I install in production, which limits my efforts considerably, but makes me feel like I'm not taking steps into the dark. It looks like I reported only three security isseus this year, and before that you have to go down to 2011 to find something I bothered to document. What would I do if I had copious free time? I wouldn't audit code. Instead I'd write test-cases for code. Many many large projects have rudimentary test-cases at best, and zero coverage at worse. I appreciate writing test-cases is hard, because lots of times it is hard to test things "for real". For example I once wrote a filesystem, using FUSE, there are some built-in unit-tests (I was pretty pleased with that, you could lauch the filesystem with a --test argument and it would invoke the unit-tests on itself. No separate steps, or source code required. If it was installed you could use it and you could test it in-situ). Beyond that I also put together a simple filesystem-stress script, which read/wrote/found random files, computes MD5 hashes of contents, etc. I've since seen similar random-filesystem-stresstest projects, and if they existed then I'd have used them. Testing filesystems is hard. I've written kernel modules that have only a single implicit test case: It compiles. (OK that's harsh, I'd usually ensure the kernel didn't die when they were inserted, and that a new node in /dev appeared ;) I've written a mail client, and beyond some trivial test-cases to prove my MIME-handling wasn't horrifically bad there are zero tests. How do you simulate all the mail that people will get, and the funky things they'll do with it? But that said I'd suggest if you're keen, if you're eager, if you want internet-points, writing test-cases/test-harnesses would be more useful than randomly auditing source code. Still what would I know, I don't even have a beard..

Daniel Pocock: Automatically creating repackaged upstream tarballs for Debian

One of the less exciting points in the day of a Debian Developer is the moment they realize they have to create a repackaged upstream source tarball. This is often a process that they have to repeat on each new upstream release too. Wouldn't it be useful to:
  • Scan all the existing repackaged upstream source tarballs and diff them against the real tarballs to catalog the things that have to be removed and spot patterns?
  • Operate a system that automatically produces repackaged upstream source tarballs for all tags in the upstream source repository or all new tarballs in the upstream download directory? Then the DD can take any of them and package them when he wants to with less manual effort.
  • Apply any insights from this process to detect non-free content in the rest of the Debian archive and when somebody is early in the process of evaluating a new upstream project?
Google Summer of Code is back One of the Google Summer of Code projects this year involves recursively building Java projects from their source. Some parts of the project, such as repackaged upstream tarballs, can be generalized for things other than Java. Web projects including minified JavaScript are a common example. Andrew Schurman, based near Vancouver, is the student selected for this project. Over the next couple of weeks, I'll be starting to discuss the ideas in more depth with him. I keep on stumbling on situations where repackaged upstream tarballs are necessary and so I'm hoping that this is one area the community will be keen to collaborate on.

C.J. Adams-Collier: AD Physical to Virtual conversion Continued!

So I wasn t able to complete the earlier attempt to boot the VM. Something to do with the SATA backplane not having enough juice to keep both my 6-disk array and the w2k8 disk online at the same time. I had to dd the contents off of the w2k8 disk and send it to the SAN via nc. And it wouldn t write at more than 5.5MB/s, so it took all day.
cjac@foxtrot:~$ sudo dd if=/dev/sdb   \
  pv -L 4M -bWearp -s 320G   \
  nc 172.16.9.80 4242
cjac@san0:~$ nc -l 4242   \
  pv -L 4M -bWearp -s 320G   \
  sudo dd of=/dev/vg0/ad0
Anyway, I ve got a /dev/vg0/ad0 logical volume all set up now which I m exporting to the guest as USB. Here s the libvirt xml file: win2k8.xml No indication as to how long this will take. But I ll be patient. It will be nice to have the AD server back online. Physical_to_Virtual_Win2k8-Startup_Repair [edit 20140422T172033 -0700]
Physical_to_Virtual_Win2k8-Startup_Repair_Failure
Well, that didn t work [edit 20140422T204322 -0700]
Maybe if I use DISM ? Physical_to_Virtual_Win2k8-Startup_Repair_DISM [edit 20140422T204904 -0700] Yup. That did er!
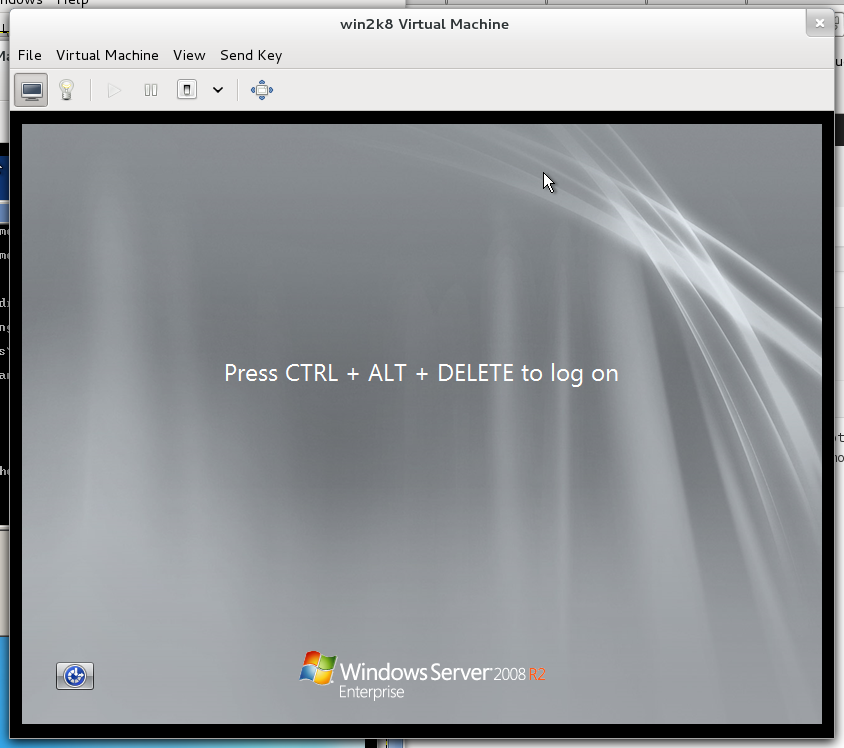
C:\>dism /image:c:\ /add-driver /driver:d:\win7\amd64\VIOSTOR.INF
Physical_to_Virtual_Win2k8-Login

Axel Beckert: GNU Screen 4.2.0 in Debian Experimental

About a month ago, on 20th of March, GNU Screen had its 27th anniversary. A few days ago, Amadeusz S awi ski, GNU Screen s new primary upstream maintainer, released the status quo of Screen development as version 4.2.0 (probably to distinguish it from all those 4.1.0 labeled development snapshots floating around in most Linux distributions nowadays). I did something similar and uploaded the status quo of Debian s screen package in git as 4.1.0~20120320gitdb59704-10 to Debian Sid shortly afterwards. That upload should hit Jessie soon, too, resolving the following two issues also in Testing: That way I could decouple these packaging fixes/features from the new upstream release which I uploaded to Debian Experimental for now. Testers for the 4.2.0-1 package are very welcome! Oh, and by the way, that upstream comment (or ArchLinux s according announcement) about broken backwards compatibility with attaching to running sessions started with older Screen releases doesn t affected Debian since that has been fixed in Debian already with the package which is in Wheezy. (Thanks again Julien Cristau for the patch back then!) While there are bigger long-term plans at upstream, Amadeusz is already working on the next 4.x release (probably named 4.2.1) which will likely incorporate some of the patches floating around in the Linux distributions packages. At least SuSE and Debian offered their patches explicitly for upstream inclusion. So far already two patches found in the Debian packages have been obsoleted by upstream git commits after the 4.2.0 release. Yay!

Erich Schubert: Kernel-density based outlier detection and the need for customization

Outlier detection (also: anomaly detection, change detection) is an unsupervised data mining task that tries to identify the unexpected.
Most outlier detection methods are based on some notion of density: in an appropriate data representation, "normal" data is expected to cluster, and outliers are expected to be further away from the normal data.
This intuition can be quantified in different ways. Common heuristics include kNN outlier detection and the Local Outlier Factor (which uses a density quotient). One of the directions in my dissertation was to understand (also from a statistical point of view) how the output and the formal structure of these methods can be best understood.
I will present two smaller results of this analysis at the SIAM Data Mining 2014 conference: instead of the very heuristic density estimation found in above methods, we design a method (using the same generalized pattern) that uses a best-practise from statistics: Kernel Density Estimation. We aren't the first to attempt this (c.f. LDF), but we actuall retain the properties of the kernel, whereas the authors of LDF tried to mimic the LOF method too closely, and this way damaged the kernel.
The other result presented in this work is the need to customize. When working with real data, using "library algorithms" will more often than not fail. The reason is that real data isn't as nicely behaved - it's dirty, it seldom is normal distributed. And the problem that we're trying to solve is often much narrower. For best results, we need to integrate our preexisting knowledge of the data into the algorithm. Sometimes we can do so by preprocessing and feature transformation. But sometimes, we can also customize the algorithm easily.
Outlier detection algorithms aren't black magic, or carefully adjusted. They follow a rather simple logic, and this means that we can easily take only parts of these methods, and adjust them as necessary for our problem at hand!
The article persented at SDM will demonstrate such a use case: analyzing 1.2 million traffic accidents in the UK (from data.gov.uk) we are not interested in "classic" density based outliers - this would be a rare traffic accident on a small road somewhere in Scotland. Instead, we're interested in unusual concentrations of traffic accidents, i.e. blackspots.
The generalized pattern can be easily customized for this task. While this data does not allow automatic evaluation, many outliers could be easily verified using Google Earth and search: often, historic imagery on Google Earth showed that the road layout was changed, or that there are many news reports about the dangerous road. The data can also be nicely visualized, and I'd like to share these examples with you. First, here is a screenshot from Google Earth for one of the hotspots (Cherry Lane Roundabout, North of Heathrow airport, which used to be a double cut-through roundabout - one of the cut-throughs was removed since):
Screenshot of Cherry Lane Roundabout hotspot
Google Earth is best for exploring this result, because you can hide and show the density overlay to see the crossroad below; and you can go back in time to access historic imagery. Unfortunately, KML does not allow easy interactions (at least it didn't last time I checked).
I have also put the KML file on Google Drive. It will automatically display it on Google Maps (nice feature of Drive, kudos to Google!), but it should also allow you to download it. I've also explored the data on an Android tablet (but I don't think you can hide elements there, or access historic imagery as in the desktop application).
With a classic outlier detection method, this analysis would not have been possible. However, it was easy to customize the method; and the results are actually more meaningful: instead of relying on some heuristic to choose kernel bandwidth, I opted for choosing the bandwidth by physical arguments: 50 meters is a reasonable bandwidth for a crossroad / roundabout, and for comparison a radius of 2 kilometers is used to model the typical accident density in this region (there should other crossroads within 2 km in Europe).
Since I advocate reproducible science, the source code of the basic method will be in the next ELKI release. For the customization case studies, I plan to share them as a how-to or tutorial type of document in the ELKI wiki; probably also detailing data preprocessing and visualization aspects. The code for the customizations is not really suited for direct inclusion in the ELKI framework, but can serve as an example for advanced usage.
Reference:
E. Schubert, A. Zimek, H.-P. Kriegel
Generalized Outlier Detection with Flexible Kernel Density Estimates
In Proceedings of the 14th SIAM International Conference on Data Mining (SDM), Philadelphia, PA, 2014.
So TLDR of the story: A) try to use more established statistics (such as KDE), and B) don't expect an off-the-shelf solution to do magic, but customize the method for your problem.
P.S. if you happen to know nice post-doc positions in academia:
I'm actively looking for a position to continue my research. I'm working on scaling these methods to larger data and to make them work with various real data that I can find. Open-source, modular and efficient implementations are very important to me, and one of the directions I'd like to investigate is porting these methods to a distributed setting, for example using Spark. In order to get closer to "real" data, I've started to make these approaches work e.g. on textual data, mixed type data, multimedia etc. And of course, I like teaching; which is why I would prefer a position in academia.

Next.

Previous.